Search Results: "nate"

18 June 2012

Gunnar Wolf: Turning failure into apparent success, and carrying on: e-voting in Jalisco

I will sound monothematic, but I have been devoting quite a bit of work to this topic lately: Trying to stop the advance of e-voting in Mexico, Latin America and the world. Why trying to stop it? Isn't technology supposed to help us, to get trustable processes? Yes, it's supposed to... but it just cannot achieve it, no matter how hard it is tried I won't get into explanations in this blog post, but there is plenty of information. Feel free to ask me for further details. Anyway Yesterday (Sunday, 2012-06-17) was the fifth simulated voting that will lead to the first wide-scale deployment of electronic voting booths in my country: About 10% of the population of the state of Jalisco (that means, ~500,000 people) will cast their votes on July 1st electronically. This particular case illustrates how simulated votings can be used to forge a lie: Pounce Consulting, the company that won the e-voting project for IEPC (Jalisco's voting authority), delivered their booths over 40 days late, just before the deadline for the project to be canceled. Oh, and by the way, it's the same company that just failed to deliver on time for another planned local authority (10% of the booths in the Federal District, where I live, where fortunately 100% of the votes will be cast on traditional, auditable and cheap paper). After this delay, five voting simulations were programmed, to get the local population acquinted with them. The first ones just failed to get the population's interest and had close to 40% failure rates (mainly regarding transmission). Several other "minor details" were reported, including mechanical details that allowed subsequent voters to see the vote of who had just left. Anyway, making long story short: The fifth and last simulation was held yesterday. Officially, it was finally successful (about time). As these booths include the "facilities" to communicate the results via the cellular network, but the populations where they are to be deployed do not yet have cellular coverage, 10% of the booths will have to be carried back to the Districtal Header (that can be a ~10hr trip) to be counted. Also, in all places, traditional paper stationery and paraphernalia will be printed just in case it is needed (and when will they now? When half of the votes are cast and lost?) Anyway... e-voting is still in its first stage in Mexico. Right now, I'm sure, no attempts to rig the election will be made (centrally). But every effort will be made (as it has been made) to dismiss the obviously big and nontrivial ways it has failed and will fail, and any problems will be labeled as "minor". And probably by 2018 we will be facing many more states (even nationwide) deployments. But propaganda fails to see the obvious: E-voting is more expensive, more complicated, leads to more possible failure states. E-voting should not be deployed in large-scale (i.e. more than a couple of hundred voters) elections. Electronic voting is insecure, violates secrecy, allows for fraud. No matter how many locks are put into it.

16 June 2012

Wouter Verhelst: Life: general update

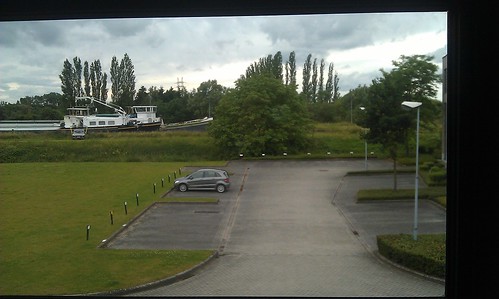
In case you were wondering what had happened to my blog over the past few weeks: the server on which it runs, samba.nixsys.be, has been down for that time, since we've just moved office. There's a story behind it, with which I won't bore you; suffice to say that we had to move out because of circumstances beyond our control. If you really do care, ask me over a beer or something (at debconf would be a good opportunity). I'll happily tell you the story. Meanwhile, the server on which this blog runs and which was located in a separate room at our office was now no longer available. But that's now over, albeit that it's behind a different IP address, and ignoring the fact that I still have some minor things to finish after the move. During this move, I found that we'd accumulated quite an amount of old unused hardware. While I've retained some of it (mostly my m68k machines, and some other machines that were given to me in order to add or improve Debian support for them), most of it has been given or thrown away. And that's even ignoring the other crap that had been in the cellar or the server/storage room. Oh my. I had severely underestimated the amount of work that would be required to clean out the office, which unfortunately also meant that I overshot the official date on which I were to leave the office by about two weeks. Luckily the landlord wasn't in a hurry or something, so no harm done. But I'll say this: if I ever say "yes" to anyone offering me some old decrepit hardware again for which I have no immediate purpose, may I be struck by lightning where I stand. Anyway. There's one significant advantage from this particular move: the view. I've gone from a dead wall to this: IMAG0004 Which is clearly an improvement... Additionally, now just over a month ago, my bother's fianc e gave birth to a boy, which makes me an uncle for the first time ever. Scary.

Steve Kemp: Sometimes the important things are those you don't do

Usually in life we focus upon the things we do, and not the things we don't do, or avoid. I don't have many "rules" for the way I behave, the things I do, but there are some. I could go on, but the "rules" are surprisingly hard to remember, having been in place for many years, they're just part of the way that I do (or do not do) things! Finally: As of this year I've now lived in Edinburgh for over half my life. ObQuote: "I don't know. We should go and like, stalk him or something. " - Megan Is Missing

15 June 2012

Jonathan Wiltshire: I m probably not going to DebConf12

For two years I have been very fortunate indeed to be fully sponsored for travel and accommodation at DebConf once on the Newbies programme, and once from normal funds. However, considering the cost this year (at least $1,000 in travel expenses) and of personal circumstances, which are not favourable, I am reliant on sponsorship this year even more than others. However, although I have accommodation sponsorship this year I am still waiting to hear about travel. The local team have said they hope to provide details by 20th June, but it s really too late by then there is time off from work to arrange, flight tickets to purchase, vaccinations to have, and of course I could really do with not having to lay out that much money in the first place, even if it s to be reimbursed later. So at this stage at least, I am sad to say that I think it unlikely I will be there. I m looking forward to Switzerland though; this time there might be two of us.
Comments
I m probably not going to DebConf12 is a post from: jwiltshire.org.uk Flattr

Matthew Garrett: No, really, secure boot does add security

Carla Schroder wrote a piece for linux.com on secure boot, which gives a reasonable overview of the technology and some of the concerns. It unfortunately then encourages everyone to ignore those legitimate concerns by making the trivially false claim that secure boot is just security theatre.

Security isn't some magic binary state where you're either secure or insecure and you can know which. Right now I'd consider my web server secure. If someone finds an exploitable bug in Apache then that would obviously no longer be the case. I could make it more secure by ensuring that Apache runs in a sufficiently isolated chroot that there's no easy mechanism for anyone to break out, which would be fine up until there's also a kernel exploit that allows someone to escalate their privileges enough to change their process root. So it's entirely possible that someone could right now be breaking into my system through bugs I don't even know exist. Am I secure? I don't know. Does that mean I should just disable all security functionality and have an open root shell bound to a well known port? No. Obviously.

Secure boot depends on the correctness of the implementation and the security of the signing key. If the implementation is flawed or if control of the signing key is lost then it stops providing security, and understanding that is important in order to decide how much trust you place in the technology. But much the same is true of any security technique. Kernel flaws make it possible for an unprivileged user to run with arbitrary privileges. Is user/admin separation security theatre? SSL certificate authorities have leaked keys. Is it security theatre for your bank to insist that you use SSL when logging in?

Secure boot doesn't instantly turn an insecure system into a secure one. It's one more technology that makes it more difficult for attackers to take control of your system. It will be broken and it will be fixed, just like almost any other security. If it's security theatre, so is your doorlock.

Why is this important? Because if you tell anyone that understands the technology that secure boot adds no security, they'll just assume that you're equally uninformed about everything else you're saying. It's a perfect excuse for them to just ignore discussion of market restrictions and user freedoms. We don't get anywhere by arguing against reality. Facts are important.

comment count unavailable comments

10 June 2012

C.J. Adams-Collier: Spinning up a telco with Asterisk

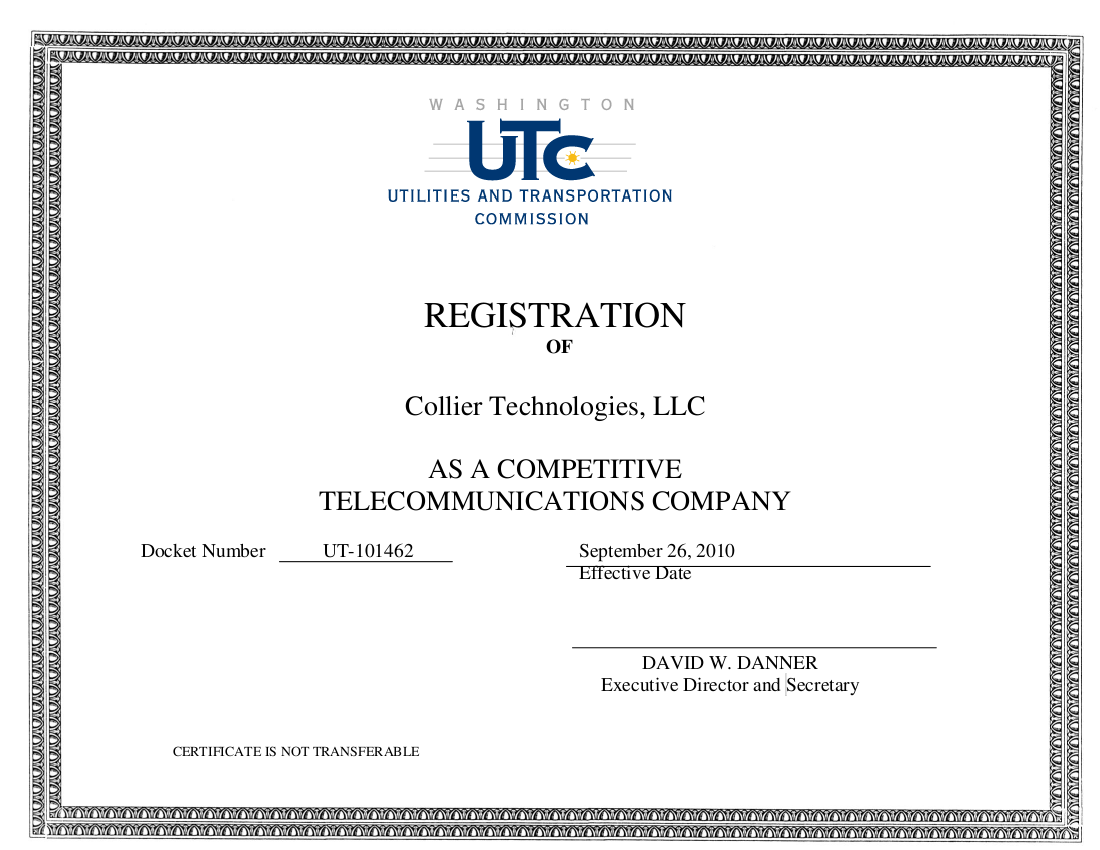
Back in 2010 our family moved to an island in an archipelago in the very top left of the US s continental 48. Before moving, we did some research regarding high speed network access. There are a number of ISPs in the county, and even one headquartered on our particular island. But we found that the location where we were moving was in a location that was only serviced by 1.5Mbit DSL. We had been spoiled in our previous two locations and had seen bittorrent swarms reach over 1 megabyte (8Mbit) per second. Our bill said 12 down and 2 up and I wouldn t be surprised if we achieved that. At any rate, we were disappointed by the speeds available and I wanted to do something to increase the availability of higher speed network access. Some of my friends from the North American Network Operators Group (NANOG) told me that one way to improve the infrastructure would be to get involved with telecommunications provisioning as a Competitive Local Exchange Carrier (CLEC). With the above in mind, I did some research and found that in my state, the authority which certifies and regulates telecommunication companies is the Washington Utilities and Transportation Commission (UTC). I found the application forms on their web site, filled them in, filed the appropriate documents with the appropriate departments and received a certificate in the mail shortly thereafter. We have since filed annual reports as required by regulations. And with the regulatory bits out of the way, we re now left with only the technical details. We have established collocation of some equipment near our state s central telecommunications facility at the Westin Building. Technically speaking, the equipment is not in the Westin, but at a facility connected to the Westin by multiple 10Gbit links. Close enough for me. On this equipment, we re running a Debian Squeeze Xen virtual machine and Digium s Asterisk packages:
cjac@sip0:/etc/asterisk$ grep -B1 -A3 Digium /etc/apt/sources.list
#
#  Digium asterisk packages
#
deb http://packages.asterisk.org/deb squeeze main
deb-src http://packages.asterisk.org/deb squeeze main
cjac@sip0:/etc/asterisk$ dpkg -l   grep digium
ii  asterisk                           1:1.8.11.1-1digium1~squeeze  Open Source Private Branch Exchange (PBX)
ii  asterisk-config                    1:1.8.11.1-1digium1~squeeze  Configuration files for Asterisk
ii  asterisk-core-sounds-en-gsm        1.4.21-1digium1~squeeze      asterisk PBX sound files - English/gsm
ii  asterisk-voicemail                 1:1.8.11.1-1digium1~squeeze  simple voicemail support for the Asterisk PBX
We saved up our nickles and dimes to purchase a 24-port analog telephony adapter (ATA). At the recommendation of one of the denizens of the #asterisk IRC channel on Freenode, we decided on the GrandStream GXW4024. It is pretty simple to configure them to register with the Asterisk server using SIP. The only problem we had was getting the RTP streams, and specifically their dynamically negotiated service ports, to traverse the NATting routers. We currently have no public IPv4 address space at the facility which hosts the ATA and so the rest of the internet sees all traffic originating from this facility as sourced from a single IP address. In order for this to work, the edge NAT/router device (in our case, BIG-IP LTM) needs to map its external L4 ports (TCP and UDP) to the ports of internal hosts so that traffic can flow correctly. This works fine for traffic which originates from internal hosts and is destined to hosts on the outside, but does not work so well when hosts on the outside wish to establish connections to hosts on the inside. Call management sessions established with the SIP protocol fall in the former category, but call media (voice, video, txt) sessions established with the RTP protocol fall into the latter; the host and port used to carry the media data are negotiated during the SIP session and the media socket is established out of band. The problem occurs when the call server (on the outside) attempts to establish an RTP stream with the caller (on the inside). The call server attempts to connect to the caller using the IP address from which it connected. The problem is that this address belongs to the NATting router, not the caller, and the router is not expecting the incoming request. To get around the NAT problem, we temporarily configured an OpenVPN tunnel to extend our L2 network segment. Our long-term solution will be to provision an Asterisk server in the same facility as the ATA and then register with it instead of the server in the exterior facility. Calls will then be switched at the local facility and the upstream link will be established using the IAX2 protocol, which does not suffer from the same NAT problems. All of the above provides us with the ability to make voice calls between the 24 channels of the ATA and any other SIP client which happens to be registered with our call server. This is all well and good, but we want to allow our customers to call the rest of the world. Enter our upstream provider, Threshold Communications, Inc. These folks are experienced and professional and have helped us successfully establish both outbound and inbound calling for very reasonable monthly costs. The call quality is indistinguishable from the lines provisioned by the local bell company, and inter-operates flawlessly with the Asterisk call server stack. Because calls transit our Asterisk server, we can add additional features such voicemail, speech to text, DTMF-driven menus, or call forwarding, for instance. We could even theoretically set up autopatch service using amateur frequencies or launch perl scripts to automate arbitrary fancyness. Our next step is to finish configuration of our 12-channel ZyXEL AAM1212 DSLAM modules so that we can deliver ADSL service over the same copper pairs as we deliver voice.

7 June 2012

Riku Voipio: Adventures in perlsembly

Some Debian packages are missing important optimizations. This one was noticed when comparing openssl benchmarks by monkeyiq to the results got on a pandaboard (OMAP 4430). Being a Cortex-A9, it should have clearly been same or faster than the N9 in the benchmark (OMAP 3630). And it was, except for AES benchmarks. Since AES is quite important, that seemed a bit odd. Turns out, that Debian/Ubuntu package had some hand-crafted arm assembler optimizations missing. Enable them, and the results with openssl speed command benchmark were quite nice:

The 'numbers' are in 1000s of bytes per second processed.

benchmark debian with patch +%
sha1 55836.67k -> 73599.08k +31.811%
aes-128 cbc 18451.11k -> 36305.34k +96.765%
aes-256 cbc 13552.30k -> 27108.31k +100.027%
sha256 20092.25k -> 43469.45k +116.349%
sha512 8052.74k -> 37194.28k +361.884 %
rsa 1024 1904.2v/S -> 3650.5v/s +91.708 %
Curiously, the assembler code is actually in perl files that output assembler code. This kind of code is affectionately called "perlsembly". A bug with patch has been filed, hopefully applied at the soonest.

Rog rio Brito: I am not going to DebConf 12

Due to some real life impediments (including a beautiful one with just over 2 months of life called Daniel), I will not be able to go to this year's DebConf, even though it seems that this DebConf will exceed many expectations with the support that the governement of Nicaragua just offered. Things that I would like to have worked on Unfortunately, this means that I will not be working with some fellows that may be there, like people from the pkg-multimedia team. In particular, as I am working on some packages that are not that well suited to distributions (especially regarding HandBrake), it would be highly productive to have a hacking session or two with other people interested in having this popular and easy-to-use video ripper/transcoder on Debian. I would also like to be able to talk in person with other people (including Joey Hess) about controversial packaging of some programs, like GNU Parallel, which I maintain in Debian. There are many things else that I would love to work on, besides helping a bit with some of the still pending transitions of the the Debian Fonts Task Force umbrella, meeting friends and other social stuff. Oh, well. I guess that working at home will be the solution for some time.

6 June 2012

Tim Retout: NMUs on the go

Today, as an experiment, I attempted to fix a Debian bug while on the train to work. I use a 3G card from Three.co.uk in my Lenovo Thinkpad x121e, and my commute is from Southampton Central to Fleet (changing at Winchester) - just under an hour. 3G coverage is not 100%, but tends to be better around the major stops. Thoughts: firstly, part of me is amazed that this is possible. Secondly, there could be a case for a local Debian mirror on my laptop. Otherwise, an interesting experimental extension to UDD would be "Required bandwidth" - the sum of the recursive build-dependencies plus the upload size of the diff/binaries.

4 June 2012

Niels Thykier: Parsing bash/shell

I have been avoiding #629247 for quite a while. Not because I think we couldn t use a better shell parser, but because I dreaded having to write the parser. Of course, #629247 blocks about 16 bugs and that number will only increase, so someone has to solve it eventually Unfortunately, that someone is likely to be me . So I managed to scrabble down the following Perl snippet. It does a decent job at getting lines split into words (which may or may not contain spaces, newlines, quotes etc.). It currently tokenizes the <<EOF -constructs (heredocs?). Also it does not allow one to distinguish between EOF and EOF (the former ends the heredoc, the latter doesn t.). Other defects includes that it does not tokenize all operators (like >& ). Probably all I need is a list of them and all the special cases (Example: >& can optionally take numbers on both sides, like >&2 or 2>&1 ). It does not always appear to terminate (I think EOF + unclosed quote triggers this). If you try it out and notice something funny, please let me know. You can also find an older version of it in the bug #629247 and the output it produced at that time (that version used instead of as token marker).
#!/usr/bin/perl
use strict;
use warnings;
use Text::ParseWords qw(quotewords);
my $opregex;
 
  my $tmp = join( " ", map   quotemeta $_   qw (&&     ; ));
  # Match & but not >& or <&
  # - Actually, it should eventually match those, but not right now.
  $tmp .= ' (?<![\>\<])\&';
  $opregex = qr/$tmp/ox;
 
my @tokens = ();
my $lno;
while (my $line = <>)  
  chomp $line;
  next if $line =~ m/^\s*(?:\# $)/;
  $lno = $. unless defined $lno;
  while ($line =~ s,\\$,,)  
  $line .= "\n" . <>;
  chomp $line;
   
  $line =~ s/^\s++//;
  $line =~ s/\s++$//;
  # Ignore empty lines (again, via "$empty \ $empty"-constructs)
  next if $line =~ m/^\s*(?:\# $)/;
  my @it = quotewords ($opregex, 'delimiters', $line);
  if (!@it)  
  # This happens if the line has unbalanced quotes, so pop another
  # line and redo the loop.
  $line .= "\n" . <>;
  redo;
   
  foreach my $orig (@it)  
  my @l;
  $orig =~ s,",\\\\",g;
  @l = quotewords (qr/\s++/, 1, $orig);
  pop @l unless defined $l[-1] && $l[-1] ne '';
  shift @l if $l[0] eq '';
  push @tokens, map   s,\\\\",",g; $_   @l;
   
  print "Line $lno: -" . join ("- -", map   s/\n/\\n/g; $_   @tokens ) . "-\n";
  @tokens = ();
  $lno = undef;
 
Here is a little example script and the tokenization of that script (no, the example script is not supposed to be useful).
$ cat test
#!/bin/sh
for p in *; do
    if [ -d "$p" ];then continue;elif
    [ -f "$p" ]
    then echo "$p is a file";fi
done
$ ./test.pl test
Line 3: -for- -p- -in- -*- -;- -do-
Line 4: -if- -[- --d- -"$p"- -]- -;- -then- -continue- -;- -elif-
Line 5: -[- --f- -"$p"- -]-
Line 6: -then- -echo- -"$p is a file"- -;- -fi-
Line 7: -done-

3 June 2012

Sandro Tosi: How to migrate your entire Google account to a new one

I've been using a Google account since years, but having a "more serious" one along. The time has come to make the switch and elect the other as main one.

Google has a lot of services, and I'm using several of them, so changing the main account requires to migrate data of those services to the new account, given it's not possible to merge two accounts. To know the full list of services your account is signed in, go to your Account Product page. Some migrations are easy, others hell no: so I'm writing this post to keep track of the migration as it's going on.

First of all, there's a really good post about this migration at LifeHacker: it contains a lot of info I'm using here, but not all the services I need. Additionally, Google has a list of services and methods to migrate from one account to another.

Just to be generic, I'll call AccountSRC the original account and AccountDST the one I want to migrate to.

Migrate GMail

GMail is probably the most important service I have, and also the most difficult one to migrate. I have a lot of filters, so the first step is to migrate them:
  1. Login into GMail for AccountSRC
  2. Gear icon > Settings > Labs
  3. Enable the "Filter import/export" plugin
  4. Reload GMail to enable the plugin (if not done automatically)
  5. Gear icon > Settings > Filters
  6. At the bottom of the page, Select all
  7. Export: this will download an XML file with the filters in it
  8. Login into GMail for AccountDST
  9. Enable "Filter import/export" plugin
  10. Load the file containing the saved filters
  11. Import all (or select which one) filters; this will also create automatically the labels defined in the filters.
I currently have a forward rule from AccountDST to AccountSRC: so let's revert the forward direction: from AccountSRC to AccountDST. This will allow the new account to receive the mails sent to the old one.
  1. Login into GMail for AccountDST
  2. Gear icon > Forwarding and POP/IMAP > Disable forwarding: this will stop redirecting mails from AccountDST to AccountSRC
  3. Login into GMail for AccountSRC
  4. Gear icon > Forwarding and POP/IMAP > add a forwarding address
  5. Enter AccountDST as the address to forward mails to
  6. A verification code is sent to AccountDST and you'll need to enter that code in AccountSRC to verify you have access to both mailboxes
  7. Once verified, select "Forward a copy of incoming mail to" to AccountDST and to delete the GMail copy on AccountSRC
There's no automatic way to migrate all your settings from the old GMail account to the new one, so you'll have to comparing settings pages to set what you had before to AccountDST. I suggest to first enable the labs you have on AccountSRC, and then go thru every page and report the configurations.

Did I forget something? yes, the hardest part: migrate mails! There are a lot of guides about migrating mails, the way I prefer is thru IMAP and Thunderbird (as described here): you'll move IMAP folders, and since they are equivalent to GMail labels, you'll automatically get your email with the correct labels (yes, the same mail appears in several folders, one for each label, and moving an email from one folder will not remove it from all the others).
  1. Enable IMAP access on both AccountSRC and AccountDST
  2. Open Thunderbird (or Icedove if you're on Debian like me) and register both accounts
  3. You can now start moving folders/emails from AccountSRC to AccountDST
    1. Copying a (missing) folder, will automatically create a label with the same name
    2. Moving a mail from the same folders on the two accounts will add the label called with the name of the folder to that email
  4. Be ready, it's a LOOOOONG process, but it's safe and it guarantees a perfect result
With the method above you have all the labels you had before, but not the label colors (and I have a lot :( ).

Another tool that's would be interesting to evaluate for this task is Gmvault.


Migrate Contacts

Contacts are available inside GMail:
  1. Login into GMail for AccountSRC
  2. On the combobox on top-left, select Contacts
  3. More > Export
  4. Export all the contacts in Google CSV, since it's specific to be re-imported
  5. Login into GMail for AccountDST
  6. Contacts > More > Import
  7. Select the previously saved file and import it

Migrate Reader

Migrating Reader subscriptions is easy:
  1. Login into Reader for AccountSRC
  2. Reader Settings -> Import/export
  3. Export your subscriptions in OPML format
  4. Now login into Reader for AccountDST
  5. Reader Settings -> Import/export
  6. And import the saved OPML file
Sadly, that doesn't migrate your starred items, but there's a (long & manual) solution here.


Migrate Blogger

Login to Blogger for AccountSRC; then, for each blog you have there do this dance:
  1. Select the blog
  2. Go into Settings > Permissions
  3. Add AccountDST as a new author: this will send an email to AccountDST GMail account
  4. Accept the invitation (this will ask you to create a new Blogger account for AccountDST if you don't already have one)
  5. Go back to to Blogger with AccountSRC
  6. Blog > Settings > Permissions
  7. Grand admin rights to AccountDST
At this point, both AccountSRC and AccountDST have admin rights; you can leave it as it is, or remove AccountSRC and so only AccountDST will be the admin (other shares should be kept unchanged). The same procedure is described in this Google support answer.

What can't be migrated as easily are all the profile settings you've done on AccountSRC. So profile information, blogs followed and so on have to be migrated by hand: boring but they are just few things, doable in a bunch of minutes.


Migrate Android phone

Android phones require a primary Google account to work, and of course my phone uses AccountSRC. Several sources say the only way to change primary account is to factory reset the phone. But since new market app supports multiple accounts and Android 4.0 (Ice Cream Sandwich) not longer needs a primary account, I just waited for the update to ICS to come.

What you really need to do is to add a new account, AccountDST, to Settings > Account & Sync, and all the Google apps on the phone will be able to use the new account (you might need to select what to sync, and the new account from inside each app).


Migrate Calendar

Even with Calendar the settings will have to be migrated by hand: they are just in one page, so just keep two windows opened and keep switching to sync them. The calendars are easy to move over: for the main calendar:
  1. Login into Calendars for AccountSRC
  2. Go into Settings > Calendars tab
  3. Select export calendars: this will download an archive of your calendars in a zip file; you will need to extract all the ics files from that zip archive so you'll have the main calendar readily available
  4. Login into Calendars for AccountDST
  5. Settings > Calendars tab
  6. Import the main calendar
for the other calendars you can do this way:
  1. Login into Calendars for AccountSRC
  2. Settings > Calendars tab
  3. Share the calendar with AccountDST and give it "Make changes AND manage sharing" right - the new account will have full control over that calendar

Migrate Docs

The procedure to migrate documents in Google Docs (now Google Drive) is described here, and it boils down to:
  1. Login into Docs for AccountSRC
  2. Select all the documents
  3. Share them with AccountDST
  4. In the same window select AccountDST as "is owner"
and you've got all the docs as owned by the new account.


Migrate Groups

There's no way to migrate all your Groups subscriptions from one account to another (if not playing with alternate email address, but it was too risky to try it), so you'll have to migrate all of them by hand.

On the other hand, if you've created some groups, that's possible to move them to the new account:
  1. Login into Groups for AccountSRC
  2. Enter in the "manage" area for the groups you've created
  3. Manage members > Invite members
  4. Invite AccountDST
  5. Accept the invitation, clicking on the email sent to AccountDST account
  6. Go back into AccountSRC manage area
  7. Select the AccountDST account
  8. Edit the subscription and set "Membership type" to "owner": now AccountDST is the owner of the list

Migrate Analytics

The process to migrate the account on Google Analytics is similar to Groups:
  1. Login into Analytics for AccountSRC
  2. Select Admin on top-right, then for each account you have
  3. Select the account, select "Users" tab, click on "+ New User"
  4. Enter AccountDST into the "Email Address" field and give that account the "Administrator" role
  5. Save
  6. Now AccountDST is able to access the same data on Analytics as AccountSRC

Migrate Picasa

To transfer your whole Picasa account follow these steps (as also described in this support post):
  1. Login into Picasa for AccountSRC
  2. Click on the gear on top-right > Photo Settings > Privacy and permissions
  3. On the "Migrate account" line click on "Migrate my photos"
  4. Insert AccountDST into the box for destination address
  5. In case you're using picasa to store blogger photos, also select the tick below
  6. At this point, AccountSRC will receive an email: copy the link in a session where you've logged in as AccountDST and then visit the page: that will start the process
  7. Wait until the transfer is completed: you'll receive an email to AccountDST when it's done

Migrate Google+

I'm not exactly a heavy user of G+ but I have some circles I'd like to move over (also because Reader sharing now works with G+ and it's a feature I user a lot), this is a process to move circles and contacts; as stated there, there's no way to move shared items and stuff (sad!).


Migrate AdSense

It's not possible to migrate the current AdSense account: you have to register a new one. When you do, it's possible that Google notice the new account is for the same person of the first one, and will ask to close the old account on AdSense in favor of the new one.


Migrate Alert

Alerts allows to export the list of alerts you've created but it's not possible to import that list in another Google account, so you'll have to recreate them from scratch (I had just a few so it was a matter of 1 minute or so).


Migrate Zoho Notebook

If you still miss Google Notebook (why big-G you let it die? couldn't you open-sourced it? it was so awesome! anyway...), you probably know that there are two main alternatives to it: Evernote and Zoho Notebook. I decided to go with Zoho (I'm not entirely happy with it, but it's running for now), and given it allows to login with Google account, it was currently using AccountSRC, so I need to migrate that too:
  1. Login into Zoho Notebook for AccountSRC
  2. My Account > Profile > Email address
  3. "Add new email" and add AccountDST, it will send a confirmation email
  4. Then "Make Primary" on AccountDST, so now the new account can login into Zoho notebook with the Google info and have all the notes there.

Migrate Bookmarks

Google provides a guide to migrate Bookmarks from one account to another that basically is:
  1. Login into Bookmarks for AccountSRC
  2. Click on Export bookmarks and it will save an HTML file with the bookmarks in it
  3. Import the file in a browser
  4. Use the Google toolbar to import in into AccountDST
That's kinda ugly way, but it seems to work.


Re-enable Web History

If you used History, then you need to re-enable it on the new account:
  1. Login into History for AccountDST
  2. Click on "Turn Web History on" to enable Web History on the new account
but it seems to be impossible to export/import or migrate the history from one account to another, that's a shame: years and years of stats lost.


Migrate Books

Books doesn't allow to migrate the contents between accounts, so you'll have to do it by hand:
  1. Select one book from AccountSRC, copying its link
  2. Go to AccountDST and navigate to the copied link
  3. Add the book to the right category, as it was before.

Migrate Webmaster Tools

Google released a document that describes how to migrate to another account; it's similar to Analytics and Groups migration.

In addition to that, you might also want to become an owner, that will give full control on the sites.


Did I forget some services? Let me know!

Everyone has a different experience with Google products, so in case you want me to let know how you migrated from one account to another for a product I didn't mentioned, just leave a comment and I'll edit the post (to be as complete as possible).

Jordi Mallach: GNOME 3.4 in wheezy

Users of Debian sid will have noticed: the final (and interesting) bits of GNOME 3.4 have landed and if all looks as good as it does now, they should migrate to wheezy in about a week. 3.2 3.4 hasn't been as complicated as the previous horrible transition, but still had some complications due to Cogl/Clutter incompatibilities. Other than that, our major problem has been manpower, but this isn't new for many other Debian teams. We've also seen new incarnations of Linux-only technology is now mandatory which makes our lives a bit more miserable due to kfreebsd-* and hurd-i386, but for now we've still been able to dodge it. It seems wheezy+1 will be fun in that regard though, and we might need to take drastic approaches. If all goes well and the current lot (GNOME Shell, Control Center, Settings daemon, Mutter...) transitions without additional problems, we should be wrapping up our transitions for wheezy with Evolution and friends (currently sitting in experimental), and hopefully GDM 3.4. As we get many questions regarding the status of GDM in Debian, let's add a short note on this. Packaging GDM, at least in its current upstream form, is not a matter of unpacking a new tarball and editing debian/changelog. When Joss works on a new major version, the amount of tweaking to break away from stuff that works on other distros but is not so simple in Debian is outstanding (see, for example, the current unfinished work for GDM 3.2 in our SVN repo). In our case, to handle our GDM defaults, we even need changes to the underlying configuration system, dconf. This evidently takes some effort to do, and unfortunately our GDM expert has had little time for Debian lately, but we're confident we'll end up with a GDM in wheezy that is on par with Debian standards. We are, as always, reachable at #debian-gnome in the OFTC IRC network. Have fun!

1 June 2012

Rapha&#235;l Hertzog: My Debian Activities in May 2012

This is my monthly summary of my Debian related activities. If you re among the people who made a donation to support my work (338.26 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Dpkg Like last month, I did almost nothing concerning dpkg. This will probably change in June now that the book is out The only thing worth noting is that I have helped Carey Underwood who was trying to diagnose why btrfs was performing so badly when unpacking Debian packages (compared to ext4). Apparently this already resulted in some btrfs improvements. But not as much as what could be hoped. The sync_file_range() calls that dpkg are doing only force the writeback of the underlying data and not of the meta-data. So the numerous fsync() that follow still create many journal transactions that would be better handled as one big transaction. As a proof of this, replacing the fsync() with a sync() brings the performance on par with ext4. (Beware this is my own recollection of the discussion, while it should be close to the truth, it s probably not 100% accurate when speaking of the brtfs behaviour) Packaging I uploaded new versions of smarty-gettext and smarty-validate because they were uninstallable after the removal of smarty. The whole history of smarty in Debian/Ubuntu has been a big FAIL since the start. Once upon a time, there was a smarty package and some plugins. Everything was great except that the files were installed in a way that differs from the upstream recommendations. So Ubuntu changed the path in their version of the package and did not check whether it broke anything else (and it did break all the plugins). Despite the brokenness of the plugins, this divergence survived for years. So several packages that were using Smarty were modified to use dpkg-vendor to use the correct path depending on whether it was built on Debian or Ubuntu. In 2010, Smarty 3.0 has been released and instead of upgrading the smarty package to this version, one of the smarty co-maintainers introduced a smarty3 package that used yet another path (despite the fact that smarty 3 had a mode to be compatible with smarty 2).

At some point, I informed him that he had to handle the migration of users of smarty to smarty3 he acknowledged and then lost interest in smarty ( I m no longer using it ) and did nothing. After some more bitrot, smarty has been forcefully orphaned in August 2011 by a member of the security team. And in March this year, it has been removed from unstable despite the fact that it still had reverse dependencies (usually removals only happen when they impact no other packages, I don t know why this wasn t the case here). At least the brokenness attracted some attention to the situation and Mike Gabriel contacted me about it. I offered him to take over the various packages since they all needed a real maintainer and he accepted. I sponsored his uploads of all smarty related packages (bringing in the latest upstream versions at the same time). In the end, the situation is looking better now, except that there s no migration path from users who rely on smarty in Squeeze. They will discover that they need smarty3 in Wheezy and that the various paths have to be adjusted. It s probably acceptable since the new upstream versions are no longer backwards compatible with smarty 2 The Debian Administrator s Handbook At the start of the month, I was busy preparing the release of the book. I introduced the publican-debian package to unstable, it s a Publican brand (aka a set of CSS and XSL stylesheets to tailor the output of Publican) using the Debian colors and using the Debian logo. This brand is used by the book. I also created the debian-handbook package and setup the public Git repository on alioth.debian.org. I was ready or so I thought. A few hours after the announce, the website became unusable because the numerous visitors were exhausting the maximum number of client connections. And I could not increase the limit due to Apache s memory usage (with PHP and WordPress). We quickly off-loaded most of the static files traffic to another machine and we setup bittorrent. The problem was solved for the short term. Thousands of persons downloaded the ebook and to this date, 135 copies of the paperback have been sold. Then I took a one-week vacation. Even though I had no Internet at the place I was, I wandered in the street to find a Freewifi wifi network (customers of the Free ISP can use those freely) to stay on top of incoming email. We quickly received some bug reports and I dealt with the easy ones (typos and the like) on the fly. When I came back at home, I manually placed 54 lulu orders for the people who opted for the paperback as reward during the fundraising campaign. A bit tedious but it had to be done (if only Lulu supported a way to batch many orders at once ). I also wanted a long term solution to avoid the use of an external host to serve static files (should a new traffic spike arrive ). So I installed nginx as a front-end. It serves static files directly, as well as WordPress pages which have been cached by wp-super-cache. Apache is still here listening on a local port and responding to the remaining queries forwarded by nginx. Once I ll migrate to wheezy, I might completely ditch apache in favor of php5-fpm to handle the PHP pages. Last but not least, I wanted to bootstrap the various translations that people offered to contribute. I wrote some documentation for interested translators and blogged about it. It s shaping up nicely check it out if you re interested to help! Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Francois Marier: Proper indentation of Javascript files using js2-mode in emacs

If you use emacs for Javascript or Node.js development, you should have a look at js2-mode (apt-get install js2-mode in Debian / Ubuntu). In addition to providing syntax highlight, it will parse your Javascript and issue errors and warnings. (It's not as pedantic as jslint or jshint so you'll probably want to fix all of them before committing your files.) Unfortunately the default indentation style looks a bit crazy and adds excessive indentation to your code. Here's an example:

navigator.id.secret.generate(identity, function (plainKey, wrappedKey)
var data = wrappedKey: wrappedKey ;
$.post('/loggedin', data, function (res)
$("#message").text('All done');
, 'json');
, function (error)
$("#message").text('ERROR: ' + error);
);
It turns out that indenting Javascript properly is really hard, but you can turn on a special flag which will cause the indentation to "bounce" between different strategies, starting with the most likely one. This is what I now have in my ~/.emacs:
(custom-set-variables
'(js2-basic-offset 2)
'(js2-bounce-indent-p t)
)
You can find and configure all other options by issuing the following command:
M-x customize-group [RET] js2-mode [RET]
So yes, you can have both the reasonable indentation of the standard js-mode and the helpful warnings and errors of js2-mode!

30 May 2012

Sorina Sandu: Initial commit

Hello!

I'm Sorina and this summer I will be working on Debian Installer network setup during Google Summer of Code. I am a second year bachelor's student at Politehnica University of Bucharest, I am studying Computer Science. I very much enjoy what I am doing even if sometimes I feel that the amount of stuff I want/have to learn/do/work on is infinite and I don't really know where to start.

I am at the beginning of the project, I believe now I am accustomed to the way things work and I am waiting forward to finishing the exam period so that I could really start working.

The hardest part for me in what I've done so far is testing what I am doing. It took me a while to figure out at least a part of how the installer functions and to solve the problems that occurred while building. Luckily, there is documentation and internet and even more important, I had help and support from my mentors.

So far I have only written two patches for netcfg, for bugs #610752 and #636211. For the first one I had a version for a while now, but I was unable to test it (unfortunately, it's likely that you will hear this a lot in the future). The idea was to make the link detection timeout preseedable and for this I have added two new templates, asking the user to provide a value for that matter.

The second one involved a missing "Go Back" button. This seemed to be the result of not letting debconf know that the program is capable of handling the user pressing a back button. That could be solved using deb_capb.

As I said before, testing was my main problem. Eventually, I built the image, wrote it to an USB and rebooted my laptop. This served its purpose, since I had access to anything I needed such as the wireless interface and physical access to the network cable. Running it through a virtual machine did not help much in this case, because I was unable to provide those.

Another thing I considered to be hard was blog posting, but now that I have just finished my first post it seems that I overreacted.

That's all for now, have a nice day!

Lucas Nussbaum: Debian archive rebuilds on Amazon Web Services

I like to think that archive rebuilds play an important role in Debian Quality Assurance and Release Management efforts. By trying to rebuild every Debian package from source, one can identify packages that do not build anymore due to changes in other packages (compilers, interpreters, libraries, ). It is also a good way to stress-test all packages that are involved in building other packages. Since 2007, I had been running Debian archive rebuilds on the Grid 5000 testbed, a research infrastructure for performing experiments on distributed systems HPC/Grid/Cloud/P2P. I filed more than 6000 release-critical bugs in the process. Late last year, Amazon kindly offered us a grant to allow us to run such QA tests on Amazon Web Services. With S bastien Badia, we ported the rebuild infrastructure to AWS (scripts), and several rebuilds have already been carried out on AWS. On the technical level, 50 to 100 EC2 spot instances are started, and then controlled from a master instance using SSH. On build instances, a classic sbuild setup is used. Logs are retrieved to the master node after rebuilds, and build instances are simply shut down when there are no more tasks to process. Several tasks are processed simultaneously on each instance, and when they fail, they are retried again with no other concurrent build on the same instance, to eliminate random failures caused by load or timing issues. All the scripts are designed to support other kind of QA tests, not just rebuilds. Moving to Amazon Web Services will facilitate sharing the human workload of doing those tests. It is now possible for developers interested in custom tests to do them themselves (hint hint).

29 May 2012

Daniel Kahn Gillmor: KVM, Windows XP, and Stop Error Code 0x0000007B

i dislike having to run Windows as much as the next free software developer, but like many sysadmins, i am occasionally asked to maintain some legacy systems. A nice way to keep these systems available (while not having to physically maintain them) is to put them in a virtual sandbox using a tool like kvm. While kvm makes it relatively straightforward to install WinXP from a CD (as long as you have the proper licensing key), it is more challenging to transition a pre-existing hardware windows XP installation into a virtual instance, due to Windows only wanting to boot to ide chipsets that it remembers being installed to. In particular, booting a disk image pulled from a soon-to-be-discarded physical disk can produce a Blue Screen of Death (BSOD) with the message:
Stop error code 0x0000007B
or
(INACCESSABLE_BOOT_DEVICE)
This seems like it's roughly the equivalent (in a standard debian GNU/Linux environment) of specifying MODULES=dep in /etc/initramfs-tools/initramfs.conf, and then trying to swap out all the hardware. At first blush, Microsoft's knowledge base suggests doing an in-place upgrade or full repartition and reinstall, which are both fairly drastic measures -- you might as well just start from scratch, which is exactly what you don't want to have to do for a nursed-along legacy system which no one who originally set it up is even with the organization any more. Fortunately, a bit more digging in the Knowledge Base turned up an unsupported set of steps that appears to be the equivalent of setting MODULES=most (at least for the IDE chipsets). Running this on the old hardware before imaging the disk worked for me, though i did need to re-validate Windows XP after the reboot by typing in the long magic code again. i guess they're keying it to the hardware, which clearly changed in this instance. Such silliness to spend time working around, really, when i'd rather be spending my time working on free software. :/

Jon Dowland: Debian Day

After a relatively long period of flux, I've managed to settle into a routine where I've got all the time I can dedicate to open source stuff bunched together: every Tuesday night. I've started calling it "Debian Day", although Debian won't get all that time exclusively. One evening a week doesn't sound like much, but that's unfortunately a realistic amount given my other commitments. Still, having a firm idea of how much resource I have makes planning what I can and can't do much easier. It also means I need to be quite selective about what I spend my time on. This also impacts the type of interactions I can use. I can respond to email, bugs, etc., but I cannot effectively interact with folks on IRC, for example: the period between windows is too large for it to work effectively. Therefore, I can't work reliably with any team or area of Debian that relies on IRC to get things done. Tonight, then. I have recently been ripping some CDs, a task for which I use grip, despite it long since having been dropped by Debian. It still works very well, whereas Sound Juicer, which still pops up whenever I insert an audio CD, does not. I've been interested in helping out with Debian GNOME packaging for a while, and it seems the issue has been fixed upstream, but after asking around in #debian-gnome, the root cause is that the newer musicbrainz API packages have not been uploaded to Debian. (the existing package uses the old API). Two separate people appear to have been working on a new Music Brainz package, but neither filed an ITP bug. I've spent the largest chunk of my Debian time just trying to figure out what has been going on, sadly, but at least there's the likelyhood this will be fixed for wheezy. There's also the tail end of a musicbrainz-2.1 transition finishing up. Another thing I considered this evening was the future of debgtd in Debian stable. On reflection, and after sitting on the fence for several months, I've decided I don't have the time to fix it up enough to have it ready for wheezy, so with regret I've filed a removal bug. With any luck, at some point in the wheezy cycle I'll manage to put more time towards this, because I think it addresses a genuine need and could be useful to people. Finally, whenever I sit down and look at Debian stuff to finish up, I have a strong temptation to fix some issues belonging to the games team. In particular, Gustavo Panizzo has put a lot of work into vavoom packages, but sadly his requests for sponsorship are falling on deaf ears. There's also Johey Shmit's work on packaging zdoom which needs some attention to finish removing some embedded libraries. I have to keep reminding myself I left the team for a reason, to focus on something else, and finding that something else should be the priority. So all in all not the most uplifting evening: I'm starting to think I simply couldn't work effectively with the Debian GNOME team without being able to dedicate more time to use IRC effectively; I spent more time that could be necessary figuring out a bunch of other folks have potentially wasted each other's time by working on packages and not filing ITPs; and I've removed one of my own packages from the distribution altogether. It's not all doom and gloom, though: last week I packaged Simon Howard's lhasa, a library and tool for decompressing LHA files, as used by various old DOS games. (See? I just can't escape that stuff ) I also managed to 'resolve' two bup bugs, one RC. I also finished transitioning from my old PGP key to my new one.

Martin-&#201;ric Racine: OpenWRT: accepting Router Adverts from the ISP in White Russian?

As we are getting closer to the World IPv6 Day, I thought that I'd see if I can upgrade my WRT54GL's OpenWRT (White Russian) installation to accept Router Adverts from the ISP to acquire an IPv6 address (rather than via a 4-to-6 tunnel broker, which seems to be the most documented case), and to propagate its IPv6 address space to my local network via my WRT45GL's radvd. Unfortunately, most of the instructions out there concern newer OpenWRT releases to which I cannot upgrade to because their software base takes up significantly more space than White Russian does. Still, I figure that someone in the community must have already succeeded at configuring their WRT54GL for this and might be able to help. Anyone? :)

28 May 2012

Vincent Bernat: Integration of NetSNMP into an event loop

NetSNMP comes with its own event loop based on the select() system call. While you can build your program around it, you may prefer to use an existing event loop, either a custom one or something like libevent, libev or Twisted.

Own custom event loop Let s start with the easiest case: you have written your own event loop. This means you make a call to select(), poll(), epoll(), kqueue() or something similar. All those functions take a set of file descriptors and wait for any of them to become available in a specified time frame. Here is a typical use of select() (adapted from Quagga)
readfd = m->readfd;
writefd = m->writefd;
exceptfd = m->exceptfd;
timer_wait = thread_timer_wait (&m->timer);
num = select (FD_SETSIZE,
              &readfd, &writefd, &exceptfd,
              timer_wait);
if (num < 0)
   
    if (errno == EINTR)
      continue; /* signal received - process it */
    zlog_warn ("select() error: %s",
               safe_strerror (errno));
    return NULL;
   
if (num == 0)
   
    /* Timeout handling */
    thread_timer_process (&m->timer);
   
if (num > 0)
   
    thread_process_fd (&readfd);
    thread_process_fd (&writefd);
   
thread_process_fd (fds) function iterates on each file descriptor fd and executes the appropriate action if FD_ISSET (fds, fd) is true. Integrating NetSNMP into such an event loop is easy: NetSNMP provides the snmp_select_info() function which alters a set of file descriptors to insert its own. Here is the new code:
#if defined HAVE_SNMP
struct timeval snmp_timer_wait;
int snmpblock = 0;
int fdsetsize;
#endif
/* ... */
#if defined HAVE_SNMP
fdsetsize = FD_SETSIZE;
snmpblock = 1;
if (timer_wait)
   
    snmpblock = 0;
    memcpy(&snmp_timer_wait, timer_wait,
           sizeof(struct timeval));
   
snmp_select_info(&fdsetsize, &readfd,
                 &snmp_timer_wait, &snmpblock);
if (snmpblock == 0)
  timer_wait = &snmp_timer_wait;
#endif
num = select (FD_SETSIZE,
              &readfd, &writefd, &exceptfd,
              timer_wait);
if (num < 0)   /* ... */  
#if defined HAVE_SNMP
if (num > 0)
  snmp_read(&readfd);
else if (num == 0)
   
    snmp_timeout();
    run_alarms();
   
netsnmp_check_outstanding_agent_requests();
#endif
/* ... */
snmp_select_info() may modify the provided set of file descriptors (and therefore, its size). It may also modify the provided timer in case it needs to schedule an action before the original timeout. snmpblock is a tricky variable. While select() can be called with a timeout set to NULL, this is not the case of snmp_select_info(): you have to pass a valid pointer. snmpblock is set to 0 if the provided timeout must be considered or to 1 otherwise. snmp_select_info() will set snmpblock to 0 if and only if it alters the timeout. Here are a two examples of integration. Both are for a subagent but the code for a manager is the same:

Third-party event loop With a third party event loop, you don t have access to the select() system call anymore. Therefore, you cannot alter it with snmp_select_info(). Instead, at each iteration of the loop, a list of SNMP related file descriptors is kept up-to-date with the help of snmp_select_info(): new ones are added and old ones are removed.

libevent Let s assume that snmp_fds is the list of current SNMP related events1. A function levent_snmp_update() calls snmp_select_info() to update this list. Here is a partial implementation (error handling removed and some declarations omitted, look at the complete version from lldpd):
static void
levent_snmp_update()
 
    int maxfd = 0;
    int block = 1;
    FD_ZERO(&fdset);
    snmp_select_info(&maxfd, &fdset, &timeout, &block);
    /* We need to untrack any event whose FD is not in  fdset 
       anymore */
    for (snmpfd = TAILQ_FIRST(snmp_fds);
         snmpfd;
         snmpfd = snmpfd_next)  
        snmpfd_next = TAILQ_NEXT(snmpfd, next);
        if (event_get_fd(snmpfd->ev) >= maxfd  
            (!FD_ISSET(event_get_fd(snmpfd->ev), &fdset)))  
            event_free(snmpfd->ev);
            TAILQ_REMOVE(snmp_fds, snmpfd, next);
            free(snmpfd);
          else
            FD_CLR(event_get_fd(snmpfd->ev), &fdset);
     
    /* Invariant: FD in  fdset  are not in list of FD */
    for (int fd = 0; fd < maxfd; fd++)
        if (FD_ISSET(fd, &fdset))  
            snmpfd->ev = event_new(base, fd,
                EV_READ   EV_PERSIST,
                levent_snmp_read,
                NULL);
            event_add(snmpfd->ev, NULL);
            TAILQ_INSERT_TAIL(snmp_fds, snmpfd, next);
         
    /* If needed, handle timeout */
    evtimer_add(snmp_timeout, block?NULL:&timeout);
 
Then, replace the main loop (usually, a call to event_base_dispatch()) with this:
do  
    if (event_base_got_break(base)  
        event_base_got_exit(base))
        break;
    netsnmp_check_outstanding_agent_requests();
    levent_snmp_update();
  while (event_base_loop(base, EVLOOP_ONCE) == 0);
Here is how are defined the two callbacks:
static void
levent_snmp_read(evutil_socket_t fd, short what, void *arg)
 
    FD_ZERO(&fdset);
    FD_SET(fd, &fdset);
    snmp_read(&fdset);
    levent_snmp_update();
 
static void
levent_snmp_timeout(evutil_socket_t fd, short what, void *arg)
 
    snmp_timeout();
    run_alarms();
    levent_snmp_update();
 

Twisted reactor As a second example, here is how to integrate NetSNMP into Twisted reactor. Twisted is an event-driven network programming framework written in Python. It does not come with support for SNMP2. Because of the language mismatch, the integration of NetSNMP in Twisted needs to be done using a C extension or the ctypes module. Twisted event loop is called a reactor. Like for libevent, events need to be registered. It is possible to register file descriptor-like objects using a class implementing a handful of methods. Here is the implementation of such a class (adapted from PyNetSNMP, a subproject of Zenoss using the ctypes module):
class SnmpReader:
    "Respond to input events"
    implements(IReadDescriptor)
    def __init__(self, fd):
        self.fd = fd
    def doRead(self):
        netsnmp.snmp_read(self.fd)
    def fileno(self):
        return self.fd
Like for libevent, we have a function to update the list of SNMP related events (stored as a mapping between file descriptors and SnmpReader instances):
class Timer(object):
    callLater = None
timer = Timer()
fdMap =  
def updateReactor():
    "Add/remove event handlers for SNMP file descriptors and timers"
    fds, t = netsnmp.snmp_select_info()
    for fd in fds:
        if fd not in fdMap:
            reader = SnmpReader(fd)
            fdMap[fd] = reader
            reactor.addReader(reader)
    current = Set(fdMap.keys())
    need = Set(fds)
    doomed = current - need
    for d in doomed:
        reactor.removeReader(fdMap[d])
        del fdMap[d]
    if timer.callLater:
        timer.callLater.cancel()
        timer.callLater = None
    if t is not None:
        timer.callLater = reactor.callLater(t, checkTimeouts)
Contrary to libevent, we cannot alter the main loop to call updateReactor() at each iteration. Therefore, it must be called after each SNMP related function. For another example, have a look at my equivalent implementation as a C extension.

Miscellaneous

Lack of asynchronicity Integrating NetSNMP into an event-based program is not risk-free. I have written a fairly comprehensive article on the lack of asynchronicity in NetSNMP AgentX protocol implementation. I urge you to read it if you want to integrate a SNMP subagent into an existing program. On the manager side, you will get similar drawbacks when using SNMPv3. To retrieve or manipulate management information using SNMPv3, it is necessary to know the identifier of the remote SNMP protocol engine. This identifier can be configured directly on each manager but it is usually discovered by querying SNMP-FRAMEWORK-MIB:: snmpEngineID, as described in RFC 5343. Unfortunately, this discovery is done synchronously by NetSNMP. There is a bug report for this issue but it seems difficult to fix. I have not been able to come up with a proper patch but I have described a workaround around snmp_sess_async_send(). There is no such problem with SNMPv2.

Limitation of file descriptor sets snmp_select_info() and snmp_read() uses the fd_set type to handle a set of file descriptors. This type should be manipulated with FD_CLR(), FD_ISSET(), FD_SET() and FD_ZERO(). Those may be defined as functions but they usually are macros. Moreover, no file descriptor greater than FD_SETSIZE (which is usually set to 1024) can be handled with the fd_set type. This means that if you have a file descriptor greater than 1024, you won t be able to use snmp_select_info() with it. Starting from NetSNMP 5.5, you can use snmp_select_info2() and snmp_read2() instead of snmp_select_info() and snmp_read(). They use the netsnmp_large_fd_set. If you want to keep compatibility with NetSNMP 5.4, here is another twist. The fd_set type is usually a fixed-size array of long integers. FD_CLR(), FD_ISSET() and FD_SET() are size-independant. The size only matters for FD_ZERO() which is not used by either snmp_select_info() or snmp_read(). You can therefore allocate a larger fd_set. A common way is to compile your program with -D__FD_SETSIZE=4096. You can still use FD_ZERO() yourself. However, this is not portable (GNU C Library only). Another way is to allocate your own array of long integers and cast it to fd_set. You ll have to redefine FD_ZERO():
typedef struct  
   long int fds_bits[4096/sizeof(long int)];
  my_fdset;
#undef FD_ZERO
#define FD_ZERO(fdset) memset((fdset), 0, sizeof(my_fdset))
 
   /* ... */
   my_fdset fdset;
   FD_ZERO(&fdset);
   /* ... */
   rc = snmp_select_info(&n, (fd_set *)&fdset, &timeout, &block);
   /* ... */
 

Threads NetSNMP provides two API:
  • the traditional session API which is not thread-safe and
  • the single session API.
In the above examples, I have used the traditional session API. If you are using threads, you need to ensure that all SNMP operations are done in a single thread. Otherwise, you need to adapt the examples to use the single session API. snmp_select_info() is part of the traditional session API. You should replace it with snmp_sess_select_info() and keep a list of SNMP sessions. This API is not available for the agent side of NetSNMP.

  1. The event list is global but some code could be added to bind a different list for each base in case you use different bases. This is not needed in the case of lldpd which uses only one event base.
  2. TwistedSNMP is an SNMP protocol implementation for Twisted based on PySNMP but is not maintained anymore. PySNMP comes with examples on how to integrate with Twisted.

Next.

Previous.