Search Results: "reg"

23 February 2014

Russell Coker: Electric Car Charging in Melbourne

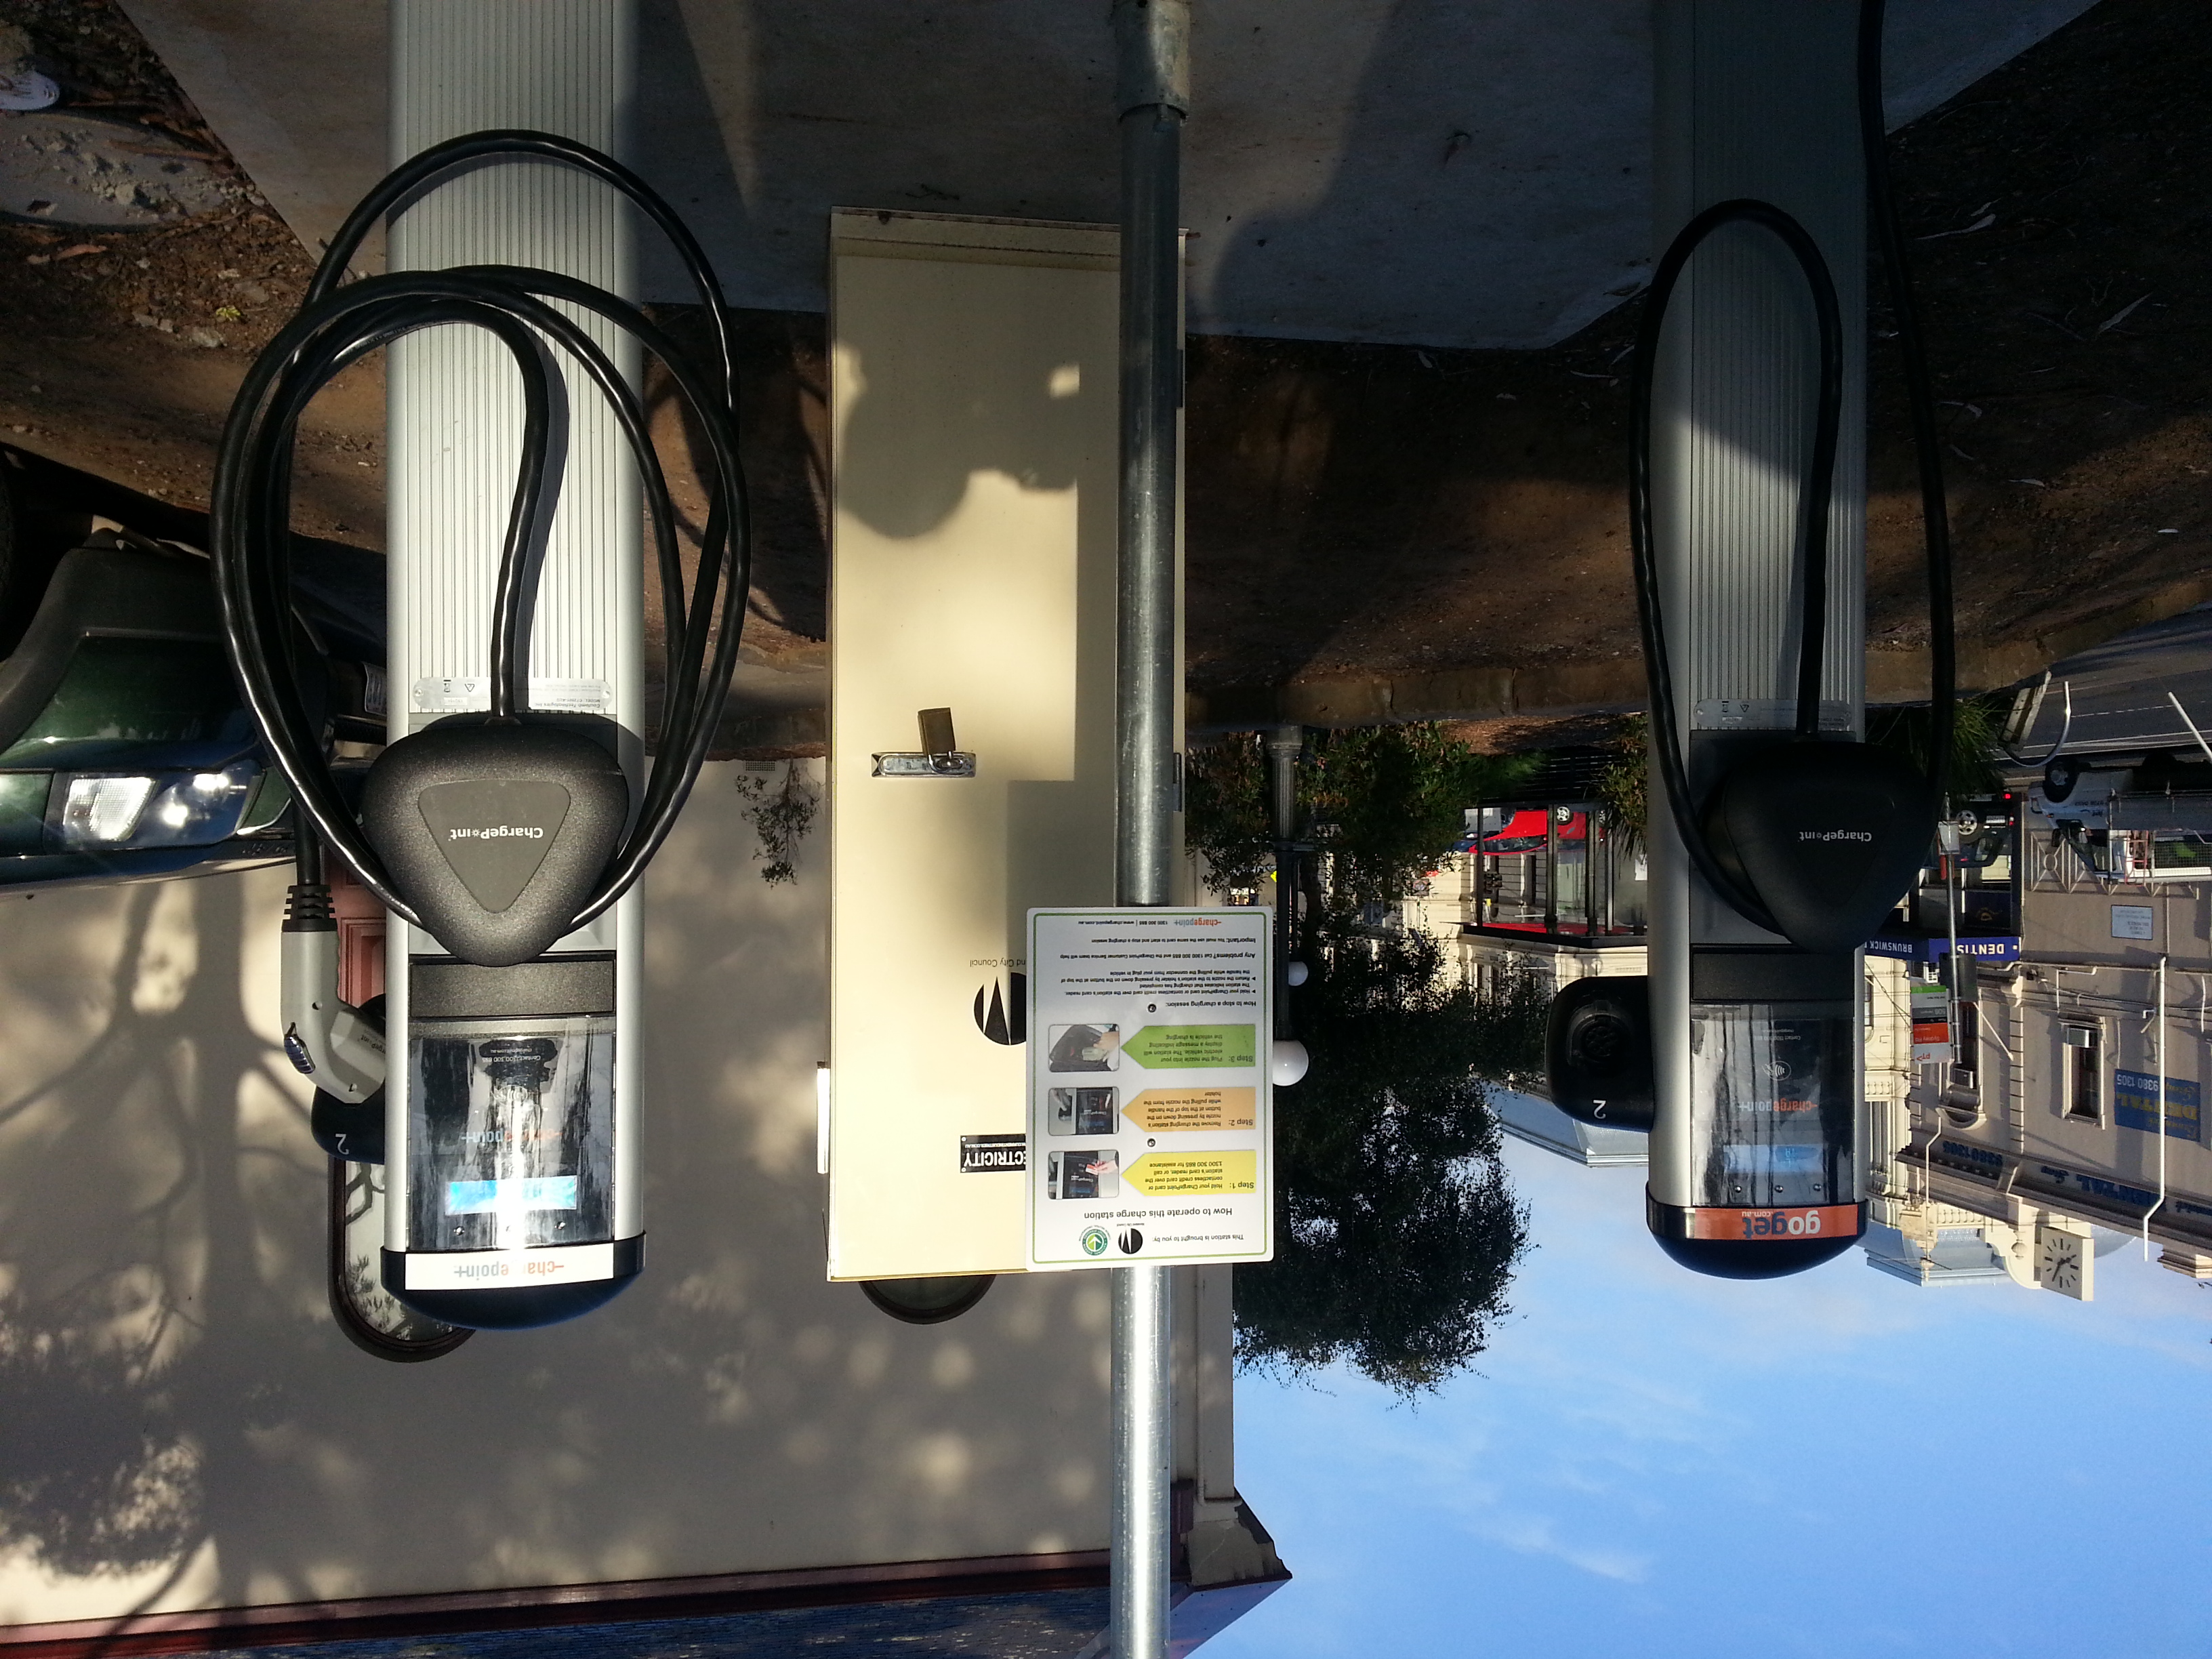
GoGet plug-in Prius chargingChargePoint Chargers This morning I noticed some parking bays reserved for car charging in a car park at the corner of Sydney Rd and Glenlyon St in Brunswick (near Aldi). One of the parking spots was occupied by a Plug-in Prius from GoGet [1]. I didn t even realise that you could get a plug-in Prius in Australia. The charging station is run by Charge Point [2]. The charging points are about 1.5m high and the cable is about 3cm thick (about as thick as the pipe used for filling a car with petrol), so it would charge a car much faster than could be done with a regular power point. One big problem with the Charge Point web site is that they don t give any information on pricing. They sell home charge points (which I guess means just an all-weather two-phase power point) but don t give a price for that. They sell charge points that can be used by commercially but don t give a price for them either. Also their infrastructure for billing is apparently based on companies installing charge points and setting a price for the service. Some charge points may offer free service (I guess staff car parks and some government agencies) and others will charge varying rates none of which is available on the web site. Apparently they have an online portal which gives information on such things to registered users so you have to register to discover what it costs. Of course hardly anyone is going to register before discovering the price, not even when registration is free. But while registration is free the web site demands the make and model of the electric car, so presumably one has to spend $40,000 or more on a vehicle before discovering the price and availability of charging it. Charge Point can be used as an example of how not to design a web site that promotes a service, or at least how not to promote a service that is aimed at saving money (electricity is significantly cheaper than petrol so it s of interest to people and organisations that want to save money). The Charge Point site seems to be better suited to showing that the concept can work than convincing people that they should sign up for it. It seems to me that the best thing that they could do would be to prominently display the average cost of all non-free charge points that are open to the public along with an explanation of the price of driving a desirable car (such as a plug-in Prius or a Nissan Leaf) with such an electricity cost. The contact section on the web site only has a link for careers . I don t think it s possible to get widespread use of electric vehicles without getting better information out there. It appears that Charge Point is relying on councils to do the work of promoting their business by installing their stations and reserving car parking as Moreland council has done in this case.

Vincent Cheng: Hello, Planet Debian! (also, RFH: sponsorship-requests)

Hi Debian! Just to briefly introduce myself, I'm Vincent (vcheng@d.o, vincent_c on OFTC/Freenode) and I'm a recent graduate of the NM process, having attained DD-ship (is that even a word?) about a month ago in January. Before that, I was a DM since mid-2012, and just another contributor for a few years prior to that. Most of my contributions to the Project are related to packaging, especially packages maintained within the Debian Games Team. Outside of Debian, well, I'm just another 20-year-old, 3rd-year undergrad student studying at the University of British Columbia, working towards a major in computer science. I anticipate that I'll be able to ditch academia for good in 2016; just 2 more years to go... More about my life story in my AM's report. It's fairly boring, if I say so myself. This blog post isn't just about me; I'd like to touch upon another topic that I consider important, i.e. attracting new contributors, and in many cases that involves package sponsorship. That's one of the many things I'd like to work on as a DD, and to that effect I've dedicated a large chunk of the time I currently spend on Debian sponsoring various packages, including packages that I'm not familiar with. I would love to see the sponsorship-requests queue empty one day, but I admit that I find that increasingly unlikely to happen, now that I've gotten a taste of the time commitment involved with sponsoring. Team maintenance and sponsorship seems to work relatively well in Debian; why does that success not translate over to sponsorship-requests / debian-mentors@l.d.o, where a considerable amount of RFS requests don't see any response at all, and merely get closed once those packages get removed from mentors.debian.net (AFAIK they automatically get removed after 20 weeks)? Well, I'm not here to offer an answer for that, but I will point out that there was a relevant thread that originated on debian-devel a month ago: <87ha8lzl7n.fsf@inf-8660.int-evry.fr> (and no, I'm not talking about the giant init-related threads that pop up on debian-devel every other week or so and drown out everything else on the list...). Are DDs in general reluctant to engage in "fly-by sponsoring"? Most packages coming through the sponsorship-requests queue are not team-maintained, and are sent from sponsorees who are not already in contact with a sponsor, and who have no other way of getting in touch with a potential sponsor (assuming that there isn't an existing team or a DD who happens to be interested in that package). Regardless of the merits of fly-by sponsoring (many arguments in favour of, and against, this type of sponsorship have already been discussed in that thread; no need to re-iterate them here), it's discouraging for potential contributors new to Debian, who may just give up and move on to something else. I've now had the opportunity to be a sponsor (rather than just a sponsoree), and I acknowledge that being a sponsor is more work than I imagined it to be a month ago, and it can be quite tedious and not-fun at times. I suppose I can draw a parallel between sponsoring packages and RC bug fixing; neither is what I'd consider to be a highly enjoyable way of spending my leisure time, and both can eat up a large chunk of time and effort; both often involve working on something that you aren't familiar with. But both are beneficial to Debian. No, beneficial isn't a strong enough word; how about "essential" instead? Yeah, that makes more sense. Without dedicated RC bug squashers, Debian would never be able to make a release; without dedicated sponsors, the size of Debian's archive would be smaller and of lesser quality, and its community also a lot smaller. With all that said...I hope this blog post inspires at least a few DDs, possibly more, to dedicate a little bit more of their time towards sponsoring packages. :)

22 February 2014

Dirk Eddelbuettel: RcppBDT 0.2.2

A new maintenance release of the RcppBDT package is now on CRAN. There is no new code in this; it mainly accomodates a request by CRAN to standardize the \code Imports: and \code Depends: relationships in the \code DESCRIPTION file. We also updated the build process now that we can use Rcpp 0.11.0. Having said that, there is a lot of new code in the git repository but I guess I'll talk about that when I can make a new upload. Yesterday, this balked because win-builder felt the need for a long long int in 64-bit mode which we can provide once C++11 will be permitted under R 3.1.0, due out in April. Oddly, no such need arose in 64-bit Linux. Oh well. The complete NEWS entry is below:
Changes in version 0.2.2 (2014-02-21)
  • Updates to current CRAN Policy standards for Depends: and Imports: in DESCRIPTION
  • Also take advantage of new Rcpp 0.11.0 build options
  • New code remains in GitHub repo master branch until R 3.1.0 is release so that we can use C++11 in order to get the long long int support without which the package does not build on Windows (whereas Linux is fine)
Courtesy of CRANberries, there is also a diffstat report for 0.2.2 relative to 0.2.1. As always, feedback is welcome and the rcpp-devel mailing list off the R-Forge page for Rcpp is the best place to start a discussion.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RDieHarder 0.1.3

A pure maintenance release of RDieHarder is now on CRAN. RDieHarder provides R bindings for the DieHarder battery of tests for random number generators by Brown et al. This release contains no new code, but the vignette needed to be moved from inst/doc to vignettes/ to help finalize that transition of the R / CRAN Package Policy. Courtesy of CRANberries, there is also a diffstat report relative to the previous release. As always, more detailed information is on the RDieHarder page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

20 February 2014

Dirk Eddelbuettel: RcppArmadillo 0.4.000.4

A new minor release of RcppArmadillo is now on CRAN and in Debian. RcppArmadillo brings the Armadillo templated C++ library for linear algebra to R by means of Rcpp. This release contains both a few minor bugfixes from the 4.000 branch of Armadillo and some enhancements in RcppArmadillo itself that are related to the recent Rcpp 0.11.0 release.
Changes in RcppArmadillo version 0.4.000.4 (2014-02-19)
  • Upgraded to Armadillo release Version 4.000.4
    • fix for randi() generating out-of-interval values
    • fix for saving field objects
    • workaround for a bug in the Intel compiler
  • Updated for Rcpp (>= 0.11.0) by removing linking step from build process, added appropriate dependency on Rcpp
  • Updated RcppArmadillo.package.skeleton function accordingly to use proper NAMESPACE import
  • Rewritten rcpparma_hello_world (which is used by the RcppArmadillo.package.skeleton function) to use Rcpp Attributes, and added more examples
  • Added two functions to set Armadillo's RNGs (ie the system RNG) from a given value and to randomize it, as suggested by G bor Cs rdi. Note that these do not work within RStudio (which itself also uses the same system RNG).
Courtesy of CRANberries, there is also a diffstat report for the most recent release As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

18 February 2014

Chris Lamb: Estimating Training Stress Score (TSS) for running on Strava

In cycling, a ride's Training Stress Score is a function of that ride's duration, average power and the intensity of the ride relative to the rider's capability. This Slowtwitch article provides a good overview on how intensity and TSS is calculated on a bike. However, having TSS values for other sports allows a multisport athelete to take into consideration the physiological cost of activities in different sports. This is achieved by ensuring, say, 50 TSS on the bike "counts" the same as a 50 TSS run. This can be used to simply determine the length, intensity and scheduling of the athletes next workout (to ensure adequate recovery) regardless of the combination of sports, or to identify the athlete's long-term tolerance to and targets for training load using metrics such as Chronic Training Load. To make this possible when using Strava, I wrote a Chrome extension that estimates the TSS score of a run from its Grade Adjusted Pace distribution:
https://chris-lamb.co.uk/wp-content/2014/strava-rtss.png

The "TSS (estimated)" value is calculated by the extension.

Source code is available. If you found this Strava extension useful, you might like my extensions to quickly switch between metric and imperial units or to change the default comparison filter.

17 February 2014

Martin Zobel-Helas: Have YOU registered Services at Debian Services Census?

Enrico and me have just started a census on Debian Services floating around, and we want YOU to participate!

The Debian Services Census is an attempt to gather detailed information about software services for the Debian community. It doesn't matter where these services live or who provides them. For now we are only interested in their existence.

Services can be anything from the mail forwarding service for @debian.org addresses that lives on master.debian.org operated by DSA, web applications, email bots, command line scripts you can run on debian.org machines, automated package checkers that report bugs to people, Debian-related services that people run on their own infrastructure like screenshots.debian.net and son on. Have a look at https://wiki.debian.org/Services for more examples.

If you think it's a service, then we think it's a service too and we want to know about it. Feel free to contribute data whether you are the maintainer of that service or not.

Here is how to let us know about the service:
  • please visit https://wiki.debian.org/Services and verify if the service is already listed there
  • if the service you had in mind is *not* listed, please create an entry for it using the "Add a new service" button.
If you are the maintainer of a service, we also encourage you to subscribe to the debian-services-admin@lists.debian.org mailing list, which is a low-traffic list and should be the contact point for inter-service communication and coordination.

Update: Up to now, 51 services have been registered (most of them within 24 hours after the d-d-a mail, WOW), but we are sure that there are a lot of more services, that still need to be registered. Help us to get a complete list!

16 February 2014

Mark Brown: Human factors

An issue which I always find depressing but sadly unsurprising in discussions of process with software is the frequent disregard for human elements; indeed often the goal people have in creating process is to try to control and eliminate human elements. Little thought is given to what is going to motivate people to do what s asked and if they are going to follow it at all, or in the spirit it was intended. One example I ve seen several times is the idea that some engineers work on irrelevant things and that this can be fixed by requiring every commit to be tied to the project plan or a bug so off project work is obvious. This isn t really attacking the problem so much as putting a roadblock in place to try to avert it; the real problem is normally people not communicating about what they re doing and what s important but those problems are really hard to address. Sadly what tends to happen is that people work around the roadblock and cause some collateral damage; for example devaluing the bug tracker by referencing irrelevant bugs or creating meaningless bugs solely to allow commits, while continuing to behave like they did originally. This is often worse than the original situation. This sort of issue is one of the things I appreciate most about working on Linux there s quite a bit of process but because of the way it has been evolved the incentives are usually right to make sure they are followed in the spirit in which they were intended. For example the patch submission process is essentially just best practices for making sure changes go to people who care in a form which makes it easy for them to work with it; there is a bunch of tooling around it which built on those practices (and in turn influenced the practices) but it all comes back to that basic thing of getting attention for changes and making them easy to work with. As a result people mostly do the right thing (or close enough) so everything runs smoothly. The trick is to remember to standardize and write things down when it s needed notice the good practice and spread its adoption. The key difference here seems to be if process is viewed as something to solve problems for people or if it is viewed as a way to solve problems with people. If the problem is with the people then the view starts off negative and it s perhaps unsurprising that there is little consideration of how they will react. Sometimes it s not so much that a problem is seen with people as that the people doing don t have any real interest in the process (write only timesheets often bear no relation to reality for example) but there is an assumption that they are going to just do what they re asked (but instead they for example don t fill in their time sheets or don t provide accurate information). The end result is the same, their needs don t get considered and their actions end up being counterproductive. Starting to avoid these problems is fairly straightforward take a step back and consider why the people expected to carry out the process are going to want to do so. How does it help them? How will they see it helping others? Generally what s in it for them? If these are difficult questions to answer then there may be a problem it is likely people will ignore the process or do it badly without a lot of active enforcement, but perhaps that s OK for the situation. Beware of using metrics to provide incentives, metrics are gameable and that game can cause problems without care. But do think about people; making software is all about people.

15 February 2014

Thomas Goirand: OpenStack 2013.2.2 uploaded

This is the 2nd point release of OpenStack Havana (this is the name of the current stable release of OpenStack). It was out on Thursday (US time), and I uploaded it on Friday (Chinese time). Unfortunately, I realized that the latest python-keystoneclient didn t support the token and endpoint command line options, effectively breaking Keystone itself, and all automated endpoint registration in all core packages. So after fixing Keystone and openstack-pkg-tools, I had to re-upload a 2nd Debian release. However, after this glitch, the packages passed successfully our CI testing suite: my friends at eNovance and I run the tempest functional test suite each time there s this kind of major update, so that we can validate the packages are working as expected. And all went well after the new keystone command line options were fixed in the postinst scripts. As a side note, I fail to see consistency on deprecating these interfaces. While we still have the old glance index thing in the Glance client (this is really old), keystoneclient just broke backward compatibility, when keystone is quite recent. So, it looks to me that it wasn t a great idea to just remove token and endpoint this way (though I can understand the need of consistency). Hopefully, this will all be fixed anyway, when we move to the unified python-openstackclient command lines instead of per-project clients. I realized today that the pkg-openstack team now maintains more than 100 packages. This of course includes general purpose Python modules, which probably will move to the Python module team if it one day supports Git (life is too short: I do not wish to learn such a deprecated technology as SVN). Though this is still a lot of packages, and some more are coming: as per the OpenStack TODO list wiki page, Ironic (a replacement for nova-baremetal), TripleO (OpenStack on OpenStack), Tuskar (contols where things are deployed with TripleO) and Designate (DNS as a Service) are already packaged, and I am waiting for the Icehouse (this is the name of the next stable release) beta3 to be out to upload them to Experimental. This is scheduled for the 6th of March. I believe I am currently nearly up-to-date with the current global-requirements.txt (eg: python dependencies of OpenStack), pending a few Python module upgrades, so hopefully, packaging OpenStack Icehouse beta3 will smooth.

13 February 2014

Erich Schubert: Google Summer of Code 2014 - not participating

Google Summer of Code 2014 is currently open for mentoring organizations to register. I've decided to not apply for GSoC with my data mining open source project ELKI anymore.

12 February 2014

Mario Lang: Roughly 1500 source packages have possibly broken links in debian/control

There are currently roughly 1500 source packages in Debian which possibly (very likely actually) do have broken URLs in debian/control. While it is quite useful that we have VCS information and Homepage URLs in the Packages file these days, we also created a rather big source of bitrot. These URLs are typically paste-and-forget. Sure, people occasionally catch the fact that a homepage or VCS has moved, especially if they are active and in good contact with their upstreams. However, there are also other cases...
DUCK to the rescue! My coworker Simon Kainz has worked on a service that helps at least to track which URLs are currently broken. We've initially discussed some way to make this a part of Lintian, which is what I would have prefered. However, for good reasons, Lintian doesn't want to call out to the net by default, so these checks would likely not get run by many developers anyway. So Simon ended up creating DUCK - the Debian Url ChecKer which actually goes out to the net and verifies that all the Vcs-* and Homepage fields of debian/control are actually reachable. The frontend allows developers to search for packages they maintain, to quickly see if they have any URLs which are possibly broken. There is a slight chance of temporary network problems of course, so what DUCK does is to show the status of checks in the last few days, so that you quickly see if you are dealing with a typical false positive. First of all, thanks to Simon! I think DUCK is an excellent project for a future NM candidate. I actually already wanted to advocate him for DD, but we ended up on a website which suggested that new contributors should start by applying for DM these days, and only later go for DD. I find that actually quite strange, especially in Simons case, but well, we did not feel like argueing. Secondly, and thats also very important: whats needed to improve the overall quality of URLs in the package system is your attention! You can easily search for email addresses of maintainers or uploaders. Team members can create a bookmark entry that checks for problems in all packages maintained by the teams they are a member of. You just need to actually visit these pages from time to time. It would probably not be well received if we filed all these bugs at once :-). So we need you to care, since we don't want to generate too much noise regarding "just these broken URLs". Or are they? If your vcs fields are broken, debcheckout will not work properly. Which defeats the purpose of debcheckout. If your homepage URL is broken, packages.d.o will also have a wrong link. 1500 packages with broken URLs. Don't you think we can do better then that?

Dirk Eddelbuettel: RInside 0.2.11

A new release 0.2.11 of RInside is now on CRAN. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by the Rcpp R and C++ integration package. This release, the first in fourteen months, fixes one important initialization issue created by the recent Rcpp 0.11.0 release, adds a few other changes related to that release and improves a number of small points such as new or improved examples. The NEWS extract below has more details.
Changes in RInside version 0.2.11 (2014-02-11)
  • Updated for Rcpp 0.11.0:
    • Updated initialization by assigning global environment via pointer only after R itself has been initialized with special thanks to Kevin Ushey for the fix
    • Updated DESCRIPTION with Imports: instead of Depends:
    • Added correspondiing importFrom(Rcpp, evalCpp) to NAMESPACE
    • Noted in all inst/examples/*/Makefile that Rcpp no longer requires a library argument, but left code for backwards compatibility in case 0.11.0 is not yet installed.
  • Added --vanilla --slave to default arguments for R initialization
  • Added a few more explicit #include statements in the qt example which Qt 5.1 now appears to require with thanks to Spencer Behling for the patch
  • Added new MPI example with worker functions and RInside instance, kindly contributed by Nicholas Pezolano and Martin Morgan
CRANberries also provides a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 February 2014

Dirk Eddelbuettel: RcppSMC 0.1.2

Late last week, and just before leaving to participate in this crazy thing, I managed to get a new version of RcppSMC onto CRAN. RcppSMC combines the SMCTC template classes for Sequential Monte Carlo and Particle Filters (Johansen, 2009, JSS) with the Rcpp package for R/C++ Integration (Eddelbuettel and Francois, 2011, JSS) and thereby allows for easier and more direct access from R to the computational core of the Sequential Monte Carlo algorithm. This release regroups a few minor changes we accumulated over the last few months, but was triggered by the Rcpp 0.11.0 release last week. The NEWS entry is below:
Changes in RcppSMC version 0.1.2 (2014-02-06)
  • Updated for Rcpp 0.11.0 with explicit importFrom in NAMESPACE and corresponding versioned Imports: in DESCRIPTION; also removed linking instruction from src/Makevars as no it is longer needed with this new Rcpp version
  • Addded GitHub / Travis CI support
  • Use more portable dev.new() rather than x11() in pfLinearBS.R
  • Applied some corrections to pfNonlinBS.R example
  • Converted NEWS to NEWS.Rd
Courtesy of CRANberries, there is also a diffstat report relative to the previous release. As always, more detailed information is on the RcppSMC page,

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

10 February 2014

Mario Lang: Neurofunkcasts

I have always loved Drum and Bass. In 2013 I rediscovered my love for Darkstep and Neurofunk, and found that these genres have developed quite a lot in the recent years. Some labels like Black Sun Empire and Evol Intent produce mixes/sets on a regular basis as podcasts these days. This article aggregates some neurofunk podcasts I like a lot, most recent first. Enjoy 33 hours and 57 minutes of fun with dark and energizing beats. Thanks to BSE Contrax and Evol Intent for providing such high quality sets. You can also see the Python source for the program that was used to generate this page.

Russell Coker: Fingerprints and Authentication

Dustin Kirkland wrote an interesting post about fingerprint authentication [1]. He suggests using fingerprints for identifying users (NOT authentication) and gives an example of a married couple sharing a tablet and using fingerprints to determine who s apps are loaded. In response Tollef Fog Heen suggests using fingerprints for lightweight authentication, such as resuming a session after a toilet break [2]. I think that one of the best comments on the issue of authentication for different tasks is in XKCD comic 1200 [3]. It seems obvious that the division between administrator (who installs new device drivers etc) and user (who does everything from playing games to online banking with the same privileges) isn t working, and never could work well particularly when the user in question installs their own software. I think that one thing which is worth considering is the uses of a signature. A signature can be easily forged in many ways and they often aren t checked well. It seems that there are two broad cases of using a signature, one is to enter into legally binding serious contract such as a mortgage (where wanting to sign is the relevant issue) and the other is cases where the issue doesn t matter so much (EG signing off on a credit card purchase where the parties at risk can afford to lose money on occasion for efficient transactions). Signing is relatively easy but that s because it either doesn t matter much or because it s just a legal issue which isn t connected to authentication. The possibility of serious damage (sending life savings or incriminating pictures to criminals in another jurisdiction) being done instantly never applied to signatures. It seems to me that in many ways signatures are comparable to fingerprints and both of them aren t particularly good for authentication to a computer. In regard to Tollef s ideas about lightweight authentication I think that the first thing that would be required is direct user control over the authentication required to unlock a system. I have read about some Microsoft research into a computer monitoring the office environment to better facilitate the user s requests, an obvious extension to such research would be to have greater unlock requirements if there are more unknown people in the area or if the device is in a known unsafe location. But apart from that sort of future development it seems that having the user request a greater or lesser authentication check either at the time they lock their session or by policy would make sense. Generally users have a reasonable idea about the risk of another user trying to login with their terminal so user should be able to decide that a toilet break when at home only requires a fingerprint (enough to keep out other family members) while a toilet break at the office requires greater authentication. Mobile devices could use GPS location to determine unlock requirements, GPS can be forged, but if your attacker is willing and able to do that then you have a greater risk than most users. Some users turn off authentication on their phone because it s too inconvenient. If they had the option of using a fingerprint most of the time and a password for the times when a fingerprint can t be read then it would give an overall increase in security. Finally it should be possible to unlock only certain applications. Recent versions of Android support widgets on the lock screen so you can perform basic tasks such as checking the weather forecast without unlocking your phone. But it should be possible to have different authentication requirements for various applications. Using a fingerprint scan to allow playing games or reading email in the mailing list folder would be more than adequate security. But reading the important email and using SMS probably needs greater authentication. This takes us back to the XKCD cartoon.

9 February 2014

Jan Dittberner: Going to Chemnitzer Linux-Tage 2014

This year I take care of organizing of the Debian booth at Chemnitzer Linux-Tage 2014 which has been approved a few days ago. The CLT is a yearly (mostly) german speaking Free Software community event which takes place on the weekend of 15th/16th march in Chemnitz (Germany). On the Linux-Live pages you find a lot of projects that will have a booth there and the talk schedule contains many interesting topics. There will also be a key signing event for which you can register until 11th of march. The Wiki page for the Event is already in a good shape. Many things are already organized, but we still have some items left. A lot of people from the Debian community have already told me that they will be there. We will have a Debian Wheezy BabelBox demonstration running on a VirtualBox host that Jan Wagner will provide as well as merchandising (Thanks to Alexander Wirt). Two talks from people on our Wiki page have been accepted by the CLT organizers too: I am happy to meet many nice people from the Free Software community in Chemnitz soon.

Neil Williams: Debian ARMMP in LAVA using iMX53

The home lab is my LAVA development environment and I ve recently got two iMX53 Quick Start Boards working with a typical LAVA master image based on a Linaro build of Linux 3.1.0 for mx5 with a Ubuntu Oneiric Ocelot 11.10 rootfs:
 3.1.0-1002-linaro-lt-mx5 (buildd@hubbard) (gcc version 4.6.1 (Ubuntu/Linaro 4.6.1-9ubuntu3) ) #13-Ubuntu PREEMPT Fri Dec 16 01:21:07 UTC 2011
As part of my Debian work, it was clearly time to look at a current, Debian, kernel and rootfs and as I m developing and testing on Debian unstable, this would necessarily mean testing the Debian ARMMP (multi-platform) kernel which replaces the mx5 build used in Wheezy.
Linux version 3.12-1-armmp (debian-kernel@lists.debian.org) (gcc version 4.8.2 (Debian 4.8.2-10) ) #1 SMP Debian 3.12.9-1 (2014-02-01)
I will be scripting the creation of a suitable image for these tests and there are other changes planned in LAVA to make it easier to build suitable images, but it is useful to document just how I worked out how to build the first image. Manual build steps First, I ve already discovered that the u-boot on the iMX53 doesn t like ext4, so the first step was to prepare an ext3 filesystem for the image. With a SATA drive attached, it was also much better to use that than the SD card, at least for generating the image. I m also doing this natively, so I am working inside the booted master image. This is fine as the master is designed to manipulate test images, so the only package I needed to install on the LAVA master image was debootstrap. I had an empty SATA drive to play with for these tests, so first prepare an ext3 filesystem:
# mkfs.ext3 /dev/sda1
# mkdir /mnt/sata
# mount /dev/sda1 /mnt/sata
# mkdir /mnt/sata/chroots/
Start the debootstrap:
# apt-get update
# apt-get install debootstrap
# debootstrap --arch=armhf --include=linux-image-armmp \
 --verbose unstable \
 /mnt/sata/chroots/unstable-armhf http://ftp.uk.debian.org/debian
Various actions in this chroot will need proc, so mount it here:
# chroot /mnt/sata/chroots/unstable-armhf
# mount proc -t proc /proc
# mount devpts -t devpts /dev/pts
# exit
You may also have to edit the apt sources the LAVA master image doesn t have editors installed, so either use echo or download an edited file. I m using:
deb http://ftp.uk.debian.org/debian sid main
flash-kernel needs changes For the initial tests, I ve got to get this image to boot directly from u-boot, so flash-kernel is going to be needed inside the chroot and to get the iMX53 to work with the ARMMP kernel and Device Tree, flash-kernel will need an update which will mean a patch:
# chroot /mnt/sata/chroots/unstable-armhf
# apt-get update
# apt-get install patch flash-kernel
# cp /usr/share/flash-kernel/db/all.db /home
# cd /home
# patch -p2
The patch itself goes through a couple of iterations. Initially, it is enough to use:
 Machine: Freescale MX53 LOCO Board
-Kernel-Flavors: mx5
+Kernel-Flavors: armmp
+DTB-Id: imx53-qsb.dtb
+DTB-Append: yes
Later, once the device has booted with the ARMMP kernel, the Machine Id can be updated to distinguish it from the mx5 flavour (from /proc/cpuinfo) and use the model name from the Device Tree (/proc/device-tree/model):
diff --git a/db/all.db b/db/all.db
index fab3407..41f6c78 100644
--- a/db/all.db
+++ b/db/all.db
@@ -62,6 +62,18 @@ U-Boot-Initrd-Address: 0x00800000
 Required-Packages: u-boot-tools
 Bootloader-Sets-Incorrect-Root: yes
 
+Machine: Freescale i.MX53 Quick Start Board
+Kernel-Flavors: armmp
+DTB-Id: imx53-qsb.dtb
+DTB-Append-From: 3.12
+Boot-DTB-Path: /boot/dtb
+U-Boot-Kernel-Address: 0x70008000
+U-Boot-Initrd-Address: 0x0
+Boot-Kernel-Path: /boot/uImage
+Boot-Initrd-Path: /boot/uInitrd
+Required-Packages: u-boot-tools
+Bootloader-Sets-Incorrect-Root: no
+
 Machine: Freescale MX53 LOCO Board
 Kernel-Flavors: mx5
 U-Boot-Kernel-Address: 0x70008000
(I will be filing this patch in a bug report against flash-kernel soon.) With that patched, update and run flash-kernel:
# mv all.db /usr/share/flash-kernel/db/all.db
# flash-kernel
flash-kernel: installing version 3.12-1-armmp
Generating kernel u-boot image... done.
Taking backup of uImage.
Installing new uImage.
Generating initramfs u-boot image... done.
Taking backup of uInitrd.
Installing new uInitrd.
Installing new dtb.
# exit
LAVA overlays This will be a LAVA test image and it needs an overlay if you want a vanilla image, set up a passwd inside the chroot instead.
# cd /mnt/sata/chroots/unstable-armhf/
# wget --no-check-certificate https://launchpad.net/~linaro-maintainers/+archive/overlay/+files/linaro-overlay-minimal_1112.2_all.deb
# wget --no-check-certificate https://launchpad.net/~linaro-maintainers/+archive/overlay/+files/linaro-overlay_1112.2_all.deb
# chroot /mnt/sata/chroots/unstable-armhf/
# dpkg -i linaro-overlay-minimal_1112.2_all.deb linaro-overlay_1112.2_all.deb
# rm linaro-overlay-minimal_1112.2_all.deb linaro-overlay_1112.2_all.deb
# exit
Changes to allow the chroot to boot Now the chroot needs setting up as a boot image:
# chroot /mnt/sata/chroots/unstable-armhf/
# echo T0:23:respawn:/sbin/getty -L ttymxc0 115200 vt102 >> ./etc/inittab
# echo auto lo eth0 > ./etc/network/interfaces.d/mx53loco
# echo iface lo inet loopback >> ./etc/network/interfaces.d/mx53loco
# echo iface eth0 inet dhcp >> ./etc/network/interfaces.d/mx53loco
# apt-get clean
# umount /dev/pts
# umount /proc
# exit
Partitioning as a LAVA test image This would be enough as a single partition test image but, currently, LAVA expects a much more hard-wired image. Depending on the history of the device and the need for LAVA to be able to put fresh kernel builds together with a known rootfs, LAVA has used a separate /boot and / partition in the test image for nearly all boards. Standard LAVA test images for many boards (like the iMX53) also have a small unallocated space at the start of the SD card, so until I can get LAVA upstream to handle test images of arbitrary design, I m adapting the image to suit the expectations inside LAVA. Yes, I know but it s better to get something working before spending time fixing things to make it work better. It will be fixed, in time. So I needed to separate out the /boot contents from the rest of the rootfs whilst keeping the chroot itself in a state which I can easily update and use to create other images.
# cd /mnt/sata/chroots/unstable-armhf/boot/
# tar -czf ../../boot.tar.gz ./*
# cd ..
# tar -czf ../root.tar.gz ./*
Now the test image file and its partitions:
# dd if=/dev/zero of=/mnt/sata/images/empty/debian.img bs=1M count=1024
# cp /mnt/sata/images/empty/debian.img /mnt/sata/images/debian-unstable-armhf-armmp.img
# losetup /dev/loop0 /mnt/sata/images/debian-unstable-armhf-armmp.img
# parted /dev/loop0 -s unit mb mktable msdos
# parted /dev/loop0 -s unit mb mkpart primary 1 10
# parted /dev/loop0 -s unit mb mkpart primary 11 110
# parted /dev/loop0 -s unit mb mkpart primary 111 1024
I did make the mistake of using kpartx at this stage but there are many areas of confusion when translating the kpartx output to offsets for mount when parted is easier:
# parted /dev/loop0 unit B -s print
Model:  (file)
Disk /dev/loop0: 1073741824B
Sector size (logical/physical): 512B/512B
Partition Table: msdos
Number  Start       End          Size        Type     File system  Flags
 1      1048576B    10485759B    9437184B    primary
 2      10485760B   110100479B   99614720B   primary
 3      110100480B  1024458751B  914358272B  primary
Use the Start numbers and use losetup to create the loop devices for each
partition
# losetup -o 10485760 /dev/loop1 /dev/loop0
# losetup -o 110100480 /dev/loop2 /dev/loop0
# mkfs.vfat /dev/loop1
# mkfs.ext3 /dev/loop2
Now clean up the loop mountpoints:
# losetup -d /dev/loop2
# losetup -d /dev/loop1
# losetup -d /dev/loop0
# losetup -a
losetup -a should return nothing. If it doesn t, investigate the contents of /dev/mapper and use dmsetup remove until losetup -a does report empty. Otherwise the subsequent stages will fail. Now deploy the /boot contents into the empty image:
# mount -oloop,offset=10485760 /mnt/sata/images/debian-unstable-armhf-armmp.img /mnt/boot/
# pushd /mnt/boot/
# tar -xzf /mnt/sata/chroots/boot.tar.gz
# popd
# sync
# umount /mnt/boot/
and the / contents (removing the duplicate ./boot contents)
# mount -oloop,offset=110100480 /mnt/sata/images/debian-unstable-armhf-armmp.img /mnt/root/
# pushd /mnt/root
# tar -xzf /mnt/sata/chroots/root.tar.gz
# rm ./boot/*
# popd
# sync
# umount /mnt/root
Check the image
# mount -oloop,offset=10485760 debian-unstable-armhf-armmp.img /mnt/boot
# ls /mnt/boot
config-3.12-1-armmp  initrd.img-3.12-1-armmp  System.map-3.12-1-armmp  uImage  uInitrd  vmlinuz-3.12-1-armmp
# umount /mnt/boot
# mount -oloop,offset=110100480 debian-unstable-armhf-armmp.img /mnt/root
# ls /mnt/root
bin  boot  dev  etc  home  initrd.img  lib  lost+found  media  mnt  opt  proc  root  run  sbin  srv  sys  tmp  usr  var  vmlinuz
# ls /mnt/root/bin/auto-serial-console
/mnt/root/bin/auto-serial-console
# umount /mnt/root
# md5sum debian-unstable-armhf-armmp.img
Downloads Yes, I have put that file online, if you are interested. Do read the readme first though. Getting the image off the device
# ip a
# python -m SimpleHTTPServer 80 2>/dev/null
then wget (just http://, IP address / and the filename), md5sum , finish with Ctrl-C. Depending on setup, it may be quicker to transfer the uncompressed
file over a LAN than to let the device compress it. Your main machine
will do the compression much faster, even with a larger download. (It also helps to not compress the image on the device, you can
test the mount offsets more easily and do check that the image
can be mounted with the offsets from parted.) Results
# cat /proc/cpuinfo
processor	: 0
model name	: ARMv7 Processor rev 5 (v7l)
Features	: swp half thumb fastmult vfp edsp thumbee neon vfpv3 tls vfpd32 
CPU implementer	: 0x41
CPU architecture: 7
CPU variant	: 0x2
CPU part	: 0xc08
CPU revision	: 5
Hardware	: Freescale i.MX53 (Device Tree Support)
Revision	: 0000
Serial		: 0000000000000000
# uname -a
Linux imx53-02 3.12-1-armmp #1 SMP Debian 3.12.9-1 (2014-02-01) armv7l GNU/Linux
# lsb_release -a
No LSB modules are available.
Distributor ID:	Debian
Description:	Debian GNU/Linux unstable (sid)
Release:	unstable
Codename:	sid
Next! Yes, there is a lot to do from here on. Then there is the whole issue of actually making this multi-platform. After all, it is far from ideal that a multi-platform kernel package has to have platform-specific operations using flash-kernel at each update. So Grub on ARM is going to be on the list of things to investigate .

8 February 2014

Enrico Zini: original-sin

Original sin I feel that I was somewhat born innocent, an animal with sound, primal instincts. But if I remained that way, I wouldn't be able to function in a complex society, so I got education. Education taught me what is expected from me in order to be accepted by my peers[1]. Education taught me more than that: it also taught me to enjoy what a complex society can give me: art, science, history, philosophy, adding depth of meaning and correlations to my perceptions and memories. Education wasn't perfect, though. Some of my educators obsessed about some of the expectations, and gave me rules to follow that aren't really needed to interact with a society. Sit down for hours in silence without complaining. Don't talk back to figures of authority, even when they are abusing me. Don't ever feel that my efforts in a task have been enough, because there is always something more that I could have done. Do what people expect me to do, regardless of what I wish to do. Do what I need to do, not what I want to do. So I grew up with a set of arbitrary expectations that weren't needed to function in a society, and weren't in any way meeting any of my needs, yet I still felt them as a part of me, putting every effort into meeting them that I would put in making myself happy. I like to call this set of learned arbitrary, unneeded expectations "neurosis". I like this as an interpretation of the "original sin" myth: in order to go from an innocent animal to a member of a complex society, I acquired a set of neuroses that make me behave in a meaningless way. Or, rephrased going along with the myth, that rob me of my innocence. In some environments like BDSM, many have a name for an unnegotiated practice forced on a person: they call it "abuse". It made sense to accept that I have been abused many times while being educated, because my educators also had their own baggage of parasite expectations, of neuroses. And since I don't currently know how I can ever be sure that I freed myself from all my neuroses, I feel like I should accept that it is possible that I do and will abuse others; by accepting it as a possibility, I hope at least to be able to realise as soon as possible that I am doing it, and try to stop. I have now realised that my life is far simpler and more rewarding when expectations are negotiated between all the parties involved. I have recently spent a substantial amount of my energy in recognising and renegotiating many of the expectations and the neuroses that I had learnt while growing up, and, who knows, perhaps this effort will continue throughout my life. So there you go, an agnostic atheist freeing himself of his original sin, and regaining his paradise lost one step at a time, alive, on earth. And enjoying every moment of it. [1] I suspect that is why people educated in a high class society tend to be accepted more easily by a high class society: they conform to the right set of expectations. But I digress.

7 February 2014

Jo Shields: Dear Fake Debian Developers, shoo.

Another post about the Valve/Collabora free games thing. This time, the bad bit people trying to scam free games from us. Before I start, I want to make one thing clear there are people who have requested keys who don t meet the criteria, but are honest and legitimate in their requests. This blogspam is not about them at all. If you re in that category, you re not being complained about. So. Some numbers. At time of writing, I ve assigned keys to 279 Debian Developers or Debian Maintainers almost 25% of the total eligible pool of about 1200. I ve denied 22 requests. Of these 10 were polite requests from people who didn t meet the conditions stated (e.g. Ubuntu developers rather than Debian). These folks weren t at all a problem for us, and I explained politely that they didn t meet the terms we had agreed at the time with Valve. No problem at all with those folks. Next, we have the chancers, 7 of them, who pretended to be eligible when they clearly weren t. For example, two people sent me signed requests pointing to their entry on the Debian New Maintainers page when challenged over the key not being in the keyring. The NM page showed that they had registered as non-uploading Debian Contributors a couple of hours previously. A few just claimed I am a DD, here is my signature when they weren t DDs at all. Those requests were also binned.
Papers, Please screenshot - denied entry application

DENIED

And then we move onto the final category. These people tried identity theft, but did a terrible job of it. There were 5 people in this category:
From: Xxxxxxxx Xxxxxx <xxxxxxxx.xxxxxx@ieee.org>
Subject: free subscription to Debian Developer
8217 A205 5E57 043B 2883 054E 7F55 BB12 A40F 862E
This is not a signature, it s a fingerprint. Amusingly, it s not the fingerprint for the person who sent my mail, but that of Neil McGovern a co-worker at Collabora. Neil assured me he knew how to sign a mail properly, so I shitcanned that entry.
From: "Xxxxx, Xxxxxxxxx" <x.xxxxx@bbw-bremen.de>
Subject: Incoming!
Hey dude,
I want to have the redemption code you are offering for the Valve Games
mQGiBEVhrscRBAD4M5+qxhZUD67PIz0JeoJ0vB0hsLE6QPV144PLjLZOzHbl4H3N
...snip...
Lz8An1TEmmq7fltTpQ+Y1oWhnE8WhVeQAKCzh3MBoNd4AIGHcVDzv0N0k+bKZQ=3D=3D
=3Du/4R
Wat? Learn to GPG!
From: Xxxxxx-Xxxx Le Xxxxxxx Xxxx <xx.xxxxxxxxx@gmail.com>
Subject: pass steam
Hey me voila
Merci beaucoup
valve
2069 1DFC C2C9 8C47 9529 84EE 0001 8C22 381A 7594
Like the first one, a fingerprint. This one is for S bastien Villemot. Don t scammers know how to GPG sign?
From: "Xxxxxxxxx Xxxxxxx" <xxxxxxxx@web.de>
Subject: thanks /DD/Steam gifts us finally something back
0x6864730DF095E5E4
Yet again, a fingerprint. This one is for Marco Nenciarini. I found this request particularly offensive due to the subject line the haughty tone from an identity thief struck me as astonishingly impertinent. Still, when will scammers learn to GPG?
From: Sven Hoexter <svenhoexter@gmail.com>
Subject: Valve produced games
I'm would like to get the valve produced games
My keyring: 0xA6DC24D9DA2493D1 Sven Hoexter <hoexter> sig:6
Easily the best scam effort, since this is the only one which both a) registered an email address under the name of a DD, and b) used a fingerprint which actually corresponds to that human. Sadly for the scammer, I m a suspicious kind of person, so my instinct was to verify the claim via IRC.
31-01-2014 16:52:48 > directhex: Hoaxter, have you started using gmail without updating your GPG key? (note: significantly more likely is someone trying to steal your identity a little to steal valve keys from collabora)
31-01-2014 16:54:51 < Hoaxter!~sh@duckpond6.stormbind.net: directhex: I do not use any Google services and did not change my key
So yeah. Nice try, scammer. I m not listing, in all of this, the mails which Neil received from people who didn t actually read his mail to d-d-a. I m also not listing a story which I ve only heard second ha actually no, this one is too good not to share. Someone went onto db.debian.org, did a search for every DD in France, and emailed every Jabber JID (since they look like email addresses) asking them to forward unwanted keys. All in all, the number of evildoers is quite low, relative to the number of legitimate claims 12 baddies to 279 legitimate keys issued. But still, this is why the whole key issuing thing has been taking me so long and why I have the convoluted signature-based validation system in place. Enjoy your keys, all 279 of you (or more by the time some of you read this). The offer has no explicit expiry on it Valve will keep issuing keys as long as there is reason to, and Collabora will continue to administer their allocation as long as they remain our clients. It s a joint gift to the community thousands of dollars worth of games from Valve, and a significant amount of my time to administer them from Collabora.

4 February 2014

Mart&iacute;n Ferrari: Telegram

This weekend I attended FOSDEM, as I did for the past 4 years. As always, it was a great experience, even if most of the talks I attended were not so interesting. One of the great things about these events, is to get together with other Free Software enthusiasts. One of them introduced me to the new kid on the block: Telegram. It is advertised as a free and secure replacement for WhatsApp, a mobile application I have been refusing to use for months, much to the anger of friends and family. People use WhatsApp because it saves them money to send SMS-like messages to other people. Which in my mind does not make much sense, as I can use email or XMPP for that same purpose, without having to enter just another walled garden. Sadly, people nowadays are using email less and less, and think that it is easier to send a Facebook message (it is not), and XMPP has became a de-facto walled garden since Google betrayed its users by dropping federation. WhatsApp has the advantage of having millions of users already inside their walled garden, like it happened with Facebook, MSN, or ICQ back in the day. Their success can possibly be attributed to the foolproof system it uses to discover contacts: it just sends your entire address book to their servers for matching against already registered users, which is in itself enough reason not to use it. So, when I was told of a secure, free and open alternative, I was eager to try it out. I started by opening their website to see what it was about. There, I found the first signs that something was wrong: no mention of licenses, almost no technical detail of how the protocol works, or how security is achieved. Still, my friend wanted to talk to me, so I rushed to install it and accept a laundry list of permissions in Android. That was a big mistake. The first thing the application did was to check my address book for contacts, without my permission or knowledge. I got greeted by being told that some of my contacts already have Telegram installed, and since then I keep getting notification that some more of my geek friends are installing it. So it is obvious that this company got all my records, breaking my privacy and security. This is enough for me to remove this piece of software from my phone, but it is not the end of the story. When checking it in more detail I found several other problems. The supposed "secret chat" cannot be possibly secure, as there is no verification of the remote party. It "just works", who cares if there is a man in the middle or not. Supposedly it employs a peer-to-peer connection, but I haven't verified that. On the other hand, the non-"secret" conversations are all routed to the main server. The client-to-server communication is supposedly encrypted, but it uses a home-made protocol (which everybody knows is a recipe for disaster), and the server has access to the cleartext of all your communications. Then, browsing the website, I've found that this "open" and "free" offer does not even have all the source code released. In particular, the server code is not public, nor you can set up your own server. Of course, it does not have federation, so even with the server code you wouldn't be able to talk with your friends. It all depends on two men funding and maintaining the project, so when the funds run out, one can only expect that all the users will be left in the dark. I think these arguments are enough to realise that Telegram is only marginally better than WhatsApp. It offers encryption at the transport layer, but you still are contributing to another walled garden, you are at the mercy of a company which does not have a funding plan, and the security practises range from weak to disturbing. In closing, if you are going to compromise your privacy, give away all your contacts' information, and rely on a single company to keep in touch with people, you might as well go and use what everybody else is using. Update: Even before submitting this post, I've found that some more qualified people has already dissected Telegram and concluded that it is basically snake oil. Please see this article. and proceed to uninstall Telegram.

Next.

Previous.