Search Results: "ron"

2 July 2015

Antonio Terceiro: Upgrades to Jessie, Ruby 2.2 transition, and chef update

Last month I started to track all the small Debian-related things that I do. My initial motivation was to be concious about how often I spend short periods of time working on Debian. Sometimes it s during lunch breaks, weekends, first thing in the morning before regular work, after I am done for the day with regular work, or even during regular work, since I do have the chance of doing Debian work as part of my regular work occasionally. Now that I have this information, I need to do something with it. So this is probably the first of monthly updates I will post about my Debian work. Hopefully it won t be the last. Upgrades to Jessie I (finally) upgraded my two servers to Jessie. The first one, my home server, is a Utilite which is a quite nice ARM box. It is silent and consumes very little power. The only problem I had with it is that the vendor-provided kernel is too old, so I couldn t upgrade udev, and therefore couldn t switch to systemd. I had to force systemv for now, until I can manage to upgrade the kernel and configure uboot to properly boot the official Debian kernel. On my VPS things are way better. I was able to upgrade nicely, and it is now running a stock Jessie system. fixed https on ci.debian.net pabs had let me know on IRC of an issue with the TLS certificate for ci.debian.net, which took me a few iterations to get right. It was missing the intermediate certificates, and is now fixed. You can now enjoy Debian CI under https . Ruby 2.2 transition I was able to start the Ruby 2.2 transition, which has the goal of switch to Ruby 2.2 on unstable. The first step was updating ruby-defaults adding support to build Ruby packgaes for both Ruby 2.1 and Ruby 2.2. This was followed by updates to gem2deb (0.18, 0.18.1, 0.18.2, and 0.18.3) and rubygems-integration . At this point, after a few rebuild requests only 50 out of 137 packages need to be looked at; some of them just use the default Ruby, so a rebuild once we switch the default will be enough to make it use Ruby 2.2, while others, specially Ruby libraries, will still need porting work or other fixes. Updated the Chef stack Bringing chef to the very latest upstream release into unstable was quite some work. I had to update: In the middle I also had to package a new dependency, ruby-ffi-yajl, which was very quickly ACCEPTED thanks to the awesome work of the ftp-master team. Random bits

Petter Reinholdtsen: MakerCon Nordic videos now available on Frikanalen

Last oktober I was involved on behalf of NUUG with recording the talks at MakerCon Nordic, a conference for the Maker movement. Since then it has been the plan to publish the recordings on Frikanalen, which finally happened the last few days. A few talks are missing because the speakers asked the organizers to not publish them, but most of the talks are available. The talks are being broadcasted on RiksTV channel 50 and using multicast on Uninett, as well as being available from the Frikanalen web site. The unedited recordings are available on Youtube too. This is the list of talks available at the moment. Visit the Frikanalen video pages to view them. Part of the reason this took so long was that the scripts NUUG had to prepare a recording for publication were five years old and no longer worked with the current video processing tools (command line argument changes). In addition, we needed better audio normalization, which sent me on a detour to package bs1770gain for Debian. Now this is in place and it became a lot easier to publish NUUG videos on Frikanalen.

1 July 2015

Christian Perrier: [LIFE] Running activities

Hello dear readers, It has been quite some time since I blogged on Planet Debian,so today, I just want to give some news to fellow Debian pals. My involvment in Debian is still there. I'm probably less visible nowadays, but I'm still actively working on some packages, monotiring some i18n activities and doing work on D-I. But, as you know, running has taken precedence nowadays and is still becoming a growing part of my life (along with my family, of course). This year, I had a first "summit" running the "Vulcain" trail race in French "Massif Central" (mountains in Central France), which was 80km and 3000m positive climb race. It was run mostly in snow and with quite bad weather conditions, a good training for more difficult races. I completed it in about more than 12 hours, for a race that finally had less than 60% finishers. Later on, most races were preparation races for the summer moutain races : I mostly ran three 50km trail races in the Paris and neighbourhood area. All of them were very good results with a good feeling. Some were run along with friends from the Kikourou.net web community, where I am now very active. My training was also strongly increased wrt former years (yes that *is* possible), peaking at more than 500km during May, where I was mostly on holidays all month long (lucky man). And now, the first Great Great Thing of the year is coming : La Montagn'hard, 110 kilometers, about 9000 meters positive climb, around Les Contamines, close to Mont-Blanc in French Alps. That is a Big One, indeed. Technically more difficult than the TDS race I ran last August, during DebConf (120km, but "only" 7000 meters climb). Montagn'hard is indeed known as one of the most difficult moutain trail races in France. I plan to complete it in about 29 hours....but that can indeed be 30, 32 or even 35, who knows what can happen? Given the very high temperatures over Europe this week (they'll peak at about 38 C on Saturday in the Alps), that will be an incredibly difficult challenge and we expect about only 40% finishers. A live tracking will be available for thos who care at http://chrono.geofp.com/montagnhard2015/v3/. Wish me luck ! Next challenge will be end of August, with the "Echappee Belle" race : 144km and 10.000 meters positive climb, still in French Alps (Belledonne range, this time). About 48 hours, or even up to 55, two nights out.....harder and hopefully better, faster, stronger...:-)

29 June 2015

Jonathan McDowell: What Jonathan Did Next

While I mentioned last September that I had failed to be selected for an H-1B and had been having discussions at DebConf about alternative employment, I never got around to elaborating on what I d ended up doing. Short answer: I ended up becoming a law student, studying for a Masters in Legal Science at Queen s University Belfast. I ve just completed my first year of the 2 year course and have managed to do well enough in the 6 modules so far to convince myself it wasn t a crazy choice. Longer answer: After Vello went under in June I decided to take a couple of months before fully investigating what to do next, largely because I figured I d either find something that wanted me to start ASAP or fail to find anything and stress about it. During this period a friend happened to mention to me that the applications for the Queen s law course were still open. He happened to know that it was something I d considered before a few times. Various discussions (some of them over gin, I ll admit) ensued and I eventually decided to submit an application. This was towards the end of August, and I figured I d also talk to people at DebConf to see if there was anything out there tech-wise that I could get excited about. It turned out that I was feeling a bit jaded about the whole tech scene. Another friend is of the strong opinion that you should take a break at least every 10 years. Heeding her advice I decided to go ahead with the law course. I haven t regretted it at all. My initial interest was largely driven by a belief that there are too few people who understand both tech and law. I started with interests around intellectual property and contract law as well as issues that arise from trying to legislate for the global nature of most tech these days. However the course is a complete UK qualifying degree (I can go on to do the professional qualification in NI or England & Wales) and the first year has been about public law. Which has been much more interesting than I was expecting (even, would you believe it, EU law). Especially given the potential changing constitutional landscape of the UK after the recent general election, with regard to talk of repeal of the Human Rights Act and a referendum on exit from the EU. Next year will concentrate more on private law, and I m hoping to be able to tie that in better to what initially drove me to pursue this path. I m still not exactly sure which direction I ll go once I complete the course, but whatever happens I want to keep a linkage between my skill sets. That could be either leaning towards the legal side but with the appreciation of tech, returning to tech but with the appreciation of the legal side of things or perhaps specialising further down an academic path that links both. I guess I ll see what the next year brings. :)

Lunar: Reproducible builds: week 9 in Stretch cycle

What happened about the reproducible builds effort this week: Toolchain fixes Norbert Preining uploaded texinfo/6.0.0.dfsg.1-2 which makes texinfo indices reproducible. Original patch by Chris Lamb. Lunar submitted recently rebased patches to make the file order of files inside .deb stable. akira filled #789843 to make tex4ht stop printing timestamps in its HTML output by default. Dhole wrote a patch for xutils-dev to prevent timestamps when creating gzip compresed files. Reiner Herrmann sent a follow-up patch for wheel to use UTC as timezone when outputing timestamps. Mattia Rizzolo started a discussion regarding the failure to build from source of subversion when -Wdate-time is added to CPPFLAGS which happens when asking dpkg-buildflags to use the reproducible profile. SWIG errors out because it doesn't recognize the aforementioned flag. Trying to get the .buildinfo specification to more definitive state, Lunar started a discussion on storing the checksums of the binary package used in dpkg status database. akira discovered while proposing a fix for simgrid that CMake internal command to create tarballs would record a timestamp in the gzip header. A way to prevent it is to use the GZIP environment variable to ask gzip not to store timestamps, but this will soon become unsupported. It's up for discussion if the best place to fix the problem would be to fix it for all CMake users at once. Infrastructure-related work Andreas Henriksson did a delayed NMU upload of pbuilder which adds minimal support for build profiles and includes several fixes from Mattia Rizzolo affecting reproducibility tests. Neils Thykier uploaded lintian which both raises the severity of package-contains-timestamped-gzip and avoids false positives for this tag (thanks to Tomasz Buchert). Petter Reinholdtsen filled #789761 suggesting that how-can-i-help should prompt its users about fixing reproducibility issues. Packages fixed The following packages became reproducible due to changes in their build dependencies: autorun4linuxcd, libwildmagic, lifelines, plexus-i18n, texlive-base, texlive-extra, texlive-lang. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Untested uploaded as they are not in main: Patches submitted which have not made their way to the archive yet: debbindiff development debbindiff/23 includes a few bugfixes by Helmut Grohne that result in a significant speedup (especially on larger files). It used to exhibit the quadratic time string concatenation antipattern. Version 24 was released on June 23rd in a hurry to fix an undefined variable introduced in the previous version. (Reiner Herrmann) debbindiff now has a test suite! It is written using the PyTest framework (thanks Isis Lovecruft for the suggestion). The current focus has been on the comparators, and we are now at 93% of code coverage for these modules. Several problems were identified and fixed in the process: paths appearing in output of javap, readelf, objdump, zipinfo, unsqusahfs; useless MD5 checksum and last modified date in javap output; bad handling of charsets in PO files; the destination path for gzip compressed files not ending in .gz; only metadata of cpio archives were actually compared. stat output was further trimmed to make directory comparison more useful. Having the test suite enabled a refactoring of how comparators were written, switching from a forest of differences to a single tree. This helped removing dust from the oldest parts of the code. Together with some other small changes, version 25 was released on June 27th. A follow up release was made the next day to fix a hole in the test suite and the resulting unidentified leftover from the comparator refactoring. (Lunar) Documentation update Ximin Luo improved code examples for some proposed environment variables for reference timestamps. Dhole added an example on how to fix timestamps C pre-processor macros by adding a way to set the build date externally. akira documented her fix for tex4ht timestamps. Package reviews 94 obsolete reviews have been removed, 330 added and 153 updated this week. Hats off for Chris West (Faux) who investigated many fail to build from source issues and reported the relevant bugs. Slight improvements were made to the scripts for editing the review database, edit-notes and clean-notes. (Mattia Rizzolo) Meetings A meeting was held on June 23rd. Minutes are available. The next meeting will happen on Tuesday 2015-07-07 at 17:00 UTC. Misc. The Linux Foundation announced that it was funding the work of Lunar and h01ger on reproducible builds in Debian and other distributions. This was further relayed in a Bits from Debian blog post.

28 June 2015

Ben Armstrong: Bluff Trail Early Summer 2015

Here s a photo journal of a walk I just completed around the Pot Lake loop of the Bluff Wilderness Hiking Trail. Hope you enjoy it! I was dissatisfied with my initial post, so have reduced the size to improve load time, changed the gallery software and have rewritten many of the captions. [slb_group]
My favourite stunted tamarack, clinging to the rocks.Click this photo to start the slideshow.
The Bluff Wilderness Hiking Trail is a series of four loops. Today I ll tackle only the first in order to get as many pictures as possible, and because when hiking solo, I prefer to stay on the more heavily traveled part. In late summer, I ll probably do all four loops with my friend Ryan again. Meanwhile, I ll stay in shape coming out here when I can for shorter walks. The trail starts here. Right away, even before heading between the marker stones, there s a pretty view of Cranberry Lake off to the right. Pink lady slippers have been plentiful this year! All along the trail, you can find hundreds, if not thousands of these. Boardwalks provide dry passage across the boggy bits. The pitcher plants are thriving, too. The vines with tiny, round leaves are wintergreen. Tasty! I ve not seen anything larger than a deer out here. Roots and rocks are a recurring theme. Many feet beating down on the first loop have packed the earth hard and have exposed more roots than you ll see deeper into the trail system where fewer hikers travel. Step carefully. Sheep laurel is an eye-catcher. To me, they look like little, pink jewels. Yellow markers clearly mark the Pot Lake loop. At crucial junctures there are some signs to point you the right way. If you re looking only at your feet, you may see black circles marked with arrows on some of the rocks, also pointing the way. The vegetation varies from scraggly and clinging to the rocks, to lush and green. The path is wet in parts. Nothing impassible, though. On the first loop in particular, and even within only the first kilometre, there are some pretty stunning views of the lake. Very quickly, you ll find yourself perched up top on the rocks. On this stretch, you need to hop a bit from one rock to the next. Just as quickly as you ascended, you descend back down to the lake again. A good place to stop and have a snack. The start of the first loop, itself. I chide myself for not having discovered this trail until about 2007, even though we moved out here in 2005. It s a treasure we re indebted to the WRWEO for preserving. Leave some comments in the box, if you like. You ll find these maps along the way to track your progress. Remember to follow proper trail etiquette. A particularly steep climb! Despite the best trail maintenance efforts, water still goes where it wants! Good to have boots. Another steep climb. This tree is chattering at me. Raising quite a racket. What s in the hole? I patiently wait with my camera to get a good shot of the tree s occupants. Mother woodpecker, feeding her babies! As the feeding continues, the chirping intensifies! Up on top of a big rock with a view over the lake is another favourite stopping place for a snack. The view at my snack break rock. I never get tired of it. There are some pretty big boulders. Next time I ll bring a friend to stand under it for scale. Another terrific view. A stream just before the first portage. This portage connects Cranberry Lake with Pot Lake. The portage is clearly marked. The Pot Lake end of the portage. One of several upturned trees, with the roots now forming a wall along one side of the trail. The spiral of the roots mimics the spiral split in this boulder which you can walk all of the way into until you reach the centre. Rocks and trees and trees and rocks White pine catkins. Suddenly the close forest opens up into a wide view all around. My favourite stunted tamarack, clinging to the rocks. Last year s cones. This year s aren t out yet on this tree. I love the tamarack s delicate new needles. These blueberries have a head start. Can t wait until it s time to harvest them. Nearly at the top of the Pot Lake loop. This is Pot Lake, itself. I was struck by this one little blighted berry, showing a blush of distress-induced colour amongst the green ones. Another view, nearly at the top. A sign beneath the map: Rare Plant Species: Mountain Sandwort Arenaria groenlandica. Use caution and stay on designated trails. Avoid disturbing habitat. Finally, the top. A map to mark your progress. Apparently the Mountain Sandwort, right at the base of the sign. The mountain sandwort is a pretty, delicate little thing. After passing the sign, the view from the top over Cranberry Lake, indeed both lakes, is a reward worth climbing all of the way up to see. Some other hiker has left a cairn. The descent is not too steep at first. The approach down to the back side of Pot Lake from the top is marked by exposed bedrock and scrubby plants. Finally back to some cover, which is welcome on hotter days. A ferny fairyland. It s not all abrupt ups and downs. Here s an easy, winding stretch of trail. Cinnamon ferns. Ambling along. Rounding the end of Pot Lake. Not very long after reaching the lake, the path climbs several metres up above it. There are some nice, rootless bits on this side of the loop, giving your ankles and knees a break. This guy seemed extremely agitated to see me. A new tamarack cone! Did I mention I like tamaracks? The steep descent back to Cranberry Lake again. Finally back where the loop starts.
[/slb_group]

23 June 2015

Ben Armstrong: Debian Live Rescue needs some love

You may have noticed that Jessie no longer includes the useful rescue flavour of live image, formerly included in Wheezy and earlier releases, and neither will Stretch unless you take action. This is my second public call for help this year to revive it. So if you care about rescue, here s how you can help: If you have any questions not answered in this post, please feel free to leave a comment on this blog, talk to the Debian Live team on irc I m SynrG, and hang out with the team at #debian-live @ irc.oftc.net) or drop us an email at debian-live@lists.debian.org.

Russell Coker: One Android Phone Per Child

I was asked for advice on whether children should have access to smart phones, it s an issue that many people are discussing and seems worthy of a blog post. Claimed Problems with Smart Phones The first thing that I think people should read is this XKCD post with quotes about the demise of letter writing from 99+ years ago [1]. Given the lack of evidence cited by people who oppose phone use I think we should consider to what extent the current concerns about smart phone use are just reactions to changes in society. I ve done some web searching for reasons that people give for opposing smart phone use by kids and addressed the issues below. Some people claim that children shouldn t get a phone when they are so young that it will just be a toy. That s interesting given the dramatic increase in the amount of money spent on toys for children in recent times. It s particularly interesting when parents buy game consoles for their children but refuse mobile phone toys (I know someone who did this). I think this is more of a social issue regarding what is a suitable toy than any real objection to phones used as toys. Obviously the educational potential of a mobile phone is much greater than that of a game console. It s often claimed that kids should spend their time reading books instead of using phones. When visiting libraries I ve observed kids using phones to store lists of books that they want to read, this seems to discredit that theory. Also some libraries have Android and iOS apps for searching their catalogs. There are a variety of apps for reading eBooks, some of which have access to many free books but I don t expect many people to read novels on a phone. Cyber-bullying is the subject of a lot of anxiety in the media. At least with cyber-bullying there s an electronic trail, anyone who suspects that their child is being cyber-bullied can check that while old-fashioned bullying is more difficult to track down. Also while cyber-bullying can happen faster on smart phones the victim can also be harassed on a PC. I don t think that waiting to use a PC and learn what nasty thing people are saying about you is going to be much better than getting an instant notification on a smart phone. It seems to me that the main disadvantage of smart phones in regard to cyber-bullying is that it s easier for a child to participate in bullying if they have such a device. As most parents don t seem concerned that their child might be a bully (unfortunately many parents think it s a good thing) this doesn t seem like a logical objection. Fear of missing out (FOMO) is claimed to be a problem, apparently if a child has a phone then they will want to take it to bed with them and that would be a bad thing. But parents could have a policy about when phones may be used and insist that a phone not be taken into the bedroom. If it s impossible for a child to own a phone without taking it to bed then the parents are probably dealing with other problems. I m not convinced that a phone in bed is necessarily a bad thing anyway, a phone can be used as an alarm clock and instant-message notifications can be turned off at night. When I was young I used to wait until my parents were asleep before getting out of bed to use my PC, so if smart-phones were available when I was young it wouldn t have changed my night-time computer use. Some people complain that kids might use phones to play games too much or talk to their friends too much. What do people expect kids to do? In recent times the fear of abduction has led to children doing playing outside a lot less, it used to be that 6yos would play with other kids in their street and 9yos would be allowed to walk to the local park. Now people aren t allowing 14yo kids walk to the nearest park alone. Playing games and socialising with other kids has to be done over the Internet because kids aren t often allowed out of the house. Play and socialising are important learning experiences that have to happen online if they can t happen offline. Apps can be expensive. But it s optional to sign up for a credit card with the Google Play store and the range of free apps is really good. Also the default configuration of the app store is to require a password entry before every purchase. Finally it is possible to give kids pre-paid credit cards and let them pay for their own stuff, such pre-paid cards are sold at Australian post offices and I m sure that most first-world countries have similar facilities. Electronic communication is claimed to be somehow different and lesser than old-fashioned communication. I presume that people made the same claims about the telephone when it first became popular. The only real difference between email and posted letters is that email tends to be shorter because the reply time is smaller, you can reply to any questions in the same day not wait a week for a response so it makes sense to expect questions rather than covering all possibilities in the first email. If it s a good thing to have longer forms of communication then a smart phone with a big screen would be a better option than a feature phone , and if face to face communication is preferred then a smart phone with video-call access would be the way to go (better even than old fashioned telephony). Real Problems with Smart Phones The majority opinion among everyone who matters (parents, teachers, and police) seems to be that crime at school isn t important. Many crimes that would result in jail sentences if committed by adults receive either no punishment or something trivial (such as lunchtime detention) if committed by school kids. Introducing items that are both intrinsically valuable and which have personal value due to the data storage into a typical school environment is probably going to increase the amount of crime. The best options to deal with this problem are to prevent kids from taking phones to school or to home-school kids. Fixing the crime problem at typical schools isn t a viable option. Bills can potentially be unexpectedly large due to kids inability to restrain their usage and telcos deliberately making their plans tricky to profit from excess usage fees. The solution is to only use pre-paid plans, fortunately many companies offer good deals for pre-paid use. In Australia Aldi sells pre-paid credit in $15 increments that lasts a year [2]. So it s possible to pay $15 per year for a child s phone use, have them use Wifi for data access and pay from their own money if they make excessive calls. For older kids who need data access when they aren t at home or near their parents there are other pre-paid phone companies that offer good deals, I ve previously compared prices of telcos in Australia, some of those telcos should do [3]. It s expensive to buy phones. The solution to this is to not buy new phones for kids, give them an old phone that was used by an older relative or buy an old phone on ebay. Also let kids petition wealthy relatives for a phone as a birthday present. If grandparents want to buy the latest smart-phone for a 7yo then there s no reason to stop them IMHO (this isn t a hypothetical situation). Kids can be irresponsible and lose or break their phone. But the way kids learn to act responsibly is by practice. If they break a good phone and get a lesser phone as a replacement or have to keep using a broken phone then it s a learning experience. A friend s son head-butted his phone and cracked the screen he used it for 6 months after that, I think he learned from that experience. I think that kids should learn to be responsible with a phone several years before they are allowed to get a learner s permit to drive a car on public roads, which means that they should have their own phone when they are 12. I ve seen an article about a school finding that tablets didn t work as well as laptops which was touted as news. Laptops or desktop PCs obviously work best for typing. Tablets are for situations where a laptop isn t convenient and when the usage involves mostly reading/watching, I ve seen school kids using tablets on excursions which seems like a good use of them. Phones are even less suited to writing than tablets. This isn t a problem for phone use, you just need to use the right device for each task. Phones vs Tablets Some people think that a tablet is somehow different from a phone. I ve just read an article by a parent who proudly described their policy of buying feature phones for their children and tablets for them to do homework etc. Really a phone is just a smaller tablet, once you have decided to buy a tablet the choice to buy a smart phone is just about whether you want a smaller version of what you have already got. The iPad doesn t appear to be able to make phone calls (but it supports many different VOIP and video-conferencing apps) so that could technically be described as a difference. AFAIK all Android tablets that support 3G networking also support making and receiving phone calls if you have a SIM installed. It is awkward to use a tablet to make phone calls but most usage of a modern phone is as an ultra portable computer not as a telephone. The phone vs tablet issue doesn t seem to be about the capabilities of the device. It s about how portable the device should be and the image of the device. I think that if a tablet is good then a more portable computing device can only be better (at least when you need greater portability). Recently I ve been carrying a 10 tablet around a lot for work, sometimes a tablet will do for emergency work when a phone is too small and a laptop is too heavy. Even though tablets are thin and light it s still inconvenient to carry, the issue of size and weight is a greater problem for kids. 7 tablets are a lot smaller and lighter, but that s getting close to a 5 phone. Benefits of Smart Phones Using a smart phone is good for teaching children dexterity. It can also be used for teaching art in situations where more traditional art forms such as finger painting aren t possible (I have met a professional artist who has used a Samsung Galaxy Note phone for creating art work). There is a huge range of educational apps for smart phones. The Wikireader (that I reviewed 4 years ago) [4] has obvious educational benefits. But a phone with Internet access (either 3G or Wifi) gives Wikipedia access including all pictures and is a better fit for most pockets. There are lots of educational web sites and random web sites that can be used for education (Googling the answer to random questions). When it comes to preparing kids for the real world or the work environment people often claim that kids need to use Microsoft software because most companies do (regardless of the fact that most companies will be using radically different versions of MS software by the time current school kids graduate from university). In my typical work environment I m expected to be able to find the answer to all sorts of random work-related questions at any time and I think that many careers have similar expectations. Being able to quickly look things up on a phone is a real work skill, and a skill that s going to last a lot longer than knowing today s version of MS-Office. There are a variety of apps for tracking phones. There are non-creepy ways of using such apps for monitoring kids. Also with two-way monitoring kids will know when their parents are about to collect them from an event and can stay inside until their parents are in the area. This combined with the phone/SMS functionality that is available on feature-phones provides some benefits for child safety. iOS vs Android Rumour has it that iOS is better than Android for kids diagnosed with Low Functioning Autism. There are apparently apps that help non-verbal kids communicate with icons and for arranging schedules for kids who have difficulty with changes to plans. I don t know anyone who has a LFA child so I haven t had any reason to investigate such things. Anyone can visit an Apple store and a Samsung Experience store as they have phones and tablets you can use to test out the apps (at least the ones with free versions). As an aside the money the Australian government provides to assist Autistic children can be used to purchase a phone or tablet if a registered therapist signs a document declaring that it has a therapeutic benefit. I think that Android devices are generally better for educational purposes than iOS devices because Android is a less restrictive platform. On an Android device you can install apps downloaded from a web site or from a 3rd party app download service. Even if you stick to the Google Play store there s a wider range of apps to choose from because Google is apparently less restrictive. Android devices usually allow installation of a replacement OS. The Nexus devices are always unlocked and have a wide range of alternate OS images and the other commonly used devices can usually have an alternate OS installed. This allows kids who have the interest and technical skill to extensively customise their device and learn all about it s operation. iOS devices are designed to be sealed against the user. Admittedly there probably aren t many kids with the skill and desire to replace the OS on their phone, but I think it s good to have option. Android phones have a range of sizes and features while Apple only makes a few devices at any time and there s usually only a couple of different phones on sale. iPhones are also a lot smaller than most Android phones, according to my previous estimates of hand size the iPhone 5 would be a good tablet for a 3yo or good for side-grasp phone use for a 10yo [5]. The main benefits of a phone are for things other than making phone calls so generally the biggest phone that will fit in a pocket is the best choice. The tiny iPhones don t seem very suitable. Also buying one of each is a viable option. Conclusion I think that mobile phone ownership is good for almost all kids even from a very young age (there are many reports of kids learning to use phones and tablets before they learn to read). There are no real down-sides that I can find. I think that Android devices are generally a better option than iOS devices. But in the case of special needs kids there may be advantages to iOS.

Orestis Ioannou: GSoC Debsources updates

The first 4 weeks have been really great. I had the chance to work on the new webapp, the copyright tracker. Here are my first 4 reports for the weeks: Summary During these weeks i completed the navigation (by prefix, list of versions etc) for the copyright tracker, the license rendering and the API for searching by checksum and by package/version/filename. Still under review the batch API (request many files at once) and the the respective views for the API. In the following weeks I ll work on the database and the plugins to mine license information on update time. Experience The experience i accumulate every week is immense. During the review process of my code i receive great feedback from zack, matthieu, and jpleau. It is a great chance for everyone to improve his/hers coding skills. At the university we barely get any feedback on our code, let alone communicate directly with professors to find the best solution for a given problem. I think it gets development in another level. For example at the university we use git/mercurial for our projects, although we don't really pay attention at commit messages and we marginally make use of these tools besides 'commit pull push'. During the last weeks i had the chance to use far more commands in order to squash amend rebase commits to have a beautiful and useful log history! And this is just a minor example. All in all I think it is a great introduction to the free/open source community for somebody, like me, who has been for years only a user and couldn't find the opportunity to contribute! And don't get me wrong, gsoc is not only about coding skills. At least for myself having the chance to get just a small taste of how the Debian community works, gets organised, get things done (!) is somehow priceless! Summer of code TDD I have finally understood why test driven development is so powerful. As i am advancing in the project i am sometimes obliged to retouch some areas, refactor pieces of code. Having a great test suite that keeps you on track about the changes, and possible outages in advance is pretty powerful. What is coming I feel the project is on the right path. Both clemux (fellow gsoc student working on debsources) and me are advancing in a productive pace. I hope that soon enough the copyright Blueprint will be completed (most notable pending functionalities are the plugins-hooks to mine the licenses at update time, introduction of at least another license oracle possible ninka, statistics) so that everyone can take profit of the new tools provided by DebSources. Although we haven't talked much about it the patch tracker should also come into the play sooner rather than later. Stay tuned!

22 June 2015

Lunar: Reproducible builds: week 8 in Stretch cycle

What happened about the reproducible builds effort this week: Toolchain fixes Andreas Henriksson has improved Johannes Schauer initial patch for pbuilder adding support for build profiles. Packages fixed The following 12 packages became reproducible due to changes in their build dependencies: collabtive, eric, file-rc, form-history-control, freehep-chartableconverter-plugin , jenkins-winstone, junit, librelaxng-datatype-java, libwildmagic, lightbeam, puppet-lint, tabble. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net Bugs with the ftbfs usertag are now visible on the bug graphs. This explain the recent spike. (h01ger) Andreas Beckmann suggested a way to test building packages using the funny paths that one can get when they contain the full Debian package version string. debbindiff development Lunar started an important refactoring introducing abstactions for containers and files in order to make file type identification more flexible, enabling fuzzy matching, and allowing parallel processing. Documentation update Ximin Luo detailed the proposal to standardize environment variables to pass a reference source date to tools that needs one (e.g. documentation generator). Package reviews 41 obsolete reviews have been removed, 168 added and 36 updated this week. Some more issues affecting packages failing to build from source have been identified. Meetings Minutes have been posted for Tuesday June 16th meeting. The next meeting is scheduled Tuesday June 23rd at 17:00 UTC. Presentations Lunar presented the project in French during Pas Sage en Seine in Paris. Video and slides are available.

21 June 2015

Steve Kemp: We're all about storing objects

Recently I've been experimenting with camlistore, which is yet another object storage system. Camlistore gains immediate points because it is written in Go, and is a project initiated by Brad Fitzpatrick, the creator of Perlbal, memcached, and Livejournal of course. Camlistore is designed exactly how I'd like to see an object storage-system - each server allows you to:
It should be noted more is possible, there's a pretty web UI for example, but I'm simplifying. Do your own homework :)
With those primitives you can allow a client-library to upload a file once, then in the background a bunch of dumb servers can decide amongst themselves "Hey I have data with ID:33333 - Do you?". If nobody else does they can upload a second copy. In short this kind of system allows the replication to be decoupled from the storage. The obvious risk is obvious though: if you upload a file the chunks might live on a host that dies 20 minutes later, just before the content was replicated. That risk is minimal, but valid. There is also the risk that sudden rashes of uploads leave the system consuming all the internal-bandwith constantly comparing chunk-IDs, trying to see if data is replaced that has been copied numerous times in the past, or trying to play "catch-up" if the new-content is larger than the replica-bandwidth. I guess it should possible to detect those conditions, but they're things to be concerned about. Anyway the biggest downside with camlistore is documentation about rebalancing, replication, or anything other than simple single-server setups. Some people have blogged about it, and I got it working between two nodes, but I didn't feel confident it was as robust as I wanted it to be. I have a strong belief that Camlistore will become a project of joy and wonder, but it isn't quite there yet. I certainly don't want to stop watching it :) On to the more personal .. I'm all about the object storage these days. Right now most of my objects are packed in a collection of boxes. On the 6th of next month a shipping container will come pick them up and take them to Finland. For pretty much 20 days in a row we've been taking things to the skip, or the local charity-shops. I expect that by the time we've relocated the amount of possesions we'll maintain will be at least a fifth of our current levels. We're working on the general rule of thumb: "If it is possible to replace an item we will not take it". That means chess-sets, mirrors, etc, will not be carried. DVDs, for example, have been slashed brutally such that we're only transferring 40 out of a starting collection of 500+. Only personal, one-off, unique, or "significant" items will be transported. This includes things like personal photographs, family items, and similar. Clothes? Well I need to take one jacket, but more can be bought. The only place I put my foot down was books. Yes I'm a kindle-user these days, but I spent many years tracking down some rare volumes, and though it would be possible to repeat that effort I just don't want to. I've also decided that I'm carrying my complete toolbox. Some of the tools I took with me when I left home at 18 have stayed with me for the past 20+ years. I don't need this specific crowbar, or axe, but I'm damned if I'm going to lose them now. So they stay. Object storage - some objects are more important than they should be!

20 June 2015

Lunar: Reproducible builds: week 4 in Stretch cycle

What happened about the reproducible builds effort for this week: Toolchain fixes Lunar rebased our custom dpkg on the new release, removing a now unneeded patch identified by Guillem Jover. An extra sort in the buildinfo generator prevented a stable order and was quickly fixed once identified. Mattia Rizzolo also rebased our custom debhelper on the latest release. Packages fixed The following 30 packages became reproducible due to changes in their build dependencies: animal-sniffer, asciidoctor, autodock-vina, camping, cookie-monster, downthemall, flashblock, gamera, httpcomponents-core, https-finder, icedove-l10n, istack-commons, jdeb, libmodule-build-perl, libur-perl, livehttpheaders, maven-dependency-plugin, maven-ejb-plugin, mozilla-noscript, nosquint, requestpolicy, ruby-benchmark-ips, ruby-benchmark-suite, ruby-expression-parser, ruby-github-markup, ruby-http-connection, ruby-settingslogic, ruby-uuidtools, webkit2gtk, wot. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which did not make their way to the archive yet: Also, the following bugs have been reported: reproducible.debian.net Holger Levsen made several small bug fixes and a few more visible changes: strip-nondeterminism Version 0.007-1 of strip-nondeterminism the tool to post-process various file formats to normalize them has been uploaded by Holger Levsen. Version 0.006-1 was already in the reproducible repository, the new version mainly improve the detection of Maven's pom.properties files. debbindiff development At the request of Emmanuel Bourg, Reiner Herrmann added a comparator for Java .class files. Documentation update Christoph Berg created a new page for the timestamps in manpages created by Doxygen. Package reviews 93 obsolete reviews have been removed, 76 added and 43 updated this week. New identified issues: timestamps in manpages generated by Doxygen, modification time differences in files extracted by unzip, tstamp task used in Ant build.xml, timestamps in documentation generated by ASDocGen. The description for build id related issues has been clarified. Meetings Holger Levsen announced a first meeting on Wednesday, June 3rd, 2015, 19:00 UTC. The agenda is amendable on the wiki. Misc. Lunar worked on a proof-of-concept script to import the build environment found in .buildinfo files to UDD. Lucas Nussbaum has positively reviewed the proposed schema. Holger Levsen cleaned up various experimental toolchain repositories, marking merged brances as such.

Russell Coker: BTRFS Status June 2015

The version of btrfs-tools in Debian/Jessie is incapable of creating a filesystem that can be mounted by the kernel in Debian/Wheezy. If you want to use a BTRFS filesystem on Jessie and Wheezy (which isn t uncommon with removable devices) the only options are to use the Wheezy version of mkfs.btrfs or to use a Jessie kernel on Wheezy. I recently got bitten by this issue when I created a BTRFS filesystem on a removable device with a lot of important data (which is why I wanted metadata duplication and checksums) and had to read it on a server running Wheezy. Fortunately KVM in Wheezy works really well so I created a virtual machine to read the disk. Setting up a new KVM isn t that difficult, but it s not something I want to do while a client is anxiously waiting for their data. BTRFS has been working well for me apart from the Jessie/Wheezy compatability issue (which was an annoyance but didn t stop me doing what I wanted). I haven t written a BTRFS status report for a while because everything has been OK and there has been nothing exciting to report. I regularly get errors from the cron jobs that run a balance supposedly running out of free space. I have the cron jobs due to past problems with BTRFS running out of metadata space. In spite of the jobs often failing the systems keep working so I m not too worried at the moment. I think this is a bug, but there are many more important bugs. Linux kernel version 3.19 was the first version to have working support for RAID-5 recovery. This means version 3.19 was the first version to have usable RAID-5 (I think there is no point even having RAID-5 without recovery). It wouldn t be prudent to trust your important data to a new feature in a filesystem. So at this stage if I needed a very large scratch space then BTRFS RAID-5 might be a viable option but for anything else I wouldn t use it. BTRFS still has had little performance optimisation, while this doesn t matter much for SSD and for single-disk filesystems for a RAID-5 of hard drives that would probably hurt a lot. Maybe BTRFS RAID-5 would be good for a scratch array of SSDs. The reports of problems with RAID-5 don t surprise me at all. I have a BTRFS RAID-1 filesystem on 2*4TB disks which is giving poor performance on metadata, simple operations like ls -l on a directory with ~200 subdirectories takes many seconds to run. I suspect that part of the problem is due to the filesystem being written by cron jobs with files accumulating over more than a year. The btrfs filesystem command (see btrfs-filesystem(8)) allows defragmenting files and directory trees, but unfortunately it doesn t support recursively defragmenting directories but not files. I really wish there was a way to get BTRFS to put all metadata on SSD and all data on hard drives. Sander suggested the following command to defragment directories on the BTRFS mailing list: find / -xdev -type d -execdir btrfs filesystem defrag -c + Below is the output of zfs list -t snapshot on a server I run, it s often handy to know how much space is used by snapshots, but unfortunately BTRFS has no support for this.
NAME USED AVAIL REFER MOUNTPOINT
hetz0/be0-mail@2015-03-10 2.88G 387G
hetz0/be0-mail@2015-03-11 1.12G 388G
hetz0/be0-mail@2015-03-12 1.11G 388G
hetz0/be0-mail@2015-03-13 1.19G 388G
Hugo pointed out on the BTRFS mailing list that the following command will give the amount of space used for snapshots. $SNAPSHOT is the name of a snapshot and $LASTGEN is the generation number of the previous snapshot you want to compare with. btrfs subvolume find-new $SNAPSHOT $LASTGEN awk ' total = total + $7 END print total ' One upside of the BTRFS implementation in this regard is that the above btrfs command without being piped through awk shows you the names of files that are being written and the amounts of data written to them. Through casually examining this output I discovered that the most written files in my home directory were under the .cache directory (which wasn t exactly a surprise). Now I am configuring workstations with a separate subvolume for ~/.cache for the main user. This means that ~/.cache changes don t get stored in the hourly snapshots and less disk space is used for snapshots. Conclusion My observation is that things are going quite well with BTRFS. It s more than 6 months since I had a noteworthy problem which is pretty good for a filesystem that s still under active development. But there are still many systems I run which could benefit from the data integrity features of ZFS and BTRFS that don t have the resources to run ZFS and need more reliability than I can expect from an unattended BTRFS system. At this time the only servers I run with BTRFS are located within a reasonable drive from my home (not the servers in Germany and the US) and are easily accessible (not the embedded systems). ZFS is working well for some of the servers in Germany. Eventually I ll probably run ZFS on all the hosted servers in Germany and the US, I expect that will happen before I m comfortable running BTRFS on such systems. For the embedded systems I will just take the risk of data loss/corruption for the next few years.

Norbert Preining: Localizing a WordPress Blog

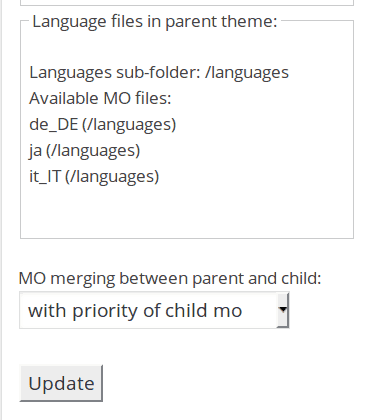
There are many translation plugins available for WordPress, and most of them deal with translations of articles. This might be of interest for others, but not for me. If you have a blog with visitors from various language background, because you are living abroad, or writing in several languages, you might feel tempted to provide visitors with a localized environment , meaning that as much as possible is translated into the native language of the visitor, without actually translating content but allowing to. xili-languages1 In my case I am writing mostly in English and Japanese, but sometimes (in former times) in Italian and now and then in my mother tongue, German. Visitors from my site are from all over the world, but at least for Japanese visitors I wanted to provide a localized environment. This blog describes how to get as much as possible translated of your blog, and here I mean not the actual articles, because this is the easy part and most translation plugins handle that fine, but the things around the articles (categories, tags, headers, ). Starting point and aims My starting point was a blog where I already had language added as extra taxonomy, and have tagged all articles with a language. But I didn t have any other translation plugin installed or used. Furthermore, I am using a child theme of the main theme in use (that is always a good idea anyway!). And of course, the theme you are using should be prepared for translation, that is that most literal strings in the theme source code are wrapped in __( ... ) or _e( ... ) calls. And by the way, if you don t have the language taxonomy, don t worry, that will come in automatically. One more thing: The following descriptions are not for the very beginner. I expect certain fluency with WordPress, where for example themese and plugins keep their files, as well as PHP programming experience is needed for some of the steps. With this starting point my aims were quite clear: Translation plugins There is a huge bunch of translation plugins, localization plugins, or internationalization plugins out there, and it is hard to select one. I don t say that what I propose here is the optimal solution, just one that I was pointed at by a colleague, namely utilizing the xili-language plugin. Installation and initial setup Not much to say here, just follow the usual procedure (search, install, activate), followed by the initial setup of xili-language. If you haven t had a language taxonomy by now, you can add languages from the preference page of xili-language, first tab. After having added some languages you should have something similar to the above screen shot. Having defined your languages, you can assign a language to your articles, but for now nothing has actually changed on the blog pages. xili-languages2As I already mentioned, I assume that you are using a child theme. In this case you should consult the fourth tab of the xili-language settings page, called Managing language files, where on the right you should see / set up things in a way that translations in the child theme override the ones in the main theme, see screen shot on the right. I just mention here that there is another xili plugin, xili-dictionary, that can do a lot of things for you when it comes to translation but I couldn t figure out its operation mode, so I switched back (i.e., uninstalled that plugin) and used normal .po/.mo files as described in the next section. Adding translations po and mo files Translations are handled in normal (at least for the Unix world) gettext format. Matthias wrote about this in this blog. In principle you have to: The contents of the po files are described in Matthias blog, and in the following when I say add a translation, then I mean: adding a stanza
msgid "some string"
msgstr "translation of some string"
to the po file, and not forgetting to recompile it to mo file. So let us go through a list of changes I made to translate various pieces of the blog appearance: Translation of categories This is the easiest part, simply throw in the names of your categories into the respective local-DD_LL.po file, and be ready. In my case I used local-ja.po which besides other categories contains stanzas like:
msgid "Travel"
msgstr " "
Translation of widget titles In most cases the widget titles are already automatically translated, if the plugin/widget author cared for it, meaning that he called the widget_title filter on the title. If this does not happen, please report this to the widget/plugin author. I have done this for example for the simple links plugin, which I use for various elements of the side-bar. The author was extremely responsive and the fix will be in the next release is already in the latest release big thanks! Translation of tags This is a bit a problem, as the tags appear in various places on my blog: next to the title line and the footer of each blog, as well as in the tag cloud in the side bar. Furthermore, I want to translate tags instead of having related tag groups as provided by xili tidy tags plugin, so we have to deal with the various appearances of tags one by one: Tags on the main page shown by the theme This is the easier part in my case I had already a customized content.php and content-single.php in my child theme folder. If not, you need to copy the one from the parent theme and change the appearance of it to translate tags. Since this is something that depends on the specific theme, I cannot give detailed advice, but if you see something like:
$tags_list = get_the_tag_list( '', __( ', ', 'mistylake' ) );
(here the get_the_tag_list is the important part), then you can replace this by the following code:
$posttags = get_the_tags();
$first = 1;
$tag_list = '';
if ($posttags)  
  foreach($posttags as $tag)  
    if ($first == 1)  
      $first = 0;
      else  
      $tag_list = $tag_list . __( ', ', 'mistylake' );
     
    $tag_list = $tag_list . '<a href="' . esc_url( home_url( '/tag/' . $tag->slug ) ) . '">' . __($tag->name, 'mistylake') . '</a>';
   
 
(there are for sure simpler ways ) This code loops over the tags and translates them using the __ function. Note that the second parameter must be the text domain of the parent theme. If you have done this right and the web site is still running (I recommend testing it on a test installation I had white pages many times due to php programming errors), and of course you have actual translations available and are looking at a localized version of the web site, then the list of tags as shown by your theme should be translated. Tag cloud widget This one is a tricky one: The tag cloud widget comes by default with WordPress, but doesn t translate the tags. I tried a few variants (e.g. creating a new widget as extension of the original tag cloud widget, and only changing the respective functions), but that didn t work out at all. I finally resorted to a trick: Reading the code of the original widget, I saw that it applies the tag-sort-filter filter on the array of tags. That allows us to hook into the tag cloud creating and translate the tags. You have to add the following code to your child theme s functions.php:
function translate_instead_of_sort($tags)  
  foreach ( (array) $tags as $tag )  
    $tag->name = __( $tag->name , 'mistylake' );
   
  return $tags;
 
add_action('tag_cloud_sort', 'translate_instead_of_sort');
xili-languages3(again, don t forget to change the text domain in the __(.., ..) call!) There might be some more things one could do, like changing the priority to be used after the sorting, or sort directly, but I haven t played around with that. Using the above code and translating several of the tags, the tag cloud now looks like the screenshot on the right I know, it could use some tweaking. Also, now the untranslated tags are sorted all before the translated, things one probably can address with the priority of the filter.
Having done the above things, my blog page when Japanese is selected is now mostly in Japanese, with of course the exception the actual articles, which are in a variety of languages. Open problems There are a few things I haven t managed till now to translate, and they are mostly related to the Jetpack plugin, but not only: I have a few ideas how to tackle this problem: With Jetpack the biggest problem seems that all the strings are translated in a different text domain. So one should be able to add some code to the functions.php to override/add translations to the jetpack text domain. But somehow it didn t work out in my case. The same goes for things that are in the WordPress core and use the translation functions without a text domain so I guess the translation function will use the main WordPress translation files/text domain. Conclusion The good thing of the xili-language plugin is that it does not change the actual posts (some plugins save the translations in the the post text), and is otherwise not too intrusive IMHO. Still, it falls short of allowing to translate various parts of the blog, including the widget areas. I am not sure whether there are better plugins for this usage scenario, I would be surprised if not, but all the plugins I have seen were doing a bit too much on the article translation side and not enough on the translation of the surroundings side. In any case, I would like to see more separation between the functionality of localization (translating the interface) and translation (translating the content). But at the moment I don t have enough impetus to write my own plugin for this. If you have any suggestions for improvement, please let me know! Enjoy.

17 June 2015

DebConf team: Striving for more diversity at DebConf15 (Posted by DebConf Team)

DebConf is not just for Debian Developers, we welcome all members of our community active in different areas, like translation, documentation, artwork, testing, specialized derivatives, and many other ways that help make Debian better. In fact, we would like to open DebConf to an even broader audience, and we strongly believe that more diversity at DebConf and in the Debian community will significantly help us towards our goal of becoming the Universal Operating System. The DebConf team is proud to announce that we have started designing a specific diversity sponsorship programme to attract people to DebConf that would otherwise not consider attending our conference or not be able to join us. In order to apply for this special sponsorship, please write an email to outreach@debian.org, before July 6th, about your interest in Debian and your sponsorship needs (accomodation, travel). Please include a sentence or two about why you are applying for a Diversity Sponsorship. You can also nominate people you think should be considered for this sponsorship programme. Please feel free to send this announcement on to groups or individuals that could be interested in this sponsorship programme. And we re also looking forward to your feedback. We re just getting started and you can help shape these efforts.

16 June 2015

C.J. Adams-Collier: Trip Report: UW signing-party

Dear Debian Users, I met last night with a friend from many years ago and a number of students of cryptography. I was disappointed to see the prevalence of black hat, anti-government hackers at the event. I was hoping that civilized humanity had come to agree that using cryptography for deception, harm to others and plausible deniability is bad, m kay? When one speaks of the government as they, nobody s going to get anywhere really quick. Let s take responsibility for the upkeep of the environment in which we find ourselves, please. Despite what I perceived as a negative focus of the presentation, it was good to meet with peers in the Seattle area. I was very pleasantly surprised to find that better than half of the attendees were not male, that many of the socioeconomic classes of the city were represented, as were those of various ethnic backgrounds. I am really quite proud of the progress of our State University, even if I m not always in agreement with the content that they re polluting our kids brains with. I guess I should roll up my sleeves and get busy, eh? V/R, C.J.

Julien Danjou: Timezones and Python

Recently, I've been fighting with the never ending issue of timezones. I never thought I would have plunged into this rabbit hole, but hacking on OpenStack and Gnocchi I felt into that trap easily is, thanks to Python. Why you really, really, should never ever deal with timezones To get a glimpse of the complexity of timezones, I recommend that you watch Tom Scott's video on the subject. It's fun and it summarizes remarkably well the nightmare that timezones are and why you should stop thinking that you're smart.
The importance of timezones in applications
Once you've heard what Tom says, I think it gets pretty clear that a timestamp without any timezone attached does not give any useful information. It should be considered irrelevant and useless. Without the necessary context given by the timezone, you cannot infer what point in time your application is really referring to. That means your application should never handle timestamps with no timezone information. It should try to guess or raises an error if no timezone is provided in any input. Of course, you can infer that having no timezone information means UTC. This sounds very handy, but can also be dangerous in certain applications or language such as Python, as we'll see. Indeed, in certain applications, converting timestamps to UTC and losing the timezone information is a terrible idea. Imagine that a user create a recurring event every Wednesday at 10:00 in its local timezone, say CET. If you convert that to UTC, the event will end up being stored as every Wednesday at 09:00. Now imagine that the CET timezone switches from UTC+01:00 to UTC+02:00: your application will compute that the event starts at 11:00 CET every Wednesday. Which is wrong, because as the user told you, the event starts at 10:00 CET, whatever the definition of CET is. Not at 11:00 CET. So CET means CET, not necessarily UTC+1. As for endpoints like REST API, a thing I daily deal with, all timestamps should include a timezone information. It's nearly impossible to know what timezone the timestamps are in otherwise: UTC? Server local? User local? No way to know. Python design & defect
Python comes with a timestamp object named datetime.datetime. It can store date and time precise to the microsecond, and is qualified of timezone "aware" or "unaware", whether it embeds a timezone information or not. To build such an object based on the current time, one can use datetime.datetime.utcnow() to retrieve the date and time for the UTC timezone, and datetime.datetime.now() to retrieve the date and time for the current timezone, whatever it is.
>>> import datetime
>>> datetime.datetime.utcnow()
datetime.datetime(2015, 6, 15, 13, 24, 48, 27631)
>>> datetime.datetime.now()
datetime.datetime(2015, 6, 15, 15, 24, 52, 276161)

As you can notice, none of these results contains timezone information. Indeed, Python datetime API always returns unaware datetime objects, which is very unfortunate. Indeed, as soon as you get one of this object, there is no way to know what the timezone is, therefore these objects are pretty "useless" on their own. Armin Ronacher proposes that an application always consider that the unaware datetime objects from Python are considered as UTC. As we just saw, that statement cannot be considered true for objects returned by datetime.datetime.now(), so I would not advise doing so. datetime objects with no timezone should be considered as a "bug" in the application.
Recommendations My recommendation list comes down to:
  1. Always use aware datetime object, i.e. with timezone information. That makes sure you can compare them directly (aware and unaware datetime objects are not comparable) and will return them correctly to users. Leverage pytz to have timezone objects.
  2. Use ISO 8601 as input and output string format. Use datetime.datetime.isoformat() to return timestamps as string formatted using that format, which includes the timezone information.
In Python, that's equivalent to having:
>>> import datetime
>>> import pytz
>>> def utcnow():
return datetime.datetime.now(tz=pytz.utc)
>>> utcnow()
datetime.datetime(2015, 6, 15, 14, 45, 19, 182703, tzinfo=<UTC>)
>>> utcnow().isoformat()
'2015-06-15T14:45:21.982600+00:00'

If you need to parse strings containing ISO 8601 formatted timestamp, you can rely on the iso8601, which returns timestamps with correct timezone information. This makes timestamps directly comparable:
>>> import iso8601
>>> iso8601.parse_date(utcnow().isoformat())
datetime.datetime(2015, 6, 15, 14, 46, 43, 945813, tzinfo=<FixedOffset '+00:00' datetime.timedelta(0)>)
>>> iso8601.parse_date(utcnow().isoformat()) < utcnow()
True

If you need to store those timestamps, the same rule should apply. If you rely on MongoDB, it assumes that all the timestamp are in UTC, so be careful when storing them you will have to normalize the timestamp to UTC. For MySQL, nothing is assumed, it's up to the application to insert them in a timezone that makes sense to it. Obviously, if you have multiple applications accessing the same database with different data sources, this can end up being a nightmare. PostgreSQL has a special data type that is recommended called timestamp with timezone, and which can store the timezone associated, and do all the computation for you. That's the recommended way to store them obviously. That does not mean you should not use UTC in most cases; that just means you are sure that the timestamp are stored in UTC since it's written in the database, and you check if any other application inserted timestamps with different timezone. OpenStack status As a side note, I've improved OpenStack situation recently by changing the oslo.utils.timeutils module to deprecate some useless and dangerous functions. I've also added support for returning timezone aware objects when using the oslo_utils.timeutils.utcnow() function. It's not possible to make it a default unfortunately for backward compatibility reason, but it's there nevertheless, and it's advised to use it. Thanks to my colleague Victor for the help! Have a nice day, whatever your timezone is!

Martin Pitt: autopkgtest 3.14 now twice as rebooty

Almost every new autopkgtest release brings some small improvements, but 3.14 got some reboot related changes worth pointing out. First of all, I simplified and unified the implementation of rebooting across all runners that support it (ssh, lxc, and qemu). If you use a custom setup script for adt-virt-ssh you might have to update it: Previously, the setup script needed to respond to a reboot function to trigger a reboot, wait for the testbed to go down, and come back up. This got split into issuing the actual reboot system command directly by adt-run itself on the testbed, and the wait for go down and back up part. The latter now has a sensible default implementation: it simply waits for the ssh port to become unavailable, and then waits for ssh to respond again; most testbeds should be fine with that. You only need to provide the new wait-reboot function in your ssh setup script if you need to do anything else (such as re-enabling ssh after reboot). Please consult the manpage and the updated SKELETON for details. The ssh runner gained a new --reboot option to indicate that the remote testbed can be rebooted. This will automatically declare the reboot testbed capability and thus you can now run rebooting tests without having to use a setup script. This is very useful for running tests on real iron. Finally, in testbeds which support rebooting your tests will now find a new /tmp/autopkgtest-reboot-prepare command. Like /tmp/autopkgtest-reboot it takes an arbitrary marker , saves the current state, restores it after reboot and re-starts your test with the marker; however, it will not trigger the actual reboot but expects the test to do that. This is useful if you want to test a piece of software which does a reboot as part of its operation, such as a system-image upgrade. Another use case is testing kernel crashes, kexec or another nonstandard way of rebooting the testbed. README.package-tests shows an example how this looks like. 3.14 is now available in Debian unstable and Ubuntu wily. As usual, for older releases you can just grab the deb and install it, it works on all supported Debian and Ubuntu releases. Enjoy, and let me know if you run into troubles or have questions!

15 June 2015

Lunar: Reproducible builds: week 7 in Stretch cycle

What happened about the reproducible builds effort for this week: Presentations On June 7th, Reiner Herrmann presented the project at the Gulaschprogrammiernacht 15 in Karlsruhe, Germany. Video and audio recordings in German are available, and so are the slides in English. Toolchain fixes Daniel Kahn Gillmor's report on help2man started a discussion with Brendan O'Dea and Ximin Luo about standardizing a common environment variable that would provide a replacement for an embedded build date. After various proposals and research by Ximin about date handling in several programming languages, the best solution seems to define SOURCE_DATE_EPOCH with a value suitable for gmtime(3).
  1. Martin Borgert wondered if Sphinx could be changed in a way that would avoid having to tweak debian/rules in packages using it to produce HTML documentation.
Daniel Kahn Gillmor opened a new report about icont producing unreproducible binaries. Packages fixed The following 32 packages became reproducible due to changes in their build dependencies: agda, alex, c2hs, clutter-1.0, colorediffs-extension, cpphs, darcs-monitor, dispmua, haskell-curl, haskell-glfw, haskell-glib, haskell-gluraw, haskell-glut, haskell-gnutls, haskell-gsasl, haskell-hfuse, haskell-hledger-interest, haskell-hslua, haskell-hsqml, haskell-hssyck, haskell-libxml-sax, haskell-openglraw, haskell-readline, haskell-terminfo, haskell-x11, jarjar-maven-plugin, kxml2, libcgi-struct-xs-perl, libobject-id-perl, maven-docck-plugin, parboiled, pegdown. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which did not make their way to the archive yet: reproducible.debian.net A new variation to better notice when a package captures the environment has been introduced. (h01ger) The test on Debian packages works by building the package twice in a short time frame. But sometimes, a mirror push can happen between the first and the second build, resulting in a package built in a different build environment. This situation is now properly detected and will run a third build automatically. (h01ger) OpenWrt, the distribution specialized in embedded devices like small routers, is now being tested for reproducibility. The situation looks very good for their packages which seems mostly affected by timestamps in the tarball. System images will require more work on debbindiff to be better understood. (h01ger) debbindiff development Reiner Herrmann added support for decompling Java .class file and .ipk package files (used by OpenWrt). This is now available in version 22 released on 2015-06-14. Documentation update Stephen Kitt documented the new --insert-timestamp available since binutils-mingw-w64 version 6.2 available to insert a ready-made date in PE binaries built with mingw-w64. Package reviews 195 obsolete reviews have been removed, 65 added and 126 updated this week. New identified issues: Misc. Holger Levsen reported an issue with the locales-all package that Provides: locales but is actually missing some of the files provided by locales. Coreboot upstream has been quick to react after the announcement of the tests set up the week before. Patrick Georgi has fixed all issues in a couple of days and all Coreboot images are now reproducible (without a payload). SeaBIOS is one of the most frequently used payload on PC hardware and can now be made reproducible too. Paul Kocialkowski wrote to the mailing list asking for help on getting U-Boot tested for reproducibility. Lunar had a chat with maintainers of Open Build Service to better understand the difference between their system and what we are doing for Debian.

Next.

Previous.