Search Results: "reg"

24 March 2014

Michael Prokop: Building Debian+Ubuntu packages on EC2

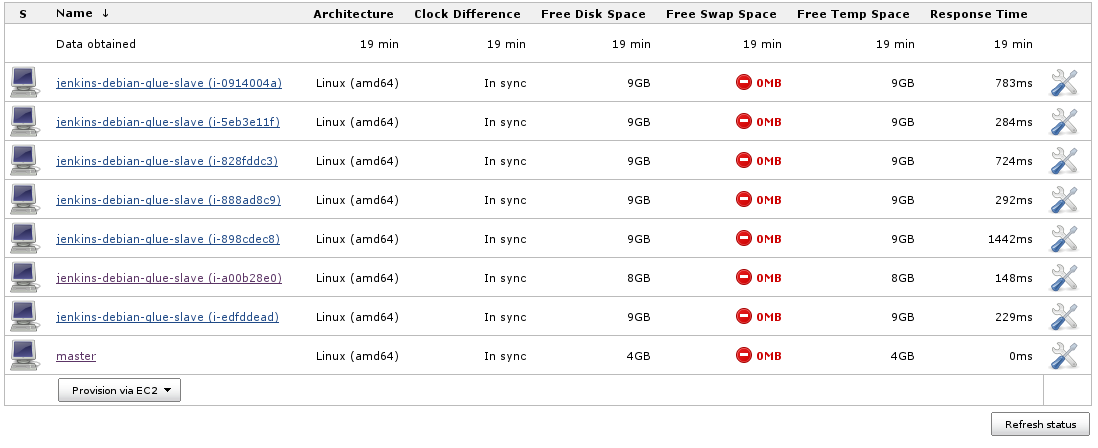
In a project I recently worked on we wanted to provide a jenkins-debian-glue based setup on Amazon s EC2 for building Debian and Ubuntu packages. The idea is to keep a not-so-strong powered Jenkins master up and running 24 7, while stronger machines serving as Jenkins slaves should be launched only as needed. The project setup in question is fully open sourced (more on that in a separate blog post), hereby I am documenting the EC2 setup in usage. Jenkins master vs. slave Debian source packages are generated on Jenkins master where a checkout of the Git repository resides. The Jenkins slaves do the actual workload by building the binary packages and executing piuparts (.deb package installation, upgrading, and removal testing tool) on the resulting binary packages. The Debian packages (source+binaries) are then provided back to Jenkins master and put into a reprepro powered Debian repository for public usage. Preparation The starting point was one of the official Debian AMIs (x86_64, paravirtual on EBS). We automatically deployed jenkins-debian-glue on the system which is used as Jenkins master (we chose a m1.small instance for our needs). We started another instance, slightly adjusted it to already include jenkins-debian-glue related stuff out-of-the-box (more details in section Reduce build time below) and created an AMI out of it. This new AMI ID can be configured for usage inside Jenkins by using the Amazon EC2 Plugin (see screenshot below). IAM policy Before configuring EC2 in Jenkins though start by adding a new user (or group) in AWS s IAM (Identity and Access Management) with a custom policy. This ensures that your EC2 user in Jenkins doesn t have more permissions than really needed. The following policy should give you a starting point (we restrict the account to allow actions only in the EC2 region eu-west-1, YMMV):
 
  "Version": "2012-10-17",
  "Statement": [
     
      "Action": [
        "ec2:CreateTags",
        "ec2:DescribeInstances",
        "ec2:DescribeImages",
        "ec2:DescribeKeyPairs",
        "ec2:GetConsoleOutput",
        "ec2:RunInstances",
        "ec2:StartInstances",
        "ec2:StopInstances",
        "ec2:TerminateInstances"
      ],
      "Effect": "Allow",
      "Resource": "*",
            "Condition":  
                "StringEquals":  
                    "ec2:Region": "eu-west-1"


  ]
 
Jenkins configuration Configure EC2 access with Access Key ID , Secret Access Key , Region and EC2 Key Pair s Private Key (for SSH login) inside Jenkins in the Cloud section on $YOUR_JENKINS_SERVER/configure. Finally add an AMI in the AMIs Amazon EC2 configuration section (adjust security-group as needed, SSH access is enough): As you can see the configuration also includes a launch script. This script ensures that slaves are set up as needed (provide all the packages and scripts that are required for building) and always get the latest configuration and scripts before starting to serve as Jenkins slave. Now your setup should be ready for launching Jenkins slaves as needed: NOTE: you can use the Instance Cap configuration inside the advanced Amazon EC2 Jenkins configuration section to place an upward limit to the number of EC2 instances that Jenkins may launch. This can be useful for avoiding surprises in your AWS invoices. :) Notice though that the cap numbers are calculated for all your running EC2 instances, so be aware if you have further machines running under your account, you might want to e.g. further restrict your IAM policy then. Reduce build time Using a plain Debian AMI and automatically installing jenkins-debian-glue and further jenkins-debian-glue-buildenv* packages on each slave startup would work but it takes time. That s why we created our own AMI which is nothing else than an official Debian AMI with the bootstrap.sh script (which is referred to in the screenshot above) already executed. All the necessary packages are pre-installed and also all the cowbuilder environments are already present then. From time to time we start the instance again to apply (security) updates and execute the bootstrap script with its &dash&dashupdate option to also have all the cowbuilder systems up2date. Creating a new AMI is a no-brainer and we can then use the up2date system for our Jenkins slaves, if something should break for whatever reason we can still fall back to an older known-to-be-good AMI. Final words How to set up your Jenkins jobs for optimal master/slave usage, multi-distribution support (Debian/Ubuntu) and further details about this setup are part of another blog post. Thanks to Andreas Granig, Victor Seva and Bernhard Miklautz for reading drafts of this.

Steve Kemp: So I failed at writing some clustered code in Perl

Until this time next month I'll be posting code-based discussions only. Recently I've been wanting to explore creating clustered services, because clusters are definitely things I use professionally. My initial attempt was to write an auto-clustering version of memcached, because that's a useful tool. Writing the core of the service took an hour or so: At the point I was done the following code worked:
use KeyVal;
# Create an object, and set some values
my $obj = KeyVal->new( logfile => "/tmp/foo.log" );
$obj->incr( "steve" );
print $obj->get( "steve" ) # prints 2.
# Now replay the append-only log
my $replay = KeyVal->new( logfile => "/tmp/foo.log" );
$replay->replay();
print $replay->get( "steve" ) # prints 2.
In the first case we used the primitives to increment a value twice, and then fetch it. In the second case we used the logfile the first object created to replay all prior transactions, then output the value. Neat. The next step was to make it work over a network. Trivial. Finally I wanted to autodetect peers, and deploy replication. Each host would send out regular messages along the lines of "Do you have updates made since $time?". Any that did would replay the logfile from the given unixtime offset. However here I ran into problems. Peer discovery was supposed to be basic, and I figured I'd write something that did leader election by magic. Unfortunately Perls threading code is .. unpleasant: This failed. Majorly. Because you cannot launch the implementation of a class-method as a thread. Equally you cannot make a variable which is "complex" shared across threads. I wrote some demo code which works without packages and a shared singleton: The Ruby version, by contrast, is much more OO and neater. Meh. I've now shelved the project. My next, big, task was to make the network service utterly memcached compatible. That would have been fiddly, but not impossible. Right now I just use a simple line-based network protocol. I suspect I could have got what I wanted using EventMachine, or similar, but that's a path I've not yet explored, and I'm happy enough with that decision.

23 March 2014

Gregor Herrmann: RC bugs 2013/49 - 2014/12

since people keep talking to me about my RC bug fixing activities, I thought it might be time again for a short report. to be honest, I mostly stopped my almost daily work at some point in december, partly because the overall number of RC bugs affecting both testing & unstable is quite low (& therefore the number of easy-to-fix bugs), due to the auto-removal policy of the release team (kudos!). but I still kept track about RC bugs I worked on, & here's the list; as you can see, mostly pkg-perl bugs ps: the how-can-i-help package is a nice tool for finding RC bugs in packages you care about. install it if you haven't so far!

Niels Thykier: Upcoming changes to Lintian (in 2.5.22)

The next version of Lintian, 2.5.22, is long overdue mostly because 2.5.21 FTBFS in sid. Besides fixing test failures, 2.5.22 also fixes: Besides bug fixes, we also added a couple of new features/nice changes: We just need to do some final tweaks and get the tag descriptions reviewed before we are ready to release the next version.

Russell Coker: Aldi Deserves an Award for Misleading Email

Aldi Mobile has made a significant change to their offerings. They previously had an offer of $35 for unlimited calls and 2.5G of data in a month for which they had to publicly apologise for misleading customers as 2500 minutes of calls a month (83 minutes per day) is no-where near unlimited [1]. They also had an offer of $15 for 2G of data. In an email about this Aldi said Many of our customers are using a lot less than what is included in our current $35 plan. So we will soon be introducing new Value Packs with more flexible options; meaning you only pay for what you really need and they start from just $10. . That is grossly misleading, if they offered new plans in addition to the old ones and allowed customers to choose the plan that is the best match then it would be useful to some customers. But removing the supposedly unlimited plan and the $15 for 2G of data option is removing affordable options for people who want to use their phones for lots of calls or very few calls but moderate amounts of data use. New Plans The base rate for calls on Aldi pre-paid is $0.12 per minute and $0.12 per SMS, consider every mention of minute in this section to be minute or SMS . The Aldi Newplans page [2] starts with a $10 per month plan which offers 100 minutes of calls which would be $12 at the previous rate of $0.12 per minute. That is OK value when compared to just using the pre-paid calls if you consistently use more than 83 minutes of calls per month. However if you don t use 84 minutes of calls (EG you don t speak much on the phone and use Google Hangouts instead of SMS) then it s not good value. Also the advertised data use is $5 per 100MB, which is way below what is needed for a typical user with an Android phone. My mother in law was barely able to stick within a limit of 300MB/month when that was her limit, but while using the Aldo 2G/month bolt-on she s increased her data usage. The smallest of the new plans costs $20 per month, it provides 300 minutes of calls and includes 300MB of data. For an extra $7 you can get another 300MB of data. For my mother in law it seems that the cheapest option on the new plans would be $27 per month, that would cover the 60 minutes of calls she might make and the 450MB of data she s probably using. That s significantly more expensive than her previous cost of $15 for 2G of data and $7.20 for calls and has the additional difficulty that I would have to be more involved in helping her avoid excessive data use. The 2G data bolt-on was really good for some of my relatives, when they use that and configure their phones not to update software over 3G they never had to ask me about any problems related to excess data use. So my mother in law is facing an extra $5 per month (or maybe more depending on data use) and more time spent calling me for tech support. The data bolt on that Aldi is going to offer in future is $30 for 3G of data to replace the previous offer of $15 for 2G of data. The cost will be unchanged for anyone who uses between 2G and 3G a month, for everyone who uses less than 2G or more than 3G the data bolt-on will cost more. There is simply no possibility for any Aldi data-only customer to save on data use. The only way someone who uses a moderate amount of data could save money is if they use more than 160 minutes of calls and less than 1G of data. Disclaimer My analysis above is based on interpreting the Aldi web site. As with most telcos they aren t trying to make things easy in this regard, it seems that the consensus of opinion among telcos is to use complex pricing to make it difficult to compare and reduce competitive pressure. I blame any inaccuracies in my analysis on the Aldi web site. Why Aldi Shouldn t Mislead Customers Aldi isn t primarily a mobile phone company, their main business is running a supermarket. The trust of customers is important to them, raising prices when competition goes away is one thing, but misleading customers about it is another. If Aldi were to honestly say now that Kogan Mobile no longer exists there is nothing forcing us to have low prices then I d have a lot more respect for their company and be more inclined to shop at their supermarket. It s a sad indictment of our society that I need to include a why lying is wrong section in such a blog post.

22 March 2014

Keith Packard: glamor-core

Core Rendering with Glamor I ve hacked up the intel driver to bypass all of the UXA paths when Glamor is enabled so I m currently running an X server that uses only Glamor for all rendering. There are still too many fall backs, and performance for some operations is not what I d like, but it s entirely usable. It supports DRI3, so I even have GL applications running. Core Rendering Status I ve continued to focus on getting the core X protocol rendering operations complete and correct; those remain a critical part of many X applications and are a poor match for GL. At this point, I ve got accelerated versions of the basic spans functions, filled rectangles, text and copies. GL and Scrolling OpenGL has been on a many-year vendetta against one of the most common 2D accelerated operations copying data within the same object, even when that operation overlaps itself. This used to be the most performance-critical operation in X; it was used for scrolling your terminal windows and when moving windows around on the screen. Reviewing the OpenGL 3.x spec, Eric and I both read the glCopyPixels specification as clearly requiring correct semantics for overlapping copy operations it says that the operation must be equivalent to reading the pixels and then writing the pixels. My CopyArea acceleration thus uses this path for the self-copy case. However, the ARB decided that having a well defined blt operation was too nice to the users, so the current 4.4 specification adds explicit language to assert that this is not well defined anymore (even in the face of the existing language which is pretty darn unambiguous). I suspect we ll end up creating an extension that offers what we need here; applications are unlikely to stop scrolling stuff around, and GPUs (at least Intel) will continue to do what we want. This is the kind of thing that makes GL maddening for 2D graphics the GPU does what we want, and the GL doesn t let us get at it. For implementations not capable of supporting the required semantic, someone will presumably need to write code that creates a temporary copy of the data. PBOs for fall backs For operations which Glamor can t manage, we need to fall back to using a software solution. Direct-to-hardware acceleration architectures do this by simply mapping the underlying GPU object to the CPU. GL doesn t provide this access, and it s probably a good thing as such access needs to be carefully synchronized with GPU access, and attempting to access tiled GPU objects with the CPU require either piles of CPU code to de-tile accesses (ala wfb), or special hardware detilers (like the Intel GTT). However, GL does provide a fairly nice abstraction called pixel buffer objects (PBOs) which work to speed access to GPU data from the CPU. The fallback code allocates a PBO for each relevant X drawable, asks GL to copy pixels in, and then calls fb, with the drawable now referencing the temporary buffer. On the way back out, any potentially modified pixels are copied back through GL and the PBOs are freed. This turns out to be dramatically faster than malloc ing temporary buffers as it allows the GL to allocate memory that it likes, and for it to manage the data upload and buffer destruction asynchronously. Because X pixmaps can contain many X windows (the root pixmap being the most obvious example), they are often significantly larger than the actual rendering target area. As an optimization, the code only copies data from the relevant area of the pixmap, saving considerable time as a result. There s even an interface which further restricts that to a subset of the target drawable which the Composite function uses. Using Scissoring for Clipping The GL scissor operation provides a single clipping rectangle. X provides a list of rectangles to clip to. There are two obvious ways to perform clipping here either perform all clipping in software, or hand each X clipping rectangle in turn to GL and re-execute the entire rendering operation for each rectangle. You d think that the former plan would be the obvious choice; clearly re-executing the entire rendering operation potentially many times is going to take a lot of time in the GPU. However, the reality is that most X drawing occurs under a single clipping rectangle. Accelerating this common case by using the hardware clipper provides enough benefit that we definitely want to use it when it works. We could duplicate all of the rendering paths and perform CPU-based clipping when the number of rectangles was above some threshold, but the additional code complexity isn t obviously worth the effort, given how infrequently it will be used. So I haven t bothered. Most operations look like this:
Allocate VBO space for data
Fill VBO with X primitives
loop over clip rects  
    glScissor()
    glDrawArrays()
 
This obviously out-sources as much of the problem as possible to the GL library, reducing the CPU time spent in glamor to a minimum. A Peek at Some Code With all of these changes in place, drawing something like a list of rectangles becomes a fairly simple piece of code: First, make sure the program we want to use is available and can be used with our GC configuration:
prog = glamor_use_program_fill(pixmap, gc,
                               &glamor_priv->poly_fill_rect_program,
                               &glamor_facet_polyfillrect);
if (!prog)
    goto bail_ctx;
Next, allocate the VBO space and copy all of the X data into it. Note that the data transfer is simply memcpy here that s because we break the X objects apart in the vertex shader using instancing, avoiding the CPU overhead of computing four corner coordinates.
/* Set up the vertex buffers for the points */
v = glamor_get_vbo_space(drawable->pScreen, nrect * (4 * sizeof (GLshort)), &vbo_offset);
glEnableVertexAttribArray(GLAMOR_VERTEX_POS);
glVertexAttribDivisor(GLAMOR_VERTEX_POS, 1);
glVertexAttribPointer(GLAMOR_VERTEX_POS, 4, GL_SHORT, GL_FALSE,
                      4 * sizeof (GLshort), vbo_offset);
memcpy(v, prect, nrect * sizeof (xRectangle));
glamor_put_vbo_space(screen);
Finally, loop over the pixmap tile fragments, and then over the clip list, selecting the drawing target and painting the rectangles:
glEnable(GL_SCISSOR_TEST);
glamor_pixmap_loop(pixmap_priv, box_x, box_y)  
    int nbox = RegionNumRects(gc->pCompositeClip);
    BoxPtr box = RegionRects(gc->pCompositeClip);
    glamor_set_destination_drawable(drawable, box_x, box_y, TRUE, FALSE, prog->matrix_uniform, &off_x, &off_y);
    while (nbox--)  
        glScissor(box->x1 + off_x,
                  box->y1 + off_y,
                  box->x2 - box->x1,
                  box->y2 - box->y1);
        box++;
        glDrawArraysInstanced(GL_TRIANGLE_STRIP, 0, 4, nrect);
     
 
GL texture size limits X pixmaps use 16 bit dimensions for width and height, allowing them to be up to 65536 x 65536 pixels. Because the X coordinate space is signed, only a quarter of this space is actually useful, which makes the useful size of X pixmaps only 32767 x 32767. This is still larger than most GL implementations offer as a maximum texture size though, and while it would be nice to just say we don t allow pixmaps larger than GL textures , the reality is that many applications expect to be able to allocate such pixmaps today, largely to hold the ever increasing size of digital photographs. Glamor has always supported large X pixmaps; it does this by splitting them up into tiles, each of which is no larger than the largest texture supported by the driver. What I ve added to Glamor is some simple macros that walk over the array of tiles, making it easy for the rendering code to support large pixmaps without needing any special case code. Glamor also had some simple testing support you can compile the code to ignore the system-provided maximum texture size and supply your own value. This code had gone stale, and couldn t work as there were parts of the code for which tiling support just doesn t make sense, like the glyph cache, or the X scanout buffer. I fixed things so that you could leave those special cases as solitary large tiles while breaking up all other pixmaps into tiles no larger than 32 pixels square. I hope to remove the single-tile case and leave the code supporting only the multiple-tile case; we have to have the latter code, and so having the single-tile code around simply increases our code size for not obvious benefit. Getting accelerated copies between tiled pixmaps added a new coordinate system to the mix and took a few hours of fussing until it was working. Rebasing Many (many) Times I m sure most of us remember the days before git; changes were often monolithic, and the notion of changing how the changes were made for the sake of clarity never occurred to anyone. It used to be that the final code was the only interesting artifact; how you got there didn t matter to anyone. Things are different today; I probably spend a third of my development time communicating how the code should change with other developers by changing the sequence of patches that are to be applied. In the case of Glamor, I ve now got a set of 28 patches. The first few are fixes outside of the glamor tree that make the rest of the server work better. Then there are a few general glamor infrastructure additions. After that, each core operation is replaced, one a at a time. Finally, a bit of stale code is removed. By sequencing things in a logical fashion, I hope to make review of the code easier, which should mean that people will spend less time trying to figure out what I did and be able to spend more time figuring out if what I did is reasonable and correct. Supporting Older Versions of GL All of the new code uses vertex instancing to move coordinate computation from the CPU to the GPU. I m also pulling textures apart using integer operations. Right now, we should correctly fall back to software for older hardware, but it would probably be nicer to just fall back to simpler GL instead. Unless everyone decides to go buy hardware with new enough GL driver support, someone is going to need to write simplified code paths for glamor. If you ve got such hardware, and are interested in making it work well, please take this as an opportunity to help yourself and others. Near-term Glamor Goals I m pretty sure we ll have the code in good enough shape to merge before the window closes for X server 1.16. Eric is in charge of the glamor tree, so it s up to him when stuff is pulled in. He and Markus Wick have also been generating code and reviewing stuff, but we could always use additional testing and review to make the code as good as possible before the merge window closes. Markus has expressed an interest in working on Glamor as a part of the X.org summer of code this year; there s clearly plenty of work to do here, Eric and I haven t touched the render acceleration stuff at all, and that code could definitely use some updating to use more modern GL features. If that works as well as the core rendering code changes, then we can look forward to a Glamor which offers GPU-limited performance for classic X applications, without requiring GPU-specific drivers for every generation of every chip.

21 March 2014

Sylvestre Ledru: Rebuild of Debian using Clang 3.4

Using the AWS donation, David Suarez and myself have been able to rebuild the whole archive with Clang 3.4.
The rebuild has been done January 10th but, with my new job, I did not find the time to publish the result.
Releases after releases, the results are getting better and better. Currently, 2193 packages in the archive are failing to build from source.
That is roughly the same number of build failures as with the precedent rebuild with Clang 3.3.
However, this is good news for two reasons:
* the number of new packages in Debian increased (18854 at time of the 3.3 release, 21204 for the 3.4)
* clang 3.4 has more checks and error detections. I also started to update clang to make it closer to gcc. For example, I transformed wrong usage of -O (> 6) error to be treated as regular warning. However, a critical bug has emerged during this release. When using -D_FORTIFY_SOURCE=2 (which is the case of many Debian packages), the binaries produced freeze (infinity loop in the ASM). This has been reported upstream as bug 16821 and concerns about 150 packages (including Firefox, gcc, LLVM, etc). Hopefully, this will be fixed in 3.5 (this is unlikely for 3.4.1). About the new build failures, now, Clang triggers an error (or warning + -Werror) on: * Wrong usage of the default argument (should be done in the definition)
16 occurrences * Usage of C++11 feature without the appropriate argument
7 occurrences * Unused static const declaration
5 occurrences * Recursive template instantiation exceeded
4 occurrences * Defitinion of a builtin function
3 occurrences * Read-only variable is not assignable
2 occurrences By the way, I proposed a Google Summer of Code Project to work faster on a support of Debian built by Clang. As requirements, I asked students to fix some bugs, they already did a great job.

Andrew Pollock: [life] Day 52, Trial Ballet class, rain and paint, Science Friday

I woke up at 2am, and then spent over an hour trying to get back to sleep. That was phenomenally annoying. Then at 5am, Zoe's white noise app on her Nexus 7 decided to go a bit wonky (as it does from time to time), which caused her to wake up. I couldn't convince her tablet to behave, so I just let her get in bed with me, but neither of us went back to sleep. I think at about 6am I told her she could turn on the TV so I could try and squeeze in a bit more rest. I managed to forget to put the oats in the Thermomix when I made porridge this morning. It took me a while to figure out why the consistency and colour didn't look quite right when I dished it up. Yep, it was one of those mornings. Zoe had her trial ballet class this morning, at 9:45am in Coorparoo. I managed to get Zoe organised a bit early, so we were the first ones there. It's in a church hall, and has a nice floor, with a mirrored wall and barres on each long wall. Eventually the other girls arrived, there were 5 regulars in total. A good sized class. I had mixed feelings when I discovered that parents weren't normally able to be present in the dance studio to watch the classes. I was today, because it was a trial, but once Zoe starts regular classes, I'll have to wait outside. I'm disappointed I won't be able to watch, but it'll be nice to have 45 minutes to myself. Zoe did really well in the class today. She picked everything up very quickly, and I don't think she'll be negatively impacted by having entered in Term 2. She seemed very comfortable and looked like she enjoyed herself. Not long after we arrived, the heavens opened in a massive downpour, which continued when we had to leave. It was a fair dash back to the car. I'd had plans of a picnic lunch in New Farm Park, but scrapped them on account of the weather. We got home, and had a late morning tea, and then Zoe wanted to play with her Marble Run. After that, we gave Smudge a good brushing and then Zoe wanted to do some craft and painting. I let Zoe set herself up, and it was fun to see what bits and pieces she chose to dig out of the arts and craft bins. She wanted to make another crown for Mummy's boss, but we don't have any crown making stuff at home (yet), so she ended up starting to decorate a wand and gluing a pom pom on a shoe box, before moving on to painting her cardboard box cubby house and rocket. She wanted to start doing some hand painting right around lunch time, but I managed to convince her to do that after lunch. We had some lunch, and then she did a little bit more painting and stickering before her nap. She passed out for her nap very quickly. After her nap, I asked her if she wanted to paint or do science, and without hesitation, she chose science! I delved into the "Weather" chapter of 365 Science Experiments and we did a couple with ice cubes and salt and then she saw one where you stick a balloon over the neck of a glass bottle and put it in hot water and the balloon "inflates", so we did that one as well. We also popped a balloon to simulate thunder. It was all nice and easy, without a lot of preparation required. After that, we did a bit of a clean up and then Zoe watched some of her DVDs from the library while she waited for Sarah to arrive to pick her up. It was a good day today. No meltdowns.

20 March 2014

Steve Kemp: Time to mix things up again

I'm currently a contractor, working for/with Dyn, until April the 11th. I need to decide what I'm doing next, if anything. In the meantime here are some diversions:
Some trivial security issues
I noticed and reported two more temporary-file issues insecure temporary file usage in apt-extracttemplates (apt), and libreadline6: Insecure use of temporary files - in _rl_trace. Neither of those are particularly serious, but looking for them took a little time. I recently started re-auditing code, and decided to do three things:
  • Download the source code to every package installed upon this system.
  • Download the source code to all packages matching the pattern ^libpam-, and ^libruby-*.
I've not yet finished slogging through the code, but my expectation will be a few more issues. I'll guess 5-10, given my cynical nature.
NFS-work
I've been tasked with the job of setting up a small cluster running from a shared and writeable NFS-root. This is a fun project which I've done before, PXE-booting a machine and telling it to mount a root filesystem over NFS is pretty straight-forward. The hard part is making that system writeable, such that you can boot and run "apt-get install XX". I've done it in the past using magic filesystems, or tmpfs. Either will work here, so I'm not going to dwell on it.
Another year
I had another birthday, so that was nice. My wife took me to a water-park where we swam like fisheseses, and that tied in nicely with a recent visit to Deep Sea World, where we got to walk through a glass tunnel, beneath a pool FULL OF SHARKS, and other beasties. Beyond that I received another Global Knife, which has now been bloodied, since I managed to slice my finger open chopping mushrooms on Friday. Oops. Currently I'm in that annoying state where I'm slowly getting used to typing with a plaster around the tip of my finger, but knowing that it'll have to come off again and I'll get confused again.
Linux Distribution
I absolutely did not start working on a "linux distribution", because that would be crazy. Do I look like a crazy-person? All I did was play around with GNU Stow, and ponder the idea of using a minimal LibC and GNU Stow to organize things. It went well, but the devil is always in the details. I like the idea of a master-distribution which installs pam, ssh, etc, but then has derivitives for "This is a webserver", "This is a Ruby server", and "This is a database server". Consider it like task-selection, but with higher ambition.
There's probably more I could say; a new kitchen sink (literally) and a new tap have made our kitchen nicer, I've made it past six months of regular gym-based workouts, and I didn't die when I went to the beach in the dark the other night, so that was nice. Umm? Stuff? Have a nice day. Thanks.

Andrew Pollock: [life] Day 51, BJJ, library, lunch at Grill'd and a play in the park

Despite having a good, unbroken night's sleep, Zoe seemed a bit out of sorts this morning. She didn't have a particularly good breakfast. I'm not sure if that was because I made the porridge with cow's milk instead of almond milk (because I had some leftover cow's milk), or she was just having a bad day. Zoe has a trial dance class booked for tomorrow, which clashes with her normal Brazilian Jiu-Jitsu class, so we skipped Playgroup and did a BJJ class this morning. It was a good class, because there were 3 other kids there, a regular boy and girl, and a girl who was taking a trial class, so it was nice to have a bit more happening, but the two other regular kids were younger and a little less focused, and I think that distracted Zoe a bit. I think the lack of a decent breakfast also kicked in, and she went on strike a couple of times. Overall, it was a pretty good class though. The one downside was when I accidentally closed her fingers in the door on the way out. I didn't realise she was holding onto the door frame when I let go of the door I was holding open for her. Luckily it wasn't a heavy door or it could have ended more badly. Zoe had chosen to go to BJJ class by car today. I wondered if it was because of the improved music selection with the new radio. Her library books were due back soon, and since I don't have her this weekend, I thought we could just go to the library after BJJ class. I gave her a muesli bar to keep her going after BJJ class, but I think the lack of a good breakfast was really starting to show after we left the library. I was feeling like lunch out, and hadn't been to Grill'd for a while, nor sampled their kids menu, so I asked Zoe if she wanted a burger for lunch, and she said she did. We got to Grill'd, and I eventually managed to extract an order out of Zoe. She went for the mini chicken burger. The kid's menu items were pretty good. They came in a little box, with the burger, some chips, a popper (a.k.a. "juice box") and a colouring sheet with a set of colouring pencils. Unfortunately Zoe had a massive meltdown because she couldn't get the angle of her straw to her liking, and wasn't doing very well expressing how she wanted it ("down and then up" didn't make a whole lot of sense without it having bendy bits in places it didn't have bendy bits). Eventually I got her to eat. I'd say that food was definitely the issue, because after lunch she perked up significantly, and we had a nice little play in Bulimba Memorial Park, where I'd parked the car, and then we went home. We read a few of the new library books, and then she passed out for a late nap without much complaint. After her nap, she was still a little bit out of sorts, but we managed a walk down to the Hawthorne Garage to grab some lamb cutlets for dinner, and then she watched some TV and ate quite a good amount of fruit while I organised dinner. After a handwashing-related meltdown and dinner, we went back to the Hawthorne Garage for a babyccino. She'd perked up somewhat by this stage, and it was a nice outing. Many dogs were patted while there and on the way home. Bath time and bedtime went pretty well. It's another warm night, so I hope she sleeps well.

18 March 2014

Vincent Bernat: EDNS client subnet support for BIND

To provide geolocation-aware answers with BIND, a common solution is to use a patch adding GeoIP support. A client can be directed to the closest (and hopefully fastest) web server:
view "FRANCE"  
     match-clients   geoip_cityDB_country_FR;  ;
     zone "example.com" in  
         type master;
         file "france.example.com.dns";
      ;
 ;
view "GERMANY"  
     match-clients   geoip_cityDB_country_DE;  ;
     zone "example.com" in  
         type master;
         file "germany.example.com.dns";
      ;
 ;
/* [...] */
view "DEFAULT"  
    zone "example.com" in  
        type master;
        file "example.com.dns";
     ;
 ;
However, an end user does not usually talk directly to authoritative servers. They proxy the query to a third-party recursor server which will query the authoritative server on their behalf. The recursor also caches the answer to be able to serve it directly to other clients. On most cases, we can still rely on the recursor GeoIP location to forward the client to the closest web server because it is located in the client s ISP network, as shown on the following schema: Query for www.example.com through an ISP recursor
  1. Juan is located in China and wants to know the IP address of www.example.com. She queries her ISP resolver.
  2. The resolver asks the authoritative server for the answer.
  3. Because the IP address of the resolver is located in China, the authoritative server decides to answer with the IP address of the web server located in Japan which is the closest one.
  4. Juan can now enjoy short round-trips with the web server.
However, this is not the case when using a public recursor as provided by Google or OpenDNS. In this case, the IP address of the end client and the source IP address of the recursor may not share the same locality. For example, in the following schema, the authoritative server now thinks it is in relation with an European customer and answers with the IP address of the web server located in Europe: Query for www.example.com through an open recursor Moreover, caching makes the problem worse. To solve this problem, a new EDNS extension to expose the client subnet has been proposed. When using this extension, the recursor will provide the client subnet to the authoritative server for it to build an optimized reply. The subnet is vague enough to respect client s privacy but precise enough to be able to locate it. A patched version of dig allows one to make queries with this new extension:
$ geoiplookup 138.231.136.0
GeoIP Country Edition: FR, France
$ ./bin/dig/dig @dns-02.dailymotion.com www.dailymotion.com \
>     +client=138.231.136.0/24
; <<>> DiG 9.8.1-P1-geoip-1.3 <<>> @dns-02.dailymotion.com www.dailymotion.com +client=138.231.136.0/24
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 23312
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
; CLIENT-SUBNET: 138.231.136.0/24/24
;; QUESTION SECTION:
;www.dailymotion.com.           IN      A
;; ANSWER SECTION:
www.dailymotion.com.    600     IN      A       195.8.215.136
www.dailymotion.com.    600     IN      A       195.8.215.137
;; Query time: 20 msec
;; SERVER: 188.65.127.2#53(188.65.127.2)
;; WHEN: Sun Oct 20 15:44:47 2013
;; MSG SIZE  rcvd: 91
$ geoiplookup 195.8.215.136
GeoIP Country Edition: FR, France
In the above example, a client located in France gets a reply with two IP addresses located in France. If we now are an US client, we will get IP addresses located in the US:
$ geoiplookup 170.149.100.0
GeoIP Country Edition: US, United States
$ ./bin/dig/dig @dns-02.dailymotion.com www.dailymotion.com \
>     +client=170.149.100.0/24
; <<>> DiG 9.8.1-P1-geoip-1.3 <<>> @dns-02.dailymotion.com www.dailymotion.com +client=170.149.100.0/24
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 23187
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
; CLIENT-SUBNET: 170.149.100.0/24/24
;; QUESTION SECTION:
;www.dailymotion.com.           IN      A
;; ANSWER SECTION:
www.dailymotion.com.    600     IN      A       188.65.120.135
www.dailymotion.com.    600     IN      A       188.65.120.136
;; Query time: 18 msec
;; SERVER: 188.65.127.2#53(188.65.127.2)
;; WHEN: Sun Oct 20 15:47:22 2013
;; MSG SIZE  rcvd: 91
$ geoiplookup 188.65.120.135
GeoIP Country Edition: US, United States
The recursor is expected to cache the two different answers and only serve them if the client matches the appropriate subnet (the one confirmed in the answer from the authoritative server). With this new extension, the authoritative server knows that Juan is located in China and answers with the appropriate IP address: Query for www.example.com through an open recursor with client subnet Not many authoritative servers support this extension (PowerDNS and gdnsd, as far as I know). At Dailymotion, we have built a patch for BIND. It only works when BIND is configured as an authoritative server and it doesn t expose no configuration knobs. Feel free to use it (at your own risk). Once installed, you need to register yourself to OpenDNS and to Google to receive queries with the extension enabled.

16 March 2014

Benjamin Mako Hill: Community Data Science Workshops in Seattle

Photo from the Boston Python Workshop   a similar workshop run in Boston that has inspired and provided a template for the CDSW.

Photo from the Boston Python Workshop a similar workshop run in Boston that has inspired and provided a template for the CDSW.

On three Saturdays in April and May, I will be helping run three day-long project-based workshops at the University of Washington in Seattle. The workshops are for anyone interested in learning how to use programming and data science tools to ask and answer questions about online communities like Wikipedia, Twitter, free and open source software, and civic media. The workshops are for people with no previous programming experience and the goal is to bring together researchers as well as participants and leaders in online communities. The workshops will all be free of charge and open to the public given availability of space. Our goal is that, after the three workshops, participants will be able to use data to produce numbers, hypothesis tests, tables, and graphical visualizations to answer questions like: If you are interested in participating, fill out our registration form here. The deadline to register is Wednesday March 26th. We will let participants know if we have room for them by Saturday March 29th. Space is limited and will depend on how many mentors we can recruit for the sessions. If you already have experience with Python, please consider helping out at the sessions as a mentor. Being a mentor will involve working with participants and talking them through the challenges they encounter in programming. No special preparation is required. If you re interested, send me an email.

Russell Coker: BTRFS Status March 2014

I m currently using BTRFS on most systems that I can access easily. It s not nearly reliable enough that I want to install it on a server in another country or an embedded device that s only accessible via 3G, but for systems where I can access the console it s not doing too badly. Balancing and Space Allocation # btrfs filesystem df /
Data, single: total=103.97GiB, used=85.91GiB
System, DUP: total=32.00MiB, used=20.00KiB
Metadata, DUP: total=1.78GiB, used=1.31GiB
# df -h /
Filesystem Size Used Avail Use% Mounted on
/dev/disk/by-uuid/ac696117-473c-4945-a71e-917e09c6503c 108G 89G 19G 84% /
Currently there are still situations where it can run out of space and deadlock on freeing space. The above shows the output of the btrfs df command and the regular df command, I have about 106G of disk space used by data and metadata in BTRFS while df shows that the entire filesystem (IE the block device) is 108G. So if I use another 2G of data or metadata then the system is at risk of deadlocking. To avoid that happening I have to run btrfs balance start / to start a balance which defragments the space use and frees some blocks. Currently there is a bug in BTRFS (present in all Debian/Unstable kernels) which prevents a balance operation from completing when systemd is used in a default configuration (there s something about the way systemd accesses it s journal files that triggers a BTRFS bug). This is really inconvenient, particularly given that there s probably a strong correlation between people who use experimental filesystems and people who use experimental init programs. When you get to the stage of the filesystem being deadlocked you can sometimes recover by removing snapshots and sometimes by adding a new device to the filesystem (even a USB flash drive will do). But I once had a filesystem get into a state where there wasn t enough space to balance, add a device, or remove a snapshot so I had to do a backup/format/restore. Quota Groups Last time I asked the developers (a few weeks ago) they told me that quota groups aren t ready to use. They also said that they know about enough bugs that there s no benefit in testing that feature. Even people who want to report bugs in BTRFS shouldn t use quotas. Kernel Panics with Kmail I ve had three systems develop filesystem corruption on files related to Kmail (the email program from KDE). I suspect that Kmail is triggering a bug in BTRFS. On all three systems the filesystem developed corruption that persisted across a reboot. One of the three systems was fixed by deleting the file for the Outbox, the others are waiting for kernel 3.14 which is supposed to fix the bug that causes kernel panics when accessing the corrupted files in question. I don t know whether kernel 3.14 will fix the bug that caused the corruption in the first place. Conclusion As I don t use quotas BTRFS is working well for me on systems that have plenty of storage space and don t run Kmail. There are some systems running systemd where I plan to upgrade the kernel before all the filesystem space is allocated. One of my systems is currently running SysVinit so I can balance the filesystem. Apart from these issues BTRFS is working reasonably well for me. I haven t yet had it s filesystem checksums correct corrupted data from disk in any situation other than tests (I have had ZFS correct such an error, so hardware I use does benefit from this). I have restored data from BTRFS snapshots on many occasions, so that feature has been a major benefit for me. When I had a system with faulty RAM the internal checks in BTRFS alerted me to the problem and I didn t lose any data, the filesystem became read-only and I was able to copy everything off even though it was too corrupted for writes.

14 March 2014

Neil Williams: LAVA server on an arndale

(ARMv7 A15 dual core) I ve covered how I set up my home LAVA lab and how I got two iMX.53 boards running, the next step was to sort out the LAVA server. My initial setup relied on using my Thinkpad as the server. This was somewhat convenient as that s how I develop the code, but didn t help me run jobs like health checks because the laptop was usually somewhere other than on the home LAN. There had been a long-standing problem with using LAVA on ARM the uwsgi support didn t compile but the code being used was old. As the same code has been in Debian for a long time, I suspected that this was fixed with a newer version. So as part of migrating LAVA to django1.6, apache2.4, postgres9.3, django-tables2 0.13 and a few other updated dependencies, I have been using the version of uwsgi from Debian unstable for quite a while without problems on x86. A simple tweak to the LAVA setup scripts and a newer version of uwsgi became available and it builds just fine on armhf. (I haven t tried armel because Linaro is ARMv7 or newer and we don t test with ARMv5/ARMv6 boards, so there s no point in trying armel it s not likely to be an issue for this fix though.) (Only the current lava-deployment-tool methods need to actually compile uwsgi directly from upstream without any patches the packaging which will replace l-d-t uses precompiled binaries, just as any admin would expect.) That initial install was on one of the iMX.53 boards, which ran as slowly as anyone who has used an iMX.53 would expect. I haven t run test jobs on that install, it had a hard enough time serving the frontend. Clearly some more cores would be a good step and when an arndale became available for the home lab, the next step was to get a SATA drive onto the arndale, put Debian unstable on that and then deploy LAVA to the arndale using the Debian packages. As a bonus, these packages are built for django1.6 (using an unreleased branch). Sounds simple enough. It works on iMX.53, it should work on an arndale. Well, it does but only after some unexpected faff. arndale, u-boot and SATA I hate u-boot every single time I ever touch it, the little I know about any other u-boot device is completely useless. Uniformity is a good thing infinite permutations are just rope to hang ourselves with cute embedded nonsense hacks and I m bored of that whole scene. So, boot the arndale, interrupt the bootloader to get to the prompt. What s the first thing most people would want? help. Denied this particular u-boot has been compiled without the ability to display any help messages. u-boot has just sunk further into the depths of please can we have something else which is uniform across devices . OK, well maybe I can get by without help. sata init unknown command sata . (Go away, do something else for a bit.) The arndale isn t one of the newest boards in the ARMv7 world, LAVA has been using them for a while, so someone has probably done some work to fix this . nope. There s a workaround a nice detailed guide by Phil Endecott which details that the kernel needs to continue to be loaded from SD and then the SATA can be used for just the rootfs. Mildly annoyed (I was hoping to be able to update the arndale kernel without the hassle of mounting the SD card at all), the rest was straight-forward. Preparing the SATA and installing Debian Due to the complexity of some of the transitions currently ongoing in Debian ahead of the Jessie release freeze, uwsgi is not in Debian testing right now so this install has to be Debian unstable. That s OK, I ve been running Debian unstable on all my machines for several years now usually updating ~5 times a week.

# parted /dev/sda -s unit mb mktable msdos
# parted /dev/sda -s unit mb mkpart primary 1 -- "-0"
# mkfs.ext4 /dev/sda1
# mount /dev/sda1 /mnt/root/
(note the in the mkpart command, that catches me out most times I try this. Without it, the special -0 gets interpreted as an option to parted but parted doesn t then tell you how to fix it, it just complains about an unknown option.) The SD image I am using is a LAVA master image, based on Ubuntu, so it was easy to put debootstrap onto it.

# apt-get install debootstrap
# debootstrap --arch=armhf sid /mnt/root/ http://ftp.uk.debian.org/debian
# chroot /mnt/root/
Inside the chroot, it s Debian as usual:

apt-get update
apt-get install emdebian-archive-keyring
passwd
emdebian-archive-keyring is a package I (ab)use to sign my LAVA packaging as it has the advantage of being in Debian and Ubuntu going back to the time of Lenny, so it is always available from a repository which has already been authenticated to apt and doesn t involve downloading some random key from a website. I use passwd manually because this rootfs won t be using auto-login, it will have regular users. root passwords can be automated, if necessary. Thinking about login, remember to give the rootfs a usable tty. (The LAVA master image has a nasty habit of mangling editors like nano and vi when used over serial, so I m using echo.) For the arndale you need:

# echo T0:23:respawn:/sbin/getty -L ttySAC2 115200 vt102 >> ./etc/inittab
# echo >> ./etc/securetty
# echo ttySAC2 >> ./etc/securetty
Then to make the hostname useful, adapt this to your needs:

echo 127.0.0.1 arndale.codehelp arndale >> ./etc/hosts
Finally, get the network running at boot and add the LAVA repository:

# echo auto lo eth0 > ./etc/network/interfaces.d/arndale
# echo iface lo inet loopback >> ./etc/network/interfaces.d/arndale
# echo iface eth0 inet dhcp >> ./etc/network/interfaces.d/arndale
# echo deb http://people.linaro.org/~neil.williams/lava sid main >> ./etc/apt/sources.list.d/lava.list
# apt-get update
# exit
Once the LAVA packaging is finalised, the packages will be uploaded to a normal Linaro PPA, I ll update the packages to use an official download location and we ll move to using sane version string handling. For now, the packages are still in development. Code for the packaging is in Alioth but there are issues with anonymous access to the pkg-linaro-lava repositories currently, so I ve also pushed to http://github.com/Linaro if you are interested in building the packages yourself. See also my packaging guide which is also linked from the Links page on my own site. With that done, time to reboot, set the SATA drive as the rootfs using the horrid u-boot and install LAVA.

# reboot
> setenv bootargs console=tty0 console=ttySAC2,115200n8 drm_kms_helper.edid_firmware=edid-1920x1080.fw root=/dev/sda1
> boot
login
# apt-get install postgresql
After this operation, 63.0 MB of additional disk space will be used.

# apt-get install lava-server
After this operation, 231 MB of additional disk space will be used.

# a2dissite 000-default
# a2ensite lava-server
# apache2ctl restart
# service lava-server restart
Take note of the IP address of your new ARM LAVA server and sign in with your regular details, e.g. using OpenID before creating a temporary superuser:

# lava-server manage createsuperuser --username default --email=user@example.com
Choose a temporary password, log out, log in as the temporary superuser, promote your regular user to superuser and default owner of unrestricted devices in the django admin interface. Finally, log out and login as regular user to delete the temporary user. (Yes, that probably could do with some improvement remind me later and I ll see if a known user can be promoted from the command line.) See also Senthil s recent post on LAVA unit tests. Getting those to run without so many steps is also on the TODO list. Results
IP Address: 127.0.0.1
Is Master? : True
Uptime: 6:02:23.700000
Architecture: armv7l
Platform: Linux-3.10.1.0-1-linaro-arndale-armv7l-with-debian-jessie-sid
Insignal Arndale evaluation board based on EXYNOS5250
System memory: 1998MiB
Next! I m working on some code upstream to make it easier to add devices from the command line. The aim is that a set of simple commands will set up an initial device, run a job on that device and submit a result bundle to the LAVA server as job #1. This gives some assurance that everything has gone well. Now I can finally add health checks for the iMX.53 boards and start regular tests on those boards. The cubie boards will wait for a later blog post, there are interesting problems with the bootloader and serial connections. That s a whole different rant.

Steve Kemp: So load-balancers are awesome

When I was recently talking about load-balancers, and automatically adding back-ends, not just removing bad ones that go offline, I obviously spent a while looking over some. There are several dedicated load-balancers packaged for Debian GNU/Linux, including: In addition to actual dedicated load-balancers there are things that can be coerced into running in that way: apache2, varnish, squid, nginx, & etc. Of the load-balancers I was immediately drawn to both pen and pound, because they have command line tools ("penctl" and "poundctl" respectively) for adding/removing/updating the running configuration. Pen I've been using for a couple of days now, and although it suffers from some security issues I'm confident they will be resolved in the near future. (#741370) My only outstanding task is to juggle some hosts around and stress-test the pair of them a little more before deciding on a winner. In other news I kinda regret the whole blogspam.net API. I'd have had a far simpler life if I'd just ran the damn thing as a DNSBL in the first place. (That's essentially how it operates on the whole anyway. Submit spammy comments for long enough and you're just blacklisted, thereafter.)

Dirk Eddelbuettel: Rcpp 0.11.1

A new minor release 0.11.1 of Rcpp is now on the CRAN network for GNU R; binaries for Debian have also been uploaded. The release fixes a number of bugs that have come up since the 0.11.0 release in January, but also brings some extensions. See the NEWS file section below for details, or the ChangeLog file in the package and on the Rcpp Changelog page Once again, we tested this release by building against all CRAN packages which depend upon Rcpp. In short, three packages are blacklisted from tests, and three came up with something we noted --- but the remaining 177 packages all build and test cleanly. Detailed results of those tests (and the scripts for it) are on GitHub. There are a number of other fixes, upgrades and other extensions detailed in NEWS file extract below, in the ChangeLog file in the package and on the Rcpp Changelog page.
Changes in Rcpp version 0.11.1 (2014-03-13)
  • Changes in Rcpp API:
    • Preserve backwards compatibility with Rcpp 0.10.* by allowing RObject extraction from vectors (or lists) of Rcpp objects
    • Add missing default constructor to Reference class that was omitted in the header-only rewrite
    • Fixes for NA and NaN handling of the IndexHash class, as well as the vector .sort() method. These fixes ensure that sugar functions depending on IndexHash (i.e. unique(), sort_unique(), match()) will now properly handle NA and NaN values for numeric vectors.
    • DataFrame::nrows now more accurately mimics R's internal behavior (checks the row.names attribute)
    • Numerous changes to permit compilation on the Solaris OS
    • Rcpp vectors gain a subsetting method it is now possible to subset an Rcpp vector using CharacterVectors (subset a by name), LogicalVectors (logical subsetting), and IntegerVectors (0-based index subsetting). Such subsetting will also work with Rcpp sugar expressions, enabling expressions such as x[ x > 0].
    • Comma initialization (e.g. CharacterVector x = "a", "b", "c";, has been disabled, as it causes problems with the behavior of the = operator with Rcpp::Lists. Users who want to re-enable this functionality can use #define RCPP_COMMA_INITIALIZATION, but be aware of the above caveat. The more verbose CharacterVector x = CharacterVector::create("a", "b", "c") is preferred.
  • Changes in Rcpp Attributes
    • Fix issue preventing packages with Rcpp::interfaces attribute from compiling.
    • Fix behavior with attributes parsing of ::create for default arguments, and also allow constructors of a given size (e.g. NumericVector v = NumericVector(10)) gives a default value of numeric(10) at the R level). Also make NAs preserve type when exported to R (e.g. NA_STRING as a default argument maps to NA_character_ at the R level)
  • Changes in Rcpp modules
    • Corrected the un_pointer implementation for object
Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

13 March 2014

Mario Lang: Living in RAM

I switched to SSD on my home server a few years ago, at a time when SSH was still new and sort of hyped. However, I immediately knew that this type of technology is for me: it is fast and rather silent. SSD storage has this air of being fragile though. You are supposed to not wear it out too much. It's not like in the good old days where you would write to your hard disk without any extra thought.
tmpfs Before I switched to SSD I was already using tmpfs to store /tmp in RAM, for performance reasons mostly. /etc/default/tmpfs:
RAMTMP=yes
Since RAM is relatively cheap these days I have lots of it in my home server.
/var/cache/apt/archives When I switched to SSD, I extended this concept by mounting /var/cache/apt/archives via tmpfs. This is to save disk I/O for package updates. And for a machine running sid which is more or less regularily updated, this saves quite some useless writes to disk. Roughly 100MB per update.
/tmp/src Nowadays, I have almost all of my source code checkouts and build-trees in /tmp/src. myrepos makes this very easy to handle. Simply clone all repositories you are interested in, and remember their details with mr register. After a reboot, all you need to do is:
$ mkdir /tmp/src
$ cd !$
$ mr up
Your repository locations have (likely) been recorded in ~/.mrconfig. Of course there is the danger of accidentally loosing data due to a power outage. However, I feel this leads to a rather clean workflow. Changes need to be pushed anyway. So since you can not trust your local repository to really persist, you are forced to push your changes regularily, which is a good thing! Besides, I have a UPS at home which gives me roughly one hour of backup power. This was enough to sustain every power outage I have witnessed in the past years. Typically, outages are rather short lived in my area, somewhere between a few seconds and 5 minutes. It is rather rare that electricity goes missing for more than half an hour. The only downside of this approach is that from time to time, you will use more bandwidth by re-cloning repositories after a reboot. But really, who needs reboots on Linux? Last time I had half a year uptime, and only rebooted because I wanted to jump from linux 3.8 to 3.13. This approach only works on long-running machines though. It is probably not very useful for a laptop.

12 March 2014

Matthew Garrett: Dealing with Apple ACPI issues

I wrote about Thunderbolt on Apple hardware a while ago. Since then Andreas Noever has somehow managed to write a working Thunderbolt stack, which awesome! But there was still the problem I mentioned of the device not appearing unless you passed acpi_osi="Darwin" on the kernel command line, and a further problem that if you suspended and then resumed it vanished again.

The ACPI _OSI interface is a mechanism for the firmware to determine the OS that the system is running. It turns out that this works fine for operating systems that export fairly static interfaces (Windows, which adds a new _OSI per release) and poorly for operating systems that don't even guarantee any kind of interface stability in security releases (Linux, which claimed to be "Linux" regardless of version until we turned that off). OS X claims to be Darwin and nothing else. As I mentioned before, claiming to be Darwin in addition to Windows was enough to get the Thunderbolt hardware to stay alive after boot, but it wasn't enough to get it powered up again after suspend.

It turns out that there's two sections of ACPI code where this Mac checks _OSI. The first is something like:

if (_OSI("Darwin")) Store 0x2710 OSYS; else if(_OSI("Windows 2009") Store 0x7D9 OSYS; else

ie, if the OS claims to be Darwin, all other strings are ignored. This is called from \_SB._INI(), which is the first ACPI method the kernel executes. The check for whether to power down the Thunderbolt controller occurs after this and then works correctly.

The second version is less helpful. It's more like:

if (_OSI("Darwin")) Store 0x2710 OSYS; if (_OSI("Windows 2009")) Store 0x7D9 OSYS; if

ie, if the OS claims to be both Darwin and Windows 2009 (which Linux will if you pass acpi_osi="Darwin"), the OSYS variable gets set to the Windows 2009 value. This version gets called during PCI initialisation, and once it's run all the other Thunderbolt ACPI calls stop doing anything and the controller gets powered down after suspend/resume. That can be fixed easily enough by special casing Darwin. If the platform requests Darwin before anything else, we'll just stop claiming to be Windows.

Phew. Working Thunderbolt! (Well, almost - _OSC fails and so we disable PCIe hotplug, but that's easy to work around). But boo, no working battery. Apple do something very strange with their ACPI battery interface. If you're running anything that doesn't claim to be Darwin, Apple expose an ACPI Control Method battery. Control Method interfaces abstract the complexity away into either ACPI bytecode or system management traps - the OS simply calls an ACPI method, magic happens and it gets an answer back. If you claim to be Darwin, Apple remove that interface and instead expose the raw ACPI Smart Battery System interface. This provides an i2c bus over which the OS must then speak the Smart Battery System protocol, allowing it to directly communicate with the battery.

Linux has support for this, but it seems that this wasn't working so well and hadn't been for years. Loading the driver resulted in modprobe hanging until a timeout occurred, and most accesses to the battery would (a) take forever and (b) probably fail. It also had the nasty habit of breaking suspend and resume, which was unfortunate since getting Thunderbolt working over suspend and resume was the whole point of this exercise.

So. I modified the sbs driver to dump every command it sent over the i2c bus and every response it got. Pretty quickly I found that the failing operation was a write - specifically, a write used to select which battery should be connected to the bus. Interestingly, Apple implemented their Control Method interface by just using ACPI bytecode to speak the SBS protocol. Looking at the code in question showed that they never issued any writes, and the battery worked fine anyway. So why were we writing? SBS provides a command to tell you the current state of the battery subsystem, including which battery (out of a maximum of 4) is currently selected. Unsurprisingly, calling this showed that the battery we wanted to talk to was already selected. We then asked the SBS manager to select it anyway, and the manager promptly fell off the bus and stopped talking to us. In keeping with the maxim of "If hardware complains when we do something, and if we don't really need to do that, don't do that", this makes it work.

Working Thunderbolt and working battery. We're even getting close to getting switchable GPU support working reasonably, which is probably just going to involve rewriting the entirety of fbcon or something similarly amusing.

comment count unavailable comments

Dirk Eddelbuettel: QuantLib 1.4 packages also available for Ubuntu and Windoze

QuantLib release 1.4 came out a couple of days ago. Sticking with standard practice, I immediately updated the Debian packages I have been maintaining for over a dozen years now, and corresponding binaries are available for Debian flavors unstable ("sid") and testing ("jessie"). I also updated my RQuantLib package accordingly (though it needed no changes -- yay to stable APIs). However, I also run Ubuntu on a few machines at work and home, and proceeded to create local packages for both 32-bit ("i386") and 64-bit ("amd64") variants of the current release 13.10 ("saucy"). As these may be of use to others, I am now making these available here from my box so that folks can run a current QuantLib version on those machines. Lastly, Brian Ripley was kind enough to also fire up his cross-compilation setup on his Linux box to create similar Windows binaries, These are e.g. used on CRAN and by the win-builder service to compile the RQuantLib CRAN Windows builds of RQuantLib. That corresponding archive file can be obtained as Quantlib14.zip see this short page for details. My thanks to Brian for helping with this. I hope this may be useful to the few people wishing to compile and/or extend RQuantLib and QuantLib.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 March 2014

Andrew Pollock: [life] Day 42, a good night's sleep, Kindergarten, make up swim class and dinner with Nana

Zoe slept through the night for the first time in recent memory, and was up at around 6am. It was lovely. I'm thinking the slightly lower temperature helped. I'm definitely going to explore air conditioning for the bedrooms before next Summer. I'd picked up some egg cups on the weekend, so we did soft boiled eggs in the Thermomix for breakfast. They turned out lovely this time, and Zoe seemed to enjoy eating hers. She dressed herself while they were cooking. Her Kindergarten t-shirts arrived yesterday, so now she looks like all the other kids. It's very cute. It rained on and off in the morning, and I was in two minds about whether to chance it on the bike or not. As it happened we ended up messing around a bit before leaving, so we drove, and it was a good call, because it started raining again as we pulled out of the driveway. Drop off was super smooth. Megan had been away yesterday, but was back today, so Zoe was very happy to see her. My financial advisor came out for a chat about investments mid-morning, and then I got stuck into my US taxes. I will not miss having to do these tax returns. The 2013 one is going to be particularly complicated by the fact we sold our home and were only in the country for like 80 days. I biked over to Kindergarten to pick up Zoe, as the weather had improved. Surprisingly, she was awake, but her teacher said she'd just woken up from a nap. We managed to clear out pretty quickly. I stopped at the health food shop on the way home to get some peanut oil for the dinner I was making. Due to a miscommunication, Zoe had missed her Saturday swim class. I explained to the swim school the error, and they were kind enough to allow Zoe to have a make up class anyway, so we went to that after Kindergarten. Zoe wanted to do some more practice riding her bike. She's got a little 10 inch bike with no training wheels and a gyrobike front wheel. We haven't had a lot of success learning to ride to date, due to a combination of her height and just time, so it was interesting that she decided today she wanted to do some more practice. She wanted to "ride" her bike from home to the park on the way to swim class, but I managed to convince her to walk the bike to the park. It turns out even walking the bike is a bit of a challenge for her, so I ended up carrying it most of the way. It's heavy. We got to the park, and had a bit of a run with the bike. I'm glad I decided to take her knee pads and elbow pads, because she did stack it fairly decently, but managed to survive mostly unscathed. To her credit, she even got back on the bike again. She's a tough kid. Once we made it to the playground, she lost all interest in the bike, and we had about 15 minutes to kill before we needed to continue to the pool. We walked/carried the bike from the park to the pool, and the make up class Zoe ended up in was Megan's regular class, so the girls had a great time together. After swim class, we walked back home. Zoe's Nana was coming over for dinner, and I wanted to make a satay chicken dish. I'd bought some peanuts from the Peanut Wagon on Sunday, when I was in Nanango for my uncle's 90th birthday party, and I wanted to try making peanut butter from scratch in the Thermomix, and use that to make the satay sauce. Long story short, dinner wasn't super great. I'd made a satay chicken in the Thermomix previously, but I couldn't find the recipe I used last time. I used this recipe tonight, but didn't really follow it properly because I was trying to cut corners due to the time. I tried cooking wild rice in the microwave and it was a total flop. The satay chicken itself turned out okay, but it was a shame about the rice. It was cool making my own peanut butter. Zoe had a great time playing with her Nana, and after we dropped her off at the train station went to bed without a peep.

Next.

Previous.