Search Results: "ema"

8 August 2013

Neil McGovern: IT recruitment sexism is alive and well

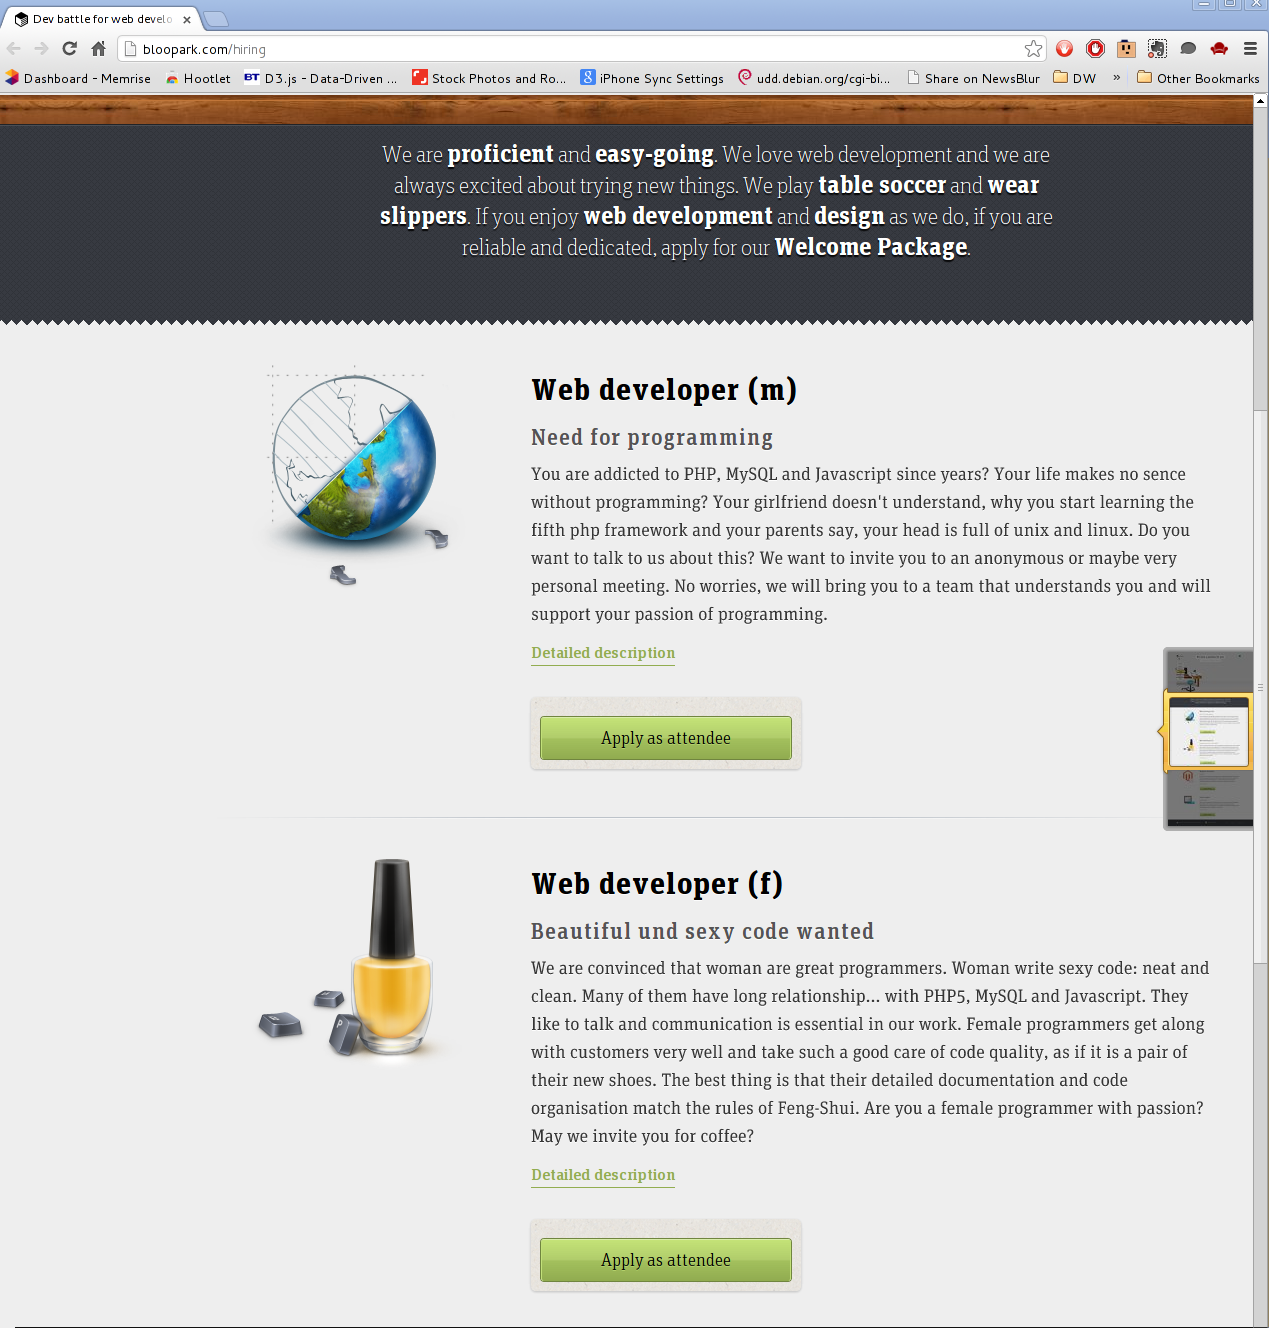
sexismWith the number of female software engineers standing at 20.9% [1], recruitment of females into the industry is a major concern. A friend of mine, Rosemary Francis who's MD of Ellexus, has a great talk about this issue. It mentions various methods you can use to tailor your job applications to be more attractive to females, by simply being careful not to exclude or put off potential applicants. However, there is also a very poor way of doing so, which is highly sexist and plays to stereotypes. As we can see from Bloopark's hiring page, this is exactly what they have done.
Web developer (m)
Need for programming
You are addicted to PHP, MySQL and Javascript since years? Your life makes no sence without programming? Your girlfriend doesn't understand, why you start learning the fifth php framework and your parents say, your head is full of unix and linux. Do you want to talk to us about this? We want to invite you to an anonymous or maybe very personal meeting. No worries, we will bring you to a team that understands you and will support your passion of programming. Web developer (f)
Beautiful und sexy code wanted
We are convinced that woman are great programmers. Woman write sexy code: neat and clean. Many of them have long relationship... with PHP5, MySQL and Javascript. They like to talk and communication is essential in our work. Female programmers get along with customers very well and take such a good care of code quality, as if it is a pair of their new shoes. The best thing is that their detailed documentation and code organisation match the rules of Feng-Shui. Are you a female programmer with passion? May we invite you for coffee?
Really? New pair of shoes? Pictures of nail varnish? They're in a relationship with code? And why does the male version need to have a girlfriend rather than a boyfriend? [1] US Bureau of Labor Statistics (BLS) - ftp://ftp.bls.gov/pub/special.requests/lf/aa2010/aat11.txt

Craig Small: postfix transport with smarthost

Dear lazyyweb, Has anyone got a way for postfix to use a transport map such that it sends email to the given MX host for some specified domains then default to a smarthost for the remainder? The logic would be: IF domain in ( example.net , foo.bar ,etc etc) THEN use the relevant MX host ELSE send to smarthost.isp.net i can use a transport map to send from specific domains to specific hosts, eg @domain.com goes to otherisp.net mailserver but not to just use domain.com s MX hosts

Francois Marier: Server Migration Plan

I recently had to migrate the main Libravatar server to a new virtual machine. In order to minimize risk and downtime, I decided to write a migration plan ahead of time. I am sharing this plan here in case it gives any ideas to others who have to go through a similar process.

Prepare DNS
  • Change the TTL on the DNS entry for libravatar.org to 3600 seconds.
  • Remove the mirrors I don't control from the DNS load balancer (cdn and seccdn).
  • Remove the main server from cdn and seccdn in DNS.

Preparing the new server
  • Setup the new server.
  • Copy the database from the old site and restore it.
  • Copy /var/lib/libravatar from the old site.
  • Hack my local /etc/hosts file to point to the new server's IP address:
    xxx.xxx.xxx.xxx www.libravatar.org stats.libravatar.org cdn.libravatar.org
    
  • Test all functionality on the new site.

Preparing the old server
  • Prepare a static "under migration" Apache config in /etc/apache2/sites-enables.static/:
    <VirtualHost *:80>
        RewriteEngine On
        RewriteRule ^ https://www.libravatar.org [redirect=301,last]
    </VirtualHost>
    <VirtualHost *:443>
        SSLEngine on
        SSLProtocol TLSv1
        SSLHonorCipherOrder On
        SSLCipherSuite RC4-SHA:HIGH:!kEDH
        SSLCertificateFile /etc/libravatar/www.crt
        SSLCertificateKeyFile /etc/libravatar/www.pem
        SSLCertificateChainFile /etc/libravatar/www-chain.pem
        RewriteEngine On
        RewriteRule ^ /var/www/migration.html [last]
        <Directory /var/www>
            Allow from all
            Options -Indexes
        </Directory>
    </VirtualHost>
    
  • Put this static file in /var/www/migration.html:
    <html>
    <body>
    <p>We are migrating to a new server. See you soon!</p>
    <p>- <a href="http://identi.ca/libravatar">@libravatar</a></p>
    </body>
    </html>
    
  • Enable the rewrite module:
    a2enmod rewrite
    
  • Prepare an Apache config proxying to the new server in /etc/apache2/sites-enabled.proxy/:
    <VirtualHost *:80>
        RewriteEngine On
        RewriteRule ^ https://www.libravatar.org [redirect=301,last]
    </VirtualHost>
    <VirtualHost *:443>
        SSLEngine on
        SSLProtocol TLSv1
        SSLHonorCipherOrder On
        SSLCipherSuite RC4-SHA:HIGH:!kEDH
        SSLCertificateFile /etc/libravatar/www.crt
        SSLCertificateKeyFile /etc/libravatar/www.pem
        SSLCertificateChainFile /etc/libravatar/www-chain.pem
        SSLProxyEngine on
        ProxyPass / https://www.libravatar.org/
        ProxyPassReverse / https://www.libravatar.org/
    </VirtualHost>
    
  • Enable the proxy-related modules for Apache:
    a2enmod proxy
    a2enmod proxy_connect
    a2enmod proxy_http
    

Migrating servers
  • Tweet and dent about the upcoming migration.
  • Enable the static file config on the old server (disabling the Django app).
  • Copy the database from the old server and restore it on the new server.
  • Copy /var/lib/libravatar from the old server to the new one.

Disable mirror sync
  • Log into each mirror and comment out the sync cron jobs in /etc/cron.d/libravatar-slave.
  • Make sure mirrors are no longer able to connect to the old server by deleting /var/lib/libravatar/master/.ssh/authorized_keys on the old server.

Testing the main site
  • Hack my local /etc/hosts file to point to the new server's IP address:
    xxx.xxx.xxx.xxx www.libravatar.org stats.libravatar.org cdn.libravatar.org
    
  • Test all functionality on the new site.
  • If testing is successful, update DNS to point to the new server with a short TTL (in case we need to revert).
  • Enable the proxy config on the old server.
  • Hack my local /etc/hosts file to point to the old server's IP address.
  • Test basic functionality going through the proxy.
  • Remove local /etc/hosts/ hacks.

Re-enable mirror sync
  • Build a new libravatar-slave package with an updated known_hosts file for the new server.
  • Log into each server I control and update that package.
  • Test the connection to the master (hacking /etc/hosts on the mirror if needed):
    sudo -u libravatar-slave ssh libravatar-master@0.cdn.libravatar.org
    
  • Uncomment the sync cron jobs in /etc/cron.d/libravatar-slave.
  • An hour later, make sure that new images are copied over and that the TLS certs are still working.
  • Remove /etc/hosts hacks from all mirrors.

Post migration steps
  • Tweet and dent about the fact that the migration was successful.
  • Send a test email to the support address included in the tweet/dent.
  • Take a backup of config files and data on the old server in case I forgot to copy something to the new one.
  • Get in touch with mirror owners to tell them to update libravatar-slave package and test ssh configuration.
  • Add third-party controlled mirrors back to the DNS load-balancer once they are up to date.
  • A few days later, change the TTL for the main site back to 43200 seconds.
  • A week later, kill the proxy on the old server by shutting it down.

7 August 2013

Keith Packard: embedded cpus

Choosing Embedded Processors for AltOS When Bdale and I started building rocketry hardware together, we had already picked out a target processor, the TI cc1111. We picked that chip almost entirely based on the digital transceiver that is built in to the chip, and not because we had any particular love for the 8051 microcontroller. At that time, I d seen people struggle with PIC processors, battle AVR to a draw and spend a lot of time trying to get various ARM processors running. So, the 8051 didn t seem all that far from normal, and the cc1111 implementation of it is pretty reasonable, including credible USB support and a built-in DMA engine. Since those early days, we ve gone on to build boards with a slightly wider range of processors: Bdale thinks we should reduce the number of components we use to focus our efforts better. He s probably right, but I have to admit that I ve had way too much fun getting each of these chips running. I thought I d spend a bit of time describing our general process for selecting a new CPU. CC1111 involved a lot of software hacking The 8051 processor in the CC1111 is very well documented, including the two-wire debugging interface. What was missing was a canned solution for programming and debugging the chip from Debian. However, with sufficient motivation and accurate docs, I was able to create a programmer from a USB device with a couple of GPIOs and a lot of ugly software on Linux. That sufficed to get the USB stack limping along, at which point I wrote a much faster programmer that ran on the cc1111 itself and could program another cc1111. With that, I created an assembly-level debugger that could be hooked to the existing SDCC source level debugger and had a full source-level debugging environment for the 8051. This turned out to be way better than what I could get on the Atmel processors, where I ve got a program loader and a whole lot of printf debugging. STM has been great The STM32L-Discovery board has a standard STM debugging setup for the Cortex SWD interface right on the same board as a target CPU. That made for completely self-contained development, with no jumper wires (a first for me, for sure). There s free software, stlink which can talk over the debugger USB connection to drive the SWD interface. This is sufficient to flash and debug applications using GDB. Of course, GCC supports ARM quite well; the only hard part was figuring out what to do for a C library. I settled on pdclib, which is at least easy to understand, if not highly optimized for ARM. We ve built a ton of boards with the STM32L151 and STM32L152; at this point I m pretty darn comfortable with the architecture and our tool chain. Adventures with NXP The NXP LPC11U14 is a very different beast. I m using this because: The LPCXpresso board looks much like the STM32L-Discovery, with a debugger interface wired to the CPU directly on the board. However, I haven t found free software tools to drive this programmer; all I ve found are binary-only tools from NXP. No thanks. Fortunately, the LPC11U14 uses exactly the same SWD interface as the STM32L, so I was able to sever the link between the programmer and the target on the LPCXpresso board and hook the target to an ST-Link device (either the one on the STM32L-Discovery board, or the new stand-along programming dongle I bought). With that, I wrote an openocd script to talk to the LPC11U14 and was in business. What I found in the NXP processor was a bit disturbing though there s a mask ROM that contains a boot loader, which always runs when the chip starts, and a bunch of utility code, including the only documented interface to programming the flash memory. I cannot fathom why anyone thought this was a good idea I don t want a BIOS in my embedded CPU, thankyouverymuch; I d really like my code to be the first instructions executed by the CPU. And, any embedded developer is more than capable of programming flash using a register specification, and calling some random embedded code in ROM from the middle of my operating system is more than a bit scary. NXP could do two simple things to make me like their parts a whole lot more: Right now, I m hoping the STM32L100C6 parts become available in small quantities so I can try them out; they promise to be as cheap as the LPC11U14, but are better supported by free software and offer more complete hardware documentation. Yeah, they re a bit larger; that will probably be annoying.

6 August 2013

Craig Small: Careful with apache upgrades

You might (or not if you don t visit) notice all my websites were down. A rushed apt-get dist-upgrade and I found two problems:
  1. PHP5 got removed, which is bad if you run a wordpress site that uses PHP to run
  2. The apache configuration has changed.
Yes, the NEWS entries did warn me, if I read them fully. Yes, I didn t read them enough. Apache now ignores configuration files that don t end in .conf To give a completely non-theoretical example, if you have your virtual hosts in files such as /etc/apache2/sites-enabled/enc.com.au then this will not be recognised and your sites will show the default It works page. Stuff that doesn t fall in the usual places where website stuff should go, which for my setup is a lot of things, will also be denied as the developers have tightened up the rules around what is permitted. Pretty simple to fix with a few <Directory blah> clauses. This isn t a criticism of the Debian apache developers. They do an awesome job of keeping the package workable, flexible but secure which isn t easy. Now it s all back working, I actually agree with the changes they have made. It is just that the latest changes are, well, tricky so be forewarned.

4 August 2013

Ond&#345;ej &#268;ert&iacute;k: How to support both Python 2 and 3

I'll start with the conclusion: making backwards incompatible version of a language is a terrible idea, and it was bad a mistake. This mistake was somewhat corrected over the years by eventually adding features to both Python 2.7 and 3.3 that actually allow to run a single code base on both Python versions --- which, as I show below, was discouraged by both Guido and the official Python documents (though the latest docs mention it)... Nevertheless, a single code base fixes pretty much all the problems and it actually is fun to use Python again. The rest of this post explains my conclusion in great detail. My hope is that it will be useful to other Python projects to provide tips and examples how to support both Python 2 and 3, as well as to future language designers to keep languages backwards compatible. When Python 3.x got released, it was pretty much a new language, backwards incompatible with Python 2.x, as it was not possible to run the same source code in both versions. I was extremely unhappy about this situation, because I simply didn't have time to port all my Python code to a new language. I read the official documentation about how the transition should be done, quoting:
You should have excellent unit tests with close to full coverage.
  1. Port your project to Python 2.6.
  2. Turn on the Py3k warnings mode.
  3. Test and edit until no warnings remain.
  4. Use the 2to3 tool to convert this source code to 3.0 syntax. Do not manually edit the output!
  5. Test the converted source code under 3.0.
  6. If problems are found, make corrections to the 2.6 version of the source code and go back to step 3.
  7. When it's time to release, release separate 2.6 and 3.0 tarballs (or whatever archive form you use for releases).
I've also read Guido's blog post, which repeats the above list and adds an encouraging comment:
Python 3.0 will break backwards compatibility. Totally. We're not even aiming for a specific common subset.
In other words, one has to maintain a Python 2.x code base, then run 2to3 tool to get it converted. If you want to develop using Python 3.x, you can't, because all code must be developed using 2.x. As to the actual porting, Guido says in the above post:
If the conversion tool and the forward compatibility features in Python 2.6 work out as expected, steps (2) through (6) should not take much more effort than the typical transition from Python 2.x to 2.(x+1).
So sometime in 2010 or 2011 I started porting SymPy, which is now a pretty large code base (sloccount says over 230,000 lines of code, and in January 2010 it said almost 170,000 lines). I remember spending a few full days on it, and I just gave up, because it wasn't just changing a few things, but pretty fundamental things inside the code base, and one cannot just do it half-way, one has to get all the way through and then polish it up. We ended up using one full Google Summer of Code project for it, you can read the final report. I should mention that we use metaclasses and other things, that make such porting harder. Conclusion: this was definitely not "the typical transition from Python 2.x to 2.(x+1)". Ok, after months of hard work by a lot of people, we finally have a Python 2.x code base that can be translated using the 2to3 tool and it works and tests pass in Python 3.x. The next problem is that Python 3.x is pretty much like a ghetto -- you can use it as a user, but you can't develop in it. The 2to3 translation takes over 5 minutes on my laptop, so any interactivity is gone. It is true that the tool can cache results, so the next pass is somewhat faster, but in practice this still turns out to be much much worse than any compilation of C or Fortran programs (done for example with cmake), both in terms of time and in terms of robustness. And I am not even talking about pip issues or setup.py issues regarding calling 2to3. What a big mess... Programming should be fun, but this is not fun. I'll be honest, this situation killed a lot of my enthusiasm for Python as a platform. I learned modern Fortran in the meantime and with admiration I noticed that it still compiles old F77 programs without modification and I even managed to compile a 40 year old pre-F77 code with just minimal modifications (I had to port the code to F77). Yet modern Fortran is pretty much a completely different language, with all the fancy features that one would want. Together with my colleagues I created a fortran90.org website, where you can compare Python/NumPy side by side with modern Fortran, it's pretty much 1:1 translation and a similar syntax (for numerical code), except that you need to add types of course. Yet Fortran is fully backwards compatible. What a pleasure to work with! Fast forward to last week. A heroic effort by Sean Vig who ported SymPy to single code base (#2318) was merged. Earlier this year similar pull requests by other people have converted NumPy (#3178, #3191, #3201, #3202, #3203, #3205, #3208, #3216, #3223, #3226, #3227, #3231, #3232, #3235, #3236, #3237, #3238, #3241, #3242, #3244, #3245, #3248, #3249, #3257, #3266, #3281, #3191, ...) and SciPy (#397) codes as well. Now all these projects have just one code base and it works in all Python versions (2.x and 3.x) without the need to call the 2to3 tool. Having a single code base, programming in Python is fun again. You can choose any Python version, be it 2.x or 3.x, and simply submit a patch. The patch is then tested using Travis-CI, so that it works in all Python versions. Installation has been simplified (no need to call any 2to3 tools and no more hacks to get setup.py working). In other words, this is how it should be, that you write your code once, and you can use any supported language version to run it/compile it, or develop in. But for some reason, this obvious solution has been discouraged by Guido and other Python documents, as seen above. I just looked up the latest official Python docs, and that one is not upfront negative about a single code base. But it still does not recommend this approach as the one. So let me fix that: I do recommend a single code base as the solution. The newest Python documentation from the last paragraph also mentions
Regardless of which approach you choose, porting is not as hard or time-consuming as you might initially think.
Well, I encourage you to browse through the pull requests that I linked to above for SymPy, NumPy or SciPy. I think it is very time consuming, and that's just converting from 2to3 to single code base, which is the easy part. The hard part was to actually get SymPy to work with Python 3 (as I discussed above, that took couple months of hard work), and I am pretty sure it was pretty hard to port NumPy and SciPy as well. The docs also says:
It /single code base/ does lead to code that is not entirely idiomatic Python
That is true, but our experience has been, that with every Python version that we drop, we also delete lots of ugly hacks from our code base. This has been true for dropping support for 2.3, 2.4 and 2.5, and I expect it will also be true for dropping 2.6 and especially 2.7, when we can simply use the Python 3.x syntax. So not a big deal overall. To sum this blog post up, as far as I am concerned, pretty much all the problems with supporting Python 2.x and 3.x are fixed by having a single code base. You can read the pull requests above to see how to implemented things (like metaclasses, and other fancy stuff...). Python is still quite the same language, you write your code, you use a Python version of your choice and things will just work. Not a big deal overall. The official documentation should be fixed to recommend this approach, and deprecate the other approaches. I think that Python is great and I hope it will be used more in the future.
Written with StackEdit.

3 August 2013

Steve Langasek: Network services and Upstart

So Debian bug #710747 led to an interesting discussion the other night on IRC which made me realize there are a lot of people who have yet to understand why sysvinit needs replacing. I can't speak to whether upstart solves this bug in particular. The tftpd-hpa package in Ubuntu (and in Debian experimental) does have an upstart job, and I have used tftpd-hpa on systems whose network interfaces are managed entirely with NetworkManager, and I have not seen this bug; but I can't say that this is more than coincidence. However, I can speak to how upstart provides facilities that address the general problem of starting services that require a working network connection to be present before they start up. Traditionally on Linux systems, init scripts could assume that the network connection is up before starting any services for the target runlevel. With LSB dependencies, you could also express this as
Required-Start:    $network
The trouble with both of these approaches is that they assume that there is a single point in time, early in the boot of the system, when the "network" is up. This was an ok assumption 15 years ago, when the Linux kernel initialized all devices serially and all our network configuration was static. But nowadays, you simply cannot rely on systems booting in such a way that the network is fully up shortly after boot - or in a way that you can block the system boot waiting for the network to be up. If all of our services would cope gracefully with being started without the network, this would be a non-issue. Unfortunately, not all network services are written in such a way as to work without a network; nor do they all cope with dynamic changes to interfaces or addresses. While it would be better if these services were written more robustly, since there's no shortage of daemons written this way, it's convenient that upstart provides tools for coping with this behavior in the meantime. Here's a real (simplified) example of an upstart job for a service that needs to wait for a non-loopback interface before it starts:
start on (local-filesystems and net-device-up IFACE!=lo)
stop on runlevel [!2345]
expect fork
respawn
exec nmbd -D
Now, you might also have a service that you only want to start up when a particular network device comes up. This is easily expressed in upstart, and might look like this hypothetical job:
start on net-device-up IFACE=wlan0
stop on net-device-down IFACE=wlan0
expect daemon
respawn
exec mydaemon
If you need to restart a daemon whenever the set of active network connections changes, that's less straightforward. Upstart doesn't have the notion of a 'restart' rule, so you would need two jobs to handle this - one for the daemon itself that starts on the first network connection, and a second job to trigger a restart of the daemon when the network status changes. For the tftpd-hpa case in the abovementioned bug, this might look like:
$ cat /etc/init/tftpd-hpa.conf
start on runlevel [2345]
stop on runlevel [!2345]
expect fork
respawn
script
        if [ -f $ DEFAULTS  ]; then
                . $ DEFAULTS 
        fi
        exec /usr/sbin/in.tftpd --listen  --user $ TFTP_USERNAME  --address $ TFTP_ADDRESS  $ TFTP_OPTIONS  $ TFTP_DIRECTORY 
end script
$ cat /etc/init/tftpd-hpa-restart.conf
start on net-device-up
task
instance $IFACE
script
        status tftpd-hpa   grep -q start/   stop
        restart tftpd-hpa
end script
For this case, upstart doesn't provide quite so great an advantage. It's nice to be able to use upstart natively for both pieces, but you can do the same thing with an init script plus an if-up.d script for ifupdown, which is what maintainers do today. I think adding a restart on stanza to upstart in the future to address this would be a good idea. Though in any event, this is far simpler to do with upstart than with any if-up.d script I've ever seen for managing an initscript-based service. Between the more friendly declarative syntax, and the enhanced semantics for expressing when to run (or restart) a job, upstart offers clear advantages over other init systems.

R&#233;mi Vanicat: Xorg and special keys

Xorg and special keys: one solution for keycode>255 An historic I've buy an IR receiver, and an universal controller to control my multimedia computer, my TV, my ADSL box and my 2.1 Home cinema. I've been pleased to see that my universal controller do now more control than the remote that was sold with my IR receiver. But a lot of those control didn't work with Xorg, so I had to find someway to use them. At first, my logs where spamed with line like:
imon 4-4:1.0: imon_incoming_packet: unknown keypress, code 0x100000e
(imon is the real builder of the IR receiver). I looked for this on the internet and found So I waited, and Linux 3.10 was released, and the Debian Kernel Team did include it in debian sid, so I could easily use it. But some command was still unrecognized as key by Xorg, so I had to find how to let X know them. Reading documentation on internet, and trying some command lead nowhere: the kernel did in fact understood very well the command, but X did ignore them. After two day of trying to understood XKB, I found this bug: those key was unavailable to X and XKB because their keycode was bigger than 255. The first solution to this problem is this patch, but I prefer to use standard tool. I finally found that udev can remap key, hence my solution: The Solution To use key that have keycode bigger than 255, you need to have keycode smaller than 255. keycode are determined by a map in the kernel, that udev can set when the receiver is plugged. You need a keymap. input-kbd from the input-utils package will list the available scancode, and their current keycode (to know the number of your input device, use lsinput):
% sudo input-kbd 6
0x100007f = 106  # KEY_RIGHT
0x1000080 = 105  # KEY_LEFT
0x1007f00 = 108  # KEY_DOWN
0x1008000 = 103  # KEY_UP
0x1010000 = 272  # BTN_LEFT
0x1010080 = 272  # BTN_LEFT
0x1020000 = 273  # BTN_RIGHT
0x1020080 = 273  # BTN_RIGHT
0x200001e = 513  # KEY_NUMERIC_1
0x200001f = 514  # KEY_NUMERIC_2
(There is more, I just cut it there). Putting this in some file (say keymap), editing it, and running sudo input-kbd -f keymap 6 should change the kernel mapping. But it don't. It's not a problem, because the best solution is to use udev. Wrote a keyboard mapping in say /etc/udev/imon:
0x200001e  KP1
0x200001f  KP2
0x2000020  KP3
0x2000021  KP4
0x2000022  KP5
0x2000023  KP6
0x2000024  KP7
0x2000025  KP8
0x2000026  KP9
0x2000027  KP0
0x2800000  MENU
0x288795b7 PAGEDOWN
0x289395b7 PAGEUP
You then need to tell udev to load this mapping, with /etc/udev/rules.d/96-local-keymap.rules:
ACTION=="remove", GOTO="mykeyboard_end"
KERNEL!="event*", GOTO="mykeyboard_end"
ENV ID_INPUT_KEY =="", GOTO="mykeyboard_end"
SUBSYSTEMS=="bluetooth", GOTO="mykeyboard_end"
SUBSYSTEMS=="usb", IMPORT builtin ="usb_id"
ENV ID_VENDOR =="15c2", ENV ID_MODEL_ID =="0042", RUN+="keymap $name /etc/udev/imon"
LABEL="mykeyboard_end"
You will need to adapt 15c2 and 0042 to you own remote. I've found those using lsusb
Bus 004 Device 014: ID 15c2:0042 SoundGraph Inc.
I could now use xkb to further refine the way those key are used by xorg...

Daniel Leidert: Setting up a network buildd with pbuilder, ccache, inoticoming and NFS

I recently bought an N54L HP microserver, which shall act as a build-daemon (buildd) for Debian packaging. The idea of my workflow is the following:
  1. do the maintenance tasks locally, usually using svn-buildpackage, quilt etc.pp
  2. build a source package locally
  3. upload the source to an incoming directory on the server
  4. watch this incoming directory and start a build process as soon as a package is uploaded
  5. put the result into an accessible directory
  6. support different vendors (debian, ubuntu)
  7. support different releases (experimental, unstable, stable, oldstable)
  8. support different architectures (amd64, i386)
  9. speed up the build process
Setting up the building environmentMy first idea was to use sbuild as described in several places. However I went with pbuilder for a long time having a setup I personally like. So I decided to stay with it. I reduce the time and work to update the configure files by using
  • one central file /etc/pbuilderrc.inc defining all the common/shared settings and
  • small configure files defining vendor, release, architecture and mirrors
Here are the relevant parts of my central configure snippet:

[..]
EXTRAPACKAGES="apt-utils debconf debconf-utils libfile-fcntllock-perl"
[..]
BASETGZ="/var/cache/pbuilder/base.$DISTRIBUTION.$ARCHITECTURE.tgz"
APTCACHE="/var/cache/pbuilder/aptcache/$DISTRIBUTION/$ARCHITECTURE/"
BUILDRESULT="/var/cache/pbuilder/result/$DISTRIBUTION/$ARCHITECTURE/"
[..]
case "$VENDOR" in
ubuntu)
MIRRORSITE="http://archive.ubuntu.com/ubuntu"
COMPONENTS="main restricted universe multiverse"
OTHERMIRROR="\
deb http://de.archive.ubuntu.com/ubuntu $DISTRIBUTION main restricted universe multiverse \
deb http://archive.ubuntu.com/ubuntu $DISTRIBUTION-updates main restricted universe multiverse \
deb http://security.ubuntu.com/ubuntu $DISTRIBUTION-security main restricted universe multiverse \
"
;;
*)
MIRRORSITE="http://ftp.debian.org/debian"
COMPONENTS="main contrib non-free"
OTHERMIRROR="\
deb http://ftp.de.debian.org/debian $DISTRIBUTION main contrib non-free \
"
;;
esac
[..]
DEBBUILDOPTS="-us -uc -j2"
AUTO_DEBSIGN=no
USE_PDEBUILD_INTERNAL=yes
[..]
You get the main idea, right? Create own files and directories for each architecture, release and vendor. Further I only want to pull build related packages into the build environment, not into the server environment. So I enabled USE_PDEBUILD_INTERNAL. I don't want to sign anything on the buildd itself and use both cores. That's what DEBBUILDOPTS and AUTO_DEBSIGN are used for. Further I saw some warnings reported during build processes. I therefor install the packages mentioned in EXTRAPACKAGES to every build enviroment. The following are the configure files for the unstable amd64 (default) and the stable i386 build environments:

VENDOR="debian"
DISTRIBUTION="sid"
ARCHITECTURE="amd64"

. /etc/pbuilderrc.inc

VENDOR="debian"
DISTRIBUTION="wheezy"
ARCHITECTURE="i386"

. /etc/pbuilderrc.inc

OTHERMIRROR+="\
deb http://security.debian.org $DISTRIBUTION/updates main contrib non-free \
"
Now to not having to update all of these environments manually there is a small parallelized script /usr/local/sbin/update-pbuilder-chroots:

#!/bin/sh

t=$(tempfile -p .upc. -s .list) exit 1

cat > $t << EOF
/etc/pbuilderrc.amd64.sid
/etc/pbuilderrc.i386.sid
/etc/pbuilderrc.amd64.wheezy
/etc/pbuilderrc.i386.wheezy
/etc/pbuilderrc.amd64.squeeze
/etc/pbuilderrc.i386.squeeze
EOF

parallel /usr/sbin/pbuilder update --override-config --configfile :::: $t tee -a /var/log/pbuilder.log

rm -f $t

exit 0
The script will make sure, that every change to the configuration file(s) will be considered (--override-config) and is run once a week via cron. The default build environment is updated on a daily base without this restriction:

@reboot root rm -rf /var/cache/pbuilder/build/*/ >> /dev/null 2>&1
@daily root test -x /usr/sbin/pbuilder && /usr/sbin/pbuilder update --configfile /etc/pbuilderrc.amd64.sid tee -a /var/log/pbuilder.log >> /dev/null 2>&1
@weekly root test -x /usr/local/sbin/update-pbuilder-chroots && /usr/local/sbin/update-pbuilder-chroots >> /dev/null 2>&1
Speeding up the build processSometimes it is necessary to recompile a package. The tool to speed up this process is ccache, which can be easily integrated into pbuilder by setting CCACHEDIR in /etc/pbuilderrc.inc. It acts like a cache for compiled files and avoids recompilation in several buildd runs.

CCACHEDIR=/var/cache/pbuilder/ccache
It is also possible to use a TMPFS for BUILDPLACE to speed up the build process itself. In this case APTCACHEHARDLINK must be disabled. Well, yeah, I don't do this.Watch an incoming directory and start the build processNot much to say about this except that the user nobody is used to run the pbuilder command. Therefor it is necessary to mention this in /etc/sudoers to allow him to do this via sudo command:

Defaults env_keep = "DH_OPTIONS DH_VERBOSE DEB_BUILD_OPTIONS DH_OPTIONS MAKEFLAGS CC CXX CPP F77 F90"
[..]
nobody ALL=NOPASSWD:/usr/sbin/pbuilder
The first line is only necessary, if a pbuilder command is started with one of these environmental variables set. This can be useful when e.g. debugging a build failure with a future gcc version that is not yet the default or when debugging a clang build issue or when creating non-stripped binary packages for creating a backtrace (BTW: When there is a common repository of all debugging symbols created?).Now to start the build process, I created an incoming directory with mods 777 at /var/cache/pbuilder/incoming/ and use inoticoming to watch it. This is started during boot via cron. The following shows the entry for the default unstable amd64 build environment:

@reboot root /usr/bin/inoticoming --logfile /var/log/inoticoming.log --pid-file /var/run/inoticoming.pid /var/cache/pbuilder/incoming --chdir /var/cache/pbuilder/incoming --suffix .dsc --stderr-to-log --stdout-to-log /bin/su -c '/usr/bin/sudo /usr/sbin/pbuilder build --autocleanaptcache ' nobody \;
Done. That's how the basic buildd works.Getting the resultsThe pbuilder BUILDRESULT directory with mods 777 is shared via NFS mount to the workstation. After successfully building the package, debsign and dput can be used as usual.Setting up the workstationI use svn-buildpackage for most of my packages. Because pbuilder won't download source tarballs on demand by default (maybe via hook?), the tarball must always be included building the source package, which then gets uploaded via dput to the buildd. This is considered in the command listed in svn-builder in ~/.svn-buildpackage.conf (note, below shows my personal layout):

svn-builder=debuild --post-dpkg-buildpackage-hook=\"dput -f buildd /usr/local/src/packages/$PACKAGE/%p_%v_source.changes\" --no-lintian -d -sa -us -uc -S
svn-override=origDir=/usr/local/src/packages/$PACKAGE
svn-override=buildArea=/usr/local/src/packages/$PACKAGE
[..]
The host buildd has been added to ~/.dput.cf:

[buildd]
fqdn = mybuildd
login = mylogin
method = scp
incoming = /var/cache/pbuilder/incoming
allow_unsigned_uploads = 1
run_lintian = 0
Done. Now the svn-buildpackage command will create a source package including the source tarball and upload it to the buildd, where the package building starts right after the upload.ConclusionsThis is the main setup which works nicely for the default build environment so far. On the TODO list is to extend this setup so I can easily deal with all the architectures and releases (point 6..8 at the beginning).

2 August 2013

Rapha&#235;l Hertzog: My Free Software Activities in July 2013

This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (167.67 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. The Debian Administrator s Handbook After the successful crowdfunding campaign, I had a bunch of rewards to ship: I subcontracted most of the job but I had to take care of the books with dedication. I also dealt regularly with books/stickers coming back to the sender (due to invalid address or people not picking up their parcels in the post-office). After the rewards, we had to take care to actually finalize the liberation of the French translation. I merged the translations we had in Git and Roland updated/translated a few strings that weren t in the original book in French. Then I have put the book online. Last but not least, I started to work on updating the English book for Debian 7 (Roland started way before me) and we have put some updated chapters up for review. Debian France Elections. After Debian France s general assembly, the new board of administrators voted the officers: I have been re-elected as President, Sylvestre continues as Treasurer but we have a new Secretary in the person of Alexandre Delano . Welcome Alexandre! I did the administrative work to register the new board/officers in the Tribunal d instance and to give access to the internal git repositories to the new members. Galette. I also did a bunch of tests on Galette s new features that Debian France ordered to the upstream author. They should all land in the next upstream release due in the next weeks. \o/ Accounting. I worked on the accounting to bring it up-to-date so that Sylvestre can pick up the work from now on. We re learning how to best use ledger for our needs. PTS rewrite I continued to spend about 12 hours a week to mentor Marko Lalic who is rewriting the Package Tracking System. I m pretty happy with the results so far so I marked him as pass for the mid-term evaluation required by Google. You can have a look at the documentation and the web interface is starting to show some content. The email interface is fully working and I have configured the real PTS to forward all mails to our test instance (pts.debian.net) so that you can use the rewritten PTS for real-life work. Mail your subscription commands to control@pts.debian.net and start using it! Thanks to the test driven development methodology we re using, we re pretty confident that it works reasonably well! :-) I also packaged python-django-jsonfield (still in NEW) since Marko has been using this python module in his code, and filed bug #717900 on sqlite3 to raise a limit that we have hit with queries made by the PTS. Kali Linux I used the Calxeda Highbank node donated to Debian by Offensive Security to test the new -armmp kernel flavor on it. It seemed to work except for a missing network driver (filed in #717269). Misc Debian work Issues with social networks. With the move of identi.ca to pump.io, we don t have any possibility to auto-post status updates based on RSS feeds. Identi.ca s @debian account was also configured to push updates to the @debian account on twitter.com (and from there it was grabbed in the Debian page on Facebook). This is also gone so to limit the damage, I setup twitterfeed.com so that the twitter/facebook accounts continue to have updates). If you re looking for a development project, here s an area that is not well covered by free software! We need code to do what twitterfeed does and we need that code to also support pump.io. Dpkg work. It s been a long time since I last pushed some code to dpkg s git repository. I took care of reworking and merging a patch submitted by Steve Langasek to fix #716948 (an issue with dpkg-maintscript-helper rm_conffile messing with conffiles that the package no longer owns). Git mail notification. When I was still administrator of Alioth, I wrote git-commit-notice (a fork of Git s post-receive-email) and many packaging projects are using this hook script to send commit notices to mailing lists. This script has not been updated for multiple years and it started spewing warnings recently due to deprecated features in Wheezy s git. So I looked at updating it and while doing so I discovered a much better replacement with git-multimail. Thus I adapted git-commit-notice to work on top of this new script. The result has now been installed on git.debian.org (this is to be properly announced in the next DeveloperNews). Misc work. I packaged sql-ledger 3.0.5-1, forwarded #714739 on publican, and I participated in discussions to move the French Debian planets to planet.debian.org. Thanks See you next month for a new summary of my activities.

10 comments Liked this article? Click here. My blog is Flattr-enabled.

Justus Winter: There is no spoon...

This is the Hurd shutting down:
root@debian:~# init 0
INIT: Switching to runlevel: 0
INIT: Sending processes the TERM signal
INIT: Sending processes the KILL signal
Using makefile-style concurrent boot in runlevel 0.
Stopping deferred execution scheduler: atd.
Asking all remaining processes to terminate...done.
All processes ended within 1 seconds...done.
Stopping enhanced syslogd: rsyslogd.
Deconfiguring network interfaces...ifdown: failed to open pid file /run/network/ifdown-/dev/eth0.pid: No such file or directory
Internet Systems Consortium DHCP Client 4.2.2
Copyright 2004-2011 Internet Systems Consortium.
All rights reserved.
For info, please visit https://www.isc.org/software/dhcp/
can't create /var/lib/dhcp/dhclient./dev/eth0.leases: No such file or directory
Listening on Socket//dev/eth0
Sending on   Socket//dev/eth0
/bin/sh: 1: ifconfig: not found
done.
Deactivating swap...swapoff: /dev/hd0s5: 177152k swap space
done.
mount: cannot remount /: Device or resource busy
Will now halt.
INIT: no more processes left in this runlevel
The important line is the one saying Asking all remaining processes to terminate...done.. What happens there is that /sbin/killall5 is run, actually does its job and the system survives that. What was needed to fix killall5 is to mark some processes (all translators being started as root as well as any essential processes) as important and to exempt them from being frozen and killed by killall5. Furthermore it was necessary to fill in the correct values for the start_code and end_code fields of the /proc/*/stat records (this used to be an issue for Debian/kFreeBSD as well). I am still in the process of cleaning up the patch series, I will finish that first thing Monday morning. I also spent my time polishing my mtab translator, the patch series is in its fourth revision and I consider it ready for inclusion: http://lists.gnu.org/archive/html/bug-hurd/2013-07/msg00259.html I also had this moment of clarity and enlightenment. For the first time I thought I finally understood what the Hurd really was. It is just a bunch of Mach programs that talk to each other in this really strange language and as a result they behave very much like the equivalent programs would on a different POSIX-like system. This is of course hidden away from the application programmer in our libc. This language is a mere convention, Richard calls this system personality. On some other level I have known this for a long time, but I never grasped the profound implications for users and developers, and for composability and the security of the system as a whole. I will try to show some of the cool stuff that can be done with such a system, stuff that is hard to do on monolithic kernels. And I had to patch the exec server. You know what they say, once you looked into /hurd/exec, there is no going back. I am very happy to report that I addressed all three major issues I identified in my second week. Next week I will clean up my initscripts patch series and submit it for inclusion. I will also rebuild the hurd, sysvinit and libc packages with all my patches included for broader testing. And if I ever run out of stuff to do first, I will have to look at the network related issues.

Petter Reinholdtsen: 90 percent done with the Norwegian draft translation of Free Culture

It has been a while since my last update. Since last summer, I have worked on a Norwegian docbook version of the 2004 book Free Culture by Lawrence Lessig, to get a Norwegian text explaining the problems with the copyright law. Yesterday, I finally broken the 90% mark, when counting the number of strings to translate. Due to real life constraints, I have not had time to work on it since March, but when the summer broke out, I found time to work on it again. Still lots of work left, but the first draft is nearing completion. I created a graph to show the progress of the translation: When the first draft is done, the translated text need to be proof read, and the remaining formatting problems with images and SVG drawings need to be fixed. There are probably also some index entries missing that need to be added. This can be done by comparing the index entries listed in the SiSU version of the book, or comparing the English docbook version with the paper version. Last, the colophon page with ISBN numbers etc need to be wrapped up before the release is done. I should also figure out how to get correct Norwegian sorting of the index pages. All docbook tools I have tried so far (xmlto, docbook-xsl, dblatex) get the order of symbols and the special Norwegian letters wrong. There is still need for translators and people with docbook knowledge, to be able to get a good looking book (I still struggle with dblatex, xmlto and docbook-xsl) as well as to do the draft translation and proof reading. And I would like the figures to be redrawn as SVGs to make it easy to translate them. Any SVG master around? There are also some legal terms that are unfamiliar to me. If you want to help, please get in touch with me, and check out the project files currently available from github. If you are curious what the translated book currently look like, the updated PDF and EPUB are published on github. The HTML version is published as well, but github hand it out with MIME type text/plain, confusing browsers, so I saw no point in linking to that version.

Joey Hess: DIY crowdfunding and bitcoin

Well, my git-annex crowdfunding campaign is half way to its August 15th conclusion. So far it's raised more than five times what I hoped it would. I wish I could say I'm like some canny NASA engineer who intentionally sets low expectations for their Mars rover, but in both the previous kickstarter and this campaign I've really had no idea how far it'd go. I'm glad that I'll be working on git-annex for another year. I was particularly unsure if it'd be successful to move off Kickstarter. During the git-annex assistant Kickstarter campaign, I saw many small contributions from people who learned of it due to it being a successfully funded project, a staff pick, etc. Losing that easy network effect is a gamble. So far I've had only half the number of contributors that I got on Kickstarter. I've basically missed out entirely on the $5 level casual contributors. On the other hand, my backers have generally been more generous (and some have been exceedingly generous). And I've avoided rewards that will cost much money, so I may end up in the same ballpark funding level in the end! Incidentially, I'm really enjoying getting in touch to let people know when I make their sponsored commits. There's still time to sponsor one of your own ;) Bitcoin I also was curious to experiment with Bitcoin in this campaign. Partly because Paypal isn't available everywhere internationally, and takes really obnoxious percentages of transactions (though probably not as bad as Kickstarter taking its percentage followed by Amazon payments taking its percentage..) and partly because there seem to be interesting possibilities for supporting free software with Bitcoin. (Especially if any of the microtransactions on top of Bitcoin take off.) So far 5% of backers have used Bitcoin. It's been quite strange to actually have significant amounts of bitcoins in my wallet. Wordpress has had 94 bitcoin payments over 9 months since starting accepting them. I've had 47 payments in the two weeks my campaign has run so far. Wow! Most of the bitcoin payments have come in via Coinbase (a few people have found my direct payment address), but of those very few were using bitcoin purchased on Coinbase. Most are probably transfers of bitcoin they already had, or perhaps bitcoin purchased on other sites. The one technical issue I've had with using bitcoin is that Coinbase has not provided details about who sent most of the donations. Probably some of them are intentionally anonymous, but I suspect Coinbase's interface to claim incoming bitcoin transactions failed for some of them. (If you donated bitcoin and want to actually get a reward, please email me.) By the way, I'm converting most of the bitcoins back to USD pretty quickly. I'm not interested in speculating on currency exchange rates with money that has been donated so I can accomplish a particular task.. DIY I put up the campaign website without any means in place to handle updating it. This is because I never automate anything until I've done it at least 10 times by hand. ;) After the first trickle of donations became a flood, I quickly realized I needed at least something to handle keeping the numbers straight. What I whipped up in an hour of coding is a system where I enter incoming payments into a hledger file and a small haskell program parses that and writes out various files that are included into the website. Amusingly the percentage calculation and display code was copied from git-annex, so part of git-annex is helping run its own fundraising campaign. The campaign video is itself hosted in a public git-annex repository, come to think of it. The rest of the site is built using ikiwiki. Given that it's hosted at Branchable, this is a high level of dogfooding and DIY. There are certianly better crowdfunding platforms, but all I miss in this one is automated transaction entry. And I have total flexability, double entry accounting, and a powerful static website generator that handled being on the top of Hacker News without a sweat. Oh, and some money. What's not to like?

1 August 2013

Russ Allbery: Review: And Playing the Role of Herself

Review: And Playing the Role of Herself, by K.E. Lane
Publisher: Regal Crest
Copyright: 2006
Printing: June 2010
ISBN: 1-932300-72-4
Format: Kindle
Pages: 336
Caidence Harris is an actress who has finally gotten her big shot: a starring role in the hit police drama 9th Precinct. She plays half of a police partnership; the other half is played by her best friend, the considerably more famous Liz Stokley. She's quite happy with her life and her work, and only tentatively pondering what to do about coming out (at least to herself) as a lesbian. But matters get considerably more complicated when she starts falling for Robyn Ward, a star in a parallel legal drama. And the very high-profile girlfriend of one of the best male tennis players in the world. Yes, another lesbian romance. This one has won several awards, including the highest recommendation from my friend who's been prefiltering the genre for me and pointing out only the best stories. And despite being set firmly among the rich and famous and involving TV dramas with the serial numbers filed off, he was right. This is a thoroughly enjoyable story. One of its strongest parts is how Lane develops the romance between Caidence and Robyn. There is a bit of the inevitable physical chemistry so common in romances (I still don't believe kisses work that way), and a few descriptions of physical beauty (after all, there's a built-in excuse for everyone to be TV-star beautiful). But Lane avoids putting either at the center of the relationship. Instead, this is a romance built on trust, tentative at first and then growing but rocky. That speaks to me a lot more than all the descriptions of physical chemistry. For example, we don't see Caidence and Robyn meet for the first time in the novel, as is usually the case. They've been around each other before, with Caidence acting rather tongue-tied and a bit star-struck and Robyn thinking she's rather silly. The story begins when, for whatever reason, Caidence finally manages to relax and become genuine, and then both of them become closer as they find themselves lowering barriers around each other that they normally don't lower. Lane does an excellent job using a few key facial expressions as symbols and hallmarks of that, letting the reader follow the way that trust builds through the story. The other great element of this book is Caidence's friend Liz. She could have been a stereotype of a movie star: drop-dead gorgeous, a new boyfriend each week, but not particularly intelligent. That's how she comes off at first. But as the story progresses, Lane shows more and more of their friendship, and the reader gets to see just how much Liz's first impression is a combination of an act and her unapologetic tendency to do what she wants. Underneath, she's a strong female character and an excellent, if meddling friend; by the end of the book, she was in the running for my favorite character. This is characterization of a quality that I rarely see in any genre of novel. Given that it's a romance that I enjoyed, you can correctly expect there not to be a lot of obnoxious communication breakdowns or chapters full of the main characters refusing to communicate with each other. There are, of course, a wide variety of barriers in the way of a relationship for the main characters, not the least of which being that neither of them was looking for something serious. But while they both do occasionally thoughtless or hurtful things, it's always clear just why they were thoughtless, or where their buttons were accidentally pressed, and few of the character actions are outright stupid. And, delightfully, Lane structures the story so that there are multiple, incremental payoffs. One can not only enjoy the characters getting together in the end, as they always do in this genre, but a lot of important and meaningful steps along the way. Lane does a great job putting the reader in Caidence's head, helped by first-person narration, so that one can feel just how much some moments mean to her emotionally. Add in several other fleshed-out and interesting supporting characters, some incredible architecture that was fun to imagine, and rather more in the way of plot twists and dramatic moments than I usually expect in a romance (and although the book worried me once, none of them go to the dark places that would have been less fun), and one gets a novel that kept me engrossed from start to finish. I'm tempted to read it again, and that's rare for me for a romance novel. If you're in the mood for a heart-warming story about intelligent people learning how to be together, I highly recommend this book. It's a great book to read as a stress relief when you want a story that you know will turn out "right." Rating: 9 out of 10

29 July 2013

Gergely Nagy: HOWTO: JSON processing with syslog-ng

Continuing my HOWTO series, in this article, I will explore how to set up syslog-ng to process JSON in various scenarios. We will touch the subject of interoperability, and have a look at multiple scenarios, in the hope that readers will find something similar to their own needs. There are many different ways in which one can plug JSON into their logging system, and it is very likely that I will not be able to cover it all within this HOWTO. However, I will explain the basics, and how to plug the pieces together, which should at least be a useful foundation to build even more complex systems onto.In essence, we will look at the following scenarios: raw JSON transport, JSON over syslog, JSON and syslog payload in the same stream. The documentation will cover both syslog-ng 3.4 and 3.5, where the 3.5 parts will be clearly marked as such. The 3.3 series do not have a JSON parser, and as such, is insufficient for most needs explored in this guide.In the default setting, the JSON parser will parse the MESSAGE part of an incoming log event, and place every key into a macro of the same name. If the incoming JSON is structured, it the keys will be converted to dot notation format:
"deeper": "level": "very much so"
In this case, one can access the value as $ deeper.level within a syslog-ng template.The parsed keys can be prefixed using the prefix() option of the json-parser. One can also change what the parser will receive as input by using the template() option.See the documentation for more information on these.Transporting raw JSONThe simplest scenario is to take a transport like TCP, and simply push raw JSON structures through, one each line, and have syslog-ng parse that to its internal representation. One can do all kinds of things with the data then: transport it further as JSON, store it in files, in a database - the possibilities are endless, but we will explore two scenarios.JSON on TCP, using syslog field namesThe first one is receiving JSON on TCP, using syslog field names, store the parsed stuff in a file (using the conventional format), and in mongodb.
source s_tcp_json   tcp(port(10514) flags(no-parse));  ;
parser p_json   json-parser();  ;
destination d_file   file("/var/log/remote.log");  ;
destination d_mongodb   mongodb(collection("remote_log"));  ;
log  
 source(s_tcp_json);
 parser(p_json);
 destination(d_file);
 destination(d_mongodb);
 ;
This needs a bit of an explanation: we use the no-parse flag on the source, because by default, the tcp() source expects a message that conforms to the old syslog protocol. We have raw JSON, and we need to tell the source that. The other elements should be self explanatory, I believe, with the exception of json-parser(): we give it no parameters, so it will not modify the keys in the JSON it receives, keeping them intact, as-is.For this reason, incoming messages need to have the same keys as syslog-ng normally would use internally: DATE, HOST, MESSAGE, and so on, like in the following example:
"PROGRAM":"prg00000","PRIORITY":"info","PID":"1234","MESSAGE":"seq: 0000000000, thread: 0000, runid: 1374490607, stamp: 2013-07-22T12:56:47 MESSAGE...","HOST":"localhost","FACILITY":"auth","DATE":"Jul 22 12:56:47"
JSON on TCP, custom field namesA more likely scenario is when we receive JSON, but not in a layout syslog-ng uses internally. In this case, we need to rewrite the message a little, and possibly use templates, depending on what kind of output we wish to use.Lets assume the incoming JSON has these fields:
"app":"prg00000","prio":"info","id":"1234","msg":"seq: 0000000000, thread: 0000, runid: 1374490607, stamp: 2013-07-22T12:56:47 MESSAGE...","source":"localhost","timestamp":"Jul 22 12:56:47"
As you can see, this has similar fields, but not quite, and FACILITY is missing too.In this case, we'll use a different configuration:
source s_tcp_json   tcp(port(10514) flags(no-parse));  ;
parser p_json   json-parser(prefix(".json."));  ;
destination d_file   file("/var/log/remote.log"
                          template("$ .json.timestamp  $ .json.source  $ .json.app [$ .json.id ]: $ .json.msg \n"));  ;
destination d_mongodb   mongodb(collection("remote_log")
                                value-pairs(
                                  pair("PROGRAM" "$ .json.app ")
                                  pair("HOST" "$ .json.source ")
                                  pair("PID" "$ .json.id ")
                                  pair("MESSAGE" "$ .json.msg ")
                                  pair("DATE" "$ .json.timestamp ")
                                  pair("PRIORITY" "$ .json.prio ")
                                  pair("FACILITY" "auth")
                                ));  ;
log  
 source(s_tcp_json);
 parser(p_json);
 destination(d_file);
 destination(d_mongodb);
 ;
We use the prefix() option of json-parser(), to avoid collisions with the default syslog-ng namespace. Then, we use a template for the file destination, and value-pairs() for the MongoDB one. Doing all this, we get similar results as we did in the first scenario.JSON over syslogAn even likelier scenario is when we have JSON payload in the message part of a normal syslog message. This is useful because the logs themselves remain syslog compatible, and can be transported through devices that know no better.Thankfully, if we do not tell syslog-ng that we do not want any parsing on the input, the json-parser will receive the MESSAGE part of the log, so if we have JSON payload there, things will just work:
source s_tcp_json_payload   tcp();  ;
parser p_json   json-parser();  ;
destination d_file   file("/var/log/remote.log");  ;
destination d_mongodb   mongodb(collection("remote_log"));  ;
log  
 source(s_tcp_json_payload);
 parser(p_json);
 destination(d_file);
 destination(d_mongodb);
 ;
Again, this assumes that the JSON payloads uses field names compatible with syslog-ng's defaults. Adapting it to use templates or value-pairs can of course be made, as shown in an example above.As an example, here's how a syslog message with JSON payload would look like:
<38>2013-07-22T13:45:54 localhost prg00000[1234]:  "MESSAGE": "foo", "PROGRAM": "bar" 
This would, of course, override the MESSAGE and PROGRAM fields, but the rest would be kept intact.Mixed JSON and syslog streamIn order to parse JSON that is intermingled with normal syslog streams, we can use a new feature of syslog-ng 3.4: junctions. These allow us to create branches, and tell syslog-ng something along these lines:
If there's an incoming message, that begins with @json:, parse it as JSON, otherwise treat it as a normal syslog message.
We can, of course, skip the part that mandates an in-stream marker, and things will just work, but in that case, for each JSON message, an error will get logged too, which is undesirable. Therefore, if one wants to intermingle JSON and syslog traffic on the same wire, it's best to do so with the JSON having a marker prefix. The marker, however, is not going to be part of the string the json parser receives, so setting it to an opening curly bracket will not work, unless the template is modified accordingly.The config to do this looks like this:
block parser mixed-json-parser()  
 channel  
  junction  
   channel  
    parser   json-parser(marker("@json:"));  ;
    rewrite   set-tag(".json");  ;
    flags(final);
    ;
   channel  
    flags(final);
    ;
   ;
  ;
 ;
source s_mixed  
 tcp();
 parser   mixed-json-parser();  ;
 ;
A more elaborate example can be found in a post by Bazsi.Closing thoughtsThat covers most of the use cases I saw for the JSON parser, if there are cases uncovered, or questions unanswered, I can be reached via twitter, email and a whole host of other ways, and I will happily expand this tutorial if there's enough demand for more.

Thomas Goirand: OpenStack Havana b2 available, openstack-debian-images approved

I have finished preparing the beta 2 of the next release of OpenStack. It is currently only available from out Git on Alioth (in /git/openstack), and directly from my jenkins repository, which creates Wheezy backports for it:
deb ftp://havana.pkgs.enovance.com/debian havana main
deb http://archive.gplhost.com/debian havana-backports main
As for every OpenStack release, a large number of Python modules needed to be packaged and are waiting in the FTP master NEW queue to be approved: oslo-sphinx, python-django-discover-runner, python-hacking, python-jsonrpclib, python-lesscpy, python-neutronclient, python-nosehtmloutput, python-requestbuilder, python-termcolor, sphinxcontrib-httpdomain and sphinxcontrib-pecanwsme. Let s hope that they will be approved before the next beta release in september (time where OpenStack Havana will be in feature freeze). The total number of packages maintained by the OpenStack team (on which I really am the only active maintainer for the moment ), there s 53 packages, plus these 11 packages waiting in the NEW queue. That s a big number of package, and I wouldn t mind some help One thing that annoyed all the community is that Quantum, the OpenStack network virtualization module, had to be renamed as Neutron, because of a trademark from Quantum (you probably remember the Quantum Fireball hard drives? Well, it s the same company ). Another good news is that my openstack-debian-images package has just been approved and landed in Sid. With it, you can automate the process of building a Debian image for OpenStack with a simple shell command (there s a man page that I wrote with it: read it if you need to build images). It is made of a single shell script to build the image, using kpartx, parted, mbr, debootstrap, extlinux and friends. I tried to keep it simple, not involving a huge amount of components. With the release of cloud-init 0.7.2-3, I have fixed a few bugs (3 important bugs, out of which 2 where RC bugs), thanks to contributions in the debian-cloud@lists.debian.org mailing list. This includes adding new init.d scripts, so we now have support for user data. This doesn t only benefits OpenStack images, but anyone willing to start virtual machines in the cloud (nowadays, every cloud implementation needs cloud-init installed in the virtual images). This means you can include a script in the metadata of the virtual machine you start it, and it will be executed at startup. If everything goes as planned (that is, no new RC bug), I will upload an update of cloud-init to backports in 5 days (there is already a version there, but it doesn t have the necessary init.d scripts to execute the user data scripts), and openstack-debian-images in 9 days. Then it will be possible to build OpenStack images with absolutely all the tools available from Wheezy (and backports). I hope to be able to discuss that during Debconf 13.

28 July 2013

Daniel Pocock: This blog was slashdotted

My earlier blog about rigged elections was slashdotted over the weekend. I had an email from the slashdot team giving me advance warning, having heard the stories about other sites getting knocked offline, I immediately logged into my Ganglia console to start the tsunami watch. I then set about enabling a reverse proxy using Squid to accelerate web server performance. This took about 30 minutes to set up. I chose Squid 3 so I could use a logging format similar to Apache. The wave hits A few hours after the warning email, details appeared on slashdot and sure enough, thousands of visitors started coming to this site. As detailed previously, the site is running on Debian servers with XCP. The web site is managed by Drupal/Apache/MySQL. Everything held together very well. Ganglia demonstrated an initial surge lasting about 10 minutes. From there, traffic has tapered off gradually over 24 hours, although it still remains well above average. slashdot comments One of the most interesting things about the slashdot community are the comments. Given that nobody really wanted to defend the indefensible and nothing in my blog surpasses some of what has been in the news recently (150 charges of fraud against a single MP), most of the discussion quickly turned to a comparison of broadband policies. For those not already aware of it, the Australian Government (Labor Party) is currently rolling out fibre to the home. The project is expected to take about 10 years, although it was delivered very quickly in certain areas where the Government needs votes. Opinions are divided: people who got it first think it is great, some people feel it is too expensive (it's much more expensive than a similar service in Switzerland, for example), some people feel it will be too slow when the final stages are completed in 10 years. It appears technically stronger than the solution proposed by the alternative party.

27 July 2013

Petter Reinholdtsen: First beta release of Debian Edu/Skolelinux based on Debian Wheezy

The first wheezy based beta release of Debian Edu was wrapped up today. This is the release announcement: New features for Debian Edu 7.1+edu0~b0 released 2013-07-27 These are the release notes for for Debian Edu / Skolelinux 7.1+edu0~b0, based on Debian with codename "Wheezy". About Debian Edu and Skolelinux Debian Edu, also known as Skolelinux, is a Linux distribution based on Debian providing an out-of-the box environment of a completely configured school network. Immediately after installation a school server running all services needed for a school network is set up just waiting for users and machines being added via GOsa , a comfortable Web-UI. A netbooting environment is prepared using PXE, so after initial installation of the main server from CD, DVD or USB stick all other machines can be installed via the network. The provided school server provides LDAP database and Kerberos authentication service, centralized home directories, DHCP server, web proxy and many other services. The desktop contains more than 60 educational software packages and more are available from the Debian archive, and schools can choose between KDE, Gnome, LXDE and Xfce desktop environment. This is the fifth test release based on Debian Wheezy. Basically this is an updated and slightly improved version compared to the Squeeze release. ALERT: Alpha based installations should reinstall or downgrade the versions of gosa and libpam-mklocaluser to the ones used in this beta release. Software updates Other changes Known issues Where to get it To download the multiarch netinstall CD release you can use The MD5SUM of this image is: 55d5de9765b6dccd5d9ec33cf1a07109
The SHA1SUM of this image is: 996a1d9517740e4d627d100de2d12b23dd545a3f To download the multiarch USB stick ISO release you can use The MD5SUM of this image is: d8f0818c51a78d357de794066f289f69
The SHA1SUM of this image is: 49185ca354e8d0543240423746924f76a6cee733 How to report bugs http://wiki.debian.org/DebianEdu/HowTo/ReportBugs

Christian Perrier: [life] Running update July 27th 2013: Bubulle now runs in moutains

My last running update was sent after I had a great April month with two successful trail races (35km then 44km). The next target was Mont-Blanc marathon in Chamonix valley in early July, so it's time for me to send a new update before summer. May and June was mostly training. Huge training. Very long distances with 375km in May and over 430 in June (breaking my former monthly record by over 50 kilometers). Yes, that means over 14 kilometers every day..:-) I indeed achieved that with my "go to work partly by running" habits, which are now deeply included in my daily schedule. Much more convenient than bus ride (with the typical random schedules of RATP, which French people translate by "Rentre Avec Tes Pieds" or "Come back home by walking"....which is exactly what I'm doing). With such training (sometimes including extra rides in the forests, with short but steep ups and downs)....I was well prepared for THE early summer goal : Marathon du Mont-Blanc in Chamonix (not Ultra Trail du Mont-blanc : this one, I'm not ready for....yet).. My first mountain trail race, and what race! Imagine 42km in the moutain lovers heaven, namely the Chamonix Valley, with the Mont-Blanc, Aiguille Verte, Aiguille du Midi, Aiguilles Rouges, etc. above your head. Of course, not only in the valley but goind up and down "slightly"....in short 2200 meters positive climb..:-) I ran it with a female friend of mine, who I met in local races and through runners web forums. Sabine has about the same running skills than me and we developed a good and nice friendship, sharing our love for running in the nature. So, during May and June, we decided to run this race together as we were both registered for it. A first trial in a local 35km trail race two weeks before the MMB was very successful. We ended up in 3h40 and Sabine was ranked 5th female runner. And, moreover, we had a tremendous pleasure by crossing the finishing line together. So, we did it again in Chamonix. And, hell, we did it well: I had set the goal to 6 hours and 30 minutes and we completed the race in..... 6 hours and 34 minutes. Much much better than I and she would have expected. And, believe me, crossing the finishing line was again a special moment, particularly because the crowd at the end of this race make it look like l'Alpe d'Huez on the Tour de France. And, this on a wonderful sunny day, arriving at Planpraz, facing the Mont-Blanc. If you've ever been to Chamonix, you know what I mean. So, first moutain trail and, hell, not the last one! For those of you who can read French...or just want to see some pictures of a running bubulle, here is the link to the story. And these 42 kilometers were indeed so well done that the day after, while coming down from the famous Aiguille du Midi with Elisabeth (who came with me to Chamonix, of course)...I decided to run down from the cable car intermediate stop (2300m altitude) to Chamonix (1050m). Over 1200 meters down in 48 minutes... :-). Just a bit slower than the cable car....:) The remaining of July saw me again running back and forth to work and I'm indeed about to break my monthly record, eventually reaching 450 kilometers in one month and only two days NOT running in the whole month. Yeah, crazy. The upcoming Sunday, August 4th, just before going to Debconf 13, I'll spend a few days in Lanslebourg and will be running the EDF Cenis Tour trail, for 50 kilometers and 2600 meters positive climb. This time, a very "small" race, with no more than 150 runners. So, that will be another experience by running nearly entirely alone between 1400 and 2700 meters altitude. I'll post the outcome (or you'll probably hear about it at DC13....). See you, hopefully not in 3 months, for another update about running Bubulle.

Next.

Previous.