Search Results: "ag"

5 December 2021

Reproducible Builds (diffoscope): diffoscope 195 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 195. This version includes the following changes:
[ Chris Lamb ]
* Don't use the runtime platform's native endianness when unpacking .pyc
  files to fix test failures on big-endian machines.
You find out more by visiting the project homepage.

4 December 2021

Jonathan Dowland: Haskell mortgage calculator

A few months ago I was trying to compare two mortgage offers, and ended up writing a small mortgage calculator to help me. Both mortgages were fixed-term for the same time period (5 years). One of the mortgages had a lower rate than the other, but much higher arrangement fees. A broker recommended the mortgage with the higher rate but lower fee, on an affordability basis for the fixed term: over all, we would spend less money within the fixed term on that deal than the other. (I thought) this left one bit of information missing: what remaining balance would there be at the end of the term? The mortgages I want to model are defined in terms of a monthly repayment figure and an annual interest rate for the fixed period. I think interest is usually recalculated on a daily basis, so I convert the annual rate down to a daily rate. Repayments only happen once a month. Months are not all the same size. Using mod 30 on the 'day' approximates a monthly payment. Over 5 years, there would be 60 months, meaning 60 repayments. (I'm ignoring leap years)
 > length . filter id .take (5*365) $ [ x mod 30==0   x <- [1..]]
60
Here's what I came up with. I was a little concerned the repayment approximation was too far out so I compared the output with a more precise (but boring) spreadsheet and they agreed to within an acceptable tolerance. The numbers that follow are all made up to illustrate the function and don't reflect my actual mortgage. :)
borrowed = 1000000 -- day 0 amount outstanding
aer   = 0.89
repay = 1000
der   = aer / 36
owed n   n == 0          = borrowed
         n  mod  30 == 0 = last + interest - repay
         otherwise       = last + interest
    where
        last     = owed (n - 1)
        interest = last * der

Paul Tagliamonte: Receiving BPSK symbols (Part 3/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we worked through how to generate a BPSK signal, and hopefully transmit it using one of our SDRs. Let s take that and move on to Receiving BPSK and turning that back into symbols! Demodulating BPSK data is a bit more tricky than transmitting BPSK data, mostly due to tedious facts of life such as space, time, and hardware built with compromises because not doing that makes the problem impossible. Unfortunately, it s now our job to work within our imperfect world to recover perfect data. We need to handle the addition of noise, differences in frequency, clock synchronization and interference in order to recover our information. This makes life a lot harder than when we transmit information, and as a result, a lot more complex.

Coarse Sync Our starting point for this section will be working from a capture of a number of generated PACKRAT packets as heard by a PlutoSDR at (xz compressed interleaved int16, 2,621,440 samples per second) Every SDR has its own oscillator, which eventually controls a number of different components of an SDR, such as the IF (if it s a superheterodyne architecture) and the sampling rate. Drift in oscillators lead to drifts in frequency such that what one SDR may think is 100MHz may be 100.01MHz for another radio. Even if the radios were perfectly in sync, other artifacts such as doppler time dilation due to motion can cause the frequency to appear higher or lower in frequency than it was transmitted. All this is a long way of saying, we need to determine when we see a strong signal that s close-ish to our tuned frequency, and take steps to roughly correct it to our center frequency (in the order of 100s of Hz to kHz) in order to acquire a phase lock on the signal to attempt to decode information contained within. The easiest way of detecting the loudest signal of interest is to use an FFT. Getting into how FFTs work is out of scope of this post, so if this is the first time you re seeing mention of an FFT, it may be a good place to take a quick break to learn a bit about the time domain (which is what the IQ data we ve been working with so far is), frequency domain, and how the FFT and iFFT operations can convert between them. Lastly, because FFTs average power over the window, swapping phases such that the transmitted wave has the same number of in-phase and inverted-phase symbols the power would wind up averaging to zero. This is not helpful, so I took a tip from Dr. Marc Lichtman s PySDR project and used complex squaring to drive our BPSK signal into a single detectable carrier by squaring the IQ data. Because points are on the unit circle and at tau/2 (specifically, tau/(2^1) for BPSK, 2^2 for QPSK) angles, and given that squaring has the effect of doubling the angle, and angles are all mod tau, this will drive our wave comprised of two opposite phases back into a continuous wave effectively removing our BPSK modulation, making it much easier to detect in the frequency domain. Thanks to Tom Bereknyei for helping me with that!
...
var iq []complex 
var freq []complex 
for i := range iq  
iq[i] = iq[i] * iq[i]
 
// perform an fft, computing the frequency
 // domain vector in  freq  given the iq data
 // contained in  iq .
 fft(iq, freq)
// get the array index of the max value in the
 // freq array given the magnitude value of the
 // complex numbers.
 var binIdx = max(abs(freq))
...
Now, most FFT operations will lay the frequency domain data out a bit differently than you may expect (as a human), which is that the 0th element of the FFT is 0Hz, not the most negative number (like in a waterfall). Generally speaking, zero first is the most common frequency domain layout (and generally speaking the most safe assumption if there s no other documentation on fft layout). Negative first is usually used when the FFT is being rendered for human consumption such as a waterfall plot. Given that we now know which FFT bin (which is to say, which index into the FFT array) contains the strongest signal, we ll go ahead and figure out what frequency that bin relates to. In the time domain, each complex number is the next time instant. In the frequency domain, each bin is a discrete frequency or more specifically a frequency range. The bandwidth of the bin is a function of the sampling rate and number of time domain samples used to do the FFT operation. As you increase the amount of time used to preform the FFT, the more precise the FFT measurement of frequency can be, but it will cover the same bandwidth, as defined by the sampling rate.
...
var sampleRate = 2,621,440
// bandwidth is the range of frequencies
 // contained inside a single FFT bin,
 // measured in Hz.
 var bandwidth = sampleRate/len(freq)
...
Now that we know we have a zero-first layout and the bin bandwidth, we can compute what our frequency offset is in Hz.
...
// binIdx is the index into the freq slice
 // containing the frequency domain data.
 var binIdx = 0
// binFreq is the frequency of the bin
 // denoted by binIdx
 var binFreq = 0
if binIdx > len(freq)/2  
// This branch covers the case where the bin
 // is past the middle point - which is to say,
 // if this is a negative frequency.
 binFreq = bandwidth * (binIdx - len(freq))
  else  
// This branch covers the case where the bin
 // is in the first half of the frequency array,
 // which is to say - if this frequency is
 // a positive frequency.
 binFreq = bandwidth * binIdx
 
...
However, sice we squared the IQ data, we re off in frequency by twice the actual frequency if we are reading 12kHz, the bin is actually 6kHz. We need to adjust for that before continuing with processing.
...
var binFreq = 0
...
// [compute the binFreq as above]
 ...
// Adjust for the squaring of our IQ data
 binFreq = binFreq / 2
...
Finally, we need to shift the frequency by the inverse of the binFreq by generating a carrier wave at a specific frequency and rotating every sample by our carrier wave so that a wave at the same frequency will slow down (or stand still!) as it approaches 0Hz relative to the carrier wave.
 var tau = pi * 2
// ts tracks where in time we are (basically: phase)
 var ts float
// inc is the amount we step forward in time (seconds)
 // each sample.
 var inc float = (1 / sampleRate)
// amount to shift frequencies, in Hz,
 // in this case, shift +12 kHz to 0Hz
 var shift = -12,000
for i := range iq  
ts += inc
if ts > tau  
// not actually needed, but keeps ts within
 // 0 to 2*pi (since it is modulus 2*pi anyway)
 ts -= tau
 
// Here, we're going to create a carrier wave
 // at the provided frequency (in this case,
 // -12kHz)
 cwIq = complex(cos(tau*shift*ts), sin(tau*shift*ts))
iq[i] = iq[i] * cwIq
 
Now we ve got the strong signal we ve observed (which may or may not be our BPSK modulated signal!) close enough to 0Hz that we ought to be able to Phase Lock the signal in order to begin demodulating the signal.

Filter After we re roughly in the neighborhood of a few kHz, we can now take some steps to cut out any high frequency components (both positive high frequencies and negative high frequencies). The normal way to do this would be to do an FFT, apply the filter in the frequency domain, and then do an iFFT to turn it back into time series data. This will work in loads of cases, but I ve found it to be incredibly tricky to get right when doing PSK. As such, I ve opted to do this the old fashioned way in the time domain. I ve again opted to go simple rather than correct, and haven t used nearly any of the advanced level trickery I ve come across for fear of using it wrong. As a result, our process here is going to be generating a sinc filter by computing a number of taps, and applying that in the time domain directly on the IQ stream.
// Generate sinc taps

func sinc(x float) float  
if x == 0  
return 1
 
var v = pi * x
return sin(v) / v
 
...
var dst []float
var length = float(len(dst))
if int(length)%2 == 0  
length++
 
for j := range dst  
i := float(j)
dst[j] = sinc(2 * cutoff * (i - (length-1)/2))
 
...
then we apply it in the time domain
...
// Apply sinc taps to an IQ stream

var iq []complex
// taps as created in  dst  above
 var taps []float
var delay = make([]complex, len(taps))
for i := range iq  
// let's shift the next sample into
 // the delay buffer
 copy(delay[1:], delay)
delay[0] = iq[i]
var phasor complex
for j := range delay  
// for each sample in the buffer, let's
 // weight them by the tap values, and
 // create a new complex number based on
 // filtering the real and imag values.
 phasor += complex(
taps[j] * real(delay[j]),
taps[j] * imag(delay[j]),
)
 
// now that we've run this sample
 // through the filter, we can go ahead
 // and scale it back (since we multiply
 // above) and drop it back into the iq
 // buffer.
 iq[i] = complex(
real(phasor) / len(taps),
imag(phasor) / len(taps),
)
 
...
After running IQ samples through the taps and back out, we ll have a signal that s been filtered to the shape of our designed Sinc filter which will cut out captured high frequency components (both positive and negative). Astute observers will note that we re using the real (float) valued taps on both the real and imaginary values independently. I m sure there s a way to apply taps using complex numbers, but it was a bit confusing to work through without being positive of the outcome. I may revisit this in the future!

Downsample Now, post-filter, we ve got a lot of extra RF bandwidth being represented in our IQ stream at our high sample rate All the high frequency values are now filtered out, which means we can reduce our sampling rate without losing much information at all. We can either do nothing about it and process at the fairly high sample rate we re capturing at, or we can drop the sample rate down and help reduce the volume of numbers coming our way. There s two big ways of doing this; either you can take every Nth sample (e.g., take every other sample to half the sample rate, or take every 10th to decimate the sample stream to a 10th of what it originally was) which is the easiest to implement (and easy on the CPU too), or to average a number of samples to create a new sample. A nice bonus to averaging samples is that you can trade-off some CPU time for a higher effective number of bits (ENOB) in your IQ stream, which helps reduce noise, among other things. Some hardware does exactly this (called Oversampling ), and like many things, it has some pros and some cons. I ve opted to treat our IQ stream like an oversampled IQ stream and average samples to get a marginal bump in ENOB. Taking a group of 4 samples and averaging them results in a bit of added precision. That means that a stream of IQ data at 8 ENOB can be bumped to 9 ENOB of precision after the process of oversampling and averaging. That resulting stream will be at 1/4 of the sample rate, and this process can be repeated 4 samples can again be taken for a bit of added precision; which is going to be 1/4 of the sample rate (again), or 1/16 of the original sample rate. If we again take a group of 4 samples, we ll wind up with another bit and a sample rate that s 1/64 of the original sample rate.

Phase Lock Our starting point for this section is the same capture as above, but post-coarse sync, filtering downsampling (xz compressed interleaved float32, 163,840 samples per second) The PLL in PACKRAT was one of the parts I spent the most time stuck on. There s no shortage of discussions of how hardware PLLs work, or even a few software PLLs, but very little by way of how to apply them and/or troubleshoot them. After getting frustrated trying to follow the well worn path, I decided to cut my own way through the bush using what I had learned about the concept, and hope that it works well enough to continue on. PLLs, in concept are fairly simple you generate a carrier wave at a frequency, compare the real-world SDR IQ sample to where your carrier wave is in phase, and use the difference between the local wave and the observed wave to adjust the frequency and phase of your carrier wave. Eventually, if all goes well, that delta is driven as small as possible, and your carrier wave can be used as a reference clock to determine if the observed signal changes in frequency or phase. In reality, tuning PLLs is a total pain, and basically no one outlines how to apply them to BPSK signals in a descriptive way. I ve had to steal an approach I ve seen in hardware to implement my software PLL, with any hope it s close enough that this isn t a hazard to learners. The concept is to generate the carrier wave (as above) and store some rolling averages to tune the carrier wave over time. I use two constants, alpha and beta (which appear to be traditional PLL variable names for this function) which control how quickly the frequency and phase is changed according to observed mismatches. Alpha is set fairly high, which means discrepancies between our carrier and observed data are quickly applied to the phase, and a lower constant for Beta, which will take long-term errors and attempt to use that to match frequency. This is all well and good. Getting to this point isn t all that obscure, but the trouble comes when processing a BPSK signal. Phase changes kick the PLL out of alignment and it tends to require some time to get back into phase lock, when we really shouldn t even be loosing it in the first place. My attempt is to generate two predicted samples, one for each phase of our BPSK signal. The delta is compared, and the lower error of the two is used to adjust the PLL, but the carrier wave itself is used to rotate the sample.
 var alpha = 0.1
var beta = (alpha * alpha) / 2
var phase = 0.0
var frequency = 0.0
...
for i := range iq  
predicted = complex(cos(phase), sin(phase))
sample = iq[i] * conj(predicted)
delta = phase(sample)
predicted2 = complex(cos(phase+pi), sin(phase+pi))
sample2 = iq[i] * conj(predicted2)
delta2 = phase(sample2)
if abs(delta2) < abs(delta)  
// note that we do not update 'sample'.
 delta = delta2
 
phase += alpha * delta
frequency += beta * delta
// adjust the iq sample to the PLL rotated
 // sample.
 iq[i] = sample
 
...
If all goes well, this loop has the effect of driving a BPSK signal s imaginary values to 0, and the real value between +1 and -1.

Average Idle / Carrier Detect Our starting point for this section is the same capture as above, but post-PLL (xz compressed interleaved float32, 163,840 samples per second) When we start out, we have IQ samples that have been mostly driven to an imaginary component of 0 and real value range between +1 and -1 for each symbol period. Our goal now is to determine if we re receiving a signal, and if so, determine if it s +1 or -1. This is a deceptively hard problem given it spans a lot of other similarly entertaining hard problems. I ve opted to not solve the hard problems involved and hope that in practice my very haphazard implementation works well enough. This turns out to be both good (not solving a problem is a great way to not spend time on it) and bad (turns out it does materially impact performance). This segment is the one I plan on revisiting, first. Expect more here at some point! Given that I want to be able to encapsulate three states in the output from this section (our Symbols are no carrier detected ( 0 ), real value 1 ( 1 ) or real value -1 ("-1")), which means spending cycles to determine what the baseline noise is to try and identify when a signal breaks through the noise becomes incredibly important.
var idleThreshold
var thresholdFactor = 10
...
// sigThreshold is used to determine if the symbol
 // is -1, +1 or 0. It's 1.3 times the idle signal
 // threshold.
 var sigThreshold = (idleThreshold * 0.3) + idleThreshold
// iq contains a single symbol's worth of IQ samples.
 // clock alignment isn't really considered; so we'll
 // get a bad packet if we have a symbol transition
 // in the middle of this buffer. No attempt is made
 // to correct for this yet.
 var iq []complex
// avg is used to average a chunk of samples in the
 // symbol buffer.
 var avg float
var mid = len(iq) / 2
// midNum is used to determine how many symbols to
 // average at the middle of the symbol.
 var midNum = len(iq) / 50
for j := mid; j < mid+midNum; j++  
avg += real(iq[j])
 
avg /= midNum
var symbol float
switch  
case avg > sigThreshold:
symbol = 1
case avg < -sigThreshold:
symbol = -1
default:
symbol = 0
// update the idleThreshold using the thresholdFactor
 // to average the idleThreshold over more samples to
 // get a better idea of average noise.
 idleThreshold = (
(idleThreshold*(thresholdFactor-1) + symbol) \
/ thresholdFactor
)
 
// write symbol to output somewhere
...

Next Steps Now that we have a stream of values that are either +1, -1 or 0, we can frame / unframe the data contained in the stream, and decode Packets contained inside, coming next in Part 4!

Dirk Eddelbuettel: RcppAPT 0.0.8: Package Maintenance

A new version of the RcppAPT package interfacing from R to the C++ library behind the awesome apt, apt-get, apt-cache, commands and their cache powering Debian, Ubuntu and the like arrived on CRAN earlier today. RcppAPT allows you to query the (Debian or Ubuntu) package dependency graph at will, with build-dependencies (if you have deb-src entries), reverse dependencies, and all other goodies. See the vignette and examples for illustrations. This release updates some package metadata, adds a new package testing helper, and, just like digest three days ago, drat two days ago, and littler yesterday, we converted the vignettes from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style.

Changes in version 0.0.8 (2021-12-04)
  • New test file version.R ensures NEWS file documents current package version
  • Travis artifacts and badges have been pruned
  • Vignettes now use simplermarkdown

Courtesy of my CRANberries, there is also a diffstat report for this release. A bit more information about the package is available here as well as as the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 December 2021

Paul Tagliamonte: Transmitting BPSK symbols (Part 2/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we worked through what IQ is, and different formats that it may be sent or received in. Let s take that and move on to Transmitting BPSK using IQ data! When we transmit and receive information through RF using an SDR, data is traditionally encoded into a stream of symbols which are then used by a program to modulate the IQ stream, and sent over the airwaves. PACKRAT uses BPSK to encode Symbols through RF. BPSK is the act of modulating the phase of a sine wave to carry information. The transmitted wave swaps between two states in order to convey a 0 or a 1. Our symbols modulate the transmitted sine wave s phase, so that it moves between in-phase with the SDR s transmitter and 180 degrees (or radians) out of phase with the SDR s transmitter. The difference between a Bit and a Symbol in PACKRAT is not incredibly meaningful, and I ll often find myself slipping up when talking about them. I ve done my best to try and use the right word at the right stage, but it s not as obvious where the line between bit and symbol is at least not as obvious as it would be with QPSK or QAM. The biggest difference is that there are three meaningful states for PACKRAT over BPSK - a 1 (for In phase ), -1 (for 180 degrees out of phase ) and 0 (for no carrier ). For my implementation, a stream of all zeros will not transmit data over the airwaves, a stream of all 1s will transmit all 1 bits over the airwaves, and a stream of all -1s will transmit all 0 bits over the airwaves. We re not going to cover turning a byte (or bit) into a symbol yet I m going to write more about that in a later section. So for now, let s just worry about symbols in, and symbols out.

Transmitting a Sine wave at 0Hz If we go back to thinking about IQ data as a precisely timed measurements of energy over time at some particular specific frequency, we can consider what a sine wave will look like in IQ. Before we dive into antennas and RF, let s go to something a bit more visual. For the first example, you can see an example of a camera who s frame rate (or Sampling Rate!) matches the exact number of rotations per second (or Frequency!) of the propeller and it appears to stand exactly still. Every time the Camera takes a frame, it s catching the propeller in the exact same place in space, even though it s made a complete rotation. The second example is very similar, it s a light strobing (in this case, our sampling rate, since the darkness is ignored by our brains) at the same rate (frequency) as water dropping from a faucet and the video creator is even nice enough to change the sampling frequency to have the droplets move both forward and backward (positive and negative frequency) in comparison to the faucet. IQ works the same way. If we catch something in perfect frequency alignment with our radio, we ll wind up with readings that are the same for the entire stream of data. This means we can transmit a sine wave by setting all of the IQ samples in our buffer to 1+0i, which will transmit a pure sine wave at exactly the center frequency of the radio.
 var sine []complex 
for i := range sine  
sine[i] = complex(1.0, 0.0)
 
Alternatively, we can transmit a Sine wave (but with the opposite phase) by flipping the real value from 1 to -1. The same Sine wave is transmitted on the same Frequency, except when the wave goes high in the example above, the wave will go low in the example below.
 var sine []complex 
for i := range sine  
sine[i] = complex(-1.0, 0.0)
 
In fact, we can make a carrier wave at any phase angle and amplitude by using a bit of trig.
 // angle is in radians - here we have
 // 1.5 Pi (3 Tau) or 270 degrees.
 var angle = pi * 1.5
// amplitude controls the transmitted
 // strength of the carrier wave.
 var amplitude = 1.0
// output buffer as above
 var sine []complex 
for i := range sine  
sine[i] = complex(
amplitude*cos(angle),
amplitude*sin(angle),
)
 
The amplitude of the transmitted wave is the absolute value of the IQ sample (sometimes called magnitude), and the phase can be computed as the angle (or argument). The amplitude remains constant (at 1) in both cases. Remember back to the airplane propeller or water droplets we re controlling where we re observing the sine wave. It looks like a consistent value to us, but in reality it s being transmitted as a pure carrier wave at the provided frequency. Changing the angle of the number we re transmitting will control where in the sine wave cycle we re observing it at.

Generating BPSK modulated IQ data Modulating our carrier wave with our symbols is fairly straightforward to do we can multiply the symbol by 1 to get the real value to be used in the IQ stream. Or, more simply - we can just use the symbol directly in the constructed IQ data.
 var sampleRate = 2,621,440
var baudRate = 1024
// This represents the number of IQ samples
 // required to send a single symbol at the
 // provided baud and sample rate. I picked
 // two numbers in order to avoid half samples.
 // We will transmit each symbol in blocks of
 // this size.
 var samplesPerSymbol = sampleRate / baudRate
var samples = make([]complex, samplesPerSymbol)
// symbol is one of 1, -1 or 0.
 for each symbol in symbols  
for i := range samples  
samples[i] = complex(symbol, 0)
 
// write the samples out to an output file
 // or radio.
 write(samples)
 
If you want to check against a baseline capture, here s 10 example packets at 204800 samples per second.

Next Steps Now that we can transmit data, we ll start working on a receive path in Part 3, in order to check our work when transmitting the packets, as well as being able to hear packets we transmit from afar, coming up next in Part 3!!

Dirk Eddelbuettel: littler 0.3.15 on CRAN: Package Updates

max-heap image The sixteenth release of littler as a CRAN package just landed, following in the now fifteen year history (!!) as a package started by Jeff in 2006, and joined by me a few weeks later. littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only started to do in recent years. littler lives on Linux and Unix, has its difficulties on macOS due to yet-another-braindeadedness there (who ever thought case-insensitive filesystems as a default were a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH. A few examples are highlighted at the Github repo, as well as in the examples vignette. This release brings a more robust and featureful install2.r script (thanks to Gergely Dar czi), corrects some documentation typos (thanks to John Kerl), and now compacts pdf vignette better when using the build.r helper. It also one more updates the URLs for the two RStudio downloaders, and adds a simplermarkdown wrapper. Next, we removed the YAML file (and badge) for the disgraced former continuous integration service we shall not name (yet that we all used to use). And, following digest two days ago and drat yesterday, we converted the vignettes from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style. The full change description follows.

Changes in littler version 0.3.15 (2021-12-03)
  • Changes in examples
    • The install2 script can select download methods, and cope with errors from parallel download (thanks to Gergely Daroczi)
    • The build.r now uses both as argument to --compact-vignettes
    • The RStudio download helper were once again updated for changed URLs
    • New caller for simplermarkdown::mdweave_to_html
  • Changes in package
    • Several typos were correct (thanks to John Kerl)
    • Travis artifacts and badges have been pruned
    • Vignettes now use simplermarkdown

My CRANberries service provides a comparison to the previous release. Full details for the littler release are provided as usual at the ChangeLog page, and also on the package docs website. The code is available via the GitHub repo, from tarballs and now of course also from its CRAN page and via install.packages("littler"). Binary packages are available directly in Debian as well as soon via Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. Comments and suggestions are welcome at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Petter Reinholdtsen: A Brazilian Portuguese translation of the book Made with Creative Commons

A few days ago, a productive translator started working on a new translation of the Made with Creative Commons book for Brazilian Portuguese. The translation take place on the Weblate web based translation system. Once the translation is complete and proof read, we can publish it on paper as well as in PDF, ePub and HTML format. The translation is already 16% complete, and if more people get involved I am conviced it can very quickly reach 100%. If you are interested in helping out with this or other translations of the Made with Creative Commons book, start translating on Weblate. There are partial translations available in Azerbaijani, Bengali, Brazilian Portuguese, Dutch, French, German, Greek, Polish, Simplified Chinese, Swedish, Thai and Ukrainian. The git repository for the book contain all source files needed to build the book for yourself. HTML editions to help with proof reading is also available. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Evgeni Golov: Dependency confusion in the Ansible Galaxy CLI

I hope you enjoyed my last post about Ansible Galaxy Namespaces. In there I noted that I originally looked for something completely different and the namespace takeover was rather accidental. Well, originally I was looking at how the different Ansible content hosting services and their client (ansible-galaxy) behave in regard to clashes in naming of the hosted content. "Ansible content hosting services"?! There are currently three main ways for users to obtain Ansible content:
  • Ansible Galaxy - the original, community oriented, free hosting platform
  • Automation Hub - the place for Red Hat certified and supported content, available only with a Red Hat subscription, hosted by Red Hat
  • Ansible Automation Platform - the on-premise version of Automation Hub, syncs content from there and allows customers to upload own content
Now the question I was curious about was: how would the tooling behave if different sources would offer identically named content? This was inspired by Alex Birsan: Dependency Confusion: How I Hacked Into Apple, Microsoft and Dozens of Other Companies and zofrex: Bundler is Still Vulnerable to Dependency Confusion Attacks (CVE - 2020 - 36327), who showed that the tooling for Python, Node.js and Ruby can be tricked into fetching content from "the wrong source", thus allowing an attacker to inject malicious code into a deployment. For the rest of this article, it's not important that there are different implementations of the hosting services, only that users can configure and use multiple sources at the same time. The problem is that, if the user configures their server_list to contain multiple Galaxy-compatible servers, like Ansible Galaxy and Automation Hub, and then asks to install a collection, the Ansible Galaxy CLI will ask every server in the list, until one returns a successful result. The exact order seems to differ between versions, but this doesn't really matter for the issue at hand. Imagine someone wants to install the redhat.satellite collection from Automation Hub (using ansible-galaxy collection install redhat.satellite). Now if their configuration defines Galaxy as the first, and Automation Hub as the second server, Galaxy is always asked whether it has redhat.satellite and only if the answer is negative, Automation Hub is asked. Today there is no redhat namespace on Galaxy, but there is a redhat user on GitHub, so The canonical answer to this issue is to use a requirements.yml file and setting the source parameter. This parameter allows you to express "regardless which sources are configured, please fetch this collection from here". That's is nice, but I think this not being the default syntax (contrary to what e.g. Bundler does) is a bad approach. Users might overlook the security implications, as the shorter syntax without the source just "magically" works. However, I think this is not even the main problem here. The documentation says: Once a collection is found, any of its requirements are only searched within the same Galaxy instance as the parent collection. The install process will not search for a collection requirement in a different Galaxy instance. But as it turns out, the source behavior was changed and now only applies to the exact collection it is set for, not for any dependencies this collection might have. For the sake of the example, imagine two collections: evgeni.test1 and evgeni.test2, where test2 declares a dependency on test1 in its galaxy.yml. Actually, no need to imagine, both collections are available in version 1.0.0 from galaxy.ansible.com and test1 version 2.0.0 is available from galaxy-dev.ansible.com. Now, given our recent reading of the docs, we craft the following requirements.yml:
collections:
- name: evgeni.test2
  version: '*'
  source: https://galaxy.ansible.com
In a perfect world, following the documentation, this would mean that both collections are fetched from galaxy.ansible.com, right? However, this is not what ansible-galaxy does. It will fetch evgeni.test2 from the specified source, determine it has a dependency on evgeni.test1 and fetch that from the "first" available source from the configuration. Take for example the following ansible.cfg:
[galaxy]
server_list = test_galaxy, release_galaxy, test_galaxy
[galaxy_server.release_galaxy]
url=https://galaxy.ansible.com/
[galaxy_server.test_galaxy]
url=https://galaxy-dev.ansible.com/
And try to install collections, using the above requirements.yml:
% ansible-galaxy collection install -r requirements.yml -vvv                 
ansible-galaxy 2.9.27
  config file = /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg
  configured module search path = ['/home/evgeni/.ansible/plugins/modules', '/usr/share/ansible/plugins/modules']
  ansible python module location = /usr/lib/python3.10/site-packages/ansible
  executable location = /usr/bin/ansible-galaxy
  python version = 3.10.0 (default, Oct  4 2021, 00:00:00) [GCC 11.2.1 20210728 (Red Hat 11.2.1-1)]
Using /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg as config file
Reading requirement file at '/home/evgeni/Devel/ansible-wtf/collections/requirements.yml'
Found installed collection theforeman.foreman:3.0.0 at '/home/evgeni/.ansible/collections/ansible_collections/theforeman/foreman'
Process install dependency map
Processing requirement collection 'evgeni.test2'
Collection 'evgeni.test2' obtained from server explicit_requirement_evgeni.test2 https://galaxy.ansible.com/api/
Opened /home/evgeni/.ansible/galaxy_token
Processing requirement collection 'evgeni.test1' - as dependency of evgeni.test2
Collection 'evgeni.test1' obtained from server test_galaxy https://galaxy-dev.ansible.com/api
Starting collection install process
Installing 'evgeni.test2:1.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test2'
Downloading https://galaxy.ansible.com/download/evgeni-test2-1.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
Installing 'evgeni.test1:2.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test1'
Downloading https://galaxy-dev.ansible.com/download/evgeni-test1-2.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
As you can see, evgeni.test1 is fetched from galaxy-dev.ansible.com, instead of galaxy.ansible.com. Now, if those servers instead would be Galaxy and Automation Hub, and somebody managed to snag the redhat namespace on Galaxy, I would be now getting the wrong stuff Another problematic setup would be with Galaxy and on-prem Ansible Automation Platform, as you can have any namespace on the later and these most certainly can clash with namespaces on public Galaxy. I have reported this behavior to Ansible Security on 2021-08-26, giving a 90 days disclosure deadline, which expired on 2021-11-24. So far, the response was that this is working as designed, to allow cross-source dependencies (e.g. a private collection referring to one on Galaxy) and there is an issue to update the docs to match the code. If users want to explicitly pin sources, they are supposed to name all dependencies and their sources in requirements.yml. Alternatively they obviously can configure only one source in the configuration and always mirror all dependencies. I am not happy with this and I think this is terrible UX, explicitly inviting people to make mistakes.

2 December 2021

Jonathan McDowell: Building a desktop to improve my work/life balance

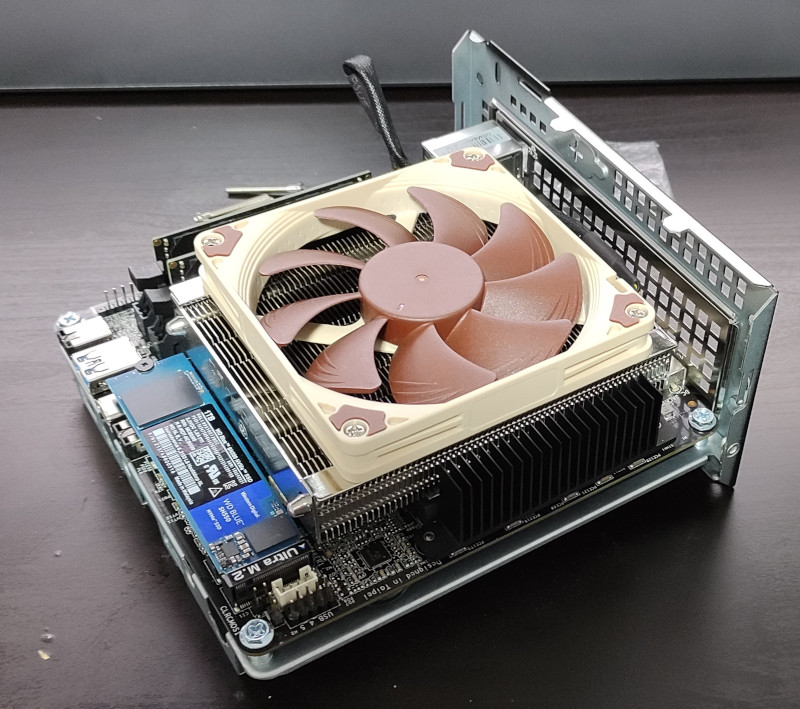
ASRock DeskMini X300 It s been over 20 months since the first COVID lockdown kicked in here in Northern Ireland and I started working from home. Even when the strict lockdown was lifted the advice here has continued to be If you can work from home you should work from home . I ve been into the office here and there (for new starts given you need to hand over a laptop and sort out some login details it s generally easier to do so in person, and I ve had a couple of whiteboard sessions that needed the high bandwidth face to face communication), but day to day is all from home. Early on I commented that work had taken over my study. This has largely continued to be true. I set my work laptop on the stand on a Monday morning and it sits there until Friday evening, when it gets switched for the personal laptop. I have a lovely LG 34UM88 21:9 Ultrawide monitor, and my laptops are small and light so I much prefer to use them docked. Also my general working pattern is to have a lot of external connections up and running (build machine, test devices, log host) which means a suspend/resume cycle disrupts things. So I like to minimise moving things about. I spent a little bit of time trying to find a dual laptop stand so I could have both machines setup and switch between them easily, but I didn t find anything that didn t seem to be geared up for DJs with a mixer + laptop combo taking up quite a bit of desk space rather than stacking laptops vertically. Eventually I realised that the right move was probably a desktop machine. Now, I haven t had a desktop machine since before I moved to the US, realising at the time that having everything on my laptop was much more convenient. I decided I didn t want something too big and noisy. Cheap GPUs seem hard to get hold of these days - I m not a gamer so all I need is something that can drive a ~ 4K monitor reliably enough. Looking around the AMD Ryzen 7 5700G seemed to be a decent CPU with one of the better integrated GPUs. I spent some time looking for a reasonable Mini-ITX case + motherboard and then I happened upon the ASRock DeskMini X300. This turns out to be perfect; I ve no need for a PCIe slot or anything more than an m.2 SSD. I paired it with a Noctua NH-L9a-AM4 heatsink + fan (same as I use in the house server), 32GB DDR4 and a 1TB WD SN550 NVMe SSD. Total cost just under 650 inc VAT + delivery (and that s a story for another post). A desktop solves the problem of fitting both machines on the desk at once, but there s still the question of smoothly switching between them. I read Evgeni Golov s article on a simple KVM switch for 30. My monitor has multiple inputs, so that s sorted. I did have a cheap USB2 switch (all I need for the keyboard/trackball) but it turned out to be pretty unreliable at the host detecting the USB change. I bought a UGREEN USB 3.0 Sharing Switch Box instead and it s turned out to be pretty reliable. The problem is that the LG 32UM88 turns out to have a poor DDC implementation, so while I can flip the keyboard easily with the UGREEN box I also have to manually select the monitor input. Which is a bit annoying, but not terrible. The important question is whether this has helped. I built all this at the end of October, so I ve had a month to play with it. Turns out I should have done it at some point last year. At the end of the day instead of either sitting at work for a bit longer, or completely avoiding the study, I m able to lock the work machine and flick to my personal setup. Even sitting in the same seat that disconnect , and the knowledge I won t see work Slack messages or emails come in and feeling I should respond, really helps. It also means I have access to my personal setup during the week without incurring a hit at the start of the working day when I have to set things up again. So it s much easier to just dip in to some personal tech stuff in the evening than it was previously. Also from the point of view I don t need to setup the personal config, I can pick up where I left off. All of which is really nice. It s also got me thinking about other minor improvements I should make to my home working environment to try and improve things. One obvious thing now the winter is here again is to improve my lighting; I have a good overhead LED panel but it s terribly positioned for video calls, being just behind me. So I think I m looking some sort of strip light I can have behind the large monitor to give a decent degree of backlight (possibly bouncing off the white wall). Lots of cheap options I m not convinced about, and I ve had a few ridiculously priced options from photographer friends; suggestions welcome.
Paul Tagliamonte: Processing IQ data formats (Part 1/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
When working with SDRs, information about the signals your radio is receiving are communicated by streams of IQ data. IQ is short for In-phase and Quadrature , which means 90 degrees out of phase. Values in the IQ stream are complex numbers, so converting them to a native complex type in your language helps greatly when processing the IQ data for meaning. I won t get too deep into what IQ is or why complex numbers (mostly since I don t think I fully understand it well enough to explain it yet), but here s some basics in case this is your first interaction with IQ data before going off and reading more.
Before we get started at any point, if you feel lost in this post, it's OK to take a break to do a bit of learning elsewhere in the internet. I'm still new to this, so I'm sure my overview in one paragraph here won't help clarify things too much. This took me months to sort out on my own. It's not you, really! I particularly enjoyed reading visual-dsp.switchb.org when it came to learning about how IQ represents signals, and Software-Defined Radio for Engineers for a more general reference.
Each value in the stream is taken at a precisely spaced sampling interval (called the sampling rate of the radio). Jitter in that sampling interval, or a drift in the requested and actual sampling rate (usually represented in PPM, or parts per million how many samples out of one million are missing) can cause errors in frequency. In the case of a PPM error, one radio may think it s 100.1MHz and the other may think it s 100.2MHz, and jitter will result in added noise in the resulting stream. A single IQ sample is both the real and imaginary values, together. The complex number (both parts) is the sample. The number of samples per second is the number of real and imaginary value pairs per second. Each sample is reading the electrical energy coming off the antenna at that exact time instant. We re looking to see how that goes up and down over time to determine what frequencies we re observing around us. If the IQ stream is only real-valued measures (e.g., float values rather than complex values reading voltage from a wire), you can still send and receive signals, but those signals will be mirrored across your 0Hz boundary. That means if you re tuned to 100MHz, and you have a nearby transmitter at 99.9MHz, you d see it at 100.1MHz. If you want to get an intuitive understanding of this concept before getting into the heavy math, a good place to start is looking at how Quadrature encoders work. Using complex numbers means we can see up in frequency as well as down in frequency, and understand that those are different signals. The reason why we need negative frequencies is that our 0Hz is the center of our SDR s tuned frequency, not actually at 0Hz in nature. Generally speaking, it s doing loads in hardware (and firmware!) to mix the raw RF signals with a local oscillator to a frequency that can be sampled at the requested rate (fundamentally the same concept as a superheterodyne receiver), so a frequency of -10MHz means that signal is 10 MHz below the center of our SDR s tuned frequency. The sampling rate dictates the amount of frequency representable in the data stream. You ll sometimes see this called the Nyquist frequency. The Nyquist Frequency is one half of the sampling rate. Intuitively, if you think about the amount of bandwidth observable as being 1:1 with the sampling rate of the stream, and the middle of your bandwidth is 0 Hz, you would only have enough space to go up in frequency for half of your bandwidth or half of your sampling rate. Same for going down in frequency.

Float 32 / Complex 64 IQ samples that are being processed by software are commonly processed as an interleaved pair of 32 bit floating point numbers, or a 64 bit complex number. The first float32 is the real value, and the second is the imaginary value.
I#0
Q#0
I#1
Q#1
I#2
Q#2
The complex number 1+1i is represented as 1.0 1.0 and the complex number -1-1i is represented as -1.0 -1.0. Unless otherwise specified, all the IQ samples and pseudocode to follow assumes interleaved float32 IQ data streams. Example interleaved float32 file (10Hz Wave at 1024 Samples per Second)

RTL-SDR IQ samples from the RTL-SDR are encoded as a stream of interleaved unsigned 8 bit integers (uint8 or u8). The first sample is the real (in-phase or I) value, and the second is the imaginary (quadrature or Q) value. Together each pair of values makes up a complex number at a specific time instant.
I#0
Q#0
I#1
Q#1
I#2
Q#2
The complex number 1+1i is represented as 0xFF 0xFF and the complex number -1-1i is represented as 0x00 0x00. The complex number 0+0i is not easily representable since half of 0xFF is 127.5.
Complex Number Representation
1+1i []uint8 0xFF, 0xFF
-1+1i []uint8 0x00, 0xFF
-1-1i []uint8 0x00, 0x00
0+0i []uint8 0x80, 0x80 or []uint8 0x7F, 0x7F
And finally, here s some pseudocode to convert an rtl-sdr style IQ sample to a floating point complex number:
...
in = []uint8 0x7F, 0x7F 
real = (float(iq[0])-127.5)/127.5
imag = (float(iq[1])-127.5)/127.5
out = complex(real, imag)
....
Example interleaved uint8 file (10Hz Wave at 1024 Samples per Second)

HackRF IQ samples from the HackRF are encoded as a stream of interleaved signed 8 bit integers (int8 or i8). The first sample is the real (in-phase or I) value, and the second is the imaginary (quadrature or Q) value. Together each pair of values makes up a complex number at a specific time instant.
I#0
Q#0
I#1
Q#1
I#2
Q#2
Formats that use signed integers do have one quirk due to two s complement, which is that the smallest negative number representable s absolute value is one more than the largest positive number. int8 values can range between -128 to 127, which means there s bit of ambiguity in how +1, 0 and -1 are represented. Either you can create perfectly symmetric ranges of values between +1 and -1, but 0 is not representable, have more possible values in the negative range, or allow values above (or just below) the maximum in the range to be allowed. Within my implementation, my approach has been to scale based on the max integer value of the type, so the lowest possible signed value is actually slightly smaller than -1. Generally, if your code is seeing values that low the difference in step between -1 and slightly less than -1 isn t very significant, even with only 8 bits. Just a curiosity to be aware of.
Complex Number Representation
1+1i []int8 127, 127
-1+1i []int8 -128, 127
-1-1i []int8 -128, -128
0+0i []int8 0, 0
And finally, here s some pseudocode to convert a hackrf style IQ sample to a floating point complex number:
...
in = []int8 -5, 112 
real = (float(in[0]))/127
imag = (float(in[1]))/127
out = complex(real, imag)
....
Example interleaved int8 file (10Hz Wave at 1024 Samples per Second)

PlutoSDR IQ samples from the PlutoSDR are encoded as a stream of interleaved signed 16 bit integers (int16 or i16). The first sample is the real (in-phase or I) value, and the second is the imaginary (quadrature or Q) value. Together each pair of values makes up a complex number at a specific time instant. Almost no SDRs capture at a 16 bit depth natively, often you ll see 12 bit integers (as is the case with the PlutoSDR) being sent around as 16 bit integers. This leads to the next possible question, which is are values LSB or MSB aligned? The PlutoSDR sends data LSB aligned (which is to say, the largest real or imaginary value in the stream will not exceed 4095), but expects data being transmitted to be MSB aligned (which is to say the lowest set bit possible is the 5th bit in the number, or values can only be set in increments of 16). As a result, the quirk observed with the HackRF (that the range of values between 0 and -1 is different than the range of values between 0 and +1) does not impact us so long as we do not use the whole 16 bit range.
Complex Number Representation
1+1i []int16 32767, 32767
-1+1i []int16 -32768, 32767
-1-1i []int16 -32768, -32768
0+0i []int16 0, 0
And finally, here s some pseudocode to convert a PlutoSDR style IQ sample to a floating point complex number, including moving the sample from LSB to MSB aligned:
...
in = []int16 -15072, 496 
// shift left 4 bits (16 bits - 12 bits = 4 bits)
 // to move from LSB aligned to MSB aligned.
 in[0] = in[0] << 4
in[1] = in[1] << 4
real = (float(in[0]))/32767
imag = (float(in[1]))/32767
out = complex(real, imag)
....
Example interleaved i16 file (10Hz Wave at 1024 Samples per Second)

Next Steps Now that we can read (and write!) IQ data, we can get started first on the transmitter, which we can (in turn) use to test receiving our own BPSK signal, coming next in Part 2!

Paul Tagliamonte: Intro to PACKRAT (Part 0/5)

Hello! Welcome. I m so thrilled you re here. Some of you may know this (as I ve written about in the past), but if you re new to my RF travels, I ve spent nights and weekends over the last two years doing some self directed learning on how radios work. I ve gone from a very basic understanding of wireless communications, all the way through the process of learning about and implementing a set of libraries to modulate and demodulate data using my now formidable stash of SDRs. I ve been implementing all of the RF processing code from first principals and purely based on other primitives I ve written myself to prove to myself that I understand each concept before moving on. I ve just finished a large personal milestone I was able to successfully send a cURL HTTP request through a network interface into my stack of libraries, through my own BPSK implementation, framed in my own artisanal hand crafted Layer 2 framing scheme, demodulated by my code on the other end, and sent into a Linux network interface. The combination of the Layer 1 PHY and Layer 2 Data Link is something that I ve been calling PACKRAT .
$ curl http://44.127.0.8:8000/
* Connected to 44.127.0.8 (44.127.0.8) port 8000 (#0)
> GET / HTTP/1.1
> Host: localhost:1313
> User-Agent: curl/7.79.1
> Accept: */*
>
* Mark bundle as not supporting multiuse
* HTTP/1.0, assume close after body
< HTTP/1.0 200 OK
< Content-Length: 236
<
____ _ ____ _ ______ _ _____
  _ \ / \ / ___   / / _ \ / \ _ _ 
   _) / _ \      ' /   _)   / _ \    
  __/ ___ \  ___  . \  _ < / ___ \   
 _  /_/ \_\____ _ \_\_  \_\/_/ \_\_ 
* Closing connection 0
In an effort to pay it forward to thank my friends for their time walking me through huge chunks of this, and those who publish their work, I m now spending some time documenting how I was able to implement this protocol. I would never have gotten as far as I did without the incredible patience and kindness of friends spending time working with me, and educators publishing their hard work for the world to learn from. Please accept my deepest thanks and appreciation. The PACKRAT posts are written from the perspective of a novice radio engineer, but experienced software engineer. I ll be leaving out a lot of the technical details on the software end and specific software implementation, focusing on the general gist of the implementation in the radio critical components exclusively. The idea here is this is intended to be a framework a jumping off point for those who are interested in doing this themselves. I hope that this series of blog posts will come to be useful to those who embark on this incredibly rewarding journey after me. This is the first post in the series, and it will contain links to all the posts to follow. This is going to be the landing page I link others to as I publish additional posts, I ll be updating the links on this page. The posts will also grow a tag, which you can check back on, or follow along with here.

Tau Tau ( ) is a much more natural expression of the mathematical constant used for circles which I use rather than Pi ( ). You may see me use Tau in code or text Tau is the same as 2 , so if you see a Tau and don t know what to do, feel free to mentally or textually replace it with 2 . I just hate always writing 2 everywhere and only using (or worse yet 2 /2) .when I mean 1/2 of a circle (or, /2).

Psuedo-code Basicaly none of the code contained in this series is valid on its own. It s very lightly basically Go, and only meant to express concepts in term of software. The examples in the post shouldn t be taken on their own as working snippits to process IQ data, but rather, be used to guide implementations to process the data in question. I d love to invite all readers to try to play at home with the examples, and try and work through the example data captures!

Captures Speaking of captures, I ve included live on-the-air captures of PACKRAT packets, as transmitted from my implementation, in different parts of these posts. This means you can go through the process of building code to parse and receive PACKRAT packets, and then build a transmitter that is validated by your receiver. It s my hope folks will follow along at home and experiment with software to process RF data on their own!

Posts in this series

Dirk Eddelbuettel: drat 0.2.2 on CRAN: Package Maintenance

drat user A fresh and new minor release of drat arrived on CRAN overnight. This is another small update relative to the 0.2.0 release in April followed by a 0.2.1 update in July. This release follows the changes made in digest yesterday. We removed the YAML file (and badge) for the disgraced former continuous integration service we shall not name (yet that we all used to use). And we converted the vignette from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style. drat stands for drat R Archive Template, and helps with easy-to-create and easy-to-use repositories for R packages. Since its inception in early 2015 it has found reasonably widespread adoption among R users because repositories with marked releases is the better way to distribute code. See below for a few custom reference examples. Because for once it really is as your mother told you: Friends don t let friends install random git commit snapshots. Properly rolled-up releases it is. Just how CRAN shows us: a model that has demonstrated for two-plus decades how to do this. And you can too: drat is easy to use, documented by six vignettes and just works. Detailed information about drat is at its documentation site. The NEWS file summarises the release as follows:

Changes in drat version 0.2.2 (2021-12-01)
  • Travis artifacts and badges have been pruned
  • Vignettes now use simplermarkdown

Courtesy of my CRANberries, there is a comparison to the previous release. More detailed information is on the drat page as well as at the documentation site. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 December 2021

Thorsten Alteholz: My Debian Activities in November 2021

FTP master This month I accepted 564 and rejected 93 packages. The overall number of packages that got accepted was 591. Debian LTS This was my eighty-ninth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 40h. During that time I did LTS and normal security uploads of: I also started to work on pgbouncer to get an update for each release and had to process packages from NEW on security-master. Further I worked on a script to automatically publish DLAs on the Debian website, that are posted to debian-lts-announce. The script can be found on salsa. It only publishes stuff from people on a whitelist. At the moment it is running on a computer at home. You might run your own copy, or just send me an email to be put on the whitelist as well. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the forty-first ELTS month. During my allocated time I uploaded: Last but not least I did some days of frontdesk duties. Debian Printing Unfortunately I did not do as much as I wanted this month. At least I looked at some old bugs and uploaded new upstream versions of I hope this will improve in December again. New versions of cups and hplip are on my TODO-list. Debian Astro This month I uploaded new versions of Other stuff I improved packaging or fixed bugs of:

Dirk Eddelbuettel: digest 0.6.29 on CRAN: Package Maintenance

Release 0.6.29 of the digest package arrived at CRAN earlier today, and will be uploaded Debian shortly. digest creates hash digests of arbitrary R objects (using the md5, sha-1, sha-256, sha-512, crc32, xxhash32, xxhash64, murmur32, spookyhash, and blake3 algorithms) permitting easy comparison of R language objects. It is a mature and widely-used as many tasks may involve caching of objects for which it provides convenient general-purpose hash key generation. This release only contains two smaller internal changes. We removed the YAML file (and badge) for the disgraced former continuous integration service we shall not name (yet that we all used to use). And we converted the vignette from using the minidown package to the (fairly new) simplermarkdown package which is so much more appropriate for our use of the minimal water.css style. My CRANberries provides the usual summary of changes to the previous version. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Utkarsh Gupta: FOSS Activites in December 2021

Here s my (twenty-sixth) monthly but brief update about the activities I ve done in the F/L/OSS world.

Debian
This was my 35th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Just churning through the backlog again this month. Ugh. Anyway, I did the following stuff in Debian:

Uploads and bug fixes:
  • rails (2:6.1.4.1+dfsg-3) - No-change rebuild for unstable.

Other $things:
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
This was my 10th month of actively contributing to Ubuntu. Now that I ve joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ I mostly worked on different things, I guess. I was too lazy to maintain a list of things I worked on so there s no concrete list atm. Maybe I ll get back to this section later or will start to list stuff from next year onward, as I was doing before. :D

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twenty-sixth month as a Debian LTS and seventeenth month as a Debian ELTS paid contributor.
I was assigned 30.00 hours for LTS and 45.00 hours for ELTS and worked on the following things:

LTS CVE Fixes and Announcements:
  • Issued DLA 2813-1, fixing CVE-2021-33829 and CVE-2021-37695, for ckeditor.
    For Debian 9 stretch, these problems have been fixed in version 4.5.7+dfsg-2+deb9u1.
  • Issued DLA 2817-1, fixing CVE-2021-23214 and CVE-2021-23222, for postgresql-9.6.
    For Debian 9 stretch, these problems have been fixed in version 9.6.24-0+deb9u1.
  • Issued DLA 2836-1, fixing CVE-2021-43527, for nss.
    For Debian 9 stretch, these problems have been fixed in version 2:3.26.2-1.1+deb9u3.
  • Started working on src:samba for CVE-2020-25717 to CVE-2020-25722 and CVE-2021-23192 for jessie and stretch, both.
    The version difference b/w the suites are a bit too much for the patch(es) to be easily backported. I ve talked to Anton to work something out. \o/
  • Found the problem w/ libjdom1-java. Will have to roll the regression upload.
    I ve prepared the patch but needs some testing to be finally rolled out. Same for jessie.
  • Started working on libgit2.

ELTS CVE Fixes and Announcements:

Other (E)LTS Work:
  • Front-desk duty from 29-11 to 05-12 for both LTS and ELTS.
  • Triaged udisk2, wordpress, samba, gmp, nss, ntfs-3g, and openssh.
  • Auto EOL ed dwarfutils, radare2, mongodb, linux for jessie.
  • As FD, did a deep dive into the no-pu-update issue. Will write to list shortly.
  • Attended monthly Debian LTS meeting.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Debian LTS Survey I ve spent 3 hours on the LTS survey on the following bits:
  • Talking to Laura to revive the old a/c on survey.d.net.
  • Setting up stuff there.
  • Discussing the survey questions and other bits w/ Jeremiah.
  • Partly reviewing the questions of the survey.
  • Doing a walkthru of the LimeSurvey instance we have to make sure there are no changes .

Until next time.
:wq for today.

Russ Allbery: Review: A World Without Email

Review: A World Without Email, by Cal Newport
Publisher: Portfolio/Penguin
Copyright: 2021
ISBN: 0-525-53657-4
Format: Kindle
Pages: 264
A World Without Email is the latest book by computer science professor and productivity writer Cal Newport. After a detour to comment on the drawbacks of social media in Digital Minimalism, Newport is back to writing about focus and concentration in the vein of Deep Work. This time, though, the topic is workplace structure and collaborative process rather than personal decisions. This book is a bit hard for me to review because I spoiled myself for the contents by listening to a lot of Newport's podcast, where he covers the same material. I therefore didn't enjoy it as much as I otherwise would have because the ideas were familiar. I recommend the book over the podcast, though; it's tighter, more coherent, and more comprehensive. The core contention of this book is that knowledge work (roughly, jobs where one spends significant time working on a computer processing information) has stumbled into a superficially tempting but inefficient and psychologically harmful structure that Newport calls the hyperactive hive mind. This way of organizing work is a local maxima: it feels productive, it's flexible and very easy to deploy, and most minor changes away from it make overall productivity worse. However, the incentive structure is all wrong. It prioritizes quick responses and coordination overhead over deep thinking and difficult accomplishments. The characteristic property of the hyperactive hive mind is free-flowing, unstructured communication between co-workers. If you need something from someone else, you ask them for it and they send it to you. The "email" in the title is not intended literally; Slack and related instant messaging apps are even more deeply entrenched in the hyperactive hive mind than email is. The key property of this workflow is that most collaborative work is done by contacting other people directly via ad hoc, unstructured messages. Newport's argument is that this workflow has multiple serious problems, not the least of which is that it makes us miserable. If you have read his previous work, you will correctly expect this to tie into his concept of deep work. Ad hoc, unstructured communication creates a constant barrage of unimportant small tasks and interrupts, most of which require several asynchronous exchanges before your brain can stop tracking the task. This creates constant context-shifting, loss of focus and competence, and background stress from ever-growing email inboxes, unread message notifications, and the semi-frantic feeling that you're forgetting something you need to do. This is not an original observation, of course. Many authors have suggested individual ways to improve this workflow: rules about how often to check one's email, filtering approaches, task managers, and other personal systems. Newport's argument is that none of these individual approaches can address the problem due to social effects. It's all well and good to say that you should unplug from distractions and ignore requests while you concentrate, but everyone else's workflow assumes that their co-workers are responsive to ad hoc requests. Ignoring this social contract makes the job of everyone still stuck in the hyperactive hive mind harder. They won't appreciate that, and your brain will not be able to relax knowing that you're not meeting your colleagues' expectations. In Newport's analysis, the necessary solution is a comprehensive redesign of how we do knowledge work, akin to the redesign of factory work that came with the assembly line. It's a collective problem that requires a collective solution. In other industries, organizing work for efficiency and quality is central to the job of management, but in knowledge work (for good historical reasons) employees are mostly left to organize their work on their own. That self-organization has produced a system that doesn't require centralized coordination or decisions and provides a lot of superficial flexibility, but which may be significantly inferior to a system designed for how people think and work. Even if you find this convincing (and I think Newport makes a good case), there are reasons to be suspicious of corporations trying to make people more productive. The assembly line made manufacturing much more efficient, but it also increased the misery of workers so much that Henry Ford had to offer substantial raises to retain workers. As one of Newport's knowledge workers, I'm not enthused about that happening to my job. Newport recognizes this and tries to address it by drawing a distinction between the workflow (how information moves between workers) and the work itself (how individual workers solve problems in their area of expertise). He argues that companies need to redesign the former, but should leave the latter to each worker. It's a nice idea, and it will probably work in industries like tech with substantial labor bargaining power. I'm more cynical about other industries. The second half of the book is Newport's specific principles and recommendations for designing better workflows that don't rely on unstructured email. Some of this will be familiar (and underwhelming) to anyone who works in tech; Newport recommends ticket systems and thinks agile, scrum, and kanban are pointed in the right direction. But there are some other good ideas in here, such as embracing specialization. Newport argues (with some evidence) that the drastic reduction in secretarial jobs, on the grounds that workers with computers can do the same work themselves, was a mistake. Even with new automation, this approach increased the range of tasks required in every other job. Not only was this a drain on the time of other workers, it caused more context switching, which made everyone less efficient and undermined work quality. He argues for reversing that trend: where the work cannot be automated, hire more support workers and more specialized workers in general, stop expecting everyone to be their own generalist admin, and empower support workers to create better systems rather than using the hyperactive hive mind model to answer requests. There's more here, ranging from specifics of how to develop a structured process for a type of work to the importance of enabling sustained concentration on a task. It's a less immediately actionable book than Newport's previous writing, but I welcome the partial shift in focus to more systemic issues. Newport continues to be relentlessly apolitical, but here it feels less like he's eliding important analysis and more like he thinks the interests of workers and good employers are both served by the approach he's advocating. I will warn that Newport leans heavily on evolutionary psychology in his argument that the hyperactive hive mind is bad for us. I think he has some good arguments about the anxiety that comes with not responding to requests from others, but I'm not sure intrusive experiments on spectacularly-unusual remnant hunter-gatherer groups, who are treated like experimental animals, are the best way of making that case. I realize this isn't Newport's research, but I think he could have made his point with more directly relevant experiments. He also continues his obsession with the superiority of in-person conversation over written communication, and while he has a few good arguments, he has a tendency to turn them into sweeping generalizations that are directly contradicted by, well, my entire life. It would be nice if he were more willing to acknowledge that it's possible to express deep emotional nuance and complex social signaling in writing; it simply requires a level of practice and familiarity (and shared vocabulary) that's often missing from the workplace. I was muttering a lot near the start of this book, but thankfully those sections are short, and I think the rest of his argument sits on a stronger foundation. I hope Newport continues moving in the direction of more systemic analysis. If you enjoyed Deep Work, you will probably find A World Without Email interesting. If you're new to Newport, this is not a bad place to start, particularly if you have influence on how communication is organized in your workplace. Those who work in tech will find some bits of this less interesting, but Newport approaches the topic from a different angle than most agile books and covers a broader range if ideas. Recommended if you like reading this sort of thing. Rating: 7 out of 10

Paul Wise: FLOSS Activities November 2021

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review

Administration
  • Debian BTS: unarchive/reopen/triage bugs for reintroduced packages
  • Debian wiki: unblock IP addresses, approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The SPTAG, visdom, gensim, purple-discord, plac, fail2ban, uvloop work was sponsored by my employer. All other work was done on a volunteer basis.

30 November 2021

Russell Coker: Links November 2021

The Guardian has an amusing article by Sophie Elmhirst about Libertarians buying a cruise ship to make a seasteading project off the coast of Panama [1]. It turns out that you need permits etc to do this and maintaining a ship is expensive. Also you wouldn t want to mine cryptocurrency in a ship cabin as most cabins are small and don t have enough airconditioning to remain pleasant if you dump 1kW or more into the air. NPR has an interesting article about the reaction of the NRA to the Columbine shootings [2]. Seems that some NRA person isn t a total asshole and is sharing their private information, maybe they are dying and are worried about going to hell. David Brin wrote an insightful blog post about the singleton hypothesis where he covers some of the evidence of autocratic societies failing [3]. I think he makes a convincing point about a single centralised government for human society not being viable. But something like the EU on a world wide scale could work well. Ken Shirriff wrote an interesting blog post about reverse engineering the Yamaha DX7 synthesiser [4]. The New York Times has an interesting article about a Baboon troop that became less aggressive after the alpha males all died at once from tuberculosis [5]. They established a new more peaceful culture that has outlived the beta males who avoided tuberculosis. The Guardian has an interesting article about how sequencing the genomes of the entire population can save healthcare costs while improving the health of the population [6]. This is somthing wealthy countries should offer for free to the world population. At a bit under $1000 per test that s only about $7 trillion to test everyone, and of course the price should drop significantly if there were billions of tests being done. The Strategy Bridge has an interesting article about SciFi books that have useful portrayals of military strategy [7]. The co-author is Major General Mick Ryan of the Australian Army which is noteworthy as Major General is the second highest rank in use by the Australian Army at this time. Vice has an interesting article about the co-evolution of penises and vaginas and how a lot of that evolution is based on avoiding impregnation from rape [8]. Cory Doctorow wrote an insightful Medium article about the way that governments could force interoperability through purchasing power [9]. Cory Doctorow wrote an insightful article for Locus Magazine about imagining life after capitalism and how capitalism might be replaced [10]. We need a Star Trek future! Arstechnica has an informative article about new developmenet in the rowhammer category of security attacks on DRAM [11]. It seems that DDR4 with ECC is the best current mitigation technique and that DDR3 with ECC is harder to attack than non-ECC RAM. So the thing to do is use ECC on all workstations and avoid doing security critical things on laptops because they can t juse ECC RAM.

Russell Coker: Your Device Has Been Improved

I ve just started a Samsung tablet downloading a 770MB update, the description says:
Technically I have no doubt that both those claims are true and accurate. But according to common understanding of the English language I think they are both misleading. By stability improved they mean fixed some bugs that made it unstable and no technical person would imagine that after a certain number of such updates the number of bugs will ever reach zero and the tablet will be perfectly reliable. In fact if you should consider yourself lucky if they fix more bugs than they add. It s not THAT uncommon for phones and tablets to be bricked (rendered unusable by software) by an update. In the past I got a Huawei Mate9 as a warranty replacement for a Nexus 6P because an update caused so many Nexus 6P phones to fail that they couldn t be replaced with an identical phone [1]. By security improved they usually mean fixed some security flaws that were recently discovered to make it almost as secure as it was designed to be . Note that I deliberately say almost as secure because it s sometimes impossible to fix a security flaw without making significant changes to interfaces which requires more work than desired for an old product and also gives a higher probability of things going wrong. So it s sometimes better to aim for almost as secure or alternatively just as secure but with some features disabled. Device manufacturers (and most companies in the Android space make the same claims while having the exact same bugs to deal with, Samsung is no different from the others in this regards) are not making devices more secure or more reliable than when they were initially released. They are aiming to make them almost as secure and reliable as when they were released. They don t have much incentive to try too hard in this regard, Samsung won t suffer if I decide my old tablet isn t reliable enough and buy a new one, which will almost certainly be from Samsung because they make nice tablets. As a thought experiment, consider if car repairers did the same thing. Getting us to service your car will improve fuel efficiency , great how much more efficient will it be than when I purchased it? As another thought experiment, consider if car companies stopped providing parts for car repair a few years after releasing a new model. This is effectively what phone and tablet manufacturers have been doing all along, software updates for stability and security are to devices what changing oil etc is for cars.

29 November 2021

Evgeni Golov: Getting access to somebody else's Ansible Galaxy namespace

TL;DR: adding features after the fact is hard, normalizing names is hard, it's patched, carry on. I promise, the longer version is more interesting and fun to read! Recently, I was poking around Ansible Galaxy and almost accidentally got access to someone else's namespace. I was actually looking for something completely different, but accidental finds are the best ones! If you're asking yourself: "what the heck is he talking about?!", let's slow down for a moment:
  • Ansible is a great automation engine built around the concept of modules that do things (mostly written in Python) and playbooks (mostly written in YAML) that tell which things to do
  • Ansible Galaxy is a place where people can share their playbooks and modules for others to reuse
  • Galaxy Namespaces are a way to allow users to distinguish who published what and reduce name clashes to a minimum
That means that if I ever want to share how to automate installing vim, I can publish evgeni.vim on Galaxy and other people can download that and use it. And if my evil twin wants their vim recipe published, it will end up being called evilme.vim. Thus while both recipes are called vim they can coexist, can be downloaded to the same machine, and used independently. How do you get a namespace? It's automatically created for you when you login for the first time. After that you can manage it, you can upload content, allow others to upload content and other things. You can also request additional namespaces, this is useful if you want one for an Organization or similar entities, which don't have a login for Galaxy. Apropos login, Galaxy uses GitHub for authentication, so you don't have to store yet another password, just smash that octocat! Did anyone actually click on those links above? If you did (you didn't, right?), you might have noticed another section in that document: Namespace Limitations. That says:
Namespace names in Galaxy are limited to lowercase word characters (i.e., a-z, 0-9) and _ , must have a minimum length of 2 characters, and cannot start with an _ . No other characters are allowed, including . , - , and space. The first time you log into Galaxy, the server will create a Namespace for you, if one does not already exist, by converting your username to lowercase, and replacing any - characters with _ .
For my login evgeni this is pretty boring, as the generated namespace is also evgeni. But for the GitHub user Evil-Pwnwil-666 it will become evil_pwnwil_666. This can be a bit confusing. Another confusing thing is that Galaxy supports two types of content: roles and collections, but namespaces are only for collections! So it is Evil-Pwnwil-666.vim if it's a role, but evil_pwnwil_666.vim if it's a collection. I think part of this split is because collections were added much later and have a much more well thought design of both the artifact itself and its delivery mechanisms. This is by the way very important for us! Due to the fact that collections (and namespaces!) were added later, there must be code that ensures that users who were created before also get a namespace. Galaxy does this (and I would have done it the same way) by hooking into the login process, and after the user is logged in it checks if a Namespace exists and if not it creates one and sets proper permissions. And this is also exactly where the issue was! The old code looked like this:
    # Create lowercase namespace if case insensitive search does not find match
    qs = models.Namespace.objects.filter(
        name__iexact=sanitized_username).order_by('name')
    if qs.exists():
        namespace = qs[0]
    else:
        namespace = models.Namespace.objects.create(**ns_defaults)
    namespace.owners.add(user)
See how namespace.owners.add is always called? Even if the namespace already existed? Yepp! But how can we exploit that? Any user either already has a namespace (and owns it) or doesn't have one that could be owned. And given users are tied to GitHub accounts, there is no way to confuse Galaxy here. Now, remember how I said one could request additional namespaces, for organizations and stuff? Those will have owners, but the namespace name might not correspond to an existing user! So all we need is to find an existing Galaxy namespace that is not a "default" namespace (aka a specially requested one) and get a GitHub account that (after the funny name conversion) matches the namespace name. Thankfully Galaxy has an API, so I could dump all existing namespaces and their owners. Next I filtered that list to have only namespaces where the owner list doesn't contain a username that would (after conversion) match the namespace name. I found a few. And for one of them (let's call it the_target), the corresponding GitHub username (the-target) was available! Jackpot! I've registered a new GitHub account with that name, logged in to Galaxy and had access to the previously found namespace. This felt like sufficient proof that my attack worked and I mailed my findings to the Ansible Security team. The issue was fixed in d4f84d3400f887a26a9032687a06dd263029bde3 by moving the namespace.owners.add call to the "new namespace" branch. And this concludes the story of how I accidentally got access to someone else's Galaxy namespace (which was revoked after the report, no worries).

Next.

Previous.