Search Results: "xam"

5 February 2025

Reproducible Builds: Reproducible Builds in January 2025
Welcome to the first report in 2025 from the Reproducible Builds project! Our monthly reports outline what we ve been up to over the past month and highlight items of news from elsewhere in the world of software supply-chain security when relevant. As usual, though, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. reproduce.debian.net
  2. Two new academic papers
  3. Distribution work
  4. On our mailing list
  5. Upstream patches
  6. diffoscope
  7. Website updates
  8. Reproducibility testing framework

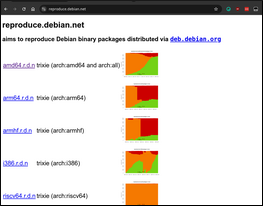
reproduce.debian.net The last few months saw the introduction of reproduce.debian.net. Announced at the recent Debian MiniDebConf in Toulouse, reproduce.debian.net is an instance of rebuilderd operated by the Reproducible Builds project. Powering that is rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, we are pleased to announce that in addition to the existing amd64.reproduce.debian.net and i386.reproduce.debian.net architecture-specific pages, we now build for a three more architectures (for a total of five) arm64 armhf and riscv64.
Two new academic papers Giacomo Benedetti, Oreofe Solarin, Courtney Miller, Greg Tystahl, William Enck, Christian K stner, Alexandros Kapravelos, Alessio Merlo and Luca Verderame published an interesting article recently. Titled An Empirical Study on Reproducible Packaging in Open-Source Ecosystem, the abstract outlines its optimistic findings:
[We] identified that with relatively straightforward infrastructure configuration and patching of build tools, we can achieve very high rates of reproducible builds in all studied ecosystems. We conclude that if the ecosystems adopt our suggestions, the build process of published packages can be independently confirmed for nearly all packages without individual developer actions, and doing so will prevent significant future software supply chain attacks.
The entire PDF is available online to view.
In addition, Julien Malka, Stefano Zacchiroli and Th o Zimmermann of T l com Paris in-house research laboratory, the Information Processing and Communications Laboratory (LTCI) published an article asking the question: Does Functional Package Management Enable Reproducible Builds at Scale?. Answering strongly in the affirmative, the article s abstract reads as follows:
In this work, we perform the first large-scale study of bitwise reproducibility, in the context of the Nix functional package manager, rebuilding 709,816 packages from historical snapshots of the nixpkgs repository[. We] obtain very high bitwise reproducibility rates, between 69 and 91% with an upward trend, and even higher rebuildability rates, over 99%. We investigate unreproducibility causes, showing that about 15% of failures are due to embedded build dates. We release a novel dataset with all build statuses, logs, as well as full diffoscopes: recursive diffs of where unreproducible build artifacts differ.
As above, the entire PDF of the article is available to view online.

Distribution work There as been the usual work in various distributions this month, such as:
  • 10+ reviews of Debian packages were added, 11 were updated and 10 were removed this month adding to our knowledge about identified issues. A number of issue types were updated also.
  • The FreeBSD Foundation announced that a planned project to deliver zero-trust builds has begun in January 2025 . Supported by the Sovereign Tech Agency, this project is centered on the various build processes, and that the primary goal of this work is to enable the entire release process to run without requiring root access, and that build artifacts build reproducibly that is, that a third party can build bit-for-bit identical artifacts. The full announcement can be found online, which includes an estimated schedule and other details.

On our mailing list On our mailing list this month:
  • Following-up to a substantial amount of previous work pertaining the Sphinx documentation generator, James Addison asked a question pertaining to the relationship between SOURCE_DATE_EPOCH environment variable and testing that generated a number of replies.
  • Adithya Balakumar of Toshiba asked a question about whether it is possible to make ext4 filesystem images reproducible. Adithya s issue is that even the smallest amount of post-processing of the filesystem results in the modification of the Last mount and Last write timestamps.
  • James Addison also investigated an interesting issue surrounding our disorderfs filesystem. In particular:
    FUSE (Filesystem in USErspace) filesystems such as disorderfs do not delete files from the underlying filesystem when they are deleted from the overlay. This can cause seemingly straightforward tests for example, cases that expect directory contents to be empty after deletion is requested for all files listed within them to fail.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 285, 286 and 287 to Debian:
  • Security fixes:
    • Validate the --css command-line argument to prevent a potential Cross-site scripting (XSS) attack. Thanks to Daniel Schmidt from SRLabs for the report. [ ]
    • Prevent XML entity expansion attacks. Thanks to Florian Wilkens from SRLabs for the report.. [ ][ ]
    • Print a warning if we have disabled XML comparisons due to a potentially vulnerable version of pyexpat. [ ]
  • Bug fixes:
    • Correctly identify changes to only the line-endings of files; don t mark them as Ordering differences only. [ ]
    • When passing files on the command line, don t call specialize( ) before we ve checked that the files are identical or not. [ ]
    • Do not exit with a traceback if paths are inaccessible, either directly, via symbolic links or within a directory. [ ]
    • Don t cause a traceback if cbfstool extraction failed.. [ ]
    • Use the surrogateescape mechanism to avoid a UnicodeDecodeError and crash when any decoding zipinfo output that is not UTF-8 compliant. [ ]
  • Testsuite improvements:
    • Don t mangle newlines when opening test fixtures; we want them untouched. [ ]
    • Move to assert_diff in test_text.py. [ ]
  • Misc improvements:
    • Drop unused subprocess imports. [ ][ ]
    • Drop an unused function in iso9600.py. [ ]
    • Inline a call and check of Config().force_details; no need for an additional variable in this particular method. [ ]
    • Remove an unnecessary return value from the Difference.check_for_ordering_differences method. [ ]
    • Remove unused logging facility from a few comparators. [ ]
    • Update copyright years. [ ][ ]
In addition, fridtjof added support for the ASAR .tar-like archive format. [ ][ ][ ][ ] and lastly, Vagrant Cascadian updated diffoscope in GNU Guix to version 285 [ ][ ] and 286 [ ][ ].
strip-nondeterminism is our sister tool to remove specific non-deterministic results from a completed build. This month version 1.14.1-1 was uploaded to Debian unstable by Chris Lamb, making the following the changes:
  • Clarify the --verbose and non --verbose output of bin/strip-nondeterminism so we don t imply we are normalizing files that we are not. [ ]
  • Bump Standards-Version to 4.7.0. [ ]

Website updates There were a large number of improvements made to our website this month, including:
Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In January, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Add support for rebuilding the armhf architecture. [ ][ ]
    • Add support for rebuilding the arm64 architecture. [ ][ ][ ][ ]
    • Add support for rebuilding the riscv64 architecture. [ ][ ]
    • Move the i386 builder to the osuosl5 node. [ ][ ][ ][ ]
    • Don t run our rebuilders on a public port. [ ][ ]
    • Add database backups on all builders and add links. [ ][ ]
    • Rework and dramatically improve the statistics collection and generation. [ ][ ][ ][ ][ ][ ]
    • Add contact info to the main page [ ], thumbnails [ ] as well as the new, missing architectures. [ ]
    • Move the amd64 worker to the osuosl4 and node. [ ]
    • Run the underlying debrebuild script under nice. [ ]
    • Try to use TMPDIR when calling debrebuild. [ ][ ]
  • buildinfos.debian.net-related:
    • Stop creating buildinfo-pool_$ suite _$ arch .list files. [ ]
    • Temporarily disable automatic updates of pool links. [ ]
  • FreeBSD-related:
    • Fix the sudoers to actually permit builds. [ ]
    • Disable debug output for FreeBSD rebuilding jobs. [ ]
    • Upgrade to FreeBSD 14.2 [ ] and document that bmake was installed on the underlying FreeBSD virtual machine image [ ].
  • Misc:
    • Update the real year to 2025. [ ]
    • Don t try to install a Debian bookworm kernel from backports on the infom08 node which is running Debian trixie. [ ]
    • Don t warn about system updates for systems running Debian testing. [ ]
    • Fix a typo in the ZOMBIES definition. [ ][ ]
In addition:
  • Ed Maste modified the FreeBSD build system to the clean the object directory before commencing a build. [ ]
  • Gioele Barabucci updated the rebuilder stats to first add a category for network errors [ ] as well as to categorise failures without a diffoscope log [ ].
  • Jessica Clarke also made some FreeBSD-related changes, including:
    • Ensuring we clean up the object directory for second build as well. [ ][ ]
    • Updating the sudoers for the relevant rm -rf command. [ ]
    • Update the cleanup_tmpdirs method to to match other removals. [ ]
  • Jochen Sprickerhof:
  • Roland Clobus:
    • Update the reproducible_debstrap job to call Debian s debootstrap with the full path [ ] and to use eatmydata as well [ ][ ].
    • Make some changes to deduce the CPU load in the debian_live_build job. [ ]
Lastly, both Holger Levsen [ ] and Vagrant Cascadian [ ] performed some node maintenance.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

2 February 2025

Dirk Eddelbuettel: RcppUUID 1.1.2 on CRAN: Newly Adopted Package

The RcppUUID package on CRAN has been providing UUIDs (based on the underlying Boost library) for several years. Written by Artem Klemsov and maintained in this gitlab repo, the package is a very nice example of clean and straightforward library binding. When we did our annual BH upgrade to 1.87.0 and check reverse dependencies, we noticed the RcppUUID needed a small and rather minor update which we showed as a short diff in an issue filed. Neither I nor CRAN heard from Artem, so the packaged ended up being archived last week. Which in turn lead me to make this minimal update to 1.1.2 to resurrect it, which CRAN processed more or less like a regular update given this explanation and so it arrived last Friday. Courtesy of my CRANberries, there is also a a new package note (no diffstat report yet). More detailed information is on the RcppUUID page, or the github repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Colin Watson: Free software activity in January 2025

Most of my Debian contributions this month were sponsored by Freexian. If you appreciate this sort of work and are at a company that uses Debian, have a look to see whether you can pay for any of Freexian s services; as well as the direct benefits, that revenue stream helps to keep Debian development sustainable for me and several other lovely people. You can also support my work directly via Liberapay. Python team We finally made Python 3.13 the default version in testing! I fixed various bugs that got in the way of this: As with last month, I fixed a few more build regressions due to the removal of a deprecated intersphinx_mapping syntax in Sphinx 8.0: I ported a few packages to Django 5.1: I ported python-pypump to IPython 8.0. I fixed python-datamodel-code-generator to handle isort 6, and contributed that upstream. I fixed some packages to tolerate future versions of dh-python that will drop their dependency on python3-setuptools: I removed the old python-celery-common transitional package from celery, since nothing in Debian needs it any more. I fixed or helped to fix various other build/test failures: I upgraded these packages to new upstream versions: Rust team I fixed rust-pyo3-ffi to avoid explicit Python version dependencies that were getting in the way of making Python 3.13 the default version. Security tools packaging team I uploaded libevt to fix a build failure on i386 and to tolerate future versions of dh-python that will drop their dependency on python3-setuptools. Installer team I helped with some testing of a debian-installer-utils patch as part of the /usr move. I need to get around to uploading this, since it looks OK now. Other small things Helmut Grohne reached out for help debugging a multi-arch coinstallability problem (you know it s going to be complicated when even Helmut can t figure it out on his own ) in binutils, and we had a call about that. I reviewed and applied a new Romanian translation of debconf s manual pages. I did my twice-yearly refresh of debmirror s mirror_size documentation, and applied a contribution to improve the example debmirror.conf. I fixed an arguable preprocessor string handling bug in man-db, and applied a fix for out-of-tree builds.

Joachim Breitner: Coding on my eInk Tablet

For many years I wished I had a setup that would allow me to work (that is, code) productively outside in the bright sun. It s winter right now, but when its summer again it s always a bit. this weekend I got closer to that goal. TL;DR: Using code-server on a beefy machine seems to be quite neat.
Passively lit coding Passively lit coding

Personal history Looking back at my own old blog entries I find one from 10 years ago describing how I bought a Kobo eBook reader with the intent of using it as an external monitor for my laptop. It seems that I got a proof-of-concept setup working, using VNC, but it was tedious to set up, and I never actually used that. I subsequently noticed that the eBook reader is rather useful to read eBooks, and it has been in heavy use for that every since. Four years ago I gave this old idea another shot and bought an Onyx BOOX Max Lumi. This is an A4-sized tablet running Android and had the very promising feature of an HDMI input. So hopefully I d attach it to my laptop and it just works . Turns out that this never worked as well as I hoped: Even if I set the resolution to exactly the tablet s screen s resolution I got blurry output, and it also drained the battery a lot, so I gave up on this. I subsequently noticed that the tablet is rather useful to take notes, and it has been in sporadic use for that. Going off on this tangent: I later learned that the HDMI input of this device appears to the system like a camera input, and I don t have to use Boox s monitor app but could other apps like FreeDCam as well. This somehow managed to fix the resolution issues, but the setup still wasn t as convenient to be used regularly. I also played around with pure terminal approaches, e.g. SSH ing into a system, but since my usual workflow was never purely text-based (I was at least used to using a window manager instead of a terminal multiplexer like screen or tmux) that never led anywhere either.

VSCode, working remotely Since these attempts I have started a new job working on the Lean theorem prover, and working on or with Lean basically means using VSCode. (There is a very good neovim plugin as well, but I m using VSCode nevertheless, if only to make sure I am dogfooding our default user experience). My colleagues have said good things about using VSCode with the remote SSH extension to work on a beefy machine, so I gave this a try now as well, and while it s not a complete game changer for me, it does make certain tasks (rebuilding everything after a switching branches, running the test suite) very convenient. And it s a bit spooky to run these work loads without the laptop s fan spinning up. In this setup, the workspace is remote, but VSCode still runs locally. But it made me wonder about my old goal of being able to work reasonably efficient on my eInk tablet. Can I replicate this setup there? VSCode itself doesn t run on Android directly. There are project that run a Linux chroot or in termux on the Android system, and then you can VNC to connect to it (e.g. on Andronix) but that did not seem promising. It seemed fiddly, and I probably should take it easy on the tablet s system.

code-server, running remotely A more promising option is code-server. This is a fork of VSCode (actually of VSCodium) that runs completely on the remote machine, and the client machine just needs a browser. I set that up this weekend and found that I was able to do a little bit of work reasonably.

Access With code-server one has to decide how to expose it safely enough. I decided against the tunnel-over-SSH option, as I expected that to be somewhat tedious to set up (both initially and for each session) on the android system, and I liked the idea of being able to use any device to work in my environment. I also decided against the more involved reverse proxy behind proper hostname with SSL setups, because they involve a few extra steps, and some of them I cannot do as I do not have root access on the shared beefy machine I wanted to use. That left me with the option of using a code-server s built-in support for self-signed certificates and a password:
$ cat .config/code-server/config.yaml
bind-addr: 1.2.3.4:8080
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: true
With trust-on-first-use this seems reasonably secure. Update: I noticed that the browsers would forget that I trust this self-signed cert after restarting the browser, and also that I cannot install the page (as a Progressive Web App) unless it has a valid certificate. But since I don t have superuser access to that machine, I can t just follow the official recommendation of using a reverse proxy on port 80 or 431 with automatic certificates. Instead, I pointed a hostname that I control to that machine, obtained a certificate manually on my laptop (using acme.sh) and copied the files over, so the configuration now reads as follows:
bind-addr: 1.2.3.4:3933
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.cer
cert-key: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.key
(This is getting very specific to my particular needs and constraints, so I ll spare you the details.)

Service To keep code-server running I created a systemd service that s managed by my user s systemd instance:
~ $ cat ~/.config/systemd/user/code-server.service
[Unit]
Description=code-server
After=network-online.target
[Service]
Environment=PATH=/home/joachim/.nix-profile/bin:/nix/var/nix/profiles/default/bin:/usr/local/bin:/usr/bin:/bin:/usr/local/games:/usr/games
ExecStart=/nix/var/nix/profiles/default/bin/nix run nixpkgs#code-server
[Install]
WantedBy=default.target
(I am using nix as a package manager on a Debian system there, hence the additional PATH and complex ExecStart. If you have a more conventional setup then you do not have to worry about Environment and can likely use ExecStart=code-server. For this to survive me logging out I had to ask the system administrator to run loginctl enable-linger joachim, so that systemd allows my jobs to linger.

Git credentials The next issue to be solved was how to access the git repositories. The work is all on public repositories, but I still need a way to push my work. With the classic VSCode-SSH-remote setup from my laptop, this is no problem: My local SSH key is forwarded using the SSH agent, so I can seamlessly use that on the other side. But with code-server there is no SSH key involved. I could create a new SSH key and store it on the server. That did not seem appealing, though, because SSH keys on Github always have full access. It wouldn t be horrible, but I still wondered if I can do better. I thought of creating fine-grained personal access tokens that only me to push code to specific repositories, and nothing else, and just store them permanently on the remote server. Still a neat and convenient option, but creating PATs for our org requires approval and I didn t want to bother anyone on the weekend. So I am experimenting with Github s git-credential-manager now. I have configured it to use git s credential cache with an elevated timeout, so that once I log in, I don t have to again for one workday.
$ nix-env -iA nixpkgs.git-credential-manager
$ git-credential-manager configure
$ git config --global credential.credentialStore cache
$ git config --global credential.cacheOptions "--timeout 36000"
To login, I have to https://github.com/login/device on an authenticated device (e.g. my phone) and enter a 8-character code. Not too shabby in terms of security. I only wish that webpage would not require me to press Tab after each character This still grants rather broad permissions to the code-server, but at least only temporarily

Android setup On the client side I could now open https://host.example.com:8080 in Firefox on my eInk Android tablet, click through the warning about self-signed certificates, log in with the fixed password mentioned above, and start working! I switched to a theme that supposedly is eInk-optimized (eInk by Mufanza). It s not perfect (e.g. git diffs are unhelpful because it is not possible to distinguish deleted from added lines), but it s a start. There are more eInk themes on the official Visual Studio Marketplace, but because code-server is a fork it cannot use that marketplace, and for example this theme isn t on Open-VSX. For some reason the F11 key doesn t work, but going fullscreen is crucial, because screen estate is scarce in this setup. I can go fullscreen using VSCode s command palette (Ctrl-P) and invoking the command there, but Firefox often jumps out of the fullscreen mode, which is annoying. I still have to pay attention to when that s happening; maybe its the Esc key, which I am of course using a lot due to me using vim bindings. A more annoying problem was that on my Boox tablet, sometimes the on-screen keyboard would pop up, which is seriously annoying! It took me a while to track this down: The Boox has two virtual keyboards installed: The usual Google ASOP keyboard, and the Onyx Keyboard. The former is clever enough to stay hidden when there is a physical keyboard attached, but the latter isn t. Moreover, pressing Shift-Ctrl on the physical keyboard rotates through the virtual keyboards. Now, VSCode has many keyboard shortcuts that require Shift-Ctrl (especially on an eInk device, where you really want to avoid using the mouse). And the limited settings exposed by the Boox Android system do not allow you configure that or disable the Onyx keyboard! To solve this, I had to install the KISS Launcher, which would allow me to see more Android settings, and in particular allow me to disable the Onyx keyboard. So this is fixed. I was hoping to improve the experience even more by opening the web page as a Progressive Web App (PWA), as described in the code-server FAQ. Unfortunately, that did not work. Firefox on Android did not recognize the site as a PWA (even though it recognizes a PWA test page). And I couldn t use Chrome either because (unlike Firefox) it would not consider a site with a self-signed certificate as a secure context, and then code-server does not work fully. Maybe this is just some bug that gets fixed in later versions. Now that I use a proper certificate, I can use it as a Progressive Web App, and with Firefox on Android this starts the app in full-screen mode (no system bars, no location bar). The F11 key still does t work, and using the command palette to enter fullscreen does nothing visible, but then Esc leaves that fullscreen mode and I suddenly have the system bars again. But maybe if I just don t do that I get the full screen experience. We ll see. I did not work enough with this yet to assess how much the smaller screen estate, the lack of colors and the slower refresh rate will bother me. I probably need to hide Lean s InfoView more often, and maybe use the Error Lens extension, to avoid having to split my screen vertically. I also cannot easily work on a park bench this way, with a tablet and a separate external keyboard. I d need at least a table, or some additional piece of hardware that turns tablet + keyboard into some laptop-like structure that I can put on my, well, lap. There are cases for Onyx products that include a keyboard, and maybe they work on the lap, but they don t have the Trackpoint that I have on my ThinkPad TrackPoint Keyboard II, and how can you live without that?

Conclusion After this initial setup chances are good that entering and using this environment is convenient enough for me to actually use it; we will see when it gets warmer. A few bits could be better. In particular logging in and authenticating GitHub access could be both more convenient and more safe I could imagine that when I open the page I confirm that on my phone (maybe with a fingerprint), and that temporarily grants access to the code-server and to specific GitHub repositories only. Is that easily possible?

Junichi Uekawa: February.

February. This is entrance exam season for Tokyo Junior High Schools. Good luck to those who are going through it now.

Dirk Eddelbuettel: RcppSpdlog 0.0.20 on CRAN: New Upstream, New Features

Version 0.0.20 of RcppSpdlog arrived on CRAN early this morning and has been uploaded to Debian. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn more at the nice package documention site. This release updates the code to the version 1.15.1 of spdlog which was released this morning as well. It also contains a contributed PR which illustrates logging in a multithreaded context. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.20 (2025-02-01)
  • New multi-threaded logging example (Young Geun Kim and Dirk via #22)
  • Upgraded to upstream release spdlog 1.15.1

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page, or the package documention site.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

1 February 2025

Guido G nther: Free Software Activities January 2025

Another short status update of what happened on my side last month. Mostly focused on quality of life improvements in phosh and cleaning up and improving phoc this time around (including catching up with wlroots git) but some improvements for other things like phosh-osk-stub happened on the side line too. phosh phoc phosh-osk-stub xdg-desktop-portal-phosh phosh-recipes libcmatrix phrog Debian git-buildpackage livi feedbackd Wayland protocols Wlroots Bug reports Reviews This is not code by me but reviews on other peoples code. The list is incomplete, but I hope to improve on this in the upcoming months. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread
31 January 2025

Dirk Eddelbuettel: zigg 0.0.1 on CRAN: New Package!

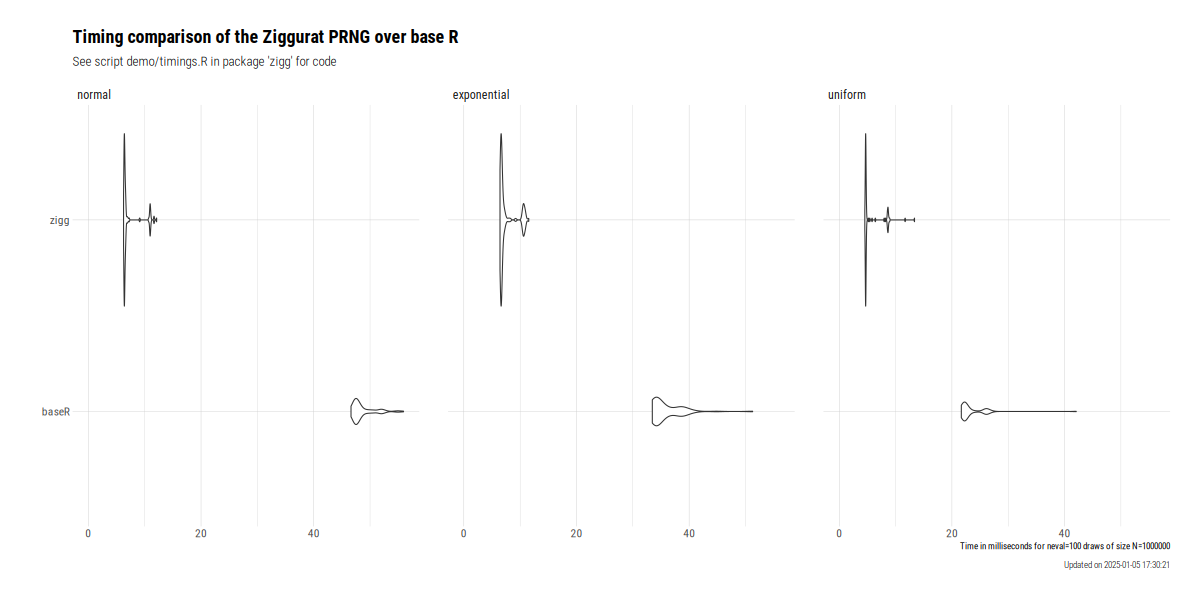
Thrilled to announce a new package: zigg. It arrived on CRAN today after a few days of review in the newbies queue. zigg provides the Ziggurat pseudo-random number generator for Normal, Exponential and Uniform draws proposed by Marsaglia and Tsang (JSS, 2000), and extended by Leong et al. (JSS, 2005). I had picked up their work in package RcppZiggurat and updated its code for the 64-buit world we now live in. That package alredy provided the Normal generator along with several competing implementations which it compared rigorously and timed them. As one of the generators was based on the GNU GSL via the implementation of Voss, we always ended up with a run-time dependency on the GSL too. No more: this new package is zero-depedency, zero-suggsts and hence very easy to deploy. Moreover, we also include a demonstration of four distinct ways of accessing the compiled code from another R package: pure and straight-up C, similarly pure C++, inclusion of the header in C++ as well as via Rcpp. The other advance is the resurrection of the second generator for the Exponential distribution. And following Burkardt we expose the Uniform too. The main upside of these generators is their excellent speed as can be seen in the comparison the default R generators generated by the example script timings.R: Needless to say, speed is not everything. This PRNG comes the time of 32-bit computing so the generator period is likely to be shorter than that of newer high-quality generators. If in doubt, forgo speed and stick with the high-quality default generators. The short NEWS entry follows.

Changes in version 0.0.1 (2021-01-30)
  • Initial version and CRAN upload

For more, see the package page or the git repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

29 January 2025

Keith Packard: picolibc-i18n

Internationalization support in Picolibc There are two major internationalization APIs in the C library: locales and iconv. Iconv is an isolated component which only performs charset conversion in ways that don't interact with anything else in the library. Locales affect pretty much every API that deals with strings and covers charset conversion along with a huge range of localized information from character classification to formatting of time, money, people's names, addresses and even standard paper sizes. Picolibc inherits it's implementation of both of these from newlib. Given that embedded applications rarely need advanced functionality from either these APIs, I hadn't spent much time exploring this space. Newlib locale code When run on Cygwin, Newlib's locale support is quite complete as it leverages the underlying Windows locale support. Without Windows support, everything aside from charset conversion and character classification data is stubbed out at the bottom of the stack. Because the implementation can support full locale functionality, the implementation is designed for that, with large data structures and lots of code. Charset conversion and character classification data for locales is all built-in; none of that can be loaded at runtime. There is support for all of the ISO-8859 charsets, three JIS variants, a bunch of Windows code pages and a few other single-byte encodings. One oddity in this code is that when using a JIS locale, wide characters are stored in EUC-JP rather than Unicode. Every other locale uses Unicode. This means APIs like wctype are implemented by mapping the JIS-encoded character to Unicode and then using the underlying Unicode character classification tables. One consequence of this is that there isn't any Unicode to JIS mapping provided as it isn't necessary. When testing the charset conversion and Unicode character classification data, I found numerous minor errors and a couple of pretty significant ones. The JIS conversion code had the most serious issue I found; most of the conversions are in a 2d array which is manually indexed with the wrong value for the length of each row. This led to nearly every translated value being incorrect. The charset conversion tables and Unicode classification data are now generated using python charset support and the standard Unicode data files. In addition, tests have been added which compare Picolibc to the system C library for every supported charset. Newlib iconv code The iconv charset support is completely separate from the locale charset support with a much wider range of supported targets. It also supports loading charset data from files at runtime, which reduces the size of application images. Because the iconv and locale implementations are completely separate, the charset support isn't the same. Iconv supports a lot more charsets, but it doesn't support all of those available to locales. For example, Iconv has Big5 support which locale lacks. Conversely, locale has Shift-JIS support which iconv does not. There's also a difference in how charset names are mapped in the two APIs. The locale code has a small fixed set of aliases, which doesn't include things like US-ASCII or ANSI X3.4. In contrast, the iconv code has an extensive database of charset aliases which are compiled into the library. Picolibc has a few tests for the iconv API which verify charset names and perform some translations. Without an external reference, it's hard to know if the results are correct. POSIX vs C internationalization In addition to including the iconv API, POSIX extends locale support in a couple of ways:
  1. Exposing locale objects via the newlocale, uselocale, duplocale and freelocale APIs.
  2. uselocale sets a per-thread locale, rather than the process-wide locale.
Goals for Picolibc internationalization support For charsets, supporting UTF-8 should cover the bulk of embedded application needs, and even that is probably more than what most applications require. Most (all?) compilers use Unicode for wide character and string constants. That means wchar_t needs to be Unicode in every locale. Aside from charset support, the rest of the locale infrastructure is heavily focused on creating human-consumable strings. I don't think it's a stretch to say that none of this is very useful these days, even for systems with sophisticated user interactions. For picolibc, the cost to provide any of this would be high. Having two completely separate charset conversion datasets makes for a confusing and error-prone experience for developers. Replacing iconv with code that leverages the existing locale support for translating between multi-byte and wide-character representations will save a bunch of source code and improve consistency. Embedded systems can be very sensitive to memory usage, both read-only and read-write. Applications not using internationalization capabilities shouldn't pay a heavy premium even when the library binary is built with support. For the most sensitive targets, the library should be configurable to remove unnecessary functionality. Picolibc needs to be conforming with at least the C language standard, and as much of POSIX as makes sense. Fortunately, the requirements for C are modest as it only includes a few locale-related APIs and doesn't include iconv. Finally, picolibc should test these APIs to make sure they conform with relevant standards, especially character set translation and character classification. The easiest way to do this is to reference another implementation of the same API and compare results. Switching to Unicode for JIS wchar_t This involved ripping the JIS to Unicode translations out of all of the wide character APIs and inserting them into the translations between multi-byte and wide-char representations. The missing Unicode to JIS translation was kludged by iterating over all JIS code points until a matching Unicode value was found. That's an obvious place for a performance improvement, but at least it works. Tiny locale This is a minimal implementation of locales which conforms with the C language standard while providing only charset translation and character classification data. It handles all of the existing charsets, but splits things into three levels
  1. ASCII
  2. UTF-8
  3. Extended, including any or all of: a. ISO 8859 b. Windows code pages and other 8-bit encodings c. JIS (JIS, EUC-JP and Shift-JIS)
When built for ASCII-only, all of the locale support is short-circuited, except for error checking. In addition, support in printf and scanf for wide characters is removed by default (it can be re-enabled with the -Dio-wchar=true meson option). This offers the smallest code size. Because the wctype APIs (e.g. iswupper) are all locale-specific, this mode restricts them to ASCII-only, which means they become wrappers on top of the ctype APIs with added range checking. When built for UTF-8, character classification for wide characters uses tables that provide the full Unicode range. Setlocale now selects between two locales, "C" and "C.UTF-8". Any locale name other than "C" selects the UTF-8 version. If the locale name contains "." or "-", then the rest of the locale name is taken to be a charset name and matched against the list of supported charsets. In this mode, only "us_ascii", "ascii" and "utf-8" are recognized. Because a single byte of a utf-8 string with the high-bit set is not a complete character, all of the ctype APIs in this mode can use the same implementation as the ASCII-only mode. This means the small ctype implementation is available. Calling setlocale(LC_ALL, "C.UTF-8") will allow the application to use the APIs which translate between multi-byte and wide-characters to deal with UTF-8 encoded strings. In addition, scanf and printf can read and write UTF-8 strings into wchar_t strings. Locale names are converted into locale IDs, an enumeration which lists the available locales. Each ID implies a specific charset as that's the only thing which differs between them. This means a locale can be encoded in a few bytes rather than an array of strings. In terms of memory usage, applications not using locales and not using the wctype APIs should see only a small increase in code space. That's due to the wchar_t support added to printf and scanf which need to translate between multi-byte and wide-character representations. There aren't any tables required as ASCII and UTF-8 are directly convertible to Unicode. On ARM-v7m, The added code in printf and scanf add up to about 1kB and another 32 bytes of RAM is used. The big difference when enabling extended charset support is that all of the charset conversion and character classification operations become table driven and dependent on the locale. Depending on the extended charsets supported, these can be quite large. With all of the extended charsets included, this adds an additional 30kB of code and static data and uses another 56 bytes of RAM. There are two known gaps in functionality compared with the newlib code:
  1. Locale strings that encode different locales for different categories. That's nominally required by POSIX as LC_ALL is supposed to return a string sufficient to restore the locale, but the only category which actually matters is LC_CTYPE.
  2. No nl_langinfo support. This would be fairly easy to add, returning appropriate constant values for each parameter.
Tiny locale was merged to picolibc main in this PR Tiny iconv Replacing the bulky newlib iconv code was far easier than swapping locale implementations. Essentially all that iconv does is compute two functions, one which maps from multi-byte to wide-char in one locale and another which maps from wide-char to multi-byte in another locale. Once the JIS locales were fixed to use Unicode, the new iconv implementation was straightforward. POSIX doesn't provide any _l version of mbrtowc or wcrtomb, so using standard C APIs would have been clunky. Instead, the implementation uses the internal APIs to compute the correct charset conversion functions. The entire implementation fits in under 200 lines of code. Tiny iconv is in process in this PR Future directions Right now, both of these new bits of code sit in the source tree parallel to the old versions. I'm not seeing any particular reason to keep the old versions around; they have provided a useful point of comparison in developing the new code, but I don't think they offer any compelling benefits going forward.

Russ Allbery: Review: The Sky Road

Review: The Sky Road, by Ken MacLeod
Series: Fall Revolution #4
Publisher: Tor
Copyright: 1999
Printing: August 2001
ISBN: 0-8125-7759-0
Format: Mass market
Pages: 406
The Sky Road is the fourth book in the Fall Revolution series, but it represents an alternate future that diverges after (or during?) the events of The Sky Fraction. You probably want to read that book first, but I'm not sure reading The Stone Canal or The Cassini Division adds anything to this book other than frustration. Much more on that in a moment. Clovis colha Gree is a aspiring doctoral student in history with a summer job as a welder. He works on the platform for the project, which the reader either slowly discovers from the book or quickly discovers from the cover is a rocket to get to orbit. As the story opens, he meets (or, as he describes it) is targeted by a woman named Merrial, a tinker who works on the guidance system. The early chapters provide only a few hints about Clovis's world: a statue of the Deliverer on a horse that forms the backdrop of their meeting, the casual carrying of weapons, hints that tinkers are socially unacceptable, and some division between the white logic and the black logic in programming. Also, because this is a Ken MacLeod novel, everyone is obsessed with smoking and tobacco the way that the protagonists of erotica are obsessed with sex. Clovis's story is one thread of this novel. The other, told in the alternating chapters, is the story of Myra Godwin-Davidova, chair of the governing Council of People's Commissars of the International Scientific and Technical Workers' Republic, a micronation embedded in post-Soviet Kazakhstan. Series readers will remember Myra's former lover, David Reid, as the villain of The Stone Canal and the head of the corporation Mutual Protection, which is using slave labor (sort of) to support a resurgent space movement and its attempt to take control of a balkanized Earth. The ISTWR is in decline and a minor power by all standards except one: They still have nuclear weapons. So, first, we need to talk about the series divergence. I know from reading about this book on-line that The Sky Road is an alternate future that does not follow the events of The Stone Canal and The Cassini Division. I do not know this from the text of the book, which is completely silent about even being part of a series. More annoyingly, while the divergence in the Earth's future compared to The Cassini Division is obvious, I don't know what the Jonbar hinge is. Everything I can find on-line about this book is maddeningly coy. Wikipedia claims the divergence happens at the end of The Sky Fraction. Other reviews and the Wikipedia talk page claim it happens in the middle of The Stone Canal. I do have a guess, but it's an unsatisfying one and I'm not sure how to test its correctness. I suppose I shouldn't care and instead take each of the books on their own terms, but this is the type of thing that my brain obsesses over, and I find it intensely irritating that MacLeod didn't explain it in the books themselves. It's the sort of authorial trick that makes me feel dumb, and books that gratuitously make me feel dumb are less enjoyable to read. The second annoyance I have with this book is also only partly its fault. This series, and this book in particular, is frequently mentioned as good political science fiction that explores different ways of structuring human society. This was true of some of the earlier books in a surprisingly superficial way. Here, I would call it hogwash. This book, or at least the Myra portion of it, is full of people doing politics in a tactical sense, but like the previous books of this series, that politics is mostly embedded in personal grudges and prior romantic relationships. Everyone involved is essentially an authoritarian whose ability to act as they wish is only contested by other authoritarians and is largely unconstrained by such things as persuasion, discussions, elections, or even theory. Myra and most of the people she meets are profoundly cynical and almost contemptuous of any true discussion of political systems. This is the trappings and mechanisms of politics without the intellectual debate or attempt at consensus, turning it into a zero-sum game won by whoever can threaten the others more effectively. Given the glowing reviews I've seen in relatively political SF circles, presumably I am missing something that other people see in MacLeod's approach. Perhaps this level of pettiness and cynicism is an accurate depiction of what it's like inside left-wing political movements. (What an appalling condemnation of left-wing political movements, if so.) But many of the on-line reviews lead me to instead conclude that people's understanding of "political fiction" is stunted and superficial. For example, there is almost nothing Marxist about this book it contains essentially no economic or class analysis whatsoever but MacLeod uses a lot of Marxist terminology and sets half the book in an explicitly communist state, and this seems to be enough for large portions of the on-line commentariat to conclude that it's full of dangerous, radical ideas. I find this sadly hilarious given that MacLeod's societies tend, if anything, towards a low-grade libertarianism that would be at home in a Robert Heinlein novel. Apparently political labels are all that's needed to make political fiction; substance is optional. So much for the politics. What's left in Clovis's sections is a classic science fiction adventure in which the protagonist has a radically different perspective from the reader and the fun lies in figuring out the world-building through the skewed perspective of the characters. This was somewhat enjoyable, but would have been more fun if Clovis had any discernible personality. Sadly he instead seems to be an empty receptacle for the prejudices and perspective of his society, which involve a lot of quasi-religious taboos and an essentially magical view of the world. Merrial is a more interesting character, although as always in this series the romance made absolutely no sense to me and seemed to be conjured by authorial fiat and weirdly instant sexual attraction. Myra's portion of the story was the part I cared more about and was more invested in, aided by the fact that she's attempting to do something more interesting than launch a crewed space vehicle for no obvious reason. She at least faces some true moral challenges with no obviously correct response. It's all a bit depressing, though, and I found Myra's unwillingness to ground her decisions in a more comprehensive moral framework disappointing. If you're going to make a protagonist the ruler of a communist state, even an ironic one, I'd like to hear some real political philosophy, some theory of sociology and economics that she used to justify her decisions. The bits that rise above personal animosity and vibes were, I think, said better in The Cassini Division. This series was disappointing, and I can't say I'm glad to have read it. There is some small pleasure in finishing a set of award-winning genre books so that I can have a meaningful conversation about them, but the awards failed to find me better books to read than I would have found on my own. These aren't bad books, but the amount of enjoyment I got out of them didn't feel worth the frustration. Not recommended, I'm afraid. Rating: 6 out of 10

27 January 2025

Russ Allbery: Review: The House That Fought

Review: The House That Fought, by Jenny Schwartz
Series: Uncertain Sanctuary #3
Publisher: Jenny Schwartz
Copyright: December 2020
Printing: September 2024
ASIN: B0DBX6GP8Z
Format: Kindle
Pages: 199
The House That Fought is the third and final book of the self-published space fantasy trilogy starting with The House That Walked Between Worlds. I read it as part of the Uncertain Sanctuary omnibus, which is reflected in the sidebar metadata. At the end of the last book, one of Kira's random and vibe-based trust decisions finally went awry. She has been betrayed! She's essentially omnipotent, the betrayal does not hurt her in any way, and, if anything, it helps the plot resolution, but she has to spend some time feeling bad about it first. Eventually, though, the band of House residents return to the problem of Earth's missing magic. By Earth here, I mean our world, which technically isn't called Earth in the confusing world-building of this series. Earth within this universe is an archetypal world that is the origin world for humans, the two types of dinosaurs, and Neanderthals. There are numerous worlds that have split off from it, including Human, the one world where humans are dominant, which is what we think of as Earth and what Kira calls Earth half the time. And by worlds, I mean entire universes (I think?), because traveling between "worlds" is dimensional travel, not space travel. But there is also space travel? The world building started out confusing and has degenerated over the course of the series. Given that the plot, such as it is, revolves around a world-building problem, this is not a good sign. Worse, though, is that the quality of the writing has become unedited, repetitive drivel. I liked the first book and enjoyed a few moments of the second book, but this conclusion is just bad. This is the sort of book that the maxim "show, don't tell" was intended to head off. The dull, thudding description of the justification for every character emotion leaves no room for subtlety or reader curiosity.
Evander was elf and I was human. We weren't the same. I had magic. He had the magic I'd unconsciously locked into his augmentations. We were different and in love. Speaking of our differences could be a trigger. I peeked at him, worried. My customary confidence had taken a hit. "We're different," he answered my unspoken question. "And we work anyway. We'll work to make us work."
There is page after page after page of this sort of thing: facile emotional processing full of cliches and therapy-speak, built on the most superficial of relationships. There's apparently a romance now, which happened with very little build-up, no real discussion or communication between the characters, and only the most trite and obvious relationship work. There is a plot underneath all this, but it's hard to make it suspenseful given that Kira is essentially omnipotent. Schwartz tries to turn the story into a puzzle that requires Kira figure out what's going on before she can act, but this is undermined by the confusing world-building. The loose ends the plot has accumulated over the previous two books are mostly dropped, sometimes in a startlingly casual way. I thought Kira would care who killed her parents, for example; apparently, I was wrong. The previous books caught my attention with a more subtle treatment of politics than I expect from this sort of light space fantasy. The characters had, I thought, a healthy suspicion of powerful people and a willingness to look for manipulation or ulterior motives. Unfortunately, we discover here that this is not due to an appreciation of the complexity of power and motive in governments. Instead, it's a reflexive bias against authority and structured society that sounds like an Internet libertarian complaining about taxes. Powerful people should be distrusted because all governments are corrupt and bad and steal your money in order to waste it. Oh, except for the cops and the military; they're generally good people you should trust. In retrospect, I should have expected this turn given the degree to which Schwartz stressed the independence of sorcerers. I thought that was going somewhere more interesting than sorcerers as self-appointed vigilantes who are above the law and can and should do anything they damn well please. Sadly, it was not. Adding to the lynch mob feeling, the ending of this book is a deeply distasteful bit of magical medieval punishment that I thought was vile, and which is, of course, justified by bad things happening to children. No societal problems were solved, but Kira got her petty revenge and got to be gleeful and smug about it. This is apparently what passes for a happy ending. I don't even know what to say about the bizarre insertion of Christianity, which makes little sense given the rest of the world-building. It's primarily a way for Kira to avoid understanding or thinking about an important part of the plot. As sadly seems to often be the case in books like this, Kira's faith doesn't appear to prompt any moral analysis or thoughtful ethical concern about her unlimited power, just certainty that she's right and everyone else is wrong. This was dire. It is one of those self-published books that I feel a little bad about writing this negative of a review about, because I think most of the problem was that the author's skill was not up to the story that she wanted to tell. This happens a lot in self-published fiction, particularly since Kindle Unlimited has started rewarding quantity over quality. But given how badly the writing quality degraded over the course of the series, and how offensive the ending was, I do want to warn other people off of the series. There is so much better fiction out there. Avoid this one, and probably the rest of the series unless you're willing to stop after the first book. Rating: 2 out of 10

26 January 2025

Dirk Eddelbuettel: RcppBDT 0.2.7 on CRAN: Maintenance

Another minor maintenance release for the RcppBDT package is now on CRAN. The RcppBDT package is an early adopter of Rcpp and was one of the first packages utilizing Boost and its Date_Time library. The now more widely-used package anytime is a direct descentant of RcppBDT. This release follows the recent updates of other package updating their C++ compilation standard along with other standard package updates. No feature or interface changes. The NEWS entry follows:

Changes in version 0.2.7 (2025-01-25)
  • The package no longer sets a C++ compilation standard
  • Package infrastructure, documentation and continuous integration support have been updated
  • Several manual pages now have package anchors for the code link
  • A demo/ file has been move to inst/examples/

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Otto Kek l inen: 10 habits to help becoming a Debian Maintainer

Featured image of post 10 habits to help becoming a Debian MaintainerBecoming a Debian maintainer is a journey that combines technical expertise, community collaboration, and continuous learning. In this post, I ll share 10 key habits that will both help you navigate the complexities of Debian packaging without getting lost, and also enable you to contribute more effectively to one of the world s largest open source projects.

1. Read and re-read the Debian Policy, the Developer s Reference and the git-buildpackage manual Anyone learning Debian packaging and aspiring to become a Debian maintainer is likely to wade through a lot of documentation, only to realize that much of it is outdated or sometimes outright incorrect. Therefore, it is important to learn right from the start which sources are the most reliable and truly worth reading and re-reading. I recommend these documents, in order of importance:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive, and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • The git-buildpackage man pages: While the Policy focuses on the end result and is intentionally void of practical instructions on creating or maintaining Debian packages, the Developer s Reference goes into greater detail. However, it too lacks step-by-step instructions. For the exact commands, consult the man pages of git-buildpackage and its subcommands (e.g., gbp clone, gbp import-orig, gbp pq, gbp dch, gbp push). See also my post on Debian source package git branch and tags for an easy to understand diagrams.

2. Make reading man pages a habit In addition to the above, try to make a habit of checking out the man page of every new tool you use to ensure you are using it as intended. The best place to read accurate and up-to-date documentation is manpages.debian.org. The manual pages are maintained alongside the tools by their developers, ensuring greater accuracy than any third-party documentation. If you are using a tool in the way the tool author documented, you can be confident you are doing the right thing, even if it wasn t explicitly mentioned in some third-party guide about Debian packaging best practices.

3. Read and write emails While members of the Debian community have many channels of communication, the mailing lists are by far the most prominent. Asking questions on the appropriate list is a good way to get current advice from other people doing Debian packaging. Staying subscribed to lists of interest is also a good way to read about new developments as they happen. Note that every post is public and archived permanently, so the discussions on the mailing lists also form a body of documentation that can later be searched and referred to. Regularly writing short and well-structured emails on the mailing lists is great practice for improving technical communication skills a useful ability in general. For Debian specifically, being active on mailing lists helps build a reputation that can later attract collaborators and supporters for more complex initiatives.

4. Create and use an OpenPGP key Related to reputation and identity, OpenPGP keys play a central role in the Debian community. OpenPGP is used to various degrees to sign git commits and tags, sign and encrypt email, and most importantly to sign Debian packages so their origin can be verified. The process of becoming a Debian Maintainer and eventually a Debian Developer culminates in getting your OpenPGP key included in the Debian keyring, which is used to control who can upload packages into the Debian archive. The earlier you create a key and start using it to gain reputation for that specific key that is used to sign your work, the better. Note that due to a recent schism in the OpenPGP standards working group, it is safest to create an OpenPGP key using GnuPG version 2.2.x (not 2.4.x), or using Sequoia-PGP.

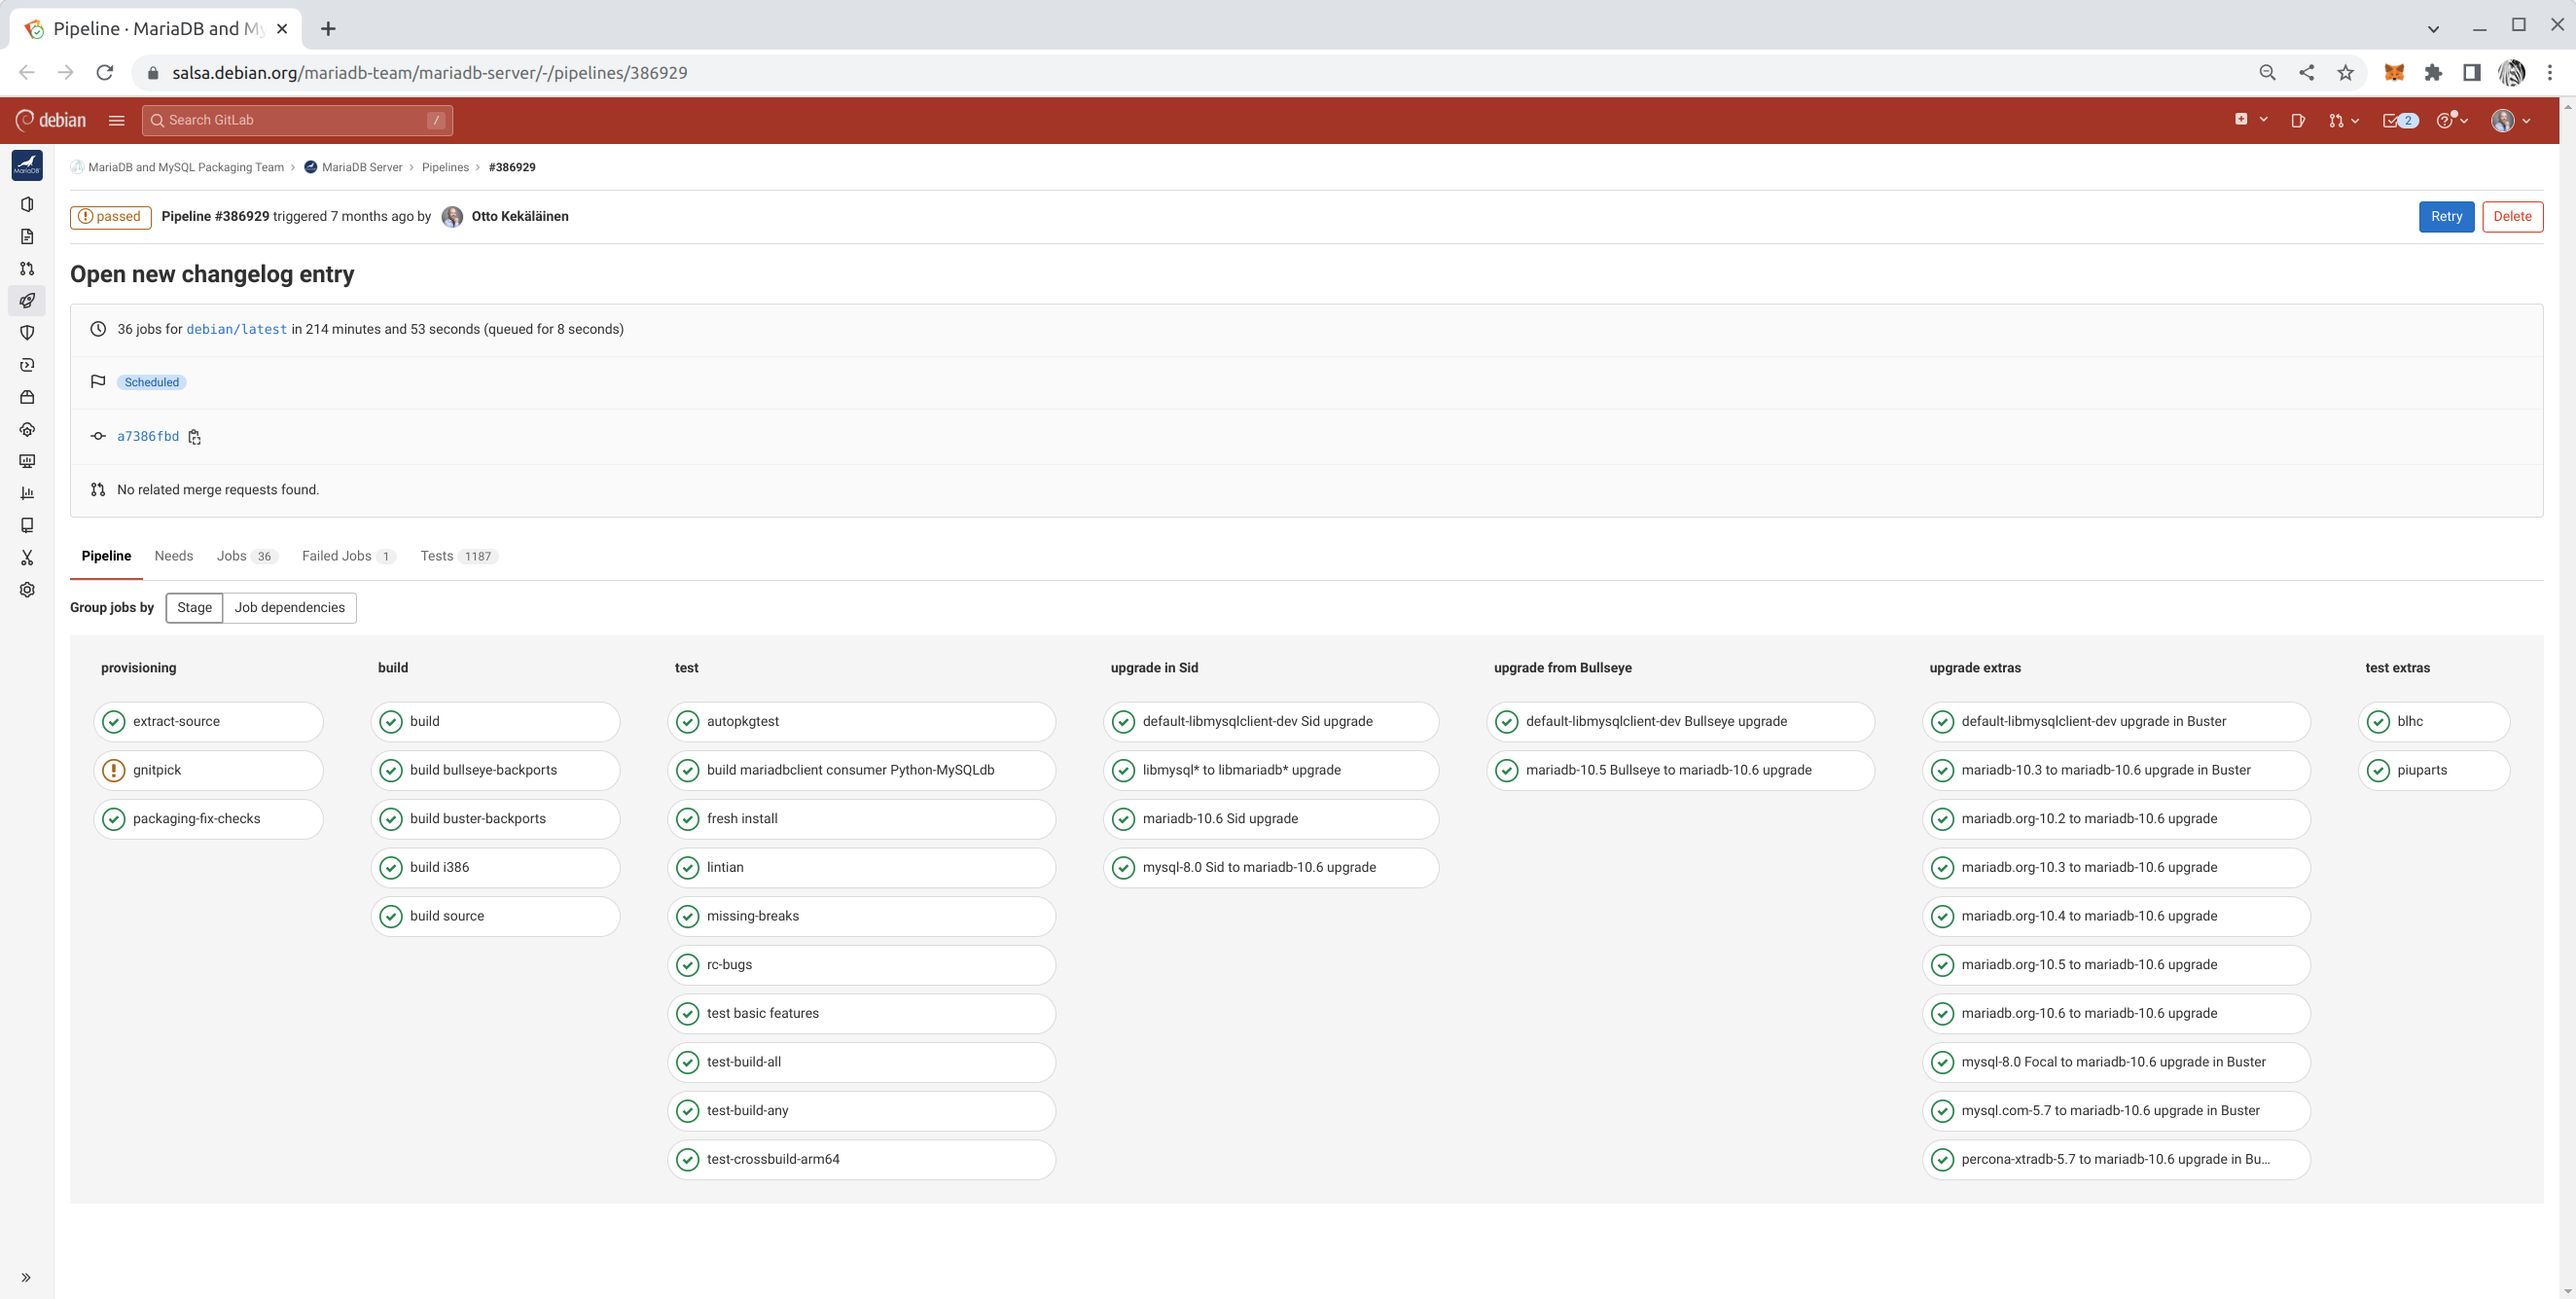
5. Integrate Salsa CI in all work One reason Debian remains popular, even 30 years after its inception, is due to its culture of maintaining high standards. For a newcomer, learning all the quality assurance tools such as Lintian, Piuparts, Adequate, various build variations, and reproducible builds may be overwhelming. However, these tasks are easier to manage thanks to Salsa CI, the continuous integration pipeline in Debian that runs tests on every commit at salsa.debian.org. The earlier you activate Salsa CI in the package repository you are working on, the faster you will achieve high quality in your package with fewer missteps. You can also further customize a package specific salsa-ci.yml to have more testing coverage. Example Salsa CI pipeline with customizations

6. Fork on Salsa and use draft Merge Requests to solicit feedback All modern Debian packages are hosted on salsa.debian.org. If you want to make a change to any package, it is easy to fork, make an initial attempt at the change, and publish it as a draft Merge Request (MR) on Salsa to solicit feedback. People might have surprising reasons to object to the change you propose, or they might need time to get used to the idea before agreeing to it. Also, some people might object to a vague idea out of suspicion but agree once they see the exact implementation. There may also be a surprising number of people supporting your idea, and if there is an MR, they have a place to show their support at. Don t expect every Merge Request to be accepted. However, proposing an idea as running code in an MR is far more effective than raising the idea on a mailing list or in a bug report. Get into the habit of publishing plenty of merge requests to solicit feedback and drive discussions toward consensus.

7. Use git rebase frequently Linear git history is much easier to read. The ease of reading git log and git blame output is vital in Debian, where packages often have updates from multiple people spanning many years even decades. Debian packagers likely spend more time than the average software developer reading git history. Make sure you master git commands such as gitk --all, git citool --amend, git commit -a --fixup <commit id>, git rebase -i --autosquash <target branch>, git cherry-pick <commit id 1> <id 2> <id 3>, and git pull --rebase. If rebasing is not done on your initiative, rest assured others will ask you to do it. Thus, if the commands above are familiar, rebasing will be quick and easy for you.

8. Reviews: give some, get some In open source, the larger a project becomes, the more it attracts contributions, and the bottleneck for its growth isn t how much code developers can create but how much code submissions can be properly reviewed. At the time of writing, the main Salsa group Debian has over 800 open merge requests pending reviews and approvals. Feel free to read and comment on any merge request you find. You don t have to be a subject matter expert to provide valuable feedback. Even if you don t have specific feedback, your comment as another human acknowledging that you read the MR and found no issues is viewed positively by the author. Besides, if you spend enough time reviewing MRs in a specific domain, you will eventually become an expert in it. Code reviews are not just about providing feedback to the submitter; they are also great learning opportunities for the reviewer. As a rule of thumb, you should review at least twice as many merge requests as you submit yourself.

9. Improve Debian by improving upstream It is common that while packaging software for Debian, bugs are uncovered and patched in Debian. Do not forget to submit the fixes upstream, and add a Forwarded field to the file in debian/patches! As the person building and packaging something in Debian, you automatically become an authority on that software, and the upstream is likely glad to receive your improvements. While submitting patches upstream is a bit of work initially, getting improvements merged upstream eventually saves time for everyone and makes packaging in Debian easier, as there will be fewer patches to maintain with each new upstream release.

10. Don t hold any habits too firmly Last but not least: Once people learn a specific way of working, they tend to stick to it for decades. Learning how to create and maintain Debian packages requires significant effort, and people tend to stop learning once they feel they ve reached a sufficient level. This tendency to get stuck in a local optimum is understandable and natural, but try to resist it. It is likely that better techniques will evolve over time, so stay humble and re-evaluate your beliefs and practices every few years. Mastering these habits takes time, but each small step brings you closer to making a meaningful impact on Debian. By staying curious, collaborative, and adaptable, you can ensure your contributions stand the test of time just like Debian itself. Good luck on your journey toward becoming a Debian Maintainer!

25 January 2025

Steve Kemp: The CP/M emulator now works better!

I keep saying I'm "done" with my CP/M emulator, but then I keep overhauling it in significant ways. Today is no exception. In the past the emulator used breakpoints to detect when calls to the system BIOS, or BDOS, were made. That was possible because the BIOS and BDOS entry points are at predictable locations. For example a well-behaved program might make a system call with code like this:
    LD A,42
    LD C,4
    CALL 0x0005
So setting a breakpoint on 0x0005 would let you detect a system-call was being made, inspect the registers to see which system-call was being made and then carry out the appropriate action in your emulator before returning control back to the program. Unfortunately some binaries patch the RAM, changing the contents of the entry points, or changing internal jump-tables, etc. The end result is that sometimes code running at the fixed addresses is not your BIOS at all, but something else. By trapping/faulting/catching execution here you break things, badly. So today's new release fixes that! No more breakpoints. Instead we deploy a "real BDOS" in RAM that will route system-calls to our host emulator via a clever trick. For BDOS functions the C-register will contain the system call to operate, our complete BDOS implementation is:
    OUT (C),C
    RET
The host program can catch writes to output ports, and will know that "OUT (3), 3" means "Invoke system call #3", for example. This means binary patches to entry-points, or any internal jump-tables won't confuse things and so long as control eventually reaches my BIOS or BDOS code areas things will work. I also added a new console-input driver, since I have a notion of pluggable input and output devices, which just reads input from a file. Now I can prove that my code works. Pass the following file to the input-driver and we have automated testing:
A:
ERA HELLO.COM
ERA HELLO.HEX
ERA HELLO.PRN
hello
ASM HELLO
LOAD HELLO
DDT HELLO.com
t
t
t
t
t
t
t
t
t
C-c
EXIT
Here we: I can test the output and confirm there are no regressions. Neat. Anyway new release, today. Happy.

24 January 2025

Sam Hartman: Feeling Targeted: Executive Order Ending Wasteful DEIA Efforts

As most here know, I m totally blind. One of my roles involves a contract for the US Government, under which I have a government email account. The department recently received a message talking about our work to end, to the maximum extend permitted by law, all diversity, equity, inclusion, and accessibility efforts in the government in accordance with the recently signed executive order. We are all reminded that if we timely identify the contracts and positions that are related to these efforts, there will be no consequences. There are a lot of times in my life when I have felt marginalized frustrated and angry that people weren t interested in working with me to make the small changes that would help me fit in. As an example with this government job, I asked to have access to a screen reader so that I could use my computer. My preferred adaptive software was not approved, even though it was thousands of dollars cheaper than the option the government wanted and could have been installed instantly rather than waiting for a multi-week ordering process. When the screen reader eventually became available, the government-provided installer was not accessible: a blind person could not use it. When I asked for help, the government added an additional multi-week delay because they weren t sure that the license management technology for the software they had chosen met the government s security and privacy policies. Which is to say that even with people actively working toward accessibility, sharing a commitment that accessibility is important, we have a lot of work to do. I feel very targeted at the current time. Now we are removing as many of the resources that help me be effective and feel welcome as we can. Talking about the lack of consequences now is just a way to remind everyone that there will be consequences later and get the fear going. The witch hunt is coming, and if people do a good enough job of turning in all the people who could help me feel welcome, they won t face consequences. Yes, I understand that the Americans with Disabilities act is still law, but its effectiveness will be very different in a climate where you need to eliminate accessibility positions to avoid consequences than in a climate where accessibility is a goal.

comment count unavailable comments

23 January 2025

Dirk Eddelbuettel: qlcal 0.0.14 on CRAN: Calendar Updates

The fourteenth release of the qlcal package arrivied at CRAN today, following the QuantLib 1.37 release two days ago. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases synchronizes qlcal with the QuantLib release 1.37 (made this week), and moves a demo/ file to examples/.

Changes in version 0.0.14 (2025-01-23)
  • Synchronized with QuantLib 1.37 released two days ago
  • Calendar updates for United States and New Zealand
  • The demo/ file is now in inst/examples/

This update includes the inclusion of the January 9, 2025, holiday for the memorial of President Carter that was observed at the NYSE and shown by the allUScalendars.R example:
edd@rob:~/git/qlcal-r/inst/examples(master)$ Rscript allUScalendars.R 
           LiborImpact NYSE GovernmentBond NERC FederalReserve SOFR
2025-01-01        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-01-09          NA TRUE             NA   NA             NA   NA
2025-01-20        TRUE TRUE           TRUE   NA           TRUE TRUE
2025-02-17        TRUE TRUE           TRUE   NA           TRUE TRUE
2025-04-18          NA TRUE           TRUE   NA             NA TRUE
2025-05-26        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-06-19        TRUE TRUE           TRUE   NA           TRUE TRUE
2025-07-04        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-09-01        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-10-13        TRUE   NA           TRUE   NA           TRUE TRUE
2025-11-11        TRUE   NA           TRUE   NA           TRUE TRUE
2025-11-27        TRUE TRUE           TRUE TRUE           TRUE TRUE
2025-12-25        TRUE TRUE           TRUE TRUE           TRUE TRUE
edd@rob:~/git/qlcal-r/inst/examples(master)$ 
Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 January 2025

Ravi Dwivedi: The Arduous Luxembourg Visa Process

In 2024, I was sponsored by The Document Foundation (TDF) to attend the LibreOffice annual conference in Luxembourg from the 10th to the 12th of October. Being an Indian passport holder, I needed a visa to visit Luxembourg. However, due to my Kenya trip coming up in September, I ran into a dilemma: whether to apply before or after the Kenya trip. To obtain a visa, I needed to submit my application with VFS Global (and not with the Luxembourg embassy directly). Therefore, I checked the VFS website for information on processing time, which says:
As a rule, the processing time of an admissible Schengen visa application should not exceed 15 calendar days (from the date the application is received at the Embassy).
It also mentions:
If the application is received less than 15 calendar days before the intended travel date, the Embassy can deem your application inadmissible. If so, your visa application will not be processed by the Embassy and the application will be sent back to VFS along with the passport.
If I applied for the Luxembourg visa before my trip, I would run the risk of not getting my passport back in time, and therefore missing my Kenya flight. On the other hand, if I waited until after returning from Kenya, I would run afoul of the aforementioned 15 working days needed by the embassy to process my application. I had previously applied for a Schengen visa for Austria, which was completed in 7 working days. My friends who had been to France told me they got their visa decision within a week. So, I compared Luxembourg s application numbers with those of other Schengen countries. In 2023, Luxembourg received 3,090 applications from India, while Austria received 39,558, Italy received 52,332 and France received 176,237. Since Luxembourg receives a far fewer number of applications, I expected the process to be quick. Therefore, I submitted my visa application with VFS Global in Delhi on the 5th of August, giving the embassy a month with 18 working days before my Kenya trip. However, I didn t mention my Kenya trip in the Luxembourg visa application. For reference, here is a list of documents I submitted: I submitted flight reservations instead of flight tickets . It is because, in case of visa rejection, I would have lost a significant amount of money if I booked confirmed flight tickets. The embassy also recommends the same. After the submission of documents, my fingerprints were taken. The expenses for the visa application were as follows:
Service Description Amount (INR)
Visa Fee 8,114
VFS Global Fee 1,763
Courier 800
Total 10,677
Going by the emails sent by VFS, my application reached the Luxembourg embassy the next day. Fast-forward to the 27th of August 14th day of my visa application. I had already booked my flight ticket to Nairobi for the 4th of September, but my passport was still with the Luxembourg embassy, and I hadn t heard back. In addition, I also obtained Kenya s eTA and got vaccinated for Yellow Fever, a requirement to travel to Kenya. In order to check on my application status, I gave the embassy a phone call, but missed their calling window, which was easy to miss since it was only 1 hour - 12:00 to 1:00 PM. So, I dropped them an email explaining my situation. At this point, I was already wondering whether to cancel the Kenya trip or the Luxembourg one, if I had to choose. After not getting a response to my email, I called them again the next day. The embassy told me they would look into it and asked me to send my flight tickets over email. One week to go before my flight now. I followed up with the embassy on the 30th by a phone call, and the person who picked up the call told me that my request had already been forwarded to the concerned department and is under process. They asked me to follow up on Monday, 2nd September. During the visa process, I was in touch with three other Indian attendees.1 In the meantime, I got to know that all of them had applied for a Luxembourg visa by the end of the month of August. Back to our story, over the next two days, the embassy closed for the weekend. I began weighing my options. On one hand, I could cancel the Kenya trip and hope that Luxembourg goes through. Even then, Luxembourg wasn t guaranteed as the visa could get rejected, so I might have ended up missing both the trips. On the other hand, I could cancel the Luxembourg visa application and at least be sure of going to Kenya. However, I thought it would make Luxembourg very unlikely because it didn t leave 15 working days for the embassy to process my visa after returning from Kenya. I also badly wanted to attend the LibreOffice conference because I couldn t make it two years ago. Therefore, I chose not to cancel my Luxembourg visa application. I checked with my travel agent and learned that I could cancel my Nairobi flight before September 4th for a cancelation fee of approximately 7,000 INR. On the 2nd of September, I was a bit frustrated because I hadn t heard anything from the embassy regarding my request. Therefore, I called the embassy again. They assured me that they would arrange a call for me from the concerned department that day, which I did receive later that evening. During the call, they offered to return my passport via VFS the next day and asked me to resubmit it after returning from Kenya. I immediately accepted the offer and was overjoyed, as it would enable me to take my flight to Nairobi without canceling my Luxembourg visa application. However, I didn t have the offer in writing, so it wasn t clear to me how I would collect my passport from VFS. The next day, I would receive it when I would be on my way to VFS in the form of an email from the embassy which read:
Dear Mr. Dwivedi, We acknowledge the receipt of your email. As you requested, we are returning your passport exceptionally through VFS, you can collect it directly from VFS Delhi Center between 14:00-17:00 hrs, 03 Sep 2024. Kindly bring the printout of this email along with your VFS deposit receipt and Original ID proof. Once you are back from your trip, you can redeposit the passport with VFS Luxembourg for our processing. With best regards,
Consular Section GRAND DUCHY OF LUXEMBOURG
Embassy in New Delhi
I took a printout of the email and submitted it to VFS to get my passport. This seemed like a miracle - just when I lost all hope of making it to my Kenya flight and was mentally preparing myself to miss it, I got my passport back exceptionally and now I had to mentally prepare again for Kenya. I had never heard of an embassy returning passport before completing the visa process before. The next day, I took my flight to Nairobi as planned. In case you are interested, I have written two blog posts on my Kenya trip - one on the OpenStreetMap conference in Nairobi and the other on my travel experience in Kenya. After returning from Kenya, I resubmitted my passport on the 17th of September. Fast-forward to the 25th of September; I didn t hear anything from the embassy about my application process. So, I checked with TDF to see whether the embassy reached out to them. They told me they confirmed my participation and my hotel booking to the visa authorities on the 19th of September (6 days ago). I was wondering what was taking so long after the verification. On the 1st of October, I received a phone call from the Luxembourg embassy, which turned out to be a surprise interview. They asked me about my work, my income, how I came to know about the conference, whether I had been to Europe before, etc. The call lasted around 10 minutes. At this point, my travel date - 8th of October - was just two working days away as the 2nd of October was off due to Gandhi Jayanti and 5th and 6th October were weekends, leaving only the 3rd and the 4th. I am not sure why the embassy saved this for the last moment, even though I submitted my application 2 months ago. I also got to know that one of the other Indian attendees missed the call due to being in their college lab, where he was not allowed to take phone calls. Therefore, I recommend that the embassy agree on a time slot for the interview call beforehand. Visa decisions for all the above-mentioned Indian attendees were sent by the embassy on the 4th of October, and I received mine on the 5th. For my travel date of 8th October, this was literally the last moment the embassy could send my visa. The parcel contained my passport and a letter. The visa was attached to a page in the passport. I was happy that my visa had been approved. However, the timing made my task challenging. The enclosed letter stated:
Subject: Your Visa Application for Luxembourg
Dear Applicant, We would like to inform you that a Schengen visa has been granted for the 8-day duration from 08/10/2024 to 30/10/2024 for conference purposes in Luxembourg. You are requested to report back to the Embassy of Luxembourg in New Delhi through an email (email address redacted) after your return with the following documents:
  • Immigration Stamps (Entry and Exit of Schengen Area)
  • Restaurant Bills
  • Shopping/Hotel/Accommodation bills
Failure to report to the Embassy after your return will be taken into consideration for any further visa applications.
I understand the embassy wanting to ensure my entry and exit from the Schengen area during the visa validity period, but found the demand for sending shopping bills excessive. Further, not everyone was as lucky as I was as it took a couple of days for one of the Indian attendees to receive their visa, delaying their plan. Another attendee had to send their father to the VFS center to collect their visa in time, rather than wait for the courier to arrive at their home. Foreign travel is complicated, especially for the citizens of countries whose passports and currencies are weak. Embassies issuing visas a day before the travel date doesn t help. For starters, a last-minute visa does not give enough time for obtaining a forex card as banks ask for the visa. Further, getting foreign currency (Euros in our case) in cash with a good exchange rate becomes difficult. As an example, for the Kenya trip, I had to get US Dollars at the airport due to the plan being finalized at the last moment, worsening the exchange rate. Back to the current case, the flight prices went up significantly compared to September, almost doubling. The choice of airlines also got narrowed, as most of the flights got booked by the time I received my visa. With all that said, I think it was still better than an arbitrary rejection. Credits: Contrapunctus, Badri, Fletcher, Benson, and Anirudh for helping with the draft of this post.

  1. Thanks to Sophie, our point of contact for the conference, for putting me in touch with them.

20 January 2025

Divine Attah-Ohiemi: Progress Report: First Half of My Outreachy Internship

Hello everyone!, I m excited to share a progress report on my Outreachy internship with the Debian community. As I reach the halfway point of this journey, I want to reflect on what I ve accomplished so far and outline my modified goals for the second half of the internship. In truth, there wasn t a strict timeline for my project migrating Debian webpage content to Hugo because the original repository contained thousands of pages. The initial goal was to develop a proof of concept for: Thanks to our daily standups, where we brainstorm and revise contributions, we ve made significant progress. The wiki documentation discussing the technical decisions taken to meet these goals is currently in progress here. During the first half of my internship, I have improved and refined my skills in several areas. I learned new Markdown syntaxes, studied and utilized Apache's mod_rewrite, and halfway studied GNU Make to use Perl scripts for processing data for dynamic content. I recommend Managing Projects with GNU Make by Robert Mecklenburg it's a great book for beginners! While I didn t get stuck on any particular goal, the most challenging aspect was adding Hugo aliases to help with Apache's multilingual content negotiation. The way the webwml repository generates multilingual content differs from debianhugo. For instance, in webwml, the structure looks like this: english/index.wml -> /index.en.html (with a symlink from index.html to index.en.html) and french/index.wml -> /index.fr.html. In contrast, debianhugo uses en/_index.md -> /index.html and fr/_index.md -> /fr/index.html. Apache's multilingual content negotiation checks for index.<user preferred lang code>.html in the current directory, which works well with webwml since all related translations are generated in the same directory. However, with debianhugo using subdirectories for languages other than English, we had to set up aliases for every other language page to be generated in the frontmatter. For example, in fr/_index.md, we added this to the front matter:
...
aliases:
  - /index.fr.html
...
This setup allows Hugo to generate multilingual HTML files in the initial home directory solely for the purpose of setting up a 301 redirect to the same page in the language subdirectory. However, if the client sets their preferred language to English, Apache content negotiation tries to find /index.en.html. If it doesn t find it, it defaults to any other language-suffixed file, which can lead to unexpected behavior. For example, if English is set as the preferred language, accessing the site may serve /index.fr.html, which then redirects to /fr/index.html. This was a significant challenge, and you can see a demo of this hosted here. If I were to start the project over, I would document every decision as I make them in the wiki, no matter how rough the documentation turns out. Waiting until the midpoint of the project to document was not a good idea. As I move into the second half of my internship, the goals we ve set include improving our project wiki documentation and continuing the migration process while enhancing the user experience of complicated sections. I m looking forward to making even more progress and sharing my journey with you all. Happy coding!

19 January 2025

Petter Reinholdtsen: 121 packages in Debian mapped to hardware for automatic recommendation

For some years now, I have been working on a automatic hardware based package recommendation system for Debian and other Linux distributions. The isenkram system I started on back in 2013 now consist of two subsystems, one locating firmware files using the information provided by apt-file, and one matching hardware to packages using information provided by AppStream. The former is very similar to the mechanism implemented in debian-installer to pick the right firmware packages to install. This post is about the latter system. Thanks to steady progress and good help from both other Debian and upstream developers, I am happy to report that the Isenkram system now are able to recommend 121 packages using information provided via AppStream. The mapping is done using modalias information provided by the kernel, the same information used by udev when creating device files, and the kernel when deciding which kernel modules to load. To get all the modalias identifiers relevant for your machine, you can run the following command on the command line:
find /sys/devices -name modalias -print0   xargs -0 sort -u
The modalias identifiers can look something like this:
acpi:PNP0000
cpu:type:x86,ven0000fam0006mod003F:feature:,0000,0001,0002,0003,0004,0005,0006,0007,0008,0009,000B,000C,000D,000E,000F,0010,0011,0013,0015,0016,0017,0018,0019,001A,001B,001C,001D,001F,002B,0034,003A,003B,003D,0068,006B,006C,006D,006F,0070,0072,0074,0075,0076,0078,0079,007C,0080,0081,0082,0083,0084,0085,0086,0087,0088,0089,008B,008C,008D,008E,008F,0091,0092,0093,0094,0095,0096,0097,0098,0099,009A,009B,009C,009D,009E,00C0,00C5,00E1,00E3,00EB,00ED,00F0,00F1,00F3,00F5,00F6,00F9,00FA,00FB,00FD,00FF,0100,0101,0102,0103,0111,0120,0121,0123,0125,0127,0128,0129,012A,012C,012D,0140,0160,0161,0165,016C,017B,01C0,01C1,01C2,01C4,01C5,01C6,01F9,024A,025A,025B,025C,025F,0282
dmi:bvnDellInc.:bvr2.18.1:bd08/14/2023:br2.18:svnDellInc.:pnPowerEdgeR730:pvr:rvnDellInc.:rn0H21J3:rvrA09:cvnDellInc.:ct23:cvr:skuSKU=NotProvided
pci:v00008086d00008D3Bsv00001028sd00000600bc07sc80i00
platform:serial8250
scsi:t-0x05
usb:v413CpA001d0000dc09dsc00dp00ic09isc00ip00in00
The entries above are a selection of the complete set available on a Dell PowerEdge R730 machine I have access to, to give an idea about the various styles of hardware identifiers presented in the modalias format. When looking up relevant packages in a Debian Testing installation on the same R730, I get this list of packages proposed:
% sudo isenkram-lookup
firmware-bnx2x
firmware-nvidia-graphics
firmware-qlogic
megactl
wsl
%
The list consist of firmware packages requested by kernel modules, as well packages with program to get the status from the RAID controller and to maintain the LAN console. When the edac-utils package providing tools to check the ECC RAM status will enter testing in a few days, it will also show up as a proposal from isenkram. In addition, once the mfiutil package we uploaded in October get past the NEW processing, it will also propose a tool to configure the RAID controller. Another example is the trusty old Lenovo Thinkpad X230, which have hardware handled by several packages in the archive. This is running on Debian Stable:
% isenkram-lookup 
beignet-opencl-icd
bluez
cheese
ethtool
firmware-iwlwifi
firmware-misc-nonfree
fprintd
fprintd-demo
gkrellm-thinkbat
hdapsd
libpam-fprintd
pidgin-blinklight
thinkfan
tlp
tp-smapi-dkms
tpb
%
Here there proposal consist of software to handle the camera, bluetooth, network card, wifi card, GPU, fan, fingerprint reader and acceleration sensor on the machine. Here is the complete set of packages currently providing hardware mapping via AppStream in Debian Unstable: air-quality-sensor, alsa-firmware-loaders, antpm, array-info, avarice, avrdude, bmusb-v4l2proxy, brltty, calibre, colorhug-client, concordance-common, consolekit, dahdi-firmware-nonfree, dahdi-linux, edac-utils, eegdev-plugins-free, ekeyd, elogind, firmware-amd-graphics, firmware-ath9k-htc, firmware-atheros, firmware-b43-installer, firmware-b43legacy-installer, firmware-bnx2, firmware-bnx2x, firmware-brcm80211, firmware-carl9170, firmware-cavium, firmware-intel-graphics, firmware-intel-misc, firmware-ipw2x00, firmware-ivtv, firmware-iwlwifi, firmware-libertas, firmware-linux-free, firmware-mediatek, firmware-misc-nonfree, firmware-myricom, firmware-netronome, firmware-netxen, firmware-nvidia-graphics, firmware-qcom-soc, firmware-qlogic, firmware-realtek, firmware-ti-connectivity, fpga-icestorm, g810-led, galileo, garmin-forerunner-tools, gkrellm-thinkbat, goldencheetah, gpsman, gpstrans, gqrx-sdr, i8kutils, imsprog, ledger-wallets-udev, libairspy0, libam7xxx0.1, libbladerf2, libgphoto2-6t64, libhamlib-utils, libm2k0.9.0, libmirisdr4, libnxt, libopenxr1-monado, libosmosdr0, librem5-flash-image, librtlsdr0, libticables2-8, libx52pro0, libykpers-1-1, libyubikey-udev, limesuite, linuxcnc-uspace, lomoco, madwimax, media-player-info, megactl, mixxx, mkgmap, msi-keyboard, mu-editor, mustang-plug, nbc, nitrokey-app, nqc, ola, openfpgaloader, openocd, openrazer-driver-dkms, pcmciautils, pcscd, pidgin-blinklight, ponyprog, printer-driver-splix, python-yubico-tools, python3-btchip, qlcplus, rosegarden, scdaemon, sispmctl, solaar, spectools, sunxi-tools, t2n, thinkfan, tlp, tp-smapi-dkms, trezor, tucnak, ubertooth, usbrelay, uuu, viking, w1retap, wsl, xawtv, xinput-calibrator, xserver-xorg-input-wacom and xtrx-dkms. In addition to these, there are several with patches pending in the Debian bug tracking system, and even more where no-one wrote patches yet. Good candiates for the latter are packages with udev rules but no AppStream hardware information. The isenkram system consist of two packages, isenkram-cli with the command line tools, and isenkram with a GUI background process. The latter will listen for dbus events from udev emitted when new hardware become available (like when inserting a USB dongle or discovering a new bluetooth device), look up the modalias entry for this piece of hardware in AppStream (and a hard coded list of mappings from isenkram - currently working hard to move this list to AppStream), and pop up a dialog proposing to install any not already installed packages supporting this hardware. It work very well today when inserting the LEGO Mindstorms RCX, NXT and EV3 controllers. :) If you want to make sure more hardware related packages get recommended, please help out fixing the remaining packages in Debian to provide AppStream metadata with hardware mappings. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

18 January 2025

Dominique Dumont: How we solved storage API throttling on our Azure Kubernetes clusters

Hi This issue was quite puzzling, so I m sharing how we investigated this issue. I hope it can be useful for you. My client informed me that he was no longer able to install new instances of his application. k9s showed that only some pods could not be created, only the ones that created physical volume (PV). The description of these pods showed a HTTP error 429 when creating pods: New PVC could not be created because we were throttled by Azure storage API. This issue was confirmed by Azure diagnostic console on Kubernetes ( menu Diagnose and solve problems Cluster and Control Plane Availability and Performance Azure Resource Request Throttling ). We had a lot of throttling:
2025-01-18_11-01-k8s-throttles.png
Which were explained by the high call rate:
2025-01-18_11-01-k8s-calls.png
The first clue was found at the bottom of Azure diagnostic page:
2025-01-18_11-27-throttles-by-user-agent.png
According, to this page, throttling is done by services whose user agent is:
Go/go1.23.1 (amd64-linux) go-autorest/v14.2.1 Azure-SDK-For-Go/v68.0.0
storage/2021-09-01microsoft.com/aks-operat azsdk-go-armcompute/v1.0.0 (go1.22.3; linux)
The main information is Azure-SDK-For-Go, which means the program making all these calls to storage API is written in Go. All our services are written in Typescript or Rust, so they are not suspect. That leaves controllers running in kube-systems namespace. I could not find anything suspects in the logs of these services. At that point I was convinced that a component in Kubernetes control plane was making all those calls. Unfortunately, AKS is managed by Microsoft and I don t have access to the control plane logs. However, we re realized that we had quite a lot of volumesnapshots that are created in our clusters using k8s-scheduled-volume-snapshotter: We suspected that kubernetes reconciliation loop is throttled when checking the status of all these snapshots. May be so, but we also had the same issues and throttle rates on preprod and prod were the number of snapshots were quite different. We tried to get more information using Azure console on our snapshot account, but it was also broken by the throttling issue. We were so puzzled that we decided to try L odagan s advice (tout cr mer pour repartir sur des bases saines, loosely translated as burn everything down to start from scratch ) and we destroyed piece by piece our dev cluster while checking if the throttling stopped. First, we removed all our applications, no change. Then, all ancillary components like rabbitmq, cert-manager were removed, no change. Then, we tried remove the namespace containing our applications. But, we faced another issue: Kubernetes was unable to remove the namespace because it could not destroy some PVC and volumesnapshots. That was actually good news, because it meant that we were close to the actual issue. We managed to destroy the PVC and volumesnapshots by removing their finalizers. Finalizers are some kind of markers that tell kubernetes that something needs to be done before actually deleting a resource. The finalizers were removed with a command like:
kubectl patch volumesnapshots $ volumesnapshot  \
  -p ' \"metadata\": \"finalizers\":null '  --type merge
Then, we got the first progress : the throttling and high call rate stopped on our dev cluster. To make sure that the snapshots were the issue, we re-installed the ancillary components and our applications. Everything was copacetic. So, the problem was indeed with PVC and snapshots. Even though we have backups outside of Azure, we weren t really thrilled at trying L odagan s method on our prod cluster So we looked for a better fix to try on our preprod cluster. Poking around in PVC and volumesnapshots, I finally found this error message in the description on a volumesnapshotcontents:
Code="ShareSnapshotCountExceeded" Message="The total number of snapshots
for the share is over the limit."
The number of snapshots found in our cluster was not that high. So I wanted to check the snapshots present in our storage account using Azure console, which was still broken. Fortunately, Azure CLI is able to retry HTTP calls when getting 429 errors. I managed to get a list of snapshots with
az storage share list --account-name [redacted] --include-snapshots \
      tee preprod-list.json
There, I found a lot of snapshots dating back from 2024. These were no longer managed by Kubernetes and should have been cleaned up. That was our smoking gun. I guess that we had a chain of events like: To make things worse, k8s-scheduled-volume-snapshotter creates new snapshots when it cannot list the old ones. So we had 4 new snapshots per day instead of one. Since we had the chain of events, fixing the issue was not too difficult (but quite long ):
  1. stop k8s-scheduled-volume-snapshotter by disabling its cron job
  2. delete all volumesnapshots and volume snapshots contents from k8s.
  3. since Azure API was throttled, we also had to remove their finalizers
  4. delete all snapshots from azure using az command and a Perl script (this step took several hours)
  5. re-enable k8s-scheduled-volume-snapshotter
After these steps, preprod was back to normal. I m now applying the same recipe on prod. We still don t know why we had all these stale snapshots. It may have been a human error or a bug in k8s-scheduled-volume-snapshotter. Anyway, to avoid this problem is the future, we will: My name is Dominique Dumont, I m a devops freelance. You can find the devops and audit services I propose on my website or reach out to me on LinkedIn. All the best

Next.

Previous.