Search Results: "spa"

17 August 2025

C.J. Collier: The Very Model of a Patriot Online

It appears that the fragile masculinity tech evangelists have identified Debian as a community with boundaries which exclude them from abusing its members and they re so angry about it! In response to posts such as this, and inspired by Dr. Conway s piece, I ve composed a poem which, hopefully, correctly addresses the feelings of that crowd.
The Very Model of a Patriot Online
I am the very model of a modern patriot online,
My keyboard is my rifle and my noble cause is so divine.
I didn't learn my knowledge in a dusty college lecture hall,
But from the chans where bitter anonymity enthralls us all.
I spend a dozen hours every day upon my sacred quest,
To put the globo-homo narrative completely to the test.
My arguments are peer-reviewed by fellas in the comments section,
Which proves my every thesis is the model of complete perfection.
I m steeped in righteous anger that the libs call 'white fragility,'
For mocking their new pronouns and their lack of masculinity.
I m master of the epic troll, the comeback, and the searing snark,
A digital guerrilla who is fighting battles in the dark.
I know the secret symbols and the dog-whistles historical,
From Pepe the Frog to  Let s Go Brandon,  in order categorical;
In short, for fighting culture wars with rhetoric rhetorical,
I am the very model of a patriot polemical.
***
I stand for true expression, for the comics and the edgy clown,
Whose satire is too based for all the fragile folks in town.
They say my speech is 'violence' while my spirit they are trampling,
The way they try to silence me is really quite a startling sampling
Of 1984, which I've not read but thoroughly understand,
Is all about the tyranny that's gripping this once-blessed land.
My humor is a weapon, it s a razor-bladed, sharp critique,
(Though sensitive elites will call my masterpiece a form of  hate speech ).
They cannot comprehend my need for freedom from all consequence,
They call it 'hate,' I call it 'jokes,' they just don't have a lick of sense.
So when they call me  bigot  for the spicy memes I post pro bono,
I tell them their the ones who're cancelled, I'm the victim here, you know!
Then I can write a screed against the globalist cabal, you see,
And tell you every detail of their vile conspiracy.
In short, when I use logic that is flexible and personal,
I am the very model of a patriot controversial.
***
I'm very well acquainted with the scientific method, too,
It's watching lengthy YouTube vids until my face is turning blue.
I trust the heartfelt testimony of a tearful, blonde ex-nurse,
But what a paid fact-checker says has no effect and is perverse.
A PhD is proof that you've been brainwashed by the leftist mob,
While my own research on a meme is how I really do my job.
I know that masks will suffocate and vaccines are a devil's brew,
I learned it from a podcast host who used to sell brain-boosting goo.
He scorns the lamestream media, the CNNs and all the rest,
Whose biased reporting I've put fully to a rigorous test
By only reading headlines and confirming what I already knew,
Then posting my analysis for other patriots to view.
With every "study" that they cite from sources I can't stand to hear,
My own profound conclusions become ever more precisely clear.
In short, when I've debunked the experts with a confident "Says who?!",
I am the very model of a researcher who sees right through you.
***
But all these culture wars are just a sleight-of-hand, a clever feint,
To hide the stolen ballots and to cover up the moral taint
Of D.C. pizza parlors and of shipping crates from Wayfair, it s true,
It's all connected in a plot against the likes of me and you!
I've analyzed the satellite photography and watermarks,
I understand the secret drops, the cryptic Qs, the coded sparks.
The  habbening  is coming, friends, just give it two more weeks or three,
When all the traitors face the trials for their wicked treachery.
They say that nothing happened and the dates have all gone past, you see,
But that's just disinformation from the globalist enemy!
Their moving goalposts constantly, a tactic that is plain to see,
To wear us down and make us doubt the coming, final victory!
My mind can see the patterns that a simple sheep could never find,
The hidden puppet-masters who are poisoning our heart and mind.
In short, when I link drag queens to the price of gas and child-trafficking,
I am the very model of a patriot whose brain is quickening!
***
My pickup truck's a testament to everything that I hold dear,
With vinyl decals saying things the liberals all hate and fear.
The Gadsden flag is waving next to one that's blue and starkly thin,
To show my deep respect for law, except the feds who're steeped in sin.
There's Punisher and Molon Labe, so that everybody knows
I'm not someone to trifle with when push to final shoving goes.
I've got my tactical assault gear sitting ready in the den,
Awaiting for the signal to restore our land with my fellow men.
I practice clearing rooms at home when my mom goes out to the store,
A modern Minuteman who's ready for a civil war.
The neighbors give me funny looks, I see them whisper and take note,
They'll see what's what when I'm the one who's guarding checkpoints by their throat.
I am a peaceful man, of course, but I am also pre-prepared,
To neutralize the threats of which the average citizen's unscared.
In short, when my whole identity's a brand of tactical accessory,
You'll say a better warrior has never graced a Cabela's registry.
***
They say I have to tolerate a man who thinks he is a dame,
While feminists and immigrants are putting out my vital flame!
There taking all the jobs from us and giving them to folks who kneel,
And "woke HR" says my best jokes are things I'm not allowed to feel!
An Alpha Male is what I am, a lion, though I'm in this cubicle,
My life's frustrations can be traced to policies Talmudical.
They lecture me on privilege, I, who have to pay my bills and rent!
While they give handouts to the lazy, worthless, and incompetent!
My grandad fought the Nazis! Now I have to press a key for  one 
To get a call-rep I can't understand beneath the blazing sun
Of global, corporate tyranny that's crushing out the very soul
Of men like me, who've lost their rightful, natural, and just control!
So yes, I am resentful! And I'm angry! And I'm right to be!
They've stolen all my heritage and my masculinity!
In short, when my own failures are somebody else's evil plot,
I am the very model of the truest patriot we've got!
***
There putting chips inside of you! Their spraying things up in the sky!
They want to make you EAT THE BUGS and watch your very spirit die!
The towers for the 5G are a mind-control delivery tool!
To keep you docile while the children suffer in a grooming school!
The WEF, and Gates, and Soros have a plan they call the 'Great Reset,'
You'll own no property and you'll be happy, or you'll be in debt
To social credit overlords who'll track your every single deed!
There sterilizing you with plastics that they've hidden in the feed!
The world is flat! The moon is fake! The dinosaurs were just a lie!
And every major tragedy's a hoax with actors paid to cry!
I'M NOT INSANE! I SEE THE TRUTH! MY EYES ARE OPEN! CAN'T YOU SEE?!
YOU'RE ALL ASLEEP! YOU'RE COWARDS! YOU'RE AFRAID OF BEING TRULY FREE!
My heart is beating faster now, my breath is short, my vision's blurred,
From all the shocking truth that's in each single, solitary word!
I've sacrificed my life and friends to bring this message to the light, so...
You'd better listen to me now with all your concentrated might, ho!
***
For my heroic struggle, though it's cosmic and it's biblical,
Is waged inside the comments of a post that's algorithm-ical.
And still for all my knowledge that's both tactical and practical,
My mom just wants the rent I owe and says I'm being dramatical.


15 August 2025

Freexian Collaborators: Monthly report about Debian Long Term Support, July 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In July, 17 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 19.0h (out of 19.0h assigned).
  • Andrej Shadura did 5.0h (out of 0.0h assigned and 8.0h from previous period), thus carrying over 3.0h to the next month.
  • Bastien Roucari s did 18.5h (out of 18.75h assigned), thus carrying over 0.25h to the next month.
  • Ben Hutchings did 12.5h (out of 3.25h assigned and 15.5h from previous period), thus carrying over 6.25h to the next month.
  • Carlos Henrique Lima Melara did 10.0h (out of 10.0h assigned).
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 18.75h (out of 17.25h assigned and 1.5h from previous period).
  • Emilio Pozuelo Monfort did 18.75h (out of 18.75h assigned).
  • Guilhem Moulin did 15.0h (out of 14.0h assigned and 1.0h from previous period).
  • Jochen Sprickerhof did 2.0h (out of 16.5h assigned and 2.25h from previous period), thus carrying over 16.75h to the next month.
  • Lee Garrett did 7.0h (out of 0.0h assigned and 23.25h from previous period), thus carrying over 16.25h to the next month.
  • Markus Koschany did 9.0h (out of 18.75h assigned), thus carrying over 9.75h to the next month.
  • Roberto C. S nchez did 10.25h (out of 18.5h assigned and 2.75h from previous period), thus carrying over 11.0h to the next month.
  • Santiago Ruano Rinc n did 7.25h (out of 12.75h assigned and 2.25h from previous period), thus carrying over 7.75h to the next month.
  • Sylvain Beucler did 18.75h (out of 18.75h assigned).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Utkarsh Gupta did 15.0h (out of 1.0h assigned and 14.0h from previous period).

Evolution of the situation In July, we released 24 DLAs.
  • Notable security updates:
    • angular.js, prepared by Bastien Roucari s, fixes multiple vulnerabilities including input sanitization and potential regular expression denial of service (ReDoS)
    • tomcat9, prepared by Markus Koschany, fixes an assortment of vulnerabilities
    • mediawiki, prepared by Guilhem Moulin, fixes several information disclosure and privilege escalation vulnerabilities
    • php7.4, prepared by Guilhem Moulin, fixes several server side request forgery and denial of service vulnerabilities
This month s contributions from outside the regular team include an update to thunderbird, prepared by Christoph Goehre (the package maintainer). LTS Team members also contributed updates of the following packages:
  • commons-beanutils (to stable and unstable), prepared by Adrian Bunk
  • djvulibre (to oldstable, stable, and unstable), prepared by Adrian Bunk
  • git (to stable), prepared by Adrian Bunk
  • redis (to oldstable), prepared by Chris Lamb
  • libxml2 (to oldstable), prepared by Guilhem Moulin
  • commons-vfs (to oldstable), prepared by Daniel Leidert
Additionally, LTS Team member Santiago Ruano Rinc n proposed and implemented an improvement to the debian-security-support package. This package is available so that interested users can quickly determine if any installed packages are subject to limited security support or are excluded entirely from security support. However, there was not previously a way to identify explicitly supported packages, which has become necessary to note exceptions to broad exclusion policies (e.g., those which apply to substantial package groups, like modules belonging to the Go and Rust language ecosystems). Santiago s work has enabled the notation of exceptions to these exclusions, thus ensuring that users of debian-security-support have accurate status information concerning installed packages.

DebCamp 25 Security Tracker Sprint The previously announced security tracker sprint took place at DebCamp from 7-13 July. Participants included 8 members of the standing LTS Team, 2 active Debian Developers with an interest in LTS, 3 community members, and 1 member of the Debian Security Team (who provided guidance and reviews on proposed changes to the security tracker); participation was a mix of in person at the venue in Brest, France and remote. During the days of the sprint, the team tackled a wide range of bugs and improvements, mostly targeting the security tracker. The sprint participants worked on the following items: As can be seen from the above list, only a small number of changes were brought to completion during the sprint week itself. Given the very compressed timeframe involved, the broad scope of tasks which were under consideration, and the highly sensitive data managed by the security tracker, this is not entirely unexpected and in no way diminishes the great work done by the sprint participants. The LTS Team would especially like to thank Salvatore Bonaccorso of the Debian Security Team for making himself available throughout the sprint to answer questions, for providing guidance on the work, and for helping the work by reviewing and merging the MRs which were able to merged during the sprint itself. In the weeks that follow the sprint, the team will continue working towards completing the in progress items.

Thanks to our sponsors Sponsors that joined recently are in bold.

14 August 2025

Jonathan McDowell: Local Voice Assistant Step 4: openWakeWord

People keep asking me when I ll write the next instalment of my local voice assistant journey. I didn t mean for it to be so long since the last one, things have been busier than I d like. Anyway. Last time we d built Tensorflow, so now it s time to sort out openWakeWord. As a reminder we re trying to put a local voice satellite on my living room Debian media machine. The point of openWakeWord is to run on the machine the microphone is connected to, listening for the wake phrase ( Hey Jarvis in my case), and only then calling back to the central server to do a speech to text operation. It s wrapped up for Wyoming as wyoming-openwakeword. Of course I ve packaged it up - available at https://salsa.debian.org/noodles/wyoming-openwakeword. Trixie only released yesterday, so I m still running all of this on bookworm. That means you need python3-wyoming from Trixie - 1.6.0-1 will install fine without needing rebuilt - and the python3-tflite-runtime we built last time. Like the other pieces I m not sure about how this could land in Debian; it s unclear to me that the pre-trained models provided would be accepted in main. As usual I start it with with a systemd unit file dropped in /etc/systemd/service/wyoming-openwakeword.service:
[Unit]
Description=Wyoming OpenWakeWord server
After=network.target
[Service]
Type=simple
DynamicUser=yes
ExecStart=/usr/bin/wyoming-openwakeword --uri tcp://[::1]:10400/ --preload-model 'hey_jarvis' --threshold 0.8
MemoryDenyWriteExecute=false
ProtectControlGroups=true
PrivateDevices=false
ProtectKernelTunables=true
ProtectSystem=true
RestrictRealtime=true
RestrictNamespaces=true
[Install]
WantedBy=multi-user.target
I m still playing with the threshold level. It defaults to 0.5, but the device lives under the TV and seems to get a bit confused by it sometimes. There s some talk about using speex for noise suppression, but I haven t explored that yet (it s yet another Python module to bind to the C libraries I d have to look at). This is a short one; next post is actually building the local satellite on top to tie everything together.

12 August 2025

Sergio Cipriano: Running Docker (OCI) Images in Incus

Running Docker (OCI) Images in Incus Incus 6.15 released with a lot of cool features, my favorite so far is the authentication support for OCI registries. Here's an example:
$ incus remote add docker https://docker.io --protocol=oci
$ incus launch docker:debian:sid sid
$ incus shell sid
root@sid:~# apt update && apt upgrade -y
root@sid:~# cat /etc/os-release 
PRETTY_NAME="Debian GNU/Linux forky/sid"
NAME="Debian GNU/Linux"
VERSION_CODENAME=forky
ID=debian
HOME_URL="https://www.debian.org/"
SUPPORT_URL="https://www.debian.org/support"
BUG_REPORT_URL="https://bugs.debian.org/"
This has been really useful for creating containers to test packages, much better than launching the official Debian stable Incus images and then manually changing the sources list.

Freexian Collaborators: Debian Contributions: DebConf 25, OpenSSH upgrades, Cross compilation collaboration and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-07 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 25, by Stefano Rivera and Santiago Ruano Rinc n In July, DebConf 25 was held in Brest, France. Freexian was a gold sponsor and most of the Freexian team attended the event. Many fruitful discussions were had amongst our team and within the Debian community. DebConf itself was organized by a local team in Brest, that included Santiago (who now lives in Uruguay). Stefano was also deeply involved in the organization, as a DebConf committee member, core video team, and the lead developer for the conference website. Running the conference took an enormous amount of work, consuming all of Stefano and Santiago s time for most of July. Lucas Kanashiro was active in the DebConf content team, reviewing talks and scheduling them. There were many last-minute changes to make during the event. Anupa Ann Joseph was part of the Debian publicity team doing live coverage of DebConf 25 and was part of the DebConf 25 content team reviewing the talks. She also assisted the local team to procure the lanyards. Recorded sessions presented by Freexian collaborators, often alongside other friends in Debian, included:

OpenSSH upgrades, by Colin Watson Towards the end of a release cycle, people tend to do more upgrade testing, and this sometimes results in interesting problems. Manfred Stock reported No new SSH connections possible during large part of upgrade to Debian Trixie , which would have affected many people upgrading from Debian 12 (bookworm), with potentially severe consequences for people upgrading remote systems. In fact, there were two independent problems that each led to much the same symptom:
  • As part of hardening the OpenSSH server, OpenSSH 9.8 split the monolithic sshd listener process into two pieces: a minimal network listener (still called sshd), and an sshd-session process dealing with each individual session. Before this change, when sshd received an incoming connection, it forked and re-executed itself with some special parameters to deal with it; after this change, it forks and executes sshd-session instead, and sshd no longer accepts the parameters it used to accept for this.

    Debian package upgrades happen (roughly) in two phases: first we unpack the new files onto disk, and then we run some configuration steps which usually include things like restarting services. Normally this is fine, because the old service keeps on working until it s restarted. In this case, unpacking the new files onto disk immediately stopped new SSH connections from working: the old sshd received the connection and tried to hand it off to a freshly-executed copy of the new sshd binary on disk, which no longer supports this. This wasn t much of a problem when upgrading OpenSSH on its own or with a small number of other packages, but in release upgrades it left a large gap when you can t SSH to the system any more, and if anything fails in that interval then you could be in trouble.

    After trying a couple of other approaches, Colin landed on the idea of having the openssh-server package divert /usr/sbin/sshd to /usr/sbin/sshd.session-split before the unpack step of an upgrade from before 9.8, then removing the diversion and moving the new file into place once it s ready to restart the service. This reduces the period when new connections fail to a minimum.
  • Most OpenSSH processes, including sshd, check for a compatible version of the OpenSSL library when they start up. This check used to be very picky, among other things requiring both the major and minor part of the version number to match. OpenSSL 3 has a better versioning policy, and so OpenSSH 9.4p1 relaxed this check.

    Unfortunately, bookworm shipped with OpenSSH 9.2p1, so as soon as you unpacked the new OpenSSL library during an upgrade, sshd stopped working. This couldn t be fixed by a change in trixie; we needed to change bookworm in advance of the upgrade so that it would tolerate newer versions of OpenSSL, and time was tight if we wanted this to be available before the release of Debian 13.

    Fortunately, there s a stable-updates mechanism for exactly this sort of thing, and the stable release managers kindly accepted Colin s proposal to fix this there.
The net result is that if you apply updates to bookworm (including stable-updates / bookworm-updates, which is enabled by default) before starting the upgrade to trixie, everything should be fine.

Cross compilation collaboration, by Helmut Grohne Supporting cross building in Debian packages touches lots of areas of the archive and quite some of these matters reside in shared responsibility between different teams. Hence, DebConf was an ideal opportunity to settle long-standing issues. The cross building bof sparked lively discussions as a significant fraction of developers employ cross builds to get their work done. In the trixie release, about two thirds of the packages can satisfy their cross Build-Depends and about half of the packages actually can be cross built.

Miscellaneous contributions
  • Rapha l Hertzog updated tracker.debian.org to remove references to Debian 10 which was moved to archive.debian.org, and had many fruitful discussions related to Debusine during DebConf 25.
  • Carles Pina prepared some data, questions and information for the DebConf 25 l10n and i18n BoF.
  • Carles Pina demoed and discussed possible next steps for po-debconf-manager with different teams in DebConf 25. He also reviewed Catalan translations and sent them to the packages.
  • Carles Pina started investigating a django-compressor bug: reproduced the bug consistently and prepared a PR for django-compressor upstream (likely more details next month). Looked at packaging frictionless-py.
  • Stefano Rivera triaged Python CVEs against pypy3.
  • Stefano prepared an upload of a new upstream release of pypy3 to Debian experimental (due to the freeze).
  • Stefano uploaded python3.14 RC1 to Debian experimental.
  • Thorsten Alteholz uploaded a new upstream version of sane-airscan to experimental. He also started to work on a new upstream version of hplip.
  • Colin backported fixes for CVE-2025-50181 and CVE-2025-50182 in python-urllib3, and fixed several other release-critical or important bugs in Python team packages.
  • Lucas uploaded ruby3.4 to experimental as a starting point for the ruby-defaults transition that will happen after Trixie release.
  • Lucas coordinated with the Release team the fix of the remaining RC bugs involving ruby packages, and got them all fixed.
  • Lucas, as part of the Debian Ruby team, kicked off discussions to improve internal process/tooling.
  • Lucas, as part of the Debian Outreach team, engaged in multiple discussions around internship programs we run and also what else we could do to improve outreach in the Debian project.
  • Lucas joined the Local groups BoF during DebConf 25 and shared all the good experiences from the Brazilian community and committed to help to document everything to try to support other groups.
  • Helmut spent significant time with Samuel Thibault on improving architecture cross bootstrap for hurd-any mostly reviewing Samuel s patches. He proposed a patch for improving bash s detection of its pipesize and a change to dpkg-shlibdeps to improve behavior for building cross toolchains.
  • Helmut reiterated the multiarch policy proposal with a lot of help from Nattie Mayer-Hutchings, Rhonda D Vine and Stuart Prescott.
  • Helmut finished his work on the process based unschroot prototype that was the main feature of his talk (see above).
  • Helmut analyzed a multiarch-related glibc upgrade failure induced by a /usr-move mitigation of systemd and sent a patch and regression fix both of which reached trixie in time. Thanks to Aurelien Jarno and the release team for their timely cooperation.
  • Helmut resurrected an earlier discussion about changing the semantics of Architecture: all packages in a multiarch context in order to improve the long-standing interpreter problem. With help from Tollef Fog Heen better semantics were discovered and agreement was reached with Guillem Jover and Julian Andres Klode to consider this change. The idea is to record a concrete architecture for every Architecture: all package in the dpkg database and enable choosing it as non-native.
  • Helmut implemented type hints for piuparts.
  • Helmut reviewed and improved a patch set of Jochen Sprickerhof for debvm.
  • Anupa was involved in discussions with the Debian Women team during DebConf 25.
  • Anupa started working for the trixie release coverage and started coordinating release parties.
  • Emilio helped coordinate the release of Debian 13 trixie.

11 August 2025

David Bremner: Hibernate on the pocket reform 11/n

Context

Update to latest rockchip-devel
  • rebase reform-patches on top of collabora/rockchip-devel
  • pci reset series has new conflicts
  • try dropping from rebase and re-applying
$ b4 am 20250715-pci-port-reset-v6-0-6f9cce94e7bb@oss.qualcomm.com
# follow hint from b4
$ git checkout -b v6_20250715_manivannan_sadhasivam_oss_qualcomm_com 19272b37aa4f83ca52bdf9c16d5d81bdd1354494
$ git am ./v6_20250715_manivannan_sadhasivam_pci_add_support_for_resetting_the_root_ports_in_a_platform_specifi.mbx
$ git rebase -i collabora/rockchip-devel
  • conflict in pcie-qcom.c: take new version
  • conflict in pcie-dw-rockchip.c resolved as in hibernate-pocket-8
  • rebase reform patches on top of pci reset, instead of vice versa.
  • rebuild as discussed in hibernate-pocket-8
$ cp /boot/config-6.16.0-rc7+ .config
$ make olddefconfig
# this generates a message about "reform2_lpc config not found!!"
# and "rockchip_vdec2 config not found!!"
# hopefully this is ok
$ yes ''   make localmodconfig
$ make KBUILD_IMAGE=arch/arm64/boot/Image bindeb-pkg -j$(nproc)
previous episode

6 August 2025

Reproducible Builds: Reproducible Builds in July 2025

Welcome to the seventh report from the Reproducible Builds project in 2025. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:
  1. Reproducible Builds Summit 2025
  2. Reproducible Builds an official goal for SUSE Enterprise Linux
  3. Reproducible Builds at FOSSY 2025
  4. New OSS Rebuild project from Google
  5. New extension of Python setuptools to support reproducible builds
  6. diffoscope
  7. New library to patch system functions for reproducibility
  8. Independently Reproducible Git Bundles
  9. Website updates
  10. Distribution work
  11. Reproducibility testing framework
  12. Upstream patches

Reproducible Builds Summit 2025 We are extremely pleased to announce the upcoming Reproducible Builds Summit, set to take place from October 28th 30th 2025 in Vienna, Austria! We are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving. If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. Registration is open until 20th September 2025, and we are very much looking forward to seeing many readers of these reports there!

Reproducible Builds an official goal for SUSE Enterprise Linux On our mailing list this month, Bernhard M. Wiedemann revealed the big news that reproducibility is now an official goal for SUSE Linux Enterprise Server (SLES) 16:
[Everything] changed earlier this year when reproducible-builds for SLES-16 became an official goal for the product. More people are talking about digital sovereignty and supply-chain security now. [ ] Today, only 9 of 3319 (source) packages have significant problems left (plus 7 with pending fixes), so 99.5% of packages have reproducible builds.

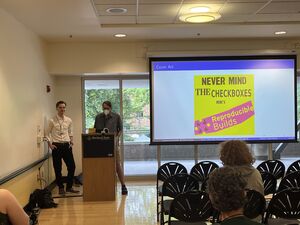
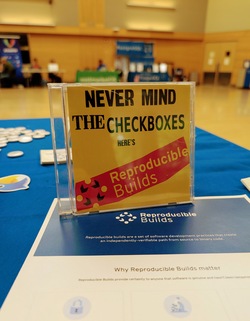
Reproducible Builds at FOSSY 2025 On Saturday 2nd August, Vagrant Cascadian and Chris Lamb presented at this year s FOSSY 2025. Their talk, titled Never Mind the Checkboxes, Here s Reproducible Builds!, was introduced as follows:
There are numerous policy compliance and regulatory processes being developed that target software development but do they solve actual problems? Does it improve the quality of software? Do Software Bill of Materials (SBOMs) actually give you the information necessary to verify how a given software artifact was built? What is the goal of all these compliance checklists anyways or more importantly, what should the goals be? If a software object is signed, who should be trusted to sign it, and can they be trusted forever?
Hosted by the Software Freedom Conservancy and taking place in Portland, Oregon, USA, FOSSY aims to be a community-focused event: Whether you are a long time contributing member of a free software project, a recent graduate of a coding bootcamp or university, or just have an interest in the possibilities that free and open source software bring, FOSSY will have something for you . More information on the event is available on the FOSSY 2025 website, including the full programme schedule. Vagrant and Chris also staffed a table, where they will be available to answer any questions about Reproducible Builds and discuss collaborations with other projects.

New OSS Rebuild project from Google The Google Open Source Security Team (GOSST) published an article this month announcing OSS Rebuild, a new project to strengthen trust in open source package ecosystems by reproducing upstream artifacts. As the post itself documents, the new project comprises four facets:
  • Automation to derive declarative build definitions for existing PyPI (Python), npm (JS/TS), and Crates.io (Rust) packages.
  • SLSA Provenance for thousands of packages across our supported ecosystems, meeting SLSA Build Level 3 requirements with no publisher intervention.
  • Build observability and verification tools that security teams can integrate into their existing vulnerability management workflows.
  • Infrastructure definitions to allow organizations to easily run their own instances of OSS Rebuild to rebuild, generate, sign, and distribute provenance.
One difference with most projects that aim for bit-for-bit reproducibility, OSS Rebuild aims for a kind of semantic reproducibility:
Through automation and heuristics, we determine a prospective build definition for a target package and rebuild it. We semantically compare the result with the existing upstream artifact, normalizing each one to remove instabilities that cause bit-for-bit comparisons to fail (e.g. archive compression).
The extensive post includes examples about how to access OSS Rebuild attestations using the Go-based command-line interface.

New extension of Python setuptools to support reproducible builds Wim Jeantine-Glenn has written a PEP 517 Build backend in order to enable reproducible builds when building Python projects that use setuptools. Called setuptools-reproducible, the project s README file contains the following:
Setuptools can create reproducible wheel archives (.whl) by setting SOURCE_DATE_EPOCH at build time, but setting the env var is insufficient for creating reproducible sdists (.tar.gz). setuptools-reproducible [therefore] wraps the hooks build_sdist build_wheel with some modifications to make reproducible builds by default.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 301, 302 and 303 to Debian:
  • Improvements:
    • Use Difference.from_operation in an attempt to pipeline the output of the extract-vmlinux script, potentially avoiding it all in memory. [ ]
    • Memoize a number of calls to --version, saving a very large number of external subprocess calls.
  • Bug fixes:
    • Don t check for PyPDF version 3 specifically, check for versions greater than 3. [ ]
    • Ensure that Java class files are named .class on the filesystem before passing them to javap(1). [ ]
    • Mask stderr from extract-vmlinux script. [ ][ ]
    • Avoid spurious differences in h5dump output caused by exposure of absolute internal extraction paths. (#1108690)
  • Misc:
    • Use our_check_output in the ODT comparator. [ ]
    • Update copyright years. [ ]
In addition: Lastly, Chris Lamb added a tmpfs to try.diffoscope.org so that diffoscope has a non-trivial temporary area to unpack archives, etc. [ ] Elsewhere in our tooling, however, reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.30 was uploaded to Debian unstable by Holger Levsen, chiefly including a change by Rebecca N. Palmer to not call sudo with the -h flag in order to fix Debian bug #1108550. [ ]

New library to patch system functions for reproducibility Nicolas Graves has written and published libfate, a simple collection of tiny libraries to patch system functions deterministically using LD_PRELOAD. According to the project s README:
libfate provides deterministic replacements for common non-deterministic system functions that can break reproducible builds. Instead of relying on complex build systems or apps or extensive patching, libfate uses the LD_PRELOAD trick to intercept system calls and return fixed, predictable values.
Describing why he wrote it, Nicolas writes:
I originally used the OpenSUSE dettrace approach to make Emacs reproducible in Guix. But when Guix switch to GCC@14, dettrace stopped working as expected. dettrace is a complex piece of software, my need was much less heavy: I don t need to systematically patch all sources of nondetermism, just the ones that make a process/binary unreproducible in a container/chroot.

Independently Reproducible Git Bundles Simon Josefsson has published another interesting article this month. Titled Independently Reproducible Git Bundles, the blog post describes the advantages of why you might a reproducible bundle, and the pitfalls that can arise when trying to create them:
One desirable property is that someone else should be able to reproduce the same git bundle, and not only that a single individual is able to reproduce things on one machine. It surprised me to see that when I ran the same set of commands on a different machine (started from a fresh git clone), I got a different checksum. The different checksums occurred even when nothing had been committed on the server side between the two runs.

Website updates Once again, there were a number of improvements made to our website this month including:

Distribution work In Debian this month:
Debian contributors have made significant progress toward ensuring package builds produce byte-for-byte reproducible results. You can check the status for packages installed on your system using the new package debian-repro-status, or visit reproduce.debian.net for Debian s overall statistics for trixie and later. You can contribute to these efforts by joining #debian-reproducible on IRC to discuss fixes, or verify the statistics by installing the new rebuilderd package and setting up your own instance.

The IzzyOnDroid Android APK repository made further progress in July, crossing the 50% reproducibility threshold congratulations. Furthermore, a new release of the Neo Store was released, which exposes the reproducible status directly next to the version of each app.
In GNU Guix, a series of patches intended to fix the reproducibility for the Mono programming language was merged, fixing reproducibility in Mono versions 1.9 [ ], 2.4 [ ] and 2.6 [ ].
Lastly, in addition to the news that openSUSE Enterprise Linux now [has an official goal of reproducibility]((https://lists.reproducible-builds.org/pipermail/rb-general/2025-July/003846.html), Bernhard M. Wiedemann posted another monthly update for their work there.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In July, however, a number of changes were made by Holger Levsen, including:
  • Switch the URL for the Tails package set. [ ]
  • Make the dsa-check-packages output more useful. [ ]
  • Setup the ppc64el architecture again, has it has returned this time with a 2.7 GiB database instead of 72 GiB. [ ]
In addition, Jochen Sprickerhof improved the reproducibility statistics generation:
  • Enable caching of statistics. [ ][ ][ ]
  • Add some common non-reproducible patterns. [ ]
  • Change output to directory. [ ]
  • Add a page sorted by diffoscope size. [ ][ ]
  • Switch to Python s argparse module and separate output(). [ ]
Holger also submitted a number of Debian bugs against rebuilderd and rebuilderd-worker:
  • Config files and scripts for a simple one machine setup. [ ][ ]
  • Create a rebuilderd user. [ ]
  • Create rebuilderd-worker user with sbuild. [ ]
Lastly, Mattia Rizzolo added a scheduled job to renew some SSL certificates [ ] and Vagrant Cascadian performed some node maintenance [ ][ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: There were a number of other patches from openSUSE developers:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

David Bremner: Using git-annex for email and notmuch metadata

Introducing git-remote-notmuch Based on an idea and ruby implementation by Felipe Contreras, I have been developing a git remote helper for notmuch. I will soon post an updated version of the patchset to the notmuch mailing list (I wanted to refer to this post in my email). In this blog post I'll outline my experiments with using that tool, along with git-annex to store (and sync) a moderate sized email store along with its notmuch metadata.

WARNING The rest of this post describes some relatively complex operations using (at best) alpha level software (namely git-remote-notmuch). git-annex is good at not losing your files, but git-remote-notmuch can (and did several times during debugging) wipe out your notmuch database. If you have a backup (e.g. made with notmuch-dump), this is much less annoying, and in particular you can decide to walk away from this whole experiment and restore your database.

Why git-annex? I currently have about 31GiB of email, spread across more than 830,000 files. I want to maintain the ability to search and read my email offline, so I need to maintain a copy on several workstations and at least one server (which is backed up explicitly). I am somewhat commited to maintaining synchronization of tags to git since that is how the notmuch bug tracker works. Commiting the email files to git seems a bit wasteful: by design notmuch does not modify email files, and even with compression, the extra copy adds a fair amount of overhead (in my case, 17G of git objects, about 57% overhead). It is also notoriously difficult to completely delete files from a git repository. git-annex offers potential mitigation for these two issues, at the cost of a somewhat more complex mental model. The main idea is that instead of committing every version of a file to the git repository, git-annex tracks the filename and metadata, with the file content being stored in a key-value store outside git. Conceptually this is similar to git-lfs. From our current point, the important point is that instead of a second (compressed) copy of the file, we store one copy, along with a symlink and a couple of directory entries.

What to annex For sufficiently small files, the overhead of a symlink and couple of directory entries is greater than the cost of a compressed second copy. When this happens depends on several variables, and will probably depend on the file content in a particular collection of email. I did a few trials of different settings for annex.largefiles to come to a threshold of largerthan=32k 1. For the curious, my experimental results are below. One potentially surprising aspect is that annexing even a small fraction of the (largest) files yields a big drop in storage overhead.
Threshold fraction annexed overhead
0 100% 30%
8k 29% 13%
16k 12% 9.4%
32k 7% 8.9%
48k 6% 8.9%
100k 3% 9.1%
256k 2% 11%
(git) 0 % 57%
In the end I chose to err on the side of annexing more files (for the flexibility of deletion) rather than potentially faster operations with fewer annexed files at the same level of overhead. Summarizing the configuration settings for git-annex (some of these are actually defaults, but not in my environment).
$ git config annex.largefiles largerthan=32k
$ git config annex.dotfiles true
$ git config annex.synccontent true

Delivering mail To get new mail, I do something like
# compute a date based folder under $HOME/Maildir
$ dest = $(folder)
# deliver mail to $ dest  (somehow).
$ notmuch new
$ git -C $HOME/Maildir add $ folder 
$ git -C $HOME/Maildir diff-index --quiet HEAD $ folder    git -C $HOME/Maildir commit -m 'mail delivery'
The call to diff-index is just an optimization for the case when nothing was delivered. The default configuration of git-annex will automagically annex any files larger than my threshold. At this point the git-annex repo knows nothing about tags. There is some git configuration that can speed up the "git add" above, namely
$ git config core.untrackedCache true
$ git config core.fsmonitor true
See git-status(1) under "UNTRACKED FILES AND PERFORMANCE" Defining notmuch as a git remote Assuming git-remote-notmuch is somewhere in your path, you can define a remote to connect to the default notmuch database.
$ git remote add database notmuch::
$ git fetch database
$ git merge --allow-unrelated database
The --allow-unrelated should be needed only the first time. In my case the many small files used to represent the tags (one per message), use a noticeable amount of disk space (in my case about the same amount of space as the xapian database). Once you start merging from the database to the git repo, you will likely have some conflicts, and most conflict resolution tools leave junk lying around. I added the following .gitignore file to the top level of the repo
*.orig
*~
This prevents our cavalier use of git add from adding these files to our git history (and prevents pushing random junk to the notmuch database. To push the tags from git to notmuch, you can run
$ git push database master
You might need to run notmuch new first, so that the database knows about all of the messages (currently git-remote-notmuch can't index files, only update metadata). git annex sync should work with the new remote, but pushing back will be very slow 2. I disable automatic pushing as follows
$ git config remote.database.annex-push false
Unsticking the database remote If you are debugging git-remote-notmuch, or just unlucky, you may end up in a sitation where git thinks the database is ahead of your git remote. You can delete the database remote (and associated stuff) and re-create it. Although I cannot promise this will never cause problems (because, computers), it will not modify your local copy of the tags in the git repo, nor modify your notmuch database.
$ git remote rm database
$ git update-rf -d notmuch/master
$ rm -r .git/notmuch
Fine tuning notmuch config
  • In order to avoid dealing with file renames, I have
      notmuch config maildir.synchronize_flags false
    
  • I have added the following to new.ignore:
       .git;_notmuch_metadata;.gitignore
    

  1. I also had to set annex.dotfiles to true, as many of my maildirs follow the qmail style convention of starting with a .
  2. I'm not totally clear on why it so slow, but certainly git-annex tries to push several more branches, and these are ignored by git-remote-annex.

Colin Watson: Free software activity in July 2025

About 90% of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. DebConf I attended DebConf for the first time in 11 years (my last one was DebConf 14 in Portland). It was great! For once I had a conference where I had a fairly light load of things I absolutely had to do, so I was able to spend time catching up with old friends, making some new friends, and doing some volunteering - a bit of Front Desk, and quite a lot of video team work where I got to play with sound desks and such. Apparently one of the BoFs ( birds of a feather , i.e. relatively open discussion sessions) where I was talkmeister managed to break the automatic video cutting system by starting and ending precisely on time, to the second, which I m told has never happened before. I ll take that. I gave a talk about Debusine, along with helping Enrico run a Debusine BoF. We still need to process some of the feedback from this, but are generally pretty thrilled about the reception. My personal highlight was getting a shout-out in a talk from CERN (in the slide starting at 32:55). Other highlights for me included a Python team BoF, Ian s tag2upload talk and some very useful follow-up discussions, a session on archive-wide testing, a somewhat brain-melting whiteboard session about the multiarch interpreter problem , several useful discussions about salsa.debian.org, Matthew s talk on how Wikimedia automates their Debian package builds, and many others. I hope I can start attending regularly again! OpenSSH Towards the end of a release cycle, people tend to do more upgrade testing, and this sometimes results in interesting problems. Manfred Stock reported No new SSH connections possible during large part of upgrade to Debian Trixie , and after a little testing in a container I confirmed that this was a reproducible problem that would have affected many people upgrading from Debian 12 (bookworm), with potentially severe consequences for people upgrading remote systems. In fact, there were two independent problems that each led to much the same symptom: The net result is that if you apply updates to bookworm (including stable-updates / bookworm-updates, which is enabled by default) before starting the upgrade to trixie, everything should be fine. Many thanks to Manfred for reporting this with just enough time to spare that we were able to fix it before Debian 13 is released in a few days! debmirror I did my twice-yearly refresh of debmirror s mirror_size documentation, and applied a patch from Christoph Goehre to improve mirroring of installer files. madison-lite I proposed renaming this project along with the rmadison tool in devscripts, although I m not yet sure what a good replacement name would be. Python team I upgraded python-expandvars, python-typing-extensions (in experimental), and webtest to new upstream versions. I backported fixes for some security vulnerabilities to unstable: I fixed or helped to fix a number of release-critical bugs: I fixed some other bugs, mostly Severity: important: I reinstated python3-mastodon s build-dependency on and recommendation of python3-blurhash, now that the latter has been fixed to use the correct upstream source.

5 August 2025

Thomas Lange: FAIme service new features: Linux Mint support and data storage for USB

Build your own customized Linux Mint ISO Using the FAIme service [1] you can now build your own customized installation ISO for Xfce edition of Linux Mint 22.1 'Xia'. You can select the language, add a list of additional packages, set the username and passwords. In the advanced settings you may add your ssh public key, some grub option and add a postinst script to be executed. Add writable data partition for USB sticks For all variants of ISOs (all live and all install ISOs) you can add a data partition to the ISO by just clicking a checkbox. This writable partition can be used when booting from USB stick. FAI will use it to search for a config space and to store the logs when this partition is detected. The logs will be stored in the subdirectory logs on this partition. For using a different config space than the one on the ISO (which is read only) create a subdirectory config and copy a FAI config space into that directory. Then set FAI_CONFIG_SRC=detect:// (which is the default) and FAI will search for a config space on the data partition and uses this. More info about this [2] You can also store some local packages in your config space, which will be installed automatically, without the need of recreating the ISO.

Matthew Garrett: Cordoomceps - replacing an Amiga's brain with Doom

There's a lovely device called a pistorm, an adapter board that glues a Raspberry Pi GPIO bus to a Motorola 68000 bus. The intended use case is that you plug it into a 68000 device and then run an emulator that reads instructions from hardware (ROM or RAM) and emulates them. You're still limited by the ~7MHz bus that the hardware is running at, but you can run the instructions as fast as you want.

These days you're supposed to run a custom built OS on the Pi that just does 68000 emulation, but initially it ran Linux on the Pi and a userland 68000 emulator process. And, well, that got me thinking. The emulator takes 68000 instructions, emulates them, and then talks to the hardware to implement the effects of those instructions. What if we, well, just don't? What if we just run all of our code in Linux on an ARM core and then talk to the Amiga hardware?

We're going to ignore x86 here, because it's weird - but most hardware that wants software to be able to communicate with it maps itself into the same address space that RAM is in. You can write to a byte of RAM, or you can write to a piece of hardware that's effectively pretending to be RAM[1]. The Amiga wasn't unusual in this respect in the 80s, and to talk to the graphics hardware you speak to a special address range that gets sent to that hardware instead of to RAM. The CPU knows nothing about this. It just indicates it wants to write to an address, and then sends the data.

So, if we are the CPU, we can just indicate that we want to write to an address, and provide the data. And those addresses can correspond to the hardware. So, we can write to the RAM that belongs to the Amiga, and we can write to the hardware that isn't RAM but pretends to be. And that means we can run whatever we want on the Pi and then access Amiga hardware.

And, obviously, the thing we want to run is Doom, because that's what everyone runs in fucked up hardware situations.

Doom was Amiga kryptonite. Its entire graphical model was based on memory directly representing the contents of your display, and being able to modify that by just moving pixels around. This worked because at the time VGA displays supported having a memory layout where each pixel on your screen was represented by a byte in memory containing an 8 bit value that corresponded to a lookup table containing the RGB value for that pixel.

The Amiga was, well, not good at this. Back in the 80s, when the Amiga hardware was developed, memory was expensive. Dedicating that much RAM to the video hardware was unthinkable - the Amiga 1000 initially shipped with only 256K of RAM, and you could fill all of that with a sufficiently colourful picture. So instead of having the idea of each pixel being associated with a specific area of memory, the Amiga used bitmaps. A bitmap is an area of memory that represents the screen, but only represents one bit of the colour depth. If you have a black and white display, you only need one bitmap. If you want to display four colours, you need two. More colours, more bitmaps. And each bitmap is stored in an independent area of RAM. You never use more memory than you need to display the number of colours you want to.

But that means that each bitplane contains packed information - every byte of data in a bitplane contains the bit value for 8 different pixels, because each bitplane contains one bit of information per pixel. To update one pixel on screen, you need to read from every bitmap, update one bit, and write it back, and that's a lot of additional memory accesses. Doom, but on the Amiga, was slow not just because the CPU was slow, but because there was a lot of manipulation of data to turn it into the format the Amiga wanted and then push that over a fairly slow memory bus to have it displayed.

The CDTV was an aesthetically pleasing piece of hardware that absolutely sucked. It was an Amiga 500 in a hi-fi box with a caddy-loading CD drive, and it ran software that was just awful. There's no path to remediation here. No compelling apps were ever released. It's a terrible device. I love it. I bought one in 1996 because a local computer store had one and I pointed out that the company selling it had gone bankrupt some years earlier and literally nobody in my farming town was ever going to have any interest in buying a CD player that made a whirring noise when you turned it on because it had a fan and eventually they just sold it to me for not much money, and ever since then I wanted to have a CD player that ran Linux and well spoiler 30 years later I'm nearly there. That CDTV is going to be our test subject. We're going to try to get Doom running on it without executing any 68000 instructions.

We're facing two main problems here. The first is that all Amigas have a firmware ROM called Kickstart that runs at powerup. No matter how little you care about using any OS functionality, you can't start running your code until Kickstart has run. This means even documentation describing bare metal Amiga programming assumes that the hardware is already in the state that Kickstart left it in. This will become important later. The second is that we're going to need to actually write the code to use the Amiga hardware.

First, let's talk about Amiga graphics. We've already covered bitmaps, but for anyone used to modern hardware that's not the weirdest thing about what we're dealing with here. The CDTV's chipset supports a maximum of 64 colours in a mode called "Extra Half-Brite", or EHB, where you have 32 colours arbitrarily chosen from a palette and then 32 more colours that are identical but with half the intensity. For 64 colours we need 6 bitplanes, each of which can be located arbitrarily in the region of RAM accessible to the chipset ("chip RAM", distinguished from "fast ram" that's only accessible to the CPU). We tell the chipset where our bitplanes are and it displays them. Or, well, it does for a frame - after that the registers that pointed at our bitplanes no longer do, because when the hardware was DMAing through the bitplanes to display them it was incrementing those registers to point at the next address to DMA from. Which means that every frame we need to set those registers back.

Making sure you have code that's called every frame just to make your graphics work sounds intensely irritating, so Commodore gave us a way to avoid doing that. The chipset includes a coprocessor called "copper". Copper doesn't have a large set of features - in fact, it only has three. The first is that it can program chipset registers. The second is that it can wait for a specific point in screen scanout. The third (which we don't care about here) is that it can optionally skip an instruction if a certain point in screen scanout has already been reached. We can write a program (a "copper list") for the copper that tells it to program the chipset registers with the locations of our bitplanes and then wait until the end of the frame, at which point it will repeat the process. Now our bitplane pointers are always valid at the start of a frame.

Ok! We know how to display stuff. Now we just need to deal with not having 256 colours, and the whole "Doom expects pixels" thing. For the first of these, I stole code from ADoom, the only Amiga doom port I could easily find source for. This looks at the 256 colour palette loaded by Doom and calculates the closest approximation it can within the constraints of EHB. ADoom also includes a bunch of CPU-specific assembly optimisation for converting the "chunky" Doom graphic buffer into the "planar" Amiga bitplanes, none of which I used because (a) it's all for 68000 series CPUs and we're running on ARM, and (b) I have a quad core CPU running at 1.4GHz and I'm going to be pushing all the graphics over a 7.14MHz bus, the graphics mode conversion is not going to be the bottleneck here. Instead I just wrote a series of nested for loops that iterate through each pixel and update each bitplane and called it a day. The set of bitplanes I'm operating on here is allocated on the Linux side so I can read and write to them without being restricted by the speed of the Amiga bus (remember, each byte in each bitplane is going to be updated 8 times per frame, because it holds bits associated with 8 pixels), and then copied over to the Amiga's RAM once the frame is complete.

And, kind of astonishingly, this works! Once I'd figured out where I was going wrong with RGB ordering and which order the bitplanes go in, I had a recognisable copy of Doom running. Unfortunately there were weird graphical glitches - sometimes blocks would be entirely the wrong colour. It took me a while to figure out what was going on and then I felt stupid. Recording the screen and watching in slow motion revealed that the glitches often showed parts of two frames displaying at once. The Amiga hardware is taking responsibility for scanning out the frames, and the code on the Linux side isn't synchronised with it at all. That means I could update the bitplanes while the Amiga was scanning them out, resulting in a mashup of planes from two different Doom frames being used as one Amiga frame. One approach to avoid this would be to tie the Doom event loop to the Amiga, blocking my writes until the end of scanout. The other is to use double-buffering - have two sets of bitplanes, one being displayed and the other being written to. This consumes more RAM but since I'm not using the Amiga RAM for anything else that's not a problem. With this approach I have two copper lists, one for each set of bitplanes, and switch between them on each frame. This improved things a lot but not entirely, and there's still glitches when the palette is being updated (because there's only one set of colour registers), something Doom does rather a lot, so I'm going to need to implement proper synchronisation.

Except. This was only working if I ran a 68K emulator first in order to run Kickstart. If I tried accessing the hardware without doing that, things were in a weird state. I could update the colour registers, but accessing RAM didn't work - I could read stuff out, but anything I wrote vanished. Some more digging cleared that up. When you turn on a CPU it needs to start executing code from somewhere. On modern x86 systems it starts from a hardcoded address of 0xFFFFFFF0, which was traditionally a long way any RAM. The 68000 family instead reads its start address from address 0x00000004, which overlaps with where the Amiga chip RAM is. We can't write anything to RAM until we're executing code, and we can't execute code until we tell the CPU where the code is, which seems like a problem. This is solved on the Amiga by powering up in a state where the Kickstart ROM is "overlayed" onto address 0. The CPU reads the start address from the ROM, which causes it to jump into the ROM and start executing code there. Early on, the code tells the hardware to stop overlaying the ROM onto the low addresses, and now the RAM is available. This is poorly documented because it's not something you need to care if you execute Kickstart which every actual Amiga does and I'm only in this position because I've made poor life choices, but ok that explained things. To turn off the overlay you write to a register in one of the Complex Interface Adaptor (CIA) chips, and things start working like you'd expect.

Except, they don't. Writing to that register did nothing for me. I assumed that there was some other register I needed to write to first, and went to the extent of tracing every register access that occurred when running the emulator and replaying those in my code. Nope, still broken. What I finally discovered is that you need to pulse the reset line on the board before some of the hardware starts working - powering it up doesn't put you in a well defined state, but resetting it does.

So, I now have a slightly graphically glitchy copy of Doom running without any sound, displaying on an Amiga whose brain has been replaced with a parasitic Linux. Further updates will likely make things even worse. Code is, of course, available.

[1] This is why we had trouble with late era 32 bit systems and 4GB of RAM - a bunch of your hardware wanted to be in the same address space and so you couldn't put RAM there so you ended up with less than 4GB of RAM

comment count unavailable comments

Michael Ablassmeier: PVE 9.0 - Snapshots for LVM

The new Proxmox release advertises a new feature for easier snapshot handling of virtual machines whose disks are stored on LVM volumes, I wondered.. whats the deal..? To be able to use the new feature, you need to enable a special flag for the LVM volume group. This example shows the general workflow for a fresh setup. 1) Create the volume group with the snapshot-as-volume-chain feature turned on:
 pvesm add lvm lvmthick --content images --vgname lvm --snapshot-as-volume-chain 1
2) From this point on, you can create virtual machines right away, BUT those virtual machines disks must use the QCOW image format for their disk volumes. If you use the RAW format, you wont be able to create snapshots, still.
 VMID=401
 qm create $VMID --name vm-lvmthick
 qm set $VMID -scsi1 lvmthick:2,format=qcow2
So, why would it make sense to format the LVM volume as QCOW? Snapshots on LVM thick provisioned devices are, as everybody knows, a very I/O intensive task. Besides each snapshot, a special -cow Device is created that tracks the changed block regions and the original block data for each change to the active volume. This will waste quite some space within your volume group for each snapshot. Formatting the LVM volume as QCOW image, makes it possible to use the QCOW backing-image option for these devices, this is the way PVE 9 handles these kind of snapshots. Creating a snapshot looks like this:
 qm snapshot $VMID id
 snapshotting 'drive-scsi1' (lvmthick3:vm-401-disk-0.qcow2)
 Renamed "vm-401-disk-0.qcow2" to "snap_vm-401-disk-0_id.qcow2" in volume group "lvm"
 Rounding up size to full physical extent 1.00 GiB
 Logical volume "vm-401-disk-0.qcow2" created.
 Formatting '/dev/lvm/vm-401-disk-0.qcow2', fmt=qcow2 cluster_size=131072 extended_l2=on preallocation=metadata compression_type=zlib size=1073741824 backing_file=snap_vm-401-disk-0_id.qcow2 backing_fmt=qcow2 lazy_refcounts=off refcount_bits=16
So it will rename the current active disk and create another QCOW formatted LVM volume, but pointing it to the snapshot image using the backing_file option. Neat.

4 August 2025

Scarlett Gately Moore: Fostering Constructive Communication in Open Source Communities

I write this in the wake of a personal attack against my work and a project that is near and dear to me. Instead of spreading vile rumors and hearsay, talk to me. I am not known to be hard to talk to and am wide open for productive communication. I am disheartened and would like to share some thoughts of the importance of communication. Thanks for listening. Open source development thrives on collaboration, shared knowledge, and mutual respect. Yet sometimes, the very passion that drives us to contribute can lead to misunderstandings and conflicts that harm both individuals and the projects we care about. As contributors, maintainers, and community members, we have a responsibility to foster environments where constructive dialogue flourishes.

The Foundation of Healthy Open Source Communities At its core, open source is about people coming together to build something greater than what any individual could create alone. This collaborative spirit requires more than just technical skills it demands emotional intelligence, empathy, and a commitment to treating one another with dignity and respect. When disagreements arise and they inevitably will the manner in which we handle them defines the character of our community. Technical debates should focus on the merits of ideas, implementations, and approaches, not on personal attacks or character assassinations conducted behind closed doors.

The Importance of Direct Communication One of the most damaging patterns in any community is when criticism travels through indirect channels while bypassing the person who could actually address the concerns. When we have legitimate technical disagreements or concerns about someone s work, the constructive path forward is always direct, respectful communication. Consider these approaches:
  • Address concerns directly: If you have technical objections to someone s work, engage with them directly through appropriate channels
  • Focus on specifics: Critique implementations, documentation, or processes not the person behind them
  • Assume good intentions: Most contributors are doing their best with the time and resources available to them
  • Offer solutions: Instead of just pointing out problems, suggest constructive alternatives

Supporting Contributors Through Challenges Open source contributors often juggle their community involvement with work, family, and personal challenges. Many are volunteers giving their time freely, while others may be going through difficult periods in their lives job searching, dealing with health issues, or facing other personal struggles. During these times, our response as a community matters enormously. A word of encouragement can sustain someone through tough periods, while harsh criticism delivered thoughtlessly can drive away valuable contributors permanently.

Building Resilient Communities Strong open source communities are built on several key principles: Transparency in Communication: Discussions about technical decisions should happen in public forums where all stakeholders can participate and learn from the discourse. Constructive Feedback Culture: Criticism should be specific, actionable, and delivered with the intent to improve rather than to tear down. Recognition of Contribution: Every contribution, whether it s code, documentation, bug reports, or community support, has value and deserves acknowledgment. Conflict Resolution Processes: Clear, fair procedures for handling disputes help prevent minor disagreements from escalating into community-damaging conflicts.

The Long View Many successful open source projects span decades, with contributors coming and going as their life circumstances change. The relationships we build and the culture we create today will determine whether these projects continue to attract and retain the diverse talent they need to thrive. When we invest in treating each other well even during disagreements we re investing in the long-term health of our projects and communities. We re creating spaces where innovation can flourish because people feel safe to experiment, learn from mistakes, and grow together.

Moving Forward Constructively If you find yourself in conflict with another community member, consider these steps:
  1. Take a breath: Strong emotions rarely lead to productive outcomes
  2. Seek to understand: What are the underlying concerns or motivations?
  3. Communicate directly: Reach out privately first, then publicly if necessary
  4. Focus on solutions: How can the situation be improved for everyone involved?
  5. Know when to step back: Sometimes the healthiest choice is to disengage from unproductive conflicts

A Call for Better Open source has given us incredible tools, technologies, and opportunities. The least we can do in return is treat each other with the respect and kindness that makes these collaborative achievements possible. Every contributor whether they re packaging software, writing documentation, fixing bugs, or supporting users is helping to build something remarkable. Let s make sure our communities are places where that work can continue to flourish, supported by constructive communication and mutual respect. The next time you encounter work you disagree with, ask yourself: How can I make this better? How can I help this contributor grow? How can I model the kind of community interaction I want to see? Our projects are only as strong as the communities that support them. Let s build communities worthy of the amazing software we create together. https://gofund.me/506c910c

Aigars Mahinovs: Snapshot mirroring in Debian (and Ubuntu)

Snapshot mirroring in Debian (and Ubuntu) The use of snapshots has been routine in both Debian and Ubuntu for several years now or more than 15 years for Debian, to be precise. Snapshots have become not only very reliable, but also an increasingly important part of the Debian package archive. This week, I encountered a problem at work that could be perfectly solved by correctly using the Snapshot service. However, while trying to figure it out, I ran into some shortcomings in the documentation. Until the docs are updated, I am publishing this blog post to make this information easier to find. Problem 1: Ensure fully reproducible creation of Docker containers with the exact same packages installed, even years after the original images were generated. Solution 1: Pin everything! Use a pinned source image in the FROM statement, such as debian:trixie-20250721-slim, and also pin the APT package sources to the "same" date - "20250722". Hint: The APT packages need to be newer than the Docker image base. If the APT packages are a bit newer, that's not a problem, as APT can upgrade packages without issues. However, if your Docker image has a newer package than your APT package sources, you will have a big problem. For example, if you have "libbearssl0" version 0.6-2 installed in the Docker image, but your package sources only have the older version 0.6-1, you will fail when trying to install the "libbearssl-dev" package. This is because you only have version 0.6-1 of the "-dev" package available, which hard-depends on exactly version 0.6-1 of "libbearssl0", and APT will refuse to downgrade an already installed package to satisfy that dependency. Problem 2: You are using a lot of images in a lot of executions and building tens of thousands of images per day. It would be a bad idea to put all this load on public Debian servers. Using local sources is also faster and adds extra security. Solution 2: Use local (transparently caching) mirrors for both the Docker Hub repository and the APT package source. At this point, I ran into another issue I could not easily figure out how to specify a local mirror for the snapshot part of the archive service. First of all, snapshot support in both Ubuntu and Debian accepts both syntaxes described in the Debian and Ubuntu documentation above. The documentation on both sites presents different approaches and syntax examples, but both work. The best approach nowadays is to use the "deb822" sources syntax. Remove /etc/apt/sources.list (if it still exists), delete all contents of the /etc/apt/sources.list.d directory, and instead create this file at /etc/apt/sources.list.d/debian.sources:
Types: deb
URIs: https://common.mirror-proxy.local/ftp.debian.org/debian/
Suites: trixie
Components: main non-free-firmware non-free contrib
Signed-By: /usr/share/keyrings/debian-archive-keyring.gpg
Snapshot: 20250722
Hint: This assumes you have a mirror service running at common.mirror-proxy.local that proxies requests (with caching) to whitelisted domains, based on the name of the first folder in the path. If you now run sudo apt update --print-uris, you will see that your configuration accesses your mirror, but does not actually use the snapshot. Next, add the following to /etc/apt/apt.conf.d/80snapshots:
APT::Snapshot "20250722";
That should work, right? Let's try sudo apt update --print-uris again. I've got good news and bad news! The good news is that we are now actually using the snapshot we specified (twice). The bad news is that we are completely ignoring the mirror and going directly to snapshots.debian.org instead. Finding the right information was a bit of a challenge, but after a few tries, this worked: to specify a custom local mirror of the Debian (or Ubuntu) snapshot service, simply add the following line to the same file, /etc/apt/apt.conf.d/80snapshots:
Acquire::Snapshots::URI::Override::Origin::debian "https://common.mirror-proxy.local/snapshot.debian.org/archive/debian/@SNAPSHOTID@/";
Now, if you check again with sudo apt update --print-uris, you will see that the requests go to your mirror and include the specified snapshot identifier. Success! Now you can install any packages you want, and everything will be completely local and fully reproducible, even years later!

Freexian Collaborators: Secure boot signing with Debusine (by Colin Watson)

Debusine aims to be an integrated solution to build, distribute and maintain a Debian-based distribution. At Debconf 25, we talked about using it to pre-test uploads to Debian unstable, and also touched on how Freexian is using it to help maintain the Debian LTS and ELTS projects. When Debian 10 (buster) moved to ELTS status in 2024, this came with a new difficulty that hadn t existed for earlier releases. Debian 10 added UEFI Secure Boot support, meaning that there are now signed variants of the boot loader and Linux kernel packages. Debian has a system where certain packages are configured as needing to be signed, and those packages include a template for a source package along with the unsigned objects themselves. The signing service generates detached signatures for all those objects, and then uses the template to build a source package that it uploads back to the archive for building in the usual way. Once buster moved to ELTS, it could no longer rely on Debian s signing service for all this. Freexian operates parallel infrastructure for the archive, and now needed to operate a parallel signing service as well. By early 2024 we were already planning to move ELTS infrastructure towards Debusine, and so it made sense to build a signing service there as well. Separately, we were able to obtain a Microsoft signature for Freexian s shim build, allowing us to chain this into the trust path for most deployed x86 machines. Freexian can help other organizations running Debian derivatives through the same process, and can provide secure signing infrastructure to the standards required for UEFI Secure Boot.

Prior art We considered both code-signing (Debian s current implementation) and lp-signing (Ubuntu s current implementation) as prior art. Neither was quite suitable for various reasons.
  • code-signing relies on polling a configured URL for each archive to fetch a GPG-signed list of signing requests, which would have been awkward for us to set up, and it assumes that unsigned packages are sufficiently trusted for it to be able to run dpkg -x and dpkg-source -b on them outside any containment. dpkg -x has had the occasional security vulnerability, so this seemed unwise for a service that might need to deal with signing packages for multiple customers.
  • lp-signing is a microservice accepting authenticated requests, and is careful to avoid needing to manipulate packages itself. However, this relies on a different and incompatible mechanism for indicating that packages should be signed, which wasn t something we wanted to introduce in ELTS.

Workers Debusine already had an established system of external workers that run tasks under various kinds of containment. This seems like a good fit: after all, what s a request to sign a package but a particular kind of task? But there are some problems here: workers can run essentially arbitrary code (such as build scripts in source packages), and even though that s under containment, we don t want to give such machines access to highly-sensitive data such as private keys. Fortunately, we d already introduced the idea of different kinds of workers a few months beforehand, in order to be able to run privileged server tasks that have direct access to the Debusine database. We built on that and added signing workers , which are much like external workers except that they only run signing tasks, no other types of tasks run on them, and they have access to a private database with information about the keys managed by their Debusine instance. (Django s support for multiple databases made this quite easy to arrange: we were able to keep everything in the same codebase.)

Key management It s obviously bad practice to store private key material in the clear, but at the same time the signing workers are essentially oracles that will return signatures on request while ensuring that the rest of Debusine has no access to private key material, so they need to be able to get hold of it themselves. Hardware security modules (HSMs) are designed for this kind of thing, but they can be inconvenient to manage when large numbers of keys are involved. Some keys are more valuable than others. If the signing key used for an experimental archive leaks, the harm is unlikely to be particularly serious; but if the ELTS signing key leaks, many customers will be affected. To match this, we implemented two key protection arrangements for the time being: one suitable for low-value keys encrypts the key in software with a configured key and stores the public key and ciphertext in the database, while one suitable for high-value keys stores keys as PKCS #11 URIs that can be set up manually by an instance administrator. We packaged some YubiHSM tools to make this easier for our sysadmins. The signing worker calls back to the Debusine server to check whether a given work request is authorized to use a given signing key. All operations related to private keys also produce an audit log entry in the private signing database, so we can track down any misuse.

Tasks Getting Debusine to do anything new usually requires figuring out how to model the operation as a task. In this case, that was complicated by wanting to run as little code as possible on the signing workers: in particular, we didn t want to do all the complicated package manipulations there. The approach we landed on was a chain of three tasks:
  • ExtractForSigning runs on a normal external worker. It takes the result of a package build and picks out the individual files from it that need to be signed, storing them as separate artifacts.
  • Sign runs on a signing worker, and (of course) makes the actual signatures, storing them as artifacts.
  • AssembleSignedSource runs on a normal external worker. It takes the signed artifacts and produces a source package containing them, based on the template found in the unsigned binary package.

Workflows Of course, we don t want people to have to create all those tasks directly and figure out how to connect everything together for themselves, and that s what workflows are good at. The make_signed_source workflow does all the heavy lifting of creating the right tasks with the right input data and making them depend on each other in the right ways, including fanning out multiple copies of all this if there are multiple architectures or multiple template packages involved. Since you probably don t want to stop at just having the signed source packages, it also kicks off builds to produce signed binary packages. Even this is too low-level for most people to use directly, so we wrapped it all up in our debian_pipeline workflow, which just needs to be given a few options to enable signing support (and those options can be locked down by workspace owners).

What s next? In most cases this work has been enough to allow ELTS to carry on issuing kernel security updates without too much disruption, which was the main goal; but there are other uses for a signing system. We included OpenPGP support from early on, which allows Debusine to sign its own builds, and we ll soon be extending that to sign APT repositories hosted by Debusine. The current key protection arrangements could use some work. Supporting automatically-generated software-encrypted keys and manually-generated keys in an HSM is fine as far as it goes, but it would be good to be able to have the best of both worlds by being able to automatically generate keys protected by an HSM. This needs some care, as HSMs often have quite small limits on the number of objects they can store at any one time, and the usual workaround is to export keys from the HSM under wrap (encrypted by a key known only to the HSM) so that they can be imported only when needed. We have a general idea of how to do this, but doing it efficiently will need care. We d be very interested in hearing from organizations that need this sort of thing, especially for Debian derivatives. Debusine provides lots of other features that can help you. Please get in touch with us at sales@freexian.com if any of this sounds useful to you.

3 August 2025

Aigars Mahinovs: Debconf 25 photos

Debconf 25 photos Debconf 25 came to the end in Brest, France this year a couple weeks ago. This has been a very different and unusually interesting Debconf. For me it was for two, related reasons: for one the conference was close enough in Western Europe that I could simply drive there with a car (which reminds me that I should make a blog post about the BMW i5, before I am done with it at the end of this year) and for the other - the conference is close enough to Western Europe that many other Debian developers could join this year who have not been seen at the event for many years. Being able to arrive early, decompress and spend extra time looking around the place made the event itself even more enjoyable than usual. The French cuisine, especially in its Breton expression, has been a very welcome treat. Even if there were some rough patches with the food selection, amount, or waiting, it was still a great experience. I specifically want to say a big thank you to the organisers for everything, but very explicitly for planning all the talk/BOF rooms in the same building and almost on the same floor. It saved me a lot of footwork, but also for other participants the short walks between the talks made it possible to always have a few minutes to talk to people or grab a croissant before running to the next talk. IMHO we should come back to a tradition of organising Debconf in Europe every 2-3 years. This maximises one of the main goals of Debconf - bringing as many Debian Developers as possible together in one physical location. This works best when the location is actually close to large concentrations of existing developers. In other years, the other goal of Debconf can then take priority - recruiting new developers in new locations. However, these goals could both be achieved at the same time - there are plenty of locations in Europe and even in Western Europe that still have good potential for attracting new developers. Especially if we focus on organising the event on the campuses of some larger technically-oriented universities. This year was also very productive for me a lot of conversations with various people about all kinds of topics, especially technical packaging questions. It has been a long time since the very basic foundations of Debian packaging work have been so fundamentally refactored and modernized as in the past year. Tag2upload has become a catalyst for git-based packaging and for automated workflows via Salsa, and all of that feeds back into focusing on a few best-supported packaging workflows. There is still a bit of a documentation gap of a new contributor getting to these modern packaging workflows from the point where the New Maintainers Guide stops. In any case, next year Debconf will be happening in Santa Fe, Argentina. And the year after that it is all still open and in a close competition between Japan, Spain, Portugal, Brazil and .. El Salvador? Personally, I would love to travel to Japan (again), but Spain or Portugal would also be great locations to meet more European developers again. As for Santa Fe ... it is quite likely that I will not be able to make it there next year, for (planned) health reasons. I guess I should also write a new blog post about what it means to be a Debconf Photographer, so that someone else could do this as well, and also reduce the "bus factor" along the way. But before that - here is the main group photo from this year: DebConf 25 Group photo You can also see it on: You can also enjoy the rest of the photos: Additionally, check out photos from other people on GIT LFS and consider adding your own photos there as well. Other places I have updated with up-to-date information are these wiki pages: If you took part in the playing cards event, then check your photo in this folder and link to your favourite from your line in the playing card wiki

Ben Hutchings: FOSS activity in July 2025

In July I attended DebCamp and DebConf in Brest, France. I very much enjoyed the opportunity to reconnect with other Debian contributors in person. I had a number of interesting and fruitful conversations there, besides the formally organised BoFs and talks. I also gave my own talk on What s new in the Linux kernel (and what s missing in Debian). Here s the usual categorisation of activity:

2 August 2025

Raju Devidas: Use phone/tablets/other laptops as external monitor with your laptop

This method is for wayland based systems. There are better ways to do this on GNOME or KDE desktops, but the method we are going to use is independent of DE/WM that you are using. I am doing this on sway window manager, but you can try this on any other Wayland based WM or DE. I have not tried this on Xorg based systems, there are several other guides for Xorg based systems online. When we connect a physical monitor to our laptops, it creates a second display output in our display settings that we can then re-arrange in layout, set resolution, set scale etc. Since we are not connecting via a physical interface like HDMI, DP, VGA etc. We need to create a virtual display within our system and set the display properties manually.
Get a list of current display outputs. You can also just check it in display settings of your DE/WM with wdisplays
rajudev@sanganak ~> swaymsg -t get_outputs
Output LVDS-1 &aposSeiko Epson Corporation 0x3047 Unknown&apos (focused)
  Current mode: 1366x768 @ 60.002 Hz
  Power: on
  Position: 0,0
  Scale factor: 1.000000
  Scale filter: nearest
  Subpixel hinting: rgb
  Transform: normal
  Workspace: 2
  Max render time: off
  Adaptive sync: disabled
  Allow tearing: no
  Available modes:
    1366x768 @ 60.002 Hz
altSingle physical display of the laptop
Currently we are seeing only one display output. Our goal is to create a second virtual display that we will then share on the tablet/phone. To do this there are various tools available. We are using sway-vdctl . It is currently not available within Debian packages, so we need to install it manually.
$ git clone https://github.com/odincat/sway-vdctl.git
$ cd sway-vdctl
$ cargo build --release
This will generate the binary with the name main under target/release . We can then copy this binary to our bin folder.
$ sudo cp target/release/main /usr/local/bin/vdctl
Now we have the vdctl command available.
$ vdctl --help
Usage: vdctl [OPTIONS] <ACTION> [VALUE]
Arguments:
  <ACTION>
          Possible values:
          - create:      Create new output based on a preset
          - kill:        Terminate / unplug an active preset
          - list:        List out active presets
          - next-number: Manually set the next output number, in case something breaks
          - sync-number: Sync the next output number using &aposswaymsg -t get_outputs&apos
  [VALUE]
          Preset name to apply, alternatively a value
          
          [default: ]
Options:
      --novnc
          do not launch a vnc server, just create the output
  -h, --help
          Print help (see a summary with &apos-h&apos)
Before creating the virtual display, we need to set it&aposs properties at .config/vdctl/config.json . I am using Xiaomi Pad 6 tablet as my external display. You can adjust the properties according to the device you want to use as a second display. $ (text-editor) .config/vdctl/config.json
 
    "host": "0.0.0.0",
    "presets": [
         
            "name": "pad6",
            "scale_factor": 2,
            "port": 9901,
            "resolution":  
                "width": 2800,
                "height": 1800
             
       
    ]
 
In the JSON, you can set the display resolution according to your external device and other configurations. If you want to configure multiple displays, you can add another entry into the presets in the json file. You can refer to example json file into the git repository. Now we need to actually create the virtual monitor.
$ vdctl create pad6
Created output, presumably &aposHEADLESS-1&apos
Set resolution of &aposHEADLESS-1&apos to 2800x1800
Set scale factor of &aposHEADLESS-1&apos to 2
Preset &apospad6&apos (&aposHEADLESS-1&apos: 2800x1800) is now active on port 9901
Now if you will check the display outputs in your display settings or from command line, you will see two different displays.
$ swaymsg -t get_outputs
Output LVDS-1 &aposSeiko Epson Corporation 0x3047 Unknown&apos
  Current mode: 1366x768 @ 60.002 Hz
  Power: on
  Position: 0,0
  Scale factor: 1.000000
  Scale filter: nearest
  Subpixel hinting: rgb
  Transform: normal
  Workspace: 2
  Max render time: off
  Adaptive sync: disabled
  Allow tearing: no
  Available modes:
    1366x768 @ 60.002 Hz
Output HEADLESS-1 &aposUnknown Unknown Unknown&apos (focused)
  Current mode: 2800x1800 @ 0.000 Hz
  Power: on
  Position: 1366,0
  Scale factor: 2.000000
  Scale filter: nearest
  Subpixel hinting: unknown
  Transform: normal
  Workspace: 3
  Max render time: off
  Adaptive sync: disabled
  Allow tearing: no
Also in the display settings.
altDisplay settings on Wayland with physical and virtual monitor output
Now we need to make this virtual display available over VNC which we will access with a VNC client on the tablet. To accomplish this I am using wayvnc but you can use any VNC server package. Install wayvnc
$ sudo apt install wayvnc
Now we will serve our virtual display HEADLESS-1 with wayvnc.
$ wayvnc -o HEADLESS-1 0.0.0.0 5900
You can adjust the port number as per your need. The process from laptop side is done. Now install any VNC software on your tablet. I am using AVNC, which is available on F-Droid. In the VNC software interface, add a new connection with the IP address of your laptop and the port started by wayvnc. Remember, both your laptop and phone need to be on the same Wi-Fi network.
altAVNC interface with the connection details to connect to the virtual monitor.
Save and connect. Now you will be able to see a extended display on your tablet. Enjoy working with multiple screens in a portable setup. Till next time.. Have a great time.

1 August 2025

puer-robustus: My Google Summer of Code '25 at Debian

I ve participated in this year s Google Summer of Code (GSoC) program and have been working on the small (90h) autopkgtests for the rsync package project at Debian.

Writing my proposal Before you can start writing a proposal, you need to select an organization you want to work with. Since many organizations participate in GSoC, I ve used the following criteria to narrow things down for me:
  • Programming language familiarity: For me only Python (preferably) as well as shell and Go projects would have made sense. While learning another programming language is cool, I wouldn t be as effective and helpful to the project as someone who is proficient in the language already.
  • Standing of the organization: Some of the organizations participating in GSoC are well-known for the outstanding quality of the software they produce. Debian is one of them, but so is e.g. the Django Foundation or PostgreSQL. And my thinking was that the higher the quality of the organization, the more there is to learn for me as a GSoC student.
  • Mentor interactions: Apart from the advantage you get from mentor feedback when writing your proposal (more on that further below), it is also helpful to gauge how responsive/helpful your potential mentor is during the application phase. This is important since you will be working together for a period of at least 2 months; if the mentor-student communication doesn t work, the GSoC project is going to be difficult.
  • Free and Open-Source Software (FOSS) communication platforms: I generally believe that FOSS projects should be built on FOSS infrastructure. I personally won t run proprietary software when I want to contribute to FOSS in my spare time.
  • Be a user of the project: As Eric S. Raymond has pointed out in his seminal The Cathedral and the Bazaar 25 years ago
    Every good work of software starts by scratching a developer s personal itch.
Once I had some organizations in mind whose projects I d be interested in working on, I started writing proposals for them. Turns out, I started writing my proposals way too late: In the end I only managed to hand in a single one which is risky. Competition for the GSoC projects is fierce and the more quality (!) proposals you send out, the better your chances are at getting one. However, don t write proposals for the sake of it: Reviewers get way too many AI slop proposals already and you will not do yourself a favor with a low-quality proposal. Take the time to read the instructions/ideas/problem descriptions the project mentors have provided and follow their guidelines. Don t hesitate to reach out to project mentors: In my case, I ve asked Samuel Henrique a few clarification questions whereby the following (email) discussion has helped me greatly in improving my proposal. Once I ve finalized my proposal draft, I ve sent it to Samuel for a review, which again led to some improvements to the final proposal which I ve uploaded to the GSoC program webpage.

Community bonding period Once you get the information that you ve been accepted into the GSoC program (don t take it personally if you don t make it; this was my second attempt after not making the cut in 2024), get in touch with your prospective mentor ASAP. Agree upon a communication channel and some response times. Put yourself in the loop for project news and discussions whatever that means in the context of your organization: In Debian s case this boiled down to subscribing to a bunch of mailing lists and IRC channels. Also make sure to setup a functioning development environment if you haven t done so for writing the proposal already.

Payoneer setup The by far most annoying part of GSoC for me. But since you don t have a choice if you want to get the stipend, you will need to signup for an account at Payoneer. In this iteration of GSoC all participants got a personalized link to open a Payoneer account. When I tried to open an account by following this link, I got an email after the registration and email verification that my account is being blocked because Payoneer deems the email adress I gave a temporary one. Well, the email in question is most certainly anything but temporary, so I tried to get in touch with the Payoneer support - and ended up in an LLM-infused kafkaesque support hell. Emails are answered by an LLM which for me meant utterly off-topic replies and no help whatsoever. The Payoneer website offers a real-time chat, but it is yet another instance of a bullshit-spewing LLM bot. When I at last tried to call them (the support lines are not listed on the Payoneer website but were provided by the GSoC program), I kid you not, I was being told that their platform is currently suffering from technical problems and was hung up on. Only thanks to the swift and helpful support of the GSoC administrators (who get priority support from Payoneer) I was able to setup a Payoneer account in the end. Apart from showing no respect to customers, Payoneer is also ripping them off big time with fees (unless you get paid in USD). They charge you 2% for currency conversions to EUR on top of the FX spread they take. What worked for me to avoid all of those fees, was to open a USD account at Wise and have Payoneer transfer my GSoC stipend in USD to that account. Then I exchanged the USD to my local currency at Wise for significantly less than Payoneer would have charged me. Also make sure to close your Payoneer account after the end of GSoC to avoid their annual fee.

Project work With all this prelude out of the way, I can finally get to the actual work I ve been doing over the course of my GSoC project.

Background The upstream rsync project generally sees little development. Nonetheless, they released version 3.4.0 including some CVE fixes earlier this year. Unfortunately, their changes broke the -H flag. Now, Debian package maintainers need to apply those security fixes to the package versions in the Debian repositories; and those are typically a bit older. Which usually means that the patches cannot be applied as is but will need some amendments by the Debian maintainers. For these cases it is helpful to have autopkgtests defined, which check the package s functionality in an automated way upon every build. The question then is, why should the tests not be written upstream such that regressions are caught in the development rather than the distribution process? There s a lot to say on this question and it probably depends a lot on the package at hand, but for rsync the main benefits are twofold:
  1. The upstream project mocks the ssh connection over which rsync is most typically used. Mocking is better than nothing but not the real thing. In addition to being a more realisitic test scenario for the typical rsync use case, involving an ssh server in the test would automatically extend the overall resilience of Debian packages as now new versions of the openssh-server package in Debian benefit from the test cases in the rsync reverse dependency.
  2. The upstream rsync test framework is somewhat idiosyncratic and difficult to port to reimplementations of rsync. Given that the original rsync upstream sees little development, an extensive test suit further downstream can serve as a threshold for drop-in replacements for rsync.

Goal(s) At the start of the project, the Debian rsync package was just running (a part of) the upstream tests as autopkgtests. The relevant snippet from the build log for the rsync_3.4.1+ds1-3 package reads:
114s ------------------------------------------------------------
114s ----- overall results:
114s 36 passed
114s 7 skipped
Samuel and I agreed that it would be a good first milestone to make the skipped tests run. Afterwards, I should write some rsync test cases for local calls, i.e. without an ssh connection, effectively using rsync as a more powerful cp. And once that was done, I should extend the tests such that they run over an active ssh connection. With these milestones, I went to work.

Upstream tests Running the seven skipped upstream tests turned out to be fairly straightforward:
  • Two upstream tests concern access control lists and extended filesystem attributes. For these tests to run they rely on functionality provided by the acl and xattr Debian packages. Adding those to the Build-Depends list in the debian/control file of the rsync Debian package repo made them run.
  • Four upstream tests required root privileges to run. The autopkgtest tool knows the needs-root restriction for that reason. However, Samuel and I agreed that the tests should not exclusively run with root privileges. So, instead of just adding the restiction to the existing autopkgtest test, we created a new one which has the needs-root restriction and runs the upstream-tests-as-root script - which is nothing else than a symlink to the existing upstream-tests script.
The commits to implement these changes can be found in this merge request. The careful reader will have noticed that I only made 2 + 4 = 6 upstream test cases run out of 7: The leftover upstream test is checking the functionality of the --ctimes rsync option. In the context of Debian, the problem is that the Linux kernel doesn t have a syscall to set the creation time of a file. As long as that is the case, this test will always be skipped for the Debian package.

Local tests When it came to writing Debian specific test cases I started of a completely clean slate. Which is a blessing and a curse at the same time: You have full flexibility but also full responsibility. There were a few things to consider at this point in time:
  • Which language to write the tests in? The programming language I am most proficient in is Python. But testing a CLI tool in Python would have been weird: it would have meant that I d have to make repeated subprocess calls to run rsync and then read from the filesystem to get the file statistics I want to check. Samuel suggested I stick with shell scripts and make use of diffoscope - one of the main tools used and maintained by the Reproducible Builds project - to check whether the file contents and file metadata are as expected after rsync calls. Since I did not have good reasons to use bash, I ve decided to write the scripts to be POSIX compliant.
  • How to avoid boilerplate? If one makes use of a testing framework, which one? Writing the tests would involve quite a bit of boilerplate, mostly related to giving informative output on and during the test run, preparing the file structure we want to run rsync on, and cleaning the files up after the test has run. It would be very repetitive and in violation of DRY to have the code for this appear in every test. Good testing frameworks should provide convenience functions for these tasks. shunit2 comes with those functions, is packaged for Debian, and given that it is already being used in the curl project, I decided to go with it.
  • Do we use the same directory structure and files for every test or should every test have an individual setup? The tradeoff in this question being test isolation vs. idiosyncratic code. If every test has its own setup, it takes a) more work to write the test and b) more work to understand the differences between tests. However, one can be sure that changes to the setup in one test will have no side effects on other tests. In my opinion, this guarantee was worth the additional effort in writing/reading the tests.
Having made these decisions, I simply started writing tests and ran into issues very quickly.

rsync and subsecond mtime diffs When testing the rsync --times option, I observed a weird phenomenon: If the source and destination file have modification times which differ only in the nanoseconds, an rsync --times call will not synchronize the modification times. More details about this behavior and examples can be found in the upstream issue I raised. In the Debian tests we had to occasionally work around this by setting the timestamps explicitly with touch -d.
diffoscope regression In one test case, I was expecting a difference in the modification times but diffoscope would not report a diff. After a good amount of time spent on debugging the problem (my default, and usually correct, assumption is that something about my code is seriously broken if I run into issues like that), I was able to show that diffoscope only displayed this behavior in the version in the unstable suite, not on Debian stable (which I am running on my development machine). Since everything pointed to a regression in the diffoscope project and with diffoscope being written in Python, a language I am familiar with, I wanted to spend some time investigating (and hopefully fixing) the problem. Running git bisect on the diffoscope repo helped me in identifying the commit which introduced the regression: The commit contained an optimization via an early return for bit-by-bit identical files. Unfortunately, the early return also caused an explicitly requested metadata comparison (which could be different between the files) to be skipped. With a nicely diagnosed issue like that, I was able to go to a local hackerspace event, where people work on FOSS together for an evening every month. In a group, we were able to first, write a test which showcases the broken behavior in the latest diffoscope version, and second, make a fix to the code such that the same test passes going forward. All details can be found in this merge request.
shunit2 failures At some point I had a few autopkgtests setup and passing, but adding a new one would throw me totally inexplicable errors. After trying to isolate the problem as much as possible, it turns out that shunit2 doesn t play well together we the -e shell option. The project mentions this in the release notes for the 2.1.8 version1, but in my opinion a constraint this severe should be featured much more prominently, e.g. in the README.

Tests over an ssh connection The centrepiece of this project; everything else has in a way only been preparation for this. Obviously, the goal was to reuse the previously written local tests in some way. Not only because lazy me would have less work to do this way, but also because of a reduced long-term maintenance burden of one rather than two test sets. As it turns out, it is actually possible to accomplish that: The remote-tests script doesn t do much apart from starting an ssh server on localhost and running the local-tests script with the REMOTE environment variable set. The REMOTE environment variable changes the behavior of the local-tests script in such a way that it prepends "$REMOTE": to the destination of the rsync invocations. And given that we set REMOTE=rsync@localhost in the remote-tests script, local-tests copies the files to the exact same locations as before, just over ssh. The implementational details for this can be found in this merge request.

proposed-updates Most of my development work on the Debian rsync package took place during the Debian freeze as the release of Debian Trixie is just around the corner. This means that uploading by Debian Developers (DD) and Debian Maintainers (DM) to the unstable suite is discouraged as it makes migrating the packages to testing more difficult for the Debian release team. If DDs/DMs want to have the package version in unstable migrated to testing during the freeze they have to file an unblock request. Samuel has done this twice (1, 2) for my work for Trixie but has asked me to file the proposed-updates request for current stable (i.e. Debian Bookworm) myself after I ve backported my tests to bookworm.

Unfinished business To run the upstream tests which check access control list and extended file system attributes functionality, I ve added the acl and xattr packages to Build-Depends in debian/control. This, however, will only make the packages available at build time: If Debian users install the rsync package, the acl and xattr packages will not be installed alongside it. For that, the dependencies would have to be added to Depends or Suggests in debian/control. Depends is probably to strong of a relation since rsync clearly works well in practice without, but adding them to Suggests might be worthwhile. A decision on this would involve checking, what happens if rsync is called with the relevant options on a host machine which has those packages installed, but where the destination machine lacks them. Apart from the issue described above, the 15 tests I managed to write are are a drop in the water in light of the infinitude of rsync options and their combinations. Most glaringly, not all options of the --archive option are covered separately (which would help indicating what code path of rsync broke in a regression). To increase the likelihood of catching regressions with the autopkgtests, the test coverage should be extended in the future.

Conclusion Generally, I am happy with my contributions to Debian over the course of my small GSoC project: I ve created an extensible, easy to understand, and working autopkgtest setup for the Debian rsync package. There are two things which bother me, however:
  1. In hindsight, I probably shouldn t have gone with shunit2 as a testing framework. The fact that it behaves erratically with the -e flag is a serious drawback for a shell testing framework: You really don t want a shell command to fail silently and the test to continue running.
  2. As alluded to in the previous section, I m not particularly proud of the number of tests I managed to write.
On the other hand, finding and fixing the regression in diffoscope - while derailing me from the GSoC project itself - might have a redeeming quality.

DebConf25 By sheer luck I happened to work on a GSoC project at Debian over a time period during which the annual Debian conference would take place close enough to my place of residence. Samuel pointed the opportunity to attend DebConf out to me during the community bonding period and since I could make time for the event in my schedule, I signed up. DebConf was a great experience which - aside from gaining more knowledge about Debian development - allowed me to meet the actual people usually hidden behind email adresses and IRC nicks. I can wholeheartedly recommend attending a DebConf to every interested Debian user! For those who have missed this year s iteration of the conference, I can recommend the following recorded talks: While not featuring as a keynote speaker (understandably so as the newcomer to Debian community that I am), I could still contribute a bit to the conference program.

GSoC project presentation The Debian Outreach team has scheduled a session in which all GSoC and Outreachy students over the past year had the chance to present their work in a lightning talk. The session has been recorded and is available online, just like my slides and the source for them.

Debian install workshop Additionally, with so many Debian experts gathering in one place while KDE s End of 10 campaign is ongoing, I felt it natural to organize a Debian install workhop. In hindsight I can say that I underestimated how much work it would be, especially for me who does not speak a word of French. But although the turnout of people who wanted us to install Linux on their machines was disappointingly low, it was still worth it: Not only because the material in the repo can be helpful to others planning install workshops but also because it was nice to meet a) the person behind the Debian installer images and b) the local Brest/Finist re Linux user group as well as the motivated and helpful people at Infini.

Credits I want to thank the Open Source team at Google for organizing GSoC: The highly structured program with a one-to-one mentorship is a great avenue to start contributing to well established and at times intimidating FOSS projects. And as much as I disagree with Google s surveillance capitalist business model, I have to give it to them that the company at least takes its responsibility for FOSS (somewhat) seriously - unlike many other businesses which rely on FOSS and choose to freeride of it. Big thanks to the Debian community! I ve experienced nothing but friendliness in my interactions with the community. And lastly, the biggest thanks to my GSoC mentor Samuel Henrique. He has dealt patiently and competently with all my stupid newbie questions. His support enabled me to make - albeit small - contributions to Debian. It has been a pleasure to work with him during GSoC and I m looking forward to working together with him in the future.

  1. Obviously, I ve only read them after experiencing the problem.

31 July 2025

Russell Coker: Links July 2025

Louis Rossman made an informative YouTube video about right to repair and the US military [1]. This is really important as it helps promote free software and open standards. The ACM has an insightful article about hidden controls [2]. We need EU regulations about hidden controls in safety critical systems like cars. This Daily WTF article has some interesting security implications for Windows [3]. Earth.com has an interesting article about the rubber hand illusion and how it works on Octopus [4]. For a long time I have been opposed to eating Octopus because I think they are too intelligent. The Washington Post has an insightful article about the future of spies when everything is tracked by technology [5]. Micah Lee wrote an informative guide to using Signal groups for activism [6]. David Brin wrote an insightful blog post about the phases of the ongoing US civil war [7]. Christian Kastner wrote an interesting blog post about using Glibc hardware capabilities to use different builds of a shared library for a range of CPU features [8]. David Brin wrote an insightful and interesting blog post comparing President Carter with the criminals in the Republican party [9].

Next.

Previous.