Search Results: "spa"

24 December 2014

Joey Hess: generating shell scripts from haskell using a shell monad

Shell script is the lingua franca of Unix, it's available everywhere and often the only reasonable choice to Get Stuff Done. But it's also clumsy and it's easy to write unsafe shell scripts, that forget to quote variables, typo names of functions, etc. Wouldn't it be nice if we could write code in some better language, that generated nicely formed shell scripts and avoided such gotchas? Today, I've built a Haskell monad that can generate shell code. Here's a fairly involved example. This demonstrates several features, including the variadic cmd, the ability to define shell functions, to bind and use shell variables, to build pipes (with the -:- operator), and to factor out generally useful haskell functions like pipeLess and promptFor ...
santa = script $ do
    hohoho <- func $
        cmd "echo" "Ho, ho, ho!" "Merry xmas!"
    hohoho
    promptFor "What's your name?" $ \name -> pipeLess $ do
        cmd "echo" "Let's see what's in" (val name <> quote "'s") "stocking!"
        forCmd (cmd "ls" "-1" (quote "/home/" <> val name)) $ \f -> do
            cmd "echo" "a shiny new" f
            hohoho
    cmd "rm" "/table/cookies" "/table/milk"
    hohoho
pipeLess :: Script () -> Script ()
pipeLess c = c - - cmd "less"
promptFor :: T.Text -> (Var -> Script ()) -> Script ()
promptFor prompt cont = do
    cmd "printf" (prompt <> " ")
    var <- newVar "prompt"
    readVar var
    cont var
When run, that haskell program generates this shell code. Which, while machine-generated, has nice indentation, and is generally pretty readable.
#!/bin/sh
f1 ()   :
    echo 'Ho, ho, ho!' 'Merry xmas!'
 
f1
printf 'What'"'"'s your name?  '
read '_prompt1'
(
    echo 'Let'"'"'s see what'"'"'s in' "$_prompt1"''"'"'s' 'stocking!'
    for _x1 in $(ls '-1' '/home/'"$_prompt1")
    do :
        echo 'a shiny new' "$_x1"
        f1
    done
)   (
    less
)
rm '/table/cookies' '/table/milk'
f1
Santa has already uploaded shell-monad to hackage and git. There's a lot of things that could be added to this library (if, while, redirection, etc), but I can already see using it in various parts of propellor and git-annex that need to generate shell code.

23 December 2014

Dirk Eddelbuettel: RcppEigen 0.3.2.3.0

A new release of RcppEigen is now on CRAN, and will get to Debian shortly. This is thanks to a fabulous pull request by Yixuan Qiu who single-handedly managed to upgrade to the new minor release of Eigen -- after having expanded the unit tests a few weeks earlier in another pull request. The NEWS file entry follows.
Changes in RcppEigen version 0.3.2.3.0 (2014-12-22)
  • Updated to version 3.2.3 of Eigen
  • Added a number of additional unit tests for wrap, transform and sparse
  • Updated one of the examples
Courtesy of CRANberries, there is also a diffstat report for the most recent release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Ulrike Uhlig: How does my AppArmor profile get into Debian?

I have spent the last days trying to understand the relationship between AppArmor, the AppArmor profiles and Debian s AppArmor profiles. Let me try to briefly introduce you to this. First of all, let me emphasize that one needs to distinguish between AppArmor, the kernel module, and the AppArmor profiles, which define rules for application confinement. As stated on the project s wiki:
The AppArmor project source is split between the kernel module, available in the Linux kernel and git development tree and the user space tools available in launchpad.
So, we can find the upstream AppArmor profile development taking place at Canonical s launchpad. The profiles which are developed there serve as a basis for those included in Debian. It is thus useful to try to contribute to this upstream when updating a profile for Debian. Since AppArmor 2.9 has been introduced, the rules of a profiles which are not applicable for a system are ignored. Thus, collaboration between different Linux distributions shipping AppArmor will become much simpler. In the aforementioned Ubuntu repository you can find the profiles that are currently in development. Once tested and ready, they are removed from this repository and finally included into the corresponding package. For example, the profile for Evince, the GNOME PDF viewer, is available in the evince package. In Debian on the contrary, there are only some packages which ship their own profiles. This concernes for example bind, clamav, cups, tor.
But many profiles are not yet included with their package, but instead delivered through the apparmor-profiles and apparmor-profiles-extra packages. These are maintained by the the Debian AppArmor packaging team. The team takes care of merging changes from the upstream profiles into Debian. Today, the relationship between Upstream and Debian looks like this:

Upstream/bzr

Debian source package

Debian binary package

Ubuntu source package

Ubuntu binary package

apparmor

apparmor

apparmor-profiles

-

-

apparmor-profiles

apparmor-profiles-extra

apparmor-profiles-extra

-

-

ubuntu-evince

apparmor-profiles-extra

apparmor-profiles-extra

evince

evince

In the future, this should change. It would indeed be desirable that package maintainers include profiles with the packages they maintain and take care of updating them accordingly when the package itself is updated. It is much more logical to to it that way, as changes in a package like Pidgin or Evince can occur at a different point in time then when the apparmor-profiles-extra package is updated. I started working on a documentation for Debian Package Maintainers which describes how to do this.

Vincent Bernat: Eudyptula Challenge: superfast Linux kernel booting

The Eudyptula Challenge is a series of programming exercises for the Linux kernel, that start from a very basic Hello world kernel module, moving on up in complexity to getting patches accepted into the main Linux kernel source tree.
One of the first tasks of this quite interesting challenge is to compile and boot your own kernel. eudyptula-boot is a self-contained shell script to boot any kernel image to a shell. It is packed with the following features: In the following video, eudyptula-boot is used to boot the host kernel and execute a few commands:
In the next one, we use it to boot a custom kernel with an additional system call. This is the fifteenth task of the Eudyptula Challenge. A test program is used to check that the system call is working as expected. Additionaly, we demonstrate how to attach a debugger to the running kernel.
While this hack could be used to run containers3 with an increased isolation, the performance of the 9p filesystem is unfortunately quite poor.

  1. The only requirement is to have 9p virtio support enabled. This can easily be enabled with make kvmconfig.
  2. Only udev is started.
  3. A good way to start a container is to combine --root, --force and --exec parameters. Add --readwrite to the mix if you want to keep the modifications.

Michael Stapelberg: Debian Code Search: taming the latency tail

It s been a couple of weeks since I ve launched Debian Code Search Instant, so people have had the chance to use it for a while and that gives me plenty of data points to look at :-). For every query, I log the search term itself as well as the duration the query took to execute. That way, I can easily identify queries that take a long time and see why that is. There is a class of queries for which Debian Code Search (DCS) doesn t perform so well, and that s queries that consist of trigrams which are extremely common. Whenever DCS receives such a query, it needs to search through a lot of files. Note that it doesn t really matter if there are plenty of results or not it s the number of files that potentially contain a result which matters. One such query is arse (we get a lot of curse words). It consists of only two trigrams ( ars and rse ), which are extremely common in program source code. As a couple of examples, the terms parse , sparse , charset and coarse are all matched by that. As an aside, if you really want to search for just arse , use word boundaries, i.e. \barse\b , which also makes the query significantly faster. Fixing the overloaded frontend When DCS first received the query, arse would lead to our frontend server crashing. That was due to (intentionally) unoptimized code we were aggregating all search results from all 6 source backends in memory, sorted them, and then wrote them out to disk. I addressed this in commit d2922fe92 with the following measures:
  1. Instead of keeping the entire result in memory, just write the result to a temporary file on disk ( unsorted.json ) and store pointers into that file in memory, i.e. (offset, length) tuples. In order to sort the results, we also need to store the ranking and the path (to resolve ties and thereby guarantee a stable result order over multiple search queries). For grouping the results by source package, we need to keep the package name.
  2. If you think about it, you don t need the entire path in order to break a tie the hash is enough, as it defines an ordering. That ordering may be different, but any ordering is good enough for the purpose of merely breaking a tie in a deterministic way. I m using Go s hash/fnv, the only non-cryptographic (fast!) hash function that is included in Go s standard library.
  3. Since this was still leading to Out Of Memory errors, I decided to not store a copy of the package name in each search result, but rather use a pointer into a string pool containing all package names. The number of source package names is relatively small, in the order of 20,000, whereas the number of search results can be in the millions. Using the stringpool is a clear win the overhead in the case where #results < #srcpackages is negligible, but as soon as #results > #srcpackages, you save memory.
With all of that fixed, the query became at all possible, albeit with a runtime of around 20 minutes. Double Writing When running such a long-running query, I noticed that the query ran smooth for a while, but then it took multiple seconds without any visible progress at the end of the query before the results appeared. This was due to the frontend ranking the results and then converting unsorted.json into actual result pages. Since we provide results ordered by ranking, but also results grouped by source packages, it was writing every result twice to disk. What s even worse is that due to re-ordering, every read was essentially random (as opposed to sequential reads). What s even worse is that nobody will ever click through all the hundreds of thousands of result pages, so they are prepared entirely in vain. Therefore, with commit c744b236e I made the frontend generate these result pages on demand. This cut down the time for the ranking phase at the end of each query from 20-30 seconds (for big queries) to typically less than one second. Profiling/Monitoring After adding monitoring to each of the source-backends, I realized that during these long-running queries, the disk I/O and network I/O was nowhere near my expectations: each source-backend was sending only a low single-digit number of megabytes per second back to the frontend (typically somewhere between 1 MB/s and 3 MB/s). This didn t match up at all with the bandwidth I observed in earlier performance tests, so I used wget -O /dev/null to send a query and discard the result in order to get some theoretical performance numbers. Suddenly, I was getting more than 10 MB/s worth of results, maxing out the disks with a read rate of about 200 MB/s. So where is the bottleneck? I double-checked that neither the CPU on any of our VMs, nor the network between them was saturated. Note that as of this point, the CPU of the frontend was at roughly 70% (of one core), which didn t seem a lot to me. Then, I followed this excellent tutorial on profiling Go programs to see where the frontend is spending its time. Turns out, the biggest consumer of CPU time was the encoding/json Go package, which is used for deserializing results received from the backend and serializing them again before sending them to the client. Since I was curious about it for a while already, I decided to give cap n proto a try to replace JSON as serialization mechanism for communication between the source backends and the frontend. Switching to it (commit 8efd3b41) brought down the CPU load immensely, and made the query a bit faster. In addition, I killed the next biggest consumer: the lseek(2) syscall, which we used to call with SEEK_CUR and an offset of 0 so that it would tell us the current position. This was necessary in the first place because we don t know in advance how many bytes we re going to write when serializing a result to disk. The replacement is a neat little trick:
type countingWriter int64
func (c *countingWriter) Write(p []byte) (n int, err error)  
    *c += countingWriter(len(p))
    return len(p), nil
 
// [ ]
// Then, use an io.MultiWriter like this:
var written countingWriter
w := io.MultiWriter(s.tempFiles[backendidx], &written)
result.WriteJSON(w)
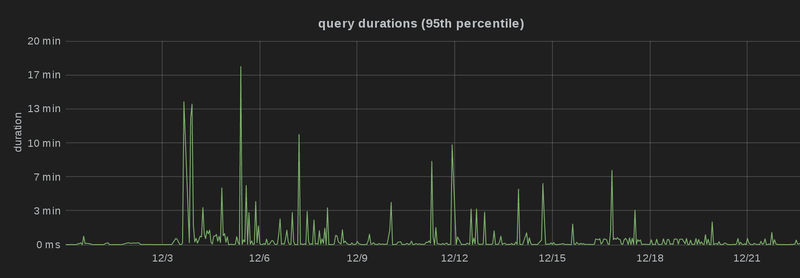
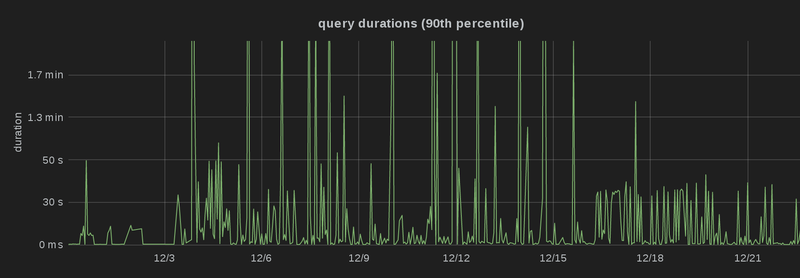
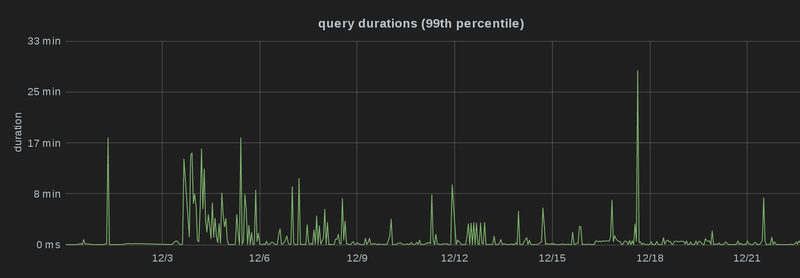
With some more profiling, the new bottleneck was suddenly the read(2) syscall, issued by the cap n proto deserialization, operating directly on the network connection buffer. strace revealed that crunching through the results of one source backend for a long query, read(2) was called about 250,000 times. By simply using a buffered reader (commit 684467ae), I could reduce that to about 2,000 times. Another bottleneck was the fact that for every processed result, the frontend needed to update the query state, which is shared amongst all goroutines (there is one goroutine for each source backend). All that parallelism isn t very effective if you need to synchronize the state updates in the end. So with commit 5d46a572, I refactored the state to be per-backend, so that locking is only necessary for the first couple of results, and the vast vast majority of results can be processed entirely without locking. This brought down the query time from 20 minutes to about 5 minutes, but I still wasn t happy with the bandwidth: the frontend was doing a bit over 10 MB/s of reads from all source backends combined, whereas with wget I could get around 40 MB/s with the same query. At this point, the CPU utilization was around 7% of one core on the frontend, and profiling didn t immediately reveal an obvious culprit. After a bit of experimenting (by commenting out code here and there ;-)), I figured out that the problem was that the frontend was still converting these results from capnproto buffers to JSON. While that doesn t take a lot of CPU time, it delays the network stream from the source-backend: once the local and remote TCP buffers are full, the source-backend will (intentionally!) not continue with its search, so that it doesn t run out of memory. I m still convinced that s a good idea, and in fact I was able to solve the problem in an elegant way: instead of writing JSON to disk and generating result pages on demand, we now write capnproto directly to disk (commit 466b7f3e) and convert it to JSON only before sending out the result pages. That decreases the overall CPU time since we only need to convert a small fraction of the results to JSON, but most importantly, the frontend is now not in the critical path anymore. It can directly pass the data through, and in fact it uses an io.TeeReader to do exactly that. Conclusion With all of these optimizations, we re now down to about 2.5 minutes for the search query arse , and the architecture of the system actually got simpler to reason about. Most importantly, though, the optimizations don t only play out for a single query, but for many different queries. I ve deployed the optimized version at the 15th of December 2014, and you can see that the 99th, 95th and 90th percentile latency dropped significantly, i.e. there are a lot fewer spikes than before, and more queries are processed faster, which is particularly obvious in the third graph (which is capped at 2 minutes):

Russell Coker: wp-spamshield

Yesterday I installed the wp-spamshield plugin for WordPress [1]. It blocks automated comment spam systems by using JavaScript and cookies, apparently most spammers can t handle that. Before I installed it I was getting hundreds of spam comments per day even with the block spam by math plugin enabled. Now I ve had it running for 24 hours without any spam. The real advantage of this is that now when a legitimate comment gets flagged as spam I ll notice it, previously I was deleting hundreds or thousands of comments at a time without reading them. deb http://www.coker.com.au wheezy wordpress The above repository has the wordpress-wp-spamshield package for Debian/Wheezy. I have no immediate plans for uploading it to Debian because the security support for WordPress plugins doesn t fit in with the Debian model. I am prepared to negotiate about this if someone has good reasons for including it or any of the other WordPress plugins I ve packages. My packaging work is under the GPL (of course) so any DD who disagrees with me could just rebuild the package and upload it. Within Debian there is no rule taking another DD s GPL d code that they decided not to upload and then uploading it. There is a consensus that such things are not appropriate without permission, but anyone who wishes can take this blog post as permission.

21 December 2014

Russ Allbery: Review: 2014 Hugos: Novelettes

Review: 2014 Hugos: Novelettes, edited by Loncon 3
Publisher: Loncon 3
Copyright: 2014
Format: Kindle
This is another weird "book review" covering the Hugo-nominated novelettes for the 2014 Hugos (given for works published in 2014) at Loncon 3, the 2014 Worldcon. The "editor" is the pool of attendees and supporting members who chose to nominate works, all of which had been previously edited by other editors in their original publication. I received all of these as part of the Hugo voter's packet for being a supporting member, but they all appear to be available for free on the Internet (at least at the time of this writing). "The Exchange Officers" by Brad Torgersen: An okay, if not particularly ground-breaking, military SF story, ruined for me by the ham-handed introduction of superficial jingoism. The protagonists are doing a tour as remote operators of humanoid battle suits in orbit: not a new premise, but a servicable one. Since this is military SF, they predictably have to defend a space installation against attackers. So we get a bit of drama, a bit of zero-g combat, and the fun of people learning how to remotely operate suits. You've probably read this before, but it passes the time reasonably well. Unfortunately, Torgersen decided to make the villains the Chinese military for no adequately-explained reason. (Well, I'm being kind; I suspect the reason is the standard yellow peril nonsense, but that's less generous.) So there is snide commentary about how only the military understand the Chinese threat and a fair bit of old-fashioned jingoism mixed in to the story, to its detriment. If you like this sort of thing, it's a typical example, although it escapes me why people thought it was exceptional enough to warrant nomination. (5) "The Lady Astronaut of Mars" by Mary Robinette Kowal: Once again, my clear favorite among the stories also won, which is a lovely pattern. Elma was the female astronaut in an alternate history in which manned space exploration continued to grow, leading to permanent settlement on Mars. She spent lots of time being photographed, being the smiling face of the space program, while her husband worked on the math and engineering of the launches. Now, she's an old woman, taking care of her failing and frail husband, her career behind her. Or so she thinks, before an offer that forces an impossible choice between space and staying with her husband for his final days. This is indeed the tear-jerker that it sounds like, but it's not as maudlin as it might sound. Kowal does an excellent job with Elma's characterization: she's no-nonsense, old enough to be confident in her opinions, and knows how to navigate through the world. The story is mixed with nostalgia and memories, including a reminder of just what Elma meant to others. It touches on heroism, symbolism, and the horrible choices around dying loved ones, but I thought it did so deftly and with grace. I was expecting the story to be too obvious, but I found I enjoyed the quotidian feel. It's not a story to read if you want to be surprised, but I loved the small touches. (9) "Opera Vita Aeterna" by Vox Day: Before the review, a note that I consider obligatory. The author of this story is an aggressively misogynistic white supremacist, well-known online for referring to black people as savages and arguing women should not be allowed to vote. To what extent you choose to take that into account when judging his fiction is up to you, but I don't think it should go unsaid. "Opera Vita Aeterna" is the story of a monastery in a typical fantasy world (at least as far as one can tell from this story; readers of Vox Day's fantasy series will probably know more background). At the start of the story, it gets an unexpected visit from an elf. Not just any elf, either, but one of the most powerful magicians of his society. He comes to the monastery out of curiousity about the god that the monks worship and stays for a project of illuminating their scriptures, while having theological debates with the abbot. This story is certainly not the offensive tirade that you might expect from its author. Its biggest problem is that nothing of substance happens in the story, either theologically or via more conventional action. It's a lot of description, a lot of talking, a lot of warmed-over Christian apologetics that dodges most of the hard problems, and a lot of assertions that the elf finds something of interest in this monastery. I can believe this could be the case, but Vox Day doesn't really show why. There is, at the end of the story, some actual drama, but I found it disappointing and pointless. It leads nowhere. The theology has the same problem: elves supposedly have no souls, which is should be the heart of a theological question or conflict Vox Day is constructing, but that conflict dies without any resolution. We know nothing more about the theology of this world at the end of the story than we do at the beginning. Some of the descriptions here aren't bad, and the atmosphere seems to want to develop into a story. But that development never happens, leaving the whole work feeling fundamentally pointless. (4) "The Truth of Fact, the Truth of Feelng" by Ted Chiang: This is another oddly-constructed story, although I think a bit more successful. It's a story in two interwoven parts. One is a fictional essay, told in a non-fiction style, about a man living in a future world with ubiquitous life recording and very efficient search software. Any part of one's life can be easily found and reviewed. The other is the story of a boy from a tribal culture during European colonialism. He learns to read and write, and from that a respect for written records, which come into conflict with the stories that the tribe elders tell about the past. The purpose of both of these stories is to question both the value and the implications of recording everything in a way that preserves and guarantees the facts instead of individual interpretations. The boy's story calls this into question; the narrator's story offers ambiguous support for its value and a deeper plea for giving people space to change. I found the style a bit difficult to get used to, since much of it did not feel like a story. But it grew on me as I read it, and the questions Chiang raises have stuck with me since. The problem of how and when to allow for change in others when we have perfect (or at least vastly improved) memory is both important and complicated, and this is one of the better presentations of the problem that I've seen. It's more of a think-y piece, and closer to non-fiction than a story, but I thought it was worth reading. (8) "The Waiting Stars" by Aliette de Bodard: I keep wanting to like de Bodard's space opera world of AIs and living ships, but it never quite works for me. I've read several stories set in this universe now, and it has some neat ideas, but I always struggle with the characters. This story at least doesn't have quite as much gruesome pregnancy as the previous ones (although there's still some). "The Waiting Stars" opens with a raid on a ship graveyard, an attempt to rescue and "reboot" an AI starship under the guidance of another Mind. This is intermixed with another story about a woman who was apparently rescued in childhood from birthing ship Minds and raised in a sort of foster institution. This feels like a flashback at first, but its interaction with the rest of the story is something more complicated. The conceptual trick de Bodard pulls here is thought-provoking, but once again I struggled to care about all of the characters. I also found the ending discouraging and unsatisfying, which didn't help. Someone who isn't me might really like this story, but it wasn't my thing. (6) Rating: 6 out of 10

Dirk Eddelbuettel: If only there was a Romeo somewhere ...

Attention: rant coming. You have been warned, and may want to tune out now. So the top of my Twitter timeline just had a re-tweet posting to this marvel on the state of Julia. I should have known better than to glance at it as it comes from someone providing (as per the side-bar) Thought leadership in Big Data, systems architecture and more. Reading something like this violates the first rule of airport book stores: never touch anything from the business school section, especially on (wait for it) leadership or, worse yet, thought leadership. But it is Sunday, my first cup of coffee still warm (after finalising two R package updates on GitHub, and one upload to CRAN) and so I read on. Only to be mildly appalled by the usual comparison to R based on the same old Fibonacci sequence. Look, I am as guilty as anyone of using it (for example all over chapter one of my Rcpp book), but at least I try to stress each and every time that this is kicking R where it is down as its (fairly) poor performance on functions calls (that is well-known and documented) obviously gets aggravated by recursive calls. But hey, for the record, let me restate those results. So Julia beats R by a factor of 385. But let's take a closer look. For n=25, I get R to take 241 milliseconds---as opposed to his 6905 milliseconds---simply by using the same function I use in every workshop, eg last used at Penn in November, which does not use the dreaded ifelse operator:
fibR <- function(n)  
  if (n < 2) return(n)
  return(fibR(n-1) + fibR(n-2))
 
Switching that to the standard C++ three-liner using Rcpp
library(Rcpp)
cppFunction('int fibCpp(int n)   
  if (n < 2) return(n);  
  return(fibCpp(n-1) + fibCpp(n-2));  
   ')
and running a standard benchmark suite gets us the usual result of
R> library(rbenchmark)
R> benchmark(fibR(25),fibCpp(25),order="relative")[,1:4]
        test replications elapsed relative
2 fibCpp(25)          100   0.048    1.000
1   fibR(25)          100  24.674  514.042
R> 
So for the record as we need this later: that is 48 milliseconds for 100 replications, or about 0.48 milliseconds per run. Now Julia. And of my standard Ubuntu server running the current release 14.10:
edd@max:~$ julia
ERROR: could not open file /home/edd//home/edd//etc/julia/juliarc.jl
 in include at boot.jl:238
edd@max:~$ 
So wait, what? You guys can't even ensure a working release on what is probably the most popular and common Linux installation? And I get to that after reading a post on the importance of "Community, Community, Community" and you can't even make sure this works on Ubuntu? Really? So a little bit of googling later, I see that julia -f is my friend for this flawed release, and I can try to replicate the original timing
edd@max:~$ julia -f
               _
   _       _ _(_)_        A fresh approach to technical computing
  (_)       (_) (_)       Documentation: http://docs.julialang.org
   _ _   _   _  __ _      Type "help()" to list help topics
               / _      
       _        (_        Version 0.2.1 (2014-02-11 06:30 UTC)
 _/  \__'_ _ _ \__'_      
 __/                      x86_64-linux-gnu
julia> fib(n) = n < 2 ? n : fib(n - 1) + fib(n - 2)
fib (generic function with 1 method)
julia> @elapsed fib(25)
0.002299559
julia> 
Interestingly the posts author claims 18 milliseconds. I see 2.3 milliseconds here. Maybe someone is having a hard time comparing things to the right of the decimal point. Or maybe his computer is an order of magnitude slower than mine. The more important thing is that Julia is of course faster than R (no surprise: LLVM at work) but also still a lot slower than a (trivial to write and deploy) C++ function. Nothing new here. So let's recap. Comparison to R was based on a flawed version of a function we only use when we deliberately want to put R down, can be improved significantly when using a better implementation, results are still off by order of magnitude to what was reported ("math is hard"), and the standard C / C++ way of doing things is still several times faster than our new saviour language---which I can't even launch on the current version of one of the more common free operating systems. Ok then. Someone please wake me up in a few years and I will try again. Now, coming to the end of the rant I should really stress that of course I too hope that Julia succeeds. Every user pulled away from Matlab is a win for all us. We're in this together and the endless navel gazing between ourselves is so tiresome and irrelevant. And as I argue here, even more so when we among ourselves stick to unfair comparisons as well as badly chosen implementation details. What matters are wins against the likes of Matlab, Excel, SAS and so on. Let's build on our joint strength. I am sure I will use Julia one day, and I am grateful for everyone helping with it---as a lot of help seems to be needed. In the meantime, and with CRAN at 6130 packages that just work I'll continue to make use of this amazing community and trying my bit to help it grow and prosper. As part of our joint community.

Steve McIntyre: UEFI Debian installer work for Jessie, part 2

A month ago , I wrote about my plans for improved (U)EFI support in Jessie. It's about time I gave an update on progress! I spoke about adding support for installing grub-efi into the removable media path (#746662). That went into Debian's grub packages already, but there were a couple of bugs. First of all, the code could end up prompting people about EFI questions even when they didn't have any grub-efi packages installed. Doh! (#773004). Then there was an unexpected bug with case-insensitive file name handling on FAT/VFAT filesystems (#773092). I've posted (and tested!) patches to fix both, hopefully in an upload any day now. Next, I mentioned getting i386 UEFI support going again. This is a major feature that a lot of people have been asking for. It's also going to involve quite a bit of effort... Our existing (amd64) UEFI-capable images in Debian use the standard x86 El Torito CD boot method, with two boot images provided. One of these images gives us the traditional isolinux BIOS-boot support. The second option is an alternate El Torito image, including at a 64-bit version of grub-efi. For most machines, this works just fine - the BIOS or UEFI firmware will automatically pick the correct image and everybody's happy. This even works on our multi-arch i386/amd64 CDs and DVDs - isolinux will boot either kernel from the first El Torito image, or the alternate UEFI image is amd64 only. However, I can now see that there's been a long-standing issue with those multi-arch images, and it's to do with Macs. On the advice of Matthew Garrett, I've borrowed an old 32-bit Intel Mac to help testing, and it's quite instructive in terms of buggy firmware! The firmware on older 32-bit Intel Macs crashes hard when it detects more than one El Torito boot image, and I've now seen this happen myself. I've not had any bug reports about this, so I can only assume that we haven't had many users try that image. As far as I can tell, they've been using the normal i386 images in BIOS boot mode, and then struggling to get bootloaders working afterwards. There are a number of different posts on the net explaining how to do that. That's OK, but... If I now start adding 32-bit UEFI support to our standard set of i386 images, this will prevent users of old Macs from installing Debian. I could just say "screw it" and decide to not support those users at all, but that's not a very nice thing to do. If we want to continue to support them and add 32-bit UEFI support, I'll have to add another flavour of i386 image, either a "Mac special" or a "32-bit UEFI special". I'm not keen on doing that if I could avoid it, but the two options are mutually exclusive. Given the Mac problem is only on older hardware which (hopefully!) will be dying out, I'll probably pick that one as the special-case CD, and I'll make an extra netinst flavour only for those users to boot off. So, I've started playing with i386 UEFI stuff in the last couple of weeks too. I almost immediately found some showstopper behaviour bugs in the i386 versions of efivar and efibootmgr (#773412 and #773007), but I've debugged these with our Debian maintainer (Jared Dominguez) and the upstream developer (Peter Jones) and fixes should be in Jessie very soon. As I mentioned last month, the machines that most people have been requesting support for are the latest Bay Trail-based laptops and tablets. There are using 64-bit Intel Atom CPUs, but crippled with 32-bit UEFI firmware with no BIOS compatibility mode. This makes for some interesting issues. It's probably impossible to get a true answer why these machines are so broken by design, but there are several rumours. As far as I can see, most of these machines seem to ship with a limited version of 32-bit Windows 8.1. 32-bit Windows is smaller than 64-bit Windows, so fits much better in limited on-board storage space. But 32-bit Windows won't boot from 64-bit UEFI, so the firmware needed buggering to match. Ugh! To support these Bay Trail machines properly, we'll want to add a 32-bit UEFI installation option to our 64-bit images. I can tweak our CDs so that both 32-bit and 64-bit versions of grub-efi are included, and the on-board UEFI will load the right one needed. Then I'll need to make sure that all the 64-bit images also include grub-efi-ia32-bin from now on. With some extra logic, we'll need to remember that these new machines need that package installing instead of grub-efi-amd64-bin. It shouldn't be too hard, but let's see! :-) So, I've been out and bought one of these machines, an Asus X205TA. Lucas agreed that Debian will reimburse me (thanks!), so I'm not stuck with spending my own money on an otherwise unwanted machine! I can see via Google that none of the mainstream Linux distros support the Bay Trail machines fully yet, so there's not a lot of documentation yet. Initial boot on the new machine was easy using a quick-hack i386 UEFI image on USB, but from there everything went downhill quickly. I'll need to investigate some more, but the laptop's own keyboard and trackpad are not detected by the installer system. Neither is its built-in WiFi. Yay! I had to go and dig out a USB hub to connect the installer image USB key, a keyboard, mouse and a USB hard drive to the machine, as it only has 2 USB ports. I've taken a complete backup of the on-board 32GB flash before I start experimenting, so I can restore the machine back to its virgin state for future testing. I guess I now have a project to keep me busy over Christmas...! In other news, we've been continuing work on UEFI support for and within the new arm64 port. My ARM/Linaro colleague Leif Lindholm has been back-porting upstream kernel features and bug fixes to make d-i work, and filing Debian bugs when silly things break on arm64 because people don't think about other architectures (e.g #773311, doh!). As there are more and more people interested in (U)EFI support these days, I've also proposed that we create a new debian-efi mailing list to help focus discussion. See #773327 and follow up there if you think you'd use the list too! You can help! Same as 2 years ago, I'll need help testing some of these images. For the 32-bit UEFI support, I now have some relevant hardware myself, but testing on other machines too will be very important! I'll start pushing unofficial Jessie EFI test images shortly - watch this space.

20 December 2014

Rudy Godoy: Apache Phoenix for Cloudera CDH

Apache Phoenix is a relational database layer over HBase delivered as a client-embedded JDBC driver targeting low latency queries over HBase data. Apache Phoenix takes your SQL query, compiles it into a series of HBase scans, and orchestrates the running of those scans to produce regular JDBC result sets. What the above statement means for developers or data scientists is that you can talk SQL to your HBase cluster. Sounds good right? Setting up Phoenix on Cloudera CDH can be really frustrating and time-consuming. I wrapped-up references from across the web with my own findings to have both play nice. Building Apache Phoenix Because of dependency mismatch for the pre-built binaries, supporting Cloudera s CDH requires to build Phoenix using the versions that match the CDH deployment. The CDH version I used is CDH4.7.0. This guide applies for any version of CDH4+. Note: You can find CDH components version in the CDH Packaging and Tarball Information section for the Cloudera Release Guide . Current release information (CDH5.2.1) is available in this link. Preparing Phoenix build environment Phoenix can be built using maven or gradle. General instructions can be found in the Building Phoenix Project webpage. Before building Phoenix you need to have: Checkout correct Phoenix branch Phoenix has two major release versions: Clone the Phoenix git repository
git clone https://github.com/apache/phoenix.git
Work with the correct branch
git fetch origin
git checkout 3.2
Modify dependencies to match CDH Before building Phoenix, you will need to modify the dependencies to match the version of CDH you are trying to support. Edit phoenix/pom.xml and do the following changes: Add Cloudera s Maven repository
+  <repository>
+  <id>cloudera</id>
+  https://repository.cloudera.com/artifactory/cloudera-repos/
+  </repository>
Change component versions to match CDH s.
  
-  <hadoop-one.version>1.0.4</hadoop-one.version>
-  <hadoop-two.version>2.0.4-alpha</hadoop-two.version>
+  <hadoop-one.version>2.0.0-mr1-cdh4.7.0</hadoop-one.version>
+  <hadoop-two.version>2.0.0-cdh4.7.0</hadoop-two.version>
  <!-- Dependency versions -->
-  <hbase.version>0.94.19
+  <hbase.version>0.94.15-cdh4.7.0
  <commons-cli.version>1.2</commons-cli.version>
-  <hadoop.version>1.0.4
+  <hadoop.version>2.0.0-cdh4.7.0
  <pig.version>0.12.0</pig.version>
  <jackson.version>1.8.8</jackson.version>
  <antlr.version>3.5</antlr.version>
  <log4j.version>1.2.16</log4j.version>
  <slf4j-api.version>1.4.3.jar</slf4j-api.version>
  <slf4j-log4j.version>1.4.3</slf4j-log4j.version>
-  <protobuf-java.version>2.4.0</protobuf-java.version>
+  <protobuf-java.version>2.4.0a</protobuf-java.version>
  <commons-configuration.version>1.6</commons-configuration.version>
  <commons-io.version>2.1</commons-io.version>
  <commons-lang.version>2.5</commons-lang.version>
Change target version, only if you are building for Java 6. CDH4 is built for JRE 6.
  <artifactId>maven-compiler-plugin</artifactId>
  <version>3.0</version>
  <configuration>
-  <source>1.7</source>
-  <target>1.7</target>
+  <source>1.6</source>
+  <target>1.6</target>
  </configuration>
Phoenix building Once, you have made the changes you are set to build Phoenix. Our CDH4.7.0 cluster uses Hadoop 2, so make sure to activate the hadoop2 profile.
mvn package -DskipTests -Dhadoop.profile=2
If everything goes well, you should see the following result:
[INFO] ------------------------------------------------------------------------
[INFO] Reactor Summary:
[INFO]
[INFO] Apache Phoenix .................................... SUCCESS [2.729s]
[INFO] Phoenix Hadoop Compatibility ...................... SUCCESS [0.882s]
[INFO] Phoenix Core ...................................... SUCCESS [24.040s]
[INFO] Phoenix - Flume ................................... SUCCESS [1.679s]
[INFO] Phoenix - Pig ..................................... SUCCESS [1.741s]
[INFO] Phoenix Hadoop2 Compatibility ..................... SUCCESS [0.200s]
[INFO] Phoenix Assembly .................................. SUCCESS [30.176s]
[INFO] ------------------------------------------------------------------------
[INFO] BUILD SUCCESS
[INFO] ------------------------------------------------------------------------
[INFO] Total time: 1:02.186s
[INFO] Finished at: Mon Dec 15 13:18:48 PET 2014
[INFO] Final Memory: 45M/1330M
[INFO] ------------------------------------------------------------------------
Phoenix Server component deployment Since Phoenix is a JDBC layer on top of HBase a server component has to be deployed on every HBase node. The goal is to have Phoenix server component added to HBase classpath. You can achieve this goal either by copying the server component directly to HBase s lib directory, or copy the component to an alternative path then modify HBase classpath definition. For the first approach, do:
cp phoenix-assembly/target/phoenix-3.2.3-SNAPSHOT-server.jar /opt/cloudera/parcels/CDH/lib/hbase/lib/
Note: In this case CDH is a synlink to the current active CDH version. For the second approach, do:
cp phoenix-assembly/target/phoenix-3.2.3-SNAPSHOT-server.jar /opt/phoenix/
Then add the following line to /etc/hbase/conf/hbase-env.sh
/etc/hbase/conf/hbase-env.sh
export HBASE_CLASSPATH_PREFIX=/opt/phoenix/phoenix-3.2.3-SNAPSHOT-server.jar
Wether you ve used any of the methods, you have to restart HBase. If you are using Cloudera Manager, restart the HBase service. To validate that Phoenix is on HBase class path, do:
sudo -u hbase hbase classpath   tr ':' '\n'   grep phoenix
Phoenix server validation Phoenix provides a set of client tools that you can use to validate the server component functioning. However, since we are supporting CDH4.7.0 we ll need to make few changes to such utilities so they use the correct dependencies. phoenix/bin/sqlline.py: sqlline.py is a wrapper for the JDBC client, it provides a SQL console interface to HBase through Phoenix.
index f48e527..bf06148 100755
--- a/bin/sqlline.py
+++ b/bin/sqlline.py
@@ -53,7 +53,8 @@ colorSetting = "true"
 if os.name == 'nt':
  colorSetting = "false"
-java_cmd = 'java -cp "' + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
+extrajars="/opt/cloudera/parcels/CDH/lib/hadoop/lib/commons-collections-3.2.1.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-auth-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-common-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcerls/CDH/lib/oozie/libserver/hbase-0.94.15-cdh4.7.0.jar"
+java_cmd = 'java -cp ".' + os.pathsep + extrajars + os.pathsep + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
  '" -Dlog4j.configuration=file:' + \
  os.path.join(phoenix_utils.current_dir, "log4j.properties") + \
  " sqlline.SqlLine -d org.apache.phoenix.jdbc.PhoenixDriver \
phoenix/bin/psql.py: psql.py is a wrapper tool that can be used to create and populate HBase tables.
index 34a95df..b61fde4 100755
--- a/bin/psql.py
+++ b/bin/psql.py
@@ -34,7 +34,8 @@ else:
 # HBase configuration folder path (where hbase-site.xml reside) for
 # HBase/Phoenix client side property override
-java_cmd = 'java -cp "' + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
+extrajars="/opt/cloudera/parcels/CDH/lib/hadoop/lib/commons-collections-3.2.1.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-auth-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-common-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcerls/CDH/lib/oozie/libserver/hbase-0.94.15-cdh4.7.0.jar"
+java_cmd = 'java -cp ".' + os.pathsep + extrajars + os.pathsep + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
  '" -Dlog4j.configuration=file:' + \
  os.path.join(phoenix_utils.current_dir, "log4j.properties") + \
  " org.apache.phoenix.util.PhoenixRuntime " + args
After you have done such changes you can test connectivity by issuing the following commands:
./bin/sqlline.py zookeeper.local
Setting property: [isolation, TRANSACTION_READ_COMMITTED]
issuing: !connect jdbc:phoenix:zookeeper.local none none org.apache.phoenix.jdbc.PhoenixDriver
Connecting to jdbc:phoenix:zookeeper.local
14/12/16 19:26:10 WARN conf.Configuration: dfs.df.interval is deprecated. Instead, use fs.df.interval
14/12/16 19:26:10 WARN conf.Configuration: hadoop.native.lib is deprecated. Instead, use io.native.lib.available
14/12/16 19:26:10 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
14/12/16 19:26:10 WARN conf.Configuration: topology.script.number.args is deprecated. Instead, use net.topology.script.number.args
14/12/16 19:26:10 WARN conf.Configuration: dfs.umaskmode is deprecated. Instead, use fs.permissions.umask-mode
14/12/16 19:26:10 WARN conf.Configuration: topology.node.switch.mapping.impl is deprecated. Instead, use net.topology.node.switch.mapping.impl
14/12/16 19:26:11 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
14/12/16 19:26:11 WARN util.NativeCodeLoader: Unable to load native-hadoop library for your platform... using builtin-java classes where applicable
14/12/16 19:26:12 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
Connected to: Phoenix (version 3.2)
Driver: PhoenixEmbeddedDriver (version 3.2)
Autocommit status: true
Transaction isolation: TRANSACTION_READ_COMMITTED
Building list of tables and columns for tab-completion (set fastconnect to true to skip)...
77/77 (100%) Done
Done
sqlline version 1.1.2
0: jdbc:phoenix:zookeeper.local>
Then, you can either issue SQL-commands or Phoenix-commands.
0: jdbc:phoenix:zookeeper.local> !tables
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+
  TABLE_CAT    TABLE_SCHEM    TABLE_NAME    TABLE_TYPE  
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+
  null    SYSTEM    CATALOG    SYSTEM TABLE   
  null    SYSTEM    SEQUENCE    SYSTEM TABLE   
  null    SYSTEM    STATS    SYSTEM TABLE   
  null    null    STOCK_SYMBOL    TABLE   
  null    null    WEB_STAT    TABLE   
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+

19 December 2014

Steve Kemp: Switched to using attic for backups

Even though seeing the word attic reminds me too much of leaking roofs and CVS, I've switched to using the attic backup tool. I want a simple system which will take incremental backups, perform duplication-elimination (to avoid taking too much space), support encryption, and be fast. I stopped using backup2l because the .tar.gz files were too annoying, and it was too slow. I started using obnam because I respect Lars and his exceptionally thorough testing-regime, but had to stop using it when things started getting "too slow". I'll document the usage/installation in the future. For the moment the only annoyance is that it is contained in the Jessie archive, not the Wheezy one. Right now only 2/19 of my hosts are Jessie.

17 December 2014

Keith Packard: MST-monitors

Multi-Stream Transport 4k Monitors and X I'm sure you've seen a 4k monitor on a friends desk running Mac OS X or Windows and are all ready to go get one so that you can use it under Linux. Once you've managed to acquire one, I'm afraid you'll discover that when you plug it in, you're limited to 30Hz refresh rates at the full size, unless you're running a kernel that is version 3.17 or later. And then... Good Grief! What Is My Computer Doing! Ok, so now you're running version 3.17 and when X starts up, it's like you're using a gigantic version of Google Cardboard. Two copies of a very tall, but very narrow screen greets you. Welcome to MST island. In order to drive these giant new panels at full speed, there isn't enough bandwidth in the display hardware to individually paint each pixel once during each frame. So, like all good hardware engineers, they invented a clever hack. This clever hack paints the screen in parallel. I'm assuming that they've got two bits of display hardware, each one hooked up to half of the monitor. Now, each paints only half of the pixels, avoiding costly redesign of expensive silicon, at least that's my surmise. In the olden days, if you did this, you'd end up running two monitor cables to your computer, and potentially even having two video cards. Today, thanks to the magic of Display Port Multi-Stream Transport, we don't need all of that; instead, MST allows us to pack multiple cables-worth of data into a single cable. I doubt the inventors of MST intended it to be used to split a single LCD panel into multiple "monitors", but hardware engineers are clever folk and are more than capable of abusing standards like this when it serves to save a buck. Turning Two Back Into One We've got lots of APIs that expose monitor information in the system, and across which we might be able to wave our magic abstraction wand to fix this:
  1. The KMS API. This is the kernel interface which is used by all graphics stuff, including user-space applications and the frame buffer console. Solve the problem here and it works everywhere automatically.
  2. The libdrm API. This is just the KMS ioctls wrapped in a simple C library. Fixing things here wouldn't make fbcons work, but would at least get all of the window systems working.
  3. Every 2D X driver. (Yeah, we're trying to replace all of these with the one true X driver). Fixing the problem here would mean that all X desktops would work. However, that's a lot of code to hack, so we'll skip this.
  4. The X server RandR code. More plausible than fixing every driver, this also makes X desktops work.
  5. The RandR library. If not in the X server itself, how about over in user space in the RandR protocol library? Well, the problem here is that we've now got two of them (Xlib and xcb), and the xcb one is auto-generated from the protocol descriptions. Not plausible.
  6. The Xinerama code in the X server. Xinerama is how we did multi-monitor stuff before RandR existed. These days, RandR provides Xinerama emulation, but we've been telling people to switch to RandR directly.
  7. Some new API. Awesome. Ok, so if we haven't fixed this in any existing API we control (kernel/libdrm/X.org), then we effectively dump the problem into the laps of the desktop and application developers. Given how long it's taken them to adopt current RandR stuff, providing yet another complication in their lives won't make them very happy.
All Our APIs Suck Dave Airlie merged MST support into the kernel for version 3.17 in the simplest possible fashion -- pushing the problem out to user space. I was initially vaguely tempted to go poke at it and try to fix things there, but he eventually convinced me that it just wasn't feasible. It turns out that all of our fancy new modesetting APIs describe the hardware in more detail than any application actually cares about. In particular, we expose a huge array of hardware objects: Each of these objects exposes intimate details about the underlying hardware -- which of them can work together, and which cannot; what kinds of limits are there on data rates and formats; and pixel-level timing details about blanking periods and refresh rates. To make things work, some piece of code needs to actually hook things up, and explain to the user why the configuration they want just isn't possible. The sticking point we reached was that when an MST monitor gets plugged in, it needs two CRTCs to drive it. If one of those is already in use by some other output, there's just no way you can steal it for MST mode. Another problem -- we expose EDID data and actual video mode timings. Our MST monitor has two EDID blocks, one for each half. They happen to describe how they're related, and how you should configure them, but if we want to hide that from the application, we'll have to pull those EDID blocks apart and construct a new one. The same goes for video modes; we'll have to construct ones for MST mode. Every single one of our APIs exposes enough of this information to be dangerous. Every one, except Xinerama. All it talks about is a list of rectangles, each of which represents a logical view into the desktop. Did I mention we've been encouraging people to stop using this? And that some of them listened to us? Foolishly? Dave's Tiling Property Dave hacked up the X server to parse the EDID strings and communicate the layout information to clients through an output property. Then he hacked up the gnome code to parse that property and build a RandR configuration that would work. Then, he changed to RandR Xinerama code to also parse the TILE properties and to fix up the data seen by application from that. This works well enough to get a desktop running correctly, assuming that desktop uses Xinerama to fetch this data. Alas, gtk has been "fixed" to use RandR if you have RandR version 1.3 or later. No biscuit for us today. Adding RandR Monitors RandR doesn't have enough data types yet, so I decided that what we wanted to do was create another one; maybe that would solve this problem. Ok, so what clients mostly want to know is which bits of the screen are going to be stuck together and should be treated as a single unit. With current RandR, that's some of the information included in a CRTC. You pull the pixel size out of the associated mode, physical size out of the associated outputs and the position from the CRTC itself. Most of that information is available through Xinerama too; it's just missing physical sizes and any kind of labeling to help the user understand which monitor you're talking about. The other problem with Xinerama is that it cannot be configured by clients; the existing RandR implementation constructs the Xinerama data directly from the RandR CRTC settings. Dave's Tiling property changes edit that data to reflect the union of associated monitors as a single Xinerama rectangle. Allowing the Xinerama data to be configured by clients would fix our 4k MST monitor problem as well as solving the longstanding video wall, WiDi and VNC troubles. All of those want to create logical monitor areas within the screen under client control What I've done is create a new RandR datatype, the "Monitor", which is a rectangular area of the screen which defines a rectangular region of the screen. Each monitor has the following data: There are three requests to define, delete and list monitors. And that's it. Now, we want the list of monitors to completely describe the environment, and yet we don't want existing tools to break completely. So, we need some way to automatically construct monitors from the existing RandR state while still letting the user override portions of it as needed to explain virtual or tiled outputs. So, what I did was to let the client specify a list of outputs for each monitor. All of the CRTCs which aren't associated with an output in any client-defined monitor are then added to the list of monitors reported back to clients. That means that clients need only define monitors for things they understand, and they can leave the other bits alone and the server will do something sensible. The second tricky bit is that if you specify an empty rectangle at 0,0 for the pixel geometry, then the server will automatically compute the geometry using the list of outputs provided. That means that if any of those outputs get disabled or reconfigured, the Monitor associated with them will appear to change as well. Current Status Gtk+ has been switched to use RandR for RandR versions 1.3 or later. Locally, I hacked libXrandr to override the RandR version through an environment variable, set that to 1.2 and Gtk+ happily reverts back to Xinerama and things work fine. I suspect the plan here will be to have it use the new Monitors when present as those provide the same info that it was pulling out of RandR's CRTCs. KDE appears to still use Xinerama data for this, so it "just works". Where's the code As usual, all of the code for this is in a collection of git repositories in my home directory on fd.o:
git://people.freedesktop.org/~keithp/randrproto master
git://people.freedesktop.org/~keithp/libXrandr master
git://people.freedesktop.org/~keithp/xrandr master
git://people.freedesktop.org/~keithp/xserver randr-monitors
RandR protocol changes Here's the new sections added to randrproto.txt
                   
1.5. Introduction to version 1.5 of the extension
Version 1.5 adds monitors
   A 'Monitor' is a rectangular subset of the screen which represents
   a coherent collection of pixels presented to the user.
   Each Monitor is be associated with a list of outputs (which may be
   empty).
   When clients define monitors, the associated outputs are removed from
   existing Monitors. If removing the output causes the list for that
   monitor to become empty, that monitor will be deleted.
   For active CRTCs that have no output associated with any
   client-defined Monitor, one server-defined monitor will
   automatically be defined of the first Output associated with them.
   When defining a monitor, setting the geometry to all zeros will
   cause that monitor to dynamically track the bounding box of the
   active outputs associated with them
This new object separates the physical configuration of the hardware
from the logical subsets  the screen that applications should
consider as single viewable areas.
1.5.1. Relationship between Monitors and Xinerama
Xinerama's information now comes from the Monitors instead of directly
from the CRTCs. The Monitor marked as Primary will be listed first.
                   
5.6. Protocol Types added in version 1.5 of the extension
MONITORINFO   name: ATOM
          primary: BOOL
          automatic: BOOL
          x: INT16
          y: INT16
          width: CARD16
          height: CARD16
          width-in-millimeters: CARD32
          height-in-millimeters: CARD32
          outputs: LISTofOUTPUT  
                   
7.5. Extension Requests added in version 1.5 of the extension.
 
    RRGetMonitors
    window : WINDOW
      
    timestamp: TIMESTAMP
    monitors: LISTofMONITORINFO
 
    Errors: Window
    Returns the list of Monitors for the screen containing
    'window'.
    'timestamp' indicates the server time when the list of
    monitors last changed.
 
    RRSetMonitor
    window : WINDOW
    info: MONITORINFO
 
    Errors: Window, Output, Atom, Value
    Create a new monitor. Any existing Monitor of the same name is deleted.
    'name' must be a valid atom or an Atom error results.
    'name' must not match the name of any Output on the screen, or
    a Value error results.
    If 'info.outputs' is non-empty, and if x, y, width, height are all
    zero, then the Monitor geometry will be dynamically defined to
    be the bounding box of the geometry of the active CRTCs
    associated with them.
    If 'name' matches an existing Monitor on the screen, the
    existing one will be deleted as if RRDeleteMonitor were called.
    For each output in 'info.outputs, each one is removed from all
    pre-existing Monitors. If removing the output causes the list of
    outputs for that Monitor to become empty, then that Monitor will
    be deleted as if RRDeleteMonitor were called.
    Only one monitor per screen may be primary. If 'info.primary'
    is true, then the primary value will be set to false on all
    other monitors on the screen.
    RRSetMonitor generates a ConfigureNotify event on the root
    window of the screen.
 
    RRDeleteMonitor
    window : WINDOW
    name: ATOM
 
    Errors: Window, Atom, Value
    Deletes the named Monitor.
    'name' must be a valid atom or an Atom error results.
    'name' must match the name of a Monitor on the screen, or a
    Value error results.
    RRDeleteMonitor generates a ConfigureNotify event on the root
    window of the screen.
                   

15 December 2014

Gustavo Noronha Silva: Web Engines Hackfest 2014

For the 6th year in a row, Igalia has organized a hackfest focused on web engines. The 5 years before this one were actually focused on the GTK+ port of WebKit, but the number of web engines that matter to us as Free Software developers and consultancies has grown, and so has the scope of the hackfest. It was a very productive and exciting event. It has already been covered by Manuel Rego, Philippe Normand, Sebastian Dr ge and Andy Wingo! I am sure more blog posts will pop up. We had Martin Robinson telling us about the new Servo engine that Mozilla has been developing as a proof of concept for both Rust as a language for building big, complex products and for doing layout in parallel. Andy gave us a very good summary of where JS engines are in terms of performance and features. We had talks about CSS grid layouts, TyGL a GL-powered implementation of the 2D painting backend in WebKit, the new Wayland port, announced by Zan Dobersek, and a lot more. With help from my colleague ChangSeok OH, I presented a description of how a team at Collabora led by Marco Barisione made the combination of WebKitGTK+ and GNOME s web browser a pretty good experience for the Raspberry Pi. It took a not so small amount of both pragmatic limitations and hacks to get to a multi-tab browser that can play youtube videos and be quite responsive, but we were very happy with how well WebKitGTK+ worked as a base for that. One of my main goals for the hackfest was to help drive features that were lingering in the bug tracker for WebKitGTK+. I picked up a patch that had gone through a number of iterations and rewrites: the HTML5 notifications support, and with help from Carlos Garcia, managed to finish it and land it at the last day of the hackfest! It provides new signals that can be used to authorize notifications, show and close them. To make notifications work in the best case scenario, the only thing that the API user needs to do is handle the permission request, since we provide a default implementation for the show and close signals that uses libnotify if it is available when building WebKitGTK+. Originally our intention was to use GNotification for the default implementation of those signals in WebKitGTK+, but it turned out to be a pain to use for our purposes. GNotification is tied to GApplication. This allows for some interesting features, like notifications being persistent and able to reactivate the application, but those make no sense in our current use case, although that may change once service workers become a thing. It can also be a bit problematic given we are a library and thus have no GApplication of our own. That was easily overcome by using the default GApplication of the process for notifications, though. The show stopper for us using GNotification was the way GNOME Shell currently deals with notifications sent using this mechanism. It will look for a .desktop file named after the application ID used to initialize the GApplication instance and reject the notification if it cannot find that. Besides making this a pain to test our test browser would need a .desktop file to be installed, that would not work for our main API user! The application ID used for all Web instances is org.gnome.Epiphany at the moment, and that is not the same as any of the desktop files used either by the main browser or by the web apps created with it. For the future we will probably move Epiphany towards this new era, and all users of the WebKitGTK+ API as well, but the strictness of GNOME Shell would hurt the usefulness of our default implementation right now, so we decided to stick to libnotify for the time being. Other than that, I managed to review a bunch of patches during the hackfest, and took part in many interesting discussions regarding the next steps for GNOME Web and the GTK+ and Wayland ports of WebKit, such as the potential introduction of a threaded compositor, which is pretty exciting. We also tried to have Bastien Nocera as a guest participant for one of our sessions, but it turns out that requires more than a notebook on top of a bench hooked up to a TV to work well. We could think of something next time ;D. I d like to thank Igalia for organizing and sponsoring the event, Collabora for sponsoring and sending ChangSeok and myself over to Spain from far away Brazil and South Korea, and Adobe for also sponsoring the event! Hope to see you all next year!
Web Engines Hackfest 2014 sponsors: Adobe, Collabora and Igalia

Web Engines Hackfest 2014 sponsors: Adobe, Collabora and Igalia

Holger Levsen: 20121214-not-everybody-is-equal

We ain't equal in Debian neither and wishful thinking won't help. "White people think calling them white is racist." - "White people think calling them racist is racist." (Thanks to and via 2damnfeisty and blackgirlsparadise!) Posted here (in this white male community...) as a food for thought. What else is invisible for whom? Or hardly visible or distorted or whatever shade of (in)visible... - and how can we know about things we cannot (yet) see...

14 December 2014

Enrico Zini: html5-sse

HTML5 Server-sent events I have a Django view that runs a slow script server-side, and streams the script output to Javascript. This is the bit of code that runs the script and turns the output into a stream of events:
def stream_output(proc):
    '''
    Take a subprocess.Popen object and generate its output, line by line,
    annotated with "stdout" or "stderr". At process termination it generates
    one last element: ("result", return_code) with the return code of the
    process.
    '''
    fds = [proc.stdout, proc.stderr]
    bufs = [b"", b""]
    types = ["stdout", "stderr"]
    # Set both pipes as non-blocking
    for fd in fds:
        fcntl.fcntl(fd, fcntl.F_SETFL, os.O_NONBLOCK)
    # Multiplex stdout and stderr with different prefixes
    while len(fds) > 0:
        s = select.select(fds, (), ())
        for fd in s[0]:
            idx = fds.index(fd)
            buf = fd.read()
            if len(buf) == 0:
                fds.pop(idx)
                if len(bufs[idx]) != 0:
                    yield types[idx], bufs.pop(idx)
                types.pop(idx)
            else:
                bufs[idx] += buf
                lines = bufs[idx].split(b"\n")
                bufs[idx] = lines.pop()
                for l in lines:
                    yield types[idx], l
    res = proc.wait()
    yield "result", res
I used to just serialize its output and stream it to JavaScript, then monitor onreadystatechange on the XMLHttpRequest object browser-side, but then it started failing on Chrome, which won't trigger onreadystatechange until something like a kilobyte of data has been received. I didn't want to stream a kilobyte of padding just to work-around this, so it was time to try out Server-sent events. See also this. This is the Django view that sends the events:
class HookRun(View):
    def get(self, request):
        proc = run_script(request)
        def make_events():
            for evtype, data in utils.stream_output(proc):
                if evtype == "result":
                    yield "event:  \ndata:  \n\n".format(evtype, data)
                else:
                    yield "event:  \ndata:  \n\n".format(evtype, data.decode("utf-8", "replace"))
        return http.StreamingHttpResponse(make_events(), content_type='text/event-stream')
    @method_decorator(never_cache)
    def dispatch(self, *args, **kwargs):
        return super().dispatch(*args, **kwargs)
And this is the template that renders it:
 % extends "base.html" % 
 % load i18n % 
 % block head_resources % 
 block.super 
<style type="text/css">
.out  
    font-family: monospace;
    padding: 0;
    margin: 0;
 
.stdout  
.stderr   color: red;  
.result  
.ok   color: green;  
.ko   color: red;  
</style>
 # Polyfill for IE, typical... https://github.com/remy/polyfills/blob/master/EventSource.js # 
<script src="  STATIC_URL  js/EventSource.js"></script>
<script type="text/javascript">
$(function()  
    // Manage spinners and other ajax-related feedback
    $(document).nav();
    $(document).nav("ajax_start");
    var out = $("#output");
    var event_source = new EventSource(" % url 'session_hookrun' name=name % ");
    event_source.addEventListener("open", function(e)  
      //console.log("EventSource open:", arguments);
     );
    event_source.addEventListener("stdout", function(e)  
      out.append($("<p>").attr("class", "out stdout").text(e.data));
     );
    event_source.addEventListener("stderr", function(e)  
      out.append($("<p>").attr("class", "out stderr").text(e.data));
     );
    event_source.addEventListener("result", function(e)  
      if (+e.data == 0)
          out.append($("<p>").attr("class", "result ok").text(" % trans 'Success' % "));
      else
          out.append($("<p>").attr("class", "result ko").text(" % trans 'Script failed with code' %  " + e.data));
      event_source.close();
      $(document).nav("ajax_end");
     );
    event_source.addEventListener("error", function(e)  
      // There is an annoyance here: e does not contain any kind of error
      // message.
      out.append($("<p>").attr("class", "result ko").text(" % trans 'Error receiving script output from the server' % "));
      console.error("EventSource error:", arguments);
      event_source.close();
      $(document).nav("ajax_end");
     );
 );
</script>
 % endblock % 
 % block content % 
<h1> % trans "Processing..." % </h1>
<div id="output">
</div>
 % endblock % 
It's simple enough, it seems reasonably well supported besides needing a polyfill for IE and, astonishingly, it even works!

12 December 2014

Jingjie Jiang: Week1

Down the rabbit hole Starting from this week, my OPW period officially begins.
I am thankful and very grateful to this chance. One for the reason I can get an opportunity to contribute to a beneficial, working, meaningful, real-world software. The other seemingly reason is, I can learn much experience and design philosophy from my mentors zack and matthieu. :) This week my fix is on, bug #763921. It s basically making the folder page rendering providing more information, specifically the ls -l format. This offers information such as filetype, permission, size, etc. I learned some new knowledge about man 2 stat , and also got more familiar(actually confident) with front end stuff, namely css. I also get myself familiar with the python test (coverage). Next week, I will try to increase the test coverage a bit. Tests is an essential part of software. It ensures the correctness and robustness. And more importantly, by making tests, we can easily debug the software. The so called, The trello cards of next week is interesting. (in case you dunno the site, it s here:http://trello.com Let s see it.

Joey Hess: a brainfuck monad

Inspired by "An ASM Monad", I've built a Haskell monad that produces brainfuck programs. The code for this monad is available on hackage, so cabal install brainfuck-monad. Here's a simple program written using this monad. See if you can guess what it might do:
import Control.Monad.BrainFuck
demo :: String
demo = brainfuckConstants $ \constants -> do
        add 31
        forever constants $ do
                add 1
                output
Here's the brainfuck code that demo generates: >+>++>+++>++++>+++++>++++++>+++++++>++++++++>++++++++++++++++++++++++++++++++<<<<<<<<[>>>>>>>>+.<<<<<<<<] If you feed that into a brainfuck interpreter (I'm using hsbrainfuck for my testing), you'll find that it loops forever and prints out each character, starting with space (32), in ASCIIbetical order. The implementation is quite similar to the ASM monad. The main differences are that it builds a String, and that the BrainFuck monad keeps track of the current position of the data pointer (as brainfuck lacks any sane way to manipulate its instruction pointer).
newtype BrainFuck a = BrainFuck (DataPointer -> ([Char], DataPointer, a))
type DataPointer = Integer
-- Gets the current address of the data pointer.
addr :: BrainFuck DataPointer
addr = BrainFuck $ \loc -> ([], loc, loc)
Having the data pointer address available allows writing some useful utility functions like this one, which uses the next (brainfuck opcode >) and prev (brainfuck opcode <) instructions.
-- Moves the data pointer to a specific address.
setAddr :: Integer -> BrainFuck ()
setAddr n = do
        a <- addr
        if a > n
                then prev >> setAddr n
                else if a < n
                        then next >> setAddr n
                        else return ()
Of course, brainfuck is a horrible language, designed to be nearly impossible to use. Here's the code to run a loop, but it's really hard to use this to build anything useful..
-- The loop is only entered if the byte at the data pointer is not zero.
-- On entry, the loop body is run, and then it loops when
-- the byte at the data pointer is not zero.
loopUnless0 :: BrainFuck () -> BrainFuck ()
loopUnless0 a = do
        open
        a
        close
To tame brainfuck a bit, I decided to treat data addresses 0-8 as constants, which will contain the numbers 0-8. Otherwise, it's very hard to ensure that the data pointer is pointing at a nonzero number when you want to start a loop. (After all, brainfuck doesn't let you set data to some fixed value like 0 or 1!) I wrote a little brainfuckConstants that runs a BrainFuck program with these constants set up at the beginning. It just generates the brainfuck code for a series of ASCII art fishes: >+>++>+++>++++>+++++>++++++>+++++++>++++++++> With the fishes^Wconstants in place, it's possible to write a more useful loop. Notice how the data pointer location is saved at the beginning, and restored inside the loop body. This ensures that the provided BrainFuck action doesn't stomp on our constants.
-- Run an action in a loop, until it sets its data pointer to 0.
loop :: BrainFuck () -> BrainFuck ()
loop a = do
    here <- addr
    setAddr 1
    loopUnless0 $ do
        setAddr here
        a
I haven't bothered to make sure that the constants are really constant, but that could be done. It would just need a Control.Monad.BrainFuck.Safe module, that uses a different monad, in which incr and decr and input don't do anything when the data pointer is pointing at a constant. Or, perhaps this could be statically checked at the type level, with type level naturals. It's Haskell, we can make it safer if we want to. ;) So, not only does this BrainFuck monad allow writing brainfuck code using crazy haskell syntax, instead of crazy brainfuck syntax, but it allows doing some higher-level programming, building up a useful(!?) library of BrainFuck combinators and using them to generate brainfuck code you'd not want to try to write by hand. Of course, the real point is that "monad" and "brainfuck" so obviously belonged together that it would have been a crime not to write this.

Dirk Eddelbuettel: RProtoBuf 0.4.2

A new release 0.4.2 of RProtoBuf is now on CRAN. RProtoBuf provides R bindings for the Google Protocol Buffers ("Protobuf") data encoding library used and released by Google, and deployed as a language and operating-system agnostic protocol by numerous projects. Murray and Jeroen did almost all of the heavy lifting. Many changes were triggered by two helpful referee reports, and we are slowly getting to the point where we will resubmit a much improved paper. Full details are below.
Changes in RProtoBuf version 0.4.2 (2014-12-10)
  • Address changes suggested by anonymous reviewers for our Journal of Statistical Software submission.
  • Make Descriptor and EnumDescriptor objects subsettable with "[[".
  • Add length() method for Descriptor objects.
  • Add names() method for Message, Descriptor, and EnumDescriptor objects.
  • Clarify order of returned list for descriptor objects in as.list documentation.
  • Correct the definition of as.list for EnumDescriptors to return a proper list instead of a named vector.
  • Update the default print methods to use cat() with fill=TRUE instead of show() to eliminate the confusing [1] since the classes in RProtoBuf are not vectorized.
  • Add support for serializing function, language, and environment objects by falling back to R's native serialization with serialize_pb and unserialize_pb to make it easy to serialize into a Protocol Buffer all of the more than 100 datasets which come with R.
  • Use normalizePath instead of creating a temporary file with file.create when getting absolute path names.
  • Add unit tests for all of the above.
CRANberries also provides a diff to the previous release. RProtoBuf page which has a draft package vignette, a a 'quick' overview vignette, and a unit test summary vignette. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 December 2014

Rapha&#235;l Hertzog: Freexian s fourth report about Debian Long Term Support

Like each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In November 42.5 work hours have been equally split among 3 paid contributors. Their reports are available: New paid contributors Last month we mentioned the possibility to recruit more paid contributors to better share the work load and this has already happened: Ben Hutchings and Mike Gabriel join the list of paid contributors. Ben, as a kernel maintainer, will obviously take care of releasing Linux security updates. We are glad to have him on board because backporting kernel fixes really need some skills that nobody else had within the team of paid contributors. Evolution of the situation Compared to last month, the number of paid work hours has almost not increased (we are at 45.7 hours per month) but we are in the process of adding a few more sponsors: Roche Diagnostics International AG, Misal-System, Bitfolk LTD. And we are still in contact with a couple of other companies which have announced their willingness to contribute but which are waiting the new fiscal year. But even with those new sponsors, we still have some way to go to reach our minimal goal of funding the equivalent of a half-time position. So consider asking your company representative to join this project! In terms of security updates waiting to be handled, the situation looks better than last month: the dla-needed.txt file lists 27 packages awaiting an update (6 less than last month), the list of open vulnerabilities in Squeeze shows about 58 affected packages in total. Like last month, we re a bit behind in terms of CVE triaging and there are still many packages using SSLv3 where we have no clear plan (in response to the POODLE issues). The good side is that even though the kernel update spent a large chunk of time to Holger and Rapha l, we still managed to further reduce the backlog of security issues. Thanks to our sponsors

No comment Liked this article? Click here. My blog is Flattr-enabled.

Steve Kemp: An anniversary and a retirement

On this day last year I we got married. This morning my wife cooked me breakfast in bed for the second time in her life, the first being this time last year. In thanks I will cook a three course meal this evening. In unrelated news the BlogSpam service will be retiring the XML/RPC API come 1st January 2015. This means that any/all plugins which have not been updated to use the JSON API will start to fail. Fingers crossed nobody will hate me too much..

Next.

Previous.