Search Results: "ema"

5 September 2013

Daniel Pocock: Will Baby Boomers strangle Australia's Internet?

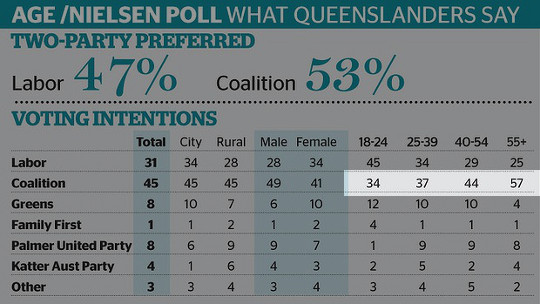
When Labor's Communications Minister Stephen Conroy won the title Internet villain of the year most educated people realised it wasn't something to celebrate. So it might be surprising for some that the title could potentially be returning to Australia so soon... Australia's main opposition party, the deceptively named Liberals (who actually lurk at the Marine Le Pen grade of conservatism) have just announced plans to resurrect the plan by implanting filtering technology in all modems, routers and smartphones. Whether they do or don't, there are serious concerns that they have described Australia's still-under-construction national broadband network as a wasteful project (which is potentially true) but failed to provide any credible alternative: who really thinks the conservative's proposed 25MBps will be a serious technology when they finish deploying it in 2019?. It is interesting to look at the bigger picture to see where this stupidity comes from. A political poll released early this week gives us half the story: Big bad baby boomers It is obvious that older voters prefer the conservative "coalition" parties, 57% of over-55s in particular. It is a huge jump from the 44% of voters in the age group below them. What this table doesn't tell us is that Australia's population is top-heavy with Baby Boomers. In other words, there are actually quite a lot of those over-55-year-old voters. In fact, it is estimated that close to 1 in 3 Australians will be in this category within the next 10 years. People who want the world to be the way it was in the 60s: many have already paid off a mortgage on a home in the suburbs with no access to things like public transport. They grew up under the white Australia policy and are frustrated at the presence of educated hard working foreigners from countries like India and China. Retired, no longer working, expecting the state to provide roads to their poorly located McMansions and free health care but little concern for broadband or anything that smells new. As they are no longer working, many have no commercial demand for broadband but will happily vote for a policy to censor it even if they don't use it themselves, simply because they want to see a Government that is blocking change. Sadly, they are shooting themselves in the foot: younger generations of Australians need to work and pay tax if there is to be any hope of keeping the dream alive for older Australians. However, with the conservatives cutting education to fund an over-dramatised response to immigration that costs billions of dollars every year, cutting corners and dumbing-down essential technology like the Internet, it seems that working-age Australians will struggle to compete in the global marketplace.
Keith Packard: Airfest-altimeter-testing

Altimeter Testing at Airfest Bdale and I, along with AJ Towns and Mike Beattie, spent last weekend in Argonia, Kansas, flying rockets with our Kloudbusters friends at Airfest 19. We had a great time! AJ and Mike both arrived a week early at Bdale s to build L3 project airframes, and both flew successful cert flights at Airfest! Airfest was an opportunity for us to test fly prototypes of new flight electronics Bdale and I have spent the last few weeks developing, and I thought I d take a few minutes today to write some notes about what we built and flew. TeleMega We ve been working on TeleMega for quite a while. It s a huge step up in complexity from our original TeleMetrum, as it has a raft of external sensors and six pyro circuits. Bdale flew TeleMega in his new fiberglass 4 airframe on a Loki 75mm blue M demo motor. GPS tracking was excellent; you can see here that GPS altitude tracked the barometric sensor timing exactly: GPS lost lock when the motor lit, but about 3 seconds after motor burnout, it re-acquired the satellite signals and was reporting usable altitude data right away. The GPS reported altitude was higher than the baro sensor, but that can be explained by our approximation of an atmospheric model used to convert pressure into altitude. The rest of the flight was also nominal; TeleMega deployed drogue and main chutes just fine. TeleMetrum We ve redesigned TeleMetrum. The new version uses better sensors (MS5607 baro sensor, MMA6555 accelerometer) and a higher power radio (CC1120 40mW). The board is the same size, all the connectors are in the same places so it s a drop-in replacement, and it s still got two pyro channels and USB for configuration, data download and battery charging. I loaded up my Candy-Cane airframe with a small 5 grain 38mm CTI classic: The flight computer worked perfectly, but GPS reception was not as good as we d like to see: Given how well TeleMega was receiving GPS signals, I m hopeful that we ll be able to tweak TeleMetrum to improve performance. TeleMini We ve also redesigned TeleMini. It s still a two-channel flight computer with logging and telemetry, but we ve replaced the baro sensor with the MS5607, added on-board flash for increased logging space and added on-board screw terminals for an external battery and power switch. You can still use one of our 3.7V batteries, but you can also use another battery providing from 3.7 to 15V. I was hoping to finish up the firmware and fly it, but I ran out of time before the launch. The good news is that all of the components of the board have been tested and work correctly, and the firmware is feature complete , meaning we ve gotten all of the features coded, it s just not quite working yet. EasyMini EasyMini is a new product for us. It s essentially the same as a TeleMini, but without a radio. Two channels, baro-only, with logging. Like TeleMini, it includes an on-board USB connector and can use either one of our 3.7V batteries, or an external battery from 3.7V to 15V. EasyMini and TeleMini are the same size, and have holes in the same places, so you can swap between them easily. I flew EasyMini in my Koala airframe with a 29mm 3 grain CTI blue-streak motor. EasyMini successfully deployed the main chute and logged flight data: We also sent a couple of boards home with Kevin Trojanowski and Greg Rothman for them to play with. TeleGPS TeleGPS is a GPS tracker, incorporating a u-blox Max receiver and a 70cm transmitter. It can send position information via APRS or our usual digital telemetry formats. I was also hoping to have the TeleGPS firmware working, and I spent a couple of nights in the motel coding, but didn t manage to finish up. So, no data from this board either. Production Plans Given the success of the latest TeleMega prototype, we re hoping to have it into production first. We ll do some more RF testing on the bench with the boards to make sure it meets our standards before sending it out for the first production run. The goal is to have TeleMega ready to sell by the end of October. TeleMetrum clearly needs work on the layout to improve GPS RF performance. With the testing equipment that Bdale is in the midst of re-acquiring, it should be possible to finish this up fairly soon. However, the flight firmware looks great, so we re hoping to get these done in time to sell by the end of November. TeleMini is looking great from a hardware perspective, but the firmware needs work. Once the firmware is running, we ll need to make enough test flights to shake out any remaining issues before moving forward with it. EasyMini is also looking finished; I ve got a stack of prototypes and will be getting people to fly them at my local launch in another couple of weeks. The plan here is to build a small batch by hand and get them into the store once we re finished testing, using those to gauge interest before we pay for a larger production run.

4 September 2013

Russell Coker: Ownership of a Club

Last night at the Annual General Meeting we had a motion to disincorporate The Linux Users of Victoria (LUV) [1]. The proposal was for LUV to cease being an incorporated society on condition that Linux Australia (LA) [2] accepts us as a sub-committee. As a sub-committee of LA we would elect our own committee to run things locally but have LA hold the finances, deal with all the paperwork that the government demands, and generally do as many of the non-core tasks associated with running a users group as possible. When we discussed this at the LUV committee meetings it didn t seem like a big deal. But as is often the case with political discussions it turned out to be difficult. There was a lot of discussion about LUV supposedly ceasing to exist, people seem to think that LUV is defined by having an incorporated society. My impression was always that it was defined by a mailing list and having meetings and I was involved in both before there was an incorporated society. Lurkers and Ownership During the discussion we had some input from members who were typically lurkers who seemed to feel that their property rights towards LUV were being infringed, this annoys me. I think that if someone chooses not to be involved in running an organisation then they should choose not to concern themselves with the details of how the organisation is to be run. People who attend the meetings should have a say in how the meetings are run and have reason to be concerned about anything that might affect them and the opinions of speakers also matter. People who are involved with mailing list discussions should have a say in how the lists are run. But people who have never volunteered for a position on the committee shouldn t be greatly concerned about the internal issues of how things are run. Finance Some concern was expressed about the financial situation of LUV and whether we would still get enough donations to keep it running when combined with LA. There was even some FUD suggesting that LA would just take our money (they had assured us that all funds and donations would be ear-marked for us). The current LUV financial situation is that Red Hat pays for the venue for the monthly meetings and the rent for the venue comprises about 2/3 of all donations. The remaining 1/3 comes from one company. So in the current situation if Red Hat ceased donating then we would have 18 months to find another donor or cease holding meetings before our bank balance became unreasonably low. If the company which gives the other significant annual donation was to cease doing so then we could operate for a few years on savings but we would need to find some other source of funding. It seems to me that joining LA would give us more financial security. Then if Red Hat ceased paying for the venue then LA could keep things running until we found another donor, I m confident that LA wouldn t allow LUV to just shut down because of a shortage of donations. If people are really concerned about the financial situation of LUV then they should urgently seek further donations such that if any one donor decided to stop giving then we could still operate as normal. To achieve that goal I think we need at least another $1,000 per annum. This issue of redundancy in donations is something I raise every time that LUV finances are discussed. My conclusion is that people aren t really bothered about the financial security of LUV except when they are looking for reasons to avoid change. Doing New Things During the course of discussion about the future of LUV there were a number of requests for improvement. One significant request was for more support for regional Linux users. Some years ago we held a mini-conference in Ballarat which went well. I think it would be good to do such things again, the cost is not particularly great and I m sure it would be accepted by LA for funding, but we need to organise it. Organising such events is something that anyone can do. Any LUV member can plan an event, get costs for everything that is needed (food, accommodation, travel, etc) and then pitch it to the LUV committee in terms of which things should be paid by LUV and which by the members concerned. We could then work on getting additional funding from LA if necessary. But planning an event takes some effort and it s often effort that can only be done by a local. Finding a suitable venue and getting some assurance that a large enough audience will attend is something that can t be done remotely. I think that the problem for LUV in regard to such things isn t a lack of money or independence. I think that the problem is that the committee spends too much volunteer time on administrative tasks and not enough time directly doing things that benefit members and the community in general. In the past I have declined nomination to the LUV committee because I felt that I could contribute more by giving lectures, finding other speakers, and doing other things to directly improve the group. I was on the committee last year and have now been elected to it again, but I m starting to think that I made a mistake. Maybe I should have declined and let others work on the new model rules and other paperwork. One committee member has claimed that the time taken on administrative tasks isn t taking time away from other LUV related tasks, I invite any committee members who feel that way to address some of the services that members are requesting. Speaking for myself my lack of time directly impacts that I can do for the club. I think that ownership of a club should be related to what people do for the club. If you have a feeling of ownership and lack ideas for how to contribute then you can ask the LUV mailing list, there are lots of people with suggestions for things to do.

3 September 2013

Julien Danjou: Announcing The Hacker Guide to Python

I've been hacking on Python for a lot of years now, on various project. For the last two years, I've beenheavily involved in OpenStack, which makes an heavy usage of Python. Once you start working with a hundred of hackers, on several software and libraries representing more than half a million source lines of Python, things change. The scalability, testing and deployment problems inherent to a cloud platform meddle with everything in designing components. During these two years working on OpenStack development, I've learned a lot on Python from astounding Python hackers. From general architecture and design principles to various tips and tricks of the language. It seemed to me like a good opportunity to share what I learnt doing so with others so you can benefit from it in other projects. I've started working a book, entitled "The Hacker Guide to Python", where I will try to share what I learnt while working with Python. The book is still a work in progress at this stage, but if you'd like to get in touch and keep updated on its advancement, you can subscribe in the following form or from the book homepage.
The Hacker Guide to Python
A book I'm writing that will be launched soon, talking about designing Python applications, state of the art, and various Python tips. If you want to be the first to hear about the launch, subscribe now.

2 September 2013

Daniel Pocock: Australia's Labor Party exposed spying on their own members

Australia's Labor Party claims to represent the little guy, advocating the interests of a wide slice of the population over the interests of those who might supposedly exploit them. In this latest blog I'll look at just how the Victorian state branch of the party is emulating the more sinister elements of monitoring and control that you would typically expect from marketers, spammers and the NSA. It makes you wonder, if they do this to their own members, how can Australia's government ever hope to rein in spammers or other undesirable practices? Europe has tried cookie laws and the right to be forgotten, while the ALP has taken these developments almost as a guide to exploiting their own most valuable resource, their membership. The email version of invisible ink Straight out of an email attempting to recruit party members to the federal election campaign, we find that the ALP's logo itself has been turned into a sinister tracking mechanism. Looking underneath the logo, there is a hidden tracking number attached to every message:
http://gallery.mailchimp.com/3021e68df9a7200135725c633/images/Email_Header_ThisisLabor.jpg
There it is, that big long code 3021e68df9a7200135725c633. On it's own, you may think this number can't do much harm. Think again. After all, as the filename says, "ThisisLabor". Reaching the grass roots by long distance email When a party member sees any of the images in the email or clicks any of the links, their email software or web browser sends a HTTP request to the ALP's outsourced tracking server in the United States. Here is an example of what that request may contain:
TCP Headers:
  SOURCE IP ADDRESS: 198.51.100.56
HTTP headers:
  GET /3021e68df9a7200135725c633/images/Email_Header_ThisisLabor.jpg
  HTTP/1.1
  Host: gallery.mailchimp.com
  User-Agent: Mozilla/5.0 (X11; Linux x86_64; rv:17.0) Gecko/20130515 Firefox/17.0 Iceweasel/17.0.6
  Accept: text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8
  Accept-Language: en-US,en;q=0.5
  Accept-Encoding: gzip, deflate
  X-Forwarded-For: 192.168.1.54
  Connection: keep-alive
These codes are all transmitted from the recipient of the email back to the ALP. Notice the tracking number is in the very first line of the HTTP request? These codes send many details to the tracking server. Just what is revealed?
  • What time the message was read
  • How many times the message was opened
  • Whether the message was read on multiple computers (perhaps it was forwarded)
  • The IP addresses reveal which network was used.
    • For people reading email at work or on wifi, the IP address reveals the name of the employer, it can be easily looked up in this public database. Here is an example querying one of the ALPs own IP addresses, 203.24.72.2
    • For people using an internet connection at home, the IP address reveals the service provider. There is more to it though: if one party member regularly visits another party member and uses their wifi, they will both appear to be using the same IP address and the party will be able to deduce that there is a connection between these two people.
  • The web browser name and version and the operating system name and version.
  • The language normally used on the computer
Crunching the numbers You may think that nobody would be interested in all that data or that it is even too much data for anybody to easily study. Think again. The ALP has outsourced processing of this data to an offshore firm that specializes in bulk email, MailChimp. After lecturing everybody about the dangers of outsourcing, the ALP has literally sold the farm (their own membership data) - to a foreign marketing company. Here are some of the claims MailChimp make on their web site:
"Dig even deeper with Subscriber Activity Reports, which give you a real time report for every subscriber s email activities: when they opened, what they clicked, and when they came back for more. You can even generate a list of people who didn t open, and send them a modified campaign."
That's right: if ALP members don't read their emails fast enough, they will send even more of them. Just who has access to this data? Well, the scope is quite broad. According to these rules, it is not only the dubious officials in the party's state office, but Labor Party regulations also list a whole lot of other officials who have access to some subset of the data: branch and FEA district committees, policy committees and maybe some trade union officials too. Once you start to contemplate this, it becomes apparent that the probability of somebody profiling members at an individual level is very real. On the other hand, those rules clearly do not permit the state branch to process the member's data offshore. Double whammy In fact, even MailChimp is further outsourcing the data. When receiving an image from the booby-trapped link in the email, we receive a response like this:
HTTP/1.1 200 OK
Content-Type: image/jpeg
Content-Length: 407474
Connection: keep-alive
Date: Wed, 10 Jul 2013 06:25:55 GMT
Last-Modified: Tue,  03 Sep 2013 04:05:37 GMT
ETag: "df9a7200135725c6331369a22"
Accept-Ranges: bytes
Server: AmazonS3
Age: 62097
Via: 1.0 e71fe855f29513f54a41e213fe653fb1.cloudfront.net (CloudFront)
X-Cache: Hit from cloudfront
X-Amz-Cf-Id: S2V2aW4gUnVkZCBpcyBhIGJhZCBib3kuCg==
which contains more tracking numbers and clearly indicates that the data is being processed in the massive AmazonS3 (a.k.a Amazon online bookstore) cloud platform. Thanks to cloud computing, there is considerable scope for cross-referencing records across other web sites. The IP address becomes a magic key, allowing a range of sinister forces to join the dots at the click of a button and profile the whole private and professional identity of any individual ALP member. Googling ALP members It doesn't stop there however, after following these links a victim will eventually end up on one of the ALP's own web pages. Looking through the HTML code underneath http://www.viclabor.com.au is very easy, in most web browsers, you can just press Control-U to see what is hidden away in the shadows. Buried in the code, I found this little gem:
  var _gaq = _gaq   [];
  _gaq.push(['_setAccount', 'UA-35325645-1']);
  _gaq.push(['_trackPageview']);
  (function()  
    var ga = document.createElement('script'); ga.type = 'text/javascript'; ga.async = true;
    ga.src = ('https:' == document.location.protocol ? 'https://ssl' : 'http://www') + '.google-analytics.com/ga.js';
    var s = document.getElementsByTagName('script')[0]; s.parentNode.insertBefore(ga, s);
   )();
This may be even scarier: it's a JavaScript code that channels all access to the ALP web site into an outsourced tracking system provided by Google. Google can now cross-reference ALP members against their Gmail accounts, their friends and the topics they search for to further profile the type of advertising they should be exposed to. Google, like any private company, has a loyalty to its shareholders and the laws of the country where it is domiciled. Will that coincide with the best interests of ALP members in Victoria? Australia's other parties: samples needed Do you have similar communications from Australia's other political parties? Please send them to me and I'll be happy to examine them for similar shortcomings.

Dmitrijs Ledkovs: My Debian Activities: Multiarch & upstart on kFreeBSD hacking

Looks like there is a recent trend to publicize one's debian activities, so I thought I should join in =) Not so sure if MDA acronym would work for these types of posts...
MultiarchI have been working on multi-arching additional libraries. In particular I am working on multiarching boost libraries. At the moment boost1.53 multiarched libraries are uploaded in the experimental, and I am still working out the quirks with those. At the same time I have submitted a patch to multiarch libicu-dev, which has been accepted by the maintainer and is currently waiting in new queue. This brings us closer to multiarching all of boost libraries. But as it has been pointed out at the Multiarch BOF at Debconf'13, one doesn't have to wait for dependencies (be it libs or lib-devs) to be Multiarched before multi-arching your own library. If you do it right (put all or arch-specifi headers in multiarch location, and place libraries in multiarch location, split utilities into a separate package), you can go and multiarch your libraries ahead of time. Maybe it's time to default to debhelper 9 in dh-make, and default to multiarch locations for all libraries?

Boost also has libraries which depend on mpi, and at the moment that's not multiarched. I'm not sure if there are additional considerations there given the support for alternative mpi implementations in Debian.

Boost also depends on libpython. At the moment it's shipping libboost_python-py2.7.so & libbost-py3.3.so, with a libboost_python.so symlink to libbost_python-py2.7.so. I do wonder if it's a sensible approach, or should the boosty_python library be simply shipped in arch specific & python implementation specific paths e.g. /usr/lib/pythonX.Y/config-X.Y$(abi_tag)-$(DEB_HOST_MULTIARCH)/ that way we'll be able to support python debug interpreter in python_boost. I guess I should seek expert opinion on other multiarch wizards.

In addition to boost, I've now started looking at qmake and how it handles multiarch. At the moment, it doesn't handle it much. All paths are statically copied around and hard-coded in each module qmake provides. I have now been working at abusing qmake's $$system to call into dpkg-architecture, and actually choose native or cross compiler & adjust settings and paths to Qt libraries. There are a couple of bugs to fix, but I should be able to propose a "debian-multiarch" qmake spec soon. Such that in calls dpkg-architecture & properly adjust compilers & locations for the DEB_HOST. qmake by the way has its quirks. For example all variable assignments seemed to default to be "by value" & not "by reference" (i.e. upon assignment all variables on the right hand side get expanded and the literal string is stored, instead of storing $(prefix)/lib/$(arch), and evaluating that later.) Hence my current qmakespec is less elegant than I hoped.
upstart on kFreeBSDFreeBSD 9.2 and up have implemented the wait6 and with it waitid is also exposed. At the moment there are some differences between glibc and FreeBSD waitid usage. I am not well versed in glibc, FreeBSD and POSIX, but the bug at hand & POSIX reference lead me to believe that POSIX is slightly ambiguous about it.

Why is waitid support is interesting? Well, kFreeBSD/libc maintainer in Debian is working on exposing it with/after (e)glibc2.18 is in Debian, which will remove one more blocker from porting Upstart to kFreeBSD. To this extend, I have in the mean time setup FreeBSD & kFreeBSD virtual machines and got libnih to compile on both (sans waitid on kFreeBSD). One of the optional upstart's features is to use inotify to spot & reload configuration files, at the moment I haven't ported that functionality to use native kevent/kqueues (EVFILT_AIO) instead I have cheated and packaged for Debian the Google Summer of Code 2011 project libinotify-kevent which provides inotify compatible API, implemented with kevent. Which is kind of the reverse strategy of libkqueue and/or libevent. It would be interesting to see kernels and/or those libraries to unify/standartise on common APIs. Unfortunately, it still seems like using native API for each kernel is best to avoid dependencies and leverage all features and semantics. Nonetheless I did package it for now. To further progress with actually porting upstart, I'd like to get my hands at (e)glibc 2.18 compiled for kFreeBSD with waitid patches. I got pointers to the patches, but I haven't yet succeeded at compiling (e)glibc with those applied. So no upstart booting kFreeBSD VM yet, but rather work in progress. It's quite fun. It's been years since I have touched a FreeBSD boxes and it's first time me using kFreeBSD. The semantics, differences and benefits of each do shine and it's a promising platform.
Multiarch on kFreeBSD?
Given the excellent multiarch implementation on Debian and sophisticated Linux Emulation Layer on FreeBSD kernel, I was half expecting the following to work:
  • on kFreeBSD enable linux i386/amd64 repository
  • apt-get install hello:i386
  • $ hello
But unfortunately this confused kFreeBSD, since it didn't find ELF tags and linker didn't seem to load the right libraries any more =( Not sure if this issue has been raised before, but I think it would be awesome if FreeBSD Linux Emulation Layer worked transparently on Debian/kFreeBSD multiarch system.

1 September 2013

Jamie McClelland: If you don't know what a quine is, consider yourself lucky

rhatto just asked me to approve a change in keygringer's license from AGPLv3+ to GPLv3+ citing a discussion about a Berkeley DB's switch to AGPLv3. For some reason, a reference to a quine caught my eye. If you don't know what a quine is, I suggest you remain ignorant. I won't even provide the Wikipedia link. A quick web search suggests that it's quite possible to write one in bash. I hope to be productive again some day.

Eddy Petrișor: Integrating Beyond Compare with Semanticmerge

Note: This post will probably not be on the liking of those who think free software is always preferable to closed source software, so if you are such a person, please take this article as an invitation to implement better open source alternatives that can realistically compete with the closed source applications I am mentioning here. I am not going to mention here where the open source alternatives are not up to the same level as the commercial tools, I'll leave that for the readers or for another article.


Semanticmerge is a merge tool that attempts to do the right thing when it comes to merging source code. It is language aware and it currently supports Java and C#. Just today the creators of the software have started working on the support for C.

Recently they added Debian packages, so I installed it on my system. For open source development Codice Software, the creators of Semanticmerge, offers free licenses, so I decided to ask for one today, and, although is Sunday, I received an answer and I will get my license on Monday.

When a method is moved from one place to another and changed in a conflicting way in two parallel development lines, Semanticmerge can isolate the offending method and can pass all its incarnations (base, source and destination or, if you prefer, base, mine and theirs) to a text based merge tool to allow the developer to decide how to resolve the merge. On Linux, the Semanticmerge samples are using kdiff3 as the text-based merge tool, which is nice, but I don't use kdiff3, I use Meld, another open source visual tool for merges and comparisons.


OTOH, Beyond Compare is a merge and compare tool made by Scooter Software which provides a very good text based 3-way merge with a 3 sources + 1 result pane, and can compare both files and directories. Two of its killer features is having the ability split differences into important and non-important ones according to the syntax of the compared/merged files, and the ability to easily change or add to the syntax rules in a very user-friendly way. This allows to easily ignore changes in comments, but also basic refactoring such as variable renaming, or other trivial code-wide changes, which allows the developer to focus on the important changes/differences during merges or code reviews.

Syntax support for usual file formats like C, Java, shell, Perl etc. is built in (but can be modified, which is a good thing) and new file types with their syntaxes can be added via the GUI from scratch or based on existing rules.

I evaluated Beyond Compare at my workplace and we decided it would be a good investment to purchases licenses for it for the people in our department.


Having these two software separate is good, but having them integrated with each other would be even better. So I decided I would try to see how it can be done. I installed Beyond compare on my system, too and looked through the examples


The first thing I discovered is that the main assumption of Semanticmerge developers was that the application would be called via the SCM when merges are to be done, so passing lots of parameters would not be problem. I realised that when I saw how one of the samples' starting script invoked semantic merge:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java -edt="kdiff3 \"#sourcefile\" \"#destinationfile\"" -emt="kdiff3 \"#basefile\" \"#sourcefile\" \"#destinationfile\" --L1 \"#basesymbolic\" --L2 \"#sourcesymbolic\" --L3 \"#destinationsymbolic\" -o \"#output\"" -e2mt="kdiff3 \"#sourcefile\" \"#destinationfile\" -o \"#output\""
Can you see the problem? It seems Semanticmerge has no persistent knowledge of the user preferences with regards to the text-based merge tool and exports the issue to the SCM, at the price of overcomplicating the command line. I already mentioned this issue in my license request mail and added the issue and my fix suggestion in their voting system of features to be implemented.

The upside was that by comparing the command line for kdiff3 invocations, the kdiff3 documentation and, by comparison, the Beyond Compare SCM integration information, I could deduce what is the command line necessary for Semanticmerge to use Beyond Compare as an external merge and diff tool.

The -edt, -emt and -e2mt options are the ones which specify how the external diff tool, external 3-way merge tool and external 2-way merge tool is to be called. Once I understood that, I split the problem in its obvious parts, each invocation had to be mapped, from kdiff3 options to beyond compare options, adding the occasional bell and whistle, if possible.

The parts to figure out, ordered by compexity, were:

  1. -edt="kdiff3 \"#sourcefile\" \"#destinationfile\"

  2. -e2mt="kdiff3 \"#sourcefile\" \"#destinationfile\" -o \"#output\""

  3. -emt="kdiff3 \"#basefile\" \"#sourcefile\" \"#destinationfile\" --L1 \"#basesymbolic\" --L2 \"#sourcesymbolic\" --L3 \"#destinationsymbolic\" -o \"#output\""

Semantic merge integrates with kdiff3 in diff mode via the -edt option. This was easy to map to Beyond Compare, I just replaced kdiff3 with bcompare:
-edt="bcompare \"#sourcefile\" \"#destinationfile\""
Integration for 2-way merges was also quite easy, the mapping to Beyond Compare was:
-e2mt="bcompare \"#sourcefile\" \"#destinationfile\" -savetarget=\"#output\""
For the 3-way merge I was a little confused because the Beyond Compare documentation and options were inconsistent between Windows and Linux. On Windows, for some of the SCMs, the options that set the titles for the panes are '/title1', '/title2', '/title3' and '/title4' (way too descriptive for my taste /sarcasm), but for some others are '/lefttitle', '/centertitle', '/righttitle', '/outputtitle', while on Linux the options are the more explicit kind, but with a '-' instead of a '/'.

The basic things were easy, ordering the parameters in the 'source, destination, base, output' instead of kdiff3's 'base, source, destination, -o ouptut', so I wanted to add the bells and whistles, since it really makes more sense for the developer to see something like 'Destination: [method] readOptions' instead of '/tmp/tmp4327687242.tmp', and because that's exactly what is necessary for Semanticmerge when merging methods, since on conflicts the various versions of the functions are placed in temporary files which don't mean anything.

So, after some digging into the examples from Beyond Compare and kdiff3 documentation, I ended up with:
-emt="bcompare \"#sourcefile\" \"#destinationfile\" \"#basefile\" \"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic' -centertitle='#basesymbolic' -outputtitle='merge result'"

Sadly, I wasn't able to identify the symbolic name for the output, so I added the hard coded 'merge result'. If Codice people would like to help with with this information (or if it exists), I would be more than willing to do update the information and do the necessary changes.

Then I added the bells and whistles for the -edt and -e2mt options, so I ended up with an even more complicated command line. The end result was this monstrosity:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java -edt="bcompare \"#sourcefile\" \"#destinationfile\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic'" -emt="bcompare \"#sourcefile\" \"#destinationfile\" \"#basefile\" \"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic' -centertitle='#basesymbolic' -outputtitle='merge result'" -e2mt="bcompare \"#sourcefile\" \"#destinationfile\" -savetarget=\"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic'"
So when I 3-way merge a function I get something like this (sorry for high resolution, lower resolutions don't do justice to the tools):


I don't expect this post to remain relevant for too much time, because after sending my feedback to Codice, they were open to my suggestion to have persistent settings for the external tool integration, so, in the future, the command line could probably be as simple as:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java
And the integration could be done via the GUI, while the command line can become a way to override the defaults.

Russ Allbery: Review: An Artificial Night

Review: An Artificial Night, by Seanan McGuire
Series: October Daye #3
Publisher: DAW
Copyright: September 2010
ISBN: 1-101-44276-X
Format: Kindle
Pages: 368
This is the third book of the October Daye series, following A Local Habitation. It could be read out of order, as each chapter of Toby's story so far is somewhat standalone, but I wouldn't recommend it. You'd miss the character development and the background behind several friendships. As with the previous book review, a caveat: I am reviewing this book four months after finishing it, rather than the normal couple of weeks, so apologies in advance for any thinness or inaccuracies. The first sign that something is about to go seriously wrong in Toby's life this time is a visitor. She says her name is May Daye, and apparently she's Toby's Fetch: a duplicate in nearly every respect except personality, manifested to guide someone to their death. Their imminent death. The second sign is that her best friend's children are kidnapped. The children who treat her like an aunt. And the cause of that kidnapping is far, far beyond the level of power that Toby could be expected to deal with. I have profound mixed feelings about this book. On one hand, McGuire further expands Toby's web of connections and shows us more of Toby's friends and their background, and that's becoming my favorite part of this series. She introduces May, who I think is a great character: at first apparently much different than Toby, but with a similarity beneath surface impressions that one notices more over time. And I thought the climax of the story, once we finally got there, was very moving and well-done. Also, I just love the way that McGuire uses children's rhymes and doggerel throughout this series as a magical element, and that's particularly well-handled here. Due to the nature of the antagonist, McGuire has a good excuse to bring that front and center, and the process of familiar rhymes expanding into deep magical rules was a fun intellectual experience. Best of all, the Luidaeg plays a significant role in the story again. The Luidaeg is, hands down, my favorite character in McGuire's constructed universe, and she becomes even more so over the course of this story. Her complex relationship with Toby is clearly blossoming into a friendship that's surprising both of them deeply, but a friendship that has to play by an odd set of rules (like so much else in Toby's life). I loved her here. Seeing someone that difficult and abrupt show unexpected emotional depths is one of the story elements I enjoy the most. The problem, though, is that quite a lot of An Artificial Night is very, very dark. And by that, I don't mean that there is a lot of tension, or that Toby is struggling against monsterous things, although both of those statements are also true. Rather, Toby is not only out of her league but ends up in some viciously nasty situations, and they persist for rather more of this book than I would have preferred. Putting one's protagonist through hell has a long tradition in urban fantasy, but I found the level of sheer helplessness that Toby struggled through to be a bit more than I wanted to read about. It was too reminiscent of events from Toby's background (as discussed in Rosemary and Rue) that I still don't like to think about. There is, of course, an eventual payoff, as dark as the interim events seem. One knows that, given the genre and given that this is an ongoing series, and even just given the nature of stories. But as much as I like the growing cast of this series, and adored the scenes with the Luidaeg, I found parts of this journey to be deeply disturbing, and not in an enjoyable dramatic tension sort of way. I don't mind protagonists being seriously hurt (although it's not my favorite plot), or even some amount of despair, but this went beyond that. I think McGuire was going for a story about sacrifice and self-definition, about trying even when one can't possibly win, and I can appreciate the narrative arc. But parts of the book were simply awful to read for me. I'm therefore not quite sure what to say in terms of a recommendation. I'm still reading the series, and will definitely read the next book. I think my reaction is somewhat idiosyncratic; the events here will probably not bother others as much as they bothered me. And I can't disagree with their dramatic effectiveness, or with the way that McGuire builds conflict out of the rules of fairy and is building Toby into a stronger and more capable person than she ever thought she could be. But there were still spots where I wished I were reading a different book. Hopefully the next book in the series will be that book I wanted to read. Followed by Late Eclipses. Rating: 6 out of 10

30 August 2013

Daniel Pocock: Big decision?

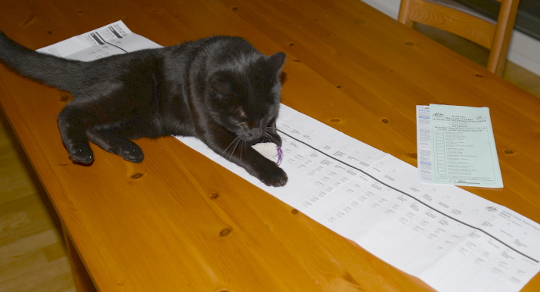
Most people have probably heard that elections are on in Australia. I just received my postal ballot paper the other day and in the spirit of transparency, I'm sharing it here on my blog. Spoilt for choice There are two ballots, one for the Lower House and the other for the Senate. The big one is for the Senate. Our cat is on top of it to help give some perspective on how big it is. Like the columns on a bloated spreadsheet, the parties are designated with symbols from A to AM and then there are some leftover candidates too. Animal instincts With so many candidates to choose from, even our kitty may have found an opportunity in the Animal Justice Party - although that little snack in her claws suggests that she is more interested in the law of the jungle than any political debate. She may want to be wary not to fall under the wheel of the party next to them, Motoring Enthusiasts. The Senate, a place for convicted hackers? The next party in the picture is Wikileaks and their number one candidate, of course, is the first person to successfully claim asylum from Australia, Julian Assange. It's no secret that he has a string of convictions for computer hacking in the 90s and that when US authorities catch up with him, their drone won't just be dropping him a letter demanding a $2,100 penalty fine through the window. So how do they compare? As I contemplate my decision, lets look at the numbers:
Party Seats won in 2010
House of Reps, Senate
Criminal charges against members in last 3 years
Labor Party 72, 31 173, mainly fraud
Liberal/National coalition (conservative) 73, 34 3, including shoplifting and assault
Wikileaks 0 None - Assange is not actually charged with any crime
All of a sudden, in a country that is often the butt of British jokes about convicts, Assange starts to look squeaky clean. He may take further comfort from knowing that out of all those crimes, hacking is the only one that appears to have the presidential seal of approval. Conclusion Whichever way I vote may or may not make so much difference. With so many candidates to choose from though, there is little sign of any quality leadership from any corner of Australian politics. Whether Mr Assange is elected or not, many people will have a chuckle when they realise he almost ended up alongside the Australian Sex Party out of 38 other possible parties randomly distributed across the ballot. Please feel free to comment: which party is the most ridiculous?

Joey Hess: best DebConf ever

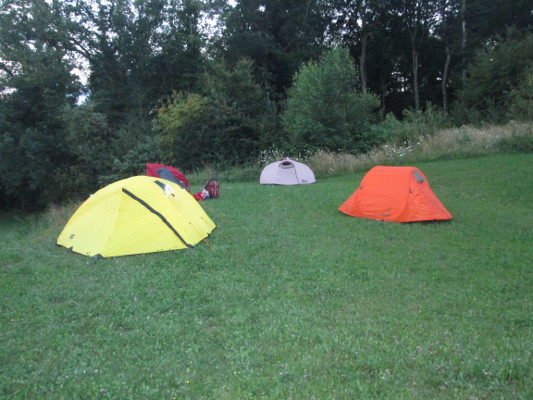
For me, DebConf13 in Switzerland was a perfect DebConf, and generally an great developer meeting and conference. I've attended several past DebConfs in Canada, Norway, Brazil, Finland, Mexico, Scotland, Spain, NYC, Bosnia, and Nicaragua. I have special memories of each. DebConf13 was ideal in every way. Let's start with the camping. Only a minority of us did it, and my campsite was located in a small field behind a bar that was often noisy late into the night, when I was trying to rest and preserve my European jetlag remedy of inverted sleeping schedule. Still, I love sleeping cocooned in a tent, and going through the routines of camping and spending time alone there was a good counterpoint to DebConf. I generally find myself retreating for a day or two in the middle of a week-long conference, burnt out with social interactions. That didn't happen this time. I need to find way to camp at future DebConfs. (Also special shout out to wonderful people who lent me a warmer sleeping bag, and bought me a pillow while on a trip to town! Upgraded my first backpacking in Europe experience's comfort level a lot!) The next perfect thing for me were the talks I gave at DebConf. I always enjoy presenting at DebConf, and barely remember when I'd get nervous doing it. But I really felt comfortable giving these talks in a way I've not before. I'm pleased with how the Debian Cosmology talk turned out; I'd worried it would be a downer talk, or too light, or not well received, and none of those problems surfaced. I was especially happy with my dh_busfactor session, which I prepared for all of 10 minutes and was structured entirely to benefit me by talking over my thoughts and getting feedback, and in which I probably drove the camerapeople crazy running my own mic into the audience. Despite all that, I think it succeeded being interesting for the participants as well as for me. Hope to follow up on it soon.. But beyond the two talks I submitted, there were a series of ad-hoc scheduled talks. It seemed that every day I spent at least an hour discussing something I'm deeply involved in. This started with the Ikiwiki bof, and then there was an epic series of (unrecorded) BoFs about git stuff, which basically turned into an unofficial git track at DebConf. Much, much discussion of git-annex and other things I'm involved in. BTW, I really like that DebConf, as well as being a formal conference on top, is really an un-conference underneath, with new BoFs and things popping up on the schedule all week long. You can even have completely unscheduled meetings that somehow get just the right mix of people to make something awesome happen.
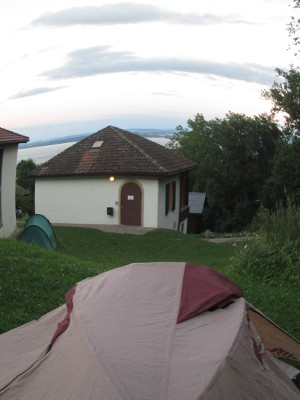
But it wasn't all about talks. Indeed, I only attended 2 or 3 sessions a day. The DebConf13 venue was controversial, but I found it excellent for getting things done. Rather than one or two massive rooms that get too noisy to think in, this venue had many little nooks and crannies suited for different types of work. There were so many I only discovered some while walking down the hill as I was leaving the venue! Anchoring it all was the excellent view, and I particularly enjoyed the "scenic hacklab". I was particularly impressed with the flexability of the venue's management. Someone asked if we could have cheese for breakfast, and every breakfast thereafter had not one but often three excellent cheeses. One day we'd be complaining that there were not enough vegetables in the food, and the next we'd be eating an excellent vegetarian Swiss lunch. They even apparently relaxed stringent Swiss rules on not allowing tents in sightlines visible from people further up the hill. They were clearly happy to welcome our crazy gathering to Le Camp. They let a DD borrow and use a chain saw and build a bonfire! The venue also encouraged getting out and exploring the surrounding countryside. Too often I end up spending the whole DebConf without seeing much of the area around. This time I at least got down the hill to see the castle in Vaumarcus a few times, and enjoyed many evening walks amoung the grape fields. The conference dinner (on a boat!) tied into this well too. And the daytrip to CERN was a great addition. We got to poke around the control center for a massive particle accellerator! My only regret is we didn't get a chance to actually go inside the LHC tunnels. Back to DebConf, another thing I really liked about this one was that its location allowed several upstream authors of software in Debian (other than the usual suspects who are both upstreams and Debian Developers) to attend. I don't know if Lennart Poettering changed any minds about systemd with his talk, but I was happy for the opportunity to buy him a beer. I didn't get to Monty's talk, but it was excellent to see him attend as well. Finally, I got to meet old friends I'd not seen in years, and new ones I've not met in real life before. We're still not sure where this whole DebConf thing is going -- will it be all about the cheese and wine party and greybeards in 20 years time? But one thing we know is we enjoy our little slice of the year where kilts and coding are equally unremarkable, where problems that seem intractable online somehow solve themselves in person, where we come away with ideas for an entire year and memories for a lifetime.

27 August 2013

John Goerzen: Engaged!

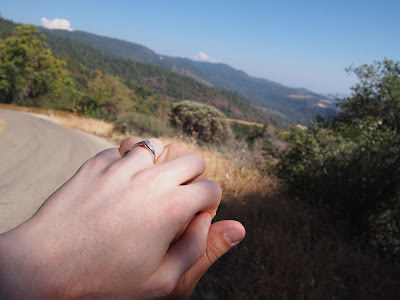
Today I have the delightful chance to write about a deep and wonderful joy. Yes, Laura and I are engaged! There are no words adequate for this kind of occasion, but there is a picture that gets close: I never imagined a person could find a friend so wonderful, a person that enjoys so much in common, someone that understands me and that I understand so well. And yet, here I am, engaged to that friend. Amazing only begins to describe the feeling. One of the first things Laura and I talked about was a hymn I was tinkering with, typesetting with GNU LilyPond. That hymn ends like this: Since Love is Lord of heav n and earth, how can I keep from singing? It is a wonderful thought, and very true. Even literally true; I often find myself singing, humming, or playing the penny whistle during my day. One of my good friends once told me, I am completely sure that your happiest days lie ahead of you. And he was right. I have already experienced them. This is a wonderful time, and every day brings plentiful reasons to be thankful. And as Laura and I prepare for a life together, I know that it is true not only that my friend was right, but that he is right my happiest days are yet to come, and our happiest days are yet to come, too. I have been blessed in many ways, and feel like the luckiest man alive. To be loved, and to love, a person so wonderful is truly a remarkable gift.

26 August 2013

Jose Luis Rivas: MongoDB: $pull from an embedded document array

TL;DR: db.collection.update( _id: 'x' , $pull: embedded_doc: _id: 'y' ) Queries are wrote for the mongo shell Dot based access If you have been using MongoDB for some time, then there are big chances that you will know the "dot-based access" on the find queries. This is the easier way to write those queries and will probably want to keep using that. Like:
db.collection.find( _id: 'x', 'embedded_doc._id': 'y' )
The thing is that does not work with everything, like: Arrays of embedded documents! Little example schema Let's suppose the following little schema (written for Mongoose): A = new Schema( w: String, x: String ); Document = new Schema( embedded_doc: [A] ); The collection of Document is called documents. Updating arrays If the arrays are not embedded documents I can actually just use a regular update like with any other field combined with a $set and change all the array like:
db.documents.update( _id: 'x',  $set:  array: [
   a: 1 , 
   a: 2 , 
   a: 3 
] )
And using conveniently $pull and $addToSet. But when it comes to embedded documents the history is very different. You can't make a simple $set because it will give you an error related to ModId which you can't change. So you really need to use $push, $addToSet, $pull and it's friends. So all those you can do it as in the manual, but what if you want to make a $pull over an array of objects and w and x are not unique? Well, that's why you probably made them an embedded document! Then you have the _id and you try to use the dot notation like:
db.documents.update( _id: 'x' ,  $pull:  "embedded_doc._id": 'y' )
And it looks good, except that it wont work. You have to use the complete syntax like:
db.documents.update( _id: 'x' ,  $pull:  embedded_doc:  _id: 'y' )

25 August 2013

Joey Hess: idea: git push requests

This is an idea that Keith Packard told me. It's a brilliant way to reduce GitHub's growing lockin, but I don't know how to implement it. And I almost forgot about it, until I had another annoying "how do I send you a patch with this amazing git technology?" experience and woke up with my memory refreshed. The idea is to allow anyone to git push to any anonymous git:// repository. But the objects pushed are not stored in a public part of the repository (which could be abused). Instead the receiving repository emails them off to the repository owner, in a git-am-able format. So this is like a github pull request except it can be made on any git repository, and you don't have to go look up the obfuscated contact email address and jump through git-format-patch hoops to make it. You just commit changes to your local repository, and git push to wherever you cloned from in the first place. If the push succeeds, you know your patch is on its way for review. Keith may have also wanted to store the objects in the repository in some way that a simple git command run there could apply them without the git-am bother on the receiving end. I forget. I think git-am would be good enough -- and including the actual diffs in the email would actually make this far superior to github pull request emails, which are maximally annoying by not doing so.
Hmm, I said I didn't know how to implement this, but I do know one way. Make the git-daemon run an arbitrary script when receiving a push request. A daemon.pushscript config setting could enable this. The script could be something like this:
#!/bin/sh
set -e
tmprepo="$(mktemp -d)"
# this shared clone is *really* fast even for huge repositories, and uses
# only a few 100 kb of disk space!
git clone --shared --bare "$GIT_DIR" "$tmprepo"
git-receive-pack "$tmprepo"
# XXX add email sending code here.
rm -rf "$tmprepo"
Of course, this functionality could be built into the git-daemon too. I suspect a script hook and an example script in contrib/ might be an easier patch to get accepted into git though. That may be as far as I take this idea, at least for now..

Vincent Bernat: Boilerplate for autotools-based C project

When starting a new HTML project, a common base is to use HTML5 Boilerplate which helps by setting up the essential bits. Such a template is quite useful for both beginners and experienced developers as it is kept up-to-date with best practices and it avoids forgetting some of them. Recently, I have started several little projects written in C for a customer. Each project was bootstrapped from the previous one. I thought it would be useful to start a template that I could reuse easily. Hence, bootstrap.c1, a template for simple projects written in C with the autotools, was born.

Usage A new project can be created from this template in three steps:
  1. Run Cookiecutter, a command-line tool to create projects from project templates, and answer the questions.
  2. Setup Git.
  3. Complete the todo list .

Cookiecutter Cookiecutter is a new tool to create projects from project templates. It uses Jinja2 as a template engine for file names and contents. It is language agnostic: you can use it for Python, HTML, Javascript or C! Cookiecutter is quite simple. You can read an introduction from Daniel Greenfeld. The Debian package is currently waiting in the NEW queue and should be available in a few weeks in Debian Sid. You can also install it with pip. Bootstrapping a new project is super easy:
$ cookiecutter https://github.com/vincentbernat/bootstrap.c.git
Cloning into 'bootstrap.c'...
remote: Counting objects: 90, done.
remote: Compressing objects: 100% (68/68), done.
remote: Total 90 (delta 48), reused 64 (delta 22)
Unpacking objects: 100% (90/90), done.
Checking connectivity... done
full_name (default is "Vincent Bernat")? Alfred Thirsty
email (default is "bernat@luffy.cx")? alfred@thirsty.eu
repo_name (default is "bootstrap")? secretproject
project_name (default is "bootstrap")? secretproject
project_description (default is "boilerplate for small C programs with autotools")? Super secret project for humans
Cookiecutter asks a few questions to instantiate the template correctly. The result has been stored in the supersecret directory:
.
  autogen.sh
  configure.ac
  get-version
  m4
      ax_cflags_gcc_option.m4
      ax_ld_check_flag.m4
  Makefile.am
  README.md
  src
      log.c
      log.h
      Makefile.am
  secretproject.8
  secretproject.c
  secretproject.h
2 directories, 13 files

Remaining steps There are still some steps to be executed manually. You first need to initalize Git, as some features of this template rely on it:
$ git init
Initialized empty Git repository in /home/bernat/tmp/secretproject/.git/
$ git add .
$ git commit -m "Initial import"
[...]
Then, you need to extract the todo list built from the comments contained in source files:
$ git ls-tree -r --name-only HEAD   \
>   xargs grep -nH "T[O]DO:"   \
>   sed 's/\([^:]*:[^:]*\):\(.*\)T[O]DO:\(.*\)/\3 (\1)/'   \
>   sort -ns   \
>   awk '(last != $1)  print ""   last=$1 ; print '
2003 Add the dependencies of your project here. (configure.ac:52)
2003 The use of "Jansson" here is an example, you don't have (configure.ac:53)
2003 to keep it. (configure.ac:54)
2004 Each time you have used  PKG_CHECK_MODULES  macro (src/Makefile.am:12)
2004 in  configure.ac , you get two variables that (src/Makefile.am:13)
2004 you can substitute like above. (src/Makefile.am:14)
3000 It's time for you program to do something. Add anything (src/secretproject.c:76)
3000 you want here. */ (src/secretproject.c:77)
[...]
Only a few minutes are needed to complete those steps.

What do you get? Here are the main features:
  • Minimal configure.ac and Makefile.am.
  • Changelog based on Git logs and automatic version from Git tags2.
  • Manual page skeleton.
  • Logging infrastructure with variadic functions like log_warn(), log_info().
logging output of lldpd

About the use of the autotools The autotools are a suite of tools to provide a build system for a project, including:
  • autoconf to generate a configure script, and
  • automake to generate makefiles using a similar but higher-level language.
Understanding the autotools can be a quite difficult task. There are a lot of bad documentations on the web and the manual does not help by describing corner-cases that would be useful if you wanted your project to compile for HP-UX. So, why do I use it?
  1. I have invested a lot of time in the understanding of this build system. Once you grasp how it should be used, it works reasonably well and can cover most of your needs. Maybe CMake would be a better choice but I have yet to learn it. Moreover, the autotools are so widespread that you have to know how they work.
  2. There are a lot of macros available for autoconf. Many of them are included in the GNU Autoconf Archive and ready to use. The quality of such macros are usually quite good. If you need to correctly detect the appropriate way to compile a program with GNU Readline or something compatible, there is a macro for that.
If you want to learn more about the autotools, do not read the manual. Instead, have a look at Autotools Mythbuster. Start with a minimal configure.ac and do not add useless macros: a macro should be used only if it solves a real problem. Happy hacking!

  1. Retrospectively, I think boilerplate.c would have been a better name.
  2. For more information on those features, have a look at their presentation in a previous post about lldpd.

Matthias Klumpp: Some Tanglu updates

Tanglu Logo (big)Long time since I published the last update about Tanglu. So here is a short summary about what we did meanwhile (even if you don t hear that much, there is lots of stuff going on!) Better QA in the archive We now use a modified version of Debian s Britney tool to migrate packages from the newly-created staging suite to our current development branch aequorea . This ensures that all packages are completely built on all architectures and don t break other packages. New uploads and syncs/merges now happen through the staging area and can be tested there as well as being blocked on demand, so our current aequorea development branch stays installable and usable for development. People who want the *very* latest stuff, can embed the staging-sources into their sources.list (but we don t encourage you to do that). Improved syncs from Debian The Synchrotron toolset we use to sync packages with Debian recently gained the ability to sync packages using regular expressions. This makes it possible to sync many packages quickly which match a pattern. Tons of infrastructure bugfixes The infrastructure has been tweaked a lot to remove quirks, and it now works quite smoothly. Also, all Debian tools now work flawless in the Tanglu environment. A few issues are remaining, but nothing really important is affected anymore (and some problems are merely cosmetic). Long term we plan to replace the Jenkins build-infrastructure with the software which is running Paul Tagliamontes debuild.me (only the buildd service, the archive will still be managed by dak). This requires lots of work, but will result in software not only usable by Tanglu, but also by Debian itself and everyone who wants a build-service capable of building a Debian-distro. KDE 4.10 and GNOME 3.8 Tanglu now offers KDE 4.10 by default, a sync of GNOME 3.8 is currently in progress. The packages will be updated depending on our resources and otherwise just be synced from Debian unstable/experimental (and made working for Tanglu). systemd 204 & libudev1 Tanglu now offers systemd 204 as default init system, and we transitioned the whole distribution to the latest version of udev. This even highlighted a few issues which could be fixed before the latest systemd reached Debian experimental. The udev transition went nicely, and hopefully Debian will fix bug#717418 too, soon, so both distributions run with the same udev version (which obviously makes things easier for Tanglu ^^) Artwork We now have a plymouth-bootscreen and wallpapers and stuff is in progress :-) Alpha-release & Live-CD ? This is what we are working on we have some issues in creating a working live-cd, since live-build does have some issues with our stack. We are currently resolving issues, but because of the lack of manpower, this is progressing slowly (all contributors also work on other FLOSS projects and of course also have their work :P ) As soon as we have working live-media, we can do a first alpha release and offer installation media. You! Tanglu is a large task. And we need every help we can get, right now especially technical help from people who can build packages (Debian Developers/Maintainers, Ubuntu developers, etc.) We especially need someone to take care of the live-cd. But also the website needs some help, and we need more artwork or improved artwork ;-) In general, if you have an idea how to make Tanglu better (of course, something which matches it s goals :P ) and want to realize it, just come back to us! You can reach us on the mailiglists (tanglu-project for stuff related to the project, tanglu-devel for development of the distro) or in #tanglu / #tanglu-devel (on Freenode).

24 August 2013

Marko Lalic: PTS rewrite: Django Memory Usage


Rewriting the PTS in a fairly large Web framework such as Django is sure to cause larger memory consumption by even the more simple tasks, when compared to a couple of (loosely related) perl scripts. If anything, simply due to the fact that the entire Django machinery needs to be loaded.

However, just how large the memory consumption difference between the two can be seen in the example of the command to dispatch received package emails to users. In the new version, the command is implemented as a Django management command, whereas before it was a perl script dispatch.pl relying on the common.pl script for some additional functions.

The reason this command's memory usage is important is an incident with the current test deployment of the new PTS found at http://pts.debian.net. All package mails that the old PTS receives are also forwarded to the new instance in order to expose the new implementation to real-world mail traffic. At a certain point, over a hundred mails were received instantly causing over a hundred dispatch processes to be launched. This led to the system running out of memory and the kernel had to run the OOM Killer which brought down PostgreSQL server thereby causing the site to become unavailable.

For now, such a problem seems to have been prevented from reoccurring by setting up exim to queue messages when a certain system average load is exceeded, however it is interesting to check how large the memory consumption difference between the old and new dispatch really is.

Measurement setupIn order to measure the memory use, two messages of different sizes were used: 1KB and 1MB.

For the new PTS two cases were considered, when the database used is sqlite3 and PostgreSQL. In both cases, it was simply initialized by syncdb, meaning it contained only the default keywords found in the initial fixture and no registered users and subscriptions. The DEBUG setting was set to False.

For testing the old PTS's dispatch.pl, the database was also initialized empty.

This way, the tests should show the actual difference between the two implementations.

Since the main concern here is the maximum memory usage of the dispatch script, a simple bash script was written which takes a PID of a running process and outputs the maximum memory usage as reported by ps once the process is terminated. The script used is shown below.

#!/usr/bin/env bash

pid=$1

while ps $pid >/dev/null
do
ps -o vsz= $ pid
sleep 0.1
done sort -n tail -n1

Old PTS Measurements
The maximum memory usage of the old PTS was:
  1. 37.8 MB for the 1 KB message
  2. 38.2 MB for the 1 MB message

New PTS Measurements

sqlite3
The maximum memory usage of the new PTS using sqlite3 was:
  1. 91.77 MB for the 1 KB message
  2. 92.59 MB for the 1 MB message

PostgreSQL

The maximum memory usage of the new PTS using PostgreSQL was:
  1. 148 MB for the 1 KB message
  2. 160 MB for the 1 MB message

Comparison and DiscussionWhen comparing the memory used by the old dispatch.pl implementation and the new PTS running sqlite3, the difference does not seem to be too large and is to be expected, since, as mentioned, the whole Django framework is loaded when executing a management command.

However, the huge difference between the two versions of the new PTS: the one using sqlite3 and the one using PostgreSQL is very surprising indeed.

Another interesting measurement is the difference between running a bare Django management command: one including only a sleep statement (in order to allow enough time to measure its memory usage) on PostgreSQL and sqlite3. In both cases, the memory usage was only about 1 MB less than what the respective maximum memory usage when processing the 1 KB message.

All this considered, the logical conclusion seems to be that either psycopg2 package and/or the Django postgresql_psycopg2 database engine use a lot more memory than the corresponding sqlite3 alternatives.

Could anyone shed some more light as to what causes this stark difference between using sqlite3 and Postgres in Django? Anything that could be done to mitigate it?

Marko Lalic: PTS Rewrite Project Status

The rewrite has already achieved some of the major goals which have been set in the beginning, as well as made some changes and improvements along the way. Some of the major points of the new system implemented so far will be presented here.

    Tasks framework
    The current PTS implementation regenerates the HTML pages for all packages a few times per day. A goal of the rewrite was to make smaller incremental updates possible so that the information displayed for each package can be much more dynamic.

    In order to allow incremental updates, it is necessary to consider the situation where updating some information should trigger an update of other information.

    This is where the tasks framework comes in. It allows developers to define a task with a list of "events" that it produces. An event can be triggered by any change to shared information or anything else the task would like to signal. Each event is identified by a simple unique string name. Events can also contain arbitrary (JSON-serializable) objects. Other than events that it produces, a task defines a list of dependencies events it depends on.

    When a single task should be executed, the tasks framework uses this information to build a dependency graph (a DAG) and executes the tasks in topological sort order, making sure each task runs only after all tasks which could raise an event it depends on have finished. It automatically makes the raised events available to the task so that it can access the extra data. Tasks for which no event was raised are skipped.

    Such execution of a task along with all its dependencies is called a Job. A Job's state is persisted to the database after each task completes its operation. This allows Jobs to be continued if there is an unexpected error causing it to terminate.

    So far, the tasks framework has already proven useful. For example, there are tasks which extract some package information to a denormalized model suited for directly displaying the data in the package page after a new package version is detected in a repository. Other examples are tasks which update standards-version warnings (after a new package version is detected) and the news generation task based on various detected changes to the packages (new source version, version removed from repository, version migrated to another repository).

    Vendor-specific customizationAnother goal of the rewrite was to make the PTS less Debian-specific. This is so that derivatives could easily deploy their own versions of the PTS. The idea is to have a number of core PTS services which alternative deployments can customize and augment.

    The simplest way vendors can customize PTS is by changing some of the local settings values. An example of this would be changing the PTS_VENDOR_NAME which leads to this name being displayed in any part of the system.

    This is fairly uninteresting since the information is always static. What is more interesting is when the vendor should provide different information based on some context, e.g. package name, received message, etc. This requirement led to the concept of the vendor app with a rules module.

    Various core parts of the PTS specify hook functions which different vendors can implement to provide customized behavior of the core component. Some examples are:
    • providing URLs to a developer information site (e.g. http://qa.debian.org/developer.php in Debian's case) based on a developer's email
    • providing a URL to a bug tracker for a particular package (based on the package type and bug category type)
    • providing additional rules to tag received package mails with keywords
    • providing additional headers to be injected in the forwarded package mails
    • providing a list of bugs which should be displayed in the bugs panel
    A settings value is set giving the full dotted path to the Python module containing the implementation of these hook functions.

    Vendor-specific featuresA step beyond customizing core features is for vendors to include their own specific functionality. The already described tasks framework allows for implementing custom data update/generation processes (optionally depending on core events). Furthermore, since a vendor-specific Django app is expected, it can contain any vendor-specific models which are managed just as the core models are (syncdb, migrations, etc. all work as expected). The last piece of the puzzle is displaying this information on the package page.

    Currently, all package information is provided in various boxes (general, bugs, links, etc.) which were named panels. The rewrite has made it possible to implement additional panels in a really elegant way.

    It is required to implement a class with some properties giving:
    • the panel's title
    • position in the page (left, center, right)
    • panel importance (higher importance panels are placed above lower importance ones in the same column)
    To generate the HTML for a package, two alternatives are allowed. The first is to provide a property which gives (explicitly marked safe) HTML output which is then included in the correct position verbatim. The second alternative, which is what should cover most needs and should be preferred, is to provide a property giving a template name and a property giving the additional context variables necessary to render this template. By using the power of Python properties, the context can be dynamically generated for each package by the panel. The PTS then makes sure to pass the correct panel's context when rendering its template and to include the rendered result in the final package page.

    Various convenience classes are implemented in the panel API, but those are better left to be read about in the panels API documentation.

    Changes from current PTSSome existing features of PTS were not simply rewritten to fit into a Django project, but also improved upon.

    One of the first such changes was reducing the number of confirmation mails sent by the email control bot to only one per received control mail (as per a wishlist PTS bug).

    Work started by Markus Wanner (see this bug) was expanded on and integrated with the new News model so that any inline GPG signatures found in the content of a news item are automatically extracted and the signers name displayed in the package page.

    The existing TODO and Probems panels have been merged into a single Action Needed panel. However, besides merging their representation in the package page, all the package issues are now represented as an ActionItem Django model which provides additional meta-data (item type, date created/updated, severity level) which could be used in the future to provide additional functionality (such as all packages with a certain issue type).

    The descriptions of the action items were also shortened from their current rendition, with the detailed description being moved to a dedicated item page. If Javascript is enabled in the user's browser, it can also be displayed in a popup.

    GUIThe graphical interface has seen some changes, however I hesitate to claim improvements. In my opinion, some of it is definitely better, more polished and more "modern" (for what it's worth).

    Still, this could benefit from more people getting involved in testing and providing feedback so that the design is polished to suit the largest number of users. For example, the padding between the panels is increased, which to me definitely looks better, however, it is possible that this introduces too much whitespace and reduces the information density below what some may expect.

    RecapOverall, I am quite pleased with where the project is currently. Most of the information provided by the current PTS has been reimplemented, with only a few smaller ones remaining. For now, since we are nearly entering the final month of GSoC, the development will switch focus from porting old features to the new PTS to adding in some new ones. Namely, user registration and account management is in the pipeline for the coming week. It entails features such as managing package subscriptions via the online interface (for multiple emails associated with the account) and sso.debian.org integration for Debian Developers.

    This post aimed to provide the most notable changes and improvements made so far to the PTS. In reality, there has been quite a lot of them and not everything is covered here. For more information, check out the PTS documentation which is updated weekly (corresponding to the weekly deployments) or the source code repository.

    The latest iteration of the PTS can always be found at http://pts.debian.net. The mail control interface bot responds to mails sent to control@pts.debian.net.

    Stay tuned for updates and be sure to check out pts.debian.net on at least a weekly basis to see new deployments in action!

    23 August 2013

    Thorsten Glaser: FrOSCon 2013, or, why is there no MirBSD exhibit?

    FrOSCon is approaching, and all MirBSD developers will attend but why s there no MirBSD exhibit? The answer to that is a bit complex. First let s state that of course we will participate in the event as well as the Open Source world. We ll also be geocaching around the campus with other interested (mostly OSS) people (including those we won for this sport) and helping out other OSS projects we ve become attached to. MirOS BSD, the operating system, is a niche system. The conference on the other hand got younger and more mainstream. This means that almost all conference visitors do not belong to the target group of MirOS BSD which somewhat is an ancient solution : the most classical BSD around (NetBSD loses because they have rc.d and PAM and lack sendmail(8), sorry guys, your attempt at being not reformable doesn t count) and running on restricted hardware (such as my 486SLC with 12 MiB RAM) and exots (SPARCstation). It s viable even as developer workstation (if your hardware is supported otherwise just virtualise it) but its strength lies with SPARC support and embedded x86 . And being run as virtual machine: we re reportedly more stable and more performant than OpenBSD. MirBSD is not cut off from modern development and occasionally takes a questionable but justified choice (such as using 16-bit Unicode internally) or a weird-looking but beneficial one (such as OPTU encoding saving us locale(1) hassles) or even acts as technological pioneer (64-bit time_t on ILP32 platforms) or, at least, is faster than OpenBSD (newer GNU toolchain, things like that), but usually more conservatively, and yes, this is by design, not by lack of manpower, most of the time. The MirPorts Framework, while technically superiour in enough places, is something that just cannot happen without manpower. I (tg@) am still using it exclusively, continuing to update ports I use and occasionally creating new ones (mupdf is in the works!), but it s not something I d recommend someone (other than an Mac OSX user) to use on a n n-MirBSD system (Interix is not exactly thriving either, and the Interix support was only begun; other OSes are not widely tested). The MirBSD Korn Shell is probably the one thing I will be remembered for. But I have absolutely no idea how one would present it on a booth at such an exhibition. A talk is much more likely. So no on that front too. jupp, the editor which sucks less, is probably something that does deserve mainstream interest (especially considering Natureshadow is using it while teaching computing to kids) but probably more in a workshop setting. And booth space is precious enough in the FH so I think that d be unfair. All the other subprojects and side projects Benny and I have, such as mir c , josef stalin, FreeWRT, Lunix Ewe, Shellsnippets, the fonts, etc. are interesting but share few, if any, common ground. Again, this does not match the vast majority of visitors. While we probably should push a number of these more, but a booth isn t it here, either. MirOS Linux ( MirLinux ) and MirOS Windows are, despite otherwise-saying rumours called W*k*p*d*a, only premature ideas that will not really be worked on (though MirLinux concepts are found in mir c and stalin). As you can see, despite all developers having full-time dayjobs, The MirOS Project is far from being obsolete. We hope that our website visitors understand our reasons to not have an exhibition booth of our own (even if the SPARCstation makes for a way cool one, it s too heavy to lift all the time), and would like to point out that there are several other booths (commercial ones, as well as OSS ones such as AllBSD, Debian and (talking to) others) and other itineries we participate in. This year both Benny and I have been roped into helping out the conference itself, too (not exactly unvoluntarily though). The best way to talk to us is IRC during regular European geek hours (i.e. until way too late into the night which Americans should benefit from), semi-synchronously, or mailing lists. We sort of expect you to not be afraid to RTFM and look up acronyms you don t understand; The MirOS Project is not unfriendly but definitely not suited for your proverbial Aunt Tilly, newbies, desktop users, and people who aren t at least somewhat capable of using written English (this is by design).

    Justus Winter: No noweb anymore...

    ... which is probably a good thing. But here is the boot log you all have been waiting for:
    start ext2fs: Hurd server bootstrap: ext2fs[device:hd0s1] exec init proc auth
    INIT: version 2.88 booting
    Using makefile-style concurrent boot in runlevel S.
    Activating swap...done.
    Checking root file system...fsck from util-linux 2.20.1
    hd2 : tray open or drive not ready
    hd2 : tray open or drive not ready
    hd2 : tray open or drive not ready
    hd2 : tray open or drive not ready
    end_request: I/O error, dev 02:00, sector 0
    /dev/hd0s1: clean, 44693/181056 files, 291766/723200 blocks
    done.
    Activating lvm and md swap...(default pager): Already paging to partition hd0s5!
    done.
    Checking file systems...fsck from util-linux 2.20.1
    hd2 : tray open or drive not ready
    hd2 : tray open or drive not ready
    end_request: I/O error, dev 02:00, sector 0
    done.
    Cleaning up temporary files... /tmp.
    Mounting local filesystems...done.
    Activating swapfile swap...(default pager): Already paging to partition hd0s5!
    done.
    df: Warning: cannot read table of mounted file systems: No such file or directory
    Cleaning up temporary files....
    Configuring network interfaces...Internet Systems Consortium DHCP Client 4.2.2
    Copyright 2004-2011 Internet Systems Consortium.
    All rights reserved.
    For info, please visit https://www.isc.org/software/dhcp/
    Listening on Socket//dev/eth0
    Sending on   Socket//dev/eth0
    *** stack smashing detected ***: dhclient terminated
    Aborted
    Failed to bring up /dev/eth0.
    done.
    Cleaning up temporary files....
    Setting up X socket directories... /tmp/.X11-unix /tmp/.ICE-unix.
    INIT: Entering runlevel: 2
    Using makefile-style concurrent boot in runlevel 2.
    Starting enhanced syslogd: rsyslogd.
    Starting deferred execution scheduler: atd.
    Starting periodic command scheduler: cron.
    Starting system message bus: dbusFailed to set socket option"/var/run/dbus/system_bus_socket": Protocol not available.
    Starting OpenBSD Secure Shell server: sshd.
    unexpected ACK from keyboard
    GNU 0.3 (debian) (console)
    login: root
    [...]
    root@debian:~# ifup /dev/eth0
    Internet Systems Consortium DHCP Client 4.2.2
    Copyright 2004-2011 Internet Systems Consortium.
    All rights reserved.
    For info, please visit https://www.isc.org/software/dhcp/
    Listening on Socket//dev/eth0
    Sending on   Socket//dev/eth0
    *** stack smashing detected ***: dhclient terminated
    Aborted
    Failed to bring up /dev/eth0.
    root@debian:~# dhclient -v -pf /run/dhclient.-dev-eth0.pid -lf /var/lib/dhcp/dhclient.-dev-eth0.leases /dev/eth0
    Internet Systems Consortium DHCP Client 4.2.2
    Copyright 2004-2011 Internet Systems Consortium.
    All rights reserved.
    For info, please visit https://www.isc.org/software/dhcp/
    Listening on Socket//dev/eth0
    Sending on   Socket//dev/eth0
    *** stack smashing detected ***: dhclient terminated
    Aborted
    root@debian:~# dhclient -pf /run/dhclient.-dev-eth0.pid -lf /var/lib/dhcp/dhclient.-dev-eth0.leases /dev/eth0
    root@debian:~# ifup /dev/eth0
    Internet Systems Consortium DHCP Client 4.2.2
    Copyright 2004-2011 Internet Systems Consortium.
    All rights reserved.
    For info, please visit https://www.isc.org/software/dhcp/
    Listening on Socket//dev/eth0
    Sending on   Socket//dev/eth0
    DHCPREQUEST on /dev/eth0 to 255.255.255.255 port 67
    DHCPACK from 10.0.2.2
    bound to 10.0.2.15 -- renewal in 34108 seconds.
    ps: comm: Unknown format spec
    root@debian:~# halt
    Broadcast message from root@debian (console) (Fri Aug 23 19:42:19 2013):
    The system is going down for system halt NOW!
    INIT: Switching to runlevel: 0root@debian:~#
    INIT: Sending processes the TERM signal
    INIT: Sending processes the KILL signal
    Using makefile-style concurrent boot in runlevel 0.
    Stopping deferred execution scheduler: atd.
    task c10f53f8 deallocating an invalid port 2098928, most probably a bug.
    Asking all remaining processes to terminate...done.
    All processes ended within 1 seconds...done.
    Stopping enhanced syslogd: rsyslogd.
    Deconfiguring network interfaces...Internet Systems Consortium DHCP Client 4.2.2
    Copyright 2004-2011 Internet Systems Consortium.
    All rights reserved.
    For info, please visit https://www.isc.org/software/dhcp/
    Listening on Socket//dev/eth0
    Sending on   Socket//dev/eth0
    DHCPRELEASE on /dev/eth0 to 10.0.2.2 port 67
    /dev/eth0 (2):
      inet address  0.0.0.0
      netmask       255.255.255.0
      broadcast     10.0.2.255
      flags         BROADCAST ALLMULTI MULTICAST
      mtu           1500
    done.
    Deactivating swap...swapoff: /dev/hd0s5: 177152k swap space
    done.
    Unmounting weak filesystems...umount: /etc/mtab: Warning: duplicate entry for device /dev/hd0s1 (/servers/socket/26)
    umount: /etc/mtab: Warning: duplicate entry for device /dev/hd0s1 (/dev/cons)
    umount: could not find entry for: /dev/cons
    umount: could not find entry for: /servers/socket/26
    done.
    mount: cannot remount /: Device or resource busy
    Will now halt.
    store a new irq 11init: notifying pfinet of shutdown...init: notifying tmpfs swap of shutdown...init: notifying tmpfs swap of shutdown...init: notifying tmpfs swap of shutdown...init: notifying ext2fs device:hd0s1 of shutdown...init: halting Mach (flags 0x8)...
    In tight loop: hit ctl-alt-del to reboot
    
    With some tiny patches for ifupdown I've been able to resolve network related issues. All of them? Of course not, funny thing about developing for the Hurd is that once you fix one thing, then some other thing or code path is executed that has never been run on Hurd before, and therefore something else breaks. In this case I fixed ifupdown to generate valid names for the pid file and leases file and all of the sudden dhclient starts dying. Funny thing about that is, if one drops the -v flag from the dhclient invocation as I did it above, the crash isn't triggered and once the lease file has been successfully written, it is safe to add the -v flag again. Not yet sure what goes on there, then again, looking at the source of isc-dhcp-client it is not so surprising that it crashes :/ When I first looked at ifupdown it was written in noweb, a literate programming tool. It is an interesting idea, even more so since (classic) c can be very verbose and cryptic. But it decouples the control flow from the structure of the program, which makes patching it quite a challenge since it is not as obvious where the changes have to go in. This is how ifupdown looked some weeks ago:
    % wc --lines ifupdown.nw
    6123 ifupdown.nw
    % pdftk ifupdown.pdf dump_data   grep NumberOfPages
    NumberOfPages: 113
    
    The ifupdown.nw is the noweb source, from which seven .c, four .h, two .pl and one Makefile are generated. It also contains a redicioulus amount of documentation, to the point that the authors at several points did not now what to write and just drop some nonsensical lines into the file. The source also compiles to a 113 page pdf file, that contains all of the documentation and all of the code, not at all in the order that one would expect a program to be written, but in the order the authors chose to structure the documentation. Fortunately for me the maintainer decided to drop the noweb source and to add the generated files to the source control system. This made my job much easier :) So here are the patches I published this week: I must admit that I do not know exactly what I will do next week. Obviously fixing the dhclient crash would be nice, I'll look into that. But I'm surely find some useful thing to do.

    Next.

    Previous.