Search Results: "ed"

8 April 2022

Dirk Eddelbuettel: RcppEigen 0.3.3.9.2 on CRAN: Maintenance

A new release 0.3.3.9.2 of RcppEigen arrived on CRAN today (and already went to Debian). Eigen is a C++ template library for linear algebra: matrices, vectors, numerical solvers, and related algorithms. This update was (as it happens) requested by CRAN as R aims to bring the Fortran / C interface to best practices. We call dgesdd twice in one example and use a character argument, and the-powers-that-be now prefer better control over that character argument. So we did. Another change, kindly contributed by Mikael Jagan, switches row and column indices for R_xlen_t allowing for greater range. Plus some more small tweaks mostly to CI, see the NEWS entry below for full details. And again as we said for the previous three releases:
One additional and recent change was the accomodation of a recent CRAN Policy change to not allow gcc or clang to mess with diagnostic messages. A word of caution: this may make your compilation of packages using RcppEigen very noisy so consider adding -Wno-ignored-attributes to the compiler flags added in your ~/.R/Makevars.
We still find this requirement rather annoying. Eigen is only usable if you set, say,
-Wno-deprecated-declarations -Wno-parentheses -Wno-ignored-attributes -Wno-unused-function
asoptions in~/.R/Makevars . But CRAN makes the rules. Maybe if a few of us gently and politely nudge them they may relent one day. One can only hope. The complete NEWS file entry follows.

Changes in RcppEigen version 0.3.3.9.2 (2022-04-05)
  • Added test coverage in continuous integration
  • Added new tests to increase test coverage
  • Small improvement to the RcppEigen.package.skeleton() code
  • Small updates and edits to README.md and inst/CITATION
  • Use R_xlen_t for vector rows and columns (by Mikael Jagan)
  • Support USE_FC_LEN_T by adding FCONE to two dgesdd calls

Courtesy of CRANberries, there is also a diffstat report for the most recent release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Reproducible Builds: Reproducible Builds in March 2022

Welcome to the March 2022 report from the Reproducible Builds project! In our monthly reports we outline the most important things that we have been up to over the past month.
The in-toto project was accepted as an incubating project within the Cloud Native Computing Foundation (CNCF). in-toto is a framework that protects the software supply chain by collecting and verifying relevant data. It does so by enabling libraries to collect information about software supply chain actions and then allowing software users and/or project managers to publish policies about software supply chain practices that can be verified before deploying or installing software. CNCF foundations hosts a number of critical components of the global technology infrastructure under the auspices of the Linux Foundation. (View full announcement.)
Herv Boutemy posted to our mailing list with an announcement that the Java Reproducible Central has hit the milestone of 500 fully reproduced builds of upstream projects . Indeed, at the time of writing, according to the nightly rebuild results, 530 releases were found to be fully reproducible, with 100% reproducible artifacts.
GitBOM is relatively new project to enable build tools trace every source file that is incorporated into build artifacts. As an experiment and/or proof-of-concept, the GitBOM developers are rebuilding Debian to generate side-channel build metadata for versions of Debian that have already been released. This only works because Debian is (partial) reproducible, so one can be sure that that, if the case where build artifacts are identical, any metadata generated during these instrumented builds applies to the binaries that were built and released in the past. More information on their approach is available in README file in the bomsh repository.
Ludovic Courtes has published an academic paper discussing how the performance requirements of high-performance computing are not (as usually assumed) at odds with reproducible builds. The received wisdom is that vendor-specific libraries and platform-specific CPU extensions have resulted in a culture of local recompilation to ensure the best performance, rendering the property of reproducibility unobtainable or even meaningless. In his paper, Ludovic explains how Guix has:
[ ] implemented what we call package multi-versioning for C/C++ software that lacks function multi-versioning and run-time dispatch [ ]. It is another way to ensure that users do not have to trade reproducibility for performance. (full PDF)

Kit Martin posted to the FOSSA blog a post titled The Three Pillars of Reproducible Builds. Inspired by the shock of infiltrated or intentionally broken NPM packages, supply chain attacks, long-unnoticed backdoors , the post goes on to outline the high-level steps that lead to a reproducible build:
It is one thing to talk about reproducible builds and how they strengthen software supply chain security, but it s quite another to effectively configure a reproducible build. Concrete steps for specific languages are a far larger topic than can be covered in a single blog post, but today we ll be talking about some guiding principles when designing reproducible builds. [ ]
The article was discussed on Hacker News.
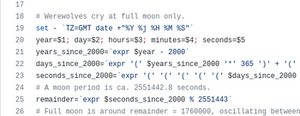
Finally, Bernhard M. Wiedemann noticed that the GNU Helloworld project varies depending on whether it is being built during a full moon! (Reddit announcement, openSUSE bug report)

Events There will be an in-person Debian Reunion in Hamburg, Germany later this year, taking place from 23 30 May. Although this is a Debian event, there will be some folks from the broader Reproducible Builds community and, of course, everyone is welcome. Please see the event page on the Debian wiki for more information. Bernhard M. Wiedemann posted to our mailing list about a meetup for Reproducible Builds folks at the openSUSE conference in Nuremberg, Germany. It was also recently announced that DebConf22 will take place this year as an in-person conference in Prizren, Kosovo. The pre-conference meeting (or Debcamp ) will take place from 10 16 July, and the main talks, workshops, etc. will take place from 17 24 July.

Misc news Holger Levsen updated the Reproducible Builds website to improve the documentation for the SOURCE_DATE_EPOCH environment variable, both by expanding parts of the existing text [ ][ ] as well as clarifying meaning by removing text in other places [ ]. In addition, Chris Lamb added a Twitter Card to our website s metadata too [ ][ ][ ]. On our mailing list this month:

Distribution work In Debian this month:
  • Johannes Schauer Marin Rodrigues posted to the debian-devel list mentioning that he exploited the property of reproducibility within Debian to demonstrate that automatically converting a large number of packages to a new internal source version did not change the resulting packages. The proposed change could therefore be applied without causing breakage:
So now we have 364 source packages for which we have a patch and for which we can show that this patch does not change the build output. Do you agree that with those two properties, the advantages of the 3.0 (quilt) format are sufficient such that the change shall be implemented at least for those 364? [ ]
In openSUSE, Bernhard M. Wiedemann posted his usual monthly reproducible builds status report.

Tooling diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 207, 208 and 209 to Debian unstable, as well as made the following changes to the code itself:
  • Update minimum version of Black to prevent test failure on Ubuntu jammy. [ ]
  • Updated the R test fixture for the 4.2.x series of the R programming language. [ ]
Brent Spillner also worked on adding graceful handling for UNIX sockets and named pipes to diffoscope. [ ][ ][ ]. Vagrant Cascadian also updated the diffoscope package in GNU Guix. [ ][ ] reprotest is the Reproducible Build s project end-user tool to build the same source code twice in widely different environments and checking whether the binaries produced by the builds have any differences. This month, Santiago Ruano Rinc n added a new --append-build-command option [ ], which was subsequently uploaded to Debian unstable by Holger Levsen.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Replace a local copy of the dsa-check-running-kernel script with a packaged version. [ ]
    • Don t hide the status of offline hosts in the Jenkins shell monitor. [ ]
    • Detect undefined service problems in the node health check. [ ]
    • Update the sources.lst file for our mail server as its still running Debian buster. [ ]
    • Add our mail server to our node inventory so it is included in the Jenkins maintenance processes. [ ]
    • Remove the debsecan package everywhere; it got installed accidentally via the Recommends relation. [ ]
    • Document the usage of the osuosl174 host. [ ]
Regular node maintenance was also performed by Holger Levsen [ ], Vagrant Cascadian [ ][ ][ ] and Mattia Rizzolo.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Jacob Adams: The Unexpected Importance of the Trailing Slash

For many using Unix-derived systems today, we take for granted that /some/path and /some/path/ are the same. Most shells will even add a trailing slash for you when you press the Tab key after the name of a directory or a symbolic link to one. However, many programs treat these two paths as subtly different in certain cases, which I outline below, as all three have tripped me up in various ways1.

POSIX and Coreutils Perhaps the trickiest use of the trailing slash in a distinguishing way is in POSIX2 which states:
When the final component of a pathname is a symbolic link, the standard requires that a trailing <slash> causes the link to be followed. This is the behavior of historical implementations3. For example, for /a/b and /a/b/, if /a/b is a symbolic link to a directory, then /a/b refers to the symbolic link, and /a/b/ refers to the directory to which the symbolic link points.
This leads to some unexpected behavior. For example, if you have the following structure of a directory dir containing a file dirfile with a symbolic link link pointing to dir. (which will be used in all shell examples throughout this article):
$ ls -lR
.:
total 4
drwxr-xr-x 2 jacob jacob 4096 Apr  3 00:00 dir
lrwxrwxrwx 1 jacob jacob    3 Apr  3 00:00 link -> dir
./dir:
total 0
-rw-r--r-- 1 jacob jacob 0 Apr  3 00:12 dirfile
On Unixes such as MacOS, FreeBSD or Illumos4, you can move a directory through a symbolic link by using a trailing slash:
$ mv link/ otherdir
$ ls
link	otherdir
On Linux5, mv will not rename the indirectly referenced directory and not the symbolic link, when given a symbolic link with a trailing slash as the source to be renamed. despite the coreutils documentation s claims to the contrary6, instead failing with Not a directory:
$ mv link/ other
mv: cannot move 'link/' to 'other': Not a directory
$ mkdir otherdir
$ mv link/ otherdir
mv: cannot move 'link/' to 'otherdir/link': Not a directory
$ mv link/ otherdir/
mv: cannot move 'link/' to 'otherdir/link': Not a directory
$ mv link otherdirlink
$ ls -l otherdirlink
lrwxrwxrwx 1 jacob jacob 3 Apr  3 00:13 otherdirlink -> dir
This is probably for the best, as it is very confusing behavior. There is still one advantage the trailing slash has when using mv, even on Linux, in that is it does not allow you to move a file to a non-existent directory, or move a file that you expect to be a directory that isn t.
$ mv dir/dirfile nonedir/
mv: cannot move 'dir/dirfile' to 'nonedir/': Not a directory
$ touch otherfile
$ mv otherfile/ dir
mv: cannot stat 'otherfile/': Not a directory
$ mv otherfile dir
$ ls dir
dirfile  otherfile
However, Linux still exhibits some confusing behavior of its own, like when you attempt to remove link recursively with a trailing slash:
rm -rvf link/
Neither link nor dir are removed, but the contents of dir are removed:
removed 'link/dirfile'
Whereas if you remove the trailing slash, you just remove the symbolic link:
$ rm -rvf link
removed 'link'
While on MacOS, FreeBSD or Illumos4, rm will also remove the source directory:
$ rm -rvf link
link/dirfile
link/
$ ls
link
The find and ls commands, in contrast, behave the same on all three operating systems. The find command only searches the contents of the directory a symbolic link points to if the trailing slash is added:
$ find link -name dirfile
$ find link/ -name dirfile
link/dirfile
The ls command acts similarly, showing information on just a symbolic link by itself unless a trailing slash is added, at which point it shows the contents of the directory that it links to:
$ ls -l link
lrwxrwxrwx 1 jacob jacob 3 Apr  3 00:13 link -> dir
$ ls -l link/
total 0
-rw-r--r-- 1 jacob jacob 0 Apr  3 00:13 dirfile

rsync The command rsync handles a trailing slash in an unusual way that trips up many new users. The rsync man page notes:
You can think of a trailing / on a source as meaning copy the contents of this directory as opposed to copy the directory by name , but in both cases the attributes of the containing directory are transferred to the containing directory on the destination.
That is to say, if we had two folders a and b each of which contained some files:
$ ls -R .
.:
a  b
./a:
a1  a2
./b:
b1  b2
Running rsync -av a b moves the entire directory a to directory b:
$ rsync -av a b
sending incremental file list
a/
a/a1
a/a2
sent 181 bytes  received 58 bytes  478.00 bytes/sec
total size is 0  speedup is 0.00
$ ls -R b
b:
a  b1  b2
b/a:
a1  a2
While running rsync -av a/ b moves the contents of directory a to b:
$ rsync -av a/ b
sending incremental file list
./
a1
a2
sent 170 bytes  received 57 bytes  454.00 bytes/sec
total size is 0  speedup is 0.00
$ ls b
a1  a2	b1  b2

Dockerfile COPY The Dockerfile COPY command also cares about the presence of the trailing slash, using it to determine whether the destination should be considered a file or directory. The Docker documentation explains the rules of the command thusly:
COPY [--chown=<user>:<group>] <src>... <dest>
If <src> is a directory, the entire contents of the directory are copied, including filesystem metadata. Note: The directory itself is not copied, just its contents. If <src> is any other kind of file, it is copied individually along with its metadata. In this case, if <dest> ends with a trailing slash /, it will be considered a directory and the contents of <src> will be written at <dest>/base(<src>). If multiple <src> resources are specified, either directly or due to the use of a wildcard, then <dest> must be a directory, and it must end with a slash /. If <dest> does not end with a trailing slash, it will be considered a regular file and the contents of <src> will be written at <dest>. If <dest> doesn t exist, it is created along with all missing directories in its path.
This means if you had a COPY command that moved file to a nonexistent containerfile without the slash, it would create containerfile as a file with the contents of file.
COPY file /containerfile
container$ stat -c %F containerfile
regular empty file
Whereas if you add a trailing slash, then file will be added as a file under the new directory containerdir:
COPY file /containerdir/
container$ stat -c %F containerdir
directory
Interestingly, at no point can you copy a directory completely, only its contents. Thus if you wanted to make a directory in the new container, you need to specify its name in both the source and the destination:
COPY dir /dirincontainer
container$ stat -c %F /dirincontainer
directory
Dockerfiles do also make good use of the trailing slash to ensure they re doing what you mean by requiring a trailing slash on the destination of multiple files:
COPY file otherfile /othercontainerdir
results in the following error:
When using COPY with more than one source file, the destination must be a directory and end with a /
  1. I m sure there are probably more than just these three cases, but these are the three I m familiar with. If you know of more, please tell me about them!.
  2. Some additional relevant sections are the Path Resolution Appendix and the section on Symbolic Links.
  3. The sentence This is the behavior of historical implementations implies that this probably originated in some ancient Unix derivative, possibly BSD or even the original Unix. I don t really have a source on that though, so please reach out if you happen to have any more knowledge on what this refers to.
  4. I tested on MacOS 11.6.5, FreeBSD 12.0 and OmniOS 5.11 2
  5. unless the source is a directory trailing slashes give -ENOTDIR
  6. In fairness to the coreutils maintainers, it seems to be true on all other Unix platforms, but it probably deserves a mention in the documentation when Linux is the most common platform on which coreutils is used. I should submit a patch.

7 April 2022

Gunnar Wolf: How is the free firmware for the Raspberry progressing?

Raspberry Pi computers require a piece of non-free software to boot the infamous raspi-firmware package. But for almost as long as there has been a Raspberry Pi to talk of (this year it turns 10 years old!), there have been efforts to get it to boot using only free software. How is it progressing? Michael Bishop (IRC user clever) explained today in the #debian-raspberrypi channel in OFTC that it advances far better than what I expected: It is even possible to boot a usable system under the RPi2 family! Just There is somewhat incomplete hardware support: For his testing, he has managed to use a xfce environment but over the composite (NTSC) video output, as HDMI initialization support is not there. However, he shared with me several interesting links and videos, and I told him I d share them there are still many issues; I do not believe it is currently worth it to make Debian images with this firmware. Before anything else: Go visit the librerpi/lk-overlay repository. Its README outlines hardware support for each of the RPi families; there is a binary build available with nixos if you want to try it out, and instructions to build it. But what clever showed me that made me write this post Is the amount of stuff you can do with the RPi s VPU (why Vision Vector Processing Unit and not the more familiar GPU, Graphical Processing Unit? I don t really know But I trust clever s definitions beyond how I trust my own ) before it loads an opearting system: There s not too much I can add to this. I was just Truly amazed. And I hope to see the remaining hurdles for regular Linux booting on this range of machines with purely free software quickly go away! Packaging this for Debian? Well, not yet not so fast I first told clever we could push this firmware to experimental instead of unstable, as it is not yet ready for most production systems. However, pabs made some spot-on further questions. And yes, it requires installing three(!) different cross-compilers, one of which vc4-toolchain, for the VPU is free software, but not yet upstreamed, and hence is not available for Debian. Anyway, the talk continued long after I had to go. I have gone a bit over the backlog, but I have to leave now so that will be it as for this blog post

6 April 2022

Jonathan Dowland: Hope in a Darkened Heart

I first heard Virginia Astley via Lauren Laverne, who played (I think) "With my eyes wide open" from her first album, "From Gardens Where We Feel Secure". Mostly ambient, a conceptual piece about a garden in an English Summer, spanning dawn to dusk. Bucolic ambient, dream pop. It was a little outside my wheel-house, but I loved it, and wanted to find out more. I soon learned that official, physical copies of it were rare and expensive.
'Hope in a Darkened Heart' spinning on my turntable
Some time later I stumbled across her second album "Hope in a Darkened Heart" (which is possibly the most commonly available of her albums) and bought it blind. It's quite different, with a lot more singing, but whatever drew me to Gardens is present. I love this. It was produced by Ryuichi Sakamoto. Only this week I was enormously pleased to discover a chunk of her discography on Bandcamp, including the two aformentioned albums. Highlights from Darkened:

Thorsten Alteholz: My Debian Activities in March 2022

FTP master This month I accepted 332 and rejected 15 packages. This ratio gives a reason to hope. The overall number of packages that got accepted was 342. Debian LTS This was my ninety-third month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 40h. During that time I did LTS and normal security uploads of: All my PU bugs for Buster and Bullseye, that accumulated over the last months, were part of the latest point release. So new ones have to be created now :-). I also continued to work on security support for golang packages. As a result #1008577 and #1008578 were the first real tests with a simple package. Debian ELTS This month was the forty-fifth ELTS month. During my allocated time I uploaded: Unfortunately uploads have to be done for younger releases first, so I had to withhold some uploads for ELTS. Hopefully they can be done in April. Probably this policy needs to be reconsidered. Last but not least I did some days of frontdesk duties. Debian Printing This month I uploaded new upstream versions or improved packaging of: In order to make the Debian Edu team happy, I uploaded a new version of cups-filters with an adapted Apparmor-file to Unstable and Bullseye. Debian Astro This month I uploaded new upstream versions or improved packaging of: Other stuff This month I uploaded new upstream versions or improved packaging of: In order to avoid an AUTORM of some Osmocom packages, I also had to NMU:

Bits from Debian: Infomaniak Platinum Sponsor of DebConf22

infomaniaklogo We are very pleased to announce that Infomaniak has committed to support DebConf22 as a Platinum sponsor. This is the fourth year in a row that Infomaniak is sponsoring The Debian Conference with the higher tier! Infomaniak is Switzerland's largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). With this commitment as Platinum Sponsor, Infomaniak contributes to make possible our annual conference, and directly supports the progress of Debian and Free Software helping to strengthen the community that continues to collaborate on Debian projects throughout the rest of the year. Thank you very much Infomaniak, for your support of DebConf22! Become a sponsor too! DebConf22 will take place from July 17th to 24th, 2022 at the Innovation and Training Park (ITP) in Prizren, Kosovo, and will be preceded by DebCamp, from July 10th to 16th. And DebConf22 is still accepting sponsors! Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf22 website at https://debconf22.debconf.org/sponsors/become-a-sponsor. DebConf22 banner open registration

Jonathan Dowland: Stanley Kubrick's A Clockwork Orange (Music From The Soundtrack)

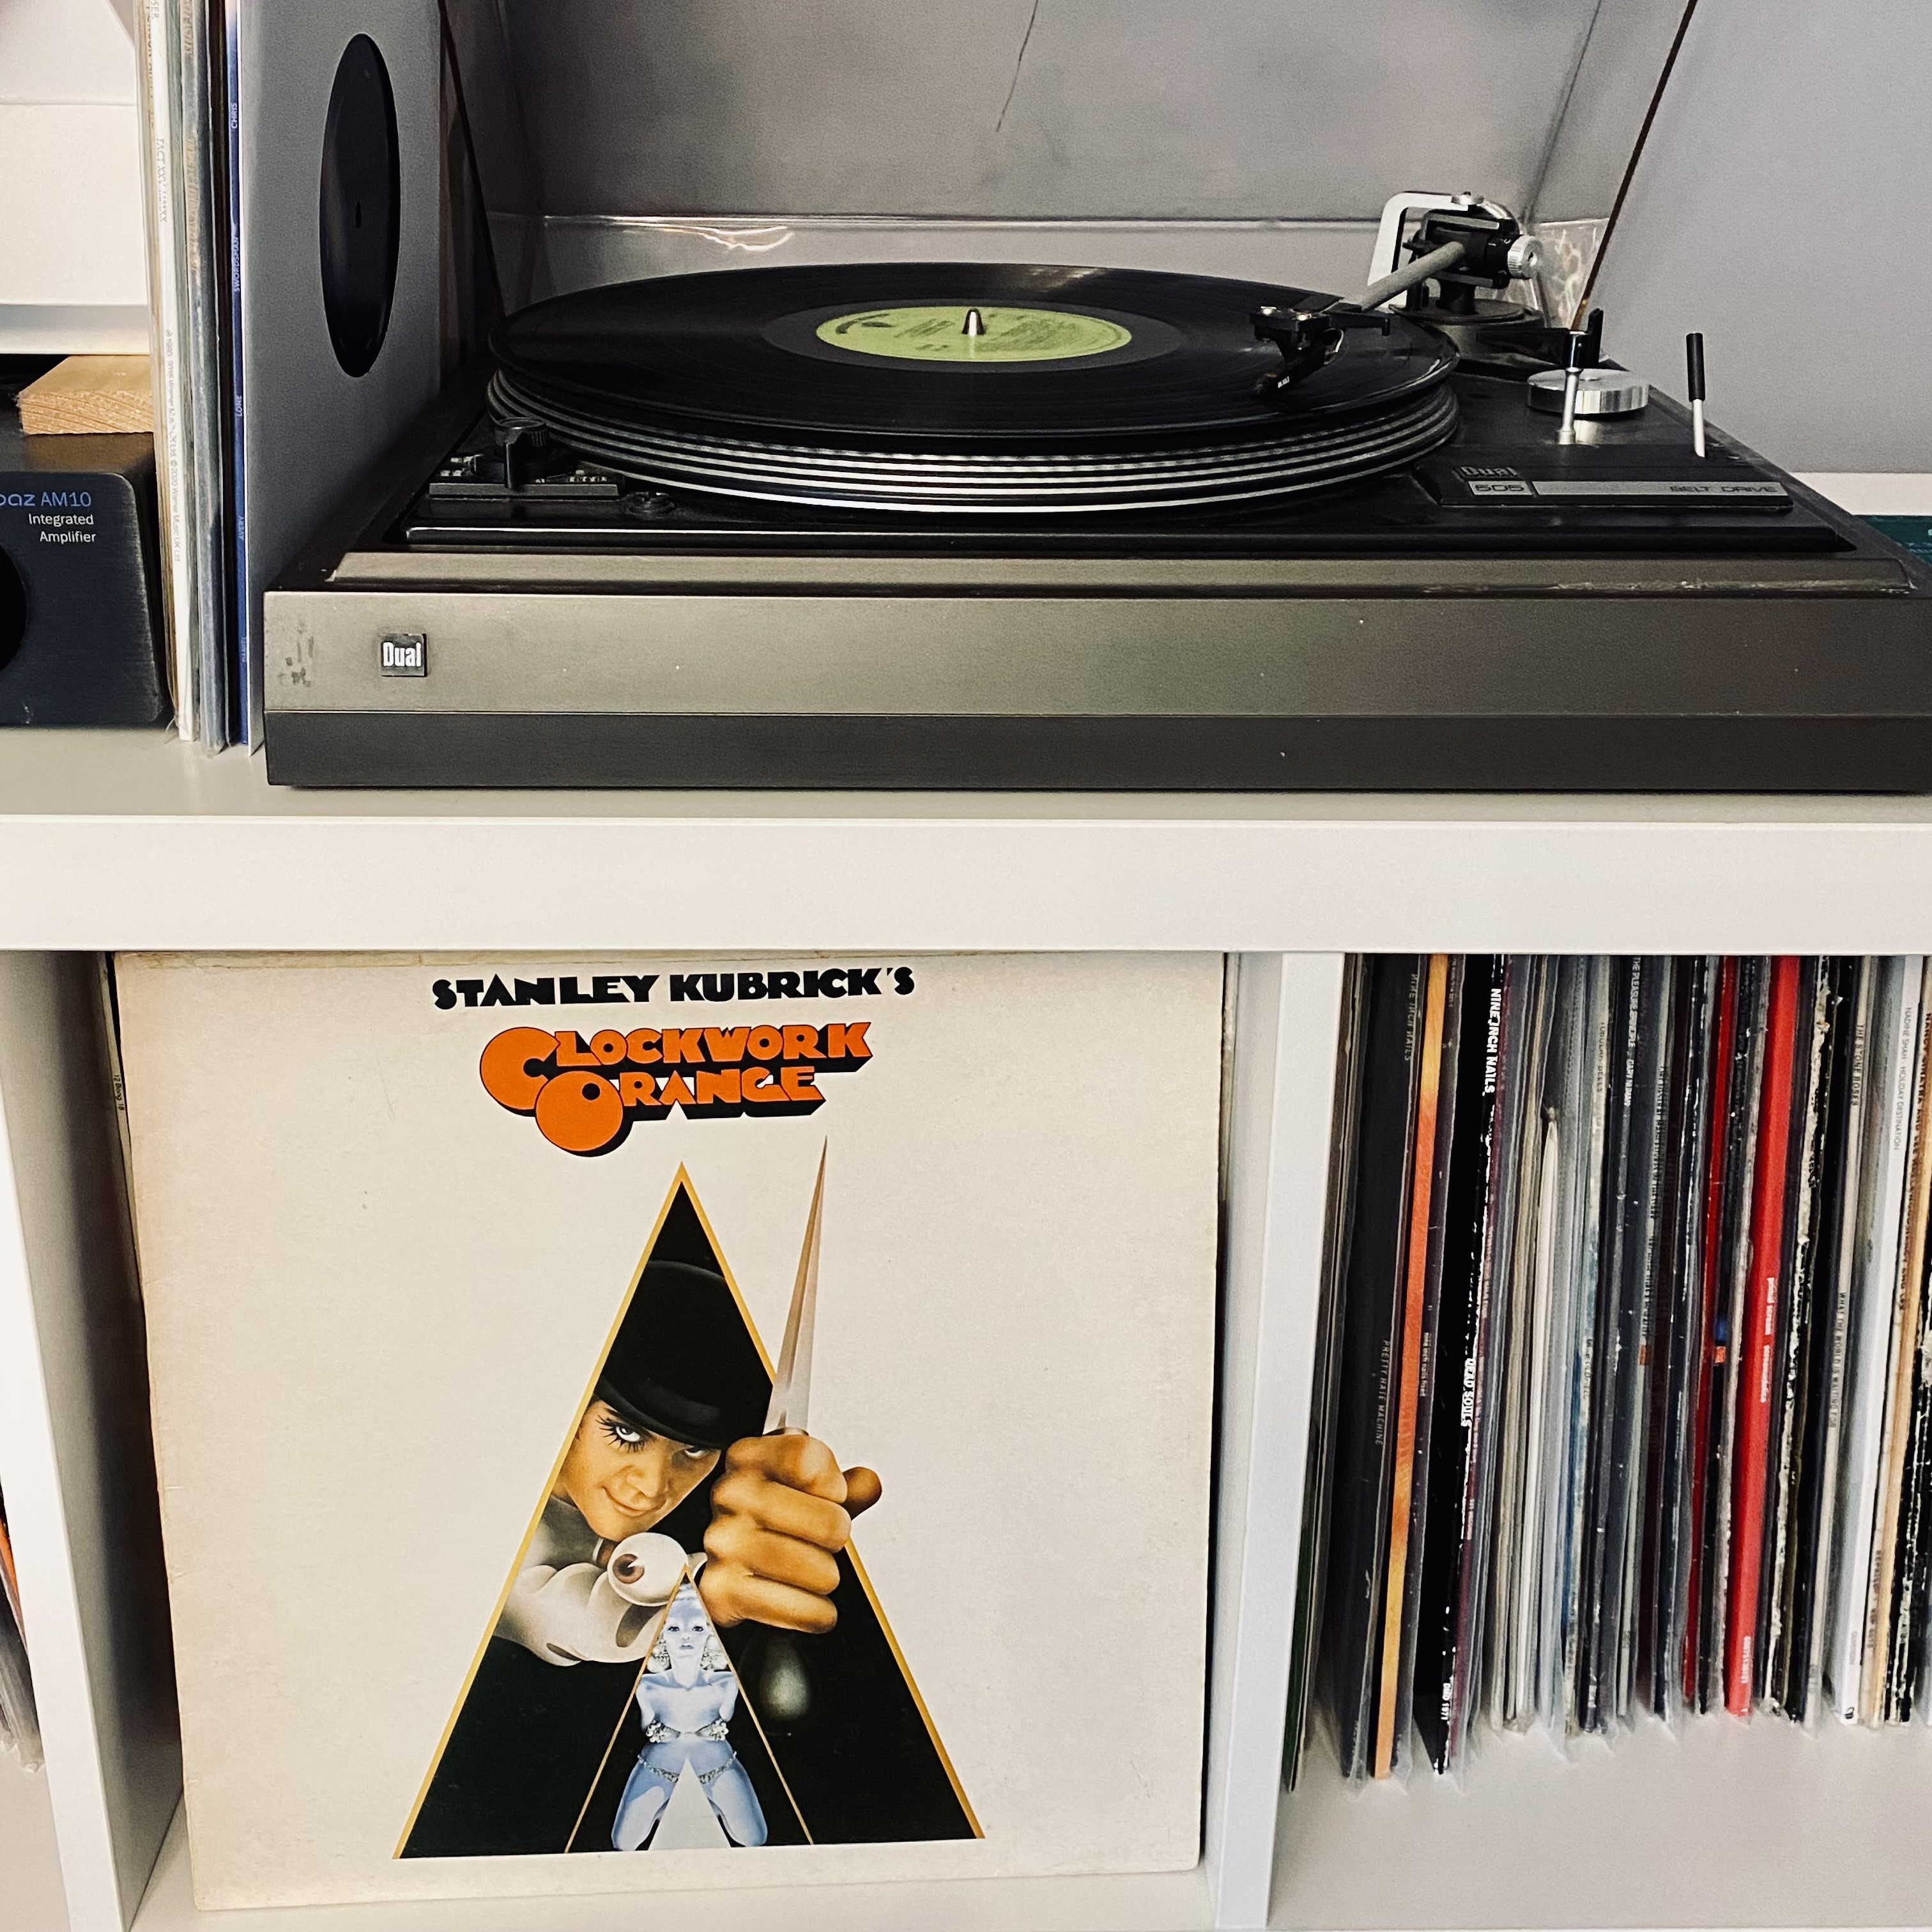
I was reminded of this record over the weekend, as Radio 4's Front Row was discussing the 50th anniversary of Kubrick's movie. To me, the soundtrack has a strange, whimsical, almost cynical element to it (especially with the selection of things like Pomp and Circumstance), but I was familiar with the movie before the soundtrack and it might just be the association that triggers those feelings.
Picture of 'A Clockwork Orange' vinyl record playing on my turntable
I think I picked this up at Tynemouth Market when I lived close by, but I'm not sure. I am sure I didn't pay much for it. Mine is a UK re-pressing from 1971. The abridged (and sped-up) version of William Tell Overture is great for getting the kids to complete a task. Burgess's novel (now 60 years old) has been on my to-read pile for years. in 2018 Electronic Sound magazine featured a cover-mount CD "New Clockwork Music" of music inspired by this soundtrack: It's very good. I must dig that out

Jonathan Dowland: Death from Above

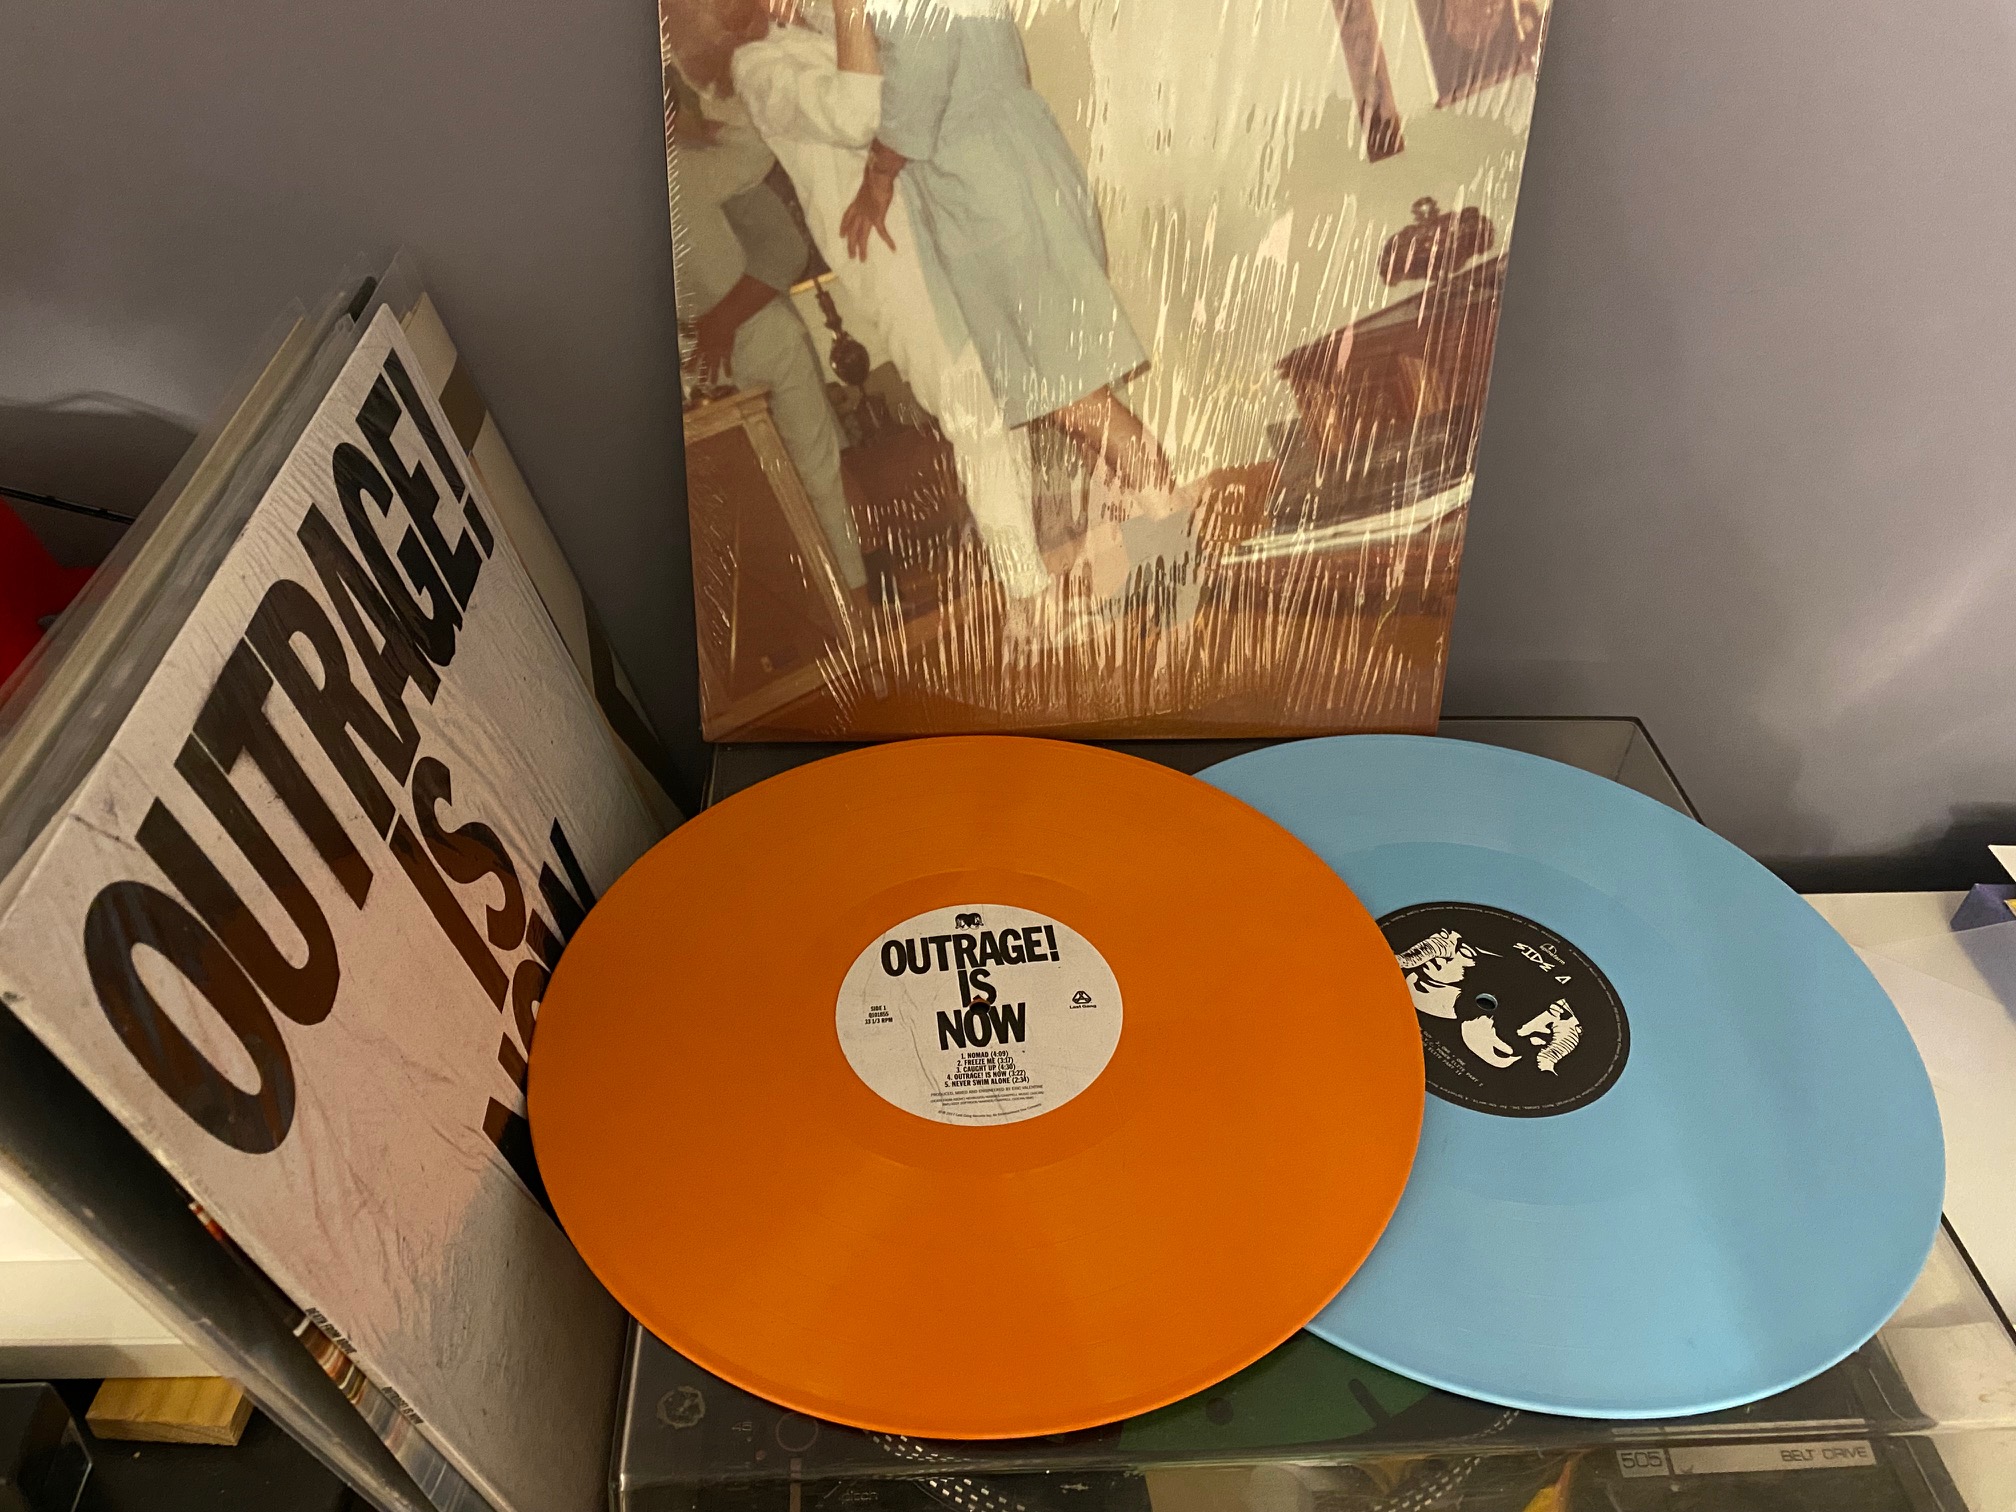
picture of two vinyl records
I received the last two Death From Above albums at Christmas and this weekend managed to give the first (Outrage Is Now) a spin. Pretty colours! They remain one of the best bands to see live. Last time I saw them in a support slot in Newcastle. My friend Rob, a man of few words said I wouldn t want to have to follow them on stage!

Jonathan Dowland: My Life In The Bush Of Ghosts

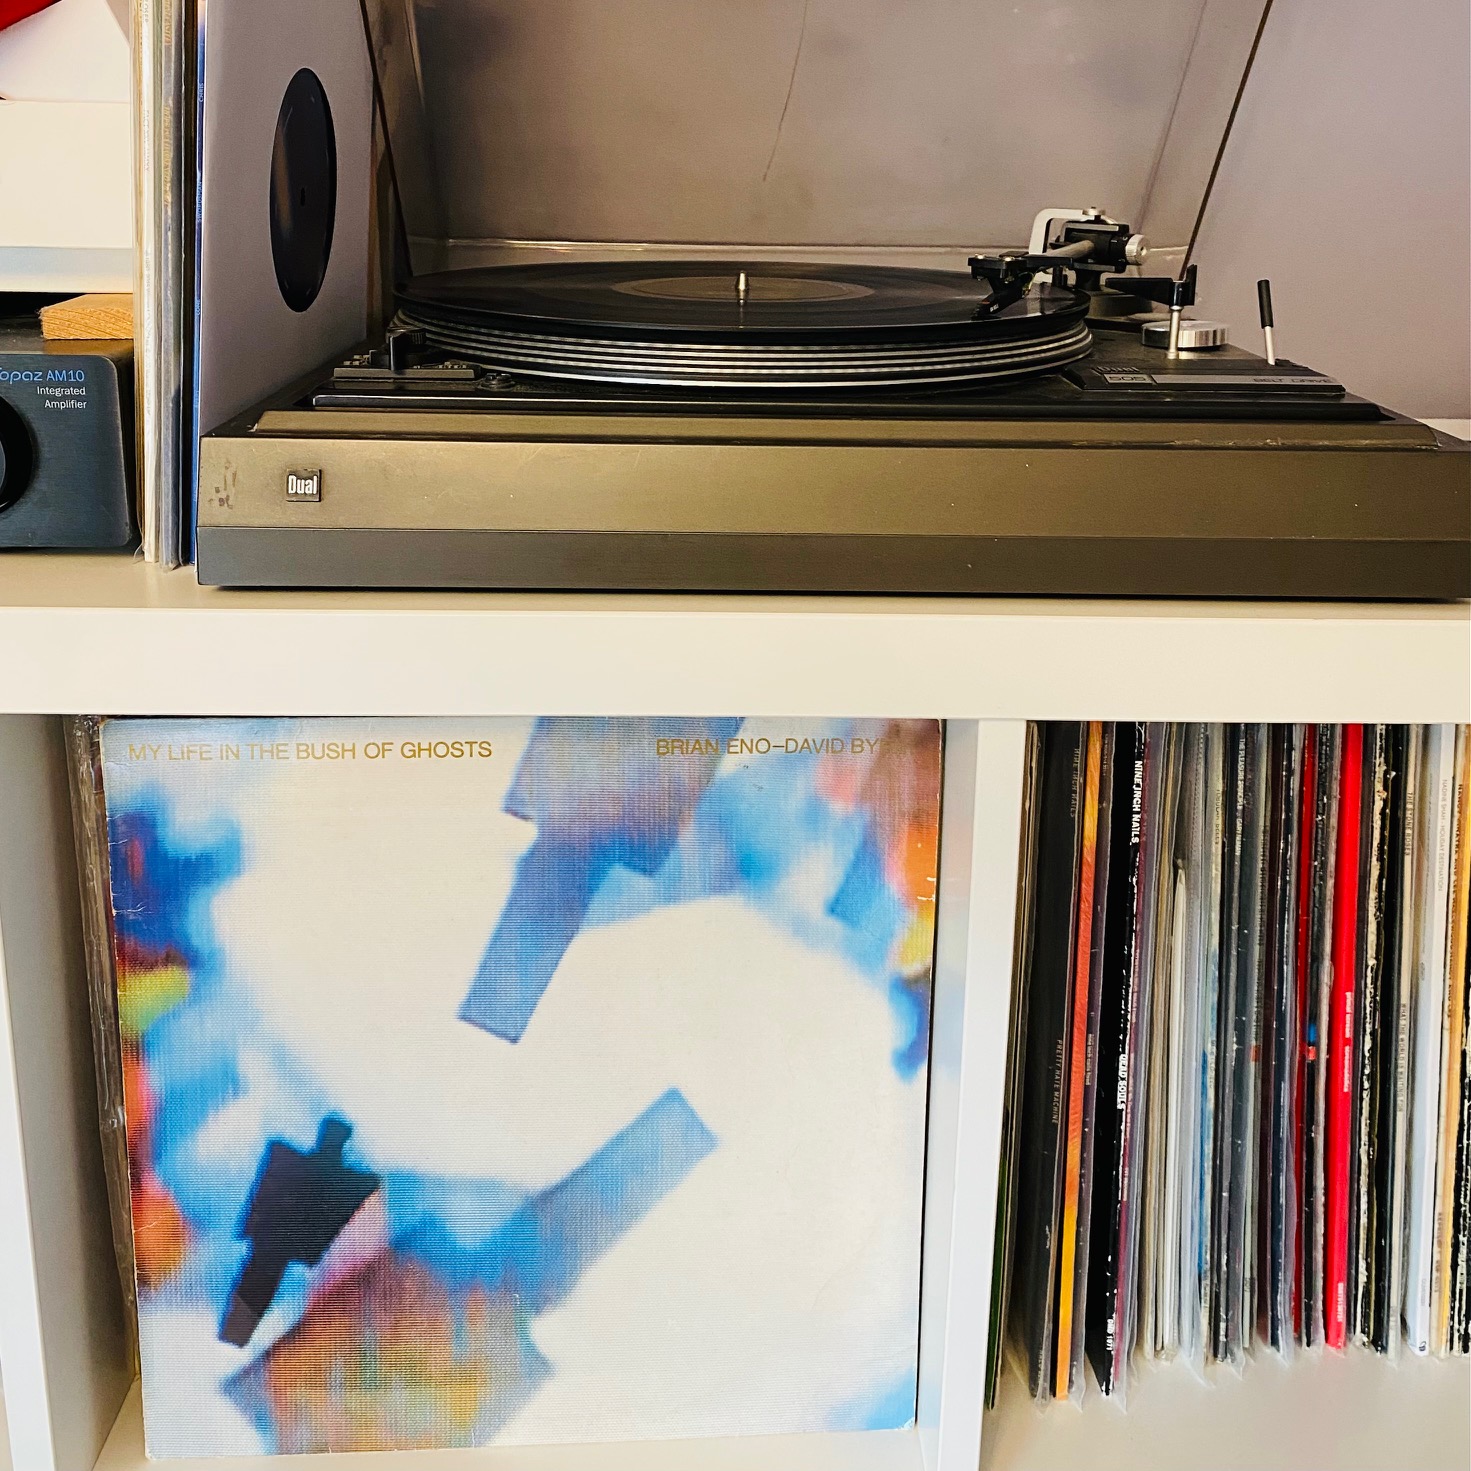
Photo of the record playing next to its cover.
My Life In The Bush Of Ghosts is a weird sound-collage-style album by Brian Eno and David Byrne, released in 1981. It has African-inspired rhythms layered with lots of samples from American radio and TV. It sounds almost like a field recording of the United States was made by wildlife surveyors. My copy is the UK first pressing which includes the track "Qu'ran" which was removed from later editions (and re-instated again later on). I previously wrote about uploading multitracks for two tracks from this album to archive.org.

Jonathan Dowland: One, by Be

picture of a vinyl record
The sublime One, by Be is a pastoral, English summer time instrumental improvisation around field recordings and the theme of the honey bee. A lovely piece to accompany deep thinking. I m reminded of Virginia Astley. Be are associated with Caught by the River, a collective who explore ways of setpping out of daily digital live and embrace, nature, walks, calm, etc.

5 April 2022

Matthew Garrett: Bearer tokens are just awful

As I mentioned last time, bearer tokens are not super compatible with a model in which every access is verified to ensure it's coming from a trusted device. Let's talk about that in a bit more detail.

First off, what is a bearer token? In its simplest form, it's simply an opaque blob that you give to a user after an authentication or authorisation challenge, and then they show it to you to prove that they should be allowed access to a resource. In theory you could just hand someone a randomly generated blob, but then you'd need to keep track of which blobs you've issued and when they should be expired and who they correspond to, so frequently this is actually done using JWTs which contain some base64 encoded JSON that describes the user and group membership and so on and then have a signature associated with them so whenever the user presents one you can just validate the signature and then assume that the contents of the JSON are trustworthy.

One thing to note here is that the crypto is purely between whoever issued the token and whoever validates the token - as far as the server is concerned, any client who can just show it the token is just fine as long as the signature is verified. There's no way to verify the client's state, so one of the core ideas of Zero Trust (that we verify that the client is in a trustworthy state on every access) is already violated.

Can we make things not terrible? Sure! We may not be able to validate the client state on every access, but we can validate the client state when we issue the token in the first place. When the user hits a login page, we do state validation according to whatever policy we want to enforce, and if the client violates that policy we refuse to issue a token to it. If the token has a sufficiently short lifetime then an attacker is only going to have a short period of time to use that token before it expires and then (with luck) they won't be able to get a new one because the state validation will fail.

Except! This is fine for cases where we control the issuance flow. What if we have a scenario where a third party authenticates the client (by verifying that they have a valid token issued by their ID provider) and then uses that to issue their own token that's much longer lived? Well, now the client has a long-lived token sitting on it. And if anyone copies that token to another device, they can now pretend to be that client.

This is, sadly, depressingly common. A lot of services will verify the user, and then issue an oauth token that'll expire some time around the heat death of the universe. If a client system is compromised and an attacker just copies that token to another system, they can continue to pretend to be the legitimate user until someone notices (which, depending on whether or not the service in question has any sort of audit logs, and whether you're paying any attention to them, may be once screenshots of your data show up on Twitter).

This is a problem! There's no way to fit a hosted service that behaves this way into a Zero Trust model - the best you can say is that a token was issued to a device that was, around that time, apparently trustworthy, and now it's some time later and you have literally no idea whether the device is still trustworthy or if the token is still even on that device.

But wait, there's more! Even if you're nowhere near doing any sort of Zero Trust stuff, imagine the case of a user having a bunch of tokens from multiple services on their laptop, and then they leave their laptop unlocked in a cafe while they head to the toilet and whoops it's not there any more, better assume that someone has access to all the data on there. How many services has our opportunistic new laptop owner gained access to as a result? How do we revoke all of the tokens that are sitting there on the local disk? Do you even have a policy for dealing with that?

There isn't a simple answer to all of these problems. Replacing bearer tokens with some sort of asymmetric cryptographic challenge to the client would at least let us tie the tokens to a TPM or other secure enclave, and then we wouldn't have to worry about them being copied elsewhere. But that wouldn't help us if the client is compromised and the attacker simply keeps using the compromised client. The entire model of simply proving knowledge of a secret being sufficient to gain access to a resource is inherently incompatible with a desire for fine-grained trust verification on every access, but I don't see anything changing until we have a standard for third party services to be able to perform that trust verification against a customer's policy.

Still, at least this means I can just run weird Android IoT apps through mitmproxy, pull the bearer token out of the request headers and then start poking the remote API with curl. It may all be broken, but it's also got me a bunch of bug bounty credit, so, it;s impossible to say if its bad or not,

(Addendum: this suggestion that we solve the hardware binding problem by simply passing all the network traffic through some sort of local enclave that could see tokens being set and would then sequester them and reinject them into later requests is OBVIOUSLY HORRIFYING and is also probably going to be at least three startup pitches by the end of next week)

comment count unavailable comments

Dirk Eddelbuettel: RcppSpdlog 0.0.8 on CRAN: Upstream Update

A new version 0.0.8 of RcppSpdlog is now on CRAN. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. This release brings a new upstream release 1.10.0 of spdlog. The (minimal) NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.8 (2022-04-04)
  • Upgraded to upstream releases spdlog 1.10.0

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page, or the package documention site. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RcppArmadillo 0.11.0.0.0 on CRAN: Upstream Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 972 other packages on CRAN, downloaded over 24 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 465 times according to Google Scholar. This release brings a new upstream release 11.0.0. We tested this very rigorously via three different RC release each of which got a full reverse-dependencies run (for which results are always logged here). The full set of changes (since the last CRAN release 0.10.8.1.0) follows.

Changes in RcppArmadillo version 0.11.0.0 (2022-04-04)
  • Upgraded to Armadillo release 11.0.0 (Creme Brulee)
    • added variants of inv() and inv_sympd() that provide rcond (reciprocal condition number)
    • expanded inv() and inv_sympd() with options inv_opts::tiny and inv_opts::allow_approx
    • stricter handling of singular matrices by inv() and inv_sympd()
    • stricter handling of non-sympd matrices by inv() and inv_sympd()
    • stricter handling of non-finitie matrices by pinv()
    • more robust handling of rank deficient matrices by solve()
    • faster handling of diagonal matrices by rcond()
    • changed eigs_sym() and eigs_gen() to use higher quality RNG
    • quantile() and median() will now throw an exception if given matrices/vectors have NaN elements
    • workaround for yet another bug in Intel MKL
  • Until May 2022, protect correction to Field behavior via define of RCPP_ARMADILLO_FIX_Field
  • If a LAPACK installation with missing complex routines is found (as e.g. Ubuntu using 3.9.0) then the LAPACK unit test is skipped.

Changes in RcppArmadillo version 0.10.8.2.0 (2022-02-01)
  • Upgraded to Armadillo release 10.8.2 (Realm Raider)
    • fix potential speed regression in pinv() and rank()

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Kees Cook: security things in Linux v5.10

Previously: v5.9 Linux v5.10 was released in December, 2020. Here s my summary of various security things that I found interesting: AMD SEV-ES
While guest VM memory encryption with AMD SEV has been supported for a while, Joerg Roedel, Thomas Lendacky, and others added register state encryption (SEV-ES). This means it s even harder for a VM host to reconstruct a guest VM s state. x86 static calls
Josh Poimboeuf and Peter Zijlstra implemented static calls for x86, which operates very similarly to the static branch infrastructure in the kernel. With static branches, an if/else choice can be hard-coded, instead of being run-time evaluated every time. Such branches can be updated too (the kernel just rewrites the code to switch around the branch ). All these principles apply to static calls as well, but they re for replacing indirect function calls (i.e. a call through a function pointer) with a direct call (i.e. a hard-coded call address). This eliminates the need for Spectre mitigations (e.g. RETPOLINE) for these indirect calls, and avoids a memory lookup for the pointer. For hot-path code (like the scheduler), this has a measurable performance impact. It also serves as a kind of Control Flow Integrity implementation: an indirect call got removed, and the potential destinations have been explicitly identified at compile-time. network RNG improvements
In an effort to improve the pseudo-random number generator used by the network subsystem (for things like port numbers and packet sequence numbers), Linux s home-grown pRNG has been replaced by the SipHash round function, and perturbed by (hopefully) hard-to-predict internal kernel states. This should make it very hard to brute force the internal state of the pRNG and make predictions about future random numbers just from examining network traffic. Similarly, ICMP s global rate limiter was adjusted to avoid leaking details of network state, as a start to fixing recent DNS Cache Poisoning attacks. SafeSetID handles GID
Thomas Cedeno improved the SafeSetID LSM to handle group IDs (which required teaching the kernel about which syscalls were actually performing setgid.) Like the earlier setuid policy, this lets the system owner define an explicit list of allowed group ID transitions under CAP_SETGID (instead of to just any group), providing a way to keep the power of granting this capability much more limited. (This isn t complete yet, though, since handling setgroups() is still needed.) improve kernel s internal checking of file contents
The kernel provides LSMs (like the Integrity subsystem) with details about files as they re loaded. (For example, loading modules, new kernel images for kexec, and firmware.) There wasn t very good coverage for cases where the contents were coming from things that weren t files. To deal with this, new hooks were added that allow the LSMs to introspect the contents directly, and to do partial reads. This will give the LSMs much finer grain visibility into these kinds of operations. set_fs removal continues
With the earlier work landed to free the core kernel code from set_fs(), Christoph Hellwig made it possible for set_fs() to be optional for an architecture. Subsequently, he then removed set_fs() entirely for x86, riscv, and powerpc. These architectures will now be free from the entire class of kernel address limit attacks that only needed to corrupt a single value in struct thead_info. sysfs_emit() replaces sprintf() in /sys
Joe Perches tackled one of the most common bug classes with sprintf() and snprintf() in /sys handlers by creating a new helper, sysfs_emit(). This will handle the cases where kernel code was not correctly dealing with the length results from sprintf() calls, which might lead to buffer overflows in the PAGE_SIZE buffer that /sys handlers operate on. With the helper in place, it was possible to start the refactoring of the many sprintf() callers. nosymfollow mount option
Mattias Nissler and Ross Zwisler implemented the nosymfollow mount option. This entirely disables symlink resolution for the given filesystem, similar to other mount options where noexec disallows execve(), nosuid disallows setid bits, and nodev disallows device files. Quoting the patch, it is useful as a defensive measure for systems that need to deal with untrusted file systems in privileged contexts. (i.e. for when /proc/sys/fs/protected_symlinks isn t a big enough hammer.) Chrome OS uses this option for its stateful filesystem, as symlink traversal as been a common attack-persistence vector. ARMv8.5 Memory Tagging Extension support
Vincenzo Frascino added support to arm64 for the coming Memory Tagging Extension, which will be available for ARMv8.5 and later chips. It provides 4 bits of tags (covering multiples of 16 byte spans of the address space). This is enough to deterministically eliminate all linear heap buffer overflow flaws (1 tag for free , and then rotate even values and odd values for neighboring allocations), which is probably one of the most common bugs being currently exploited. It also makes use-after-free and over/under indexing much more difficult for attackers (but still possible if the target s tag bits can be exposed). Maybe some day we can switch to 128 bit virtual memory addresses and have fully versioned allocations. But for now, 16 tag values is better than none, though we do still need to wait for anyone to actually be shipping ARMv8.5 hardware. fixes for flaws found by UBSAN
The work to make UBSAN generally usable under syzkaller continues to bear fruit, with various fixes all over the kernel for stuff like shift-out-of-bounds, divide-by-zero, and integer overflow. Seeing these kinds of patches land reinforces the the rationale of shifting the burden of these kinds of checks to the toolchain: these run-time bugs continue to pop up. flexible array conversions
The work on flexible array conversions continues. Gustavo A. R. Silva and others continued to grind on the conversions, getting the kernel ever closer to being able to enable the -Warray-bounds compiler flag and clear the path for saner bounds checking of array indexes and memcpy() usage. That s it for now! Please let me know if you think anything else needs some attention. Next up is Linux v5.11.

2022, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

4 April 2022

Ben Hutchings: Debian LTS work, March 2022

In March I was assigned 16 hours of work by Freexian's Debian LTS initiative and carried over 8 hours from February. I worked 16 hours, and will carry over the remaining time to April. I backported the mitigations for Spectre-BHB (CVE-2022-0001, CVE-2022-0002) on x86 processors, to Linux 4.9. I worked together with Salvatore Bonaccorso in preparing the kernel updates that were needed in all suites, and writing advisory text. I uploaded both the linux (4.9) and linux-4.19 packages to stretch, and issued DLA-2940-1 and DLA-2941-1. I also triaged new issues that were reported later in the month.
Arturo Borrero Gonz lez: Wikimedia Toolforge and Grid Engine

Logos This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. One of the most important and successful products provided by the Wikimedia Cloud Services team at the Wikimedia Foundation is Toolforge, a hosting service commonly known in the industry as Platform as a Service (PaaS). In particular, it is a platform that allows users and developers to run and use a variety of applications with the ultimate goal of helping the Wikimedia mission from the technical side. Toolforge is powered by two different backend engines, Kubernetes and Grid Engine. The two backends have traditionally offered different features for tool developers. But as time moves forward we ve learnt that Kubernetes is the future. Explaining why is the purpose of this blog post: we want to share more information and reasoning behind this mindset. There are a number of reasons that make Grid Engine poorly suitable to remain as execution backend in Toolforge:
  • There has not been a new Grid Engine release (bug fixes, security patches, or otherwise) since 2016. This doesn t feel like a project being actively developed or maintained.
  • The grid has poor support and controls for important aspects such as high availability, fault tolerance and self-recovery.
  • Maintaining a healthy grid requires plenty of manual operations, like manual queue cleanups in case of failures, hand-crafted scripts for pooling/depooling nodes, etc.
  • There is no good or modern monitoring support for the grid, and we need to craft and maintain several monitoring pieces for proper observability, and to be able to do proper maintenance.
  • The grid is also strongly tied to the underlying operating system release version. Migrating from one Debian version to the next is painful (a dedicated blog post about this will follow shortly).
  • The grid imposes a strong dependency on NFS, another old technology. We would like to reduce dependency on NFS overall, and in the future we will explore NFS-free approaches for Toolforge.
  • In general, Grid Engine is old software, old technology, which can be replaced by more modern approaches for providing an equivalent or better service.
As mentioned above, our desire is to cover all our grid-like needs with Kubernetes, a technology which has several benefits:
  • Good high availability, fault tolerance and self-recovery semantics, constructs and facilities.
  • Maintaining a running Kubernetes cluster requires little manual operations.
  • There are good monitoring and observability options for Kubernetes deployments, including seamless integration with industry standards like prometheus.
  • Our current approach to deploying and upgrading Kubernetes is independent of the underlying operating system.
  • While our current Kubernetes deployment uses NFS as a central component, there is support for using other, more modern, approaches for the kind of shared storage needs we have in Toolforge.
  • In general, Kubernetes is a modern technology, with a vibrant and healthy community, that enables new use cases and has enough flexibility to adapt legacy ones.
The relationship between Toolforge and Grid Engine has been interesting over the years. The grid has been used for quite a lot of time, we have plenty of documentation and established good practices. On the other hand, the grid is hard to maintain, imposes a heavy burden on the WMCS team and is a technology we must eventually discontinue. How to accommodate the two realities is a refreshing challenge, one that we hope to tackle together in the near future. A tradeoff exists here, but it is clear to us which option is best. So we will work on deprecating and removing Grid Engine and migrating use cases into Kubernetes. This deprecation, however, will be done with care, as we know our technical community relies on the grid for some import Toolforge tools. And some of these workflows will need some adaptation in order to be fully supported on Kubernetes. Stay tuned for more information on present and next works surrounding the Wikimedia Toolforge service. The next blog post will share more concrete details. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

2 April 2022

Ian Jackson: Otter (game server) 1.0.0 released

I have just released Otter 1.0.0. Recap: what is Otter Otter is my game server for arbitrary board games. Unlike most online game systems. It does not know (nor does it need to know) the rules of the game you are playing. Instead, it lets you and your friends play with common tabletop/boardgame elements such as hands of cards, boards, and so on. So it s something like a tabletop simulator (but it does not have any 3D, or a physics engine, or anything like that). There are provided game materials and templates for Penultima, Mao, and card games in general. Otter also supports uploadable game bundles, which allows users to add support for additional games - and this can be done without programming. For more information, see the online documentation. There are a longer intro and some screenshots in my 2021 introductory blog post about Otter Releasing 1.0.0 I m calling this release 1.0.0 because I think I can now say that its quality, reliability and stability is suitable for general use. In particular, Otter now builds on Stable Rust, which makes it a lot easier to install and maintain. Switching web framework, and async Rust I switched Otter from the Rocket web framework to Actix. There are things to prefer about both systems, and I still have a soft spot for Rocket. But ultimately I needed a framework which was fully released and supported for use with Stable Rust. There are few if any Rust web frameworks that are not async. This is rather a shame. Async Rust is a considerably more awkward programming environment than ordinary non-async Rust. I don t want to digress into a litany of complaints, but suffice it to say that while I really love Rust, my views on async Rust are considerably more mixed. Future plans In the near future I plan to add a couple of features to better support some particular games: currency-like resources, and a better UI for dice-like randomness. In the longer term, Otter s, installation and account management arrangements are rather unsophisticated and un-webby. There is not currently any publicly available instance for you to try it out without installing it on a machine of your own. There s not even any provided binaries: you must built Otter yourself. I hope to be able to improve this situation but it involves dealing with cloud CI and containers and so-on, which can all be rather unpleasant. Users on chiark will find an instance of Otter there.

comment count unavailable comments

1 April 2022

Dirk Eddelbuettel: RInside 0.2.17

A new release 0.2.17 of RInside arrived on CRAN and in Debian today. This is the first release in two years since the 0.2.16 release. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by Rcpp. This release brings a minor update for R 4.2.0, due out later this month, and kindly provided by Tomas Kalibera. It updates one function declaration; we wrapped some conditioning around so that RInside continues to build with older releases too. Besides that minor updates were made to continuous integration and some of the package files. The short list of changes since the last release were:

Changes in RInside version 0.2.17 (2022-03-31)
  • A Windows-only patch for R 4.2.0 kindly provided by Tomas Kalibera was applied, and also conditioned on R (>= 4.2.0)
  • Continuous Integration setup was updated and now uses r-ci.
  • Several updates were made to README.md (badges etc) and DESCRIPTION

My CRANberries also provides a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page, or to issues tickets at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Junichi Uekawa: I am more used to Rust.

I am more used to Rust. I can do simple string processing faster in Rust than say Python. It has enough things to make it more pleasant to work with than C++.

Next.

Previous.