Search Results: "ema"

26 January 2014

Neil Williams: Home server rack

The uses of this particular rack I ll cover in future entries this is about how I made the rack itself, with help from friends (Steve McIntyre & Andy Simpkins). A common theme is making allowances for using dev kit boards ready-to-rack ARM servers are not here yet. My aim was to have 4, possibly 6 ARM dev kit boards running services from home, so there was no need for a standard 42U rack, a 9U rack is enough. Hence:
Wall Mounted 9U 450mm deep 19 inch rack enclosure glass door To run various other services around the house (firewall, file server etc.), a microserver was also necessary:
HP 704941-421 ProLiant Micro Server (AMD Turion II Neo N54L 2.2GHz, 2GB RAM, 250GB HDD, 2 Core, 7th Generation) I chose to mount that on a bookcase beneath the wall mounted rack as it kept all the cables at the bottom of the rack itself. The microserver needed a second gigabit network card fitted to cope with being a firewall as well, if you do the same, ensure you find a suitable card with a low profile bracket. Some are described as being low profile but do not package the low profile bracket, only a low profile card and a full height bracket.
Intel EXPI9301CTBLK PRO1000 Network Card note the low profile bracket in the pack. The first of the dev kit requirements is the lack of boards which can be racked, so shelves are going to be needed, leading on to something to stop the boards wandering across the shelf when the cables are adjusted velcro pads in my case. Second requirement is that dev kit boards are notorious for not rebooting cleanly. Nothing to do with the image being run, the board just doesn t cut power or doesn t come back after cutting power. Sometimes this is down to early revisions of the board, sometimes the board pulls enough power through the USB serial converter to remain alive, whatever the cause, it won t reboot without user involvement. So a PDU becomes necessary remotely controllable. New units tend to be expensive and/or only suitable for larger racks, I managed to find an older 8 port APC unit, something like: (Don t be surprised if that becomes a dead link search for APC Smart Slot Master Switch Power Distribution Unit). Talking of power, I m looking to use SATA drives with these boards and the boards themselves come with a variety of wall wart plugs or USB cables, so a number of IEC sockets are needed not the usual plugs:
Power cable IEC C14 plug 13A socket 25 cm or, for devices which genuinely need 2A to boot (use the 1A for attached SATA or leave empty):

Black Universal 3.1A 15W 5V Dual USB Rapid Mains Charger Plug Check the power output rating of the USB plugs used to connect to the mains as well many are 1A or less. Keep the right plug for the right board.
Power is going to also be a problem if, like me, you want to run SATA drives off boards which support SATA. The lack of a standard case means that ATX power is awkward, so check out some cheap SATA enclosures to get a SATA connector with USB power. I am using these enclosures (prices seem to have risen since I obtained them):

Startech 2.5 inch eSATA USB External Hard Drive Enclosure for SATA HDD Along with these:
eSATA to SATA Serial External Shielded Cable 1m because the iMx53 boards have SATA connectors but the enclosure exports eSATA. Whilst this might seem awkward, the merit of having both eSATA and simple USB power on one enclosure is not to be under-estimated. (Avoid the stiffer black cables space will get tight inside the rack.) Naturally, a 2.5 inch SATA drive is going to be needed for each enclosure, I m using HDD but SSD is also an option. Also, consider simple 2 or 3 way fused adaptors so that the board and the SATA drive can be powered from a single PDU port, this makes rebooting much simpler if the board needs a power supply with integrated plug instead of over USB. Now to the networking (2 x 8 port was cheaper than 1 x 16):
Netgear GS108 8-port Gigabit Ethernet Unmanaged Switch Don t forget the cat5 cables too you ll want lots of short cables, 1m or shorter inside the rack and a few longer ones going to the microserver and wall socket. I used 8x1m. Naturally, on the floor below your rack you are going to put a UPS, so the PDU power then needs to be converted to draw from the UPS via IEC plugs instead of standard mains. I decided to use a 6 gang extension 1m cable with an IEC plug it was the only bit of wiring I had to do and even those are available ready-made if you want to do it that way. Depending on the board, you may need your own serial to USB converters, you ll certainly need some powered USB hubs. I m using a wall mounted 9U rack, so I also needed a masonry drill and 4 heavy duty masonry M8 bolts. The rack comes with a mounting plate which needs to be bolted to the wall but nothing else is included. This step is much easier with someone else to take the weight of the rack as it is guided into the brackets on the mounting plate the bracket may need a little persuasion to allow for the bolt heads to not get in the way during mounting. Once mounted, the holes in the back of the rack allow for plenty of room, it s just getting to that point. The rack has side panels which latch out easily, providing easy maintenance. The glass door can be easily reversed to open from the opposite side. However, the key in the glass door is largely useless. The expectation is that the units in the rack are attached at the front but the dev boards on shelves are not going to be protected by a key in the front door. The key therefore ends up being little more than a handle for the glass door. OK. If you ve got this far, it s a case of putting things together:
Economy Cage Nut Tool 19 inch racking for cagenut extraction Yes, you really do want one. Fine, do without the premium one, but the economy one will save you a lot of (physical) pain. At this stage, it becomes clear that the normal 19 inch server rack shelves don t leave a lot of room at the back of the rack for the cables and there are a lot of cables. Each board has power, USB serial connection and network. The SATA has power too. The PDU has a power lead and you ll need network switches too. The network switches need power and an uplink cable. I positioned the supports in the rack as far forward as possible and attached the shelves to give enough room for the PDU on the base of the rack, the network switches resting on top and the extension bar (with the heavier, stiffer cables) at the back. (I need to bring my shelves another 1 or 2 positions further forward as there is barely enough room for one cable between the shelf and the back of the rack and that makes moving boards around harder than it needs to be.) The PDU defaults to enabling all ports at startup, so connect to it over telnet and turn off the ports before connecting things and sorting out the network interface to what the rest of the lab needs. (I m using a 10. range and the PDU was originally set to use 192.168.1.) That s about it as far as the hardware setup is concerned. Just time to label up each board, note down which PDU port does which device, which serial to USB converter is on which device on the microserver and check the power my initial problem with one board was traced to the inability of the board to power SATA off the on-board USB port even when using the provided 2A power supply. That meant adding a standard mains adaptor to feed both the SATA power and the board power off the one PDU port there is little point powering off the board but not the SATA, or vice versa. I haven t totalled up the expenditure but the biggest expenses were the microserver and the wall mounted rack but don t underestimate how much it will cost to buy 6 IEC plugs, various USB serial converters and how much you may spend on peripheral items. There is quite a lot of room on the 2 shelves for more boards, what will limit the deployment in this rack is space for the cables, especially power. The shorter the power cables, the easier it will be to maintain the devices in the rack. It might be worth looking at a 12U rack, if only to give plenty of space for cables. Once I ve got the software working, I ll describe what this rack will be doing it s got something to do with Debian, ARM, Linux and tests but you ve probably already guessed that much


Daniel Pocock: Beyond init systems: other opportunities for simplification

One thing that everybody agrees on in the debate about Debian's init system replacement is that the manifests used by most of the new schemes are far more concise than traditional init scripts. Simplification need not stop there however. Another opportunity for simplification exists in the creation of users at package installation. Every packaging tool has a different approach and all of them involve multiple lines of boilerplate script code duplicated between hundreds of packages that all need exactly the same thing. What is worse, embedding this logic into the postinst scripts on Debian or %post logic of an RPM makes it far more awkard for a system administrator to audit the user account requirements of packages (when installing many of them in a hurry) or to customise the logic for a whole site without rebuilding the whole packages. Potential improvement How to improve this? Well, packages (on any distribution) could be invited to declare the user and group accounts they depend on. A central configuration parameter in /etc/dpkg/dpkg.cfg or /etc/rpm would then control how the package manager behaves, with several possible options:
  • Create users/groups on demand without prompting
  • Abort installation/configuration of any package if the pre-requisite users do not exist on the system
  • Prompt: at the beginning of any package install, ask the administrator to create the users himself before proceeding, with an option to abort and potentially displaying some convenient LDIF fragments and other samples that the administrator can cut and paste.
Running a command like apt-get --simulate would give a system administrator an immediate view of all users/groups required by the packages they propose to install.

24 January 2014

Erich Schubert: Definition of Data Science

Everything is "big data" now, and everything is "data science". Because these terms lack a proper, falsifiable definition.
A number of attempts to define them exist, but they usually only consist of a number of "nice to haves" strung together. For Big Data, it's the 3+ V's, and for Data Science, this diagram on Wikipedia is a typical example.
This is not surprising: effectively these term are all marketing, not scientific attempts at definiting a research domain.
Actually, my favorite definition is this, except that it should maybe read pink pony in the middle, instead of unicorn.
Data science has been called "the sexiest job" so often, this has recently led to an integer overflow.
The problem with these definitions is that they are open-ended. They name some examples (like "volume") but they essentially leave it open to call anything "big data" or "data science" that you would like to. This is, of course, a marketers dream buzzword. There is nothing saying that "picking my nose" is not big data science.

If we ever want to get to a usable definition and get rid of all the hype, we should consider a more precise definition; even when this means making it more exclusive (funnily enough, some people already called above open-ended definitions "elitist" ...).
Big data:
  • Must involve distributed computation on multiple servers
  • Must intermix computation and data management
  • Must advance over the state-of-the-art of relational databases, data warehousing and cloud computing in 2005
  • Must enable results that were unavailable with earlier approaches, or that would take substantially longer (runtime or latency)
  • Must be disruptively more data-driven
Data science:
  • Must incorporate domain knowledge (e.g. business, geology, etc.).
  • Must take computational aspects into account (scalability etc.).
  • Must involve scientific techniques such as hypothesis testing and result validation.
  • Results must be falsifiable.
  • Should involve more mathematics and statistics than earlier approaches.
  • Should involve more data management than earlier approaches (indexing, sketching&hashing etc.).
  • Should involve machine learning, AI or knowledge discovery algorithms.
  • Should involve visualization and rapid prototyping for software development.
  • Must satisfy at least one of these shoulds in a disruptive level.
But this is all far from a proper definition. Partially because these fields are so much in flux; but largely because they're just too ill-defined.
There is a lot of overlap, that we should try to flesh out. For example, data science is not just statistics. Because it is much more concerned with how data is organized and how the computations can be made efficiently. Yet often, statistics is much better at integrating domain knowledge. People coming from computation, on the other hand, usually care too little about the domain knowledge and falsifiability of their results - they're happy if they can compute anything.
Last but not least, nobody will be in favor of such a rigid definition and requirements. Because most likely, you will have to strip that "data scientist" label off your business card - and why bite the hand that feeds? Most of what I do certainly would not qualify as data science or big data anymore with an "elitist" definition. While this doesn't lessen my scientific results, it makes them less marketable.
Essentially, this is like a global "gentlemans agreement". Buzz these words while they last, then move on to the next similar "trending topic".

Maybe we should just leave these terms to the marketing folks, and let them bubble them till it bursts. Instead, we should just stick to the established and better defined terms...
Thank you.
Of course, sometimes you will have to play Buzzword Bingo. Nobody is going to stop you. But I will understand that you are doing "playing buzzword bingo", unless you get more precise.
Once you then have results that are so massively better, and really disrupted science, then you can still call it "data science" later on.
You have been seeing, I've been picking on the word "disruptive" a lot. As long as you are doing "business as usual", and focusing on off-the-shelf solution, it will not be disruptive. And it then won't be big data science, or a big data approach that yields major gains. It will be just "business as usual" with different labels, and return results as usual.
Let's face it. We don't just want big data or data science. What everybody is looking for is disruptive results, which will require a radical approach, not a slight modification involving slightly more computers of what you have been doing all along.

23 January 2014

John Goerzen: Why and how to run ZFS on Linux

I m writing a bit about ZFS these days, and I thought I d write a bit about why I am using it, why it might or might not be interesting for you, and what you might do about it. ZFS Features and Background ZFS is not just a filesystem in the traditional sense, though you can use it that way. It is an integrated storage stack, which can completely replace the need for LVM, md-raid, and even hardware RAID controllers. This permits quite a bit of flexibility and optimization not present when building a stack involving those components. For instance, if a drive in a RAID fails, it needs only rebuild the parts that have actual data stored on them. Let s look at some of the features of ZFS: Although it is often considered a server filesystem, ZFS has been used in plenty of other situations for some time now, with ports to FreeBSD, Linux, and MacOS. I find it particularly useful: The added level of security in having cheap snapshots available is almost worth it by itself. ZFS drawbacks Compared to other Linux filesystems, there are a few drawbacks of ZFS: Converting to ZFS I have written up an extensive HOWTO on converting an existing system to use ZFS. It covers workarounds for all the boot-time bugs I have encountered as well as documenting all steps needed to make it happen. It works quite well. Additional Hints If setting up zvols to be used by VirtualBox or some such system, you might be interested in managing zvol ownership and permissions with udev.

22 January 2014

Craig Small: WordPress 3.8 for Debian

Well if you can read this then you know it s working. After way too many weeks, Debian will have WordPress version 3.8. Thanks to Rapha l for his kind assistance and answering my questions about how it was built. The upload is still gurgling along and will make it there in its own time. He said Handing over packages is hard, I d agree but say taking over them is too. So, what does WordPress 3.8 look like? From the frontend I didn t really notice much. The big changes, at least cosmetically, seem to be for the admin backend. It just look slicker and cleaner. Hopefully Debian users find the update useful and I ve not broken anything. There s always the BTS if there is. I ve deliberately tried to minimise the changes for this version to limit the breakage.

20 January 2014

Dirk Eddelbuettel: RProtoBuf 0.4.0: A whole lot of goodies and Windoze support

A new major release 0.4.0 of RProtoBuf, is now on CRAN. RProtoBuf provides GNU R bindings for the Google Protocol Buffers ("Protobuf") data encoding library used and released by Google, and deployed as a language and operating-system agnostic protocol by numerous projects. With this release, we are welcoming Jeroen Ooms to the team. Jeroen had already worked on some RProtoBuf extensions in the context of his OpenCPU project; we have now integrated those Protocol Buffers functions. And Jeroen pushed all the right buttons to finally get RProtoBuf built on everybody's least-favourite operating system by provding a static library for use by win-builder and CRAN. Murray once again did a lot of work on internals. His use of the LLVM tool llvm-format was particular helpful to make our coding style a little more consistent. The complete NEWS file entry for this release follows:
Changes in RProtoBuf version 0.4.0 (2014-01-14)
  • Changes to support CRAN builds for MS Windows.
  • Added functions serialize_pb, unserialize_pb, and can_serialize_pb plus documentation from Jeroen Ooms RProtoBufUtils package.
  • New dir inst/python with some Python examples.
  • Added Jeroen Ooms as author.
  • Vignettes have been converted to the R 3.0.0 or later use of external vignette builders, no longer need a Makefile
  • Added missing methods to dollar completion list for Message, Descriptor, EnumValueDescriptor, and FileDescriptor classes.
  • Add missing export for .DollarNames EnumValueDescriptor to allow completion on that class.
  • Add more than 15 additional pages to the main Intro vignette documenting better all of the S4 classes implemented by RProtoBuf, updating the type mapping tables to take into account 64-bit support, and documenting advanced features such as Extensions.
  • Added better error checking in EnumDescriptors to catch the case when wrong types are provided.
  • Updated the FileDescriptor name() method to accept a boolean for full paths just like the generic name() method.
  • Correct a bug that incorrectly dispatched as.character() when as.list() was called on Descriptor objects.
  • Update FileDescriptor $ dispatch to work properly for the names of fields defined in the FileDescriptor, instead of just returning NULL even for types returned by $ completion.
  • Added a reservation for extension fields in the example tutorial.Person schema.
  • Support setting int32 fields with character representations and raise an R-level stop() error if the provided string can not be parsed as a 32-bit integer, rather than crashing the R instance.
  • Update the project TODO file.
  • Add better documentation and tests for all of the above.
  • Corrected the handling of uint32 and fixed32 types in protocol buffers to ensure that they work with numbers as large as 2^32 - 1, which is larger than an integer can hold in R since R does not have an unsigned integer class. These values are stored as doubles internally now to avoid losing precision.
  • Added unit tests to verify behavior of RProtoBuf with extreme values for uint32 types.
  • Removed old exception handling code and instead rely on the more modern Rcpp::stop method maintained in Rcpp.
  • Add better error messages when setting a repeated field of messages to inform the user which element index was of the wrong type and what the expected type was.
  • Add an optional 'partial' argument to readASCII allowing uninitialized message fragments to be read in.
  • (internal) Added const qualifiers in more places throughout the C++ code for type safety.
  • (internal) Standardize coding conventions of the C++ files and run them through clang-format for consistency. A STYLE file has been submitted to R-Forge with details about the coding standards and how they are enforced with Emacs and clang-format.
  • Applied changes suggested by Kevin Ushey to the S4 class handling to support both the currently released Rcpp as well as the currently pending next version.
CRANberries also provides a diff to the previous release 0.3.2. More information is at the RProtoBuf page which has a draft package vignette, a 'quick' overview vignette and a unit test summary vignette. Questions, comments etc should go to the rprotobuf mailing list off the RProtoBuf page at R-Forge.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

18 January 2014

James Bromberger: Linux.conf.au 2014: LCA TV

The radio silence here on my blog has been not from lack of activity, but the inverse. Linux.conf.au chewed up the few remaining spare cycles I have had recently (after family and work), but not from organising the conference (been there, got the T-Shirt and the bag). So, let s do a run through of what has happened LCA2014 Perth has come and gone in pretty smooth fashion. A remarkable effort from the likes of the Perth crew of Luke, Paul, Euan, Leon, Jason, Michael, and a slew of volunteers who stepped up not to mention our interstate firends of Steve and Erin, Matthew, James I, Tim the Streaming guy and others, and our pro organisers at Manhattan Events. It was a reasonably smooth ride: the UWA campus was beautiful, the leacture theatres were workable, and the Octogon Theatre was at its best when filled with just shy of 500 like minded people and an accomplished person gracing the stage. What was impressive (to me, at least) was the effort of the AV team (which I was on the extreme edges of); videos of keynotes hit the Linux Australia mirror within hours of the event. Recording and live streaming of all keynotes and sessions happend almost flawlessly. Leon had built a reasonably robust video capture management system (eventstreamer on github) to ensure that people fresh to DVswitch had nothing break so bad it didn t automatically fix itself and all of this was monitored from the Operations Room (called the TAVNOC, which would have been the AV NOC, but somehow a loose reference to the UWA Tavern the Tav crept in there). Some 167 videos were made and uploaded most of this was also mirrored on campus before th end of the conference so attendees could load up their laptops with plenty of content for the return trip home. Euan s quick Blender work meant there was a nice intro and outro graphic, and Leon s scripting ensured that Zookeepr, the LCA conference manegment software, was the source of truth in getting all videos processed and tagged correctly. I was scheduled (and did give) a presentation at LCA 2014 about Debian on Amazon Web Services (on Thursday), and attended as many of the sessions as possible, but my good friend Michael Davies (LCA 2004 chair, and chair of the LCA Papers Committee for a good many years) had another role for this year. We wanted to capture some of the hallway track of Linux.conf.au that is missed in all the videos of presentations. And thus was born LCA TV. LCA TV consisted of the video equipment for an additional stream mixer host, cameras, cables and switches, hooking into the same streaming framework as the rest of the sessions. We took over a corner of the registration room (UWA Undercroft), brought in a few stage lights, a couch, coffee table, seat, some extra mics, and aimed to fill the session gaps with informal chats with some of the people at Linux.conf.au speakers, attendees, volunteers alike. And come they did. One or two interviews didn t succeed (this was an experiment), but in the end, we ve got over 20 interviews with some interesting people. These streamed out live to the people watching LCA from afar; those unable to make it to Perth in early January; but they were recorded too and we can start to watch them (see below) I was also lucky enough to mix the video for the three keynotes as well as the opening and closing, with very capable crew around the Octogon Theatre. As the curtain came down, and the 2014 crew took to the stage to be congratulated by the attendees, I couldn t help but feel a little bit proud and a touch nostalgic memories from 11 years earlier when LCA 2003 came to a close in the very same venue. So, before we head into the viewing season for LCA TV, let me thank all the volunteers who organised, the AV volunteers, the Registration volunteers, the UWA team who helped with Octogon, Networking, awesome CB Radios hooked up to the UWA repeated that worked all the way to the airport. Thanks to the Speakers who submitted proposals. The Speakers who were accepted, made the journey and took to the stage. The people who attended. The sponsors who help make this happen. All of the above helps share the knowledge, and ultimately, move the community forward. But my thanks to Luke and Paul for agreeing to stand there in the middle of all this madness and hive of semi structured activity that just worked. Please remember this was experimental; the noise was the buzz of the conference going on around us. There was pretty much only one person on the AV kit my thanks to Andrew Cooks who I ll dub as our sound editor, vision director, floor manager, and anything else. So who did we interview? One or two talks did not work, so appologies to those that are missing. Here s the playlist to start you off! Enjoy.

17 January 2014

Chris Lamb: Captain Phillips: Pontius Pirate

https://chris-lamb.co.uk/wp-content/2014/phillips_b.jpg Somalia's chief exports appear to be morally-ambiguous Salon articles about piracy and sophomoric evidence against libertarianism. However, it is the former topic that Captain Phillips concerns itself with, inspired by the hijacking of the Maersk Alabama container ship in 2009. What is truth? In the end, Captain Phillips does not rise above Pontius Pilate in providing an answer, but it certainly tries using more refined instruments than irony or leaden sarcasm. This motif pervades the film. Obviously, it is based on a "true story" and brings aboard that baggage, but it also permeates the plot in a much deeper sense. For example, Phillips and the US Navy lie almost compulsively to the pirates, whilst the pirates only really lie once (where they put Phillips in greater danger). Notice further that Phillips only starts to tell the truth when he thinks all hope is lost. These telling observations become even more fascinating when you realise that they must be based on the testimony of the, well, liars. Clearly, deception is a weapon to be monopolised and there are few limits on what good guys can or should lie about if they believe they can save lives.
https://chris-lamb.co.uk/wp-content/2014/phillips_c.jpg

Even Phillip's nickname ("Irish") is a falsehood he straight-up admits he is an American citizen.

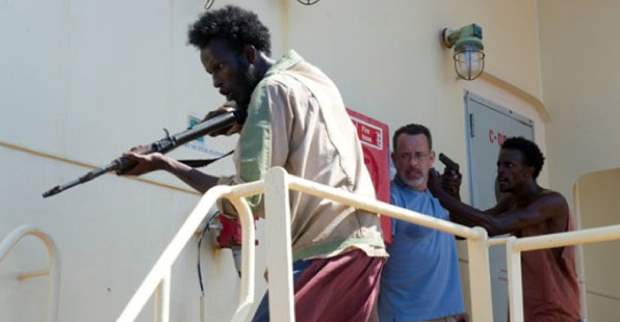
Futhermore, there is an utterly disarming epilogue where Phillips is being treated for shock by clinical efficient medical staff. Not only will this scuttle any "blanket around the shoulders" clich but is probably a highly accurate portrayal of what actually happens post-trauma. This echoes the kind of truth Werner Herzog aims for in his filmmaking as well his guilt-inducing duality between uncomfortable lingering and compulsive viewing. Lastly, a starter for a meta-discussion: can a film based on real-world events even be "spoilered"? Hearing headlines on the radio before you read your newspaper hardly robs you of a literary journey... Captain Phillips does have some quotidian problems. Firstly, the only tool for ratcheting up tension is for the Somalians to launch verbal broadsides at the Americans, with each compromise somehow escalating the situation. This technique is effective but well before the climatic rescue scene where it is really needed it has been subject to the most extreme diminishing returns. (I cannot be the first to notice the "Africans festooned with guns shouting incomphensively" trope I hope it is based on a Babel-esque mechanism of disorientation from miscommunication rather than anything more unsavoury.)
https://chris-lamb.co.uk/wp-content/2014/phillips_a.jpg

The racist idea that Africans prefer an AK-47 rotated about the Z-axis is socially constructed.

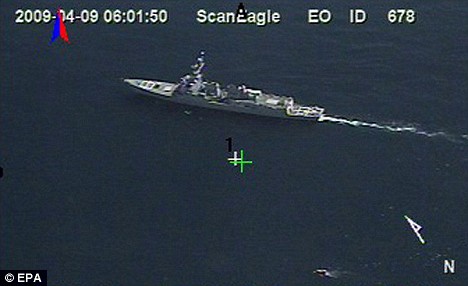
Secondly, the US Navy acts like a teacher with an Ofsted inspector observing quietly from the corner of the classroom; far too well-behaved it suspends belief, with no post-kill gloating or even the tiniest of post-arrest congratulations. Whilst nobody wants to see the Navy overreact badly to other military branches getting all the glory, nobody wants to see a suspiciously bland recruitment vehicle either. Paradoxically, this hermetic treatment made me unduly fascinated by them as if they were part of some military "uncanny valley". Two quick observations:
https://chris-lamb.co.uk/wp-content/2014/phillips_d.jpg

The drone footage: I'd love to write an essay about how Call of Duty might have influenced (or even be) cinema.

Finally, despite the title, the film is actually about two captains; the skillful liar Phillips and ... well, that's the real problem. Whilst Captain Muse is certainly no caricatured Hook, we are offered little depth beyond a "You're not just a fisherman" faux-revelation that leads nowhere. I was left inventing reasons for his akrasia so that he made any sense whatsoever. One could charitably argue that the film attempts to stay objective on Muse, but the inability for the film to take any obvious ethical stance actually seems to confuse and then compromise the narrative. What deeper truth is actually being revealed? Is this film or documentary? Worse still, the moral vacuum is invariably filled by the viewer's existing political outlook: are Somali pirates victims of circumstance who are forced into (alas, regrettable) swashbuckling adventures to pacify plank-threatening warlords? Or are they violent and dangerous criminals who habour an irrational resentment against the West, flimsily represented by material goods in shipping containers? Your improvised answer to this Rorschach test will always sit more haphazardly in the film than any pre-constructed treatment ever could. 6/10

Chris Lamb: Review: Captain Phillips (2013)

https://chris-lamb.co.uk/wp-content/2014/phillips_b.jpg Somalia's chief exports appear to be morally-ambiguous Salon articles about piracy and sophomoric evidence against libertarianism. However, it is the former topic that Captain Phillips concerns itself with, inspired by the hijacking of the Maersk Alabama container ship in 2009. What is truth? In the end, Captain Phillips does not rise above Pontius Pilate in providing an answer, but it certainly tries using more refined instruments than irony or leaden sarcasm. This motif pervades the film. Obviously, it is based on a "true story" and brings aboard all that well-travelled baggage, but it also permeates the plot in a much deeper sense. For example, Phillips and the US Navy lie almost compulsively to the pirates, whilst the pirates only really lie once where they put Phillips in greater danger. Notice further that Phillips only starts to tell the truth when he thinks all hope is lost. These telling observations become even more fascinating when you realise that they must be based on the testimony of the, well, liars. Clearly, deception is a weapon to be monopolised and there are few limits on what good guys can or should lie about if they believe they can save lives.
https://chris-lamb.co.uk/wp-content/2014/phillips_c.jpg

Even Phillip's nickname ("Irish") is a falsehood he straight-up admits he is an American citizen.

Lastly, there is an utterly disarming epilogue where Phillips is being treated for shock by clinical efficient medical staff. Not only will it scuttle any "blanket around the shoulders" clich but is probably a highly accurate portrayal of what actually happens post-trauma. This echoes the kind of truth Werner Herzog often aims for in his filmmaking as well his guilt-inducing duality between uncomfortable lingering and compulsive viewing. Another angle worthy of discussion: can a film based on real-world events even be "spoilered"? Hearing headlines on the before you read the newspaper hardly robs you of a literary journey... Captain Phillips does have some quotidian problems. Firstly, the only tool for ratcheting up tension is for the Somalians to launch verbal broadsides at the Americans, with each compromise somehow escalating the situation further. This technique is genuinely effective but well before the climatic rescue scene where it is really needed it has been subject to the most extreme diminishing returns. (I cannot be the first to notice the "Africans festooned with guns shouting incomphensively" trope I hope it is based on a Babel-esque mechanism of disorientation and miscommunication rather than anything, frankly, unsavoury.)
https://chris-lamb.co.uk/wp-content/2014/phillips_a.jpg

The racist idea that Africans prefer a AK-47 rotated about the Z-axis is socially constructed.

Secondly, the US Navy acts like a teacher with an Ofsted inspector observing quietly from the corner of the classroom; far too well-behaved it suspends belief, with no post-kill gloating or even the tiniest of post-arrest congratulations. Whilst nobody wants to see the Navy overreact badly to other military branches getting all the glory, nobody wants to see a suspiciously bland recruitment vehicle either. Paradoxically, this hermetic treatment made me unduly fascinated by them, as if they were part of some military "uncanny valley". Two quick observations:
https://chris-lamb.co.uk/wp-content/2014/phillips_d.jpg

The drone footage: I'd love to read (or write) an essay about how Call of Duty might have influenced cinema.

Finally, despite the title, the film is actually about two captains; the skillful liar Phillips and ... well, that's the real problem. Whilst Captain Muse is certainly no caricatured Hook, we are offered little depth beyond a "You're not just a fisherman" faux-revelation that leads nowhere. I was left inventing reasons for his akrasia so that he made any sense whatsoever. One could charitably argue that the film attempts to stay objective on Muse, but the inability for the film to take any obvious ethical stance actually seems to confuse and then compromise the narrative. What deeper truth is actually being revealed? Is this film or documentary? Worse still, the moral vacuum is invariably filled by the viewer's existing political outlook: are Somali pirates victims of circumstance who are forced into (alas, regrettable) swashbuckling adventures to pacify plank-threatening warlords? Or are they violent and dangerous criminals who habour an irrational resentment against the West, flimsily represented by material goods in shipping containers? Your improvised answer to this Rorschach test will always sit more haphazardly in the film than any pre-constructed treatment ever could. 6/10

Steve Kemp: So I found a job.

Just to recap my life since December:
I had worked with Bytemark for seven years and left for reasons which made sense. I started working for "big corp" with a job that on-paper sounded good, but ultimately turned out to be a poor fit for my tastes. I spent a month trying to decide "Is this bad, or is this just not what I'm used to?", because I was aware that there would obviously be big differences as well as little ones. At the point I realized some of the niggles could be fixed but most couldn't then I resigned, rather than prolong the initial probationary training period - because I knew I wouldn't stay, and it seemed unfair and misleading to stay for the full duration of the probationary period knowing full well I'd leave the moment it concluded - and the notice period switched from seven days to one month.
A couple of people were kind enough to get in touch and discuss potential offers, both locally, remotely in the UK, and from abroad (the latter surprised me, but pleased me too). I spent a couple of days "contracting", by which I really mean doing a few favours for friends, some of whom paid me in Amazon vouchers, and some of whom paid me in beer.
e.g. I tweaked the upcoming death Knight site to handle 3000 simultaneous HTTP connections, then I upgraded some servers from Squeeze to Wheezy for some other folk.
That aside I've largely been idle for about 10 days and have now picked the company to work for - so I'm going to be a contractor with a day-rate for an American firm for the next couple of months. If that goes well then I'll become a full-time employee, hopefully.

Lucas Nussbaum: RSS feed available in the Debian Maintainer Dashboard

One of my pet projects in Debian is the Debian Maintainer Dashboard. Built on top of UDD, DMD provides a maintainer-centric view to answer the I have a few hours for Debian, what should I do now? question (see example). Christophe Siraut did a lot of great work recently on DMD, rewriting much of the internals. As a result, he also added a RSS feed feature: you can now get notified of new TODO list items by subscribing to that feed. If you have suggestions or comments, please use the debian-qa@ list (see this thread). Thanks, Christophe!

16 January 2014

Iustin Pop: What's in a community?

I haven't been doing Debian work for a while now, due to various reasons. However, I try to keep reading (but not posting to) the mailing list, such as to keep in touch (in a virtual way). What surprises me is how the community evolves: in some ways not at all (was there an init-system flamewar this week already or not?), in some ways a lot (mailing list bans!). Since I don't post to the mailing lists, consider this post as my +1 towards the listmaster's work: yes, we should limit the damage that abusive people do to the project. I'm surprised at how some people call list bans as censorship (it's not, IMHO), and how they treat abuse as something light. Another thing that surprises me is how abuse and arrogance go hand in hand. In the explanations for bans, I've seen not just one example where the abusive person is not only, well, abusive, but also considers themselves superior (morally, technically, etc.). If you're already so much superior, why hit on people? If you already know so much, why the personal attacks? And no, being immature is not the whole or even the only explanation This page has a nice collection of quotes around the same motive: how you treat other people, especially people whom you regard less knowledgeable than you, tells a lot about your character. One quote is nice in how succinct and how applicable it is to the kind of abuse I've seen:
To insult or to abuse those who cannot resist, or dare not resent the injury, is a sure mark of cowardice, [ ].
From 1852 September 30, Farmer s Cabinet, Courtesy to Inferiors, Page 1, Column 2, Volume 51, Number 8, Amherst, New Hampshire. The rest of the quote also contains a somewhat sexist remark, so I've left that part out (but I'm surprised they still talked about swords in the 1850s). And yes, I hope that this spring I'll be able to get back to my Debian work.

15 January 2014

Bits from Debian: Call for Proposals for the MiniDebConf 2014 Barcelona

Debian Women will hold a MiniDebConf in Barcelona on March 15-16, 2014. Everyone is invited to both talks and social events, but the speakers will all be people who identify themselves as female. This is not a conference about women in Free Software, or women in Debian, rather a usual Debian Mini-DebConf where all the speakers are women. Debian Women invites submissions of proposals for papers, presentations, discussion sessions and tutorials for the event. Submissions are not limited to traditional talks: you could propose a performance, an art installation, a debate or anything else. All talks are welcome, whether newbie or very advanced level. Please, forward this call to potential speakers and help us make this event a great success! Please send your proposals to proposals@bcn2014.mini.debconf.org. Don't forget to include in your message: your name or nick the title of the event, description, language, and any other information that might be useful. Please submit your proposal(s) as soon as possible. For more information, visit the website of the event: http://bcn2014.mini.debconf.org We hope to see you in Barcelona!

Sylvestre Ledru: Some thoughts concerning LLVM & Clang and their evolutions: Release of LLVM & Clang 3.4

We just released LLVM & Clang 3.4 (already available in Debian Jessie and Ubuntu Trusty). The clang new release introduces some more warning and error detections. The point of the blog post is not to detail the changes (LLVM / Clang) but more to take a step back on the LLVM and Clang toolchains, usages and dissemination. For the last couple years, I have been presenting our work on the Debian side to make Clang part of the Debian infrastructure. I add the chance to speak at many events (Debconf 12 & 13, FOSDEM 2013, Linux Plumbers 2013, Distro recipes, etc). I even had Linus Torvalds attending to one of these talks (and proposing new approach). I had many feedback from the Debian/Ubuntu communities but also from other communities.
More and more projects are using Clang as part of their workflows, in term of development, production and QA. For example, some of them are running continuous integration using clang instead of gcc, others are running scan-build (Wireshark or LLVM itself) or Address Sanitizer (asan) (Firefox for example), etc.
More and more actors are moving from gcc to clang for their developments (Sony with their PS4, Chrome under Mac OS X, Apple, the Linux Kernel with the LLVMLinux project, FreeBSD, etc).
I stopped counting the number of times when people answered me "Yeh, I am now using Clang" when I said I am involved upstream. In parallel, more and more projects are using LLVM as a backend or computing engine and, in the meantime, getting more and more attraction (not because they are based on LLVM but just because they are great projects). For example, Mesa (llvmpipe), Julia, Rust, Emscripten or Native Client (NaCL) are excellent examples of this. The two last are excellent proofs that LLVM based technologies have an impact which goes further than geek-tools and will be used on a daily basis by millions of users. I also saw an interesting and growing number of new projects using libclang and libTooling. My feeling is that the lack of plugin capabilities in gcc for a long time and, now, its current complexity limited the innovation in term of compilation capabilities, analysis and fun tools. The features and the quality of this library are enabling new developments and I am sure we will see more and more excellent tools based on this library during 2014.
For example, the LLVM toolchain ships Clang modernize and clang format and some cool projects like include-what-you-use, DXR, OCLint or creduce are emerging. Thanks to this great competition, gcc is also improving (ASAN, JIT, better warnings, etc), remaining still relevant as before. No doubt that 2014 will be a great year for compilers.

Jan Wagner: Bye bye Nagios-Plugins

Last night it seems the so called 'Nagios Plugins' project was cut off. The story started a decade ago when development of the plugins compatible with Nagios was taken over by an independend group of developers. Some time later, the domain of the 'Nagios Plugins' project was handed over to 'Nagios Enterprises, LLC.' due trademark reasons. To get an idea about that, I suggest to read on the 'Nagios Trademark Truth' and 'Nagios Trademark Triumph Provides Promise To Open Source Developers, Shows Power of Community'. In the latter Mr. Galstad is cited with "This violation took more than four years and thousands in legal fees before it was finally resolved. My hope is that this can serve as an example to Open Source developers worldwide that they can overcome infringements and protect their brands if they are persistent and engage their respective communities.". Yesterday in the evening the project members recognised that the DNS of nagios-plugins.org was moved to a different location. Now there seems to be a hosted (some may call that 'hijacked' or 'pirated') 'mirror' of the old site. Anyhow ... the content is already different from the original one or maybe changed even more in the future. From my point of view this can serve as an example to Open Source developers worldwide that they can be obstructed by (trademark holding) companies even if those companies profit from the work of them. So please don't use downloads from there, even the release tarballs maybe modified. The news all about that: 'Nagios Plugins are dead, we now have Monitoring Plugins in place!" Be sure you download your tarballs from https://www.monitoring-plugins.org/download.html and verify your checksums! You can follow the Monitoring Plugins Development Team also via Twitter.

14 January 2014

Daniel Pocock: Blog comments working again

Blog comments have been problematic on this site for some months now. I finally had a look into the problem last night and identified the cause of the problem and implemented a workaround which other Drupal Blogspam module users are welcome to copy. Thanks to Steve Kemp for providing the Blogspam service. Anything but thanks to those who provide the spam.

13 January 2014

Daniel Pocock: PostFinance, where is my money?

Update: my money has been returned by PostFinance very soon after this blog appeared There's no better way to get the year off to a good start than finding money has gone missing from your bank account. Where I live in Switzerland, it is mandatory for everybody to make a monthly payment for health insurance (as it is mandatory, it is basically a tax, like the monthly council tax in England). Just like British council tax, the premiums go up each year and every person in the country has to log into their bank's web site and change their standing order. A few days after doing just that, I went back in to the web site to make another payment and noticed that the first health insurance payment for 2014 had been duplicated on two consecutive days, the 30th and 31st of December: I immediately sent them an email to alert them to the fault and ask for the duplicate transaction to be corrected. Normally, when a company makes a mistake, it would be fixed within a couple of days and certainly never reach my blog. Instead of getting a helpful reply, I was astonished to receive this:
There has been a misunderstanding when you have set up your standing order.
You selected "First execution" December 30, 2013 and then "monthly execution" 31. The system has followed your instruction and it results a double execution December 30 and 31.
Unfortunately, we are not able to return you the amount.
Great, apparently it is all my own fault. I thought "monthly" would mean one payment in each one month but apparently not everybody uses the same definition of monthly. (Actually, banks do have systems such as the 360 day calendar but that is another story). So let's look at these faulty instructions I supposedly gave. I immediately went back to the standing order page to take a screenshot. I even compared the page in English (my default language, which they are kind enough to let me use) and French (one of the four official languages of the Swiss Confederation) and I found they say much the same thing: Note: exact amounts and account numbers concealed The form is relatively clear: I authorised a monthly payment (Periodicite: mensuel) with the first (Premiere) payment on 30.12.2013 and then, or so I believed (and still do) a following payment (ensuite) on the 31st of each month, with the last payment at the end of November, for 12 payments in total. Simple, right? Where it says ensuite le 31, I sincerely believe that means the second payment is on 31 January, but Postfinance seem to be arguing that I meant the 31 December: just one day, rather than one month, after the first payment. Delaying tactics I replied to their email, telling them explicitly that I had authorized a monthly payment only and demanding the immediate return of the duplicate payment. When I got their next reply, I didn't know what to think:
We are pleased to do the necessary to revoke the transfer to SWICA. This will take at least two weeks.
On the one hand, it appears they are now starting to accept they may have made a blunder. But two more weeks? This was already 10 days after the money went missing. Do they even know what is wrong with their system? It doesn't give me confidence. I wrote back again and insisted that this is their error and that an immediate correction is required. Pass the buck, take three Today, another reply came back. After almost 14 days, I've now got three fob-off excuse mails and none of my money returned:
We did the request at SWICA to send back the money on your account on the 8th January 2014. The decision will be taken by them if they agree to send back this amount.
Unfortunately, we cannot do more except waiting their answer. You can call them and explain them the situation. With your call, maybe the reimbursement could be faster.
Why is it in the hands of the health insurance company? It is not their fault that Postfinance has a problem processing standing orders. Why do I have to waste my time chasing people, will I get compensation for that? Am I the only victim? With many people configuring their new health insurance payments at this time of the year, I can imagine that there may be other victims of this fault too. Are they all being fobbed off with these excuses? Some may not even realize if they don't check their account closely. What next? Sure, maybe I can just cancel the next health insurance payment: but why should I have that inconvenience? What exactly was I supposed to put on that form to not make this mistake they suggest I made? If I cancel the next payment like they suggest and then set up the payment again from March, how can I be sure the same duplication won't happen again? Using customers as unpaid QA testers Many leading financial organisations have experienced teams of developers, QA testers, and comprehensive regime of simulation/testing with paid participants to ensure their systems are reliable and as friendly and accurate as possible. Here, it feels like PostFinance has skipped all that, deploying a form that is ambiguous at best and they are using real customers like me to test the system and report the bugs. Normally organisations pay me for doing that very same task as part of my job as a software engineer. Not only have Postfinance taken almost 200 CHF of my money, but they have wasted my time with their strategy of fobbing me off and at the same time they are probably sending my feedback to their developers instead of paying a QA tester to check their systems. You be the judge What is your opinion?
  • Daniel can't use a web form, it is definitely Daniel's mistake, nobody else would make a mistake like that
  • The Postfinance form is ambiguous and so it is probably their fault and they should give back the money, it is likely these are cut and paste emails they send to all the customers who are duped by the form
  • Postfinance is completely wrong. Monthly means one payment each month.

11 January 2014

Steve Kemp: Some productive work

Having decided to take a fortnight off, between looking for a new job, I assumed I'd spend a while coding. Happily my wife, who is a (medical) doctor, has been home recently so we've got to spend time together instead. I'm currently pondering projects which will be small enough to be complete in a week, but large enough to be useful. Thus far I've just reimplemented RSS -> chat which I liked a lot at Bytemark. I have my own chat-server setup, which doesn't have any users but myself. Instead it has a bunch of rooms setup, and different rooms get different messages. I've now created a new "RSS" room, and a bunch of RSS feeds get announced there when new posts appear. It's a useful thing if you like following feeds, and happen to have a chat-room setup. I use Prosody as my chat-server, and I use my http2xmpp code to implement a simple HTTP-POST to XMPP broadcast mechanism. The new script is included as examples/rss-announcer and just polls RSS feeds - URLs which haven't been broadcast previously are posted to the HTTP-server, and thus get injected into the chatroom. A little convoluted, but simple to understand. This time round I'm using Redis to keep track of which URLs have been seen already. Beyond that I've been doing a bit of work for friends, and have recently setup an nginx server which will handle 3000+ simultaneous connections. Not too bad, but I'm sure we can make it do better - another server running on BigV which is nice to see :) I'll be handling a few Squeeze -> Wheezy upgrades in the next week too, setting up backups, and doing some other related "consultation". If I thought there was a big enough market locally I might consider doing that full-time, but I suspect that relying upon random work wouldn't work long-term.

10 January 2014

Paul Tagliamonte: Docker in Debian

Hello, World! Docker s in Debian! Isn t that great! Let s all get happy! It s called docker.io, so go ahead and sudo apt-get install docker.io whenever you want :) The first two uploads have a few errors, which are 100% my fault. The first were a set of FTBFS bugs, which were a stupid error on my part. Thanks to olasd for catching the remaining bug, related to stripping the binaries. I m so sorry this happened, it slipped through as a result of me having a local docker binary in /usr/local, which I tested completely before uploading a totally different binary. I won t let it happen again. It should be fixed now. However, this comes with a warning. It appears as though systemd (which, for the record I adore) is allowing lxc-start unmount /dev/pts and friends, which causes a bunch of damage to the host. I ve filed the bug as bug #734813. Currently the outdated mount(1) is holding back a workaround. Hopefully we get util-linux updated so we can hack around this in the short-term. Hopefully the bigger issues get solved. So, if you re a systemd user, please hold off on using docker.io until we resolve this issue in Debian.

8 January 2014

Gunnar Wolf: [review] Packt's Instant Haml

Packt Publishing sent me Krzysztof Niki ski's Instant Haml to do a short blog review... Thing is, and those who read me know, I cannot write short reviews ;-) So lets see how this goes. Packt's Instant series First, as for the format this book follows and the series it fits in: They are very short books. I was the tech reviewer for their Instant Debian Build a Web Server , and when I opened it for the first time, I thought I had received only the first chapter. This series' motto is Short Fast Focused so, yes, the books are ~50 pages long, with ample margins and many big screenshots. I told the editors I was quite unsure about the value this kind of publications add, as they are very similar to online tutorials, but given they have so many books in this series (printed and electronic), there must be a market for them. They surely know their business better than me! There is one other detail regarding the publisher I'll stick in this section, although it is not specific to their Instant series: I do most of my reading in my Kindle. Packt seems to have chosen to specify a very small font for their texts. Besides the two books mentioned, I also have their Object Oriented JavaScript book. For all of the other books I read, I use the smallest font setting. Packt books in mobi format (what they present as Amazon format in their web site) are basically illegible without bumping up the font size through the roof. As I understand it, publishers should use industry-wide default sizes, and let the reader adjust their reading experience. Yes, books of technical nature (such as Packt's) often benefit from having more displayed information than what an ebook reader normally shows... But that's for me to decide! And no, this is not a Kindle-specific glitch: I also get a similar experience when opening it from Calibre. And as for the book... I am a long-time Haml convert/fan; I packaged its Ruby implementation for Debian (and should update it soon :-/ as new versions have appeared), the corresponding Emacs Lisp mode, and I use it for basically all of my static HTML sites and Ruby-based Web systems. Haml is a great templating language, meant to make dynamic HTML generation leaner and easier. It is a clean and elegant technology, and can clearly sell itself. And the project webpage has very good documentation, ranging from a short tutorial and a full API documentation for people to contribute to the project. The first part of this book, of course, covers the "why is Haml so great?" part, presenting the basic equivalences with HTML. In my opinion, the book could be structured a bit differently and would generate a stronger following. Why? Because, even given that Haml is greatly benefited from its Ruby integration and has many hooks to be tightly integrated in a Rails workflow, it can also be used by people who don't want to do Ruby. I have some static websites that are just a bunch of Haml files, compiled by a very simple Makefile and calling the haml command from the shell. I think there would be some value in presenting this invocation before learning how to call it from the Gems environment (i.e. bundle install). Using Haml as a standalone tool is only presented almost as an appendix ("Using HAML outside of Rails" section). Even more so if the author presents four different static-site solutions (probably more non-programmer-friendly than my trusty Makefile). Oh, and this little section uses the (old? obsolete?) uppercase HAML notation for the project's name instead of the now-standard Haml. Dirty screenshots About the screenshots presented in this first section (and I refer mainly to the scaffolding examples), they are meant to show how easy things are, but have an important stylistic mistake: Terminals with transparency might look cool (I hate using them, but then again I'm a very boring person when it comes to my computer habits ;-) ), but transparencies have no place in a book (be it printed or e-book), as the images appear very uncrisp. In the Kindle, they just seemed dirty Now that I'm browsing the PDF from my desktop, I see that the screenshot in "Step 1" has a photo of Earth from space behind the terminal, and even worse, in "Step 2" it is shown over a Web page detailing the installation! These elements are just distracting, and the text would be much cleaerer if it were presented typeset just as a regular code fragment. Opening many of those screenshots in the Kindle was plain useless. Editor integration It is perfectly clear from this text that the author strongly prefers Sublime Text, sometimes uses TextMate, and has just heard reports that Haml has some support in Vim, Rubymine, Emacs and Coda. Of course, devoting a full page (as it is for the first case) for each editor would be out of proportion for this size of book... I just felt the imbalance too big, specially given that most editors will sport approximately the same feature set. Text redundancy If the Instant series is about making short books, I would expect them to be loaded with easy to follow content (as they are), but free of repetition. I felt, however, a large chunk of step 1 of the "Quick start" chapter to be repeated with the the first section of the "Top 6 features" chapter. Yes, the second one adds some depth, but very little. Still, in the later parts of this "Top 6 features" chapter, a more thorough explanation could be used for the Filters, Multiline attributes/code/strings and helpers and extensions sections. It seems the author was on a hurry trying to get it finished, as it is barely explained Explaining a bit more deeply would surely benefit readers. Wrapping up Reading my review, I'm mostly talking about negative issues. IMO, the book is not excellent, but it is clearly not bad. Specially given it fits very well the format for which it was designed. There are many items that could be fixed, and I hope some of them can be fixed (i.e. the screenshots) before the book goes to print If I understand Packt's page correctly, it is currently only available as ebook, contrary to most of the Instant series' titles.

Next.

Previous.