Search Results: "ron"

7 November 2015

Mehdi Dogguy: 3rd annual Aaron Swartz Day, November 7-8

This weekend is organized the Aaron Swartz Day across the world. There are events organized in many cities and video streams available. It is important that we remember Aaron's projects and fights. If you want to know more about Aaron Swartz, you may start by watching the excellent documentary The Internet's Own Boy : The Story of Aaron Swartz. His work was very inspirational and should not be forgotten!

Andrew Cater: Mini Debconf ARM Cambridge 1115 7 November

Between talks - coding and testing going on in the row infront of me - vmdebootstrap rework for Debian Live CD still going on.

Beaglebone SBC hanging from a Thinkpad in the row behind

Others talking - most getting coffee

Next up - Daniel Silverstone on Lua

Andrew Cater: Mini Debconf 2015 ARM Cambridge - ARM, 7 November

Belated thanks to the ARM folk who arranged car park spaces for me for Thursday and Friday. I'm mobility impaired so this made a huge difference.

Today is the more open day - not so much programming, more presentations and talks. Also being live streamed. http://video.debconf.org:8000/minidebconf.ogv

Schedule is slightly changed but the wiki is correct

The auditorium is pretty full even at 0925

Thanks as ever to front desk and the ARM security staff who have wekcined ** welcomed us. Here's to a good day

** typing on laptop balanced on lap

6 November 2015

Matthew Garrett: Why improving kernel security is important

The Washington Post published an article today which describes the ongoing tension between the security community and Linux kernel developers. This has been roundly denounced as FUD, with Rob Graham going so far as to claim that nobody ever attacks the kernel.

Unfortunately he's entirely and demonstrably wrong, it's not FUD and the state of security in the kernel is currently far short of where it should be.

An example. Recent versions of Android use SELinux to confine applications. Even if you have full control over an application running on Android, the SELinux rules make it very difficult to do anything especially user-hostile. Hacking Team, the GPL-violating Italian company who sells surveillance software to human rights abusers, found that this impeded their ability to drop their spyware onto targets' devices. So they took advantage of the fact that many Android devices shipped a kernel with a flawed copy_from_user() implementation that allowed them to copy arbitrary userspace data over arbitrary kernel code, thus allowing them to disable SELinux.

If we could trust userspace applications, we wouldn't need SELinux. But we assume that userspace code may be buggy, misconfigured or actively hostile, and we use technologies such as SELinux or AppArmor to restrict its behaviour. There's simply too much userspace code for us to guarantee that it's all correct, so we do our best to prevent it from doing harm anyway.

This is significantly less true in the kernel. The model up until now has largely been "Fix security bugs as we find them", an approach that fails on two levels:

1) Once we find them and fix them, there's still a window between the fixed version being available and it actually being deployed
2) The forces of good may not be the first ones to find them

This reactive approach is fine for a world where it's possible to push out software updates without having to perform extensive testing first, a world where the only people hunting for interesting kernel vulnerabilities are nice people. This isn't that world, and this approach isn't fine.

Just as features like SELinux allow us to reduce the harm that can occur if a new userspace vulnerability is found, we can add features to the kernel that make it more difficult (or impossible) for attackers to turn a kernel bug into an exploitable vulnerability. The number of people using Linux systems is increasing every day, and many of these users depend on the security of these systems in critical ways. It's vital that we do what we can to avoid their trust being misplaced.

Many useful mitigation features already exist in the Grsecurity patchset, but a combination of technical disagreements around certain features, personality conflicts and an apparent lack of enthusiasm on the side of upstream kernel developers has resulted in almost none of it landing in the kernels that most people use. Kees Cook has proposed a new project to start making a more concerted effort to migrate components of Grsecurity to upstream. If you rely on the kernel being a secure component, either because you ship a product based on it or because you use it yourself, you should probably be doing what you can to support this.

Microsoft received entirely justifiable criticism for the terrible state of security on their platform. They responded by introducing cutting-edge security features across the OS, including the kernel. Accusing anyone who says we need to do the same of spreading FUD is risking free software being sidelined in favour of proprietary software providing more real-world security. That doesn't seem like a good outcome.

comment count unavailable comments

Norbert Preining: Japanese TeX User Meeting Support for Japanese in TeX (Live) present state and future?

Tomorrow the Japanese TeX User Meeting 2015 will be held in Tokyo. Since I have come to Japan I have attended more or less every year this meeting, and in 2013 we could get the (international) TeX User Group Meeting to Tokyo and had a joint conference TUG 2013, which was a great success. (update 2015-11-09: slides added at the end) Japanese-TeX
During tomorrows meeting I will give a talk on Support for Japanese in TeX (Live) present state and future?:
The support for typesetting Japanese in TeX, in particular TeX Live, has been improved over the last few years considerably, so that at the current point we can ask ourselves what is next? This talk reviews a bit of the history of Japanese typesetting support in TeX Live, and discusses future development directions.
For those interested, here is a bit of an extended abstract. With a set of Japan specific TeX engines, the Japanese TeX Users always had a hard time setting up a proper TeX environment. Besides compiling the programs for each new version again, users had to install packages from a variety of sources, which often involved complicated routines. Fortunately, due to the excellent support on the TeX Q&A these difficulties were manageable. Compiling the Japanese TeX engines was first part of the pteTeX project, which adjusted teTeX to include also the required programs. Compilation was done by obtaining the source code of teTeX, plus patches that implement the Japanese TeX engines and support in driver programs. After the end of development of teTeX, TeX Live became the main TeX distribution system, and ptexlive was born to adjust the TeX Live sources to include the Japanese TeX engines. But fundamentally the same procedure remain: Get the source code, patch in additional functionality, compile and install. The last five years have seen a step-wise inclusion of various Japan-related programs in the main TeX Live source repository. Starting with pTeX (and pbibtex etc) and adjustments to dvipdfmx, followed by upTeX, and later on also (u)pmetapost, the main TeX Live source repository now contains all (with the exception of pxdvi) programs related to the Japanese TeX environment. At the same time, developers of various packages started to upload their packages to CTAN, which automatically made these packages available in TeX Live. Thus, the current status is quite satisfactory, since a normal TeX Live installation, without the need for any compilation, provides all necessary programs and packages. What remains a problem are inter-release updates of the binaries, when bugs in various engines are found. Future developments Besides the actual development of packages, and in particular luatexja, I see possible improvements in the following area: Summing up, I am quite happy to see that both the Japanese community, as well as the Korean community, have now taken the step to make their achievements available in an easy and straightforward way for everyone using TeX Live, and I am sure that the future will bring further improvements!
The slides accompanying the talk can be downloaded here: texconf15-texlive-japan.pdf. I also talked briefly on CJK font integration for Ghostscript, these slides can be downloaded here: texconf15-cjk-gs.pdf.

5 November 2015

Gunnar Wolf: WTF @omarfayad Should *all* computer activity be illegal now? #LeyFayad

Last week, Senator Omar Fayad presented one of the prime examples of a poorly redacted law that, if enacted, will make basically any way of computer use illegal. And yes, even if he states this is merely a draft, it has so many factual and conceptual errors that there is no way to trust sanity can be regained at any point. Oh, and before I continue with this rant: If the topic interests you, I suggest you to read the 10 key points about Ley Fayad, the worst Internet initiative in history, published by r3d.mx. [update] An English equivalent of the work at r3d, at revolution-news.com: #LeyFayad: The Worst Bill in Internet History The full text (in Spanish, of course) for the law initiative is available at the Senate webpage; the law will be called Ley Federal para Prevenir y Sancionar los Delitos Inform ticos (Federal law to prevent and punish informatic felonies<) A bad name to start with, as there are many laws already in that contested area. I started reading with the preamble (Exposici n de motivos), which already shows bad signs of imprecise redaction and is plagued with factual errors (i.e. asserting that the real danger stems from the Web migrating to the Web 2.0, from which stems that this migration and not any previous one. Or by stating that (quoting+translating a full paragraph):
Activities such as electronic commerce, digital periodism, publicity and the opinions, messages or elements written in social networks can lead to patrimonial, reputation, honor or professional activity losses for people.
He continues by stating that only 16% of the countries have some kind of cybersecurity strategy (and, of course, Mexico doesn't). That... Well, is very hard to believe, as Mexico has two separate policial groups devoted to cybersecurity, and laws regulating from electronic signatures, commerce, identity, privacy, use and abuse, and a long list. Of course, as most law proposals go, it quickly decays into a dry, boring document... And I must admit I didn't fully read it, but picked here and there. I won't copy in full the note I mentioned at the beginning at r3d.mx, but will continue with some strange points, such as:
Article 16
Every person that, without the corresponding authorization or exceeding the authorization confered, accesses, intercepts, interfers or uses an information system, will be punished by one to eight years of prision and fined by 800 to 1000 days of minimum wage
So, yes, borrowing your computer without getting explicit permission, or playing around with the options in kiosks, or tons of whatever we curious people do with systems we encounter are basis for jail. (And yes, fines in this country are expressed in "days of minimum wage", which goes at ~MX$70 per day, which is ~US$4). But it gets funkier quickly:
Article 17
Whoever fraudulently destroys, disables, damages or in any way alters the working of an informatic system or any of its components, will be punished by fice to fifteen years of jail and fined by up to a thousand minimum wage days The same punishment will be given to whoever, without authorization, destroys, damages, modifies, divulges, transfers or disables information contained in any Informatic System or any of its components. The punishment will be ten to twenty years in prision and a fine of up to a thousand days of minimum wage if the effects here mentioned are done by the creation, introduction or fraudulent transmission, by any means, of an informatic weapon or malicious code
This law is meant to protect against cyberfelonies, if such a thing exists. However, here we are putting at risk people even for accidental equipment destructions. I dropped your portable hard disk with my elbow off the table? Accuse me of acting fraudulently, and I'm up for a serious jail time. And yes, laws are meant to be interpreted... And I don't want to be at the receiving end of this one! In this last article, Fayad mentions informatic weapons, which are defined in the preamble as any informatic program, informatic system, or in general, any device or material created or designed with the purpose of committing an informatic crime. So the very next article makes me, as it should make all of my fellow students and researchers, very uneasy:
Article 18
Whoever uses informatic weapons or malicious code will be imprisioned by two to six years, and fined with 200 to 500 days of minimum wage.
Article 19
Whoever builds, distributes, commerces with informatic weapons or malicious codes will be punished by three to seven years of prision and 200 to 500 days of minimum wage.
If we need to analyze malware for our classes (or for paid work, or as a hobby), we clearly fall in article 18. If we write something that can be classified as malware (without even releasing it, as an academic excercise only!), we are covered by article 19. If I give my students code that's known to be malicious (which could be as inofensive as linking to a well-known Web comic), I'm also covered by article 19. I'll jump all the way to article 31 (reproduced only partially):
Article 31
Whoever, by any means, creates, captures, records, copies, alters, duplicates, clones or deletes the information contained in a credit or debit card (...) will be punished by 8 to 14 years of prision and 300 to 500 days of minimum wage. (...)
This clearly disincentivates any way of e-commerce. When I try to buy anything online, I have to capture+copy my (rightfully owned) credit card data. The services provider has to copy, process and then delete said information. Any e-transaction is punished by jail! Well... But thinking about this again, maybe I shouldn't be so worried about the malware distribution issue at my classes. There are clearer and more contundent articles. Say...
Article 35
Whoever convenes, organizes, is part of, or executes a cibernetic attack, will be punished by 20 to 30 years of prision and fined with 100 to 1000 days of minimum wage
Of course we have convened, organized, been part of and executed cibernetic attacks at the computer security lab at ESIME. Why would there be such a lab otherwise? Then, there are clear indications that the Senator didn't understand the topic his team was working on:
Article 37
Who manipulates the digital seals used by command of the public authority will be punished with 240 days of community work
Now... What is a digital seal? It's not a phisical one that does not allow opening the doors to a business found at fault, but something that just proves a document is legitimate and pristine. How can I manipulate them? Of course, if the seals are MD5-based, I can easily forge them (and SHA1-based, it seems they will be broken enough soon to be considered no longer trustable)... But that's about it! And there is more, lots more. I'm swamped with work, and have to get back to it. But chapters the following chapters have a lot of potential for finding holes. PS - And yes, the only use I do of Twitter is via the headlines in my blog ;-) [update] Ley Fayad is dead, yay! \o/ The senator withdrew the proposal.
Sven Hoexter: dh, dpkg-buildflags, LDFLAGS and the ugly way to stop overlinking

I just got asked by someone I help out with sponsoring uploads from time to time how to get rid of overlinking. Since wheezy or maybe even earlier dpkg-shlipdeps will complain with a warning like this:
dpkg-shlibdeps: warning: package could avoid a useless dependency if debian/
foobar/usr/bin/foobar was not linked against libatk-1.0.so.0 (it uses none of the
library's symbols)
That usually requires some build system fixes, or pkg-config fixes or something else. This one should provide a starting point if you'd like to read a bit more. But in case you're lucky, and you use debhelper, and the buildsystem is sane enough to read the LDCONFIG environment variable
export DEB_LDFLAGS_MAINT_PREPEND := -Wl,-z,defs -Wl,--as-needed
in your debian/rules can be enough. I admit that's still a bit of a hack that requires some luck to work out and can break in strange and nasty ways. But if it work's I'm fine with it. man 1 dpkg-buildflags hold the details to the mechanics in use here regarding the environment variables.

Andrew Cater: MiniDebconf2015, ARM Cambridge 1320 5 November

Back after lunch - chatting about video and stuff with the Video Team sprint.
Thanks to the ARM employees swiping us in and out and shepherding the bunch of us over to lunch and keeping track of us.

From behind me, there's the chat over sorting out a switch to handle the LAN setup to test the video equipment later on.

Next door, they're busy, busy, busy - four tables full of people working fairly quietly. Steve McIntyre (Sledge) is running around facilitating, answering questions, sorting out "stuff"

Front desk are still front desking although most of us have arrived: I'm guessing they'll be busiest over the weekend.

Three of us on laptops doing whatever in here: Helen busy working to make sense of scribbled notes on whiteboards into a proper diagramming package - green and red marker pen on two walls full of whiteboard becomes a sensible project - objectives, bullet points, tasking - seemingly far too much organisation for this sort of thing and not the way some of us naturally work but necessary if we're not to forget something tiny but vital.

Thanks for this expertise, Helen, that most of us don't have :)


4 November 2015

Mart n Ferrari: Tales from the SRE trenches: What can SRE do for you?

This is the fourth part in a series of articles about SRE, based on the talk I gave in the Romanian Association for Better Software. Previous articles can be found here: part 1, part 2, and part 3. As a side note, I am writing this from Heathrow Airport, about to board my plane to EZE. Buenos Aires, here I come!

So, what does SRE actually do? Enough about how to keep the holy wars under control and how to get work away from Ops. Let's talk about some of the things that SRE does. Obviously, SRE runs your service, performing all the traditional SysAdmin duties needed for your cat pictures to reach their consumers: provisioning, configuration, resource allocation, etc. They use specialised tools to monitor the service, and get alerted as soon as a problem is detected. They are also the ones waking up to fix your bugs in the middle of the night. But that is not the whole story: reliability is not only impacted by new launches. Suddenly usage grows, hardware fails, networks lose packets, solar flares flip your bits... When working at scale, things are going to break more often than not. You want these breakages to affect your availability as little as possible, there are three strategies you can apply to this end: minimise the impact of each failure, recover quickly, and avoid repetition. And of course, the best strategy of them all: preventing outages from happening at all.

Minimizing the impact of failures A single failure that takes the whole service down will affect severely your availability, so the first strategy as an SRE is to make sure your service is fragmented and distributed across what is called "failure domains". If the data center catches fire, you are going to have a bad day, but it is a lot better if only a fraction of your users depend on that one data center, while the others keep happily browsing cat pictures. SREs spend a lot of their time planning and deploying systems that span the globe to maximise redundancy while keeping latencies at reasonable levels.

Recovering quickly Many times, retrying after a failure is actually the best option. So another strategy is to automatically restart in milliseconds any piece of your system that fails. This way, less users are affected, while a human has time to investigate and fix the real problem. If a human needs to intervene, it is crucial that they get notified as fast as possible, and that they have quick access to all the information that is needed to solve the problem: detailed documentation of the production environment, meaningful and extensive monitoring, play-books1, etc. After all, at 2 AM you probably don't remember in which country the database shard lives, or what were the series of commands to redirect all the traffic to a different location. Implementing monitoring and automated alerts, writing documentation and play-books, and practising for disaster are other areas where SREs devote much effort.

Avoiding repetition Outages happen, pages ring, problems get fixed, but it should always be a chance for learning and improving. A page should require a human to think about a problem and find a solution. If the same problem keeps appearing, the human is not needed any more: the problem needs to be fixed at the root. Another key aspect of dealing with incidents is to write post-mortems2. Every incident should have one, and these should be tools for learning, not finger-pointing. Post-mortems can be an excellent tool, if people are honest about their mistakes, they are not used to blame other people, and issues are followed up by bug reports and discussions.

Preventing outages Of course nobody can prevent hard drives from failing, but there are certain classes of outages that can be forecasted with careful analysis. Usage spikes can bring a service down, but an SRE team will ensure that the systems are load-tested at higher-than-normal rates. They could also be prepared to quickly scale the service, provided the monitoring system will alert as soon as a certain threshold is reached. Monitoring is actually the key part in this: measuring relevant metrics for all the components of a system, and following their trends over time, SREs can completely avoid many outages: latencies growing out of acceptable bounds, disks filling up, progressive degradation of components, are all examples of typical problems automatically monitored (and alerted on) in an SRE team.
This is getting pretty long, so the next post will be the last one of these series, with some extra tips from SRE experience that I am sure can be applied in many places.

  1. A play-book is a document containing critical information needed when dealing with a specific alert: possible causes, hints for troubleshooting, links to more documentation. Some monitoring systems will automatically add a play-book URL to every alert sent, and you should be doing it too.
  2. Similarly to their real-life counterparts, a post-mortem is the process of examining a dead body (the outage), gutting it out and trying to understand what caused its demise.
Comment

Arturo Borrero Gonz lez: Rant: Software Engineering in the University of Seville


I'm an IT engineering student at the University of Seville, where there are 3 flavours to choose:
* Computers engineering: mostly focused on hardware
* Software engineering: focused on software
* IT engineering: a mixture of things, including subjects dedicated to security and virtualization

Each of these last a total amount of 4 years (better said: courses).

Software Engineering is mostly the traditional IT engineering and it's what I'm doing.

The first course is almost common to all engineering: algebra, calculus, phyisics, electronics and so on.
You may find these subjects in all IT engineering flavours and also in other traditional engineering
like telecommunications, mechanical, industrial or aeronautics.

In the second year, the subjects tend to be specific for IT engineering: networking, databases, algorithms and so on.
The third and fourth courses are almost fully specific for each flavour of IT engineering.

The problem I've found is in the third year of Software engineering.
We have here subjects like the following:
* requirements engineering
* design and testing
* software process management

All of these are focused in what they consider our biggest possibility in our professional career: the regional government.

It turns out this is not Silicon Valley, and the regional government (Junta de Andaluc a) is in fact the biggest IT player in our region.
They run thousands of servers, networks and digital services both for the public and for internal administrative usage.
The government is known for massively running concrete technologies: Oracle and java. Almost all of the biggest applications are running these technologies.

The problem here is that our subjects are fully headed towards these technologies, also using methodologies
that I consider outdated. They think you are going to work in a classical software factory on the classical software consulting business.
And they do this explicitly: the first day in the 'design & testing' subject we were told by the professor that we are likely going to work in the 'local industry', so we need to learn these technologies and no others.

An example: last week I was given by a professor a VirtualBox (sic) virtual machine running Windows XP (yeah...) just to run Eclipse (for java development) in a controlled environment. They expect the host OS to be Windows as well.
Other example: to this day, no subject which requires the usage of a VCS is using git. They stick to svn.

This is very sad!

The other day, it felt event worse because a RedHat internship was announce in a college mailing list, which explicitly excluded students from Software Engineering.... because all the reasons above. How is this possible? RedHat is a software company!

Let's be constructive. These are some things I would like to see in Software Engineering:
* other software workflows (for example, the linux kernel development model or debian package lifecycle)
* modern free libre open source technologies! python! golang!
* packaging (for example: debian, rpm, docker...)
* new database systems (nosql) or at least no more Oracle (please switch to PostgreSQL or whatever)
* no more java! enough of java!

BTW some time ago I read somewhere that no student should graduate without contributing to a major open source project. I can't agree more.

Rapha&#235;l Hertzog: My Free Software Activities in October 2015

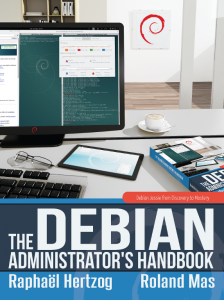
My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS This month I have been paid to work 13.25 hours on Debian LTS. During this time I worked on the following things: I also started a conversation about what paid contributors could work on if they have some spare cycle as the current funding level might allow us to invest some time on work outside of just plain security updates. The Debian Administrator s Handbook I spent quite some time finalizing the Jessie book update, both for the content and for the layout of the printed book. Debian Handbook: cover of the jessie edition Misc Debian work GNOME 3.18. I uploaded a new gnome-shell-timer working with GNOME Shell 3.18 and I filed bugs #800660 and #802480 about an annoying gnome-keyring regression I did multiple test rounds with the Debian maintainers (Dmitry Shachnev, kudos to him!) and the upstream developers (see here and here). Apart from those regressions, I like GNOME 3.18! Python-modules team migration to Git. After the Git migration, and since the team policy now imposes usage of git-dpm on all members, I made some tries with it on the python-django package while pushing version 1.8.5 to experimental. And the least I can say is that I m not pleased with the result. I thus filed 3 bugs summarizing the problems I have with git-dpm: #801666 (no way to set the upstream branch names from within the repository), #801667 (no clean way to merge between packaging branches), #801668 (does not create upstream tag immediately on tarball import). That is on top of other randomly stupid bugs that were already reported like #801548 (does not work with perfectly valid pre-existing upstream tags). Django packaging. I filed bugs on all packages build-depending on python-django that fail to build with Django 1.8 and informed them that I would upload Django 1.8 to unstable in early November (it s done already). Then I fixed python-django-jsonfield myself since Distro Tracker relies on this package. Following this small mass-bug filing, I filed a wishlist bug on devscripts to improve the mass-bug helper script (see #801926). And since I used ratt to rebuild the packages, I filed a wishlist issue on this new tool as well. Tryton 3.6 upgrade. I upgraded my own Tryton installation to version 3.6 and filed bug #803066 because the SysV init script was not working properly. That also reminded me that the DD process of Matthias Behrle (the tryton package maintainer) was stalled due to a bug in the NM infrastructure so I pinged the NM team and we sorted out a way for me to advocate him and get his process going Distro Tracker. I continued my work to refactor the way we handle incoming mail processing (branch people/hertzog/mailprocessing). It s now mostly finished and I need to deploy it in a test environment before being able to roll it out on tracker.debian.org. Thanks See you next month for a new summary of my activities.
No comment Liked this article? Click here. My blog is Flattr-enabled.

Vincent Sanders: I am not a number I am a free man

Once more the NetSurf developers tried to escape from a mysterious village by writing web browser code.

Michael Drake, Daniel Silverstone, Dave Higton and Vincent Sanders at NetSurf Developer workshop
The sixth developer workshop was an opportunity for us to gather together in person to contribute to NetSurf.

We were hosted by Codethink in their Manchester offices which provided a comfortable and pleasant space to work in.

Four developers managed to attend in person from around the UK: Michael Drake, Daniel Silverstone, Dave Higton and Vincent Sanders.

The main focus of the weekends activities was to work on improving our JavaScript implementation. At the previous workshop we had laid the groundwork for a shift to the Duktape JavaScript engine and since then put several hundred hours of time into completing this transition.

During this weekend Daniel built upon this previous work and managed to get DOM events working. This was a major missing piece of implementation which will mean NetSurf will be capable of interpreting JavaScript based web content in a more complete fashion. This work revealed several issues with our DOM library which were also resolved.

We were also able to merge several improvements provided by the Duktape upstream maintainer Sami Vaarala which addressed performance problems with regular expressions which were causing reports of "hangs" on slow processors.

The responsiveness of Sami and the Ducktape project has been a pleasant surprise making our switch to the library look like an increasingly worthwhile effort.

Overall some good solid progress was made on JavaScript support. Around half of the DOM interfaces in the specifications have now been implemented leaving around fifteen hundred methods and properties remaining. There is an aim to have this under the thousand mark before the new year which should result in a generally useful implementation of the basic interfaces.

Once the DOM interfaces have been addressed our focus will move onto the dynamic layout engine necessary to allow rendering of the changing content.

The 3.4 release is proposed to occur sometime early in the new year and depends on getting the JavaScript work to a suitable stable state.

Dave joined us for the first time, he was principally concerned with dealing with bugs and the bug tracker. It was agreeable to have a new face at the meeting and some enthusiasm for the RISC OS port which has been lacking an active maintainer for some time.

The turnout for this workshop was the same as the previous one and the issues raised then are still true. We still have a very small active core team who can commit only limited time which is making progress very slow and are lacking significant maintenance for several frontends.

Overall we managed to pack 16 hours of work into the weekend and addressed several significant problems.

Johannes Schauer: Let's Encrypt with Pound on Debian

TLDR: mister-muffin.de (and all its subdomains), bootstrap.debian.net and binarycontrol.debian.net are now finally signed by "Let's Encrypt Authority X1" \o/ I just tried out the letsencrypt client Debian packages prepared by Harlan Lieberman-Berg which can be found here: My server setup uses Pound as a reverse proxy in front of a number of LXC based containers running the actual services. Furthermore, letsencrypt only supports Nginx and Apache for now, so I had to manually setup things anyways. Here is how. After installing the Debian packages I built from above git repositories, I ran the following commands:
$ mkdir -p letsencrypt/etc letsencrypt/lib letsencrypt/log
$ letsencrypt certonly --authenticator manual --agree-dev-preview \
    --server https://acme-v01.api.letsencrypt.org/directory --text \
    --config-dir letsencrypt/etc --logs-dir letsencrypt/log \
    --work-dir letsencrypt/lib --email josch@mister-muffin.de \
    --domains mister-muffin.de --domains blog.mister-muffin.de \
    --domains [...]
I created the letsencrypt directory structure to be able to run letsencrypt as a normal user. Otherwise, running this command would require access to /etc/letsencrypt and others. Having to set this up and pass all these parameters is a bit bothersome but there is an upstream issue about making this easier when using the "certonly" option which in princible should not require superuser privileges. The --server option is necessary for now because "Let's Encrypt" is still in beta and one needs to register for it. Without the --server option one will get an untrusted certificate from the "happy hacker fake CA". The letsencrypt program will then ask me for my agreement to the Terms of Service and then, for each domain I specified with the --domains option present me the token content and the location under each domain where it expects to find this content, respectively. This looks like this each time:
-------------------------------------------------------------------------------
NOTE: The IP of this machine will be publicly logged as having requested this
certificate. If you're running letsencrypt in manual mode on a machine that is
not your server, please ensure you're okay with that.
Are you OK with your IP being logged?
-------------------------------------------------------------------------------
(Y)es/(N)o: Y
Make sure your web server displays the following content at
http://mister-muffin.de/.well-known/acme-challenge/XXXX before continuing:
 "header":  "alg": "RS256", "jwk":  "e": "AQAB", "kty": "RSA", "n": "YYYY" , "payload": "ZZZZ", "signature": "QQQQ" 
Content-Type header MUST be set to application/jose+json.
If you don't have HTTP server configured, you can run the following
command on the target server (as root):
mkdir -p /tmp/letsencrypt/public_html/.well-known/acme-challenge
cd /tmp/letsencrypt/public_html
echo -n ' "header":  "alg": "RS256", "jwk":  "e": "AQAB", "kty": "RSA", "n": "YYYY" , "payload": "ZZZZ", "signature": "QQQQ" ' > .well-known/acme-challenge/XXXX
# run only once per server:
$(command -v python2   command -v python2.7   command -v python2.6) -c \
"import BaseHTTPServer, SimpleHTTPServer; \
SimpleHTTPServer.SimpleHTTPRequestHandler.extensions_map =  '': 'application/jose+json' ; \
s = BaseHTTPServer.HTTPServer(('', 80), SimpleHTTPServer.SimpleHTTPRequestHandler); \
s.serve_forever()" 
Press ENTER to continue
For brevity I replaced any large base64 encoded chunks of the messages with YYYY, ZZZZ and QQQQ. The token location is abbreviated with XXXX. After temporarily stopping Pound on my webserver I created the directory /tmp/letsencrypt/public_html/.well-known/acme-challenge and then opened two shells on my server, both at /tmp/letsencrypt/public_html. In one, I kept a tiny HTTP server running (like the suggested Python SimpleHTTPServer which will also work if one has Python installed). In the other I copy pasted the echo line that the letsencrypt program suggested me to run. I had to copypaste that echo command for each domain I wanted to verify. This could easily be automated, so I filed an issue about this with upstream. It seems that the letsencrypt servers query each of these tokens twice: once directly each time after having hit enter after seeing the message above and another time once all tokens are in place. At the end of this ordeal I get:
2015-11-04 11:12:18,409:WARNING:letsencrypt.client:Non-standard path(s), might not work with crontab installed by your operating system package manager
IMPORTANT NOTES:
 - If you lose your account credentials, you can recover through
   e-mails sent to josch@mister-muffin.de.
 - Congratulations! Your certificate and chain have been saved at
   letsencrypt/etc/live/mister-muffin.de/fullchain.pem. Your cert will
   expire on 2016-02-02. To obtain a new version of the certificate in
   the future, simply run Let's Encrypt again.
 - Your account credentials have been saved in your Let's Encrypt
   configuration directory at letsencrypt/etc. You should make a
   secure backup of this folder now. This configuration directory will
   also contain certificates and private keys obtained by Let's
   Encrypt so making regular backups of this folder is ideal.
I can now scp the content of letsencrypt/etc/live/mister-muffin.de/* to my server. Unfortunately, Pound (and also my ejabberd XMPP server) requires the private key to be in the same file as the certificate and the chain, so on the server I also had to do:
cat /etc/ssl/private/privkey.pem /etc/ssl/private/fullchain.pem > /etc/ssl/private/private_fullchain.pem
And edit the Pound config to use /etc/ssl/private/private_fullchain.pem. But that's all, folks! EDIT It seems that manually copying over the echo commands as I described above is not necessary. Instead of using the certonly plugin, I can use the webroot plugin. That plugin takes the --webroot-path option and will copy the tokens to there. Since my webroot is on a remote machine, I could just mount it locally via sshfs and pass the mountpoint as --webroot-path. That I didn't realize that the webroot plugin does what I want (and not the certonly plugin) can easily be explained by the only documentation of the webroot plugin in the help output and the man page generated from it being "Webroot Authenticator" which is not very helpful. Another user seems to have run into similar problems. Better documenting the plugins so that these situations can be prevented in the future is tracked in this upstream bug.

Julien Danjou: Gnocchi 1.3.0 release

Finally, Gnocchi 1.3.0 is out. This is our final release, more or less matching the OpenStack 6 months schedule, that concludes the Liberty development cycle.
This release was supposed to be released a few weeks earlier, but our integration test got completely blocked for several days just the week before the OpenStack Mitaka summit. New website We build a new dedicated website for Gnocchi at gnocchi.xyz. We want to promote Gnocchi outside of the OpenStack bubble, as it a useful timeseries database on its own that can work without the rest of the stack. We'll try to improve the documentation. If you're curious, feel free to check it out and report anything you miss! The speed bump Obviously, if it was a bug in Gnocchi that we have hit, it would have been quick to fix. However, we found a nasty bug in Swift caused by the evil monkey-patching of Eventlet (once again) blended with a mixed usage of native threads and Eventlet threads in Swift. Shake all of that, and you got yourself pretty race conditions when using the Keystone middleware authentication. In the meantime, we disabled Swift multi-threading by using mod_wsgi instead of Eventlet in devstack. New features So what's new in this new shiny release? A few interesting things: And that's all we did in the last couple of months. We have a lot of things on the roadmap that are pretty exciting, and I'll sure talk about them in the next weeks.

Craig Sanders: Part-time sysadmin work in Melbourne?

I m looking for a part-time Systems Administration role in Melbourne, either in a senior capacity or happy to assist an existing sysadmin or development team. I m mostly recovered from a long illness and want to get back to work, on a part-time basis (up to 3 days per week). Preferably in the City or Inner North near public transport. I can commute further if there is scope for telecommuting once I know your systems and people, and trust has been established. If you have a suitable position available or know of someone who does, please contact me by email. Why hire me? Pros: Cons: Full CV available on request. I m in the top few percent on ServerFault and Unix & Linux StackExchange sites if you want to get a preview of my problem-solving and technical communication skills, see my profile at: http://unix.stackexchange.com/users/7696/cas?tab=profile CV Summary: Systems Administrator and Programmer with extensive exposure to a wide variety of hardware and software systems. Excellent fault-diagnosis, problem-solving and system design skills. Strong technical/user support background. Ability to communicate technical concepts clearly to non-IT people. Significant IT Management and supervisory experience. Particular Skills Part-time sysadmin work in Melbourne? is a post from: Errata

3 November 2015

Daniel Pocock: How much of Linux will be illegal in the UK?

This week I've been in the UK again, giving a talk about Lumicall and JSCommunicator in Manchester last night and a talk about Free Real-Time Communications at the mini-DebConf in Cambridge on the weekend of 7-8 November. An interesting backdrop to these activities has been a national debate about Internet privacy. The UK Government and police are demanding laws to mandate back doors in all communications products and services. It leaves me wondering about a range of issues:
  • Will overzealous UK police, reknowned for singling out and bullying people who don't conform with their idea of normality, start taking a more sinister attitude to people using software like Linux? For example, if airport security asks to inspect a laptop and doesn't see the familiar Windows or Mac OS desktop, will the owner of the laptop be delayed or told to leave it behind? Some people may feel this is extreme, but workers in these roles are known for taking initiative in their own special way, such as the infamous baby pat-down. If the owner of a Linux laptop is a Muslim, like the Texas schoolboy recently arrested because his clock looks suspicious to the untrained eye of a policeman, the chances of a rough encounter with authority probably rise even further.
  • Will developers still be able to use technologies like PGP and ZRTP in the UK? Will PGP key-signing parties become illegal or have to be held 20 miles offshore on a boat like the legendary pirate radio stations of the sixties?
  • Will Linux distributions such as Debian and Fedora have to avoid distributing packages such as Enigmail?
  • Will updates to Android and iOS on smartphones seek to automatically disable or remove apps like Lumicall?
  • Even if a user chooses a secure app like Lumicall for communication, will the vendor of the operating system be required to provide alternative ways to monitor the user, for example, by intercepting audio before it is encrypted by the app?
  • Without strong encryption algorithms, digital signatures will no longer be possible either and it will be impossible for software vendors to securely distribute new versions of their software.
  • Why should the police be the only workers to have their job done for them by Internet snooping? Why shouldn't spouses have a right to all their partner's communications to periodically verify they are not cheating and putting themselves at risk of diseases? Why shouldn't employers be able to check on employee's private communications and home computers to help prevent leaks of customer data? Why shouldn't the NHS be able to go through people's garbage to monitor what they eat given the WHO warning that bacon is more likely to kill you than a terrorist?
  • While the authorities moan about the internet being a "safe" place for terrorists and paedophiles, what is their real motivation for trying to bring in these new laws, even when their best technical advisors must surely be telling them about the risks and negative consequences for compatibility of UK systems in a global Internet? If the terrorist scare story is not so credible, is it more likely they are seeking to snoop on people who may not be paying taxes or to maintain the upper hand over rival political parties like the Greens and the UKIP in a time of prolonged and increasingly punitive austerity?
  • Australia already introduced similar laws a few weeks ago, despite widespread criticism from around the world. With cricket and rugby now over, is the UK just looking to go one up on Australia in the game of snooping?
Island mentality in the Internet age Politics aside, what would this mean from a technical perspective? The overwhelming consensus among experts is that secure technology that people use and expect in many other parts of the world, including the US, simply won't be compatible with the products and services that UK residents will be permitted to use. Bigger companies like Google and Apple may be able to offer differentiated versions of their services for the UK but smaller companies or companies who have built their reputation on technical excellence simply won't be able or willing to offer crippled versions of their products with backdoors for the UK. The UK's island geography will become a metaphor for its relationship with the global marketplace. The first thing to take note of is that encryption and authentication are closely related. Public-key cryptography, for example, simply swaps the public key and private key when being used to authenticate instead of encrypt. An effective and wide-reaching legal ban on encryption would also potentially prohibit the algorithms used for authentication. Many methods of distributing software, including packages distributed through Linux distributions or apps distributed through the Google Play store are authenticated with such algorithms. This is often referred to as a digital signature. Digital signatures help ensure that software is not corrupted, tampered with by hackers or infected by viruses when it is transmitted and stored in the public Internet. To correctly implement these mechanisms for installing software safely, every device running an operating system such as Debian, Ubuntu, Fedora or Android needs to include some software modules implementing the algorithms. In Linux, for example, I'm referring to packages like GnuPG, OpenSSL and GnuTLS. Without these components, it would be hard or even impossible for developers in the UK to contribute or publish new versions of their software. Users of the software would not be able to securely receive vital updates to their systems. An opportunity for free software? Some people say that any publicity can be good publicity. Now the Government has put the ball into play, people promoting secure solutions based on free software have an opportunity to participate in the debate too. While laws may or may not change, principles don't. It is a perfect time to remind users that many of the principles of software freedom were written down many years ago, before the opportunity for mass surveillance came into existence. These principles remain relevant to this day. The experts who developed these principles back then are also far more likely to offer insights and trustworthy solutions for the road ahead. If you'd like to discuss these issues or ask questions, please join the Free-RTC mailing list.

Petter Reinholdtsen: Is Pentagon deciding the Norwegian negotiating position on Internet governance?

In Norway, all government offices are required by law to keep a list of every document or letter arriving and leaving their offices. Internal notes should also be documented. The document list (called a mail journal - "postjournal" in Norwegian) is public information and thanks to the Norwegian Freedom of Information Act (Offentleglova) the mail journal is available for everyone. Most offices even publish the mail journal on their web pages, as PDFs or tables in web pages. The state-level offices even have a shared web based search service (called Offentlig Elektronisk Postjournal - OEP) to make it possible to search the entries in the list. Not all journal entries show up on OEP, and the search service is hard to use, but OEP does make it easier to find at least some interesting journal entries . In 2012 I came across a document in the mail journal for the Norwegian Ministry of Transport and Communications on OEP that piqued my interest. The title of the document was "Internet Governance and how it affects national security" (Norwegian: "Internet Governance og p virkning p nasjonal sikkerhet"). The document date was 2012-05-22, and it was said to be sent from the "Permanent Mission of Norway to the United Nations". I asked for a copy, but my request was rejected with a reference to a legal clause said to authorize them to reject it (offentleglova 20, letter c) and an explanation that the document was exempt because of foreign policy interests as it contained information related to the Norwegian negotiating position, negotiating strategies or similar. I was told the information in the document related to the ongoing negotiation in the International Telecommunications Union (ITU). The explanation made sense to me in early January 2013, as a ITU conference in Dubay discussing Internet Governance (World Conference on International Telecommunications - WCIT-12) had just ended, reportedly in chaos when USA walked out of the negotiations and 25 countries including Norway refused to sign the new treaty. It seemed reasonable to believe talks were still going on a few weeks later. Norway was represented at the ITU meeting by two authorities, the Norwegian Communications Authority and the Ministry of Transport and Communications. This might be the reason the letter was sent to the ministry. As I was unable to find the document in the mail journal of any Norwegian UN mission, I asked the ministry who had sent the document to the ministry, and was told that it was the Deputy Permanent Representative with the Permanent Mission of Norway in Geneva. Three years later, I was still curious about the content of that document, and again asked for a copy, believing the negotiation was over now. This time I asked both the Ministry of Transport and Communications as the receiver and asked the Permanent Mission of Norway in Geneva as the sender for a copy, to see if they both agreed that it should be withheld from the public. The ministry upheld its rejection quoting the same law reference as before, while the permanent mission rejected it quoting a different clause (offentleglova 20 letter b), claiming that they were required to keep the content of the document from the public because it contained information given to Norway with the expressed or implied expectation that the information should not be made public. I asked the permanent mission for an explanation, and was told that the document contained an account from a meeting held in the Pentagon for a limited group of NATO nations where the organiser of the meeting did not intend the content of the meeting to be publicly known. They explained that giving me a copy might cause Norway to not get access to similar information in the future and thus hurt the future foreign interests of Norway. They also explained that the Permanent Mission of Norway in Geneva was not the author of the document, they only got a copy of it, and because of this had not listed it in their mail journal. Armed with this knowledge I asked the Ministry to reconsider and asked who was the author of the document, now realising that it was not same as the "sender" according to Ministry of Transport and Communications. The ministry upheld its rejection but told me the name of the author of the document. According to a government report the author was with the Permanent Mission of Norway in New York a bit more than a year later (2014-09-22), so I guessed that might be the office responsible for writing and sending the report initially and asked them for a copy but I was obviously wrong as I was told that the document was unknown to them and that the author did not work there when the document was written. Next, I asked the Permanent Mission of Norway in Geneva and the Foreign Ministry to reconsider and at least tell me who sent the document to Deputy Permanent Representative with the Permanent Mission of Norway in Geneva. The Foreign Ministry also upheld its rejection, but told me that the person sending the document to Permanent Mission of Norway in Geneva was the defence attach with the Norwegian Embassy in Washington. I do not know if this is the same person as the author of the document. If I understand the situation correctly, someone capable of inviting selected NATO nations to a meeting in Pentagon organised a meeting where someone representing the Norwegian defence attach in Washington attended, and the account from this meeting is interpreted by the Ministry of Transport and Communications to expose Norways negotiating position, negotiating strategies and similar regarding the ITU negotiations on Internet Governance. It is truly amazing what can be derived from mere meta-data. I wonder which NATO countries besides Norway attended this meeting? And what exactly was said and done at the meeting? Anyone know?

2 November 2015

Pau Garcia i Quiles: FOSDEM Desktops DevRoom 2016 Call for Participation

FOSDEM is one of the largest gatherings of Free Software contributors in the world and happens each February in Brussels (Belgium, Europe). One of the tracks will be the Desktops DevRoom (formerly known as CrossDesktop DevRoom ), which will host Desktop-related talks. We are now inviting proposals for talks about Free/Libre/Open-source Software on the topics of Desktop development, Desktop applications and interoperability amongst Desktop Environments. This is a unique opportunity to show novel ideas and developments to a wide technical audience. Topics accepted include, but are not limited to: Talks can be very specific, such as the advantages/disadvantages of development with Qt on Wayland over X11/Mir; or as general as predictions for the fusion of Desktop and web in 5 years time. Topics that are of interest to the users and developers of all desktop environments are especially welcome. The FOSDEM 2015 schedule might give you some inspiration. Submissions Please include the following information when submitting a proposal: How to submit All submissions are made in the Pentabarf event planning tool: https://penta.fosdem.org/submission/FOSDEM16 When submitting your talk, make sure to select the Desktops devroom as the Track . Otherwise your talk will not be even considered for any devroom. If you already have a Pentabarf account from a previous year, even if your talk was not accepted, please reuse it. Create an account if, and only if, you don t have one from a previous year. If you have any issues with Pentabarf, please contact pgquiles at elpauer dot org. Deadline The deadline for submissions is December 6th 2015. FOSDEM will be held on the weekend of January 30th and 31st 2015 and the Desktops DevRoom will take place on Sunday, January 31st 2015. We will contact every submitter with a yes or no before December 18th 2015. Recording permission The talks in the Desktops devroom will be audio and video recorded, and possibly streamed live too. By submitting a proposal you consent to be recorded and agree to license the content of your talk under a Creative Commons (CC-BY) license. If you want us to stop the recording in the Q & A part (should you have one), please tell us. We can do that but only for the Q & A part. More information The official communication channel for the Desktops DevRoom is its mailing list desktops-devroom@lists.fosdem.org. Use this page to manage your subscription: https://lists.fosdem.org/listinfo/desktops-devroom Organization The Desktops DevRoom 2016 is managed by a team representing the most notable open desktops: If you want to join the team, please contact pgquiles at elpauer dot org

Julien Danjou: OpenStack Summit Mitaka from a Telemetry point of view

Last week I was in Tokyo, Japan for the OpenStack Summit, discussing the new Mitaka version that will be released in 6 months. I've attended the summit mainly to discuss and follow-up new developments on Ceilometer, Gnocchi, Aodh and Oslo. It has been a pretty good week and we were able to discuss and plan a few interesting things. Below are what I found remarkable during this summit concerning those projects. Distributed lock manager
I did not attend this session, but I need to write something about it. See, when working in a distributed environment like OpenStack, it's almost obvious that sooner or later you end up needing a distributed lock mechanism. It started to be pretty obvious and a serious problem for us 2 years ago in Ceilometer. Back then, we proposed the service-sync blueprint and talked about it during the OpenStack Icehouse Design Summit in Hong-Kong. The session at that time was a success, and in 20 minutes I convinced everyone it was the good thing to do. The night following the session, we picked a named, Tooz, to name this new library. It was the first time I met Joshua Harlow, which became one of the biggest Tooz contributor since then. For the following months, we tried to move the lines in OpenStack. It was very hard to convince people that it was the solution to their problem. Most of the time, they did not seem to grasp the entirety of what was at stake. This time, it seems that we managed to convince everyone that a DLM is indeed needed. Joshua wrote an extensive specification called Chronicle of a DLM, which ended up being discussed and somehow adopted during that session in Tokyo. So yes, Tooz will be the weapon of choice for OpenStack. It will avoid a hard requirement on any DLM solution directly. The best driver right now is the ZooKeeper one, but it'll still be possible for operators to use e.g. Redis. This is a great achievement for us, after spending years trying to fix features such as the Nova service group subsystem and seeing our proposals postponed forever. (If you want to know more, LWN.net has a great article about that session.) Telemetry team name
With the new projects launched this last year, Aodh & Gnocchi, in parallel of the old Ceilometer, plus the change from programs to Big Tent in OpenSack, the team is having an identity issue. Being referred to as the "Ceilometer team" is not really accurate, as some of us only work on Aodh or on Gnocchi. So after discussing that, I proposed to rename the team to Telemetry instead. We'll see how it goes. Alarms
The first session was about alarms and the Aodh project. It turns out that the project is in pretty good shape, but probably need some more love, which I hope I'll be able to provide in the next months. The need for a new aodhclient based on the technologies we recently used building gnocchiclient has been reasserted, so we might end up working on that pretty soon. The Tempest support also needs some improvement, and we have a plan to enhance that. Data visualisation
We got David Lyle in this session, the Project Technical Leader for Horizon. It was an interesting discussion. It used to be technically challenging to draw charts from the data Ceilometer collects, but it's now very easy with Gnocchi and its API. While the technical side is resolved, the more political and user experience side of was to draw and how was discussed at length. We don't want to make people think that Ceilometer and Gnocchi are a full monitoring solution, so there's some precaution to take. Other than that, it would be pretty cool to have view of the data in Horizon. Rolling upgrade
It turns out that Ceilometer has an architecture that makes it easy to have rolling upgrade. We just need to write a proper documentation explaining how to do it and in which order the services should be upgraded. Ceilometer splitting
The split of the alarm feature of Ceilometer in its own project Aodh in the last cycle was a great success for the whole team. We want to split other pieces of Ceilometer, as they make sense on their own, makes it easier to manage. They are also some projects that want to use them without the whole stack, so that's a good idea to make it happen. CloudKitty & Gnocchi
I attended the 2 sessions that were allocated to CloudKitty. It was pretty interesting as they want to simplify their architecture and leverage what Gnocchi provides. I proposed my view of the project architecture and how they could leverage the more of Gnocchi to retrieve and store data. They want to go in that direction though it's a large amount of work and refactoring on their side, so it'll take time. We also need to enhance the support of extension for new resources in Gnocchi, and that's something I hope I'll work on in the next months. Overall, this summit was pretty good and I got a tremendous amount of good feedback on Gnocchi. I again managed to get enough ideas and tasks to tackle for the next 6 months. It really looks interesting to see where the whole team will go from that. Stay tuned!

Rapha&#235;l Hertzog: The Debian Administrator s Handbook Updated for Debian 8 Jessie

Debian Handbook: cover of the jessie editionLater than what I hoped, I m still pleased to be able to announce the availability of the Jessie version of the Debian Administrator s Handbook. Check out the official announce with its special launch offer (a 15% discount on the paperback until Sunday!). The book s preface is co-signed by the last three Debian Project Leaders and it has been available through debian.org for a few months now. We are glad to have so much recognition for the hard work we have put in the book over the years. Thank you all and I hope you will enjoy this new edition! The work is not yet entirely over us for Roland and I, since we re now busy updating the French translation of the book. It should be available in the upcoming weeks. Keep posted!

3 comments Liked this article? Click here. My blog is Flattr-enabled.

Next.

Previous.


