Search Results: "reg"

24 September 2014

Laura Arjona: 10 short steps to contribute translations to free software for Android

This small guide assumes that you know how to create a public repository with git (or other version control system). Maybe some projects use other VCS, Subversion or whatever; the process would be similar although the commands will be different of course. If you don t want to use any VCS, you can just download the corresponding file, translate it, and send it by email or to the BTS of the project, but the commands required are very easy and you ll see soon that using git (or any VCS) is quite comfortable and less scary than what it seems. So, you were going to recommend a nice app that you use or found in F-Droid to your friend, but she does not understand English. Why not translating the app for her? And for everybody? It s a job that can be done in 15 minutes or so (Android apps have very short strings, few menus, and so). Let s go! 1.- Search the app in the F-Droid website You can do it going to the URL: https://f-droid.org/repository/browse/?fdfilter=wordofappname Example: https://f-droid.org/repository/browse/?fdfilter=pomodoro Then, open the details of the app, and learn where s the source code. 2.- Clone the source code If you have an account in that forge, fork/clone the project into your account, and then, clone your fork/clone in local. If you haven t got an account in that forge, clone the project in local. git clone URLofTheProjectOrYourClone 3.- In local, create a new branch, and checkout to it. cd nameofrepo git checkout -b Spanish 4.- Then, copy the /res/values folder into res/values-XX folder (where XX is your language code) cp ./res/values /res/values-es -R 5.- Translate Edit the strings.xml file that is in the res/values-XX folder, and change the English strings to your language (respect the XML format). 6.- Translate other files, or delete them If there are more files in that folder (e.g. arrays.xml ), review them to know if they have translatable strings. If yes, translate them. If not, delete the files. 7.- Commit When you are finished, commit your changes: git add res/values-es/* git commit -a (Message can be Spanish translation or so) 8.- Push your changes to your public repo If you didn t create a public clone of the repo in your forge, create a public repo and push your local stuff into there. git push --all 9.- Request a merge to the original repo (Using the web interface of the forge, if it is the same for the original repo and your clone, or sending an email or creating an issue and providing the URL of your repo). For example, open a new issue in the project s BTS Title: Spanish translation available for merging Body: Hi everybody. Thanks for your work in "nameofapp". I have completed a Spanish translation, it's available for review/merge in the Spanish branch of my repo: https://urlofyourclone Best regards 10.- Congratulations! Translations are new features, and having a new feature in your app for free is a great thing, so probably the app developer(s) will merge your translation soon. Share your joy with your friends, so they begin to use the app you translated, and maybe become translators too! Comments? You can comment on this post in this pump.io thread.
Filed under: Tools, Writings (translations) Tagged: Android, Contributing to libre software, English, Free Software, libre software, translations

Matthew Garrett: My free software will respect users or it will be bullshit

I had dinner with a friend this evening and ended up discussing the FSF's four freedoms. The fundamental premise of the discussion was that the freedoms guaranteed by free software are largely academic unless you fall into one of two categories - someone who is sufficiently skilled in the arts of software development to examine and modify software to meet their own needs, or someone who is sufficiently privileged[1] to be able to encourage developers to modify the software to meet their needs.

The problem is that most people don't fall into either of these categories, and so the benefits of free software are often largely theoretical to them. Concentrating on philosophical freedoms without considering whether these freedoms provide meaningful benefits to most users risks these freedoms being perceived as abstract ideals, divorced from the real world - nice to have, but fundamentally not important. How can we tie these freedoms to issues that affect users on a daily basis?

In the past the answer would probably have been along the lines of "Free software inherently respects users", but reality has pretty clearly disproven that. Unity is free software that is fundamentally designed to tie the user into services that provide financial benefit to Canonical, with user privacy as a secondary concern. Despite Android largely being free software, many users are left with phones that no longer receive security updates[2]. Textsecure is free software but the author requests that builds not be uploaded to third party app stores because there's no meaningful way for users to verify that the code has not been modified - and there's a direct incentive for hostile actors to modify the software in order to circumvent the security of messages sent via it.

We're left in an awkward situation. Free software is fundamental to providing user privacy. The ability for third parties to continue providing security updates is vital for ensuring user safety. But in the real world, we are failing to make this argument - the freedoms we provide are largely theoretical for most users. The nominal security and privacy benefits we provide frequently don't make it to the real world. If users do wish to take advantage of the four freedoms, they frequently do so at a potential cost of security and privacy. Our focus on the four freedoms may be coming at a cost to the pragmatic freedoms that our users desire - the freedom to be free of surveillance (be that government or corporate), the freedom to receive security updates without having to purchase new hardware on a regular basis, the freedom to choose to run free software without having to give up basic safety features.

That's why projects like the GNOME safety and privacy team are so important. This is an example of tying the four freedoms to real-world user benefits, demonstrating that free software can be written and managed in such a way that it actually makes life better for the average user. Designing code so that users are fundamentally in control of any privacy tradeoffs they make is critical to empowering users to make informed decisions. Committing to meaningful audits of all network transmissions to ensure they don't leak personal data is vital in demonstrating that developers fundamentally respect the rights of those users. Working on designing security measures that make it difficult for a user to be tricked into handing over access to private data is going to be a necessary precaution against hostile actors, and getting it wrong is going to ruin lives.

The four freedoms are only meaningful if they result in real-world benefits to the entire population, not a privileged minority. If your approach to releasing free software is merely to ensure that it has an approved license and throw it over the wall, you're doing it wrong. We need to design software from the ground up in such a way that those freedoms provide immediate and real benefits to our users. Anything else is a failure.

(title courtesy of My Feminism will be Intersectional or it will be Bullshit by Flavia Dzodan. While I'm less angry, I'm solidly convinced that free software that does nothing to respect or empower users is an absolute waste of time)

[1] Either in the sense of having enough money that you can simply pay, having enough background in the field that you can file meaningful bug reports or having enough followers on Twitter that simply complaining about something results in people fixing it for you

[2] The free software nature of Android often makes it possible for users to receive security updates from a third party, but this is not always the case. Free software makes this kind of support more likely, but it is in no way guaranteed.

comment count unavailable comments

23 September 2014

Steve Kemp: Waiting for features upstream

I (grudgingly) use the Calibre e-book management software to handle my collection of books, and copy them over to my kindle-toy. One thing that has always bothered me was the fact that when books are imported their ratings are too. If I receive a small sample of ebooks from a friend their ratings are added to my collections. I've always regarded ratings as things personal to me, rather than attributes of a book itself; as my tastes might not match yours, and vice-versa. On that basis the last time I was importing a small number of books and getting annoyed at having to manually reset all the imported ratings I decided to do something about it. I started hacking and put together a simple Calibre plugin to automatically zero ratings when books are imported to the collection (i.e. set the rating to be zero). Sadly this work wasn't painless, despite the small size, as an unfortunate bug in Calibre meant my plugin method wasn't called. Happily Kovid Goyal helped me work through the problem, and he committed a fix that will be in the next Calibre release. For the moment I'm using today's git-snapshot and it works well. Similarly I've recently started using extended file attributes to store metadata on my desktop system. Unfortunately the GNU findutils package doesn't allow you to do the obvious thing:
$ find ~/foo -xattr user.comment
/home/skx/foo/bar/t.txt
/home/skx/foo/bar/xc.txt
/home/skx/foo/bar/x.txt
There are several xattr patches floating around, but I had to bundle my own in debian/patches to get support for finding files that have particular attribute names. Maybe one day extended attributes will be taken seriously. (rsync, cp, etc will preserve them. I'm hazy on the compatibility with tar, but most things seem to be working.)

Gunnar Wolf: Can printing be so hard

Dear lazyweb, I am tired of finding how to get my users to happily print again. Please help. Details follow. Several years ago, I configured our Institute's server to provide easy, nifty printing support for all of our users. Using Samba+CUPS, I automatically provided drivers to Windows client machines, integration with our network user scheme (allowing for groups authorization That means, you can only print in your designated printer), flexible printer management (i.e. I can change printers on the server side without the users even noticing Great when we get new hardware or printers get sent to repairs!)... Then, this year the people in charge of client machines in the institute decided to finally ditch WinXP licenses and migrate to Windows 7. Sweet! How can it hurt? Oh, it can hurt. Terribly. Windows 7 uses a different driver model, and after quite a bit of hair loss, I was not able to convince Samba to deliver drivers to Win7 (FWIW, I think we are mostly using 64 bit versions). Not only that, it also barfs when we try to install drivers manually and print to a share. And of course, it barfs in the least useful way, so it took me quite a bit of debugging and Web reading to find out it was not only my fault. So, many people have told me that Samba (or rather, Windows-type networking) is no longer regarded as a good idea for printing. The future is here, and it's called IPP. And it is simpler, because Windows can talk directly with CUPS! Not only that, CUPS allows me to set valid users+groups to each printer. So, what's there to lose? Besides time, that is. It took me some more hair pulling to find out that Windows 7 is shipped by default (at least in the version I'm using) with the Internet Printing Server feature disabled. Duh. OK, enable it, and... Ta-da! It works with CUPS! Joy, happiness! Only that... It works only when I use it with no authentication. Windows has an open issue, with its corresponding hotfix even, because Win7 and 2008 fail to provide user credentials to print servers... So, yes, I can provide site-wide printing capabilities, but I still cannot provide per-user or per-group authorization and accounting, which are needed here. I cannot believe this issue cannot be solved under Windows 7, several years after it hit the market. Or am I just too blunt and cannot find an obvious solution? Dear lazyweb, I did my homework. Please help me!

Dirk Eddelbuettel: RcppArmadillo 0.4.450.1.0

Continuing with his standard pace of approximately one new version per month, Conrad released a new minor release of Armadillo a few days ago. As before, I had created a GitHub-only pre-release which was tested against all eighty-seven (!!) CRAN dependents of our RcppArmadillo package and then uploaded RcppArmadillo 0.4.450.0 to CRAN. The CRAN maintainers pointed out that under the R-development release, a NOTE was issued concerning the C-library's rand() call. This is a pretty new NOTE, but it means using the (sometimes poor quality) rand() generator is now a no-no. Now, Armadillo being as robustly engineered as it is offers a new random number generator based on C++11 as well as a fallback generator for those unfortunate enough to live with an older C++98 compiler. (I would like to note here that I find Conrad's continued support for both C++11, offering very useful modern language idioms, as well as the fallback code for continued deployment and usage by those constrained in their choice of compilers rather exemplary --- because contrary to what some people may claim, it is not a matter of one or the other. C++ always was, and continues to be, a multi-paradigm language which can be supported easily by several standard. But I digress...) In any event, one cannot argue with CRAN about their prescription of a C++98 compiler. So Conrad and I discussed this over email, and came up with a scheme where a user-package (such as RcppArmadillo) can provide an alternate generator which Armadillo then deploys. I implemented a first solution which was then altered / reflected by Conrad in a revised version 4.450.1 of Armadillo. I packaged, and now uploaded, that version as RcppArmadillo 0.4.450.1.0 to both CRAN and into Debian. Besides the RNG change already discussed, this release brings a few smaller changes from the Armadillo side. These are detailed below in the extract from the NEWS file. On the RcppArmadillo side, we now have support for pkgKitten which is both very exciting and likely the topic of another blog post with an example of creating an RcppArmadillo package that purrs. In the process, I overhauled and polished how new packages are created by RcppArmadillo.package.skeleton(). An upcoming blog post may provide an example.
Changes in RcppArmadillo version 0.4.450.1.0 (2014-09-21)
  • Upgraded to Armadillo release Version 4.450.1 (Spring Hill Fort)
    • faster handling of matrix transposes within compound expressions
    • expanded symmatu()/symmatl() to optionally disable taking the complex conjugate of elements
    • expanded sort_index() to handle complex vectors
    • expanded the gmm_diag class with functions to generate random samples
  • A new random-number implementation for Armadillo uses the RNG from R as a fallback (when C++11 is not selected so the C++11-based RNG is unavailable) which avoids using the older C++98-based std::rand
  • The RcppArmadillo.package.skeleton() function was updated to only set an "Imports:" for Rcpp, but not RcppArmadillo which (as a template library) needs only LinkingTo:
  • The RcppArmadillo.package.skeleton() function will now prefer pkgKitten::kitten() over package.skeleton() in order to create a working package which passes R CMD check.
  • The pkgKitten package is now a Suggests:
  • A manual page was added to provide documentation for the functions provided by the skeleton package.
  • A small update was made to the package manual page.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

22 September 2014

Gunnar Wolf: One month later: How is the set of Debian keyrings faring?

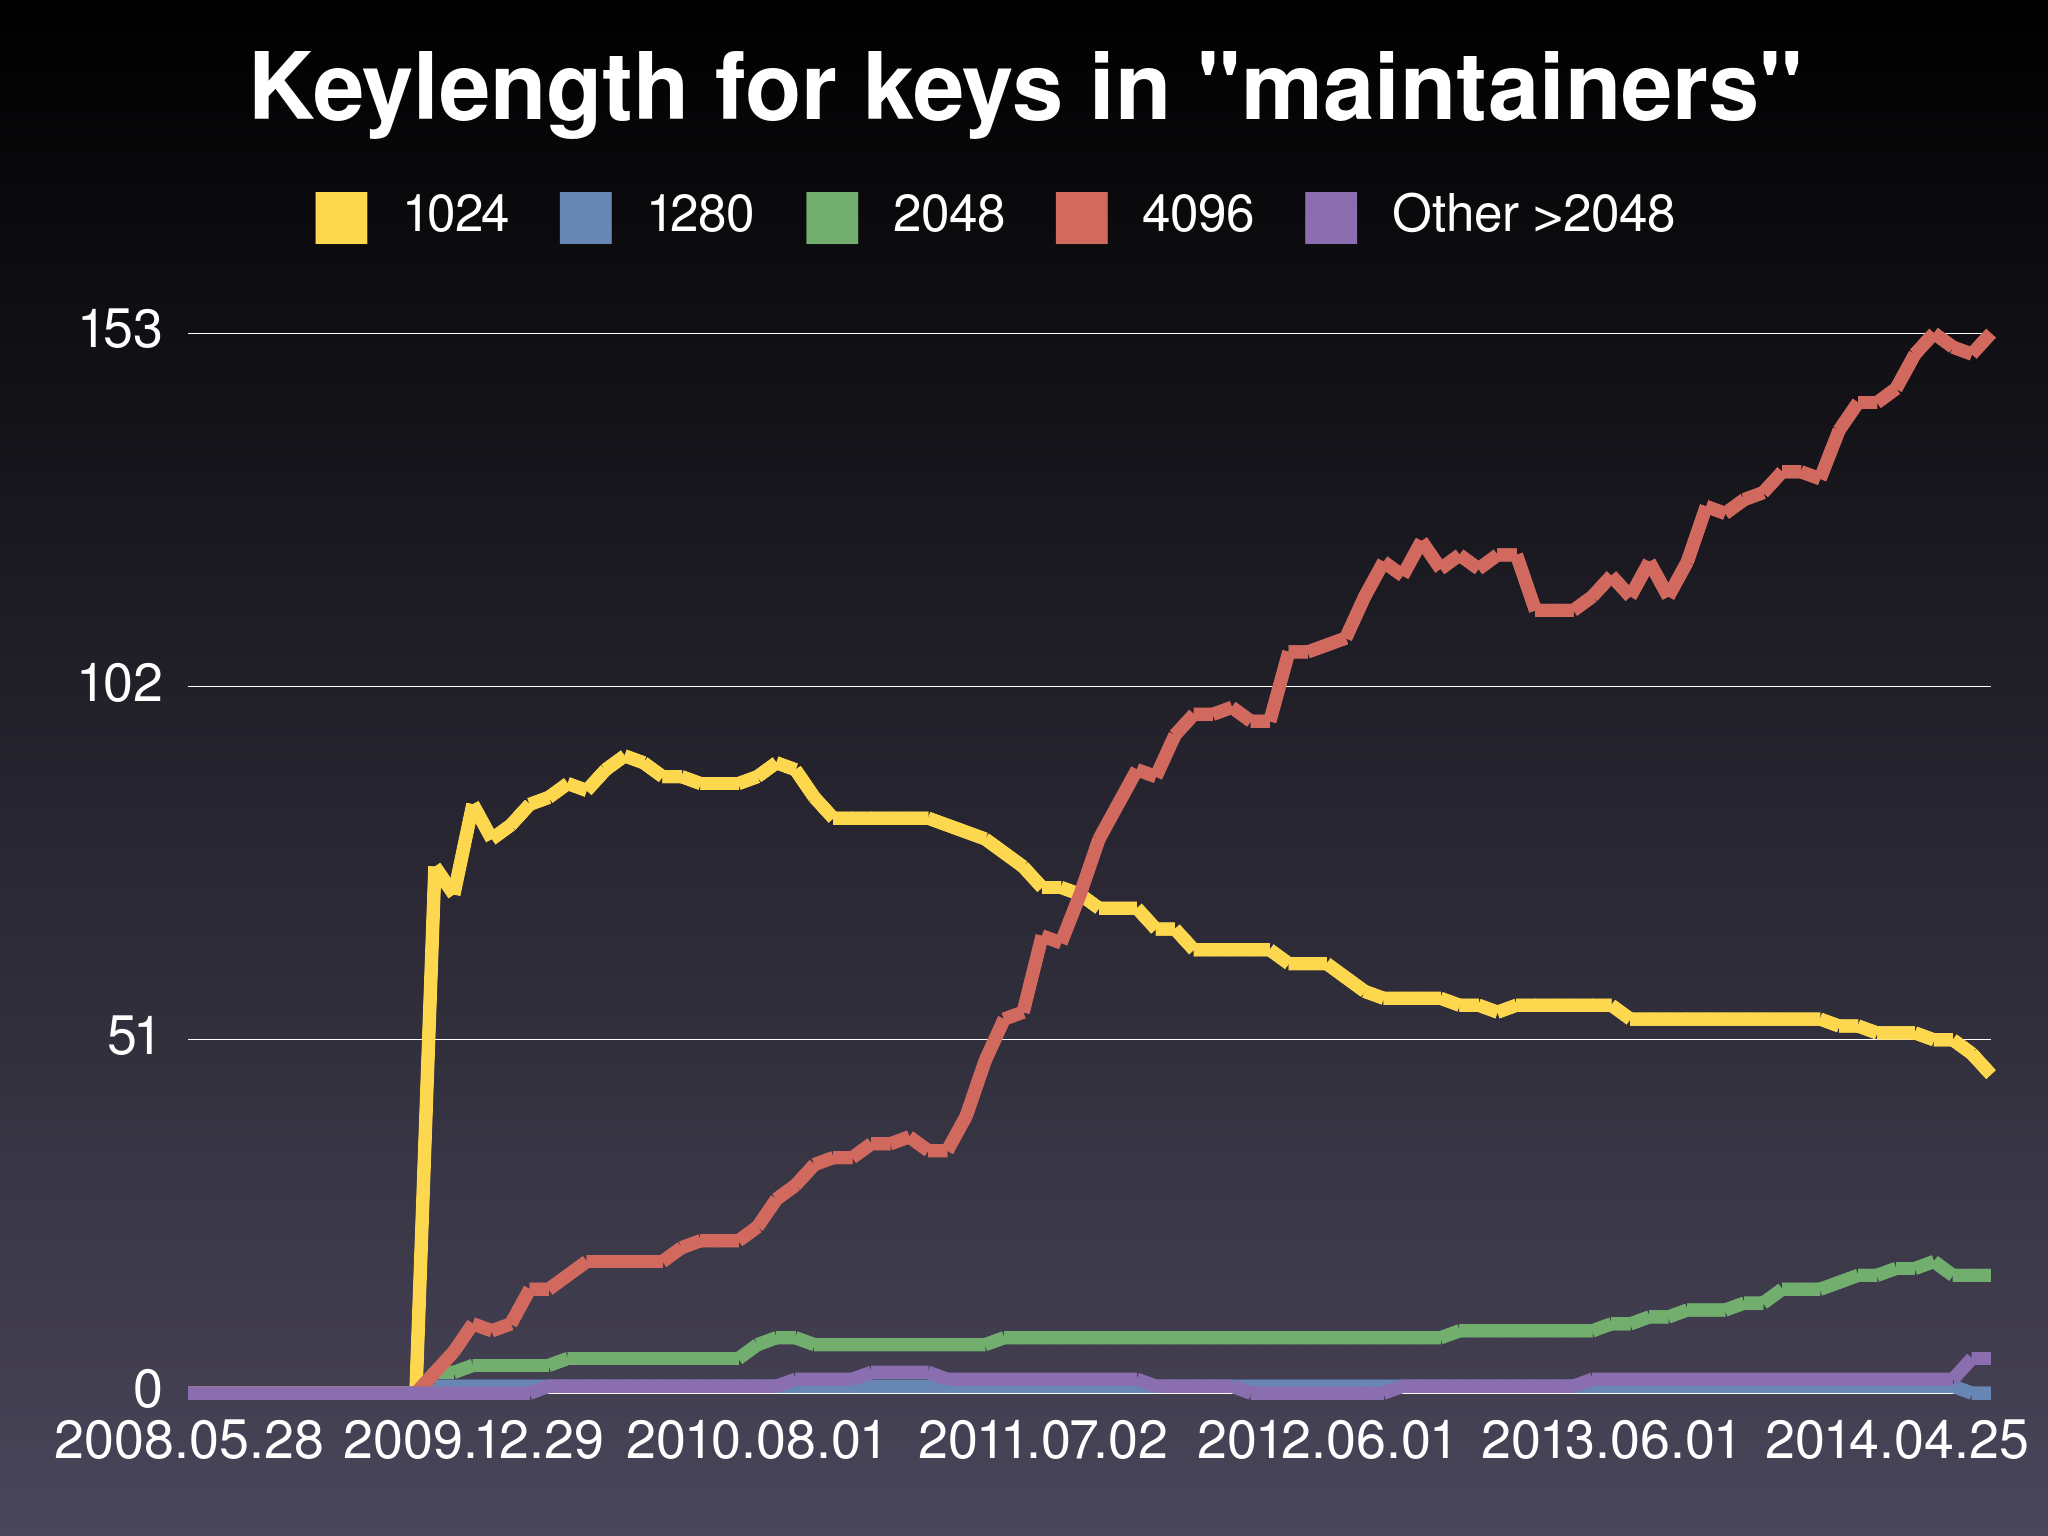
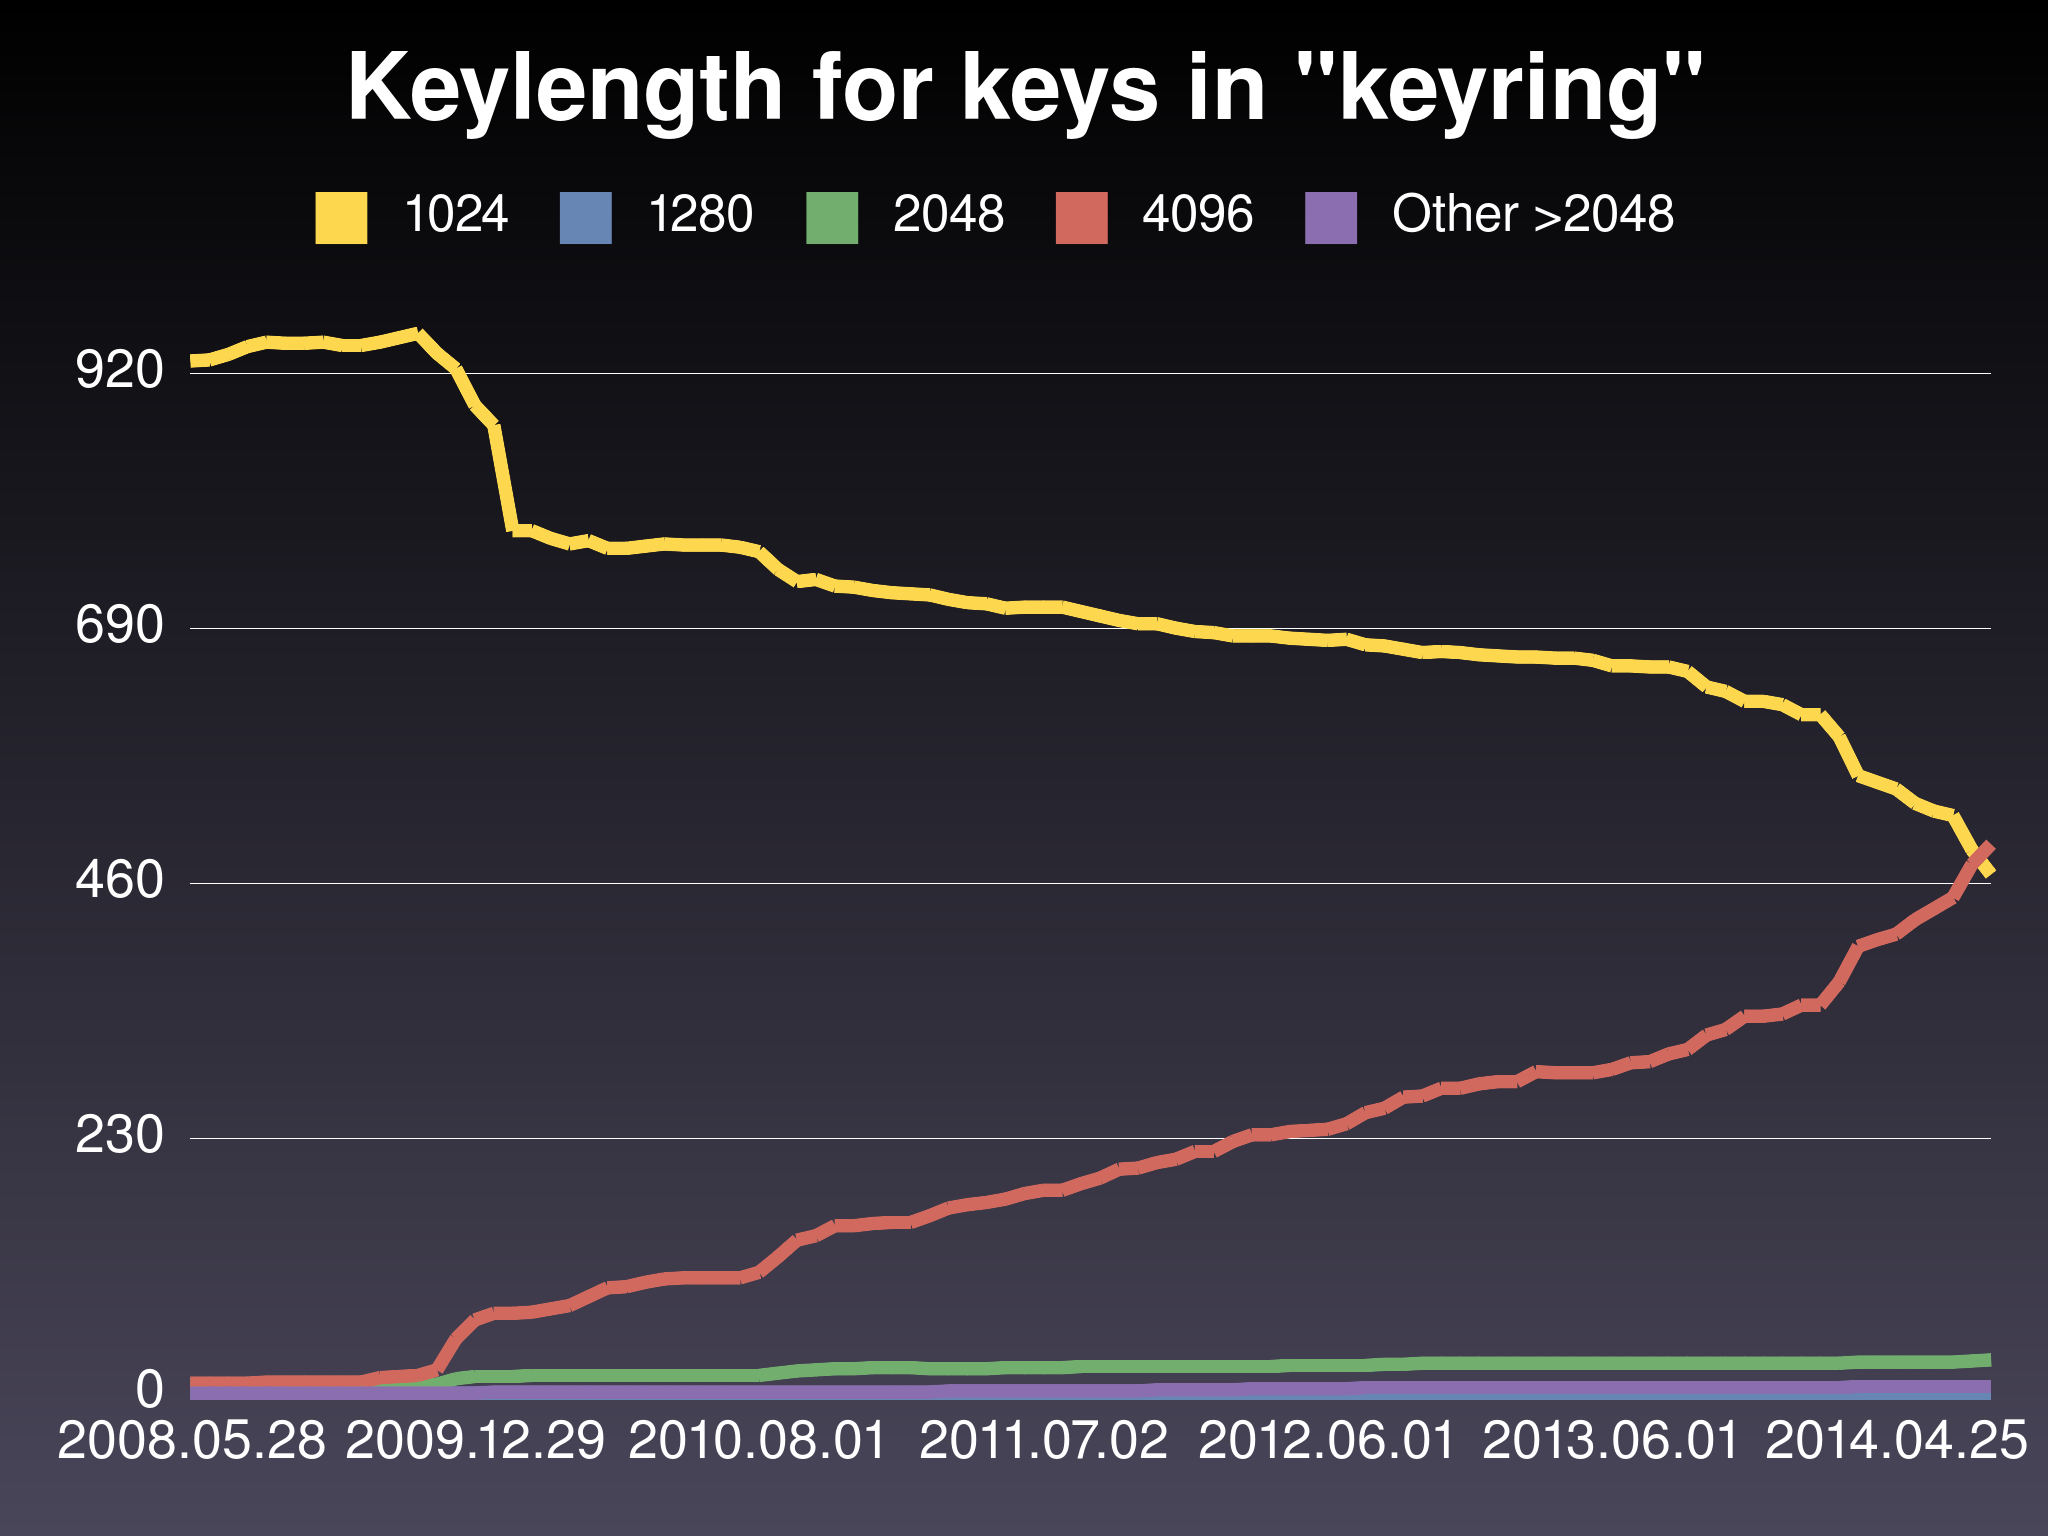
OK, it's almost one month since we (the keyring-maintainers) gave our talk at DebConf14; how are we faring regarding key transitions since then? You can compare the numbers (the graphs, really) to those in our DC14 presentation. Since the presentation, we have had two keyring pushes: First of all, the Non-uploading keyring is all fine: As it was quite recently created, and as it is much smaller than our other keyrings, it has no weak (1024 bit) keys. It briefly had one in 2010-2011, but it's long been replaced. Second, the Maintainers keyring: In late July we had 222 maintainers (170 with >=2048 bit keys, 52 with weak keys). By the end of August we had 221: 172 and 49 respectively, and by September 18 we had 221: 175 and 46. As for the Uploading developers, in late July we had 1002 uploading developers (481 with >=2048 bit keys, 521 with weak keys). By the end of August we had 1002: 512 and 490 respectively, and by September 18 we had 999: 531 and 468. Please note that these numbers do not say directly that six DMs or that 50 uploading DDs moved to stronger keys, as you'd have to factor in new people being added, keys migrating between different keyrings (mostly DM DD), and people retiring from the project; you can get the detailed information looking at the public copy of our Git repository, particularly of its changelog. And where does that put us? Of course, I'm very happy to see that the lines in our largest keyring have already crossed. We now have more people with >=2048 bit keys. And there was a lot of work to do this processing done! But that still means... That in order not to lock a large proportion of Debian Developers and Maintainers out of the project, we have a real lot of work to do. We would like to keep the replacement slope high (because, remember, in January 1st we will remove all small keys from the keyring). And yes, we are willing to do the work. But we need you to push us for it: We need you to get a new key created, to gather enough (two!) DD signatures in it, and to request a key replacement via RT. So, by all means: Do keep us busy!
AttachmentSize
Debian Developers (uploading)266.66 KB
Debian Developers (non-uploading)204.17 KB
Debian Maintainers296.73 KB

21 September 2014

Joachim Breitner: Using my Kobo eBook reader as an external eInk monitor

I have an office with a nice large window, but more often than not I have to close the shades to be able to see something on my screen. Even worse: There were so many nice and sunny days where I would have loved to take my laptop outside and work there, but it (a Thinkpad T430s) is simply not usable in bright sun. I have seen those nice eInk based eBook readers, who are clearer the brighter they are. That s what I want for my laptop, and I am willing to sacrifice color and a bit of usability due to latency for being able to work in the bright daylight! So while I was in Portland for DebConf14 (where I guess I felt a bit more like tinkering than otherwise) I bought a Kobo Aura HD. I chose this device because it has a resolution similar to my laptop (1440 1080) and I have seen reports from people running their own software on it, including completely separate systems such as Debian or Android. This week, I was able to play around with it. It was indeed simple to tinker with: You can simply copy a tarball to it which is then extracted over the root file system. There are plenty of instructions online, but I found it easier to take them as inspiration and do it my way with basic Linux knowledge that s possible. This way, I extended the system boot script with a hook to a file on the internal SD card, and this file then runs the telnetd daemon that comes with the device s busybox installation. Then I just have to make the device go online and telnet onto it. From there it is a pretty normal Linux system, albeit without an X server, using the framebuffer directly. I even found an existing project providing a VNC client implementation for this and other devices, and pretty soon I could see my laptop screen on the Kobo. Black and white worked fine, but colors and greyscales, including all anti-aliased fonts, were quite broken. After some analysis I concluded that it was confusing the bit pattern of the pixels. Luckily kvncclient shares that code with koreader, which worked fine on my device, so I could copy some files and settings from there et voil : I now have an eInk monitor for my laptop. As a matter of fact, I am writing this text with my Kobo sitting on top of the folded-back laptop screen! I did some minor adjustments to my laptop: All this is still very manual (going online with the kobo, finding its IP address, logging in via telnet, killing the Kobo's normal main program, starting x11vnc, finding my ip address, starting the vnc client, doing the adjustments mentioned above), so I need to automate it a bit. Unfortunately, there is no canonical way to extend the Kobo by your own application: The Kobo developers made their device quite open, but stopped short from actually encouraging extensions, so people have created many weird ways to start programs on the Kobo dedicated start menus, background programs observing when the regular Kobo app opens a specific file, complete replacements for the system. I am considering to simply run an SSH server on the device and drive the whole process from the laptop. I ll keep you up-to-date. A dream for the future would be to turn the kobo into a USB monitor and simply connect it to any computer, where it then shows up as a new external monitor. I wonder if there is a standard for USB monitors, and if it is simple enough (but I doubt it). A word about the kobo development scene: It seems to be quite active and healthy, and a number of interesting applications are provided for it. But unfortunately it all happens on a web forum, and they use it not only for discussion, but also as a wiki, a release page, a bug tracker, a feature request list and as a support line often on one single thread with dozens of posts. This makes it quite hard to find relevant information and decide whether it is still up-to-date. Unfortunately, you cannot really do without it. The PDF viewer that comes with the kobo is barely okish (e.g. no crop functionality), so installing, say, koreader is a must if you read more PDFs than actual ebooks. And then you have to deal with the how-to-start-it problem. That reminds me: I need to find a decent RSS reader for the kobo, or possibly a good RSS-to-epub converter that I can run automatically. Any suggestions? PS and related to this project: Thanks to Kathey!

19 September 2014

Dariusz Dwornikowski: getting real "done date" of a bug from Debian BTS

As I wrote in my last post currently, SOAP interface, nor Ultimate Debian Database do not provide a date when a given bug was closed (done date). It is quite hard to calculate statistics on a bug tracker when you do not know when a bug was closed (!!). Done date of bug can be found in its log. The log itself can be downloaded by SOAP method get_bug_log but the processing of it is quite complicated. The same comes to web scrapping of a BTS's web interface. Fortunatelly the web interface gives a possibility to download a log in an mbox format. Below is a script that extracts the done date of a bug from its log in mbox format. It uses requests to download the mbox and caches the result in ~/.cache/rfs_bugs, which you need to create. It performs different checks:
  1. Check existence of a header e.g. Received: (at 657783-done) by bugs.debian.org; 29 Jan 2012 13:27:42 +0000
  2. Check for header CC: NUMBER-close done
  3. Check for header TO: NUMBER-close done
  4. Check for Close: NUMBER in body.
The code is below:
import requests
from datetime import datetime
import mailbox
import re
import os
import tempfile
def get_done_date(bug_num):
    CACHE_DIR = os.path.expanduser("~") + "/.cache/rfs_bugs/"
    def get_from_cache():
        if os.path.exists(" ".format(CACHE_DIR, bug_num)):
            with open(" ".format(CACHE_DIR, bug_num)) as f:
                return datetime.strptime(f.readlines()[0].rstrip(), "%Y-%m-%d").date()
        else:
            return None
    done_date = get_from_cache()
    if done_date is not None:
        return done_date
    else:
        r = requests.get("https://bugs.debian.org/cgi-bin/bugreport.cgi?mbox=yes;bug= ;mboxstatus=yes".format(self._num))
        d = try_header(r.text)
        if d is None:
            d = try_cc(r.text)
        if d is None:
            d = try_body(r.text)
        if d is not None:
            with open(" ".format(CACHE_DIR, bug_num), "w") as f:
                f.write(" ".format(d.date()))
        else:
            return None
        return d.date()
    def try_body(text):
        reg = "\(at\s.+\)\s+by\sbugs\.debian\.org;\s(\d 1,2 \s\w\w\w\s\d\d\d\d)"
        handle, name = tempfile.mkstemp()
        with open(name, "w") as f:
            f.write(text.encode('latin-1'))
        mbox = mailbox.mbox(name)
        for i in mbox.items():
            if i[1].is_multipart():
                for m in i[1].get_payload():
                    if "close" in str(m) or "done" in str(m):
                        try:
                            result = re.search(reg, i[1]['Received'])
                            return datetime.strptime(result.group(1), "%d %b %Y")
                        except:
                            return None
            else:
                if "close" in i[1].get_payload() or "done" in i[1].get_payload():
                    try:
                        result = re.search(reg, i[1]['Received'])
                        return datetime.strptime(result.group(1), "%d %b %Y")
                    except:
                        return None
        return None
    def try_header(text):
        reg = "Received:\s\(at\s\d\d\d\d\d\d-(close done)\)\s+by.+"
        try:
            result = re.search(reg, r.text)
            line = result.group(0)
            reg2 = "\d 1,2 \s\w\w\w\s\d\d\d\d"
            result = re.search(reg2, line)
            d = datetime.strptime(result.group(0), "%d %b %Y")
            return d
        except:
            return None
    def try_cc(text):
        reg = "\(at\s.+\)\s+by\sbugs\.debian\.org;\s(\d 1,2 \s\w\w\w\s\d\d\d\d)"
        handle, name = tempfile.mkstemp()
        with open(name, "w") as f:
            f.write(text.encode('latin-1'))
        mbox = mailbox.mbox(name)
        for i in mbox.items():
            if ('CC' in i[1] and "done" in i[1]['CC']) or ('To' in i[1] and "done" in i[1]['To']):
                try:
                    result = re.search(reg, i[1]['Received'])
                    return datetime.strptime(result.group(1), "%d %b %Y")
                except:
                    return None
if __name__ == "__main__":
    print get_done_date(752210)
PS: I hope that the script will be not needed in the near future, as Don Armstrong plans a new BTS database, a Debconf14 video is here.

15 September 2014

Keith Packard: xserver-pending-fixes

A Forest of X Server Changes We've got about another month left in the X server merge window for 1.17 and I've written a small set of fixes which haven't been reviewed yet for merging. I thought I'd advertise them a bit and see if I couldn't encourage a few of you to take a look and see if they're useful, correct and complete. All of these are in my personal X server repository:
git://people.freedesktop.org/~keithp/xserver.git
Cleaning up the X Registry Branch: registry-fixes I'll bet most of you don't even know about this code. It serves as a database mapping various X enumerations to strings to aid in diagnostics. For the security extensions, SECURITY and XSELinux, it holds names for all of the request, event and errors in the core protocol and all registered extensions. For X-Resource, it has the names of the registered resource types. The X registry gets the request, event and error data from a file, "protocol.txt", which is installed in /usr/lib/xorg/protocol.txt on my machine. It gets the resource names as a part of resource type allocation. So, what's wrong with this? Three basic things:
  1. A simple bug -- protocol.txt is left open while the server runs. This consumes a file descriptor for no good reason.
  2. protocol.txt is read and parsed even if the security extensions aren't available. This wastes time and memory.
  3. The resource names are kept even if X-Resource isn't in use.
The fixes remove the configure options for including the registry code; these functions are only used by the above extensions, so we can tell whether to include the code based solely on whether the extensions are being built. Getting rid of the TCP listener by default Branch: listen-fixes We've had the '-nolisten' option for a while now to disable inbound TCP connections. It's useful for security reasons, but we've never enabled this by default. This patch sequence provides configure options for each of the listen sockets (tcp, unix and local), leaves unix and local enabled by default and disables tcp by default. A new option, '-listen', is added which allows the user to override the -nolisten defaults in case they actually want to use TCP connections to X. Glamor bug fixes branch: glamor-fixes This branch fixes two bugs:
  1. Scale a large pixmap down to a small pixmap. This happens when you display enormous images in a web page. Iceweasel sends the whole huge image to X and uses Render to scale it to the screen. If the image is larger than a single texture, the X server splits it up into tiles, but the code which tries to perform the merged scale is just broken. Five patches fix this.
  2. Shader-based trapezoids. This code uses area coverage to compute trapezoids. That violates the Render spec, which requires point sampling. Further, the performance of these trapezoids is lower than software (by a lot). This one patch removes the code.
Present bug fixes branch: present-fixes A selection of small bug fixes:
  1. Clear pending flips at CloseScreen. This removes a reference to any pending flip pixmap, allowing it to be freed. Otherwise, we'll leak memory across server reset.
  2. Add support for PresentOptionCopy. This has been in the protocol spec for a while, and was completely trivial to implement. However, it never got done. One tiny little patch.
  3. Expose the Present API to drivers via sdksyms.sh. Until now, the present extension APIs have only been available inside the X server. This exposes them to drivers. This took a few cleanup patches first.
Use Present for Glamor XV branch: glamor-present-xv Painting XV to the screen should be done at vblank time to avoid tearing. Present offers vblank synchronized operations. Hooking those two together required a few new present APIs to expose the vblank functionality outside of the present code, then a bit of glamor code to hook up that new API to the XV bits. Switching Glamor to a GL core profile context branch: glamor-core-profile This patch set is still in progress, but demonstrates how close we are. We'll be requiring OpenGL 3.3 for this so that we get texture swizzling, which is required for our single channel objects. The changes present on the branch are:
  1. Switch single channel surfaces from GL_ALPHA to GL_RED.
  2. Use vertex array objects.
  3. Switch ephyr over to using a core 3.3 profile.
Still left to do is
  1. Switch Render code to VBOs
The core code uses VBOs everywhere, but the Render code doesn't. This means that all Render drawing fails, which makes the resulting server not very useful. My main objective for getting this done is to reduce memory usage by about 16MB, which is the space allocated for software rendering in Mesa in case someone does something which the hardware doesn't handle, and that can only with some legacy OpenGL APIs. Please help out! All of these friendly little patches are looking for a bit of review so that they can get merged before the 1.17 window closes.

Julien Danjou: Python bad practice, a concrete case

A lot of people read up on good Python practice, and there's plenty of information about that on the Internet. Many tips are included in the book I wrote this year, The Hacker's Guide to Python. Today I'd like to show a concrete case of code that I don't consider being the state of the art. In my last article where I talked about my new project Gnocchi, I wrote about how I tested, hacked and then ditched whisper out. Here I'm going to explain part of my thought process and a few things that raised my eyebrows when hacking this code. Before I start, please don't get the spirit of this article wrong. It's in no way a personal attack to the authors and contributors (who I don't know). Furthermore, whisper is a piece of code that is in production in thousands of installation, storing metrics for years. While I can argue that I consider the code not to be following best practice, it definitely works well enough and is worthy to a lot of people. Tests The first thing that I noticed when trying to hack on whisper, is the lack of test. There's only one file containing tests, named test_whisper.py, and the coverage it provides is pretty low. One can check that using the coverage tool.
$ coverage run test_whisper.py
...........
----------------------------------------------------------------------
Ran 11 tests in 0.014s

OK
$ coverage report
Name Stmts Miss Cover
----------------------------------
test_whisper 134 4 97%
whisper 584 227 61%
----------------------------------
TOTAL 718 231 67%

While one would think that 61% is "not so bad", taking a quick peak at the actual test code shows that the tests are incomplete. Why I mean by incomplete is that they for example use the library to store values into a database, but they never check if the results can be fetched and if the fetched results are accurate. Here's a good reason one should never blindly trust the test cover percentage as a quality metric. When I tried to modify whisper, as the tests do not check the entire cycle of the values fed into the database, I ended up doing wrong changes but had the tests still pass. No PEP 8, no Python 3 The code doesn't respect PEP 8 . A run of flake8 + hacking shows 732 errors While it does not impact the code itself, it's more painful to hack on it than it is on most Python projects. The hacking tool also shows that the code is not Python 3 ready as there is usage of Python 2 only syntax. A good way to fix that would be to set up tox and adds a few targets for PEP 8 checks and Python 3 tests. Even if the test suite is not complete, starting by having flake8 run without errors and the few unit tests working with Python 3 should put the project in a better light. Not using idiomatic Python A lot of the code could be simplified by using idiomatic Python. Let's take a simple example:
def fetch(path,fromTime,untilTime=None,now=None):
fh = None
try:
fh = open(path,'rb')
return file_fetch(fh, fromTime, untilTime, now)
finally:
if fh:
fh.close()

That piece of code could be easily rewritten as:
def fetch(path,fromTime,untilTime=None,now=None):
with open(path, 'rb') as fh:
return file_fetch(fh, fromTime, untilTime, now)

This way, the function looks actually so simple that one can even wonder why it should exists but why not. Usage of loops could also be made more Pythonic:
for i,archive in enumerate(archiveList):
if i == len(archiveList) - 1:
break

could be actually:
for i, archive in itertools.islice(archiveList, len(archiveList) - 1):

That reduce the code size and makes it easier to read through the code. Wrong abstraction level Also, one thing that I noticed in whisper, is that it abstracts its features at the wrong level. Take the create() function, it's pretty obvious:
def create(path,archiveList,xFilesFactor=None,aggregationMethod=None,sparse=False,useFallocate=False):
# Set default params
if xFilesFactor is None:
xFilesFactor = 0.5
if aggregationMethod is None:
aggregationMethod = 'average'

#Validate archive configurations...
validateArchiveList(archiveList)

#Looks good, now we create the file and write the header
if os.path.exists(path):
raise InvalidConfiguration("File %s already exists!" % path)
fh = None
try:
fh = open(path,'wb')
if LOCK:
fcntl.flock( fh.fileno(), fcntl.LOCK_EX )

aggregationType = struct.pack( longFormat, aggregationMethodToType.get(aggregationMethod, 1) )
oldest = max([secondsPerPoint * points for secondsPerPoint,points in archiveList])
maxRetention = struct.pack( longFormat, oldest )
xFilesFactor = struct.pack( floatFormat, float(xFilesFactor) )
archiveCount = struct.pack(longFormat, len(archiveList))
packedMetadata = aggregationType + maxRetention + xFilesFactor + archiveCount
fh.write(packedMetadata)
headerSize = metadataSize + (archiveInfoSize * len(archiveList))
archiveOffsetPointer = headerSize

for secondsPerPoint,points in archiveList:
archiveInfo = struct.pack(archiveInfoFormat, archiveOffsetPointer, secondsPerPoint, points)
fh.write(archiveInfo)
archiveOffsetPointer += (points * pointSize)

#If configured to use fallocate and capable of fallocate use that, else
#attempt sparse if configure or zero pre-allocate if sparse isn't configured.
if CAN_FALLOCATE and useFallocate:
remaining = archiveOffsetPointer - headerSize
fallocate(fh, headerSize, remaining)
elif sparse:
fh.seek(archiveOffsetPointer - 1)
fh.write('\x00')
else:
remaining = archiveOffsetPointer - headerSize
chunksize = 16384
zeroes = '\x00' * chunksize
while remaining > chunksize:
fh.write(zeroes)
remaining -= chunksize
fh.write(zeroes[:remaining])

if AUTOFLUSH:
fh.flush()
os.fsync(fh.fileno())
finally:
if fh:
fh.close()

The function is doing everything: checking if the file doesn't exist already, opening it, building the structured data, writing this, building more structure, then writing that, etc. That means that the caller has to give a file path, even if it just wants a whipser data structure to store itself elsewhere. StringIO() could be used to fake a file handler, but it will fail if the call to fcntl.flock() is not disabled and it is inefficient anyway. There's a lot of other functions in the code, such as for example setAggregationMethod(), that mixes the handling of the files even doing things like os.fsync() while manipulating structured data. This is definitely not a good design, especially for a library, as it turns out reusing the function in different context is near impossible. Race conditions There are race conditions, for example in create() (see added comment):
if os.path.exists(path):
raise InvalidConfiguration("File %s already exists!" % path)
fh = None
try:
# TOO LATE I ALREADY CREATED THE FILE IN ANOTHER PROCESS YOU ARE GOING TO
# FAIL WITHOUT GIVING ANY USEFUL INFORMATION TO THE CALLER :-(
fh = open(path,'wb')

That code should be:
try:
fh = os.fdopen(os.open(path, os.O_WRONLY os.O_CREAT os.O_EXCL), 'wb')
except OSError as e:
if e.errno = errno.EEXIST:
raise InvalidConfiguration("File %s already exists!" % path)

to avoid any race condition. Unwanted optimization We saw earlier the fetch() function that is barely useful, so let's take a look at the file_fetch() function that it's calling.
def file_fetch(fh, fromTime, untilTime, now = None):
header = __readHeader(fh)
[...]

The first thing the function does is to read the header from the file handler. Let's take a look at that function:
def __readHeader(fh):
info = __headerCache.get(fh.name)
if info:
return info

originalOffset = fh.tell()
fh.seek(0)
packedMetadata = fh.read(metadataSize)

try:
(aggregationType,maxRetention,xff,archiveCount) = struct.unpack(metadataFormat,packedMetadata)
except:
raise CorruptWhisperFile("Unable to read header", fh.name)
[...]

The first thing the function does is to look into a cache. Why is there a cache? It actually caches the header based with an index based on the file path (fh.name). Except that if one for example decide not to use file and cheat using StringIO, then it does not have any name attribute. So this code path will raise an AttributeError. One has to set a fake name manually on the StringIO instance, and it must be unique so nobody messes with the cache
import StringIO

packedMetadata = <some source>
fh = StringIO.StringIO(packedMetadata)
fh.name = "myfakename"
header = __readHeader(fh)

The cache may actually be useful when accessing files, but it's definitely useless when not using files. But it's not necessarily true that the complexity (even if small) that the cache adds is worth it. I doubt most of whisper based tools are long run processes, so the cache that is really used when accessing the files is the one handled by the operating system kernel, and this one is going to be much more efficient anyway, and shared between processed. There's also no expiry of that cache, which could end up of tons of memory used and wasted. Docstrings None of the docstrings are written in a a parsable syntax like Sphinx. This means you cannot generate any documentation in a nice format that a developer using the library could read easily. The documentation is also not up to date:
def fetch(path,fromTime,untilTime=None,now=None):
"""fetch(path,fromTime,untilTime=None)
[...]
"""

def create(path,archiveList,xFilesFactor=None,aggregationMethod=None,sparse=False,useFallocate=False):
"""create(path,archiveList,xFilesFactor=0.5,aggregationMethod='average')
[...]
"""

This is something that could be avoided if a proper format was picked to write the docstring. A tool cool be used to be noticed when there's a diversion between the actual function signature and the documented one, like missing an argument. Duplicated code Last but not least, there's a lot of code that is duplicated around in the scripts provided by whisper in its bin directory. Theses scripts should be very lightweight and be using the console_scripts facility of setuptools, but they actually contains a lot of (untested) code. Furthermore, some of that code is partially duplicated from the whisper.py library which is against DRY. Conclusion There are a few more things that made me stop considering whisper, but these are part of the whisper features, not necessarily code quality. One can also point out that the code is very condensed and hard to read, and that's a more general problem about how it is organized and abstracted. A lot of these defects are actually points that made me start writing The Hacker's Guide to Python a year ago. Running into this kind of code makes me think it was a really good idea to write a book on advice to write better Python code!
The Hacker's Guide to Python
A book I wrote talking about designing Python applications, state of the art, advice to apply when building your application, various Python tips, etc. Interested? Check it out.

Cyril Brulebois: Freelance Debian consultant

I m not used to talking about my day job but here s an exception. Over the past few years I worked in two startups (3 years each). It was nice to spend time in different areas: one job was mostly about research and development in a Linux cluster environment; the other one was about maintaining a highly-customized, Linux-based operating system, managing a small support team, and performing technological surveillance in IT security. In the meanwhile I ve reached a milestone: 10 years with Debian. I had been wondering for a few months whether I could try my luck going freelance, becoming a Debian consultant. I finally decided to go ahead and started in August! The idea is to lend a hand for various Debian-related things like systems administration, development/debugging, packaging/repository maintenance, or Debian Installer support, be it one-shot or on a regular basis. I didn t think about trainings/workshops at first but sharing knowledge is something I ve always liked, even if I didn t become a teacher. For those interested, details can be found on my website: https://mraw.org/. Of course this doesn t mean I m going to put an end to my volunteer activities within Debian, especially as a Debian Installer release manager. Quite the contrary in fact! See the August and September debian-boot@ archives, which have been busy months. :)

14 September 2014

Gregor Herrmann: RC bugs 2014/34-37

the perl 5.20 transition is over, debconf14 is over, so I should have more time for RC bugs? yes & no: I fixed some, but only in "our" (as in: pkg-perl) packages:

12 September 2014

Jonathan McDowell: Back from DebConf 14

I previously forgot to mention that I was planning to attend DebConf14, having missed DebConf13. This year the conference was held in Portland, OR. This is a city I've been to many times before, and enjoy, but I hadn't spent any time wandering around its city centre as a pedestrian. I have to say I really prefer DebConfs that are held in middle of city. It always seems a bit of a shame to travel some distance to somewhere new and spend all the time there in a conference venue. Plus these days I have the added lure of going out and playing Ingress in a new location. DebConf14 didn't disappoint in these respects; the location was super easy to get to from the airport via public transportation, all of the evening social events were within reasonable walking distance (I'll tend to default to walking when possible) and the talk venue/accommodation were close to each other and various eating + drinking options. Throw in the fact at Portland managed to produce some excellent weather (modulo my Ingress session on the last Saturday morning, when rained on me) and it's impossible to fault the physicalities of DebConf this year. This year the conference format was a bit different; previous years have had a week long DebConf before the week of the conference itself. This year went for a 9 day talk schedule (Saturday -> Sunday) with various gaps of hacking time interspersed. I've found it hard to justify a full two weeks away in the past, so this setup worked a lot better from my viewpoint. Also I rarely go to DebConf with a predetermined list of things to do; the stuff I work on naturally falls out of talks I attend and informal discussions I have. Having hack time throughout the conference helped me avoid feeling I was having to trade off hacking vs talks. Naturally enough a lot of my involvement at DebConf was around OpenPGP. Gunnar and I spent a fair bit of time getting Daniel up to speed with the keyring-maint team (Gunnar more than I, I'll confess). We finally set a hard timeframe for freeing Debian of older 1024 bit keys. I was introduced to the Gnuk, which is a particularly interesting piece of open specification hardware with a completely Free software stack on top if it that implements the OpenPGP smartcard spec. Currently it's limited to 2K keys but it's hoped that 4K support can be added (and I ended up spending a couple of hours after the closing talk hacking on the source and seeing how much needs to change for 4K support, aided by the very patient Niibe). These are the sort of things that really benefit from the face time that DebConf offers to the Debian project. I've said it before, but I think it's worth saying again: Debian is a bit like a huge telecommuting organization and it's my opinion that any such organization should try and ensure its members actually spend some time together on a regular basis. It improves the ability to work remotely a hell of a lot if you can actually put a face to the entity you're emailing / IRCing and have some sort of idea where they're coming from because you've spent some time with them, whether that's in talks or over dinner or just casual hallway chats. For once I also found myself considering alternative employment while at DebConf and it was incredibly useful to be able to have various conversations with both old friends and people who were there with an eye on recruitment. Thanks to all those whose ears I bent about the subject (and more on the outcome in a future post). Thank you also to the many people involved with the organization of DebConf; I've been on the periphery a few times over the years and it's given me a glimpse into the amount of hard work all of the volunteers (be they global team, local organizing team, video team or just random volunteers) put into making DebConf one of my must-attend yearly conferences. If you're at all involved in Debian and haven't attended I strongly urge you to do so - I'll see you all next year at DebConf15 in Heidelberg!
11 September 2014

Dirk Eddelbuettel: pkgKitten 0.1.2: Still creating R Packages that purr

A brown bag release 0.1.2 of pkgKitten is now on CRAN, following yesterday's 0.1.1 upload Next time I'll try to remember that when I have parameters name and path, it won't work so well to call them as path and name ...
Changes in version 0.1.2 (2014-09-11)
  • Brown-bag fix of calling the new helper function with then correct order of arguments.
More details about the package are at the pkgKitten webpage and the pkgKitten GitHub repo. Courtesy of CRANberries, there is also a diffstat report for this release

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

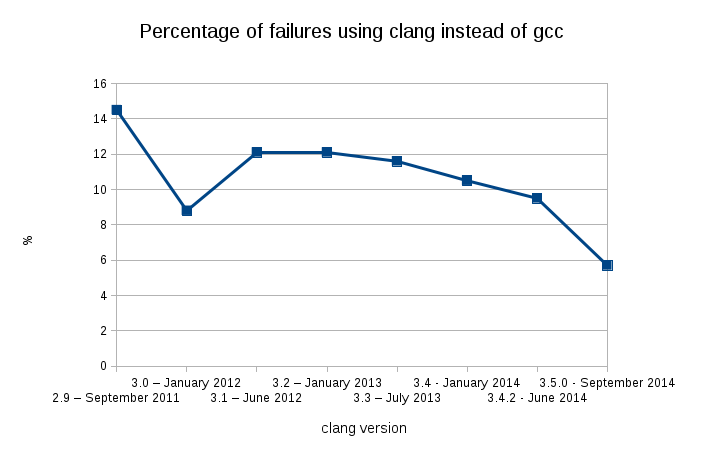
Sylvestre Ledru: Rebuild of Debian using Clang 3.5.0

Clang 3.5.0 has just been released. A new rebuild has been done highlight the progress to get Debian built with clang. tl;dr: Great progress. We decreased from 9.5% to 5.7% of failures. Full results are available on http://clang.debian.net At time of the rebuild with 3.4.2, we had 2040 packages failing to build with clang. With 3.5.0, this dropped to 1261 packages. Fixes With Arthur Marble and Alexander Ovchinnikov, both GSoC students, we worked on various ways to decrease the number of errors. Upstream fixes First, the most obvious way, we fixed programming bugs/mistakes in upstream sources. Basically, we took categories of failure and fixed issues one after the other. We started with simple bugs like 'Wrong main declaration', 'non-void function should return a value' or 'Void function should not return a value'.

They are trivial to fix. We continued with harder fixes like ' Undefined reference' or 'Variable length array for a non POD (plain old data) element'.

So, besides these one, we worked on:
In total, we reported 295 bugs with patches. 85 of them have been fixed (meaning that the Debian maintainer uploaded a new version with the fix).

In parallel, I think that the switch by FreeBSD and Mac OS X to Clang also helped to fix various issues by upstreams. Hacking in clang As a parallel approach, we started to implement a suggestion from Linus Torvalds and a few others. Instead of trying to fix all upstream, where we can, we tried to update clang to improve the gcc compatibility.

gcc has many flags to disable or enable optimizations. Some of them are legacy, others have no sense in clang, etc. Instead of failing in clang with an error, we create a new category of warnings (showing optimization flag '%0' is not supported) and moved all relevant flags into it. Some examples, r212805, r213365, r214906 or r214907

We also updated clang to silent some useless arguments like -finput_charset=UTF-8 (r212110), clang being UTF-8 compliant.

Finally, we worked on the forwarding of linker flags. Clang and gcc have a very different behavior: when gcc does not know an argument, it is going to forward the argument to the linker. Clang, in this case, is going to reject the argument and fail with an error. In clang, we have to explicitly declare which arguments are going to be transfer to the linker. Of course, the correct way to pass arguments to the linker is to use -Xlinker or -Wl but the Debian rebuild proved that these shortcuts are used. Two of these arguments are now forwarded: New errors Just like in other releases, new warnings are added in clang. With (bad) usage of -Werror by upstream software, this causes new build failures: I also took the opportunity to add some further categorizations in the list of errors. Some examples: Next steps The Debile project being close to ready with Cl ment Schreiner's GSoC, we will now have an automatic and transparent way to rebuild packages using clang. Conclusion As stated, we can see a huge drop in term of number of failures over time:
Hopefully, Clang getting better and better, more and more projects adopting it as the default compiler or as a base for plugin/extension developments, this percentage will continue to decrease.
Having some kind of release goal with clang for Jessie+1 can now be considered as potentially reachable. Want to help? There are several things which can be done to help: Acknowledgments Thanks to David Suarez for the rebuilds of the archive, Arthur Marble and Alexander Ovchinnikov for their GSoC works and Nicolas S velin-Radiguet for the few fixes.

Dirk Eddelbuettel: pkgKitten 0.1.1: Still creating R Packages that purr

A maintenance release 0.1.1 of pkgKitten is now on CRAN. It has only one small change: the function playWithPerPackageHelpPage() was factored out of the main function kitten() as I happened to be needing something just like playWithPerPackageHelpPage() to make packages created by the Rcpp function Rcpp.package.skeleton() a little nicer. We also added a NEWS.Rd file which restates major release features. As it is so short, we include it in its entirety.
Changes in version 0.1.1 (2014-09-09)
  • New (exported) function playWithPerPackageHelpPage() which lets other packages create a non-complaint-generating package help page
Changes in version 0.1.0 (2014-06-13)
  • Initial public version and CRAN upload
More details about the package are at the pkgKitten webpage and the pkgKitten GitHub repo. Courtesy of CRANberries, there is also a diffstat report for this release

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

10 September 2014

Rapha&#235;l Hertzog: Freexian s first report about Debian Long Term Support

When we setup Freexian s offer to bring together funding from multiple companies in order to sponsor the work of multiple developers on Debian LTS, one of the rules that I imposed is that all paid contributors must provide a public monthly report of their paid work. While the LTS project officially started in June, the first month where contributors were actually paid has been July. Freexian sponsored Thorsten Alteholz and Holger Levsen for 10.5 hours each in July and for 16.5 hours each in August. Here are their reports: It s worth noting that Freexian sponsored Holger s work to fix the security tracker to support squeeze-lts. It s my belief that using the money of our sponsors to make it easier for everybody to contribute to Debian LTS is money well spent. As evidenced by the progress bar on Freexian s offer page, we have not yet reached our minimal goal of funding the equivalent of a half-time position. And it shows in the results, the dla-needed.txt still shows around 30 open issues. This is slightly better than the state two months ago but we can improve a lot on the average time to push out a security update To have an idea of the relative importance of the contributions of the paid developers, I counted the number of uploads made by Thorsten and Holger since July: of 40 updates, they took care of 19 of them, so about the half. I also looked at the other contributors: Rapha l Geissert stands out with 9 updates (I believe that he is contracted by lectricit de France for doing this) and most of the other contributors look like regular Debian maintainers taking care of their own packages (Paul Gevers with cacti, Christoph Berg with postgresql, Peter Palfrader with tor, Didier Raboud with cups, Kurt Roeckx with openssl, Balint Reczey with wireshark) except Matt Palmer and Luciano Bello who (likely) are benevolent members of the LTS team. There are multiple things to learn here:
  1. Paid contributors already handle almost 70% of the updates. Counting only on volunteers would not have worked.
  2. Quite a few companies that promised help (and got mentioned in the press release) have not delivered the promised help yet (neither through Freexian nor directly).
Last but not least, this project wouldn t exist without the support of multiple companies and organizations. Many thanks to them: Hopefully this list will expand over time! Any help to reach out to new companies and organizations is more than welcome.

One comment Liked this article? Click here. My blog is Flattr-enabled.

9 September 2014

Daniel Pocock: xTupleCon WebRTC talk schedule change, new free event

As mentioned in my earlier blog, I'm visiting several events in the US and Canada in October and November. The first of these, the talk about WebRTC in CRM at xTupleCon, has moved from the previously advertised timeslot to Wednesday, 15 October at 14:15. WebRTC meeting, Norfolk, VA Later that day, there will be a WebRTC/JavaScript meetup in Norfolk hosted at the offices of xTuple. It is not part of xTupleCon and free to attend. Please register using the Eventbrite page created by xTuple. This will be a hands on event for developers and other IT professionals, especially those in web development, network administration and IP telephony. Please bring laptops and mobile devices with the latest versions of both Firefox and Chrome to experience WebRTC. Free software developers at xTupleCon If you do want to attend xTupleCon itself, please contact xTuple directly through this form for details about the promotional tickets for free software developers.

4 September 2014

Steve Kemp: systemd, a brave new world

After spending a while fighting with upstart, at work, I decided that systemd couldn't be any worse and yesterday morning upgraded one of my servers to run it. I have two classes of servers: I thought it would be a fair test to upgrade one of each systems, to see how it worked. The Debian wiki has instructions for installing Systemd, and both systems came up just fine. Although I realize I should replace my current runit jobs with systemd units I didn't want to do that. So I wrote a systemd .service file to launch runit against /etc/service, as expected, and that was fine. Docker was a special case. I wrote a docker.service + docker.socket file to launch the deamon, but when I wrote a graphite.service file to start a docker instance it kept on restarting, or failing to stop. In short I couldn't use systemd to manage running a docker guest, but that was probably user-error. For the moment the docker-host has a shell script in root's home directory to launch the guest:
#!/bin/sh
#
# Run Graphite in a detached state.
#
/usr/bin/docker run -d -t -i -p 8080:80 -p 2003:2003 skxskx/graphite
Without getting into politics (ha), systemd installation seemed simple, resulted in a faster boot, and didn't cause me horrific problems. Yet. ObRandom: Not sure how systemd is controlling prosody, for example. If I run the status command I can see it is using the legacy system:
root@chat ~ # systemctl status prosody.service 
prosody.service - LSB: Prosody XMPP Server
      Loaded: loaded (/etc/init.d/prosody)
      Active: active (running) since Wed, 03 Sep 2014 07:59:44 +0100; 18h ago
      CGroup: name=systemd:/system/prosody.service
            942 lua5.1 /usr/bin/prosody
I've installed systemd and systemd-sysv, so I thought /etc/init.d was obsolete. I guess it is making pretend-services for things it doesn't know about (because obviously not all packages contain /lib/systemd/system entries), but I'm unsure how that works.

3 September 2014

Dirk Eddelbuettel: littler is faster at doing nothing!

With yesterday's announcement of littler 0.2.0, I kept thinking about a few not-so-frequently-asked but recurring questions about littler. And an obvious one if of course the relationship to Rscript. As we have pointed out before, littler preceded Rscript. Now, with Rscript being present in every R installation, it is of course by now more widely known. But there is one important aspect which I stressed once or twice in the past and which bears repeating. Due to the lean and mean way in which littler is designed and set-up, it actually starts a lot faster than either Rscript or R. How, you ask? Well we actually query the environement at build time and hardcode a number of settings which R and Rscript re-acquire and learn each time they start. Which is more flexible. But slower. So consider the following, really simple example. In it, we create a simple worker function f which launches the given (and simplest possible) R command of just quitting 250 times (by launching a shell command which loops). We then let littler, Rscript and R (in its just execute this expression mode) run this, and time it via one of the common benchmarking packages.
R> library(rbenchmark)
R> f <- function(cmd)   system(paste0("bash -c \"for i in \\$(seq 1 250); do ", cmd, " -e 'q()'; done\""));  
R> res <- benchmark(f("r"), f("Rscript"), f("R --slave"), replications=5, order="relative")
R> res
            test replications elapsed relative user.self sys.self user.child sys.child
1         f("r")            5  32.256    1.000     0.001    0.004     26.538     5.706
2   f("Rscript")            5 180.154    5.585     0.001    0.004    152.751    28.522
3 f("R --slave")            5 302.714    9.385     0.001    0.004    270.569    33.098
R> 
So there: littler does "nothing" about five times as fast as Rscript, and about nine times as fast as R. Not that this matters greatly -- but when you design something for repeated (unsupervised) execution, say in a cronjob, it might as well be lightweight.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.