Search Results: "will"

21 December 2025

Ian Jackson: Debian s git transition

tl;dr: There is a Debian git transition plan. It s going OK so far but we need help, especially with outreach and updating Debian s documentation. Goals of the Debian git transition project
  1. Everyone who interacts with Debian source code should be able to do so entirely in git.
That means, more specifically:
  1. All examination and edits to the source should be performed via normal git operations.
  2. Source code should be transferred and exchanged as git data, not tarballs. git should be the canonical form everywhere.
  3. Upstream git histories should be re-published, traceably, as part of formal git releases published by Debian.
  4. No-one should have to learn about Debian Source Packages, which are bizarre, and have been obsoleted by modern version control.
This is very ambitious, but we have come a long way! Achievements so far, and current status We have come a very long way. But, there is still much to do - especially, the git transition team needs your help with adoption, developer outreach, and developer documentation overhaul. We ve made big strides towards goals 1 and 4. Goal 2 is partially achieved: we currently have dual running. Goal 3 is within our reach but depends on widespread adoption of tag2upload (and/or dgit push). Downstreams and users can obtain the source code of any Debian package in git form. (dgit clone, 2013). They can then work with this source code completely in git, including building binaries, merging new versions, even automatically (eg Raspbian, 2016), and all without having to deal with source packages at all (eg Wikimedia 2025). A Debian maintainer can maintain their own package entirely in git. They can obtain upstream source code from git, and do their packaging work in git (git-buildpackage, 2006). Every Debian maintainer can (and should!) release their package from git reliably and in a standard form (dgit push, 2013; tag2upload, 2025). This is not only more principled, but also more convenient, and with better UX, than pre-dgit tooling like dput. Indeed a Debian maintainer can now often release their changes to Debian, from git, using only git branches (so no tarballs). Releasing to Debian can be simply pushing a signed tag (tag2upload, 2025). A Debian maintainer can maintain a stack of changes to upstream source code in git (gbp pq 2009). They can even maintain such a delta series as a rebasing git branch, directly buildable, and use normal git rebase style operations to edit their changes, (git-dpm, 2010; git-debrebase, 2018) An authorised Debian developer can do a modest update to any package in Debian, even one maintained by someone else, working entirely in git in a standard and convenient way (dgit, 2013). Debian contributors can share their work-in-progress on git forges and collaborate using merge requests, git based code review, and so on. (Alioth, 2003; Salsa, 2018.) Core engineering principle The Debian git transition project is based on one core engineering principle: Every Debian Source Package can be losslessly converted to and from git. In order to transition away from Debian Source Packages, we need to gateway between the old dsc approach, and the new git approach. This gateway obviously needs to be bidirectional: source packages uploaded with legacy tooling like dput need to be imported into a canonical git representation; and of course git branches prepared by developers need to be converted to source packages for the benefit of legacy downstream systems (such as the Debian Archive and apt source). This bidirectional gateway is implemented in src:dgit, and is allowing us to gradually replace dsc-based parts of the Debian system with git-based ones. Correspondence between dsc and git A faithful bidirectional gateway must define an invariant: The canonical git tree, corresponding to a .dsc, is the tree resulting from dpkg-source -x. This canonical form is sometimes called the dgit view . It s sometimes not the same as the maintainer s git branch, because many maintainers are still working with patches-unapplied git branches. More on this below. (For 3.0 (quilt) .dscs, the canonical git tree doesn t include the quilt .pc directory.) Patches-applied vs patches-unapplied The canonical git format is patches applied . That is: If Debian has modified the upstream source code, a normal git clone of the canonical branch gives the modified source tree, ready for reading and building. Many Debian maintainers keep their packages in a different git branch format, where the changes made by Debian, to the upstream source code, are in actual patch files in a debian/patches/ subdirectory. Patches-applied has a number of important advantages over patches-unapplied: The downside is that, with the (bizarre) 3.0 (quilt) source format, the patch files files in debian/patches/ must somehow be kept up to date. Nowadays though, tools like git-debrebase and git-dpm (and dgit for NMUs) make it very easy to work with patches-applied git branches. git-debrebase can deal very ergonomically even with big patch stacks. (For smaller packages which usually have no patches, plain git merge with an upstream git branch, and a much simpler dsc format, sidesteps the problem entirely.) Prioritising Debian s users (and other outsiders) We want everyone to be able to share and modify the software that they interact with. That means we should make source code truly accessible, on the user s terms. Many of Debian s processes assume everyone is an insider. It s okay that there are Debian insiders and that people feel part of something that they worked hard to become involved with. But lack of perspective can lead to software which fails to uphold our values. Our source code practices in particular, our determination to share properly (and systematically) are a key part of what makes Debian worthwhile at all. Like Debian s installer, we want our source code to be useable by Debian outsiders. This is why we have chosen to privilege a git branch format which is more familiar to the world at large, even if it s less popular in Debian. Consequences, some of which are annoying The requirement that the conversion be bidirectional, lossless, and context-free can be inconvenient. For example, we cannot support .gitattributes which modify files during git checkin and checkout. .gitattributes cause the meaning of a git tree to depend on the context, in possibly arbitrary ways, so the conversion from git to source package wouldn t be stable. And, worse, some source packages might not to be representable in git at all. Another example: Maintainers often have existing git branches for their packages, generated with pre-dgit tooling which is less careful and less principled than ours. That can result in discrepancies between git and dsc, which need to be resolved before a proper git-based upload can succeed. That some maintainers use patches-unapplied, and some patches-unapplied, means that there has to be some kind of conversion to a standard git representation. Choosing the less-popular patches-applied format as the canonical form, means that many packages need their git representation converted. It also means that user- and outsider-facing branches from browse,git .dgit.d.o and dgit clone are not always compatible with maintainer branches on Salsa. User-contributed changes need cherry-picking rather than merging, or conversion back to the maintainer format. The good news is that dgit can automate much of this, and the manual parts are usually easy git operations. Distributing the source code as git Our source code management should be normal, modern, and based on git. That means the Debian Archive is obsolete and needs to be replaced with a set of git repositories. The replacement repository for source code formally released to Debian is *.dgit.debian.org. This contains all the git objects for every git-based upload since 2013, including the signed tag for each released package version. The plan is that it will contain a git view of every uploaded Debian package, by centrally importing all legacy uploads into git. Tracking the relevant git data, when changes are made in the legacy Archive Currently, many critical source code management tasks are done by changes to the legacy Debian Archive, which works entirely with dsc files (and the associated tarballs etc). The contents of the Archive are therefore still an important source of truth. But, the Archive s architecture means it cannot sensibly directly contain git data. To track changes made in the Archive, we added the Dgit: field to the .dsc of a git-based upload (2013). This declares which git commit this package was converted from. and where those git objects can be obtained. Thus, given a Debian Source Package from a git-based upload, it is possible for the new git tooling to obtain the equivalent git objects. If the user is going to work in git, there is no need for any tarballs to be downloaded: the git data could be obtained from the depository using the git protocol. The signed tags, available from the git depository, have standardised metdata which gives traceability back to the uploading Debian contributor. Why *.dgit.debian.org is not Salsa We need a git depository - a formal, reliable and permanent git repository of source code actually released to Debian. Git forges like Gitlab can be very convenient. But Gitlab is not sufficiently secure, and too full of bugs, to be the principal and only archive of all our source code. (The open core business model of the Gitlab corporation, and the constant-churn development approach, are critical underlying problems.) Our git depository lacks forge features like Merge Requests. But: The dgit git depository outlasted Alioth and it may well outlast Salsa. We need both a good forge, and the *.dgit.debian.org formal git depository. Roadmap In progress Right now we are quite focused on tag2upload. We are working hard on eliminating the remaining issues that we feel need to be addressed before declaring the service out of beta. Future Technology Whole-archive dsc importer Currently, the git depository only has git data for git-based package updates (tag2upload and dgit push). Legacy dput-based uploads are not currently present there. This means that the git-based and legacy uploads must be resolved client-side, by dgit clone. We will want to start importing legacy uploads to git. Then downstreams and users will be able to get the source code for any package simply with git clone, even if the maintainer is using legacy upload tools like dput. Support for git-based uploads to security.debian.org Security patching is a task which would particularly benefit from better and more formal use of git. git-based approaches to applying and backporting security patches are much more convenient than messing about with actual patch files. Currently, one can use git to help prepare a security upload, but it often involves starting with a dsc import (which lacks the proper git history) or figuring out a package maintainer s unstandardised git usage conventions on Salsa. And it is not possible to properly perform the security release as git. Internal Debian consumers switch to getting source from git Buildds, QA work such as lintian checks, and so on, could be simpler if they don t need to deal with source packages. And since git is actually the canonical form, we want them to use it directly. Problems for the distant future For decades, Debian has been built around source packages. Replacing them is a long and complex process. Certainly source packages are going to continue to be supported for the foreseeable future. There are no doubt going to be unanticipated problems. There are also foreseeable issues: for example, perhaps there are packages that work very badly when represented in git. We think we can rise to these challenges as they come up. Mindshare and adoption - please help! We and our users are very pleased with our technology. It is convenient and highly dependable. dgit in particular is superb, even if we say so ourselves. As technologists, we have been very focused on building good software, but it seems we have fallen short in the marketing department. A rant about publishing the source code git is the preferred form for modification. Our upstreams are overwhelmingly using git. We are overwhelmingly using git. It is a scandal that for many packages, Debian does not properly, formally and officially publish the git history. Properly publishing the source code as git means publishing it in a way that means that anyone can automatically and reliably obtain and build the exact source code corresponding to the binaries. The test is: could you use that to build a derivative? Putting a package in git on Salsa is often a good idea, but it is not sufficient. No standard branch structure git on Salsa is enforced, nor should it be (so it can t be automatically and reliably obtained), the tree is not in a standard form (so it can t be automatically built), and is not necessarily identical to the source package. So Vcs-Git fields, and git from Salsa, will never be sufficient to make a derivative. Debian is not publishing the source code! The time has come for proper publication of source code by Debian to no longer be a minority sport. Every maintainer of a package whose upstream is using git (which is nearly all packages nowadays) should be basing their work on upstream git, and properly publishing that via tag2upload or dgit. And it s not even difficult! The modern git-based tooling provides a far superior upload experience. A common misunderstanding dgit push is not an alternative to gbp pq or quilt. Nor is tag2upload. These upload tools complement your existing git workflow. They replace and improve source package building/signing and the subsequent dput. If you are using one of the usual git layouts on salsa, and your package is in good shape, you can adopt tag2upload and/or dgit push right away. git-debrebase is distinct and does provides an alternative way to manage your git packaging, do your upstream rebases, etc. Documentation Debian s documentation all needs to be updated, including particularly instructions for packaging, to recommend use of git-first workflows. Debian should not be importing git-using upstreams release tarballs into git. (Debian outsiders who discover this practice are typically horrified.) We should use only upstream git, work only in git, and properly release (and publish) in git form. We, the git transition team, are experts in the technology, and can provide good suggestions. But we do not have the bandwidth to also engage in the massive campaigns of education and documentation updates that are necessary especially given that (as with any programme for change) many people will be sceptical or even hostile. So we would greatly appreciate help with writing and outreach. Personnel We consider ourselves the Debian git transition team. Currently we are: We wear the following hats related to the git transition: You can contact us: We do most of our heavy-duty development on Salsa. Thanks Particular thanks are due to Joey Hess, who, in the now-famous design session in Vaumarcus in 2013, helped invent dgit. Since then we have had a lot of support: most recently political support to help get tag2upload deployed, but also, over the years, helpful bug reports and kind words from our users, as well as translations and code contributions. Many other people have contributed more generally to support for working with Debian source code in git. We particularly want to mention Guido G nther (git-buildpackage); and of course Alexander Wirt, Joerg Jaspert, Thomas Goirand and Antonio Terceiro (Salsa administrators); and before them the Alioth administrators.

comment count unavailable comments

19 December 2025

Otto Kek l inen: Backtesting trailing stop-loss strategies with Python and market data

Featured image of post Backtesting trailing stop-loss strategies with Python and market dataIn January 2024 I wrote about the insanity of the Magnificent Seven dominating the MSCI World Index, and I wondered how long the number can continue to go up? It has continued to surge upward at an accelerating pace, which makes me worry that a crash is likely closer. As a software professional, I decided to analyze whether using stop-loss orders could reliably automate avoiding deep drawdowns. As everyone with some savings in the stock market (hopefully) knows, the stock market eventually experiences crashes. It is just a matter of when and how deep the crash will be. Staying on the sidelines for years is not a good investment strategy, as inflation will erode the value of your savings. Assuming the current true inflation rate is around 7%, a restaurant dinner that costs 20 euros today will cost 24.50 euros in three years. Savings of 1000 euros today would drop in purchasing power from 50 dinners to only 40 dinners in three years. Hence, if you intend to retain the value of your hard-earned savings, they need to be invested in something that grows in value. Most people try to beat inflation by buying shares in stable companies, directly or via broad market ETFs. These historically grow faster than inflation during normal years, but likely drop in value during recessions.

What is a trailing stop-loss order? What if you could buy stocks to benefit from their value increasing without having to worry about a potential crash? All modern online stock brokers have a feature called stop-loss, where you can enter a price at which your stocks automatically get sold if they drop down to that price. A trailing stop-loss order is similar, but instead of a fixed price, you enter a margin (e.g. 10%). If the stock price rises, the stop-loss price will trail upwards by that margin. For example, if you buy a share at 100 euros and it has risen to 110 euros, you can set a 10% trailing stop-loss order which automatically sells it if the price drops 10% from the peak of 110 euros, at 99 euros. Thus, no matter what happens, you only lost 1 euro. And if the stock price continues to rise to 150 euros, the trailing stop-loss would automatically readjust to 150 euros minus 10%, which is 135 euros (150-15=135). If the price dropped to 135 euros, you would lock in a gain of 35 euros, which is not the peak price of 150 euros, but still better than whatever the price fell down to as a result of a large crash. In the simple case above, it obviously makes sense in theory, but it might not make sense in practice. Prices constantly oscillate, so you don t want a margin that is too small, otherwise you exit too early. Conversely, having a large margin may result in too large a drawdown before exiting. If markets crash rapidly, it might be that nobody buys your stocks at the stop-loss price, and shares have to be sold at an even lower price. Also, what will you do once the position is sold? The reason you invested in the stock market was to avoid holding cash, so would you buy the same stock back when the crash bottoms? But how will you know when the bottom has been reached?

Backtesting stock market strategies with Python, YFinance, Pandas and Lightweight Charts I am not a professional investor, and nobody should take investment advice from me. However, I know what backtesting is and how to leverage open source software. So, I wrote a Python script to test if the trading strategy of using trailing stop-loss orders with specific margin values would have worked for a particular stock. First you need to have data. YFinance is a handy Python library that can be used to download the historic price data for any stock ticker on Yahoo.com. Then you need to manipulate the data. Pandas is the Python data analysis library with advanced data structures for working with relational or labeled data. Finally, to visualize the results, I used Lightweight Charts, which is a fast, interactive library for rendering financial charts, allowing you to plot the stock price, the trailing stop-loss line, and the points where trades would have occurred. I really like how the zoom is implemented in Lightweight Charts, which makes drilling into the data points feel effortless. The full solution is not polished enough to be published for others to use, but you can piece together your own by reusing some of the key snippets. To avoid re-downloading the same data repeatedly, I implemented a small caching wrapper that saves the data locally (as Parquet files):
python
CACHE_DIR.mkdir(parents=True, exist_ok=True)
end_date = datetime.today().strftime("%Y-%m-%d")
cache_file = CACHE_DIR / f" TICKER - START_DATE -- end_date .parquet"

if cache_file.is_file():
 dataframe = pandas.read_parquet(cache_file)
 print(f"Loaded price data from cache:  cache_file ")
else:
 dataframe = yfinance.download(
 TICKER,
 start=START_DATE,
 end=end_date,
 progress=False,
 auto_adjust=False
 )

 dataframe.to_parquet(cache_file)
 print(f"Fetched new price data from Yahoo Finance and cached to:  cache_file ")
The dataframe is a Pandas object with a powerful API. For example, to print a snippet from the beginning and the end of the dataframe to see what the data looks like, you can use:
python
print("First 5 rows of the raw data:")
print(df.head())
print("Last 5 rows of the raw data:")
print(df.tail())
Example output:
First 5 rows of the raw data
Price Adj Close Close High Low Open Volume
Ticker BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA
Date
2014-01-02 29.956285 55.540001 56.910000 55.349998 56.700001 316552
2014-01-03 30.031801 55.680000 55.990002 55.290001 55.580002 210044
2014-01-06 30.080338 55.770000 56.230000 55.529999 55.560001 185142
2014-01-07 30.943321 57.369999 57.619999 55.790001 55.880001 370397
2014-01-08 31.385597 58.189999 59.209999 57.750000 57.790001 489940
Last 5 rows of the raw data
Price Adj Close Close High Low Open Volume
Ticker BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA
Date
2025-12-11 78.669998 78.669998 78.919998 76.900002 76.919998 357918
2025-12-12 78.089996 78.089996 80.269997 78.089996 79.470001 280477
2025-12-15 79.080002 79.080002 79.449997 78.559998 78.559998 233852
2025-12-16 78.860001 78.860001 79.980003 78.809998 79.430000 283057
2025-12-17 80.080002 80.080002 80.150002 79.080002 79.199997 262818
Adding new columns to the dataframe is easy. For example, I used a custom function to calculate the Relative Strength Index (RSI). To add a new column RSI with a value for every row based on the price from that row, only one line of code is needed, without custom loops:
python
df["RSI"] = compute_rsi(df["price"], period=14)
After manipulating the data, the series can be converted into an array structure and printed as JSON into a placeholder in an HTML template:
python
 baseline_series = [
  "time": ts, "value": val 
 for ts, val in df_plot[["timestamp", BASELINE_LABEL]].itertuples(index=False)
 ]

 baseline_json = json.dumps(baseline_series)
 template = jinja2.Template("template.html")
 rendered_html = template.render(
 title=title,
 heading=heading,
 description=description_html,
 ...
 baseline_json=baseline_json,
 ...
 )

 with open("report.html", "w", encoding="utf-8") as f:
 f.write(rendered_html)
 print("Report generated!")
In the HTML template, the marker variable in Jinja syntax gets replaced with the actual JSON:
html
<!DOCTYPE html>
<html lang="en">
<head>
 <meta charset="UTF-8">
 <title>  title  </title>
 ...
</head>
<body>
 <h1>  heading  </h1>
 <div id="chart"></div>
 <script>
 // Ensure the DOM is ready before we initialise the chart
 document.addEventListener('DOMContentLoaded', () =>  
 // Parse the JSON data passed from Python
 const baselineData =   baseline_json   safe  ;
 const strategyData =   strategy_json   safe  ;
 const markersData =   markers_json   safe  ;

 // Create the chart
 const chart = LightweightCharts.createChart(document.getElementById('chart'),  
 width: document.getElementById('chart').clientWidth,
 height: 500,
 layout:  
 background:   color: "#222"  ,
 textColor: "#ccc"
  ,
 grid:  
 vertLines:   color: "#555"  ,
 horzLines:   color: "#555"  
  
  );

 // Add baseline series
 const baselineSeries = chart.addLineSeries( 
 title: '  baseline_label  ',
 lastValueVisible: false,
 priceLineVisible: false,
 priceLineWidth: 1
  );
 baselineSeries.setData(baselineData);

 baselineSeries.priceScale().applyOptions( 
 entireTextOnly: true
  );

 // Add strategy series
 const strategySeries = chart.addLineSeries( 
 title: '  strategy_label  ',
 lastValueVisible: false,
 priceLineVisible: false,
 color: '#FF6D00'
  );
 strategySeries.setData(strategyData);

 // Add buy/sell markers to the strategy series
 strategySeries.setMarkers(markersData);

 // Fit the chart to show the full data range (full zoom)
 chart.timeScale().fitContent();
  )
 </script>
</body>
</html>
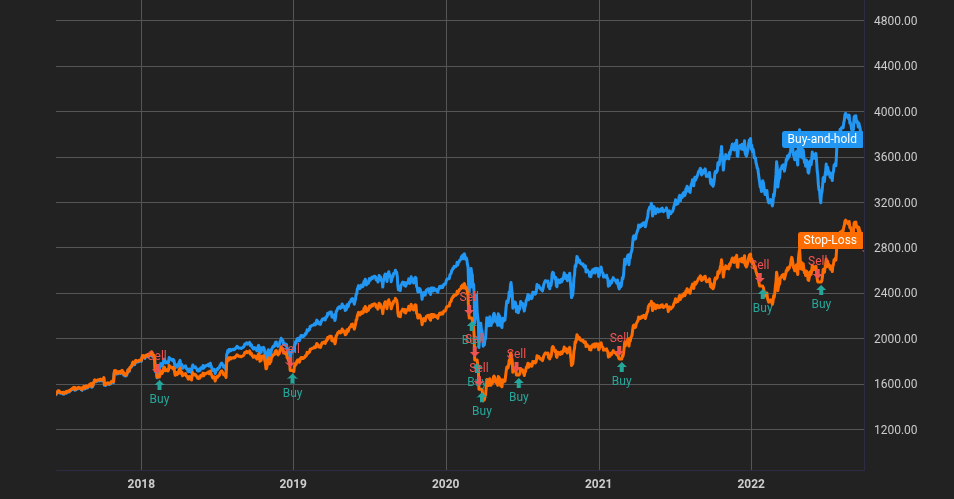
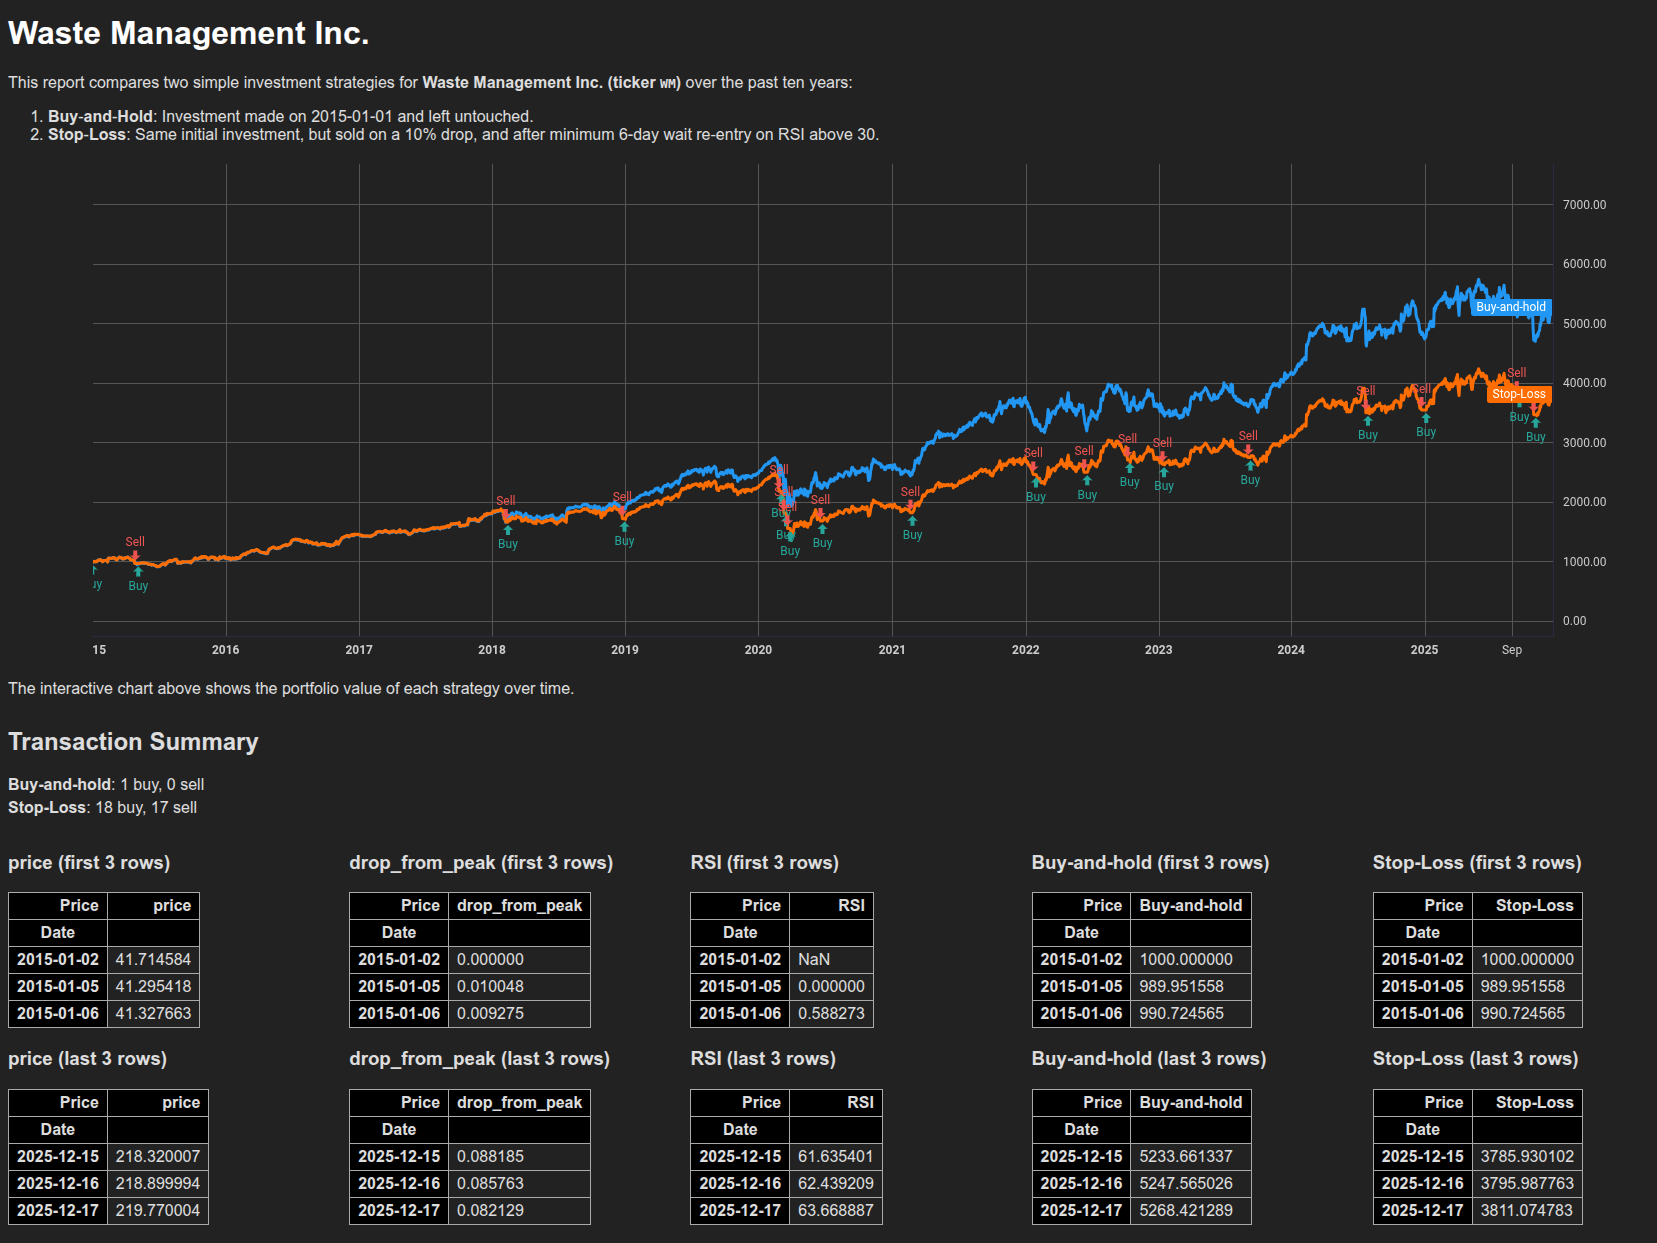
There are also Python libraries built specifically for backtesting investment strategies, such as Backtrader and Zipline, but they do not seem to be actively maintained, and probably have too many features and complexity compared to what I needed for doing this simple test. The screenshot below shows an example of backtesting a strategy on the Waste Management Inc stock from January 2015 to December 2025. The baseline Buy and hold scenario is shown as the blue line and it fully tracks the stock price, while the orange line shows how the strategy would have performed, with markers for the sells and buys along the way. Backtest run example

Results I experimented with multiple strategies and tested them with various parameters, but I don t think I found a strategy that was consistently and clearly better than just buy-and-hold. It basically boils down to the fact that I was not able to find any way to calculate when the crash has bottomed based on historical data. You can only know in hindsight that the price has stopped dropping and is on a steady path to recovery, but at that point it is already too late to buy in. In my testing, most strategies underperformed buy-and-hold because they sold when the crash started, but bought back after it recovered at a slightly higher price. In particular when using narrow margins and selling on a 3-6% drawdown the strategy performed very badly, as those small dips tend to recover in a few days. Essentially, the strategy was repeating the pattern of selling 100 stocks at a 6% discount, then being able to buy back only 94 shares the next day, then again selling 94 shares at a 6% discount, and only being able to buy back maybe 90 shares after recovery, and so forth, never catching up to the buy-and-hold. The strategy worked better in large market crashes as they tended to last longer, and there were higher chances of buying back the shares while the price was still low. For example, in the 2020 crash selling at a 20% drawdown was a good strategy, as the stock I tested dropped nearly 50% and remained low for several weeks; thus, the strategy bought back the stocks while the price was still low and had not yet started to climb significantly. But that was just a lucky incident, as the delta between the trailing stop-loss margin of 20% and total crash of 50% was large enough. If the crash had been only 25%, the strategy would have missed the rebound and ended up buying back the stocks at a slightly higher price. Also, note that the simulation assumes that the trade itself is too small to affect the price formation. We should keep in mind that in reality, if many people have stop-loss orders in place, a large price drop would trigger all of them, creating a flood of sell orders, which in turn would affect the price and drive it lower even faster and deeper. Luckily, it seems that stop-loss orders are generally not a good strategy, and we don t need to fear that too many people will be using them.

Conclusion Even though using a trailing stop-loss strategy does not seem to help in getting consistently higher returns based on my backtesting, I would still say it is useful in protecting from the downside of stock investing. It can act as a kind of insurance policy to considerably decrease the chances of losing big while increasing the chances of losing a little bit. If you are risk-averse, which I think I probably am, this tradeoff can make sense. I d rather miss out on an initial 50% loss and an overall 3% gain on recovery than have to sit through weeks or months with a 50% loss before the price recovers to prior levels. Most notably, the trailing stop-loss strategy works best if used only once. If it is repeated multiple times, the small losses in gains will compound into big losses overall. Thus, I think I might actually put this automation in place at least on the stocks in my portfolio that have had the highest gains. If they keep going up, I will ride along, but once the crash happens, I will be out of those particular stocks permanently. Do you have a favorite open source investment tool or are you aware of any strategy that actually works? Comment below!

18 December 2025

Dirk Eddelbuettel: dang 0.0.17: New Features, Plus Maintenance

dang image A new release of my mixed collection of things package dang package arrived at CRAN earlier today. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!), the overbought/oversold price band plotter from an older blog post, the market monitor blogged about as well as the checkCRANStatus() function tweeted about by Tim Taylor. And more so take a look. This release retires two functions: the social media site nobody ever visits anymore shut down its API too, so no way to mute posts by a given handle. Similarly, the (never official) ability by Google to supply financial data is no more, so the function to access data this way is gone too. But we also have two new ones: one that helps with CRAN entries for ORCiD ids, and another little helper to re-order microbenchmark results by summary column (defaulting to the median). Other than the usual updates to continuous integrations, as well as a switch to Authors@R which will result in CRAN nagging me less about this, and another argument update. The detailed NEWS entry follows.

Changes in version 0.0.17 (2025-12-18)
  • Added new funtion reorderMicrobenchmarkResults with alias rmr
  • Use tolower on email argument to checkCRANStatus
  • Added new function cranORCIDs bootstrapped from two emails by Kurt Hornik
  • Switched to using Authors@R in DESCRIPTION and added ORCIDs where available
  • Switched to r-ci action with included bootstrap step; updated updated the checkout action (twice); added (commented-out) log accessor
  • Removed googleFinanceData as the (unofficial) API access point no longer works
  • Removed muteTweeters because the API was turned off

Via my CRANberries, there is a comparison to the previous release. For questions or comments use the the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Colin Watson: Preparing a transition in Debusine

We announced a public beta of Debusine repositories recently (Freexian blog, debian-devel-announce). One thing I m very keen on is being able to use these to prepare transitions : changes to multiple packages that need to be prepared together in order to land in testing. As I said in my DebConf25 talk:
We have distribution-wide CI in unstable, but there s only one of it and it s shared between all of us. As a result it s very possible to get into tangles when multiple people are working on related things at the same time, and we only avoid that as much as we do by careful coordination such as transition bugs. Experimental helps, but again, there s only one of it and setting up another one is far from trivial. So, what we want is a system where you can run experiments on possible Debian changes at a large scale without a high setup cost and without fear of breaking things for other people. And then, if it all works, push the whole lot into Debian.
Time to practice what I preach. Setup The setup process is documented on the Debian wiki. You need to decide whether you re working on a short-lived experiment, in which case you ll run the create-experiment workflow and your workspace will expire after 60 days of inactivity, or something that you expect to keep around for longer, in which case you ll run the create-repository workflow. Either one of those will create a new workspace for you. Then, in that workspace, you run debusine archive suite create for whichever suites you want to use. For the case of a transition that you plan to land in unstable, you ll most likely use create-experiment and then create a single suite with the pattern sid-<name>. The situation I was dealing with here was moving to Pylint 4. Tests showed that we needed this as part of adding Python 3.14 as a supported Python version, and I knew that I was going to need newer upstream versions of the astroid and pylint packages. However, I wasn t quite sure what the fallout of a new major version of pylint was going to be. Fortunately, the Debian Python ecosystem has pretty good autopkgtest coverage, so I thought I d see what Debusine said about it. I created an experiment called cjwatson-pylint (resulting in https://debusine.debian.net/debian/developers-cjwatson-pylint/ - I m not making that a proper link since it will expire in a couple of months) and a sid-pylint suite in it. Iteration From this starting point, the basic cycle involved uploading each package like this for each package I d prepared:
$ dput -O debusine_workspace=developers-cjwatson-pylint \
       -O debusine_workflow=publish-to-sid-pylint \
       debusine.debian.net foo.changes
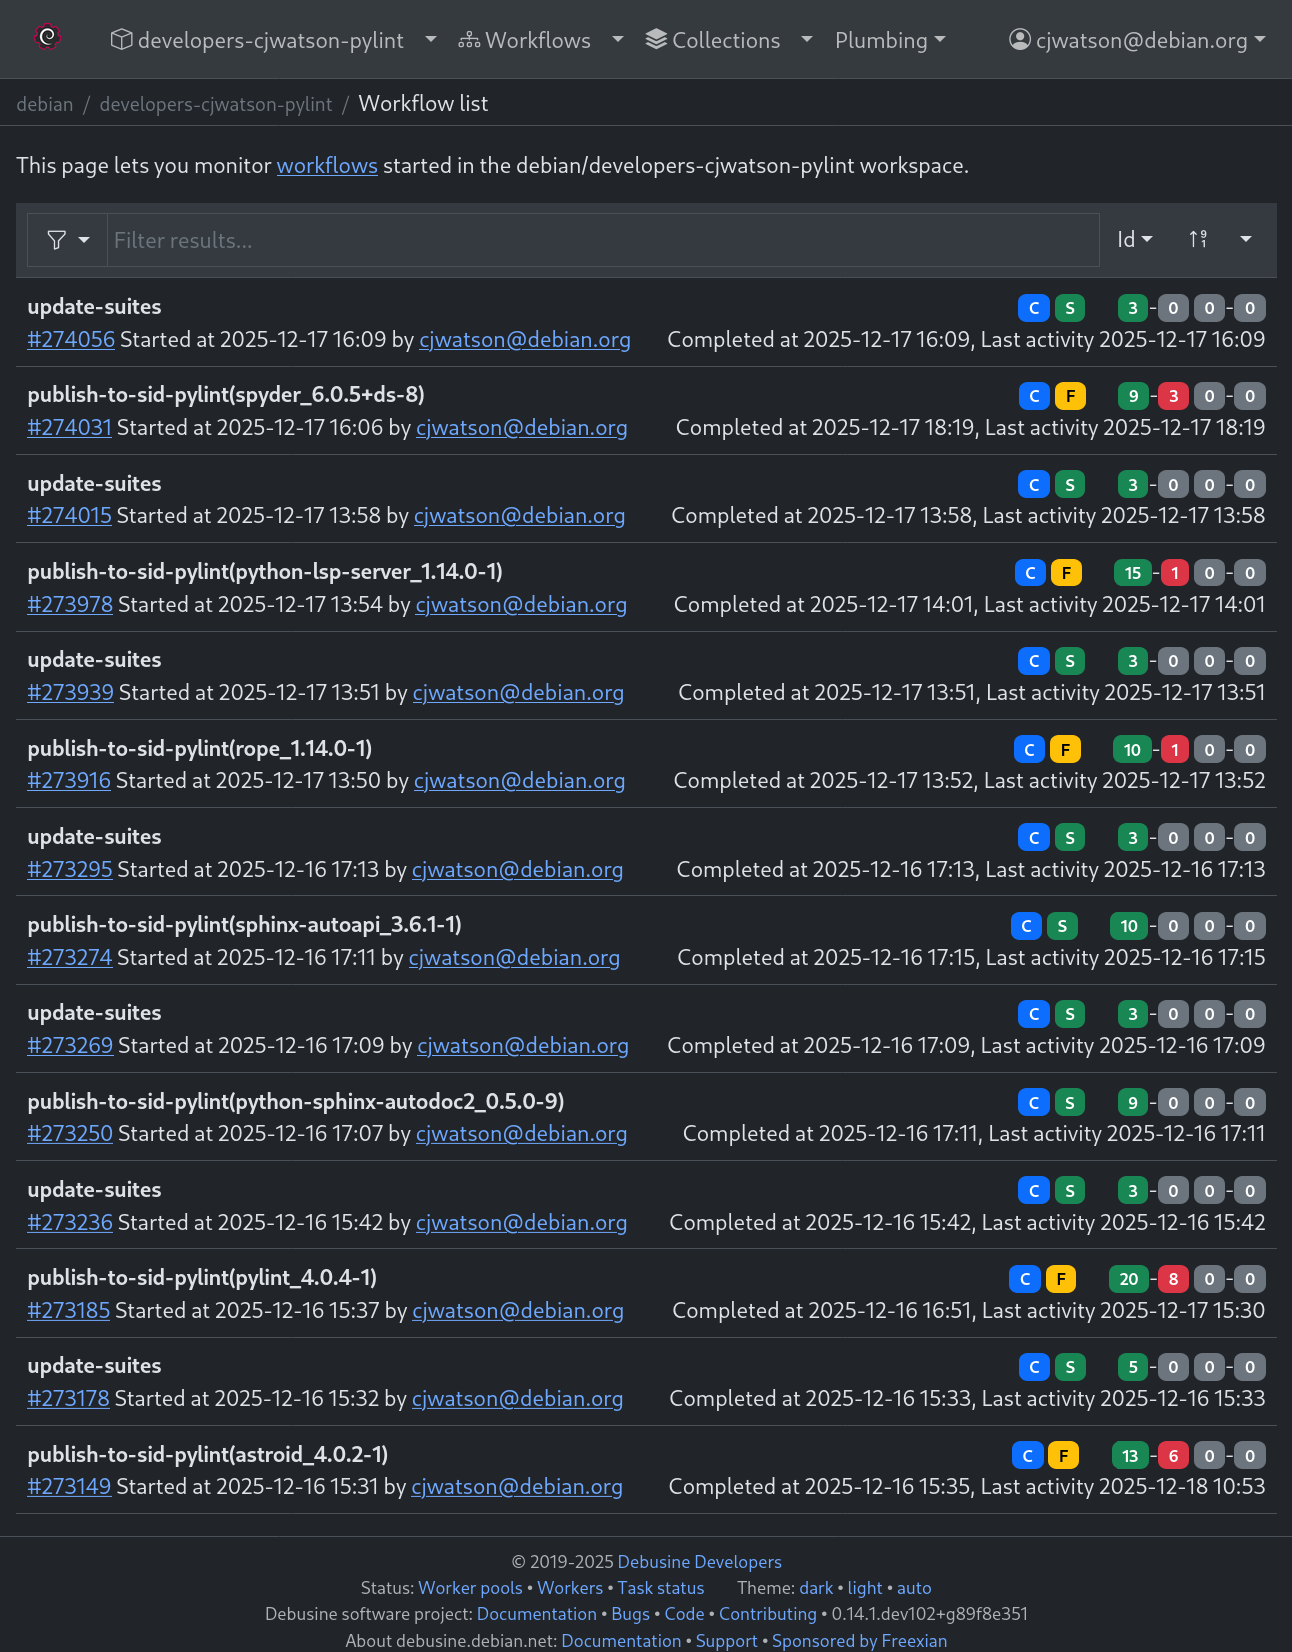
I could have made a new dput-ng profile to cut down on typing, but it wasn t worth it here. Then I looked at the workflow results, figured out which other packages I needed to fix based on those, and repeated until the whole set looked coherent. Debusine automatically built each upload against whatever else was currently in the repository, as you d expect. I should probably have used version numbers with tilde suffixes (e.g. 4.0.2-1~test1) in case I needed to correct anything, but fortunately that was mostly unnecessary. I did at least run initial test-builds locally of just the individual packages I was directly changing to make sure that they weren t too egregiously broken, just because I usually find it quicker to iterate that way. I didn t take screenshots as I was going along, but here s what the list of top-level workflows in my workspace looked like by the end: Workflows You can see that not all of the workflows are successful. This is because we currently just show everything in every workflow; we don t consider whether a task was retried and succeeded on the second try, or whether there s now a newer version of a reverse-dependency so tests of the older version should be disregarded, and so on. More fundamentally, you have to look through each individual workflow, which is a bit of a pain: we plan to add a dashboard that shows you the current state of a suite as a whole rather than the current workflow-oriented view, but we haven t started on that yet. Drilling down into one of these workflows, it looks something like this: astroid workflow This was the first package I uploaded. The first pass of failures told me about pylint (expected), pylint-flask (an obvious consequence), and python-sphinx-autodoc2 and sphinx-autoapi (surprises). The slightly odd pattern of failures and errors is because I retried a few things, and we sometimes report retries in a slightly strange way, especially when there are workflows involved that might not be able to resolve their input parameters any more. The next level was: pylint workflow Again, there were some retries involved here, and also some cases where packages were already failing in unstable so the failures weren t the fault of my change; for now I had to go through and analyze these by hand, but we ll soon have regression tracking to compare with reference runs and show you where things have got better or worse. After excluding those, that left pytest-pylint (not caused by my changes, but I fixed it anyway in unstable to clear out some noise) and spyder. I d seen people talking about spyder on #debian-python recently, so after a bit of conversation there I sponsored a rope upload by Aeliton Silva, upgraded python-lsp-server, and patched spyder. All those went into my repository too, exposing a couple more tests I d forgotten in spyder. Once I was satisfied with the results, I uploaded everything to unstable. The next day, I looked through the tracker as usual starting from astroid, and while there are some test failures showing up right now it looks as though they should all clear out as pieces migrate to testing. Success! Conclusions We still have some way to go before this is a completely smooth experience that I d be prepared to say that every developer can and should be using; there are all sorts of fit-and-finish issues that I can easily see here. Still, I do think we re at the point where a tolerant developer can use this to deal with the common case of a mid-sized transition, and get more out of it than they put in. Without Debusine, either I d have had to put much more effort into searching for and testing reverse-dependencies myself, or (more likely, let s face it) I d have just dumped things into unstable and sorted them out afterwards, resulting in potentially delaying other people s work. This way, everything was done with as little disruption as possible. This works best when the packages likely to be involved have reasonably good autopkgtest coverage (even if the tests themselves are relatively basic). This is an increasingly good bet in Debian, but we have plans to add installability comparisons (similar to how Debian s testing suite works) as well as optional rebuild testing. If this has got you interested, please try it out for yourself and let us know how it goes!
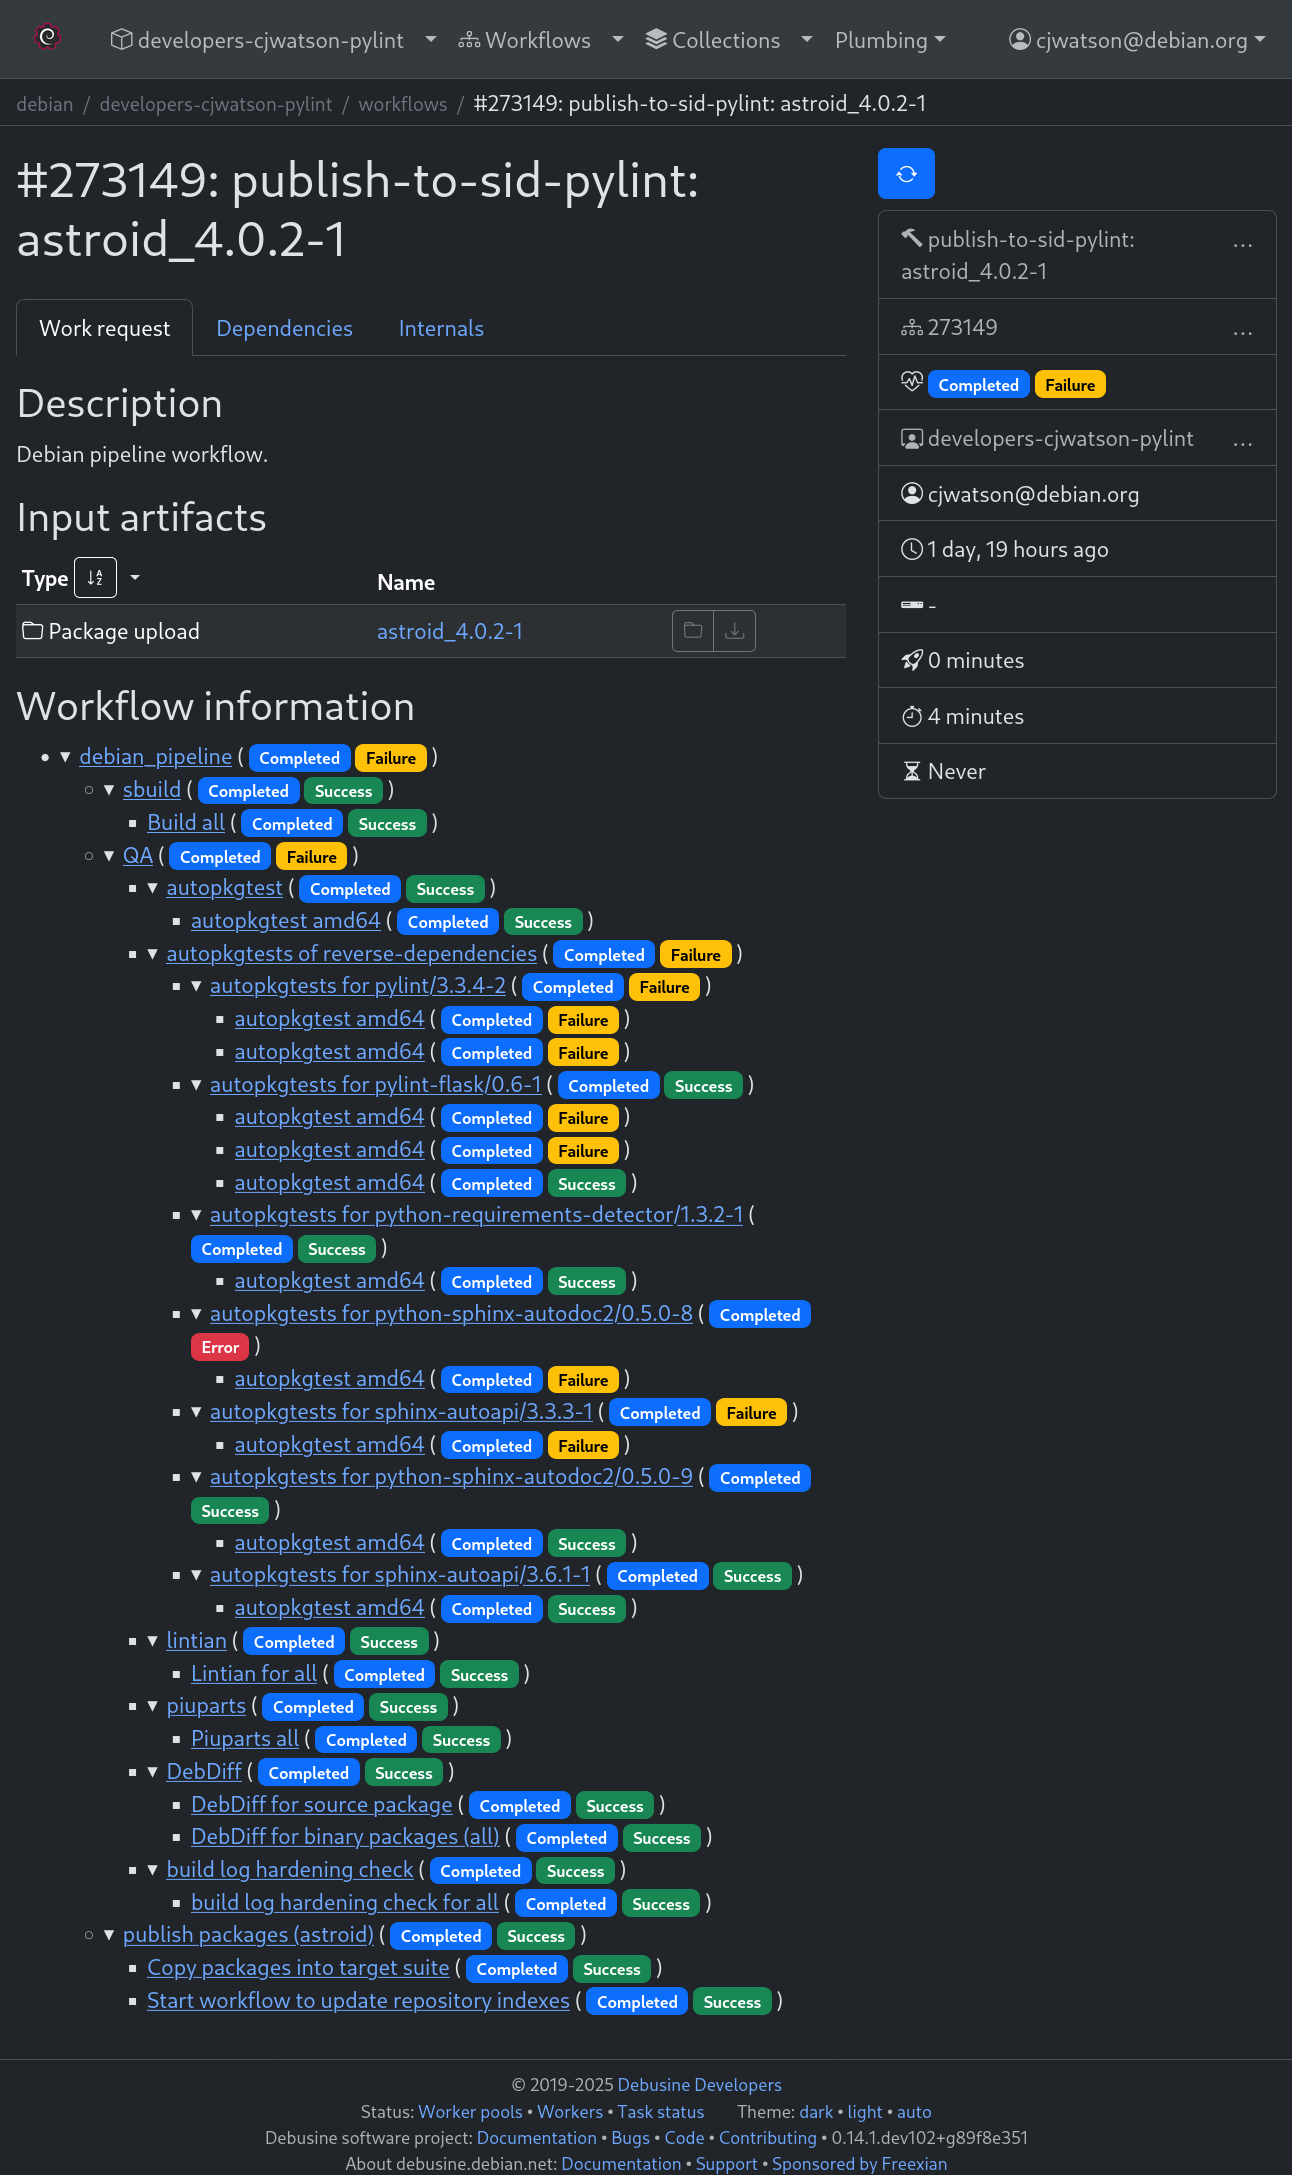
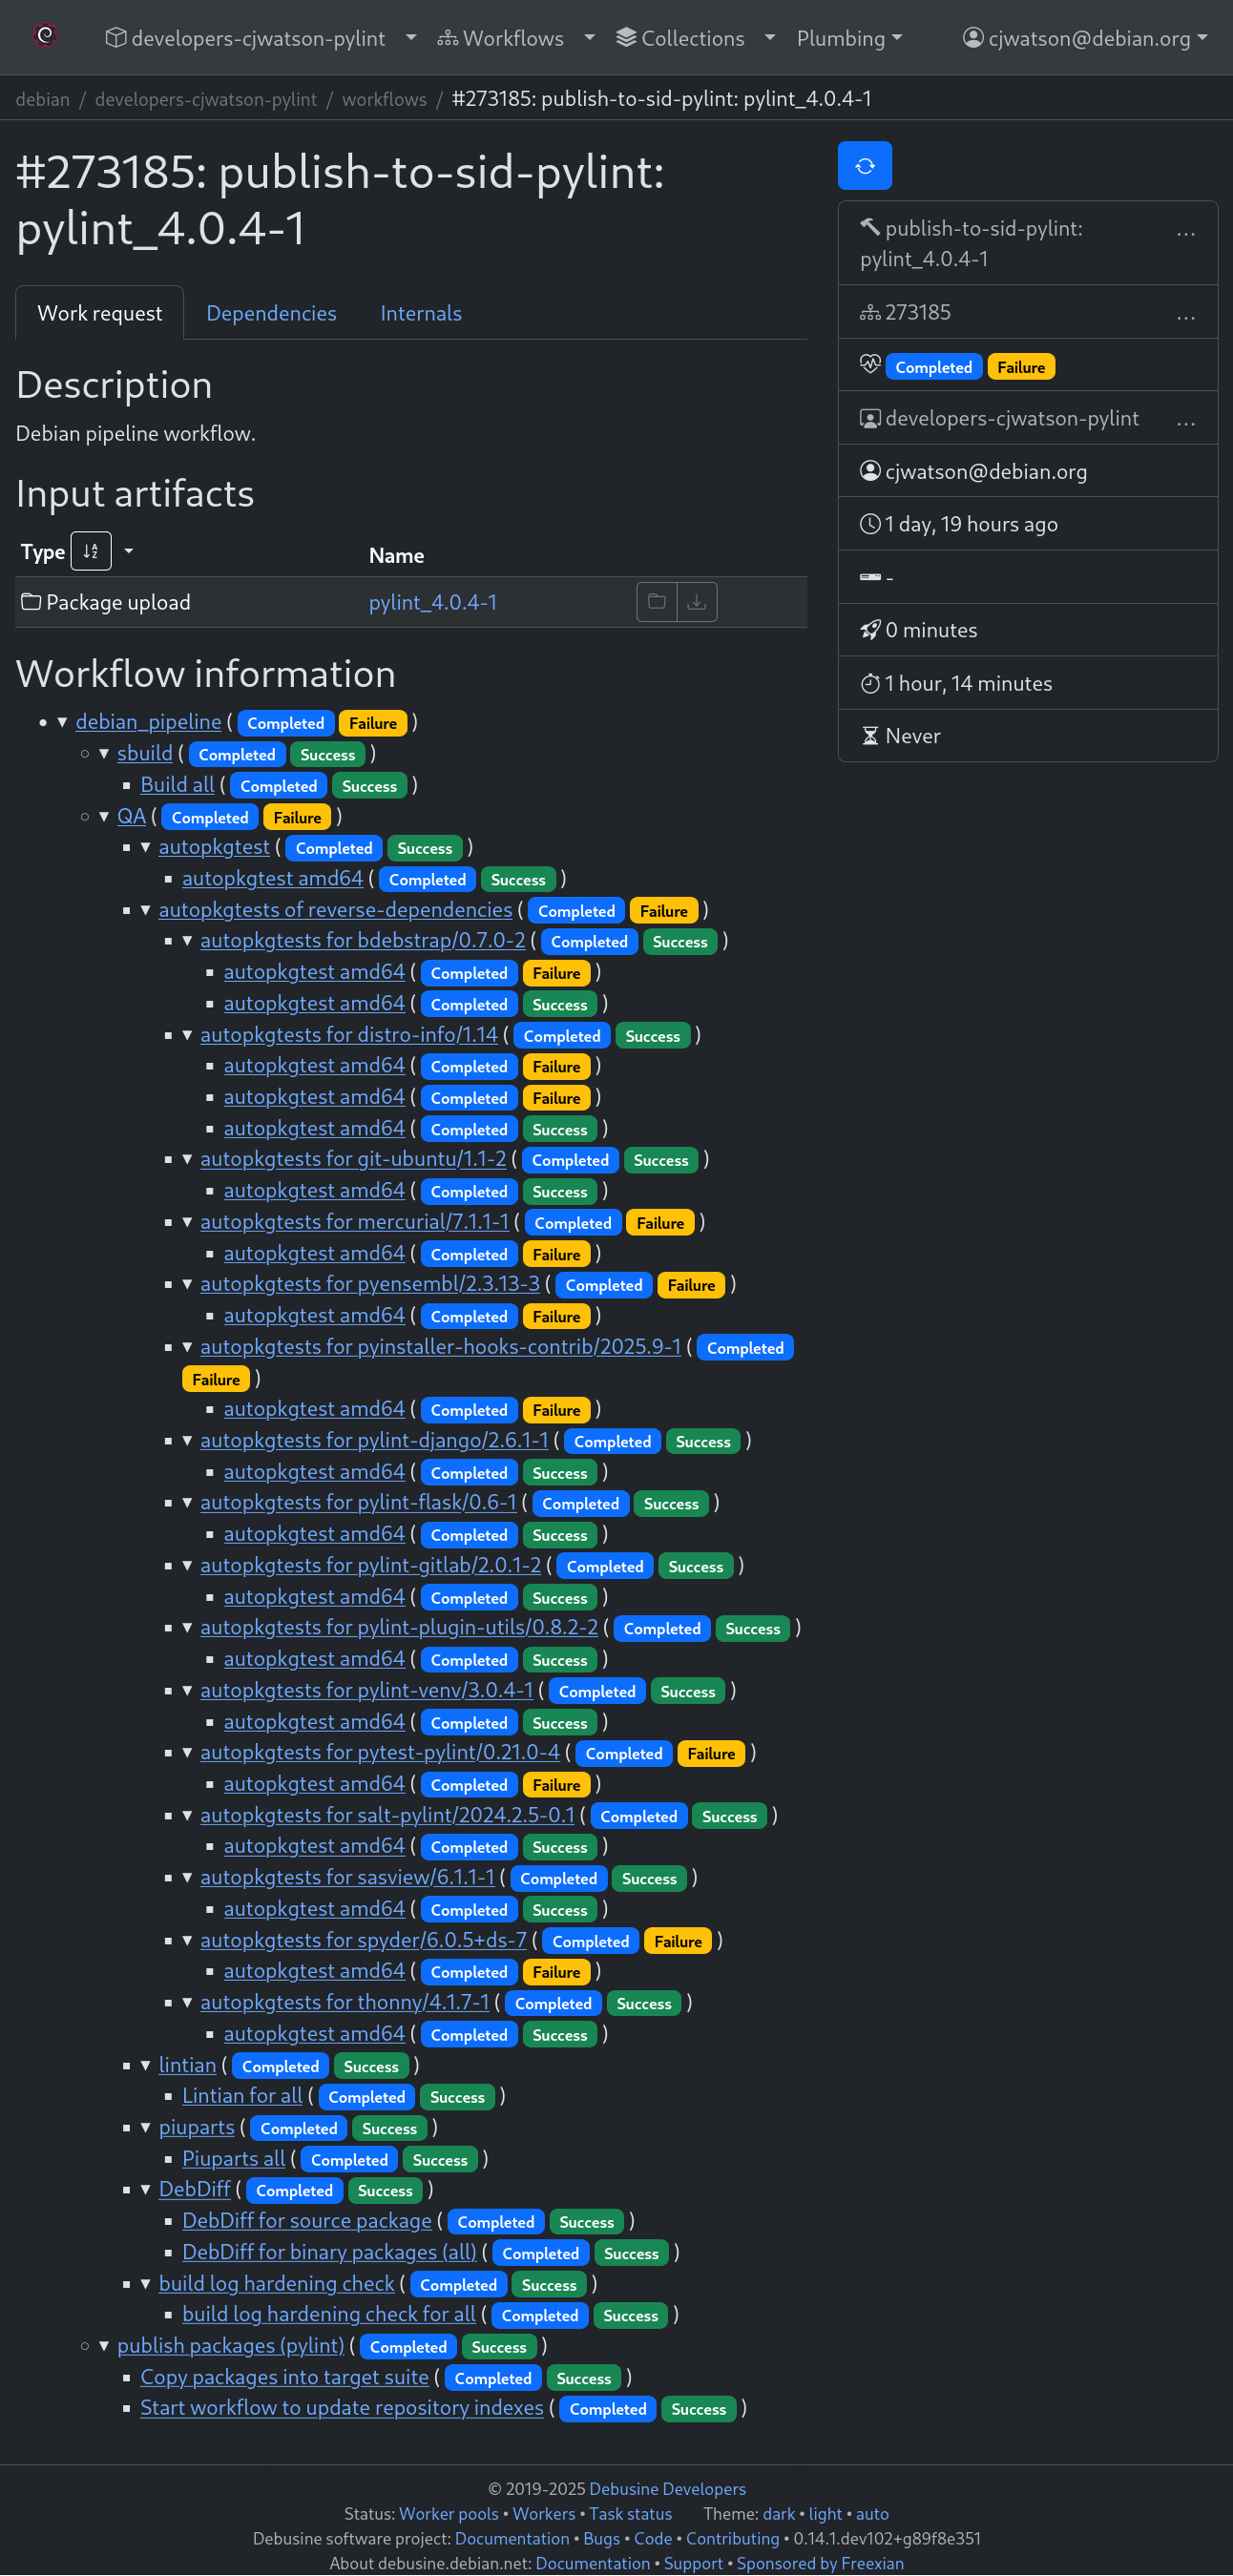
17 December 2025

Sven Hoexter: exfatprogs: Do not try defrag.exfat / mkfs.exfat Windows compatibility in Trixie

exfatprogs 1.3.0 added a new defrag.exfat utility which turned out to be not reliable and cause data loss. exfatprogs 1.3.1 disabled the utility, and I followed that decision with the upload to Debian/unstable yesterday. But as usual it will take some time until it's migrating to testing. Thus if you use testing do not try defag.exfat! At least not without a vetted and current backup. Beside of that there is a compatibility issue with the way mkfs.exfat, as shipped in trixie (exfatprogs 1.2.9), handles drives which have a physical sector size of 4096 bytes but emulate a logical size of 512 bytes. With exfatprogs 1.2.6 a change was implemented to prefer the physical sector size on those devices. That turned out to be not compatible with Windows, and was reverted in exfatprogs 1.3.0. Sadly John Ogness ran into the issue and spent some time to debug it. I've to admit that I missed the relevance of that change. Huge kudos to John for the bug report. Based on that I prepared an update for the next trixie point release. If you hit that issue on trixie with exfatprogs 1.2.9-1 you can work around it by formating with mkfs.exfat -s 512 /dev/sdX to get Windows compatibility. If you use exfatprogs 1.2.9-1+deb13u1 or later, and want the performance gain back, and do not need Windows compatibility, you can format with mkfs.exfat -s 4096 /dev/sdX.

Dirk Eddelbuettel: RcppArmadillo 15.2.3-1 on CRAN: Upstream Update

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1272 other packages on CRAN, downloaded 43.2 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 661 times according to Google Scholar. This versions updates to the 15.2.3 upstream Armadillo release from yesterday. It brings minor changes over the RcppArmadillo 15.2.2 release made last month (and described in this post). As noted previously, and due to both the upstream transition to C++14 coupled with the CRAN move away from C++11, the package offers a transition by allowing packages to remain with the older, pre-15.0.0 legacy Armadillo yet offering the current version as the default. If and when CRAN will have nudged (nearly) all maintainers away from C++11 (and now also C++14 !!) we can remove the fallback. Our offer to help with the C++ modernization still stands, so please get in touch if we can be of assistance. As a reminder, the meta-issue #475 regroups all the resources for the C++11 transition. There were no R-side changes in this release. The detailed changes since the last release follow.

Changes in RcppArmadillo version 15.2.3-1 (2025-12-16)
  • Upgraded to Armadillo release 15.2.3 (Medium Roast Deluxe)
    • Faster .resize() for vectors
    • Faster repcube()

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Matthew Garrett: How did IRC ping timeouts end up in a lawsuit?

I recently won a lawsuit against Roy and Rianne Schestowitz, the authors and publishers of the Techrights and Tuxmachines websites. The short version of events is that they were subject to an online harassment campaign, which they incorrectly blamed me for. They responded with a large number of defamatory online posts about me, which the judge described as unsubstantiated character assassination and consequently awarded me significant damages. That's not what this post is about, as such. It's about the sole meaningful claim made that tied me to the abuse.

In the defendants' defence and counterclaim[1], 15.27 asserts in part The facts linking the Claimant to the sock puppet accounts include, on the IRC network: simultaneous dropped connections to the mjg59_ and elusive_woman accounts. This is so unlikely to be coincidental that the natural inference is that the same person posted under both names. "elusive_woman" here is an account linked to the harassment, and "mjg59_" is me. This is actually a surprisingly interesting claim to make, and it's worth going into in some more detail.

The event in question occurred on the 28th of April, 2023. You can see a line reading *elusive_woman has quit (Ping timeout: 2m30s), followed by one reading *mjg59_ has quit (Ping timeout: 2m30s). The timestamp listed for the first is 09:52, and for the second 09:53. Is that actually simultaneous? We can actually gain some more information - if you hover over the timestamp links on the right hand side you can see that the link is actually accurate to the second even if that's not displayed. The first event took place at 09:52:52, and the second at 09:53:03. That's 11 seconds apart, which is clearly not simultaneous, but maybe it's close enough. Figuring out more requires knowing what a "ping timeout" actually means here.

The IRC server in question is running Ergo (link to source code), and the relevant function is handleIdleTimeout(). The logic here is fairly simple - track the time since activity was last seen from the client. If that time is longer than DefaultIdleTimeout (which defaults to 90 seconds) and a ping hasn't been sent yet, send a ping to the client. If a ping has been sent and the timeout is greater than DefaultTotalTimeout (which defaults to 150 seconds), disconnect the client with a "Ping timeout" message. There's no special logic for handling the ping reply - a pong simply counts as any other client activity and resets the "last activity" value and timeout.

What does this mean? Well, for a start, two clients running on the same system will only have simultaneous ping timeouts if their last activity was simultaneous. Let's imagine a machine with two clients, A and B. A sends a message at 02:22:59. B sends a message 2 seconds later, at 02:23:01. The idle timeout for A will fire at 02:24:29, and for B at 02:24:31. A ping is sent for A at 02:24:29 and is responded to immediately - the idle timeout for A is now reset to 02:25:59, 90 seconds later. The machine hosting A and B has its network cable pulled out at 02:24:30. The ping to B is sent at 02:24:31, but receives no reply. A minute later, at 02:25:31, B quits with a "Ping timeout" message. A ping is sent to A at 02:25:59, but receives no reply. A minute later, at 02:26:59, A quits with a "Ping timeout" message. Despite both clients having their network interrupted simultaneously, the ping timeouts occur 88 seconds apart.

So, two clients disconnecting with ping timeouts 11 seconds apart is not incompatible with the network connection being interrupted simultaneously - depending on activity, simultaneous network interruption may result in disconnections up to 90 seconds apart. But another way of looking at this is that network interruptions may occur up to 90 seconds apart and generate simultaneous disconnections[2]. Without additional information it's impossible to determine which is the case.

This already casts doubt over the assertion that the disconnection was simultaneous, but if this is unusual enough it's still potentially significant. Unfortunately for the Schestowitzes, even looking just at the elusive_woman account, there were several cases where elusive_woman and another user had a ping timeout within 90 seconds of each other - including one case where elusive_woman and schestowitz[TR] disconnect 40 seconds apart. By the Schestowitzes argument, it's also a natural inference that elusive_woman and schestowitz[TR] (one of Roy Schestowitz's accounts) are the same person.

We didn't actually need to make this argument, though. In England it's necessary to file a witness statement describing the evidence that you're going to present in advance of the actual court hearing. Despite being warned of the consequences on multiple occasions the Schestowitzes never provided any witness statements, and as a result weren't allowed to provide any evidence in court, which made for a fairly foregone conclusion.

[1] As well as defending themselves against my claim, the Schestowitzes made a counterclaim on the basis that I had engaged in a campaign of harassment against them. This counterclaim failed.

[2] Client A and client B both send messages at 02:22:59. A falls off the network at 02:23:00, has a ping sent at 02:24:29, and has a ping timeout at 02:25:29. B falls off the network at 02:24:28, has a ping sent at 02:24:29, and has a ping timeout at 02:25:29. Simultaneous disconnects despite over a minute of difference in the network interruption.

comment count unavailable comments

16 December 2025

Christian Kastner: Simple-PPA, a minimalistic PPA implementation

Today, the Debusine developers launched Debusine repositories, a beta implementation of PPAs. In the announcement, Colin remarks that "[d]iscussions about this have been happening for long enough that people started referring to PPAs for Debian as 'bikesheds'"; a characterization that I'm sure most will agree with. So it is with great amusement that on this same day, I launch a second PPA implementation for Debian: Simple-PPA. Simple-PPA was never meant to compete with Debusine, though. In fact, it's entirely the opposite: from discussions at DebConf, I knew that it was only a matter of time until Debusine gained a PPA-like feature, but I needed a stop-gap solution earlier, and with some polish, what was once by Python script already doing APT processing for apt.ai.debian.net, recently became Simple-PPA. Consequently, Simple-PPA lacks (and will always lack) all of the features that Debusine offers: there is no auto-building, no CI, nor any other type of QA. It's the simplest possible type of APT repository: you just upload packages, they get imported into an archive, and the archive is exposed via a web server. Under the hood, reprepro does all the heavy lifting. However, this also means it's trivial to set up. The following is the entire configuration that simple-ppa.debian.net started with:
# simple-ppa.conf
[CORE]
SignWith = 2906D748B7551BC8
ExportDir = /srv/www/simple-ppa
MailFrom: Simple-PPA <admin@simple-ppa.debian.net>
Codenames = sid forky trixie trixie-backports bookworm bookworm-backports
AlsoAllow = forky: unstable
            trixie: unstable
            bookworm: unstable
[simple-ppa-dev]
Label = Simple-PPA's self-hosted development repository
# ckk's key
Uploaders = allow * by key E76004C5CEF0C94C+
[ckk]
Label = Christian Kastner at Simple-PPA
Uploaders = allow * by key E76004C5CEF0C94C+
The CORE section just sets some defaults and sensible rules. Two PPAs are defined, simple-ppa-dev and ckk, which accept packages signed by the key with the ID E76004C5CEF0C94C. These PPAs use the global defaults, but individual PPAs can override Architectures, Suites, and Components, and of course allow an arbitrary number of users. Users upload to this archive using SFTP (e.g.: with dput-ng). Every 15 minutes, uploads get processed, with ACCEPTED or REJECTED mails sent to the Maintainer address. The APT archive of all PPAs is signed with a single global key. I myself intend to use Debusine repositories soon, as the autobuilding and the QA tasks Debusine offers are something I need. However, I do still see a niche use case for Simple-PPA: when you need an APT archive, but don't want to do a deep dive into reprepro (which is extremely powerful). If you'd like to give Simple-PPA a try, head over to simple-ppa.debian.net and follow the instructions for users.

Freexian Collaborators: Debusine repositories now in beta (by Colin Watson)

We re happy to announce that Debusine can now be used to maintain APT-compatible add-on package repositories for Debian. This facility is available in public beta to Debian developers and maintainers.

Why? Debian developers typically put most of their effort towards maintaining the main Debian archive. However, it s often useful to have other places to work, for various reasons:
  • Developers working on a set of packages might need to check that changes to several of them all work properly together on a real system.
  • Somebody fixing a bug might need to ask affected users to test the fix before uploading it to Debian.
  • Some projects are difficult to package in a way that meets Debian policy, or are too niche to include in Debian, but it s still useful to distribute them in a packaged form.
  • For some packages, it s useful to provide multiple upstream versions for multiple Debian releases, even though Debian itself would normally want to keep that to a minimum.
The Ubuntu ecosystem has had PPAs for a long time to meet these sorts of needs, but people working directly on Debian have had to make do with putting things together themselves using something like reprepro or aptly. Discussions about this have been happening for long enough that people started referring to PPAs for Debian as bikesheds , and users often find themselves trying to use Ubuntu PPAs on Debian systems and hoping that dependencies will be compatible enough for things to more or less work. This clearly isn t ideal, and solving it is one of Freexian s objectives for Debusine. Developers publishing packages to Debusine repositories can take advantage of all Debusine s existing facilities, including a battery of QA tests and regression tracking (coming soon). Repositories are signed using per-repository keys held in Debusine s signing service, and uploads to repositories are built against the current contents of that repository as well as the corresponding base Debian release. All repositories include automatic built-in snapshot capabilities.

Who can use this service? We ve set up debusine.debian.net to allow using repositories. All Debian Developers and Debian Maintainers can log in there and publish packages to it. The resulting repositories are public by default. debusine.debian.net only allows packages with licences that allow distribution by Debian, and it is intended primarily for work that could reasonably end up in Debian; Freexian reserves the right to remove repositories from it.

How can I use it? If you are a Debian contributor, we d be very excited to have you try this out, especially if you give us feedback. We have published instructions for developers on using this. Since this is a beta service, you can expect things to change, but we ll maintain compatibility where we can. If you re interested in using this in a commercial setting, please contact Freexian to discuss what we can do for you.

15 December 2025

Gunnar Wolf: Unique security and privacy threats of large language models a comprehensive survey

This post is an unpublished review for Unique security and privacy threats of large language models a comprehensive survey
Much has been written about large language models (LLMs) being a risk to user security and privacy, including the issue that, being trained with datasets whose provenance and licensing are not always clear, they can be tricked into producing bits of data that should not be divulgated. I took on reading this article as means to gain a better understanding of this area. The article completely fulfilled my expectations. This is a review article, which is not a common format for me to follow: instead of digging deep into a given topic, including an experiment or some way of proofing the authors claims, a review article will contain a brief explanation and taxonomy of the issues at hand, and a large number of references covering the field. And, at 36 pages and 151 references, that s exactly what we get. The article is roughly split in two parts: The first three sections present the issue of security and privacy threats as seen by the authors, as well as the taxonomy within which the review will be performed, and sections 4 through 7 cover the different moments in the life cycle of a LLM model (at pre-training, during fine-tuning, when deploying systems that will interact with end-users, and when deploying LLM-based agents), detailing their relevant publications. For each of said moments, the authors first explore the nature of the relevant risks, then present relevant attacks, and finally close outlining countermeasures to said attacks. The text is accompanied all throughout its development with tables, pipeline diagrams and attack examples that visually guide the reader. While the examples presented are sometimes a bit simplistic, they are a welcome guide and aid to follow the explanations; the explanations for each of the attack models are necessarily not very deep, and I was often left wondering I correctly understood a given topic, or wanting to dig deeper but being this a review article, it is absolutely understandable. The authors present an easy to read prose, and this article covers an important spot in understanding this large, important, and emerging area of LLM-related study.

Russ Allbery: Review: Brigands & Breadknives

Review: Brigands & Breadknives, by Travis Baldree
Series: Legends & Lattes #3
Publisher: Tor
Copyright: 2025
ISBN: 1-250-33489-6
Format: Kindle
Pages: 325
Brigands & Breadknives is a secondary-world sword-and-sorcery fantasy and a sequel to both Legends & Lattes and Bookshops & Bonedust. It takes place shortly after Legends & Lattes chronologically, but Fern, the protagonist, was introduced in the Bookshops & Bonedust prequel. You may have noticed I didn't describe this as cozy fantasy. That is intentional. When we left Fern at the end of Bookshops & Bonedust, the rattkin was running a bookshop in the town of Murk. As Brigands & Breadknives opens, Fern is moving, for complicated and hard-to-describe personal reasons, to Thune where Viv has her coffee shop. Her plan is to open a new bookstore next door to Legends and Lattes. This is exactly the sort of plot one might expect from this series, and the first few chapters feel like yet another version of the first two novels. Then Fern makes an impulsive and rather inexplicable (even to herself) decision and the plot goes delightfully sideways. Brigands & Breadknives is not, as Baldree puts it in the afterword, a book about fantasy small-business ownership as the answer to all of life's woes. It is, instead, a sword and sorcery story about a possibly immortal elven bounty hunter, her utterly baffling goblin prisoner, and a rattkin bookseller who becomes their unexpected travel companion for reasons she can't explain. It's a story about a mid-life crisis in a world and with supporting characters that I can only describe as inspired by a T. Kingfisher novel. Baldree is not Ursula Vernon, of course. This book does not contain paladins or a romance, possibly to the relief of some readers. It's slower, a bit more introspective, and doesn't have as sharp of edges or the casual eerie unsettlingness. But there is a religious order that worships a tentacled space horror for entirely unexpected reasons, pompous and oleaginous talking swords with verbose opinions about everything, a mischievously chaotic orange-haired goblin who quickly became one of my favorite fantasy characters and then kept getting better, and a whole lot of heart. You may see why Kingfisher was my first thought for a comparison point. Unlike Baldree's previous novels, there is a lot of combat and injury. I think some people will still describe this book as cozy, and I'm not going to argue too strongly because the conflicts are a bit lighter than the sort of rape and murder one would see in a Mercedes Lackey novel. But to me this felt like sword and sorcery in a Dungeons and Dragons universe made more interesting by letting the world-building go feral and a little bit sarcastic. Most of the book is spent traveling, there are a lot of random encounters that build into a connected plot, and some scenes (particularly the defense of the forest village) felt like they could have sold to the Swords and Sorceress anthology series. Also, this was really good! I liked both Legends & Lattes and Bookshops & Bonedust, maybe a bit more than the prevailing opinion among reviewers since the anachronisms never bothered me, but I wasn't sure whether to dive directly into this book because I was expecting more of the same. This is not more of the same. I think it's clearly better writing and world-building than either of the previous books. It helps that Fern is the protagonist; as much as I like Viv, I think Fern is a more interesting character, and I am glad she got a book of her own. Baldree takes a big risk on the emotional arc of this book. Fern starts the story in a bad state and makes some decisions to kick off the plot that are difficult to defend. She beats herself up for those decisions for most of the book, deservedly, and parts of that emotional turmoil are difficult to read. Baldree resists the urge to smooth everything over and instead provides a rather raw sense of depression, avoidance, and social anxiety that some readers are going to have to brace themselves for. I respect the decision to not write the easy series book people probably expected, but I'm not sure Fern's emotional arc quite worked. Baldree is hinting at something that's hard to describe logically, and I'm not sure he was able to draw a clear enough map of Fern's thought process for the reader to understand her catharsis. The "follow your passion" self-help mindset has formed a gravitational singularity in the vicinity of this book's theme, it takes some skillful piloting to avoid being sucked into its event horizon, and I don't think Baldree quite managed to escape it. He made a valiant attempt, though, and it created a far more interesting book than one about safer emotions. I wanted more of an emotional payoff than I got, but the journey, even with the moments of guilt and anxiety, was so worth it. The world-building is funnier and more interesting than the previous books of the series, and the supporting cast is fantastic. If you bailed on the series but you like sword and sorcery and T. Kingfisher novels, consider returning. You do probably need to read Bookshops & Bonedust first, if you haven't already, since it helps to know the start of Fern's story. Recommended, and shortcomings aside, much better than I had expected. Content notes: Bloody sword fights, major injury, some very raw emotions about letting down friends and destroying friendships. Rating: 8 out of 10

14 December 2025

Evgeni Golov: Home Assistant, Govee Lights Local, VLANs, Oh my!

We recently bought some Govee Glide Hexa Light Panels, because they have a local LAN API that is well integrated into Home Assistant. Or so we thought. Our network is not that complicated, but there is a dedicated VLAN for IOT devices. Home Assistant runs in a container (with network=host) on a box in the basement, and that box has a NIC in the IOT VLAN so it can reach devices there easily. So far, this has never been a problem. Enter the Govee LAN API. Or maybe its Python implementation. Not exactly sure who's to blame here. The API involves sending JSON over multicast, which the Govee device will answer to.
No devices found on the network
After turning logging for homeassistant.components.govee_light_local to 11, erm debug, we see:
DEBUG (MainThread) [homeassistant.components.govee_light_local.config_flow] Starting discovery with IP 192.168.42.2
DEBUG (MainThread) [homeassistant.components.govee_light_local.config_flow] No devices found with IP 192.168.42.2
That's not the IP address in the IOT VLAN! Turns out the integration recently got support for multiple NICs, but Home Assistant doesn't just use all the interfaces it sees by default. You need to go to Settings Network Network adapter and deselect "Autoconfigure", which will allow your to select individual interfaces. Once you've done that, you'll see Starting discovery with IP messages for all selected interfaces and adding of Govee Lights Local will work.

11 December 2025

Dirk Eddelbuettel: #056: Running r-ci with R-devel

Welcome to post 56 in the R4 series. The recent post #54 reviewed a number of earlier posts on r-ci, our small (but very versatile) runner for continunous integration (CI) with R. The post also introduced the notion of using a container in the matrix of jobs defined and running in parallel. The initial motivation was the (still ongoing, and still puzzling) variation in run-times of GitHub Actions. So when running CI and relying on r2u for the fast, easy, reliable: pick all three! provision of CRAN packages as Ubuntu binaries, a small amount of time is spent prepping a basic Ubuntu instance with the necessary setup. This can be as fast as maybe 20 to 30 seconds, but it can also stretch to almost two minutes when GitHub is busier or out of sorts for other reasons. When the CI job itself is short, that is a nuisance. We presented relying on a pre-made r2u4ci container that adds just a few commands to the standard r2u container to be complete for CI. And with that setup CI runs tend to be reliably faster. This situation is still evolving. I have not converted any of my existing CI scripts (apart from a test instance or two), but I keep monitoring the situation. However, this also offered another perspective: why not rely on a different container for a different CI aspect? When discussing the CI approach with Jeff the other day (and helping add CI to his mmap repo), it occurred to me we could also use on of the Rocker containers for R-devel. A minimal change to the underlying run.sh script later, this was accomplished. An example is provided as both a test and an illustration in the repo for package RcppInt64 in its script ci.yaml:
    strategy:
      matrix:
        include:
          -   name: container, os: ubuntu-latest, container: rocker/r2u4ci  
          -   name: r-devel,   os: ubuntu-latest, container: rocker/drd  
          -   name: macos,     os: macos-latest  
          -   name: ubuntu,    os: ubuntu-latest  

    runs-on: $  matrix.os  
    container: $  matrix.container  
This runs both a standard Ubuntu setup (fourth entry) and the alternate just described relying on the container (first entry) along with the (usually commented-out) optional macOS setup (third entry). And line two brings the drd container from Rocker. The CI runner script now checks for a possible Rdevel binary as provided inside drd (along with alias RD) and uses it when present. And that is all that there is: no other change on the user side; tests now run under R-devel. You can see some of the initial runs at the rcppint64 repo actions log. Another example is now also at Jeff s mmap repo. It should be noted that this relies on R-devel running packages made with R-release. Every few years this breaks when R needs to break its binary API. If and when that happens this option will be costlier as the R-devel instance will then have to (re-)install its R package dependencies. This can be accomodated easily as a step in the yaml file. And under normal circumstances it is not needed. Having easy access to recent builds of R-devel (the container refreshes weekly on a schedule) with the convenience of r2u gives another option for package testing. I may continue to test locally with R-devel as my primary option, and most likely keep my CI small and lean (usually just one R-relase run on Ubuntu) but having another option at GitHub Actions is also a good thing.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

8 December 2025

Isoken Ibizugbe: Beginning My Outreachy Journey With Debian

Hello, my name is Isoken, I m a software engineer and product manager from Nigeria. I am excited and grateful to begin this journey as an Outreachy intern working on the project Debian Images Testing with OpenQA . I am particularly drawn to helping solve problems for people; it keeps bugging me till I can find a way to help. This interest in problem-solving and improving quality is what drew me to this project. OpenQA is an automated test tool that simulates a user s interaction by looking at the screen and sending actions like mouse clicks and keyboard inputs. It takes screenshots and compares the image to known reference images to verify if the system is behaving correctly. During the contribution phase (which was 4 weeks), I got to know about Debian software, it s different mode of installation and available different desktop environments, at first I felt intimidated as most of it was new to me, but the setup material and docs for the project made it easy for me, the fact that it looked like a gradual process, getting to know the program, registering the steps in mind and then take notes of every step and visuals, writing it in a way another developer would understand (this is called detail level 3), and then translate it to test code level 1. I contributed to improving the installation documents and a detail level 3 doc for a bug report on the system locale being incorrect. This strengthened my documentation skills and ability to adjust to the writing style of the project. I also started working on app start-stop tests for two desktop environments. I was able to explore, check the applications, and note their differences and similarities. It was really interesting to me; this was where I started writing on coding level 1, and my tests started passing. I will spend the next few weeks continuing on it and hopefully creating a way to synergize the tests and make it easy to maintain later on. I am also grateful for the assistance from other candidates during the contribution stage and the privilege of having the mentors, Tassia Camoes Araujo and Roland Clobus, and Philip Hands, to guide and correct me through the internship period. I will share my progress regularly here on the blog. You can follow the progress of the work here on the main repo. Wish me luck on the rest of this journey

Thorsten Alteholz: My Debian Activities in November 2025

Debian LTS/ELTS This was my hundred-thirty-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian and my eighty-eighth ELTS month. As the LTS- and ELTS-teams have been merged now, there is only one paragraph left for both activities. During my allocated time I uploaded or worked on: I also attended the monthly LTS/ELTS meeting and did a week of LTS/ELTS frontdesk duties. I also stumbled upon a bug in python3-paramiko, where the parsing of include statements in the ssh_config does not work. Rather annoying but already fixed in the newest version, that only needs to find its way to my old VM. Debian Printing This month I uploaded a new upstream version or a bugfix version of: I also uploaded cups to Trixie, to fix bug #1109471 related to a configuration problem with the admin panel. This work is generously funded by Freexian! Debian Astro This month I uploaded a new upstream version or a bugfix version of: Debian IoT This month I uploaded a new upstream version or a bugfix version of: Debian Mobcom This month I uploaded a new upstream version or a bugfix version of: misc This month I uploaded a new upstream version or a bugfix version of: On my fight against outdated RFPs, I closed 30 of them in November. I started with about 3500 open RFP bugs. and after working six months on this project, I have closed 183 bugs. Of course new bugs appeared, so the overall number of bugs is only down to about 3360. Though I view this as a successful project, I also have to admit that it is a bit boring to work on this daily. Therefore I close this diary again and will add the closed RFP bugs to my bug logbook now. I also try to close some of these bugs by really uploading some software, probably one package per month. FTP master This month I accepted 236 and rejected 16 packages. The overall number of packages that got accepted was 247.

Fran ois Marier: Learning a new programming language with an LLM

I started learning Go this year. First, I picked a Perl project I wanted to rewrite, got a good book and ignored AI tools since I thought they would do nothing but interfere with learning. Eventually though, I decided to experiment a bit and ended up finding a few ways to use AI assistants effectively even when learning something new.

Searching more efficiently The first use case that worked for me was search. Instead of searching on a traditional search engine and then ending up on Stack Overflow, I could get the answer I was looking for directly in an AI side-window in my editor. Of course, that's bad news for Stack Overflow. I was however skeptical from the beginning since LLMs make mistakes, sometimes they making up function signatures or APIs that don't exist. Therefore I got into the habit of going to the official standard library documentation to double-check suggestions. For example, if the LLM suggests using strings.SplitN, I verify the function signature and behaviour carefully before using it. Basically, "don't trust and do verify." I stuck to the standard library in my project, but if an LLM recommends third-party dependencies for you, make sure they exist and that Socket doesn't flag them as malicious. Research has found that 5-20% of packages suggested by LLMs don't actually exist, making this a real attack vector (dubbed "slopsquatting").

Autocomplete is too distracting A step I took early on was to disable AI autocomplete in my editor. When learning a new language, you need to develop muscle memory for the syntax. Also, Go is no Java. There's not that much boilerplate to write in general. I found it quite distracting to see some almost correct code replace my thinking about the next step. I can see how one could go faster with these suggestions, but being a developer is not just about cranking out lines of code as fast as possible, it's also about constantly learning new things (and retaining them).

Asking about idiomatic code One of the most useful prompts when learning a new language is "Is this the most idiomatic way to do this in Go?". Large language models are good at recognizing patterns and can point out when you're writing code that works but doesn't follow the conventions of the language. This is especially valuable early on when you don't yet have a feel for what "good" code looks like in that language. It's usually pretty easy (at least for an experience developer) to tell when the LLM suggestion is actually counter productive or wrong. If it increases complexity or is harder to read/decode, it's probably not a good idea to do it.

Reviews One way a new dev gets better is through code review. If you have access to a friend who's an expert in the language you're learning, then you can definitely gain a lot by asking for feedback on your code. If you don't have access to such a valuable resource, or as a first step before you consult your friend, I found that AI-assisted code reviews can be useful:
  1. Get the model to write the review prompt for you. Describe what you want reviewed and let it generate a detailed prompt.
  2. Feed that prompt to multiple models. They each have different answers and will detect different problems.
  3. Be prepared to ignore 50% of what they recommend. Some suggestions will be stylistic preferences, others will be wrong, or irrelevant.
The value is in the other 50%: the suggestions that make you think about your code differently or catch genuine problems. Similarly for security reviews:
  • A lot of what they flag will need to be ignored (false positives, or things that don't apply to your threat model).
  • Some of it may highlight areas for improvement that you hadn't considered.
  • Occasionally, they will point out real vulnerabilities.
But always keep in mind that AI chatbots are trained to be people-pleasers and often feel the need to suggest something when nothing was needed

An unexpected benefit One side effect of using AI assistants was that having them write the scaffolding for unit tests motivated me to increase my code coverage. Trimming unnecessary test cases and adding missing ones is pretty quick when the grunt work is already done, and I ended up testing more of my code (being a personal project written in my own time) than I might have otherwise.

Learning In the end, I continue to believe in the value of learning from quality books (I find reading paper-based most effective). In addition, I like to create Anki questions for common mistakes or things I find I have to look up often. Remembering something will always be faster than asking an AI tool. So my experience this year tells me that LLMs can supplement traditional time-tested learning techniques, but I don't believe it obsoletes them. P.S. I experimented with getting an LLM to ghost-write this post for me from an outline (+ a detailed style guide) and I ended up having to rewrite at least 75% of it. It was largely a waste of time.

7 December 2025

Vincent Bernat: Compressing embedded files in Go

Go s embed feature lets you bundle static assets into an executable, but it stores them uncompressed. This wastes space: a web interface with documentation can bloat your binary by dozens of megabytes. A proposition to optionally enable compression was declined because it is difficult to handle all use cases. One solution? Put all the assets into a ZIP archive!

Code The Go standard library includes a module to read and write ZIP archives. It contains a function that turns a ZIP archive into an io/fs.FS structure that can replace embed.FS in most contexts.1
package embed
import (
  "archive/zip"
  "bytes"
  _ "embed"
  "fmt"
  "io/fs"
  "sync"
)
//go:embed data/embed.zip
var embeddedZip []byte
var dataOnce = sync.OnceValue(func() *zip.Reader  
  r, err := zip.NewReader(bytes.NewReader(embeddedZip), int64(len(embeddedZip)))
  if err != nil  
    panic(fmt.Sprintf("cannot read embedded archive: %s", err))
   
  return r
 )
func Data() fs.FS  
  return dataOnce()
 
We can build the embed.zip archive with a rule in a Makefile. We specify the files to embed as dependencies to ensure changes are detected.
common/embed/data/embed.zip: console/data/frontend console/data/docs
common/embed/data/embed.zip: orchestrator/clickhouse/data/protocols.csv 
common/embed/data/embed.zip: orchestrator/clickhouse/data/icmp.csv
common/embed/data/embed.zip: orchestrator/clickhouse/data/asns.csv
common/embed/data/embed.zip:
    mkdir -p common/embed/data && zip --quiet --recurse-paths --filesync $@ $^
The automatic variable $@ is the rule target, while $^ expands to all the dependencies, modified or not.

Space gain Akvorado, a flow collector written in Go, embeds several static assets:
  • CSV files to translate port numbers, protocols or AS numbers, and
  • HTML, CSS, JS, and image files for the web interface, and
  • the documentation.
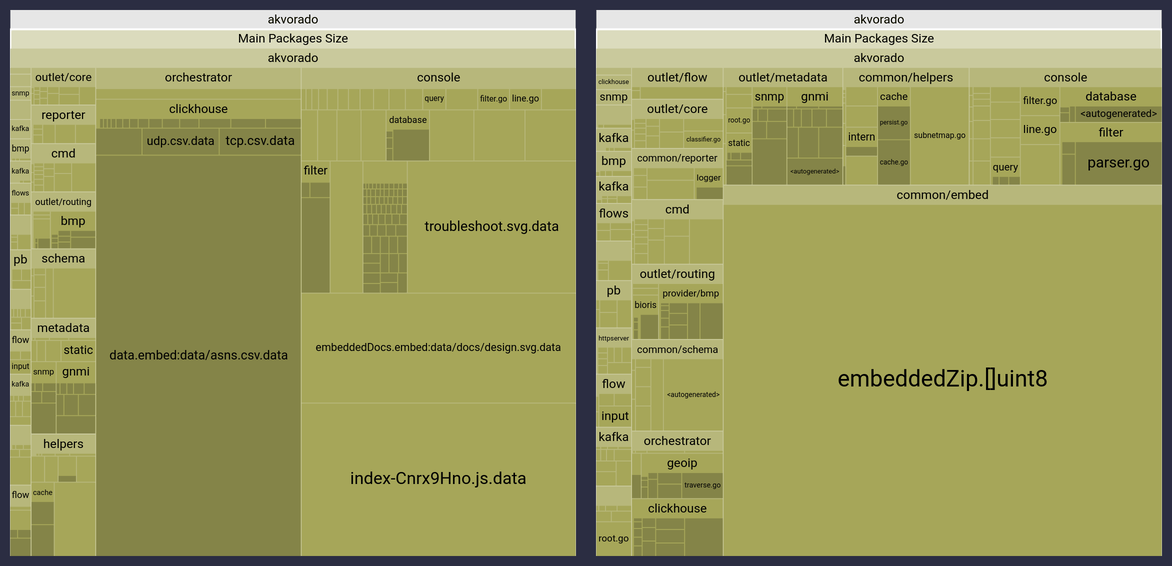
Breakdown of space used by each package before and after introducing embed.zip. It is displayed as a treemap and we can see many embedded files replaced by a bigger one.
Breakdown of the space used by each component before (left) and after (right) the introduction of embed.zip.
Embedding these assets into a ZIP archive reduced the size of the Akvorado executable by more than 4 MiB:
$ unzip -p common/embed/data/embed.zip   wc -c   numfmt --to=iec
7.3M
$ ll common/embed/data/embed.zip
-rw-r--r-- 1 bernat users 2.9M Dec  7 17:17 common/embed/data/embed.zip

Performance loss Reading from a compressed archive is not as fast as reading a flat file. A simple benchmark shows it is more than 4 slower. It also allocates some memory.2
goos: linux
goarch: amd64
pkg: akvorado/common/embed
cpu: AMD Ryzen 5 5600X 6-Core Processor
BenchmarkData/compressed-12     2262   526553 ns/op   610 B/op   10 allocs/op
BenchmarkData/uncompressed-12   9482   123175 ns/op     0 B/op    0 allocs/op
Each access to an asset requires a decompression step, as seen in this flame graph:
&#128444; Flame graph when reading data from embed.zip compared to reading data directly
CPU flame graph comparing the time spent on CPU when reading data from embed.zip (left) versus reading data directly (right). Because the Go testing framework executes the benchmark for uncompressed data 4 times more often, it uses the same horizontal space as the benchmark for compressed data. The graph is interactive.
While a ZIP archive has an index to quickly find the requested file, seeking inside a compressed file is currently not possible.3 Therefore, the files from a compressed archive do not implement the io.ReaderAt or io.Seeker interfaces, unlike directly embedded files. This prevents some features, like serving partial files or detecting MIME types when serving files over HTTP.
For Akvorado, this is an acceptable compromise to save a few mebibytes from an executable of almost 100 MiB. Next week, I will continue this futile adventure by explaining how I prevented Go from disabling dead code elimination!

  1. You can safely read multiple files concurrently. However, it does not implement ReadDir() and ReadFile() methods.
  2. You could keep frequently accessed assets in memory. This reduces CPU usage and trades cached memory for resident memory.
  3. SOZip is a profile that enables fast random access in a compressed file. However, Go s archive/zip module does not support it.

Iustin Pop: Yes, still alive!

Yeah, again three months have passed since my last (trivial) post, and I really don t know where the time has flown. I suppose the biggest problem was the long summer vacation, which threw me off-track, and then craziness started. Work work work, no time for anything, which kept me fully busy in August, and then you should travel . So mid-September I went on my first business trip since Covid, again to Kirkland, which in itself was awesome. Flew out Sunday, and as I was concerned I was going to lose too much fitness had a half-marathon planned on the weekend after the return I ran every morning of the four days I was there. And of course, on the last day, I woke up even earlier (05:30 AM), went out to run before sunrise, intending to do a very simple run along the road that borders the lake for 2.5K, then back . And right at the farthest point, a hundred metres before my goal of turning around, I tripped, started falling, and as I was falling, I hit sideways a metal pole. I was in a bus station, it was the pole that has the schedule at the top, and I hit it at relatively full speed, right across my left-side ribs. The crash took the entire air out of my lungs, and I don t remember if I ever felt pain/sensation like that I was seriously not able to breathe for 20 seconds or so, and I was wondering if I m going to pass out at this rate. Only 20 seconds, because my Garmin started howling like a police siren, and the screen was saying something along the lines of: Incident detected; contacting emergency services in 40 35 and I was fumbling to cancel that, since a) I wasn t that bad, b) notifying my wife that I had a crash would have not been a smart idea. My left leg was scraped in a few places, my left hand pretty badly, or more than just scraped, so my focus was on limping back, and finding a fountain to wash my injuries, which I did, so I kept running with blood dripping down my hand. Fun fun, everything was hurting, I took an Uber for the ~1Km to the office, had many meetings, took another Uber and flew back to Zurich. Seattle San Francisco Z rich, I think 14 hours, with my ribs hurting pretty badly. But I got home (Friday afternoon), and was wondering if I can run or not on Saturday. Saturday comes, I feel pretty OK, so I said let s try, will stop if the pain is too great. I pick up my number, I go to the start, of course in the last block and not my normal block, and I start running. After 50 metres, I knew this won t be good enough, but I said, let s make it to the first kilometre. Then to the first fuelling point, then to the first aid point, at which moment I felt good enough to go to the second one. Long story short, I ran the whole half marathon, with pain. Every stop for fuelling was mentally hard, as the pain stopped, and I knew I had to start running again, and the pain would resume. In the end, managed to finish: two and a half hours, instead of just two hours, but alive and very happy. Of course, I didn t know what was waiting for me Sunday I wake up in heavy pain, and despite painkillers, I was not feeling much better. The following night was terrible, Monday morning I went to the doctor, had X-rays, discussion with a radiologist. Not really broken, but more than just bruised. See this angle here? Bones don t have angles normally . Painkillers, chest/abdomen wrapping, no running! So my attempts to not lose fitness put me off running for a couple of weeks. Then October came, and I was getting better, but work was getting even more crazy. I don t know where November passed, honestly, and now we re already in December. I did manage to run, quite well, managed to bike a tiny bit and swim a little, but I m not in a place where I can keep a regular and consistent schedule. On the good side, I managed this year, for the first time since Covid, to not get sick. Hey, a sport injury is 100 better than a sickness, like I had in previous years, taking me out for two weeks. But life was crazy enough that I didn t read some of my email accounts for months, and I m just now starting to catch up to, well, baseline. Of course, the rib the lowest one on the left side is long-healed, or so I thought. After some strength training early this week, I was very sore the next day, and I wanted to test whether my rib is still sore. I touched it at the point , and it hurt so badly I couldn t believe. Two and a half months, and it s not done-done. And now it s just two weeks before Christmas and New Year s, and that time off will ruin my rhythm again. At least ski vacation is booked, ski service is done, and slowly, work is getting in good enough shape to actually enjoy thinking about vacation. So, in the end, a very adventurous last third of the year, and that wasn t even all. As I m writing this, my right wrist is bandaged and for the past 24 hours it hasn t hurt too much, but that s another, and not so interesting, story. I ll close with a yay for always being behind/backlogged, but alive and relatively well. My sport injuries are elective injuries so to speak, and I m very thankful for that. See you in the next post!

6 December 2025

Simon Josefsson: Reproducible Guix Container Images

Around a year ago I wrote about Guix Container Images for GitLab CI/CD and these images have served the community well. Besides continous use in CI/CD, these Guix container images are used to confirm reproducibility of the source tarball artifacts in the releases of Libtasn1 v4.20, InetUtils v2.6, Libidn2 v2.3.8, Libidn v1.43, SASL v2.2.2, Guile-GnuTLS v5.0.1, and OATH Toolkit v2.6.13. See how all those release announcements mention a Guix commit? That s the essential supply-chain information about the Guix build environment that allows the artifacts to be re-created. To make sure this is repeatable, the release tarball artifacts are re-created from source code every week in the verify-reproducible-artifacts project, that I wrote about earlier. Guix s time travelling feature make this sustainable to maintain, and hopefully will continue to be able to reproduce the exact same tarball artifacts for years to come. During the last year, unfortunately Guix was removed from Debian stable. My Guix container images were created from Debian with that Guix package. My setup continued to work since the old stage0 Debian+Guix containers were still available. Such a setup is not sustainable, as there will be bit-rot and we don t want to rely on old containers forever, which (after the removal of Guix in Debian) could not be re-produced any more. Let this be a reminder how user-empowering features such as Guix time-travelling is! I have reworked my Guix container image setup, and this post is an update on the current status of this effort. The first step was to re-engineer Debian container images with Guix, and I realized these were useful on their own, and warrant a separate project. A more narrowly scoped project makes will hopefully make it easier to keep them working. Now instead of apt-get install guix they use the official Guix guix-install.sh approach. Read more about that effort in the announcement of Debian with Guix. The second step was to reconsider my approach to generate the Guix images. The earlier design had several stages. First, Debian+Guix containers were created. Then from those containers, a pure Guix container was created. Finally, using the pure Guix container another pure Guix container was created. The idea behind that GCC-like approach was to get to reproducible images that were created from an image that had no Debian left on it. However, I never managed to finish this. Partially because I hadn t realized that every time you build a Guix container image from Guix, you effectively go back in time. When using Guix version X to build a container with Guix on it, it will not put Guix version X into the container but will put whatever version of Guix is available in its package archive, which will be an earlier version, such as version X-N. I had hope to overcome this somehow (running a guix pull in newly generated images may work), but never finished this before Guix was removed from Debian. So what could a better design look like? For efficiency, I had already started experimenting with generating the final images directly from the Debian+Guix images, and after reproducibility bugs were fixed I was able to get to reproducible images. However, I was still concerned that the Debian container could taint the process somehow, and was also concerned about the implied dependency on non-free software in Debian. I ve been using comparative rebuilds using similar distributions to confirm artifact reproducibility for my software projects, comparing builds on Trisquel 11 with Ubuntu 22.04, and AlmaLinux 9 with RockyLinux 9 for example. This works surprisingly well. Including one freedom-respecting distribution like Trisquel will detect if any non-free software has bearing on artifacts. Using different architectures, such as amd64 vs arm64 also help with deeper supply-chain concerns. My conclusion was that I wanted containers with the same Guix commit for both Trisquel and Ubuntu. Given the similarity with Debian, adapting and launching the Guix on Trisquel/Debian project was straight forward. So we now have Trisquel 11/12 and Ubuntu 22.04/24.04 images with the same Guix on them. Do you see where the debian-with-guix and guix-on-dpkg projects are leading to? We are now ready to look at the modernized Guix Container Images project. The tags are the same as before:
registry.gitlab.com/debdistutils/guix/container:latest
registry.gitlab.com/debdistutils/guix/container:slim
registry.gitlab.com/debdistutils/guix/container:extra
registry.gitlab.com/debdistutils/guix/container:gash
The method to create them is different. Now there is a build job that uses the earlier Guix+Trisquel container (for amd64) or Guix+Debian (for arm64, pending Trisquel arm64 containers). The build job create the final containers directly. Next a Ubuntu reproduce job is launched that runs the same commands, failing if it cannot generate the bit-by-bit identical container. Then single-arch images are tested (installing/building GNU hello and building libksba), and then pushed to the GitLab registry, adding multi-arch images in the process. Then the final multi-arch containers are tested by building Guile-GnuTLS and, on success, uploaded to the Docker Hub. How would you use them? A small way to start the container is like this:
jas@kaka:~$ podman run -it --privileged --entrypoint=/bin/sh registry.gitlab.com/debdistutils/guix/container:latest
sh-5.2# env HOME=/ guix describe # https://issues.guix.gnu.org/74949
  guix 21ce6b3
    repository URL: https://git.guix.gnu.org/guix.git
    branch: master
    commit: 21ce6b392ace4c4d22543abc41bd7c22596cd6d2
sh-5.2# 
The need for --entrypoint=/bin/sh is because Guix s pack command sets up the entry point differently than most other containers. This could probably be fixed if people want that, and there may be open bug reports about this. The need for --privileged is more problematic, but is discussed upstream. The above example works fine without it, but running anything more elaborate with guix-daemon installing packages will trigger a fatal error. Speaking of that, here is a snippet of commands that allow you to install Guix packages in the container.
cp -rL /gnu/store/*profile/etc/* /etc/
echo 'root:x:0:0:root:/:/bin/sh' > /etc/passwd
echo 'root:x:0:' > /etc/group
groupadd --system guixbuild
for i in $(seq -w 1 10); do useradd -g guixbuild -G guixbuild -d /var/empty -s $(command -v nologin) -c "Guix build user $i" --system guixbuilder$i; done
env LANG=C.UTF-8 guix-daemon --build-users-group=guixbuild &
guix archive --authorize < /share/guix/ci.guix.gnu.org.pub
guix archive --authorize < /share/guix/bordeaux.guix.gnu.org.pub
guix install hello
GUIX_PROFILE="/var/guix/profiles/per-user/root/guix-profile"
. "$GUIX_PROFILE/etc/profile"
hello
This could be simplified, but we chose to not hard-code in our containers because some of these are things that probably shouldn t be papered over but fixed properly somehow. In some execution environments, you may need to pass --disable-chroot to guix-daemon. To use the containers to build something in a GitLab pipeline, here is an example snippet:
test-amd64-latest-wget-configure-make-libksba:
  image: registry.gitlab.com/debdistutils/guix/container:latest
  before_script:
  - cp -rL /gnu/store/*profile/etc/* /etc/
  - echo 'root:x:0:0:root:/:/bin/sh' > /etc/passwd
  - echo 'root:x:0:' > /etc/group
  - groupadd --system guixbuild
  - for i in $(seq -w 1 10); do useradd -g guixbuild -G guixbuild -d /var/empty -s $(command -v nologin) -c "Guix build user $i" --system guixbuilder$i; done
  - export HOME=/
  - env LANG=C.UTF-8 guix-daemon --build-users-group=guixbuild &
  - guix archive --authorize < /share/guix/ci.guix.gnu.org.pub
  - guix archive --authorize < /share/guix/bordeaux.guix.gnu.org.pub
  - guix describe
  - guix install libgpg-error
  - GUIX_PROFILE="//.guix-profile"
  - . "$GUIX_PROFILE/etc/profile"
  script:
  - wget https://www.gnupg.org/ftp/gcrypt/libksba/libksba-1.6.7.tar.bz2
  - tar xfa libksba-1.6.7.tar.bz2
  - cd libksba-1.6.7
  - ./configure
  - make V=1
  - make check VERBOSE=t V=1
More help on the project page for the Guix Container Images. That s it for tonight folks, and remember, Happy Hacking!

4 December 2025

Colin Watson: Free software activity in November 2025

My Debian contributions this month were all sponsored by Freexian. I had a bit less time than usual, because Freexian collaborators gathered in Marseille this month for our yearly sprint, doing some planning for next year. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I began preparing for the second stage of the GSS-API key exchange package split (some details have changed since that message). It seems that we ll need to wait until Ubuntu 26.04 LTS has been released, but that s close enough that it s worth making sure we re ready. This month I just did some packaging cleanups that would otherwise have been annoying to copy, such as removing support for direct upgrades from pre-bookworm. I m considering some other package rearrangements to make the split easier to manage, but haven t made any decisions here yet. This also led me to start on a long-overdue bug triage pass, mainly consisting of applying usertags to lots of our open bugs to sort them by which program they apply to, and also closing a few that have been fixed, since some bugs will eventually need to be reassigned to GSS-API packages and it would be helpful to make them easier to find. At the time of writing, about 30% of the bug list remains to be categorized this way. Python packaging I upgraded these packages to new upstream versions: I packaged django-pgtransaction and backported it to trixie, since we plan to use it in Debusine; and I adopted python-certifi for the Python team. I fixed or helped to fix several other build/test failures: I fixed a couple of other bugs: Other bits and pieces Code reviews

Next.

Previous.