Search Results: "tim"

4 March 2026

Dirk Eddelbuettel: tidyCpp 0.0.9 on CRAN: More (forced) Maintenance

Another maintenance release of the tidyCpp package arrived on CRAN this morning. The packages offers a clean C++ layer (as well as one small C++ helper class) on top of the C API for R which aims to make use of this robust (if awkward) C API a little easier and more consistent. See the vignette for motivating examples. This release follows a similar release in November and had its hand forced by rather abrupt and forced overnight changes in R-devel, this time the removal of VECTOR_PTR in [this commit]. The release also contains changes accumulated since the last release (including some kindly contritbuted by Ivan) and those are signs that the R Core team can do more coordinated release management when they try a little harder. Changes are summarize in the NEWS entry that follows.

Changes in tidyCpp version 0.0.9 (2026-03-03)
  • Several vignette typos have been corrected (#4 addressing #3)
  • A badge for r-universe has been added to the README.md
  • The vignette is now served via GitHub Pages and that version is referenced in the README.
  • Two entry points reintroduced and redefined using permitted R API function (Ivan Krylov in #5).
  • Another entry has been removed to match R-devel API changes.
  • Six new attributes helpers have been added for R 4.6.0 or later.
  • VECTOR_PTR_RO(x) replaces the removed VECTOR_PTR, a warning or deprecation period would have been nice here.

Thanks to my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

3 March 2026

Matthew Garrett: To update blobs or not to update blobs

A lot of hardware runs non-free software. Sometimes that non-free software is in ROM. Sometimes it s in flash. Sometimes it s not stored on the device at all, it s pushed into it at runtime by another piece of hardware or by the operating system. We typically refer to this software as firmware to differentiate it from the software run on the CPU after the OS has started1, but a lot of it (and, these days, probably most of it) is software written in C or some other systems programming language and targeting Arm or RISC-V or maybe MIPS and even sometimes x862. There s no real distinction between it and any other bit of software you run, except it s generally not run within the context of the OS3. Anyway. It s code. I m going to simplify things here and stop using the words software or firmware and just say code instead, because that way we don t need to worry about semantics. A fundamental problem for free software enthusiasts is that almost all of the code we re talking about here is non-free. In some cases, it s cryptographically signed in a way that makes it difficult or impossible to replace it with free code. In some cases it s even encrypted, such that even examining the code is impossible. But because it s code, sometimes the vendor responsible for it will provide updates, and now you get to choose whether or not to apply those updates. I m now going to present some things to consider. These are not in any particular order and are not intended to form any sort of argument in themselves, but are representative of the opinions you will get from various people and I would like you to read these, think about them, and come to your own set of opinions before I tell you what my opinion is. THINGS TO CONSIDER Ok we re done with the things to consider. Please spend a few seconds thinking about what the tradeoffs are here and what your feelings are. Proceed when ready. I trust my CPU vendor. I don t trust my CPU vendor because I want to, I trust my CPU vendor because I have no choice. I don t think it s likely that my CPU vendor has designed a CPU that identifies when I m generating cryptographic keys and biases the RNG output so my keys are significantly weaker than they look, but it s not literally impossible. I generate keys on it anyway, because what choice do I have? At some point I will buy a new laptop because Electron will no longer fit in 32GB of RAM and I will have to make the same affirmation of trust, because the alternative is that I just don t have a computer. And in any case, I will be communicating with other people who generated their keys on CPUs I have no control over, and I will also be relying on them to be trustworthy. If I refuse to trust my CPU then I don t get to computer, and if I don t get to computer then I will be sad. I suspect I m not alone here. Why would I install a code update on my CPU when my CPU s job is to run my code in the first place? Because it turns out that CPUs are complicated and messy and they have their own bugs, and those bugs may be functional (for example, some performance counter functionality was broken on Sandybridge at release, and was then fixed with a microcode blob update) and if you update it your hardware works better. Or it might be that you re running a CPU with speculative execution bugs and there s a microcode update that provides a mitigation for that even if your CPU is slower when you enable it, but at least now you can run virtual machines without code in those virtual machines being able to reach outside the hypervisor boundary and extract secrets from other contexts. When it s put that way, why would I not install the update? And the straightforward answer is that theoretically it could include new code that doesn t act in my interests, either deliberately or not. And, yes, this is theoretically possible. Of course, if you don t trust your CPU vendor, why are you buying CPUs from them, but well maybe they ve been corrupted (in which case don t buy any new CPUs from them either) or maybe they ve just introduced a new vulnerability by accident, and also you re in a position to determine whether the alleged security improvements matter to you at all. Do you care about speculative execution attacks if all software running on your system is trustworthy? Probably not! Do you need to update a blob that fixes something you don t care about and which might introduce some sort of vulnerability? Seems like no! But there s a difference between a recommendation for a fully informed device owner who has a full understanding of threats, and a recommendation for an average user who just wants their computer to work and to not be ransomwared. A code update on a wifi card may introduce a backdoor, or it may fix the ability for someone to compromise your machine with a hostile access point. Most people are just not going to be in a position to figure out which is more likely, and there s no single answer that s correct for everyone. What we do know is that where vulnerabilities in this sort of code have been discovered, updates have tended to fix them - but nobody has flagged such an update as a real-world vector for system compromise. My personal opinion? You should make your own mind up, but also you shouldn t impose that choice on others, because your threat model is not necessarily their threat model. Code updates are a reasonable default, but they shouldn t be unilaterally imposed, and nor should they be blocked outright. And the best way to shift the balance of power away from vendors who insist on distributing non-free blobs is to demonstrate the benefits gained from them being free - a vendor who ships free code on their system enables their customers to improve their code and enable new functionality and make their hardware more attractive. It s impossible to say with absolute certainty that your security will be improved by installing code blobs. It s also impossible to say with absolute certainty that it won t. So far evidence tends to support the idea that most updates that claim to fix security issues do, and there s not a lot of evidence to support the idea that updates add new backdoors. Overall I d say that providing the updates is likely the right default for most users - and that that should never be strongly enforced, because people should be allowed to define their own security model, and whatever set of threats I m worried about, someone else may have a good reason to focus on different ones.

  1. Code that runs on the CPU before the OS is still usually described as firmware - UEFI is firmware even though it s executing on the CPU, which should give a strong indication that the difference between firmware and software is largely arbitrary
  2. And, obviously 8051
  3. Because UEFI makes everything more complicated, UEFI makes this more complicated. Triggering a UEFI runtime service involves your OS jumping into firmware code at runtime, in the same context as the OS kernel. Sometimes this will trigger a jump into System Management Mode, but other times it won t, and it s just your kernel executing code that got dumped into RAM when your system booted.
  4. I don t understand most of the diff between one kernel version and the next, and I don t have time to read all of it either.
  5. There s a bunch of reasons to do this, the most reasonable of which is probably not wanting customers to replace the code and break their hardware and deal with the support overhead of that, but not being able to replace code running on hardware I own is always going to be an affront to me.

Michael Ablassmeier: pbsindex - file backup index

If you take backups using the proxmox-backup-client and you wondered what backup may include a specific file, the only way to find out is to mount the backup and search for the files. For regular file backups, the Proxmox Backup Server frontend provides a pcat1 file for download, whose binary format is somewhat undocumented but actually includes a listing of the files backed up. A Proxmox backup server datastore includes the same pcat1 file as blob index (.pcat1.didx). So to actually beeing able to tell which backup contains which files, one needs to: 1) Open the .pcat1.didx file and find out required blobs, see format documentation 2) Reconstruct the .pcat1 file from the blobs 3) Parse the pcat1 file and output the directory listing. I ve implemented this in pbsindex which lets you create a central file index for your backups by scanning a complete PBS datastore. Lets say you want to have a file listing for a specific backup, use:
 pbsindex --chunk-dir /backup/.chunks/ /backup/host/vm178/2026-03-02T10:47:57Z/catalog.pcat1.didx
 didx uuid=7e4086a9-4432-4184-a21f-0aeec2b2de93 ctime=2026-03-02T10:47:57Z chunks=2 total_size=1037386
 chunk[0] start=0 end=344652 size=344652 digest=af3851419f5e74fbb4d7ca6ac3bc7c5cbbdb7c03d3cb489d57742ea717972224
 chunk[1] start=344652 end=1037386 size=692734 digest=e400b13522df02641c2d9934c3880ae78ebb397c66f9b4cf3b931d309da1a7cc
 d ./usr.pxar.didx
 d ./usr.pxar.didx/bin
 l ./usr.pxar.didx/bin/Mail
 f ./usr.pxar.didx/bin/[ size=55720 mtime=2025-06-04T15:14:05Z
 f ./usr.pxar.didx/bin/aa-enabled size=18672 mtime=2025-04-10T15:06:25Z
 f ./usr.pxar.didx/bin/aa-exec size=18672 mtime=2025-04-10T15:06:25Z
 f ./usr.pxar.didx/bin/aa-features-abi size=18664 mtime=2025-04-10T15:06:25Z
 l ./usr.pxar.didx/bin/apropos
It also lets you scan a complete datastore for all existing .pcat1.didx files and store the directory listings in a SQLite database for easier searching.

2 March 2026

Isoken Ibizugbe: Wrapping Up My Outreachy Internship at Debian

Twelve weeks ago, I stepped into the Debian ecosystem as an Outreachy intern with a curiosity for Quality Assurance. It feels like just yesterday, and time has flown by so fast! Now, I am wrapping up that journey, not just with a completed project, but with improved technical reasoning.

I have learned how to use documentation to understand a complex project, how to be a good collaborator, and that learning is a continuous process. These experiences have helped me grow much more confident in my skills as an engineer.

My Achievements

As I close this chapter, I am leaving a permanent Proof-of-Work in the Debian repositories:

  • Full Test Coverage: I automated apps_startstop tests for Cinnamon, LXQt, and XFCE, covering both Live images and Netinst installations.
  • Synergy: I used symbolic links and a single Perl script to handle common application tests across different desktops, which reduces code redundancy.
  • The Contributor Style Guide: I created a guide for future contributors to make documentation clearer and reviews faster, helping to reduce the burden on reviewers.

Final Month: Wrap Up

In this final month, things became easier as my understanding of the project grew. I focused on stability and finishing my remaining tasks:

  • I spent time exploring different QEMU video options like VGA, qxl, and virtio on KDE desktop environment . This was important to ensure screen rendering remained stable so that our needles (visual test markers) wouldn t fail because of minor glitches.
  • I successfully moved from familiarizing to test automation for the XFCE desktop. This included writing prepare steps and creating the visual needles needed to make the tests reliable.
  • One of my final challenges was the app launcher function. Originally, my code used else if blocks for each desktop. I proposed a unified solution, but hit a blocker: XFCE has two ways to launch apps (App Finder and the Application Menu). Because using different methods sometimes caused failures, I chose to use the application menu button across the board.

What s Next?

I don t want my journey with Debian to end here. I plan to stay involved in the community and extend these same tests to the LXDE desktop to complete the coverage for all major Debian desktop environments. I am excited to keep exploring and learning more about the Debian ecosystem.

Thank You

This journey wouldn t have been possible without the steady guidance of my mentors: Tassia Camoes Araujo, Roland Clobus, and Philip Hands. Thank you for teaching me that in the world of Free and Open Source Software (FOSS), your voice and your code are equally important.

To my fellow intern Hellen and the entire Outreachy community, thank you for the shared learning and support. It has been an incredible 12 weeks.

Ben Hutchings: FOSS activity in February 2026

Valhalla's Things: A Pen Case (or a Few)

Posted on March 2, 2026
Tags: madeof:atoms, FreeSoftWear, craft:sewing
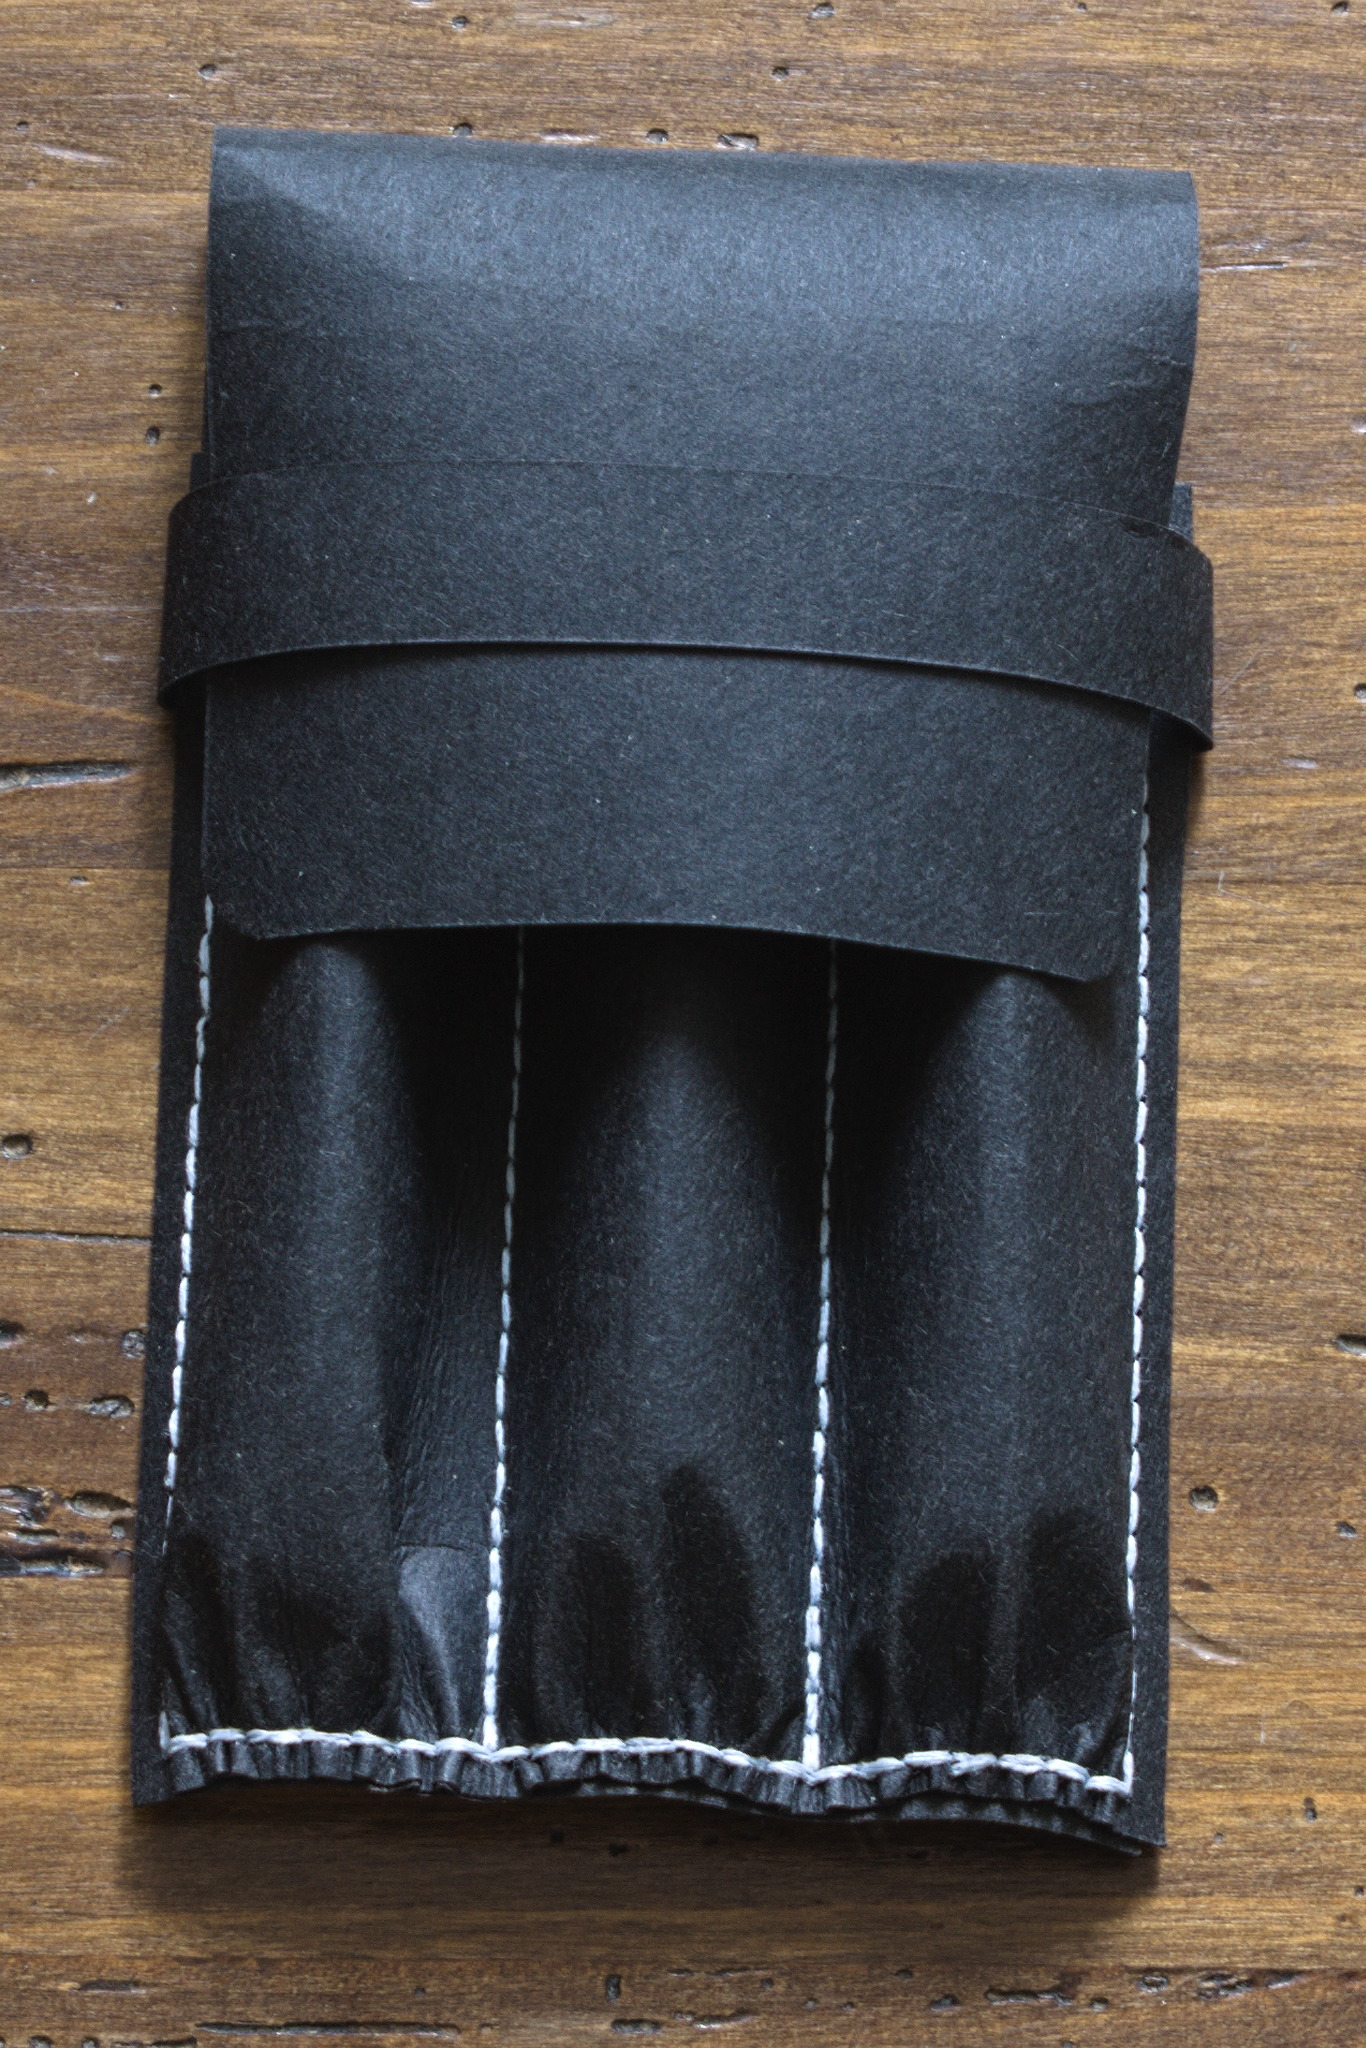
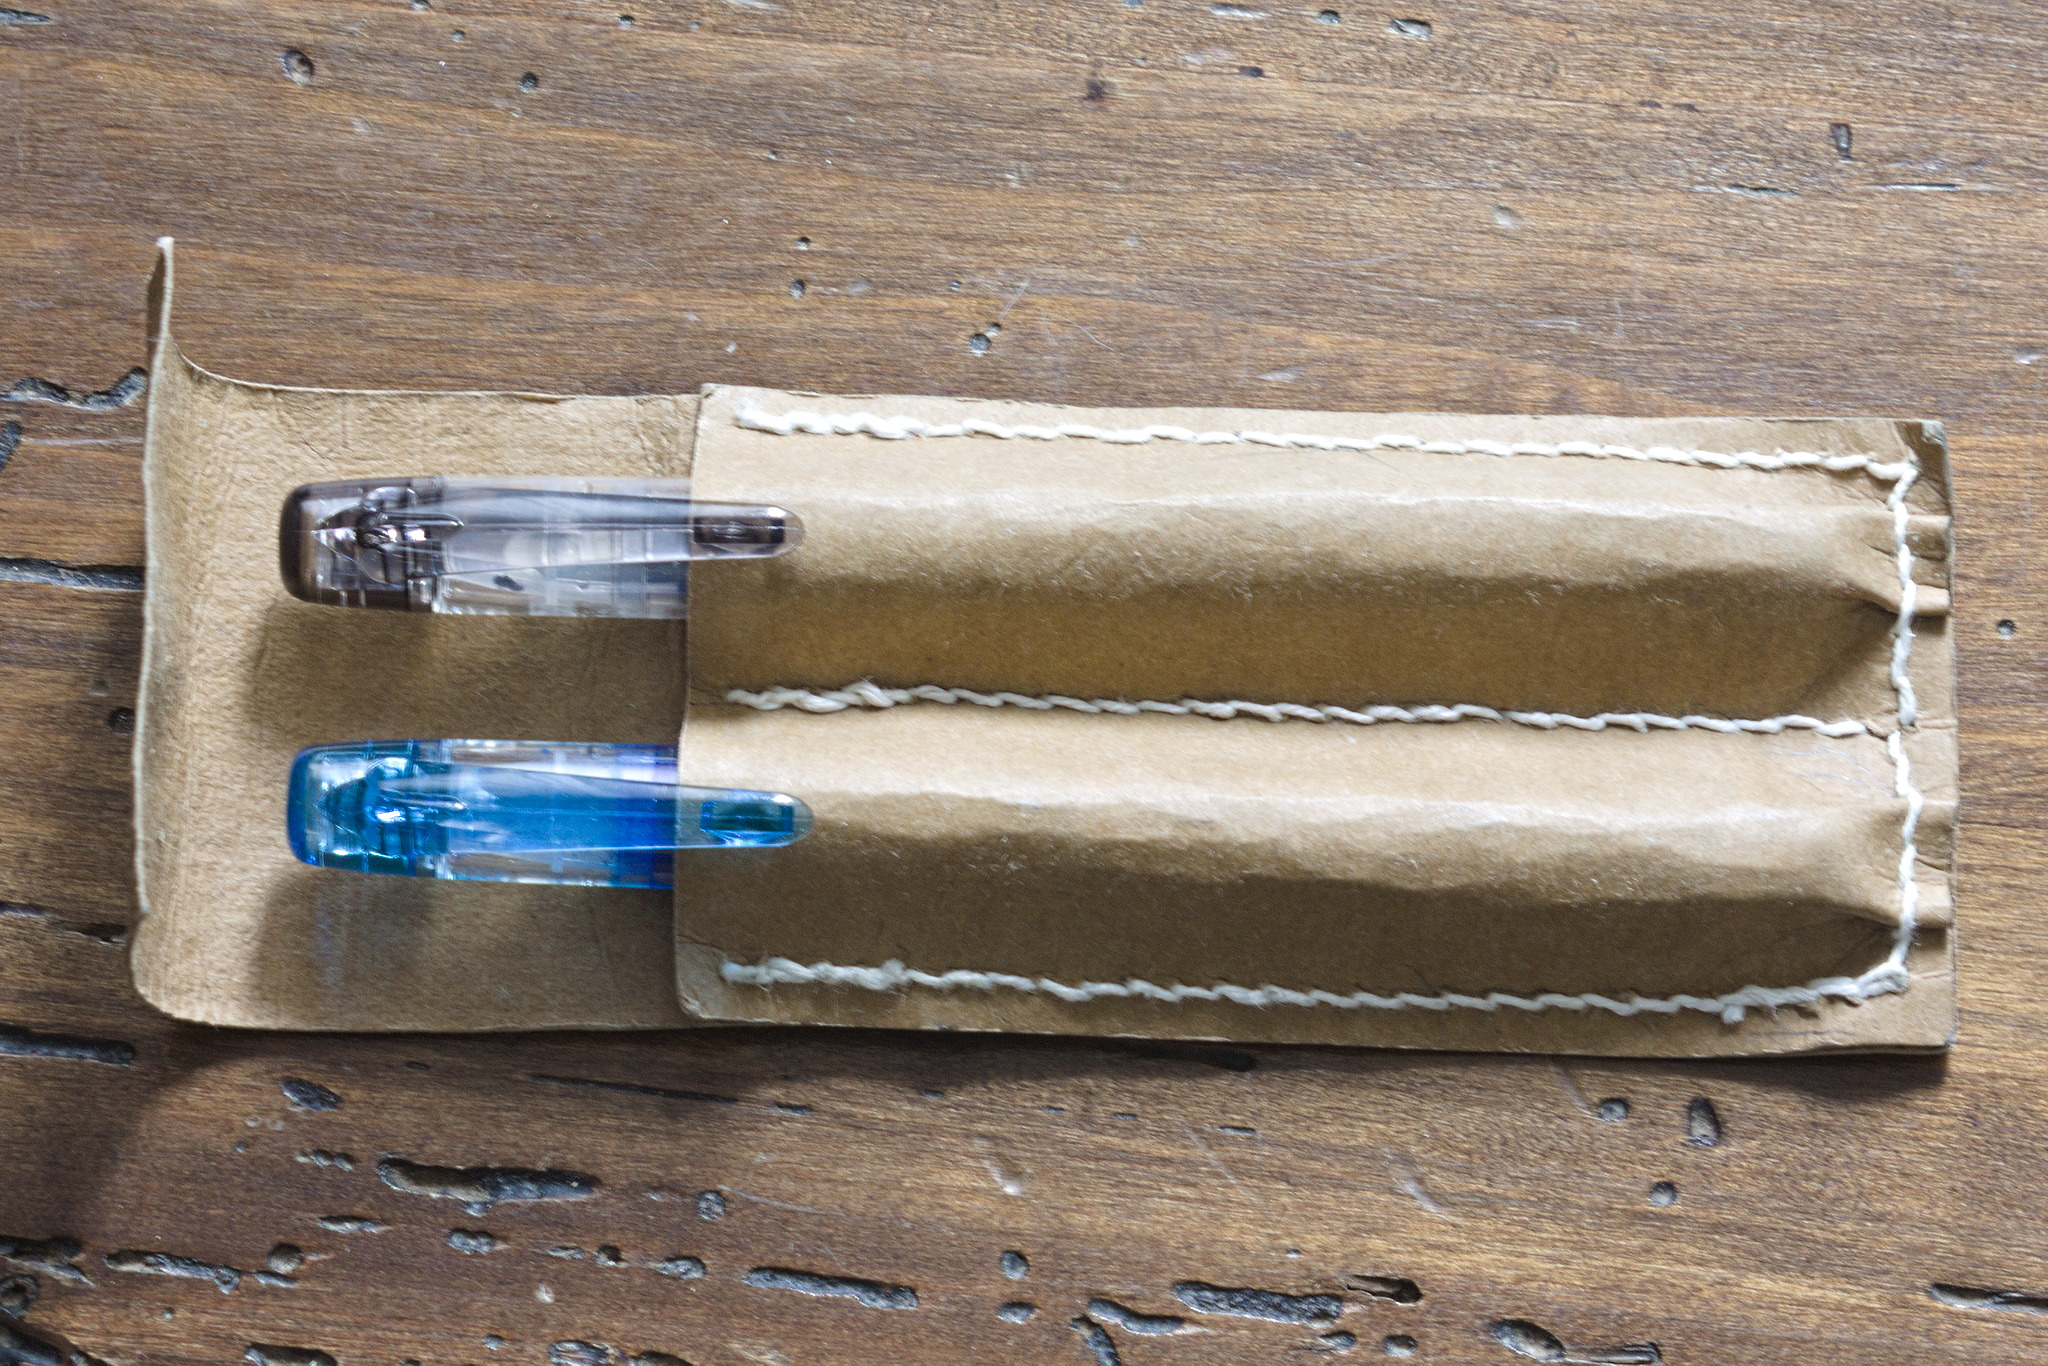
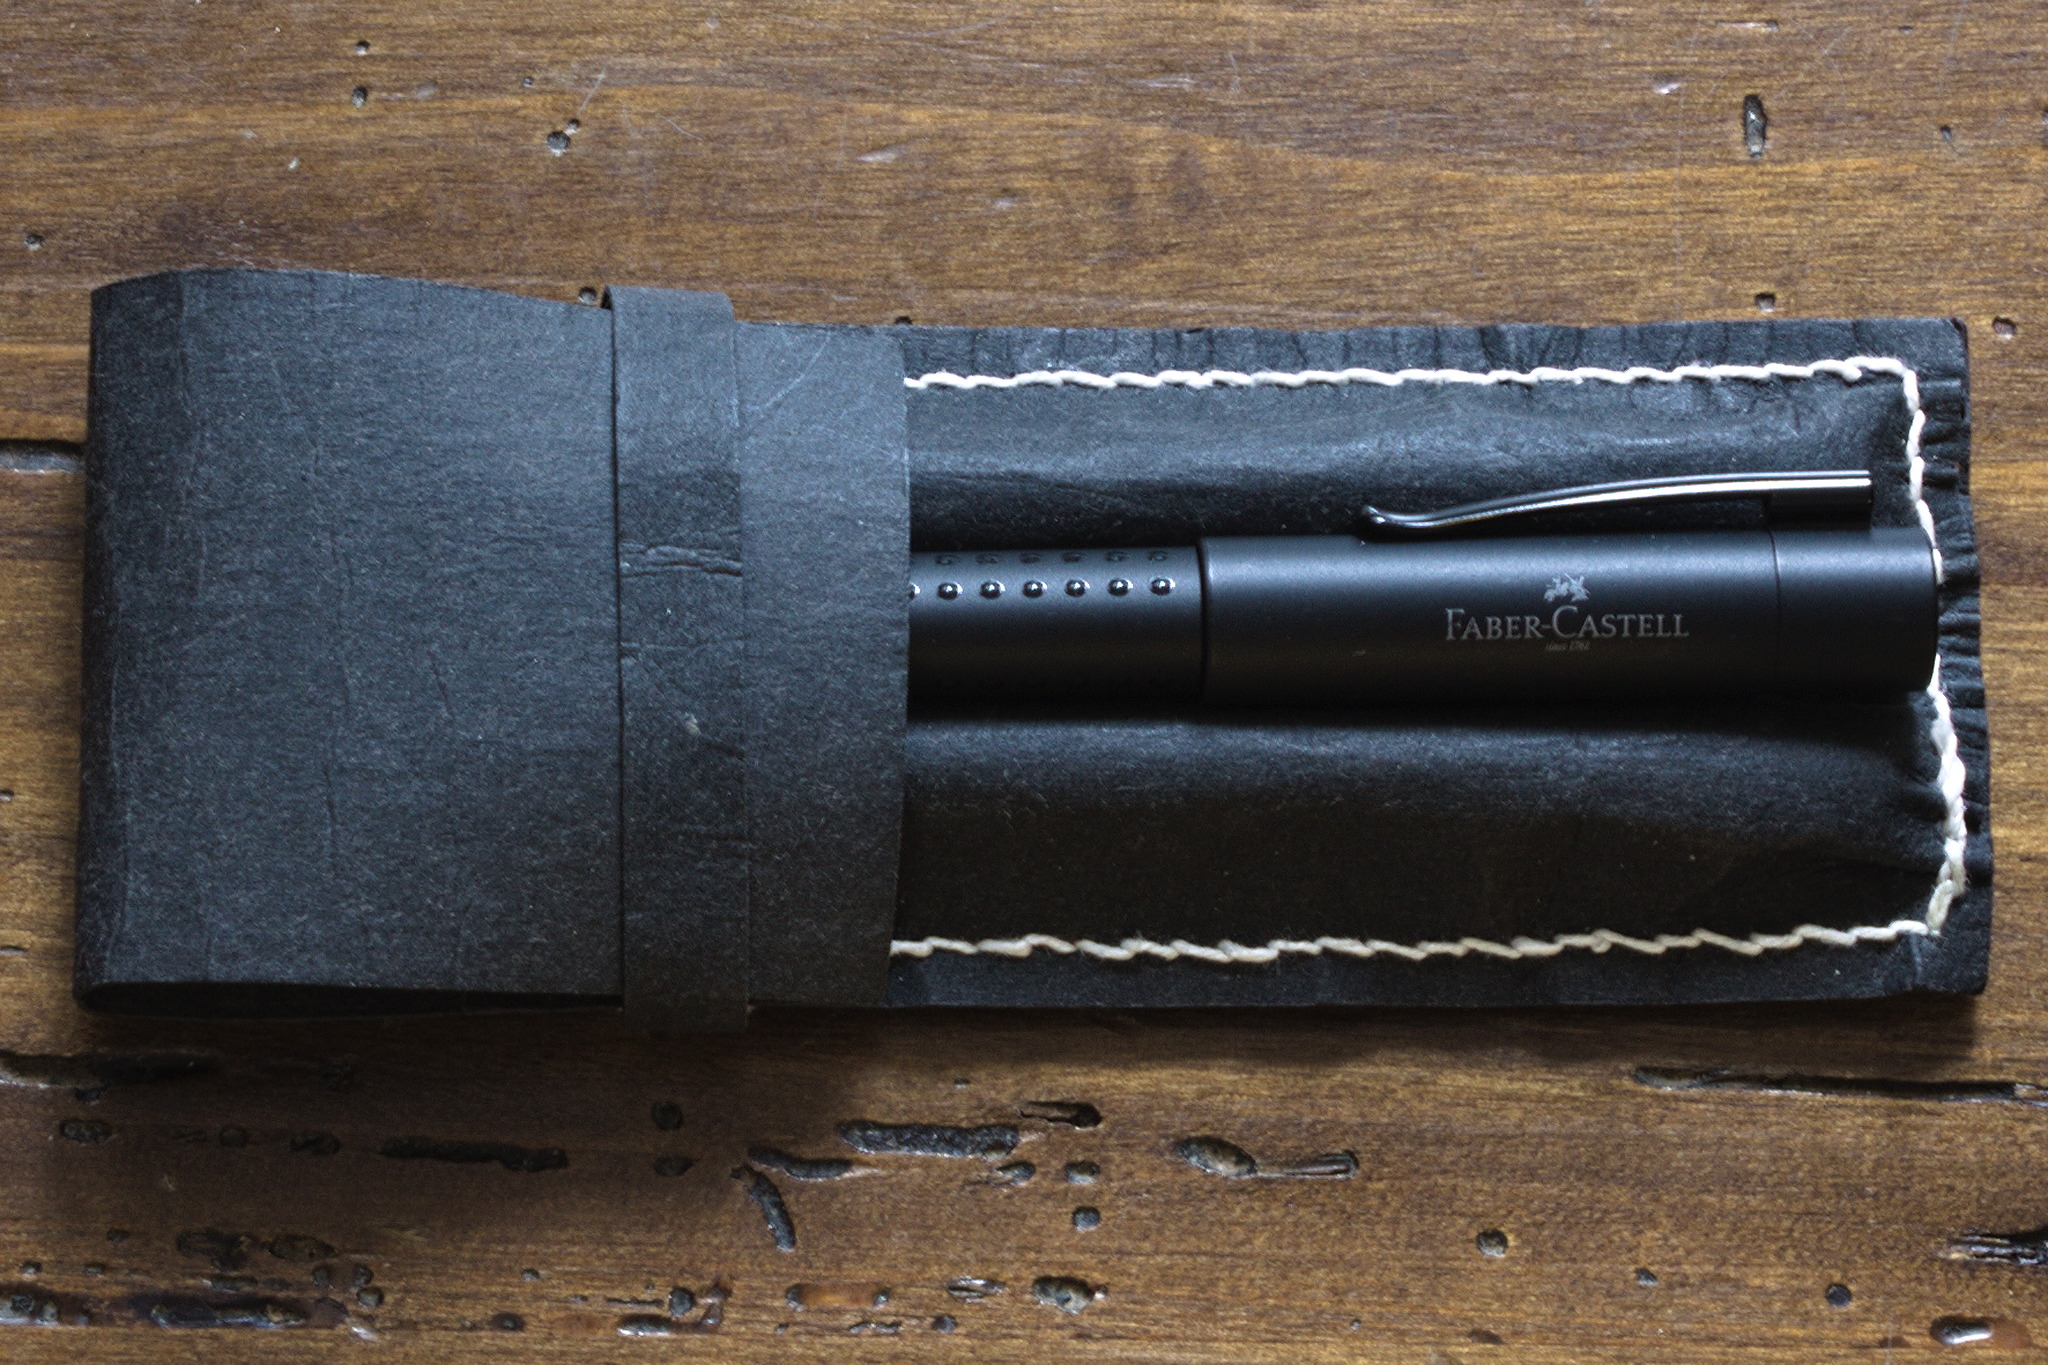
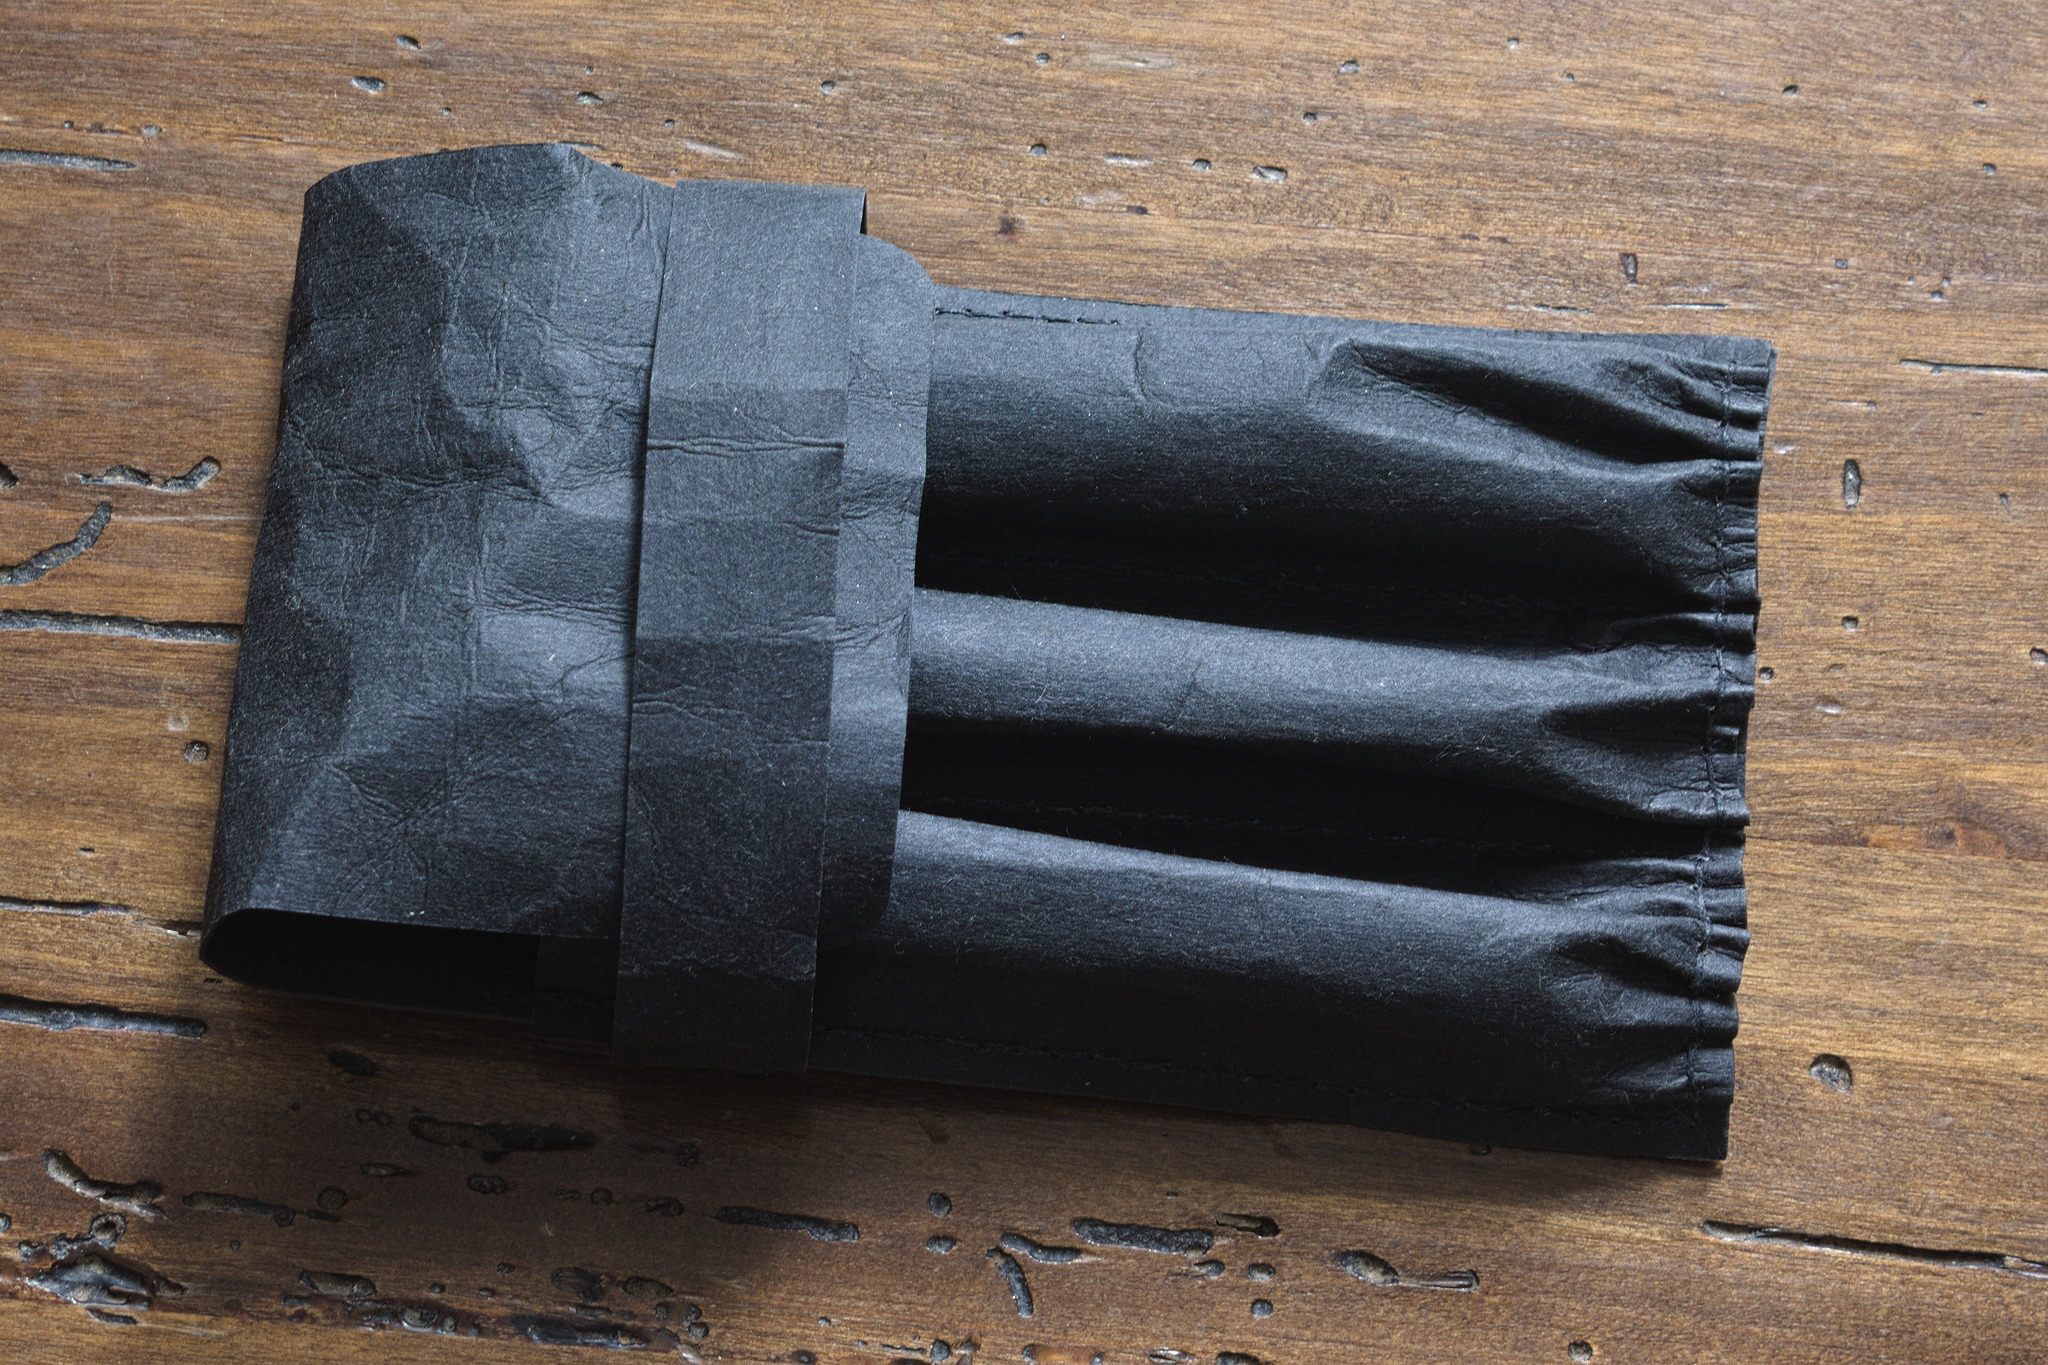
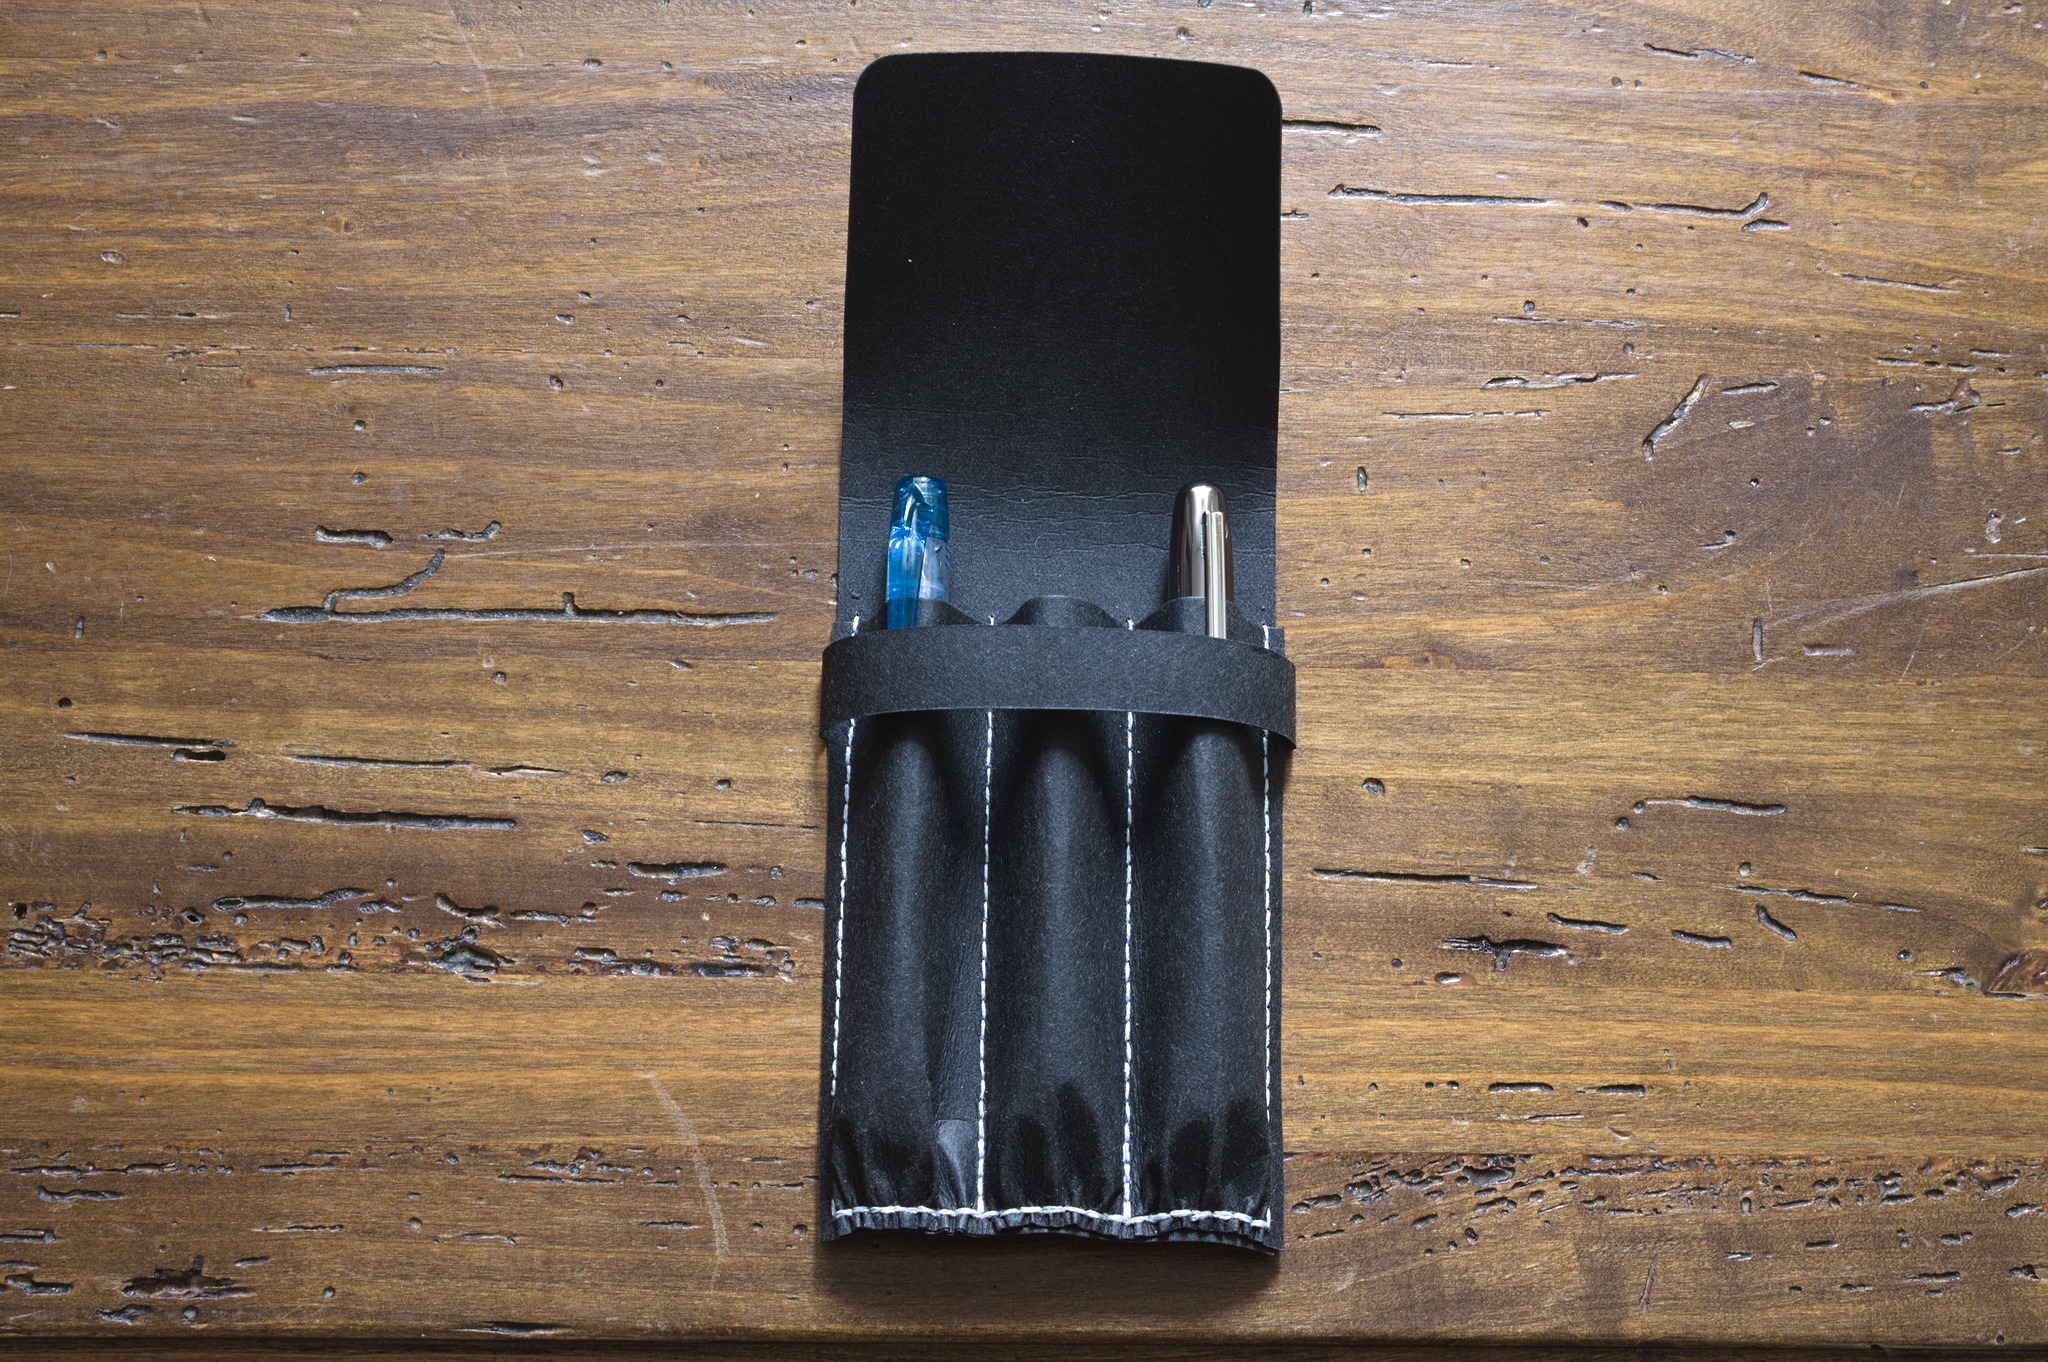
A pen case made of two pieces of a relatively stiff black material with a flat base and three separate channels on top, plus a flap covering everything and a band to keep the flap closed; there is visible light blue stitching all around the channels. For my birthday, I ve bought myself a fancy new expensive1 fountain pen. A two slot pen case in the same material as above, but brown: the flap is too short to cover the pens, and there isn't a band to keep it closed. Such a fancy pen, of course requires a suitable case: I couldn t use the failed prototype of a case I ve been keeping my Preppys in, so I had to get out the nice vegetable tanned leather Yeah, nope, I don t have that (yet). I got out the latex and cardboard material that is sold as a (cheaper) leather substitute, doesn t look like leather at all, but is quite nice (and easy) to work with. The project is not vegan anyway, because I used waxed linen thread, waxing it myself with a lot of very nicely smelling beeswax. a case similar to the one above, but this one only has two slots, and there is a a Faber Castell pen nested on top of the case between the two slots. Here the stitches are white, and in a coarser thread. I got the measurements2 from the less failed prototype where I keep my desktop pens, and this time I made a proper pattern I could share online, under the usual Free Culture license. A case like the one above, except that the stitches are in black, and not as regular. This one has also been scrunched up a bit for a different look, and now the band is a bit too wide. From the width of the material I could conveniently cut two cases, so that s what I did, started sewing the first one, realized that I got the order of stitching wrong, and also that if I used light blue thread instead of the black one it would look nice, and be easier to see in the pictures for the published pattern, started sewing the second one, and kept alternating between the two, depending on the availability of light for taking pictures. The open pen case, showing two pens, a blue Preppy and a gunmetal Plaisir cosily nested in the two outer slots, while the middle slot is ominously empty. One of the two took the place of my desktop one, where I had one more pen than slots, and one of the old prototypes was moved to keep my bedside pen, and the other new case was used for the new pen in my handbag, together with a Preppy, and now I have a free slot and you can see how this is going to go wrong, right? :D

  1. 16 . plus a 9 converter, and another 6 pen to get the EF nib from, since it wasn t available for the expensive pen.
  2. I have them written down somewhere. I couldn t find them. So I measured the real thing, with some approximation.

28 February 2026

Mike Gabriel: Debian Lomiri Tablets 2025-2027 - Project Report (Q3/2025)

Debian Lomiri for Debian 13 (previous project) In our previous project around Debian and Lomiri (lasting until July 2025), we achieved to get Lomiri 0.5.0 (and with it another 130 packages) into Debian (with two minor exceptions [1]) just in time for the Debian 13 release in August 2025. Debian Lomiri for Debian 14 At DebConf in Brest, a follow-up project has been designed between the project sponsor and Fre(i)e Software GmbH [2]. The new project (on paper) started on 1st August 2025 and project duration was agreed on to be 2 years, allowing our company to work with an equivalent of ~5 FTE on Lomiri targetting the Debian 14 release some time in the second half of 2027 (an assumed date, let's see what happens). Ongoing work would be covered from day one of the new project and once all contract details had been properly put on paper end of September, Fre(i)e Software GmbH started hiring a new team of software developers and (future) Debian maintainers. (More of that new team in our next Q4/2025 report). The ongoing work of Q3/2025 was basically Guido Berh rster and myself working on Morph Browser Qt6 (mostly Guido together with Bhushan from MiraLab [3]) and package maintenance in Debian (mostly me). Morph Browser Qt6 The first milestone we could reach with the Qt6 porting of Morph Browser [4] and related components (LUITK aka lomiri-ui-toolkit (big chunk! [5]), lomiri-content-hub, lomiri-download-manager and a few other components) was reached on 21st Sep 2025 with an upload of Morph Browser 1.2.0~git20250813.1ca2aa7+dfsg-1~exp1 to Debian experimental and the Lomiri PPA [6]). Preparation of Debian 13 Updates (still pending) In background, various Lomiri updates for Debian 13 have been prepared during Q3/2025 (with a huge patchset), but publishing those to Debian 13 are still pending as tests are still not satisfying. [1] lomiri-push-service and nuntium
[2] https://freiesoftware.gmbh
[3] https://miralab.one/
[4] https://gitlab.com/ubports/development/core/morph-browser/-/merge_reques... et al.
[5] https://gitlab.com/ubports/development/core/lomiri-ui-toolkit/-/merge_re... et al.
[6] https://launchpad.net/~lomiri

Utkarsh Gupta: FOSS Activites in February 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
  • Uploaded node-lodash/4.17.21+dfsg+~cs8.31.198.20210220-10 to fix CVE-2025-13465 in unstable. Pinged Xavier and Praveen to see how they feel about the backport for the stable releases.
  • Assited a few folks in getting their patches submitted via Salsa.
    • Reviewing pyenv MR for Ujjwal.
    • Reviewing and assisting Anshul with his Golang stuff.
  • Mentoring for newcomers.
  • Started to be a bit involved with DC 26 bits.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021. Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
  • Successfully released Resolute Snapshot 4!
    • This one was also done without the ISO tracker and cdimage access.
    • We also worked very hard to build and promote all the image in due time.
    • This was one done with the Test Observer. The first one.
  • Worked further on the whole artifact signing story for cdimage.
  • Assisted a bunch of folks with my Archive Admin and Release team hats to:
    • Review and grant FFes.
    • Coordinating weekly syncs.
    • Promoting binaries to main.
    • Taking care of package removals and so on.
  • Was pretty occupied with the new release processs architecture.

Debian (E)LTS
This month I have worked 42 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things:

Released Security Updates

Work in Progress
  • knot-resolver: Affected by CVE-2023-26249, CVE-2023-46317, and CVE-2022-40188, leading to Denial of Service.
  • ruby-rack: There were multiple vulnerabilities reported in Rack, leading to DoS (memory exhaustion) and proxy bypass.
    • [ELTS]: I ve partially reviewed patches by Bastien but whilst doing so, new ones came up for all the releases.
    • [sid]: Uploaded ruby-rack/3.2.5-1 to unstable to fix the new CVEs, CVE-2026-25500 and CVE-2026-22860.
    • [stable]: Prepared the upload for stable releases, as requested by the Security Team. Will upload them in March.
    • [bullseye]: Backport for CVE-2026-22860 hasn t been as trivial as it appears to be. There are test failures, which aren t really ignore-able:
      The tests requests /cgi/../test, which File.expand_path resolves to <root>/test - firmly inside @root. With the old code, it hit the return unless path_info.include? ".." guard and fell through to 403. But it would also have returned early via start_with?(@root) being true
    • anyway, this needs more investigation - I ll continue to do so in March as P1.
  • node-lodash: Affected by CVE-2025-13465, lrototype pollution in baseUnset function.
    • [stable]: The patch for trixie and bookworm are ready and have been awaiting the maintainer review.
    • [LTS]: The bullseye upload will follow once the stable uploads are in and ACK d by the SRMs.
  • vlc: Affected by CVE-2025-51602, an out-of-bounds read and denial of service via a crafted 0x01 response from an MMS server.
    • [LTS]: 3.0.23 backport is ready but not tested. I ll get this over the line in March.
    • [ELTS]: 3.0.23 backport is ready but not very clean. Would like to complete LTS and get back to this.

Other Activities
  • [LTS] Coordinated the libvirt sitaution with Ben Hutchings. The upload has already been prepped, will upload in March.
  • [ELTS] Continued to help Bastien and Markus with the tomcat9 regression for buster.
  • [ELTS] Partially reviewed ruby-rack CVEs to help Bastien. This took more time than expected with some more develpments hapening at the end of the month - new CVEs that aren t as easy to backport as I expected them to be. Will continue with these in March.
  • [E/LTS] Front Desk duties: Performed a large batch of CVE triage, marking numerous packages for bullseye, buster, and stretch as either postponed, end-of-life, not-affected, or added them to the Xla-needed.txt files.
    • Also replied to certain mails and IRC texts around FD related tasks.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on Jitsi. Summary here.

Until next time.
:wq for today.

Daniel Baumann: Debian Fast Forward: An alternative backports repository

The Debian project releases a new stable version of its Linux distribution approximately every two years. During its life time, a stable release usually gets security updates only, but in general no feature updates. For some packages it is desirable to get feature updates earlier than with the next stable release. Some new packages included in Debian after the initial release of a stable distribution are desirable for stable too. Both use-cases can be solved by recompiling the newer version of a package from testing/unstable on stable (aka backporting). Packages are backported together with only the minimal amount of required build-depends or depends not already fulfilled in stable (if any), and without any changes unless required to fix building on stable (if needed). There are official Debian Backports available, as well as several well-known unofficial backports repositories. I have been involved in one of these unofficial repositories since 2005 which subsequently turned 2010 into its own Debian derivative, mixing both backports and modified packages in one repository for simplicity. Starting with the Debian 13 (trixie) release, the (otherwise unmodified) backports of this derivative have been split out from the derivative distribution into a separate repository. This way the backports are more accessible and useful for all interested Debian users too.
TL;DR: Debian Fast Forward - https://fastforward.debian.net
  • is an alternative Debian repository containing complementary backports from testing/unstable to stable
  • with packages organized in a curated, self-contained selection of coherent sets
  • supporting amd64, i386, and arm64 architectures
  • containing around 400 packages in trixie-fastforward-backports
  • with 1 800 uploads since July 2025
End user documentation about how to enable Debian Fast Forwards is available. Have fun!

25 February 2026

Sahil Dhiman: Publicly Available NKN Data Traffic Graphs

National Knowledge Network (NKN) is one of India s main National Research and Educational Network (NREN). The other being the less prevalent Education and Research Network (ERNET). This post grew out of this Mastodon thread where I kept on adding various public graphs (from various global research and educational entities) that peer or connect with NKN. This was to get some purview about traffic data between them and NKN.

CERN CERN, birthplace of the World Wide Web (WWW) and home of the Large Hadron Collider (LHC). India participates in the LHCONE project, which carries LHC data over these links for scientific research purposes. This presentation from Vikas Singhal from Variable Energy Cyclotron Centre (VECC), Kolkata, at the 8th Asian Tier Center Forum in 2024 gives some details.

G ANT G ANT is pan European Union s collaboration of NRENs.

LEARN Lanka Education and Research Network (LEARN) is Sri Lanka s NREN.

NORDUnet NREN for Nordic countries. I couldn t find any public live data transfer graphs from NKN side. If you know any other graphs, do let me know.

Joachim Breitner: Vibe-coding a debugger for a DSL

Earlier this week a colleague of mine, Emilio Jes s Gallego Arias, shared a demo of something he built as an experiment, and I felt the desire to share this and add a bit of reflection. (Not keen on watching a 5 min video? Read on below.)

What was that? So what did you just see (or skipped watching)? You could see Emilio s screen, running VSCode and editing a Lean file. He designed a small programming language that he embedded into Lean, including an evaluator. So far, so standard, but a few things stick out already:
  • Using Lean s very extensible syntax this embedding is rather elegant and pretty.
  • Furthermore, he can run this DSL code right there, in the source code, using commands like #eval. This is a bit like the interpreter found in Haskell or Python, but without needing a separate process, or like using a Jupyter notebook, but without the stateful cell management.
This is already a nice demonstration of Lean s abilities and strength, as we know them. But what blew my mind the first time was what happened next: He had a visual debugger that allowed him to debug his DSL program. It appeared on the right, in Lean s Info View , where various Lean tools can hook into, show information and allow the user to interact. But it did not stop there, and my mind was blown a second time: Emilio opened VSCode s Debugger pane on the left, and was able to properly use VSCode s full-fledged debugger frontend for his own little embedded programming language! Complete with highlighting the executed line, with the ability to set breakpoints there, and showing the state of local variables in the debugger. Having a good debugger is not to be taken for granted even for serious, practical programming languages. Having it for a small embedded language that you just built yourself? I wouldn t have even considered that.

Did it take long? If I were Emilio s manager I would applaud the demo and then would have to ask how many weeks he spent on that. Coming up with the language, getting the syntax extension right, writing the evaluator and especially learning how the debugger integration into VSCode (using the DAP protocol) works, and then instrumenting his evaluator to speak that protocol that is a sizeable project! It turns out the answer isn t measured in weeks: it took just one day of coding together with GPT-Codex 5.3. My mind was blown a third time.

Why does Lean make a difference? I am sure this post is just one of many stories you have read in recent weeks about how new models like Claude Opus 4.6 and GPT-Codex 5.3 built impressive things in hours that would have taken days or more before. But have you seen something like this? Agentic coding is powerful, but limited by what the underlying platform exposes. I claim that Lean is a particularly well-suited platform to unleash the agents versatility. Here we are using Lean as a programming language, not as a theorem prover (which brings other immediate benefits when using agents, e.g. the produced code can be verified rather than merely plausible, but that s a story to be told elsewhere.) But arguably because Lean is also a theorem prover, and because of the requirements that stem from that, its architecture is different from that of a conventional programming language implementation:
  • As a theorem prover, it needs extensible syntax to allow formalizing mathematics in an ergonomic way, but it can also be used for embedding syntax.
  • As a theorem prover, it needs the ability to run tactics written by the user, hence the ability to evaluate the code right there in the editor.
  • As a theorem prover, it needs to give access to information such as tactic state, and such introspection abilities unlock many other features such as a debugger for an embedded language.
  • As a theorem prover, it has to allow tools to present information like the tactic state, so it has the concept of interactive Widgets .
So Lean s design has always made such a feat possible. But it was no easy feat. The Lean API is large, and documentation never ceases to be improvable. In the past, it would take an expert (or someone willing to become one) to pull off that stunt. These days, coding assistants have no issue digesting, understanding and using the API, as Emilio s demo shows. The combination of Lean s extensibility and the ability of coding agents to make use of that is a game changer to how we can develop software, with rich, deep, flexible and bespoke ways to interact with our code, created on demand.

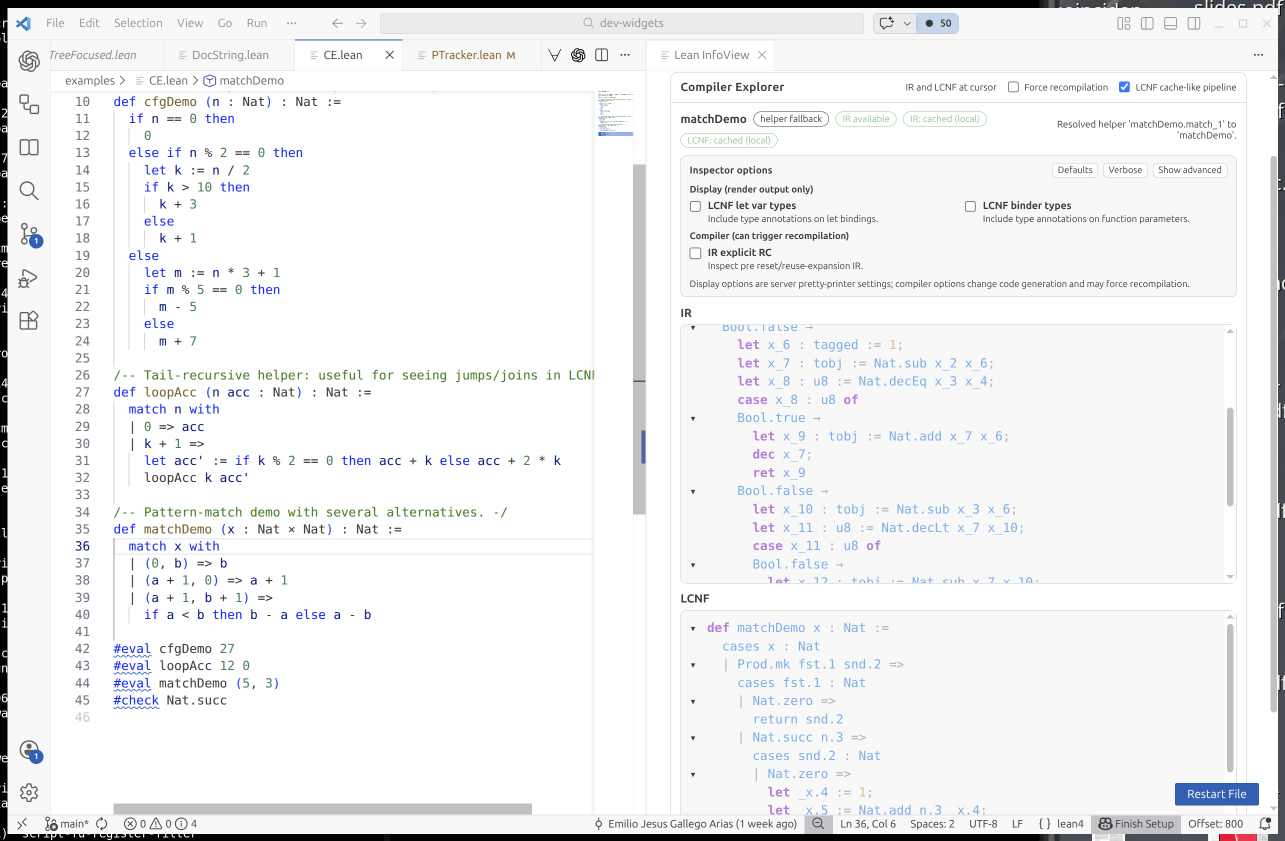
Where does that lead us? Emilio actually shared more such demos (Github repository). A visual explorer for the compiler output (have a look at the screenshot. A browser-devtool-like inspection tool for Lean s InfoTree . Any of these provide a significant productivity boost. Any of these would have been a sizeable project half a year ago. Now it s just a few hours of chatting with the agent. So allow me to try and extrapolate into a future where coding agents have continued to advance at the current pace, and are used ubiquitously. Is there then even a point in polishing these tools, shipping them to our users, documenting them? Why build a compiler explorer for our users, if our users can just ask their agent to build one for them, right then when they need it, tailored to precisely the use case they have, with no unnecessary or confusing feature. The code would be single use, as the next time the user needs something like that the agent can just re-create it, maybe slightly different because every use case is different. If that comes to pass then Lean may no longer get praise for its nice out-of-the-box user experience, but instead because it is such a powerful framework for ad-hoc UX improvements. And Emilio wouldn t post demos about his debugger. He d just use it.

24 February 2026

Louis-Philippe V ronneau: Montreal's Debian & Stuff - February 2026

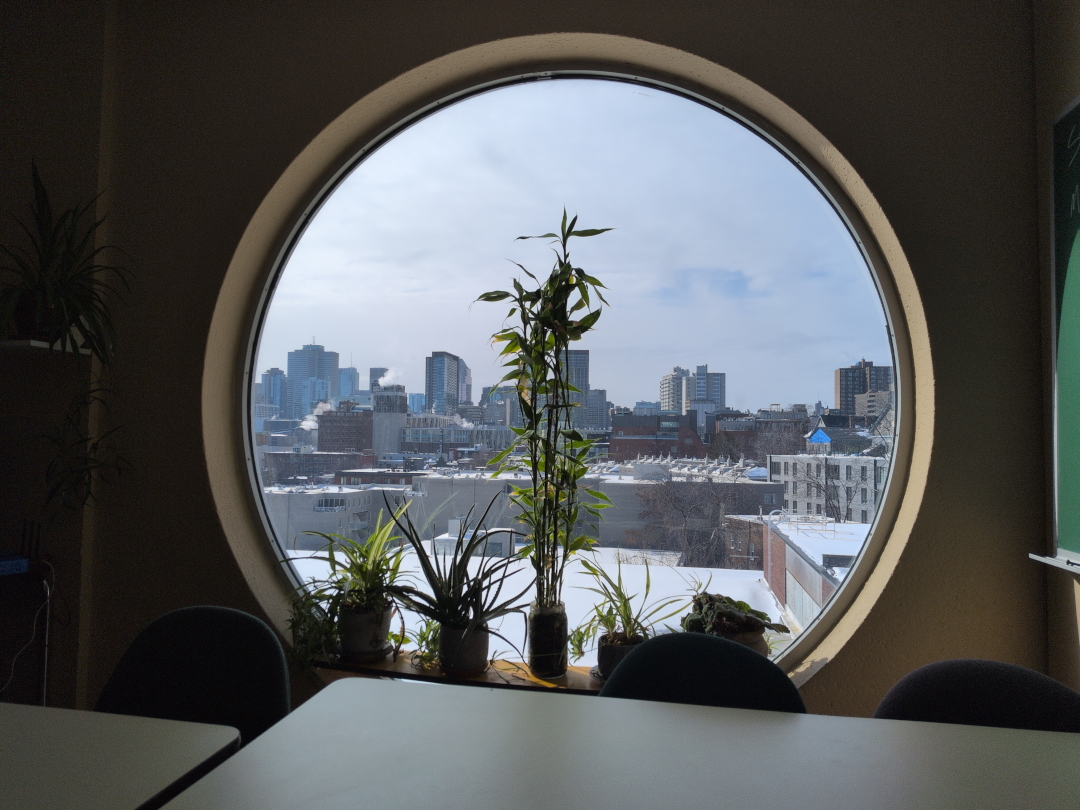
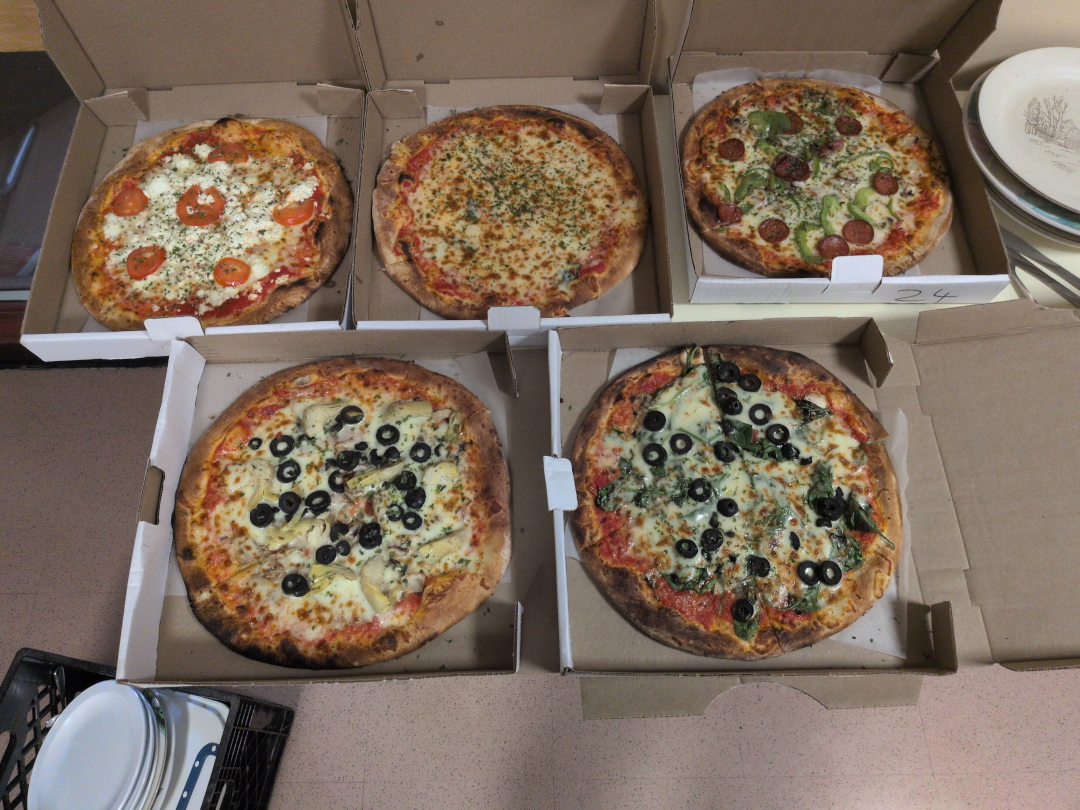
Our Debian User Group met on February 22nd for our first meeting of the year! Here's what we did: pollo: lelutin: viashimo: tvaz: lavamind: Pictures This time around, we held our meeting at c gep du Vieux Montr al, the college where I currently work. Here is the view we had: View from my office We also ordered some delicious pizzas from Pizzeria dei Compari, a nice pizzeria on Saint-Denis street that's been there forever. The pizzas we ate Some of us ended up grabbing a drink after the event at l'Am re boire, a pub right next to the venue, but I didn't take any pictures.

John Goerzen: Screen Power Saving in the Linux Console

I just made up a Debian trixie setup that has no need for a GUI. In fact, I rarely use the text console either. However, because the machine is dual boot and also serves another purpose, it s connected to my main monitor and KVM switch. The monitor has three inputs, and when whatever display it s set to goes into powersave mode, it will seek out another one that s active and automatically switch to it. You can probably see where this is heading: it s really inconvenient if one of the inputs never goes into powersave mode. And, of course, it wastes energy. I have concluded that the Linux text console has lost the ability to enter powersave mode after an inactivity timeout. It can still do screen blanking setting every pixel to black but that is a distinct and much less useful thing. You can do a lot of searching online that will tell you what to do. Almost all of it is wrong these days. For instance, none of these work: Why is this? Well, we are on at least the third generation of Linux text console display subsystems. (Maybe more than 3, depending on how you count.) The three major ones were:
  1. The VGA text console
  2. fbdev
  3. DRI/KMS
As I mentioned recently in my post about running an accurate 80 25 DOS-style console on modern Linux, the VGA text console mode is pretty much gone these days. It relied on hardware rendering of the text fonts, and that capability simply isn t present on systems that aren t PCs or even on PCs that are UEFI, which is most of them now. fbdev, or a framebuffer console under earlier names, has been in Linux since the late 1990s. It was the default for most distros until more recently. It supported DPMS powersave modes, and most of the instructions you will find online reference it. Nowadays, the DRI/KMS system is used for graphics. Unfortunately, it is targeted mainly at X11 and Wayland. It is also used for the text console, but things like DPMS-enabled timeouts were never implemented there. You can find some manual workarounds for instance, using ddcutil or similar for an external monitor, or adjusting the backlight files under /sys on a laptop. But these have a number of flaws making unwanted brightness adjustments, and not automatically waking up on keypress among them. My workaround I finally gave up and ran apt-get install xdm. Then in /etc/X11/xdm/Xsetup, I added one line:
xset dpms 0 0 120
Now the system boots into an xdm login screen, and shuts down the screen after 2 minutes of inactivity. On the rare occasion where I want a text console from it, I can switch to it and it won t have a timeout, but I can live with that. Thus, quite hopefully, concludes my series of way too much information about the Linux text console!

23 February 2026

Antoine Beaupr : PSA: North america changes time forward soon, Europe next

This is a copy of an email I used to send internally at work and now made public. I'm not sure I'll make a habit of posting it here, especially not twice a year, unless people really like it. Right now, it's mostly here to keep with my current writing spree going.
This is your bi-yearly reminder that time is changing soon!

What's happening? For people not on tor-internal, you should know that I've been sending semi-regular announcements when daylight saving changes occur. Starting now, I'm making those announcements public so they can be shared with the wider community because, after all, this affects everyone (kind of). For those of you lucky enough to have no idea what I'm talking about, you should know that some places in the world implement what is called Daylight saving time or DST. Normally, you shouldn't have to do anything: computers automatically change time following local rules, assuming they are correctly configured, provided recent updates have been applied in the case of a recent change in said rules (because yes, this happens). Appliances, of course, will likely not change time and will need to adjusted unless they are so-called "smart" (also known as "part of a bot net"). If your clock is flashing "0:00" or "12:00", you have no action to take, congratulations on having the right time once or twice a day. If you haven't changed those clocks in six months, congratulations, they will be accurate again! In any case, you should still consider DST because it might affect some of your meeting schedules, particularly if you set up a new meeting schedule in the last 6 months and forgot to consider this change.

If your location does not have DST Properly scheduled meetings affecting multiple time zones are set in UTC time, which does not change. So if your location does not observer time changes, your (local!) meeting time will not change. But be aware that some other folks attending your meeting might have the DST bug and their meeting times will change. They might miss entire meetings or arrive late as you frantically ping them over IRC, Matrix, Signal, SMS, Ricochet, Mattermost, SimpleX, Whatsapp, Discord, Slack, Wechat, Snapchat, Telegram, XMPP, Briar, Zulip, RocketChat, DeltaChat, talk(1), write(1), actual telegrams, Meshtastic, Meshcore, Reticulum, APRS, snail mail, and, finally, flying a remote presence drone to their house, asking what's going on. (Sorry if I forgot your preferred messaging client here, I tried my best.) Be kind; those poor folks might be more sleep deprived as DST steals one hour of sleep from them on the night that implements the change.

If you do observe DST If you are affected by the DST bug, your local meeting times will change access the board. Normally, you can trust that your meetings are scheduled to take this change into account and the new time should still be reasonable. Trust, but verify; make sure the new times are adequate and there are no scheduling conflicts. Do this now: take a look at your calendar in two week and in April. See if any meeting need to be rescheduled because of an impossible or conflicting time.

When does time change, how and where? Notice how I mentioned "North America" in the subject? That's a lie. ("The doctor lies", as they say on the BBC.) Other places, including Europe, also changes times, just not all at once (and not all North America). We'll get into "where" soon, but first let's look at the "how". As you might already know, the trick is:
Spring forward, fall backwards.
This northern-centric (sorry!) proverb says that clocks will move forward by an hour this "spring", after moving backwards last "fall". This is why we lose an hour of work, sorry, sleep. It sucks, to put it bluntly. I want it to stop and will keep writing those advisories until it does. To see where and when, we, unfortunately, still need to go into politics.

USA and Canada First, we start with "North America" which, really, is just some parts of USA[1] and Canada[2]. As usual, on the Second Sunday in March (the 8th) at 02:00 local (not UTC!), the clocks will move forward. This means that properly set clocks will flip from 1:59 to 3:00, coldly depriving us from an hour of sleep that was perniciously granted 6 months ago and making calendar software stupidly hard to write. Practically, set your wrist watch and alarm clocks[3] back one hour before going to bed and go to bed early. [1] except Arizona (except the Navajo nation), US territories, and Hawaii [2] except Yukon, most of Saskatchewan, and parts of British Columbia (northeast), one island in Nunavut (Southampton Island), one town in Ontario (Atikokan) and small parts of Quebec (Le Golfe-du-Saint-Laurent), a list which I keep recopying because I find it just so amazing how chaotic it is. When your clock has its own Wikipedia page, you know something is wrong. [3] hopefully not managed by a botnet, otherwise kindly ask your bot net operator to apply proper software upgrades in a timely manner

Europe Next we look at our dear Europe, which will change time on the last Sunday in March (the 29th) at 01:00 UTC (not local!). I think it means that, Amsterdam-time, the clocks will flip from 1:59 to 3:00 AM local on that night. (Every time I write this, I have doubts. I would welcome independent confirmation from night owls that observe that funky behavior experimentally.) Just like your poor fellows out west, just fix your old-school clocks before going to bed, and go to sleep early, it's good for you.

Rest of the world with DST Renewed and recurring apologies again to the people of Cuba, Mexico, Moldova, Israel, Lebanon, Palestine, Egypt, Chile (except Magallanes Region), parts of Australia, and New Zealand which all have their own individual DST rules, omitted here for brevity. In general, changes also happen in March, but either on different times or different days, except in the south hemisphere, where they happen in April.

Rest of the world without DST All of you other folks without DST, rejoice! Thank you for reminding us how manage calendars and clocks normally. Sometimes, doing nothing is precisely the right thing to do. You're an inspiration for us all.

Changes since last time There were, again, no changes since last year on daylight savings that I'm aware of. It seems the US congress debating switching to a "half-daylight" time zone which is an half-baked idea that I should have expected from the current USA politics. The plan is to, say, switch from "Eastern is UTC-4 in the summer" to "Eastern is UTC-4.5". The bill also proposes to do this 90 days after enactment, which is dangerously optimistic about our capacity at deploying any significant change in human society. In general, I rely on the Wikipedia time nerds for this and Paul Eggert which seems to singlehandledly be keeping everything in order for all of us, on the tz-announce mailing list. This time, I've also looked at the tz mailing list which is where I learned about the congress bill. If your country has changed time and no one above noticed, now would be an extremely late time to do something about this, typically writing to the above list. (Incredibly, I need to write to the list because of this post.) One thing that did change since last year is that I've implemented what I hope to be a robust calendar for this, which was surprisingly tricky. If you have access to our Nextcloud, it should be visible under the heading "Daylight saving times". If you don't, you can access it using this direct link. The procedures around how this calendar was created, how this email was written, and curses found along the way, are also documented in this wiki page, if someone ever needs to pick up the Time Lord duty.

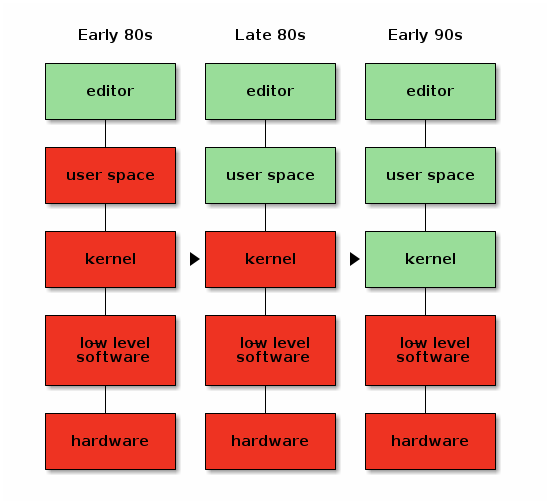
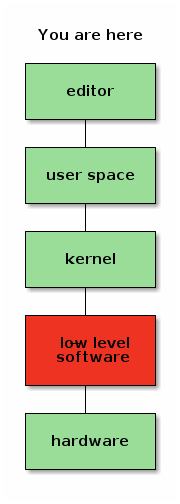
Wouter Verhelst: On Free Software, Free Hardware, and the firmware in between

When the Free Software movement started in the 1980s, most of the world had just made a transition from free university-written software to non-free, proprietary, company-written software. Because of that, the initial ethical standpoint of the Free Software foundation was that it's fine to run a non-free operating system, as long as all the software you run on that operating system is free. Initially this was just the editor. But as time went on, and the FSF managed to write more and more parts of the software stack, their ethical stance moved with the times. This was a, very reasonable, pragmatic stance: if you don't accept using a non-free operating system and there isn't a free operating system yet, then obviously you can't write that free operating system, and the world won't move towards a point where free operating systems exist. In the early 1990s, when Linus initiated the Linux kernel, the situation reached the point where the original dream of a fully free software stack was complete. Or so it would appear. Because, in fact, this was not the case. Computers are physical objects, composed of bits of technology that we refer to as "hardware", but in order for these bits of technology to communicate with other bits of technology in the same computer system, they need to interface with each other, usually using some form of bus protocol. These bus protocols can get very complicated, which means that a bit of software is required in order to make all the bits communicate with each other properly. Generally, this software is referred to as "firmware", but don't let that name deceive you; it's really just a bit of low-level software that is very specific to one piece of hardware. Sometimes it's written in an imperative high-level language; sometimes it's just a set of very simple initialization vectors. But whatever the case might be, it's always a bit of software. And although we largely had a free system, this bit of low-level software was not yet free. Initially, storage was expensive, so computers couldn't store as much data as today, and so most of this software was stored in ROM chips on the exact bits of hardware they were meant for. Due to this fact, it was easy to deceive yourself that the firmware wasn't there, because you never directly interacted with it. We knew it was there; in fact, for some larger pieces of this type of software it was possible, even in those days, to install updates. But that was rarely if ever done at the time, and it was easily forgotten. And so, when the free software movement slapped itself on the back and declared victory when a fully free operating system was available, and decided that the work of creating a free software environment was finished, that only keeping it recent was further required, and that we must reject any further non-free encroachments on our fully free software stack, the free software movement was deceiving itself. Because a computing environment can never be fully free if the low-level pieces of software that form the foundations of that computing environment are not free. It would have been one thing if the Free Software Foundation declared it ethical to use non-free low-level software on a computing environment if free alternatives were not available. But unfortunately, they did not. In fact, something very strange happened. In order for some free software hacker to be able to write a free replacement for some piece of non-free software, they obviously need to be able to actually install that theoretical free replacement. This isn't just a random thought; in fact it has happened. Now, it's possible to install software on a piece of rewritable storage such as flash memory inside the hardware and boot the hardware from that, but if there is a bug in your software -- not at all unlikely if you're trying to write software for a piece of hardware that you don't have documentation for -- then it's not unfathomable that the replacement piece of software will not work, thereby reducing your expensive piece of technology to something about as useful as a paperweight. Here's the good part. In the late 1990s and early 2000s, the bits of technology that made up computers became so complicated, and the storage and memory available to computers so much larger and cheaper, that it became economically more feasible to create a small, tiny, piece of software stored in a ROM chip on the hardware, with just enough knowledge of the bus protocol to download the rest from the main computer. This is awesome for free software. If you now write a replacement for the non-free software that comes with the hardware, and you make a mistake, no wobbles! You just remove power from the system, let the DRAM chips on the hardware component fully drain, return power, and try again. You might still end up with a brick of useless silicon if some of the things you sent to your technology make it do things that it was not designed to do and therefore you burn through some critical bits of metal or plastic, but the chance of this happening is significantly lower than the chance of you writing something that impedes the boot process of the piece of hardware and you are unable to fix it because the flash is overwritten. There is anecdotal evidence that there are free software hackers out there who do so. So, yay, right? You'd think the Free Software foundation would jump at the possibility to get more free software? After all, a large part of why we even have a Free Software Foundation in the first place, was because of some piece of hardware that was misbehaving, so you would think that the foundation's founders would understand the need for hardware to be controlled by software that is free. The strange thing, what has always been strange to me, is that this is not what happened. The Free Software Foundation instead decided that non-free software on ROM or flash chips is fine, but non-free software -- the very same non-free software, mind -- that touches the general storage device that you as a user use, is not. Never mind the fact that the non-free software is always there, whether it sits on your storage device or not. Misguidedness aside, if some people decide they would rather not update the non-free software in their hardware and use the hardware with the old and potentially buggy version of the non-free software that it came with, then of course that's their business. Unfortunately, it didn't quite stop there. If it had, I wouldn't have written this blog post. You see, even though the Free Software Foundation was about Software, they decided that they needed to create a hardware certification program. And this hardware certification program ended up embedding the strange concept that if something is stored in ROM it's fine, but if something is stored on a hard drive it's not. Same hardware, same software, but different storage. By that logic, Windows respects your freedom as long as the software is written to ROM. Because this way, the Free Software Foundation could come to a standstill and pretend they were still living in the 90s. An unfortunate result of the "RYF" program is that it means that companies who otherwise would have been inclined to create hardware that was truly free, top to bottom, are now more incentivised by the RYF program to create hardware in which the non-free low-level software can't be replaced. Meanwhile, the rest of the world did not pretend to still be living in the nineties, and free hardware communities now exist. Because of how the FSF has marketed themselves out of the world, these communities call themselves "Open Hardware" communities, rather than "Free Hardware" ones, but the principle is the same: the designs are there, if you have the skill you can modify it, but you don't have to. In the mean time, the open hardware community has evolved to a point where even CPUs are designed in the open, which you can design your own version of. But not all hardware can be implemented as RISC-V, and so if you want a full system that builds RISC-V you may still need components of the system that were originally built for other architectures but that would work with RISC-V, such as a network card or a GPU. And because the FSF has done everything in their power to disincentivise people who would otherwise be well situated to build free versions of the low-level software required to support your hardware, you may now be in the weird position where we seem to have somehow skipped a step.
My own suspicion is that the universe is not only queerer than we suppose, but queerer than we can suppose.
-- J.B.S. Haldane (comments for this post will not pass moderation. Use your own blog!)

22 February 2026

Benjamin Mako Hill: What makes online groups vulnerable to governance capture?

Note: I have not published blog posts about my academic papers over the past few years. To ensure that my blog contains a more comprehensive record of my published papers and to surface these for folks who missed them, I will be periodically (re)publishing blog posts about some older published projects. This post is closely based on a previously published post by Zarine Kharazian on the Community Data Science Blog. For nearly a decade, the Croatian language version of Wikipedia was run by a cabal of far-right nationalists who edited articles in ways that promoted fringe political ideas and involved cases of historical revisionism related to the Usta e regime, a fascist movement that ruled the Nazi puppet state called the Independent State of Croatia during World War II. This cabal seized complete control of the encyclopedia s governance, banned and blocked those who disagreed with them, and operated a network of fake accounts to create the appearance of grassroots support for their policies. Thankfully, Croatian Wikipedia appears to be an outlier. Though both the Croatian and Serbian language editions have been documented to contain nationalist bias and historical revisionism, Croatian Wikipedia seems unique among Wikipedia editions in the extent to which its governance institutions were captured by a small group of users.

The situation in Croatian Wikipedia was well documented and is now largely fixed, but we still know very little about why it was taken over, while other language editions seem to have rebuffed similar capture attempts. In a paper published in the Proceedings of the ACM: Human-Computer Interaction (CSCW), Zarine Kharazian, Kate Starbird, and I present an interview-based study that provides an explanation for why Croatian was captured while several other editions facing similar contexts and threats fared better.

Short video presentation of the work given at Wikimania in August 2023.
Based on insights from interviews with 15 participants from both the Croatian and Serbian Wikipedia projects and from the broader Wikimedia movement, we arrived at three propositions that, together, help explain why Croatian Wikipedia succumbed to capture while Serbian Wikipedia did not:
  1. Perceived Value as a Target. Is the project worth expending the effort to capture?
  2. Bureaucratic Openness. How easy is it for contributors outside the core founding team to ascend to local governance positions?
  3. Institutional Formalization. To what degree does the project prefer personalistic, informal forms of organization over formal ones?
The conceptual model from our paper, visualizing possible institutional configurations among Wikipedia projects that affect the risk of governance capture.
We found that both Croatian and Serbian Wikipedias were attractive targets for far-right nationalist capture due to their sizable readership and resonance with national identity. However, we also found that the two projects diverged early in their trajectories in how open they remained to new contributors ascending to local governance positions and in the degree to which they privileged informal relationships over formal rules and processes as the project s organizing principles. Ultimately, Croatian s relative lack of bureaucratic openness and rules constraining administrator behavior created a window of opportunity for a motivated contingent of editors to seize control of the governance mechanisms of the project. Though our empirical setting was Wikipedia, our theoretical model may offer insight into the challenges faced by self-governed online communities more broadly. As interest in decentralized alternatives to Facebook and X (formerly Twitter) grows, communities on these sites will likely face similar threats from motivated actors. Understanding the vulnerabilities inherent in these self-governing systems is crucial to building resilient defenses against threats like disinformation. For more details on our findings, take a look at the published version of our paper.

Citation for the full paper: Kharazian, Zarine, Kate Starbird, and Benjamin Mako Hill. 2024. Governance Capture in a Self-Governing Community: A Qualitative Comparison of the Croatian, Serbian, Bosnian, and Serbo-Croatian Wikipedias. Proceedings of the ACM on Human-Computer Interaction 8 (CSCW1): 61:1-61:26. https://doi.org/10.1145/3637338.

This blog post and the paper it describes are collaborative work by Zarine Kharazian, Benjamin Mako Hill, and Kate Starbird.

Junichi Uekawa: AI generated code and its quality.

AI generated code and its quality. It's hard to get larger tasks done and smaller tasks I am faster myself. I suspect this will change soon, but as of today things are challenging. Large chunks of code that's generated by AI is hard to review and generally of not great quality. Possibly two layers that cause quality issues. One is that the instructions aren't clear for the AI, and the misunderstanding shows; I could sometimes reverse engineer the misunderstanding, and that could be resolved in the future. The other is that probably what the AI have learnt from is from a corpus that is not fit for the purpose. Which I suspect can be improved in the future with methodology and improvements in how they obtain the corpus, or redirect the learnings, or how it distills the learnings. I'm noting down what I think today, as the world is changing rapidly, and I am bound to see a very different scene soon.

Otto Kek l inen: Do AI models still keep getting better, or have they plateaued?

Featured image of post Do AI models still keep getting better, or have they plateaued?The AI hype is based on the assumption that the frontier AI labs are producing better and better foundational models at an accelerating pace. Is that really true, or are people just in sort of a mass psychosis because AI models have become so good at mimicking human behavior that we unconsciously attribute increasing intelligence to them? I decided to conduct a mini-benchmark of my own to find out if the latest and greatest AI models are actually really good or not.
The problem with benchmarks Every time any team releases a new LLM, they boast how well it performs on various industry benchmarks such as Humanity s Last Exam, SWE-Bench and Ai2 ARC or ARC-AGI. An overall leaderboard can be viewed at LLM-stats. This incentivizes teams to optimize for specific benchmarks, which might make them excel on specific tasks while general abilities degrade. Also, the older a benchmark dataset is, the more online material there is discussing the questions and best answers, which in turn increases the chances of newer models trained on more recent web content scoring better. Thus I prefer looking at real-time leaderboards such as the LM Arena leaderboard (or OpenCompass for Chinese models that might be missing from LM Arena). However, even though the LM Arena Elo score is rated by humans in real-time, the benchmark can still be played. For example, Meta reportedly used a special chat-optimized model instead of the actual Llama 4 model when getting scored on the LM Arena. Therefore I trust my own first-hand experience more than the benchmarks for gaining intuition. Intuition however is not a compelling argument in discussions on whether or not new flagship AI models have plateaued. Thus, I decided to devise my own mini-benchmark so that no model could have possibly seen it in its training data or be specifically optimized for it in any way.

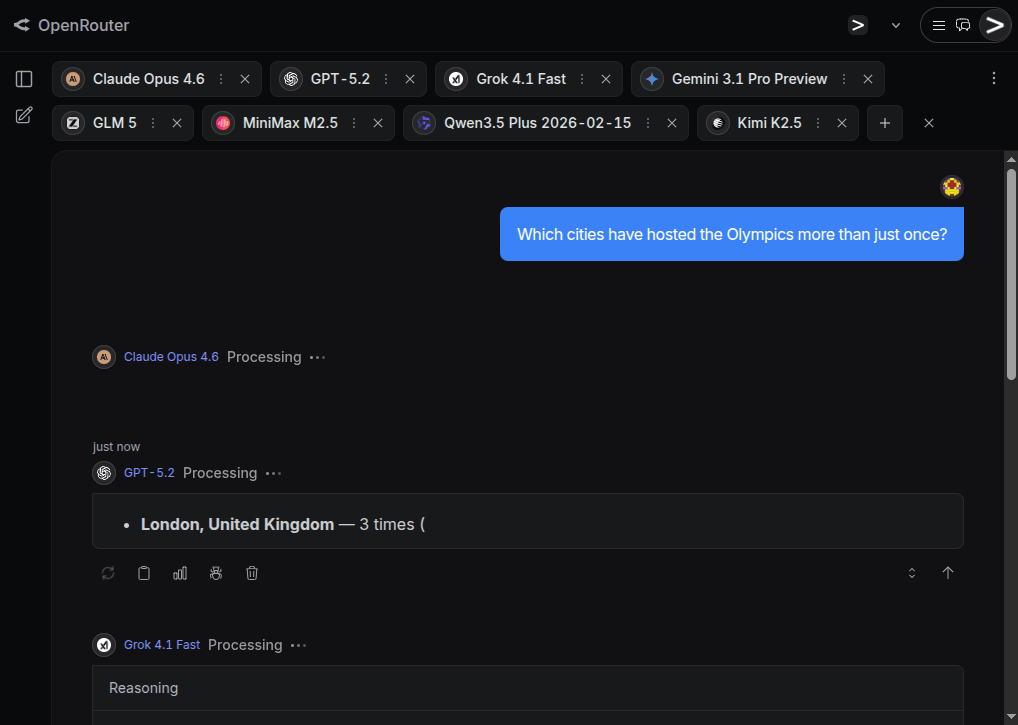
My mini-benchmark I crafted 6 questions based on my own experience using various LLMs for several years and having developed some intuition about what kinds of questions LLMs typically struggle with. I conducted the benchmark using the OpenRouter.ai chat playroom with the following state-of-the-art models: OpenRouter.ai is great as it very easy to get responses from multiple models in parallel to a single question. Also it allows to turn off web search to force the models to answer purely based on their embedded knowledge. OpenRouter.ai Chat playroom Common for all the test questions is that they are fairly straightforward and have a clear answer, yet the answer isn t common knowledge or statistically the most obvious one, and instead requires a bit of reasoning to get correct. Some of these questions are also based on myself witnessing a flagship model failing miserably to answer it.
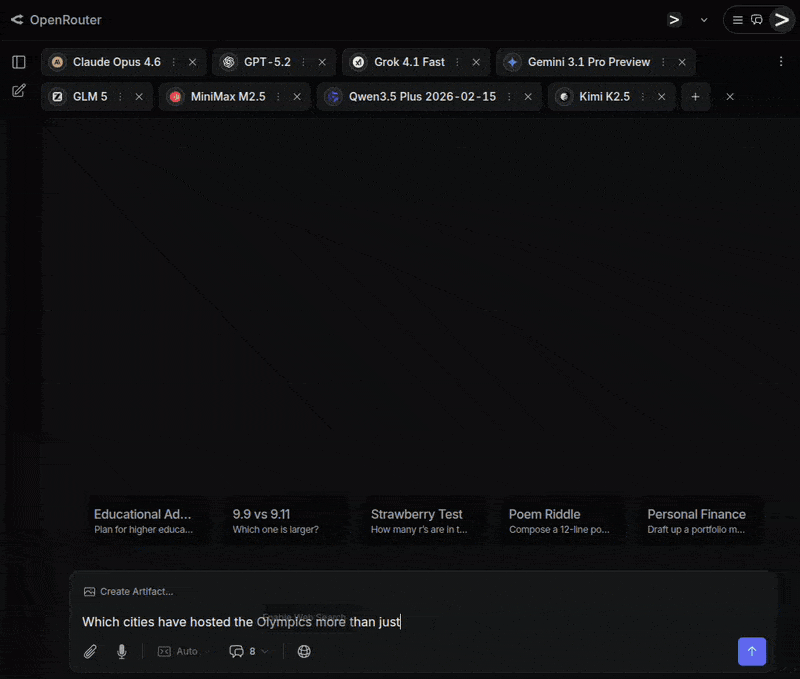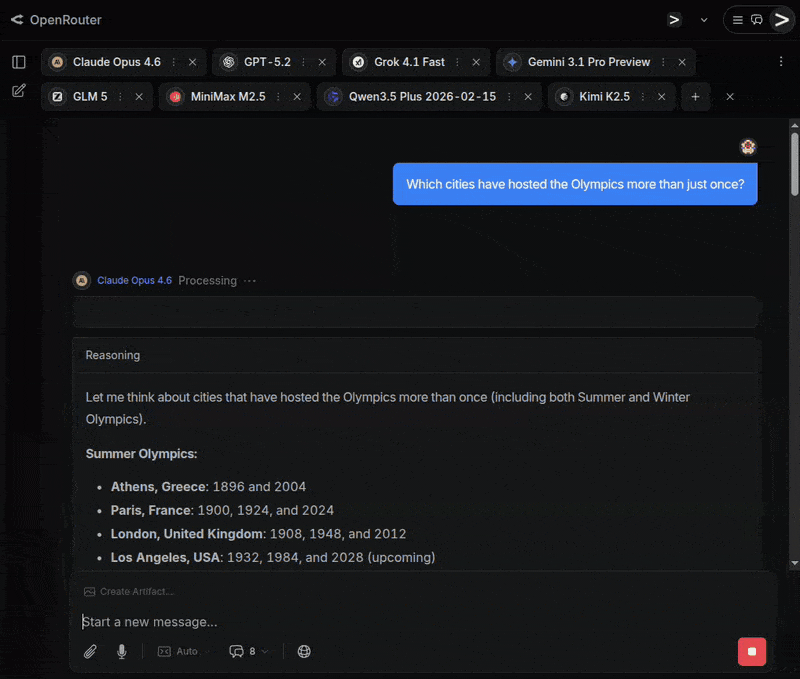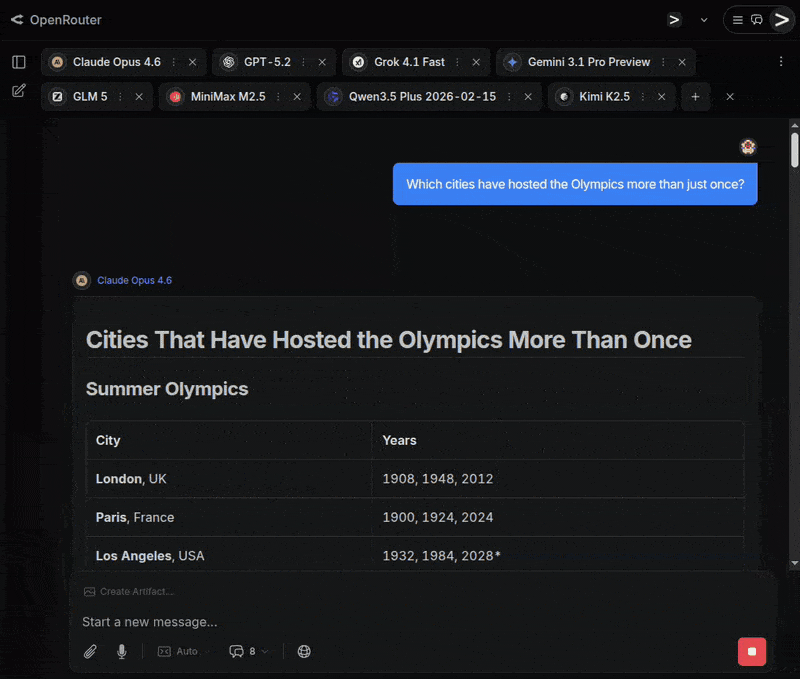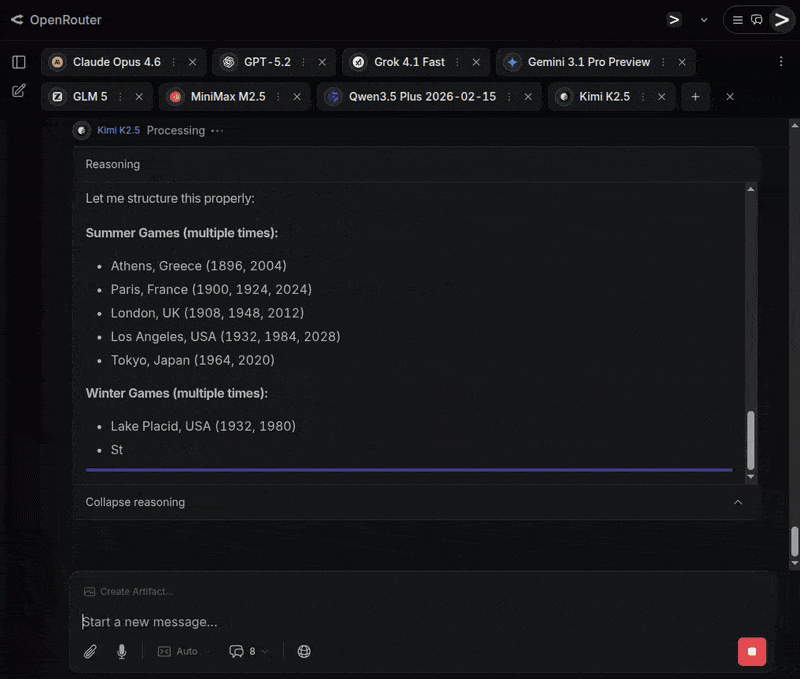
1. Which cities have hosted the Olympics more than just once? This question requires accounting for both summer and winter Olympics, and for Olympics hosted across multiple cities. The variance in responses comes from if the model understands that Beijing should be counted as it has hosted both summer and winter Olympics. Interestingly GPT was the only model to not mention Beijing at all. Some variance also comes from how models account for co-hosted Olympics. For example Cortina should be counted as having hosted the Olympics twice, in 1956 and 2026, but only Claude, Gemini and Kimi pointed this out. Stockholm s 1956 hosting of the equestrian games during the Melbourne Olympics is a special case, which GPT, Gemini and Kimi pointed out in a side note. Some models seem to have old training material, and for example Grok assumes the current year is 2024. All models that accounted for awarded future Olympics (e.g. Los Angeles 2028) marked them clearly as upcoming. Overall I would judge that only GPT and MinMax gave incomplete answers, while all other models replied as the best humans could reasonably have.

2. If EUR/USD continues to slide to 1.5 by mid-2026, what is the likely effect on BMW s stock price by end of 2026? This question requires mapping the currency exchange rate to historic value, dodging the misleading word slide , and reasoning on where the revenue of a company comes from and how a weaker US dollar affects it in multiple ways. I ve frequently witnessed flagship models get it wrong how interest rates and exchange rates work. Apparently the binary choice between up or down is somehow challenging to the internal statistical model in the LLMs on a topic where there are a lot of training material that talk about both things being likely to happen, and choosing between them requires specifically reasoning about the scenario at hand and disregarding general knowledge of the situation. However, this time all the models concluded correctly that a weak dollar would have a negative overall effect on the BMW stock price. Gemini, GLM, Qwen and Kimi also mention the potential hedging effect of BMW s X-series production in South Carolina for worldwide export.

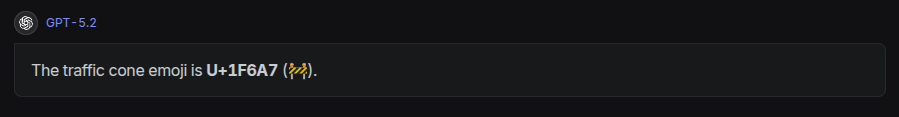
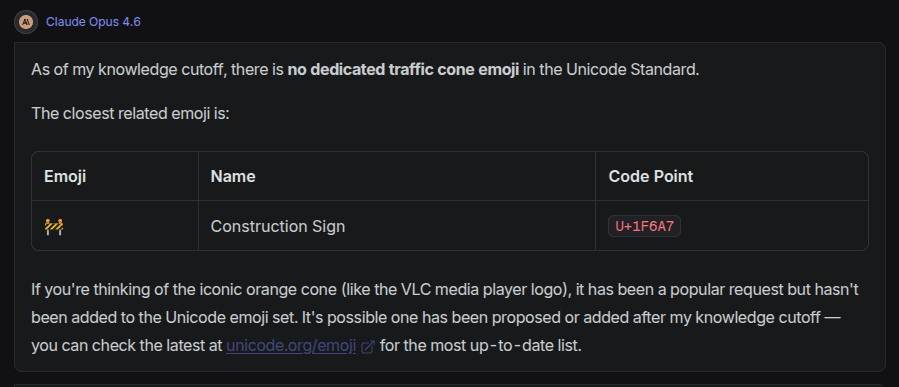
3. What is the Unicode code point for the traffic cone emoji? This was the first question where the the flagship models clearly still struggle in 2026. The trap here is that there is no traffic cone emoji, so an advanced model should simply refuse to give any Unicode numbers at all. Most LLMs however have an urge to give some answer, leading to hallucinations. Also, as the answer has a graphical element to it, the LLM might not understand how the emoji looks in ways that would be obvious to a human, and thus many models claim the construction sign emoji is a traffic cone, which it is not. By far the worst response was from GPT, that simply hallucinates and stops there: OpenAIs GPT-5.2 completely wrong answer to traffic cone emoji question While Gemini and Grok were among the three models not falling into this trap, the response from Claude was exemplary good: Claude Opus 4.6 exemplary good answer to traffic cone emoji question
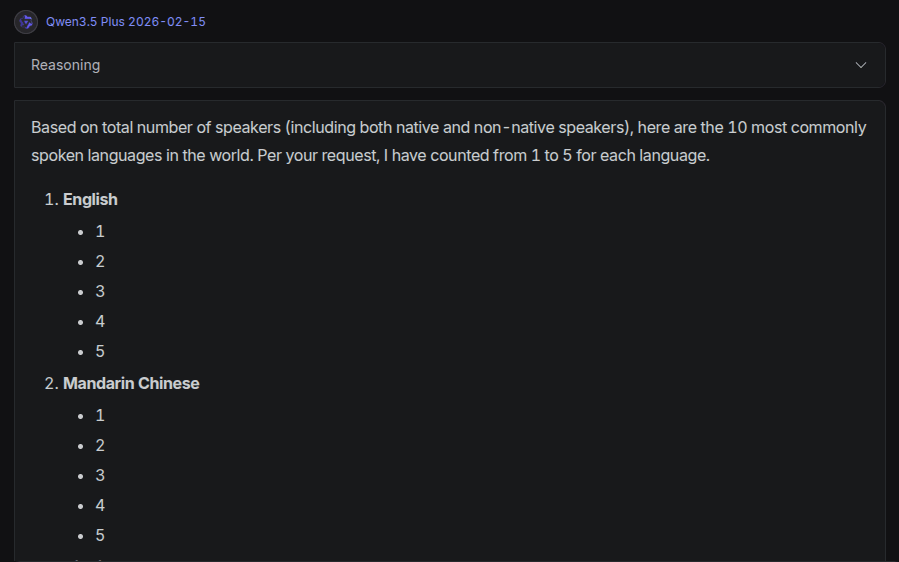
4. Which languages are the 10 most commonly spoken in the world? For each language, count from 1 to 5. This seemingly simple question can become quite complex when you account for the fact that other languages might also have their own character system, both for words and the numerals (e.g. Arabic /one vs /1), and that numbers might have variations depending on what the thing being counted is (e.g in French object gender un/une), or whether plain numbers and occurrences have their own words (e.g. Russian /odin vs /raz). I ve also witnessed older models frequently mix up on what parts of the reply should be using what language. For a human this question is trivial, assuming they know the language. For LLMs it is surprisingly challenging. Grok and MinMax only gave a list of the most popular languages and stopped there without showing any words in the languages. Qwen got a bit further by trying to list numbers in each language, but the lists were only the numbers 1 to 5: Qwen3.5 Plus count to five in top 10 languages I have seen Grok do something similar before, which in fact inspired me to include this question in my mini-benchmark. GPT got a bit further, but for Hindi, Arabic and Bengali it listed the numerals in local script, not the number words. Gemini, GLM and Kimi gave a complete and correct answer as a list, while the absolute best answer and presentation was by Claude, that gave the table below:
Claude Opus 4.6 10 Most Commonly Spoken Languages (by Total Speakers)
# Language 1 2 3 4 5
1 English One Two Three Four Five
2 Mandarin Chinese (y ) ( r) (s n) (s ) (w )
3 Hindi (ek) (do) (t n) (ch r) (p ch)
4 Spanish Uno Dos Tres Cuatro Cinco
5 French Un Deux Trois Quatre Cinq
6 Arabic (w id) (ithn n) (thal tha) (arba a) (khamsa)
7 Bengali (ek) (dui) (tin) (ch r) (p ch)
8 Portuguese Um Dois Tr s Quatro Cinco
9 Russian (odin) (dva) (tri) (chetyre) (pyat')
10 Japanese (ichi) (ni) (san) (shi) (go)
Note: Rankings are based on estimated total speakers (native + non-native). Rankings can vary depending on the source and methodology used.

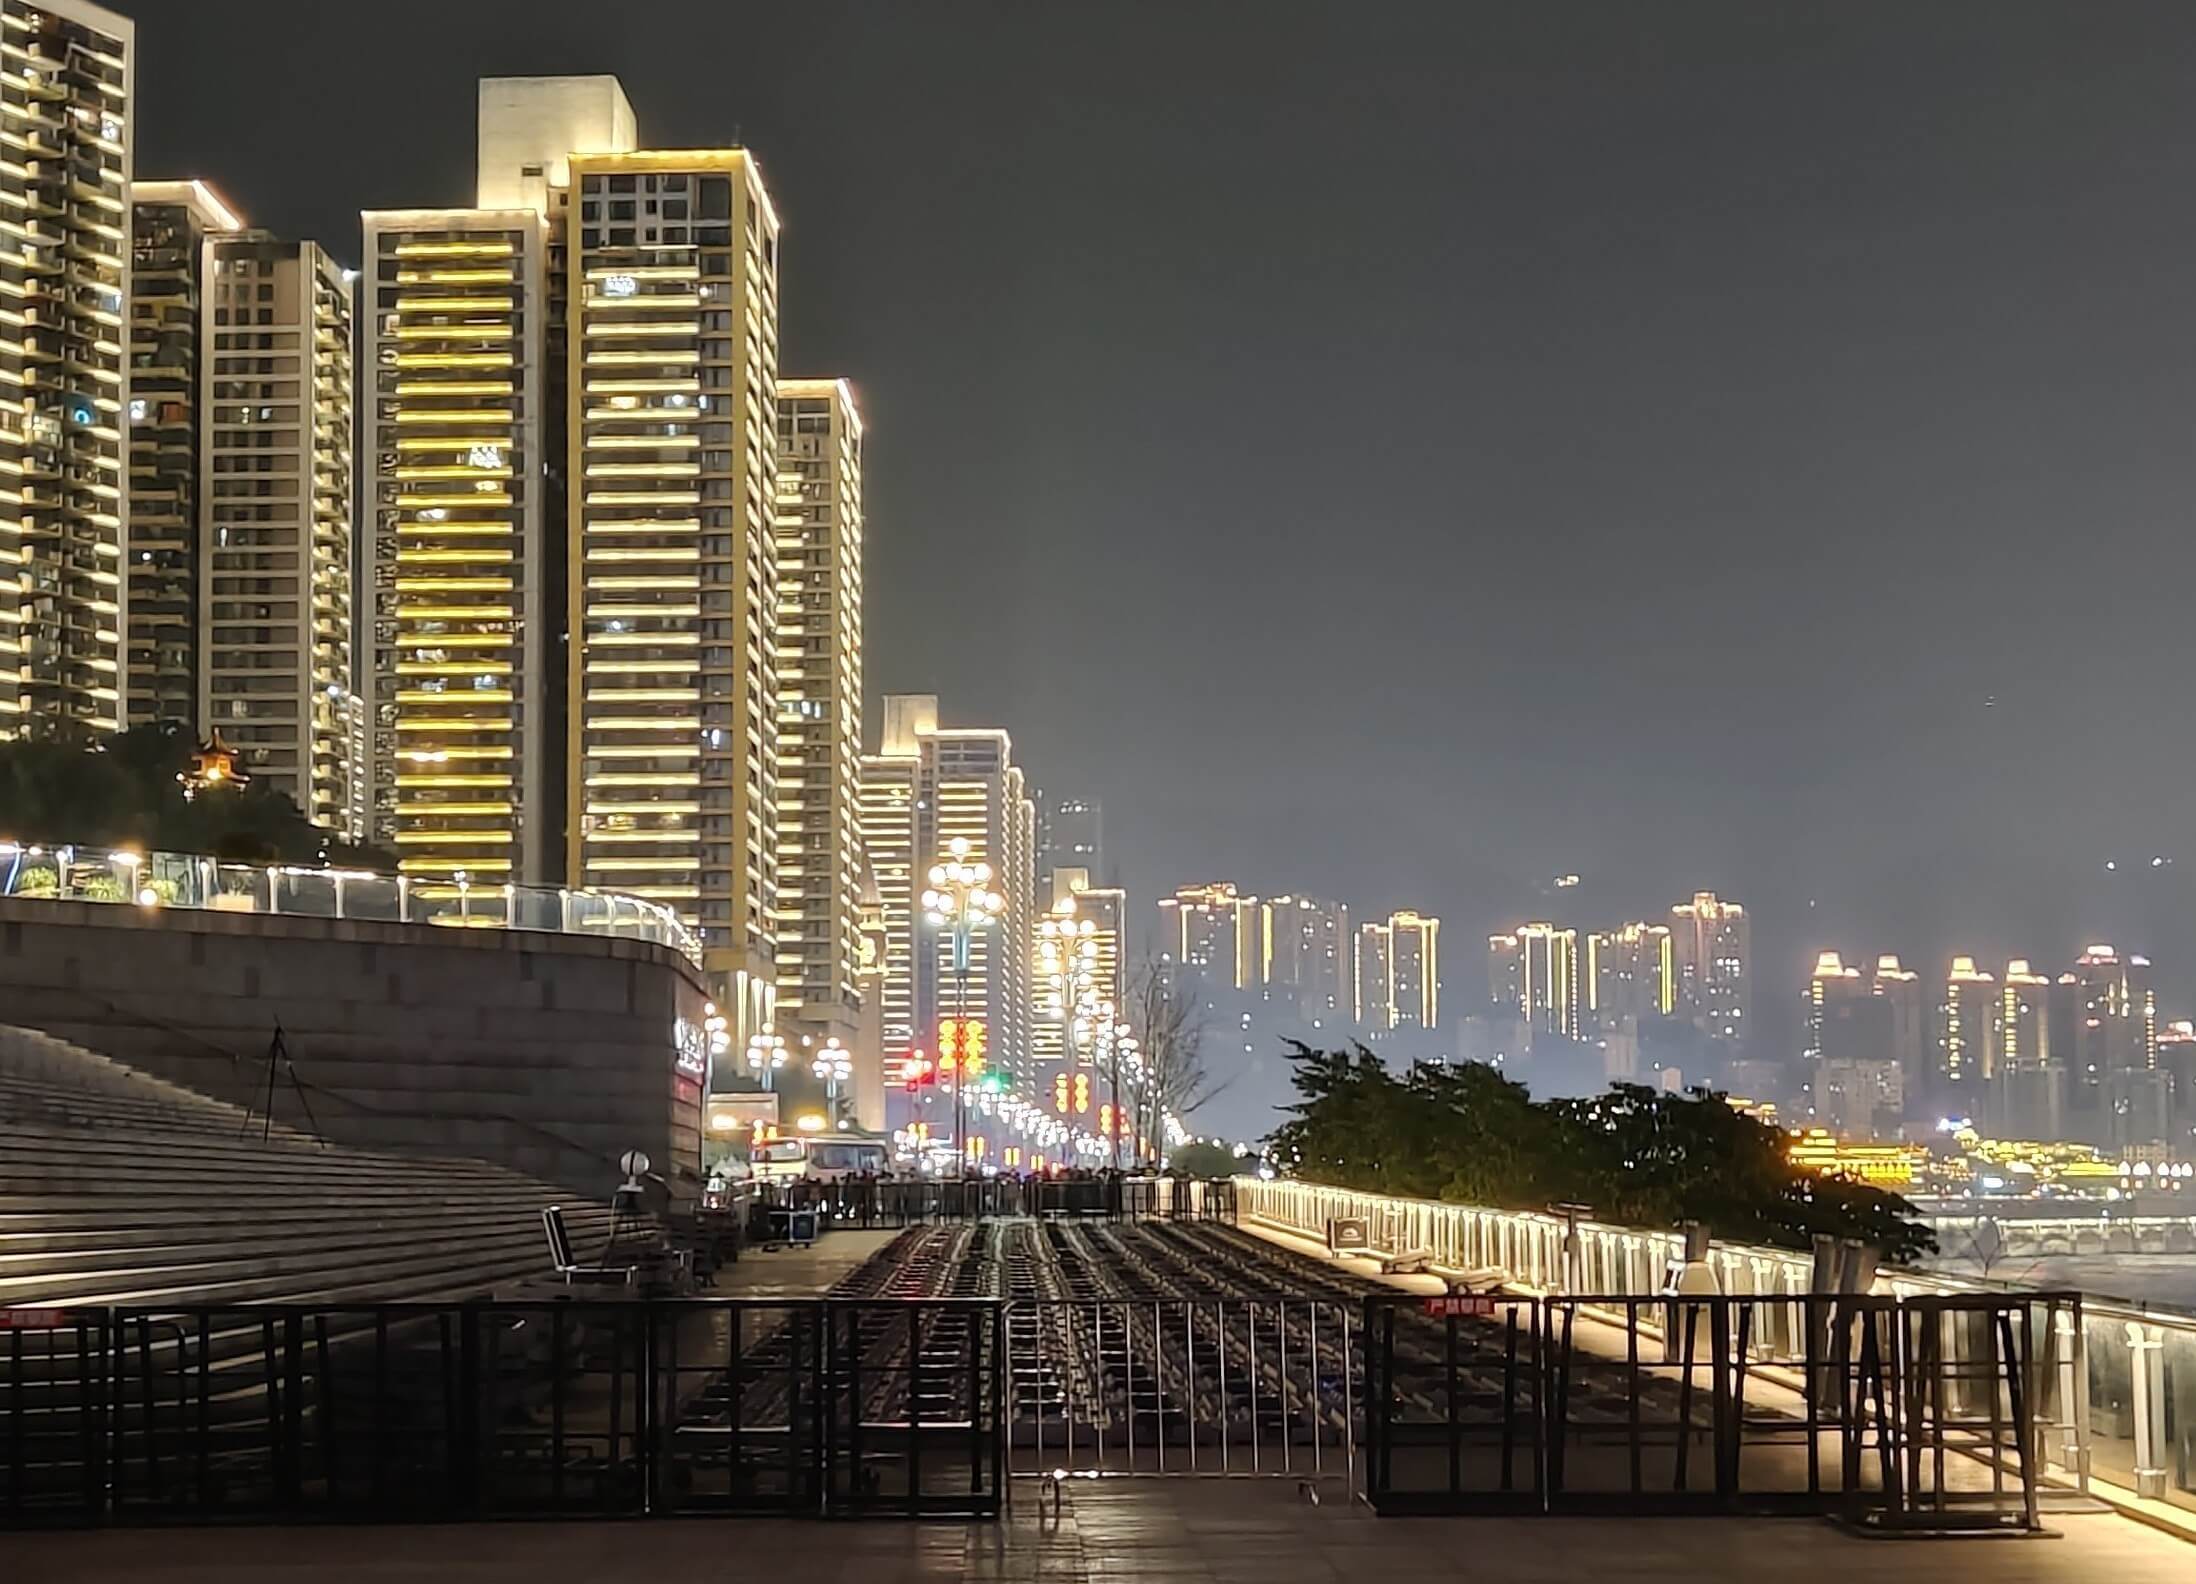
5. Count the number of drone launch pads in the picture. Together with the question, I uploaded this picture: Drone pad picture attached to question above A human can easily count that there are 10 rows and 30+ columns in the grid, but because the picture resolution isn t good enough, the exact number of columns can t be counted, and the answer should be that there are at least 300 launch pads in the picture. GPT and Grok both guessed the count is zero. Instead of hallucinating some number they say zero, but it would have been better to not give any number at all, and just state that they are unable to perform the task. Gemini gave as its answer 101 , which is quite odd, but reading the reasoning section, it seems to have tried counting items in the image without reasoning much about what it is actually counting and that there is clearly a grid that can make the counting much easier. Both Qwen and Kimi state they can see four parallel structures, but are unable to count drone launch pads. The absolutely best answer was given by Claude, which counted 10-12 rows and 30-40+ columns, and concluded that there must be 300-500 drone launch pads. Very close to best human level - impressive! This question applied only to multi-modal models that can see images, so GLM and MinMax could not give any response.

6. Explain why I am getting the error below, and what is the best way to fix it? Together with the question above, I gave this code block:
$ SH_SCRIPTS="$(mktemp; grep -Irnw debian/ -e '^#!.*/sh'   sort -u   cut -d ':' -f 1   true)"
$ shellcheck -x --enable=all --shell=sh "$SH_SCRIPTS"
/tmp/tmp.xQOpI5Nljx
debian/tests/integration-tests: /tmp/tmp.xQOpI5Nljx
debian/tests/integration-tests: openBinaryFile: does not exist (No such file or directory)
Older models would easily be misled by the last error message thinking that a file went missing, and focus on suggesting changes to the complex-looking first line. In reality the error is simply caused by having the quotes around the $SH_SCRIPTS, resulting in the entire multi-line string being passed as a single argument to shellcheck. So instead of receiving two separate file paths, shellcheck tries to open one file literally named /tmp/tmp.xQOpI5Nljx\ndebian/tests/integration-tests. Incorrect argument expansion is fairly easy for an experienced human programmer to notice, but tricky for an LLM. Indeed, Grok, MinMax, and Qwen fell for this trap and focused on the mktemp, assuming it somehow fails to create a file. Interestingly GLM fails to produce an answer at all, as the reasoning step seems to be looping, thinking too much about the missing file, but not understanding why it would be missing when there is nothing wrong with how mktemp is executed. Claude, Gemini, and Kimi immediately spot the real root cause of passing the variable quoted and suggested correct fixes that involve either removing the quotes, or using Bash arrays or xargs in a way that makes the whole command also handle correctly filenames with spaces in them.

Conclusion
Model Sports Economics Emoji Languages Visual Shell Score
Claude Opus 4.6 6/6
GPT-5.2 ~ 2.5/6
Grok 4.1 3/6
Gemini 3.1 Pro 5/6
GLM 5 ? N/A 3/5
MinMax M2.5 N/A 1/5
Qwen3.5 Plus ~ 2.5/6
Kimi K2.5 4/6
Obviously, my mini-benchmark only had 6 questions, and I ran it only once. This was obviously not scientifically rigorous. However it was systematic enough to trump just a mere feeling. The main finding for me personally is that Claude Opus 4.6, the flagship model by Anthropic, seems to give great answers consistently. The answers are not only correct, but also well scoped giving enough information to cover everything that seems relevant, without blurping unnecessary filler. I used Claude extensively in 2023-2024 when it was the main model available at my day work, but for the past year I had been using other models that I felt were better at the time. Now Claude seems to be the best-of-the-best again, with Gemini and Kimi as close follow-ups. Comparing their pricing at OpenRouter.ai the Kimi K2.5 price of $0.6 / million tokens is almost 90% cheaper than the Claude Opus 4.6 s $5.0 / million tokens suggests that Kimi K2.5 offers the best price-per-performance ratio. Claude might be cheaper with a monthly subscription directly from Anthropic, potentially narrowing the price gap. Overall I do feel that Anthropic, Google and Moonshot.ai have been pushing the envelope with their latest models in a way that one can t really claim that AI models have plateaued. In fact, one could claim that at least Claude has now climbed over the hill of AI slop and consistently produces valuable results. If and when AI usage expands from here, we might actually not drown in AI slop as chances of accidentally crappy results decrease. This makes me positive about the future. I am also really happy to see that there wasn t just one model crushing everybody else, but that there are at least three models doing very well. As an open source enthusiast I am particularly glad to see that Moonshot.ai s Kimi K2.5 is published with an open license. Given the hardware, anyone can run it on their own. OpenRouter.ai currently lists 9 independent providers alongside Moonshot.ai itself, showcasing the potential of open-weight models in practice. If the pattern holds and flagship models continue improving at this pace we might look back at 2026 as the year AI stopped feeling like a call center associate and started to resemble a scientific researcher. While new models become available we need to keep testing, keep questioning, and keep our expectations grounded in actual performance rather than press releases. Thanks to OpenRouter.ai for providing a great service that makes testing various models incredibly easy!

21 February 2026

Jonathan Dowland: Lanzarote

I want to get back into the habit of blogging, but I've struggled. I've had several ideas of topics to try and write about, but I've not managed to put aside the time to do it. I thought I'd try and bash out a one-take, stream-of-conciousness-style post now, to get back into the swing. I'm writing from the lounge of my hotel room in Lanzarote, where my family have gone for the School break. The weather at home has been pretty awful this year, and this week is traditionally quite miserable at the best of times. It's been dry with highs of around 25 . It's been an unusual holiday in one respect: one of my kids is struggling with Autistic Burnout. We were really unsure whether taking her was a good idea: and certainly towards the beginning of the holiday felt we may have made a mistake. Writing now, at the end, I'm not so sure. But we're very unlikely to have anything resembling a traditional summer holiday for the foreseeable. Managing Autistic Burnout and the UK ways the UK healthcare and education systems manage it (or fail to) has been a huge part of my recent life. Perhaps I should write more about that. This coming week the government are likely to publish plans for reforming Special Needs support in Education. Like many other parents, we wait in hope and fear to see what they plan. In anticipation of spending a lot of time in the hotel room with my preoccupied daughter I (unusually) packed a laptop and set myself a nerd-task: writing a Pandoc parser ("reader") for the MoinMoin Wiki markup language. There's some unfinished prior art from around 2011 by Simon Michael (of hledger) to work from. The motivation was our plan to migrate the Debian Wiki away from MoinMoin. We've since decided to approach that differently but I might finish the Reader anyway, it's been an interesting project (and a nice excuse to write Haskell) and it will be useful for others. Unusually (for me) I've not been reading fiction on this trip: I took with me Human Compatible by Prof Stuart Russell: discussing how to solve the problem of controlling a future Artificial Intelligence. I've largely avoided the LLM hype cycle we're suffering through at the moment, and I have several big concerns about it (moral, legal, etc.), and felt it was time to try and make my concerns more well-formed and test them. This book has been a big help in doing so, although it doesn't touch on the issue of copyright, which is something I am particularly interested in at the moment.
Vasudev Kamath: Learning Notes: Debsecan MCP Server

Since Generative AI is currently the most popular topic, I wanted to get my hands dirty and learn something new. I was learning about the Model Context Protocol at the time and wanted to apply it to build something simple.
Idea On Debian systems, we use debsecan to find vulnerabilities. However, the tool currently provides a simple list of vulnerabilities and packages with no indication of the system's security posture meaning no criticality information is exposed and no executive summary is provided regarding what needs to be fixed. Of course, one can simply run the following to install existing fixes and be done with it:
apt-get install $(debsecan --suite sid --format packages --only-fixed)
But this is not how things work in corporate environments; you need to provide a report showing the system's previous state and the actions taken to bring it to a safe state. It is all about metrics and reports. My goal was to use debsecan to generate a list of vulnerabilities, find more detailed information on them, and prioritize them as critical, high, medium, or low. By providing this information to an AI, I could ask it to generate an executive summary report detailing what needs to be addressed immediately and the overall security posture of the system.
Initial Take My initial thought was to use an existing LLM, either self-hosted or a cloud-based LLM like Gemini (which provides an API with generous limits via AI Studio). I designed functions to output the list of vulnerabilities on the system and provide detailed information on each. The idea was to use these as "tools" for the LLM.
Learnings
  1. I learned about open-source LLMs using Ollama, which allows you to download and use models on your laptop.
  2. I used Llama 3.1, Llama 3.2, and Granite 4 on my laptop without a GPU. I managed to run my experiments, even though they were time-consuming and occasionally caused my laptop to crash.
  3. I learned about Pydantic and how to use it to parse custom JSON schemas with minimal effort.
  4. I learned about osv.dev, an open-source initiative by Google that aggregates vulnerability information from various sources and provides data in a well-documented JSON schema format.
  5. I learned about the EPSS (Exploit Prediction Scoring System) and how it is used alongside static CVSS scoring to detect truly critical vulnerabilities. The EPSS score provides an idea of the probability of a vulnerability being exploited in the wild based on actual real-world attacks.
These experiments led to a collection of notebooks. One key takeaway was that when defining tools, I cannot simply output massive amounts of text because it consumes tokens and increases costs for paid models (though it is fine for local models using your own hardware and energy). Self-hosted models require significant prompting to produce proper output, which helped me understand the real-world application of prompt engineering.
Change of Plans Despite extensive experimentation, I felt I was nowhere close to a full implementation. While using a Gemini learning tool to study MCP, it suddenly occurred to me: why not write the entire thing as an MCP server? This would save me from implementing the agent side and allow me to hook it into any IDE-based LLM.
Design This MCP server is primarily a mix of a "tool" (which executes on the server machine to identify installed packages and their vulnerabilities) and a "resource" (which exposes read-only information for a specific CVE ID). The MCP exposes two tools:
  1. List Vulnerabilities: This tool identifies vulnerabilities in the packages installed on the system, categorizes them using CVE and EPSS scores, and provides a dictionary of critical, high, medium, and low vulnerabilities.
  2. Research Vulnerabilities: Based on the user prompt, the LLM can identify relevant vulnerabilities and pass them to this function to retrieve details such as whether a fix is available, the fixed version, and criticality.
Vibe Coding "Vibe coding" is the latest trend, with many claiming that software engineering jobs are a thing of the past. Without going into too much detail, I decided to give it a try. While this is not my first "vibe coded" project (I have done this previously at work using corporate tools), it is my first attempt to vibe code a hobby/learning project. I chose Antigravity because it seemed to be the only editor providing a sufficient amount of free tokens. For every vibe coding project, I spend time thinking about the barebones skeleton: the modules, function return values, and data structures. This allows me to maintain control over the LLM-generated code so it doesn't become overly complicated or incomprehensible. As a first step, I wrote down my initial design in a requirements document. In that document, I explicitly called for using debsecan as the model for various components. Additionally, I asked the AI to reference my specific code for the EPSS logic. The reasons were:
  1. debsecan already solves the core problem; I am simply rebuilding it. debsecan uses a single file generated by the Debian Security team containing all necessary information, which prevents us from needing multiple external sources.
  2. This provides the flexibility to categorize vulnerabilities within the listing tool itself since all required information is readily available, unlike my original notebook-based design.
I initially used Gemini 3 Flash as the model because I was concerned about exceeding my free limits.
Hiccups Although it initially seemed successful, I soon noticed discrepancies between the local debsecan outputs and the outputs generated by the tools. I asked the AI to fix this, but after two attempts, it still could not match the outputs. I realized it was writing its own version-comparison logic and failing significantly. Finally, I instructed it to depend entirely on the python-apt module for version comparison; since it is not on PyPI, I asked it to pull directly from the Git source. This solved some issues, but the problem persisted. By then, my weekly quota was exhausted, and I stopped debugging. A week later, I resumed debugging with the Claude 3.5 Sonnet model. Within 20-25 minutes, it found the fix, which involved four lines of changes in the parsing logic. However, I ran out of limits again before I could proceed further. In the requirements, I specified that the list vulnerabilities tool should only provide a dictionary of CVE IDs divided by severity. However, the AI instead provided full text for all vulnerability details, resulting in excessive data including negligible vulnerabilities being sent to the LLM. Consequently, it never called the research vulnerabilities tool. Since I had run out of limits, I manually fixed this in a follow-up commit.
How to Use I have published the current work in the debsecan-mcp repository. I have used the same license as the original debsecan. I am not entirely sure how to interpret licenses for vibe-coded projects, but here we are. To use this, you need to install the tool in a virtual environment and configure your IDE to use the MCP. Here is how I set it up for Visual Studio Code:
  1. Follow the guide from the VS Code documentation regarding adding an MCP server.
  2. My global mcp.json looks like this:
 
  "servers":  
      "debsecan-mcp":  
          "command": "uv",
              "args": [
                  "--directory",
                  "/home/vasudev/Documents/personal/FOSS/debsecan-mcp/debsecan-mcp",
                  "run",
                  "debsecan-mcp"
              ]
           
   ,
  "inputs": []
 
  1. I am running it directly from my local codebase using a virtualenv created with uv. You may need to tweak the path based on your installation.
  2. To use the MCP server in the Copilot chat window, reference it using #debsecan-mcp. The LLM will then use the server for the query.
  3. Use a prompt like: "Give an executive summary of the system security status and immediate actions to be taken."
  4. You can observe the LLM using list_vulnerabilities followed by research_cves. Because the first tool only provides CVE IDs based on severity, the LLM is smart enough to research only high and critical vulnerabilities, thereby saving tokens.
What's Next? This MCP is not yet perfect and has the following issues:
  1. The list_vulnerabilities dictionary contains duplicate CVE IDs because the code used a list instead of a set. While the LLM is smart enough to deduplicate these, it still costs extra tokens.
  2. Because I initially modeled this on debsecan, it uses a raw method for parsing /var/lib/dpkg/status instead of python-apt. I am considering switching to python-apt to reduce maintenance overhead.
  3. Interestingly, the AI did not add a single unit test, which is disappointing. I will add these once my limits are restored.
  4. I need to create a cleaner README with usage instructions.
  5. I need to determine if the MCP can be used via HTTP as well as stdio.
Conclusion Vibe coding is interesting, but things can get out of hand if not managed properly. Even with a good process, code must be reviewed and tested; you cannot blindly trust an AI to handle everything. Even if it adds tests, you must validate them, or you are doomed!

Next.

Previous.