Search Results: "reg"

17 July 2025

Birger Schacht: My first tag2upload upload

Following the DebConf25 talk by Ian Jackson tag2upload - upload simply by pushing a signed git tag I decided to use the quiet time during the day of the DayTrip on DebConf 25 to try out uploading a package using tag2upload. Given the current freeze a couple of the packages I maintainer have new releases waiting. I decided on uploading the new version of labwc to experimental. Labwc is a Wayland compositor based on the wlroots compositor library (the library that sway is using). Labwc is inspired by the Openbox window manager. The upstream team of Labwc released version 0.9.0 last week, the first version that is based on wlroots 0.19.x. Wlroots 0.19.x is also only available in experimental, so that was a good fit for trying an upload with tag2upload. I first used my usual workflow, going into my package repository, doing get fetch origin, checking out the tag of the new release and tagging that with git tag upstream/0.9.0. Then I bumped the version in the debian/experimental branch, adapted the debian/control file for the changed wlroots dependency, committed and built the package using git-buildpackage to check if it builds fine and there are no lintian errors. Then I moved on to look at tag2upload. As a starting point for using tag2upload I read the blogpost by Jonathan Carter My first tag2upload upload. It pointed me to one very important option of git debpush, namely the --baredebian option which I have to use because I use the bare Debian git layout. Given that the last upload of labwc I did was to unstable, I also had to add the --force=changed-suite. I also started right away to use the --tag-only option, because for my first tests I only wanted to have local changes and nothing pushed to anywhere. I also used the --dry-run option. This led to the following command:
> git debpush --baredebian --force=changed-suite --dry-run --tag-only
tags 0.9.0, upstream/0.9.0 all exist in this repository
tell me which one you want to make an orig.tar from: git deborig --just-print '--version=0.9.0-1' TAG
git-debpush: git-deborig failed; maybe try git-debpush --upstream=TAG
This was a bit confusing, because the error message talked about git-deborig, but I was using git-debpush. I also did not want to make an orig.tar! The --upstream option in the git-debpush(1) manual gave an explanation for this:
When pushing a non-native package, git-debpush needs a tag for the upstream part of your package. By default git-debpush asks git-deborig(1), which searches for a suitable tag based on the upstream version in debian/changelog.
So apparently git-debpush can not find out what the correct tag for the upstream version is, because git-deborig can not find out what the correct tag for the upstream version is. git-debpush simply calls git deborig --just-print --version="$version" in line 437. This fails because I initially created a second upstream/0.9.0 to the existing 0.9.0 release tag. I do this for git-buildpackage to find the upstream sources, but with multiple tags git-deborig is not sure which one is the tag it should use (although both point to the same commit). So I removed the upstream/0.9.0 tag and ran git debpush again and now there was no error message (besides the warning regarding the changed suite) but it also did not give an feedback about what is happening. So I tried without the --dry-run option. Again, no output whatsoever, other than the warning about the changed release, BUT my gnupg asked me for permission to sign via my yubikey! And when I looked at the list of tags, I saw that there is now a debian/0.9.0-1 tag that was not there before! Looking at the tag I saw that it was a tag in the format described in the tag2upload(5) manual page, containing the following lines:
labwc release 0.9.0-1 for experimental
[dgit distro=debian split --quilt=baredebian]
[dgit please-upload source=labwc version=0.9.0-1 upstream-tag=0.9.0 upstream=4beee3851f75b53afc2e8699c594c0cc222115bd]
and the tag was signed by me. The 4beee3851f75b53afc2e8699c594c0cc222115bd commit ID is the commit the 0.9.0 tag points to. Now that I had a signed commit tag in the correct format, I went to the labwc packaging repository on salsa and enabled the webhook to trigger the tag2upload service (I just saw that the documentation was updated and there is now a global webhook on salsa, so this step is not needed anymore). Finally I pushed the tags using git push --tags. I could also have used git-debpush for this step, but I d rather use git directly. I then looked at the tag2upload queue and saw how a worker built and uploaded the newest labwc release and I also got an email from the tag2upload service [tag2upload 275] uploaded labwc 0.9.0-1. And a couple of minutes later I got the confirmation that labwc 0.9.0-1 was accepted into experimental. Great! So, to conclude: for tag2upload to work we simply need a git tag in the correct format. The tag2upload service now gets triggered by every pushed tag on salsa but only acts on tags that adhere to the tag2upload(5) format. git-debpush is a simply bash script that creates such a tag and by default also pushes the tag. I think the script could be a bit more verbose, for example telling me that it created a tag and the name of that tag. I think the dependency on git-deborig is also a problem. I use git-buildpackage to build my packages and by default git-buildpacakge assumes upstream tags are of the form upstream/%(version)s (source). I could now change that for all the packages I maintain, but I also think it makes sense to control the tag myself and not use a tag that is controlled by upstream. Upstream could change or delete that tag or I might need to create a tag for a version that is not tagged by upstream. I also think git-debpush is a rather mileading command name, given that the main task of the script is to create a tag in the correct format. Other than that, I m pretty happy about this service. I have a rather crappy uplink at home and it is not so uncommon for my uploads to fail because the connection dropped during dput. Using a simple git based upload approach makes these problems a thing of the past. I might look into other ways to create the needed tag, though.

Arnaud Rebillout: Acquire-By-Hash for APT packages repositories, and the lack of it in Kali Linux

This is a lenghty blog post. It features a long introduction that explains how apt update acquires various files from a package repository, what is Acquire-By-Hash, and how it all works for Kali Linux: a Debian-based distro that doesn't support Acquire-By-Hash, and which is distributed via a network of mirrors and a redirector. In a second part, I explore some "Hash Sum Mismatch" errors that we can hit with Kali Linux, errors that would not happen if only Acquire-By-Hash was supported. If anything, this blog post supports the case for adding Acquire-By-Hash support in reprepro, as requested at https://bugs.debian.org/820660. All of this could have just remained some personal notes for myself, but I got carried away and turned it into a blog post, dunno why... Hopefully others will find it interesting, but you really need to like troubleshooting stories, packed with details, and poorly written at that. You've been warned! Introducing Acquire-By-Hash Acquire-By-Hash is a feature of APT package repositories, that might or might not be supported by your favorite Debian-based distribution. A repository that supports it says so, in the Release file, by setting the field Acquire-By-Hash: yes. It's easy to check. Debian and Ubuntu both support it:
$ wget -qO- http://deb.debian.org/debian/dists/sid/Release   grep -i ^Acquire-By-Hash:
Acquire-By-Hash: yes
$ wget -qO- http://archive.ubuntu.com/ubuntu/dists/devel/Release   grep -i ^Acquire-By-Hash:
Acquire-By-Hash: yes
What about other Debian derivatives?
$ wget -qO- http://http.kali.org/kali/dists/kali-rolling/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
$ wget -qO- https://archive.raspberrypi.com/debian/dists/trixie/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
$ wget -qO- http://packages.linuxmint.com/dists/faye/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
$ wget -qO- https://apt.pop-os.org/release/dists/noble/Release   grep -i ^Acquire-By-Hash:   echo not supported
not supported
Huhu, Acquire-By-Hash is not ubiquitous. But wait, what is Acquire-By-Hash to start with? To answer that, we have to take a step back and cover some basics first. The HTTP requests performed by 'apt update' What happens when one runs apt update? APT first requests the Release file from the repository(ies) configured in the APT sources. This file is a starting point, it contains a list of other files (sometimes called "Index files") that are available in the repository, along with their hashes. After fetching the Release file, APT proceeds to request those Index files. To give you an idea, there are many kinds of Index files, among which: There's an excellent Wiki page that details the structure of a Debian package repository, it's there: https://wiki.debian.org/DebianRepository/Format. Note that APT doesn't necessarily download ALL of those Index files. For simplicity, we'll limit ourselves to the minimal scenario, where apt update downloads only the Packages files. Let's try to make it more visual: here's a representation of a apt update transaction, assuming that all the components of the repository are enabled:
apt update -> Release -> Packages (main/amd64)
                      -> Packages (contrib/amd64)
                      -> Packages (non-free/amd64)
                      -> Packages (non-free-firmware/amd64)
Meaning that, in a first step, APT downloads the Release file, reads its content, and then in a second step it downloads the Index files in parallel. You can actually see that happen with a command such as apt -q -o Debug::Acquire::http=true update 2>&1 grep ^GET. For Kali Linux you'll see something pretty similar to what I described above. Try it!
$ podman run --rm kali-rolling apt -q -o Debug::Acquire::http=true update 2>&1   grep ^GET
GET /kali/dists/kali-rolling/InRelease HTTP/1.1    # <- returns a redirect, that is why the file is requested twice
GET /kali/dists/kali-rolling/InRelease HTTP/1.1
GET /kali/dists/kali-rolling/non-free/binary-amd64/Packages.gz HTTP/1.1
GET /kali/dists/kali-rolling/main/binary-amd64/Packages.gz HTTP/1.1
GET /kali/dists/kali-rolling/non-free-firmware/binary-amd64/Packages.gz HTTP/1.1
GET /kali/dists/kali-rolling/contrib/binary-amd64/Packages.gz HTTP/1.1
However, and it's now becoming interesting, for Debian or Ubuntu you won't see the same kind of URLs:
$ podman run --rm debian:sid apt -q -o Debug::Acquire::http=true update 2>&1   grep ^GET
GET /debian/dists/sid/InRelease HTTP/1.1
GET /debian/dists/sid/main/binary-amd64/by-hash/SHA256/22709f0ce67e5e0a33a6e6e64d96a83805903a3376e042c83d64886bb555a9c3 HTTP/1.1
APT doesn't download a file named Packages, instead it fetches a file named after a hash. Why? This is due to the field Acquire-By-Hash: yes that is present in the Debian's Release file. What does Acquire-By-Hash mean for 'apt update' The idea with Acquire-By-Hash is that the Index files are named after their hash on the repository, so if the MD5 sum of main/binary-amd64/Packages is 77b2c1539f816832e2d762adb20a2bb1, then the file will be stored at main/binary-amd64/by-hash/MD5Sum/77b2c1539f816832e2d762adb20a2bb1. The path main/binary-amd64/Packages still exists (it's the "Canonical Location" of this particular Index file), but APT won't use it, instead it downloads the file located in the by-hash/ directory. Why does it matter? This has to do with repository updates, and allowing the package repository to be updated atomically, without interruption of service, and without risk of failure client-side. It's important to understand that the Release file and the Index files are part of a whole, a set of files that go altogether, given that Index files are validated by their hash (as listed in the Release file) after download by APT. If those files are simply named "Release" and "Packages", it means they are not immutable: when the repository is updated, all of those files are updated "in place". And it causes problems. A typical failure mode for the client, during a repository update, is that: 1) APT requests the Release file, then 2) the repository is updated and finally 3) APT requests the Packages files, but their checksum don't match, causing apt update to fail. There are variations of this error, but you get the idea: updating a set of files "in place" is problematic. The Acquire-By-Hash mechanism was introduced exactly to solve this problem: now the Index files have a unique, immutable name. When the repository is updated, at first new Index files are added in the by-hash/ directory, and only after the Release file is updated. Old Index files in by-hash/ are retained for a while, so there's a grace period during which both the old and the new Release files are valid and working: the Index files that they refer to are available in the repo. As a result: no interruption of service, no failure client-side during repository updates. This is explained in more details at https://www.chiark.greenend.org.uk/~cjwatson/blog/no-more-hash-sum-mismatch-errors.html, which is the blog post from Colin Watson that came out at the time Acquire-By-Hash was introduced in... 2016. This is still an excellent read in 2025. So you might be wondering why I'm rambling about a problem that's been solved 10 years ago, but then as I've shown in the introduction, the problem is not solved for everyone. Support for Acquire-By-Hash server side is not for granted, and unfortunately it never landed in reprepro, as one can see at https://bugs.debian.org/820660. reprepro is a popular tool for creating APT package repositories. In particular, at Kali Linux we use reprepro, and that's why there's no Acquire-By-Hash: yes in the Kali Release file. As one can guess, it leads to subtle issues during those moments when the repository is updated. However... we're not ready to talk about that yet! There's still another topic that we need to cover: this window of time during which a repository is being updated, and during which apt update might fail. The window for Hash Sum Mismatches, and the APT trick that saves the day Pay attention! In this section, we're now talking about packages repositories that do NOT support Acquire-By-Hash, such as the Kali Linux repository. As I've said above, it's only when the repository is being updated that there is a "Hash Sum Mismatch Window", ie. a moment when apt update might fail for some unlucky clients, due to invalid Index files. Surely, it's a very very short window of time, right? I mean, it can't take that long to update files on a server, especially when you know that a repository is usually updated via rsync, and rsync goes to great length to update files the most atomically as it can (with the option --delay=updates). So if apt update fails for me, I've been very unlucky, but I can just retry in a few seconds and it should be fixed, isn't it? The answer is: it's not that simple. So far I pictured the "package repository" as a single server, for simplicity. But it's not always what it is. For Kali Linux, by default users have http.kali.org configured in their APT sources, and it is a redirector, ie. a web server that redirects requests to mirrors that are nearby the client. Some context that matters for what comes next: the Kali repository is synced with ~70 mirrors all around the world, 4 times a day. What happens if your apt update requests are redirected to 2 mirrors close-by, and one was just synced, while the other is still syncing (or even worse, failed to sync entirely)? You'll get a mix of old and new Index files. Hash Sum Mismatch! As you can see, with this setup the "Hash Sum Mismatch Window" becomes much longer than a few seconds: as long as nearby mirrors are syncing the window is opened. You could have a fast and a slow mirror next to you, and they can be out of sync with each other for several minutes every time the repository is updated, for example. For Kali Linux in particular, there's a "detail" in our network of mirrors that, as a side-effect, almost guarantees that this window lasts several minutes at least. This is because the pool of mirrors includes kali.download which is in fact the Cloudflare CDN, and from the redirector point of view, it's seen as a "super mirror" that is present in every country. So when APT fires a bunch of requests against http.kali.org, it's likely that some of them will be redirected to the Kali CDN, and others will be redirected to a mirror nearby you. So far so good, but there's another point of detail to be aware of: the Kali CDN is synced first, before the other mirrors. Another thing: usually the mirrors that are the farthest from the Tier-0 mirror are the longest to sync. Packing all of that together: if you live somewhere in Asia, it's not uncommon for your "Hash Sum Mismatch Window" to be as long as 30 minutes, between the moment the Kali CDN is synced, and the moment your nearby mirrors catch up and are finally in sync as well. Having said all of that, and assuming you're still reading (anyone here?), you might be wondering... Does that mean that apt update is broken 4 times a day, for around 30 minutes, for every Kali user out there? How can they bear with that? Answer is: no, of course not, it's not broken like that. It works despite all of that, and this is thanks to yet another detail that we didn't go into yet. This detail lies in APT itself. APT is in fact "redirector aware", in a sense. When it fetches a Release file, and if ever the request is redirected, it then fires the subsequent requests against the server where it was initially redirected. So you are guaranteed that the Release file and the Index files are retrieved from the same mirror! Which brings back our "Hash Sum Mismatch Window" to the window for a single server, ie. something like a few seconds at worst, hopefully. And that's what makes it work for Kali, literally. Without this trick, everything would fall apart. For reference, this feature was implemented in APT back in... 2016! A busy year it seems! Here's the link to the commit: use the same redirection mirror for all index files. To finish, a dump from the console. You can see this behaviour play out easily, again with APT debugging turned on. Below we can see that only the first request hits the Kali redirector:
$ podman run --rm kali-rolling apt -q -o Debug::Acquire::http=true update 2>&1   grep -e ^Answer -e ^HTTP
Answer for: http://http.kali.org/kali/dists/kali-rolling/InRelease
HTTP/1.1 302 Found
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/InRelease
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/non-free-firmware/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/contrib/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/main/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-rolling/non-free/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Interlude Believe it or not, we're done with the introduction! At this point, we have a good understanding of what apt update does (in terms of HTTP requests), we know that Release files and Index files are part of a whole, and we know that a repository can be updated atomically thanks to the Acquire-By-Hash feature, so that users don't experience interruption of service or failures of any sort, even with a rolling repository that is updated several times a day, like Debian sid. We've also learnt that, despite the fact that Acquire-By-Hash landed almost 10 years ago, some distributions like Kali Linux are still doing without it... and yet it works! But the reason why it works is more complicated to grasp, especially when you add a network of mirrors and a redirector to the picture. Moreover, it doesn't work as flawlessly as with the Acquire-By-Hash feature: we still expect some short (seconds at worst) "Hash Sum Mismatch Windows" for those unlucky users that run apt update at the wrong moment. This was a long intro, but that really sets the stage for what comes next: the edge cases. Some situations in which we can hit some Hash Sum Mismatch errors with Kali. Error cases that I've collected and investigated over the time... If anything, it supports the case that Acquire-By-Hash is really something that should be implemented in reprepro. More on that in the conclusion, but for now, let's look at those edge cases. Edge Case 1: the caching proxy If you put a caching proxy (such as approx, my APT caching proxy of choice) between yourself and the actual packages repository, then obviously it's the caching proxy that performs the HTTP requests, and therefore APT will never know about the redirections returned by the server, if any. So the APT trick of downloading all the Index files from the same server in case of redirect doesn't work anymore. It was rather easy to confirm that by building a Kali package during a mirror sync, and watch if fail at the "Update chroot" step:
$ sudo rm /var/cache/approx/kali/dists/ -fr
$ gbp buildpackage --git-builder=sbuild
+------------------------------------------------------------------------------+
  Update chroot                                Wed, 11 Jun 2025 10:33:32 +0000  
+------------------------------------------------------------------------------+
Get:1 http://http.kali.org/kali kali-dev InRelease [41.4 kB]
Get:2 http://http.kali.org/kali kali-dev/contrib Sources [81.6 kB]
Get:3 http://http.kali.org/kali kali-dev/main Sources [17.3 MB]
Get:4 http://http.kali.org/kali kali-dev/non-free Sources [122 kB]
Get:5 http://http.kali.org/kali kali-dev/non-free-firmware Sources [8297 B]
Get:6 http://http.kali.org/kali kali-dev/non-free amd64 Packages [197 kB]
Get:7 http://http.kali.org/kali kali-dev/non-free-firmware amd64 Packages [10.6 kB]
Get:8 http://http.kali.org/kali kali-dev/contrib amd64 Packages [120 kB]
Get:9 http://http.kali.org/kali kali-dev/main amd64 Packages [21.0 MB]
Err:9 http://http.kali.org/kali kali-dev/main amd64 Packages
  File has unexpected size (20984689 != 20984861). Mirror sync in progress? [IP: ::1 9999]
  Hashes of expected file:
   - Filesize:20984861 [weak]
   - SHA256:6cbbee5838849ffb24a800bdcd1477e2f4adf5838a844f3838b8b66b7493879e
   - SHA1:a5c7e557a506013bd0cf938ab575fc084ed57dba [weak]
   - MD5Sum:1433ce57419414ffb348fca14ca1b00f [weak]
  Release file created at: Wed, 11 Jun 2025 07:15:10 +0000
Fetched 17.9 MB in 9s (1893 kB/s)
Reading package lists...
E: Failed to fetch http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz  File has unexpected size (20984689 != 20984861). Mirror sync in progress? [IP: ::1 9999]
   Hashes of expected file:
    - Filesize:20984861 [weak]
    - SHA256:6cbbee5838849ffb24a800bdcd1477e2f4adf5838a844f3838b8b66b7493879e
    - SHA1:a5c7e557a506013bd0cf938ab575fc084ed57dba [weak]
    - MD5Sum:1433ce57419414ffb348fca14ca1b00f [weak]
   Release file created at: Wed, 11 Jun 2025 07:15:10 +0000
E: Some index files failed to download. They have been ignored, or old ones used instead.
E: apt-get update failed
The obvious workaround is to NOT use the redirector in the approx configuration. Either use a mirror close by, or the Kali CDN:
$ grep kali /etc/approx/approx.conf 
#kali http://http.kali.org/kali <- do not use the redirector!
kali  http://kali.download/kali
Edge Case 2: debootstrap struggles What if one tries to debootstrap Kali while mirrors are being synced? It can give you some ugly logs, but it might not be fatal:
$ sudo debootstrap kali-dev kali-dev http://http.kali.org/kali
[...]
I: Target architecture can be executed
I: Retrieving InRelease 
I: Checking Release signature
I: Valid Release signature (key id 827C8569F2518CC677FECA1AED65462EC8D5E4C5)
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
W: Retrying failed download of http://http.kali.org/kali/dists/kali-dev/main/binary-amd64/Packages.gz
I: Retrieving Packages 
I: Validating Packages 
I: Resolving dependencies of required packages...
I: Resolving dependencies of base packages...
I: Checking component main on http://http.kali.org/kali...
I: Retrieving adduser 3.152
[...]
To understand this one, we have to go and look at the debootstrap source code. How does debootstrap fetch the Release file and the Index files? It uses wget, and it retries up to 10 times in case of failure. It's not as sophisticated as APT: it doesn't detect when the Release file is served via a redirect. As a consequence, what happens above can be explained as such:
  1. debootstrap requests the Release file, gets redirected to a mirror, and retrieves it from there
  2. then it requests the Packages file, gets redirected to another mirror that is not in sync with the first one, and retrieves it from there
  3. validation fails, since the checksum is not as expected
  4. try again and again
Since debootstrap retries up to 10 times, at some point it's lucky enough to get redirected to the same mirror as the one from where it got its Release file from, and this time it gets the right Packages file, with the expected checksum. So ultimately it succeeds. Edge Case 3: post-debootstrap failure I like this one, because it gets us to yet another detail that we didn't talk about yet. So, what happens after we successfully debootstraped Kali? We have only the main component enabled, and only the Index file for this component have been retrieved. It looks like that:
$ sudo debootstrap kali-dev kali-dev http://http.kali.org/kali
[...]
I: Base system installed successfully.
$ cat kali-dev/etc/apt/sources.list
deb http://http.kali.org/kali kali-dev main
$ ls -l kali-dev/var/lib/apt/lists/
total 80468
-rw-r--r-- 1 root root    41445 Jun 19 07:02 http.kali.org_kali_dists_kali-dev_InRelease
-rw-r--r-- 1 root root 82299122 Jun 19 07:01 http.kali.org_kali_dists_kali-dev_main_binary-amd64_Packages
-rw-r--r-- 1 root root    40562 Jun 19 11:54 http.kali.org_kali_dists_kali-dev_Release
-rw-r--r-- 1 root root      833 Jun 19 11:54 http.kali.org_kali_dists_kali-dev_Release.gpg
drwxr-xr-x 2 root root     4096 Jun 19 11:54 partial
So far so good. Next step would be to complete the sources.list with other components, then run apt update: APT will download the missing Index files. But if you're unlucky, that might fail:
$ sudo sed -i 's/main$/main contrib non-free non-free-firmware/' kali-dev/etc/apt/sources.list
$ cat kali-dev/etc/apt/sources.list
deb http://http.kali.org/kali kali-dev main contrib non-free non-free-firmware
$ sudo chroot kali-dev apt update
Hit:1 http://http.kali.org/kali kali-dev InRelease
Get:2 http://kali.download/kali kali-dev/contrib amd64 Packages [121 kB]
Get:4 http://mirror.sg.gs/kali kali-dev/non-free-firmware amd64 Packages [10.6 kB]
Get:3 http://mirror.freedif.org/kali kali-dev/non-free amd64 Packages [198 kB]
Err:3 http://mirror.freedif.org/kali kali-dev/non-free amd64 Packages
  File has unexpected size (10442 != 10584). Mirror sync in progress? [IP: 66.96.199.63 80]
  Hashes of expected file:
   - Filesize:10584 [weak]
   - SHA256:71a83d895f3488d8ebf63ccd3216923a7196f06f088461f8770cee3645376abb
   - SHA1:c4ff126b151f5150d6a8464bc6ed3c768627a197 [weak]
   - MD5Sum:a49f46a85febb275346c51ba0aa8c110 [weak]
  Release file created at: Fri, 23 May 2025 06:48:41 +0000
Fetched 336 kB in 4s (77.5 kB/s)  
Reading package lists... Done
E: Failed to fetch http://mirror.freedif.org/kali/dists/kali-dev/non-free/binary-amd64/Packages.gz  File has unexpected size (10442 != 10584). Mirror sync in progress? [IP: 66.96.199.63 80]
   Hashes of expected file:
    - Filesize:10584 [weak]
    - SHA256:71a83d895f3488d8ebf63ccd3216923a7196f06f088461f8770cee3645376abb
    - SHA1:c4ff126b151f5150d6a8464bc6ed3c768627a197 [weak]
    - MD5Sum:a49f46a85febb275346c51ba0aa8c110 [weak]
   Release file created at: Fri, 23 May 2025 06:48:41 +0000
E: Some index files failed to download. They have been ignored, or old ones used instead.
What happened here? Again, we need APT debugging options to have a hint:
$ sudo chroot kali-dev apt -q -o Debug::Acquire::http=true update 2>&1   grep -e ^Answer -e ^HTTP
Answer for: http://http.kali.org/kali/dists/kali-dev/InRelease
HTTP/1.1 304 Not Modified
Answer for: http://http.kali.org/kali/dists/kali-dev/contrib/binary-amd64/Packages.gz
HTTP/1.1 302 Found
Answer for: http://http.kali.org/kali/dists/kali-dev/non-free/binary-amd64/Packages.gz
HTTP/1.1 302 Found
Answer for: http://http.kali.org/kali/dists/kali-dev/non-free-firmware/binary-amd64/Packages.gz
HTTP/1.1 302 Found
Answer for: http://kali.download/kali/dists/kali-dev/contrib/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.sg.gs/kali/dists/kali-dev/non-free-firmware/binary-amd64/Packages.gz
HTTP/1.1 200 OK
Answer for: http://mirror.freedif.org/kali/dists/kali-dev/non-free/binary-amd64/Packages.gz
HTTP/1.1 200 OK
As we can see above, for the Release file we get a 304 (aka. "Not Modified") from the redirector. Why is that? This is due to If-Modified-Since also known as RFC-7232. APT supports this feature when it retrieves the Release file, it basically says to the server "Give me the Release file, but only if it's newer than what I already have". If the file on the server is not newer than that, it answers with a 304, which basically says to the client "You have the latest version already". So APT doesn't get a new Release file, it uses the Release file that is already present locally in /var/lib/apt/lists/, and then it proceeeds to download the missing Index files. And as we can see above: it then hits the redirector for each requests, and might be redirected to different mirrors for each Index file. So the important bit here is: the APT "trick" of downloading all the Index files from the same mirror only works if the Release file is served via a redirect. If it's not, like in this case, then APT hits the redirector for each files it needs to download, and it's subject to the "Hash Sum Mismatch" error again. In practice, for the casual user running apt update every now and then, it's not an issue. If they have the latest Release file, no extra requests are done, because they also have the latest Index files, from a previous apt update transaction. So APT doesn't re-download those Index files. The only reason why they'd have the latest Release file, and would miss some Index files, would be that they added new components to their APT sources, like we just did above. Not so common, and then they'd need to run apt update at a unlucky moment. I don't think many users are affected in practice. Note that this issue is rather new for Kali Linux. The redirector running on http.kali.org is mirrorbits, and support for If-Modified-Since just landed in the latest release, version 0.6. This feature was added by no one else than me, a great example of the expression "shooting oneself in the foot". An obvious workaround here is to empty /var/lib/apt/lists/ in the chroot after debootstrap completed. Or we could disable support for If-Modified-Since entirely for Kali's instance of mirrorbits. Summary and Conclusion The Hash Sum Mismatch failures above are caused by a combination of things: At the same time: All in all, it seems that all those issues would go away if only Acquire-By-Hash was supported in the Kali packages repository. Now is not a bad moment to try to land this feature in reprepro. After development halted in 2019, there's now a new upstream, and patches are being merged again. But it won't be easy: reprepro is a C codebase of around 50k lines of code, and it will take time and effort for the newcomer to get acquainted with the codebase, to the point of being able to implement a significant feature like this one. As an alternative, aptly is another popular tool to manage APT package repositories. And it seems to support Acquire-By-Hash already. Another alternative: I was told that debusine has (experimental) support for package repositories, and that Acquire-By-Hash is supported as well. Options are on the table, and I hope that Kali will eventually get support for Acquire-By-Hash, one way or another. To finish, due credits: this blog post exists thanks to my employer OffSec. Thanks for reading!
16 July 2025

Sven Hoexter: Google Cloud Oddities Summer 2025 Edition

Latest oddities I ran into with Google Cloud products before I start to forget about them again. e2 Compute Instances vs CloudNAT Years ago I already had a surprising encounter with the Google Cloud e2 instances. Back then we observed CPU steal time from 20-60%, which made the instances unusable for anything remotely latency sensitive. Now someone started to run a workload which creates many outbound connections to the same destination IP:Port. To connect to the internet we utilize the Google Cloud product "CloudNAT" which implements a NAT solution somewhere in the network layer. Starting the workload let after a few seconds to all sort of connection issues, and of course logs from CloudNAT that it dropped connections. The simplest reproducer I could find was while true; do curl http://sven.stormbind.net; done which already let to connection drops on CloudNAT. We starred a bit at output of gcloud compute routers get-nat-mapping-info our-default-natgw, but allocating additional ports still worked fine in general. Further investigation let to two differences between a project which was fine and those that failed:
  1. c2d or n2d machine types instead of e2 and
  2. usage of gVNIC.
Moving away from the e2 instances instantly fixed our issue. Only some connection drops could be observed on CloudNAT if we set the min_ports_per_vm value too low and it could not allocate new ports in time. Thus we did some additional optimizations: See also upstream documentation regarding timeouts. To complete the setup alignment we also enabled gVNIC on all GKE pools. Noteworthy detail a colleague figured out: If you use terraform to provision GKE pools make sure to use at least google provider v6.33.0 to avoid a re-creation of your node pool. GKE LoadBalancer Force allPorts: true on Forwarding Rule Technically it's possible to configure a forwarding rule to listen on some or all ports. That gets more complicated if you do not configure the forwarding rule via terraform or gcloud cli, but use a GKE resource kind: Service with spec.type: LoadBalancer. The logic documented by Google Cloud is that the forwarding rule will have per port configuration if it's five or less, and above that it will open for all ports. Sadly that does not work e.g. in cases where you've an internal load balancer and a serviceAttachment attached to the forwarding rule. In my experience reconfiguring was also unreliable in cases without a serviceAttachment and required a manual deletion of the service load balancer to have the operator reconcile it and create it correctly. Given that we wanted to have all ports open to allow us to dynamically add more ports on a specific load balancer, but there is no annotation for that, I worked around with this beauty:
      ports:
        - name: dummy-0
          port: 2342
          protocol: TCP
          targetPort: 2342
        - name: dummy-1
          port: 2343
          protocol: TCP
          targetPort: 2343
        - name: dummy-2
          port: 2344
          protocol: TCP
          targetPort: 2344
        - name: dummy-3
          port: 2345
          protocol: TCP
          targetPort: 2345
        - name: service-1
          port: 4242
          protocol: TCP
          targetPort: 4242
        - name: service-2
          port: 4343
          protocol: TCP
          targetPort: 4343
If something in that area did not work out there's basically two things to check:
  1. Is the port open on the forwarding rule / is the forwarding rule configured with allPorts: true?
  2. Got the VPC firewall rule created by the service operator in GKE updated to open all required ports?
Rate Limiting with Cloud Armor on Global TCP Proxy Load Balancer According to the Google Cloud support rate limiting on a TCP proxy is a preview feature. That seems to be the excuse why it's all very inconsistent right now, but it works. Terraform Sample Snippet
  rule  
    description = "L3-L4 Rate Limit"
    action      = "rate_based_ban"
    priority    = "2342"
    match  
      versioned_expr = "SRC_IPS_V1"
      config  
        src_ip_ranges = ["*"]
       
     
    rate_limit_options  
      enforce_on_key = "IP"
      # exceed_action only supports deny() with a response code
      exceed_action = "deny(429)"
      rate_limit_threshold  
        count        = 320
        interval_sec = 60
       
      ban_duration_sec = 240
      ban_threshold  
        count        = 320
        interval_sec = 60
       
      conform_action = "allow"
     
   
Config-Connector Sample Snippet
  - action: rate_based_ban
    description: L3-L4 Rate Limit
    match:
      config:
        srcIpRanges:
          - "*"
      versionedExpr: SRC_IPS_V1
    preview: false
    priority: 2342
    rateLimitOptions:
      banDurationSec: 240
      banThreshold:
        count: 320
        intervalSec: 60
      conformAction: allow
      enforceOnKey: IP
      exceedAction: deny
      rateLimitThreshold:
         count: 320
         intervalSec: 60

15 July 2025

Alberto Garc a: Converting QEMU qcow2 images directly to stdout

Introduction Some months ago, my colleague Madeeha Javed and I wrote a tool to convert QEMU disk images into qcow2, writing the result directly to stdout. This tool is called qcow2-to-stdout.py and can be used for example to create a new image and pipe it through gzip and/or send it directly over the network without having to write it to disk first. This program is included in the QEMU repository: https://github.com/qemu/qemu/blob/master/scripts/qcow2-to-stdout.py If you simply want to use it then all you need to do is have a look at these examples: $ qcow2-to-stdout.py source.raw > dest.qcow2
$ qcow2-to-stdout.py -f dmg source.dmg gzip > dest.qcow2.gz If you re interested in the technical details, read on.

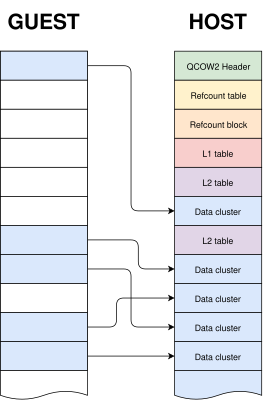
A closer look under the hood QEMU uses disk images to store the contents of the VM s hard drive. Images are often in qcow2, QEMU s native format, although a variety of other formats and protocols are also supported. I have written in detail about the qcow2 format in the past (for example, here and here), but the general idea is very easy to understand: the virtual drive is divided into clusters of a certain size (64 KB by default), and only the clusters containing non-zero data need to be physically present in the qcow2 image. So what we have is essentially a collection of data clusters and a set of tables that map guest clusters (what the VM sees) to host clusters (what the qcow2 file actually stores).
A qcow2 file is a collection of data clusters plus some metadata to map them to what the guest VM sees.
qemu-img is a powerful and versatile tool that can be used to create, modify and convert disk images. It has many different options, but one question that sometimes arises is whether it can use stdin or stdout instead of regular files when converting images. The short answer is that this is not possible in general. qemu-img convert works by checking the (virtual) size of the source image, creating a destination image of that same size and finally copying all the data from start to finish. Reading a qcow2 image from stdin doesn t work because data and metadata blocks can come in any arbitrary order, so it s perfectly possible that the information that we need in order to start writing the destination image is at the end of the input data . Writing a qcow2 image to stdout doesn t work either because we need to know in advance the complete list of clusters from the source image that contain non-zero data (this is essential because it affects the destination file s metadata). However, if we do have that information then writing a new image directly to stdout is technically possible. The bad news is that qemu-img won t help us here: it uses the same I/O code as the rest of QEMU. This generic approach makes total sense because it s simple, versatile and is valid for any kind of source and destination image that QEMU supports. However, it needs random access to both images. If we want to write a qcow2 file directly to stdout we need new code written specifically for this purpose, and since it cannot reuse the logic present in the QEMU code this was written as a separate tool (a Python script). The process itself goes like this:
  • Read the source image from start to finish in order to determine which clusters contain non-zero data. These are the only clusters that need to be present in the new image.
  • Write to stdout all the metadata structures of the new image. This is now possible because after the previous step we know how much data we have and where it is located.
  • Read the source image again and copy the clusters with non-zero data to stdout.
Images created with this program always have the same layout: header, refcount tables and blocks, L1 and L2 tables, and finally all data clusters. One problem here is that, while QEMU can read many different image formats, qcow2-to-stdout.py is an independent tool that does not share any of the code and therefore can only read raw files. The solution here is to use qemu-storage-daemon. This program is part of QEMU and it can use FUSE to export any file that QEMU can read as a raw file. The usage of qemu-storage-daemon is handled automatically and the user only needs to specify the format of the source file: $ qcow2-to-stdout.py -f dmg source.dmg > dest.qcow2 qcow2-to-stdout.py can only create basic qcow2 files and does not support features like compression or encryption. However, a few parameters can be adjusted, like the cluster size (-c), the width of the reference count entries (-r) and whether the new image is created with the input as an external data file (-d and -R). And this is all, I hope that you find this tool useful and this post informative. Enjoy!

Acknowledgments This work has been developed by Igalia and sponsored by Outscale, a Dassault Syst mes brand.
Logos of Igalia and Outscale

This problem would not happen if the input data was in raw format but in this case we would not know the size in advance.

14 July 2025

David Bremner: Hibernate on the pocket reform 6/n

Context

Another kernel patch?
  • Confused about prerequisites, I wrote
  • A reply from Niklas Cassel suggested I look at https://lore.kernel.org/linux-pci/1744940759-23823-1-git-send-email-shawn.lin@rock-chips.com/
  • EDIT It turns out that this patch is already shipped as part of the mnt research kernel. It will need rebasing for 6.16.x.

Applying the prerequisites
  • Niklas also point me to https://lore.kernel.org/linux-pci/20250508-pcie-reset-slot-v4-0-7050093e2b50@linaro.org/
  • Since the new patch doesn't apply to linux master either, I guess I need to apply that series. But part of it is already applied, fun.
  • I'm not claiming this is the best way...
# index 31090770fffcc94e15 from the first patch in the series
$ git log --raw --all --find-object=31090770fffcc94e15
# The applied version of the first patch is  b06d125e6280603a34d9064cd9c12748ca2edb04 
$ git switch -c base b06d125e6280603a34d9064cd9c12748ca2edb04^
$ mbox-extract-patch < ~/Downloads/PATCH-v4-1-5-PCI-ERR-Remove-misleading-TODO-regarding-kernel-panic.mbox   git am
$ git rebase -i master  # two applied patches skipped
$ git switch master && git merge base
  • mbox-extract-patch is from package mailscripts.
  • git am -3 ~/tmp/PATCH-v3-PCI-dw-rockchip-Add-support-for-slot-reset-on-link-down-event.txt
  • Currently can't get the "Add system PM support" patch to apply, will test the others first.
  • Except that a test build tells me I need to rebase all of my patches against 6.15.x, rather the the current 6.16~rcX
previous episode next episode

12 July 2025

Reproducible Builds: Reproducible Builds in June 2025

Welcome to the 6th report from the Reproducible Builds project in 2025. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:
  1. Reproducible Builds at FOSSY 2025
  2. Distribution work
  3. diffoscope
  4. OSS Rebuild updates
  5. Website updates
  6. Upstream patches
  7. Reproducibility testing framework

Reproducible Builds at FOSSY 2025 On Saturday 2nd August, Vagrant Cascadian and Chris Lamb will be presenting at this year s FOSSY 2025. Their talk, titled Never Mind the Checkboxes, Here s Reproducible Builds!, is being introduced as follows:
There are numerous policy compliance and regulatory processes being developed that target software development but do they solve actual problems? Does it improve the quality of software? Do Software Bill of Materials (SBOMs) actually give you the information necessary to verify how a given software artifact was built? What is the goal of all these compliance checklists anyways or more importantly, what should the goals be? If a software object is signed, who should be trusted to sign it, and can they be trusted forever?
The talk will introduce the audience to Reproducible Builds as a set of best practices which allow users and developers to verify that software artifacts were built from the source code, but also allows auditing for license compliance, providing security benefits, and removes the need to trust arbitrary software vendors. Hosted by the Software Freedom Conservancy and taking place in Portland, Oregon, USA, FOSSY aims to be a community-focused event: Whether you are a long time contributing member of a free software project, a recent graduate of a coding bootcamp or university, or just have an interest in the possibilities that free and open source software bring, FOSSY will have something for you . More information on the event is available on the FOSSY 2025 website, including the full programme schedule. Vagrant and Chris will also be staffing a table this year, where they will be available to answer any questions about Reproducible Builds and discuss collaborations with other projects.

Distribution work In Debian this month:
  • Holger Levsen has discovered that it is now possible to bootstrap a minimal Debian trixie using 100% reproducible packages. This result can itself be reproduced, using the debian-repro-status tool and mmdebstrap s support for hooks:
      $ mmdebstrap --variant=apt --include=debian-repro-status \
           --chrooted-customize-hook=debian-repro-status \
           trixie /dev/null 2>&1   grep "Your system has"
       INFO  debian-repro-status > Your system has 100.00% been reproduced.
    
  • On our mailing list this month, Helmut Grohne wrote an extensive message raising an issue related to Uploads with conflicting buildinfo filenames:
    Having several .buildinfo files for the same architecture is something that we plausibly want to have eventually. Imagine running two sets of buildds and assembling a single upload containing buildinfo files from both buildds in the same upload. In a similar vein, as a developer I may want to supply several .buildinfo files with my source upload (e.g. for multiple architectures). Doing any of this is incompatible with current incoming processing and with reprepro.
  • 5 reviews of Debian packages were added, 4 were updated and 8 were removed this month adding to our ever-growing knowledge about identified issues.

In GNU Guix, Timothee Mathieu reported that a long-standing issue with reproducibility of shell containers across different host operating systems has been solved. In their message, Timothee mentions:
I discovered that pytorch (and maybe other dependencies) has a reproducibility problem of order 1e-5 when on AVX512 compared to AVX2. I first tried to solve the problem by disabling AVX512 at the level of pytorch, but it did not work. The dev of pytorch said that it may be because some components dispatch computation to MKL-DNN, I tried to disable AVX512 on MKL, and still the results were not reproducible, I also tried to deactivate in openmpi without success. I finally concluded that there was a problem with AVX512 somewhere in the dependencies graph but I gave up identifying where, as this seems very complicated.

The IzzyOnDroid Android APK repository made more progress in June. Not only have they just passed 48% reproducibility coverage, Ben started making their reproducible builds more visible, by offering rbtlog shields, a kind of badge that has been quickly picked up by many developers who are proud to present their applications reproducibility status.
Lastly, in openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 298, 299 and 300 to Debian:
  • Add python3-defusedxml to the Build-Depends in order to include it in the Docker image. [ ]
  • Handle the RPM format s HEADERSIGNATURES and HEADERIMMUTABLE as a special-case to avoid unnecessarily large diffs. Thanks to Daniel Duan for the report and suggestion. [ ][ ]
  • Update copyright years. [ ]
In addition, @puer-robustus fixed a regression introduced in an earlier commit which resulted in some differences being lost. [ ][ ] Lastly, Vagrant Cascadian updated diffoscope in GNU Guix to version 299 [ ][ ] and 300 [ ][ ].

OSS Rebuild updates OSS Rebuild has added a new network analyzer that provides transparent HTTP(S) interception during builds, capturing all network traffic to monitor external dependencies and identify suspicious behavior, even in unmodified maintainer-controlled build processes. The text-based user interface now features automated failure clustering that can group similar rebuild failures and provides natural language failure summaries, making it easier to identify and understand patterns across large numbers of build failures. OSS Rebuild has also improved the local development experience with a unified interface for build execution strategies, allowing for more extensible environment setup for build execution. The team also designed a new website and logo.

Website updates Once again, there were a number of improvements made to our website this month including:
  • Arnaud Brousseau added Stage , a new Linux distribution, to our Tools page.
  • Chris Lamb improved the docker instructions on the diffoscope website. [ ]


Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In June, however, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Installed and deployed rebuilderd version 0.24 from Debian unstable in order to make use of the new compression feature added by Jarl Gullberg for the database. This resulted in massive decrease of the SQLite databases:
      • 79G 2.8G (all)
      • 84G 3.2G (amd64)
      • 75G 2.9G (arm64)
      • 45G 2.1G (armel)
      • 48G 2.2G (armhf)
      • 73G 2.8G (i386)
      • 72G 2.7G (ppc64el)
      • 45G 2.1G (riscv64)
      for a combined saving from 521G 20.8G. This naturally reduces the requirements to run an independent rebuilderd instance and will permit us to add more Debian suites as well.
    • During migration to the latest version of rebuilderd, make sure several services are not started. [ ]
    • Actually run rebuilderd from /usr/bin. [ ]
    • Raise temperatures for NVME devices on some riscv64 nodes that should be ignored. [ ][ ]
    • Use a 64KB kernel page size on the ppc64el architecture (see #1106757). [ ]
    • Improve ordering of some failed to reproduce statistics. [ ]
    • Detect a number of potential causes of build failures within the statistics. [ ][ ]
    • Add support for manually scheduling for the any architecture. [ ]
  • Misc:
    • Update the Codethink nodes as there are now many kernels installed. [ ][ ]
    • Install linux-sysctl-defaults on Debian trixie systems as we need ping functionality. [ ]
    • Limit the fs.nr_open kernel turnable. [ ]
    • Stop submitting results to deprecated buildinfo.debian.net service. [ ][ ]
In addition, Jochen Sprickerhof greatly improved the statistics and the logging functionality, including adopting to the new database format of rebuilderd version 0.24.0 [ ] and temporarily increasing maximum log size in order to debug a nettlesome build [ ]. Jochen also dropped the CPUSchedulingPolicy=idle systemd flag on the workers. [ ]

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Freexian Collaborators: Monthly report about Debian Long Term Support, June 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In June, 20 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 14.0h (out of 14.0h assigned).
  • Adrian Bunk did 23.5h (out of 23.5h assigned).
  • Andreas Henriksson did 3.0h (out of 3.0h assigned and 17.0h from previous period), thus carrying over 17.0h to the next month.
  • Andrej Shadura did 2.0h (out of 3.0h assigned and 7.0h from previous period), thus carrying over 8.0h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 8.0h (out of 7.5h assigned and 16.0h from previous period), thus carrying over 15.5h to the next month.
  • Carlos Henrique Lima Melara did 12.0h (out of 12.0h assigned).
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 22.0h (out of 22.5h assigned and 1.0h from previous period), thus carrying over 1.5h to the next month.
  • Emilio Pozuelo Monfort did 23.5h (out of 16.75h assigned and 6.75h from previous period).
  • Guilhem Moulin did 14.0h (out of 11.5h assigned and 3.5h from previous period), thus carrying over 1.0h to the next month.
  • Jochen Sprickerhof did 21.0h (out of 0.5h assigned and 22.75h from previous period), thus carrying over 2.25h to the next month.
  • Lucas Kanashiro did 20.0h (out of 20.0h assigned).
  • Markus Koschany did 23.25h (out of 17.0h assigned and 6.25h from previous period).
  • Roberto C. S nchez did 21.25h (out of 20.75h assigned and 3.25h from previous period), thus carrying over 2.75h to the next month.
  • Santiago Ruano Rinc n did 12.75h (out of 15.0h assigned), thus carrying over 2.25h to the next month.
  • Sean Whitton did 1.0h (out of 4.25h assigned and 1.75h from previous period), thus carrying over 5.0h to the next month.
  • Sylvain Beucler did 23.5h (out of 23.5h assigned).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Tobias Frost did 2.5h (out of 12.0h assigned), thus carrying over 9.5h to the next month.

Evolution of the situation In June, we released 35 DLAs.
  • Notable security updates:
    • mariadb-10.5, prepared by Otto Kek l inen, fixes vulnerabilities which could result in denial of service, information disclosure, or unauthorized data modification
    • python-django, prepared by Chris Lamb, fixes vulnerabilities which would result in log injection or denial of service
    • webkit2gtk, prepared by Emilio Pozuelo Monfort, fixes many vulnerabilities which could results in a wide range of issues
    • xorg-server, prepared by Emilio Pozuelo Monfort, fixes multiple vulnerabilities which may result in privilege escalation
    • sudo, prepared by Thorsten Alteholz, fixes a vulnerability which could result in privilege escalation
  • Notable non-security updates:
    • debian-security-support, prepared by Santiago Ruano Rinc n, updates status of packages which receive limited security support or which have reached the end of security support
    • dns-root-data, prepared by Sylvain Beucler, updates the DNSSEC trust anchors
This month s contributions from outside the regular team include the mariadb-10.5 update mentioned above, prepared by Otto Kek l inen (the package maintainer); an update to libfile-find-rule-perl, prepared by Salvatore Bonaccorso (a member of the Debian Security Team); an update to activemq, prepared by Emmanuel Arias (a maintainer of the package). Additionally, LTS Team members contributed stable updates of the following packages:
  • curl, prepared by Carlos Henrique Lima Melara
  • python-tornado, prepared by Daniel Leidert
  • python-flask-cors, prepared by Daniel Leidert
  • common-vfs, prepared by Daniel Leidert
  • cjson, prepared by Adrian Bunk
  • icu, prepared by Adrian Bunk
  • node-tar-fs, prepared by Adrian Bunk
  • rar, prepared by Adrian Bunk
Something of particular noteworthiness is that LTS contributor Carlos Henrique Lima Melara discovered a regression in the upstream fix for CVE-2023-2753 in curl. The corrective action which he took included providing a patch to upstream, uploading a stable update of curl, and further updating the version of curl in LTS. DebConf, the annual Debian Conference, is coming up in July and, as is customary each year, the week preceding the conference will feature an event called DebCamp. The DebCamp week provides an opportunity for teams and other interested groups/individuals to meet together in person in the same venue as the conference itself, with the purpose of doing focused work, often called sprints . LTS coordinator Roberto C. S nchez has announced that the LTS Team is planning to hold a sprint primarily focused on the Debian security tracker and the associated tooling used by the LTS Team and the Debian Security Team.

Thanks to our sponsors Sponsors that joined recently are in bold.

Freexian Collaborators: Debian Contributions: unschroot, DebConf 25 preparations and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-06 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

unschroot, by Helmut Grohne Quite a while back, the sbuild maintainers added the unshare backend to enable better isolation of builds, but in doing so sbuild now effectively bundles a container runtime. unschroot is an attempt to separate containment from sbuild by implementing the same features and more in a schroot-compatible way. Last year, vague feature parity was achieved, but going beyond required changing the model from keeping state in the filesystem to keeping Linux namespaces as session state. A proof of concept is now available. While it still has sharp corners, it enables building packages on a squashfs with an overlayfs or id-mapped bind mounting of your ccache neither of which is possible with sbuild s unshare backend. There shall be a DebConf25 presentation about this work.

DebConf 25, by Stefano Rivera, Santiago Ruano Rinc n and Lucas Kanashiro DebConf 25 is now under way in Brest, France. Santiago is part of the local team running the event, and Stefano Rivera is part of the DebConf committee, supporting the event, as well as the video team. Both have spent considerable time in the last month, getting things ready for DebConf. Lucas Kanashiro built the schedule for DebConf 25. Also followed-up on multiple requests from speakers and stakeholders.

Miscellaneous contributions
  • Carles did general maintenance on simplemonitor, qnetload and qdacco packages; provided simplemonitor upstream feedback on new feature.
  • Carles s updates about po-debconf-manager: prepared for DebCamp/DebConf, used it for reviewing and merging different packages. Also fixed multispeech po-debconf templates.
  • Colin Watson found a crash in pterm (PuTTY s terminal emulator) when running in a Wayland session, and backported the resulting upstream fix to trixie.
  • Colin responded to an upstream groff bug report about URLs being dropped from PDF output in some cases on Debian, and backported the fix to trixie.
  • Helmut dealt with issues related to /usr-move. Most prominently Christian Hofstaedler reported an upgrade failure. /usr-move is a contributing factor here as that s what caused systemd to upgrade a number of Breaks and Replaces to Conflicts. dumat needed some help with dropping mips64el from testing and Theodore Ts o forwarded a fuse2fs upgrade failure.
  • Helmut sent patches for 25 cross build failures.
  • Helmut debugged rebootstrap failures and worked around build failures related to gcc-15 when they had patches and sent ones otherwise.
  • Thorsten Alteholz uploaded cups to fix a FTBFS-bug. This bug was introduced by a change in systemd, which bumped the maximum number of open files. This resulted in a longer test duration that triggered a timeout so that the build failed. Thorsten also uploaded mtink and lprng, which got new translation files.
  • Lucas Kanashiro followed-up on multiple unblock requests for ruby packages due to reproducible builds fixes. All of them were accepted into trixie.
  • Lucas Kanashiro discussed license issues with upstream involving Redis 8 new license and the possibility of backporting patches to old versions with a different license. Outcome is that upstream is adding a new paragraph to their license to allow the backport for security fixes.
  • Lucas Kanashiro fixed multiple CVEs reported against valkey in unstable and trixie.
  • Lucas Kanashiro gave a Debian packaging course of 8 hours for students at a free software development course at the University of Sao Paulo.
  • Lucas Kanashiro fixed a couple of cross building issues in the ruby ecosystem with Helmut s help.
  • Lucas Kanashiro is working on a debci fix for #1107645 (ongoing).
  • Stefano Rivera updated python-mitogen to the latest beta releases with upstream support for Ansible 12.
  • Stefano Rivera spent some time winding up DebConf 24 books.
  • Stefano Rivera fixed packages that were blocking cPython 3.13.5 from migrating to trixie, and filed an unblock request.
  • Stefano Rivera investigated a regression in cPython 3.13 that was breaking OpenStack Nova. There is a patch in progress for cPython, but it is not ready for use, yet.
  • Santiago reviewed different MRs in Salsa CI. For example, the MR !605 proposed by Aquila that aims to introduce a new debdiff job, as well as the autopkgtest MR !33 to extend the support to architectures other than amd64. Also reviewed MR !611 by Aayush Raj that fixes the autopkgtest images cleanup. And the MR !614, prepared by Charles, to change the suffix name used to bump the version used in the pipeline.
  • Anupa procured supplies needed for the DebConf ID tag for the DebConf registration team and co-ordinated its transport to the venue.
  • Anupa joined Nattie to complete the registration team tasks.

11 July 2025

David Bremner: Hibernate on the pocket reform 5/n

Context

A Kernel Patch
  • The follow patch looks potentially relevant:
https://patchwork.kernel.org/project/linux-rockchip/patch/20250509-b4-pci_dwc_reset_support-v3-1-37e96b4692e7@wdc.com/
  • git clone https://github.com/torvalds/linux.git (Is there a better place? kernel.org is pretty opaque)
  • are the pre-reqs in mnt kernel? The patch header contains
    base-commit: 08733088b566b58283f0f12fb73f5db6a9a9de30
    change-id: 20250430-b4-pci_dwc_reset_support-d720dbafb7ea
    prerequisite-change-id: 20250404-pcie-reset-slot-730bfa71a202:v4
    prerequisite-patch-id: 2dad85eb26838d89569b12c19d70f392fa592667
    prerequisite-patch-id: 6238a682bd8e9476e5911b7a59263c3fc618d63e
    prerequisite-patch-id: 37cab00bc255a62b1e8396a48a3afba5e1751abd
    prerequisite-patch-id: ff711f65cf9926374646b76cd38bdd823d576764
    prerequisite-patch-id: 1654cca919d024b9a9190b28e90f722975c797e8
  • First check and see what is upstream. I had to remember how to use git-patch-id and also how to split a long regex disjunction into multiple lines.
git log --patch --no-merges v6.13..   \
  git patch-id --stable   \
  grep -F -e 2dad85eb26838d89569b12c19d70f392fa592667 \
    -e 6238a682bd8e9476e5911b7a59263c3fc618d63e \
    -e 37cab00bc255a62b1e8396a48a3afba5e1751abd \
    -e ff711f65cf9926374646b76cd38bdd823d576764 \
    -e 1654cca919d024b9a9190b28e90f722975c797e8
yields
37cab00bc255a62b1e8396a48a3afba5e1751abd d1c696dba120624256ab335ab8247f535b872309
2dad85eb26838d89569b12c19d70f392fa592667 b06d125e6280603a34d9064cd9c12748ca2edb04
The two commits that are actually found, are only in tag 'v6.16~rc1'
  • The discussion on LKML mentions pci/slot-reset. Where does that branch live?
git remote add pci https://git.kernel.org/pub/scm/linux/kernel/git/pci/pci.git
git fetch pci
git for-each-ref refs/remotes/pci --format "%(refname)"   \
    while read branch
    do
        echo "checking $branch"
        git log --patch --no-merges --since 2025-01-01 $branch   \
            git patch-id --stable   \
            grep -F -e 2dad85eb26838d89569b12c19d70f392fa592667 \
                 -e 6238a682bd8e9476e5911b7a59263c3fc618d63e \
                 -e 37cab00bc255a62b1e8396a48a3afba5e1751abd \
                 -e ff711f65cf9926374646b76cd38bdd823d576764 \
                 -e 1654cca919d024b9a9190b28e90f722975c797e8
    done
This did not find any more commits, but I did learn how to use git-for-each-ref, so I guess not a total loss. previous episode next episode

10 July 2025

David Bremner: Hibernate on the pocket reform 4/n

Context

Log from (failed) platform test After some fun I got the serial console working and re-ran the platform test. After a bit of reading the serial console, I realized that rmmod dwc3 was causing more problems than it solved, in particularly reliable hard lockup on one of the CPUs. My revised test script is
set -x
echo platform >  /sys/power/pm_test
echo reboot > /sys/power/disk
sleep 2
rmmod mt76x2u
sleep 2
echo disk >  /sys/power/state
sleep 2
modprobe mt76x2u
The current problem seems to be pcie not resuming properly.
[   65.306842] usbcore: deregistering interface driver mt76x2u
[   65.343606] wlx000a5205eb2d: deauthenticating from 20:05:b7:00:2d:89 by local choice (Reason: 3=DEAUTH_LEAVING)
[   67.995239] PM: hibernation: hibernation entry
[   68.048103] Filesystems sync: 0.022 seconds
[   68.049005] Freezing user space processes
[   68.051075] Freezing user space processes completed (elapsed 0.001 seconds)
[   68.051760] OOM killer disabled.
[   68.052597] PM: hibernation: Basic memory bitmaps created
[   68.053108] PM: hibernation: Preallocating image memory
[   69.719040] PM: hibernation: Allocated 366708 pages for snapshot
[   69.719650] PM: hibernation: Allocated 1466832 kbytes in 1.66 seconds (883.63 MB/s)
[   69.720370] Freezing remaining freezable tasks
[   69.723558] Freezing remaining freezable tasks completed (elapsed 0.002 seconds)
[   69.728002] rk_gmac-dwmac fe1b0000.ethernet end0: Link is Down
[   69.992324] rockchip-dw-pcie a40c00000.pcie: Failed to receive PME_TO_Ack
[   69.993405] PM: hibernation: debug: Waiting for 5 seconds.
[   76.059484] rockchip-dw-pcie a40c00000.pcie: Phy link never came up
[   76.060043] rockchip-dw-pcie a40c00000.pcie: fail to resume
[   76.060546] rockchip-dw-pcie a40c00000.pcie: PM: dpm_run_callback(): genpd_restore_noirq returns -110
[   76.061363] rockchip-dw-pcie a40c00000.pcie: PM: failed to restore noirq: error -110
previous episode next episode

Russell Coker: Bad Product Comparisons and EVs

When companies design products a major concern seems to be what the reviewers will have to say about it. For any product of significant value the users are unable to perform any reasonable test before buying, for a casual user some problems may only be apparent after weeks of use so professional reviews are important to many people. The market apparently doesn t want reviews of the form here s a list of products that are quite similar and all do the job well, you can buy any of them, it s no big deal which would be the most technically accurate way of doing it. So the reviewers compare the products on the criteria that are easiest to measure, this lead to phones being compared by how light and thin they are. I think it s often the case that users would be better served by thicker heavier phones that have larger batteries but instead they are being sold phones that have good battery life in a fresh installation but which don t last a day with a full load of apps installed. The latest issue with bad reviews driving poor product design is electric cars. For a while the advocates of old fashioned cars have touted the range of petrol cars which has become an issue for comparing EVs. I have been driving cars for 35 years and so far I have never driven anywhere that s out of range of the current electric charging network, even with the range of the LEAF (which is smaller than many other EVs). If I ever felt the need to drive across the Nullarbor Plain then I could rent a car to do that and the costs of such car rental would be small compared to the money I m saving by driving an EV and also small when compared to the premium I would have to pay for an EV with a larger range. Some of the recent articles I ve seen about EVs have covered vehicles with a battery range over 700Km which is greater than the legal distance a commercial driver can drive without a break. I ve also seen articles about plans to have a small petrol or Diesel motor in an EV to recharge the battery without directly driving the wheels. A 9KW Diesel motor could provide enough electricity on average to keep the charge maintained in a LEAF battery and according to the specs of Diesel generators would take about 55Kg of fuel to provide the charge a LEAF needs to drive 1000Km. The idea of a mostly electric hybrid car that can do 1000Km on one tank of fuel is interesting as a thought experiment but doesn t seem to have much actual use. Apparently a Chinese company is planning to release a car that can do 1400Km one one tank of fuel using such technology which is impressive but not particularly useful. The next issue of unreasonable competition is in charge speed. Charging a car at 2KW from a regular power socket is a real limit to what you can do with a car. It s a limit that hasn t bothered me so far because the most driving I typically do in a week is less than one full charge, so at most I have to charge overnight twice in a week. But if I was going to drive to another city without hiring a car that has better range I d need a fast charger. Most current models of the Nissan LEAF support charging speeds up to 50KW which means fully charging the battery in under an hour (or slightly over an hour for the long range version). If I was to drive from Melbourne to Canberra in my LEAF I d have to charge twice which would be an annoyance at those speeds. There are a variety of EVs that can charge at 100KW and some as high as 350KW. 350KW is enough to fully charge the largest EV batteries in half an hour which seems to be as much as anyone would need. But there are apparently plans for 1MW car chargers which would theoretically be able to charge a Hummer (the EV with the largest battery) in 12 minutes. One obvious part of the solution to EV charging times is to not drive a Hummer! Another thing to note is that batteries can t be charged at a high rate for all charge levels, this is why advertising for fast chargers makes claims like 80% charge in half an hour which definitely doesn t mean 100% charge in 37.5 minutes ! There are significant engineering issues with high power applications. A 1MW cable is not just a bigger version of a regular power cable, there are additional safety issues, user training is required and cooling of the connector is probably required. That s a lot to just get a better number in the table at the end of a review. There is research in progress on the Megawatt Charging System which is designed to charge heavy vehicles (presumably trucks and buses) at up to 3.75MW. Charging a truck at that rate is reasonable as the process of obtaining and maintaining a heavy vehicle license requires a significant amount of effort and some extra training in 3.75MW charging probably doesn t make much difference. A final issue with fast charging is the capacity of the grid. A few years ago I attended a lecture by an electrical engineer who works for the Victorian railway system which was very interesting. The Vic rail power setup involved about 100MW of grid connectivity with special contracts with the grid operators due to the fact that 1MW trains suddenly starting and stopping causes engineering problems that aren t trivial to solve. They were also working on battery packs and super capacitors to deal with regenerative braking and to avoid brownouts in long sections of track. For a medium size petrol station 14 bays for fuelling cars is common. If 6 such petrol stations were replaced with fast charging stations that can charge cars at 1MW each that would draw the same power as the train network for the entire state! There is a need for significant engineering work to allow most cars to be electric no matter how it s done, but we don t need to make that worse just for benchmarks.

7 July 2025

Sahil Dhiman: Let's Talk About AI

Recently, Seth Godin wrote Productivity, AI and pushback:
Typesetters did not like the laser printer. Wedding photographers still hate the iphone. And some musicians are outraged that AI is now making mediocre pop music.
In the article, Seth connected how AI is increasing productivity and how anything that improves productivity always wins. Nowadays, large language models (LLMs) have become synonymous with AI, while AI is a broader field. AI has brought a shift in how things are done. Use cases might vary, but it s helping in ways like quickly summarizing huge knowledge bases to answer questions or, in my case, helping understand the contextual meaning of complex word (or sentence) usage in language and literature in both English and Hindi, which was sometimes not easy to comprehend with simple web search results. Even if you or I don t really like AI in everything , we can t deny the fact that AI is here to stay. This doesn t take away from the fact that AI needs to become ethical, regulated, and environmentally sustainable.

5 July 2025

Bits from Debian: Bits from the DPL

Dear Debian community, This is bits from the DPL for June. The Challenge of Mentoring Newcomers In June there was an extended discussion about the ongoing challenges around mentoring newcomers in Debian. As many of you know, this is a topic I ve cared about deeply--long before becoming DPL. In my view, the issue isn t just a matter of lacking tools or needing to try harder to attract contributors. Anyone who followed the discussion will likely agree that it s more complex than that. I sometimes wonder whether Debian s success contributes to the problem. From the outside, things may appear to just work , which can lead to the impression: Debian is doing fine without me--they clearly have everything under control. But that overlooks how much volunteer effort it takes to keep the project running smoothly. We should make it clearer that help is always needed--not only in packaging, but also in writing technical documentation, designing web pages, reaching out to upstreams about license issues, finding sponsors, or organising events. (Speaking from experience, I would have appreciated help in patiently explaining Free Software benefits to upstream authors.) Sometimes we think too narrowly about what newcomers can do, and also about which tasks could be offloaded from overcommitted contributors. In fact, one of the most valuable things a newcomer can contribute is better documentation. Those of us who ve been around for years may be too used to how things work--or make assumptions about what others already know. A person who just joined the project is often in the best position to document what s confusing, what s missing, and what they wish they had known sooner. In that sense, the recent "random new contributor s experience" posts might be a useful starting point for further reflection. I think we can learn a lot from positive user stories, like this recent experience of a newcomer adopting the courier package. I'm absolutely convinced that those who just found their way into Debian have valuable perspectives--and that we stand to learn the most from listening to them. We should also take seriously what Russ Allbery noted in the discussion: "This says bad things about the project's sustainability and I think everyone knows that." Volunteers move on--that s normal and expected. But it makes it all the more important that we put effort into keeping Debian's contributor base at least stable, if not growing. Project-wide LLM budget for helping people Lucas Nussbaum has volunteered to handle the paperwork and submit a request on Debian s behalf to LLM providers, aiming to secure project-wide access for Debian Developers. If successful, every DD will be free to use this access--or not--according to their own preferences. Kind regards Andreas.

Taavi V n nen: Tracking my train travel by parsing tickets in emails

Rumour has it that I might be a bit of a train nerd. At least I want to collect various nerdy data about my travels. Historically that data has lived in manual form in several places,1 but over the past year and a half I've been working on a toy project to collect most of that information into a custom tool. That toy project2 uses various sources to get information about trains to fill up its database: for example, in Finland Fintraffic, the organization responsible for railway traffic management, publishes very comprehensive open data about almost everything that's moving on the Finnish railway network. Unfortunately, I cannot be on all of the trains.3 Thus I need to tell the system details about my journeys. The obvious solution is to make a form that lets me save that data. Which I did, but I got very quickly bored of filling out that form, and as regular readers of this blog know, there is no reason to settle for a simple but boring solution when the alternative is to make something that is ridiculously overengineered.

Parsing data out of my train tickets Finnish long-distance trains generally require train-specific seat reservations, which means VR (the train company) knows which trains I am on. We just need to find a way to extract that information in some machine-readable format. So my plan for the ridiculously overengineered solution was to parse the booking emails to get the details I need. Now, VR ticket emails include the data I want in a couple of different formats: they're included as text in the HTML email body, they're in the embedded calendar invite, as text in the included PDF ticket, and encoded in the Aztec Code in the included PDF ticket. I chose to parse the last option with the hopes of building something that could be ported to parse other operators' tickets with relative ease.
Example Aztec code
Example Aztec code
After a bit of digging (thank you to the KDE Itinerary people for documenting this!) I stumbled upon an European Union Agency for Railways PDF titled ELECTRONIC SEAT/BERTH RESERVATION AND ELECTRONIC PRODUCTION OF TRANSPORT DOCUMENTS - TRANSPORT DOCUMENTS (RCT2 STANDARD) which, in its Appendix C.1, describes how the information is encoded in the code.4 (As a side note, various sources call these codes SSB version 1 codes, although that term isn't used in this specification. So maybe there are more specifications about the format that I haven't discovered yet!) I then wrote a parser in Go for the binary data embedded in these codes. So far it works, although I wouldn't be surprised if there are some edge cases that it doesn't handle. In particular, the spec specifies a custom lookup table for converting between text and binary data, and that only has support for characters 0-9 and A-Z. But Finnish railway station codes can also use and .. maybe I need to buy a ticket to a station with one of those.

Extracting barcodes out of emails A parser just for the binary format isn't enough here if the intended source input is the emails that VR sends upon making a booking. Time to write a single-purpose email server! In short, the logic in the server, again written in Go and with the help of go-smtp and go-message, is:
  • Accept any mail with a reasonable body size
  • Process through all body parts
  • For all PDF parts, extract all images
  • For all images, run them through ZXing
  • For all decoded barcodes, try to parse them with my new ticket parsing library I mentioned earlier
  • If any tickets are found, send the data from them and any metadata to the main backend, which will save them to a database
The custom mail server exposes an LMTP interface over TCP for my internet-facing mail servers to forward to. I chose LMTP for this because it seemed like a better fit in theory than normal (E)SMTP. I've since discovered that curl doesn't support LMTP which makes development much harder, and in practice there's no benefit of LMTP here as all mails are being sent to the backend in a single request regardless of the number of recipients, so maybe I'll migrate it to regular SMTP at some point.

Side quest time The last missing part is automatically forwarding the ticket mails to the new service. I've routed a dedicated subdomain to the new service, and the backend is configured to allocate addresses like i2v44g2pygkcth64stjgyuqz@somedomain.example for each user. That's great if we wanted to manually forward mails to the service, but we can go one step above that. I created a dedicated email alias in my mail server config that routes both to my regular mailbox and the service address. That way I can update my VR account to use the alias and have mails automatically processed while still receiving backup copies of the tickets (and any other important mail that VR might send me). Unfortunately that last part turns out something that's easier said than done. Logging in on the website, I'm greeted by this text stating I need to contact customer service by phone to change the address associated with my account.5 After a bit of digging, I noticed that the mobile app suggests filling out a feedback form in order to change the address. So I filled that, and after a day or two I got a "confirm you want to change your email" mail. Success!

  1. Including (but not limited to): a page of this website, the notes app on my phone, and an uMap map.
  2. Which I'm not directly naming here because I still think it needs a lot more work before being presentable, but if you're really interested it's not that hard to find out.
  3. Someone should invent human cloning so that we can fix this.
  4. People who know much more about railway ticketing than I do were surprised when I told them this format is still in use somewhere. So, uh, sorry if you were expecting a nice universal worldwide standard!
  5. In case you have not guessed yet, I do not like making phone calls.

4 July 2025

Russell Coker: Function Keys

For at least 12 years laptops have been defaulting to not having the traditional PC 101 key keyboard function key functionality and instead have had other functions like controlling the volume and have had a key labelled Fn to toggle the functions. It s been a BIOS option to control whether traditional function keys or controls for volume etc are the default and for at least 12 years I ve configured all my laptops to have the traditional function keys as the default. Recently I ve been working in corporate IT and having exposure to many laptops with the default BIOS settings for those keys to change volume etc and no reasonable option for addressing it. This has made me reconsider the options for configuring these things. Here s a page listing the standard uses of function keys [1]. Here is a summary of the relevant part of that page: The keys F1, F3, F4, F7, F9, F10, and F12 don t get much use for me and for the people I observe. The F2 and F8 keys aren t useful in most programs, F6 is only really used in web browsers but the web browser counts as most programs nowadays. Here s the description of Thinkpad Fn keys [2]. I use Thinkpads for fun and Dell laptops for work, so it would be nice if they both worked in similar ways but of course they don t. Dell doesn t document how their Fn keys are laid out, but the relevant bit is that F1 to F4 are the same as on Thinkpads which is convenient as they are the ones that are likely to be commonly used and needed in a hurry. I have used the KDE settings on my Thinkpad to map the function F1 to F3 keys to the Fn equivalents which are F1 to mute-audio, F2 for vol-down, and F3 for vol-up to allow using them without holding down the Fn key while having other function keys such as F5 and F6 have their usual GUI functionality. Now I have to could train myself to use F8 in situations where I usually use F2, at least when using a laptop. The only other Fn combinations I use are F5 and F6 for controlling screen brightness, but that s not something I use much. It s annoying that the laptop manufacturers forced me to this. Having a Fn key to get extra functions and not need 101+ keys on a laptop size device is a reasonable design choice. But they could have done away with the PrintScreen key to make space for something else. Also for Thinkpads a touch pad is something that could obviously be removed to gain some extra space as the Trackpoint does all that s needed in that regard.

Sahil Dhiman: Secondary Authoritative Name Server Options for Self-Hosted Domains

In the past few months, I have moved authoritative name servers (NS) of two of my domains (sahilister.net and sahil.rocks) in house using PowerDNS. Subdomains of sahilister.net see roughly 320,000 hits/day across my IN and DE mirror nodes, so adding secondary name servers with good availability (in addition to my own) servers was one of my first priorities. I explored the following options for my secondary NS, which also didn t cost me anything:

1984 Hosting

Hurriance Electric

Afraid.org

Puck

NS-Global

Asking friends Two of my friends and fellow mirror hosts have their own authoritative name server setup, Shrirang (ie albony) and Luke. Shirang gave me another POP in IN and through Luke (who does have an insane amount of in-house NS, see dig ns jing.rocks +short), I added a JP POP. If we know each other, I would be glad to host a secondary NS for you in (IN and/or DE locations).

Some notes
  • Adding a third-party secondary is putting trust that the third party would serve your zone right.
  • Hurricane Electric and 1984 hosting provide multiple NS. One can use some or all of them. Ideally, you can get away with just using your own with full set from any of these two. Play around with adding and removing secondaries, which gives you the best results. . Using everyone is anyhow overkill, unless you have specific reasons for it.
  • Moving NS in-house isn t that hard. Though, be prepared to get it wrong a few times (and some more). I have already faced partial outages because:
    • Recursive resolvers (RR) in the wild behave in a weird way and cache the wrong NS response for longer time than in TTL.
    • NS expiry took more than time. 2 out of 3 of my Netim s NS (my domain registrar) had stopped serving my domain, while RRs in the wild hadn t picked up my new in-house NS. I couldn t really do anything about it, though.
    • Dot is pretty important at the end.
    • With HE.net, I forgot to delegate my domain on their panel and just added in my NS set, thinking I ve already done so (which I did but for another domain), leading to a lame server situation.
  • In terms of serving traffic, there s no distinction between primary and secondary NS. RR don t really care who they re asking the query to. So one can have hidden primary too.
  • I initially thought of adding periodic RIPE Atlas measurements from the global set but thought against it as I already host a termux mirror, which brings in thousands of queries from around the world leading to a diverse set of RRs querying my domain already.
  • In most cases, query resolution time would increase with out of zone NS servers (which most likely would be in external secondary). 1 query vs. 2 queries. Pay close attention to ADDITIONAL SECTION Shrirang s case followed by mine:
$ dig ns albony.in
; <<>> DiG 9.18.36 <<>> ns albony.in
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 60525
;; flags: qr rd ra; QUERY: 1, ANSWER: 4, AUTHORITY: 0, ADDITIONAL: 9
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 65494
;; QUESTION SECTION:
;albony.in.			IN	NS
;; ANSWER SECTION:
albony.in.		1049	IN	NS	ns3.albony.in.
albony.in.		1049	IN	NS	ns4.albony.in.
albony.in.		1049	IN	NS	ns2.albony.in.
albony.in.		1049	IN	NS	ns1.albony.in.
;; ADDITIONAL SECTION:
ns3.albony.in.		1049	IN	AAAA	2a14:3f87:f002:7::a
ns1.albony.in.		1049	IN	A	82.180.145.196
ns2.albony.in.		1049	IN	AAAA	2403:44c0:1:4::2
ns4.albony.in.		1049	IN	A	45.64.190.62
ns2.albony.in.		1049	IN	A	103.77.111.150
ns1.albony.in.		1049	IN	AAAA	2400:d321:2191:8363::1
ns3.albony.in.		1049	IN	A	45.90.187.14
ns4.albony.in.		1049	IN	AAAA	2402:c4c0:1:10::2
;; Query time: 29 msec
;; SERVER: 127.0.0.53#53(127.0.0.53) (UDP)
;; WHEN: Fri Jul 04 07:57:01 IST 2025
;; MSG SIZE  rcvd: 286
vs mine
$ dig ns sahil.rocks
; <<>> DiG 9.18.36 <<>> ns sahil.rocks
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 64497
;; flags: qr rd ra; QUERY: 1, ANSWER: 11, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 65494
;; QUESTION SECTION:
;sahil.rocks.			IN	NS
;; ANSWER SECTION:
sahil.rocks.		6385	IN	NS	ns5.he.net.
sahil.rocks.		6385	IN	NS	puck.nether.net.
sahil.rocks.		6385	IN	NS	colin.sahilister.net.
sahil.rocks.		6385	IN	NS	marvin.sahilister.net.
sahil.rocks.		6385	IN	NS	ns2.afraid.org.
sahil.rocks.		6385	IN	NS	ns4.he.net.
sahil.rocks.		6385	IN	NS	ns2.albony.in.
sahil.rocks.		6385	IN	NS	ns3.jing.rocks.
sahil.rocks.		6385	IN	NS	ns0.1984.is.
sahil.rocks.		6385	IN	NS	ns1.1984.is.
sahil.rocks.		6385	IN	NS	ns-global.kjsl.com.
;; Query time: 24 msec
;; SERVER: 127.0.0.53#53(127.0.0.53) (UDP)
;; WHEN: Fri Jul 04 07:57:20 IST 2025
;; MSG SIZE  rcvd: 313
  • Theoretically speaking, a small increase/decrease in resolution would occur based on the chosen TLD and the popularity of the TLD in query originators area (already cached vs. fresh recursion).
  • One can get away with having only 3 NS (or be like Google and have 4 anycast NS or like Amazon and have 8 or like Verisign and make it 13 :P).
  • Nowhere it s written, your NS needs not to be called dns* or ns1, ns2 etc. Get creative with naming NS; be deceptive with the naming :D.
  • A good understanding of RR behavior can help engineer a good authoritative NS system.

Further reading

2 July 2025

Dirk Eddelbuettel: Rcpp 1.1.0 on CRAN: C++11 now Minimum, Regular Semi-Annual Update

rcpp logo With a friendly Canadian hand wave from vacation in Beautiful British Columbia, and speaking on behalf of the Rcpp Core Team, I am excited to shared that the (regularly scheduled bi-annual) update to Rcpp just brought version 1.1.0 to CRAN. Debian builds haven been prepared and uploaded, Windows and macOS builds should appear at CRAN in the next few days, as will builds in different Linux distribution and of course r2u should catch up tomorrow as well. The key highlight of this release is the switch to C++11 as minimum standard. R itself did so in release 4.0.0 more than half a decade ago; if someone is really tied to an older version of R and an equally old compiler then using an older Rcpp with it has to be acceptable. Our own tests (using continuous integration at GitHub) still go back all the way to R 3.5.* and work fine (with a new-enough compiler). In the previous release post, we commented that we had only reverse dependency (falsely) come up in the tests by CRAN, this time there was none among the well over 3000 packages using Rcpp at CRAN. Which really is quite amazing, and possibly also a testament to our rigorous continued testing of our development and snapshot releases on the key branch. This release continues with the six-months January-July cycle started with release 1.0.5 in July 2020. As just mentioned, we do of course make interim snapshot dev or rc releases available. While we not longer regularly update the Rcpp drat repo, the r-universe page and repo now really fill this role admirably (and with many more builds besides just source). We continue to strongly encourage their use and testing I run my systems with these versions which tend to work just as well, and are of course also fully tested against all reverse-dependencies. Rcpp has long established itself as the most popular way of enhancing R with C or C++ code. Right now, 3038 packages on CRAN depend on Rcpp for making analytical code go faster and further. On CRAN, 13.6% of all packages depend (directly) on Rcpp, and 61.3% of all compiled packages do. From the cloud mirror of CRAN (which is but a subset of all CRAN downloads), Rcpp has been downloaded 100.8 million times. The two published papers (also included in the package as preprint vignettes) have, respectively, 2023 (JSS, 2011) and 380 (TAS, 2018) citations, while the the book (Springer useR!, 2013) has another 695. As mentioned, this release switches to C++11 as the minimum standard. The diffstat display in the CRANberries comparison to the previous release shows how several (generated) sources files with C++98 boilerplate have now been removed; we also flattened a number of if/else sections we no longer need to cater to older compilers (see below for details). We also managed more accommodation for the demands of tighter use of the C API of R by removing DATAPTR and CLOENV use. A number of other changes are detailed below. The full list below details all changes, their respective PRs and, if applicable, issue tickets. Big thanks from all of us to all contributors!

Changes in Rcpp release version 1.1.0 (2025-07-01)
  • Changes in Rcpp API:
    • C++11 is now the required minimal C++ standard
    • The std::string_view type is now covered by wrap() (Lev Kandel in #1356 as discussed in #1357)
    • A last remaining DATAPTR use has been converted to DATAPTR_RO (Dirk in #1359)
    • Under R 4.5.0 or later, R_ClosureEnv is used instead of CLOENV (Dirk in #1361 fixing #1360)
    • Use of lsInternal switched to lsInternal3 (Dirk in #1362)
    • Removed compiler detection macro in a header cleanup setting C++11 as the minunum (Dirk in #1364 closing #1363)
    • Variadic templates are now used onconditionally given C++11 (Dirk in #1367 closing #1366)
    • Remove RCPP_USING_CXX11 as a #define as C++11 is now a given (Dirk in #1369)
    • Additional cleanup for __cplusplus checks (I aki in #1371 fixing #1370)
    • Unordered set construction no longer needs a macro for the pre-C++11 case (I aki in #1372)
    • Lambdas are supported in a Rcpp Sugar functions (I aki in #1373)
    • The Date(time)Vector classes now have default ctor (Dirk in #1385 closing #1384)
    • Fixed an issue where Rcpp::Language would duplicate its arguments (Kevin in #1388, fixing #1386)
  • Changes in Rcpp Attributes:
    • The C++26 standard now has plugin support (Dirk in #1381 closing #1380)
  • Changes in Rcpp Documentation:
    • Several typos were correct in the NEWS file (Ben Bolker in #1354)
    • The Rcpp Libraries vignette mentions PACKAGE_types.h to declare types used in RcppExports.cpp (Dirk in #1355)
    • The vignettes bibliography file was updated to current package versions, and now uses doi references (Dirk in #1389)
  • Changes in Rcpp Deployment:
    • Rcpp.package.skeleton() creates URL and BugReports if given a GitHub username (Dirk in #1358)
    • R 4.4.* has been added to the CI matrix (Dirk in #1376)
    • Tests involving NA propagation are skipped under linux-arm64 as they are under macos-arm (Dirk in #1379 closing #1378)

Thanks to my CRANberries, you can also look at a diff to the previous release Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues).

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

30 June 2025

Gunnar Wolf: Get your personalized map of DebConf25 in Brest

As I often do, this year I have also prepared a set of personalized maps for your OpenPGP keysigning in DebConf25, in Brest! What is that, dare you ask? Partial view of my OpenPGP map One of the not-to-be-missed traditions of DebConf is a Key-Signing Party (KSP) that spans the whole conference! Travelling from all the corners of the world to a single, large group gathering, we have the ideal opportunity to spread some communicable diseases trust on your peers identities and strengthen Debian s OpenPGP keyring. But whom should you approach for keysigning? Go find yourself in the nice listing I have prepared. By clicking on your long keyid (in my case, the link labeled 0x2404C9546E145360), anybody can download your certificate (public key + signatures). The SVG and PNG links will yield a graphic version of your position within the DC25 keyring, and the TXT link will give you a textual explanation of it. (of course, your links will differ, yada yada ) Please note this is still a preview of our KSP information: You will notice there are outstanding several things for me to fix before marking the file as final. First, some names have encoding issues I will fix. Second, some keys might be missing if you submitted your key as part of the conference registration form but it is not showing, it must be because my scripts didn t find it in any of the queried keyservers. My scripts are querying the following servers:
hkps://keyring.debian.org/
hkps://keys.openpgp.org/
hkps://keyserver.computer42.org/
hkps://keyserver.ubuntu.com/
hkps://pgp.mit.edu/
hkps://pgp.pm/
hkps://pgp.surf.nl/
hkps://pgpkeys.eu/
hkps://the.earth.li/
Make sure your key is available in at least some of them; I will try to do a further run on Friday, before travelling, or shortly after arriving to France. If you didn t submit your key in time, but you will be at DC25, please mail me stating [DC25 KSP] in your mail title, and I will manually add it to the list. On (hopefully!) Friday, I ll post the final, canonical KSP coordination page which you should download and calculate its SHA256-sum. We will have printed out convenience sheets to help you do your keysigning at the front desk.

Russell Coker: Links June 2025

Jonathan McDowell wrote part 2 of his blog series about setting up a voice assistant on Debian, I look forward to reading further posts [1]. I m working on some related things for Debian that will hopefully work with this. I m testing out OpenSnitch on Trixie inspired by this blog post, it s an interesting package [2]. Valerie wrote an informative article about creating mesh networks using LORA for emergency use [3]. Interesting article about Signal and Windows Recall. That gives us some things to consider regarding ML features on Linux systems [4]. Insightful article about AI and the end of prestige [5]. We should all learn about LLMs. Jonathan Dowland wrote an informative blog post about how to manage namespaces on Linux [6]. The Consumer Rights wiki is a great resource for raising awareness of corporations exploiting their customers for computer related goods and services [7]. Interesting article about Schizophrenia and the cliff-edge function of evolution [8].

Otto Kek l inen: Corporate best practices for upstream open source contributions

Featured image of post Corporate best practices for upstream open source contributions
This post is based on presentation given at the Validos annual members meeting on June 25th, 2025.
When I started getting into Linux and open source over 25 years ago, the majority of the software development in this area was done by academics and hobbyists. The number of companies participating in open source has since exploded in parallel with the growth of mobile and cloud software, the majority of which is built on top of open source. For example, Android powers most mobile phones today and is based on Linux. Almost all software used to operate large cloud provider data centers, such as AWS or Google, is either open source or made in-house by the cloud provider. Pretty much all companies, regardless of the industry, have been using open source software at least to some extent for years. However, the degree to which they collaborate with the upstream origins of the software varies. I encourage all companies in a technical industry to start contributing upstream. There are many benefits to having a good relationship with your upstream open source software vendors, both for the short term and especially for the long term. Moreover, with the rollout of CRA in EU in 2025-2027, the law will require software companies to contribute security fixes upstream to the open source projects their products use. To ensure the process is well managed, business-aligned and legally compliant, there are a few do s and don t do s that are important to be aware of.

Maintain your SBOMs For every piece of software, regardless of whether the code was done in-house, from an open source project, or a combination of these, every company needs to produce a Software Bill of Materials (SBOM). The SBOMs provide a standardized and interoperable way to track what software and which versions are used where, what software licenses apply, who holds the copyright of which component, which security fixes have been applied and so forth. A catalog of SBOMs, or equivalent, forms the backbone of software supply-chain management in corporations.

Identify your strategic upstream vendors The SBOMs are likely to reveal that for any piece of non-trivial software, there are hundreds or thousands of upstream open source projects in use. Few organizations have resources to contribute to all of their upstreams. If your organization is just starting to organize upstream contribution activities, identify the key projects that have the largest impact on your business and prioritize forming a relationship with them first. Organizations with a mature contribution process will be collaborating with tens or hundreds of upstreams.

Appoint an internal coordinator and champions Having a written policy on how to contribute upstream will help ensure a consistent process and avoid common pitfalls. However, a written policy alone does not automatically translate into a well-running process. It is highly recommended to appoint at least one internal coordinator who is knowledgeable about how open source communities work, how software licensing and patents work, and is senior enough to have a good sense of what business priorities to optimize for. In small organizations it can be a single person, while larger organizations typically have a full Open Source Programs Office. This coordinator should oversee the contribution process, track all contributions made across the organization, and further optimize the process by working with stakeholders across the business, including legal experts, business owners and CTOs. The marketing and recruiting folks should also be involved, as upstream contributions will have a reputation-building aspect as well, which can be enhanced with systematic tracking and publishing of activities. Additionally, at least in the beginning, the organization should also appoint key staff members as open source champions. Implementing a new process always includes some obstacles and occasional setbacks, which may discourage employees from putting in the extra effort to reap the full long-term benefits for the company. Having named champions will empower them to make the first few contributions themselves, setting a good example and encouraging and mentoring others to contribute upstream as well.

Avoid excessive approvals To maintain a high quality bar, it is always good to have all outgoing submissions reviewed by at least one or two people. Two or three pairs of eyeballs are significantly more likely to catch issues that might slip by someone working alone. The review also slows down the process by a day or two, which gives the author time to sleep on it , which usually helps to ensure the final submission is well-thought-out by the author. Do not require more than one or two reviewers. The marginal utility goes quickly to zero beyond a few reviewers, and at around four or five people the effect becomes negative, as the weight of each approval decreases and the reviewers begin to take less personal responsibility. Having too many people in the loop also makes each feedback round slow and expensive, to the extent that the author will hesitate to make updates and ask for re-reviews due to the costs involved. If the organization experiences setbacks due to mistakes slipping through the review process, do not respond by adding more reviewers, as it will just grind the contribution process to a halt. If there are quality concerns, invest in training for engineers, CI systems and perhaps an internal certification program for those making public upstream code submissions. A typical software engineer is more likely to seriously try to become proficient at their job and put effort into a one-off certification exam and then make multiple high-quality contributions, than it is for a low-skilled engineer to improve and even want to continue doing more upstream contributions if they are burdened by heavy review processes every time they try to submit an upstream contribution.

Don t expect upstream to accept all code contributions Sure, identifying the root cause of and fixing a tricky bug or writing a new feature requires significant effort. While an open source project will certainly appreciate the effort invested, it doesn t mean it will always welcome all contributions with open arms. Occasionally, the project won t agree that the code is correct or the feature is useful, and some contributions are bound to be rejected. You can minimize the chance of experiencing rejections by having a solid internal review process that includes assessing how the upstream community is likely to understand the proposal. Sometimes how things are communicated is more important than how they are coded. Polishing inline comments and git commit messages help ensure high-quality communication, along with a commitment to respond quickly to review feedback and conducting regular follow-ups until a contribution is finalized and accepted.

Start small to grow expertise and reputation In addition to keeping the open source contribution policy lean and nimble, it is also good to start practical contributions with small issues. Don t aim to contribute massive features until you have a track record of being able to make multiple small contributions. Keep in mind that not all open source projects are equal. Each has its own culture, written and unwritten rules, development process, documented requirements (which may be outdated) and more. Starting with a tiny contribution, even just a typo fix, is a good way to validate how code submissions, reviews and approvals work in a particular project. Once you have staff who have successfully landed smaller contributions, you can start planning larger proposals. The exact same proposal might be unsuccessful when proposed by a new person, and successful when proposed by a person who already has a reputation for prior high-quality work.

Embrace all and any publicity you get Some companies have concerns about their employees working in the open. Indeed, every email and code patch an employee submits, and all related discussions become public. This may initially sound scary, but is actually a potential source of good publicity. Employees need to be trained on how to conduct themselves publicly, and the discussions about code should contain only information strictly related to the code, without any references to actual production environments or other sensitive information. In the long run most employees contributing have a positive impact and the company should reap the benefits of positive publicity. If there are quality issues or employee judgment issues, hiding the activity or forcing employees to contribute with pseudonyms is not a proper solution. Instead, the problems should be addressed at the root, and bad behavior addressed rather than tolerated. When people are working publicly, there tends to also be some degree of additional pride involved, which motivates people to try their best. Contributions need to be public for the sponsoring corporation to later be able to claim copyright or licenses. Considering that thousands of companies participate in open source every day, the prevalence of bad publicity is quite low, and the benefits far exceed the risks.

Scratch your own itch When choosing what to contribute, select things that benefit your own company. This is not purely about being selfish - often people working on resolving a problem they suffer from are the same people with the best expertise of what the problem is and what kind of solution is optimal. Also, the issues that are most pressing to your company are more likely to be universally useful to solve than any random bug or feature request in the upstream project s issue tracker.

Remember there are many ways to help upstream While submitting code is often considered the primary way to contribute, please keep in mind there are also other highly impactful ways to contribute. Submitting high-quality bug reports will help developers quickly identify and prioritize issues to fix. Providing good research, benchmarks, statistics or feedback helps guide development and the project make better design decisions. Documentation, translations, organizing events and providing marketing support can help increase adoption and strengthen long-term viability for the project. In some of the largest open source projects there are already far more pending contributions than the core maintainers can process. Therefore, developers who contribute code should also get into the habit of contributing reviews. As Linus law states, given enough eyeballs, all bugs are shallow. Reviewing other contributors submissions will help improve quality, and also alleviate the pressure on core maintainers who are the only ones providing feedback. Reviewing code submitted by others is also a great learning opportunity for the reviewer. The reviewer does not need to be better than the submitter - any feedback is useful; merely posting review feedback is not the same thing as making an approval decision. Many projects are also happy to accept monetary support and sponsorships. Some offer specific perks in return. By human nature, the largest sponsors always get their voice heard in important decisions, as no open source project wants to take actions that scare away major financial contributors.

Starting is the hardest part Long-term success in open source comes from a positive feedback loop of an ever-increasing number of users and collaborators. As seen in the examples of countless corporations contributing open source, the benefits are concrete, and the process usually runs well after the initial ramp-up and organizational learning phase has passed. In open source ecosystems, contributing upstream should be as natural as paying vendors in any business. If you are using open source and not contributing at all, you likely have latent business risks without realizing it. You don t want to wake up one morning to learn that your top talent left because they were forbidden from participating in open source for the company s benefit, or that you were fined due to CRA violations and mismanagement in sharing security fixes with the correct parties. The faster you start with the process, the less likely those risks will materialize.

Next.

Previous.