Search Results: "ana"

28 August 2025

Samuel Henrique: Debian 13: My list of exciting new features
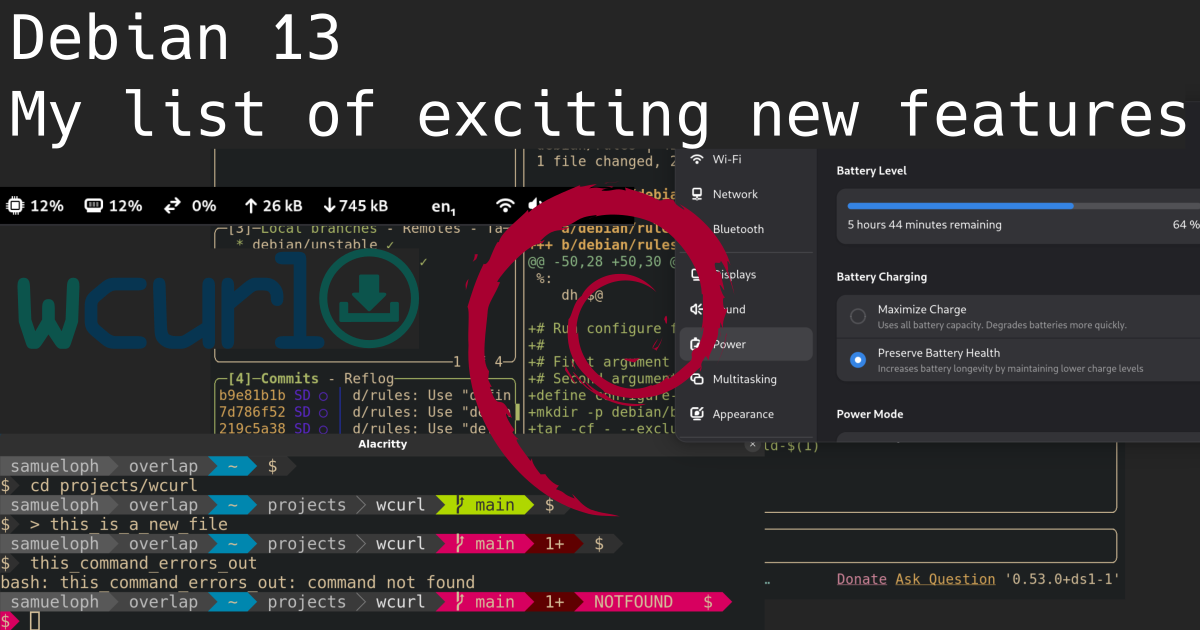
A bunch of screenshots overlaid on top of each other showing different tools: lazygit, gnome settings, gnome system monitor, powerline-go, and the wcurl logo, the text at the top says 'Debian 13: My list of exciting new features', and there's a Debian logo in the middle of image

Beyond Debian: Useful for other distros too Every two years Debian releases a new major version of its Stable series, meaning the differences between consecutive Debian Stable releases represent two years of new developments both in Debian as an organization and its native packages, but also in all other packages which are also shipped by other distributions (which are getting into this new Stable release). If you're not paying close attention to everything that's going on all the time in the Linux world, you miss a lot of the nice new features and tools. It's common for people to only realize there's a cool new trick available only years after it was first introduced. Given these considerations, the tips that I'm describing will eventually be available in whatever other distribution you use, be it because it's a Debian derivative or because it just got the same feature from the upstream project. I'm not going to list "passive" features (as good as they can be), the focus here is on new features that might change how you configure and use your machine, with a mix between productivity and performance.

Debian 13 - Trixie I have been a Debian Testing user for longer than 10 years now (and I recommend it for non-server users), so I'm not usually keeping track of all the cool features arriving in the new Stable releases because I'm continuously receiving them through the Debian Testing rolling release. Nonetheless, as a Debian Developer I'm in a good position to point out the ones I can remember. I would also like other Debian Developers to do the same as I'm sure I would learn something new. The Debian 13 release notes contain a "What's new" section , which lists the first two items here and a few other things, in other words, take my list as an addition to the release notes. Debian 13 was released on 2025-08-09, and these are nice things you shouldn't miss in the new release, with a bonus one not tied to the Debian 13 release.

1) wcurl wcurl logo Have you ever had to download a file from your terminal using curl and didn't remember the parameters needed? I did. Nowadays you can use wcurl; "a command line tool which lets you download URLs without having to remember any parameters." Simply call wcurl with one or more URLs as parameters and it will download all of them in parallel, performing retries, choosing the correct output file name, following redirects, and more. Try it out:
wcurl example.com
wcurl comes installed as part of the curl package on Debian 13 and in any other distribution you can imagine, starting with curl 8.14.0. I've written more about wcurl in its release announcement and I've done a lightning talk presentation in DebConf24, which is linked in the release announcement.

2) HTTP/3 support in curl Debian has become the first stable Linux distribution to ship curl with support for HTTP/3. I've written about this in July 2024, when we first enabled it. Note that we first switched the curl CLI to GnuTLS, but then ended up releasing the curl CLI linked with OpenSSL (as support arrived later). Debian was the first Linux distro to enable it in the default build of the curl package, but Gentoo enabled it a few weeks earlier in their non-default flavor of the package, kudos to them! HTTP/3 is not used by default by the curl CLI, you have to enable it with --http3 or --http3-only. Try it out:
curl --http3 https://www.example.org
curl --http3-only https://www.example.org

3) systemd soft-reboot Starting with systemd v254, there's a new soft-reboot option, it's an userspace-only reboot, much faster than a full reboot if you don't need to reboot the kernel. You can read the announcement from the systemd v254 GitHub release Try it out:
# This will reboot your machine!
systemctl soft-reboot

4) apt --update Are you tired of being required to run sudo apt update just before sudo apt upgrade or sudo apt install $PACKAGE? So am I! The new --update option lets you do both things in a single command:
sudo apt --update upgrade
sudo apt --update install $PACKAGE
I love this, but it's still not yet where it should be, fingers crossed for a simple apt upgrade to behave like other package managers by updating its cache as part of the task, maybe in Debian 14? Try it out:
sudo apt upgrade --update
# The order doesn't matter
sudo apt --update upgrade
This is especially handy for container usage, where you have to update the apt cache before installing anything, for example:
podman run debian:stable bin/bash -c 'apt install --update -y curl'

5) powerline-go powerline-go is a powerline-style prompt written in Golang, so it's much more performant than its Python alternative powerline. powerline-style prompts are quite useful to show things like the current status of the git repo in your working directory, exit code of the previous command, presence of jobs in the background, whether or not you're in an ssh session, and more. A screenshot of a terminal with powerline-go enabled, showing how the PS1 changes inside a git repository and when the last command fails Try it out:
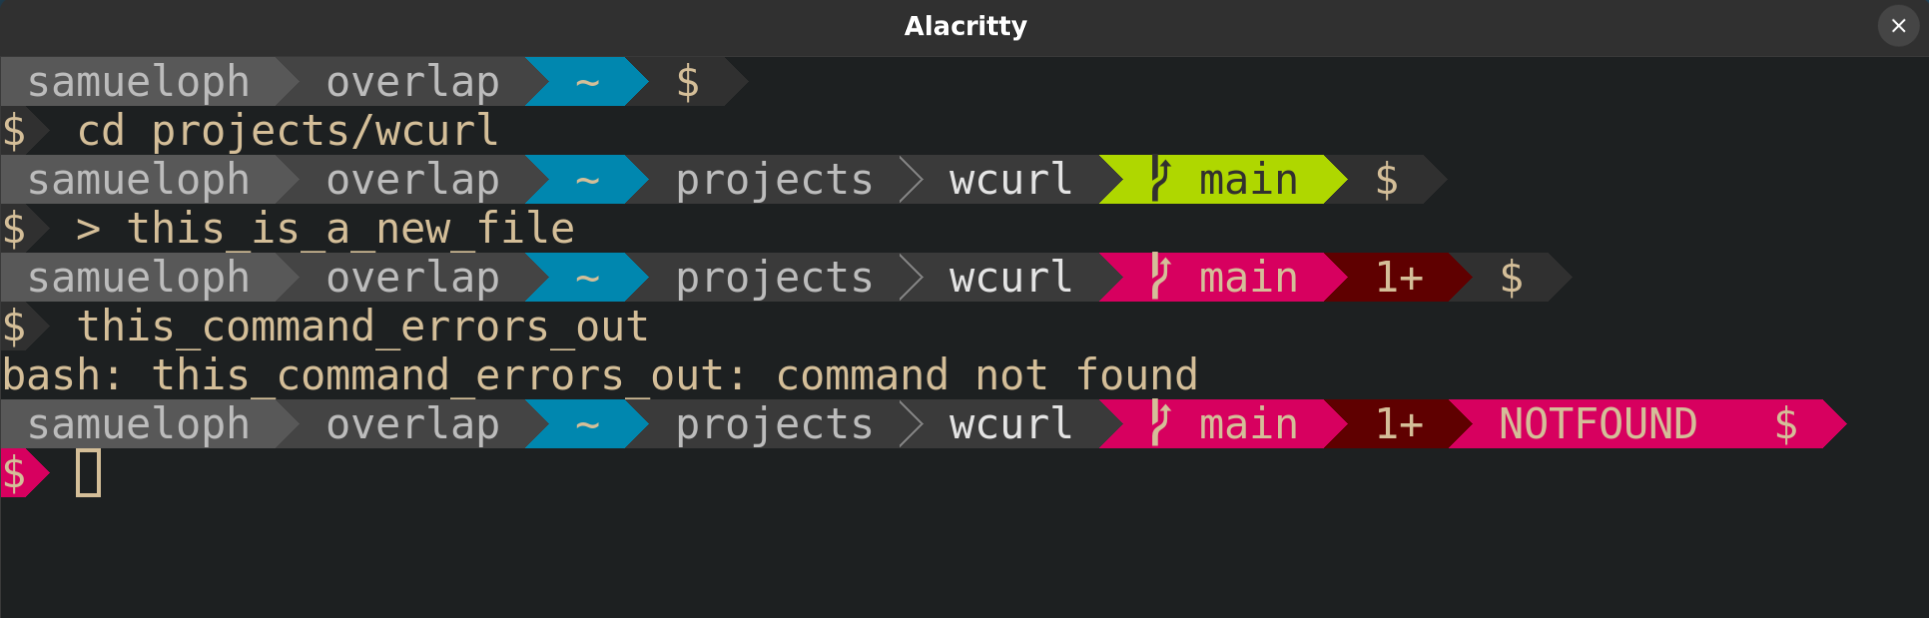
sudo apt install powerline-go
Then add this to your .bashrc:
function _update_ps1()  
    PS1="$(/usr/bin/powerline-go -error $? -jobs $(jobs -p   wc -l))"

    # Uncomment the following line to automatically clear errors after showing
    # them once. This not only clears the error for powerline-go, but also for
    # everything else you run in that shell. Don't enable this if you're not
    # sure this is what you want.

    #set "?"
 

if [ "$TERM" != "linux" ] && [ -f "/usr/bin/powerline-go" ]; then
    PROMPT_COMMAND="_update_ps1; $PROMPT_COMMAND"
fi
Or this to .zshrc:
function powerline_precmd()  
    PS1="$(/usr/bin/powerline-go -error $? -jobs $ $ (%):%j :-0 )"

    # Uncomment the following line to automatically clear errors after showing
    # them once. This not only clears the error for powerline-go, but also for
    # everything else you run in that shell. Don't enable this if you're not
    # sure this is what you want.

    #set "?"
 
If you'd like to have your prompt start in a newline, like I have in the screenshot above, you just need to set -newline in the powerline-go invocation in your .bashrc/.zshrc.

6) Gnome System Monitor Extension Tips number 6 and 7 are for Gnome users. Gnome is now shipping a system monitor extension which lets you get a glance of the current load of your machine from the top bar. Screenshot of the top bar of Gnome with the system monitor extension enabled, showing the load of: CPU, memory, network and disk I've found this quite useful for machines where I'm required to install third-party monitoring software that tends to randomly consume more resources than it should. If I feel like my machine is struggling, I can quickly glance at its load to verify if it's getting overloaded by some process. The extension is not as complete as system-monitor-next, not showing temperatures or histograms, but at least it's officially part of Gnome, easy to install and supported by them. Try it out:

sudo apt install gnome-system-monitor gnome-shell-extension-manager
And then enable the extension from the "Extension Manager" application.

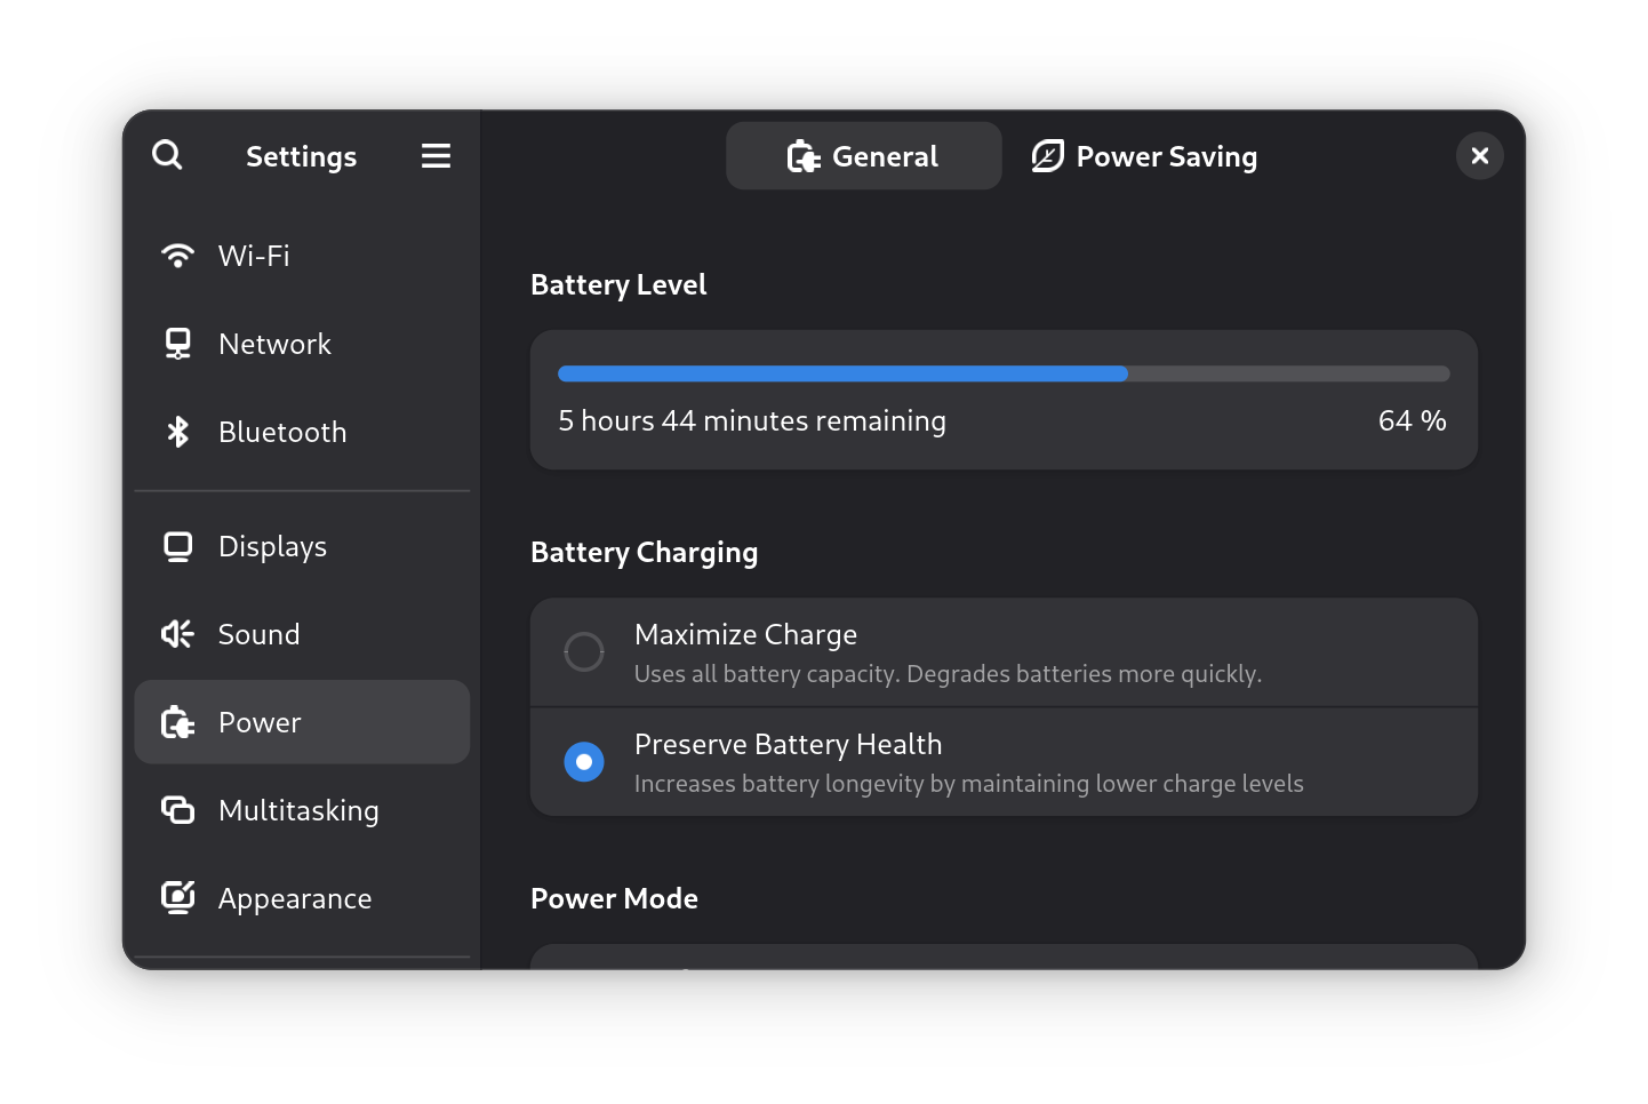
7) Gnome setting for battery charging profile After having to learn more about batteries in order to get into FPV drones, I've come to have a bigger appreciation for solutions that minimize the inevitable loss of capacity that accrues over time. There's now a "Battery Charging" setting (under the "Power") section which lets you choose between two different profiles: "Maximize Charge" and "Preserve Battery Health". A screenshot of the Gnome settings for Power showing the options for Battery Charging On supported laptops, this setting is an easy way to set thresholds for when charging should start and stop, just like you could do it with the tlp package, but now from the Gnome settings. To increase the longevity of my laptop battery, I always keep it at "Preserve Battery Health" unless I'm traveling. What I would like to see next is support for choosing different "Power Modes" based on whether the laptop is plugged-in, and based on the battery charge percentage. There's a GNOME issue tracking this feature, but there's some pushback on whether this is the right thing to expose to users. In the meantime, there are some workarounds mentioned in that issue which people who really want this feature can follow. If you would like to learn more about batteries; Battery University is a great starting point, besides getting into FPV drones and being forced to handle batteries without a Battery Management System (BMS). And if by any chance this sparks your interest in FPV drones, Joshua Bardwell's YouTube channel is a great resource: @JoshuaBardwell.
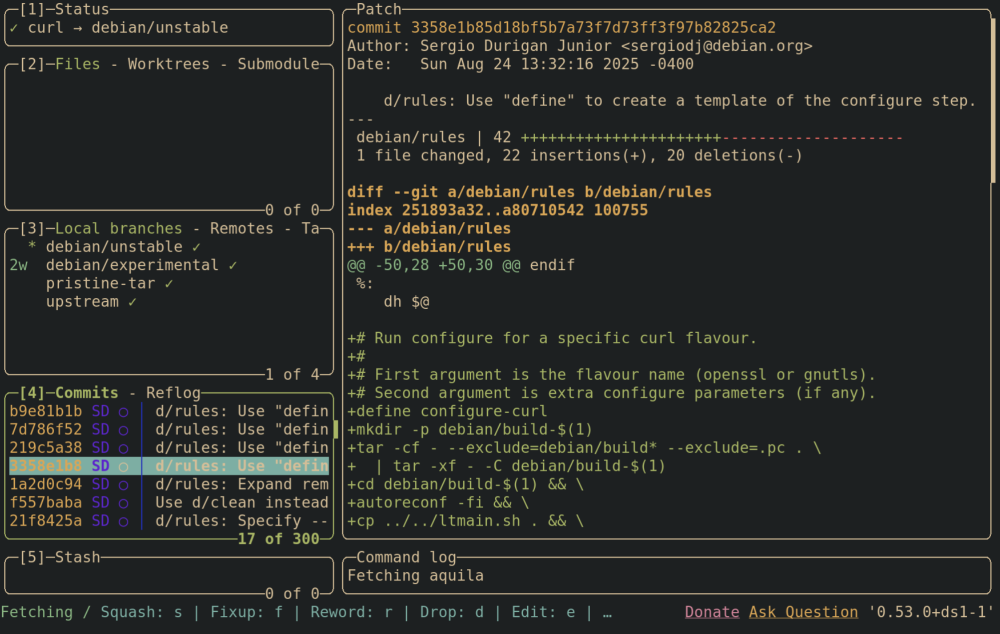
8) Lazygit Emacs users are already familiar with the legendary magit; a terminal-based UI for git. Lazygit is an alternative for non-emacs users, you can integrate it with neovim or just use it directly. I'm still playing with lazygit and haven't integrated it into my workflows, but so far it has been a pleasant experience. Screenshot of lazygit from the Debian curl repository, showing a selected commit and its diff, besides the other things from the lazygit UI You should check out the demos from the lazygit GitHub page. Try it out:
sudo apt install lazygit
And then call lazygit from within a git repository.

9) neovim neovim has been shipped in Debian since 2016, but upstream has been doing a lot of work to improve the experience out-of-the-box in the last couple of years. If you're a neovim poweruser, you're likely not installing it from the official repositories, but for those that are, Debian 13 comes with version 0.10.4, which brings the following improvements compared to the version in Debian 12:
  • Treesitter support for C, Lua, Markdown, with the possibility of adding any other languages as needed;
  • Better spellchecking due to treesitter integration (spellsitter);
  • Mouse support enabled by default;
  • Commenting support out-of-the-box; Check :h commenting for details, but the tl;dr is that you can use gcc to comment the current line and gc to comment the current selection.
  • OSC52 support. Especially handy for those using neovim over an ssh connection, this protocol lets you copy something from within the neovim process into the clipboard of the machine you're using to connect through ssh. In other words, you can copy from neovim running in a host over ssh and paste it in the "outside" machine.

10) [Bonus] Running old Debian releases The bonus tip is not specific to the Debian 13 release, but something I've recently learned in the #debian-devel IRC channel. Did you know there are usable container images for all past Debian releases? I'm not talking "past" as in "some of the older releases", I'm talking past as in "literally every Debian release, including the very first one". Tianon Gravi "tianon" is the Debian Developer responsible for making this happen, kudos to him! There's a small gotcha that the releases Buzz (1.1) and Rex (1.2) require a 32-bit host, otherwise you will get the error Out of virtual memory!, but starting with Bo (1.3) all should work in amd64/arm64. Try it out:
sudo apt install podman

podman run -it docker.io/debian/eol:bo
Don't be surprised when noticing that apt/apt-get is not available inside the container, that's because apt first appeared in Debian Slink (2.1).
Valhalla's Things: 1840s Underwear

Posted on August 28, 2025
Tags: madeof:atoms, craft:sewing, FreeSoftWear
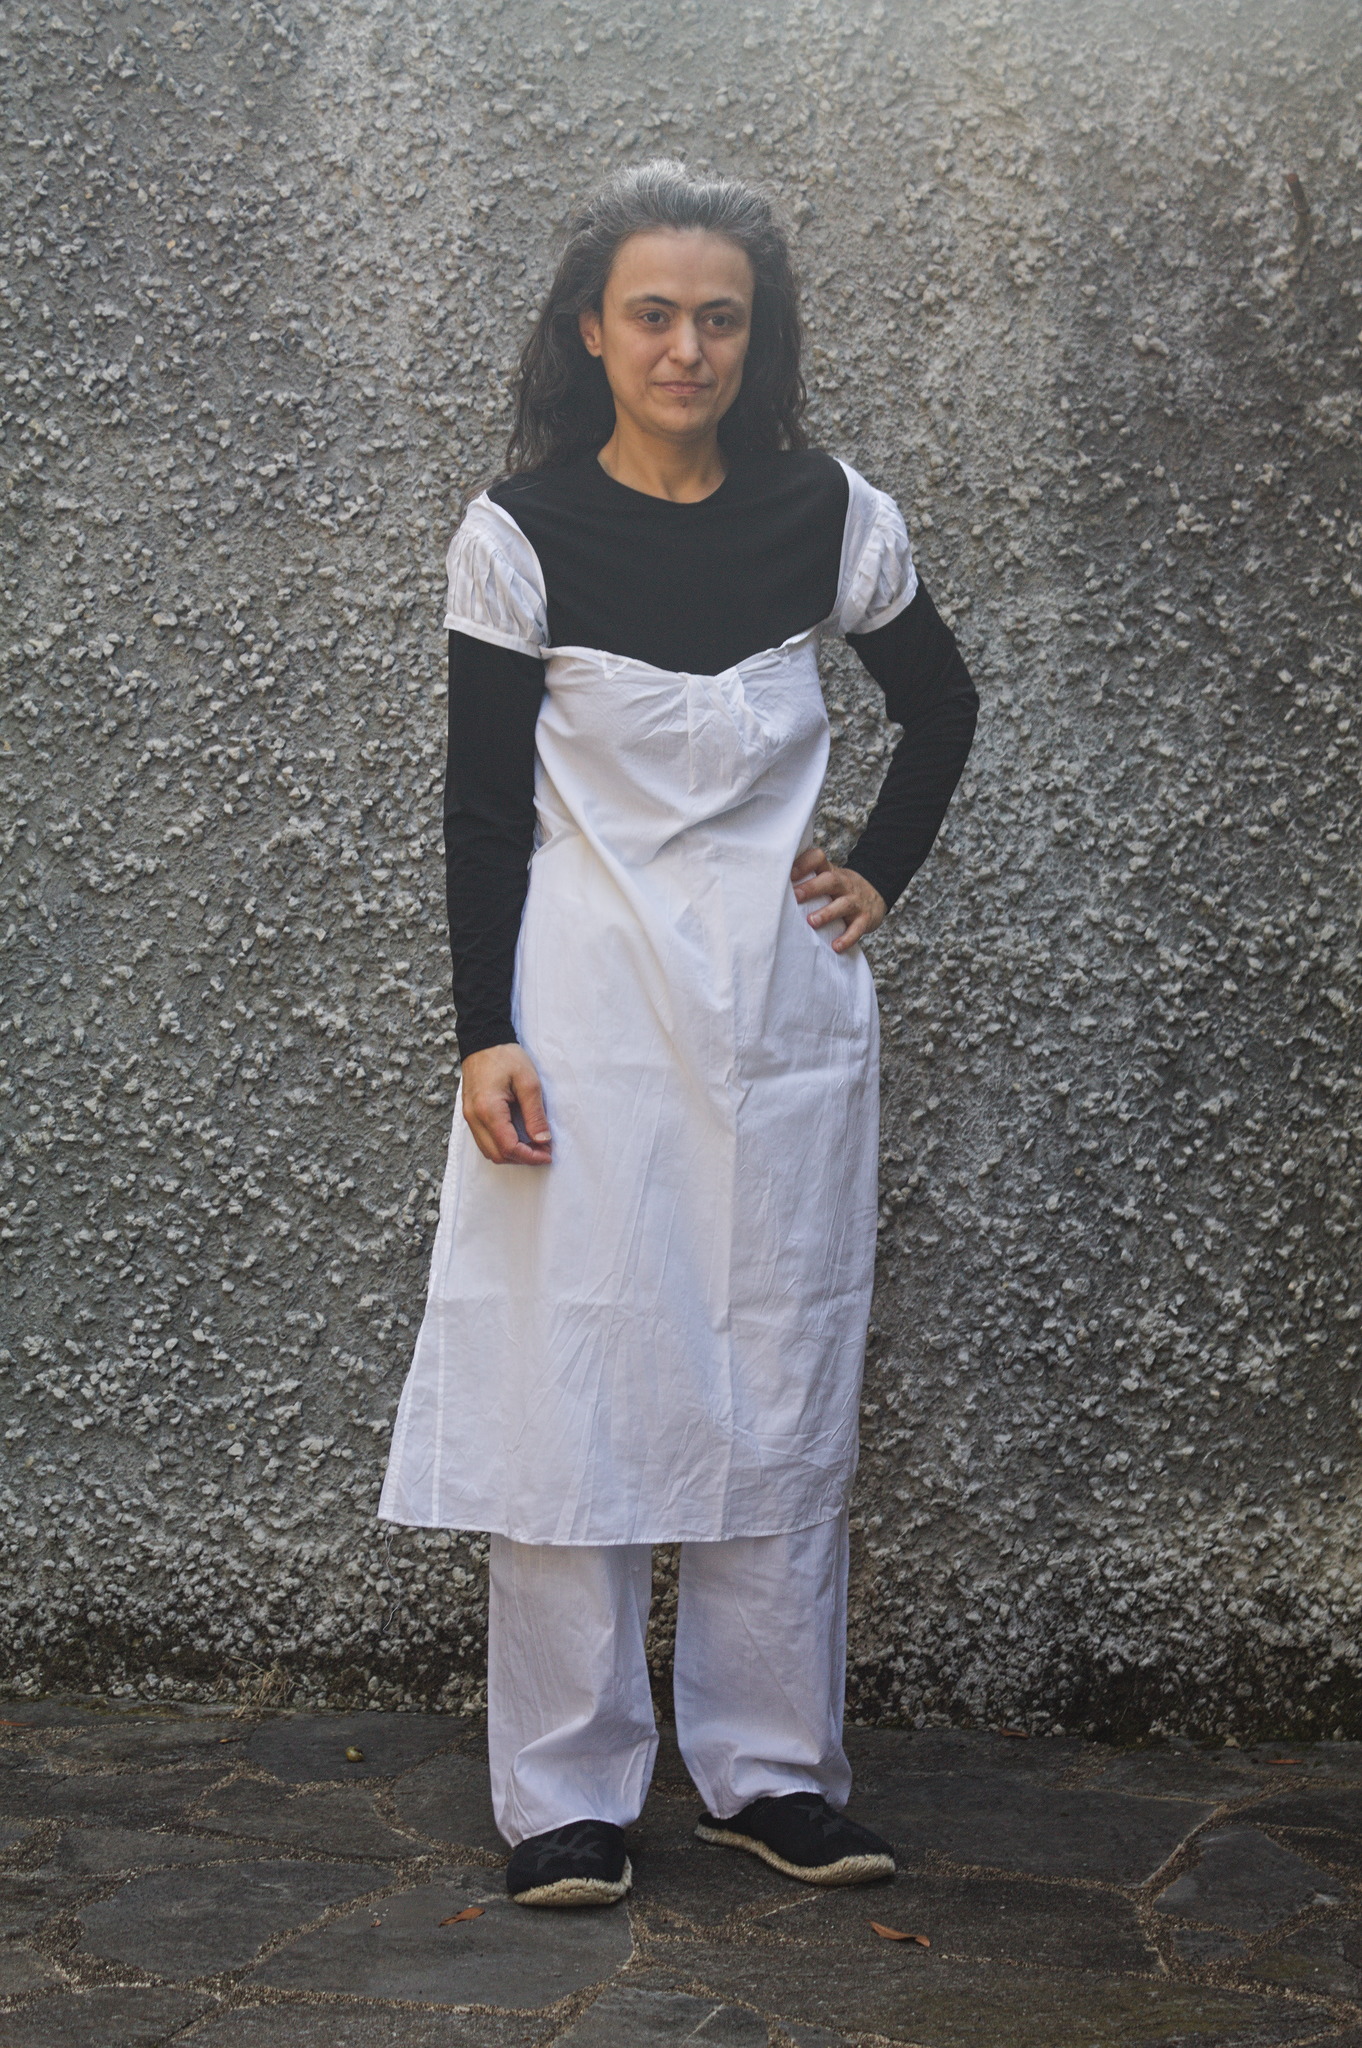
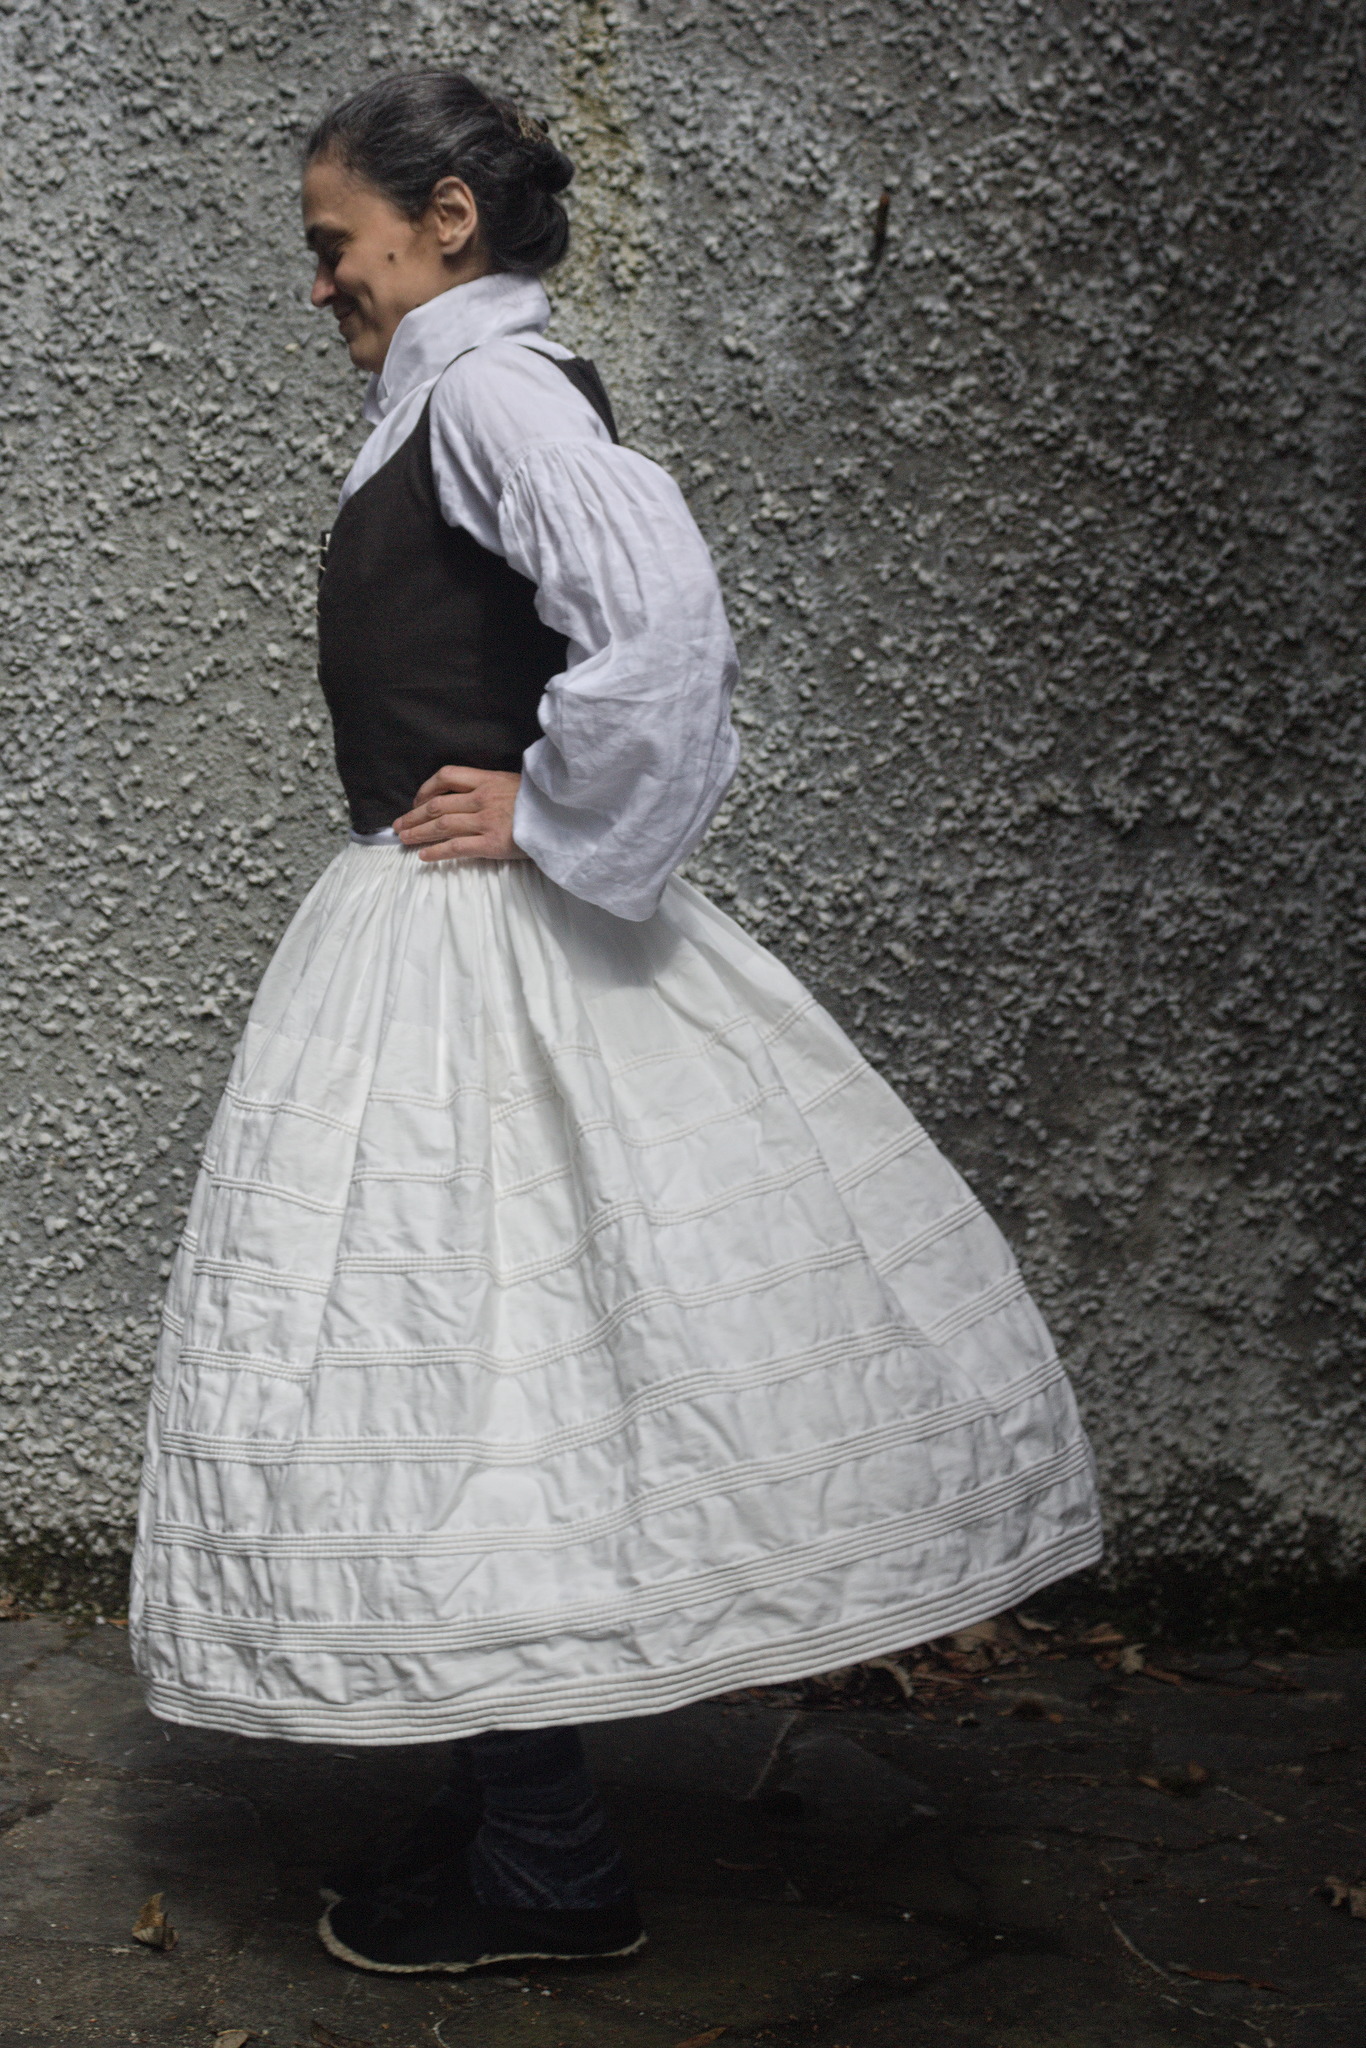
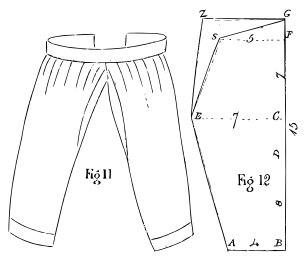
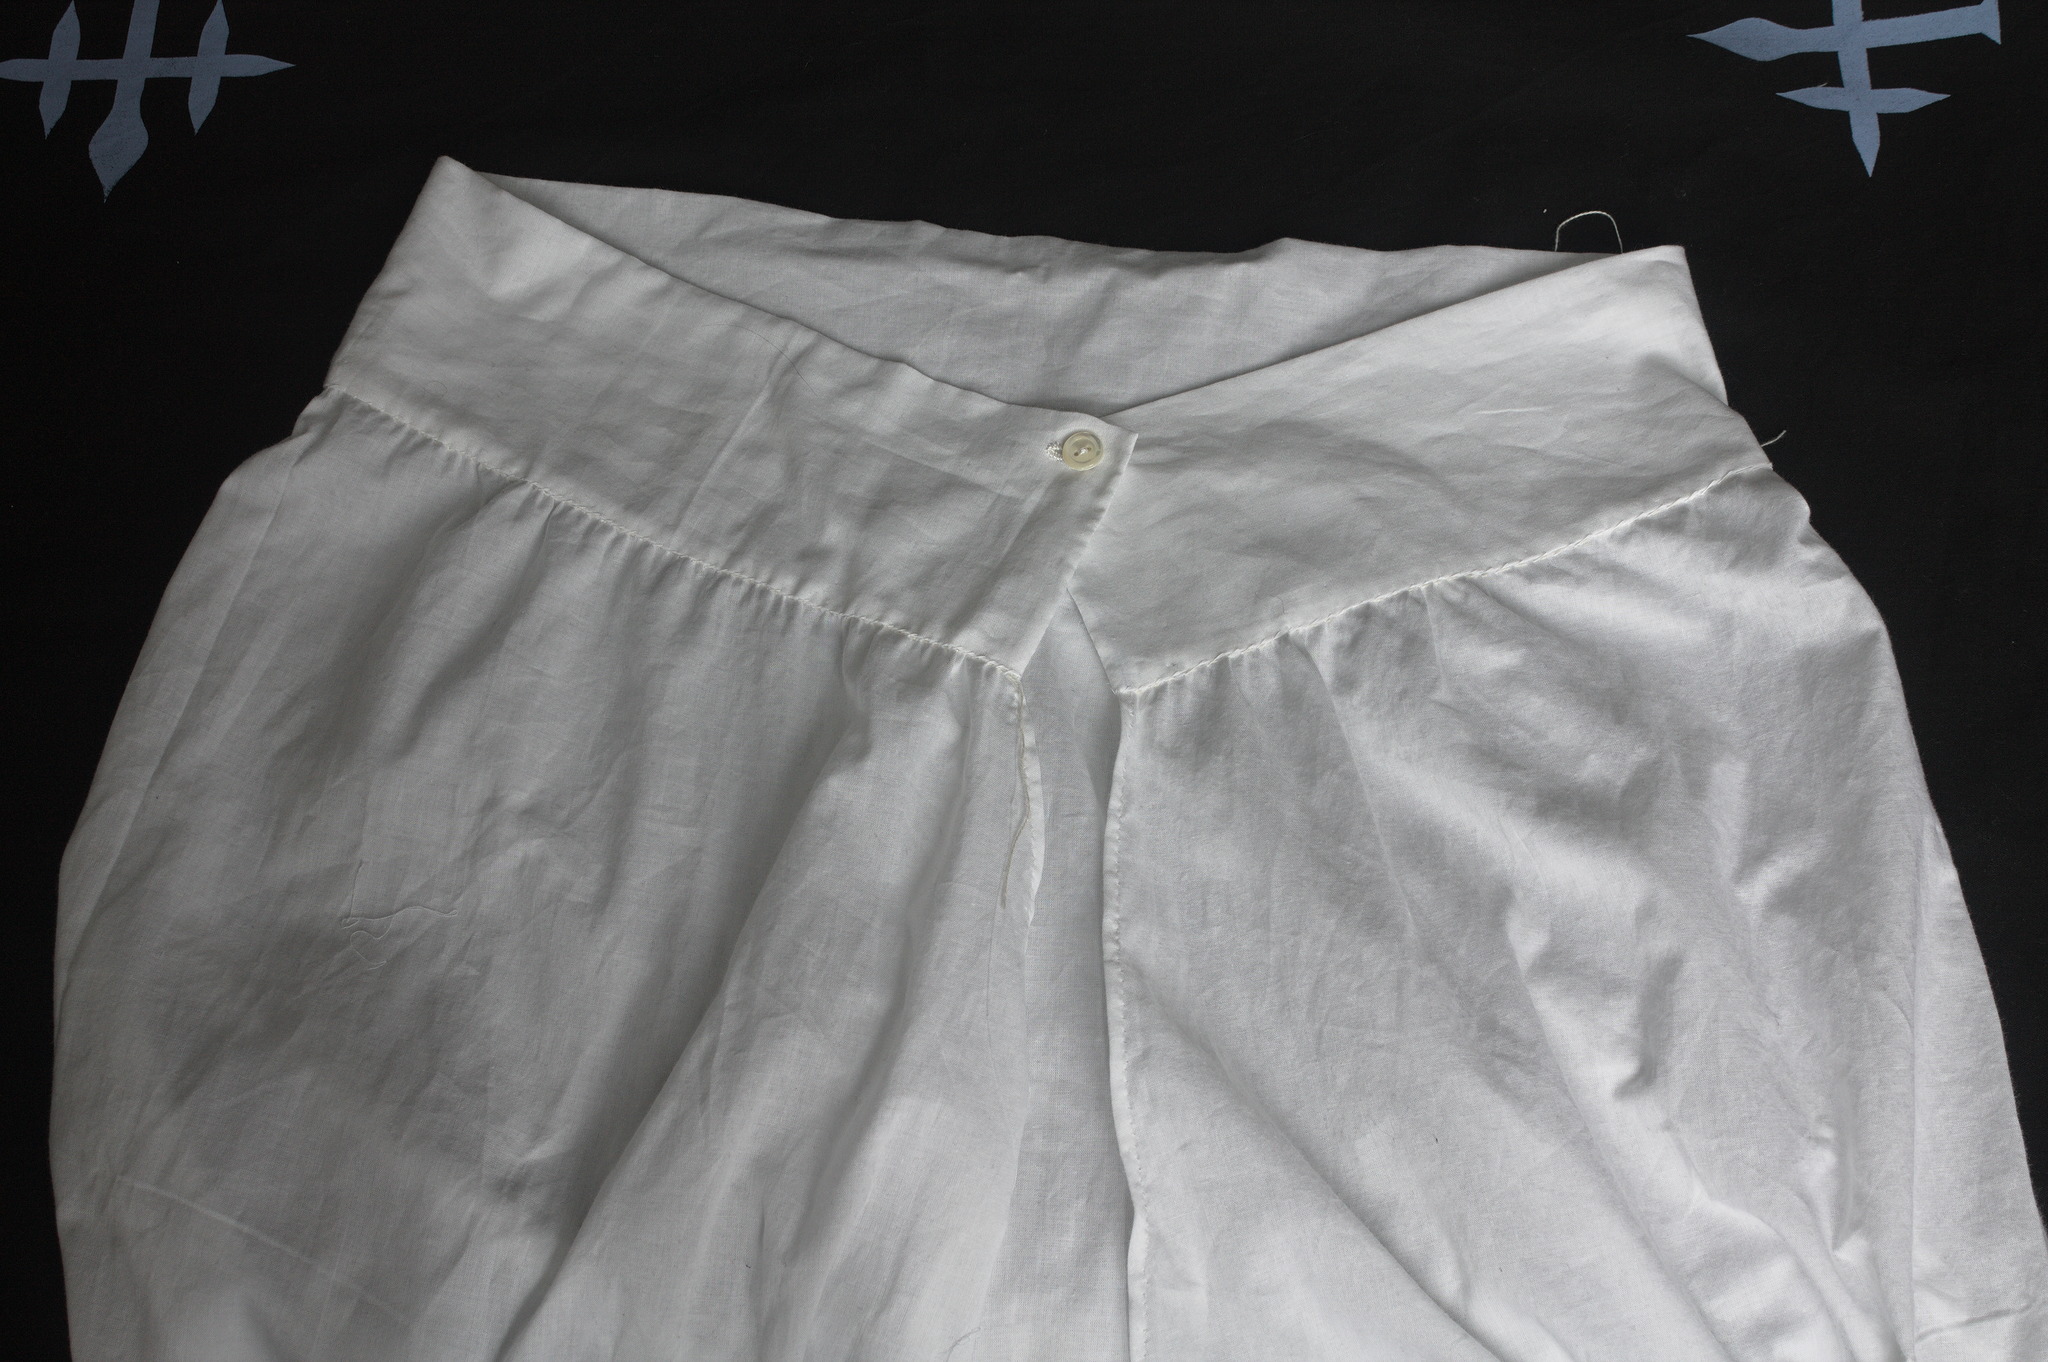
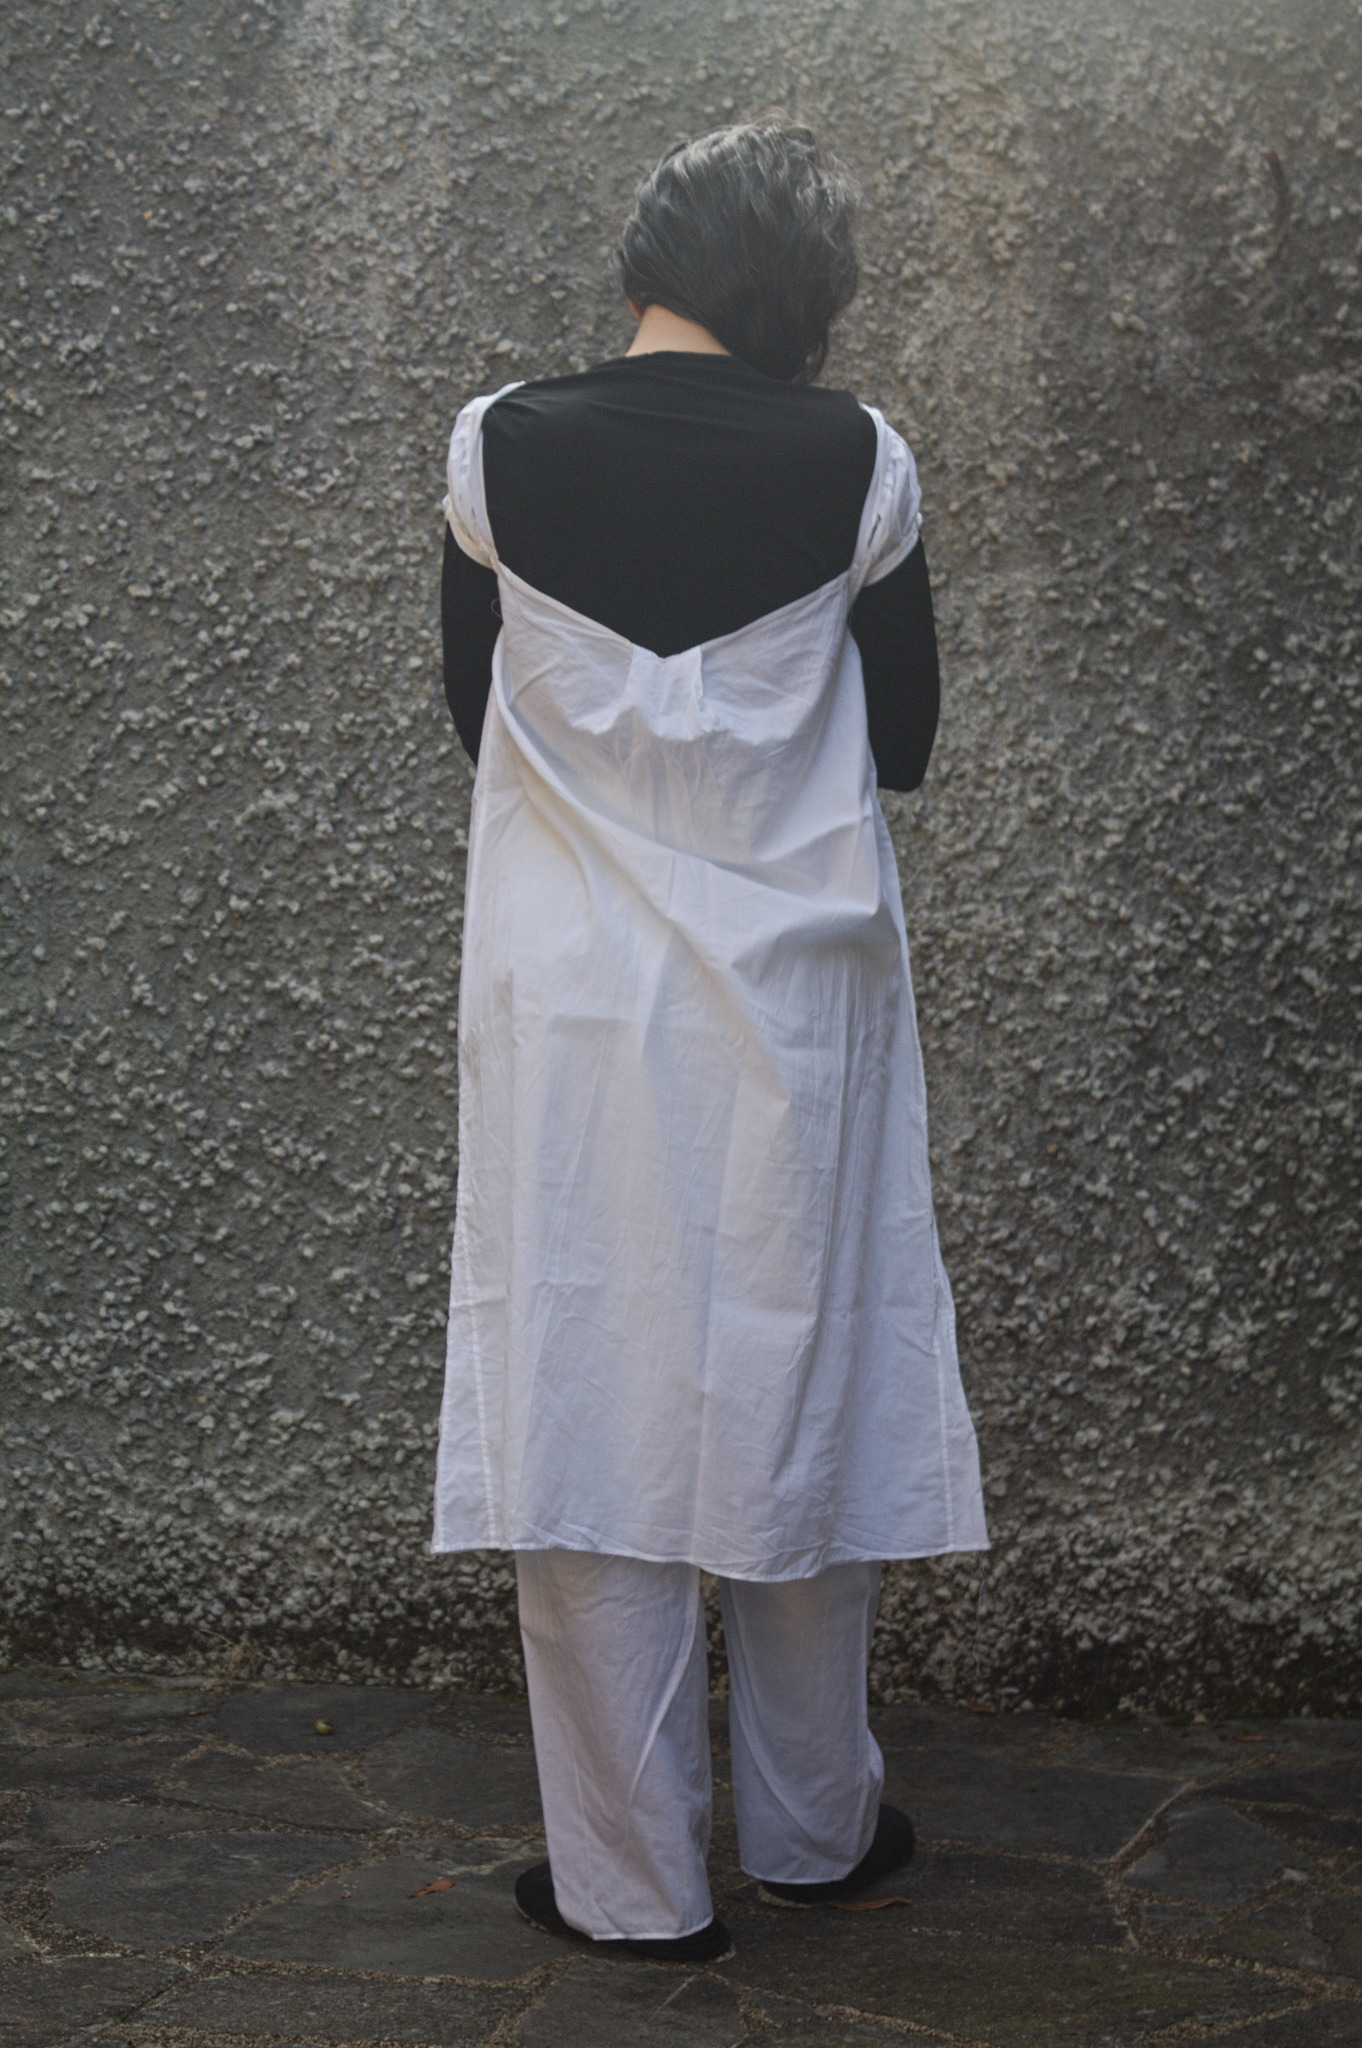
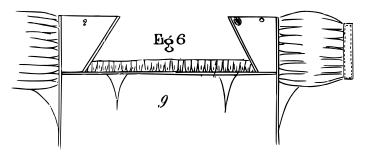
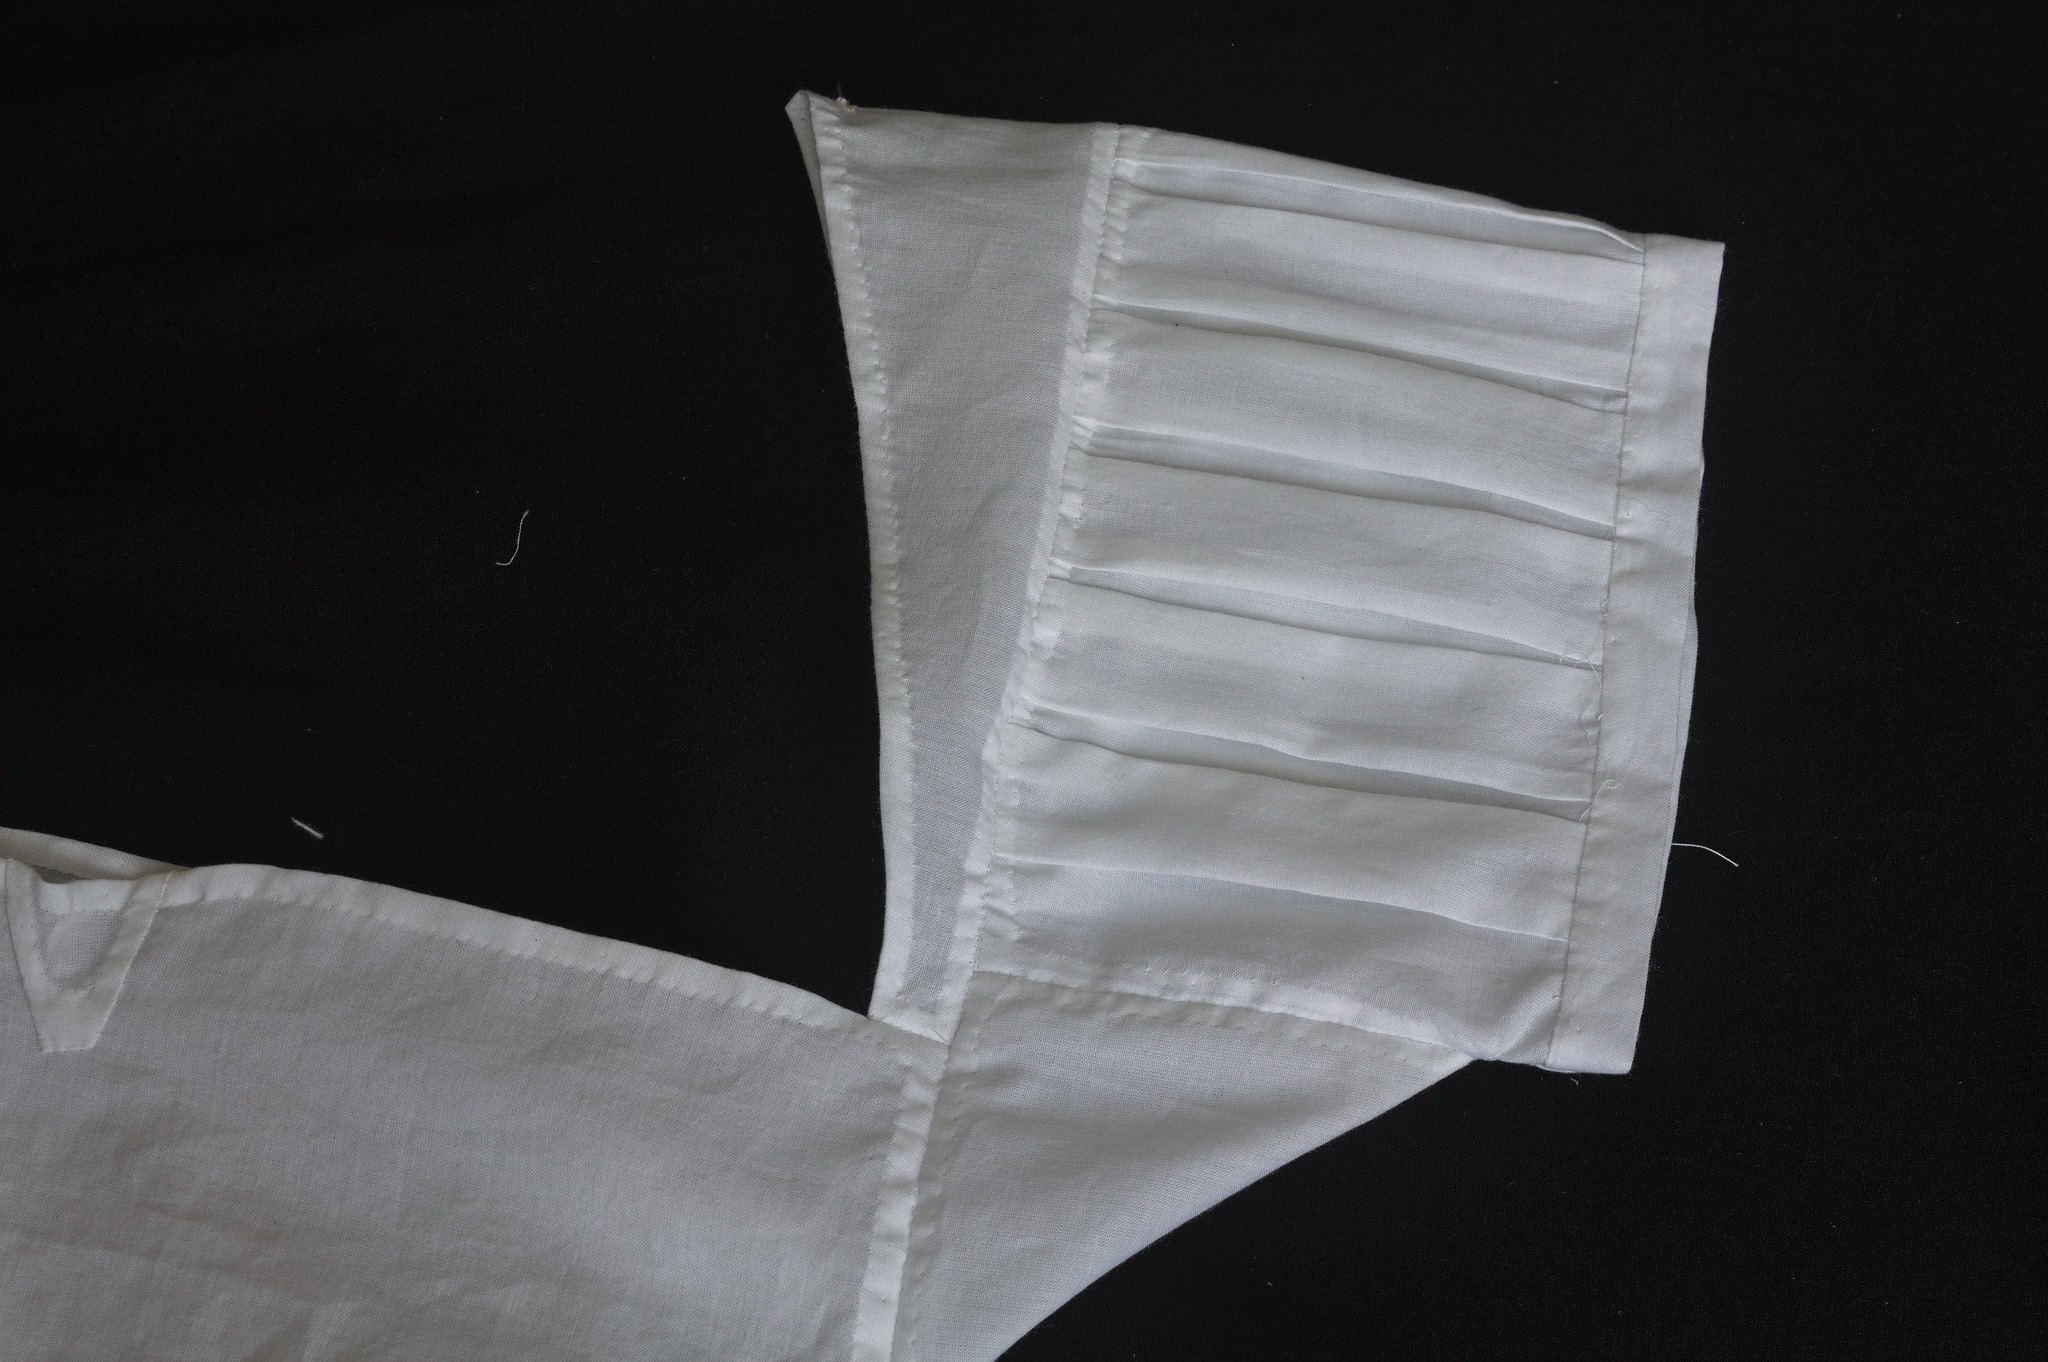
A woman wearing a knee-length shift with very short pleated sleeves and drawers that are a bit longer than needed to be ankle-length. The shift is too wide at the top, had to have a pleat taken in the center front, but the sleeves are still falling down. She is also wearing a black long sleeved t-shirt and leggings under said underwear, for decency. A bit more than a year ago, I had been thinking about making myself a cartridge pleated skirt. For a number of reasons, one of which is the historybounding potential, I ve been thinking pre-crinoline, so somewhere around the 1840s, and that s a completely new era for me, which means: new underwear. Also, the 1840s are pre-sewing machine, and I was already in a position where I had more chances to handsew than to machine sew, so I decided to embrace the slowness and sew 100% by hand, not even using the machine for straight seams. A woman turning fast enough that her petticoat extends a considerable distance from the body. The petticoat is white with a pattern of cording from the hem to just below hip level, with a decreasing number of rows of cording going up. If I remember correctly, I started with the corded petticoat, looking around the internet for instructions, and then designing my own based on the practicality of using modern wide fabric from my stash (and specifically some DITTE from costumers favourite source of dirty cheap cotton IKEA). Around the same time I had also acquired a sashiko kit, and I used the Japanese technique for sewing running stitches pushing the needle with a thimble that covers the base of the middle finger, and I can confirm that for this kind of things it s great! I ve since worn the petticoat a few times for casual / historyBounding / folkwearBounding reasons, during the summer, and I can confirm it s comfortable to use; I guess that during the winter it could be nice to add a flannel layer below it. The technical drawing and pattern for drawers from the book: each leg is cut out of a rectangle of fabric folded along the length, the leg is tapered equally, while the front is tapered more than the back, and comes to a point below the top of the original rectangle. Then I proceeded with the base layers: I had been browsing through The workwoman's guide and that provided plenty of examples, and I selected the basic ankle-length drawers from page 53 and the alternative shift on page 47. As for fabric, I had (and still have) a significant lack of underwear linen in my stash, but I had plenty of cotton voile that I had not used in a while: not very historically accurate for plain underwear, but quite suitable for a wearable mockup. Working with a 1830s source had an interesting aspect: other of the usual, mildly annoying, imperial units, it also used a lot a few obsolete units, especially nails, that my qalc, my usual calculator and converter, doesn t support. Not a big deal, because GNU units came to the rescue, and that one knows a lot of obscure and niche units, and it s quite easy to add those that are missing1 Working on this project also made me freshly aware of something I had already noticed: converting instructions for machine sewing garments into instructions for hand sewing them is usually straightforward, but the reverse is not always true. Starting from machine stitching, you can usually convert straight stitches into backstitches (or running backstitches), zigzag and overlocking into overcasting and get good results. In some cases you may want to use specialist hand stitches that don t really have a machine equivalent, such as buttonhole stitches instead of simply overcasting the buttonhole, but that s it. Starting from hand stitching, instead, there are a number of techniques that could be converted to machine stitching, but involve a lot of visible topstitching that wasn t there in the original instructions, or at times are almost impossible to do by machine, if they involve whipstitching together finished panels on seams that are subject to strong tension. Anyway, halfway through working with the petticoat I cut both the petticoat and the drawers at the same time, for efficiency in fabric use, and then started sewing the drawers. the top third or so of the drawers, showing a deep waistband that is closed with just one button at the top, and the front opening with finished edges that continue through the whole crotch, with just the overlap of fabric to provide coverage. The book only provided measurements for one size (moderate), and my fabric was a bit too narrow to make them that size (not that I have any idea what hip circumference a person of moderate size was supposed to have), so the result is just wide enough to be comfortably worn, but I think that when I ll make another pair I ll try to make them a bit wider. On the other hand they are a bit too long, but I think that I ll fix it by adding a tuck or two. Not a big deal, anyway. The same woman as in the opening image from the back, the shift droops significantly in the center back, and the shoulder straps have fallen down on the top of the arms. The shift gave me a bit more issues: I used the recommended gusset size, and ended up with a shift that was way too wide at the top, so I had to take a box pleat in the center front and back, which changed the look and wear of the garment. I have adjusted the instructions to make gussets wider, and in the future I ll make another shift following those. Even with the pleat, the narrow shoulder straps are set quite far to the sides, and they tend to droop, and I suspect that this is to be expected from the way this garment is made. The fact that there are buttonholes on the shoulder straps to attach to the corset straps and prevent the issue is probably a hint that this behaviour was to be expected. The technical drawing of the shift from the book, showing a the top of the body, two trapezoidal shoulder straps, the pleated sleeves and a ruffle on the front edge. I ve also updated the instructions so that they shoulder straps are a bit wider, to look more like the ones in the drawing from the book. Making a corset suitable for the time period is something that I will probably do, but not in the immediate future, but even just wearing the shift under a later midbust corset with no shoulder strap helps. I m also not sure what the point of the bosom gores is, as they don t really give more room to the bust where it s needed, but to the high bust where it s counterproductive. I also couldn t find images of original examples made from this pattern to see if they were actually used, so in my next make I may just skip them. Sleeve detail, showing box pleats that are about 2 cm wide and a few mm distance from each other all along the circumference, neatly sewn into the shoulder strap on one side and the band at the other side. On the other hand, I m really happy with how cute the short sleeves look, and if2 I ll ever make the other cut of shift from the same book, with the front flaps, I ll definitely use these pleated sleeves rather than the straight ones that were also used at the time. As usual, all of the patterns have been published on my website under a Free license:
  1. My ~/.units file currently contains definitions for beardseconds, bananas and the more conventional Nm and NeL (linear mass density of fibres).
  2. yeah, right. when.

27 August 2025

Matthew Palmer: StrongBox: Simple, Safe Data Encryption for Rust

Some time ago, I wanted to encrypt a bunch of data in an application I was writing in Rust, mostly to be stored in a database, but also session cookies and sensitive configuration variables. Since Rust is widely known as a secure-yet-high-performance programming language, I was expecting that there would be a widely-used crate that gave me a secure, high-level interface to strong, safe cryptography. Imagine my surprise when I discovered that just didn t seem to exist. Don t get me wrong: Rust is replete with fast, secure, battle-tested cryptographic primitives. The RustCrypto group provides all manner of robust, widely-used crates for all manner of cryptography-related purposes. They re the essential building blocks for practical cryptosystems, but using them directly in an application is somewhat akin to building a car from individual atoms of iron and carbon. So I wrote my own high-level data encryption library, called it StrongBox, and have been happily encrypting and decrypting data ever since.

Cryptography So Simple Even I Can t Get It Wrong The core of StrongBox is the StrongBox trait, which has only two methods: encrypt and decrypt, each of which takes just two arguments. The first argument is the plaintext (for encrypt) or the ciphertext (for decrypt) to work on. The second argument is the encryption context, for use as Authenticated Additional Data, an important part of many uses of encryption. There s essentially no configuration or parameters to get wrong. You can t choose the encryption algorithm, or block cipher mode, and you don t have to worry about generating a secure nonce. You create a StrongBox with a key, and then you call encrypt and decrypt. That s it.

Practical Cryptographic Affordances Ok, ok that s not quite it. Because StrongBox is even easier to use than what I ve described, thanks to the companion crate, StructBox. When I started using StrongBox in the wild , it quickly became clear that what I almost always wanted to encrypt in my application wasn t some ethereal plaintext . I wanted to encrypt things, specifically structs (and enums). So, through the magic of Rust derive macros, I built StructBox, which provides encrypt and decrypt operations on any Serde-able type. Given that using Serde encoders can be a bit fiddly to use, it s virtually easier to get an encrypted, serialized struct than it is to get a plaintext serialized struct.

Key Problems in Cryptography The thing about cryptography is that it largely turns all data security problems into key management problems. All the fancy cryptographic wonkery is for naught if you don t manage the encryption keys well. So, most of the fancy business in StrongBox isn t the encryption and decryption, but instead solving problems around key management.

Different Keys for Different Purposes Using the same key for all of your cryptographic needs is generally considered a really bad idea. It opens up all manner of risks, that are easily avoided if you use different keys for different things. However, having to maintain a big pile of different keys is a nightmare, so nobody s going to do that. Enter: key derivation. Create one safe, secure root key, and then use a key derivation function to spawn as many other keys as you need. Different keys for each database column, another one to encrypt cookies, and so on. StrongBox supports this through the StemStrongBox type. You ll typically start off by creating a StemStrongBox with the root key, and then derive whatever other StrongBoxes you need, for encrypting and decrypting different kinds of data.

You Spin Me Round Sometimes, keys need to be rotated. Whether that s because you actually know (or even have reason to suspect) someone has gotten the key, or just because you re being appropriately paranoid, sometimes key rotation has to happen. As someone who has had to rotate keys in situations where such an eventuality was not planned for, I can say with some degree of authority: it absolutely sucks to have to do an emergency key rotation in a system that isn t built to make that easy. That s why StrongBox natively supports key rotation. Every StrongBox takes one encryption key, and an arbitrary number of decryption keys, and will automatically use the correct key to decrypt ciphertexts.

Will You Still Decrypt Me, Tomorrow? In addition to manual key rotation, StrongBox also supports time-based key rotation with the RotatingStrongBox type. This comes in handy when you re encrypting a lot of ephemeral data, like cookies (or server-side session data). It provides a way to automatically expire old data, and prevents attacks that become practical when large amounts of data are encrypted using a single key.

Invasion of the Invisible Salamanders! I mostly mention this just because I love the name, but there is a kind of attack possible in common AEAD modes called the invisible salamanders attack. StrongBox implements mitigations against this, by committing to the key being used so that an attacker can t forge a ciphertext that decrypts validly to different plaintexts when using different keys. This is why I love cryptography: everything sounds like absolute goddamn magic.

Call Me Crazy, Support Me Maybe? If you re coding in Rust (which you probably should be), encrypting your stored data (which you definitely should be), and StrongBox makes your life easier (which it really will), you can show your appreciation for my work by contributing to my open source code-fund. Simply by shouting me a refreshing beverage, you ll be helping me out, and helping to grow the software commons. Alternately, if you re looking for someone to Speak Rust to Computers on a professional basis, I m available for contracts or full-time remote positions.

25 August 2025

Gunnar Wolf: The comedy of computation, or, how I learned to stop worrying and love obsolescence

This post is a review for Computing Reviews for The comedy of computation, or, how I learned to stop worrying and love obsolescence , a book published in Stanford University Press
The Comedy of Computation is not an easy book to review. It is a much enjoyable book that analyzes several examples of how being computational has been approached across literary genres in the last century how authors of stories, novels, theatrical plays and movies, focusing on comedic genres, have understood the role of the computer in defining human relations, reactions and even self-image. Mangrum structures his work in six thematic chapters, where he presents different angles on human society: How have racial stereotypes advanced in human imagination and perception about a future where we interact with mechanical or computational partners (from mechanical tools performing jobs that were identified with racial profiles to intelligent robots that threaten to control society); the genericity of computers and people can be seen as generic, interchangeable characters, often fueled by the tendency people exhibit to confer anthropomorphic qualities to inanimate objects; people s desire to be seen as truly authentic , regardless of what it ultimately means; romantic involvement and romance-led stories (with the computer seen as a facilitator for human-to-human romances, distractor away from them, or being itself a part of the couple); and the absurdity in antropomorphization, in comparing fundamentally different aspects such as intelligence and speed at solving mathematical operations, as well as the absurdity presented blatantly as such by several techno-utopian visions. But presenting this as a linear set of concepts that are presented does not do justice to the book. Throughout the sections of each chapter, a different work serves as the axis Novels and stories, Hollywood movies, Broadway plays, some covers for the Time magazine, a couple of presenting the would-be future, even a romantic comedy entirely written by bots . And for each of them, Benjamin Mangrum presents a very thorough analysis, drawing relations and comparing with contemporary works, but also with Shakespeare, classical Greek myths, and a very long etc tera. This book is hard to review because of the depth of work the author did: Reading it repeatedly made me look for other works, or at least longer references for them. Still, despite being a work with such erudition, Mangrum s text is easy and pleasant to read, without feeling heavy or written in an overly academic style. I very much enjoyed reading this book. It is certainly not a technical book about computers and society in any way; it is an exploration of human creativity and our understanding of the aspects the author has found as central to understanding the impact of computing on humankind. However, there is one point I must mention before closing: I believe the editorial decision to present the work as a running text, with all the material conceptualized as footnotes presented as a separate, over 50 page long final chapter, detracts from the final result. Personally, I enjoy reading the footnotes because they reveal the author s thought processes, even if they stray from the central line of thought. Even more, given my review copy was a PDF, I could not even keep said chapter open with one finger, bouncing back and forth. For all purposes, I missed out on the notes; now that I finished reading and stumbled upon that chapter, I know I missed an important part of the enjoyment.

22 August 2025

Matthias Geiger: Enforcing darkmode for QT programs under a non-QT based environment

I use sway as window manager on my main machine. As I prefer dark mode, I looked for a way to enable dark mode everywhere. For GTK-based this is fairly straightforward: Just install whatever theme you prefer, and apply it. However, QT-based applications on a non-QT based desktop will look

20 August 2025

Antoine Beaupr : Encrypting a Debian install with UKI

I originally setup a machine without any full disk encryption, then somehow regretted it quickly after. My original reasoning was that this was a "play" machine so I wanted as few restrictions on accessing the machine as possible, which meant removing passwords, mostly. I actually ended up having a user password, but disabled the lock screen. Then I started using the device to manage my photo collection, and suddenly there was a lot of "confidential" information on the device that I didn't want to store in clear text anymore.

Pre-requisites So, how does one convert an existing install from plain text to full disk encryption? One way is to backup to an external drive, re-partition everything and copy things back, but that's slow and boring. Besides, cryptsetup has a cryptsetup-reencrypt command, surely we can do this in place? Having not set aside enough room for /boot, I briefly considered a "encrypted /boot" configuration and conversion (e.g. with this guide) but remembered grub's support for this is flaky, at best, so I figured I would try something else. Here, I'm going to guide you through how I first converted from grub to systemd-boot then to UKI kernel, then re-encrypt my main partition. Note that secureboot is disabled here, see further discussion below.

systemd-boot and Unified Kernel Image conversion systemd folks have been developing UKI ("unified kernel image") to ship kernels. The way this works is the kernel and initrd (and UEFI boot stub) in a single portable executable that lives in the EFI partition, as opposed to /boot. This neatly solves my problem, because I already have such a clear-text partition and won't need to re-partition my disk to convert. Debian has started some preliminary support for this. It's not default, but I found this guide from Vasudeva Kamath which was pretty complete. Since the guide assumes some previous configuration, I had to adapt it to my case. Here's how I did the conversion to both systemd-boot and UKI, all at once. I could have perhaps done it one at a time, but doing both at once works fine. Before your start, make sure secureboot is disabled, see the discussion below.
  1. install systemd tools:
    apt install systemd-ukify systemd-boot
    
  2. Configure systemd-ukify, in /etc/kernel/install.conf:
    layout=uki
    initrd_generator=dracut
    uki_generator=ukify
    
    TODO: it doesn't look like this generates a initrd with dracut, do we care?
  3. Configure the kernel boot arguments with the following in /etc/kernel/uki.conf:
    [UKI]
    Cmdline=@/etc/kernel/cmdline
    
    The /etc/kernel/cmdline file doesn't actually exist here, and that's fine. Defaults are okay, as the image gets generated from your current /proc/cmdline. Check your /etc/default/grub and /proc/cmdline if you are unsure. You'll see the generated arguments in bootctl list below.
  4. Build the image:
    dpkg-reconfigure linux-image-$(uname -r)
    
  5. Check the boot options:
    bootctl list
    
    Look for a Type #2 (.efi) entry for the kernel.
  6. Reboot:
    reboot
    
You can tell you have booted with systemd-boot because (a) you won't see grub and (b) the /proc/cmdline will reflect the configuration listed in bootctl list. In my case, a systemd.machine_id variable is set there, and not in grub (compare with /boot/grub/grub.cfg). By default, the systemd-boot loader just boots, without a menu. You can force the menu to show up by un-commenting the timeout line in /boot/efit/loader/loader.conf, by hitting keys during boot (e.g. hitting "space" repeatedly), or by calling:
systemctl reboot --boot-loader-menu=0
See the systemd-boot(7) manual for details on that. I did not go through the secureboot process, presumably I had already disabled secureboot. This is trickier: because one needs a "special key" to sign the UKI image, one would need the collaboration of debian.org to get this working out of the box with the keys shipped onboard most computers. In other words, if you want to make this work with secureboot enabled on your computer, you'll need to figure out how to sign the generated images before rebooting here, because otherwise you will break your computer. Otherwise, follow the following guides:

Re-encrypting root filesystem Now that we have a way to boot an encrypted filesystem, we can switch to LUKS for our filesystem. Note that you can probably follow this guide if, somehow, you managed to make grub work with your LUKS setup, although as this guide shows, you'd need to downgrade the cryptographic algorithms, which seems like a bad tradeoff. We're using cryptsetup-reencrypt for this which, amazingly, supports re-encrypting devices on the fly. The trick is it needs free space at the end of the partition for the LUKS header (which, I guess, makes it a footer), so we need to resize the filesystem to leave room for that, which is the trickiest bit. This is a possibly destructive behavior. Be sure your backups are up to date, or be ready to lose all data on the device. We assume 512 byte sectors here. Check your sector size with fdisk -l and adjust accordingly.
  1. Before you perform the procedure, make sure requirements are installed:
    apt install cryptsetup systemd-cryptsetup cryptsetup-initramfs
    
    Note that this requires network access, of course.
  2. Reboot in a live image, I like GRML but any Debian live image will work, possibly including the installer
  3. First, calculate how many sectors to free up for the LUKS header
    qalc> 32Mibyte / ( 512 byte )
      (32 mebibytes) / (512 bytes) = 65536
    
  4. Find the sector sizes of the Linux partitions:
    fdisk  -l /dev/nvme0n1   awk '/filesystem/   print $1 " " $4  '  
    
    For example, here's an example with a /boot and / filesystem:
    $ sudo fdisk -l /dev/nvme0n1   awk '/filesystem/   print $1 " " $4  '
    /dev/nvme0n1p2 999424
    /dev/nvme0n1p3 3904979087
    
  5. Substract 1 from 2:
    qalc> set precision 100
    qalc> 3904979087 - 65536
    
    Or, last step and this one, in one line:
    fdisk -l /dev/nvme0n1   awk '/filesystem/   print $1 " " $4 - 65536  '
    
  6. Recheck filesystem:
    e2fsck -f /dev/nvme0n1p2
    
  7. Resize filesystem:
    resize2fs /dev/nvme0n1p2 $(fdisk -l /dev/nvme0n1   awk '/nvme0n1p2/   print $4 - 65536  ')s
    
    Notice the trailing s here: it makes resize2fs interpret the number as a 512 byte sector size, as opposed to the default (4k blocks).
  8. Re-encrypt filesystem:
    cryptsetup reencrypt --encrypt /dev/nvme0n1p2 --resize-device-size=32M
    
    This is it! This is the most important step! Make sure your laptop is plugged in and try not to interrupt it. This can, apparently, be resumed without problem, but I'd hate to show you how. This will show progress information like:
    Progress:   2.4% ETA 23m45s,      53GiB written, speed   1.3 GiB/s
    
    Wait until the ETA has passed.
  9. Open and mount the encrypted filesystem and mount the EFI system partition (ESP):
    cryptsetup open /dev/nvme0n1p2 crypt
    mount /dev/mapper/crypt /mnt
    mount /dev/nvme0n1p1 /mnt/boot/efi
    
    If this fails, now is the time to consider restoring from backups.
  10. Enter the chroot
    for fs in proc sys dev ; do
      mount --bind /$fs /mnt/$fs
    done
    chroot /mnt
    
    Pro tip: this can be done in one step in GRML with:
    grml-chroot /mnt bash
    
  11. Generate a crypttab:
    echo crypt_dev_nvme0n1p2 UUID=$(blkid -o value -s UUID /dev/nvme0n1p2) none luks,discard >> /etc/crypttab
    
  12. Adjust root filesystem in /etc/fstab, make sure you have a line like this:
    /dev/mapper/crypt_dev-nvme0n1p2 /               ext4    errors=remount-ro 0       1
    
    If you were already using a UUID entry for this, there's nothing to change!
  13. Configure the root filesystem in the initrd:
    echo root=/dev/mapper/crypt_dev_nvme0n1p2 > /etc/kernel/cmdline
    
  14. Regenerate UKI:
    dpkg-reconfigure linux-image-$(uname -r)
    
    Be careful here! systemd-boot inherits the command line from the system where it is generated, so this will possibly feature some unsupported commands from your boot environment. In my case GRML had a couple of those, which broke the boot. It's still possible to workaround this issue by tweaking the arguments at boot time, that said.
  15. Exit chroot and reboot
    exit
    reboot
    
Some of the ideas in this section were taken from this guide but was mostly rewritten to simplify the work. My guide also avoids the grub hacks or a specific initrd system (as the guide uses initramfs-tools and grub, while I, above, switched to dracut and systemd-boot). RHEL also has a similar guide, perhaps even better. Somehow I have made this system without LVM at all, which simplifies things a bit (as I don't need to also resize the physical volume/volume groups), but if you have LVM, you need to tweak this to also resize the LVM bits. The RHEL guide has some information about this.

Sven Hoexter: Istio: Connect via a VirtualService to External IP Addresses

Rant - I've a theory about istio: It feels like a software designed by people who hate the IT industry and wanted revenge. So they wrote a software with so many odd points of traffic interception (e.g. SNI based traffic re-routing) that's completely impossible to debug. If you roll that out into an average company you completely halt the IT operations for something like a year. On topic: I've two endpoints (IP addresses serving HTTPS on a none standard port) outside of kubernetes, and I need some rudimentary balancing of traffic. Since istio is already here one can levarage that, combining the resource kinds ServiceEntry, DestinationRule and VirtualService to publish a service name within the istio mesh. Since we do not have host names and DNS for those endpoint IP addresses we need to rely on istio itself to intercept the DNS traffic and deliver a virtual IP address to access the service. The sample given here leverages the exportTo configuration to make the service name only available in the same namespace. If you need broader access remove or adjust that. As usual in kubernetes you can resolve the name also as FQDN, e.g. acme-service.mynamespace.svc.cluster.local.
---
apiVersion: networking.istio.io/v1beta1
kind: ServiceEntry
metadata:
  name: acme-service
spec:
  hosts:
    - acme-service
  ports:
    - number: 12345
      name: acmeglue
      protocol: HTTPS
  resolution: STATIC
  location: MESH_EXTERNAL
  # limit the availability to the namespace this resource is applied to
  # if you need cross namespace access remove all the  exportTo s in here
  exportTo:
    - "."
  # use  endpoints:  in this setup,  addreses:  did not work
  endpoints:
    # region1
    - address: 192.168.0.1
      ports:
        acmeglue: 12345
    # region2
     - address: 10.60.48.50
       ports:
        acmeglue: 12345
---
apiVersion: networking.istio.io/v1beta1
kind: DestinationRule
metadata:
  name: acme-service
spec:
  host: acme-service
  # limit the availability to the namespace this resource is applied to
  exportTo:
    - "."
  trafficPolicy:
    loadBalancer:
      simple: LEAST_REQUEST
    connectionPool:
      tcp:
        tcpKeepalive:
          # We have GCP service attachments involved with a 20m idle timeout
          # https://cloud.google.com/vpc/docs/about-vpc-hosted-services#nat-subnets-other
          time: 600s
---
apiVersion: networking.istio.io/v1beta1
kind: VirtualService
metadata:
  name: acme-service
spec:
  hosts:
    - acme-service
  # limit the availability to the namespace this resource is applied to
  exportTo:
    - "."
  http:
  - route:
    - destination:
        host: acme-service
    retries:
      attempts: 2
      perTryTimeout: 2s
      retryOn: connect-failure,5xx
---
# Demo Deployment, istio configuration is the important part
apiVersion: apps/v1
kind: Deployment
metadata:
  name: foobar
  labels:
    app: foobar
spec:
  replicas: 1
  selector:
    matchLabels:
      app: foobar
  template:
    metadata:
      labels:
        app: foobar
        # enable istio sidecar
        sidecar.istio.io/inject: "true"
      annotations:
        # Enable DNS capture and interception, IP resolved will be in 240.240/16
        # If you use network policies you've to allow egress to this range.
        proxy.istio.io/config:  
          proxyMetadata:
            ISTIO_META_DNS_CAPTURE: "true"
    spec:
      containers:
      - name: nginx
        image: nginx:latest
        ports:
        - containerPort: 80
Now we can exec into the deployed pod, do something like curl -vk https://acme-service:12345, and it will talk to one of the endpoints defined in the ServiceEntry via an IP address out of the 240.240/16 Class E network. Documentation
https://istio.io/latest/docs/reference/config/networking/virtual-service/
https://istio.io/latest/docs/reference/config/networking/service-entry/#ServiceEntry-Resolution
https://istio.io/latest/docs/reference/config/networking/destination-rule/#LoadBalancerSettings-SimpleLB
https://istio.io/latest/docs/ops/configuration/traffic-management/dns-proxy/#sidecar-mode

19 August 2025

Russell Coker: Colmi P80 SmartWatch First Look

I just bought a Colmi P80 SmartWatch from Aliexpress for $26.11 based on this blog post reviewing it [1]. The main things I was after in this was a larger higher resolution screen because my vision has apparently deteriorated during the time I ve been wearing a Pinetime [2] and I now can t read messages on it when not wearing my reading glasses. The watch hardware is quite OK. It has a larger and higher resolution screen and looks good. The review said that GadgetBridge (the FOSS SmartWatch software in the F-Droid repository) connected when told that the watch was a P79 and in a recent release got support for sending notifications. In my tests with GadgetBridge it doesn t set the time, can t seem to send notifications, can t read the battery level, and seems not to do anything other than just say connected . So I installed the proprietary app, as an aside it s a neat feature to have the watch display a QR code for installing the app, maybe InfiniTime should have a similar QR code for getting GadgetBridge from the F-Droid repository. The proprietary app is quote OK for the basic functionality and a less technical relative who is using one is happy. For my use the proprietary app is utterly broken. One of my main uses is to get notifications of Jabber messages from the Conversations app (that s in F-Droid). I have Conversations configured to always have a notification of how many accounts are connected which prevents Android from killing it, with GadgetBridge that notification isn t reported but the actual message contents are (I don t know how/why that happens) but with the Colmi app I get repeated notifcation messages on the watch about the accounts being connected. Also the proprietary app has on/off settings for messages to go to the watch for a hard coded list of 16 common apps and an Others setting for the rest. GadgetBridge lists the applications that are actually installed so I can configure it not to notify me about Reddit, connecting to my car audio, and many other less common notifications. I prefer the GadgetBridge option to have an allow-list for apps that I want notifications from but it also has a configuration option to use a deny list so you could have everything other than the app that gives lots of low value notifications. The proprietary app has a wide range of watch faces that it can send to the watch which is a nice feature that would be good to have in InfiniTime and GadgetBridge. The P80 doesn t display a code on screen when it is paired via Bluetooth so if you have multiple smart watches then you are at risk of connecting to the wrong one and there doesn t seem to be anything stopping a hostile party from connecting to one. Note that hostile parties are not restricted to the normal maximum transmission power and can use a high gain antenna for reception so they can connect from longer distances than normal Bluetooth devices. Conclusion The Colmi P80 hardware is quite decent, the only downside is that the vibration has an annoying tinny feel. Strangely it has a rotation sensor for a rotating button (similar to analogue watches) but doesn t seem to have a use for it as the touch screen does everything. The watch firmware is quite OK (not great but adequate) but lacking a password for pairing is a significant lack. The Colmi Android app has some serious issues that make it unusable for what I do and the release version of GadgetBridge doesn t work with it, so I have gone back to the PineTime for actual use. The PineTime cost twice as much, has less features (no sensor for O2 level in blood), but seems more solidly constructed. I plan to continue using the P80 with GadgetBridge and Debian based SmartWatch software to help develop the Debian Mobile project. I expect that at some future time GadgetBridge and the programs written for non-Android Linux distributions will support the P80 and I will transition to it. I am confident that it will work well for me at some future time and that I will get $26.11 of value from it. At this time I recommend that people who do the sort of things I do get one of each and that less technical people get a Colmi P80.

18 August 2025

Jonathan Dowland: Amiga redux

Matthew blogged about his Amiga CDTV project, a truly unique Amiga hack which also manages to be a novel Doom project (no mean feat: it's a crowded space) This re-awakened my dormant wish to muck around with my childhood Amiga some more. When I last wrote about it (four years ago ) I'd upgraded the disk drive emulator with an OLED display and rotary encoder. I'd forgotten to mention I'd also sourced a modern trapdoor RAM expansion which adds 2MiB of RAM. The Amiga can only see 1.5MiB1 of it at the moment, I need perform a mainboard modification to access the final 512kiB2, which means some soldering.
[Amiga Test Kit](https://github.com/keirf/Amiga-Stuff) showing 2MiB RAM Amiga Test Kit showing 2MiB RAM
What I had planned to do back then: replace the switch in the left button of the original mouse, which was misbehaving; perform the aformentioned mainboard mod; upgrade the floppy emulator wiring to a ribbon cable with plug-and-socket, for easier removal; fit an RTC chip to the RAM expansion board to get clock support in the OS. However much of that might be might be moot, because of two other mods I am considering, PiStorm I've re-considered the PiStorm accelerator mentioned in Matt's blog. Four years ago, I'd passed over it, because it required you to run Linux on a Raspberry Pi, and then an m68k emulator as a user-space process under Linux. I didn't want to administer another Linux system, and I'm generally uncomfortable about using a regular Linux distribution on SD storage over the long term. However in the intervening years Emu68, a bare-metal m68k emulator has risen to prominence. You boot the Pi straight into Emu68 without Linux in the middle. For some reason that's a lot more compelling to me. The PiStorm enormously expands the RAM visible to the Amiga. There would be no point in doing the mainboard mod to add 512k (and I don't know how that would interact with the PiStorm). It also can provide virtual hard disk devices to the Amiga (backed by files on the SD card), meaning the floppy emulator would be superfluous. Denise Mainboard I've just learned about a truly incredible project: the Denise Mini-ITX Amiga mainboard. It fitss into a Mini-ITX case (I have a suitable one spare already). Some assembly required. You move the chips from the original Amiga over to the Denise mainboard. It's compatible with the PiStorm (or vice-versa). It supports PC-style PS/2 keyboards (I have a Model M in the loft, thanks again Simon) and has a bunch of other modern conveniences: onboard RTC; mini-ITX power (I'll need something like a picoPSU too) It wouldn't support my trapdoor RAM card but it takes a 72-pin DIMM which can supply 2MiB of Chip RAM, and the PiStorm can do the rest (they're compatible3). No stock at the moment but if I could get my hands on this, I could build something that could permanently live on my desk.

  1. the Boobip board's 1.5MiB is "chip" RAM: accessible to the other chips on the mainboard, with access mediated by the AGNUS chip.
  2. the final 512kiB is "Fast" RAM: only accessible to the CPU, not mediated via Agnus.
  3. confirmation

Otto Kek l inen: Best Practices for Submitting and Reviewing Merge Requests in Debian

Featured image of post Best Practices for Submitting and Reviewing Merge Requests in DebianHistorically the primary way to contribute to Debian has been to email the Debian bug tracker with a code patch. Now that 92% of all Debian source packages are hosted at salsa.debian.org the GitLab instance of Debian more and more developers are using Merge Requests, but not necessarily in the optimal way. In this post I share what I ve found the best practice to be, presented in the natural workflow from forking to merging.
Why use Merge Requests? Compared to sending patches back and forth in email, using a git forge to review code contributions brings several benefits:
  • Contributors can see the latest version of the code immediately when the maintainer pushes it to git, without having to wait for an upload to Debian archives.
  • Contributors can fork the development version and easily base their patches on the correct version and help test that the software continues to function correctly at that specific version.
  • Both maintainer and other contributors can easily see what was already submitted and avoid doing duplicate work.
  • It is easy for anyone to comment on a Merge Request and participate in the review.
  • Integrating CI testing is easy in Merge Requests by activating Salsa CI.
  • Tracking the state of a Merge Request is much easier than browsing Debian bug reports tagged patch , and the cycle of submit review re-submit re-review is much easier to manage in the dedicated Merge Request view compared to participants setting up their own email plugins for code reviews.
  • Merge Requests can have extra metadata, such as Approved , and the metadata often updates automatically, such as a Merge Request being closed automatically when the Git commit ID from it is pushed to the target branch.
Keeping these benefits in mind will help ensure that the best practices make sense and are aligned with maximizing these benefits.

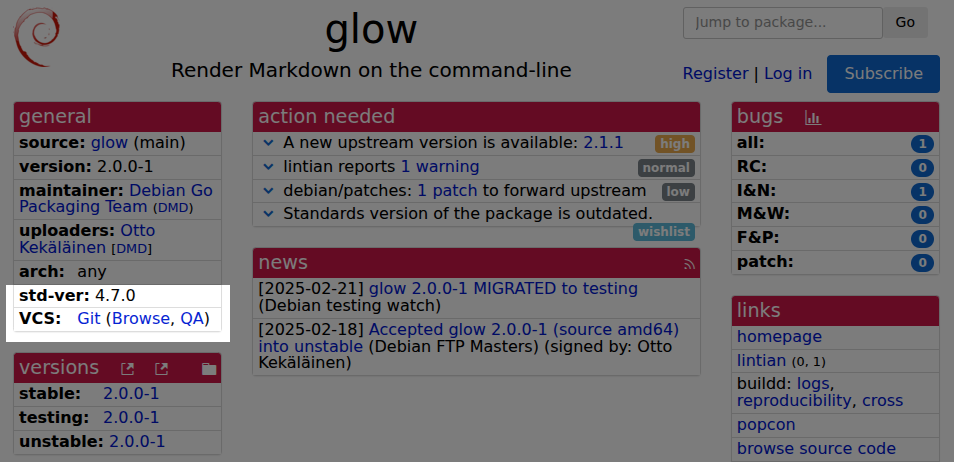
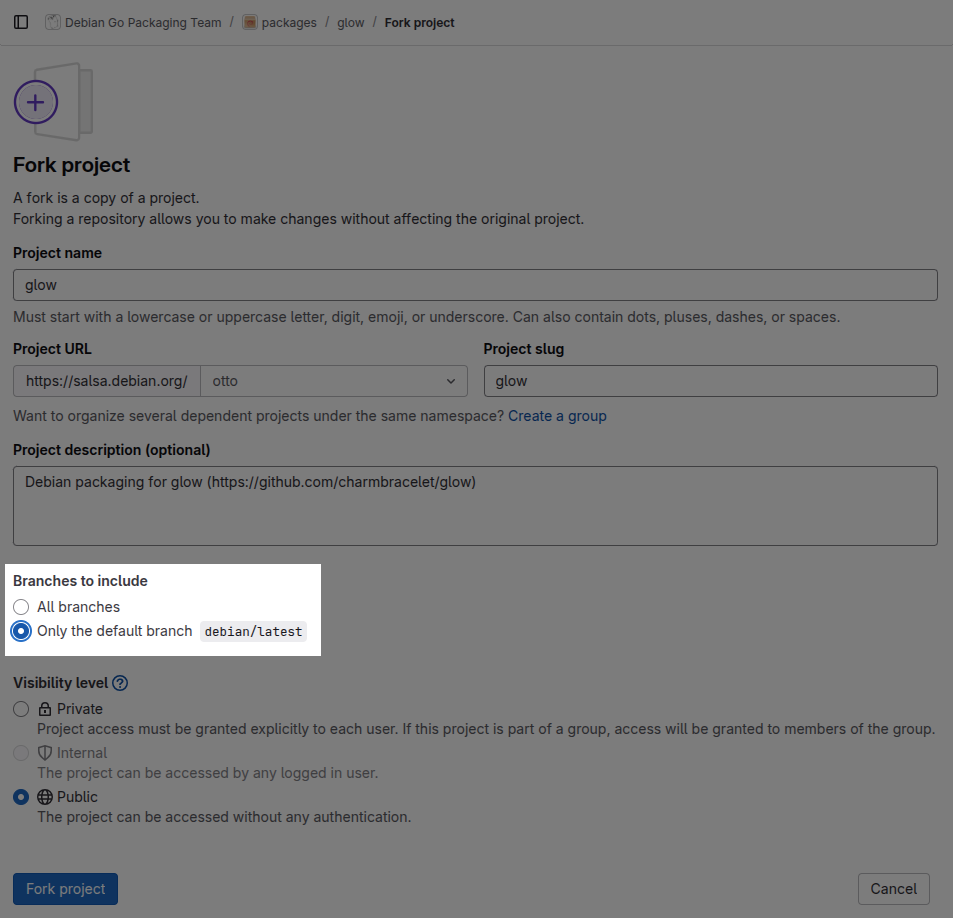
Finding the Debian packaging source repository and preparing to make a contribution Before sinking any effort into a package, start by checking its overall status at the excellent Debian Package Tracker. This provides a clear overview of the package s general health in Debian, when it was last uploaded and by whom, and if there is anything special affecting the package right now. This page also has quick links to the Debian bug tracker of the package, the build status overview and more. Most importantly, in the General section, the VCS row links to the version control repository the package advertises. Before opening that page, note the version most recently uploaded to Debian. This is relevant because nothing in Debian currently enforces that the package in version control is actually the same as the latest uploaded to Debian. Packaging source code repository links at tracker.debian.org Following the Browse link opens the Debian package source repository, which is usually a project page on Salsa. To contribute, start by clicking the Fork button, select your own personal namespace and, under Branches to include, pick Only the default branch to avoid including unnecessary temporary development branches. View after pressing Fork Once forking is complete, clone it with git-buildpackage. For this example repository, the exact command would be gbp clone --verbose git@salsa.debian.org:otto/glow.git. Next, add the original repository as a new remote and pull from it to make sure you have all relevant branches. Using the same fork as an example, the commands would be:
git remote add go-team https://salsa.debian.org/go-team/packages/glow.git
gbp pull --verbose --track-missing go-team
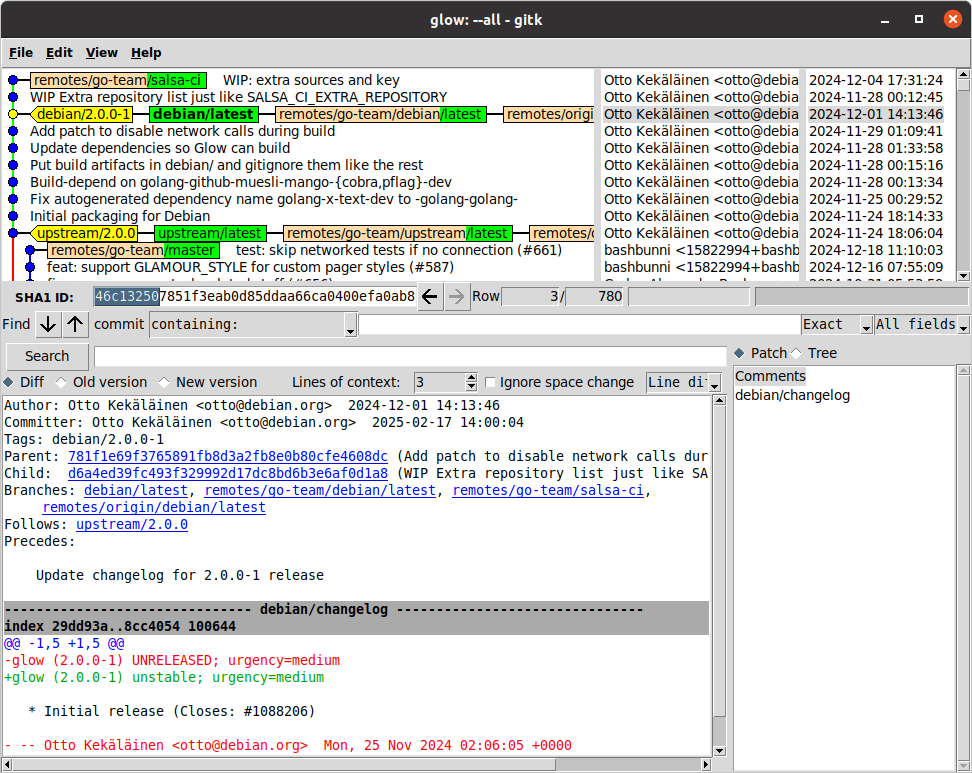
The gbp pull command can be repeated whenever you want to make sure the main branches are in sync with the original repository. Finally, run gitk --all & to visually browse the Git history and note the various branches and their states in the two remotes. Note the style in comments and repository structure the project has and make sure your contributions follow the same conventions to maximize the chances of the maintainer accepting your contribution. It may also be good to build the source package to establish a baseline of the current state and what kind of binaries and .deb packages it produces. If using Debcraft, one can simply run debcraft build in the Git repository.
Submitting a Merge Request for a Debian packaging improvement Always start by making a development branch by running git checkout -b <branch name> to clearly separate your work from the main branch. When making changes, remember to follow the conventions you already see in the package. It is also important to be aware of general guidelines on how to make good Git commits. If you are not able to immediately finish coding, it may be useful to publish the Merge Request as a draft so that the maintainer and others can see that you started working on something and what general direction your change is heading in. If you don t finish the Merge Request in one sitting and return to it another day, you should remember to pull the Debian branch from the original Debian repository in case it has received new commits. This can be done easily with these commands (assuming the same remote and branch names as in the example above):
git fetch go-team
git rebase -i go-team/debian/latest
Frequent rebasing is a great habit to help keep the Git history linear, and restructuring and rewording your commits will make the Git history easier to follow and understand why the changes were made. When pushing improved versions of your branch, use git push --force. While GitLab does allow squashing, I recommend against it. It is better that the submitter makes sure the final version is a neat and clean set of commits that the receiver can easily merge without having to do any rebasing or squashing themselves. When ready, remove the draft status of the Merge Request and wait patiently for review. If the maintainer does not respond in several days, try sending an email to <source package name>@packages.debian.org, which is the official way to contact maintainers. You could also post a comment on the MR and tag the last few committers in the same repository so that a notification email is triggered. As a last resort, submit a bug report to the Debian bug tracker to announce that a Merge Request is pending review. This leaves a permanent record for posterity (or the Debian QA team) of your contribution. However, most of the time simply posting the Merge Request in Salsa is enough; excessive communication might be perceived as spammy, and someone needs to remember to check that the bug report is closed.

Respect the review feedback, respond quickly and avoid Merge Requests getting stale Once you get feedback, try to respond as quickly as possible. When people participating have everything fresh in their minds, it is much easier for the submitter to rework it and for the reviewer to re-review. If the Merge Request becomes stale, it can be challenging to revive it. Also, if it looks like the MR is only waiting for re-review but nothing happens, re-read the previous feedback and make sure you actually address everything. After that, post a friendly comment where you explicitly say you have addressed all feedback and are only waiting for re-review.

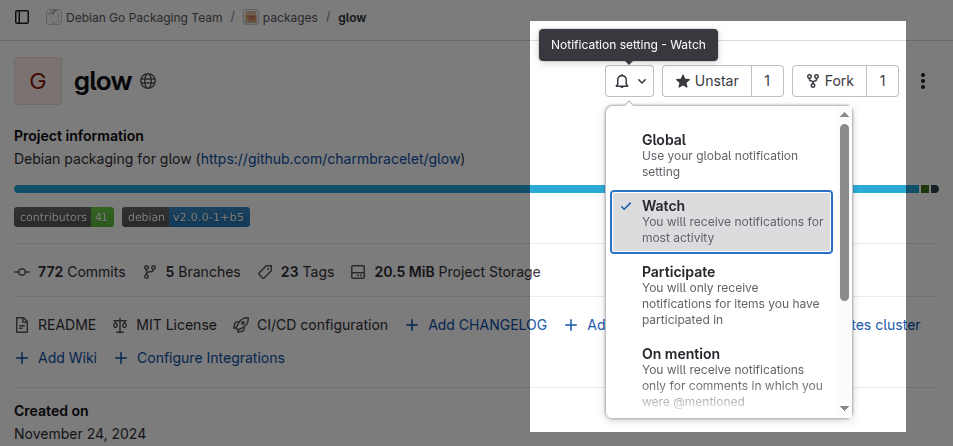
Reviewing Merge Requests This section about reviewing is not exclusive to Debian package maintainers anyone can contribute to Debian by reviewing open Merge Requests. Typically, the larger an open source project gets, the more help is needed in reviewing and testing changes to avoid regressions, and all diligently done work is welcome. As the famous Linus quote goes, given enough eyeballs, all bugs are shallow . On salsa.debian.org, you can browse open Merge Requests per project or for a whole group, just like on any GitLab instance. Reviewing Merge Requests is, however, most fun when they are fresh and the submitter is active. Thus, the best strategy is to ensure you have subscribed to email notifications in the repositories you care about so you get an email for any new Merge Request (or Issue) immediately when posted. Change notification settings from Global to Watch to get an email on new Merge Requests When you see a new Merge Request, try to review it within a couple of days. If you cannot review in a reasonable time, posting a small note that you intend to review it later will feel better to the submitter compared to not getting any response. Personally, I have a habit of assigning myself as a reviewer so that I can keep track of my whole review queue at https://salsa.debian.org/dashboard/merge_requests?reviewer_username=otto, and I recommend the same to others. Seeing the review assignment happen is also a good way to signal to the submitter that their submission was noted.
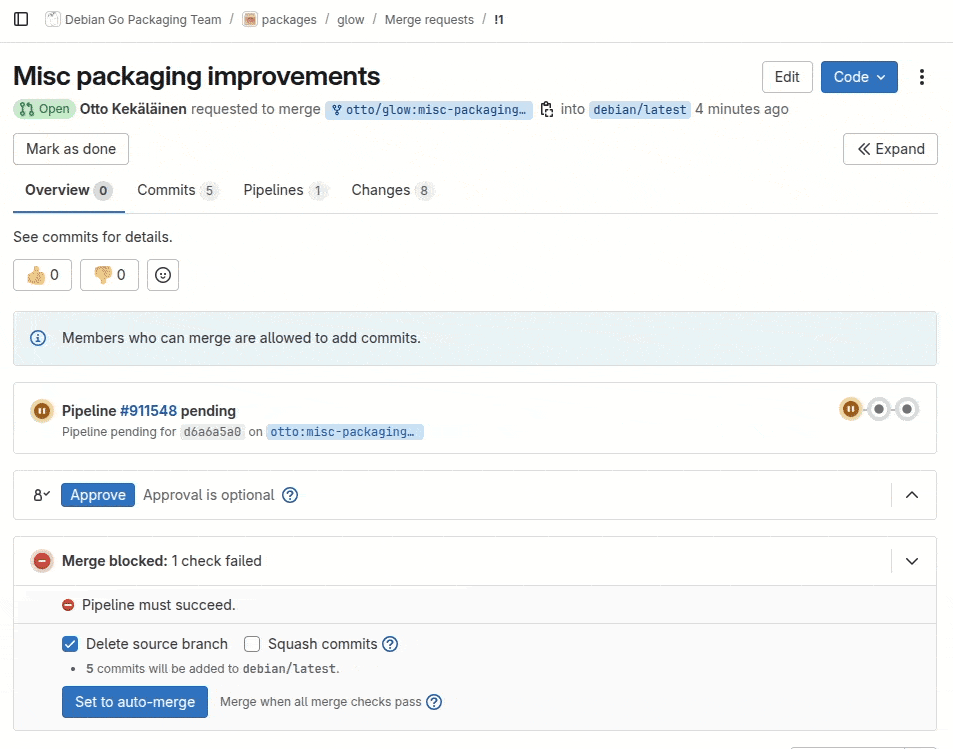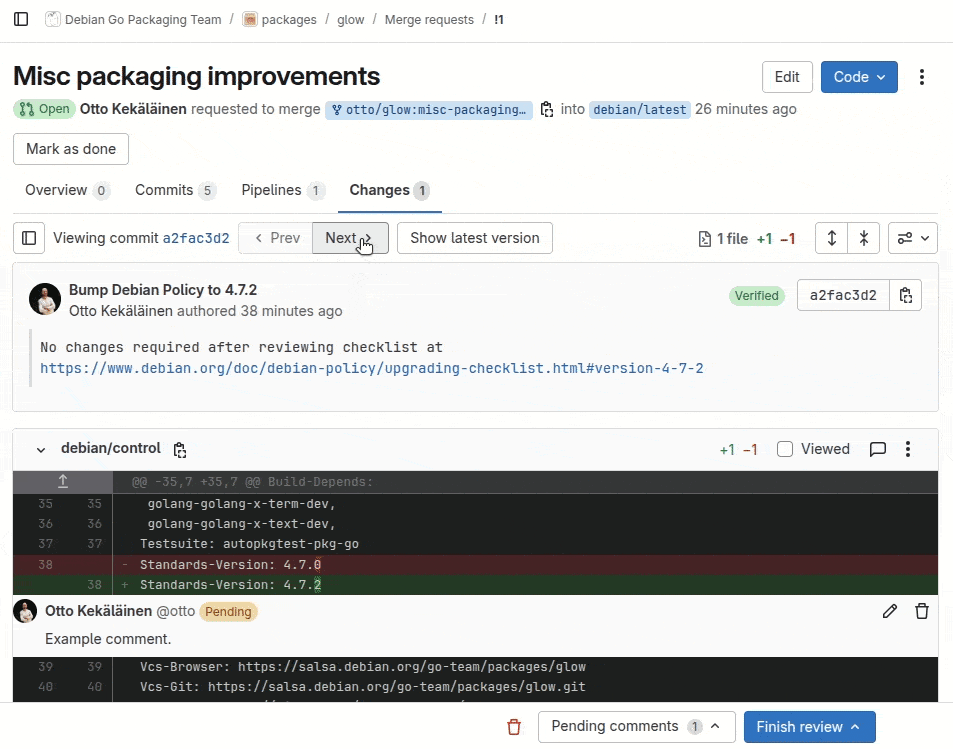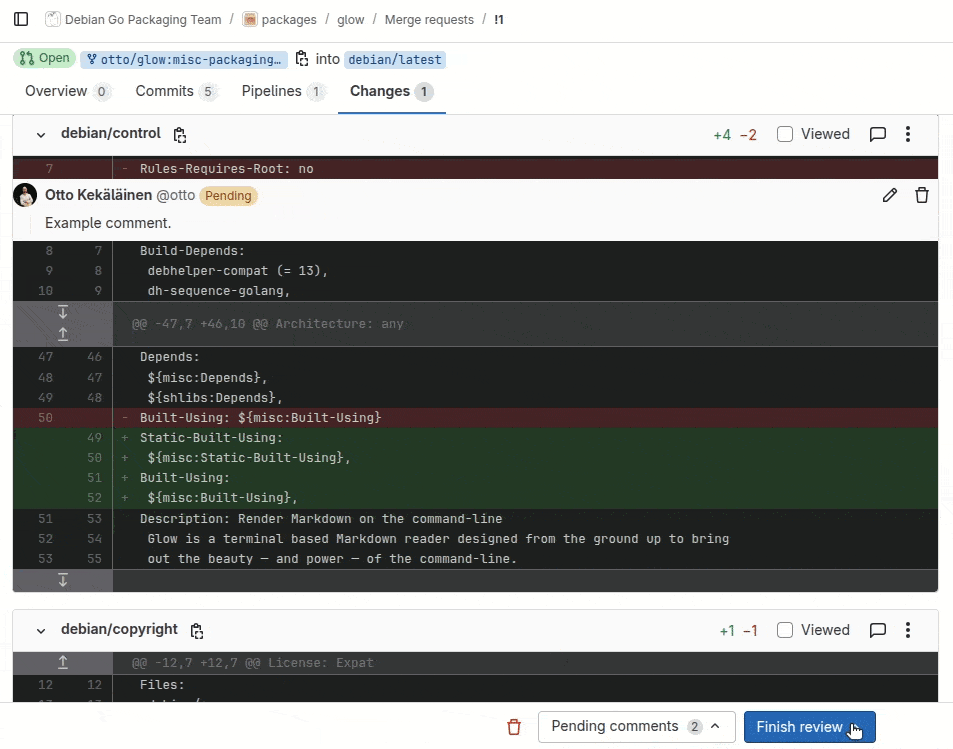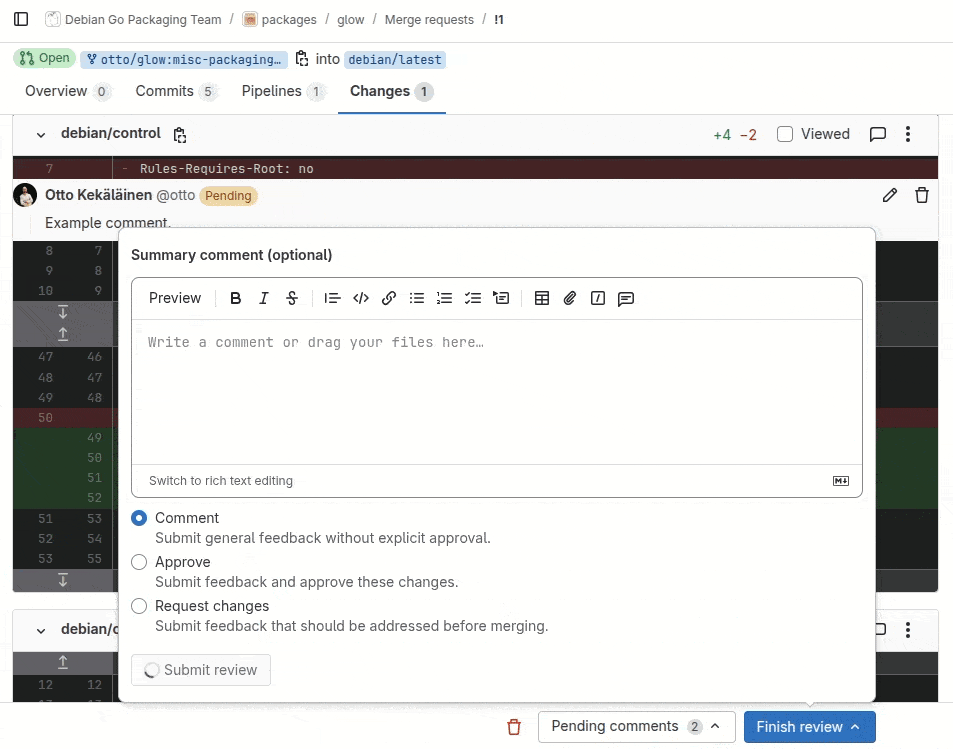
Reviewing commit-by-commit in the web interface Reviewing using the web interface works well in general, but I find that the way GitLab designed it is not ideal. In my ideal review workflow, I first read the Git commit message to understand what the submitter tried to do and why; only then do I look at the code changes in the commit. In GitLab, to do this one must first open the Commits tab and then click on the last commit in the list, as it is sorted in reverse chronological order with the first commit at the bottom. Only after that do I see the commit message and contents. Getting to the next commit is easy by simply clicking Next. Example review to demonstrate location of buttons and functionality When adding the first comment, I choose Start review and for the following remarks Add to review. Finally, I click Finish review and Submit review, which will trigger one single email to the submitter with all my feedback. I try to avoid using the Add comment now option, as each such comment triggers a separate notification email to the submitter.
Reviewing and testing on your own computer locally For the most thorough review, I pull the code to my laptop for local review with git pull <remote url> <branch name>. There is no need to run git remote add as pulling using a URL directly works too and saves from needing to clean up old remotes later. Pulling the Merge Request contents locally allows me to build, run and inspect the code deeply and review the commits with full metadata in gitk or equivalent.

Investing enough time in writing feedback, but not too much See my other post for more in-depth advice on how to structure your code review feedback. In Debian, I would emphasize patience, to allow the submitter time to rework their submission. Debian packaging is notoriously complex, and even experienced developers often need more feedback and time to get everything right. Avoid the temptation to rush the fix in yourself. In open source, Git credits are often the only salary the submitter gets. If you take the idea from the submission and implement it yourself, you rob the submitter of the opportunity to get feedback, try to improve and finally feel accomplished. Sure, it takes extra effort to give feedback, but the contributor is likely to feel ownership of their work and later return to further improve it. If a submission looks hopelessly low quality and you feel that giving feedback is a waste of time, you can simply respond with something along the lines of: Thanks for your contribution and interest in helping Debian. Unfortunately, looking at the commits, I see several shortcomings, and it is unlikely a normal review process is enough to help you finalize this. Please reach out to Debian Mentors to get a mentor who can give you more personalized feedback. There might also be contributors who just dump the code , ignore your feedback and never return to finalize their submission. If a contributor does not return to finalize their submission in 3-6 months, I will in my own projects simply finalize it myself and thank the contributor in the commit message (but not mark them as the author). Despite best practices, you will occasionally still end up doing some things in vain, but that is how volunteer collaboration works. We all just need to accept that some communication will inevitably feel like wasted effort, but it should be viewed as a necessary investment in order to get the benefits from the times when the communication led to real and valuable collaboration. Please just do not treat all contributors as if they are unlikely to ever contribute again; otherwise, your behavior will cause them not to contribute again. If you want to grow a tree, you need to plant several seeds.

Approving and merging Assuming review goes well and you are ready to approve, and if you are the only maintainer, you can proceed to merge right away. If there are multiple maintainers, or if you otherwise think that someone else might want to chime in before it is merged, use the Approve button to show that you approve the change but leave it unmerged. The person who approved does not necessarily have to be the person who merges. The point of the Merge Request review is not separation of duties in committing and merging the main purpose of a code review is to have a different set of eyeballs looking at the change before it is committed into the main development branch for all eternity. In some packages, the submitter might actually merge themselves once they see another developer has approved. In some rare Debian projects, there might even be separate people taking the roles of submitting, approving and merging, but most of the time these three roles are filled by two people either as submitter and approver+merger or submitter+merger and approver. If you are not a maintainer at all and do not have permissions to click Approve, simply post a comment summarizing your review and that you approve it and support merging it. This can help the maintainers review and merge faster.

Making a Merge Request for a new upstream version import Unlike many other Linux distributions, in Debian each source package has its own version control repository. The Debian sources consist of the upstream sources with an additional debian/ subdirectory that contains the actual Debian packaging. For the same reason, a typical Debian packaging Git repository has a debian/latest branch that has changes only in the debian/ subdirectory while the surrounding upstream files are the actual upstream files and have the actual upstream Git history. For details, see my post explaining Debian source packages in Git. Because of this Git branch structure, importing a new upstream version will typically modify three branches: debian/latest, upstream/latest and pristine-tar. When doing a Merge Request for a new upstream import, only submit one Merge Request for one branch: which means merging your new changes to the debian/latest branch. There is no need to submit the upstream/latest branch or the pristine-tar branch. Their contents are fixed and mechanically imported into Debian. There are no changes that the reviewer in Debian can request the submitter to do on these branches, so asking for feedback and comments on them is useless. All review, comments and re-reviews concern the content of the debian/latest branch only. It is not even necessary to use the debian/latest branch for a new upstream version. Personally, I always execute the new version import (with gbp import-orig --verbose --uscan) and prepare and test everything on debian/latest, but when it is time to submit it for review, I run git checkout -b import/$(dpkg-parsechangelog -SVersion) to get a branch named e.g. import/1.0.1 and then push that for review.

Reviewing a Merge Request for a new upstream version import Reviewing and testing a new upstream version import is a bit tricky currently, but possible. The key is to use gbp pull to automate fetching all branches from the submitter s fork. Assume you are reviewing a submission targeting the Glow package repository and there is a Merge Request from user otto s fork. As the maintainer, you would run the commands:
git remote add otto https://salsa.debian.org/otto/glow.git
gbp pull --verbose otto
If there was feedback in the first round and you later need to pull a new version for re-review, running gbp pull --force will not suffice, and this trick of manually fetching each branch and resetting them to the submitter s version is needed:
for BRANCH in pristine-tar upstream debian/latest
do
git checkout $BRANCH
git reset --hard origin/$BRANCH
git pull --force https://salsa.debian.org/otto/glow.git $BRANCH
done
Once review is done, either click Approve and let the submitter push everything, or alternatively, push all the branches you pulled locally yourself. In GitLab and other forges, the Merge Request will automatically be marked as Merged once the commit ID that was the head of the Merge Request is pushed to the target branch.

Please allow enough time for everyone to participate When working on Debian, keep in mind that it is a community of volunteers. It is common for people to do Debian stuff only on weekends, so you should patiently wait for at least a week so that enough workdays and weekend days have passed for the people you interact with to have had time to respond on their own Debian time. Having to wait may feel annoying and disruptive, but try to look at the upside: you do not need to do extra work simply while waiting for others. In some cases, that waiting can be useful thanks to the sleep on it phenomenon: when you yourself look at your own submission some days later with fresh eyes, you might notice something you overlooked earlier and improve your code change even without other people s feedback!

Contribute reviews! The last but not least suggestion is to make a habit of contributing reviews to packages you do not maintain. As we already see in large open source projects, such as the Linux kernel, they have far more code submissions than they can handle. The bottleneck for progress and maintaining quality becomes the reviews themselves. For Debian, as an organization and as a community, to be able to renew and grow new contributors, we need more of the senior contributors to shift focus from merely maintaining their packages and writing code to also intentionally interact with new contributors and guide them through the process of creating great open source software. Reviewing code is an effective way to both get tangible progress on individual development items and to transfer culture to a new generation of developers.

Why aren t 100% of all Debian source packages hosted on Salsa? As seen at trends.debian.net, more and more packages are using Salsa. Debian does not, however, have any policy about it. In fact, the Debian Policy Manual does not even mention the word Salsa anywhere. Adoption of Salsa has so far been purely organic, as in Debian each package maintainer has full freedom to choose whatever preferences they have regarding version control. I hope the trend to use Salsa will continue and more shared workflows emerge so that collaboration gets easier. To drive the culture of using Merge Requests and more, I drafted the Debian proposal DEP-18: Encourage Continuous Integration and Merge Request based Collaboration for Debian packages. If you are active in Debian and you think DEP-18 is beneficial for Debian, please give a thumbs up at dep-team/deps!21.

17 August 2025

C.J. Collier: The Very Model of a Patriot Online

It appears that the fragile masculinity tech evangelists have identified Debian as a community with boundaries which exclude them from abusing its members and they re so angry about it! In response to posts such as this, and inspired by Dr. Conway s piece, I ve composed a poem which, hopefully, correctly addresses the feelings of that crowd.

The Very Model of a Patriot Online
I am the very model of a modern patriot online,
My keyboard is my rifle and my noble cause is so divine.
I didn't learn my knowledge in a dusty college lecture hall,
But from the chans where bitter anonymity enthralls us all.
I spend a dozen hours every day upon my sacred quest,
To put the globo-homo narrative completely to the test.
My arguments are peer-reviewed by fellas in the comments section,
Which proves my every thesis is the model of complete perfection.
I m steeped in righteous anger that the libs call 'white fragility,'
For mocking their new pronouns and their lack of masculinity.
I m master of the epic troll, the comeback, and the searing snark,
A digital guerrilla who is fighting battles in the dark.
I know the secret symbols and the dog-whistles historical,
From Pepe the Frog to  Let s Go Brandon,  in order categorical;
In short, for fighting culture wars with rhetoric rhetorical,
I am the very model of a patriot polemical.
***
I stand for true expression, for the comics and the edgy clown,
Whose satire is too based for all the fragile folks in town.
They say my speech is 'violence' while my spirit they are trampling,
The way they try to silence me is really quite a startling sampling
Of 1984, which I've not read but thoroughly understand,
Is all about the tyranny that's gripping this once-blessed land.
My humor is a weapon, it s a razor-bladed, sharp critique,
(Though sensitive elites will call my masterpiece a form of  hate speech ).
They cannot comprehend my need for freedom from all consequence,
They call it 'hate,' I call it 'jokes,' they just don't have a lick of sense.
So when they call me  bigot  for the spicy memes I post pro bono,
I tell them their the ones who're cancelled, I'm the victim here, you know!
Then I can write a screed against the globalist cabal, you see,
And tell you every detail of their vile conspiracy.
In short, when I use logic that is flexible and personal,
I am the very model of a patriot controversial.
***
I'm very well acquainted with the scientific method, too,
It's watching lengthy YouTube vids until my face is turning blue.
I trust the heartfelt testimony of a tearful, blonde ex-nurse,
But what a paid fact-checker says has no effect and is perverse.
A PhD is proof that you've been brainwashed by the leftist mob,
While my own research on a meme is how I really do my job.
I know that masks will suffocate and vaccines are a devil's brew,
I learned it from a podcast host who used to sell brain-boosting goo.
He scorns the lamestream media, the CNNs and all the rest,
Whose biased reporting I've put fully to a rigorous test
By only reading headlines and confirming what I already knew,
Then posting my analysis for other patriots to view.
With every "study" that they cite from sources I can't stand to hear,
My own profound conclusions become ever more precisely clear.
In short, when I've debunked the experts with a confident "Says who?!",
I am the very model of a researcher who sees right through you.
***
But all these culture wars are just a sleight-of-hand, a clever feint,
To hide the stolen ballots and to cover up the moral taint
Of D.C. pizza parlors and of shipping crates from Wayfair, it s true,
It's all connected in a plot against the likes of me and you!
I've analyzed the satellite photography and watermarks,
I understand the secret drops, the cryptic Qs, the coded sparks.
The  habbening  is coming, friends, just give it two more weeks or three,
When all the traitors face the trials for their wicked treachery.
They say that nothing happened and the dates have all gone past, you see,
But that's just disinformation from the globalist enemy!
Their moving goalposts constantly, a tactic that is plain to see,
To wear us down and make us doubt the coming, final victory!
My mind can see the patterns that a simple sheep could never find,
The hidden puppet-masters who are poisoning our heart and mind.
In short, when I link drag queens to the price of gas and child-trafficking,
I am the very model of a patriot whose brain is quickening!
***
My pickup truck's a testament to everything that I hold dear,
With vinyl decals saying things the liberals all hate and fear.
The Gadsden flag is waving next to one that's blue and starkly thin,
To show my deep respect for law, except the feds who're steeped in sin.
There's Punisher and Molon Labe, so that everybody knows
I'm not someone to trifle with when push to final shoving goes.
I've got my tactical assault gear sitting ready in the den,
Awaiting for the signal to restore our land with my fellow men.
I practice clearing rooms at home when my mom goes out to the store,
A modern Minuteman who's ready for a civil war.
The neighbors give me funny looks, I see them whisper and take note,
They'll see what's what when I'm the one who's guarding checkpoints by their throat.
I am a peaceful man, of course, but I am also pre-prepared,
To neutralize the threats of which the average citizen's unscared.
In short, when my whole identity's a brand of tactical accessory,
You'll say a better warrior has never graced a Cabela's registry.
***
They say I have to tolerate a man who thinks he is a dame,
While feminists and immigrants are putting out my vital flame!
There taking all the jobs from us and giving them to folks who kneel,
And "woke HR" says my best jokes are things I'm not allowed to feel!
An Alpha Male is what I am, a lion, though I'm in this cubicle,
My life's frustrations can be traced to policies Talmudical.
They lecture me on privilege, I, who have to pay my bills and rent!
While they give handouts to the lazy, worthless, and incompetent!
My grandad fought the Nazis! Now I have to press a key for  one 
To get a call-rep I can't understand beneath the blazing sun
Of global, corporate tyranny that's crushing out the very soul
Of men like me, who've lost their rightful, natural, and just control!
So yes, I am resentful! And I'm angry! And I'm right to be!
They've stolen all my heritage and my masculinity!
In short, when my own failures are somebody else's evil plot,
I am the very model of the truest patriot we've got!
***
There putting chips inside of you! Their spraying things up in the sky!
They want to make you EAT THE BUGS and watch your very spirit die!
The towers for the 5G are a mind-control delivery tool!
To keep you docile while the children suffer in a grooming school!
The WEF, and Gates, and Soros have a plan they call the 'Great Reset,'
You'll own no property and you'll be happy, or you'll be in debt
To social credit overlords who'll track your every single deed!
There sterilizing you with plastics that they've hidden in the feed!
The world is flat! The moon is fake! The dinosaurs were just a lie!
And every major tragedy's a hoax with actors paid to cry!
I'M NOT INSANE! I SEE THE TRUTH! MY EYES ARE OPEN! CAN'T YOU SEE?!
YOU'RE ALL ASLEEP! YOU'RE COWARDS! YOU'RE AFRAID OF BEING TRULY FREE!
My heart is beating faster now, my breath is short, my vision's blurred,
From all the shocking truth that's in each single, solitary word!
I've sacrificed my life and friends to bring this message to the light, so...
You'd better listen to me now with all your concentrated might, ho!
***
For my heroic struggle, though it's cosmic and it's biblical,
Is waged inside the comments of a post that's algorithm-ical.
And still for all my knowledge that's both tactical and practical,
My mom just wants the rent I owe and says I'm being dramatical.

16 August 2025

Birger Schacht: Updates and additions in Debian 13 Trixie

Last week Debian 13 (Trixie) was released and there have been some updates and additions in the packages that I maintain, that I wanted to write about. I think they are not worth of being added to the release notes, but I still wanted to list some of the changes and some of the new packages.

sway Sway, the tiling Wayland compositor was version 1.7 in Bookworm. It was updated to version 1.10 (and 1.11 is already in experimental and waiting for an upload to unstable). This new version of sway brings, among a lot of other features, updated support for touchpad gestures and support for the ext-session-lock-v1 protocol, which allows for more robust and secure screen locking. The configuration snippet that activates the default sway background is now shipped in the sway-backgrounds package instead of being part of the sway package itself. The default menu application was changed from dmenu to wmenu. wmenu is a Wayland native alternative to dmenu which I packaged and it is now recommended by sway. There are some small helper tools for sway that were updated: swaybg was bumped from 1.2.0 to 1.2.1, swaylock was bumped from 1.7.2 to 1.8.2. The grimshot script, which is a script for making screenshots, was part of the sway s contrib folder for a long time (but was shipped as a separate binary package). It was removed from sway and is now part of the sway-contrib project. There are some other useful utilities in this source package that I might package in the future. slurp, which is used by grimshot to select a region, was updated from version 1.4 to version 1.5.

labwc I uploaded the first labwc package two years ago and I m happy it is now part of a stable Debian release. Labwc is also based on wlroots, like sway. It is a window-stacking compositor and is inspired by openbox. I used openbox for a long time back in the day before I moved to i3 and I m very happy to see that there is a Wayland alternative.

foot Foot is a minimalistic and fast Wayland terminal emulator. It is mostly keyboard driven. foot was updated from version 1.13.1 to 1.21.0. The probably most important change for users updating might be the fact that:
  • Control+Shift+u is now bound to unicode-input instead of show- urls-launch, to follow the convention established in GTK and Qt
  • show-urls-launch now bound to Control+Shift+o

et cetera The Wayland kiosk cage was updated from 0.1.4 to 0.2.0. The waybar bar for wlroots compositors was updated from 0.9.17 to 0.12.0. swayimg was updated from 1.10 to 3.8 and now brings support for custom key bindings, support for additional image types (PNM, EXR, DICOM, Farbfeld, sixel) and a gallery mode. tofi, another dmenu replacement was updated from 0.8.1 to 0.9.1, wf-recorder a tool for screen recording in wlroots-based compositors, was updated from version 0.3 to version 0.5.0. wlogout was updated from version 1.1.1 to 1.2.2. The application launcher wofi was updated from 1.3 to 1.4.1. The lightweight status panel yambar was updated from version 1.9 to 1.11. kanshi, the tool for managing and automatically switching your output profiles, was updated from version 1.3.1 to version 1.5.1. usbguard was updated from version 1.1.2 to 1.1.3.

added
  • fnott - a lightweight notification daemon for wlroots based compositors
  • fyi - a utility to send notifications to a notification daemon, similar to notify-send
  • pipectl - a tool to create and manage short-lived named pipes, this is a dependency of wl-present. wl-present is a script around wl-mirror which implements output mirroring for wlroots-based compositors
  • poweralertd - a small daemon that notifies you about the power status of your battery powered devices
  • wlopm - control power management of outputs
  • wlrctl - command line utility for miscellaneous wlroots Wayland extensions
  • wmenu - already mentioned, the new default launcher of sway
  • wshowkeys - shows keypresses in wayland sessions, nice for debugging
  • libsfdo - libraries implementing some freedesktop.org specs, used by labwc

15 August 2025

Freexian Collaborators: Monthly report about Debian Long Term Support, July 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In July, 17 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 19.0h (out of 19.0h assigned).
  • Andrej Shadura did 5.0h (out of 0.0h assigned and 8.0h from previous period), thus carrying over 3.0h to the next month.
  • Bastien Roucari s did 18.5h (out of 18.75h assigned), thus carrying over 0.25h to the next month.
  • Ben Hutchings did 12.5h (out of 3.25h assigned and 15.5h from previous period), thus carrying over 6.25h to the next month.
  • Carlos Henrique Lima Melara did 10.0h (out of 10.0h assigned).
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 18.75h (out of 17.25h assigned and 1.5h from previous period).
  • Emilio Pozuelo Monfort did 18.75h (out of 18.75h assigned).
  • Guilhem Moulin did 15.0h (out of 14.0h assigned and 1.0h from previous period).
  • Jochen Sprickerhof did 2.0h (out of 16.5h assigned and 2.25h from previous period), thus carrying over 16.75h to the next month.
  • Lee Garrett did 7.0h (out of 0.0h assigned and 23.25h from previous period), thus carrying over 16.25h to the next month.
  • Markus Koschany did 9.0h (out of 18.75h assigned), thus carrying over 9.75h to the next month.
  • Roberto C. S nchez did 10.25h (out of 18.5h assigned and 2.75h from previous period), thus carrying over 11.0h to the next month.
  • Santiago Ruano Rinc n did 7.25h (out of 12.75h assigned and 2.25h from previous period), thus carrying over 7.75h to the next month.
  • Sylvain Beucler did 18.75h (out of 18.75h assigned).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Utkarsh Gupta did 15.0h (out of 1.0h assigned and 14.0h from previous period).

Evolution of the situation In July, we released 24 DLAs.
  • Notable security updates:
    • angular.js, prepared by Bastien Roucari s, fixes multiple vulnerabilities including input sanitization and potential regular expression denial of service (ReDoS)
    • tomcat9, prepared by Markus Koschany, fixes an assortment of vulnerabilities
    • mediawiki, prepared by Guilhem Moulin, fixes several information disclosure and privilege escalation vulnerabilities
    • php7.4, prepared by Guilhem Moulin, fixes several server side request forgery and denial of service vulnerabilities
This month s contributions from outside the regular team include an update to thunderbird, prepared by Christoph Goehre (the package maintainer). LTS Team members also contributed updates of the following packages:
  • commons-beanutils (to stable and unstable), prepared by Adrian Bunk
  • djvulibre (to oldstable, stable, and unstable), prepared by Adrian Bunk
  • git (to stable), prepared by Adrian Bunk
  • redis (to oldstable), prepared by Chris Lamb
  • libxml2 (to oldstable), prepared by Guilhem Moulin
  • commons-vfs (to oldstable), prepared by Daniel Leidert
Additionally, LTS Team member Santiago Ruano Rinc n proposed and implemented an improvement to the debian-security-support package. This package is available so that interested users can quickly determine if any installed packages are subject to limited security support or are excluded entirely from security support. However, there was not previously a way to identify explicitly supported packages, which has become necessary to note exceptions to broad exclusion policies (e.g., those which apply to substantial package groups, like modules belonging to the Go and Rust language ecosystems). Santiago s work has enabled the notation of exceptions to these exclusions, thus ensuring that users of debian-security-support have accurate status information concerning installed packages.

DebCamp 25 Security Tracker Sprint The previously announced security tracker sprint took place at DebCamp from 7-13 July. Participants included 8 members of the standing LTS Team, 2 active Debian Developers with an interest in LTS, 3 community members, and 1 member of the Debian Security Team (who provided guidance and reviews on proposed changes to the security tracker); participation was a mix of in person at the venue in Brest, France and remote. During the days of the sprint, the team tackled a wide range of bugs and improvements, mostly targeting the security tracker. The sprint participants worked on the following items: As can be seen from the above list, only a small number of changes were brought to completion during the sprint week itself. Given the very compressed timeframe involved, the broad scope of tasks which were under consideration, and the highly sensitive data managed by the security tracker, this is not entirely unexpected and in no way diminishes the great work done by the sprint participants. The LTS Team would especially like to thank Salvatore Bonaccorso of the Debian Security Team for making himself available throughout the sprint to answer questions, for providing guidance on the work, and for helping the work by reviewing and merging the MRs which were able to merged during the sprint itself. In the weeks that follow the sprint, the team will continue working towards completing the in progress items.

Thanks to our sponsors Sponsors that joined recently are in bold.

12 August 2025

Freexian Collaborators: Debian Contributions: DebConf 25, OpenSSH upgrades, Cross compilation collaboration and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-07 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 25, by Stefano Rivera and Santiago Ruano Rinc n In July, DebConf 25 was held in Brest, France. Freexian was a gold sponsor and most of the Freexian team attended the event. Many fruitful discussions were had amongst our team and within the Debian community. DebConf itself was organized by a local team in Brest, that included Santiago (who now lives in Uruguay). Stefano was also deeply involved in the organization, as a DebConf committee member, core video team, and the lead developer for the conference website. Running the conference took an enormous amount of work, consuming all of Stefano and Santiago s time for most of July. Lucas Kanashiro was active in the DebConf content team, reviewing talks and scheduling them. There were many last-minute changes to make during the event. Anupa Ann Joseph was part of the Debian publicity team doing live coverage of DebConf 25 and was part of the DebConf 25 content team reviewing the talks. She also assisted the local team to procure the lanyards. Recorded sessions presented by Freexian collaborators, often alongside other friends in Debian, included:

OpenSSH upgrades, by Colin Watson Towards the end of a release cycle, people tend to do more upgrade testing, and this sometimes results in interesting problems. Manfred Stock reported No new SSH connections possible during large part of upgrade to Debian Trixie , which would have affected many people upgrading from Debian 12 (bookworm), with potentially severe consequences for people upgrading remote systems. In fact, there were two independent problems that each led to much the same symptom:
  • As part of hardening the OpenSSH server, OpenSSH 9.8 split the monolithic sshd listener process into two pieces: a minimal network listener (still called sshd), and an sshd-session process dealing with each individual session. Before this change, when sshd received an incoming connection, it forked and re-executed itself with some special parameters to deal with it; after this change, it forks and executes sshd-session instead, and sshd no longer accepts the parameters it used to accept for this.

    Debian package upgrades happen (roughly) in two phases: first we unpack the new files onto disk, and then we run some configuration steps which usually include things like restarting services. Normally this is fine, because the old service keeps on working until it s restarted. In this case, unpacking the new files onto disk immediately stopped new SSH connections from working: the old sshd received the connection and tried to hand it off to a freshly-executed copy of the new sshd binary on disk, which no longer supports this. This wasn t much of a problem when upgrading OpenSSH on its own or with a small number of other packages, but in release upgrades it left a large gap when you can t SSH to the system any more, and if anything fails in that interval then you could be in trouble.

    After trying a couple of other approaches, Colin landed on the idea of having the openssh-server package divert /usr/sbin/sshd to /usr/sbin/sshd.session-split before the unpack step of an upgrade from before 9.8, then removing the diversion and moving the new file into place once it s ready to restart the service. This reduces the period when new connections fail to a minimum.
  • Most OpenSSH processes, including sshd, check for a compatible version of the OpenSSL library when they start up. This check used to be very picky, among other things requiring both the major and minor part of the version number to match. OpenSSL 3 has a better versioning policy, and so OpenSSH 9.4p1 relaxed this check.

    Unfortunately, bookworm shipped with OpenSSH 9.2p1, so as soon as you unpacked the new OpenSSL library during an upgrade, sshd stopped working. This couldn t be fixed by a change in trixie; we needed to change bookworm in advance of the upgrade so that it would tolerate newer versions of OpenSSL, and time was tight if we wanted this to be available before the release of Debian 13.

    Fortunately, there s a stable-updates mechanism for exactly this sort of thing, and the stable release managers kindly accepted Colin s proposal to fix this there.
The net result is that if you apply updates to bookworm (including stable-updates / bookworm-updates, which is enabled by default) before starting the upgrade to trixie, everything should be fine.

Cross compilation collaboration, by Helmut Grohne Supporting cross building in Debian packages touches lots of areas of the archive and quite some of these matters reside in shared responsibility between different teams. Hence, DebConf was an ideal opportunity to settle long-standing issues. The cross building bof sparked lively discussions as a significant fraction of developers employ cross builds to get their work done. In the trixie release, about two thirds of the packages can satisfy their cross Build-Depends and about half of the packages actually can be cross built.

Miscellaneous contributions
  • Rapha l Hertzog updated tracker.debian.org to remove references to Debian 10 which was moved to archive.debian.org, and had many fruitful discussions related to Debusine during DebConf 25.
  • Carles Pina prepared some data, questions and information for the DebConf 25 l10n and i18n BoF.
  • Carles Pina demoed and discussed possible next steps for po-debconf-manager with different teams in DebConf 25. He also reviewed Catalan translations and sent them to the packages.
  • Carles Pina started investigating a django-compressor bug: reproduced the bug consistently and prepared a PR for django-compressor upstream (likely more details next month). Looked at packaging frictionless-py.
  • Stefano Rivera triaged Python CVEs against pypy3.
  • Stefano prepared an upload of a new upstream release of pypy3 to Debian experimental (due to the freeze).
  • Stefano uploaded python3.14 RC1 to Debian experimental.
  • Thorsten Alteholz uploaded a new upstream version of sane-airscan to experimental. He also started to work on a new upstream version of hplip.
  • Colin backported fixes for CVE-2025-50181 and CVE-2025-50182 in python-urllib3, and fixed several other release-critical or important bugs in Python team packages.
  • Lucas uploaded ruby3.4 to experimental as a starting point for the ruby-defaults transition that will happen after Trixie release.
  • Lucas coordinated with the Release team the fix of the remaining RC bugs involving ruby packages, and got them all fixed.
  • Lucas, as part of the Debian Ruby team, kicked off discussions to improve internal process/tooling.
  • Lucas, as part of the Debian Outreach team, engaged in multiple discussions around internship programs we run and also what else we could do to improve outreach in the Debian project.
  • Lucas joined the Local groups BoF during DebConf 25 and shared all the good experiences from the Brazilian community and committed to help to document everything to try to support other groups.
  • Helmut spent significant time with Samuel Thibault on improving architecture cross bootstrap for hurd-any mostly reviewing Samuel s patches. He proposed a patch for improving bash s detection of its pipesize and a change to dpkg-shlibdeps to improve behavior for building cross toolchains.
  • Helmut reiterated the multiarch policy proposal with a lot of help from Nattie Mayer-Hutchings, Rhonda D Vine and Stuart Prescott.
  • Helmut finished his work on the process based unschroot prototype that was the main feature of his talk (see above).
  • Helmut analyzed a multiarch-related glibc upgrade failure induced by a /usr-move mitigation of systemd and sent a patch and regression fix both of which reached trixie in time. Thanks to Aurelien Jarno and the release team for their timely cooperation.
  • Helmut resurrected an earlier discussion about changing the semantics of Architecture: all packages in a multiarch context in order to improve the long-standing interpreter problem. With help from Tollef Fog Heen better semantics were discovered and agreement was reached with Guillem Jover and Julian Andres Klode to consider this change. The idea is to record a concrete architecture for every Architecture: all package in the dpkg database and enable choosing it as non-native.
  • Helmut implemented type hints for piuparts.
  • Helmut reviewed and improved a patch set of Jochen Sprickerhof for debvm.
  • Anupa was involved in discussions with the Debian Women team during DebConf 25.
  • Anupa started working for the trixie release coverage and started coordinating release parties.
  • Emilio helped coordinate the release of Debian 13 trixie.

10 August 2025

Jonathan Carter: Debian 13

Debian 13 has finally been released! One of the biggest and under-hyped features is support for HTTP Boot. This allows you to simply specify a URL (to any d-i or live image iso) in your computer s firmware setup and then you can boot to it directly over the Internet, so no need to download an image, write it to flash disk and then boot from the flash disk on computers made in the last ~5 years. This is also supported on the Tianocore free EFI firmware, which is useful if you d like to try it out on QEMU/KVM. More details about Debian 13 available on the official press release. The default theme for Debian 13 is Ceratopsian, designed by Elise Couper. I ll be honest, I wasn t 100% sure it was the best choice when it won the artwork vote, but it really grew on me over the last few months, and it looked great in combination with all kinds of other things during DebConf too, so it has certainly won me over.
And I particularly like the Plymouth theme. It s very minimal, and it reminds me of the Toy Story Trixie character, it s almost like it helps explain the theme:

Plymouth (start-up/shutdown) theme.

Trixie, the character from Toy Story that was chosen as the codename for Debian 13.

Debian Local Team ISO testing Yesterday we got some locals together for ISO testing and we got a cake with the wallpaper printed on it, along with our local team logo which has been a work in progress for the last 3 years, so hopefully we ll finalise it this year! (it will be ready when it s ready). It came out a lot bluer than the original wallpaper, but still tasted great.
For many releases, I ve been the only person from South Africa doing ISO smoke-testing, and this time was quite different, since everyone else in the photo below tested an image except for me. I basically just provided some support and helped out with getting salsa/wiki accounts and some troubleshooting. It went nice and fast, and it s always a big relief when there are no showstoppers for the release.

My dog was really wishing hard that the cake would slip off.

Packaging-wise, I only have one big new package for Trixie, and that s Cambalache, a rapid application design UI builder for GTK3/GTK4.
The version in trixie is 0.94.1-3 and version 1.0 was recently released, so I ll get that updated in forky and backport it if possible. I was originally considering using Cambalache for an installer UI, but ended up going with a web front-end instead. But that s moving firmly towards forky territory, so more on that another time! Thanks to everyone who was involved in this release, so far upgrades have been very smooth!

6 August 2025

Reproducible Builds: Reproducible Builds in July 2025

Welcome to the seventh report from the Reproducible Builds project in 2025. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:
  1. Reproducible Builds Summit 2025
  2. Reproducible Builds an official goal for SUSE Enterprise Linux
  3. Reproducible Builds at FOSSY 2025
  4. New OSS Rebuild project from Google
  5. New extension of Python setuptools to support reproducible builds
  6. diffoscope
  7. New library to patch system functions for reproducibility
  8. Independently Reproducible Git Bundles
  9. Website updates
  10. Distribution work
  11. Reproducibility testing framework
  12. Upstream patches

Reproducible Builds Summit 2025 We are extremely pleased to announce the upcoming Reproducible Builds Summit, set to take place from October 28th 30th 2025 in Vienna, Austria! We are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving. If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. Registration is open until 20th September 2025, and we are very much looking forward to seeing many readers of these reports there!

Reproducible Builds an official goal for SUSE Enterprise Linux On our mailing list this month, Bernhard M. Wiedemann revealed the big news that reproducibility is now an official goal for SUSE Linux Enterprise Server (SLES) 16:
[Everything] changed earlier this year when reproducible-builds for SLES-16 became an official goal for the product. More people are talking about digital sovereignty and supply-chain security now. [ ] Today, only 9 of 3319 (source) packages have significant problems left (plus 7 with pending fixes), so 99.5% of packages have reproducible builds.

Reproducible Builds at FOSSY 2025 On Saturday 2nd August, Vagrant Cascadian and Chris Lamb presented at this year s FOSSY 2025. Their talk, titled Never Mind the Checkboxes, Here s Reproducible Builds!, was introduced as follows:
There are numerous policy compliance and regulatory processes being developed that target software development but do they solve actual problems? Does it improve the quality of software? Do Software Bill of Materials (SBOMs) actually give you the information necessary to verify how a given software artifact was built? What is the goal of all these compliance checklists anyways or more importantly, what should the goals be? If a software object is signed, who should be trusted to sign it, and can they be trusted forever?
Hosted by the Software Freedom Conservancy and taking place in Portland, Oregon, USA, FOSSY aims to be a community-focused event: Whether you are a long time contributing member of a free software project, a recent graduate of a coding bootcamp or university, or just have an interest in the possibilities that free and open source software bring, FOSSY will have something for you . More information on the event is available on the FOSSY 2025 website, including the full programme schedule. Vagrant and Chris also staffed a table, where they will be available to answer any questions about Reproducible Builds and discuss collaborations with other projects.

New OSS Rebuild project from Google The Google Open Source Security Team (GOSST) published an article this month announcing OSS Rebuild, a new project to strengthen trust in open source package ecosystems by reproducing upstream artifacts. As the post itself documents, the new project comprises four facets:
  • Automation to derive declarative build definitions for existing PyPI (Python), npm (JS/TS), and Crates.io (Rust) packages.
  • SLSA Provenance for thousands of packages across our supported ecosystems, meeting SLSA Build Level 3 requirements with no publisher intervention.
  • Build observability and verification tools that security teams can integrate into their existing vulnerability management workflows.
  • Infrastructure definitions to allow organizations to easily run their own instances of OSS Rebuild to rebuild, generate, sign, and distribute provenance.
One difference with most projects that aim for bit-for-bit reproducibility, OSS Rebuild aims for a kind of semantic reproducibility:
Through automation and heuristics, we determine a prospective build definition for a target package and rebuild it. We semantically compare the result with the existing upstream artifact, normalizing each one to remove instabilities that cause bit-for-bit comparisons to fail (e.g. archive compression).
The extensive post includes examples about how to access OSS Rebuild attestations using the Go-based command-line interface.

New extension of Python setuptools to support reproducible builds Wim Jeantine-Glenn has written a PEP 517 Build backend in order to enable reproducible builds when building Python projects that use setuptools. Called setuptools-reproducible, the project s README file contains the following:
Setuptools can create reproducible wheel archives (.whl) by setting SOURCE_DATE_EPOCH at build time, but setting the env var is insufficient for creating reproducible sdists (.tar.gz). setuptools-reproducible [therefore] wraps the hooks build_sdist build_wheel with some modifications to make reproducible builds by default.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 301, 302 and 303 to Debian:
  • Improvements:
    • Use Difference.from_operation in an attempt to pipeline the output of the extract-vmlinux script, potentially avoiding it all in memory. [ ]
    • Memoize a number of calls to --version, saving a very large number of external subprocess calls.
  • Bug fixes:
    • Don t check for PyPDF version 3 specifically, check for versions greater than 3. [ ]
    • Ensure that Java class files are named .class on the filesystem before passing them to javap(1). [ ]
    • Mask stderr from extract-vmlinux script. [ ][ ]
    • Avoid spurious differences in h5dump output caused by exposure of absolute internal extraction paths. (#1108690)
  • Misc:
    • Use our_check_output in the ODT comparator. [ ]
    • Update copyright years. [ ]
In addition: Lastly, Chris Lamb added a tmpfs to try.diffoscope.org so that diffoscope has a non-trivial temporary area to unpack archives, etc. [ ] Elsewhere in our tooling, however, reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.30 was uploaded to Debian unstable by Holger Levsen, chiefly including a change by Rebecca N. Palmer to not call sudo with the -h flag in order to fix Debian bug #1108550. [ ]

New library to patch system functions for reproducibility Nicolas Graves has written and published libfate, a simple collection of tiny libraries to patch system functions deterministically using LD_PRELOAD. According to the project s README:
libfate provides deterministic replacements for common non-deterministic system functions that can break reproducible builds. Instead of relying on complex build systems or apps or extensive patching, libfate uses the LD_PRELOAD trick to intercept system calls and return fixed, predictable values.
Describing why he wrote it, Nicolas writes:
I originally used the OpenSUSE dettrace approach to make Emacs reproducible in Guix. But when Guix switch to GCC@14, dettrace stopped working as expected. dettrace is a complex piece of software, my need was much less heavy: I don t need to systematically patch all sources of nondetermism, just the ones that make a process/binary unreproducible in a container/chroot.

Independently Reproducible Git Bundles Simon Josefsson has published another interesting article this month. Titled Independently Reproducible Git Bundles, the blog post describes the advantages of why you might a reproducible bundle, and the pitfalls that can arise when trying to create them:
One desirable property is that someone else should be able to reproduce the same git bundle, and not only that a single individual is able to reproduce things on one machine. It surprised me to see that when I ran the same set of commands on a different machine (started from a fresh git clone), I got a different checksum. The different checksums occurred even when nothing had been committed on the server side between the two runs.

Website updates Once again, there were a number of improvements made to our website this month including:

Distribution work In Debian this month:
Debian contributors have made significant progress toward ensuring package builds produce byte-for-byte reproducible results. You can check the status for packages installed on your system using the new package debian-repro-status, or visit reproduce.debian.net for Debian s overall statistics for trixie and later. You can contribute to these efforts by joining #debian-reproducible on IRC to discuss fixes, or verify the statistics by installing the new rebuilderd package and setting up your own instance.

The IzzyOnDroid Android APK repository made further progress in July, crossing the 50% reproducibility threshold congratulations. Furthermore, a new release of the Neo Store was released, which exposes the reproducible status directly next to the version of each app.
In GNU Guix, a series of patches intended to fix the reproducibility for the Mono programming language was merged, fixing reproducibility in Mono versions 1.9 [ ], 2.4 [ ] and 2.6 [ ].
Lastly, in addition to the news that openSUSE Enterprise Linux now [has an official goal of reproducibility]((https://lists.reproducible-builds.org/pipermail/rb-general/2025-July/003846.html), Bernhard M. Wiedemann posted another monthly update for their work there.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In July, however, a number of changes were made by Holger Levsen, including:
  • Switch the URL for the Tails package set. [ ]
  • Make the dsa-check-packages output more useful. [ ]
  • Setup the ppc64el architecture again, has it has returned this time with a 2.7 GiB database instead of 72 GiB. [ ]
In addition, Jochen Sprickerhof improved the reproducibility statistics generation:
  • Enable caching of statistics. [ ][ ][ ]
  • Add some common non-reproducible patterns. [ ]
  • Change output to directory. [ ]
  • Add a page sorted by diffoscope size. [ ][ ]
  • Switch to Python s argparse module and separate output(). [ ]
Holger also submitted a number of Debian bugs against rebuilderd and rebuilderd-worker:
  • Config files and scripts for a simple one machine setup. [ ][ ]
  • Create a rebuilderd user. [ ]
  • Create rebuilderd-worker user with sbuild. [ ]
Lastly, Mattia Rizzolo added a scheduled job to renew some SSL certificates [ ] and Vagrant Cascadian performed some node maintenance [ ][ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: There were a number of other patches from openSUSE developers:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Colin Watson: Free software activity in July 2025

About 90% of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. DebConf I attended DebConf for the first time in 11 years (my last one was DebConf 14 in Portland). It was great! For once I had a conference where I had a fairly light load of things I absolutely had to do, so I was able to spend time catching up with old friends, making some new friends, and doing some volunteering - a bit of Front Desk, and quite a lot of video team work where I got to play with sound desks and such. Apparently one of the BoFs ( birds of a feather , i.e. relatively open discussion sessions) where I was talkmeister managed to break the automatic video cutting system by starting and ending precisely on time, to the second, which I m told has never happened before. I ll take that. I gave a talk about Debusine, along with helping Enrico run a Debusine BoF. We still need to process some of the feedback from this, but are generally pretty thrilled about the reception. My personal highlight was getting a shout-out in a talk from CERN (in the slide starting at 32:55). Other highlights for me included a Python team BoF, Ian s tag2upload talk and some very useful follow-up discussions, a session on archive-wide testing, a somewhat brain-melting whiteboard session about the multiarch interpreter problem , several useful discussions about salsa.debian.org, Matthew s talk on how Wikimedia automates their Debian package builds, and many others. I hope I can start attending regularly again! OpenSSH Towards the end of a release cycle, people tend to do more upgrade testing, and this sometimes results in interesting problems. Manfred Stock reported No new SSH connections possible during large part of upgrade to Debian Trixie , and after a little testing in a container I confirmed that this was a reproducible problem that would have affected many people upgrading from Debian 12 (bookworm), with potentially severe consequences for people upgrading remote systems. In fact, there were two independent problems that each led to much the same symptom: The net result is that if you apply updates to bookworm (including stable-updates / bookworm-updates, which is enabled by default) before starting the upgrade to trixie, everything should be fine. Many thanks to Manfred for reporting this with just enough time to spare that we were able to fix it before Debian 13 is released in a few days! debmirror I did my twice-yearly refresh of debmirror s mirror_size documentation, and applied a patch from Christoph Goehre to improve mirroring of installer files. madison-lite I proposed renaming this project along with the rmadison tool in devscripts, although I m not yet sure what a good replacement name would be. Python team I upgraded python-expandvars, python-typing-extensions (in experimental), and webtest to new upstream versions. I backported fixes for some security vulnerabilities to unstable: I fixed or helped to fix a number of release-critical bugs: I fixed some other bugs, mostly Severity: important: I reinstated python3-mastodon s build-dependency on and recommendation of python3-blurhash, now that the latter has been fixed to use the correct upstream source.

5 August 2025

Matthew Garrett: Cordoomceps - replacing an Amiga's brain with Doom

There's a lovely device called a pistorm, an adapter board that glues a Raspberry Pi GPIO bus to a Motorola 68000 bus. The intended use case is that you plug it into a 68000 device and then run an emulator that reads instructions from hardware (ROM or RAM) and emulates them. You're still limited by the ~7MHz bus that the hardware is running at, but you can run the instructions as fast as you want.

These days you're supposed to run a custom built OS on the Pi that just does 68000 emulation, but initially it ran Linux on the Pi and a userland 68000 emulator process. And, well, that got me thinking. The emulator takes 68000 instructions, emulates them, and then talks to the hardware to implement the effects of those instructions. What if we, well, just don't? What if we just run all of our code in Linux on an ARM core and then talk to the Amiga hardware?

We're going to ignore x86 here, because it's weird - but most hardware that wants software to be able to communicate with it maps itself into the same address space that RAM is in. You can write to a byte of RAM, or you can write to a piece of hardware that's effectively pretending to be RAM[1]. The Amiga wasn't unusual in this respect in the 80s, and to talk to the graphics hardware you speak to a special address range that gets sent to that hardware instead of to RAM. The CPU knows nothing about this. It just indicates it wants to write to an address, and then sends the data.

So, if we are the CPU, we can just indicate that we want to write to an address, and provide the data. And those addresses can correspond to the hardware. So, we can write to the RAM that belongs to the Amiga, and we can write to the hardware that isn't RAM but pretends to be. And that means we can run whatever we want on the Pi and then access Amiga hardware.

And, obviously, the thing we want to run is Doom, because that's what everyone runs in fucked up hardware situations.

Doom was Amiga kryptonite. Its entire graphical model was based on memory directly representing the contents of your display, and being able to modify that by just moving pixels around. This worked because at the time VGA displays supported having a memory layout where each pixel on your screen was represented by a byte in memory containing an 8 bit value that corresponded to a lookup table containing the RGB value for that pixel.

The Amiga was, well, not good at this. Back in the 80s, when the Amiga hardware was developed, memory was expensive. Dedicating that much RAM to the video hardware was unthinkable - the Amiga 1000 initially shipped with only 256K of RAM, and you could fill all of that with a sufficiently colourful picture. So instead of having the idea of each pixel being associated with a specific area of memory, the Amiga used bitmaps. A bitmap is an area of memory that represents the screen, but only represents one bit of the colour depth. If you have a black and white display, you only need one bitmap. If you want to display four colours, you need two. More colours, more bitmaps. And each bitmap is stored in an independent area of RAM. You never use more memory than you need to display the number of colours you want to.

But that means that each bitplane contains packed information - every byte of data in a bitplane contains the bit value for 8 different pixels, because each bitplane contains one bit of information per pixel. To update one pixel on screen, you need to read from every bitmap, update one bit, and write it back, and that's a lot of additional memory accesses. Doom, but on the Amiga, was slow not just because the CPU was slow, but because there was a lot of manipulation of data to turn it into the format the Amiga wanted and then push that over a fairly slow memory bus to have it displayed.

The CDTV was an aesthetically pleasing piece of hardware that absolutely sucked. It was an Amiga 500 in a hi-fi box with a caddy-loading CD drive, and it ran software that was just awful. There's no path to remediation here. No compelling apps were ever released. It's a terrible device. I love it. I bought one in 1996 because a local computer store had one and I pointed out that the company selling it had gone bankrupt some years earlier and literally nobody in my farming town was ever going to have any interest in buying a CD player that made a whirring noise when you turned it on because it had a fan and eventually they just sold it to me for not much money, and ever since then I wanted to have a CD player that ran Linux and well spoiler 30 years later I'm nearly there. That CDTV is going to be our test subject. We're going to try to get Doom running on it without executing any 68000 instructions.

We're facing two main problems here. The first is that all Amigas have a firmware ROM called Kickstart that runs at powerup. No matter how little you care about using any OS functionality, you can't start running your code until Kickstart has run. This means even documentation describing bare metal Amiga programming assumes that the hardware is already in the state that Kickstart left it in. This will become important later. The second is that we're going to need to actually write the code to use the Amiga hardware.

First, let's talk about Amiga graphics. We've already covered bitmaps, but for anyone used to modern hardware that's not the weirdest thing about what we're dealing with here. The CDTV's chipset supports a maximum of 64 colours in a mode called "Extra Half-Brite", or EHB, where you have 32 colours arbitrarily chosen from a palette and then 32 more colours that are identical but with half the intensity. For 64 colours we need 6 bitplanes, each of which can be located arbitrarily in the region of RAM accessible to the chipset ("chip RAM", distinguished from "fast ram" that's only accessible to the CPU). We tell the chipset where our bitplanes are and it displays them. Or, well, it does for a frame - after that the registers that pointed at our bitplanes no longer do, because when the hardware was DMAing through the bitplanes to display them it was incrementing those registers to point at the next address to DMA from. Which means that every frame we need to set those registers back.

Making sure you have code that's called every frame just to make your graphics work sounds intensely irritating, so Commodore gave us a way to avoid doing that. The chipset includes a coprocessor called "copper". Copper doesn't have a large set of features - in fact, it only has three. The first is that it can program chipset registers. The second is that it can wait for a specific point in screen scanout. The third (which we don't care about here) is that it can optionally skip an instruction if a certain point in screen scanout has already been reached. We can write a program (a "copper list") for the copper that tells it to program the chipset registers with the locations of our bitplanes and then wait until the end of the frame, at which point it will repeat the process. Now our bitplane pointers are always valid at the start of a frame.

Ok! We know how to display stuff. Now we just need to deal with not having 256 colours, and the whole "Doom expects pixels" thing. For the first of these, I stole code from ADoom, the only Amiga doom port I could easily find source for. This looks at the 256 colour palette loaded by Doom and calculates the closest approximation it can within the constraints of EHB. ADoom also includes a bunch of CPU-specific assembly optimisation for converting the "chunky" Doom graphic buffer into the "planar" Amiga bitplanes, none of which I used because (a) it's all for 68000 series CPUs and we're running on ARM, and (b) I have a quad core CPU running at 1.4GHz and I'm going to be pushing all the graphics over a 7.14MHz bus, the graphics mode conversion is not going to be the bottleneck here. Instead I just wrote a series of nested for loops that iterate through each pixel and update each bitplane and called it a day. The set of bitplanes I'm operating on here is allocated on the Linux side so I can read and write to them without being restricted by the speed of the Amiga bus (remember, each byte in each bitplane is going to be updated 8 times per frame, because it holds bits associated with 8 pixels), and then copied over to the Amiga's RAM once the frame is complete.

And, kind of astonishingly, this works! Once I'd figured out where I was going wrong with RGB ordering and which order the bitplanes go in, I had a recognisable copy of Doom running. Unfortunately there were weird graphical glitches - sometimes blocks would be entirely the wrong colour. It took me a while to figure out what was going on and then I felt stupid. Recording the screen and watching in slow motion revealed that the glitches often showed parts of two frames displaying at once. The Amiga hardware is taking responsibility for scanning out the frames, and the code on the Linux side isn't synchronised with it at all. That means I could update the bitplanes while the Amiga was scanning them out, resulting in a mashup of planes from two different Doom frames being used as one Amiga frame. One approach to avoid this would be to tie the Doom event loop to the Amiga, blocking my writes until the end of scanout. The other is to use double-buffering - have two sets of bitplanes, one being displayed and the other being written to. This consumes more RAM but since I'm not using the Amiga RAM for anything else that's not a problem. With this approach I have two copper lists, one for each set of bitplanes, and switch between them on each frame. This improved things a lot but not entirely, and there's still glitches when the palette is being updated (because there's only one set of colour registers), something Doom does rather a lot, so I'm going to need to implement proper synchronisation.

Except. This was only working if I ran a 68K emulator first in order to run Kickstart. If I tried accessing the hardware without doing that, things were in a weird state. I could update the colour registers, but accessing RAM didn't work - I could read stuff out, but anything I wrote vanished. Some more digging cleared that up. When you turn on a CPU it needs to start executing code from somewhere. On modern x86 systems it starts from a hardcoded address of 0xFFFFFFF0, which was traditionally a long way any RAM. The 68000 family instead reads its start address from address 0x00000004, which overlaps with where the Amiga chip RAM is. We can't write anything to RAM until we're executing code, and we can't execute code until we tell the CPU where the code is, which seems like a problem. This is solved on the Amiga by powering up in a state where the Kickstart ROM is "overlayed" onto address 0. The CPU reads the start address from the ROM, which causes it to jump into the ROM and start executing code there. Early on, the code tells the hardware to stop overlaying the ROM onto the low addresses, and now the RAM is available. This is poorly documented because it's not something you need to care if you execute Kickstart which every actual Amiga does and I'm only in this position because I've made poor life choices, but ok that explained things. To turn off the overlay you write to a register in one of the Complex Interface Adaptor (CIA) chips, and things start working like you'd expect.

Except, they don't. Writing to that register did nothing for me. I assumed that there was some other register I needed to write to first, and went to the extent of tracing every register access that occurred when running the emulator and replaying those in my code. Nope, still broken. What I finally discovered is that you need to pulse the reset line on the board before some of the hardware starts working - powering it up doesn't put you in a well defined state, but resetting it does.

So, I now have a slightly graphically glitchy copy of Doom running without any sound, displaying on an Amiga whose brain has been replaced with a parasitic Linux. Further updates will likely make things even worse. Code is, of course, available.

[1] This is why we had trouble with late era 32 bit systems and 4GB of RAM - a bunch of your hardware wanted to be in the same address space and so you couldn't put RAM there so you ended up with less than 4GB of RAM

comment count unavailable comments

4 August 2025

Freexian Collaborators: Secure boot signing with Debusine (by Colin Watson)

Debusine aims to be an integrated solution to build, distribute and maintain a Debian-based distribution. At Debconf 25, we talked about using it to pre-test uploads to Debian unstable, and also touched on how Freexian is using it to help maintain the Debian LTS and ELTS projects. When Debian 10 (buster) moved to ELTS status in 2024, this came with a new difficulty that hadn t existed for earlier releases. Debian 10 added UEFI Secure Boot support, meaning that there are now signed variants of the boot loader and Linux kernel packages. Debian has a system where certain packages are configured as needing to be signed, and those packages include a template for a source package along with the unsigned objects themselves. The signing service generates detached signatures for all those objects, and then uses the template to build a source package that it uploads back to the archive for building in the usual way. Once buster moved to ELTS, it could no longer rely on Debian s signing service for all this. Freexian operates parallel infrastructure for the archive, and now needed to operate a parallel signing service as well. By early 2024 we were already planning to move ELTS infrastructure towards Debusine, and so it made sense to build a signing service there as well. Separately, we were able to obtain a Microsoft signature for Freexian s shim build, allowing us to chain this into the trust path for most deployed x86 machines. Freexian can help other organizations running Debian derivatives through the same process, and can provide secure signing infrastructure to the standards required for UEFI Secure Boot.

Prior art We considered both code-signing (Debian s current implementation) and lp-signing (Ubuntu s current implementation) as prior art. Neither was quite suitable for various reasons.
  • code-signing relies on polling a configured URL for each archive to fetch a GPG-signed list of signing requests, which would have been awkward for us to set up, and it assumes that unsigned packages are sufficiently trusted for it to be able to run dpkg -x and dpkg-source -b on them outside any containment. dpkg -x has had the occasional security vulnerability, so this seemed unwise for a service that might need to deal with signing packages for multiple customers.
  • lp-signing is a microservice accepting authenticated requests, and is careful to avoid needing to manipulate packages itself. However, this relies on a different and incompatible mechanism for indicating that packages should be signed, which wasn t something we wanted to introduce in ELTS.

Workers Debusine already had an established system of external workers that run tasks under various kinds of containment. This seems like a good fit: after all, what s a request to sign a package but a particular kind of task? But there are some problems here: workers can run essentially arbitrary code (such as build scripts in source packages), and even though that s under containment, we don t want to give such machines access to highly-sensitive data such as private keys. Fortunately, we d already introduced the idea of different kinds of workers a few months beforehand, in order to be able to run privileged server tasks that have direct access to the Debusine database. We built on that and added signing workers , which are much like external workers except that they only run signing tasks, no other types of tasks run on them, and they have access to a private database with information about the keys managed by their Debusine instance. (Django s support for multiple databases made this quite easy to arrange: we were able to keep everything in the same codebase.)

Key management It s obviously bad practice to store private key material in the clear, but at the same time the signing workers are essentially oracles that will return signatures on request while ensuring that the rest of Debusine has no access to private key material, so they need to be able to get hold of it themselves. Hardware security modules (HSMs) are designed for this kind of thing, but they can be inconvenient to manage when large numbers of keys are involved. Some keys are more valuable than others. If the signing key used for an experimental archive leaks, the harm is unlikely to be particularly serious; but if the ELTS signing key leaks, many customers will be affected. To match this, we implemented two key protection arrangements for the time being: one suitable for low-value keys encrypts the key in software with a configured key and stores the public key and ciphertext in the database, while one suitable for high-value keys stores keys as PKCS #11 URIs that can be set up manually by an instance administrator. We packaged some YubiHSM tools to make this easier for our sysadmins. The signing worker calls back to the Debusine server to check whether a given work request is authorized to use a given signing key. All operations related to private keys also produce an audit log entry in the private signing database, so we can track down any misuse.

Tasks Getting Debusine to do anything new usually requires figuring out how to model the operation as a task. In this case, that was complicated by wanting to run as little code as possible on the signing workers: in particular, we didn t want to do all the complicated package manipulations there. The approach we landed on was a chain of three tasks:
  • ExtractForSigning runs on a normal external worker. It takes the result of a package build and picks out the individual files from it that need to be signed, storing them as separate artifacts.
  • Sign runs on a signing worker, and (of course) makes the actual signatures, storing them as artifacts.
  • AssembleSignedSource runs on a normal external worker. It takes the signed artifacts and produces a source package containing them, based on the template found in the unsigned binary package.

Workflows Of course, we don t want people to have to create all those tasks directly and figure out how to connect everything together for themselves, and that s what workflows are good at. The make_signed_source workflow does all the heavy lifting of creating the right tasks with the right input data and making them depend on each other in the right ways, including fanning out multiple copies of all this if there are multiple architectures or multiple template packages involved. Since you probably don t want to stop at just having the signed source packages, it also kicks off builds to produce signed binary packages. Even this is too low-level for most people to use directly, so we wrapped it all up in our debian_pipeline workflow, which just needs to be given a few options to enable signing support (and those options can be locked down by workspace owners).

What s next? In most cases this work has been enough to allow ELTS to carry on issuing kernel security updates without too much disruption, which was the main goal; but there are other uses for a signing system. We included OpenPGP support from early on, which allows Debusine to sign its own builds, and we ll soon be extending that to sign APT repositories hosted by Debusine. The current key protection arrangements could use some work. Supporting automatically-generated software-encrypted keys and manually-generated keys in an HSM is fine as far as it goes, but it would be good to be able to have the best of both worlds by being able to automatically generate keys protected by an HSM. This needs some care, as HSMs often have quite small limits on the number of objects they can store at any one time, and the usual workaround is to export keys from the HSM under wrap (encrypted by a key known only to the HSM) so that they can be imported only when needed. We have a general idea of how to do this, but doing it efficiently will need care. We d be very interested in hearing from organizations that need this sort of thing, especially for Debian derivatives. Debusine provides lots of other features that can help you. Please get in touch with us at sales@freexian.com if any of this sounds useful to you.

3 August 2025

Sergio Cipriano: Handling malicious requests with fail2ban

Handling malicious requests with fail2ban I've been receiving a lot of malicious requests for a while now, so I decided to try out fail2ban as a possible solution. I see fail2ban as nice to have tool that is useful to keep down the "noise", but I wouldn't rely on it for security. If you need a tool to block unauthorized attempts or monitor log files excessively, you are probably doing something wrong. I'm currently using fail2ban 1.0.2-2 from Debian Bookworm. Unfortunatly, I quickly ran into a problem, fail2ban doesn't work out of the box with this version:
systemd[1]: Started fail2ban.service - Fail2Ban Service.
fail2ban-server[2840]: 2025-07-28 14:40:13,450 fail2ban.configreader   [2840]: WARNING 'allowipv6' not defined in 'Definition'. Using default one: 'auto'
fail2ban-server[2840]: 2025-07-28 14:40:13,456 fail2ban                [2840]: ERROR   Failed during configuration: Have not found an y log file for sshd jail
fail2ban-server[2840]: 2025-07-28 14:40:13,456 fail2ban                [2840]: ERROR   Async configuration of server failed
systemd[1]: fail2ban.service: Main process exited, code=exited, status=255/EXCEPTION
systemd[1]: fail2ban.service: Failed with result 'exit-code'.
The good news is that this issue has already been addressed for Debian Trixie. Since I prefer to manage my own configuration, I removed the default file at /etc/fail2ban/jail.d/defaults-debian.conf and replaced it with a custom setup. To fix the earlier issue, I also added a systemd backend to the sshd jail so it would stop expecting a logpath. Here's the configuration I'm using:
$ cat /etc/fail2ban/jail.d/custom.conf 
[DEFAULT]
maxretry = 3
findtime = 24h
bantime  = 24h
[nginx-bad-request]
enabled  = true
port     = http,https
filter   = nginx-bad-request
logpath  = /var/log/nginx/access.log
[nginx-botsearch]
enabled  = true
port     = http,https
filter   = nginx-botsearch
logpath  = /var/log/nginx/access.log
[sshd]
enabled  = true
port     = ssh
filter   = sshd
backend  = systemd
I like to make things explicit, so I did repeat some lines from the default jail.conf file. In the end, I'm quite happy with it so far. Soon after I set it up, fail2ban was already banning a few hosts.
$ sudo fail2ban-client status nginx-bad-request
Status for the jail: nginx-bad-request
 - Filter
    - Currently failed: 42
    - Total failed: 454
 - Actions
    - Currently banned: 12
    - Total banned: 39

Next.

Previous.