Andrew Pollock: [life/americania] Viva la fortnight!
 I'm slowly converting the team I work with to use the term fortnight. It's
so much less ambiguous than "bi-weekly".
(Provoked by Dave
Jones' post)
I'm slowly converting the team I work with to use the term fortnight. It's
so much less ambiguous than "bi-weekly".
(Provoked by Dave
Jones' post)
I first heard about Jon Oxer's home automation setup when he visited Google
last year to give a tech
talk (heh, that's right, I introduced him).
After reading this latest
article on his house, I've come to realise that he's implementing pretty
much every cool thing I wanted to do when I get around to building the
"dream house" (except I'm not too keen to go microchipping myself).
The main difference is Jon's actually electronically inclined, whereas I
have all the ideas, but lack the ability to go hack them together myself.
So many things I'd like to learn, so little time to learn them...
So today is the third anniversary of my first upload of the ISC DHCP v3 package to
Debian.
It all started back in the days of the linux.conf.au 2005 organising
committee. Bob
Edwards, who ran the ANU Department of Computer Science computer
labs (which ran on Debian at the time), was constantly complaining about
bugs like #286011, once he'd found out I was a Debian developer.
So I figured I'd try and do something about it, so I think I emailed the
maintainers, who had been fairly inactive (the last upload before mine was
in July the year before), and asked if they'd like me to NMU the package.
I think Matt Zimmerman emailed me back and told me to knock myself out, and
add myself as an uploader while I was at it, and well, the rest is
history...
I've had fun fixing bugs, trying to clean things up, deal with a pretty
archaic upstream build system and get the package up to current Debian
standards compliance. One of the highlights was being able to finally get
rid of Debian Installer's dependence on the v2 DHCP client package, so we
could finally jettison the v2 packages for Lenny (which reminds me, I still
have to figure out how to handle the transition from Etch with respect to
that).
I've been working hard to try and get as many of the patches in Debian's
DHCP packages incorporated upstream. Unfortunately, they have a totally
unpredictable release cycle, and they have feature releases and bug fix
releases. The feature releases are very few and far between, and they won't
introduce new features into a bugfix release.
Speaking of patches, my personal philosophy is that distribution packages
shouldn't differ radically in behaviour or functionality from their upstream
source, so I've resisted incorporating some of the more deviant patches from
Ubuntu, instead forwarding them directly upstream.
There's still a bit of work to be done with the package. The ISC released
version 3.1.0 a while ago, and that's the version I'm trying to standardise
on for Lenny. It's got new support for a domain-search option,
which means people can stop abusing the domain-name option to set a
domain search list in their clients. The domain-search option is
also honoured by Mac OS X (Leopard), and I dare say Windows Vista probably
supports it as well, but I haven't checked.
Unfortunately the client-side support for the domain-search option
is a bit flaky in 3.1.0, so I'm hoping the ISC will release 3.1.1 real soon
now, as I believe most of the flakiness issues are addressed in it. Of
course, for Lenny to do the right thing consistently with this new option,
#460609 and #465158 need to be resolved also.
The last thing I'm trying to sort out for Lenny is the reasonably in-demand
LDAP patch. It's been floating around out-of-tree for longer than I've been
maintaining the package. Jos L. Redrejo Rodr guez has been kind enough to
clean up the patch for me, so that rather than bastardising the standard
DHCP package to build a dhcp3-server package that has LDAP support, it
basically builds DHCP twice, once with the patch and once without, and the
dhcp3-server-ldap package just diverts /usr/sbin/dhcpd3 out of the
way and plonks in the LDAP-enabled binary in its place. I hope to upload a
new revision of the package that builds this new binary package within the
next week (hopefully this weekend).
After that's done, and hopefully 3.1.1 has been released, and Lenny is out
of the way, I'm going to focus on transitioning away from a versioned set of
DHCP packages. The whole "3" in everything was to allow the v2 and v3
packages to coexist. I've sought advice from the release team about this,
and they said not to bother, but it feels really gross to have the version 4
package (4.0.0 has been released by the ISC for a while now as well) be
still called dhcp3, and to install into /etc/dhcp3 and other such
versioned directories.
The final thing I want to look into is collaborative maintenance. I've been
wanting to do this for a while, but I wanted to get the package into a
revision control system (shock horror, it's not currently) and I've been
baulking at how to do it the "right" way. I'm pretty sold on using Git for
the revision control system, I just haven't figured out the right approach
yet. Martin Krafft's articles about it
have been interesting, but feel a bit overly advanced, and don't quite suit
my situation. I've been hesitant to start using Git, then discover I've done
it all wrong, and have to start again. I need to just bite the bullet. My
upstream also doesn't use Git, and doesn't make their revision control
system publicly available, so I just get the tarballs when they're released.
Speaking of upstream, I made the discovery last year that they're just down
the road from me in Redwood City, so I've been trying to improve relations
by getting the main folks who work on DHCP at ISC to pop up to Google for
lunch every now and then, which so far has happened twice, and been good a
opportunity to have a chat. In fact, they're keen for Debian to join the
DHCP Forum (Debian is already
a member of the BIND Forum) and I think they've started talking to the
Debian folks responsible for our BIND Forum membership about extending that
to cover the DHCP Forum as well.
So that's about it. I think after three years of being the sole uploader,
I'll formally put myself in as the maintainer and Eloy as an uploader until
I get around to implementing collaborative maintenance.
Jeremy Visser writes about the evilness
of User-Agent sniffing
I tend to disagree with him, particularly after reading Wikipedia's
robots.txt file, and some of the comments in there.
wget can be quite a nasty program if used incorrectly. Chances are,
if you know what you're doing, you'll know how to change the User-Agent
string, and therefore you're probably not going to do something dumb like
try to download the entire site recursively.
If you don't, you're probably Doing It Wrong.
One of Sarah's university subjects this semester is a statistics course. One
of the requirements of this course is some software package that only runs
on Windows. As the only Windows machines in the house are my laptop, which
dual-boots between Linux and Windows XP and goes for many months without XP
seeing the light of day, and our desktop, which dual-boots between Linux and
an ageing Windows 2000 installation (which blue-screens on boot at the
moment because I have a Sun Quad Fast-Ethernet card in it), we figured it
might be a good idea to look into getting a copy of Windows XP (especially
before it stops becoming available). I wouldn't buy Vista, given all the bad
things I've heard about it.
The game plan was to either throw it on the desktop (and see if it tolerated
the QFE card better than 2000) or try out Boot Camp on Sarah's MacBook Pro.
We ended up doing the latter.
I did all of the post-installation configuration of XP while Sarah was
napping this afternoon, and I have to say I'm impressed. Apple (for whatever
reason) has gone to a fair amount of trouble to make sure that Windows runs
really well on their hardware, and the Boot Camp stuff is really slick. It
all "just works". Even the built-in iSight camera.
So I feel pretty dirty for forking out for a copy of Windows XP (although
I'm deriving some pleasure from boosting the Windows XP sales figures in
spite of Windows Vista being available), and then putting it on a Mac to
boot, but we'll blame the university for being uncool.
Now if I could just get the Windows version of ClamAV to make me feel
confident it was actually providing some protection...
From the e2fsck man page:
SIGNALS
       The following signals have the following effect when sent to e2fsck.
       SIGUSR1
              This  signal causes e2fsck to start displaying a completion bar.
              (See discussion of the -C option.)
I was just lamenting to myself how e2fsck should default to showing
a progress bar for those times when you check a multi-terabyte filesystem,
and would really like to know how long it's going to take so you can decide
to go to bed or not, and you've learned about the -C option
after you've started e2fsck.
I'd been thinking to myself how grouse it would be if e2fsck would
let you know how far it had gotten on receipt of some signal of some sort.
Ted Ts'o, I salute you.
Update
Too bad I can't say the same thing for resize2fs.
I wonder if things could go any worse if we actively tried?
So despite going back to see the cardiologist on Monday afternoon, concerned
about there possibly being still some sort of infection, and being told
there wasn't, on Thursday morning, the top part of the incision was looking
swollen.
It looked even more so by the evening when I got home from work, and Sarah
emailed a photo to the cardiologist, and he agreed it didn't look too crash
hot, so he phoned a prescription for another, longer course of antibiotics
through to the pharmacy, but too late to get filled last night.
By bedtime it was looking even more ready to blow, and sure enough, around
1am (it's always 1am) it erupted everywhere. Fortunately (for me), I missed
all the gory details, but I think there was a fair bit of fluid built up in
there.
So we went back to the clinic this morning, and they decided that they
needed to open up part of the incision to let it drain and heal properly.
They took another swab to run another culture, and then got a physician's
assistant to take to her with a scalpel. I've seen my poor wife go through
too many painful things in the last six months. Today's was no better. Most
of the problem was the local anaesthetic injections, but watching them open
up the incision again wasn't much fun either. No one should have to go
through as much shit in a short time as what Sarah has had to. It's just not
fair.
She now has a gaping hole in her chest with some gauze packed in it, which
has to be changed twice a day (by lucky old me). The idea is to let it heal
from the bottom up, rather than the top down, as it seems an abscess had
formed in the wound, and that was were all the trouble was. So by leaving it
all open, it can drain properly, and heal from the bottom up. $DEITY only
knows what sort of mess it's going to make of the incision area, but we can
deal with that later. They reckon it'll take another 4-6 weeks to heal.
I'm really hoping now that with it draining, and another course of
antibiotics, Sarah will be in much less pain.
I just did the evening gauze change. Fun. The opening in the incision is
longer than I remembered them making this morning. It's about an inch long,
and a centimetre deep, and there's a small hole in the bottom that
presumably leads to the "interior". It's not as bad looking as I thought it
might be. Packing the gauze in didn't seem to hurt Sarah too much, which is
just as well.
This really is the pits. I really hope this is the end of this, and the
infection goes away for good, and the incision heals quickly. In terms of
recovery, this is a pretty major setback in my opinion. From now on, we
won't be relying on the cardiologist for surgical opinions, we'll be
insisting a member of the surgical team checks Sarah out.
I don't think the first trip ever made a mention in either of our blogs.
Funny how an exhausting trip tends to stem the care factor to write about
it afterwards...
Anyway, Sarah was in a fair bit of pain last night when she went to bed,
and despite taking 800mg of Ibuprofen, some amount of Oxycodone, and some
sleeping tablets, she was up again under 2 hours later, in agony.
The main concern was that the staph infection she'd apparently had in the
incision a few weeks prior hadn't been kicked fully by the antibiotics, and
was coming back.
So off we trotted to Stanford's ER, getting there around 1am. Fortunately it
was very quiet (not that it matters when you mention the magic words "chest
pain") and Sarah got straight in.
They did the usual battery of tests and decided to keep her in for
observation, so I trundled off home for some sleep at about 5am.
They told her she could go home at about 1:30pm. Apparently the problem was
muscle spasms, which can happen in some people after having heart surgery
(even this long after the surgery). The solution? Valium. The poor girl's
going to rattle soon with all these pills.
They did some blood work and there's no sign of the staph infection.
Whatever pain medication they gave Sarah intravenously today made her
extremely nauseous, and she was still concerned about the state of the
incision around the area that had been weeping previously, so we trekked back
in to Stanford this afternoon to see the cardiologist, who wasn't concerned
about the incision at all. In fact, he said the surgical doctor had been a
bit generous with pronouncing a staph infection in the incision two weeks
previously, saying that the swab they took at the time probably just picked
it up off Sarah's skin, where it's quite common to be found. So she may
never have had a staph infection in the first place.
In light of this Linux
kernel local root vulnerability, I thought I should audit the
trustworthiness of users with logins on systems I administer, so I slapped
together this
script to find users who had a valid shell and an unlocked account.
Disclaimer: I wrote it in bed on a Sunday morning. It may be utter crap.
I went back to work today after something like a total of 6 weeks off. (2
weeks vacation, 4 weeks unpaid leave).
The month of January went pretty quickly really. The week in hospital with
Sarah was a blur. The week and a half afterwards was also pretty much a
blur. Then we had the week where things went a bit backwards, and then we
had this week, a few days of which were spent up north at an inn in Little
River, Mendocino County. Heck, let's just call the entire month a blur and
be done with it.
Sarah's doing pretty well now. Surgery on the 3rd, discharged on the 9th,
back in the Emergency Room on the 21st with tachycardia. Concerns about the
incision weeping on the 21st, and again on the 28th. General increase in
pain on the 28th, along with a few sleepless nights preceding.
But now, with a doubling of her beta blockers, some antibiotics, pain
killers, anti-inflammatories and sleeping tablets, she's feeling a bit more
human again, if not like a human pill bottle.
The surgical folks want to see her again on Monday to follow up how the
incision is going since they prescribed the antibiotics. The weeping has
calmed down significantly, but hasn't gone away completely.
A couple more months to go before we can call her "recovered".
So it's been a few days since I swapped in the Zonbu I bought, as my
ATA over Ethernet "head".
It hasn't been all ponies and roses, but it hasn't been a total loss either.
The main problem I was having was a lot of
usb 5-2: reset high speed USB device using ehci_hcd and address 2type of errors during moderate I/O to the RAID10, which was connected to the four USB ports on the back of the unit (similar errors for all four USB devices). Initial Googling suggested that it was a USB mass-storage thing, and that lowering the maximum number of sectors read (and/or written?) a once in /sys/block/sd[a-d]/device/max_sectors would fix the problem. Well that didn't really seem to make a difference. Then I did some rummaging in the Zonbu forums, and it became apparent that there were some problems with the four USB ports on the back of the unit and USB 2.0 mass-storage devices. One of the forum threads pointed me at this bug, which had been subsequently fixed in a newer release of the Zonbu OS. I apprehensively emailed the Zonbu support folks lateish on Friday evening, not expecting to hear anything back until Monday, and half expecting to be unsupported because I was running Debian on it, when I got a reply fairly promptly telling me this kernel patch would fix the problem. It turns out that the VIA CX700 is a wee bit buggy, or the BIOS support for it is or something. Anyway, I spent the better part of two days compiling a new Debian 2.6.22 kernel with this patch applied (took me two goes, the first time the patch wasn't applied), but the Zonbu is now running a 2.6.22 kernel with this patch. Notably you get this message during bootup now:
PCI: VIA CX700 PCI parking/caching fixup on 0000:00:11.7It's a bit early to tell how it's going to work out. I don't have a scheduled recording until tonight, but I've just scheduled something random to see how it works out. Playing back a recording made before I swapped the Zonbu in seemed to go fine.
After the debacle
last time I tried to grow the size of my existing RAID1 when I put new
disks in daedalus, I thought this time I'd do my homework.
I did some research, I found out the way I should
have done it. I did a practice run on a USB key. I fully planned how I
was going to do it:
mdadm /dev/md2 --fail /dev/sdb3
<delete /dev/sdb3, recreate at new full size>
reboot
mdadm /dev/md2 --add /dev/sdb3
<wait for sync>
mdadm /dev/md2 --fail /dev/sda3
<delete /dev/sda3, recreate at new full size>
reboot
mdadm /dev/md2 --add /dev/sda3
<wait for sync>
mdadm --grow /dev/md2
<wait for sync>
pvresize /dev/md2
Everything went as planned, until I went to grow the RAID1 volume. It still thought the underlying device was the same size. There was nothing to grow. So at this point, I decided to do something similar to what I did last time to get around the failing disk, and should have done last time anyway. I broke the mirror, created a new degraded RAID1 using the full size of the new partition on the half I pulled out of the mirror, and did a pvmove from the old non-full-sized degraded mirror to the new full-sized degraded mirror. All of that went swimmingly until the pvmove was around 50% complete, when the kernel decided to oops spectacularly. I had to power cycle daedalus to get it back under control, and even in single-user mode, without me doing anything, the kernel started oopsing again. Dammit. I had to boot into emergency-mode (insert standard gripe about Debian's single-user mode being far too non-singular here), then I could resume the pvmove without any further oopsing. After that completed, I was able to ditch the old non-full-sized degraded RAID1 device and resync the new one onto the old partition. There was still some minor filesystem corruption, more likely because I had everything mounted at the time of the crash. Yes, I still haven't learned not to do this kind of thing in multi-user mode. It seems every time I try to minimise the size and duration of an outage, it bites me in the arse. Even though I should have been able to move open logical volumes between physical volumes, the kernel oops seemed to be in the dm_mirror code. daedalus is running a fairly old kernel. The annoying thing is that getting some additional disk space on board was the dependency for doing a general upgrade of all of the software on it. Argh. Anyway, it's done. I hope not to have to go through this again. I just have to sit through a potentially nail-biting remote upgrade of Debian now, and I should be good for a couple more years hopefully.
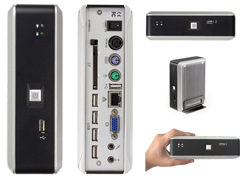 I've been quietly
coveting the Zonbu
for a number of months now. I finally caved in and ordered one when we got
back from Australia, with the intention of using it to replace
minotaur, the computer that exports my RAID10 via ATA over Ethernet
to my MythTV box.
minotaur is the old daedalus, which I bought back around
2000. It's a VA Linux Pentium III. It's old, noisy, and has no idea what
power management is. The Zonbu has more grunt than it (in terms of
BogoMIPS), and it's a fraction of the size. Our linen cupboard is now
significantly quieter (and hopefully cooler). Heck, hopefully the power bill
will be lower as well.
Anyway, I put the order in when we returned from Australia, with the
expectation that it'd turn up some time while Sarah was in hospital, or
shortly afterwards, and I could use the rest of the month that I was off
work to play with it. Well, I got an email on the 31st of December, telling
me they were out of stock, and unless I wanted to pay $29 more for one with
built-in WiFi, I'd have to wait until mid-January.
As I just couldn't see the point of having WiFi (or spending more money) and
not needing the thing in a hurry anyway, because I had more important things
to worry about in the meantime, I opted to wait. This morning, I emailed
them to enquire about whether or not more stock had arrived, and they
emailed back to say that they were still waiting, but they'd found one they
could sell to me anyway. The company happens to be close by in Menlo Park,
so I picked it up today in our travels.
Let me just say that it is a very cool little computer, just if you use it
for its intended purpose. It's running a customised Gentoo Linux, with a
2.6.22 kernel. I'm a bit surprised about their choice of Gentoo. I think
they'd be better off partnering with Canonical, given that Mark Shuttleworth
is trying to make a Linux distribution easy enough for his grandmother to
use. That'd take the work of engineering the operating system out of the
equation, then they could just focus on the hardware and a bit of
integration with Amazon's S3.
The thing I have to give them mad props for is documenting how to hack the
tripe out of the box. They tell you how to enable
root. They tell you how to enable PXE
booting. So once I figured out that the front USB port seems to get
treated slightly differently for a USB keyboard than the back ones, it was
very easy to PXE boot it and install Debian.
I initially started with trying to install Etch, but I kept getting missed
interrupts on the CompactFlash device, which resulted in the filesystems
panicking. So I gave up and went with Lenny, and presumably because it also
uses 2.6.22, everything seemed to go fine. The box comes with a 4Gb
CompactFlash card, which is ample for my needs. It's running the
686-optimised kernel, which is probably not ideal, but works. We'll see how
things go.
Interestingly, I blew another hard drive power supply, exactly
like last time. I've no idea if it's the act of plugging everything back
in again that's causing the problem, or they're generally flaky, and they
don't fail until they're powered off and back on again. Maybe that IEC
Y-cable wasn't such a good idea after all. I've now run out of spare power
supplies, so I'm going to have to get some more for when these two
inevitably fry themselves.
Overall, I'm very pleased with this purchase, but it's a bit early to see
how it's going to perform. I can't imagine it's going to perform
worse than the computer it's replacing, but it was probably never intended
for what I'm using it for either...
Oh, and I discovered vblade-persist, which seems to be a very nice
framework for managing ATA over Ethernet exports.
Now I just need to get my hands on a big tub of Lego to build a nice chassis
for the whole thing.
Erich Schubert's two
posts
about embedding spamtraps in web pages got me wondering about trying to
track the web crawlers that harvest such addresses.
If the pages that had the embedded spamtraps could be dynamically generated,
it'd be interesting to generate email addresses that encoded the time of the
crawl (well the page load I guess) and the IP address of the remote host.
I expect that most of the harvesting is done by botnets, so it possibly
wouldn't tell you a lot, but it'd be kind of cool to maintain a central
blacklist of known harvesting IP addresses, that sites like mailing list
archives could use to try and block the harvesters with.
I've been a bit behind with the ISC DHCP v3 package of late. I've had a
package of 3.1.0 for a few months, but I'm becoming more and more reluctant
to make uploads of this package without giving it some rudimentary testing.
Real life has been demanding of late, so I haven't had a chance to do that
testing. Nothing's gone wrong with the package to date, I just feel
negligent not giving it some basic testing before throwing it out there.
So I chucked a spare QFE card in my workstation brutus, put
unstable on the second hard drive, installed Debian unstable on the spare
10G partition of Sarah's old PowerBook, and lashed the two together with a
bit of CAT-5, and voila, instant DHCP client/server testbed.
So now that I'd verified that version 3.1.0 wasn't blatantly broken, I could
have a fiddle with the new support for option 119 (domain-search) that has
people at work very excited. I spent a bit of time off on a wild goose chase
trying to figure out how to configure the DHCP server for this new option
before I realised it was as simple as option domain-search "foo bar
baz"; and then made the necessary tweaks to dhclient-script.
I'm figuring that since one of the blokes who wrote the RFC works at Apple, and
since Leopard supports option 119, the way they're doing it in Leopard must
be approximately correct, so I've altered the behaviour of the DHCP client
accordingly.
All of this assumes you're not using resolvconf.
Prior to 3.1.0, if you had the domain-name option set, the
/etc/resolv.conf created by dhclient-script would set the
search directive to the domain name. With 3.1.0, I've decided to
make this set the domain option instead. The resolver behaviour
remains the same, as best as I can determine.
With 3.1.0, if the domain-search option is set, then the
search directive is set to this. If the domain-name option
is set, this is prepended to the list of domains in the
domain-search option. This is consistent with what MacOS X 10.5
(Leopard) does. I'm not sure what Windows does (nor what version started
honouring the domain-search DHCP option)), and since it doesn't
have an /etc/resolv.conf equivalent, it's a bit hard to test. I'm
going to hazard a guess and hope that since the other bloke who wrote the
RFC works for Microsoft, that maybe, just maybe, Windows and MacOS X at
least behave the same way.
Currently, if resolvconf is in use, you get the old
behaviour whereby the search directive is populated with the
contents of the domain-name option, and the domain-search
option is ignored completely. I've filed #460609 with a patch to fix this.
Interestingly, resolvconf itself internally collapses the domain
and search directives into the search directive of the
/etc/resolv.conf it generates, so I can't quite get the same
/etc/resolv.conf generated as would be generated without resolvconf
being used. No big deal, the behaviour should be the same. The
domain directive is largely unnecessary as I understand it.
I have unearthed what I consider to be a bug with the domain-search
option handling code in the client. It seems to be largely benign, apart
from causing the client to emit some errors when it's obtaining a lease that
contains the domain-search option, and possibly not splitting the
domains in the domain-search option correctly. There's also another
(I think unrelated) warning that gets emitted as well. I'm waiting to hear
back from upstream about both.
I'm not going to package the recently released 4.0 DHCP until I've figured
out a transition plan to go from the old DHCP v2 packages to the v3 ones.
Sarah and I went to see I
am legend with Shona
today.
How many more post-apocalyptic, zombies-created-by-a-virus movies can
Hollywood possibly churn out? That said, it was a good watch. Will Smith did
a really excellent job, and there were plenty of edge-of-the-seat suspense
moments.
One of the things I noticed when I was fiddling
around with daedalus the other week, was that when I had
everything stopped, linux.org.au seemed to stop resolving (and
therefore semi-important things like ftp.au.debian.org, which is a
CNAME to mirror.linux.org.au
This made me very sad, because I'm always harping on about BCP 16 when I see
other sites go down because all of their name servers are on the
same subnet.
Now that wasn't the reason for this particular "outage", though. It seems
that because one of the name servers is russell.linux.org.au, and
there's no glue
record for this host on any of the .org.au name servers, I don't
think russell is seeing any DNS traffic at all (perhaps only from
resolvers that somehow already happened to have a cached entry for it
obtained through other means than an NS query for linux.org.au)
So before I go doing any further disruptive maintenance on daedalus
I guess I'll be needing to get a glue record for
russell.linux.org.au. I'm surprised that searching Enetica's knowledge-base for "glue"
didn't raise a mention of it. I would have almost thought that they could
detect the need for a glue record when you're adjusting a domain's
delegation, so I wonder if it's a failure of their domain management system,
or a complete oversight. Maybe people just don't go sticking their name
servers in the domain they're hosting any more.
Discharged!
Sarah was discharged almost bang on 11am, the advertised discharge time,
which is less than 6 full days after she got out of surgery. Pretty amazing
stuff, and not a moment too soon, if you ask Sarah. She had a final chest
x-ray this morning, and that was about it.
We took a non-highway route home, and stopped via the supermarket to get a
few things and get her prescriptions filled, so we got home at about
12:20pm.
The rest of her recovery can be followed on her blog.
We both feel forever indebted to the wonderful doctors and nursing staff at
Stanford Hospital. Being in a hospital is certainly a lot better when you're
not grieving, and the outcome is positive.
Not a whole lot to report.
Sarah's still yet to have a decent night's sleep.
The cardiac rehab lady came by to go through the do's and don't's and answer
any questions we had.
They did an echocardiogram. I tagged along to watch. The Dacron looks a bit
whiter on the ultrasound than the aortic tissue, other than that, there's
not a lot to see.
It's looking like she'll be discharged tomorrow.
Next.