Search Results: "reg"

12 October 2014

Mario Lang: soundCLI works again

I recently ranted about my frustration with GStreamer in a SoundCloud command-line client written in Ruby. Well, it turns out that there was quite a bit confusion going on. I still haven't figured out why my initial tries resulted in an error regarding $DISPLAY not being set. But now that I have played a bit with gst-launch-1.0, I can positively confirm that this was very likely not the fault of GStreamer. THe actual issue is, that ruby-gstreamer is assuming gstreamer-1.0, while soundCLI was still written against the gstreamer-0.10 API. Since the ruby gst module doesn't have the Gstreamer API version in its name, and since Ruby is a dynamic language that only detects most errors at runtime, this led to all sorts of cascaded errors. It turns out I only had to correct the use of query_position, query_duration, and get_state, as well as switching from playbin2 to playbin. soundCLI is now running in the background and playing my SoundCloud stream. A pull request against soundCLI has also been opened. On a somewhat related note, I found a GCC bug (ICE SIGSEGV) this weekend. My first one. It is related to C++11 bracketed initializers. Given that I have heard GCC 5.0 aims to remove the experimental nature of C++11 (and maybe also C++14), this seems like a good time to hit this one. I guess that means I should finally isolate the C++ regex (runtime) segfault I recently stumbled across.

11 October 2014

Dirk Eddelbuettel: RPushbullet 0.1.0 with a lot more awesome

A new release 0.1.0 of the RPushbullet package (interfacing the neat Pushbullet service) landed on CRAN today. It brings a number of goodies relative to the first release 0.0.2 of a few months ago: There is a whole boat load of more wickedness in the Pushbullet API so if anybody feels compelled to add it, fire off pull requests at GitHub. More details about the package are at the RPushbullet webpage and the RPushbullet GitHub repo. Courtesy of CRANberries, there is also a diffstat report for this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

10 October 2014

Matthias Klumpp: Listaller + Glick: Some new ideas

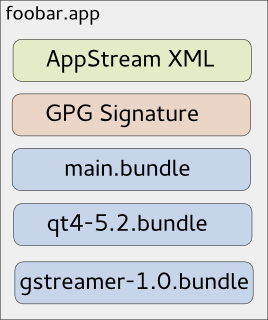
As you might know, due to invasive changes in PackageKit, I am currently rewriting the 3rd-party application installer Listaller. Since I am not the only one looking at the 3rd-party app-installation issue (there is a larger effort going on at GNOME, based on Lennarts ideas), it makes sense to redesign some concepts of Listaller. Currently, dependencies and applications are installed into directories in /opt, and Listaller contains some logic to make applications find dependencies, and to talk to the package manager to install missing things. This has some drawbacks, like the need to install an application before using it, the need for applications to be relocatable, and application-installations being non-atomic. Glick2 There is/was another 3rd-party app installer approach on the GNOME side, by Alexander Larsson, called Glick2. Glick uses application bundles (do you remember Klik from back in the days?) mounted via FUSE. This allows some neat features, like atomic installations and software upgrades, no need for relocatable apps and no need to install the application. However, it also has disadvantages. Quoting the introduction document for Glick2: Bundling isn t perfect, there are some well known disadvantages. Increased disk footprint is one, although current storage space size makes this not such a big issues. Another problem is with security (or bugfix) updates in bundled libraries. With bundled libraries its much harder to upgrade a single library, as you need to find and upgrade each app that uses it. Better tooling and upgrader support can lessen the impact of this, but not completely eliminate it. This is what Listaller does better, since it was designed to do a large effort to avoid duplication of code. Also, currently Glick doesn t have support for updates and software-repositories, which Listaller had. Combining Listaller and Glick ideas So, why not combine the ideas of Listaller and Glick? In order to have Glick share resources, the system needs to know which shared resources are available. This is not possible if there is one huge Glick bundle containing all of the application s dependencies. So I modularized Glick bundles to contain just one software component, which is e.g. GTK+ or Qt, GStreamer or could even be a larger framework (e.g. GNOME 3.14 Platform ). These components are identified using AppStream XML metadata, which allows them to be installed from the distributor s software repositories as well, if that is wanted. If you now want to deploy your application, you first create a Glick bundle for it. Then, in a second step, you bundle your application bundle with it s dependencies in one larger tarball, which can also be GPG signed and can contain additional metadata. The resulting metabundle will look like this: glick-libundle This doesn t look like we share resources yet, right? The dependencies are still bundled with the application requiring them. The trick lies in the installation step: While the application above can be executed right away without installing it, there will also be an option to install it. For the user, this will mean that the application shows up in GNOME-Shell s overview or KDEs Plasma launcher, gets properly registered with mimetypes and is if installed for all users available system-wide. Technically, this will mean that the application s main bundle is extracted and moved to a special location on the file system, so are the dependency-bundles. If bundles already exist, they will not be installed again, and the new application will simply use the existing software. Since the bundles contain information about their dependencies, the system is able to determine which software is needed and which can simply be deleted from the installation directories. If the application is started now, the bundles are combined and mounted, so the application can see the libraries it depends on. Additionally, this concept allows secure updates of applications and shared resources. The bundle metadata contains an URL which points to a bundle repository. If new versions are released, the system s auto-updater can automatically pick these up and install them this means e.g. the Qt bundle will receive security updates, even if the developer who shipped it with his/her app didn t think of updating it. Conclusion So far, no productive code exists for this I just have a proof-of-concept here. But I pretty much like the idea, and I am thinking about going further in that direction, since it allows deploying applications on the Linux desktop as well as deploying software on servers in a way which plays nice with the native package manager, and which does not duplicate much code (less risk of having not-updated libraries with security flaws around). However, there might be issues I haven t thought about yet. Also, it makes sense to look at GNOME to see how the whole 3rd-party app deployment issue develops. In case I go further with Listaller-NEXT, it is highly likely that it will make use of the ideas sketched above (comments and feedback are more than welcome!).

8 October 2014

Elena 'valhalla' Grandi: New gpg subkey

The GPG subkey I keep for daily use was going to expire, and this time I decided to create a new one instead of changing the expiration date.

Doing so I've found out that gnupg does not support importing just a private subkey for a key it already has (on IRC I've heard that there may be more informations on it on the gpg-users mailing list), so I've written a few notes on what I had to do on my website, so that I can remember them next year.

The short version is:

* Create your subkey (in the full keyring, the one with the private master key)
* export every subkey (including the expired ones, if you want to keep them available), but not the master key
* (copy the exported key from the offline computer to the online one)
* delete your private key from your regular use keyring
* import back the private keys you have exported before.

7 October 2014

Thorsten Glaser: mksh R50d released

The last MirBSD Korn Shell update broke update-initramfs because I accidentally introduced a regression in field splitting while fixing other bugs sorry! mksh R50d was just released to fix that, and a small NULL pointer dereference found by Goodbox on IRC. Thanks to my employer tarent for a bit of time to work on it.

Joachim Breitner: New website layout

After 10 years I finally got around to re-decorating my website. One reason was ICFP, where just too many people told me that I don t look like on my old website any more (which is very true). Another reason was that I was visting my brother, who is very good at web design (check out his portfolio), who could help me a bit. I wanted something practical and maybe a bit staid, so I drew inspiration from typical Latex typography, and also from Edward Z. Yang s blog: A serif font (Utopia) for the main body, justified and hyphenated text. Large section headers in a knobbly bold sans-serif font (Latin Modern Sans, which reasonably resembles Computer Modern). To intensify that impression, I put the main text on a white box that lies like a paper on the background. As a special gimmic the per-page navigation (or, in the case of the blog, the list of categories) is marked up like a figure in a paper. Of course this would be very dire without a suitable background. I really like the procedural art by Jared Tarbell, espcially substrate and interAggregate. Both have been turned into screensavers shipped with xscreensaver, so I hacked the substrate code to generate a seamless tile and took a screenshot of the result. I could not make up my mind yet how dense it has to be to look good, so I for every page I randomly pick one of six variants randomly for now. I simplified the navigation a bit. The old News section has been removed recently already. The Links section is gone I guess link lists on homepages are so 90s. The section Contact and About me are merged and awaiting some cleanup. The link to the satire news Heisse News is demoted to a mention on the Contents section. This hopefully helps to make the site navigatable on mobile devices (the old homepage was unusable). CSS media queries adjust the layout slightly on narrow screens, and separately for print devices. Being the nostaltic I am, I still keep the old design, as well as the two designs before that, around and commented their history.

Andrea Veri: The GNOME Infrastructure is now powered by FreeIPA!

As preannounced here the GNOME Infrastructure switched to a new Account Management System which is reachable at https://account.gnome.org. All the details will follow. Introduction It s been a while since someone actually touched the underlaying authentication infrastructure that powers the GNOME machines. The very first setup was originally configured by Jonathan Blandford (jrb) who configured an OpenLDAP istance with several customized schemas. (pServer fields in the old CVS days, pubAuthorizedKeys and GNOME modules related fields in recent times) While OpenLDAP-server was living on the GNOME machine called clipboard (aka ldap.gnome.org) the clients were configured to synchronize users, groups, passwords through the nslcd daemon. After several years Jeff Schroeder joined the Sysadmin Team and during one cold evening (date is Tue, February 1st 2011) spent some time configuring SSSD to replace the nslcd daemon which was missing one of the most important SSSD features: caching. What surely convinced Jeff to adopt SSSD (a very new but promising sofware at that time as the first release happened right before 2010 s Christmas) and as the commit log also states ( New sssd module for ldap information caching ) was SSSD s caching feature. It was enough for a certain user to log in once and the /var/lib/sss/db directory was populated with its login information preventing the LDAP daemon in charge of picking up login details (from the LDAP server) to query the LDAP server itself every single time a request was made against it. This feature has definitely helped in many occasions especially when the LDAP server was down for a particular reason and sysadmins needed to access a specific machine or service: without SSSD this wasn t ever going to work and sysadmins were probably going to be locked out from the machines they were used to manage. (except if you still had /etc/passwd , /etc/group and /etc/shadow entries as fallback) Things were working just fine except for a few downsides that appeared later on:
  1. the web interface (view) on our LDAP user database was managed by Mango, an outdated tool which many wanted to rewrite in Django that slowly became a huge dinosaur nobody ever wanted to look into again
  2. the Foundation membership information were managed through a MySQL database, so two databases, two sets of users unrelated to each other
  3. users were not able to modify their own account information on their own but even a single e-mail change required them to mail the GNOME Accounts Team which was then going to authenticate their request and finally update the account.
Today s infrastructure changes are here to finally say the issues outlined at (1, 2, 3) are now fixed. What has changed? The GNOME Infrastructure is now powered by Red Hat s FreeIPA which bundles several FOSS softwares into one big bundle all surrounded by an easy and intuitive web UI that will help users update their account information on their own without the need of the Accounts Team or any other administrative entity. Users will also find two custom fields on their Overview page, these being Foundation Member since and Last Renewed on date . As you may have understood already we finally managed to migrate the Foundation membership database into LDAP itself to store the information we want once and for all. As a side note it might be possible that some users that were Foundation members in the past won t find any detail stored on the Foundation fields outlined above. That is actually expected as we were able to migrate all the current and old Foundation members that had an LDAP account registered at the time of the migration. If that s your case and you still would like the information to be stored on the new setup please get in contact with the Membership Committee at stating so. Where can I get my first login credentials? Let s make a little distinction between users that previously had access to Mango (usually maintainers) and users that didn t. If you were used to access Mango before you should be able to login on the new Account Management System by entering your GNOME username and the password you were used to use for loggin in into Mango. (after loggin in the very first time you will be prompted to update your password, please choose a strong password as this account will be unique across all the GNOME Infrastructure) If you never had access to Mango, you lost your password or the first time you read the word Mango on this post you thought why is he talking about a fruit now? you should be able to reset it by using the following command:
ssh -l yourgnomeuserid account.gnome.org
The command will start an SSH connection between you and account.gnome.org, once authenticated (with the SSH key you previously had registered on our Infrastructure) you will trigger a command that will directly send your brand new password on the e-mail registered for your account. From my tests seems GMail sees the e-mail as a phishing attempt probably because the body contains the word password twice. That said if the e-mail won t appear on your INBOX, please double-check your Spam folder. Now that Mango is gone how can I request a new account? With Mango we used to have a form that automatically e-mailed the maintainer of the selected GNOME module which was then going to approve / reject the request. From there and in the case of a positive vote from the maintainer the Accounts Team was going to create the account itself. With the recent introduction of a commit robot directly on l10n.gnome.org the number of account requests reduced its numbers. In addition to that users will now be able to perform pretty much all the needed maintenance on their accounts themselves. That said and while we will probably work on building a form in the future we feel that requesting accounts can definitely be achieved directly by mailing the Accounts Team itself which will mail the maintainer of the respective module and create the account. As just said the number of account creations has become very low and the queue is currently clear. The documentation has been updated to reflect these changes at: https://wiki.gnome.org/AccountsTeam
https://wiki.gnome.org/AccountsTeam/NewAccounts The migration of all the user data and ACLs has been massive and I ve been spending a lot of time reviewing the existing HBAC rules trying to spot possible errors or misconfigurations. If you happen to not being able to access a certain service as you were used to in the past, please get in contact with the Sysadmin Team. All the possible ways to contact us are available at https://wiki.gnome.org/Sysadmin/Contact. What is missing still? Now that the Foundation membership information has been moved to LDAP I ll be looking at porting some of the existing membership scripts to it. What I managed to port already are welcome e-mails for new or existing members. (renewals) Next step will be generating a membership page from LDAP (to populate http://www.gnome.org/foundation/membership) and all the your-membership-is-going-to-lapse e-mails that were being sent till today. Other news /home/users mount on master.gnome.org You will notice that loggin in into master.gnome.org will result in your home directory being empty, don t worry, you did not lose any of your files but master.gnome.org is now currently hosting your home directories itself. As you may have been aware of adding files to the public_html directory on master resulted in them appearing on your people.gnome.org/~userid space. That was unfortunately expected as both master and webapps2 (the machine serving people.gnome.org s webspaces) were mounting the same GlusterFS share. We wanted to prevent that behaviour to happen as we wanted to know who has access to what resource and where. From today master s home directories will be there just as a temporary spot for your tarballs, just scp and use ftpadmin against them, that should be all you need from master. If you are interested in receiving or keeping using your people.gnome.org s webspace please mail stating so. Other news a shiny and new error 500 page has been deployed Thanks to Magdalen Berns (magpie) a new error 500 web page has been deployed on all the Apache istances we host. The page contains an iframe of status.gnome.org and will appear every single time the web server behind the service you are trying to reach will be unreachable for maintenance or other purposes. While I hope you won t see the page that often you can still enjoy it at https://static.gnome.org/error-500/500.html. Make sure to whitelist status.gnome.org on your browser as it currently loads it without https. (as the service is currently hosted on OpenShift which provides us with a *.rhcloud.com wildcard certificate, which differs from the CN the browser would expect it to be)

Andrea Veri: The GNOME Infrastructure is now powered by FreeIPA!

As preannounced here the GNOME Infrastructure switched to a new Account Management System which is reachable at https://account.gnome.org. All the details will follow. Introduction It s been a while since someone actually touched the underlying authentication infrastructure that powers the GNOME machines. The very first setup was originally configured by Jonathan Blandford (jrb) who configured an OpenLDAP istance with several customized schemas. (pServer fields in the old CVS days, pubAuthorizedKeys and GNOME modules related fields in recent times) While OpenLDAP-server was living on the GNOME machine called clipboard (aka ldap.gnome.org) the clients were configured to synchronize users, groups, passwords through the nslcd daemon. After several years Jeff Schroeder joined the Sysadmin Team and during one cold evening (date is Tue, February 1st 2011) spent some time configuring SSSD to replace the nslcd daemon which was missing one of the most important SSSD features: caching. What surely convinced Jeff to adopt SSSD (a very new but promising sofware at that time as the first release happened right before 2010 s Christmas) and as the commit log also states ( New sssd module for ldap information caching ) was SSSD s caching feature. It was enough for a certain user to log in once and the /var/lib/sss/db directory was populated with its login information preventing the LDAP daemon in charge of picking up login details (from the LDAP server) to query the LDAP server itself every single time a request was made against it. This feature has definitely helped in many occasions especially when the LDAP server was down for a particular reason and sysadmins needed to access a specific machine or service: without SSSD this wasn t ever going to work and sysadmins were probably going to be locked out from the machines they were used to manage. (except if you still had /etc/passwd , /etc/group and /etc/shadow entries as fallback) Things were working just fine except for a few downsides that appeared later on:
  1. the web interface (view) on our LDAP user database was managed by Mango, an outdated tool which many wanted to rewrite in Django that slowly became a huge dinosaur nobody ever wanted to look into again
  2. the Foundation membership information were managed through a MySQL database, so two databases, two sets of users unrelated to each other
  3. users were not able to modify their own account information on their own but even a single e-mail change required them to mail the GNOME Accounts Team which was then going to authenticate their request and finally update the account.
Today s infrastructure changes are here to finally say the issues outlined at (1, 2, 3) are now fixed. What has changed? The GNOME Infrastructure is now powered by Red Hat s FreeIPA which bundles several FOSS softwares into one big bundle all surrounded by an easy and intuitive web UI that will help users update their account information on their own without the need of the Accounts Team or any other administrative entity. Users will also find two custom fields on their Overview page, these being Foundation Member since and Last Renewed on date . As you may have understood already we finally managed to migrate the Foundation membership database into LDAP itself to store the information we want once and for all. As a side note it might be possible that some users that were Foundation members in the past won t find any detail stored on the Foundation fields outlined above. That is actually expected as we were able to migrate all the current and old Foundation members that had an LDAP account registered at the time of the migration. If that s your case and you still would like the information to be stored on the new setup please get in contact with the Membership Committee at stating so. Where can I get my first login credentials? Let s make a little distinction between users that previously had access to Mango (usually maintainers) and users that didn t. If you were used to access Mango before you should be able to login on the new Account Management System by entering your GNOME username and the password you were used to use for loggin in into Mango. (after loggin in the very first time you will be prompted to update your password, please choose a strong password as this account will be unique across all the GNOME Infrastructure) If you never had access to Mango, you lost your password or the first time you read the word Mango on this post you thought why is he talking about a fruit now? you should be able to reset it by using the following command:
ssh -l yourgnomeuserid account.gnome.org
The command will start an SSH connection between you and account.gnome.org, once authenticated (with the SSH key you previously had registered on our Infrastructure) you will trigger a command that will directly send your brand new password on the e-mail registered for your account. From my tests seems GMail sees the e-mail as a phishing attempt probably because the body contains the word password twice. That said if the e-mail won t appear on your INBOX, please double-check your Spam folder. Now that Mango is gone how can I request a new account? With Mango we used to have a form that automatically e-mailed the maintainer of the selected GNOME module which was then going to approve / reject the request. From there and in the case of a positive vote from the maintainer the Accounts Team was going to create the account itself. With the recent introduction of a commit robot directly on l10n.gnome.org the number of account requests reduced its numbers. In addition to that users will now be able to perform pretty much all the needed maintenance on their accounts themselves. That said and while we will probably work on building a form in the future we feel that requesting accounts can definitely be achieved directly by mailing the Accounts Team itself which will mail the maintainer of the respective module and create the account. As just said the number of account creations has become very low and the queue is currently clear. The documentation has been updated to reflect these changes at: https://wiki.gnome.org/AccountsTeam
https://wiki.gnome.org/AccountsTeam/NewAccounts I was used to have access to a specific service but I don t anymore, what should I do? The migration of all the user data and ACLs has been massive and I ve been spending a lot of time reviewing the existing HBAC rules trying to spot possible errors or misconfigurations. If you happen to not being able to access a certain service as you were used to in the past, please get in contact with the Sysadmin Team. All the possible ways to contact us are available at https://wiki.gnome.org/Sysadmin/Contact. What is missing still? Now that the Foundation membership information has been moved to LDAP I ll be looking at porting some of the existing membership scripts to it. What I managed to port already are welcome e-mails for new or existing members. (renewals) Next step will be generating a membership page from LDAP (to populate http://www.gnome.org/foundation/membership) and all the your-membership-is-going-to-lapse e-mails that were being sent till today. Other news /home/users mount on master.gnome.org You will notice that loggin in into master.gnome.org will result in your home directory being empty, don t worry, you did not lose any of your files but master.gnome.org is now currently hosting your home directories itself. As you may have been aware of adding files to the public_html directory on master resulted in them appearing on your people.gnome.org/~userid space. That was unfortunately expected as both master and webapps2 (the machine serving people.gnome.org s webspaces) were mounting the same GlusterFS share. We wanted to prevent that behaviour to happen as we wanted to know who has access to what resource and where. From today master s home directories will be there just as a temporary spot for your tarballs, just scp and use ftpadmin against them, that should be all you need from master. If you are interested in receiving or keeping using your people.gnome.org s webspace please mail <accounts AT gnome DOT org> stating so. Other news a shiny and new error 500 page has been deployed Thanks to Magdalen Berns (magpie) a new error 500 web page has been deployed on all the Apache istances we host. The page contains an iframe of status.gnome.org and will appear every single time the web server behind the service you are trying to reach will be unreachable for maintenance or other purposes. While I hope you won t see the page that often you can still enjoy it at https://static.gnome.org/error-500/500.html. Make sure to whitelist status.gnome.org on your browser as it currently loads it without https. (as the service is currently hosted on OpenShift which provides us with a *.rhcloud.com wildcard certificate, which differs from the CN the browser would expect it to be) Updates UPDATE on status.gnome.org s SSL certificate: the certificate has been provisioned and it should result in the 500 s page to be displayed correctly with no warnings from your browser. UPDATE from Adam Young on Kerberos ports being closed on many DC s firewalls:
The next version of upstream MIT Kerberos will have support for fetching a ticket via ports 443 and marshalling the request over HTTPS. We ll need to run a proxy on the server side, but we should be able to make it work: Read up here
http://adam.younglogic.com/2014/06/kerberos-firewalls

5 October 2014

Steve Kemp: Before I forget, a simple virtual machine

Before I forget I had meant to write about a toy virtual machine which I'ce been playing with. It is register-based with ten registers, each of which can hold either a string or int, and there are enough instructions to make it fun to use. I didn't go overboard and write a complete grammer, or a real compiler, but I did do enough that you can compile and execute obvious programs. First compile from the source to the bytecodes:
$ ./compiler examples/loop.in
Mmm bytecodes are fun:
$ xxd  ./examples/loop.raw
0000000: 3001 1943 6f75 6e74 696e 6720 6672 6f6d  0..Counting from
0000010: 2074 656e 2074 6f20 7a65 726f 3101 0101   ten to zero1...
0000020: 0a00 0102 0100 2201 0102 0201 1226 0030  ......"......&.0
0000030: 0104 446f 6e65 3101 00                   ..Done1..
Now the compiled program can be executed:
$ ./simple-vm ./examples/loop.raw
[stdout] register R01 = Counting from ten to zero
[stdout] register R01 = 9 [Hex:0009]
[stdout] register R01 = 8 [Hex:0008]
[stdout] register R01 = 7 [Hex:0007]
[stdout] register R01 = 6 [Hex:0006]
[stdout] register R01 = 5 [Hex:0005]
[stdout] register R01 = 4 [Hex:0004]
[stdout] register R01 = 3 [Hex:0003]
[stdout] register R01 = 2 [Hex:0002]
[stdout] register R01 = 1 [Hex:0001]
[stdout] register R01 = 0 [Hex:0000]
[stdout] register R01 = Done
There could be more operations added, but I'm pleased with the general behaviour, and embedding is trivial. The only two things that make this even remotely interesting are: Anyway that concludes todays computer-fun.

3 October 2014

Marco d'Itri: 15 years of whois

Exactly 15 years ago I uploaded to Debian the first release of my whois client. At the end of 1999 the United States Government forced Network Solutions, at the time the only registrar for the .com, .net and .org top level domains, to split their functions in a registry and a registrar and to and allow competing registrars to operate. Since then, two whois queries are needed to access the data for a domain in a TLD operating with a thin registry model: first one to the registry to find out which registrar was used to register the domain, and then one the registrar to actually get the data. Being as lazy as I am I tought that this was unacceptable, so I implemented a whois client that would know which whois server to query for all TLDs and then automatically follow the referrals to the registrars. But the initial reason for writing this program was to replace the simplistic BSD-derived whois client that was shipped with Debian with one that would know which server to query for IP addresses and autonomous system numbers, a useful feature in a time when people still used to manually report all their spam to the originating ISPs. Over the years I have spent countless hours searching for the right servers for the domains of far away countries (something that has often been incredibly instructive) and now the program database is usually more up to date than the official IANA one. One of my goals for this program has always been wide portability, so I am happy that over the years it was adopted by other Linux distributions, made available by third parties to all common variants of UNIX and even to systems as alien as Windows and OS/2. Now that whois is 15 years old I am happy to announce that I have recently achieved complete world domination and that all Linux distributions use it as their default whois client.

2 October 2014

Matthew Garrett: Actions have consequences (or: why I'm not fixing Intel's bugs any more)

A lot of the kernel work I've ended up doing has involved dealing with bugs on Intel-based systems - figuring out interactions between their hardware and firmware, reverse engineering features that they refuse to document, improving their power management support, handling platform integration stuff for their GPUs and so on. Some of this I've been paid for, but a bunch has been unpaid work in my spare time[1].

Recently, as part of the anti-women #GamerGate campaign[2], a set of awful humans convinced Intel to terminate an advertising campaign because the site hosting the campaign had dared to suggest that the sexism present throughout the gaming industry might be a problem. Despite being awful humans, it is absolutely their right to request that a company choose to spend its money in a different way. And despite it being a dreadful decision, Intel is obviously entitled to spend their money as they wish. But I'm also free to spend my unpaid spare time as I wish, and I no longer wish to spend it doing unpaid work to enable an abhorrently-behaving company to sell more hardware. I won't be working on any Intel-specific bugs. I won't be reverse engineering any Intel-based features[3]. If the backlight on your laptop with an Intel GPU doesn't work, the number of fucks I'll be giving will fail to register on even the most sensitive measuring device.

On the plus side, this is probably going to significantly reduce my gin consumption.

[1] In the spirit of full disclosure: in some cases this has resulted in me being sent laptops in order to figure stuff out, and I was not always asked to return those laptops. My current laptop was purchased by me.

[2] I appreciate that there are some people involved in this campaign who earnestly believe that they are working to improve the state of professional ethics in games media. That is a worthy goal! But you're allying yourself to a cause that disproportionately attacks women while ignoring almost every other conflict of interest in the industry. If this is what you care about, find a new way to do it - and perhaps deal with the rather more obvious cases involving giant corporations, rather than obsessing over indie developers.

For avoidance of doubt, any comments arguing this point will be replaced with the phrase "Fart fart fart".

[3] Except for the purposes of finding entertaining security bugs

comment count unavailable comments

30 September 2014

Rapha&#235;l Hertzog: My Debian LTS report for September

Thanks to the sponsorship of multiple companies, I have been paid to work 11 hours on Debian LTS this month. CVE triagingI started by doing lots of triage in the security tracker (if you want to help, instructions are here) because I noticed that the dla-needed.txt list (which contains the list of packages that must be taken care of via an LTS security update) was missing quite a few packages that had open vulnerabilities in oldstable. In the end, I pushed 23 commits to the security tracker. I won t list the details each time but for once, it s interesting to let you know the kind of things that this work entailed: And when I say I reviewed it s a simplification for this kind of process: CVE triaging is often almost half the work in the general process: once you know that you are affected and that you have a patch, the process to release an update is relatively straightforward (sometimes there s still work to do to backport the patch). Once I was over that first pass of triaging, I had already spent more than the 11 hours paid but I still took care of preparing the security update for python-django. Thorsten Alteholz had started the work but got stuck in the process of backporting the patches. Since I m co-maintainer of the package, I took over and finished the work to release it as DLA-65-1.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Mario Lang: A simple C++11 concurrent workqueue

For a little toy project of mine (a wikipedia XML dump word counter) I wrote a little C++11 helper class to distribute work to all available CPU cores. It took me many years to overcome my fear of threading: In the past, whenever I toyed with threaded code, I ended up having a lot of deadlocks, and generally being confused. It appears that I finally have understood enough of this crazyness to be able to come up with the small helper class below.
The problem We want to spread work amongst all available CPU cores. There are no dependencies between items in our work queue. So every thread can just pick up and process an item as soon as it is ready.
The solution This simple implementation makes use of C++11 threading primitives, lambda functions and move semantics. The idea is simple: You provide a function at construction time which defines how to process one item of work. To pass work to the queue, simply call the function operator of the object, repeatedly. When the destructor is called (once the object reachs the end of its scope), all remaining items are processed and all background threads are joined. The number of threads defaults to the value of std::thread::hardware_concurrency(). This appears to work at least since GCC 4.9. Earlier tests have shown that std::thread::hardware_concurrency() always returned 1. I don't know when exactly GCC (or libstdc++, actually) started to support this, but at least since GCC 4.9, it is usable. Prerequisite on Linux is a mounted /proc. The number of maximum items per thread in the queue defaults to 1. If the queue is full, calls to the function operator will block. So the most basic usage example is probably something like:
int main()  
  typedef std::string item_type;
  distributor<item_type> process([](item_type &item)  
    // do work
   );
  while (/* input */) process(std::move(/* item */));
  return 0;
 
That is about as simple as it can get, IMHO. The code can be found in the GitHub project mentioned above. However, since the class template is relatively short, here it is.
#include <condition_variable>
#include <mutex>
#include <queue>
#include <stdexcept>
#include <thread>
#include <vector>
template <typename Type, typename Queue = std::queue<Type>>
class distributor: Queue, std::mutex, std::condition_variable  
  typename Queue::size_type capacity;
  bool done = false;
  std::vector<std::thread> threads;
public:
  template<typename Function>
  distributor( Function function
             , unsigned int concurrency = std::thread::hardware_concurrency()
             , typename Queue::size_type max_items_per_thread = 1
             )
  : capacity concurrency * max_items_per_thread 
   
    if (not concurrency)
      throw std::invalid_argument("Concurrency must be non-zero");
    if (not max_items_per_thread)
      throw std::invalid_argument("Max items per thread must be non-zero");
    for (unsigned int count  0 ; count < concurrency; count += 1)
      threads.emplace_back(static_cast<void (distributor::*)(Function)>
                           (&distributor::consume), this, function);
   
  distributor(distributor &&) = default;
  distributor &operator=(distributor &&) = delete;
  ~distributor()
   
     
      std::lock_guard<std::mutex> guard(*this);
      done = true;
      notify_all();
     
    for (auto &&thread: threads) thread.join();
   
  void operator()(Type &&value)
   
    std::unique_lock<std::mutex> lock(*this);
    while (Queue::size() == capacity) wait(lock);
    Queue::push(std::forward<Type>(value));
    notify_one();
   
private:
  template <typename Function>
  void consume(Function process)
   
    std::unique_lock<std::mutex> lock(*this);
    while (true)  
      if (not Queue::empty())  
        Type item   std::move(Queue::front())  ;
        Queue::pop();
        notify_one();
        lock.unlock();
        process(item);
        lock.lock();
        else if (done)  
        break;
        else  
        wait(lock);


 ;
If you have any comments regarding the implementation, please drop me a mail.

Dirk Eddelbuettel: Rcpp 0.11.3

A new release 0.11.3 of Rcpp is now on the CRAN network for GNU R, and an updated Debian package has been uploaded too. Rcpp has become the most popular way of enhancing GNU R with C++ code. As of today, 273 packages on CRAN depend on Rcpp for making analyses go faster and further. This release brings a fairly large number of continued enhancements, fixes and polishing to Rcpp. These were provided by a total of seven different contributors---which is a new record as well. See below for a detailed list of changes extracted from the NEWS file, but some highlights included in this release are One sore point, however, is that we missed that packages using Rcpp Modules appear to require a rebuild. We are sorry for the inconvenience; this has highlighted a shortcoming in our fairly robust and extensive tests. While we test our packages against all known CRAN dependents, such tests check for the ability to compile and run freshly and not whether previously built packages still run. We intend to augment our testing in this direction to avoid a repeat occurrence of such a misfeature.
Changes in Rcpp version 0.11.3 (2014-09-27)
  • Changes in Rcpp API:
    • The deprecation of RCPP_FUNCTION_* which was announced with release 0.10.5 last year is proceeding as planned, and the file macros/preprocessor_generated.h has been removed.
    • Timer no longer records time between steps, but times from the origin. It also gains a get_timers(int) methods that creates a vector of Timer that have the same origin. This is modelled on the Rcpp11 implementation and is more useful for situations where we use timers in several threads. Timer also gains a constructor taking a nanotime_t to use as its origin, and a origin method. This can be useful for situations where the number of threads is not known in advance but we still want to track what goes on in each thread.
    • A cast to bool was removed in the vector proxy code as inconsistent behaviour between clang and g++ compilations was noticed.
    • A missing update(SEXP) method was added thanks to pull request by Omar Andres Zapata Mesa.
    • A proxy for DimNames was added.
    • A no_init option was added for Matrices and Vectors.
    • The InternalFunction class was updated to work with std::function (provided a suitable C++11 compiler is available) via a pull request by Christian Authmann.
    • A new_env() function was added to Environment.h
    • The return value of range eraser for Vectors was fixed in a pull request by Yixuan Qiu.
  • Changes in Rcpp Sugar:
    • In ifelse(), the returned NA type was corrected for operator[].
  • Changes in Rcpp Attributes:
    • Include LinkingTo in DESCRIPTION fields scanned to confirm that C++ dependencies are referenced by package.
    • Add dryRun parameter to sourceCpp.
    • Corrected issue with relative path and R chunk use for sourceCpp.
  • Changes in Rcpp Documentation:
    • The Rcpp-FAQ vignette was updated with respect to OS X issues.
    • A new entry in the Rcpp-FAQ clarifies the use of licenses.
    • Vignettes build results no longer copied to /tmp to please CRAN.
    • The Description in DESCRIPTION has been shortened.
  • Changes in Rcpp support functions:
    • The Rcpp.package.skeleton() function will now use pkgKitten package, if available, to create a package which passes R CMD check without warnings. A new Suggests: has been added for pkgKitten.
    • The modules=TRUE case for Rcpp.package.skeleton() has been improved and now runs without complaints from R CMD check as well.
  • Changes in Rcpp unit test functions:
    • Functions from the RUnit package are now prefixed with RUnit::
    • The testRcppModule and testRcppClass sample packages now pass R CMD check --as-cran cleanly with NOTES or WARNINGS
Thanks to CRANberries, you can also look at a diff to the previous release As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

28 September 2014

Ean Schuessler: RoboJuggy at JavaOne

A few months ago I was showing my friend Bruno Souza the work I had been doing with my childhood friend and robotics genius, David Hanson. I had been watching what David was going through in his process of creating life-like robots with the limited industrial software available for motor control. I had suggested to David that binding motors to Blender control structures was a genuinely viable possibility. David talked with his forward looking CEO, Jong Lee, and they were gracious enough to invite me to Hong Kong to make this exciting idea a reality. Working closely the HRI team (Vytas, Gabrielos, Fabien and Davide) with David s friend and collaborators at OpenCog (Ben Goertzel, Mandeep, David, Jamie, Alex and Samuel) a month long creative hack-fest yielded pretty amazing results. Bruno is an avid puppeteer, a global organizer of java user groups and creator of Juggy the Java Finch, mascot of Java users and user groups everywhere. We started talking about how cool it would be to have a robot version of Juggy. When I was in China I had spent a little time playing with Mark Tilden s RSMedia and various versions of David s hobby servo based emotive heads. Bruno and I did a little research into the ROS Java bindings for the Robot Operating System and decided that if we could make that part of the picture we had a great and fun idea for a JavaOne talk. Hunting and gathering I tracked down a fairly priced RSMedia in Alaska, Bruno put a pair of rubber Juggy puppet heads in the mail and we were on our way.
We had decided that we wanted RoboJuggy to be able to run about untethered and the new RaspberryPi B+ seemed like the perfect low power brain to make that happen. I like the Debian based Raspbian distributions but had lately started using the netinst Pi images. These get your Pi up and running in about 15 minutes with a nicely minimalistic install instead of a pile of dependencies you probably don t need. I d recommend anyone interested I m duplicating our work to stay their journey there: Raspbian UA Net Installer Robots seem like an embedded application but ROS only ships packages for Ubuntu. I was pleasantly surprised that there are very good instructions for building ROS from source on the Pi. I ended up following these instructions: Setting up ROS Hydro on the Raspberry Pi Building from source means that all your install ends up being isolated (in ROS speak) and your file locations and build instructions end up being subtly current. As explained in the linked article, this process is also very time consuming. One thing I would recommend once you get past this step is to use the UNIX dd command to back up your entire SD card to a desktop. This way if you make a mess of things in later steps you can restore your install to a pristine Raspbian+ROS install. If your SD drive was on /dev/sdb you might use something like this to do the job:
sudo dd bs=4M if=/dev/sdb   gzip > /home/your_username/image date +%d%m%y .gz
Getting Java in the mix Once you have your Pi all set up with minimal Raspbian and ROS you are going to want a Java VM. The Pi runs the ARM CPU so you need the corresponding version of Java. I tried getting things going initially with OpenJDK and I had some issues with that. I will work on resolving that in the future because I would like to have a 100% Free Software kit for this but since this was for JavaOne I also wanted JDK8, which isn t available in Debian yet. So, I downloaded the Oracle JDK8 package for ARM. Java 8 JDK for ARM At this point you are ready to start installing the ROS Java packages. I m pretty sure the way I did this initially is wrong but I was trying to reconcile the two install procedures for ROS Java and ROS Hydro for Raspberry Pi. I started by following these directions for ROS Java but with a few exceptions (you have to click the install from source link in the page to see the right stuff: Installing ROS Java on Hydro Now these instructions are good but this is a Pi running Debian and not an Ubuntu install. You won t run the apt-get package commands because those tools were already installed in your earlier steps. Also, this creates its own workspace and we really want these packages all in one workspace. You can apparently chain workspaces in ROS but I didn t understand this well enough to get it working so what I did was this:
> mkdir -p ~/rosjava 
> wstool init -j4 ~/rosjava/src https://raw.github.com/rosjava/rosjava/hydro/rosjava.rosinstall
> source ~/ros_catkin_ws/install_isolated/setup.bash > cd ~/rosjava # Make sure we've got all rosdeps and msg packages.
> rosdep update 
> rosdep install --from-paths src -i -y
and then copied the sources installed into ~/rosjava/src into my main ~/ros_catkin_ws/src. Once those were copied over I was able to run a standard build.
> catkin_make_isolated --install
Like the main ROS install this process will take a little while. The Java gradle builds take an especially long time. One thing I would recommend to speed up your workflow is to have an x86 Debian install (native desktop, QEMU instance, docker, whatever) and do these same build from source installs there. This will let you try your steps out on a much faster system before you try them out in the Pi. That can be a big time saver. Putting together the pieces Around this time my RSMedia had finally showed up from Alaska. At first I thought I had a broken unit because it would power up, complain about not passing system tests and then shut back down. It turns out that if you just put the D batteries in and miss the four AAs that it will kind of pretend to be working so watch for that mistake. Here is a picture of the RSMedia when it first came out of the box: wpid-20140911_142904.jpg Other parts were starting to roll in as well. The rubber puppet heads had made their way through Brazilian customs and my Pololu Mini Maestro 24 had also shown up as well as the my servo motors and pan and tilt camera rig. I had previously bought a set of 10 motors for goofing around so I bought the pan and tilt rig by itself for about $5(!) but you can buy a complete set for around $25 from a number of EBay stores. Complete pan and tilt rig with motors for $25 A bit more about the Pololu. This astonishing little motor controller costs about $25 and gives you control of 24 motors with an easy to use and high level serial API. It is probably also possible to control these servos directly from the Pi and eliminate this board but that will be genuinely difficult because of the real-time timing issues. For $25 this thing is a real gem and you won t regret buying it. Now it was time to start dissecting the RSMedia and getting control of its brain. Unfortunately a lot of great information about the RSMedia has floated away since it was in its heyday 5 years ago but there is still some solid information out there that we need to round up and preserve. A great resource is the SourceForge based website here at http://rsmediadevkit.sourceforge.net. That site has links to a number of useful sites. You will definitely want to check out their wiki. To disassemble the RSMedia I followed their instructions. I will say, it would be smart to take more pictures as you are going because they don t take as many as they should. I took pictures of each board and its associated connections as dismantled the unit and that helped me get things back together later. Another important note is that if all you want to do is solder onto the control board and not replace the head then its feasible to solder the board in place without completely disassembling the unit. Here are some photos of the dis-assembly: wpid-20140921_114742.jpg wpid-20140921_113054.jpg wpid-20140921_112619.jpg Now I also had to start adjusting the puppet head, building an armature for the motors to control it and hooking it into the robot. I need to take some more photos of the actual armature. I like to use cardboard for this kind of stuff because it is so fast to work with and relatively strong. One trick I have also learned about cardboard is that if you get something going with it and you need it to be a little more production strength you can paint it down with fiberglass resin from your local auto store. Once it dries it becomes incredibly tough because it soaks through the fibers of the cardboard and hardens around them. You will want to do this in a well ventilated area but its a great way to build super tough prototypes. Another prototyping trick I can suggest is using a combination of Velcro and zipties to hook things together. The result is surprisingly strong and still easy to take apart if things aren t working out. Velcro self-adhesive pads stick to rubber like magic and that is actually how I hooked the jaw servo onto the mask. You can see me torturing its first initial connection here: Since the puppet head had come all the way from Brazil I decided to cook some chicken hearts in the churrascaria style while I worked on them in the garage. This may sound gross but I m telling you, you need to try it! I soaked mine in soy sauce, Sriracha and chinese cooking wine. Delicious but I digress. wpid-20140920_191551.jpg As I was eating my chicken hearts I was also connecting the pan and tilt armature onto the puppet s jaw and eye assembly. It took me most of the evening to get all this going but by about one in the morning things were starting to look good! I only had a few days left to hack things together before JavaOne and things were starting to get tight. I had so much to do and had also started to run into some nasty surprises with the ROS Java control software. It turns out that ROS Java is less than friendly with ROS message structures that are not built in . I had tried to follow the provided instructions but was not (and still have not) been able to get that working. Using unofficial messages with ROS Java I still needed to get control of the RSMedia. Doing that required the delicate operation of soldering to its control board. On the board there are a set of pins that provide a serial interface to the ARM based embedded Linux computer that controls the robot. To do that I followed these excellent instructions: Connecting to the RSMedia Linux Console Port After some sweaty time bent over a magnifying glass I had success: wpid-20140921_143327.jpg I had previously purchased the USB-TTL232 accessory described in the article from Dallas awesome Tanner Electronics store in Dallas. If you are a geek I would recommend that you go there and say hi to its proprietor (and walking encyclopedia of electronics knowledge) Jim Tanner. It was very gratifying when I started a copy of minicom, set it to 115200, N, 8, 1, plugged in the serial widget to the RSMedia and booted it up. I was greeted with a clearly recognizable Linux startup and console prompt. At first I thought I had done something wrong because I couldn t get it to respond to commands but I quickly realized I had flow control turned on. Once turned off I was able to navigate around the file system, execute commands and have some fun. A little research and I found this useful resource which let me get all kinds of body movements going: A collection of useful commands for the RSMedia At this point, I had a usable set of controls for the body as well as the neck armature. I had a controller running the industry s latest and greatest robotics framework that could run on the RSMedia without being tethered to power and I had most of a connection to Java going. Now I just had to get all those pieces working together. The only problem is that time was running out and I only had a couple of days until my talk and still had to pack and square things away at work. The last day was spent doing things that I wouldn t be able to do on the road. My brother Erik (and fantastic artist) came over to help paint up the juggy head and fix the eyeball armature. He used a mix of oil paint, rubber cement which stuck to the mask beautifully. I bought battery packs for the USB Pi power and the 6v motor control and integrated them into a box that could sit below the neck armature. I fixed up a cloth neck sleeve that could cover everything. Luckily during all this my beautiful and ever so supportive girlfriend Becca had helped me get packed or I probably wouldn t have made it out the door. Welcome to San Francisco THIS ARTICLE IS STILL BEING WRITTEN

27 September 2014

DebConf team: Wrapping up DebConf14 (Posted by Paul Wise, Donald Norwood)

The annual Debian developer meeting took place in Portland, Oregon, 23 to 31 August 2014. DebConf14 attendees participated in talks, discussions, workshops and programming sessions. Video teams captured a lot of the main talks and discussions for streaming for interactive attendees and for the Debian video archive. Between the video, presentations, and handouts the coverage came from the attendees in blogs, posts, and project updates. We ve gathered a few articles for your reading pleasure: Gregor Herrmann and a few members of the Debian Perl group had an informal unofficial pkg-perl micro-sprint and were very productive. Vincent Sanders shared an inspired gift in the form of a plaque given to Russ Allbery in thanks for his tireless work of keeping sanity in the Debian mailing lists. Pictures of the plaque and design scheme are linked in the post. Vincent also shared his experiences of the conference and hopes the organisers have recovered. Noah Meyerhans adventuring to Debian by train, (Inter)netted some interesting IPv6 data for future road and railwarriors. Hideki Yamane sent a gentle reminder for English speakers to speak more slowly. Daniel Pocock posted of GSoC talks at DebConf14, highlights include the Java Project Dependency Builder and the WebRTC JSCommunicator. Thomas Goirand gives us some insight into a working task list of accomplishments and projects he was able to complete at DebConf14, from the OpenStack discussion to tasksel talks, and completion of some things started last year at DebConf13. Antonio Terceiro blogged about debci and the Debian Continuous Integration project, Ruby, Redmine, and Noosfero. His post also shares the atmosphere of being able to interact directly with peers once a year. Stefano Zacchiroli blogged about a talk he did on debsources which now has its own HACKING file. Juliana Louback penned: DebConf 2014 and How I Became a Debian Contributor. Elizabeth Krumbach Joseph s in-depth summary of DebConf14 is a great read. She discussed Debian Validation & CI, debci and the Continuous Integration project, Automated Validation in Debian using LAVA, and Outsourcing webapp maintenance. Lucas Nussbaum by way of a blog post releases the very first version of Debian Trivia modelled after the TCP/IP Drinking Game. Fran ois Marier s shares additional information and further discussion on Outsourcing your webapp maintenance to Debian. Joachim Breitner gave a talk on Haskell and Debian, created a new tool for binNMUs for Haskell packages which runs via cron job. The output is available for Haskell and for OCaml, and he still had a small amount of time to go dancing. Jaldhar Harshad Vyas was not able to attend DebConf this year, but he did tune in to the videos made available by the video team and gives an insightful viewpoint to what was being seen. J r my Bobbio posted about Reproducible builds in Debian in his recap of DebConf14. One of the topics at hand involved defining a canonical path where packages must be built and a BOF discussion on reproducible builds from where the conversation moved to discussions in both Octave and Groff. New helpers dh_fixmtimes and dh_genbuildinfo were added to BTS. The .buildinfo format has been specified on the wiki and reviewed. Lots of work is being done in the project, interested parties can help with the TODO list or join the new IRC channel #debian-reproducible on irc.debian.org. Steve McIntyre posted a Summary from the d-i / debian-cd BoF at DC14, with some of the session video available online. Current jessie D-I needs some help with the testing on less common architectures and languages, and release scheduling could be improved. Future plans: Switching to a GUI by default for jessie, a default desktop and desktop choice, artwork, bug fixes and new architecture support. debian-cd: Things are working well. Improvement discussions are on selecting which images to make I.E. netinst, DVD, et al., debian-cd in progress with http download support, Regular live test builds, Other discussions and questions revolve around which ARM platforms to support, specially-designed images, multi-arch CDs, and cloud-init based images. There is also a call for help as the team needs help with testing, bug-handling, and translations. Holger Levsen reports on feedback about the feedback from his LTS talk at DebConf14. LTS has been perceived well, fits a demand, and people are expecting it to continue; however, this is not without a few issues as Holger explains in greater detail the lacking gatekeeper mechanisms, and how contributions are needed from finance to uploads. In other news the security-tracker is now fixed to know about old stable. Time is short for that fix as once jessie is released the tracker will need to support stable, oldstable which will be wheezy, and oldoldstable. Jonathan McDowell s summary of DebConf14 includes a fair perspective of the host city and the benefits of planning of a good DebConf14 location. He also talks about the need for facetime in the Debian project as it correlates with and improves everyone s ability to work together. DebConf14 also provided the chance to set up a hard time frame for removing older 1024 bit keys from Debian keyrings. Steve McIntyre posted a Summary from the State of the ARM BoF at DebConf14 with updates on the 3 current ports armel, armhf and arm64. armel which targets the ARM EABI soft-float ARMv4t processor may eventually be going away, while armhf which targets the ARM EABI hard-float ARMv7 is doing well as the cross-distro standard. Debian is has moved to a single armmp kernel flavour using Device Tree Blobs and should be able to run on a large range of ARMv7 hardware. The arm64 port recently entered the main archive and it is hoped to release with jessie with 2 official builds hosted at ARM. There is talk of laptop development with an arm64 CPU. Buildds and hardware are mentioned with acknowledgements for donated new machines, Banana Pi boards, and software by way of ARM s DS-5 Development Studio - free for all Debian Developers. Help is needed! Join #debian-arm on irc.debian.org and/or the debian-arm mailing list. There is an upcoming Mini-DebConf in November 2014 hosted by ARM in Cambridge, UK. Tianon Gravi posted about the atmosphere and contrast between an average conference and a DebConf. Joseph Bisch posted about meeting his GSOC mentors, attending and contributing to a keysigning event and did some work on debmetrics which is powering metrics.debian.net. Debmetrics provides a uniform interface for adding, updating, and viewing various metrics concerning Debian. Harlan Lieberman-Berg s DebConf Retrospective shared the feel of DebConf, and detailed some of the work on debugging a build failure, work with the pkg-perl team on a few uploads, and work on a javascript slowdown issue on codeeditor. Ana Guerrero L pez reflected on Ten years contributing to Debian.

Niels Thykier: Lintian Upcoming API making it easier to write correct and safe code

The upcoming version of Lintian will feature a new set of API that attempts to promote safer code. It is hardly a ground-breaking discovery , just a much needed feature. The primary reason for this API is that writing safe and correct code is simply too complicated that people get it wrong (including yours truly on occasion). The second reason is that I feel it is a waste having to repeat myself when reviewing patches for Lintian. Fortunately, the kind of issues this kind of mistake creates are usually minor information leaks, often with no chance of exploiting it remotely without the owner reviewing the output first[0]. Part of the complexity of writing correct code originates from the fact that Lintian must assume Debian packages to be hostile until otherwise proven[1]. Consider a simplified case where we want to read a file (e.g. the copyright file):
package Lintian::cpy_check;
use strict; use warnings; use autodie;
sub run  
  my ($pkg, undef, $info) = @_;
  my $filename = "usr/share/doc/$pkg/copyright";
  # BAD: This is an example of doing it wrong
  open(my $fd, '<', $info->unpacked($filename));
  ...;
  close($fd);
  return;
 
This has two trivial vulnerabilities[2].
  1. Any part of the path (usr,usr/share, ) can be asymlink to somewhere else like /
    1. Problem: Access to potentially any file on the system with the credentials of the user running Lintian. But even then, Lintian generally never write to those files and the user has to (usually manually) disclose the report before any information leak can be completed.
  2. The target path can point to a non-file.
    1. Problem: Minor inconvenience by DoS of Lintian. Examples include a named pipe, where Lintian will get stuck until a signal kills it.

Of course, we can do this right[3]:
package Lintian::cpy_check;
use strict; use warnings; use autodie;
use Lintian::Util qw(is_ancestor_of);
sub run  
  my ($pkg, undef, $info) = @_;
  my $filename = "usr/share/doc/$pkg/copyright";
  my $root = $info->unpacked
  my $path = $info->unpacked($filename);
  if ( -f $path and is_ancestor_of($root, $path))  
    open(my $fd, '<', $path);
    ...;
    close($fd);
   
  return;
 
Where is_ancestor_of is the only available utility to assist you currently. It hides away some 10-12 lines of code to resolve the two paths and correctly asserting that $path is (an ancestor of) $root. Prior to Lintian 2.5.12, you would have to do that ancestor check by hand in each and every check[4]. In the new version, the correct code would look something like this:
package Lintian::cpy_check;
use strict; use warnings; use autodie;
sub run  
  my ($pkg, undef, $info) = @_;
  my $filename = "usr/share/doc/$pkg/copyright";
  my $path = $info->index_resolved_path($filename);
  if ($path and $path->is_open_ok)  
    my $fd = $path->open;
    ...;
    close($fd);
   
  return;
 
Now, you may wonder how that promotes safer code. At first glance, the checking code is not a lot simpler than the previous correct example. However, the new code has the advantage of being safer even if you forget the checks. The reasons are:
  1. The return value is entirely based on the file index of the package (think: tar vtf data.tar.gz). At no point does it use the file system to resolve the path. Whether your malicious package trigger an undef warning based on the return value of index_resolved_index leaks nothing about the host machine.
    1. However, it does take safe symlinks into account and resolves them for you. If you ask for foo/bar and foo is a symlink to baz and baz/bar exists in the package, you will get baz/bar . If baz/bar happens to be a symlink, then it is resolved as well.
    2. Bonus: You are much more likely to trigger the undef warning during regular testing, since it also happens if the file is simply missing.
  2. If you attempt to call $path->open without calling $path->is_open_ok first, Lintian can now validate the call for you and stop it on unsafe actions.
It also has the advantage of centralising the code for asserting safe access, so bugs in it only needs to be fixed in one place. Of course, it is still possible to write unsafe code. But at least, the new API is safer by default and (hopefully) more convenient to use. [0] Lintian.debian.org being the primary exception here. [1] This is in contrast to e.g. piuparts, which very much trusts its input packages by handing the package root access (albeit chroot ed, but still). [2] And also a bug. Not all binary packages have a copyright instead some while have a symlink to another package. [3] The code is hand-typed into the blog without prior testing (not even compile testing it). The code may be subject to typos, brown-paper-bag bugs etc. which are all disclaimed (of course). [4] Fun fact, our documented example for doing it correctly prior to implementing is_ancestor_of was in fact not correct. It used the root path in a regex (without quoting the root path) fortunately, it just broke lintian when your TMPDIR / LINTIAN_LAB contained certain regex meta-characters (which is pretty rare).

26 September 2014

Holger Levsen: 20140925-reproducible-builds

Reproducible builds? I never did any - manually :) I've never done a reproducible build attempt of any package, manually, ever. But what I've done now is setting up reproducible builds on jenkins.debian.net which will build hundreds or thousands of packages, hopefully reproducibly, regularily in the future. Thanks to Lunar's and many other peoples work, this was actually rather easy. If you want to do this manually, it should take you just a few minutes to setup a suitable build environment. So three days ago when I wasn't exactly bored I decided that it was a good moment to implement some reproducible build jobs on jenkins.d.n, and so I gave it a try and two hours later the basic implementation was working, and then it was an evening and morning of fine tuning until I was mostly satisfied. Since then there has been some polishing, but the basic setup is done and has been working since. What's the result? One job, reproducible_setup will just create a suitable environment for pbuilding reproducible packages as documented so well on the Debian wiki. And as that job runs 3.5 minutes only (to debootstrap from scratch), it's run daily. And then there are currently 16 other jobs, which test reproducible builds in different areas: d-i, core, some six major desktops and some selected desktop applications, some security + privacy related packages, some build chains we have in Debian, libreoffice and X.org. Most of these jobs run several hours, but luckily not days. And they discover packages which still fail to build reproducibly, which already has caused some bugs to be filed, eg. #762732 "libdebian-installer: please do not write timestamps in Doxygen generated documentation". So this is the output from testing the reproducibilty of all debian-installer packages: 72 packages were successfully built reproducibly, while 6 packages failed to do so. I was quite impressed by these numbers as AFAIK noone tried to build d-i reproducibly before.
72 packages successfully built reproducibly: userdevfs user-setup usb-discover udpkg tzsetup rootskel rootskel-gtk rescue preseed pkgsel partman-xfs partman-target partman-partitioning partman-nbd partman-multipath partman-md partman-lvm partman-jfs partman-iscsi partman-ext3 partman-efi partman-crypto partman-btrfs partman-basicmethods partman-basicfilesystems partman-base partman-auto partman-auto-raid partman-auto-lvm partman-auto-crypto partconf os-prober oldsys-preseed nobootloader network-console netcfg net-retriever mountmedia mklibs media-retriever mdcfg main-menu lvmcfg lowmem localechooser live-installer lilo-installer kickseed kernel-wedge kbd-chooser iso-scan installation-report installation-locale hw-detect grub-installer finish-install efi-reader dh-di debian-installer-utils debian-installer-netboot-images debian-installer-launcher clock-setup choose-mirror cdrom-retriever cdrom-detect cdrom-checker cdebconf-terminal cdebconf-entropy bterm-unifont base-installer apt-setup anna 
6 packages failed to built reproducibly: win32-loader libdebian-installer debootstrap console-setup cdebconf busybox 
What's also impressive: all packages for the newly introduced Cinnamon Desktop build reproducibly from the start! The jenkins setup is configured via just three small files: That's it and that's enough to keep several cores busy for days. :-) But as each job only takes a few hours each is scheduled twice a month and more jobs and packages shall be added in future (with some heuristics to schedule known good packages less often...) I guess it's an appropriate opportunity to say "many thanks to Profitbricks", who have been donating the powerful virtual machine jenkins.debian.net is running on since October 2012. I also want to say "many many thanks to Helmut" (Grohne) who has recently joined me in maintaining this jenkins setup. And then I'd like to thank "the KGB trio" (Gregor, Tincho and Dam!) for providing those KGB bots on IRC, which are very helpful for providing notifications on IRC channels and last but not least thanks to everybody who contributed so that reproducible builds got this far! Keep up the jolly good work! And If you happen to know failing packages not included in job-cfg/reproducible.yaml I'd like to hear about those, so they'll get regularily tested and appear on the radar, until finally bugs are filed, fixed and migrated to stable. So one day all binary packages in Debian stable will be build reproducibly. An important step on this road is probably to have this defined as an release goal for Jessie+1. And then for jessie+1 hopefully the first 10k packages will build reproducibly? Or whooping 23k maybe? ;-) And maybe release jessie+2 with 100%?!? We will see! Even Jessie already has quite some packages (someone needs to count them...) which build reproducibly with just modified dpkg(-dev) and debhelper packages alone... So let's fix all the bugs! That said, an easier start for most of you is probably the list of useful things you (yes, you!) can do! :-) Oh, and last but surely not least in my book: many thanks too to the nice people hosting me so friendly in the last days! Keep on rockin'!

Dirk Eddelbuettel: R and Docker

r and docker talk picture by @mediafly Earlier this evening I gave a short talk about R and Docker at the September Meetup of the Docker Chicago group. Thanks to Karl Grzeszczak for setting the meeting, and for providing a pretty thorough intro talk regarding CoreOS and Docker. My slides are now up on my presentations page.

25 September 2014

Petter Reinholdtsen: Suddenly I am the new upstream of the lsdvd command line tool

I use the lsdvd tool to handle my fairly large DVD collection. It is a nice command line tool to get details about a DVD, like title, tracks, track length, etc, in XML, Perl or human readable format. But lsdvd have not seen any new development since 2006 and had a few irritating bugs affecting its use with some DVDs. Upstream seemed to be dead, and in January I sent a small probe asking for a version control repository for the project, without any reply. But I use it regularly and would like to get an updated version into Debian. So two weeks ago I tried harder to get in touch with the project admin, and after getting a reply from him explaining that he was no longer interested in the project, I asked if I could take over. And yesterday, I became project admin. I've been in touch with a Gentoo developer and the Debian maintainer interested in joining forces to maintain the upstream project, and I hope we can get a new release out fairly quickly, collecting the patches spread around on the internet into on place. I've added the relevant Debian patches to the freshly created git repository, and expect the Gentoo patches to make it too. If you got a DVD collection and care about command line tools, check out the git source and join the project mailing list. :)

Next.

Previous.