Search Results: "will"

19 April 2017

Reproducible builds folks: Reproducible Builds: week 103 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday April 9 and Saturday April 15 2017: Upcoming events On April 26th Chris Lamb will give a talk at foss-north 2017 in Gothenburg, Sweden on Reproducible Builds. Media coverage Jake Edge wrote a summary of Vagrant Cascadian's talk on Reproducible Builds at LibrePlanet. Toolchain development and fixes Ximin Luo forwarded patches to GCC for BUILD_PATH_PREFIX_MAP support. With this patch to backported to GCC-6, as well as a patched dpkg to set the environment variable, he scheduled ~3,300 packages that are unreproducible in unstable-amd64 but reproducible in testing-amd64 - because we vary the build path in the former but not latter case. Our infrastructure ran these in just under 3 days, and we reproduced ~1,700 extra packages. This is about 6.5% of ~26,100 Debian source packages, and about 1/2 of the ones whose irreproducibility is due to build-path issues. Most of the rest are not related to GCC, such as things built by R, OCaml, Erlang, LLVM, PDF IDs, etc. (The dip afterwards, in the graph linked above, is due to reverting back to an unpatched GCC-6, but we'll be rebasing the patch continually over the next few weeks so the graph should stay up.) Packages reviewed and fixed, and bugs filed Chris Lamb: Chris West: Reviews of unreproducible packages 38 package reviews have been added, 111 have been updated and 85 have been removed in this week, adding to our knowledge about identified issues. 6 issue types have been updated: Added: Updated: Removed: diffoscope development Development continued in git on the experimental branch: Chris Lamb: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: Misc. This week's edition was written by Ximin Luo, Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Steve Kemp: 3d-Printing is cool

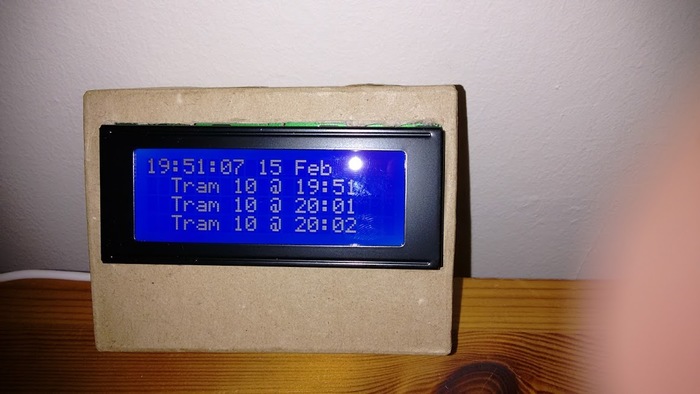
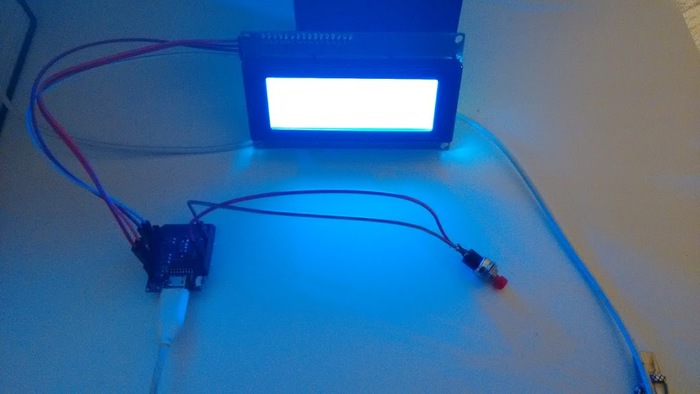
I've heard about 3d-printing a lot in the past, although the hype seems to have mostly died down. My view has always been "That seems cool", coupled with "Everybody says making the models is very hard", and "the process itself is fiddly & time-consuming". I've been sporadically working on a project for a few months now which displays tram-departure times, this is part of my drive to "hardware" things with Arduino/ESP8266 devices . Most visitors to our flat have commented on it, at least once, and over time it has become gradually more and more user-friendly. Initially it was just a toy-project for myself, so everything was hard-coded in the source but over time that changed - which I mentioned here, (specifically the Access-point setup): I've now wired up an input-button to the device too, experimenting with the different ways that a single button can carry out multiple actions: Anyway the software is neat, and I can't think of anything obvious to change. So lets move onto the real topic of this post: 3D Printing. I randomly remembered that I'd heard about an online site holding 3D-models, and on a whim I searched for "4x20 LCD". That lead me to this design, which is exactly what I was looking for. Just like open-source software we're now living in a world where you can get open-source hardware! How cool is that? I had to trust the dimensions of the model, and obviously I was going to mount my new button into the box, rather than the knob shown. But having a model was great. I could download it, for free, and I could view it online at viewstl.com. But with a model obtained the next step was getting it printed. I found a bunch of commercial companies, here in Europe, who would print a model, and ship it to me, but when I uploaded the model they priced it at 90+. Too much. I'd almost lost interest when I stumbled across a site which provides a gateway into a series of individual/companies who will print things for you, on-demand: 3dhubs. Once again I uploaded my model, and this time I was able to select a guy in the same city as me. He printed my model for 1/3-1/4 of the price of the companies I'd found, and sent me fun pictures of the object while it was in the process of being printed. To recap I started like this:
Then I boxed it in cardboard which looked better than nothing, but still not terribly great:
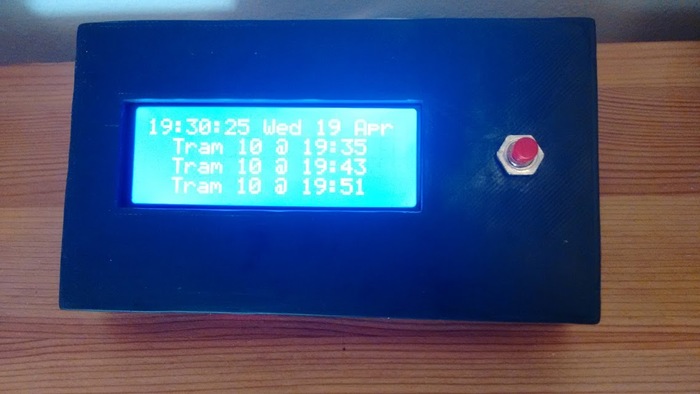
Now I've found an online case-design for free, got it printed cheaply by a volunteer (feels like the wrong word, after-all I did pay him), and I have something which look significantly more professional:
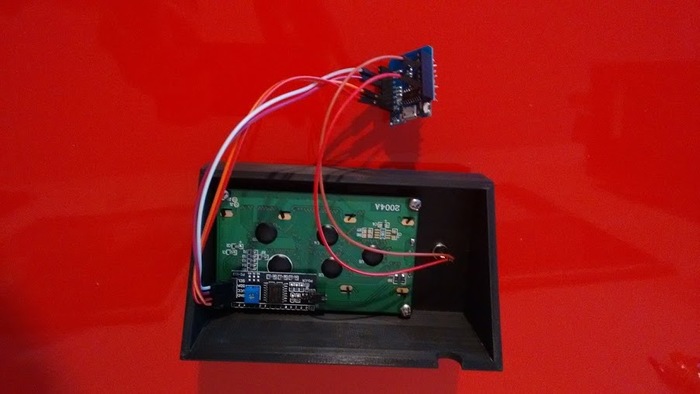
Inside it looks as neat as you would expect:
Of course the case still cost 5 times as much as the actual hardware involved (button: 0.05, processor-board 2.00 and LCD I2C display 3.00). But I've gone from being somebody who had zero experience with hardware-based projects 4 months ago, to somebody who has built a project which is functional and "pretty". The internet really is a glorious thing. Using it for learning, and coding is good, using it for building actual physical parts too? That's something I never could have predicted a few years ago and I can see myself doing it more in the future. Sure the case is a little rough around the edges, but I suspect it is now only a matter of time until I learn how to design my own models. An obvious extension is to add a status-LED above the switch, for example. How hard can it be to add a new hole to a model? (Hell I could just drill it!)

Antoine Beaupr : The rise of Linux-based networking hardware

Linux usage in networking hardware has been on the rise for some time. During the latest Netdev conference held in Montreal this April, people talked seriously about Linux running on high end, "top of rack" (TOR) networking equipment. Those devices have long been the realm of proprietary hardware and software companies like Cisco or Juniper, but Linux seems to be making some significant headway into the domain. According to Shrijeet Mukherjee, VP of Engineering at Cumulus Networks: "we are seeing a 28% adoption rate in the Fortune 50" companies. As someone who has worked in system administration and networking for over a decade, I was surprised by this: switches have always been black boxes of proprietary hardware that we barely get a shell into. But as more and more TOR hardware gets Linux support, some of that work trickles down outside of that niche. Are we really seeing the rise of Linux in high-end networking hardware?

Linux as the standard interface During his keynote at Netdev, Jesse Brandeburg explained that traffic is exploding on the Internet: "From 2006 to 2016 the compound annual growth rate was 78% of network traffic. So the network traffic is growing like crazy. In 2010 to 2023, it's going to grow by a thousand times." He also mentioned Intel was working on devices that could do up to 400 Gbps. In his talk, he argued that Linux has a critical place in the modern world by repeating the mantra that "everything is on the network, and the network runs Linux", but does it really? Through Android, Linux has become the most popular end-user device operating system and is also dominant on the server but what about the actual fabric of the network: the routers and switches that interconnect all those machines? Mukherjee, in his own keynote, argued that even though Linux has achieved dominance in the server and virtualization markets, there is a "discontinuity [...] at the boundary where the host and the network meet" and argued "that the host without the network will not survive". In other words, proprietary hardware and software in the network threaten free software in the server. Even though some manufacturers are already providing a "Linux interface" in their hardware, it is often only some sort of compatibility shell which might be compared with the Ubuntu compatibility layer in Windows: it's not a real Linux. Mukherjee pushed this idea further by saying that those companies are limiting themselves by not using the full Linux stack. He presented Linux as the "top vehicle for innovation" that provides a featureful network stack, citing VXLAN, eBPF, and Quagga as prime features used on switches. Mukherjee also praised the diversity of the user-space Linux ecosystem as something that commercial alternatives can't rival; he compared the faster Linux development to the commercial sector where similar top features stay in the beta stage for up to 3 years. Because of its dominance in the server market, consumers are expecting a Linux-like interface on their networking gear now, which means Linux could be the standard interface all providers strive toward. As a Debian developer, I can't help but smile at the thought; if there's one thing we have not been able to do among Linux distributions, it's pretty much standardize user space in a consistent interface. POSIX is old and incomplete, the FHS is showing its age, and most distributions have abandoned LSB. Yet, the idea is certainly enticing: there is a base set of tools and applications, especially for the Linux kernel, that are standardized: iproute2, ethtool, and iptables are generally consistent across distributions, even though each distribution has its own way of using them. Yet Linux is not dominant, why? Mukherjee identified the problem as "packaging issues" and listed a set of features he would like Linux to improve:
  • Standardization of the ethtool interface. The idea is to make ethtool a de-facto standard to manage switches and ports. Mukherjee gave the example that data centers spend more money on cables than any other hardware and explained that making it easier to identify cables is therefore a key functionality. Getting consistent interface naming was also a key problem identified by numerous participants at the conference. While systemd tried to fix this with the predictable network interface names specification, the interface names are not necessarily predictable across virtual machines or on special hardware; in fact, this was the topic of the first talk of the conference. ethtool also needs to support interfaces that run faster than 1 Gbps, something that still has limited support in Linux at the moment.
  • Scaling of the Linux bridge. Through the rise of "software defined networking", we are likely to see multi-switch virtual environments that need to scale to hundreds of interfaces and devices easily. This is something the Linux bridge was never designed to do and it's showing scalability issues. During the conference, there was hope that the new XDP and eBPF developments could help, but also concerns this would create yet another bridge layer inside the kernel.
Cumulus's goal seems to be to establish Linux as the industry standard for this new era of networking and it is not alone. Through its Open Compute project, Facebook is sharing open designs of data center products and, while we have yet to see commercial off-the-shelf (COTS) 24 and 48-port gigabit switches trickle down to the consumer market, the company is definitely deploying new hardware based on those specifications in its own data centers, and those devices are often based on Linux.

The Linux switch implementation So how exactly do switches work in Linux? The Linux kernel manipulates switches with three different operation structures: switchdev_ops, which we previously covered, ethtool_ops, and netdev_ops. Certain switches, however, also need distributed switch architecture (DSA) features to be properly handled. DSA is a more obscure part of the network stack that allows Linux to represent hardware switches or chains of switches using regular Linux tools like bridge, ifconfig, and so on. While switchdev is a new layer, DSA has been in the kernel since 2.6.28 in 2008. Originally developed to support Marvell switches, DSA is now a generic layer deployed in WiFi access points, set-top boxes, on-board flight entertainment systems, trains, and other industrial equipment. Switches that have an Ethernet controller need DSA, whereas the kernel can support switches without Ethernet controllers directly with switchdev drivers. The first years of DSA's development consisted only of basic maintenance but, in the last three years, DSA has seen a resurgence of contributions, as part of Linux networking push to support hardware offloading and network switches. Between 2014 and 2015, DSA added support for Broadcom hardware, wake on LAN, and hardware port bridging, among other features. DSA's development was parallel to swconfig, written by the OpenWrt project to support the small office and home office (SOHO) routers that the project is targeting. The main difference between swconfig and DSA is that DSA-supported switches show one network interface per port, whereas swconfig-configured switches show up as a single port, which limits the amount of information that can be extracted from the switch. For example, you cannot have per-port traffic statistics with swconfig. That limitation is what led to the creation of the switchdev framework, when swconfig was proposed (then refused) for inclusion in mainline. Another goal of switchdev was to support bridge hardware offloading and network interface card (NIC) virtualization. Also, whereas swconfig uses virtual LAN (VLAN) tagging to address ports, DSA enables the use of device-specific tagging headers to address different ports, which enables DSA to have better control over the switches. This allows, for example, DSA to do internet group management protocol (IGMP) snooping or implement the spanning tree protocol, whereas swconfig doesn't have those features. Some switches are actually connected to the host CPU through an Ethernet interface instead of regular PCI-Express interface, and DSA supports this as well. One advantage that remains in the swconfig approach is that it treats the internal switch as a simple external switch, and addresses ports with standard VLAN tags. This is something DSA could do, as well, but no one has bothered implementing this just yet. For now, DSA drivers use device-specific tagging mechanisms that limit the number of supported devices. Other areas of future improvement for DSA are better multi-chip support, IGMP snooping, and bonding, as well as firewall, NAT, and TC offloading.

Where is the freedom? Given all those technical improvements, you might rightfully wonder if your own wireless router or data center switch runs Linux. In recent years, we have seen more and more networking devices shipped with Linux and sometimes even OpenWrt (e.g. in the case of the Turris Omnia, which we previously covered), and especially on SOHO routers, but it sometimes means a crippled operating system that only offers you a proprietary web interface. But at least those efforts make it easier to deploy free operating systems on those devices. Based on my experience running OpenWrt on wireless routers to build the Montreal mesh network, deploying Linux on routers and switches has always been a manual process. The Ubiquiti hardware being used in the mesh network comes with an OpenWrt derivative, but it includes proprietary drivers and a proprietary web interface. To use the mesh networking protocol that was chosen, it was necessary to deploy custom OpenWrt images by hand. For years, it was a continuous struggle for OpenWrt developers to liberate generation after generation of proprietary hardware with companies like Cisco locking down the venerable WRT platform in 2006 and the US Federal Communications Commission (FCC) rules that forced TP-Link to block free software on its routers, a change that was later reverted. Most hardware providers are obviously not dedicated to software freedom: deploying Linux on their hardware is for them an economic, not political choice. As you might expect, a "Linux router" these days often means a closed device and operating system, using Linux as the only free component. I had the privilege of doing some reverse engineering on the SmartRG SR603n VDSL modem, which also doubles as a WiFi router and VoIP phone adapter. I was able to get a shell on that machine, and what I found was a custom operating system built on top of the Linux kernel. I wrote a detailed report about this two years ago and the situation then was pretty grim. Another experience I had was working over a decade in data centers, which tells an even worse story: most switches and routers there are not running free software at all. We have deployed HP ProCurve switches that provide free (as in beer) software updates and have struggled for years to find free (as in speech) software alternatives for those. We built our own routers using COTS server hardware, at a significant performance cost over the dedicated application-specific integrated circuits (ASICs) built into commercial routers, which do not offer us the trust and flexibility we were looking for. But Linux is definitely making some headway, and has been for a while. When we covered switchdev in February 2016, it was just getting started, but now vendors like Mellanox, Broadcom, Cumulus, and Intel are writing and shipping code using the framework. Cumulus, in particular, is developing a Debian-based distribution (Cumulus Linux) that it deploys for clients on targeted hardware. Most of the hardware in that list, however, is not actually open in the more radical sense: they are devices that can run free software but are not generally open-source hardware. There are some exceptions, but they sit at the higher end of the spectrum: most organizations probably don't need a 100 Gbps ports, let alone the 128 ports in the Backpack switch that Cumulus is shipping. How much this translates to actual freedom for the end-user is therefore questionable. While I have seen encouraging progress on the high end of the hardware spectrum at Netdev, I'm not sure this will translate into immediate wins in the data center or even for home users in the short term. In the long term, however, we will hopefully see some progress in Linux's rise in general-purpose networking hardware following its dominance in general-purpose computing.
The author would like to thank the Netdev organizers for travel assistance. Also, thanks to Andrew Lunn for a technical review of this article. Note: this article first appeared in the Linux Weekly News.

18 April 2017

Steinar H. Gunderson: Chinese HDMI-to-SDI converters

I often need to convert signals from HDMI to SDI (and occasionally back). This requires a box of some sort, and eBay obliges; there's a bunch of different sellers of the same devices, selling them around $20 25. They don't seem to have a brand name, but they are invariably sold as 3G-SDI converters (meaning they should go up to 1080p60) and look like this: There are also corresponding SDI-to-HDMI converters that look pretty much the same except they convert the other way. (They're easy to confuse, but that's not a problem unique tothem.) I've used them for a while now, and there are pros and cons. They seem reliable enough, and they're 1/4th the price of e.g. Blackmagic's Micro converters, which is a real bargain. However, there are also some issues: The last issue is by far the worst, but it only affects 3G-SDI resolutions. 720p60, 1080p30 and 1080i60 all work fine. And to be fair, not even Blackmagic's own converters actually send 352M correctly most of the time I wish there were a way I could publish this somewhere people would actually read it before buying these things, but without a name, it's hard for people to find it. They're great value for money, and I wouldn't hesitate to recommend them for almost all use but then, there's that almost. :-)
Bits from Debian: Call for Proposals for DebConf17 Open Day

The DebConf team would like to call for proposals for the DebConf17 Open Day, a whole day dedicated to sessions about Debian and Free Software, and aimed at the general public. Open Day will preceed DebConf17 and will be held in Montreal, Canada, on August 5th 2017. DebConf Open Day will be a great opportunity for users, developers and people simply curious about our work to meet and learn about the Debian Project, Free Software in general and related topics. Submit your proposal We welcome submissions of workshops, presentations or any other activity which involves Debian and Free Software. Activities in both English and French are accepted. Here are some ideas about content we'd love to offer during Open Day. This list is not exhaustive, feel free to propose other ideas! To submit your proposal, please fill the form at https://debconf17.debconf.org/talks/new/ Volunteer We need volunteers to help ensure Open Day is a success! We are specifically looking for people familiar with the Debian installer to attend the Debian installfest, as resources for people seeking help to install Debian on their devices. If you're interested, please add your name to our wiki: https://wiki.debconf.org/wiki/DebConf17/OpenDay#Installfest Attend Participation to Open Day is free and no registration is required. The schedule for Open Day will be announced in June 2017. DebConf17 logo

17 April 2017

Sylvain Beucler: Practical basics of reproducible builds 3

On my quest to generate reproducible standalone binaries for GNU FreeDink, I met new friends but currently lie defeated by an unexpected enemy... Episode 1: Episode 2:
First, the random build differences when using -Wl,--no-insert-timestamp were explained.
peanalysis shows random build dates:
$ reprotest 'i686-w64-mingw32.static-gcc hello.c -I /opt/mxe/usr/i686-w64-mingw32.static/include -I/opt/mxe/usr/i686-w64-mingw32.static/include/SDL2 -L/opt/mxe/usr/i686-w64-mingw32.static/lib -lmingw32 -Dmain=SDL_main -lSDL2main -lSDL2 -lSDL2main -Wl,--no-insert-timestamp -luser32 -lgdi32 -lwinmm -limm32 -lole32 -loleaut32 -lshell32 -lversion -o hello && chmod 700 hello && analysePE.py hello   tee /tmp/hello.log-$(date +%s); sleep 1' 'hello'
$ diff -au /tmp/hello.log-1*
--- /tmp/hello.log-1490950327   2017-03-31 10:52:07.788616930 +0200
+++ /tmp/hello.log-1523203509   2017-03-31 10:52:09.064633539 +0200
@@ -18,7 +18,7 @@
 found PE header (size: 20)
     machine: i386
     number of sections: 17
-    timedatestamp: -1198218512 (Tue Jan 12 05:31:28 1932)
+    timedatestamp: 632430928 (Tue Jan 16 09:15:28 1990)
     pointer to symbol table: 4593152 (0x461600)
     number of symbols: 11581 (0x2d3d)
     size of optional header: 224
@@ -47,7 +47,7 @@
     Win32VersionValue: 0
     size of image (memory): 4640768
     size of headers (offset to first section raw data): 1536
-    checksum (for drivers): 4927867
+    checksum (for drivers): 4922616
     subsystem: 3
         win32 console binary
     DllCharacteristics: 0
Stephen Kitt mentioned 2 simple patches (1 2) fixing uninitialized memory in binutils. These patches fix the variation and were submitted to MXE (pull request).
Next was playing with compiler support for SOURCE_DATE_EPOCH (which e.g. sets __DATE__ macros).
The FreeDink DFArc frontend historically displays a build date in the About box:
    "Build Date: %s\n", ..., __TDATE__
sadly support is only landing upstream in GCC 7 :/
I had to remove that date.
Now comes the challenging parts. All my tests with reprotest checked. I started writing a reproducible build environment based on Docker (git browse).
At first I could not run reprotest in the container, so I reworked it with SSH support, and reprotest validated determinism.
(I also generate a reproducible .zip archive, more on that later.) So far so good, but were the release identical when running reprotest successively on the different environments?
(reminder: this is a .exe build that is insensitive to varying path, hence consistent in a full reprotest)
$ sha256sum *.zip
189d0ca5240374896c6ecc6dfcca00905ae60797ab48abce2162fa36568e7cf1  freedink-109.0-bin-buildsh.zip
e182406b4f4d7c3a4d239eee126134ba5c0304bbaa4af3de15fd4f8bda5634a9  freedink-109.0-bin-docker.zip
e182406b4f4d7c3a4d239eee126134ba5c0304bbaa4af3de15fd4f8bda5634a9  freedink-109.0-bin-reprotest-docker.zip
37007f6ee043d9479d8c48ea0a861ae1d79fb234cd05920a25bb3db704828ece  freedink-109.0-bin-reprotest-null.zip
Ouch! Even though both the Docker and my host are running Stretch, there are differences.
For the two host builds (direct and reprotest), there is a subtle but simple difference: HOME.
HOME is invariably non-existant in reprotest, while my normal compilation environment has an existing home (duh!). This caused a subtle bug when cross-compiling with mingw and wine-binfmt:
  checking whether we are cross compiling... no
  checking whether we are cross compiling... yes
The respective binaries were very different notably due to a different config.h.
This can be fixed by specifying --build in addition to --host when calling ./configure. I suggested reprotest have one of the tests with a valid HOME (#860428).
Now comes the big one, after the fix I still got:
$ sha256sum *.zip
3545270ef6eaa997640cb62d66dc610a328ce0e7d412f24c8f18fdc7445907fd  freedink-109.0-bin-buildsh.zip
cc50ec1a38598d143650bdff66904438f0f5c1d3e2bea0219b749be2dcd2c3eb  freedink-109.0-bin-docker.zip
3545270ef6eaa997640cb62d66dc610a328ce0e7d412f24c8f18fdc7445907fd  freedink-109.0-bin-reprotest-chroot.zip
cc50ec1a38598d143650bdff66904438f0f5c1d3e2bea0219b749be2dcd2c3eb  freedink-109.0-bin-reprotest-docker.zip
3545270ef6eaa997640cb62d66dc610a328ce0e7d412f24c8f18fdc7445907fd  freedink-109.0-bin-reprotest-null.zip
There is consistency on my host, and consistency within docker, but both are different.
Moreover, all the .o files were identical, so something must have gone wrong when compiling the libs, that is MXE. After many checks it appears that libstdc++.a is different.
Just overwriting it gets me a consistent FreeDink release on all environments.
Still, when rebuilding it (make gcc), libstdc++.a always has the same environment-dependent checksum.
45f8c5d50a68aa9919ee3602a4e3f5b2bd0333bc8d781d7852b2b6121c8ba27b  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a  # host
6870b84f8e17aec4b5cf23cfe9c2e87e40d9cf59772a92707152361b6ebc1eb4  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a  # docker
The 2 libraries are much different, there's barely any blue in hexcompare. At that time, I realized that the Docker "official" Debian are not really official, as Joey explains.
Could it be that Docker maliciously tampered with the compiler as Ken Thompson warned in 1984?? Well before jumping to conclusion let's mix & match.
$ sudo env -i /usr/sbin/chroot chroot-docker/
$ exec bash -l
$ cd /opt/mxe
$ touch src/gcc.mk
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a 
6870b84f8e17aec4b5cf23cfe9c2e87e40d9cf59772a92707152361b6ebc1eb4  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
$ make gcc
[build]     gcc                    i686-w64-mingw32.static
[done]      gcc                    i686-w64-mingw32.static                                 2709464 KiB    7m2.039s
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a 
45f8c5d50a68aa9919ee3602a4e3f5b2bd0333bc8d781d7852b2b6121c8ba27b  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
# consistent with host builds
$ sudo tar -C chroot -c .   docker import - chroot-debootstrap
$ docker run -ti chroot-debootstrap /bin/bash
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
45f8c5d50a68aa9919ee3602a4e3f5b2bd0333bc8d781d7852b2b6121c8ba27b  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
$ touch src/gcc.mk
$ make gcc
[build]     gcc                    i686-w64-mingw32.static
[done]      gcc                    i686-w64-mingw32.static                                 2709412 KiB    7m6.608s
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
6870b84f8e17aec4b5cf23cfe9c2e87e40d9cf59772a92707152361b6ebc1eb4  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
# consistent with docker builds
So, AFAICS when building with: then depending on whether running in a container or not we get a consistent but different libstdc++.a. This kind of issue is not detected with a simple reprotest build, as it only tests variations within a fixed build environment.
This is quite worrisome, I intend to use a container to control my build environment, but I can't guarantee that the container technology will be exactly the same 5 years from now. All my setup is simple and available for inspection at https://git.savannah.gnu.org/cgit/freedink.git/tree/autobuild/freedink-w32-snapshot/. I'd very much welcome enlightenment :)

Norbert Preining: Systemd again (or how to obliterate your system)

Ok, I have been silent about systemd and its being forced onto us in Debian like force-feeding Foie gras gooses. I have complained about systemd a few times (here and here), but what I read today really made me loose my last drips of trust I had in this monster-piece of software. If you are up for some really surprising read about the main figure behind systemd, enjoy this github issue. It s about a bug that simply does the equivalent of rm -rf / in some cases. The OP gave clear indications, the bug was fixes immediately, but then a comment from the God Poettering himself appeared that made the case drip over:
I am not sure I d consider this much of a problem. Yeah, it s a UNIX pitfall, but rm -rf /foo/.* will work the exact same way, no?Lennart Poettering, systemd issue 5644
Well, no, a total of 1min would have shown him that this is not the case. But we trust this guy the whole management of the init process, servers, logs (and soon our toilet and fridge management, X, DNS, whatever you ask for). There are two issues here: One is that such a bug is lurking in systemd since probably years. The reason is simple we pay with these kinds of bugs for the incredible complexity increase of the init process which takes over too much services. Referring back to the Turing Award lecture given by Hoare, we see that systemd took the later path:
I conclude that there are two ways of constructing a software design: One way is to make it so simple that there are obviously no deficiencies and the other way is to make it so complicated that there are no obvious deficiencies. Antony Hoare, Turing Award Lecture 1980
The other issue is how systemd developers deal with bug reports. I have reported several cases here, this is just another one: Close the issue for comments, shut up, put it under the carpet. (Image credit: The musings of an Indian Faust)

Ross Gammon: My March 2017 Activities

March was a busy month, so this monthly report is a little late. I worked two weekends, and I was planning my Easter holiday, so there wasn t a lot of spare time. Debian
  • Updated Dominate to the latest version and uploaded to experimental (due to the Debian Stretch release freeze).
  • Uploaded the latest version of abcmidi (also to experimental).
  • Pinged the bugs for reverse dependencies of pygoocanvas and goocanvas with a view to getting them removed from the archive during the Buster cycle.
  • Asked for help on the Ubuntu Studio developers and users mailing lists to test the coming Ubuntu Studio 17.04 release ISO, because I would be away on holiday for most of it.
Ubuntu
  • Worked on ubuntustudio-controls, reverting it back to an earlier revision that Len said was working fine. Unfortunately, when I built and installed it from my ppa, it crashed. Eventually found my mistake with the bzr reversion, fixed it and prepared an upload ready for sponsorship. Submitted a Freeze Exception bug in the hope that the Release Team would accept it even though we had missed the Final Beta.
  • Put a new power supply in an old computer that was kaput, and got it working again. Set up Ubuntu Server 16.04 on it so that I could get a bit more experience with running a server. It won t last very long, because it is a 32 bit machine, and Ubuntu will probably drop support for that architecture eventually. I used two small spare drives to set up RAID 1 & LVM (so that I can add more space to it later). I set up some Samba shares, so that my wife will be able to get at them from her Windows machine. For music streaming, I set up Emby Server. I wold be great to see this packaged for Debian. I uploaded all of my photos and music for Emby to serve around the home (and remotely as well). Set up Obnam to back up the server to an external USB stick (temporarily until I set up something remote). Set LetsEncrypt with the wonderful Certbot program.
  • Did the Release Notes for Ubuntu Studio 17.04 Final Beta. As I was in Brussels for two days, I was not able to do any ISO testing myself.
Other
  • Measured up the new model railway layout and documented it in xtrkcad.
  • Started learning Ansible some more by setting up ssh on all my machines so that I could access them with Ansible and manipulate them using a playbook.
  • Went to the Open Source Days conference just down the road in Copenhagen. Saw some good presentations. Of interest for my previous work in the Debian GIS Team, was a presentation from the Danish Municipalities on how they run projects using Open Source. I noted how their use of Proj 4 and OSGeo. I was also pleased to see a presentation from Ximin Luo on Reproducible Builds, and introduced myself briefly after his talk (during the break).
  • Started looking at creating a Django website to store and publish my One Name Study sources (indexes). Started by creating a library to list some of my recently read Journals. I will eventually need to import all the others I have listed in a cvs spreadsheet that was originally exported from the commercial (Windows only) Custodian software.
Plan status from last month & update for next month Debian For the Debian Stretch release:
  • Keep an eye on the Release Critical bugs list, and see if I can help fix any. In Progress
Generally:
  • Package all the latest upstream versions of my Debian packages, and upload them to Experimental to keep them out of the way of the Stretch release. In Progress
  • Begin working again on all the new stuff I want packaged in Debian.
Ubuntu
  • Start working on an Ubuntu Studio package tracker website so that we can keep an eye on the status of the packages we are interested in. Started
  • Start testing & bug triaging Ubuntu Studio packages. In progress
  • Test Len s work on ubuntustudio-controls Done
  • Do the Ubuntu Studio Zesty 17.04 Final Beta release. Done
  • Sort out the Blueprints for the coming Ubuntu Studio 17.10 release cycle.
Other
  • Give JMRI a good try out and look at what it would take to package it. In progress
  • Also look at OpenPLC for simulating the relay logic of real railway interlockings (i.e. a little bit of the day job at home involving free software fun!). In progress

Russell Coker: More KVM Modules Configuration

Last year I blogged about blacklisting a video driver so that KVM virtual machines didn t go into graphics mode [1]. Now I ve been working on some other things to make virtual machines run better. I use the same initramfs for the physical hardware as for the virtual machines. So I need to remove modules that are needed for booting the physical hardware from the VMs as well as other modules that get dragged in by systemd and other things. One significant saving from this is that I use BTRFS for the physical machine and the BTRFS driver takes 1M of RAM! The first thing I did to reduce the number of modules was to edit /etc/initramfs-tools/initramfs.conf and change MODULES=most to MODULES=dep . This significantly reduced the number of modules loaded and also stopped the initramfs from probing for a non-existant floppy drive which added about 20 seconds to the boot. Note that this will result in your initramfs not supporting different hardware. So if you plan to take a hard drive out of your desktop PC and install it in another PC this could be bad for you, but for servers it s OK as that sort of upgrade is uncommon for servers and only done with some planning (such as creating an initramfs just for the migration). I put the following rmmod commands in /etc/rc.local to remove modules that are automatically loaded:
rmmod btrfs
rmmod evdev
rmmod lrw
rmmod glue_helper
rmmod ablk_helper
rmmod aes_x86_64
rmmod ecb
rmmod xor
rmmod raid6_pq
rmmod cryptd
rmmod gf128mul
rmmod ata_generic
rmmod ata_piix
rmmod i2c_piix4
rmmod libata
rmmod scsi_mod In /etc/modprobe.d/blacklist.conf I have the following lines to stop drivers being loaded. The first line is to stop the video mode being set and the rest are just to save space. One thing that inspired me to do this is that the parallel port driver gave a kernel error when it loaded and tried to access non-existant hardware.
blacklist bochs_drm
blacklist joydev
blacklist ppdev
blacklist sg
blacklist psmouse
blacklist pcspkr
blacklist sr_mod
blacklist acpi_cpufreq
blacklist cdrom
blacklist tpm
blacklist tpm_tis
blacklist floppy
blacklist parport_pc
blacklist serio_raw
blacklist button On the physical machine I have the following in /etc/modprobe.d/blacklist.conf. Most of this is to prevent loading of filesystem drivers when making an initramfs. I do this because I know there s never going to be any need for CDs, parallel devices, graphics, or strange block devices in a server room. I wouldn t do any of this for a desktop workstation or laptop.
blacklist ppdev
blacklist parport_pc
blacklist cdrom
blacklist sr_mod
blacklist nouveau blacklist ufs
blacklist qnx4
blacklist hfsplus
blacklist hfs
blacklist minix
blacklist ntfs
blacklist jfs
blacklist xfs

16 April 2017

Antoine Beaupr : Montreal Bug Squashing Party report

Un sommaire de cet article est galement traduit vers le fran ais, merci!
Last friday, a group of Debian users, developers and enthusiasts met at Koumbit.org offices for a bug squashing party. We were about a dozen people of various levels: developers, hackers and users. I gave a quick overview of Debian packaging using my quick development guide, which proved to be pretty useful. I made a deb.li link (https://deb.li/quickdev) for people to be able to easily find the guide on their computers. Then I started going through a list of different programs used to do Debian packaging, to try and see the level of the people attending: So mostly skilled Debian users (they know apt-get source) but not used to packaging (they don't know about dpkg-buildpackage). So I went through the list again and explained how they all fit together and could be used to work on Debian packages in the context of a Debian release bug squashing party. This was the fastest crash course in Debian packaging I have ever given (and probably the first too) - going through those tools in about 30 minutes. I was happy to have the guide that people could refer to later in the back. The first question after the presentation was "how do we find bugs"? which led me to add links to the UDD bugs page and release-critical bugs page. I also explained the key links on top of the UDD page to find specific sets of bugs, and explained the useful "patch" filter that allows to select bugs with our without patch. I guess that maybe half of the people were able to learn new, or improve their skills to make significant contributions or test actual patches. Other learned how to hunt and triage bugs in the BTS. Update: sorry for the wording: all contributions were really useful, thanks and apologies to bug hunters!! I myself learned how to use sbuild thanks to the excellent sbuild wiki page which I improved upon. A friend was able to pick up sbuild very quickly and use it to build a package for stretch, which I find encouraging: my first experience with pbuilder was definitely not as good. I have therefore starting the process of switching my build chroots to sbuild, which didn't go so well on Jessie because I use a backported kernel, and had to use the backported sbuild as well. That required a lot of poking around, so I ended up just using pbuilder for now, but I will definitely switch on my home machine, and I updated the sbuild wiki page to give out more explanations on how to setup pbuilder. We worked on a bunch of bugs, and learned how to tag them as part of the BSP, which was documented in the BSP wiki page. It seems we have worked on about 11 different bugs which is a better average than the last BSP that I organized, so I'm pretty happy with that. More importantly, we got Debian people together to meet and talk, over delicious pizza, thanks to a sponsorship granted by the DPL. Some people got involved in the next DebConf which is also great. On top of fixing bugs and getting people involved in Debian, my third goal was to have fun, and fun we certainly had. I didn't work on as many bugs as I expected myself, achieving only one upload in the end, but since I was answering so many questions left and right, I felt useful and that is certainly gratifying. Organization was simple enough: just get a place, send invites and get food, and the rest is just sharing knowledge and answering questions. Thanks everyone for coming, and let's do this again soon!

Shirish Agarwal: single person cult-based political parties

Summer heat

Summer heat

I would like to start with sharing is the mercury has been shot in recent times to record temperatures. For instance, Pune has been recording temperatures between 41 and 43 degrees consistently. The result of that has been a massive reduction in volunteer activity on my part as well as some reduction in work activity. The body wants and needs to conserve energy. Even my mobile phone s lithium-ion battery becomes too hot and I have to turn it off in the crucial time from 12 17:00 hrs after which the weather cools down a bit. I am curious to know if I m the only one or there are others like me. I have seen quite a few construction, re-construction and renovation projects taking quite a hit by this incredible heat wave. If it isn t climate change then I don t know what is. And this is not limited to Pune but the whole of Western Maharashtra, Gujarat, Madhya Pradesh and quite a few parts of North India too. In Pune we are expecting it to hit 45 degrees pretty soon. And I don t see this ending anytime soon, at least till July when the rains comes and we have some relief from this weather. Balasaheb Thackeray, Founder Shiv Sena Balasaheb Thakre/Thackeray founded the Shiv Sena in/around 1966. While he was cartoonist by trade, most of his cartoons were anti-migrant in nature. The target was the urban, unemployed Marathi youth based mostly in Mumbai and the suburbs. The Shiv Sena vandalized properties run by South Indian businessman, Gujaratis. The Shiv Sena and Balasaheb Thackeray were also responsible in part due to the massive closure of cloth mills in South Mumbai. While the workers struggled to make ends meet, some whose wife and children died, fell into prostitution, drugs or whatever they could to make ends meet while the party and more important Mr. Balasahab Thackeray prospered. In spite of the many threats, there are and were many South Indians who prospered inspite of Shiv Sena s threats. Gujaratis on the other hand went back to Gujarat and now Surat rivals Mumbai. Another decade or so and Surat and not Mumbai would be the financial capital of India, the way Gujaratis are working towards it. Then in the 90 s people from U.P. and Bihar came in search of livelihood, again the same rhetoric and even attacks were done against people from U.P. and Bihar. The only thing that was missing for all these people is a domicile certificate which you can get only after living 15 years in Mumbai. The only thing that they and other political parties have been successful is murdering journalists. I m sad to report that Maharashtra, my home state has a very bad report card in preventing such murders. And it s both the State and the Centre who have to share the blame equally. Come to 2017 and Shiv Sena doesn t have a leg to stand on. Balasaheb Thackeray is no more, his son didn t inherit Balasaheb s fiery character and the nephew has now another outfit called Maha Navnirman Sena. Also, all those who were one-time outsiders are now residents of Mumbai (with the domicile certificate) and hence registered voters. There is another angle to it as well, Marathas for far too long thought that people they will elect from their community will do something from their community just like auto rickshaw drivers thought that educated unemployed youth from their community would be better than the agents who rip them off whenever they have some work in the local R.T.O. (Road Transport Office) . Similar to auto rickshaw drivers, the Marathas realized that none of the leaders whom they elected would ever do the work. This is why when last year there were huge Maratha rallies all over the state (peaceful demonstrations all around though). I just shared Pune as am most concerned with my city although similar rallies were held in Mumbai (Khargar), Nagpur, Solapur among other places that I know of. But as shown on youtube there was no central leadership (a.k.a. leaders) and still they were the most disciplined lot. While the Marathas may say one thing, in part they are also culprits of their own past. My interactions with few Marathas was that they are still smitten by what happened in the second and the third Anglo-Maratha War . It is sad because I do see them adding lot of value provided they keep a cool head as I have seen some do. Business or service is the game only for cooler heads. Things came to a head though about couple of weeks back when Mr. Ravindra Gaikwad, a Shiv Sena M.P. assaulted some elderly Air India Staff. While things have cooled down since then, it only belittles both the person and the party. If anything, Air India can be accused of being to gentleman like in the whole case. The only crime of its own making is it has been looted since the beginning by Indian MP s and their relatives with over-staffing and old age of the planes and being over-priced in an extremely price sensitive market. It doesn t have any low-cost options but all of that is another story altogether. Converse to this, the current Prime Minister, Mr. Narendra Modi and Malcolm Turnbull enjoyed the ride of the Delhi Metro. In Politics as well as in life, symbolism scores big. That showed where Mr. Modi s priorities lie and where Mr. Gaikwad s. In the end, the writing seems to be on the wall for not just the Shiv Sena but I would say all single-personality based parties. They need to widen both their political scope and activities and have prominent personalities with strong leadership taking the country along rather than being petty-minded.
Filed under: Miscellenous Tagged: #17th century, #Air India, #anti-migrant policy, #Indian Summer, #Maratha, #Maratha History, #Me Maratha, #Me Maratha rallies, #planet-debian

15 April 2017

Gunnar Wolf: On Dmitry Bogatov and empowering privacy-protecting tools

There is a thorny topic we have been discussing in nonpublic channels (say, the debian-private mailing list... It is impossible to call it a private list if it has close to a thousand subscribers, but it sometimes deals with sensitive material) for the last week. We have finally confirmation that we can bring this topic out to the open, and I expect several Debian people to talk about this. Besides, this information is now repeated all over the public Internet, so I'm not revealing anything sensitive. Oh, and there is a statement regarding Dmitry Bogatov published by the Tor project But I'll get to Tor soon. One week ago, the 25-year old mathematician and Debian Maintainer Dmitry Bogatov was arrested, accused of organizing riots and calling for terrorist activities. Every evidence so far points to the fact that Dmitry is not guilty of what he is charged of He was filmed at different places at the times where the calls for terrorism happened. It seems that Dmitry was arrested because he runs a Tor exit node. I don't know the current situation in Russia, nor his political leanings But I do know what a Tor exit node looks like. I even had one at home for a short while. What is Tor? It is a network overlay, meant for people to hide where they come from or who they are. Why? There are many reasons Uninformed people will talk about the evil wrongdoers (starting the list of course with the drug sellers or child porn distributors). People who have taken their time to understand what this is about will rather talk about people for whom free speech is not a given; journalists, political activists, whistleblowers. And also, about regular people Many among us have taken the habit of doing some of our Web surfing using Tor (probably via the very fine and interesting TAILS distribution The Amnesiac Incognito Live System), just to increase the entropy, and just because we can, because we want to preserve the freedom to be anonymous before it's taken away from us. There are many types of nodes in Tor; most of them are just regular users or bridges that forward traffic, helping Tor's anonymization. Exit nodes, where packets leave the Tor network and enter the regular Internet, are much scarcer Partly because they can be quite problematic to people hosting them. But, yes, Tor needs more exit nodes, not just for bandwidth sake, but because the more exit nodes there are, the harder it is for a hostile third party to monitor a sizable number of them for activity (and break the anonymization). I am coincidentially starting a project with a group of students of my Faculty (we want to breathe life again into LIDSOL - Laboratorio de Investigaci n y Desarrollo de Software Libre). As we are just starting, they are documenting some technical and social aspects of the need for privacy and how Tor works; I expect them to publish their findings in El Nigromante soon (which means... what? ), but definitively, part of what we want to do is to set up a Tor exit node at the university Well documented and with enough academic justification to avoid our network operation area ordering us to shut it down. Lets see what happens :) Anyway, all in all Dmitry is in for a heavy time. He has been detained pre-trial at least until June, and he faces quite serious charges. He has done a lot of good, specialized work for the whole world to benefit. So, given I cannot do more, I'm just speaking my mind here in this space. [Update] Dmitry's case has been covered in LWN. There is also a statement concerning the arrest of Dmitry Bogatov by the Debian project. This case is also covered at The Register.

Dirk Eddelbuettel: #5: Easy package information

Welcome to the fifth post in the recklessly rambling R rants series, or R4 for short. The third post showed an easy way to follow R development by monitoring (curated) changes on the NEWS file for the development version r-devel. As a concrete example, I mentioned that it has shown a nice new function (tools::CRAN_package_db()) coming up in R 3.4.0. Today we will build on that. Consider the following short snippet:

library(data.table)
getPkgInfo <- function()  
    if (exists("tools::CRAN_package_db"))  
        dat <- tools::CRAN_package_db()
      else  
        tf <- tempfile()
        download.file("https://cloud.r-project.org/src/contrib/PACKAGES.rds", tf, quiet=TRUE)
        dat <- readRDS(tf)              # r-devel can now readRDS off a URL too
     
    dat <- as.data.frame(dat)
    setDT(dat)
    dat
 
It defines a simple function getPkgInfo() as a wrapper around said new function from R 3.4.0, ie tools::CRAN_package_db(), and a fallback alternative using a tempfile (in the automagically cleaned R temp directory) and an explicit download and read of the underlying RDS file. As an aside, just this week the r-devel NEWS told us that such readRDS() operations can now read directly from URL connection. Very nice---as RDS is a fantastic file format when you are working in R. Anyway, back to the RDS file! The snippet above returns a data.table object with as many rows as there are packages on CRAN, and basically all their (parsed !!) DESCRIPTION info and then some. A gold mine! Consider this to see how many package have a dependency (in the sense of Depends, Imports or LinkingTo, but not Suggests because Suggests != Depends) on Rcpp:
R> dat <- getPkgInfo()
R> rcppRevDepInd <- as.integer(tools::dependsOnPkgs("Rcpp", recursive=FALSE, installed=dat))
R> length(rcppRevDepInd)
[1] 998
R>
So exciting---we will hit 1000 within days! But let's do some more analysis:
R> dat[ rcppRevDepInd, RcppRevDep := TRUE]  # set to TRUE for given set
R> dat[ RcppRevDep==TRUE, 1:2]
           Package Version
  1:      ABCoptim  0.14.0
  2: AbsFilterGSEA     1.5
  3:           acc   1.3.3
  4: accelerometry   2.2.5
  5:      acebayes   1.3.4
 ---                      
994:        yakmoR   0.1.1
995:  yCrypticRNAs  0.99.2
996:         yuima   1.5.9
997:           zic     0.9
998:       ziphsmm   1.0.4
R>
Here we index the reverse dependency using the vector we had just computed, and then that new variable to subset the data.table object. Given the aforementioned parsed information from all the DESCRIPTION files, we can learn more:
R> ## likely false entries
R> dat[ RcppRevDep==TRUE, ][NeedsCompilation!="yes", c(1:2,4)]
            Package Version                                                                         Depends
 1:         baitmet   1.0.0                                                           Rcpp, erah (>= 1.0.5)
 2:           bea.R   1.0.1                                                        R (>= 3.2.1), data.table
 3:            brms   1.6.0                     R (>= 3.2.0), Rcpp (>= 0.12.0), ggplot2 (>= 2.0.0), methods
 4: classifierplots   1.3.3                             R (>= 3.1), ggplot2 (>= 2.2), data.table (>= 1.10),
 5:           ctsem   2.3.1                                           R (>= 3.2.0), OpenMx (>= 2.3.0), Rcpp
 6:        DeLorean   1.2.4                                                  R (>= 3.0.2), Rcpp (>= 0.12.0)
 7:            erah   1.0.5                                                               R (>= 2.10), Rcpp
 8:             GxM     1.1                                                                              NA
 9:             hmi   0.6.3                                                                    R (>= 3.0.0)
10:        humarray     1.1 R (>= 3.2), NCmisc (>= 1.1.4), IRanges (>= 1.22.10),\nGenomicRanges (>= 1.16.4)
11:         iNextPD   0.3.2                                                                    R (>= 3.1.2)
12:          joinXL   1.0.1                                                                    R (>= 3.3.1)
13:            mafs   0.0.2                                                                              NA
14:            mlxR   3.1.0                                                           R (>= 3.0.1), ggplot2
15:    RmixmodCombi     1.0              R(>= 3.0.2), Rmixmod(>= 2.0.1), Rcpp(>= 0.8.0), methods,\ngraphics
16:             rrr   1.0.0                                                                    R (>= 3.2.0)
17:        UncerIn2     2.0                          R (>= 3.0.0), sp, RandomFields, automap, fields, gstat
R> 
There are a full seventeen packages which claim to depend on Rcpp while not having any compiled code of their own. That is likely false---but I keep them in my counts, however relunctantly. A CRAN-declared Depends: is a Depends:, after all. Another nice thing to look at is the total number of package that declare that they need compilation:
R> ## number of packages with compiled code
R> dat[ , .(N=.N), by=NeedsCompilation]
   NeedsCompilation    N
1:               no 7625
2:              yes 2832
3:               No    1
R>
Isn't that awesome? It is 2832 out of (currently) 10458, or about 27.1%. Just over one in four. Now the 998 for Rcpp look even better as they are about 35% of all such packages. In order words, a little over one third of all packages with compiled code (which may be legacy C, Fortran or C++) use Rcpp. Wow. Before closing, one shoutout to Dirk Schumacher whose thankr which I made the center of the last post is now on CRAN. As a mighty fine and slim micropackage without external dependencies. Neat.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

14 April 2017

Laura Arjona Reina: Underestimating Debian

I had two issues in the last days that lead me a bit into panic until they got solved. In both cases the issue was external to Debian but I first thought that the problem was in Debian. I m not sure why I had those thoughts, I should be more confident in myself, this awesome operating system, and the community around it! The good thing is that I ll be more confident from now on, and I ve learned that hurry is not a good friend, and I should face my computer problems (and everything in life, probably) with a bit more patience (and backups). Issue 1: Corrupt ext partition in a laptop I have a laptop at home with dual boot Windows 7 + Debian 9 (Stretch). I rarely boot the Windows partition. When I do, I do whatever I need to do/test there, then install updates, and then shutdown the laptop or reboot in Debian to feel happy again when using computers. Some months ago I noticed that booting in Debian was not possible and I was left in an initramfs console that was suggesting to e2fsck /dev/sda6 (my Debian partition). Then I ran e2fsck, say a to fix all the issues found, and the system was booting properly. This issue was a bit scary-looking because of the e2fsck output making screen show random numbers and scrolling quickly for 1 or 2 minutes, until all the inodes or blocks or whatever were fixed. I thought about the disk being faulty, and ran badblocks, but faced the former boot issue again some time after, and then decided to change the disk (then I took the opportunity to make backups, and install a fresh Debian 9 Stretch in the laptop, instead of the Debian 8 stable that was running). The experience with Stretch has been great since then, but some days ago I faced the boot issue again. Then I realised that maybe the issue was appearing when I booted Debian right after using Windows (and this was why it was appearing not very often in my timeline  ). Then I payed more attention to the message that I was receiving in the console
Superblock checksum does not match superblock while trying to open /dev/sda6
 /dev/sda6:
 The superblock could not be read or does not describe a valid ext2/ext3/ext4
 filesystem. If the device is valid and it really contains an ext2/ext3/ext4
 filesystem (and not swap or ufs or something else), then the superblock
 is corrupt, and you might try running e2fsck with an alternate superblock:
 e2fsck -b 8193
 or
 e2fsck -b 32768
and searched about it, and also asked about it to my friends in the redeslibres XMPP chat room  I found this question in the AskUbuntu forum that was exactly my issue (I had ext2fsd installed in Windows). My friends in the XMPP room friendly yelled booo! at me for letting Windows touch my ext partitions (I apologised, it will never happen again!). I now consistently could reproduce the issue (boot Windows, then boot Debian, bang!: initramfs console, e2fsck, reboot Debian, no problem, boot Windows, boot Debian, again the problem, etc). I uninstalled the ext2fsd program and tried to reproduce the issue, and I couldn t reproduce it. So happy end. Issue 2: Accessing Android internal memory to backup files The other issue was with my tablet running Android 4.0.4. It was facing a charge issue, and I wanted to backup the files there before sending it to repair. I connected the tablet with USB to my laptop, and enabled USB debugging. The laptop recognized a MZ604 camera connected, but Dolphin (the file browser of my KDE Plasma desktop) could not show the files. I looked at the settings in the tablet to try to find the setting that allowed me to switch between camera/MTP when connecting with USB, but couldn t find it. I guessed that the tablet was correctly configured because I recall having made a backup some months ago, with no hassle (in Debian 8). I checked that my Debian (9) had installed the needed packages:
 ii kio-mtp 0.75+git20140304-2 amd64 access to MTP devices for applications using the KDE Platform
 ii libmtp-common 1.1.12-1 all Media Transfer Protocol (MTP) common files
 ii libmtp-runtime 1.1.12-1+b1 amd64 Media Transfer Protocol (MTP) runtime tools
 ii libmtp9:amd64 1.1.12-1+b1 amd64 Media Transfer Protocol (MTP) library
So I had no idea about what was going on. Then I suspected some problem in my Debian (maybe I was needing some driver for the Motorola tablet?) and booted Windows 7 to see what happened there. Windows detected a MZ604 device too, but couldn t access the files either (when clicking in the device, no folders were shown). I began to search the internet to see if there were some Motorola drivers out there, and then found the clue to enable the correct settings in the Android device: you need to go to Settings > Storage, and then press the 3-dots button that makes the Menu function, and then appears USB computer connection and there, you can enable Camera or MTP. Very hidden setting! I enabled MTP, and then I could see the folders and files in my Windows system (without need of installing any additional driver), and make my backup. And of course after rebooting and trying in Debian, it worked too. Some outcomes/conclusions Comments? You can comment on this post using this pump.io thread.
Filed under: My experiences and opinion Tagged: Android, Debian, English, KDE, Libre software for Windows

13 April 2017

Antoine Beaupr : New approaches to network fast paths

With the speed of network hardware now reaching 100 Gbps and distributed denial-of-service (DDoS) attacks going in the Tbps range, Linux kernel developers are scrambling to optimize key network paths in the kernel to keep up. Many efforts are actually geared toward getting traffic out of the costly Linux TCP stack. We have already covered the XDP (eXpress Data Path) patch set, but two new ideas surfaced during the Netconf and Netdev conferences held in Toronto and Montreal in early April 2017. One is a patch set called af_packet, which aims at extracting raw packets from the kernel as fast as possible; the other is the idea of implementing in-kernel layer-7 proxying. There are also user-space network stacks like Netmap, DPDK, or Snabb (which we previously covered). This article aims at clarifying what all those components do and to provide a short status update for the tools we have already covered. We will focus on in-kernel solutions for now. Indeed, user-space tools have a fundamental limitation: if they need to re-inject packets onto the network, they must again pay the expensive cost of crossing the kernel barrier. User-space performance is effectively bounded by that fundamental design. So we'll focus on kernel solutions here. We will start from the lowest part of the stack, the af_packet patch set, and work our way up the stack all the way up to layer-7 and in-kernel proxying.

af_packet v4 John Fastabend presented a new version of a patch set that was first published in January regarding the af_packet protocol family, which is currently used by tcpdump to extract packets from network interfaces. The goal of this change is to allow zero-copy transfers between user-space applications and the NIC (network interface card) transmit and receive ring buffers. Such optimizations are useful for telecommunications companies, which may use it for deep packet inspection or running exotic protocols in user space. Another use case is running a high-performance intrusion detection system that needs to watch large traffic streams in realtime to catch certain types of attacks. Fastabend presented his work during the Netdev network-performance workshop, but also brought the patch set up for discussion during Netconf. There, he said he could achieve line-rate extraction (and injection) of packets, with packet rates as high as 30Mpps. This performance gain is possible because user-space pages are directly DMA-mapped to the NIC, which is also a security concern. The other downside of this approach is that a complete pair of ring buffers needs to be dedicated for this purpose; whereas before packets were copied to user space, now they are memory-mapped, so the user-space side needs to process those packets quickly otherwise they are simply dropped. Furthermore, it's an "all or nothing" approach; while NIC-level classifiers could be used to steer part of the traffic to a specific queue, once traffic hits that queue, it is only accessible through the af_packet interface and not the rest of the regular stack. If done correctly, however, this could actually improve the way user-space stacks access those packets, providing projects like DPDK a safer way to share pages with the NIC, because it is well defined and kernel-controlled. According to Jesper Dangaard Brouer (during review of this article):
This proposal will be a safer way to share raw packet data between user space and kernel space than what DPDK is doing, [by providing] a cleaner separation as we keep driver code in the kernel where it belongs.
During the Netdev network-performance workshop, Fastabend asked if there was a better data structure to use for such a purpose. The goal here is to provide a consistent interface to user space regardless of the driver or hardware used to extract packets from the wire. af_packet currently defines its own packet format that abstracts away the NIC-specific details, but there are other possible formats. For example, someone in the audience proposed the virtio packet format. Alexei Starovoitov rejected this idea because af_packet is a kernel-specific facility while virtio has its own separate specification with its own requirements. The next step for af_packet is the posting of the new "v4" patch set, although Miller warned that this wouldn't get merged until proper XDP support lands in the Intel drivers. The concern, of course, is that the kernel would have multiple incomplete bypass solutions available at once. Hopefully, Fastabend will present the (by then) merged patch set at the next Netdev conference in November.

XDP updates Higher up in the networking stack sits XDP. The af_packet feature differs from XDP in that it does not perform any sort of analysis or mangling of packets; its objective is purely to get the data into and out of the kernel as fast as possible, completely bypassing the regular kernel networking stack. XDP also sits before the networking stack except that, according to Brouer, it is "focused on cooperating with the existing network stack infrastructure, and on use-cases where the packet doesn't necessarily need to leave kernel space (like routing and bridging, or skipping complex code-paths)." XDP has evolved quite a bit since we last covered it in LWN. It seems that most of the controversy surrounding the introduction of XDP in the Linux kernel has died down in public discussions, under the leadership of David Miller, who heralded XDP as the right solution for a long-term architecture in the kernel. He presented XDP as a fast, flexible, and safe solution. Indeed, one of the controversies surrounding XDP was the question of the inherent security challenges with introducing user-provided programs directly into the Linux kernel to mangle packets at such a low level. Miller argued that whatever protections are expected for user-space programs also apply to XDP programs, comparing the virtual memory protections to the eBPF (extended BPF) verifier applied to XDP programs. Those programs are actually eBPF that have an interesting set of restrictions:
  • they have a limited size
  • they cannot jump backward (and thus cannot loop), so they execute in predictable time
  • they do only static allocation, so they are also limited in memory
XDP is not a one-size-fits-all solution: netfilter, the TC traffic shaper, and other normal Linux utilities still have their place. There is, however, a clear use case for a solution like XDP in the kernel. For example, Facebook and Cloudflare have both started testing XDP and, in Facebook's case, deploying XDP in production. Martin Kafai Lau, from Facebook, presented the tool set the company is using to construct a DDoS-resilience solution and a level-4 load balancer (L4LB), which got a ten-times performance improvement over the previous IPVS-based solution. Facebook rolled out its own user-space solution called "Droplet" to detect hostile traffic and deploy blocking rules in the form of eBPF programs loaded in XDP. Lau demonstrated the way Facebook deploys a three-part chained eBPF program: the first part allows debugging and dumping of packets, the second is Droplet itself, which drops undesirable traffic, and the last segment is the load balancer, which mangles the packets to tweak their destination according to internal rules. Droplet can drop DDoS attacks at line rate while keeping the architecture flexible, which were two key design requirements. Gilberto Bertin, from Cloudflare, presented a similar approach: Cloudflare has a tool that processes sFlow data generated from iptables in order to generate cBPF (classic BPF) mitigation rules that are then deployed on edge routers. Those rules are created with a tool called bpfgen, part of Cloudflare's BSD-licensed bpftools suite. For example, it could create a cBPF bytecode blob that would match DNS queries to any example.com domain with something like:
    bpfgen dns *.example.com
Originally, Cloudflare would deploy those rules to plain iptables firewalls with the xt_bpf module, but this led to performance issues. It then deployed a proprietary user-space solution based on Solarflare hardware, but this has the performance limitations of user-space applications getting packets back onto the wire involves the cost of re-injecting packets back into the kernel. This is why Cloudflare is experimenting with XDP, which was partly developed in response to the company's problems, to deploy those BPF programs. A concern that Bertin identified was the lack of visibility into dropped packets. Cloudflare currently samples some of the dropped traffic to analyze attacks; this is not currently possible with XDP unless you pass the packets down the stack, which is expensive. Miller agreed that the lack of monitoring for XDP programs is a large issue that needs to be resolved, and suggested creating a way to mark packets for extraction to allow analysis. Cloudflare is currently in a testing phase with XDP and it is unclear if its whole XDP tool chain will be publicly available. While those two companies are starting to use XDP as-is, there is more work needed to complete the XDP project. As mentioned above and in our previous coverage, massive statistics extraction is still limited in the Linux kernel and introspection is difficult. Furthermore, while the existing actions (XDP_DROP and XDP_TX, see the documentation for more information) are well implemented and used, another action may be introduced, called XDP_REDIRECT, which would allow redirecting packets to different network interfaces. Such an action could also be used to accelerate bridges as packets could be "switched" based on the MAC address table. XDP also requires network driver support, which is currently limited. For example, the Intel drivers still do not support XDP, although that should come pretty soon. Miller, in his Netdev keynote, focused on XDP and presented it as the standard solution that is safe, fast, and usable. He identified the next steps of XDP development to be the addition of debugging mechanisms, better sampling tools for statistics and analysis, and user-space consistency. Miller foresees a future for XDP similar to the popularization of the Arduino chips: a simple set of tools that anyone, not just developers, can use. He gave the example of an Arduino tutorial that he followed where he could just look up a part number and get easy-to-use instructions on how to program it. Similar components should be available for XDP. For this purpose, the conference saw the creation of a new mailing list called xdp-newbies where people can learn how to create XDP build environments and how to write XDP programs.

In-kernel layer-7 proxying The third approach that struck me as innovative is the idea of doing layer-7 (application) proxying directly in the kernel. This comes from the idea that, traditionally, we build firewalls to segregate traffic and apply controls, but as most services move to HTTP, those policies become ineffective. Thomas Graf, presented this idea during Netconf using a Star Wars allegory: what if the Death Star were a server with an API? You would have endpoints like /dock or /comms that would allow you to dock a ship or communicate with the Death Star. Those API endpoints should obviously be public, but then there is this /exhaust-port endpoint that should never be publicly available. In order for a firewall to protect such a system, it must be able to inspect traffic at a higher level than the traditional address-port pairs. Graf presented a design where the kernel would create an in-kernel socket that would negotiate TCP connections on behalf of user space and then be able to apply arbitrary eBPF rules in the kernel. Graf's design of in-kernel proxying In this scenario, instead of doing the traditional transfer from Netfilter's TPROXY to user space, the kernel directly decapsulates the HTTP traffic and passes it to BPF rules that can make decisions without doing expensive context switches or memory copies in the case of simply wanting to refuse traffic (e.g. issue an HTTP 403 error). This, of course, requires the inclusion of kTLS to process HTTPS connections. HTTP2 support may also prove problematic, as it multiplexes connections and is harder to decapsulate. This design was described as a "pure pre-accept() hook". Starovoitov also compared the design to the kernel connection multiplexer (KCM). Tom Herbert, KCM's author, agreed that it could be extended to support this, but would require some extensions in user space to provide an interface between regular socket-based applications and the KCM layer. In any case, if the application does TLS (and lots of them do), kTLS gets tricky because it breaks the end-to-end nature of TLS, in effect becoming a man in the middle between the client and the application. Eric Dumazet argued that HA-Proxy already does things like this: it uses splice() to avoid copying too much data around, but it still does a context switch to hand over processing to user space, something that could be fixed in the general case. Another similar project that was presented at Netdev is the Tempesta firewall and reverse-proxy. The speaker, Alex Krizhanovsky, explained the Tempesta developers have taken one person month to port the mbed TLS stack to the Linux kernel to allow an in-kernel TLS handshake. Tempesta also implements rate limiting, cookies, and JavaScript challenges to mitigate DDoS attacks. The argument behind the project is that "it's easier to move TLS to the kernel than it is to move the TCP/IP stack to user space". Graf explained that he is familiar with Krizhanovsky's work and he is hoping to collaborate. In effect, the design Graf is working on would serve as a foundation for Krizhanovsky's in-kernel HTTP server (kHTTP). In a private email, Graf explained that:
The main differences in the implementation are currently that we foresee to use BPF for protocol parsing to avoid having to implement every single application protocol natively in the kernel. Tempesta likely sees this less of an issue as they are probably only targeting HTTP/1.1 and HTTP/2 and to some [extent] JavaScript.
Neither project is really ready for production yet. There didn't seem to be any significant pushback from key network developers against the idea, which surprised some people, so it is likely we will see more and more layer-7 intelligence move into the kernel sooner rather than later.

Conclusion All of this work aims at replacing a rag-tag bunch of proprietary solutions that recently came up to bypass the Linux kernel TCP/IP stack and improve performance for firewalls, proxies, and other key edge network elements. The idea is that, unless the kernel improves its performance, or at least provides a way to bypass its more complex code paths, people will work around it. With this set of solutions in place, engineers will now be able to use standard APIs to hook high-performance systems into the Linux kernel.
The author would like to thank the Netdev and Netconf organizers for travel assistance, Thomas Graf for a review of the in-kernel proxying section of this article, and Jesper Dangaard Brouer for review of the af_packet and XDP sections. Note: this article first appeared in the Linux Weekly News.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, March 2017

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In March, about 190 work hours have been dispatched among 14 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours has been unchanged but will likely decrease slightly next month as one sponsor will not renew his support (because they have switched to CentOS). The security tracker currently lists 52 packages with a known CVE and the dla-needed.txt file 40. The number of open issues continued its slight increase not worrisome yet but we need to keep an eye on this situation. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Francois Marier: Automatically renewing Let's Encrypt TLS certificates on Debian using Certbot

I use Let's Encrypt TLS certificates on my Debian servers along with the Certbot tool. Since I use the "temporary webserver" method of proving domain ownership via the ACME protocol, I cannot use the cert renewal cronjob built into Certbot. Instead, this is the script I put in /etc/cron.daily/certbot-renew:
#!/bin/bash
/usr/bin/certbot renew --quiet --pre-hook "/bin/systemctl stop apache2.service" --post-hook "/bin/systemctl start apache2.service"
pushd /etc/ > /dev/null
/usr/bin/git add letsencrypt
DIFFSTAT="$(/usr/bin/git diff --cached --stat)"
if [ -n "$DIFFSTAT" ] ; then
    /usr/bin/git commit --quiet -m "Renewed letsencrypt certs"
    echo "$DIFFSTAT"
fi
popd > /dev/null
It temporarily disables my Apache webserver while it renews the certificates and then only outputs something to STDOUT (since my cronjob will email me any output) if certs have been renewed. Since I'm using etckeeper to keep track of config changes on my servers, my renewal script also commits to the repository if any certs have changed.

External Monitoring In order to catch mistakes or oversights, I use ssl-cert-check to monitor my domains once a day:
ssl-cert-check -s fmarier.org -p 443 -q -a -e francois@fmarier.org
I also signed up with Cert Spotter which watches the Certificate Transparency log and notifies me of any newly-issued certificates for my domains. In other words, I get notified:
  • if my cronjob fails and a cert is about to expire, or
  • as soon as a new cert is issued.
The whole thing seems to work well, but if there's anything I could be doing better, feel free to leave a comment!

12 April 2017

Vincent Bernat: Proper isolation of a Linux bridge

TL;DR: when configuring a Linux bridge, use the following commands to enforce isolation:
# bridge vlan del dev br0 vid 1 self
# echo 1 > /sys/class/net/br0/bridge/vlan_filtering

A network bridge (also commonly called a switch ) brings several Ethernet segments together. It is a common element in most infrastructures. Linux provides its own implementation. A typical use of a Linux bridge is shown below. The hypervisor is running three virtual hosts. Each virtual host is attached to the br0 bridge (represented by the horizontal segment). The hypervisor has two physical network interfaces: Typical use of Linux bridging with virtual machines The main expectation of such a setup is that while the virtual hosts should be able to use resources from the public network, they should not be able to access resources from the infrastructure network (including resources hosted on the hypervisor itself, like a SSH server). In other words, we expect a total isolation between the green domain and the purple one. That s not the case. From any virtual host:
# ip route add 192.168.14.3/32 dev eth0
# ping -c 3 192.168.14.3
PING 192.168.14.3 (192.168.14.3) 56(84) bytes of data.
64 bytes from 192.168.14.3: icmp_seq=1 ttl=59 time=0.644 ms
64 bytes from 192.168.14.3: icmp_seq=2 ttl=59 time=0.829 ms
64 bytes from 192.168.14.3: icmp_seq=3 ttl=59 time=0.894 ms
--- 192.168.14.3 ping statistics ---
3 packets transmitted, 3 received, 0% packet loss, time 2033ms
rtt min/avg/max/mdev = 0.644/0.789/0.894/0.105 ms

Why? There are two main factors of this behavior:
  1. A bridge can accept IP traffic. This is a useful feature if you want Linux to act as a bridge and provide some IP services to bridge users (a DHCP relay or a default gateway). This is usually done by configuring the IP address on the bridge device: ip addr add 192.0.2.2/25 dev br0.
  2. An interface doesn t need an IP address to process incoming IP traffic. Additionally, by default, Linux accepts to answer ARP requests independently from the incoming interface.

Bridge processing After turning an incoming Ethernet frame into a socket buffer, the network driver transfers the buffer to the netif_receive_skb() function. The following actions are executed:
  1. copy the frame to any registered global or per-device taps (e.g. tcpdump),
  2. evaluate the ingress policy (configured with tc),
  3. hand over the frame to the device-specific receive handler, if any,
  4. hand over the frame to a global or device-specific protocol handler (e.g. IPv4, ARP, IPv6).
For a bridged interface, the kernel has configured a device-specific receive handler, br_handle_frame(). This function won t allow any additional processing in the context of the incoming interface, except for STP and LLDP frames or if brouting is enabled1. Therefore, the protocol handlers are never executed in this case. After a few additional checks, Linux will decide if the frame has to be locally delivered:
  • the entry for the target MAC in the FDB is marked for local delivery, or
  • the target MAC is a broadcast or a multicast address.
In this case, the frame is passed to the br_pass_frame_up() function. A VLAN-related check is optionally performed. The socket buffer is attached to the bridge interface (br0) instead of the physical interface (eth0), is evaluated by Netfilter and sent back to netif_receive_skb(). It will go through the four steps a second time.

IPv4 processing When a device doesn t have a protocol-independent receive handler, a protocol-specific handler will be used:
# cat /proc/net/ptype
Type Device      Function
0800          ip_rcv
0011          llc_rcv [llc]
0004          llc_rcv [llc]
0806          arp_rcv
86dd          ipv6_rcv
Therefore, if the Ethernet type of the incoming frame is 0x800, the socket buffer is handled by ip_rcv(). Among other things, the three following steps will happen:
  • If the frame destination address is not the MAC address of the incoming interface, not a multicast one and not a broadcast one, the frame is dropped ( not for us ).
  • Netfilter gets a chance to evaluate the packet (in a PREROUTING chain).
  • The routing subsystem will decide the destination of the packet in ip_route_input_slow(): is it a local packet, should it be forwarded, should it be dropped, should it be encapsulated? Notably, the reverse-path filtering is done during this evaluation in fib_validate_source().
Reverse-path filtering (also known as uRPF, or unicast reverse-path forwarding, RFC 3704) enables Linux to reject traffic on interfaces which it should never have originated: the source address is looked up in the routing tables and if the outgoing interface is different from the current incoming one, the packet is rejected.

ARP processing When the Ethernet type of the incoming frame is 0x806, the socket buffer is handled by arp_rcv().
  • Like for IPv4, if the frame is not for us, it is dropped.
  • If the incoming device has the NOARP flag, the frame is dropped.
  • Netfilter gets a chance to evaluate the packet (configuration is done with arptables).
  • For an ARP request, the values of arp_ignore and arp_filter may trigger a drop of the packet.

IPv6 processing When the Ethernet type of the incoming frame is 0x86dd, the socket buffer is handled by ipv6_rcv().
  • Like for IPv4, if the frame is not for us, it is dropped.
  • If IPv6 is disabled on the interface, the packet is dropped.
  • Netfilter gets a chance to evaluate the packet (in a PREROUTING chain).
  • The routing subsystem will decide the destination of the packet. However, unlike IPv4, there is no reverse-path filtering2.

Workarounds There are various methods to fix the situation. We can completely ignore the bridged interfaces: as long as they are attached to the bridge, they cannot process any upper layer protocol (IPv4, IPv6, ARP). Therefore, we can focus on filtering incoming traffic from br0. It should be noted that for IPv4, IPv6 and ARP protocols, the MAC address check can be circumvented by using the broadcast MAC address.

Protocol-independent workarounds The four following fixes will indistinctly drop IPv4, ARP and IPv6 packets.

Using VLAN-aware bridge Linux 3.9 introduced the ability to use VLAN filtering on bridge ports. This can be used to prevent any local traffic:
# echo 1 > /sys/class/net/br0/bridge/vlan_filtering
# bridge vlan del dev br0 vid 1 self
# bridge vlan show
port    vlan ids
eth0     1 PVID Egress Untagged
eth2     1 PVID Egress Untagged
eth3     1 PVID Egress Untagged
eth4     1 PVID Egress Untagged
br0     None
This is the most efficient method since the frame is dropped directly in br_pass_frame_up().

Using ingress policy It s also possible to drop the bridged frame early after it has been re-delivered to netif_receive_skb() by br_pass_frame_up(). The ingress policy of an interface is evaluated before any handler. Therefore, the following commands will ensure no local delivery (the source interface of the packet is the bridge interface) happens:
# tc qdisc add dev br0 handle ffff: ingress
# tc filter add dev br0 parent ffff: u32 match u8 0 0 action drop
In my opinion, this is the second most efficient method.

Using ebtables Just before re-delivering the frame to netif_receive_skb(), Netfilter gets a chance to issue a decision. It s easy to configure it to drop the frame:
# ebtables -A INPUT --logical-in br0 -j DROP
However, to the best of my knowledge, this part of Netfilter is known to be inefficient.

Using namespaces Isolation can also be obtained by moving all the bridged interfaces into a dedicated network namespace and configure the bridge inside this namespace:
# ip netns add bridge0
# ip link set netns bridge0 eth0
# ip link set netns bridge0 eth2
# ip link set netns bridge0 eth3
# ip link set netns bridge0 eth4
# ip link del dev br0
# ip netns exec bridge0 brctl addbr br0
# for i in 0 2 3 4; do
>    ip netns exec bridge0 brctl addif br0 eth$i
>    ip netns exec bridge0 ip link set up dev eth$i
> done
# ip netns exec bridge0 ip link set up dev br0
The frame will still wander a bit inside the IP stack, wasting some CPU cycles and increasing the possible attack surface. But ultimately, it will be dropped.

Protocol-dependent workarounds Unless you require multiple layers of security, if one of the previous workarounds is already applied, there is no need to apply one of the protocol-dependent fix below. It s still interesting to know them because it is not uncommon to already have them in place.

ARP The easiest way to disable ARP processing on a bridge is to set the NOARP flag on the device. The ARP packet will be dropped as the very first step of the ARP handler.
# ip link set arp off dev br0
# ip l l dev br0
8: br0: <BROADCAST,MULTICAST,NOARP,UP,LOWER_UP> mtu 1500 qdisc noqueue state UP mode DEFAULT group default qlen 1000
    link/ether 50:54:33:00:00:04 brd ff:ff:ff:ff:ff:ff
arptables can also drop the packet quite early:
# arptables -A INPUT -i br0 -j DROP
Another way is to set arp_ignore to 2 for the given interface. The kernel will only answer to ARP requests whose target IP address is configured on the incoming interface. Since the bridge interface doesn t have any IP address, no ARP requests will be answered.
# sysctl -qw net.ipv4.conf.br0.arp_ignore=2
Disabling ARP processing is not a sufficient workaround for IPv4. A user can still insert the appropriate entry in its neighbor cache:
# ip neigh replace 192.168.14.3 lladdr 50:54:33:00:00:04 dev eth0
# ping -c 1 192.168.14.3
PING 192.168.14.3 (192.168.14.3) 56(84) bytes of data.
64 bytes from 192.168.14.3: icmp_seq=1 ttl=49 time=1.30 ms
--- 192.168.14.3 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 1.309/1.309/1.309/0.000 ms
As the check on the target MAC address is quite loose, they don t even need to guess the MAC address:
# ip neigh replace 192.168.14.3 lladdr ff:ff:ff:ff:ff:ff dev eth0
# ping -c 1 192.168.14.3
PING 192.168.14.3 (192.168.14.3) 56(84) bytes of data.
64 bytes from 192.168.14.3: icmp_seq=1 ttl=49 time=1.12 ms
--- 192.168.14.3 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 1.129/1.129/1.129/0.000 ms

IPv4 The earliest place to drop an IPv4 packet is with Netfilter3:
# iptables -t raw -I PREROUTING -i br0 -j DROP
If Netfilter is disabled, another possibility is to enable strict reverse-path filtering for the interface. In this case, since there is no IP address configured on the interface, the packet will be dropped during the route lookup:
# sysctl -qw net.ipv4.conf.br0.rp_filter=1
Another option is the use of a dedicated routing rule. Compared to the reverse-path filtering option, the packet will be dropped a bit earlier, still during the route lookup.
# ip rule add iif br0 blackhole

IPv6 Linux provides a way to completely disable IPv6 on a given interface. The packet will be dropped as the very first step of the IPv6 handler:
# sysctl -qw net.ipv6.conf.br0.disable_ipv6=1
Like for IPv4, it s possible to use Netfilter or a dedicated routing rule.

About the example In the above example, the virtual host get ICMP replies because they are routed through the infrastructure network to Internet (e.g. the hypervisor has a default gateway which also acts as a NAT router to Internet). This may not be the case. If you want to check if you are vulnerable despite not getting an ICMP reply, look at the guest neighbor table to check if you got an ARP reply from the host:
# ip route add 192.168.14.3/32 dev eth0
# ip neigh show dev eth0
192.168.14.3 lladdr 50:54:33:00:00:04 REACHABLE
If you didn t get a reply, you could still have issues with IP processing. Add a static neighbor entry before checking the next step:
# ip neigh replace 192.168.14.3 lladdr ff:ff:ff:ff:ff:ff dev eth0
To check if IP processing is enabled, check the bridge host s network statistics:
# netstat -s   grep "ICMP messages"
    15 ICMP messages received
    15 ICMP messages sent
    0 ICMP messages failed
If the counters are increasing, it is processing incoming IP packets. One-way communication still allows a lot of bad things, like DoS attacks. Additionally, if the hypervisor happens to also act as a router, the reach is extended to the whole infrastructure network, potentially exposing weak devices (e.g. PDU) exposing an SNMP agent. If one-way communication is all that s needed, the attacker can also spoof its source IP address, bypassing IP-based authentication.

  1. A frame can be forcibly routed (L3) instead of bridged (L2) by brouting the packet. This action can be triggered using ebtables.
  2. For IPv6, reverse-path filtering needs to be implemented with Netfilter, using the rpfilter match.
  3. If the br_netfilter module is loaded, net.bridge.bridge-nf-call-ipatbles sysctl has to be set to 0. Otherwise, you also need to use the physdev match to not drop IPv4 packets going through the bridge.

Daniel Pocock: What is the risk of using proprietary software for people who prefer not to?

Jonas berg has recently blogged about Using Proprietary Software for Freedom. He argues that it can be acceptable to use proprietary software to further free and open source software ambitions if that is indeed the purpose. Jonas' blog suggests that each time proprietary software is used, the relative risk and reward should be considered and there may be situations where the reward is big enough and the risk low enough that proprietary software can be used. A question of leadership Many of the free software users and developers I've spoken to express frustration about how difficult it is to communicate to their family and friends about the risks of proprietary software. A typical example is explaining to family members why you would never install Skype. Imagine a doctor who gives a talk to school children about the dangers of smoking and is then spotted having a fag at the bus stop. After a month, if you ask the children what they remember about that doctor, is it more likely to be what he said or what he did? When contemplating Jonas' words, it is important to consider this leadership factor as a significant risk every time proprietary software or services are used. Getting busted with just one piece of proprietary software undermines your own credibility and posture now and well into the future. Research has shown that when communicating with people, what they see and how you communicate is ninety three percent of the impression you make. What you actually say to them is only seven percent. When giving a talk at a conference or a demo to a client, or communicating with family members in our everyday lives, using a proprietary application or a product or service that is obviously proprietary like an iPhone or Facebook will have far more impact than the words you say. It is not only a question of what you are seen doing in public: somebody who lives happily and comfortably without using proprietary software sounds a lot more credible than somebody who tries to explain freedom without living it. The many faces of proprietary software One of the first things to consider is that even for those developers who have a completely free operating system, there may well be some proprietary code lurking in their BIOS or other parts of their hardware. Their mobile phone, their car, their oven and even their alarm clock are all likely to contain some proprietary code too. The risks associated with these technologies may well be quite minimal, at least until that alarm clock becomes part of the Internet of Things and can be hacked by the bored teenager next door. Accessing most web sites these days inevitably involves some interaction with proprietary software, even if it is not running on your own computer. There is no need to give up Some people may consider this state of affairs and simply give up, using whatever appears to be the easiest solution for each problem at hand without thinking too much about whether it is proprietary or not. I don't think Jonas' blog intended to sanction this level of complacency. Every time you come across a piece of software, it is worth considering whether a free alternative exists and whether the software is really needed at all. An orderly migration to free software In our professional context, most software developers come across proprietary software every day in the networks operated by our employers and their clients. Sometimes we have the opportunity to influence the future of these systems. There are many cases where telling the client to go cold-turkey on their proprietary software would simply lead to the client choosing to get advice from somebody else. The free software engineer who looks at the situation strategically may find that it is possible to continue using the proprietary software as part of a staged migration, gradually helping the user to reduce their exposure over a period of months or even a few years. This may be one of the scenarios where Jonas is sanctioning the use of proprietary software. On a technical level, it may be possible to show the client that we are concerned about the dangers but that we also want to ensure the continuity of their business. We may propose a solution that involves sandboxing the proprietary software in a virtual machine or a DMZ to prevent it from compromising other systems or "calling home" to the vendor. As well as technical concerns about a sudden migration, promoters of free software frequently encounter political issues as well. For example, the IT manager in a company may be five years from retirement and is not concerned about his employer's long term ability to extricate itself from a web of Microsoft licenses after he or she has the freedom to go fishing every day. The free software professional may need to invest significant time winning the trust of senior management before he is able to work around a belligerant IT manager like this. No deal is better than a bad deal People in the UK have probably encountered the expression "No deal is better than a bad deal" many times already in the last few weeks. Please excuse me for borrowing it. If there is no free software alternative to a particular piece of proprietary software, maybe it is better to simply do without it. Facebook is a great example of this principle: life without social media is great and rather than trying to find or create a free alternative, why not just do something in the real world, like riding motorcycles, reading books or getting a cat or dog? Burning bridges behind you For those who are keen to be the visionaries and leaders in a world where free software is the dominant paradigm, would you really feel satisfied if you got there on the back of proprietary solutions? Or are you concerned that taking such shortcuts is only going to put that vision further out of reach? Each time you solve a problem with free software, whether it is small or large, in your personal life or in your business, the process you went through strengthens you to solve bigger problems the same way. Each time you solve a problem using a proprietary solution, not only do you miss out on that process of discovery but you also risk conditioning yourself to be dependent in future. For those who hope to build a successful startup company or be part of one, how would you feel if you reach your goal and then the rug is pulled out underneath you when a proprietary software vendor or cloud service you depend on changes the rules? Personally, in my own life, I prefer to avoid and weed out proprietary solutions wherever I can and force myself to either make free solutions work or do without them. Using proprietary software and services is living your life like a rat in a maze, where the oligarchs in Silicon Valley can move the walls around as they see fit.

11 April 2017

Matthew Garrett: Disabling SSL validation in binary apps

Reverse engineering protocols is a great deal easier when they're not encrypted. Thankfully most apps I've dealt with have been doing something convenient like using AES with a key embedded in the app, but others use remote protocols over HTTPS and that makes things much less straightforward. MITMProxy will solve this, as long as you're able to get the app to trust its certificate, but if there's a built-in pinned certificate that's going to be a pain. So, given an app written in C running on an embedded device, and without an easy way to inject new certificates into that device, what do you do?

First: The app is probably using libcurl, because it's free, works and is under a license that allows you to link it into proprietary apps. This is also bad news, because libcurl defaults to having sensible security settings. In the worst case we've got a statically linked binary with all the symbols stripped out, so we're left with the problem of (a) finding the relevant code and (b) replacing it with modified code. Fortuntely, this is much less difficult than you might imagine.

First, let's find where curl sets up its defaults. Curl_init_userdefined() in curl/lib/url.c has the following code:
set->ssl.primary.verifypeer = TRUE;
set->ssl.primary.verifyhost = TRUE;
#ifdef USE_TLS_SRP
set->ssl.authtype = CURL_TLSAUTH_NONE;
#endif
set->ssh_auth_types = CURLSSH_AUTH_DEFAULT; /* defaults to any auth
type */
set->general_ssl.sessionid = TRUE; /* session ID caching enabled by
default */
set->proxy_ssl = set->ssl;

set->new_file_perms = 0644; /* Default permissions */
set->new_directory_perms = 0755; /* Default permissions */

TRUE is defined as 1, so we want to change the code that currently sets verifypeer and verifyhost to 1 to instead set them to 0. How to find it? Look further down - new_file_perms is set to 0644 and new_directory_perms is set to 0755. The leading 0 indicates octal, so these correspond to decimal 420 and 493. Passing the file to objdump -d (assuming a build of objdump that supports this architecture) will give us a disassembled version of the code, so time to fix our problems with grep:
objdump -d target grep --after=20 ,420 grep ,493

This gives us the disassembly of target, searches for any occurrence of ",420" (indicating that 420 is being used as an argument in an instruction), prints the following 20 lines and then searches for a reference to 493. It spits out a single hit:
43e864: 240301ed li v1,493
Which is promising. Looking at the surrounding code gives:
43e820: 24030001 li v1,1
43e824: a0430138 sb v1,312(v0)
43e828: 8fc20018 lw v0,24(s8)
43e82c: 24030001 li v1,1
43e830: a0430139 sb v1,313(v0)
43e834: 8fc20018 lw v0,24(s8)
43e838: ac400170 sw zero,368(v0)
43e83c: 8fc20018 lw v0,24(s8)
43e840: 2403ffff li v1,-1
43e844: ac4301dc sw v1,476(v0)
43e848: 8fc20018 lw v0,24(s8)
43e84c: 24030001 li v1,1
43e850: a0430164 sb v1,356(v0)
43e854: 8fc20018 lw v0,24(s8)
43e858: 240301a4 li v1,420
43e85c: ac4301e4 sw v1,484(v0)
43e860: 8fc20018 lw v0,24(s8)
43e864: 240301ed li v1,493
43e868: ac4301e8 sw v1,488(v0)

Towards the end we can see 493 being loaded into v1, and v1 then being copied into an offset from v0. This looks like a structure member being set to 493, which is what we expected. Above that we see the same thing being done to 420. Further up we have some more stuff being set, including a -1 - that corresponds to CURLSSH_AUTH_DEFAULT, so we seem to be in the right place. There's a zero above that, which corresponds to CURL_TLSAUTH_NONE. That means that the two 1 operations above the -1 are the code we want, and simply changing 43e820 and 43e82c to 24030000 instead of 24030001 means that our targets will be set to 0 (ie, FALSE) rather than 1 (ie, TRUE). Copy the modified binary back to the device, run it and now it happily talks to MITMProxy. Huge success.

(If the app calls Curl_setopt() to reconfigure the state of these values, you'll need to stub those out as well - thankfully, recent versions of curl include a convenient string "CURLOPT_SSL_VERIFYHOST no longer supports 1 as value!" in this function, so if the code in question is using semi-recent curl it's easy to find. Then it's just a matter of looking for the constants that CURLOPT_SSL_VERIFYHOST and CURLOPT_SSL_VERIFYPEER are set to, following the jumps and hacking the code to always set them to 0 regardless of the argument)

comment count unavailable comments

Next.

Previous.