Search Results: "reg"

9 November 2014

Charles Plessy: Did we need a general resolution?

In 2009 I called for a general resolution regarding membership procedures in Debian, to block a change that, in my opinion, was going against our values. Results, even if they satisfied the majority came with a bitter feeling and it became questioned whether a better solution could have been reached without using a constraining procedure. I did not think so, but not to the point of not having doubts about it, and therefore, regrets. This year, we are again having a vote related to a change that some people think it goes against our values, and again the existence of this vote makes it hard to find compromises. Bitterness will win whatever the result is. For the avoidance of doubt, I have proposed the amendment number 3, stating that this general resolution should not have been started. I hope that this amendment will defeat the original proposition and will make people think twice before pressing Debian's alarm button next time. PS: amendment 3, that is amendment C, that is choice 4. If there was a need for an example that the procedure is complex, here it is...

8 November 2014

Ingo Juergensmann: Bind9 vs. PowerDNS - part 2

AttachmentSize
dnssec.sh.txt3.55 KB
Two weeks ago I wrote about implementing DNSSEC with Bind9 or PowerDNS and asked for opinions, because Bind9 appeared to me to be too complex to set it up with regular key signing and such and PowerDNS seemed to me to be nice and easy, but some kind of black box where I don't now what's happening. I think I've now found the best and most suitable way for me to deal with DNSSEC. Or in short words: Bind9 won! It won because of its inline-signing config option that you can use in bind9.9, which happens to be in backports. Another tip I can give due to my findings on the web: if you plan to implement DNSSEC with Bind9, do NOT! search for "bind dnssec" on the web. This will only bring up old HowTos and manuals which leaves you with the burden of manually update your keys. Just add the magic word "inline-signing" to your search phrase and you'll find proper results like the one from Michael McNally on a subpage of ISC.org: In-line Signing With NSEC3 in BIND 9.9+ -- A Walk-through. It's a fairly good starting point, but still left me with several manual steps to do to get a DNSSEC-signed zone. I'm quite a lazy guy when it comes down to manual steps that needs to get executed repeatedly, as many others in IT as well, I think. So I wrote some sort of small wrapper script to do the necessary steps of creating the keys, adding the necessary config options to your named.conf.local, enabling nsec3params, add the DS records to your zone file and displaying the DNSKEY to you, so that you just need to upload it to your registrar. One problem was still open: when doing auto-signing/inline-signing with bind9, you are left with your plain text zone file whereas your signed zone file will keep to increase the serial with each key rollover. When changing your plain text zone file by adding, changing or removing RRs of that domain, you'll be left with the manual task of finding out was your actual serial is that is currently used, because it's not your serial +1 from your plain text zone file anymore. This is of course an awkward part I wanted to get rid off. And therefor my script includes an option to edit zone files with your favorite editor, increase the serial automatically by determing the currently highest number, either on disk or in DNS and raising this serial by 1. Finally the zone is automatically reloaded by rndc. That way I now have the same comfort as in PowerDNS with Bind9, but also know what's going on, because it's not a black box anymore. Me happy. :-) P.S.: I don't know whether this script is of interest to other users, because it relies heavily on my own setting, e.g. paths and such. But if there's interest, just ask... P.P.S.: Well, I think it's better when you can decide yourself if my script is of interest to you... please find it attached...
Kategorie:

7 November 2014

Dirk Eddelbuettel: RcppRedis 0.1.2

A new release of RcppRedis is now on CRAN. It contains additional commands for hashes and sets, all contributed by John Laing and Whit Armstrong.
Changes in version 0.1.2 (2014-11-06)
  • New commands execv, hset, hget, sadd, srem, and smembers contributed by John Laing and Whit Armstrong over several pull requests.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. As always, more detailed information is on the RcppRedis page page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

6 November 2014

Daniel Kahn Gillmor: GnuPG 2.1.0 in debian experimental

Today, i uploaded GnuPG 2.1.0 into debian's experimental suite. It's built for amd64 and i386 and powerpc already. You can monitor its progress on the buildds to see when it's available for your architecture. ChangesGnuPG 2.1 offers many new and interesting features, but one of the most important changes is the introduction of elliptic curve crypto (ECC). While GnuPG 2.1 discourages the creation of ECC keys by default, it's important that we have the ability to verify ECC signatures and to encrypt to ECC keys if other people are using this tech. It seems likely, for example, that Google's End-To-End Chrome OpenPGP extension will use ECC. GnuPG users who don't have this capability available won't be able to communicate with End-To-End users. There are many other architectural changes, including a move to more daemonized interactions with the outside world, including using dirmngr to talk to the keyservers, and relying more heavily on gpg-agent for secret key access. The gpg-agent change is a welcome one -- the agent now holds the secret key material entirely and never releases it -- as of 2.1 gpg2 never has any asymmetric secret key material in its process space at all. One other nice change for those of us with large keyrings is the new keybox format for public key material. This provides much faster indexed access to the public keyring. I've been using GnuPG 2.1.0 betas regularly for the last month, and i think that for the most part, they're ready for regular use. Timing for debian The timing between the debian freeze and the GnuPG upstream is unfortunate, but i don't think i'm prepared to push for this as a jessie transition yet, without more backup. I'm talking to other members of the GnuPG packaging team to see if they think this is worth even bringing to the attention of the release team, but i'm not pursuing it at the moment. If you really want to see this in debian jessie, please install the experimental package and let me know how it works for you. Long term migration concerns GnuPG upstream is now maintaining three branches concurrently: modern (2.1.x), stable (2.0.x), and classic (1.4.x). I think this is stretches the GnuPG upstream development team too thin, and we should do what we can to help them transition to supporting fewer releases concurrently. In the long-term, I'd ultimately like to see gnupg 2.1.x to replace all use of gpg 1.4.x and gpg 2.0.x in debian, but unlikely to to happen right now. In particular, the following two bugs make it impossible to use my current, common monkeysphere workflow: And GnuPG 2.1.0 drops support for the older, known-weak OpenPGPv3 key formats. This is an important step for simplification, but there are a few people who probably still need to use v3 keys for obscure/janky reasons, or have data encrypted to a v3 key that they need to be able to decrypt. Those people will want to have GnuPG 1.4 around. Call for testing Anyway, if you use debian testing or unstable, and you are interested in these features, i invite you to install gnupg2 and its friends from experimental. If you want to be sensibly conservative, i recommend backing up ~/.gnupg before trying to use it:
cp -aT .gnupg .gnupg.bak
sudo apt install -t experimental gnupg2 gnupg-agent dirmngr gpgsm gpgv2 scdaemon
If you find issues, please file them via the debian BTS as usual. I (or other members of the pkg-gnupg team) will help you triage them to upstream as needed. Tags: ecc, experimental, gnupg

Michal Čihař: Weblate 2.0

Weblate 2.0 has been released today. It comes with lot of improvements in backend and completely new user interface. Full list of changes for 2.0: You can find more information about Weblate on http://weblate.org, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Ready to run appliances will be soon available in SUSE Studio Gallery. Weblate is also being used https://hosted.weblate.org/ as official translating service for phpMyAdmin, Gammu, Weblate itself and others. If you are free software project which would like to use Weblate, I'm happy to help you with set up or even host Weblate for you. Further development of Weblate would not be possible without people providing donations, thanks to everybody who have helped so far!

Filed under: English phpMyAdmin SUSE Weblate 0 comments Flattr this!

Dirk Eddelbuettel: A Software Carpentry workshop at Northwestern

On Friday October 31, 2014, and Saturday November 1, 2014, around thirty-five graduate students and faculty members attended a Software Carpentry workshop. Attendees came primarily from the Economics department and the Kellogg School of Management, which was also the host and sponsor providing an excellent venue with the Allen Center on the (main) Evanston campus of Northwestern University. The focus of the two-day workshop was an introduction, and practical initiation, to working effectively at the shell, getting introduced and familiar with the git revision control system, as well as a thorough introduction to working and programming in R---from the basics all the way to advanced graphing as well as creating reproducible research documents. The idea of the workshop had come out of discussion during our R/Finance 2014 conference. Bob McDonald of Northwestern, one of this year's keynote speakers, and I were discussing various topic related to open source and good programming practice --- as well as the lack of a thorough introduction to either for graduate students and researcher. And once I mentioned and explained Software Carpentry, Bob was rather intrigued. And just a few months later we were hosting a workshop (along with outstanding support from Jackie Milhans from Research Computing at Northwestern). We were extremely fortunate in that Karthik Ram and Ramnath Vaidyanathan were able to come to Chicago and act as lead instructors, giving me an opportunity to get my feet wet. The workshop began with a session on shell and automation, which was followed by three session focusing on R: a core introduction, a session focused on function, and to end the day, a session on the split-apply-combine approach to data transformation and analysis. The second day started with two concentrated session on git and the git workflow. In the afternoon, one session on visualization with R as well as a capstone-alike session on reproducible research rounded out the second day.

Things that worked The experience of the instructors showed, as the material was presented and an effective manner. The selection of topics, as well as the pace were seen by most students to be appropriate and just right. Karthik and Ramnath both did an outstanding job. No students experienced any real difficulties installing software, or using the supplied information. Participants were roughly split between Windows and OS X laptops, and had generally no problem with bash, git, or R via RStudio. The overall Software Carpentry setup, the lesson layout, the focus on hands-on exercises along with instruction, the use of the electronic noteboard provided by etherpad and, of course, the tried-and-tested material worked very well.

Things that could have worked better Even more breaks for exercises could have been added. Students had difficulty staying on pace in some of the exercise: once someone fell behind even for a small error (maybe a typo) it was sometimes hard to catch up. That is a general problem for hands-on classes. I feel I could have done better with the scope of my two session. Even more cohesion among the topics could have been achieved via a single continually used example dataset and analysis.

Acknowledgments Robert McDonald from Kellogg, and Jackie Milhans from Research Computing IT, were superb hosts and organizers. Their help in preparing for the workshop was tremendous, and the pick of venue was excellent, and allowed for a stress-free two days of classes. We could not have done this without Karthik and Ramnath, so a very big Thank You to both of them. Last but not least the Software Carpentry 'head office' was always ready to help Bob, Jackie and myself during the earlier planning stage, so another big Thank You! to Greg and Arliss.

Dirk Eddelbuettel: RPushbullet 0.1.1

A minor bugfix release 0.1.1 of the RPushbullet package (interfacing the neat Pushbullet service) landed on CRAN yesterday morning. It cleans up a small issue related to the ability to transfer files between devices via the Pushbullet service where the ability to select a (non-default) target device has now been restored. With that, allow me to borrow one excellent use case of RPushbullet from the blog of Karl Broman: how to use RPushbullet for error notifications from R:
options(error = function()  
    library(RPushbullet)
    pbPost("note", "Error", geterrmessage())
 )
This is very clever: should an error occur, you get immediate notification in browser or on your phone. Left as an exercise for the reader is to combine this with the equally excellent rfoaas package (github cran) to get appropriately colourful error messages... More details about the package are at the RPushbullet webpage and the RPushbullet GitHub repo. Courtesy of CRANberries, there is also a diffstat report for this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 November 2014

Raphaël Hertzog: My Free Software Activities in October 2014

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Packaging work With the Jessie freeze approaching, I took care of packaging some new upstream releases that I wanted to get in. I started with zim 0.62, I had skipped 0.61 due to some annoying regressions. Since I had two bugs to forward, I took the opportunity to reach out to the upstream author to see if he had some important fixes to get into Jessie. This resulted in me pushing another update with 3 commits cherry picked from the upstream VCS. I also sponsored a wheezy-backports of the new version. I pushed two new bugfixes releases of Publican (4.2.3 and 4.2.6) but I had to include a work-around for a bug that I reported earlier on docbook-xml (#763598: the XML catalog doesn t allow libxml2/xmllint to identify the local copy of some entities files) and that is unlikely to be fixed in time for Jessie. Last but not least, I pushed the first point release of Django 1.7, aka version 1.7.1 to unstable and asked release managers to ensure it migrates to testing before the real freeze. This is important because the closer we are to upstream, the easier it is to apply security patches during the lifetime of Jessie (which will hopefully be 5 years, thanks to Debian LTS!). I also released a backport of python-django 1.7 to wheezy-backports. I sponsored galette 0.7.8+dfsg-1 fixing an RC bug so that it can get back to testing (it got removed from testing due to the bug). Debian LTS See my dedicated report for the paid work I did on that area. Apart from that, I took some time to get in touch with all the Debian consultants and see if they knew some companies to reach out. There are a few new sponsors in the pipe thanks to this, but given the large set of people that it represents, I was expecting more. I used this opportunity to report all bogus entries (i.e bouncing email, broken URL) to the maintainer of the said webpage. Distro Tracker Only 30 commits this month, with almost no external contribution, I m a bit saddened by this situation because it s not very difficult to contribute to this project and we have plenty of easy bugs to get you started. That said I m still happy with the work done. Most of the changes have been made for Kali but will be useful for all derivatives: it s now possible to add external repositories in the tracker and not display them in the list of available versions, and not generate automatic news about those repositories. There s a new derivative application which is only in its infancy but can already provide a useful comparison of a derivative with its parent. See it in action on the Kali Package Tracker: http://pkg.kali.org/derivative/ Thanks to Offensive Security which is sponsoring this work! Since I have pushed Django 1.7 to wheezy-backports, all distro tracker instances that I manage are now running that version of Django and I opted to make that version mandatory. This made it possible to add initial Django migrations and rely on this new feature for future database schema upgrade (I have voluntarily avoided schema change up to now to avoid problems migrating from South to Django migrations). Thanks See you next month for a new summary of my activities.

One comment Liked this article? Click here. My blog is Flattr-enabled.

Carl Chenet: Send the same short message on Twitter, Pump.io, Diaspora* and a lot more

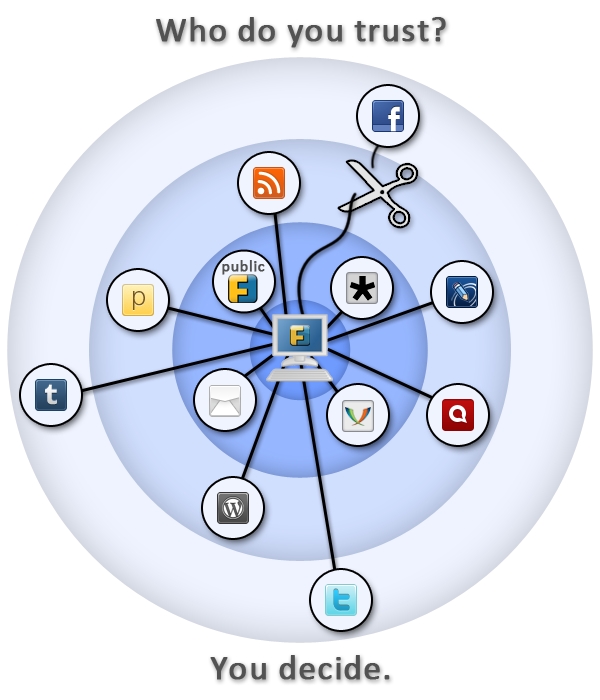
Follow me on Identi.ca or Twitter or Diaspora*diaspora-banner This is a feedback about installing a self hosted instance of Friendica on a Debian server (Jessie). If you re not interested in why I use Friendica, just go to Prerequisite for Friendica section below. Frustration about social networks Being a huge user of short messages, I was quite frustated to spend so much time on my Twitter account. To be quite honest, there is no much I like about this social network, except the huge population of people being potentially interested in what I write. twitter-logo I also have been using Identi.ca (now powered by Pump.io) for a while. But I tried for a while to manage both networks Pump.io and Twitter by hand and it was quite painful. And something was telling me another social network was going to appear from nowhere one of these days and I ll be just horrible to try to keep it up this way. identica-logo So I was looking for a scalable solution not asking too much personal investment. Subscribing to Diaspora* some days ago on the Framasphere pod, tintouli told me to try Friendica. Hmmm, what s Friendica ? f-intro Friendica is a content manager you can plug on almost anything: social networks (Facebook, Twitter, Pump.io, Diaspora*, ), but also WordPress, XMPP, emails I m in fact just discovering the power of this tool but to plug it on my different social network accounts was quite a good use case for me. And I guess if you re still reading, for you too. I tried to use some shared public servers but I was not quite happy with the result, one connector was still missing or public servers were really unstable. So I m at last self hosting my Friendica. Here is how. Prerequisite for Friendica You need to install the following packages: # apt-get install apache2 libapache2-mod-php5 php5 php5-curl php5-gd php5-mysql mysql-server git Having a already self-modified /etc/php5/apache2/php.ini, I encountered a small issue with libCurl and had to manually add the following line in the php.ini: extension=curl.so Setting up MySQL Connect to MySQL and create an empty database with a dedicated user: # mysql -u root -pV3rYS3cr3t -e create database friendica; GRANT ALL PRIVILEGES ON friendica.* TO friendica@localhost IDENTIFIED BY R3AlLyH4rdT0Gu3ss mysql Setting up Apache My server hosts several services, so I use a subdomain friendica.mydomain.com. If you use a subdomain, of course check you do have declared this subdomain in your DNS zone. apache-logo I use SSL encryption with a wildcard certificate for all my subdomains. My Friendica data are stored in /var/www/friendica. Here is my virtual host configuration for Friendica stored in the file /etc/apache2/sites-available/friendicassl.conf : <VirtualHost *:443>
ServerName friendica.mydomain.com
DocumentRoot /var/www/friendica/
DirectoryIndex index.php index.html
ErrorLog /var/log/apache2/friendica-error-ssl.log
TransferLog /var/log/apache2/friendica-access-ssl.log SSLEngine on
SSLCertificateFile /etc/ssl/certs/mydomain/mydomain.com.crt
SSLCertificateKeyFile /etc/ssl/private/mydomain.com.key
SSLVerifyClient None <Directory /var/www/friendica/>
AllowOverride All
Options FollowSymLinks
Order allow,deny
Allow from all
</Directory>
</VirtualHost> After writing the configuration file, just launch the following commands and it should be good for the Apache configuration: # a2ensite friendicassl && /etc/init.d/apache2 reload friendica-trust Setting up Friendica Get the master zip file of Friendica, copy it on your server and decompress it. Something like : # cd /var/www/ && wget https://github.com/friendica/friendica/archive/master.zip && unzip master.zip && mv friendica-master friendica You need to give www-data (Apache user) the rights to write in /var/www/friendica/view/smarty3/ : # chown -R www-data:www-data /var/www/friendica/view/smarty3 && chmod -R ug+w var/www/friendica/view/smarty3 Ok, I guess we re all set, lets launch the installation process! Using your web browser, connect to friendica.mydomain.com. First step you ll see the installation window which checks the prerequisite before installing. Complete if something is missing.
friendica-installation

First window of the Friendica installation process

Second step asks the host/user/password of the database, complete and the installation process starts. Hopefully all goes just fine. Next you ll have to create a /var/www/friendica/.htconfig.php with the content that the last page of the installation process provides. Just copy/paste, check the rights of this file and now you can connect again to see the register page of friendica at the url https://friendlica.mydomain.com/register . Pretty cool! Register a user That s a fairly easy step. You just need to check before that your server is able to send emails, because the password is going to be sent to you by email. If it is ok, you should now identify on the welcome page of friendica and access your account. That s a huge step to broadcast your short messages everywhere, but we have some last steps before being able to send your short messages on all the social networks we need. A small break, create an app for twitter on apps.twitter.com To send your short messages to Twitter, you need to create an app on apps.twitter.com. Just check you re logged in Twitter and connect to apps.twitter.com. Create an app called with a unique name (apparently), then go to the Keys and Access tokens page, note the consumer key and the consumer secret. You ll later need the name of the app, the consumer key and the consumer secret. friendica-decentralized-network Install and configure the addons Friendica uses an addon system in order to plug on the different third-parties it needs. We are going to configure Twitter, Pump.io and the Diaspora* plug. Let s go back to our server and launches some commands: # cd /tmp && git clone https://github.com/friendica/friendica-addons.git && cd friendica-addons # tar xvf twitter.tgz -C /var/www/friendica/addon # tar xvf pumpio.tgz -C /var/www/friendica/addon # cp -a diaspora /var/www/friendica/addon You need to modify your /var/www/friendica/.htconfig.php file and add the following content at the end: // names of your addons, separated by a comma $a->config['system']['addon'] = pumpio, twitter, diaspora ; // your Twitter consumer key
$a->config['twitter']['consumerkey'] = P4Jl2Pe4j7Lj91eIn0AR8vIl2 ; // your Twitter consumer secret
$a->config['twitter']['consumersecret'] = 1DnVkllPik9Ua8jW4fncxwtXZJbs9iFfI5epFzmeI8VxM9pqP1 ; // you Twitter app name $a->config['twitter']['application_name'] = whatever-twitter ; banner_friendica Connect again to Friendica. Go to settings => social networks, you will see the options for Twitter, Pump.io and Diaspora*. Complete the requested information for each of them. Important options you should not forget to check are: Pump.io Twitter Diaspora* Done? Now it s time to send your first broadcasted short message. Yay! Send a short message to your different social networks Connect to Friendica, click on the network page, write your short message in the Share box. Click on the lock lock, you ll see the following setup: friendica-post-default It means your short messages will be broadcasted to the three networks. Or more, it s up to you! That s my setup, feel free to modify. Now close the lock window and send your message. For me it takes some time to appear on Twitter and Diaspora* and it immediatly appears on Identi.ca. Last words friendica-stand Friendica offers to take back the control of your data, by broadcasting content on different media from a single source. While self hosting, you keep your data whatever happends and are not subject to companies losing your data like recently Twitpic. Moreover the philosophy behind Friendica pushed me to dig and test the solution What about you? How do you proceed to broadcast your short messages? Does Friendica offer a good solution in your opinion? Are you interested in the philosophy behind this project? Feel free to share your thoughs in the comments. LAST MINUTE: hey, this article is on Hacker News, don t hesitate to vote for it if you liked it!

4 November 2014

Tiago Bortoletto Vaz: A few words on the recent Brazilian elections

The Brazilian presidential election was exceedingly intense this year. Among many inferences that we can make by following the news and investigating data from the voting results I'd like to share this one, which in my opinion reflects quite well the vote preferences in the country. First, let me introduce you "Bel gua", a small town located in the Northeast region of Brazil. It has 6,524 habitants, 3 buses and 2 hospitals. According to the Brazilian Institute of Geography and Statistics (IBGE), the income per person in Bel gua is $146 BRL (or U$59) per month. Believe it or not, it used to be much less. Actually, the city reported in 2013 the highest economic jump in the country, rising more than a thousand positions in the ranking of GDP per capita (from position 4,991 to 3,849). This recent growth was consequence of the social welfare program of the Brazilian government, which also boosted artisanal and manioc flour production. This federal assistance is called "Bolsa fam lia", which benefits 1.814 families in Bel gua.
"Bolsa Fam lia currently gives families with per-capita monthly income below $140 BRL (poverty line, ~$56 USD) a monthly stipend of $32 BRL (~$13 USD) per vaccinated child (< 16 years old) attending school (up to 5), and $38 BRL (~$15 USD) per youth (16 or 17 years old) attending school (up to 2). Furthermore, to families whose per-capita monthly income below $70 BRL (extreme poverty line, ~$28 USD), the program gives the Basic Benefit $70 BRL per month." (from Wikipedia)
Contrary to what many of my middle-class friends believe, and as you can calculate yourself, this little amount of money does not offer anybody a luxury life. It does not make anybody stopping working, nor stopping looking for paid job (but yes, it makes people to start saying NO to forced labor, which is amazing, right?).
/images/belagua.jpg

Bel gua, where Dilma got 93.93% of votes (photo by Clarissa Carramilo / from G1)

Also, Bel gua has no much physicians around because doctors in Brazil usually wouldn't live in a such city. But now Bel gua population can be treated by foreign doctors imported by the recently launched program "Mais M dicos" (More Physicians for Brazil), which hosts two Cuban doctors 15km away. Finally, Bel gua people have light, due to the "Luz para Todos" ("Light for All") program. It's not surprising that Bel gua has re-elected the party which has motivated these changes. For 2014 presidential election, Bel gua people gave 3.558 votes (93.93%) to Dilma Rousseff (candidate of the current government, from a left-ish party), against 230 (6,07%) to A cio Neves (from the right coalition), being the city with the largest amount of votes for Dilma, proportionally, followed by "Serrano do Maranh o" (93,75%), which is located in the same region. On the other hand, the city which gave, proportionally, the largest amount of votes for A cio Neves has a population of 5,564,635 habitants, where most of citizens are not Brazilians, not yet. Miami, located in US, was the city where Brazilian residents would elect A cio by 7,225 votes (91,79%), against 646 (8,21%) for Dilma, followed by Atlanta/US (89,47%) and Houston/US (89,22%).
/images/miami.jpg

Miami, where 91,79% of Brazilians voted A cio (photo by Marc Averette / from Wikipedia)

It's so clear that we do what people call "selfish vote". In general, we don't care about which party has better proposals for the society as whole. Rich people will go against any serious social equality proposal, which will necessarily be followed by higher taxes on their fortunes. As middle class citizens, we care about dollar rates, because we want to get cheaper iStuff from Miami. We're also very upset by the fact that new apartments are being built without that small room in the back, which has been used to accommodate a subservient housemaid who, until last year was not even legally considered a worker. Those people from Bel gua, who used to live in extreme poverty for decades, serving as slaves, they mostly care about having something to eat. Now they eat, so they can think better, they can work, they can sell what they produce in their little yard. And like middle-class and rich citizens, they will give their vote in exchange of what they think is better for them. The big difference here is, if we ask Bel gua people why they voted for Dilma, with no embarrassment they will make it very clear, that's because her government has provided them lots of benefits. Asking the same question for most Brazilians in Miami, Atlant, Houston or S o Paulo, you'll get not only a bunch of allegedly moral/altruistic reasons, but they will also try to delegitimize in many ways the votes from those marginalized citizens. You'll never get the real reasons from them. They will even try to convince you that whoever receives federal assistance should automatically lose right to vote. Such a statement may seem ridiculous, however it has been very present recently. Actually, such hate speech is happening right now. While I'm writing this post about 2500 people are protesting in S o Paulo streets, asking for an immediate military coup because they don't agree with the elections result. These people keep pushing the limits of ridiculousness. Dilma won with 51.64% of valid votes, a very tight result. The country is clearly divided, mostly by hate, unfortunately.

2 November 2014

Gregor Herrmann: RC bugs 2014/44

this week, my main contribution to fixing RC bugs was to ask others what they think about closing bugs which looked already fixed to me. worked quite fine. full list:

Dirk Eddelbuettel: RcppArmadillo 0.4.500.0

A few days ago, Conrad provided another minor release of Armadillo. Once again, I had created a GitHub-only pre-release of his pre-release which was tested against (then) all ninety (!!) CRAN dependents of our RcppArmadillo package, providing a further test for Conrad's code and uploaded RcppArmadillo 0.4.500.0 to CRAN and Debian once his release was finalized. The few changes from his end are summarized below; our end also includes an update / extension to the sample() method provided by Christian Gunning --- and used to great effect in the excellent Rcpp Gallery post by Jonathan Olmsted.
Changes in RcppArmadillo version 0.4.500.0 (2014-10-30)
  • Upgraded to Armadillo release Version 4.500 ("Singapore Sling")
    • faster handling of complex vectors by norm()
    • expanded chol() to optionally specify output matrix as upper or lower triangular
    • better handling of non-finite values when saving matrices as text files
  • The sample functionality has been extended to provide the Walker Alias method (including new unit tests) via a pull request by Christian Gunning
Courtesy of CRANberries, there is also a diffstat report for the most recent release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Thomas Goirand: OpenStack packaging activity: October 2014

Wednesday 1:
Uploaded python-xstatic-jquery removing the .pth file from package.
Uploaded python-taskflow 0.4 to experimental, needed by Cinder Juno RC1
Uploaded Cinder Juno RC1 to experimental Thuesday 2:
Finally understood that the issue with murano-dashboard was that it doesn t build without django-nose >= 1.2. Opened new patch at: https://review.openstack.org/125565
Uploaded murano-dashboard to Experimental, now using django-nose from wheezy-backports in my jenkins setup, so murano-dashboard can be built for Wheezy.
Uploaded python-oslotest 1.1.0.0 (really is upstream 1.1.0)
Uploaded python-oslo.serialization 1.0.0-1 (needed by Ceilometer Juno RC1)
Uploaded Ceilometer Juno RC1
Uploaded Heat Juno RC1
Uploaded oslo.rootwrap 1.3.0.0
Uploaded oslo.db 1.0.2 (bugfix release)
Wrote a new system in openstack-pkg-tools to generate init scripts and. service files from a template, so we don t have to write N times the same thing. Friday 3:
Reworked openstack-pkg-tools to generate automatically sysv-rc init scripts, upstart jobs and systemd unit files, making the system more unified and consistent.
Applied the new system to all packages in Juno.
Uploaded Keystone 2014.1.3-1 to Sid
Uploaded Nova 2014.1.3-1 to Sid
Uploaded Glance 2014.1.3-1 to Sid
Uploaded Neutron 2014.1.3-1 to Sid
Uploaded Horizon 2014.1.3-1 to Sid
Uploaded Cinder 2014.1.3-1 to Sid
Uploaded Trove 2014.1.3-1 to Sid
Uploaded Ceilometer 2014.1.3-1 to Sid Saturday 4:
Uploaded Horizon Juno RC1 to Experimental
Uploaded oslotest 1.1.0.0 to Experimental
Uploaded Ironic Juno RC1 to Experimental
Uploaded Designate Juno RC1 to Experimental
Uploaded Nova Juno RC1 to Experimental
Uploaded Neutron Juno RC1 to Experimental
Uploaded openstack-meta-packages 0.10 to Sid
Uploaded openstack-pkg-tools 13 to Experimental
Uploaded murano-agent Juno RC1 to Experimental Sunday 5:
Uploaded Sahara Juno RC1 to Experimental (it s been approved by FTP masters)
Uploaded Murano Juno RC1 to Experimental (it s been approved by FTP masters)
Fixed all debian/watch file to understand ~b and ~rc releases (fixed applied on both Icehouse and Juno branches, though no upload yet, I ll wait until uploads are needed to have this in the archive ).
Uploaded Trove Juno RC1 to Experimental
Uploaded Sahara Juno RC1 to Experimental With this last upload, everything of Juno RC1 is in Debian Experimental! \o/ Monday 6:
Uploaded some fixes for Nova 2014.1.3-2 in Sid:
* Removed contrib/boto_v6/* in debian/copyright, replaced bin/nova-manage by nova/cmd/ baremetal_, manage.py.
* Mangling upstream rc and beta versions in watch file.
* Added 9990_update_german_programm_messages.patch, thanks to Helge Kreutzmann <debian@helgefjell.de>.
* Fixed correct de.po (Closes: #763682).
* Added nl.po initial Debconf translation, thanks to Frans Spiesschaert <Frans.Spiesschaert@yucom.be> (Closes: #764125).
* Standards-Version is now 3.9.6 (no change).
Upstreamed german translation of po file: https://review.openstack.org/126212
Uploaded Designate 2014.1-12 to Sid, added new de.po also to the Juno branch on alioth (but didn t upload the fix yet).
Uploaded sphinxcontrib-httpdomain new upstream 1.3.0 release, added Python 3.x support to the package, and transitionning to the correct namespaced python-sphinxcontrib.httpdomain package name.
Spent most of the day fixing python-xstatic issues:
o uploaded libjs-twitter-bootstrap-datepicker 1.3.1
o uploaded python-xstatic-bootstrap-datepicker requiring this libjs package
o fixed python-xstatic-jquery-ui package
Now Horizon Juno RC1 builds well, and can be installed again. \o/ Tuesday 7:
Backported python-libvirt 1.2.8 in Wheezy (for Nova Juno support )
Uploaded Ceilometer Juno RC1 with ceilometer-agent-ipmi added (the package will therefore go through the NEW queue).
Uploaded python-requestbuilder 0.2.2-1, needed by the maintainers of euca2ools.
Ported the unified generated init system scripts to Icehouse packages.
Uploaded to Sid updates for: openstack-pkg-tools, ceilometer, cinder, glance, keystone, cinder, nova. Wednesday 8:
Uploaded openstack-pkg-tools 16 to Sid
Uploaded murano-dashboard (with upstream fix to remove font-awesome, which was the reason for FTP master s rejection)
Uploaded ceilometer Juno RC1 with new IPMI agent package (needed for Ironic support).
Uploaded heat 2014.1.3 which I forgot.
Tested https://review.openstack.org/#/c/126777/ which solves the bug I sent to launchpad and approved the patch.
Uploaded python-requestbuilder 0.2.3 Thesday 9:
Worked on fixing Neutron Alembic migration with SQLite3.
Uploade Neutron 2014.2~rc1-3 with a fix for a patch that was destroying dhcp.py. This still doesn t include the Alembic migration fixes, which are still a WIP. Firday 10:
Finished fixing Neutron SQLite 3 Alembic migrations.
Uploaded neutron 2014.2~rc1-3 with the fixes.
Fixed Ceilometer wrong generation of sample config file, using upstream patch (after discussing with Julien Danjou so he wrote it).
Uploaded Ceilometer 2014.2~rc1-4 with the fix
Checked that all packages can be installed in non-interactive mode. This works well now! \o/ Saturday 11:
Uploaded new version of python-xstatic-angular-cookies (ie: 1.2.24.1-2) which allows a higher version of libjs-angularjs (otherwise the package is not installable in Sid/Jessie since last version of angularjs is uploaded). Sunday 12:
Uploaded factory-boy fix for FTBFS
Uploaded python-django-appconf FTBFS
Uploaded Horizon Juno RC2
Uploaded Heat Juno RC3
Uploaded Trove Juno RC2
Uploaded Glance Juno RC2
Uploaded Sahara Juno RC2
Uploaded Nova Juno RC2
Uploaded Neutron Juno RC2
Uploaded Cinder Juno RC2
Uploaded murano-dashboard Juno RC2 Monday 13:
Uploaded python-heatclient 0.2.12-1 to Experimental
Uploaded python-yaql with RC bugfix to Sid (missing dep on python3-ply). Thuesday 14:
Fixed arping newly added dependency in Neutron
Started testing install of all of openstack Juno at once Wednesday 15:
Fixed missing configuration files in Ceilometer (ceilometer-api couldn t start)
Upgraded to Ceilometer Juno RC3.
Backported python-setuptools, as keystone and others are broken due to the namespace of modules not working correctly with the old version of python-pkg-resources. With the new one, everything is back in order. Thesday 16:
Uploaded to Debian Experimental the final release of Juno (ie: 2014.2) for:
Sahara
Nova
Ceilometer
Cinder
Heat
Neutron
Glance
Keystone
Horizon (with fix for Django 1.7 in the wsgi file)
Uploaded to Sid:
Swift 2.2.0
Horizon 2014.1.3-3 with fix for Django 1.7 in the wsgi file that was crashing apache. OpenStack Juno packages are out!!! (ready the day of the upstream release ) Friday 17:
Investigated Trove RC bug #765348, couldn t reproduce, and therefore closed it.
Uploaded Ironic Juno final to Experimental
Uploaded Designate Juno final to Experimental
Uploaded a fix for python-jingo which failed to build with Django 1.7. Sent pull request upstream: https://github.com/jbalogh/jingo/pull/63
Uploaded CVE-2014-7230 & CVE-2014-7231 fixes for both Cinder and Nova in Debian Sid, as per OSSA 2014-036 patches. No need to upload a fix for Trove, as 2014.1.3 already has the fixes. Saturday 18:
Started building Trusty packages
Fixed oslo-config so that it never depends on python3-argparse, which doesn t exist (uploaded to Experimental)
Uploaded python-django-pyscss 1.0.3-2 with python-simplejson now as build-depends (it failed to build in my Trusty jenkins without it).
Uploaded a fix for stevedore and oslo-config to not depends on python3-argparse in Ubuntu (added debian/py3dist-overrides) Sunday 19:
Uploaded python-taskflow with ordereddict in debian/pydist-overrides.
Backported JS packages for Horizon and libvirt for Trusty (from Sid). My new Jenkin server is now producing a full set of Juno packages for Ubuntu trusty. And of course, it s updated on each git push, just like for the Wheezy backports. Monday 20:
Added FORCE_COULEUR=1 when running tests in python-couleur, so that it doesn t fail when running with git-buildpackage. Uploaded result in Sid.
Fixed python-mockito so that it never downloads distribute or nose on its clean target, which was annoying when running git-buildpackage. Uploaded to Sid.
Started to work again on automatic package deployment using openstack-deploy, from the openstack-meta-packages source package. Thuesday 21, Wednesday 22:
Worked on testing packages, did couples of minor fixes, reworked some of the default configuration files to match the install-guide, move configuration directive to the correct new section in nova.conf, etc. Thursday 23:
Patch the Neutron chapter in the install-guide to take into account the changes done on Thuesday 21, Wednesday 22, and simplify the install procedure in Debian. https://review.openstack.org/#/c/130501/ Friday 24:
Busy packing my stuff for moving to France Not much packaging work, except more auto-deploy stuff and some tests. Saturday 25:
Uploaded Nova, Neutron, Cinder and Horizon Icehouse in Sid, including some debconf translation updates, beating the Jessie freeze deadline in 10 days.
Fixed and uploaded openstack-debian-images in Sid: the login option wasn t modifying the default sudoers file, which always contained debian , instead of the custom login. Sunday 26:
Traveled to Moscow Monday 27 & Tuesday 28:
Fixed some murano & murano-dashboard stuff, thanks to the help of some murano team members in Moscow office. Uploaded fixes for murano & murano-dashboard. Tested that murano-dashboard works well, and now it does! :)
Uploaded version dependency fixes for python-xstatic-angular-cookies and python-xstatic-d3 which couldn t be installed in Sid/Jessie because of libjs-* updates. Wednesday 29:
Meeting with Saratov team
Updated sahara endpoints, but didn t upload the package yet to Debian. Thursday 30:
Uploaded ruby-raemon needed for Astute (part of Fuel web).
Packaged ruby-symboltable (not uploaded yet). Friday 31:
Wrote unit test runner for python-webpy (the current package doesn t have unit test runs).
Uploaded python-dbutils (needed by python-web.py unit tests) to Sid: now in NEW queue
Uploaded python-nose-parametrized & python-nose-timer to Sid: now in NEW queue
Uploaded sahara -2 fixing the API endpoint registration URL and service name.
Uploaded python-sphinxcontrib.plantuml to Sid: : now in NEW queue

1 November 2014

Thorsten Alteholz: My Debian Activities in October 2014

FTP assistant This month has been the month before the freeze. Lots of people uploaded a package at the last moment and wanted to have it in testing before everything is over. This resulted in even more processed package than in September. I was able to accept 407 packages and had to reject 77. The whole FTP team managed it to bring the NEW queue below 40 waiting packages. As the Release team doesn t like to see binary-NEW packages appearing in unstable (at least those which change the soname of a lib), this number will increase again. But, that s life I am glad that a freeze happens only every few years. So I would particularly thank my dear wife for her patience, when she saw me sitting in front of that damned computer again and again. Squeeze LTS This was my fourth month that I did some work for the Squeeze LTS initiative, started by Raphael Hertzog at Freexian. This month I got assigned a workload of 13.75h and I spent these hours to upload new versions of I also prepared a new upload of wget and still wait for some feedback. In this case some default values had to be changed and I better wait a bit before I break some scripts. Moreover five CVEs accumulated for php5, so I guess another upload has to be done for this package. This will be ready in the next days I also tried to work on libtasn1-3 and librack-ruby. There hadn t been DSAs for these packages and I tried to dig into the upstream repositories. Unfortunately I failed to find the correct patches. Kudos to the Security Team who have to struggle with all kind of commit messages on a daily basis. Other packages I didn t have time to do any work on my own packages. But during my ftp-time I saw one or another package that deals with some kind of home automation. Up to now there doesn t seem to be a Debian group who deals with this topic. Maybe it is time to start one? Support If you would like to support my Debian work you could either be part of the Freexian initiative (see above) or consider to send some bitcoins to 1JHnNpbgzxkoNexeXsTUGS6qUp5P88vHej. Contact me at donation@alteholz.eu if you prefer another way to donate. Every kind of support is most appreciated.

30 October 2014

Chris Lamb: Are you building an internet fridge?

Mikkel Rasmussen:
If you look at the idea of "The Kitchen of Tomorrow" as IKEA thought about it is the core idea is that cooking is slavery. It's the idea that technology can free us from making food. It can do it for us. It can recognise who we are, we don't have to be tied to the kitchen all day, we don't have to think about it. Now if you're an anthropologist, they would tell you that cooking is perhaps one of the most complicated things you can think about when it comes to the human condition. If you think about your own cooking habits they probably come from your childhood, the nation you're from, the region you're from. It takes a lot of skill to cook. It's not so easy. And actually, it's quite fun to cook. there's also a lot of improvisation. I don't know if you ever tried to come home to a fridge and you just look into the fridge: oh, there's a carrot and some milk and some white wine and you figure it out. That's what cooking is like it's a very human thing to do.
https://chris-lamb.co.uk/wp-content/2014/fridge.jpg

The physical version of your smart recipe site?


Therefore, if you think about it, having anything that automates this for you or decides for you or improvises for you is actually not doing anything to help you with what you want to do, which is that it's nice to cook. More generally, if you make technology for example that has at its core the idea that cooking is slavery and that idea is wrong, then your technology will fail. Not because of the technology, but because it simply gets people wrong. This happens all the time. You cannot swing a cat these days without hitting one of those refrigerator companies that make smart fridges. I don't know you've ever seen them, like a "intelligent fridge". There's so many of them that there is actually a website called "Fuck your internet fridge" by a guy who tracks failed prototypes on intelligent fridges. Why? Because the idea is wrong. Not the technology, but the idea about who we are - that we do not want the kitchen to be automated for us. We want to cook. We want Japanese knives. We want complicated cooking. And so what we are saying here is not that technology is wrong as such. It's just you need to base it especially when you are innovating really big ideas on something that's a true human insight. And cooking as slavery is not a true human insight and therefore the prototypes will fail.
(I hereby nominate "internet fridge" as the term to describe products or ideas that whilst technologically sound is based on fundamentally flawed anthropology.) Hearing "I hate X" and thinking that simply removing X will provide real value to your users is short-sighted, especially when you don't really understand why humans are doing X in the first place.

Matthew Garrett: Hacker News metrics (first rough approach)

I'm not a huge fan of Hacker News[1]. My impression continues to be that it ends up promoting stories that align with the Silicon Valley narrative of meritocracy, technology will fix everything, regulation is the cancer killing agile startups, and discouraging stories that suggest that the world of technology is, broadly speaking, awful and we should all be ashamed of ourselves.

But as a good data-driven person[2], wouldn't it be nice to have numbers rather than just handwaving? In the absence of a good public dataset, I scraped Hacker Slide to get just over two months of data in the form of hourly snapshots of stories, their age, their score and their position. I then applied a trivial test:
  1. If the story is younger than any other story
  2. and the story has a higher score than that other story
  3. and the story has a worse ranking than that other story
  4. and at least one of these two stories is on the front page
then the story is considered to have been penalised.

(note: "penalised" can have several meanings. It may be due to explicit flagging, or it may be due to an automated system deciding that the story is controversial or appears to be supported by a voting ring. There may be other reasons. I haven't attempted to separate them, because for my purposes it doesn't matter. The algorithm is discussed here.)

Now, ideally I'd classify my dataset based on manual analysis and classification of stories, but I'm lazy (see [2]) and so just tried some keyword analysis:
KeywordPenalisedUnpenalised
Women134
Harass20
Female51
Intel23
x8634
ARM34
Airplane12
Startup4626

A few things to note:
  1. Lots of stories are penalised. Of the front page stories in my dataset, I count 3240 stories that have some kind of penalty applied, against 2848 that don't. The default seems to be that some kind of detection will kick in.
  2. Stories containing keywords that suggest they refer to issues around social justice appear more likely to be penalised than stories that refer to technical matters
  3. There are other topics that are also disproportionately likely to be penalised. That's interesting, but not really relevant - I'm not necessarily arguing that social issues are penalised out of an active desire to make them go away, merely that the existing ranking system tends to result in it happening anyway.

This clearly isn't an especially rigorous analysis, and in future I hope to do a better job. But for now the evidence appears consistent with my innate prejudice - the Hacker News ranking algorithm tends to penalise stories that address social issues. An interesting next step would be to attempt to infer whether the reasons for the penalties are similar between different categories of penalised stories[3], but I'm not sure how practical that is with the publicly available data.

(Raw data is here, penalised stories are here, unpenalised stories are here)


[1] Moving to San Francisco has resulted in it making more sense, but really that just makes me even more depressed.
[2] Ha ha like fuck my PhD's in biology
[3] Perhaps stories about startups tend to get penalised because of voter ring detection from people trying to promote their startup, while stories about social issues tend to get penalised because of controversy detection?

comment count unavailable comments

Alessio Treglia: Handling identities in distributed Linux cloud instances

I ve many distributed Linux instances across several clouds, be them global, such as Amazon or Digital Ocean, or regional clouds such as TeutoStack or Enter. Probably many of you are facing the same issue: having a consistent UNIX identity across all multiple instances. While in an ideal world LDAP would be a perfect choice, letting LDAP open to the wild Internet is not a great idea. So, how to solve this issue, while being secure? The trick is to use the new NSS module for SecurePass. While SecurePass has been traditionally used into the operating system just as a two factor authentication, the new beta release is capable of holding extended attributes , i.e. arbitrary information for each user profile. We will use SecurePass to authenticate users and store Unix information with this new capability. In detail, we will: SecurePass and extended attributes The next generation of SecurePass (currently in beta) is capable of storing arbitrary data for each profile. This is called Extended Attributes (or xattrs) and -as you can imagine- is organized as key/value pair. You will need the SecurePass tools to be able to modify users extended attributes. The new releases of Debian Jessie and Ubuntu Vivid Vervet have a package for it, just:
# apt-get install securepass-tools
ERRATA CORRIGE: securepass-tools hasn t been uploaded to Debian yet, Alessio is working hard to make the package available in time for Jessie though.
For other distributions or previous releases, there s a python package (PIP) available. Make sure that you have pycurl installed and then:
# pip install securepass-tools
While SecurePass tools allow local configuration file, we highly recommend for this tutorial to create a global /etc/securepass.conf, so that it will be useful for the NSS module. The configuration file looks like:
[default]
app_id = xxxxx
app_secret = xxxx
endpoint = https://beta.secure-pass.net/
Where app_id and app_secrets are valid API keys to access SecurePass beta. Through the command line, we will be able to set UID, GID and all the required Unix attributes for each user:
# sp-user-xattrs user@domain.net set posixuid 1000
While posixuid is the bare minimum attribute to have a Unix login, the following attributes are valid: Install and Configure NSS SecurePass In a similar way to the tools, Debian Jessie and Ubuntu Vivid Vervet have native package for SecurePass:
# apt-get install libnss-securepass
For previous releases of Debian and Ubuntu can still run the NSS module, as well as CentOS and RHEL. Download the sources from: https://github.com/garlsecurity/nss_securepass Then:
./configure
make
make install (Debian/Ubuntu Only)
For CentOS/RHEL/Fedora you will need to copy files in the right place:
/usr/bin/install -c -o root -g root libnss_sp.so.2 /usr/lib64/libnss_sp.so.2
ln -sf libnss_sp.so.2 /usr/lib64/libnss_sp.so
The /etc/securepass.conf configuration file should be extended to hold defaults for NSS by creating an [nss] section as follows:
[nss]
realm = company.net
default_gid = 100
default_home = "/home"
default_shell = "/bin/bash"
This will create defaults in case values other than posixuid are not being used. We need to configure the Name Service Switch (NSS) to use SecurePass. We will change the /etc/nsswitch.conf by adding sp to the passwd entry as follows:
$ grep sp /etc/nsswitch.conf
 passwd:  files sp
Double check that NSS is picking up our new SecurePass configuration by querying the passwd entries as follows:
$ getent passwd user
 user:x:1000:100:My User:/home/user:/bin/bash
$ id user
 uid=1000(user)  gid=100(users) groups=100(users)
Using this setup by itself wouldn t allow users to login to a system because the password is missing. We will use SecurePass authentication to access the remote machine. Configure PAM for SecurePass On Debian/Ubuntu, install the RADIUS PAM module with:
# apt-get install libpam-radius-auth
If you are using CentOS or RHEL, you need to have the EPEL repository configured. In order to activate EPEL, follow the instructions on http://fedoraproject.org/wiki/EPEL Be aware that this has not being tested with SE-Linux enabled (check off or permissive). On CentOS/RHEL, install the RADIUS PAM module with:
# yum -y install pam_radius
Note: as per the time of writing, EPEL 7 is still in beta and does not contain the Radius PAM module. A request has been filed through RedHat s Bugzilla to include this package also in EPEL 7 Configure SecurePass with your RADIUS device. We only need to set the public IP Address of the server, a fully qualified domain name (FQDN), and the secret password for the radius authentication. In case of the server being under NAT, specify the public IP address that will be translated into it. After completion we get a small recap of the already created device. For the sake of example, we use secret as our secret password. Configure the RADIUS PAM module accordingly, i.e. open /etc/pam_radius.conf and add the following lines:
radius1.secure-pass.net secret 3
radius2.secure-pass.net secret 3
Of course the secret is the same we have set up on the SecurePass administration interface. Beyond this point we need to configure the PAM to correct manage the authentication. In CentOS, open the configuration file /etc/pam.d/password-auth-ac; in Debian/Ubuntu open the /etc/pam.d/common-auth configuration and make sure that pam_radius_auth.so is in the list.
auth required   pam_env.so
auth sufficient pam_radius_auth.so try_first_pass
auth sufficient pam_unix.so nullok try_first_pass
auth requisite  pam_succeed_if.so uid >= 500 quiet
auth required   pam_deny.so
Conclusions Handling many distributed Linux poses several challenges, from software updates to identity management and central logging. In a cloud scenario, it is not always applicable to use traditional enterprise solutions, but new tools might become very handy. To freely subscribe to securepass beta, join SecurePass on: http://www.secure-pass.net/open
And then send an e-mail to info@garl.ch requesting beta access.

Juliana Louback: JSCommunicator at xTupleCon 2014

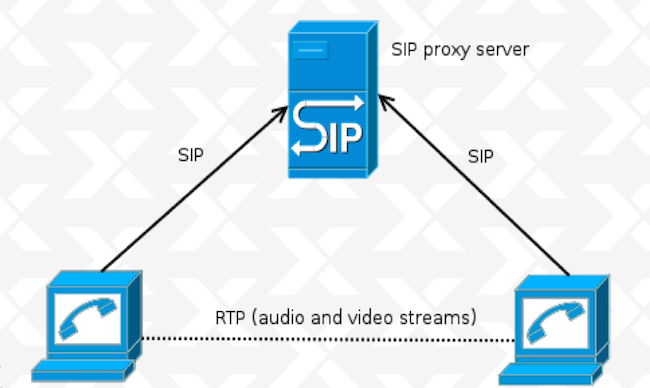
Two weeks ago I left NYC for a day trip to Norfolk, Virginia, to attend xTupleCon 2014. For those who don t know, xTuple is an incredibly reknown open source Enterprise Resource Planning (ERP) software. If you ve been following this blog, you might recall that during my participation in the Google Summer of Code 2014, I wrote a beta JSCommunicator extension for xTuple (to see how I went about doing that, look up Kickstarting the JSCommunicator-xTuple extension). Now, I wasn t flying down to Virginia on the eve of my first grad school midterms (gasp!) for fun - although I will admit, I enjoyed myself a fair amount. My GSoC mentor, Daniel Pocock was giving a talk about WebRTC and JSCommunicator at xTupleCon and invited me to participate. So that was the first perk of going to xTupleCon, I got to finally meet my GSoC mentor in person! During the presentation, Daniel provided a high level expanation of WebRTC and how it works. WebRTC (Web Real Time Communications) enables real time transmission of audio, video and data streams through browser-to-browser applications. This is one of the many perks of WebRTC; it doesn t require installation of plugins, making its use less vulnerable to security breaches. Websockets are used for the signalling channel and the SIP or XMPP can be used as the signaling protocol - in JSCommunicator, we used SIP. What was also done in JSCommunicator and can be done in other applications is to use a library to implement the signaling and SIP stack. JSCommunicator uses (and I highly reccomend) JsSIP. The basic SIP architecture is comprised of peers and a SIP Proxy Server that supports SIP over Websockets transport: sipArch If you have users behind NAT, you ll also need a TURN server for relay: sipArch2 In both cases, setup is not too difficult, particularly if using reSIProcate which offers both the SIP proxy and the TURN server. Daniel Pocock has an excellent post on how to setup and configure your SIP proxy and TURN server. With regard to JSCommunicator, it is a generic telephone in HTML5 which can easily be embedded in any web site or web app. Almost every aspect of JSCommunicator is easily customizable. More about JSCommunicator setup and architecture is detailed in a previous post. The JSCommunicator-xTuple extension can be installed in xTuple as an npm package (xtuple-jscommunicator). It is still at a very beta - or even pre-beta - stage and there are various limitations; the configuration must be hard-coded and dialing is done manually as opposed to clicking on a contact. Some of these limitations are features are on the wish list for future work. For example, some ideas for the next version of the extension are a click to dial from CRM records functionality and to bring up CRM records for an incomming call. Additionaly, the SIP proxy could be automatically installed with the xTuple server installation if desired. We closed the presentation with a live demo during which I made a video call from a JSCommunicator instance embedded in freephonebox.net to the JSCommunicator xTuple extension running on Daniel s laptop. Despite the occasionally iffy hotel Wifi, the demo was a hit - at one point I even left the conference room and took a quick walk around the hotel and invited other xTupleCon attendees to say hello to those in the room. The audience s reception was more enthusiastic than I anticipated, giving way to a pretty extensive Q&A session. It s great to see more and more people interested in WebRTC, I can t emphasize enough what a useful and versatile tool it is. Here s an action shot of part of the xTuple WebRTC presentation: xtuple

Keith Packard: Glamor cleanup

Glamor Cleanup Before I start really digging in to reworking the Render support in Glamor, I wanted to take a stab at cleaning up some cruft which has accumulated in Glamor over the years. Here's what I've done so far. Get rid of the Intel fallback paths I think it's my fault, and I'm sorry. The original Intel Glamor code has Glamor implement accelerated operations using GL, and when those fail, the Intel driver would fall back to its existing code, either UXA acceleration or software. Note that it wasn't Glamor doing these fallbacks, instead the Intel driver had a complete wrapper around every rendering API, calling special Glamor entry points which would return FALSE if GL couldn't accelerate the specified operation. The thinking was that when GL couldn't do something, it would be far faster to take advantage of the existing UXA paths than to have Glamor fall back to pulling the bits out of GL, drawing to temporary images with software, and pushing the bits back to GL. And, that may well be true, but what we've managed to prove is that there really aren't any interesting rendering paths which GL can't do directly. For core X, the only fallbacks we have today are for operations using a weird planemask, and some CopyPlane operations. For Render, essentially everything can be accelerated with the GPU. At this point, the old Intel Glamor implementation is a lot of ugly code in Glamor without any use. I posted patches to the Intel driver several months ago which fix the Glamor bits there, but they haven't seen any review yet and so they haven't been merged, although I've been running them since 1.16 was released... Getting rid of this support let me eliminate all of the _nf functions exported from Glamor, along with the GLAMOR_USE_SCREEN and GLAMOR_USE_PICTURE_SCREEN parameters, along with the GLAMOR_SEPARATE_TEXTURE pixmap type. Force all pixmaps to have exact allocations Glamor has a cache of recently used textures that it uses to avoid allocating and de-allocating GL textures rapidly. For pixmaps small enough to fit in a single texture, Glamor would use a cache texture that was larger than the pixmap. I disabled this when I rewrote the Glamor rendering code for core X; that code used texture repeat modes for tiles and stipples; if the texture wasn't the same size as the pixmap, then texturing would fail. On the Render side, Glamor would actually reallocate pixmaps used as repeating texture sources. I could have fixed up the core rendering code to use this, but I decided instead to just simplify things and eliminate the ability to use larger textures for pixmaps everywhere. Remove redundant pixmap and screen private pointers Every Glamor pixmap private structure had a pointer back to the pixmap it was allocated for, along with a pointer to the the Glamor screen private structure for the related screen. There's no particularly good reason for this, other than making it possible to pass just the Glamor pixmap private around a lot of places. So, I removed those pointers and fixed up the functions to take the necessary extra or replaced parameters. Similarly, every Glamor fbo had a pointer back to the Glamor screen private too; I removed that and now pass the Glamor screen private parameter as needed. Reducing pixmap private complexity Glamor had three separate kinds of pixmap private structures, one for 'normal' pixmaps (those allocated by them selves in a single FBO), one for 'large' pixmaps, where the pixmap was tiled across many FBOs, and a third for 'atlas' pixmaps, which presumably would be a single FBO holding multiple pixmaps. The 'atlas' form was never actually implemented, so it was pretty easy to get rid of that. For large vs normal pixmaps, the solution was to move the extra data needed by large pixmaps into the same structure as that used by normal pixmaps and simply initialize those elements correctly in all cases. Now, most code can ignore the difference and simply walk the array of FBOs as necessary. The other thing I did was to shrink the number of possible pixmap types from 8 down to three. Glamor now exposes just these possible pixmap types: Future Work

Matthew Garrett: On joining the FSF board

I joined the board of directors of the Free Software Foundation a couple of weeks ago. I've been travelling a bunch since then, so haven't really had time to write about it. But since I'm currently waiting for a test job to finish, why not?

It's impossible to overstate how important free software is. A movement that began with a quest to work around a faulty printer is now our greatest defence against a world full of hostile actors. Without the ability to examine software, we can have no real faith that we haven't been put at risk by backdoors introduced through incompetence or malice. Without the freedom to modify software, we have no chance of updating it to deal with the new challenges that we face on a daily basis. Without the freedom to pass that modified software on to others, we are unable to help people who don't have the technical skills to protect themselves.

Free software isn't sufficient for building a trustworthy computing environment, one that not merely protects the user but respects the user. But it is necessary for that, and that's why I continue to evangelise on its behalf at every opportunity.

However.

Free software has a problem. It's natural to write software to satisfy our own needs, but in doing so we write software that doesn't provide as much benefit to people who have different needs. We need to listen to others, improve our knowledge of their requirements and ensure that they are in a position to benefit from the freedoms we espouse. And that means building diverse communities, communities that are inclusive regardless of people's race, gender, sexuality or economic background. Free software that ends up designed primarily to meet the needs of well-off white men is a failure. We do not improve the world by ignoring the majority of people in it. To do that, we need to listen to others. And to do that, we need to ensure that our community is accessible to everybody.

That's not the case right now. We are a community that is disproportionately male, disproportionately white, disproportionately rich. This is made strikingly obvious by looking at the composition of the FSF board, a body made up entirely of white men. In joining the board, I have perpetuated this. I do not bring new experiences. I do not bring an understanding of an entirely different set of problems. I do not serve as an inspiration to groups currently under-represented in our communities. I am, in short, a hypocrite.

So why did I do it? Why have I joined an organisation whose founder I publicly criticised for making sexist jokes in a conference presentation? I'm afraid that my answer may not seem convincing, but in the end it boils down to feeling that I can make more of a difference from within than from outside. I am now in a position to ensure that the board never forgets to consider diversity when making decisions. I am in a position to advocate for programs that build us stronger, more representative communities. I am in a position to take responsibility for our failings and try to do better in future.

People can justifiably conclude that I'm making excuses, and I can make no argument against that other than to be asked to be judged by my actions. I hope to be able to look back at my time with the FSF and believe that I helped make a positive difference. But maybe this is hubris. Maybe I am just perpetuating the status quo. If so, I absolutely deserve criticism for my choices. We'll find out in a few years.

comment count unavailable comments

Next.

Previous.