Search Results: "nate"

28 May 2013

Russ Allbery: Review: Advanced Perl Programming

Review: Advanced Perl Programming, by Sriram Srinivasan
Publisher: O'Reilly
Copyright: August 1997
ISBN: 1-56592-220-4
Format: Trade paperback
Pages: 392
The problem with buying lots of books is that one frequently doesn't read them soon after purchase. And while nearly all fiction and most non-fiction doesn't have a time limit, technical books are more of a problem. As you might have guessed from the publication date and subject matter of this book, it's one I waited too long to read. I picked up Advanced Perl Programming not too long after it was first published in 1997. I bought it primarily for the chapters on XS programming, since I was just starting to develop and help maintain code that built Perl interfaces for C libraries. And then it sat on my bookshelf in the office, and then at home, until it was 16 years old. That's problematic for a general Perl programming guide; it's particularly troublesome for a book that dives deep into internals. That said, I still got some interesting information from it. Advanced Perl Programming is something of a grab bag of different and largely unrelated topics. It starts with a data structures overview (which is mostly about references), covers typeglobs and the Perl symbol table, briefly discusses closures, and then dives deeper into eval. That's followed by an overview of modules and object-oriented programming in Perl. The general Perl topics close with a solid (if outdated) discussion of tied objects and a somewhat rambling and remarkably general discussion of persistance. Srinivasan then covers some recommended module APIs for networking and graphics (Tk, specifically) while working through some complex examples, takes a deeper dive into eval and code generation, and concludes with three chapters on XS and embedded Perl interpreters. This is all solid material, but a lot of it is at least partly obsolete. The chapters on modules and object-oriented programming fare the worst; you'll find much better guides to those topics elsewhere. Data structures also fare poorly, partly because Srinivasan is still happy to use symbolic references, now considered bad style due to lack of compile-time checking. (That does mean, though, that this is one of the best introductions to symbolic references that you'll find, since few other Perl programmers discuss them.) But the rest of the book is fairly solid, if limited by age. If I'd read it when I first started with XS, it would have indeed helped. Advanced Perl Programming contains a succinct and clear overview of Perl internals and data representation (assuming, of course, it's not changed drastically, but I didn't notice any significant issues from what I know of internals from quite a lot of XS programming), particularly when combined with the earlier chapter on typeglobs and the symbol table. It is interesting, though, to see how much accepted Perl style has changed. Srinivasan is quite fond of eval with a scalar argument to construct code at runtime, something that most current authors recommend against when it can be avoided. The loss of static syntax checking means the technique is often hard to debug and can cause surprising runtime errors. Several of the more advanced tricks in this book are built on that framework, including a moderately interesting templating system that he constructs from scratch in this book. The examples here are also missing the focus on use strict, warnings, and avoiding special variables and unusual constructs that you see in more recent Perl books. This is a very thoughtful book, with several structural techniques that I appreciated and would like to see more technical writers use. One is the comparisons to the approaches of other languages at the end of most chapters. It puts Perl's approach in a broader context and encourages thought about alternative ways to view a particular feature and implementation tradeoffs in Perl's choices. Another is the careful discussion of design approaches and possibilities during the construction of larger examples. I think there's a tendency in technical books to spend a lot of time developing the best possible implementation of something and then show that completed example. Even with a detailed analysis of its construction, this can be less useful than a broader discussion of possible approaches, including dead ends. The problem, of course, is that 16 years is a long time, even for a relatively mature programming language, and Perl has changed. There are significant improvements not only to the standard library but to Perl core functionality that have happened since this book was written. The chapter on tying, which is otherwise excellent, is badly out of date on what functionality and methods are available and is no longer a reliable guide to using that feature except for simple cases. Similar problems plague the chapter on persistence, which develops the concept from basics that most programmers reading an advanced book no longer need, and which has been rendered mostly obsolete by further developments in the Perl module ecosystem. I think the best parts of this book, the ones that cover material that I think is still relatively accurate and that are not well-covered by other resources, are the chapters on typeglobs and on XS. The typeglob discussion is both clear and informative, covering material and techniques that are used in a few core Perl modules and that I've never seen adequately addressed elsewhere. I'd subsequently picked up XS and Perl embedding the hard way: lots of trial and error and reading difficult POD documentation. I wish I'd read this book earlier, since Srinivasan does a great job of basic orientation. He doesn't go far enough for me (the book I probably wanted was Extending and Embedding Perl by Jenness and Cozens, published five years later), but I would have been up and running with basic XS much faster by starting here. If this were 1997, or even 2000, I would probably recommend this book, albeit with a few caveats. Higher Order Perl is the place you should go for discussion of closures, rather than here (although of course it didn't exist then). I wasn't fond of string eval even in 1997, and I still think it produces code that, while efficient and quite powerful, is horribly difficult to understand. And the introduction to modules is adequate but not compelling; most other introductions to object-oriented programming and module construction in Perl are better. But even discarding those chapters (and the mostly unnecessary Tk reference), there's a lot of great material here that would have been quite helpful in 2000. Unfortunately, this is not the sort of technical book that ages well, and while I did pick up some useful background knowledge and a much better understanding of typeglobs, I mostly read this book because I wanted to salvage some knowledge from a book that sat for far too long on my shelves. There's really no reason to buy it today. If you run across it in a library, there are a few chapters that are still worth reading, but by and large if you know enough Perl to know where to be careful of landmines due to changes in Perl since the book was written, you also know enough Perl to not really need this book. Rating: 5 out of 10

26 May 2013

Andrew Pollock: [life] Maker Fair 2013 virtual trip report

The Maker Faire is one of the Bay Area things that I'll really miss. Zoe had a ball last year (for weeks afterwards every outing was "Maker Faire!" regardless of what or where it was) Last year I didn't really get to cover it very well, so I ended up doing a bit of a virtual tour via the exhibitor list on their website, and so this year I thought I'd be there in spirit by doing the same thing again. Here's my picks:

24 May 2013

Wouter Verhelst: Not switching to 3.0 (quilt) just yet

I had a look at the 3.0 source formats just now. I've never been very fond of that, mainly because of the fact that it wants to store individual patches for no particularly good reason1. However, recently I found out about the --single-debian-patch option to dpkg-source, which makes the 3.0 (quilt) format behave somewhat more like the non-native 1.0 format, which is good. Unfortunately, "somewhat more" does not mean "entirely". For some weird reason, after converting the source to a 3.0 source package and running "dpkg-buildpackage", I find that suddenly my source tree is devoid of the patches that I'd applied to it. I'm sure there's another option hidden somewhere to make it not do that either, but I was quickly annoyed about it enough that I didn't care anymore. I just removed the debian/source directory entirely again, instead. Maybe I'll look into this again at some future point, but it's pretty unlikely. 1I have all my packages stored in git with a proper Vcs-Git: header; if people really want to look at individual patches, they can just use debcheckout, kthxbye.

19 May 2013

Neil Williams: pybit 1.0.0 - distributed, scalable builds direct from VCS or archives

PyBit is a distributed build system able to build packages in response to VCS commits or other triggers, across multiple architectures, multiple clients and multiple build environments with automated uploads to a nominated repository.

Support is included in 1.0.0 for building Debian packages using sbuild in response to subversion commits or changes in debian-devel-changes@lists.debian.org (by using apt as a version control handler) for any architecture and build environment which sbuild can support. There is also an example git commit template. Pybit has been designed to be fully extensible, so support for RPM or other package formats can be added as well as other version control handlers, other build environments and other architectures. Pybit is also scalable, when one type of client is struggling with the workload, another machine of the same architecture can be added to the pool to share the load. Pybit can also build a package for any number of architectures and build environments at the same time. The Pybit web interface provides an at-a-glance summary of all current builds as well as options to blacklist certain combinations, cancel and retry specific jobs and add monitor each pybit client. Current use cases include:

17 May 2013

Rob Bradford: GNOME in Moblin: Myzone

Howdy, i m sure most people are aware of the recent release of Moblin 2.0; a user experience for netbooks. I m going to write a few blog posts about how the Moblin user experience is built on the awesome technologies in the GNOME platform. So first up, let s look at the Myzone, we re starting here since this is the first thing I really worked on in the Moblin UX and i ve been able to see it through from early ideas to the 2.0 and 2.1 releases. So, deep breath, the idea behind the Myzone is to provide a springboard to things that matter to you most: your recent files and web pages you ve visited, your upcoming events and things you need to do, things that are happening on social web services and your favourite applications. Now then, that s the theory, how does it work:

Petter Reinholdtsen: How to transform a Debian based system to a Debian Edu installation

Debian Edu / Skolelinux is an operating system based on Debian intended for use in schools. It contain a turn-key solution for the computer network provided to pupils in the primary schools. It provide both the central server, network boot servers and desktop environments with heaps of educational software. The project was founded almost 12 years ago, 2001-07-02. If you want to support the project, which is in need for cash to fund developer gatherings and other project related activity, please donate some money. A topic that come up again and again on the Debian Edu mailing lists and elsewhere, is the question on how to transform a Debian or Ubuntu installation into a Debian Edu installation. It isn't very hard, and last week I wrote a script to replicate the steps done by the Debian Edu installer. The script, debian-edu-bless in the debian-edu-config package, will go through these six steps and transform an existing Debian Wheezy or Ubuntu (untested) installation into a Debian Edu Workstation:
  1. Add skolelinux related APT sources.
  2. Create /etc/debian-edu/config with the wanted configuration.
  3. Install debian-edu-install to load preseeding values and pull in our configuration.
  4. Preseed debconf database with profile setup in /etc/debian-edu/config, and run tasksel to install packages according to the profile specified in the config above, overriding some of the Debian automation machinery.
  5. Run debian-edu-cfengine-D installation to configure everything that could not be done using preseeding.
  6. Ask for a reboot to enable all the configuration changes.
There are some steps in the Debian Edu installation that can not be replicated like this. Disk partitioning and LVM setup, for example. So this script just assume there is enough disk space to install all the needed packages. The script was created to help a Debian Edu student working on setting up Raspberry Pi as a Debian Edu client, and using it he can take the existing Raspbian installation and transform it into a fully functioning Debian Edu Workstation (or Roaming Workstation, or whatever :). The default setting in the script is to create a KDE Workstation. If a LXDE based Roaming workstation is wanted instead, modify the PROFILE and DESKTOP values at the top to look like this instead:
PROFILE="Roaming-Workstation"
DESKTOP="lxde"
The script could even become useful to set up Debian Edu servers in the cloud, by starting with a virtual Debian installation at some virtual hosting service and setting up all the services on first boot.

16 May 2013

Vincent Sanders: True art selects and paraphrases, but seldom gives a verbatim translation

In my professional life I am sometimes required to provide technical support to one of our salesmen. I find this an interesting change in pace though sometimes challenging.

Occasionally I fail to clearly convey the solution we are trying to sell because of my tendency to focus on detail the customer probably does not need to understand but I think is the interesting part of the problem.

Conversely sometimes the sales people gloss over important technology choices which have a deeper impact on the overall solution. I was recently in such a situation where as part of a larger project the subject of internationalisation (you can see why it gets abbreviated to i18n) was raised.

I had little direct personal experience with handling this within a project workflow so could not give any guidance but the salesman recommended the Transifex service as he had seen it used before, indicated integration was simple and we moved onto the next topic.

Unfortunately previous experience tells me that sometime in the near future someone is going to ask me hard technical questions about i18n and possibly how to integrate Transifex into their workflow (or at least give a good estimate on the work required).
LearningBeing an engineer I have few coping strategies available for situations when I do not know how something works. The approach I best know how to employ is to give myself a practical crash course and write up what I learned...so I did.

I proceeded to do all the usual things you do when approaching something unfamiliar (wikipedia, google, colleagues etc.) and got a basic understanding of internationalisation and localisation and how they fit together.

This enabled me to understand that the Transifex workflow proposed only covered the translation part of the problem and that, as Aldrich observed in my title quote, there is an awful lot more to translation than I suspected.
PlatformsMy research indicated that there are numerous translation platforms available for both open source and commercial projects and Transifex is one of many solutions.

Although the specific platform used was Transifex most of these observations apply to all these other platforms. The main lesson though is that all platforms are special snowflakes and once a project invests effort and time into one platform it will result in the dreaded lock in. The effort to move to another platform afterwards is at least as great as the initial implementation.

It became apparent to me that all of these services, regardless of their type, boil down to a very simple data structure. They appear to be a trivial table of Key:Language:Value wrapped in a selection of tools to perform format conversions and interfaces to manipulate the data.

There may be facilities to attach additional metadata to the table such as groupings for specific sets of keys (often referred to as resources) or translator hints to provide context but the fundamental operation is common.

The pseudo workflow is:
The first three steps are almost always performed together by the uploading of a resource file containing an initial set of translations in the "default" language and due to the world being the way it is this is almost always english (some services are so poorly tested with other defaults they fail if this is not the case!)

The platforms I looked at generally follow this pattern with a greater or lesser degree of freedom in what the keys are, how the groupings into resources are made and the languages that can be used. The most common issue with these platforms (especially open source ones) is that the input convertors will only accept a very limited number of formats and often restricted to just GNU gettext PO files. This means that to use those platforms a project would have to be able to convert any internal resources into gettext translatable format.

The prevalence of the PO format pushes assumptions into almost every platform I examined, mainly that a resource is for a single language translation and that the Key (msgid in gettext terms) is the untranslated default language string in the C locale.

The Transifex service does at least allow for the Key values to be arbitrary although the resources are separated by language.

Even assuming a project uses gettext PO files and UTF-8 character encoding (and please can we kill every other character encoding and move the whole world to UTF-8) the tools to integrate the import/export into the project must be written.

A project must decide some pretty important policies, including:
These are project policy decisions and, as I discovered, just as difficult to answer as the technical challenges.

Armed with my basic understanding it was time to move on and see how the transifex platform could be integrated into a real project workflow.
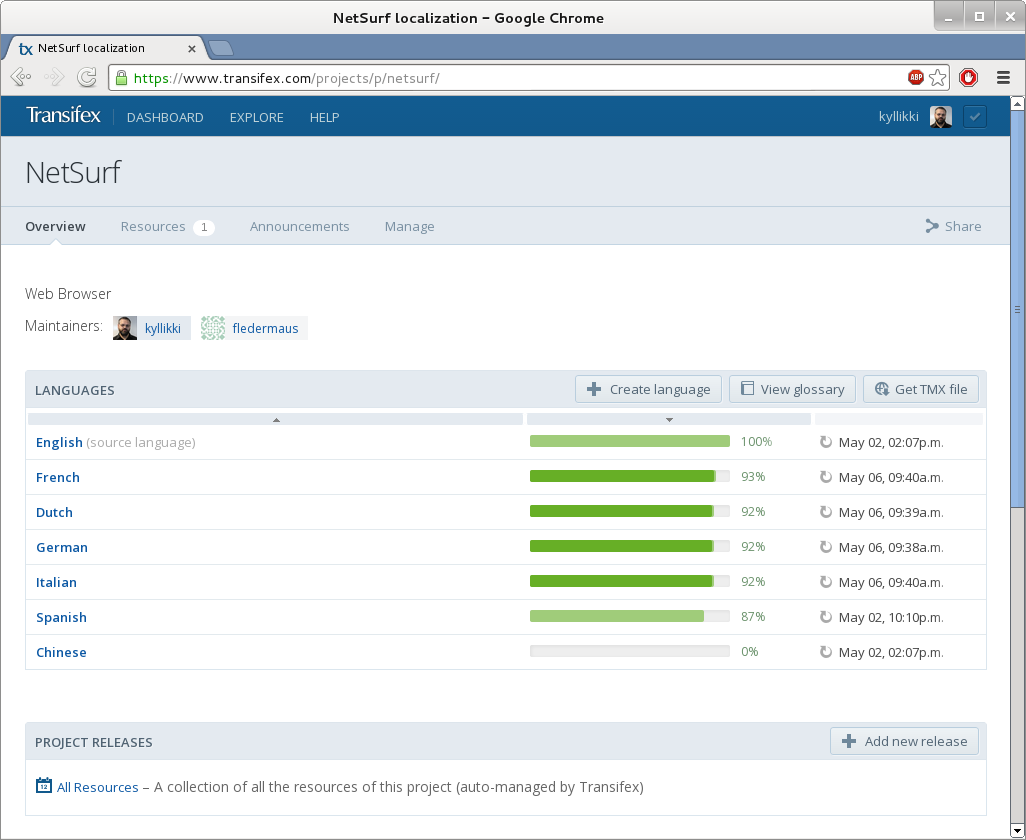
ImplementingProof of conceptMy first exercise was to take a trivial command line tool, use xgettext to generate a PO file and add the relevant libintl calls to produce gettext internationalised tool.

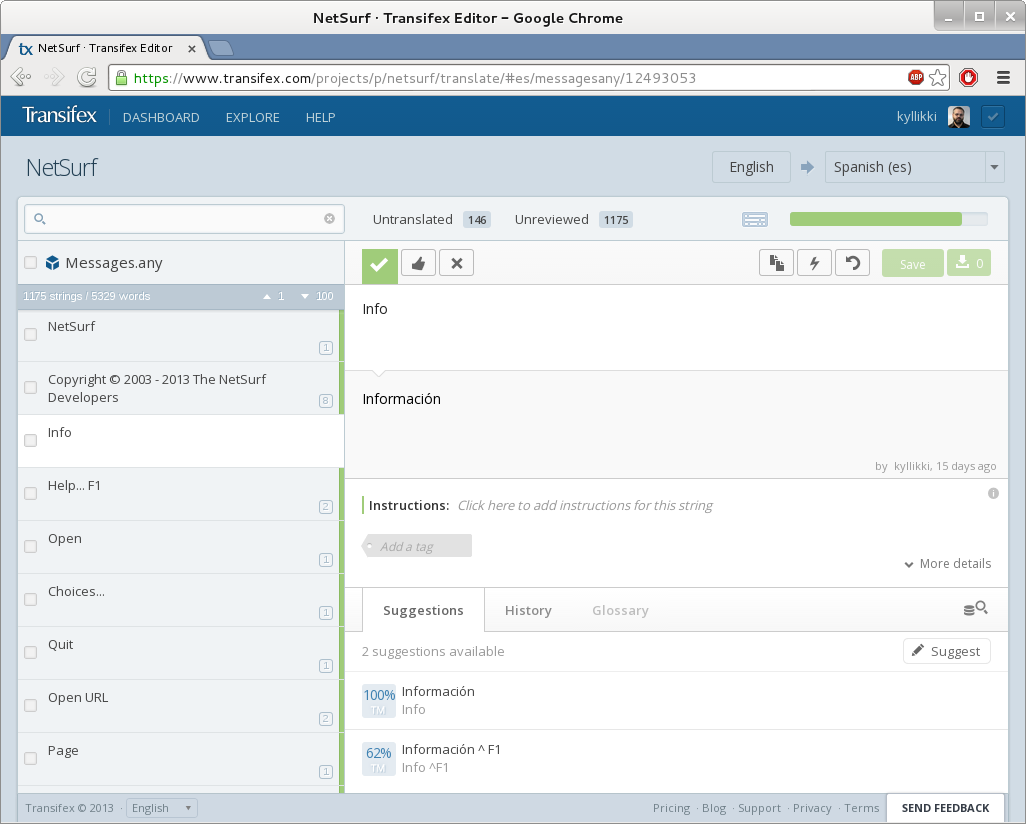
A transifex project was created and the english po file uploaded as the initial resource. A french language was added and the online editor used to provide translations for some strings. The PO resource file for french was exported and the tool executed with LANGUAGE=fr and the french translation seen.

This proved the trivial workflow was straightforward to implement. It also provided insight into the need to automate the process as the manual website operation would soon become exceptionally tedious and error prone.
Something more usefulTo get a better understanding of a real world workflow I needed a project that:
I selected the NetSurf web browser as it best fit this list.

Internally NetSurf keeps all the translated messages in a simple associative array this is serialised to an equally straightforward file named FatMessages. The file is UTF-8 encoded with keys separated from values by a colon. The Key is constrained to be ASCII characters with no colons and is structured as language.toolkit.identifier and is unique on identifier part alone.

This file is processed at build time into a simple identifier:value dictionary for each language and toolkit.

Transifex can import several resource formats similar to this, after experimenting with YAML and Android Resource format I immediately discovered a problem, the services import and export routines were somewhat buggy.

These routines coped ok with simple use cases but having more complex characters such as angle brackets and quotation marks in the translated strings would completely defeat the escaping mechanisms employed by both these formats (through entity escaping in android resource format XML is problematic anyway)

Finally the Java property file format was used (with UTF-8 encoding) which while having bugs in the import and export escaping these could at least be worked around. The existing tool that was used to process the FatMessages file was rewritten to cope with generating different output formats and a second tool to merge the java property format resources.

To create these two tools I enlisted the assistance of my colleague Vivek Dasmohapatra as his Perl language skills exceeded my own. He eventually managed to overcome the format translation issues and produce correct input and output.
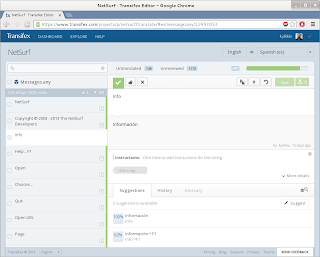
I used the Transifex platforms free open source product, created a new project and configured it for free machine translation from the Microsoft service, all of which is pretty clearly documented by Transifex.

Once this was done the messages file was split up tinto resources for the supported languages and uploaded to the transifex system.

I manually marked all the uploaded translations as "verified" and then added a few machine translations to a couple of languages. I also created spanish as a new language and machine translated most of the keys.

The resources for each language were then downloaded and merged and the resulting FatMessages file checked for differences and verified only the changes I expected appeared.

I quickly determined that manually downloading the language resources every time was not going to work with any form of automation, so I wrote a perl script to retrieve the resources automatically (might be useful for other projects too).

Once these tools were written and integrated into the build system I could finally make an evaluation as to how successful this exercise had been.
ConclusionsThe main things I learned from this investigation were:

Overall I think the final observation has to be that integrating translation services is not a straightforward operation and each project has unique challenges and requirements which reduce the existing platforms to compromise solutions.

Russ Allbery: Review: Asimov's, July 2011

Review: Asimov's Science Fiction, July 2011
Editor: Sheila Williams
Issue: Volume 35, No. 7
ISSN: 1065-2698
Pages: 112
Williams's editorial is a mildly interesting piece about story titles. Silverberg's column is a more interesting (and rather convincing) rebuttal of the joke that fiction authors are "professional liars," combined with an examination of a fake and fantastic 14th travelogue that (at least in Silverberg's telling) was widely believed at the time. The precis of Silverberg's argument is that lying requires an intent to deceive, which is a property of deceptive memoir writers but not of fiction authors. Di Filippo's review column, as usual, is devoted almost entirely to esoterica, although I was moderately interested to hear of Stableford's continued work on translating early French SF. None of it seems compelling enough to go buy, but good translations of early works seem like a good thing to have in the world. "Day 29" by Chris Beckett: The conceit of this novelette is an interstellar travel system akin to a transporter that allows near-instantaneous travel between worlds. The drawback is that all memories from somewhere between 40 and 29 days before transit up until transit are wiped. The progatonist is a data analyst who is about to travel, and therefore by agency rule is required to stop doing work on day 40 before transmission since he can't be held legally liable for anything he has no recollection of doing. (I would like to say that I find this implausible, since one could always keep records, but it's exactly the sort of ass-covering regulation that a human resources department would come up with.) The premise is quite interesting: what do you do during that period that you're going to forget? Beckett wisely mixes Stephen's current waiting period on the colony world with his diary of his original waiting period on Earth the first time he went through the transmission process, and the latter adds greatly to the reader's appreciation of the weirdness of the forgotten interval. Unfortunately, this is a story more about psychological exploration than about plot, and Stephen just isn't very interesting. The telepathic but possibly nonsentient aliens add weirdness but not much else, and the ending of the story provided little sense of closure or conclusion for me. A good idea, but not the execution I wanted. (5) "Pug" by Theodora Goss: Since I grew up with a pug, I have a soft spot for a story featuring one; sadly, though, this story has insufficient pug in it. This is a quiet fantasy (Asimov's calls it SF, presumably on the basis of parallel worlds and a hypothesized scientific explanation, but it reads like fantasy to me) featuring Victorian girls, including one with a bad heart. They discover a hidden door to other versions of their world and do some minor exploration. There's little or nothing in the way of plot; the story is more of an attempt to capture a mood. It's mildly diverting, but I wish it had gone somewhere more substantial. (5) "Dunyon" by Kristine Kathryn Rusch: A Rusch story is often the highlight of an issue, and this is no exception. The protagonist is the owner of a bar in a space station that's become a combination of a refugee camp and a slum. War and chaos have created desperate people, most of whom are attempting to find some way to resources and get out of the bottom of society. The story is about a rumor: a mythical system named Dunyon that's safe and far away. And it's about how people react to that rumor. There's nothing particularly surprising about the direction the story goes (it's fairly short), but Rusch is always a good storyteller. (7) "The Music of the Sphere" by Norman Spinrad: I've had mixed feelings about Spinrad's fiction (and some of his essays), but I liked this story, despite its implausibility. It's set in the near future, featuring an expert in cetaceans and dolphin perception and a composer obsessed with both loud music and classical musical style. Just from that description, you can probably predict much of the story, but I thought it had some neat ideas about dolphins, whales, and alternate perception and aesthetics. (Note: neat, not necessarily biologically plausible.) Enjoyable. (6) "Bring on the Rain" by Josh Roseman: In a change of pace from the rest of the issue, this is a post-apocalyptic story of caravans of wheeled ships traversing a scorched and ruined landscape in search of weather systems and rain. The feel is of an inverted Waterworld, but with more emphasis on military tactics and cooperating fleets. The transposition of fleet maneuvers to huge ground vehicles adds some extra fun. The plot has little to do with the background and is a fairly stock military adventure scenario, but it's reasonably well-told. The story feels like an excerpt from a larger military-SF-inspired adventure, but the length keeps the quantity of tactics and maneuvering below the threshold where I would get bored. (6) "Twelvers" by Leah Cypess: This is a sharp and occasionally mean story of adolescent cruelty and alienation. Darla is a "twelver," a child who was carried an extra three months in the womb using newly-invented medical technology because of a belief in the advantages this would bring in later life. Unfortunately for all those who used this technique, what it also brought was a preternatural calm and an unusual reaction to emotions. Darla finds it almost impossible to get upset at anything, and that, of course, prompts the cruelty and abuse of other children. Most of the story is a description of that abuse, leading up to Darla stumbling into a nasty solution to her immediate problem. It's all very believable (well, apart from the motivating biology), but I didn't enjoy reading about it, and I'm certainly not convinced that the ending will lead to anything good. (5) "The Messenger" by Bruce McAllister: This is a very short time travel story, where time travel is used to try to unwind old family pain. This world follows the unalterable history model: no changes to the past are possible, and anything you do in the past has already happened. The mechanics are mostly avoided. Instead, McAllister concentrates on his mother, his father, and their complex relationship. I would have needed a bit more background on the characters to care enough about them for the story to be fully effective, but while the heartstring-pulling is kind of obvious, it's still a solid story. (6) "The Copenhagen Interpretation" by Paul Cornell: This is the most ingenious of the stories in this issue. It's set in a future world that extends what seemed to me to be pre-World-War-I great power politics, although there may be a hint of the Cold War. Great nations have reached a careful balance of power, and spies and secret services work to sustain that balance. The progatonist is one of those agents, making use of advanced technology like space folds in the service of a cause that he doesn't entirely believe in. Cornell mixes in mental conditioning, artificial people, space travel, and even aliens (maybe) in a taut thriller plot that, for me, gained a great deal from the unexplained strangeness of its background. If you like diving into the deep end and following a fast-moving plot against a background of strangeness, this is the sort of SF you'll enjoy. (7) Rating: 6 out of 10

15 May 2013

Bastian Venthur: How to get the most precise time, comparable between processes in Python?

Let s consider the following scenario: I have two Python processes receiving the same events and I have to measure the delay between when process A received the event and when process B received it, as precisely as possible (i.e. less than 1ms). Using Python 2.7 and a Unix system you can use the time.time method which provides the time in seconds since Epoch and has a typical resolution of a fraction of a ms on Unix. You can use it on different processes and still compare the results, since both processes receive the time since Epoch, a defined and fixed time in the past. On Windows time.time also provides the time since Epoch, but the resolution is in the range of 10ms, which is not suitable for my application. There is also time.clock which is super precise on Windows, and much less precise on Unix. The mayor drawback is that it returns the time since the process started or since the first call of time.clock within that processes. This means you cannot compare the results of time.clock between two processes as they are not calibrated to a common t-zero. I had high hopes for Python 3.3 where the time module was revamped and I was reading about time.monotonic and time.perf_counter. Especially time.perf_counter looked like it would suit my needs as the documentation said it provides the highest available resolution for the system and was system-wide , in contrast to for example the new time.process_time which was process_wide . Unfortunately it turned out that time.perf_counter acts similar to time.clock on Python 2.7 as it provides you with the time since the process started or the first time the method was called within the process. The results of time.monotonic are comparable between processes, but again not precise enough on Windows. Here is a small script which demonstrates how the times provided by time.clock and time.perf_counter are not comparable between processes. It starts two processes and lets both of them print out the output of the timer to stdout. In the output the times should be monotonically increasing. Since I let process 2 sleep for one second before calling the timer method for the first time, the output of this process is usually one second smaller when using time.clock or time.perf_counter.
#!/usr/bin/env python
from multiprocessing import Process
import time
timers = ['clock', 'time', 'monotonic', 'perf_counter']
def proc(timer):
    timer = getattr(time, timer)
    time.sleep(1)
    for i in range(3):
        print('P2  time '.format(time=timer()))
        time.sleep(1)
if __name__ == '__main__':
    for t in timers:
        print("Using  timer ".format(timer=t))
        p = Process(target=proc, args=(t,))
        timer = getattr(time, t)
        p.start()
        for i in range(3):
            print('P1  time '.format(time=timer()))
            time.sleep(1)
        p.join()
The result when running on Windows with Python 3.3:
$ python timertest.py
Using clock
P1 6.146032526480321e-06
P1 0.9926582847820045
P2 2.9612702173041547e-05
P1 1.9941743992602412
P2 1.0008579302676737
P2 2.0022709590185346
Using time
P1 1368614235.509732
P1 1368614236.511172
P2 1368614236.601301
P1 1368614237.512612
P2 1368614237.602741
P2 1368614238.604181
Using monotonic
P1 484.636
P1 485.63800000000003
P2 485.738
P1 486.639
P2 486.73900000000003
P2 487.741
Using perf_counter
P1 12.390910576623565
P1 13.39050745276285
P2 7.542858100680394e-06
P1 14.39190763071843
P2 1.0014012954160376
P2 2.0041399116368144
So as far as I see it, there is no way of getting comparable times between two processes on Windows with more precision than 10ms. Is that correct or am I missing something?

Daniel Kahn Gillmor: OpenPGP User ID Comments considered harmful

Most OpenPGP User IDs look like this:

Jane Q. Public <jane@example.org>
This is clean, clear, and unambiguous. However, some tools (gpg, enigmail among others) ask the user to provide a "Comment:" field when they are choosing a new User ID (e.g. when making a new key). These UI prompts are evil. The savvy user knows to avoid entering anything in this field, so that they can end up with a User ID like the one above. The user who provides something here (perhaps even something inconsequential like "I like strawberries", due to not being sure what should go in this little box) will instead end up with a User ID like:
Jane Q. Public (I like strawberries) <jane@example.org>
This is bad. This means that Jane is asking the people who certify her key+userid to certify whether she actually likes strawberries (how could they know? what if she changes her mind? should they revoke their certifications?) and anywhere that she is referred to by name will include this mention of strawberries. This is not Jane's identity, and it doesn't belong in an OpenPGP User ID packet. Furthermore, since User IDs are atomic, if Jane wants to change the comment field (but leave her name and e-mail address the same), she will instead need to create a new User ID, publish it, get everyone who has certified her old key+userid to certify the key+newuserid, and then revoke the old one. It is difficult already to help people understand and participate in the certification network that forms that backbone of OpenPGP's so-called "web of trust". These bogus comment fields make an already-difficult task harder. And all because of strawberries! Tools like enigmail and gpg should not expose the "Comment:" field to users who are generating keys or choosing new User IDs. If they feel it absolutely must be present for some weird corner case that 0.1% of their users will have, they could require that the user enters some sort of "expert mode" before prompting the user to do something that is likely to be a mistake. There is almost no legitimate reason for anyone to use this field. Let's go through some examples of this people use, taken from some examples i have lying around (identifying marks have been changed to protect the innocent who were duped by this bad UI choice, but you can probably find them on the public keyserver network if you want to hunt around):
domain repetition
John Q. Public (Debian) <johnqpublic@debian.org>
We know you're with debian already from the @debian.org address. If this is in contrast to your other address (johnqpublic@example.org) so that people know where to send you debian-related e-mail, this is still not necessary. Lest you think i'm just calling out debian developers, people with @ubuntu.com addresses and (Ubuntu) comments (as well as @example.edu addresses and (Example University) comments and @example.com addresses and (Example Corp) comments) are out there too.
nicknames already evident
John Q. Public (Johnny) <johnqpublic@example.net>
John Q. Public (wackydude) <wackydude@example.net>
Again, the information these comments are providing offers no clear disambiguation from the info already contained in the name and e-mail address, and just muddies the water about what the people who certify this identity should actually be trying to verify before they make their certification.
"Work"
John Q. Public (Work) <johnqpublic@example.com>
if John's correspondents know that he works for Example Corp, then "Work" isn't helpful to them, because they already know this as the address that they're writing to him with. If they don't know that, then they probably aren't writing to him at work, so they don't need this comment either. The same problem appears (for example) with literal comments of (School) next to their @example.edu address.
This is my nth try at this crazy system!
John Q. Public (This is my second key) <johnqpublic@example.com>
John Q. Public (This is my primary key) <johnqpublic@example.com>
John Q. Public (No wait really use this one) <johnqpublic@example.com>
OpenPGP is confusing, and it can be tricky to get it right. We all know :) This is still not part of John's identity. If you want to designate a key as your preferred key, keep it up-to-date, get people to certify it, and revoke or expire your old keys. People who care can look at the timestamps on your keys and tell which ones are the most recent ones. You do have a revocation certificate for your key handy just in case you lose it, right?
Don't use this key
John Q. Public (Old key, do not use) <johnqpublic@example.com>
John Q. Public (Please only use this through September 2004) <johnqpublic@example.com>
This kind of sentiment is better expressed by revoking the key in question or setting an expiration time on the key or User ID self-sig directly. This sentiment is not part of John's identity, and shouldn't be included as though it were.
"none"
John Q. Public (none) <johnqpublic@example.com>
sigh. This is clearly someone getting mixed up by the UI.
I use strong crypto!
John Q. Public (3092 bits of RSA) <johnqpublic@example.com>
This comment refers to the strength of the key material, or the algorithms preferred by the user. Since the User ID is associated with the key material already, people who care about this information can get it from the key directly. This is also not part of the user's actual identity.
"no comment"
John Q. Public (no comment) <johnqpublic@example.com>
This is actually not uncommon (some keyservers reply "too many matches!"). It shows that the user is witty and can think on their feet (at least once), but it is still not part of the user's identity.
But wait (i hear you say)! I have a special case that actually is a legitimate use of the comment field that cannot be expressed in OpenPGP in any other way! I'm sure that such cases exist. I've even seen one or two of them. The fact that one or two cases exist does not excuse the fact that that overwhelming majority of these comments in OpenPGP User IDs are a mistake, caused only by bad UI design that prompts people to put something (anything!) in the empty box (or on the command prompt, depending on your preference). And this mistake is one of the thousand papercuts that inhibits the robust growth of the OpenPGP certification network that some people call the "web of trust". Let's avoid them so we can focus on the other 999 papercuts. Please don't use comments in your OpenPGP User ID. And if you make a user interface for OpenPGP that prompts the user to decide on a new User ID, please don't include a prompt for "Comment" unless the user has already certified that they are really and truly a special special snowflake. Thanks!Tags: openpgp, ui

14 May 2013

Steve Kemp: Some good, some bad

Today my main machine was down for about 8 hours. Oops. That meant when I got home, after a long and dull train journey, I received a bunch of mails from various hosts each saying: Slaughter is my sysadmin utility which pulls policies/recipies from a central location and applies them to the local host. Slaughter has a bunch of different transports, which are the means by which policies and files are transferred from the remote "central host" to the local machine. Since git is supported I've now switched my policies to be fetched from the master github repository. This means: In other news I've fettled with lumail a bit this week, but I'm basically doing nothing until I've pondered my way out of the hole I've dug myself into. Like mutt lumail has the notion of "limiting" the display of things: Unfortunately the latter has caused an annoying, and anticipated, failure case. If you open a folder and cause it to only show unread messages all looks good. Until you read a message. At which point it is no longer allowed to be displayed, so it disappears. Since you were reading a message the next one is opened instead. WHich then becomes marked as read, and no longer should be displayed, because we've said "show me new/unread-only messages please". The net result is if you show only unread messages and make the mistake of reading one .. you quickly cycle through reading all of them, and are left with an empty display. As each message in turn is opened, read, and marked as non-new. There are solutions, one of which I documented on the issue. But this has a bad side-effect that message navigation is suddenly complicated in ways that are annoying. For the moment I'm mulling the problem over and I will only make trivial cleanup changes until I've got my head back in the game and a good solution that won't cause me more pain.

13 May 2013

Jan Wagner: 500 OOPS: vsftpd: refusing to run with writable root inside chroot ()

If you updated recently your system to Debian wheezy and you are using vsftpd with enabled chrooted local users ...
[~] # grep -i  ^chroot_local_user=yes /etc/vsftpd.conf   tail -1
chroot_local_user=YES
... you maybe faced with the following problem:
500 OOPS: vsftpd: refusing to run with writable root inside chroot()
Login failed.
This problem raised already in Bug #656900 and it was fixed by adjusting the documentation. Beside that there maybe configurations you want to relax such a strict check. Unfortunately this feature was implemented in version 3.0.0 which is not part of Debian wheezy:
- Add new config setting "allow_writeable_chroot" to help people in a bit of
a spot with the v2.3.5 defensive change. Only applies to non-anonymous.
The Frontier Group created a patched package of vsftpd for Ubuntu. After reviewing the patch we decided to also create a Debian package for wheezy. You can easily install the package by the following sniplet:
echo "deb http://ftp.cyconet.org/debian wheezy-updates main non-free contrib" >> \
/etc/apt/sources.list.d/wheezy-updates.cyconet.list; \
aptitude update; aptitude install -t wheezy-updates debian-cyconet-archive-keyring vsftpd && \
echo "allow_writeable_chroot=YES" >> /etc/vsftpd.conf && /etc/init.d/vsftpd restart
Updates, in case of bugfixes in Debian wheezy, should be also available through this distribution channel.

12 May 2013

Matthias Klumpp: PackageKit, AppStream and Listaller A status report

I was asked by some people to write a status report about the whole PK/AS/LI stuff sorry guys that it took so much time to write it ;-) . PackageKit (PackageKit is an abstraction layer for package-management systems, allowing applications to access the package-manager using simple DBus calls)Package (with list) PackageKit is an incredibly successful project. With the 0.8.x series, it received many performance improvements, and has now the same speed on my computer than the distribution s native tools. PackageKit is used in almost all major Linux distributions, except for Ubuntu[1]. But even Ubuntu has written some compatibility layer, so most calls to PackageKit will work. The only major distro where PackageKit is currently not available, seems to be Gentoo (and I am not sure about the shape of the Gentoo PackageKit backend too). Debian Wheezy includes PackageKit by default, and in Jessy we are going to replace some distribution-specific tools with PackageKit frontends (mostly the old and unmaintained update-notifier and Software-Updater no worries, we are not going for a Synaptic replacement ;-) (currently this won t be possible with PK anyway)) Unfortunately, some PackageKit backends are still not adjusted for the 0.8.x API and are only running on 0.7.x. This is bad, since 0.8.x is a huge step forward for PackageKit. But the situation is slowly improving, with the latest OpenSUSE release, the Zypper backend is now available on 0.8.x too. Being able to run a PackageKit from the 0.8.x series is a requirement for both AppStream and Listaller. AppStream (AppStream is a cross-distro effort for building Software-Center-like Software Center Logoapplications. It contains stuff like a screenshot-service, ratings&reviews etc. The most important component is a Xapian database, storing information about all available applications in the distribution s repositories. The Xapian DB is distro-agnostik, but distributors need to provide data to fill it. AppStream offers an application-centric way to look at a package database) The AppStream side doesn t look incredibly great, but the situation is improving. As far as I know, OpenSUSE is shipping AppStream XML to generate the database. Ubuntu ships the desktop-files, and I am working on AppStream support in Debian s Archive Kit. On the Fedora side, negotiations with the infrastructure-team are still going on. I haven t heard anything from Mageia and other AppStream participants yet. Unfortunately, at least for OpenSUSE, the AppStream efforts seem to be stalled, due to people having moved to different tasks. But efforts to add the remaining missing things exist. On the software side, Apper (KDE PackageKit frontend) has full support for AppStream. Apper just needs to be compiled with some extra flags to make it use the AppStream database. On the GNOME-side, GNOME-Software is being developed. The tool will make use of the AppStream database, on distributions where it is available. Also, a Software-Center for Elementary and other GTK+-based desktops is being developed, which is based on AppStream (already quite usable!). Using the Ubuntu Software Center on not-Ubuntu-based distributions ist still not much fun, but with the AppStream database available and a working PackageKit 0.8.x with a backend which supports parallel transactions, it is possible to use it. On the infrastructure side: I recently landed some patches in AppStream-Core, which will improve the search function a lot. AppStream-Core contains all tools necessary to generate the AppStream database. It also contains libappstream, a GObject-based library which can be used to access the AppStream database. Also, we discuss dropping PackageKit s internal desktop-file-cache in favour of using the AppStream database. If we do that, we will also add software descriptions to the AppStream db, to improve search results and to speed up search for applications. Because we have to deprecate API for that, I expect this change to happen with PackageKit 0.9.x. As soon as the Freedesktop-Wiki is alive again and my account is re-enabled, I will create compatibility-list, showing which distribution implements what of the PK/AS/LI stuff, especially focusing on components needed for AppStream. Only a few distributions package AppStream-Core so far. Although it is beta-software, creating packages for it and shipping the required data to generate the AppStream database would be a very huge step forward. Listaller (Listaller is a cross-distro 3rd-party software installer, which integrates into Listaller-LogoPackageKit and AppStream. It allows installing 3rd-party applications, which are not part of the distributor s repositories, using standard tools used also for native-package handling. Everything which uses PackageKit can make use of Listaller packages too. Listaller also allows sandboxing of new applications, and uses an AppDir-like approach for installing software.) Listaller is currently undergoing it s last transition before a release with stable API and specifications can be made. Dependency solving will be improved a lot during the current release-cycle, making it less powerful, but working on all distributions instead. (Fedora always had an advantage in dependency-solving, due to RPM providing more package metadata for Listaller to use) This change was delayed due to discussing a possible use of ZeroInstall-feeds to provide missing dependencies with the ZeroInstall team. We did not come to a conclusion about extending the XML, so Listaller will contain an own format to define a dependency, which can reference a ZeroInstall feed. That should be a good solution for everyone. All these changes will result in IPK1.2, a new version of the IPK spec with small changes in the pkoptions file syntax and huge changes in dependency-handling. The new code is slowly stabilizing in a separate branch, and will soon be merged into master. The next Listaller release will be the last one of the 0.5.x series, we will start 0.6.x then. KDE currently has support for Listaller through Apper, which is enabled on a few distributions. In GNOME, optional Listaller support is being developed and will be available in one of the upcoming releases. Currently, to my knowledge, only a few distributions package Listaller. This should improve, so it is easier for application developers to deploy IPK packages. The upcoming changes in KDE and GNOME to build stable developer platforms will help Listaller a lot in finding matching dependencies, and for stuff which only depends on one software frameworks, installations should be a matter of seconds. As you can see, lots of things are happening, and there is improvement in all components related to installing and presenting software on Linux machines. However, all these projects have a severe lack of manpower, especially AppStream and Listaller have the lowest number of developers working on the tools (at time, only two active developers). This is the main reason for the slow development. But I am confident that we will have something shipped in the next distribution releases. At least AppStream should be ready then. [1]: I don t blame Ubuntu for that during the time they wrote an own solution, PackageKit did not have all the required features. (This situation has changed now, fortunately.) NOTE: I might extend this post with feedback from the different distributions, as soon as I get it.

8 May 2013

Ben Hutchings: Warning: Debian 7.0 'wheezy' on VIA C3 and Cyrix III systems

The 'longhaul' module may cause instability or even hardware damage on some systems. Unfortunately, it is now being auto-loaded on all systems with a compatible CPU (VIA C3 or Cyrix III). See bug #707047. Before upgrading one of these systems to Debian 7.0 'wheezy', if you do not currently use the 'longhaul' module, you should blacklist it by creating e.g. /etc/modprobe.d/blacklist-longhaul.conf containing the line:

  blacklist longhaul
I would advise against attempting a fresh installation on these systems at present.

7 May 2013

Matthew Garrett: A short introduction to TPMs

I've been working on TPMs lately. It turns out that they're moderately awful, but what's significantly more awful is basically all the existing documentation. So here's some of what I've learned, presented in the hope that it saves someone else some amount of misery.
What is a TPM?TPMs are devices that adhere to the Trusted Computing Group's Trusted Platform Module specification. They're typically microcontrollers[1] with a small amount of flash, and attached via either i2c (on embedded devices) or LPC[2] (on PCs). While designed for performing cryptographic tasks, TPMs are not cryptographic accelerators - in almost all situations, carrying out any TPM operations on the CPU instead would be massively faster[3]. So why use a TPM at all?
Keeping secrets with a TPMTPMs can encrypt and decrypt things. They're not terribly fast at doing so, but they have one significant benefit over doing it on the CPU - they can do it with keys that are tied to the TPM. All TPMs have something called a Storage Root Key (or SRK) that's generated when the TPM is initially configured. You can ask the TPM to generate a new keypair, and it'll do so, encrypt them with the SRK (or another key descended from the SRK) and hand it back to you. Other than the SRK (and another key called the Endorsement Key, which we'll get back to later), these keys aren't actually kept on the TPM - the running OS stores them on disk. If the OS wants to encrypt or decrypt something, it loads the key into the TPM and asks it to perform the desired operation. The TPM decrypts the key and then goes to work on the data. For small quantities of data, the secret can even be stored in the TPM's nvram rather than on disk.

All of this means that the keys are tied to a system, which is great for security. An attacker can't obtain the decrypted keys, even if they have a keylogger and full access to your filesystem. If I encrypt my laptop's drive and then encrypt the decryption key with the TPM, stealing my drive won't help even if you have my passphrase - any other TPM simply doesn't have the keys necessary to give you access.

That's fine for keys which are system specific, but what about keys that I might want to use on multiple systems, or keys that I want to carry on using when I need to replace my hardware? Keys can optionally be flagged as migratable, which makes it possible to export them from the TPM and import them to another TPM. This seems like it defeats most of the benefits, but there's a couple of features that improve security here. The first is that you need the TPM ownership password, which is something that's set during initial TPM setup and then not usually used afterwards. An attacker would need to obtain this somehow. The other is that you can set limits on migration when you initially import the key. In this scenario the TPM will only be willing to export the key by encrypting it with a pre-configured public key. If the private half is kept offline, an attacker is still unable to obtain a decrypted copy of the key.
So I just replace the OS with one that steals the secret, right?Say my root filesystem is encrypted with a secret that's stored on the TPM. An attacker can replace my kernel with one that grabs that secret once the TPM's released it. How can I avoid that?

TPMs have a series of Platform Configuration Registers (PCRs) that are used to record system state. These all start off programmed to zero, but applications can extend them at runtime by writing a sha1 hash into them. The new hash is concatenated to the existing PCR value and another sha1 calculated, and then this value is stored in the PCR. The firmware hashes itself and various option ROMs and adds those values to some PCRs, and then grabs the bootloader and hashes that. The bootloader then hashes its configuration and the files it reads before executing them.

This chain of trust means that you can verify that no prior system component has been modified. If an attacker modifies the bootloader then the firmware will calculate a different hash value, and there's no way for the attacker to force that back to the original value. Changing the kernel or the initrd will result in the same problem. Other than replacing the very low level firmware code that controls the root of trust, there's no way an attacker can replace any fundamental system components without changing the hash values.

TPMs support using these hash values to decide whether or not to perform a decryption operation. If an attacker replaces the initrd, the PCRs won't match and the TPM will simply refuse to hand over the secret. You can actually see this in use on Windows devices using Bitlocker - if you do anything that would change the PCR state (like booting into recovery mode), the TPM won't hand over the key and Bitlocker has to prompt for a recovery key. Choosing which PCRs to care about is something of a balancing act. Firmware configuration is typically hashed into PCR 1, so changing any firmware configuration options will change it. If PCR 1 is listed as one of the values that must match in order to release the secret, changing any firmware options will prevent the secret from being released. That's probably overkill. On the other hand, PCR 0 will normally contain the firmware hash itself. Including this means that the user will need to recover after updating their firmware, but failing to include it means that an attacker can subvert the system by replacing the firmware.
What about using TPMs for DRM?In theory you could populate TPMs with DRM keys for media playback, and seal them such that the hardware wouldn't hand them over. In practice this is probably too easily subverted or too user-hostile - changing default boot order in your firmware would result in validation failing, and permitting that would allow fairly straightforward subverted boot processes. You really need a finer grained policy management approach, and that's something that the TPM itself can't support.

This is where Remote Attestation comes in. Rather than keep any secrets on the local TPM, the TPM can assert to a remote site that the system is in a specific state. The remote site can then make a policy determination based on multiple factors and decide whether or not to hand over session decryption keys. The idea here is fairly straightforward. The remote site sends a nonce and a list of PCRs. The TPM generates a blob with the requested PCR values, sticks the nonce on, encrypts it and sends it back to the remote site. The remote site verifies that the reply was encrypted with an actual TPM key, makes sure that the nonce matches and then makes a policy determination based on the PCR state.

But hold on. How does the remote site know that the reply was encrypted with an actual TPM? When TPMs are built, they have something called an Endorsement Key (EK) flashed into them. The idea is that the only way to have a valid EK is to have a TPM, and that the TPM will never release this key to anything else. There's a couple of problems here. The first is that proving you have a valid EK to a remote site involves having a chain of trust between the EK and some globally trusted third party. Most TPMs don't have this - the only ones I know of that do are recent Infineon and STMicro parts. The second is that TPMs only have a single EK, and so any site performing remote attestation can cross-correlate you with any other site. That's a pretty significant privacy concern.

There's a theoretical solution to the privacy issue. TPMs never actually sign PCR quotes with the EK. Instead, TPMs can generate something called an Attestation Identity Key (AIK) and sign it with the EK. The OS can then provide this to a site called a PrivacyCA, which verifies that the AIK is signed by a real EK (and hence a real TPM). When a third party site requests remote attestation, the TPM signs the PCRs with the AIK and the third party site asks the PrivacyCA whether the AIK is real. You can have as many AIKs as you want, so you can provide each service with a different AIK.

As long as the PrivacyCA only keeps track of whether an AIK is valid and not which EK it was signed with, this avoids the privacy concerns - nobody would be able to tell that multiple AIKs came from the same TPM. On the other hand, it makes any PrivacyCA a pretty attractive target. Compromising one would not only allow you to fake up any remote attestation requests, it would let you violate user privacy expectations by seeing that (say) the TPM being used to attest to HolyScriptureVideos.com was also being used to attest to DegradingPornographyInvolvingAnimals.com.

Perhaps unsurprisingly (given the associated liability concerns), there's no public and trusted PrivacyCAs yet, and even if they were (a) many computers are still being sold without TPMs and (b) even those with TPMs often don't have the EK certificate that would be required to make remote attestation possible. So while remote attestation could theoretically be used to impose DRM in a way that would require you to be running a specific OS, practical concerns make it pretty difficult for anyone to deploy that at any point in the near future.
Is this just limited to early OS components?Nope. The Linux kernel has support for measuring each binary run or each module loaded and extending PCRs accordingly. This makes it possible to ensure that the running binaries haven't been modified on disk. There's not a lot of distribution infrastructure for setting this up, but in theory a distribution could deploy an entirely signed userspace and allow the user to opt into only executing correctly signed binaries. Things get more interesting when you add interpreted scripts to the mix, so there's still plenty of work to do there.
So what can I actually use a TPM for?Drive encryption is probably the best example (Bitlocker does it on Windows, and there's a LUKS-based implementation for Linux here) - while in theory you could do things like use your TPM as a factor in two-factor authentication or tie your GPG key to it, there's not a lot of existing infrastructure for handling all of that. For the majority of people, the most useful feature of the TPM is probably the random number generator. rngd has support for pulling numbers out of it and stashing them in /dev/random, and it's probably worth doing that unless you have an Ivy Bridge or other CPU with an RNG.

Things get more interesting in more niche cases. Corporations can bind VPN keys to corporate machines, making it possible to impose varying security policies. Intel use the TPM as part of their anti-theft technology on education-oriented devices like the Classmate. And in the cloud, projects like Trusted Computing Pools use remote attestation to verify that compute nodes are in a known good state before scheduling jobs on them.
Is there a threat to freedom?At the moment, probably not. The lack of any workable general purpose remote attestation makes it difficult for anyone to impose TPM-based restrictions on users, and any local code is obviously under the user's control - got a program that wants to read the PCR state before letting you do something? LD_PRELOAD something that gives it the desired response, or hack it so it ignores failure. It's just far too easy to circumvent.
Summary?TPMs are useful for some very domain-specific applications, drive encryption and random number generation. The current state of technology doesn't make them useful for practical limitations of end-user freedom.

[1] Ranging from 8-bit things that are better suited to driving washing machines, up to full ARM cores
[2] "Low Pin Count", basically ISA without the slots.
[3] Loading a key and decrypting a 5 byte payload takes 1.5 seconds on my laptop's TPM.

comment count unavailable comments

4 May 2013

Ian Campbell: Taking over qcontrol upstream, releasing qcontrol 0.5.0

Taking over Qcontrol upstream When I took over the qcontrol package in Debian, back in October 2012, I was aware that upstream hadn't been active for quite a while (since late 2009). I figured that would be OK since the software was pretty simple and pretty much feature complete. Nevertheless since I've been maintaining the package I've had a small number of wishlist bugs (many with patches, thanks guys!) which are really upstream issues. While I could carry them as patches in the Debian package they would really be better taken care of by an upstream. With that in mind I mailed the previous upstream (and original author) Byron Bradley back in February to ask if he would mind if I took over as upstream. Unfortunately I haven't yet heard back, given how long upstream has been inactive for this isn't terribly surprising so having waited several months I have decided to just go ahead and take over upstream development. Thanks Byron for all your work on the project, I hope you don't mind me taking over. Since it is unlikely that I will be able to access the old website or Subversion repository I have converted the repository to git and uploaded it to gitorious: I don't expect I'll be doing an awful lot of proactive upstream development but at least now I have a hat I can put on when someone reports an "upstream" issue against qcontrol and somewhere which can accept upstream patches from myself and others. I'm still deciding what to do about a website etc. I may just enable the gitorious wiki or I may setup an ikiwiki software site type setup, which has the advantage of being a little more flexible and providing a neat way of dealing with bug reports without being too much overhead to setup up. In the meantime its been almost 5 years since the last release, so... New Release: qcontrol 0.5.0 This is a rollup of some changes which were made in the old upstream SVN repository but never released and some patches which had been made in the Debian packaging. What's here corresponds to the Debian 0.4.2+svn-r40-3 package. The 0.4.2 release was untagged in SVN, but corresponds to r14, new stuff since then includes: As well as the change of maintainer I think the addition of the daemon mode warrants the bump to 0.5.0. Get the new release from git or http://www.hellion.org.uk/qcontrol/releases/0.5.0/.

Russ Allbery: Review: Democracy at Work

Review: Democracy at Work, by Richard Wolff
Publisher: Haymarket
Copyright: 2012
ISBN: 1-60846-247-1
Format: Kindle
Pages: 220
I've been reading (mostly on-line) and thinking quite a bit lately about workplace governance models, economic structure, and why the current organization of the US workplace bothers me so intensely, partly triggered by reading John Kenneth Galbraith's The Affluent Society. The economic monoculture has made that process particularly frustrating. It's rare to find a discussion, even in the context of organizational strategies that are considered radical, that avoids the standard frame of productivity and business value. Most discussion is long on tactics and short on strategy and examination of goals. Wolff's appearance on Moyers & Company was a rare breath of fresh air, enough so that I grabbed his book shortly afterwards. Wolff is a Marxian economist (meaning that he makes use of Marxist analysis of economics and capitalism while separating them from Marxist politics and Marx's advocacy of revolutionary socialism), which for me was part of the interest. Marxist thought of any branch is not common in the United States; we're regularly deprived of several sides in the international conversation on economic models. I was taught Marxist theory in elementary and high school (in retrospect, surprisingly even-handedly and well, despite the biases of my schooling), but none of the later developments of Marxist thought. I think that's a typical experience here; in the United States, Marxism culminated in Mao and Stalin, and no further development of the underlying theories is ever mentioned. Democracy at Work is subtitled A Cure for Capitalism and does indeed advocate a concrete alternative to capitalist business structures. But this is only the last third of the book (and in some ways the least useful, as I'll discuss in a moment). The first two-thirds of the book is basically a remedial education in modern, as opposed to historic, Marxian economics for US readers like myself who have never heard it before, cast in the context of the current financial crisis. This may well be old hat for Europeans, but if you've been wondering what (at least some) modern-day Marxists actually believe, or are saying to yourself "there are modern-day Marxists after the collapse of the Soviet Union?", I recommend this book to your attention. It's an excellent summary, which I read with the delightful feeling of an expanding viewpoint and the discovery of new directions from which to look at a problem. There's quite a bit in this section that's worth thinking about, including another take on the nature of the recent economic collapse and how that fits into a Marxian analysis of capitalist crises. But there was one point in Wolff's explanation that I found particularly helpful. He completely restructured my understanding of the Marxian analysis of worker exploitation and profit allocation. There are two angles of Marxist economic thought and socialist economics that get a great deal of attention, at least in the United States, in history and economics classes: the role (or lack thereof) of markets in price setting, and the ownership of the means of production. Defenders of capitalism like to focus on the former, since it's quite easy to identify the advantages of theoretical free markets in finding ideal prices and balancing supply and demand, whereas central planning of prices and production has resulted in some catastrophic and deadly failures. (Although I will note, with passing interest, that those failures predate large-scale computing, and there are now large corporations that manage budgets larger than some countries via centralized command-and-control economic practices.) Defenders of socialism are more likely to focus on the ownership of the means of production, since it's easy to show prima facie unfairness in owners of capital extracting vast profits without having to do any work themselves, only be lucky enough to start with large quantities of money. Wolff, however, argues that both of these focuses misses a core critique by Marx of the workplace structure in capitalism, and that, by ignoring that critique, supposedly Marxist countries did not create anything that was actually Marxist in implementation. The Soviet Union was just as much a capitalist country as the United States is. It was state capitalism rather than private capitalism, but the core capitalist structure was intact. Wolff arrives at this conclusion, which may be well-trodden ground in parts of the world that include active Marxist thought but which was quite startling to this American, by treating the ownership of capital as a partial distraction. He focuses on a more direct question and practical question: who determines what a worker does on a day-to-day basis and how that product is used? Who determines what profits are collected and how they are spent? In private capitalism, this is done by the owners of the capital: large shareholders, major investors, and the managerial class that they hire. In Soviet state capitalism, this is done by national politicians, bureaucrats, and the managerial class that they hire. In neither model is it done by the workers themselves. The Soviet model gives theoretical ownership of the capital to the workers, but that ownership is diffused, centralized, and politicized, redirected through the mechanisms of the state, and therefore is effectively ignored. Ownership and control is entirely captured by the political class. Both of these systems are capitalist in Wolff's view of Marx: there is a class of owners and managers, who control the terms and nature of work and who allocate the profits, and a class of workers, who have to do what they're told, are not paid full value for their labor, and don't have a say in how the profits their work generates are spent. At the most important level of day-to-day autonomy and empowerment, they are functionally identical. They are both equally hierarchical and exploitative; the only difference is in whether the system is controlled by rich individuals or by well-connected politicians. (And, as any study of modern politics quickly reveals, the distinction between those two groups in most countries is murky at best.) Wolff convincingly recasts modern economic history as a constant pendulum swing between private capitalism and state capitalism. Crises in one system push countries towards the other system; subsequent crises push the country back towards the first system. Regulation grows and shrinks, companies are nationalized and then privatized, but both systems are united in excluding the worker from any meaningful control over their work life. The first two-thirds of the book was full of insights like this for me. I didn't agree with all of it, but all of it was worthwhile and thought-provoking. But I was a bit leery of Wolff's proposed solution. My past experience with critics of capitalism is that the critique is often quite compelling, but the proposed solution is much less believable. And, sadly, that concern was warranted here as well. The core of Wolff's proposal is predictable but possibly sound: a restructuring of the workplace to be radically democratic. The business would be owned entirely and exclusively by the people who work for it, equally regardless of the job of the worker, and the workers would decide democratically or via elected repesentatives from among the workers how to allocate the profits of the business, what standards and business practices should be followed, and how the work is to be done. I was particularly interested to hear that this model (workers' self-directed enterprises) has apparently been successful in Spain in the form of the Mondragon Cooperative. Given all the tricky, small details that have to be resolved in an actual workplace, an existence proof is worth more than pounds of theory. Unfortunately, like a lot of proposed alternatives, Wolff's description of WSDEs is quite fuzzy and involves a lot of hand-waving. I was never able to build, from this book, a coherent and complete mental model of how such a workplace would function. Wolff tends to surround every specific in a halo of contingencies, possibilities, and alternative models, and is maddeningly nonspecific on such practical matters as how line management would work, how such a business would do financial planning or project approval, how competing interests in different parts of the organization would be balanced, and other practical governance matters that fill my work life. Maybe the answer to all of that is just "democracy," but I'm dubious. Democracy has a number of well-known flaws that I thought weren't adequately addressed. For example, democracies are often quite happy to further and reinforce existing prejudice (such as sexism or racism), and are prone to yielding control to the most charismatic. Democracies also have an informed voter problem, which seems like it would be particularly acute if democracy is going to make detailed business decisions. And, for larger organizations, control by pre-existing money could re-enter the equation via propaganda and campaigning around votes. Some of this gap in the book could be addressed via a more in-depth look at how Mondragon and any other real-life examples work, but that is sadly missing here. (I am interested enough now, though, that I'd read a good popular treatment of the history and methodology of Mondragon, although I don't think I'm up to working through an academic study.) The hierarchical, dictatorial management structure imposed by capitalism is so awful that WSDEs don't have a particularly high bar to meet to be fairer and more empowering than what we have today. The question, rather, is would they function sufficiently well that the business would be able to make effective decisions, and that's unclear to me from this book. This is, as Wolff spends some time discussing, particularly difficult when in direct competition with capitalist enterprises. This sort of endeavor will probably trade some degree of economic efficiency and raw marketplace power for improvements to fairness and empowerment, but that means it's going to require support from the surrounding society, which is a huge obstacle. I doubt there's a free lunch here: true fairness and equity also leading to improved economic efficiency in a capitalist context is a nice dream, but not horribly practical. Wolff also seems to suffer from something else I associate with Marxist thought: a preferential focus on a very narrowly-defined type of productive worker, apparently left over from Marx's original critique in the context of industrialization. Wolff inserts a very odd and quite awkward distinction in his WSDE model between workers who directly produce the product that's sold, and who in his model therefore produce the profits of the business, and all other workers in the business. He then gives special privileges to the former group to decide how much profit to return in worker compensation and how much to use for other purposes, thus making the supporting workers second-class citizens within this supposedly equal workplace. Speaking as someone who works in IT, and hence would be classified by Wolff into the supporting rather than directly productive category, I do not find this division at all convincing, and Wolff never provides a coherent explanation for why he introduced it. He only says that it's necessary for the governance of the business to not be exploitative, which seems to assume that there is a special economic role played by the workers who work directly on a saleable product. Maybe there is some analysis that could convince me of this, but, if so, it's not present in this book. It struck me as a recipe for continuing the exploitation of the most invisible and powerless workers in capitalism: janitors, groundskeepers, and other low-paid service jobs. I wish the whole book were as insightful and pointed as the first two-thirds, but alas I found the WSDE discussion to be somewhat muddled and utopian. "How do we get there from here" is always the hardest part of this type of discussion, and Wolff has no special skill in that department. But, despite that, I got a lot of fascinating ideas and new conceptual frameworks out of this book, and I'm tempted to read it again. I suspect some of this, similar to my discovery of promises and infinite streams in programming, is filling in of odd gaps in my personal education rather than a discovery of unusual, new ideas. But if you too have gotten your political education within the US capitalism ber alles bubble, this book may fill in similar gaps in your knowledge. If so, it's a very rewarding experience. If you're curious about a preview of Wolff's perspective without paying for the book, I recommend watching the first episode of Moyers & Company in which he appeared. Wolff is a clear and engaging speaker, and his interview provides a good feel for his discussion style and his general perspective. Rating: 8 out of 10

3 May 2013

Wouter Verhelst: Oops, I did it again...

For (at least) the third time, I managed to register for debconf before registration was actually open. Oops. I found out that unfortunately, it's not quite certain yet that there will actually be a debcamp this year and if there is going to be a debcamp, it won't be a full week. Pity. At any rate, I'll be there the whole time, whatever the duration of debcamp. Since Vaumarcus is closer to Mechelen than Edinburgh (by about 250km), this is going to be the closest debconf for me, ever. And if I could go to Banja Luka by car, I can certainly go to Vaumarcus by car. Anyone care to join me?

DebConf team: The DebConf13 matching fund completes, raising 2500 USD, twice (Posted by Didier Raboud)

The DebConf13 matching fund announced previously is now complete. The matching sponsor, Brandorr Group will match the collected amount of 2513 USD, resulting in 5026 USD of sponsoring money for DebConf13, for the benefit of all attendees. Despite raising only slightly more than half of the expected money, this first experience of raising funds through this matching fund mechanism can be considered successful.
DebConf is very important to the health of Debian, and Debian is very important to our team, so we re doing what we can to help. In this case we really wanted to see if we could provide an incentive for individual users of Debian to donate to the project. It seems like it worked well, and we d love to do something like this again in the future.
Brian Gupta, Brandorr Group
DebConf13 continues to welcome donations from individuals and is also seeking further sponsors. Registration opening Registration for DebConf13 will be opening shortly: stay tuned! We look forward to welcoming you to Vaumarcus!

1 May 2013

Russ Allbery: WebAuth 4.5.1

Unfortunately, as always seems to happen with large releases, one of the features that we added in WebAuth 4.5.0 wasn't adequately tested and had some lingering issues. In this case, it was a last minute change: from a UI perspective, we decided it was better to present the user with a checkbox (checked by default) saying "remember my login on this computer" instead of a checkbox (off by default) saying "this is a public computer; don't remember me." People are much more familiar with the former than the latter. Unfortunately, due to how HTML checkboxes work, this required changing the default in the code, and that turned out to break single sign-on completely. We were assuming we should not maintain single sign-on credentials by default, so all the WebLogin interactions that never passed through the forms so that the form could establish a default would delete the cookies. This should be all sorted out in this release, along with a few other edge cases that became apparent when I thought harder about this. The documentation also makes clearer the required template changes when upgrading from versions prior to 4.5.0. We also snuck in one new feature: the user information service can pass a message to the user through to the confirmation page. You can get the latest release from the official WebAuth distribution site or from my WebAuth distribution pages.

Next.

Previous.