Search Results: "ema"

14 March 2014

Neil Williams: LAVA server on an arndale

(ARMv7 A15 dual core) I ve covered how I set up my home LAVA lab and how I got two iMX.53 boards running, the next step was to sort out the LAVA server. My initial setup relied on using my Thinkpad as the server. This was somewhat convenient as that s how I develop the code, but didn t help me run jobs like health checks because the laptop was usually somewhere other than on the home LAN. There had been a long-standing problem with using LAVA on ARM the uwsgi support didn t compile but the code being used was old. As the same code has been in Debian for a long time, I suspected that this was fixed with a newer version. So as part of migrating LAVA to django1.6, apache2.4, postgres9.3, django-tables2 0.13 and a few other updated dependencies, I have been using the version of uwsgi from Debian unstable for quite a while without problems on x86. A simple tweak to the LAVA setup scripts and a newer version of uwsgi became available and it builds just fine on armhf. (I haven t tried armel because Linaro is ARMv7 or newer and we don t test with ARMv5/ARMv6 boards, so there s no point in trying armel it s not likely to be an issue for this fix though.) (Only the current lava-deployment-tool methods need to actually compile uwsgi directly from upstream without any patches the packaging which will replace l-d-t uses precompiled binaries, just as any admin would expect.) That initial install was on one of the iMX.53 boards, which ran as slowly as anyone who has used an iMX.53 would expect. I haven t run test jobs on that install, it had a hard enough time serving the frontend. Clearly some more cores would be a good step and when an arndale became available for the home lab, the next step was to get a SATA drive onto the arndale, put Debian unstable on that and then deploy LAVA to the arndale using the Debian packages. As a bonus, these packages are built for django1.6 (using an unreleased branch). Sounds simple enough. It works on iMX.53, it should work on an arndale. Well, it does but only after some unexpected faff. arndale, u-boot and SATA I hate u-boot every single time I ever touch it, the little I know about any other u-boot device is completely useless. Uniformity is a good thing infinite permutations are just rope to hang ourselves with cute embedded nonsense hacks and I m bored of that whole scene. So, boot the arndale, interrupt the bootloader to get to the prompt. What s the first thing most people would want? help. Denied this particular u-boot has been compiled without the ability to display any help messages. u-boot has just sunk further into the depths of please can we have something else which is uniform across devices . OK, well maybe I can get by without help. sata init unknown command sata . (Go away, do something else for a bit.) The arndale isn t one of the newest boards in the ARMv7 world, LAVA has been using them for a while, so someone has probably done some work to fix this . nope. There s a workaround a nice detailed guide by Phil Endecott which details that the kernel needs to continue to be loaded from SD and then the SATA can be used for just the rootfs. Mildly annoyed (I was hoping to be able to update the arndale kernel without the hassle of mounting the SD card at all), the rest was straight-forward. Preparing the SATA and installing Debian Due to the complexity of some of the transitions currently ongoing in Debian ahead of the Jessie release freeze, uwsgi is not in Debian testing right now so this install has to be Debian unstable. That s OK, I ve been running Debian unstable on all my machines for several years now usually updating ~5 times a week.

# parted /dev/sda -s unit mb mktable msdos
# parted /dev/sda -s unit mb mkpart primary 1 -- "-0"
# mkfs.ext4 /dev/sda1
# mount /dev/sda1 /mnt/root/
(note the in the mkpart command, that catches me out most times I try this. Without it, the special -0 gets interpreted as an option to parted but parted doesn t then tell you how to fix it, it just complains about an unknown option.) The SD image I am using is a LAVA master image, based on Ubuntu, so it was easy to put debootstrap onto it.

# apt-get install debootstrap
# debootstrap --arch=armhf sid /mnt/root/ http://ftp.uk.debian.org/debian
# chroot /mnt/root/
Inside the chroot, it s Debian as usual:

apt-get update
apt-get install emdebian-archive-keyring
passwd
emdebian-archive-keyring is a package I (ab)use to sign my LAVA packaging as it has the advantage of being in Debian and Ubuntu going back to the time of Lenny, so it is always available from a repository which has already been authenticated to apt and doesn t involve downloading some random key from a website. I use passwd manually because this rootfs won t be using auto-login, it will have regular users. root passwords can be automated, if necessary. Thinking about login, remember to give the rootfs a usable tty. (The LAVA master image has a nasty habit of mangling editors like nano and vi when used over serial, so I m using echo.) For the arndale you need:

# echo T0:23:respawn:/sbin/getty -L ttySAC2 115200 vt102 >> ./etc/inittab
# echo >> ./etc/securetty
# echo ttySAC2 >> ./etc/securetty
Then to make the hostname useful, adapt this to your needs:

echo 127.0.0.1 arndale.codehelp arndale >> ./etc/hosts
Finally, get the network running at boot and add the LAVA repository:

# echo auto lo eth0 > ./etc/network/interfaces.d/arndale
# echo iface lo inet loopback >> ./etc/network/interfaces.d/arndale
# echo iface eth0 inet dhcp >> ./etc/network/interfaces.d/arndale
# echo deb http://people.linaro.org/~neil.williams/lava sid main >> ./etc/apt/sources.list.d/lava.list
# apt-get update
# exit
Once the LAVA packaging is finalised, the packages will be uploaded to a normal Linaro PPA, I ll update the packages to use an official download location and we ll move to using sane version string handling. For now, the packages are still in development. Code for the packaging is in Alioth but there are issues with anonymous access to the pkg-linaro-lava repositories currently, so I ve also pushed to http://github.com/Linaro if you are interested in building the packages yourself. See also my packaging guide which is also linked from the Links page on my own site. With that done, time to reboot, set the SATA drive as the rootfs using the horrid u-boot and install LAVA.

# reboot
> setenv bootargs console=tty0 console=ttySAC2,115200n8 drm_kms_helper.edid_firmware=edid-1920x1080.fw root=/dev/sda1
> boot
login
# apt-get install postgresql
After this operation, 63.0 MB of additional disk space will be used.

# apt-get install lava-server
After this operation, 231 MB of additional disk space will be used.

# a2dissite 000-default
# a2ensite lava-server
# apache2ctl restart
# service lava-server restart
Take note of the IP address of your new ARM LAVA server and sign in with your regular details, e.g. using OpenID before creating a temporary superuser:

# lava-server manage createsuperuser --username default --email=user@example.com
Choose a temporary password, log out, log in as the temporary superuser, promote your regular user to superuser and default owner of unrestricted devices in the django admin interface. Finally, log out and login as regular user to delete the temporary user. (Yes, that probably could do with some improvement remind me later and I ll see if a known user can be promoted from the command line.) See also Senthil s recent post on LAVA unit tests. Getting those to run without so many steps is also on the TODO list. Results
IP Address: 127.0.0.1
Is Master? : True
Uptime: 6:02:23.700000
Architecture: armv7l
Platform: Linux-3.10.1.0-1-linaro-arndale-armv7l-with-debian-jessie-sid
Insignal Arndale evaluation board based on EXYNOS5250
System memory: 1998MiB
Next! I m working on some code upstream to make it easier to add devices from the command line. The aim is that a set of simple commands will set up an initial device, run a job on that device and submit a result bundle to the LAVA server as job #1. This gives some assurance that everything has gone well. Now I can finally add health checks for the iMX.53 boards and start regular tests on those boards. The cubie boards will wait for a later blog post, there are interesting problems with the bootloader and serial connections. That s a whole different rant.

Dirk Eddelbuettel: Rcpp 0.11.1

A new minor release 0.11.1 of Rcpp is now on the CRAN network for GNU R; binaries for Debian have also been uploaded. The release fixes a number of bugs that have come up since the 0.11.0 release in January, but also brings some extensions. See the NEWS file section below for details, or the ChangeLog file in the package and on the Rcpp Changelog page Once again, we tested this release by building against all CRAN packages which depend upon Rcpp. In short, three packages are blacklisted from tests, and three came up with something we noted --- but the remaining 177 packages all build and test cleanly. Detailed results of those tests (and the scripts for it) are on GitHub. There are a number of other fixes, upgrades and other extensions detailed in NEWS file extract below, in the ChangeLog file in the package and on the Rcpp Changelog page.
Changes in Rcpp version 0.11.1 (2014-03-13)
  • Changes in Rcpp API:
    • Preserve backwards compatibility with Rcpp 0.10.* by allowing RObject extraction from vectors (or lists) of Rcpp objects
    • Add missing default constructor to Reference class that was omitted in the header-only rewrite
    • Fixes for NA and NaN handling of the IndexHash class, as well as the vector .sort() method. These fixes ensure that sugar functions depending on IndexHash (i.e. unique(), sort_unique(), match()) will now properly handle NA and NaN values for numeric vectors.
    • DataFrame::nrows now more accurately mimics R's internal behavior (checks the row.names attribute)
    • Numerous changes to permit compilation on the Solaris OS
    • Rcpp vectors gain a subsetting method it is now possible to subset an Rcpp vector using CharacterVectors (subset a by name), LogicalVectors (logical subsetting), and IntegerVectors (0-based index subsetting). Such subsetting will also work with Rcpp sugar expressions, enabling expressions such as x[ x > 0].
    • Comma initialization (e.g. CharacterVector x = "a", "b", "c";, has been disabled, as it causes problems with the behavior of the = operator with Rcpp::Lists. Users who want to re-enable this functionality can use #define RCPP_COMMA_INITIALIZATION, but be aware of the above caveat. The more verbose CharacterVector x = CharacterVector::create("a", "b", "c") is preferred.
  • Changes in Rcpp Attributes
    • Fix issue preventing packages with Rcpp::interfaces attribute from compiling.
    • Fix behavior with attributes parsing of ::create for default arguments, and also allow constructors of a given size (e.g. NumericVector v = NumericVector(10)) gives a default value of numeric(10) at the R level). Also make NAs preserve type when exported to R (e.g. NA_STRING as a default argument maps to NA_character_ at the R level)
  • Changes in Rcpp modules
    • Corrected the un_pointer implementation for object
Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 March 2014

Andrew Pollock: [life] Day 43, a lovely lazy day, until we got on the bike

Zoe slept through the night again last night. Two nights of uninterrupted sleep has been totally amazing! We had a slower start to the day because we didn't have to be anywhere. I've been meaning to do a massive cull of Zoe's wardrobe for a while, and this morning seemed like as good an opportunity as any, so after TV, I managed to get Zoe to cooperate with trying on clothes for about an hour. She really enjoyed pulling everything out of her wardrobe and putting it all back again neatly. After that, she asked me if I could make her a bus out of the last remaining moving box, so I managed to make something approximating a bus. The port-a-robe boxes are really rather handy for this sort of thing. The balcony is starting to look like a cardboard box shanty town, with a cubby house, a rocket and now a bus. I think we need to host a few more play dates so they all get a good work out. It was time for lunch after that. I'd had a bucket of caramel popcorn, which I used for the journey to Coochiemudlo the other week. Zoe had asked me how popcorn was made, so I had resolved to make popcorn with her sometime soon. Yesterday at the health food shop, I opportunistically noticed some popping corn, so I grabbed a small bag of it. It turned out that buying peanut oil was good for more than just making peanut butter, as it came in handy today for popping corn. I've never popped corn before, aside from occasionally getting a bag of the microwave stuff, so it was a fun experience to do it "from scratch". It turned out pretty well, with only a few burned ones and a few unpopped ones. It'd be fun to try and dry out a corn cob and totally do it from scratch. After that I tried to get Zoe to take a nap, but it didn't work out so well, so after her quiet time we cleaned up her bedroom and generally fooled around for a bit. Throughout the day, Zoe did lots of little bouts of self-directed play. She dredged up this little wooden xylophone that we'd made in the US from a Kiwi Crate and had a great time banging away on it until she stood on it and broke it. The doctor's kit got a good workout. It was just a really nice, relaxing day at home. Zoe's Kindergarten was having a play date meet-and-greet in the park, for all the parents to meet each other. It was a fair way from home, but there was a nice, albeit circuitous, bike path to get there, and I decided to try and bike there, without really properly estimating the distance or length of time it would take. The play date was due to start at 3:30pm, and I was planning on leaving at 3pm. We were about 5 minutes late getting out of the door. I think it ended up taking us about 50 minutes to get there. It was a beautiful ride though, once we got onto the Bulimba Creek bikeway, through the Minippi Parklands. It would have been the longest ride Zoe's had on the bike, and she wasn't fazed at all. The play date itself was nice. For some reason, I'm a bit shy about going and introducing myself to the mothers (I kept wanting to write "other mothers"), but I sucked it up and made a few introductions. I'm terrible about remembering names though. At least I've got a few faces I can say hi to at drop off and pick up now. Sarah met us at the park and hung out for a bit as well, and then Zoe and her left together and I biked back home. I was feeling pretty good, and thought I'd try and bang out a run when I got home, but I didn't end up having the fuel in the tank, and blew up after about 1.5km.

11 March 2014

Ian Wienand: Tenvis IP391W meta-page

Recently I purchased a Tenvis IP391W-HD camera. I would be unlikely to recommend it. The price is certainly right and the picture quality is quite good. The Android and iPhone apps do work to watch the stream live. However, the interface is terrible and almost useless without Internet Explorer. There is a RTSP stream (rtsp://admin:password@ip) which VLC can seem to handle, but not mplayer. The recording format (.h264) is not viewable by VLC or mplayer and all I could find is a Windows .exe to convert them to an .avi. The motion detection gets troubled by the dark. It would really only be useful for something permanently well-lit. It did send me emails via gmail. I have got it recording to a NFS server, but I don't have a lot of confidence in the reliability of it. I think I have it configured to record in 3600-second blocks (given the interface, it's hard to tell if I've set it up to the network, or to the internal flash, etc), but it seems to intersperse 60 minute recordings with random small recordings. Given the whole idea of a security camera is to record the unexpected, you want a lot of confidence you're actually recording, which you don't get with this. You can see below it recorded 3 hour blocks, then started going a little crazy...
-rw-r--r-- 1 nobody nogroup  69M Mar 11 01:25 0-003035.v264
-rw-r--r-- 1 nobody nogroup  69M Mar 11 02:25 0-013049.v264
-rw-r--r-- 1 nobody nogroup  69M Mar 11 03:26 0-023103.v264
-rw-r--r-- 1 nobody nogroup 5.9M Mar 11 03:31 0-033117.v264
-rw-r--r-- 1 nobody nogroup 1.5M Mar 11 03:40 0-034350.v264
-rw-r--r-- 1 nobody nogroup  17M Mar 11 04:02 0-035259.v264
-rw-r--r-- 1 nobody nogroup 306K Mar 11 04:10 0-041548.v264
-rw-r--r-- 1 nobody nogroup 4.9M Mar 11 04:23 0-042457.v264
There is a support forum, where I found the following files scattered in various posts. From what I can tell, they are the latest as of this writing. I can confirm they work with my IP391W-HD, which the system tells me is GM8126 hardware and came with firmware 1.2.8.3.
  • 1.3.3.3.pk2 - firmware (b56f211a569fb03a37d13b706c660dcb)
  • web.pk2 - a UI update that includes dropbox support. This is really for the model that has pan and tilt, so those buttons don't work. (0e42e42bd6f8034e87dcd443dcc3594d)
  • V264ToAVIen.exe - converts the output to an AVI file that mplayer will play (with some complaints) (9c5a858aa454fed4a0186cf244c0d234)
www.modern.ie offers free limited-time Windows VM's which will work to upload this firmware. Just make sure you use a bridged network in the VM; I'm guessing the firmware ActiveX control tells the camera to TFTP the data from it, which doesn't work via NAT. Somewhat worryingly, you can telnet to it and get a login prompt (TASTECH login). So it has a built-in backdoor you can't disable. There have been some efforts to hack the device. leecher@dose.0wnz.at did an excellent job reverse engineering the .pk2 format and writing tenvis_pack.c (no license, I'm generously assuming public domain). I used this to recreate the firmware above with a telnet daemon listening with a shell on port 2525 (no password, just telnet to it)
It's interesting to poke around, but it seems like the whole thing is really driven by a binary called ipc8126
/ # ipc8126 --help
*** TAS-Tech IPCAM/DVS
*** Version: 1.3.3.3
*** Release date: 2013-08-05 15:48:32
In general, I'd say hackability is quite low. Warning : any of the above might turn your camera into a paperweight. It worked for me, but that's all I can say...

10 March 2014

Simon Kainz: DUCK for packagers

I finally managed to package duck 0.4 for Debian/unstable. Additionally to duck.debian.net you can now run all (in fact even more than on the website) checks on your own. Intended as as helper tool for packaging work, it inspects debian/control files as well as upstream metadata files. By trying to use the approriate tool for each URL, it tries to find out (eg. using git ls-remote for GIT repos) if a given repository is availabe. Email addresses in Maintainer and Uploaders fields as well as mailto: URLs are checked by trying to find MX, A or AAAA records for the email domain. Usage Without any additional options, duck looks for the following files: Just hop into your extracted package source tree (the one containing the debian subdir), and run:
$ duck
If everything is ok, you won't get any output. To see what's going on, run:
$ duck -v
debian/control: Maintainer: Simon Kainz simon@familiekainz.at: OK
debian/control: Vcs-Git: git://anonscm.debian.org/collab-maint/duck.git: OK
debian/control: Vcs-Browser: http://anonscm.debian.org/gitweb/?p=collab-maint/duck.git: OK
debian/control: Homepage: http://duck.debian.net: OK
Errors show up like this:
$ duck -v
debian/control: Maintainer: Simon Kainz simon@domain.invalid: ERROR
Simon Kainz simon@domain.invalid: No MX entry found.
Simon Kainz simon@domain.invalid: No A entry found.
Simon Kainz simon@domain.invalid: No AAAA entry found.
debian/control: Vcs-Git: git://anonscm.insanetypo..debian.org/collab-maint/duck.git: ERROR
fatal: unable to connect to anonscm.insanetypo..debian.org:
anonscm.insanetypo..debian.org: Name or service not known
debian/control: Vcs-Browser: http://anonscm.debian.org/gitweb/?p=collab-maint/duck.git: OK
debian/control: Homepage: http://duck.debian.net: OK
skainz@zidpc9027:~/debian/sid/home/skainz/packages/duck_2014/duck$ 
Missing features Currently the following VCS URLs are not supported: If someone knows how to get the state of one of the repos based on the VCSs above, preferably without needing to check out the complete source code, please contact me. And remember: "Always duck before dput" :-)

8 March 2014

Martín Ferrari: Fun with the Linux desktop

Or, "Why 2014 will NOT be the year of Linux in the desktop". So, it happens that my mum (66 yo) has been a Debian user for over a year now. With highs and lows, she manages to do what she needs; sometimes I need to intervene. Today I thought I could send her a quick email explaining how to download using BitTorrent, because of reasons. So, as I was writing, I realised that in many torrent sites, you only get a magnet link these days. No problem! Click on the magnet link, at it should work automagically. Then I remembered: it works on my computer, because I've spent a couple of hours some time ago researching how to make FireFox work with magnet links, creating a custom script, etc. I hoped that by now this must have been solved, at least in Debian unstable. Wrong again. I created a new user in my computer, launched IceWeasel/FireFox and boom: I get a dialog asking me to select a program, not from a list of desktop applications, taken from one of the gazillion sources where applications are defined, but just from any place on the file system! (At least, now you don't need to go tweaking with the hidden FireFox configuration editor). I was very angry at the brainiac at Mozilla who thought it was a great idea to ignore the host system and do their own MIMEtype handling. And then, tried Chromium to see what would happen... And I get first a scary message telling me that it is going to use the super-obscure xdg-open program to open my link, and that it could harm my computer! It was followed by another very helpful dialog telling me something like:
Unable to detect the URI-scheme of "magnet:?xt=urn:btih:diePh6iengei4quaep4shai8ahshahnae9 oolahtetheir2bohmu1eelaChui1ohdahruegh4wief6PusahDae4ho oshahjoogai7bae9shuvei9shufeX4boog8neichi3OoDee5ei9Uori c6aingairepon9gok8Mee7uRahphah4EucoopheiYin4xe4lahn0goh"
Then the real fun started... I starting looking around to understand how this is supposed to work, I wanted to provide a patch! So, it turns out that if you add some values to GConf this should work. So, try to find where would that be. Read about GConf schemas, default and mandatory values, and their 10 possible locations. Find that Azureus provides an schema, use that to create one for Transmission. Then find that in fact, Transmission was providing defaults, which are not the same but work the same, and that they had an error there: yes, problem found! (#741069) No! It turns out that the Gnome desktop does not use that any more, and now they scan the .desktop (who knows in which of the 100 directory tress where .destop files are present) files for MIME handlers, and the transmission-gtk.desktop file had that correctly. So why does it not work? Well, it turns out that if I used gvfs-open instead of xdg-open, it did work! The thing is, I am running XFCE here, which is GTK based, but it is not Gnome: instead of gvfs-open, I was getting exo-open, which is it's brain-dead cousin, and can't do anything but files, email and web. It is fecking 2014, and we still don't have a sensible, unified way to select preferred applications. We still have incompatible, duplicated, incomplete, competing implementations. We have FreeDesktop doing one thing to try and unify criteria, which is then ignored or mis-implemented up and down by some desktops and applications. Some days I get really angry at the Free Software world. PS: I guess I will tell mum to copy&paste the links from the browser to the torrent client, but not today. I have already lost 4 hours of sleep on this.

Russell Coker: Less Work

I previously wrote about the idea of a Basic Income for Australia [1], that post was mainly to show how it could be introduced with little real change. That is not because I don t think that we need real changes, but because we should consider the various changes separately as much as possible. In terms of how society works I think that we need to move from the current model where most people are expected to work most of the time and the people who don t work are treated badly to encourage them to work for low wages. I think that we should aim as a society to have less time spent doing paid work which means more people working part time (maybe 6 months a year, 3 or 4 days a week, or other ways of doing less than 40 hours a week * ~45 weeks) and more people who aren t doing paid work. The idea of 100% employment is the cause of many jokes about the Soviet Union. I don t know how much truth is behind the jokes about needless work being done to fulfill Soviet plans, but regardless of the accuracy I think we should take such things as an idea of what not to do in our society. The Broken Window Fallacy is an example of the Soviet production problem in supposedly capitalist societies. Here are some of my ideas for decreasing the amount of needless work without decreasing anyone s quality of life in fact most of these make things better for most people. The War on Drugs The easiest way to reduce needless employees is to end the war on drugs . During the course of the war the drug use has steadily increased and the amount of law enforcement energy devoted to it has also increased. Some estimates claim that 50% of law enforcement is devoted to it. Also some of the hospital budget is related to drug use. I think that we should allow adults to consume any drug that they wish (not just tobacco, alcohol, caffeine, and other popular drugs) and apply the same laws regarding product quality to all of them. That will reduce the violence related to drugs, reduce the health impact (it s usually poor quality control that causes medical problems), and allow law enforcement to concentrate on crimes that hurt other people. Treating drug addiction as a medical problem has been shown to be the most effective way of reducing drug use, reducing violent crime, and reducing the health impact of drug use. Other Crime Issues Gary Slutkin s TED talk about treating violence as a contagious disease has some interesting ideas for reducing violence in the community [2]. Implementing those ideas on a wide scale seems to have the potential for reducing law enforcement and medical work. Generally I think we should aim to have as few laws as possible. Whenever adults want to do things that don t hurt other people they should be permitted to do so. There should also be an aim for laws to be consistent and easy to understand. Ideally there would be a single database with all laws in some form of hypertext (maybe some type of Wiki) so that any citizen can discover all implications of the laws that affect them. Health More money should be spent on preventing people getting sick. One problem we have in recent times is silly people refusing to get their children vaccinated because they take medical advice from a playboy model instead of doctors. I think that as a society we need to do more to protect children from stupid things that their parents do and that reducing the amount of medical work is the least of the reasons for doing so. Another problem is the quality of food. The big supermarket chains are pushing prices down which reduces food quality. The excessive use of anti-biotics is a serious threat to world health that is driven by the low price of meat. Robots Rodney Brooks gave an interesting TED talk about robotics [2]. He showed how robots can be programmed/trained and talked about the factory workers who want their children to do anything other than factory work. Work that can be done by robots should be done by robots so that people can do better things. Travel One problem that we have in Australia is rent-seeking companies being permitted to establish toll roads. To make such toll roads profitable (which is guaranteed by corrupt politicians) they close roads that might be used to bypass the toll roads. This creates needless traffic congestion (wasted work time driving). Also running toll roads involves employing people to collect the tolls and take legal action against people who don t pay. I believe that toll roads shouldn t exist, this will reduce the number of needless workers and make everything more efficient. Also as a matter of principle I believe that the government should own and control every monopoly in the country. Currently in Australia most adults own cars, this involves a lot of work in car maintenance. Even when not being used a car needs to be maintained for safety. When people drive to work instead of using public transport their travel time counts as work. While time spent on a train, tram, or bus isn t leisure time it s a lesser degree of work than driving a car. You can read a book, play phone games, or do other recreational activities when on public transport. Car sharing companies are taking off in urban areas, this allows some people to avoid owning a car and some families to own fewer cars. We also need more government investment in public transport including more routes, greater passenger capacity, and more service late at night. We also need to encourage companies not to have employees working from 9 to 5 to reduce the peak demand for public transport. A short term tax incentive would do some good in this regard, if companies were to encourage their employees to work different hours for a year then it might change the norms for work enough to permanently break the 9-5 concept. I believe that all land-based mass public transport (buses, trams, and trains) should be free. That would remove the need to pay people to collect fares and fine people who don t have tickets, and also remove the work time involved in buying tickets. Not requiring tickets would also decrease the time needed to get on and off public transport which would improve the speed of public transport and reduce disruption to traffic. One simulation of traffic in New York City showed that collecting fares on buses slowed down traffic enough to impose costs on all workers that were greater than the fares collected so it would be cheaper overall for people in NYC to have free buses paid by the government. I don t think that Melbourne has congestion similar to NYC and even Sydney might not have the same economic issues. But I still think that we should have free transport for the convenience of everyone. Google has been doing some interesting research into cars that are driven by computer, their prototypes have been shown to work well in practice but have not been approved for real use. Trains and trams are easier to drive because there is no steering so it seems that they would be good options for the first implementation of computer driven public transport. Robot trams would allow more regular service late at night and thus make the network more useful. Stop Buying Rubbish A significant waste of resources is the commercial events of Christmas, Valentine s day, and Easter. A lot of marketing money is spent to encourage people to buy rubbish for other people in celebration of such events. I think that Christmas presents for children are a good thing and that even the trivial things (crackers and party hats) are OK, but adults don t need it. Valentine s day is OK for people who are in relationships, but coercing single people to rush to find someone so that they aren t single on that day is bad for everyone. Most Easter and Valentine s chocolate is rubbish, cheap and nasty chocolate in fancy wrappings. Buy a small quantity of good chocolate instead of a large quantity of rubbish. There s a big market for knick-nacks for adults outside of those holidays too. Stands at trade shows usually give away junk to delegates, some of it has enough value to be taken home but really it s mostly rubbish. If you can t sell your stuff without giving away freebies then giving away plastic toys or cheap chocolate isn t going to make it sell. Any Other Ideas? Does anyone have other ideas about how to reduce the amount of work required to sustain our society? Suggestions for improvements that suit other countries are welcome too, while I m mostly thinking about Australia while writing this I m interested in ways of making things better all around the world.

Dirk Eddelbuettel: RcppEigen 0.3.2.1.0 and 0.3.2.1.1

Shortly after I prepared the bug-fix / maintenance release 0.3.2.0.3 of RcppEigen, the code based was updated to the recent Eigen release 3.2.1 by Doug Bates. I wrapped this up in release 0.3.2.1.0 of RcppEigen. The next day, Brian Ripley noticed a build failure on Solaris; and followed up with a better ifdef test for one problematic line which now also addresses the equally irrelevant Unix variants of HP, SGI, and AIX (IBM). May it help someone ... In any event, this constituted release 0.3.2.1.1. The NEWS entries for both follow.
Changes in RcppEigen version 0.3.2.1.1 (2014-03-06)
  • Better ifdef on one directory entry feature, with thanks to Brian Ripley.
Changes in RcppEigen version 0.3.2.1.0 (2014-03-03)
  • Updated to version 3.2.0 of Eigen
Courtesy of CRANberries, there are diffstat reports for the most recent release and preceding release. Questions, comments etc about RcppEigen should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

7 March 2014

Keith Packard: glamor-hacking

Brief Glamor Hacks Eric Anholt started writing Glamor a few years ago. The goal was to provide credible 2D acceleration based solely on the OpenGL API, in particular, to implement the X drawing primitives, both core and Render extension, without any GPU-specific code. When he started, the thinking was that fixed-function devices were still relevant, so that original code didn t insist upon modern OpenGL features like GLSL shaders. That made the code less efficient and hard to write. Glamor used to be a side-project within the X world; seen as something that really wasn t very useful; something that any credible 2D driver would replace with custom highly-optimized GPU-specific code. Eric and I both hoped that Glamor would turn into something credible and that we d be able to eliminate all of the horror-show GPU-specific code in every driver for drawing X text, rectangles and composited images. That hadn t happened though, until now. Fast forward to the last six months. Eric has spent a bunch of time cleaning up Glamor internals, and in fact he s had it merged into the core X server for version 1.16 which will be coming up this July. Within the Glamor code base, he s been cleaning some internal structures up and making life more tolerable for Glamor developers. Using libepoxy A big part of the cleanup was a transition all of the extension function calls to use his other new project, libepoxy, which provides a sane, consistent and performant API to OpenGL extensions for Linux, Mac OS and Windows. That library is awesome, and you should use it for everything you do with OpenGL because not using it is like pounding nails into your head. Or eating non-tasty pie. Using VBOs in Glamor One thing he recently cleaned up was how to deal with VBOs during X operations. VBOs are absolutely essential to modern OpenGL applications; they re really the only way to efficiently pass vertex data from application to the GPU. And, every other mechanism is deprecated by the ARB as not a part of the blessed core context . Glamor provides a simple way of getting some VBO space, dumping data into it, and then using it through two wrapping calls which you use along with glVertexAttribPointer as follows:
pointer = glamor_get_vbo_space(screen, size, &offset);
glVertexAttribPointer(attribute_location, count, type,
              GL_FALSE, stride, offset);
memcpy(pointer, data, size);
glamor_put_vbo_space(screen);
glamor_get_vbo_space allocates the specified amount of VBO space and returns a pointer to that along with an offset , which is suitable to pass to glVertexAttribPointer. You dump your data into the returned pointer, call glamor_put_vbo_space and you re all done. Actually Drawing Stuff At the same time, Eric has been optimizing some of the existing rendering code. But, all of it is still frankly terrible. Our dream of credible 2D graphics through OpenGL just wasn t being realized at all. On Monday, I decided that I should go play in Glamor for a few days, both to hack up some simple rendering paths and to familiarize myself with the insides of Glamor as I m getting asked to review piles of patches for it, and not understanding a code base is a great way to help introduce serious bugs during review. I started with the core text operations. Not because they re particularly relevant these days as most applications draw text with the Render extension to provide better looking results, but instead because they re often one of the hardest things to do efficiently with a heavy weight GPU interface, and OpenGL can be amazingly heavy weight if you let it. Eric spent a bunch of time optimizing the existing text code to try and make it faster, but at the bottom, it actually draws each lit pixel as a tiny GL_POINT object by sending a separate x/y vertex value to the GPU (using the above VBO interface). This code walks the array of bits in the font and checking each one to see if it is lit, then checking if the lit pixel is within the clip region and only then adding the coordinates of the lit pixel to the VBO. The amazing thing is that even with all of this CPU and GPU work, the venerable 6x13 font is drawn at an astonishing 3.2 million glyphs per second. Of course, pure software draws text at 9.3 million glyphs per second. I suspected that a more efficient implementation might be able to draw text a bit faster, so I decided to just start from scratch with a new GL-based core X text drawing function. The plan was pretty simple:
  1. Dump all glyphs in the font into a texture. Store them in 1bpp format to minimize memory consumption.
  2. Place raw (integer) glyph coordinates into the VBO. Place four coordinates for each and draw a GL_QUAD for each glyph.
  3. Transform the glyph coordinates into the usual GL range (-1..1) in the vertex shader.
  4. Fetch a suitable byte from the glyph texture, extract a single bit and then either draw a solid color or discard the fragment.
This makes the X server code surprisingly simple; it computes integer coordinates for the glyph destination and glyph image source and writes those to the VBO. When all of the glyphs are in the VBO, it just calls glDrawArrays(GL_QUADS, 0, 4 * count). The results were encouraging :
1: fb-text.perf
2: glamor-text.perf
3: keith-text.perf
       1                 2                           3                 Operation
------------   -------------------------   -------------------------   -------------------------
   9300000.0      3160000.0 (     0.340)     18000000.0 (     1.935)   Char in 80-char line (6x13) 
   8700000.0      2850000.0 (     0.328)     16500000.0 (     1.897)   Char in 70-char line (8x13) 
   6560000.0      2380000.0 (     0.363)     11900000.0 (     1.814)   Char in 60-char line (9x15) 
   2150000.0       700000.0 (     0.326)      7710000.0 (     3.586)   Char16 in 40-char line (k14) 
    894000.0       283000.0 (     0.317)      4500000.0 (     5.034)   Char16 in 23-char line (k24) 
   9170000.0      4400000.0 (     0.480)     17300000.0 (     1.887)   Char in 80-char line (TR 10) 
   3080000.0      1090000.0 (     0.354)      7810000.0 (     2.536)   Char in 30-char line (TR 24) 
   6690000.0      2640000.0 (     0.395)      5180000.0 (     0.774)   Char in 20/40/20 line (6x13, TR 10) 
   1160000.0       351000.0 (     0.303)      2080000.0 (     1.793)   Char16 in 7/14/7 line (k14, k24) 
   8310000.0      2880000.0 (     0.347)     15600000.0 (     1.877)   Char in 80-char image line (6x13) 
   7510000.0      2550000.0 (     0.340)     12900000.0 (     1.718)   Char in 70-char image line (8x13) 
   5650000.0      2090000.0 (     0.370)     11400000.0 (     2.018)   Char in 60-char image line (9x15) 
   2000000.0       670000.0 (     0.335)      7780000.0 (     3.890)   Char16 in 40-char image line (k14) 
    823000.0       270000.0 (     0.328)      4470000.0 (     5.431)   Char16 in 23-char image line (k24) 
   8500000.0      3710000.0 (     0.436)      8250000.0 (     0.971)   Char in 80-char image line (TR 10) 
   2620000.0       983000.0 (     0.375)      3650000.0 (     1.393)   Char in 30-char image line (TR 24)
This is our old friend x11perfcomp, but slightly adjusted for a modern reality where you really do end up drawing billions of objects (hence the wider columns). This table lists the performance for drawing a range of different fonts in both poly text and image text variants. The first column is for Xephyr using software (fb) rendering, the second is for the existing Glamor GL_POINT based code and the third is the latest GL_QUAD based code. As you can see, drawing points for every lit pixel in a glyph is surprisingly fast, but only about 1/3 the speed of software for essentially any size glyph. By minimizing the use of the CPU and pushing piles of work into the GPU, we manage to increase the speed of most of the operations, with larger glyphs improving significantly more than smaller glyphs. Now, you ask how much code this involved. And, I can truthfully say that it was a very small amount to write:
 Makefile.am             2 
 glamor.c                5 
 glamor_core.c           8 
 glamor_font.c         181 ++++++++++++++++++++
 glamor_font.h          50 +++++
 glamor_priv.h          26 ++
 glamor_text.c         472 +++++++++++++++++++++++++++++++++++++++++++++++++++++
 glamor_transform.c      2 
 8 files changed, 741 insertions(+), 5 deletions(-)
Let s Start At The Very Beginning The results of optimizing text encouraged me to start at the top of x11perf and see what progress I could make. In particular, looking at the current Glamor code, I noticed that it did all of the vertex transformation with the CPU. That makes no sense at all for any GPU built in the last decade; they ve got massive numbers of transistors dedicated to performing precisely this kind of operation. So, I decided to see what I could do with PolyPoint. PolyPoint is absolutely brutal on any GPU; you have to pass it two coordinates for each pixel, and so the very best you can do is send it 32 bits, or precisely the same amount of data needed to actually draw a pixel on the frame buffer. With this in mind, one expects that about the best you can do compared with software is tie. Of course, the CPU version is actually computing an address and clipping, but those are all easily buried in the cost of actually storing a pixel. In any case, the results of this little exercise are pretty close to a tie the CPU draws 190,000,000 dots per second and the GPU draws 189,000,000 dots per second. Looking at the vertex and fragment shaders generated by the compiler, it s clear that there s room for improvement. The fragment shader is simply pulling the constant pixel color from a uniform and assigning it to the fragment color in this the simplest of all possible shaders:
uniform vec4 color;
void main()
 
       gl_FragColor = color;
 ;
This generates five instructions:
Native code for point fragment shader 7 (SIMD8 dispatch):
   START B0
   FB write target 0
0x00000000: mov(8)          g113<1>F        g2<0,1,0>F                        align1 WE_normal 1Q  ;
0x00000010: mov(8)          g114<1>F        g2.1<0,1,0>F                      align1 WE_normal 1Q  ;
0x00000020: mov(8)          g115<1>F        g2.2<0,1,0>F                      align1 WE_normal 1Q  ;
0x00000030: mov(8)          g116<1>F        g2.3<0,1,0>F                      align1 WE_normal 1Q  ;
0x00000040: sendc(8)        null            g113<8,8,1>F
                render ( RT write, 0, 4, 12) mlen 4 rlen 0        align1 WE_normal 1Q EOT  ;
   END B0
As this pattern is actually pretty common, it turns out there s a single instruction that can replace all four of the moves. That should actually make a significant difference in the run time of this shader, and this shader runs once for every single pixel. The vertex shader has some similar optimization opportunities, but it only runs once for every 8 pixels with the SIMD format flipped around, the vertex shader can compute 8 vertices in parallel, so it ends up executing 8 times less often. It s got some redundant moves, which could be optimized by improving the copy propagation analysis code in the compiler. Of course, improving the compiler to make these cases run faster will probably make a lot of other applications run faster too, so it s probably worth doing at some point. Again, the amount of code necessary to add this path was tiny:
 Makefile.am             1 
 glamor.c                2 
 glamor_polyops.c      116 ++++++++++++++++++++++++++++++++++++++++++++++++++--
 glamor_priv.h           8 +++
 glamor_transform.c    118 +++++++++++++++++++++++++++++++++++++++++++++++++++++
 glamor_transform.h     51 ++++++++++++++++++++++
 6 files changed, 292 insertions(+), 4 deletions(-)
Discussion of Results These two cases, text and points, are probably the hardest operations to accelerate with a GPU and yet a small amount of OpenGL code was able to meet or beat software easily. The advantage of this work over traditional GPU 2D acceleration implementations should be pretty clear this same code should work well on any GPU which offers a reasonable OpenGL implementation. That means everyone shares the benefits of this code, and everyone can contribute to making 2D operations faster. All of these measurements were actually done using Xephyr, which offers a testing environment unlike any I ve ever had build and test hardware acceleration code within a nested X server, debugging it in a windowed environment on a single machine. Here s how I m running it:
$ ./Xephyr  -glamor :1 -schedMax 2000 -screen 1024x768 -retro
The one bit of magic here is the -schedMax 2000 flag, which causes Xephyr to update the screen less often when applications are very busy and serves to reduce the overhead of screen updates while running x11perf. Future Work Having managed to accelerate 17 of the 392 operations in x11perf, it s pretty clear that I could spend a bunch of time just stepping through each of the remaining ones and working on them. Before doing that, we want to try and work out some general principles about how to handle core X fill styles. Moving all of the stipple and tile computation to the GPU will help reduce the amount of code necessary to fill rectangles and spans, along with improving performance, assuming the above exercise generalizes to other primitives. Getting and Testing the Code Most of the changes here are from Eric s glamor-server branch:
git://people.freedesktop.org/~anholt/xserver glamor-server
The two patches shown above, along with a pair of simple clean up patches that I ve written this week are available here:
git://people.freedesktop.org/~keithp/xserver glamor-server
Of course, as this now uses libepoxy, you ll need to fetch, build and install that before trying to compile this X server. Because you can try all of this out in Xephyr, it s easy to download and build this X server and then run it right on top of your current driver stack inside of X. I d really like to hear from people with Radeon or nVidia hardware to know whether the code works, and how it compares with fb on the same machine, which you get when you elide the -glamor argument from the example Xephyr command line above.

Vincent Fourmond: Removing the background of an image

While in the process of polishing up a paper, I had to draw figures using a well-known proprietary program for drawing chemical formula whose name I will not write down, out of decency (but you know which one it is anyway). I'm using the mac version (yes, no version for Linux) which has a neat glitch in that the "Save As" button does not work at all: no way to export your chemical formula as a SVG/PDF/PNG picture or whatever ! So I resorted to the neat Print as PDF feature of macintosh. I had to edit the resulting PDF files by hand as some of the colors were wrong (great !), and when I tried to include the PDF, I realized they had a white background... No way !So I dug in ImageMagick's convert documentation, and came up with the following code that converts the PDF file into a PNG with a transparent background:
convert -density 600 figure.pdf -channel alpha \
  -fx '((r == 1 && g == 1 && b == 1) ? 0 : 1)' figure.png
There are still some few points that look white but are probably not that white (due to antialiased rendering of the PDF file ?). There are many more things that can be done using the -fx operator, this page was helpful to me !Edit: while the alpha channel seems to be on by default for PDF files, it is not necessarily the case for all images. If the above doesn't work, try adding -alpha Set before the -fx bit.

6 March 2014

Steve Kemp: So I bought some new hardware, for audio purposes.

This week I received a logitech squeezebox radio, which is basically an expensive toy that allows you to listen to either "internet radio", or music streamed from your own PC via a portable device that accesses the network wirelessly. The main goal of this purchase was to allow us to listen to media stored on a local computer in the bedroom, or living-room. The hardware scans your network looking for a media server, so the first step is to install that: The media-server has a couple of open ports; one for streaming the media, and one for a user-browsable HTML interface. Interestingly the radio-device shows up in the web-interface, so you can mess around with the currently loaded playlist from your office, while your wife is casually listening to music in the bedroom. (I'm not sure if that's a feature or not yet ;) Although I didn't find any alternative server-implementations I did find a software-client which you can use to play music from the central server - slimp3slave - and again you can push playlists, media, etc, to this. My impressions are pretty positive; the device was too expensive, certainly I wouldn't buy two, but it is functional. The user-interface is decent, and the software being available and open is a big win. Downsides? No remote-control for the player, because paying an additional 70 is never going to happen, but otherwise I can't think of anything. (Shame the squeezebox product line seems to have been cancelled (?)) Procmail Alternatives?
Although I did start hacking a C & Lua alternative, it looks like there are enough implementations out there that I don't feel so strongly any more. I'm working in a different way to most people, rather than sort mails at delivery time I'm going to write a trivial daemon that will just watch ~/Maildir/.Incoming, and move mails out of there. That means that no errors will cause mail to be lost at SMTP/delivery time. I'm going to base my work on Email::Filter since it offers 90% of the primitives I want. The only missing thing is the ability to filter mails via external commands which has now been reported as a bug/omission.

5 March 2014

Steve Kemp: Replacing ugly things would save the world many hours

There are some tools that we use daily, whether we realize it or not, that are unduly ugly. Over time you learn to use them and you forget just how hard they are to learn, and you take it for granted. Today I had to guide somebody through using procmail, and I'd forgotten how annoying it is. In brief I use procmail in three ways, each of which I had to document: There are some projects that are too entrenched to ever be replaced ("make", I'm looking at you), but procmail? I reckon there's a chance a replacement would be useful, quickly. Then again, maybe I'm biased.

Andrew Pollock: [life] Day 36, Kindergarten, cleaning and pee pee accidents in hardware stores

Today was my "clean the house" day. I made a start, then went for my chiropractic assessment and adjustment. I now only need to see him fortnightly, which is nice. I knocked out most of the cleaning, and then went for a massage and had some lunch. The next thing I knew it was about time to pick up Zoe. I biked to Kindergarten, and she was asleep again. She woke up reasonably easily, but was grumpy not long after that. She was very uncooperative, and didn't want to go home on the bike, and wouldn't let me put sunscreen on her. After a bit of work, I managed to extract from her that she didn't like my "sweaty hands" from riding the bike there, so I washed my hands and then she let me sunscreen her up. I'll try doing pick ups in the car next week I think. We got home, and I needed to get some more kitty litter, so we went out to Pet Barn. Zoe had a great time checking out all the fish, and also playing with aquarium decor. It got me thinking that maybe an aquarium might be a good birthday present for her, if not this year, maybe next year. It turns out that fish aren't particularly expensive, so they'd make for easy presents for people. After that, we popped across to Bunnings, because I needed a couple of things. While we were there, Zoe announced she wanted to go to the toilet, so we started trekking off to where I thought the toilets were. Turned out I was wrong, and they were at the opposite end of the building, so we had to trek all the way back again. Zoe got all the way into the ladies bathroom and failed to make it onto the toilet in time, so that concluded our visit to Bunnings. We got home and she got changed, and I started making dinner. While dinner was cooking, Zoe watched a bit of TV, and then I decided to try making some lunch box pies, essentially a piece of buttered bread jammed into a muffin tray with some creamed corn and bacon in the bottom and beaten egg on top, thrown in the oven. Zoe helped sample the bacon and cracked the eggs for me, while I buttered bread and cut the crusts off and jammed slices into muffin trays. Bedtime was remarkably uneventful for a change.

4 March 2014

Mario Lang: Personal mail server

I used to use Fetchmail and Gnus with its mail splitting capabilites and nnml backend to handle my private mail setup for many years. This worked pretty fine since I am used to accessing my home server through SSH. I have Gnus running inside of a GNU screen session. So I can check mail from remote by using a SSH terminal. This works fine as long as I have a good SSH terminal on a desktop or laptop computer. However, it does not work very well on tablets or smaller mobile devices. Additionally, mail splitting has become a performance burden over the years. I do not want to wait for Gnus to sort incoming mail into different folders while checking for new mail. That is something which should have been done in the background already, and thats what we are going to cover with the setup described below. So I had to change my simple setup to accomodate for the new trends in mobile computing. The obvious core of such a setup is an IMAP server which receives and stores your mail such that different clients can access it. So the time of my Gnus nnml storage are definitely over. Mail is no longer stored in and by my mail client.
Dovecot While there are several IMAP server solutions out there, I find Dovecot fits my needs quite nicely. I've decided to store my mail in Maildir format in ~/Maildir. I prefer storing data like that in the home directory to avoid having to backup separate files from /var/. Maildir also features some index files which should help performance in the long run. Incoming mail will solely be delivered by fetchmail and should be checked for spam. While I can probably configure Exim to run SpamAssassin on mails before delivering them to Dovecot, there is a much more elegant solution: the dovecot local delivery agent (LDA). /usr/lib/dovecot/deliver takes mail from standard input and performs Sieve filtering and updates the mail indexes. We will call this executable more or less directly from fetchmail. Incoming mail from mailing lists will be sorted into different folders using Sieve. Dovecot needs to be told to enable the sieve plugin and to create new folders on demand. /etc/dovecot/local.conf:
disable_plaintext_auth = yes
mail_location = maildir:~/Maildir
lda_mailbox_autocreate = yes
lda_mailbox_autosubscribe = yes
protocol lda  
  mail_plugins = sieve
 
Sieve scripts are actually quite intuitive once you have a template to start from. ~/.dovecot.sieve:
require "fileinto";
if exists "X-Spam-Flag"  
  # Store spam tagged by SpamAssassin into dedicated Spam folder
  if header :contains "X-Spam-Flag" "YES"  
    fileinto "Spam";
   
  elsif exists "X-Cron-Env"  
  # Store mails from Cron daemon in dedicated folder
  fileinto "cron";
  elsif exists "List-Id"  
  # File list-mail into dedicated folders, matching on List-Id
  if header :contains "List-Id" "boost-users.lists.boost.org"  
    fileinto "boost-users";
    elsif header :contains "List-Id" "brltty.mielke.cc"  
    fileinto "brltty";
    elsif header :contains "List-Id" "debian-accessibility.lists.debian.org"  
    fileinto "debian-accessibility";
    elsif header :contains "List-Id" "debian-devel-announce.lists.debian.org"  
    fileinto "debian-devel-announce";
    elsif header :contains "List-Id" "debian-devel.lists.debian.org"  
    fileinto "debian-devel";
    elsif header :contains "List-Id" "spirit-general.lists.sourceforge.net"  
    fileinto "spirit-general";
   
  # ...
 
SpamAssassin Since I want automatic classification of spam messages, I use SpamAssassin. Just install spamassasin and enable spamd in /etc/default/spamassassin:
ENABLE=1
We will use spamc in the Fetchmail configuration.
Fetchmail My ~/.fetchmailrc is a straightforward list of some mailboxes to fetch mail from. I use the mda directive to skip the MTA and send mail through SpamAssassin and deliver it to Dovecot via its LDA mechanism. ~/.fetchmailrc:
set daemon 1200 # Poll at 10 minute intervals
poll blind.guru protocol IMAP: ssl;
# ... add more sources here ...
mda "/usr/bin/spamc -u %T -e /usr/lib/dovecot/deliver -d %T"
To avoid spreading access information in too many configuration files I am using the ability of Fetchmail to use netrc to retrieve account passwords. ~/.netrc:
machine blind.guru login mlang password <hidden>
Gnus I am using Gnus to read mail, newsgroups and RSS feeds since many years now. It would be quite a mouthful to explain all the customizations I am using by now. But there is one very important bit in the context of this article: How to access the IMAP server? In my setup, Emacs and therefore Gnus is running on the same machine as the IMAP server. So I can avoid authentication at all. This configuration will avoid unnecessary password prompts or caching. In ~/.emacs or ~/.gnus:
(setq gnus-secondary-select-methods '((nnimap "localhost"
                                       (nnimap-stream shell)))
      nnimap-shell-program "/usr/lib/dovecot/imap")
With this you should be able to subscribe to your IMAP folders from within Gnus with ease. Sorting incoming mails into folders is now performed by the IMAP server through Sieve scripts. Instead of changing Gnus' configuration I now edit ~/.dovecot.sieve when I subscribe to a new mailing list. If you add a new Sieve rule for a mailing list and the associated folder does not exist yet, Dovecot will autocreate it, very convenient.
Mobile devices Now all that is left is a way for your mobile devices to read and eventually send mail. This is very much dependant on your network setup, so I am not going to go into any detail here. If you are accessing your mail setup from a tablet in your local network you might get away without tinkering with your router configuration. If you want to read/send mail on the go you need some way to get to your external IP. Either it is stable enough or you need some dynamic DNS service. You will definitely want to forward IMAP and maybe SMTP ports from your router to your home server. If you don't have an existing SMTP server for your mobile device that accepts your outgoing mails you can also set one up yourself and deliver outgoing mails from your mobile device to the world with Exim or qmail. I am personally using Exim since I am going with the default MTA for Debian. Configuring Exim to take mail from iOS devices was as simple as enabling an appropriate authentication method and adding an account to /etc/exim4/passwd. I have to admit though that I don't particularily like Exim's configuration files. That is why I ended up using dovecot's LDA in the first place.

Andrew Pollock: [life] Day 35, Kindergarten, taxes, makeup BJJ

I foolishly had a late night last night, for no particularly good reason, so I slept in quite late this morning. I didn't start getting going until about 8am. How decadent. I'd forgotten to send Zoe to Kindergarten with her water bottle yesterday, and forgotten to give it to Sarah when she picked her up yesterday, so I dropped it and a fresh set of spare clothes out to Kindergarten after I had breakfast and a shower. I managed to sneak in and out without Zoe seeing me. I did some more work on my taxes before popping out for lunch to discuss my main start up idea. I also renamed my old shelf company today. I biked over to Kindergarten for pick up, and sure enough, Zoe was fast asleep. It took quite a bit of work to rouse her. I was pretty sure she was just faking it though. She moved pretty fast when I said I had a surprise at home for her. We biked home, and I gave her the surprise (some Pop Rocks I'd been saving for a special occasion) and headed out by car to a makeup Brazilian Jiu-Jitsu class to make up for the one she missed on Friday. It turned out that trying to do an afternoon class after Kindergarten and being woken up from a nap wasn't the best idea. Zoe tired out pretty quickly, during the warm up exercises, and was moderately uncooperative for the remainder of the class (she kept going on strike). I've never driven to or from BJJ classes until today, and I wasn't actually sure how best to drive home, since we've always taken the Norman Park Greenway. Zoe was asking for a "different way" anyway, so that worked out well. We winged it through Coorparoo and the back of Norman Park and tacked onto the end of how we'd normally cycle home. Zoe had enough time to watch a little bit of TV before Sarah arrived to pick her up.

3 March 2014

DebConf team: DebConf8 registration open and CfP (Posted by Mart n Ferrari)

Registration is now open for DebConf8, which will take place in Mar del Plata from Sunday 10 to Saturday 16 August 2008. To register follow one of the processes outlined below: After you logged in After you successfully logged in, please fill in at least the General , Contact and Travel tabs reachable through the Registration details button on the bar on the left of the page. Please pay special attention to the DebConf and DebCamp boxes on the General tab. You need to select at least the I want to attend this conference checkbox or your registration won t be valid. Note to users who have an account from last year: We did our best in making sure you do not have to reenter all your personal data again, just the conference specific changes. But please check if it is all still valid. We suggest that attendees begin making travel arrangements as soon as possible. Some travel information has already been collected at the DebConf 8 site. Submitting a paper/event To submit papers, first register for DebConf as described above. Then use the New event/paper button on this page and fill in information about your submission on the various tabs. You can use the same interface to submit papers for DebConf and DebCamp, by choosing the appropriate track.

Daniel Pocock: Automatically building Java projects

Another of the GSoC project areas I have offered to mentor involves automatically and recursively building Java projects. Why is this important? Recently, I decided to start using travis-ci to automatically build some of my Java projects. One of the projects, JMXetric, depends on another, gmetric4j. When travis-ci builds JMXetric, it needs to look in Maven repositories to find gmetric4j (and also remotetea / oncrpc.jar and junit). The alternative to fetching things from repositories is to stop using Maven and ship the binary JARs of dependencies in the JMXetric repository itself, which is not desirable for various reasons. Therefore, I submitted gmetric4j into the Maven Central repository by using the Sonatype Nexus service. One discovery I made in this process disturbed me: Sonatype allows me to sign and upload my binary JAR, they don't build it from source themselves, so users of the JAR have no way to know that it really is built from the source I publish in Github. In fact, as anybody who works with Java knows, there is no shortage of Java projects out there that have a mix of binary dependencies in their source tree, sometimes without any easy way to find the dependency sources. HermesJMS is one popular example that is crippled by the inclusion of some JARs that are binary-only. No silver bullet, but there is hope Although there are now tens of thousands of JAR libraries out there in repositories and projects that depend on them (and their transitive dependencies and build tools and such), there is some hope:
  • Many JARs provide a -source JAR including source. This doesn't include all of the build artifacts of a true source package or source tarball, it just provides a subset of the source for use with a debugger.
  • Many Maven pom.xml files now include metadata about where the source is located - example
With that in mind, I'm hopeful that a system could be developed to scrape some of these data sources to find some source code and properly build some subset of the thousands of JARs available in the Maven Central Repository. But why bother if you can't completely succeed? One recent post on maven-users suggested that because nobody would ever be able to build 100% of JARs from source, the project is already doomed to failure. Personally, I feel it is quite the opposite: by failing to build 100% of JARs from source, the project will help to pinpoint those hierarchies of JARs that are not really free software and increase pressure on their publishers to adhere to the standards that people reasonably expect for source distribution or provide a red flag to help dependant projects stop using them. On top of that, the confirmation of true free-software status for many other JARs will make it safer for people to rely on them, package them and distribute them in various ways. Dumping a gazillion new Java packages into Debian Just to clear up one point: being able to automatically build JARs from source (or a chain of dependencies involving hundreds of them) doesn't mean they will be automatically uploaded to the official Debian archive by a Debian Developer (DD). Having this view of the source will make it easier for a DD to look at a set of JARs and decide if they are suitable for packaging, but there would still be some manual oversight involved. The tool would simply take out some of the tedious manual steps (where possible) and give the DD the ability to spot traps (JARs without real source hidden in the dependency hierarchy) much more quickly. How would it work? The project - whether completed under GSoC or by other means - would probably be broken down into a few discrete components. Furthermore, it would utilize some existing tools where possible. All of this makes it easier for a student to focus on and complete some subset of the work even if the whole thing is quite daunting. Here are some of the ideas for the architecture of the solution and the different components to be used or developed:
  • The data set:
    • A database schema, tracking each binary artifact, the source repository location (e.g. Git or SVN URL), source tarball location, source JAR availability and dependency relationships (including versions)
    • A local Maven repository - only containing JARs that we have built locally from some source
    • A set of Git repositories to mirror the upstream repositories of projects that need to be tweaked.
  • Tool set:
    • A web interface or command line tool would be necessary for a user to kick-start the process by specifying some artifact they want to build
    • There would need to be a script that tries to work out all the possible ways to get the source for an artifact (e.g. by looking for a Git URL in the pom.xml from the Maven Central repository). This script would be able to do other things, like identifying the existence of -source JARs which may or may not be sufficient to build the artifact.
    • A script would need to be created for testing the artifact's source tarball or repository for binary artifacts (e.g. copies of junit.jar). Whenever such things were found, the script would mirror the repository into our local git and create a branch with binaries removed. A record of the binaries would be added to the local database so we can symlink them from a trusted source when building.
    • A script would need to be created for testing whether the project includes a recognised build system (such as build.xml for ant or pom.xml for Maven). For projects without such artifacts, the script would need to generate a template build.xml and store it in a local clone of the repository
    • Jenkins would be used to build the JARs. A script would need to be created to build the Jenkins job config file for the artifact, pointing Jenkins to the upstream Git or the local Git repository depending upon the situation.
    • If the project is a Maven or Ivy project, then there are likely to be attempts to find dependencies during the build process. Running under Jenkins, these tools would be configured in such a way that they only look to the local repository and use dependencies that we have already built. If the build fails during dependency resolution, this is where the recursive process would kick off: the attempt to find each missing dependency would be logged to a queue, and the requests in this queue would each be handled by restarting the whole process again at the beginning. Each of these requests would also be logged to the database.
    • Sometimes, the system would be unable to proceed (e.g. because there are no clues about source locations in a given pom.xml). A user interface would need to be constructed to show a list of artifacts with exceptions and allow the user to manually locate the source and supply the URLs. The system would then continue iterating with this new data.
  • Reporting: we already know that for some JARs, we will simply fail to make any progress and we are not going to lose any sleep over that. The important thing is to provide accurate reports to help people make decisions that may involve working around those JARs in future:
    • For what percentage of projects could we determine the license from the pom.xml? Reports on licensing: can we spot any license mismatch in the dependency hierarchy?
    • Tools: which build tools in the chain of dependencies don't provide any source code? Are they optional tools (such as code quality analysis) that we can skip in the build process (e.g. by producing a mock version of the tool or plugin)?
    • Which non-free/sourceless JARs are most widely depended upon by other projects in the free Java eco-system? Can we make a list of the top 10 or 20?
    • Abandonware: can we detect JARs that haven't been updated for an extended period of time, with no activity in the source repository? For these projects in particular, it is a really good idea to make backups of the source repositories (or mirrors of their web sites and source download directories) in case they disappear altogether.

Rog rio Brito: More completed MOOCs

This weekend I received my 17th certification (or Statement of Accomplishment) for MOOCs. In particular, this last MOOC that I took was Creative, Serious and Playful Science of Android Apps, offered by Lawrence Angrave of University of Illinois at Urbana-Champaign. While I certainly knew that the course was an Introduction to Programming, the reasons I took it were twofold:
  1. For the "novelty" (for me, at least) of writing some Android Apps
  2. To reacquaint myself with Java, which I have not touched since 1999, when I wrote a compiler, in the ages of JDK 1.0 being transitioned to JDK 1.1.
I think that the time the course took (and which I invested in) was really well spent. In fact, I learned some nice things which I would not have touched otherwise. For instance, I made the conscious effort to use an IDE (Eclipse), despite being a person that would do most of the things inside Emacs and compile the programs with command-line tools. Despite being huge, Eclipse has some really nice features and the auto-completion is amazing. Since Java is so strongly typed and Eclipse knows Java pretty well, it almost completely writes your programs for you. :) Of course, my interest also made me want to streamline the build process and use the command line tools (with ant, another tool that was "alien" to me, having used makefiles for everything that I needed). The use of Eclipse (and the Android development environment in general) in my Debian unstable computers was not without problems, but after spending more time trying to fix Eclipse than really doing the homework (and pulling the little hair that I still have left), one really helpful post nailed it. (Yes, I had to remove other packages like gimp, but such is life). While playing with the Android side of things, I put one badly written (and not really "android-ish") app in a github repository (which I think is aptly named "Toy Android Apps"), which served me the purpose of learning some Android-specific concepts. But the course was helpful not only to get in touch with the tools (Eclipse, ant, running Android virtual machines with the help of kvm), but also on the Java side. I lost a bit of the prejudice against it (even though I still think it is a verbose language, especially when compared to, say Python), and I, also intend to contribute to one apache project or another that have low-hanging fruits. Actually, I have signed their Contributor License Agreement and I even had my first patch accepted! Aside: Well, sadly SVN doesn't support different committer and author fields like git does and it seems that doing many small commits may not be the Apache way of doing things but the important part of all this is that the code is there and there is so much more to be done. Aside #2: After a lot of time spent converting the repository to git (which is, after all, what I use), I put a mirror of Apache's the commons graph project.

2 March 2014

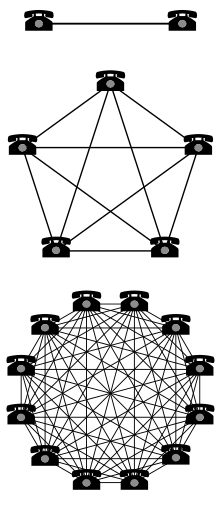
Daniel Pocock: Google Summer of Code opportunities in JavaScript, HTML5, jQuery and WebRTC

WebRTC is one of the highlights of HTML5. The latest stable releases of Google Chrome (including the free Chromium browser) and Firefox include support for this technology and although the specifications are still being finalized, this is the time when developers can start preparing the first generation of web-apps that will define the future of this technology. The JSCommunicator project aims to make it easy to integrate WebRTC into existing web applications. It provides a high-level API on top of the popular JsSIP SIP stack for JavaScript. The JSCommunicator API provides basic dialing and call control features, allowing you to focus on the application level rather than the SIP level. The configuration file suggests many possible ways it can be deployed and customized without any coding at all. The popular DruCall module for the Drupal CMS provides a practical demonstration of how JSCommunicator can be embedded in other products, multiplying the power of WebRTC for millions of other web developers, bloggers, online shops and other sites. This part of the DruCall source code provides a practical demonstration of how JSCommunicator integrates with PHP and this demonstrates how we extract the parameters from PHP in the JavaScript and convert them to the JSCommunicator configuration object. Practical deployments of WebRTC today The student selected for this GSoC project will focus on two practical, real-world deployments of JSCommunicator: It is particularly important to think about ways to make this technology useful for the Debian Developer community in the pursuit of Debian's work. Not just for Debian A communication product is not much use if there is nobody to talk to. The optimal outcome of this project may involve helping two or three additional free software communities to build portals similar to https://rtc.debian.org so that they can interact with Debian and each other using Federated SIP. As Metcalfe's Law explains, this outcome would be a win-win situation for everybody. Metcalfe's Law - Network effect Mentors needed too The more diverse the mentoring community, the more positive outcomes we can achieve with this project. If you would like to be part of a mentoring team for this project, please email me and subscribe to the Debian SOC co-ordination email list. There is no strict requirement for all mentors in the team to be full Debian Developers and emerging technology like this clearly needs people with strengths in a range of different areas. Get started now For general ideas about getting selected for Google Summer of Code, please see the comments at the bottom of my earlier blog post about Ganglia projects For this project in WebRTC in particular, please:
  • Review the project brief on the Debian wiki
  • Discuss your ideas on the JsSIP Google group
  • Send an email to introduce yourself on the Debian SOC co-ordination email list and give a link to your post on the JsSIP list
  • You must complete a coding test. Please see the open bug list for JSCommunicator, complete one of these tasks and submit a pull request on Github. Please send an email to the JsSIP Google group to discuss your pull request.
  • Explain what features you would create during the summer
  • Explain which other tools or libraries you would like to use
  • Give examples of previous work you have done with HTML and JavaScript
  • Explain how your participation will benefit Debian, free software and the wider world. Give some practical examples.
  • If you are interested in other JavaScript and jQuery opportunities for GSoC 2014, please also read more about the web components in the Ganglia project - if you apply for both Debian and Ganglia, you only have to complete one coding test as part of your application.

1 March 2014

Sune Vuorela: Diploma thesis about media choice and usage in Free Software communities: I need your help

My hard-working KDE friend Mario asked me to help him to get Debian people to help him with his thesis. Here is what he writes: Dear Free Software contributor* I m currently in the process of writing my diploma thesis. I ve worked hard during the last few weeks and months on a questionnaire which shall collect some data for my thesis. Furthermore the data of this survey will be interesting for the Free Software communities as well. So please take some time or add it to your todo list or, even better, go directly to my questionnaire and help me make a great diploma thesis and improve the Free Software community in some ways. The questionnaire takes some 20 to 30 minutes. At the end of the questionnaire you ll find a way to participate in a draw where you can even win something nice. In a first round I got the feedback that the length of the questionnaire and that some questions (mostly the ones at the beginning of the questionnaire about the 12 different tasks) are quite abstract and difficult. But please try it, try your best and take the time and brain power. The remaining part of the questionnaire [1] (after these two pages with the tasks questions) is quite
easy and quickly done. And you have the possibility to come back to where you
have left filling in the questionnaire after a shorter or longer break. And if there are any questions, feedback or you need help don t hesitate a moment to write me an email or ping me on IRC (freenode.net and oftc.net) as unormal. This survey will be open till Sunday, the 9th of March 2014, 23.59 UTC. Thanks to all for reading and helping and towards the summer of 2014 you can read here what all the data you gave me showed us and where we can learn and improve. Thanks in advance and best regards
Mario Fux * By contributor I mean not just developers but translators, artist, usability
people, documentation writers and many more. Everybody who contributes in one
way or the other to Free Software.

Next.

Previous.