Search Results: "ag"

6 April 2022

Jonathan Dowland: Stanley Kubrick's A Clockwork Orange (Music From The Soundtrack)

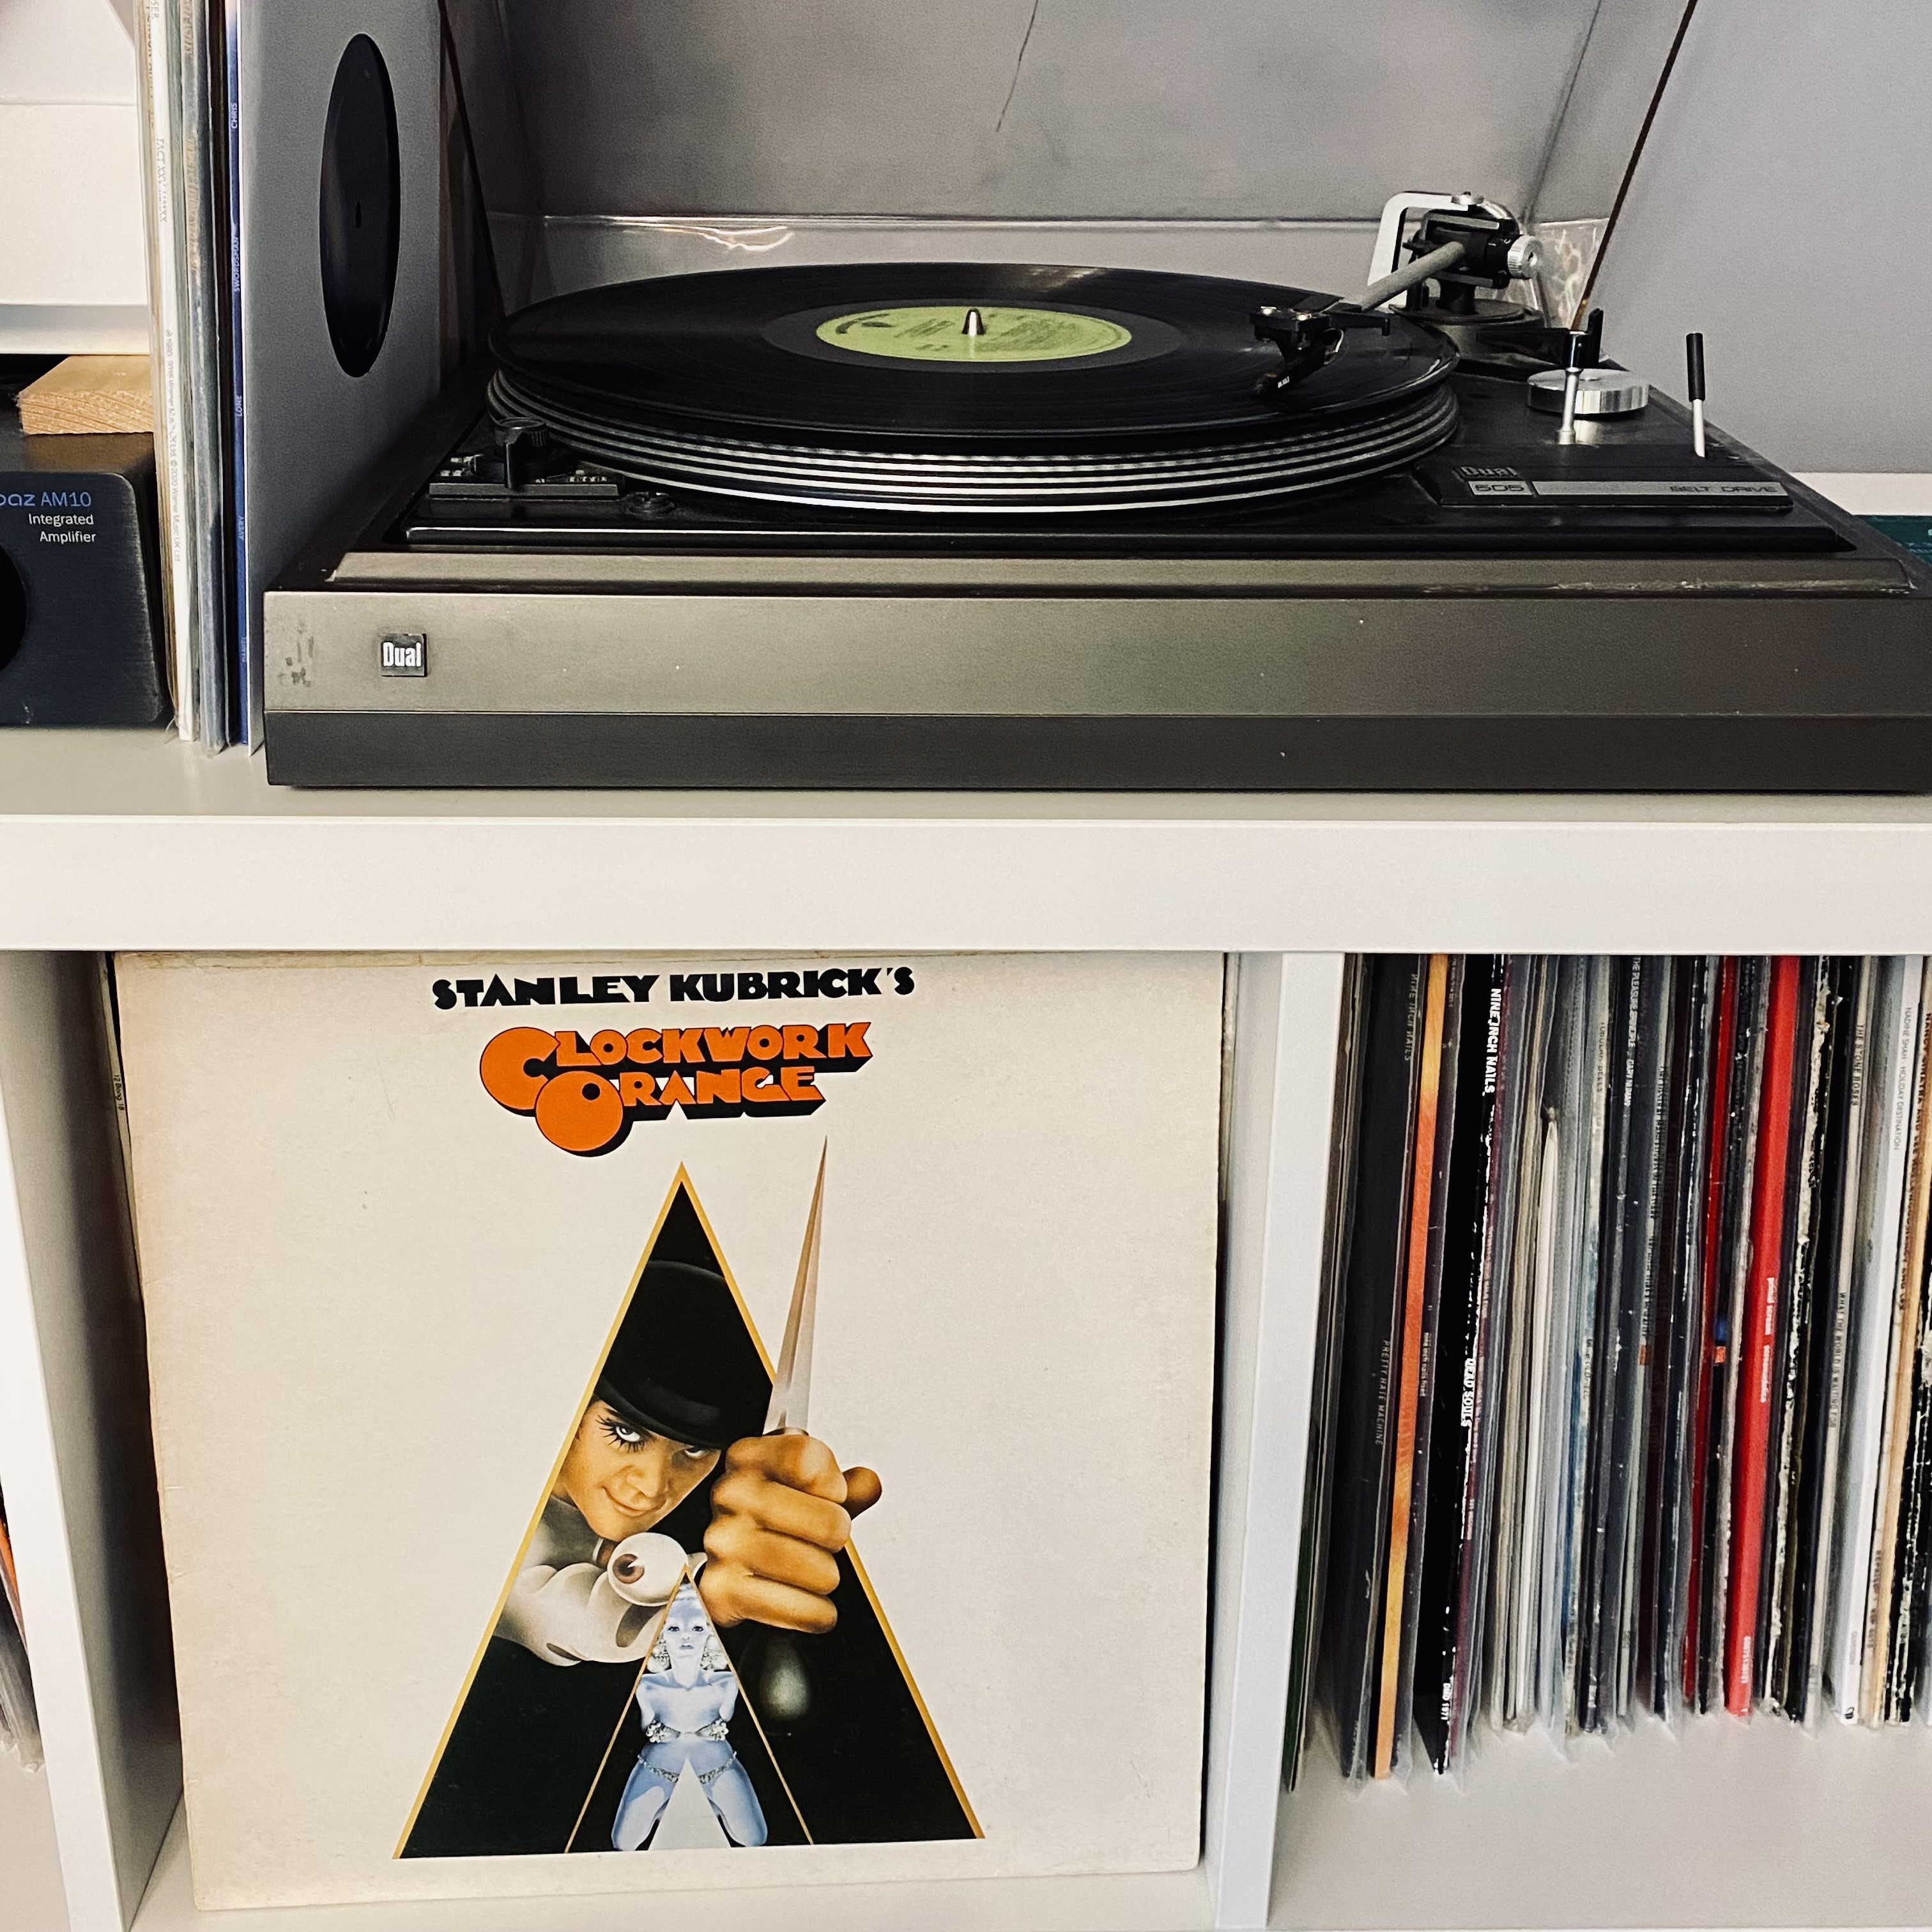
I was reminded of this record over the weekend, as Radio 4's Front Row was discussing the 50th anniversary of Kubrick's movie. To me, the soundtrack has a strange, whimsical, almost cynical element to it (especially with the selection of things like Pomp and Circumstance), but I was familiar with the movie before the soundtrack and it might just be the association that triggers those feelings.
Picture of 'A Clockwork Orange' vinyl record playing on my turntable
I think I picked this up at Tynemouth Market when I lived close by, but I'm not sure. I am sure I didn't pay much for it. Mine is a UK re-pressing from 1971. The abridged (and sped-up) version of William Tell Overture is great for getting the kids to complete a task. Burgess's novel (now 60 years old) has been on my to-read pile for years. in 2018 Electronic Sound magazine featured a cover-mount CD "New Clockwork Music" of music inspired by this soundtrack: It's very good. I must dig that out

Jonathan Dowland: Death from Above

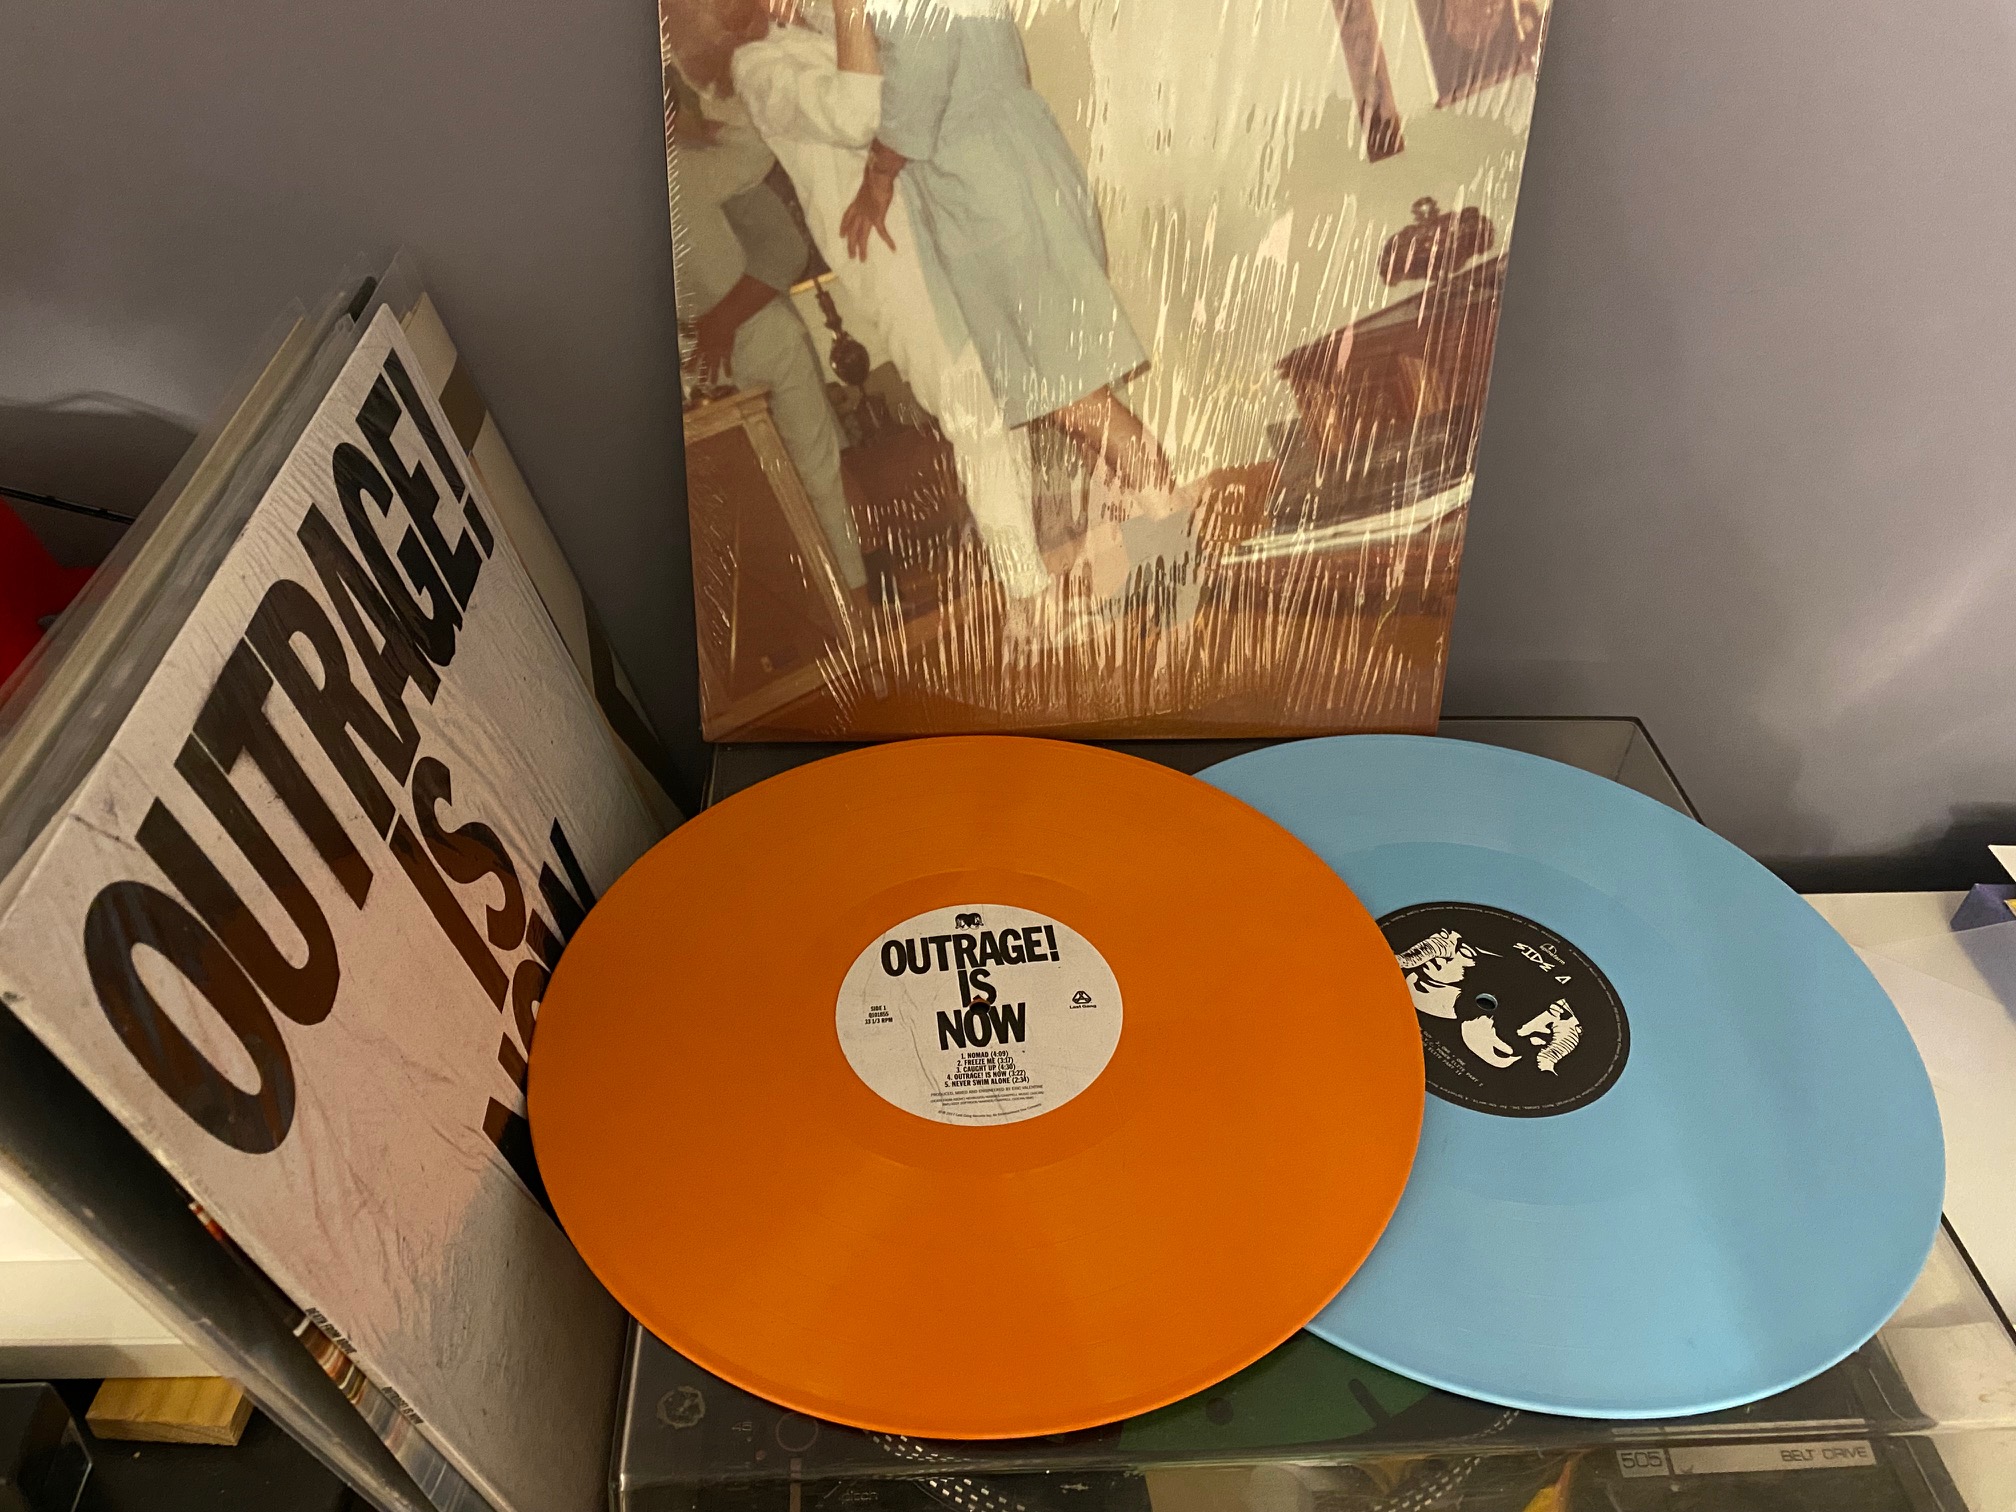
picture of two vinyl records
I received the last two Death From Above albums at Christmas and this weekend managed to give the first (Outrage Is Now) a spin. Pretty colours! They remain one of the best bands to see live. Last time I saw them in a support slot in Newcastle. My friend Rob, a man of few words said I wouldn t want to have to follow them on stage!

Jonathan Dowland: My Life In The Bush Of Ghosts

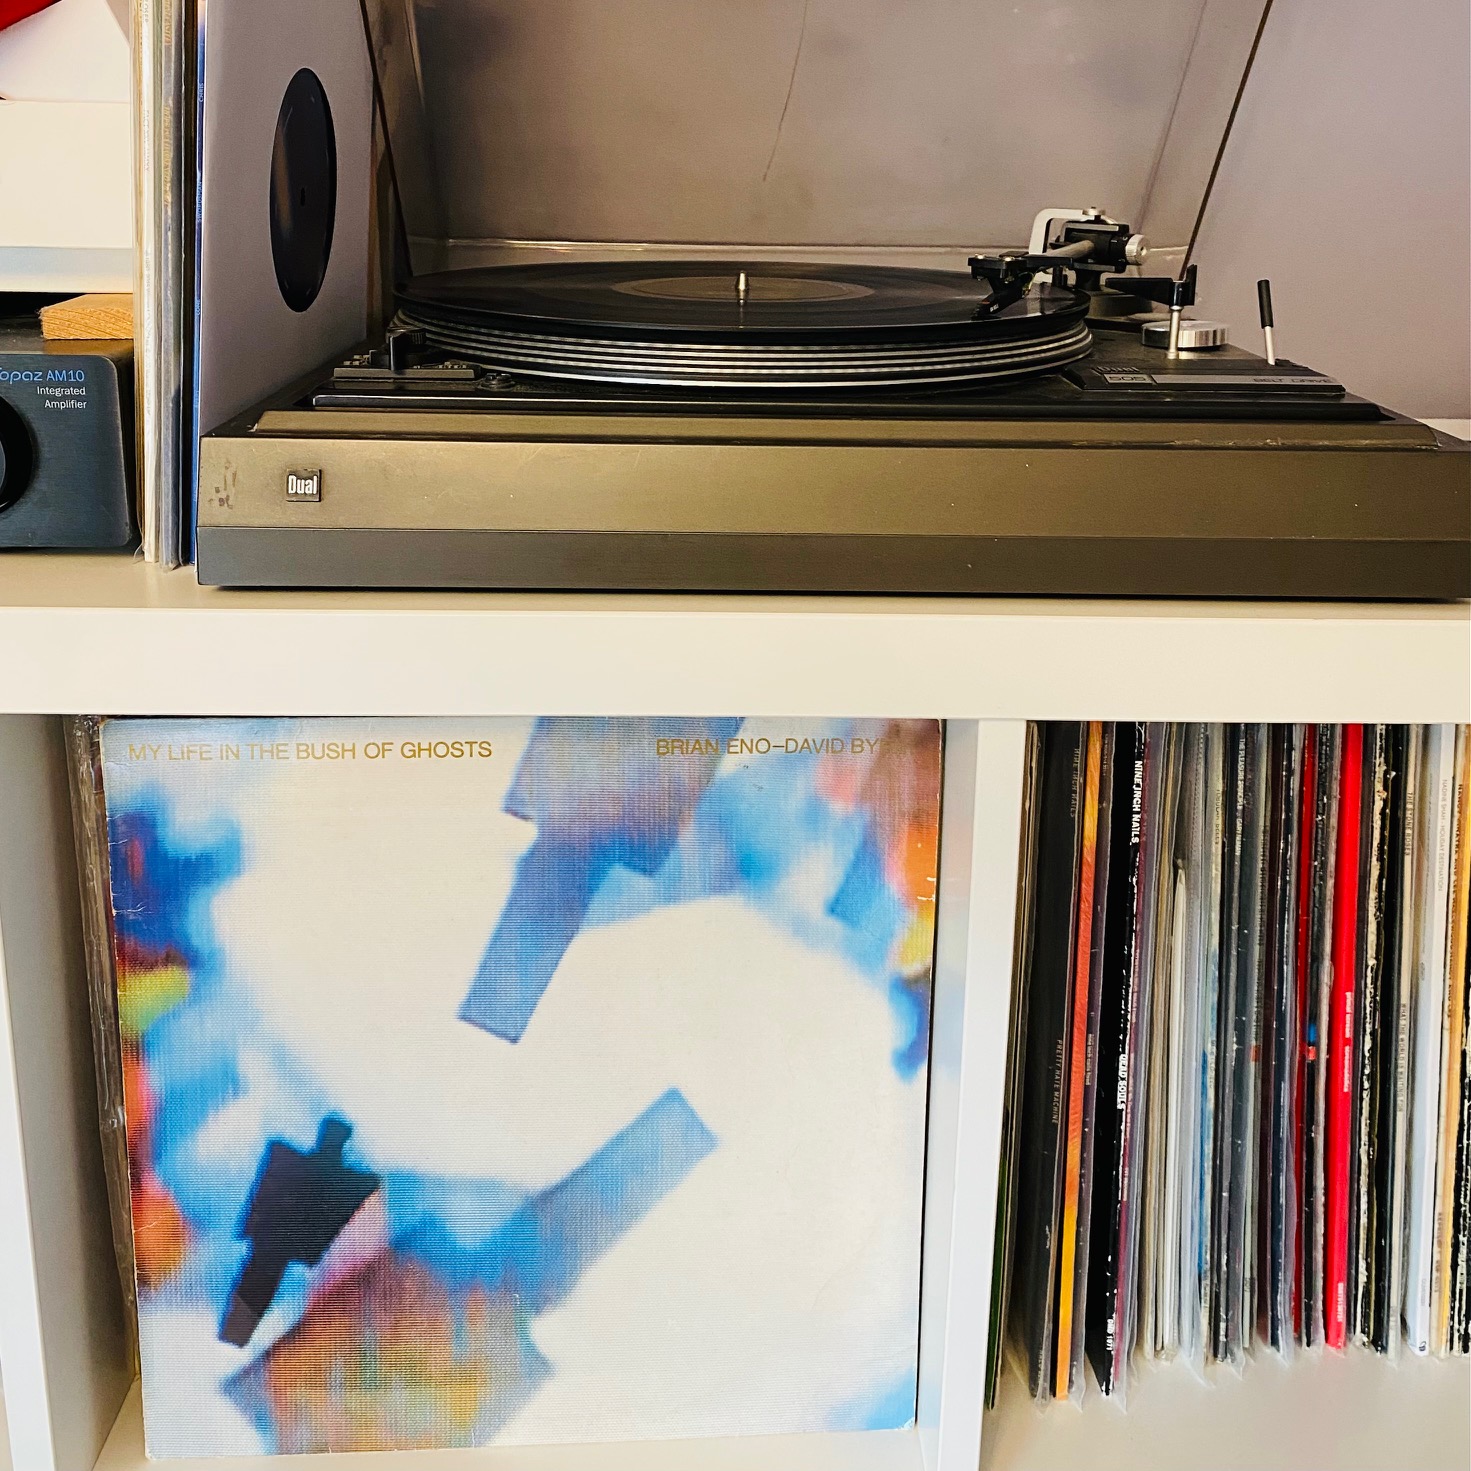
Photo of the record playing next to its cover.
My Life In The Bush Of Ghosts is a weird sound-collage-style album by Brian Eno and David Byrne, released in 1981. It has African-inspired rhythms layered with lots of samples from American radio and TV. It sounds almost like a field recording of the United States was made by wildlife surveyors. My copy is the UK first pressing which includes the track "Qu'ran" which was removed from later editions (and re-instated again later on). I previously wrote about uploading multitracks for two tracks from this album to archive.org.

Jonathan Dowland: One, by Be

picture of a vinyl record
The sublime One, by Be is a pastoral, English summer time instrumental improvisation around field recordings and the theme of the honey bee. A lovely piece to accompany deep thinking. I m reminded of Virginia Astley. Be are associated with Caught by the River, a collective who explore ways of setpping out of daily digital live and embrace, nature, walks, calm, etc.

5 April 2022

Matthew Garrett: Bearer tokens are just awful

As I mentioned last time, bearer tokens are not super compatible with a model in which every access is verified to ensure it's coming from a trusted device. Let's talk about that in a bit more detail.

First off, what is a bearer token? In its simplest form, it's simply an opaque blob that you give to a user after an authentication or authorisation challenge, and then they show it to you to prove that they should be allowed access to a resource. In theory you could just hand someone a randomly generated blob, but then you'd need to keep track of which blobs you've issued and when they should be expired and who they correspond to, so frequently this is actually done using JWTs which contain some base64 encoded JSON that describes the user and group membership and so on and then have a signature associated with them so whenever the user presents one you can just validate the signature and then assume that the contents of the JSON are trustworthy.

One thing to note here is that the crypto is purely between whoever issued the token and whoever validates the token - as far as the server is concerned, any client who can just show it the token is just fine as long as the signature is verified. There's no way to verify the client's state, so one of the core ideas of Zero Trust (that we verify that the client is in a trustworthy state on every access) is already violated.

Can we make things not terrible? Sure! We may not be able to validate the client state on every access, but we can validate the client state when we issue the token in the first place. When the user hits a login page, we do state validation according to whatever policy we want to enforce, and if the client violates that policy we refuse to issue a token to it. If the token has a sufficiently short lifetime then an attacker is only going to have a short period of time to use that token before it expires and then (with luck) they won't be able to get a new one because the state validation will fail.

Except! This is fine for cases where we control the issuance flow. What if we have a scenario where a third party authenticates the client (by verifying that they have a valid token issued by their ID provider) and then uses that to issue their own token that's much longer lived? Well, now the client has a long-lived token sitting on it. And if anyone copies that token to another device, they can now pretend to be that client.

This is, sadly, depressingly common. A lot of services will verify the user, and then issue an oauth token that'll expire some time around the heat death of the universe. If a client system is compromised and an attacker just copies that token to another system, they can continue to pretend to be the legitimate user until someone notices (which, depending on whether or not the service in question has any sort of audit logs, and whether you're paying any attention to them, may be once screenshots of your data show up on Twitter).

This is a problem! There's no way to fit a hosted service that behaves this way into a Zero Trust model - the best you can say is that a token was issued to a device that was, around that time, apparently trustworthy, and now it's some time later and you have literally no idea whether the device is still trustworthy or if the token is still even on that device.

But wait, there's more! Even if you're nowhere near doing any sort of Zero Trust stuff, imagine the case of a user having a bunch of tokens from multiple services on their laptop, and then they leave their laptop unlocked in a cafe while they head to the toilet and whoops it's not there any more, better assume that someone has access to all the data on there. How many services has our opportunistic new laptop owner gained access to as a result? How do we revoke all of the tokens that are sitting there on the local disk? Do you even have a policy for dealing with that?

There isn't a simple answer to all of these problems. Replacing bearer tokens with some sort of asymmetric cryptographic challenge to the client would at least let us tie the tokens to a TPM or other secure enclave, and then we wouldn't have to worry about them being copied elsewhere. But that wouldn't help us if the client is compromised and the attacker simply keeps using the compromised client. The entire model of simply proving knowledge of a secret being sufficient to gain access to a resource is inherently incompatible with a desire for fine-grained trust verification on every access, but I don't see anything changing until we have a standard for third party services to be able to perform that trust verification against a customer's policy.

Still, at least this means I can just run weird Android IoT apps through mitmproxy, pull the bearer token out of the request headers and then start poking the remote API with curl. It may all be broken, but it's also got me a bunch of bug bounty credit, so, it;s impossible to say if its bad or not,

(Addendum: this suggestion that we solve the hardware binding problem by simply passing all the network traffic through some sort of local enclave that could see tokens being set and would then sequester them and reinject them into later requests is OBVIOUSLY HORRIFYING and is also probably going to be at least three startup pitches by the end of next week)

comment count unavailable comments

Dirk Eddelbuettel: RcppSpdlog 0.0.8 on CRAN: Upstream Update

A new version 0.0.8 of RcppSpdlog is now on CRAN. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. This release brings a new upstream release 1.10.0 of spdlog. The (minimal) NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.8 (2022-04-04)
  • Upgraded to upstream releases spdlog 1.10.0

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page, or the package documention site. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RcppArmadillo 0.11.0.0.0 on CRAN: Upstream Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 972 other packages on CRAN, downloaded over 24 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 465 times according to Google Scholar. This release brings a new upstream release 11.0.0. We tested this very rigorously via three different RC release each of which got a full reverse-dependencies run (for which results are always logged here). The full set of changes (since the last CRAN release 0.10.8.1.0) follows.

Changes in RcppArmadillo version 0.11.0.0 (2022-04-04)
  • Upgraded to Armadillo release 11.0.0 (Creme Brulee)
    • added variants of inv() and inv_sympd() that provide rcond (reciprocal condition number)
    • expanded inv() and inv_sympd() with options inv_opts::tiny and inv_opts::allow_approx
    • stricter handling of singular matrices by inv() and inv_sympd()
    • stricter handling of non-sympd matrices by inv() and inv_sympd()
    • stricter handling of non-finitie matrices by pinv()
    • more robust handling of rank deficient matrices by solve()
    • faster handling of diagonal matrices by rcond()
    • changed eigs_sym() and eigs_gen() to use higher quality RNG
    • quantile() and median() will now throw an exception if given matrices/vectors have NaN elements
    • workaround for yet another bug in Intel MKL
  • Until May 2022, protect correction to Field behavior via define of RCPP_ARMADILLO_FIX_Field
  • If a LAPACK installation with missing complex routines is found (as e.g. Ubuntu using 3.9.0) then the LAPACK unit test is skipped.

Changes in RcppArmadillo version 0.10.8.2.0 (2022-02-01)
  • Upgraded to Armadillo release 10.8.2 (Realm Raider)
    • fix potential speed regression in pinv() and rank()

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Kees Cook: security things in Linux v5.10

Previously: v5.9 Linux v5.10 was released in December, 2020. Here s my summary of various security things that I found interesting: AMD SEV-ES
While guest VM memory encryption with AMD SEV has been supported for a while, Joerg Roedel, Thomas Lendacky, and others added register state encryption (SEV-ES). This means it s even harder for a VM host to reconstruct a guest VM s state. x86 static calls
Josh Poimboeuf and Peter Zijlstra implemented static calls for x86, which operates very similarly to the static branch infrastructure in the kernel. With static branches, an if/else choice can be hard-coded, instead of being run-time evaluated every time. Such branches can be updated too (the kernel just rewrites the code to switch around the branch ). All these principles apply to static calls as well, but they re for replacing indirect function calls (i.e. a call through a function pointer) with a direct call (i.e. a hard-coded call address). This eliminates the need for Spectre mitigations (e.g. RETPOLINE) for these indirect calls, and avoids a memory lookup for the pointer. For hot-path code (like the scheduler), this has a measurable performance impact. It also serves as a kind of Control Flow Integrity implementation: an indirect call got removed, and the potential destinations have been explicitly identified at compile-time. network RNG improvements
In an effort to improve the pseudo-random number generator used by the network subsystem (for things like port numbers and packet sequence numbers), Linux s home-grown pRNG has been replaced by the SipHash round function, and perturbed by (hopefully) hard-to-predict internal kernel states. This should make it very hard to brute force the internal state of the pRNG and make predictions about future random numbers just from examining network traffic. Similarly, ICMP s global rate limiter was adjusted to avoid leaking details of network state, as a start to fixing recent DNS Cache Poisoning attacks. SafeSetID handles GID
Thomas Cedeno improved the SafeSetID LSM to handle group IDs (which required teaching the kernel about which syscalls were actually performing setgid.) Like the earlier setuid policy, this lets the system owner define an explicit list of allowed group ID transitions under CAP_SETGID (instead of to just any group), providing a way to keep the power of granting this capability much more limited. (This isn t complete yet, though, since handling setgroups() is still needed.) improve kernel s internal checking of file contents
The kernel provides LSMs (like the Integrity subsystem) with details about files as they re loaded. (For example, loading modules, new kernel images for kexec, and firmware.) There wasn t very good coverage for cases where the contents were coming from things that weren t files. To deal with this, new hooks were added that allow the LSMs to introspect the contents directly, and to do partial reads. This will give the LSMs much finer grain visibility into these kinds of operations. set_fs removal continues
With the earlier work landed to free the core kernel code from set_fs(), Christoph Hellwig made it possible for set_fs() to be optional for an architecture. Subsequently, he then removed set_fs() entirely for x86, riscv, and powerpc. These architectures will now be free from the entire class of kernel address limit attacks that only needed to corrupt a single value in struct thead_info. sysfs_emit() replaces sprintf() in /sys
Joe Perches tackled one of the most common bug classes with sprintf() and snprintf() in /sys handlers by creating a new helper, sysfs_emit(). This will handle the cases where kernel code was not correctly dealing with the length results from sprintf() calls, which might lead to buffer overflows in the PAGE_SIZE buffer that /sys handlers operate on. With the helper in place, it was possible to start the refactoring of the many sprintf() callers. nosymfollow mount option
Mattias Nissler and Ross Zwisler implemented the nosymfollow mount option. This entirely disables symlink resolution for the given filesystem, similar to other mount options where noexec disallows execve(), nosuid disallows setid bits, and nodev disallows device files. Quoting the patch, it is useful as a defensive measure for systems that need to deal with untrusted file systems in privileged contexts. (i.e. for when /proc/sys/fs/protected_symlinks isn t a big enough hammer.) Chrome OS uses this option for its stateful filesystem, as symlink traversal as been a common attack-persistence vector. ARMv8.5 Memory Tagging Extension support
Vincenzo Frascino added support to arm64 for the coming Memory Tagging Extension, which will be available for ARMv8.5 and later chips. It provides 4 bits of tags (covering multiples of 16 byte spans of the address space). This is enough to deterministically eliminate all linear heap buffer overflow flaws (1 tag for free , and then rotate even values and odd values for neighboring allocations), which is probably one of the most common bugs being currently exploited. It also makes use-after-free and over/under indexing much more difficult for attackers (but still possible if the target s tag bits can be exposed). Maybe some day we can switch to 128 bit virtual memory addresses and have fully versioned allocations. But for now, 16 tag values is better than none, though we do still need to wait for anyone to actually be shipping ARMv8.5 hardware. fixes for flaws found by UBSAN
The work to make UBSAN generally usable under syzkaller continues to bear fruit, with various fixes all over the kernel for stuff like shift-out-of-bounds, divide-by-zero, and integer overflow. Seeing these kinds of patches land reinforces the the rationale of shifting the burden of these kinds of checks to the toolchain: these run-time bugs continue to pop up. flexible array conversions
The work on flexible array conversions continues. Gustavo A. R. Silva and others continued to grind on the conversions, getting the kernel ever closer to being able to enable the -Warray-bounds compiler flag and clear the path for saner bounds checking of array indexes and memcpy() usage. That s it for now! Please let me know if you think anything else needs some attention. Next up is Linux v5.11.

2022, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

4 April 2022

Ben Hutchings: Debian LTS work, March 2022

In March I was assigned 16 hours of work by Freexian's Debian LTS initiative and carried over 8 hours from February. I worked 16 hours, and will carry over the remaining time to April. I backported the mitigations for Spectre-BHB (CVE-2022-0001, CVE-2022-0002) on x86 processors, to Linux 4.9. I worked together with Salvatore Bonaccorso in preparing the kernel updates that were needed in all suites, and writing advisory text. I uploaded both the linux (4.9) and linux-4.19 packages to stretch, and issued DLA-2940-1 and DLA-2941-1. I also triaged new issues that were reported later in the month.

Arturo Borrero Gonz lez: Wikimedia Toolforge and Grid Engine

Logos This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. One of the most important and successful products provided by the Wikimedia Cloud Services team at the Wikimedia Foundation is Toolforge, a hosting service commonly known in the industry as Platform as a Service (PaaS). In particular, it is a platform that allows users and developers to run and use a variety of applications with the ultimate goal of helping the Wikimedia mission from the technical side. Toolforge is powered by two different backend engines, Kubernetes and Grid Engine. The two backends have traditionally offered different features for tool developers. But as time moves forward we ve learnt that Kubernetes is the future. Explaining why is the purpose of this blog post: we want to share more information and reasoning behind this mindset. There are a number of reasons that make Grid Engine poorly suitable to remain as execution backend in Toolforge:
  • There has not been a new Grid Engine release (bug fixes, security patches, or otherwise) since 2016. This doesn t feel like a project being actively developed or maintained.
  • The grid has poor support and controls for important aspects such as high availability, fault tolerance and self-recovery.
  • Maintaining a healthy grid requires plenty of manual operations, like manual queue cleanups in case of failures, hand-crafted scripts for pooling/depooling nodes, etc.
  • There is no good or modern monitoring support for the grid, and we need to craft and maintain several monitoring pieces for proper observability, and to be able to do proper maintenance.
  • The grid is also strongly tied to the underlying operating system release version. Migrating from one Debian version to the next is painful (a dedicated blog post about this will follow shortly).
  • The grid imposes a strong dependency on NFS, another old technology. We would like to reduce dependency on NFS overall, and in the future we will explore NFS-free approaches for Toolforge.
  • In general, Grid Engine is old software, old technology, which can be replaced by more modern approaches for providing an equivalent or better service.
As mentioned above, our desire is to cover all our grid-like needs with Kubernetes, a technology which has several benefits:
  • Good high availability, fault tolerance and self-recovery semantics, constructs and facilities.
  • Maintaining a running Kubernetes cluster requires little manual operations.
  • There are good monitoring and observability options for Kubernetes deployments, including seamless integration with industry standards like prometheus.
  • Our current approach to deploying and upgrading Kubernetes is independent of the underlying operating system.
  • While our current Kubernetes deployment uses NFS as a central component, there is support for using other, more modern, approaches for the kind of shared storage needs we have in Toolforge.
  • In general, Kubernetes is a modern technology, with a vibrant and healthy community, that enables new use cases and has enough flexibility to adapt legacy ones.
The relationship between Toolforge and Grid Engine has been interesting over the years. The grid has been used for quite a lot of time, we have plenty of documentation and established good practices. On the other hand, the grid is hard to maintain, imposes a heavy burden on the WMCS team and is a technology we must eventually discontinue. How to accommodate the two realities is a refreshing challenge, one that we hope to tackle together in the near future. A tradeoff exists here, but it is clear to us which option is best. So we will work on deprecating and removing Grid Engine and migrating use cases into Kubernetes. This deprecation, however, will be done with care, as we know our technical community relies on the grid for some import Toolforge tools. And some of these workflows will need some adaptation in order to be fully supported on Kubernetes. Stay tuned for more information on present and next works surrounding the Wikimedia Toolforge service. The next blog post will share more concrete details. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

2 April 2022

Ian Jackson: Otter (game server) 1.0.0 released

I have just released Otter 1.0.0. Recap: what is Otter Otter is my game server for arbitrary board games. Unlike most online game systems. It does not know (nor does it need to know) the rules of the game you are playing. Instead, it lets you and your friends play with common tabletop/boardgame elements such as hands of cards, boards, and so on. So it s something like a tabletop simulator (but it does not have any 3D, or a physics engine, or anything like that). There are provided game materials and templates for Penultima, Mao, and card games in general. Otter also supports uploadable game bundles, which allows users to add support for additional games - and this can be done without programming. For more information, see the online documentation. There are a longer intro and some screenshots in my 2021 introductory blog post about Otter Releasing 1.0.0 I m calling this release 1.0.0 because I think I can now say that its quality, reliability and stability is suitable for general use. In particular, Otter now builds on Stable Rust, which makes it a lot easier to install and maintain. Switching web framework, and async Rust I switched Otter from the Rocket web framework to Actix. There are things to prefer about both systems, and I still have a soft spot for Rocket. But ultimately I needed a framework which was fully released and supported for use with Stable Rust. There are few if any Rust web frameworks that are not async. This is rather a shame. Async Rust is a considerably more awkward programming environment than ordinary non-async Rust. I don t want to digress into a litany of complaints, but suffice it to say that while I really love Rust, my views on async Rust are considerably more mixed. Future plans In the near future I plan to add a couple of features to better support some particular games: currency-like resources, and a better UI for dice-like randomness. In the longer term, Otter s, installation and account management arrangements are rather unsophisticated and un-webby. There is not currently any publicly available instance for you to try it out without installing it on a machine of your own. There s not even any provided binaries: you must built Otter yourself. I hope to be able to improve this situation but it involves dealing with cloud CI and containers and so-on, which can all be rather unpleasant. Users on chiark will find an instance of Otter there.

comment count unavailable comments

1 April 2022

Dirk Eddelbuettel: RInside 0.2.17

A new release 0.2.17 of RInside arrived on CRAN and in Debian today. This is the first release in two years since the 0.2.16 release. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by Rcpp. This release brings a minor update for R 4.2.0, due out later this month, and kindly provided by Tomas Kalibera. It updates one function declaration; we wrapped some conditioning around so that RInside continues to build with older releases too. Besides that minor updates were made to continuous integration and some of the package files. The short list of changes since the last release were:

Changes in RInside version 0.2.17 (2022-03-31)
  • A Windows-only patch for R 4.2.0 kindly provided by Tomas Kalibera was applied, and also conditioned on R (>= 4.2.0)
  • Continuous Integration setup was updated and now uses r-ci.
  • Several updates were made to README.md (badges etc) and DESCRIPTION

My CRANberries also provides a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page, or to issues tickets at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russ Allbery: Review: Princess Floralinda and the Forty-Flight Tower

Review: Princess Floralinda and the Forty-Flight Tower, by Tamsyn Muir
Publisher: Subterranean Press
Copyright: 2020
ISBN: 1-59606-992-9
Format: Kindle
Pages: 111
A witch put Princess Floralinda at the top of a forty-flight tower, but it wasn't personal. This is just what witches do, particularly with princesses with butter-coloured curls and sapphire-blue eyes. Princes would come from miles around to battle up the floors of the tower and rescue the princess. The witch even helpfully provided a golden sword, in case a prince didn't care that much about princesses. Floralinda was provided with water and milk, two loaves of bread, and an orange, all of them magically renewing, to sustain her while she waited. In retrospect, the dragon with diamond-encrusted scales on the first floor may have been a mistake. None of the princely endeavors ever saw the second floor. The diary that Floralinda found in her room indicated that she may not be the first princess to have failed to be rescued from this tower. Floralinda finally reaches the rather astonishing conclusion that she might have to venture down the tower herself, despite the goblins she was warned were on the 39th floor (not to mention all the other monsters). The result of that short adventure, after some fast thinking, a great deal of luck, and an unforeseen assist from her magical food, is a surprising number of dead goblins. Also seriously infected hand wounds, because it wouldn't be a Tamsyn Muir story without wasting illness and body horror. That probably would have been the end of Floralinda, except a storm blew a bottom-of-the-garden fairy in through the window, sufficiently injured that she and Floralinda were stuck with each other, at least temporarily. Cobweb, the fairy, is neither kind nor inclined to help Floralinda (particularly given that Floralinda is not a child whose mother is currently in hospital), but it is an amateur chemist and finds both Floralinda's tears and magical food intriguing. Cobweb's magic is also based on wishes, and after a few failed attempts, Floralinda manages to make a wish that takes hold. Whether she'll regret the results is another question. This is a fairly short novella by the same author as Gideon the Ninth, but it's in a different universe and quite different in tone. This summary doesn't capture the writing style, which is a hard-to-describe mix of fairy tale, children's story, and slightly archaic and long-winded sentence construction. This is probably easier to show with a quote:
"You are displaying a very small-minded attitude," said the fairy, who seemed genuinely grieved by this. "Consider the orange-peel, which by itself has many very nice properties. Now, if you had a more educated brain (I cannot consider myself educated; I have only attempted to better my situation) you would have immediately said, 'Why, if I had some liquor, or even very hot water, I could extract some oil from this orange-peel, which as everyone knows is antibacterial; that may well do my hands some good,' and you wouldn't be in such a stupid predicament."
On balance, I think this style worked. It occasionally annoyed me, but it has some charm. About halfway through, I was finding the story lightly entertaining, although I would have preferred a bit less grime, illness, and physical injury. Unfortunately, the rest of the story didn't work for me. The dynamic between Floralinda and Cobweb turns into a sort of D&D progression through monster fights, and while there are some creative twists to those fights, they become all of a sameness. And while I won't spoil the ending, it didn't work for me. I think I see what Muir was trying to do, and I have some intellectual appreciation for the idea, but it wasn't emotionally satisfying. I think my root problem with this story is that Muir sets up a rather interesting world, one in which witches artistically imprison princesses, and particularly bright princesses (with the help of amateur chemist fairies) can use the trappings of a magical tower in ways the witch never intended. I liked that; it has a lot of potential. But I didn't feel like that potential went anywhere satisfying. There is some relationship and characterization work, and it reached some resolution, but it didn't go as far as I wanted. And, most significantly, I found the end point the characters reached in relation to the world to be deeply unsatisfying and vaguely irritating. I wanted to like this more than I did. I think there's a story idea in here that I would have enjoyed more. Unfortunately, it's not the one that Muir wrote, and since so much of my problem is with the ending, I can't provide much guidance on whether someone else would like this story better (and why). But if the idea of taking apart a fairy-tale tower and repurposing the pieces sounds appealing, and if you get along better with Muir's illness motif than I do, you may enjoy this more than I did. Rating: 5 out of 10

Russ Allbery: Updated eyrie Debian archive keyring

For anyone who uses my personal Debian repository (there are fewer and fewer reasons to do that, but there are still some Debian packages there that aren't available anywhere else), I've (finally) refreshed the archive signing key. The new key is available through the eyrie-archive-keyring package as normal. Both the new and the old keys were provided in that package for a while. As of today, the old key has been removed. The key can also be downloaded from my web site.

Russell Coker: Converting to UEFI

When I got my HP ML110 Gen9 working as a workstation I initially was under the impression that boot wasn t supported on NVMe and booted it from USB. I found USB booting with legacy boot to be unreliable so decided to try EFI booting and noticed that the NVMe devices were boot candidates with UEFI. Making one of them bootable was more complex than expected because no-one seems to have documented such things. So here s my documentation, it s not great but this method has worked once for me. Before starting major partitioning work it s best to run parted -l and save the output to a file, that can allow you to recreate partitions if you corrupt them. One thing I m doing on systems I manage is putting @reboot /usr/sbin/parted -l > /root/parted.log in the root crontab, then when the system is backed up the backup server gets any recent changes to partitioning (I don t backup /var/log on all my systems). Firstly run parted on the device to create the EFI and /boot partitions, note that if you want to copy and paste from this you must do so one line at a time, a block paste seemed to confuse parted.
mklabel gpt
mkpart EFI fat32 1 99
mkpart boot ext3 99 300
toggle 1 boot
toggle 1 esp
p
# Model: CT1000P1SSD8 (nvme)
# Disk /dev/nvme1n1: 1000GB
# Sector size (logical/physical): 512B/512B
# Partition Table: gpt
# Disk Flags: 
#
# Number  Start   End     Size    File system  Name  Flags
#  1      1049kB  98.6MB  97.5MB  fat32        EFI   boot, esp
#  2      98.6MB  300MB   201MB   ext3         boot
q
Here are the commands needed to create the filesystems and install the necessary files. This is almost to the stage of being scriptable. Some minor changes need to be made to convert from NVMe device names to SATA/SAS but nothing serious.
mkfs.vfat /dev/nvme1n1p1
mkfs.ext3 -N 1000 /dev/nvme1n1p2
file -s /dev/nvme1n1p2   sed -e s/^.*UUID/UUID/ -e "s/ .*$/ \/boot ext3 noatime 0 1/" >> /etc/fstab
file -s /dev/nvme1n1p1   tr "[a-f]" "[A-F]"  sed -e s/^.*numBEr.0x/UUID=/ -e "s/, .*$/ \/boot\/efi vfat umask=0077 0 1/" >> /etc/fstab
# edit /etc/fstab to put a hyphen between the 2 groups of 4 chars for the VFAT filesystem UUID
mount /boot
mkdir -p /boot/efi /boot/grub
mount /boot/efi
mkdir -p /boot/efi/EFI/debian
apt install efibootmgr shim-unsigned grub-efi-amd64
cp /usr/lib/shim/* /usr/lib/grub/x86_64-efi/monolithic/grubx64.efi /boot/efi/EFI/debian
file -s /dev/nvme1n1p2   sed -e "s/^.*UUID=/search.fs_uuid /" -e "s/ .needs.*$/ root hd0,gpt2/" > /boot/efi/EFI/debian/grub.cfg
echo "set prefix=(\$root)'/boot/grub'" >> /boot/efi/EFI/debian/grub.cfg
echo "configfile \$prefix/grub.cfg" >> /boot/efi/EFI/debian/grub.cfg
grub-install
update-grub
If someone would like to make a script that can handle the different partition names of regular SCSI/SATA disks, NVMe, CCISS, etc then that would be great. It would be good to have a script in Debian that creates the partitions and sets up the EFI files. If you want to have a second bootable device then the following commands will copy a GPT partition table and give it new UUIDs, make very certain that $DISKB is the one you want to be wiped and refer to my previous mention of parted -l . Also note that parted has a rescue command which works very well.
sgdisk /dev/$DISKA -R /dev/$DISKB 
sgdisk -G /dev/$DISKB
To backup a GPT partition table run a command like this. Note that if sgdisk is told to backup a MBR partitioned disk it will say Found invalid GPT and valid MBR; converting MBR to GPT forma which is probably a viable way of converting MBR format to GPT.
sgdisk -b sda.bak /dev/sda

Antoine Beaupr : Salvaged my first Debian package

I finally salvaged my first Debian package, python-invoke. As part of ITS 964718, I moved the package from the Openstack Team to the Python team. The Python team might not be super happy with it, because it's breaking some of its rules, but at least someone (ie. me) is actively working (and using) the package.

Wait what People not familiar with Debian will not understand anything in that first paragraph, so let me expand. Know-it-all Debian developers (you know who you are) can skip to the next section. Traditionally, the Debian project (my Linux-based operating system of choice) has prided itself on the self-managed, anarchistic organisation of its packaging. Each package maintainer is the lord of their little kingdom. Some maintainers like to accumulate lots of kingdoms to rule over. (Yes, it really doesn't sound like anarchism when you put it like that. Yes, it's complicated: there's a constitution and voting involved. And yes, we're old.) Therefore, it's really hard to make package maintainers do something they don't want. Typically, when things go south, someone makes a complaint to the Debian Technical Committee (CTTE) which is established by the Debian constitution to resolve such conflicts. The committee is appointed by the Debian Project leader, elected each year (and there's an election coming up if you haven't heard). Typically, the CTTE will then vote and formulate a decision. But here's the trick: maintainers are still free to do whatever they want after that, in a sense. It's not like the CTTE can just break down doors and force maintainers to type code. (I won't go into the details of the why of that, but it involves legal issues and, I think, something about the Turing halting problem. Or something like that.) Anyways. The point is all that is super heavy and no one wants to go there... (Know-it-all Debian developers, I know you are still reading this anyways and disagree with that statement, but please, please, make it true.) ... but sometimes, packages just get lost. Maintainers get distracted, or busy with something else. It's not that they want to abandon their packages. They love their little fiefdoms. It's just there was a famine or a war or something and everyone died, and they have better things to do than put up fences or whatever. So clever people in Debian found a better way of handling such problems than waging war in the poor old CTTE's backyard. It's called the Package Salvaging process. Through that process, a maintainer can propose to take over an existing package from another maintainer, if a certain set of condition are met and a specific process is followed. Normally, taking over another maintainer's package is basically a war declaration, rarely seen in the history of Debian (yes, I do think it happened!), as rowdy as ours is. But through this process, it seems we have found a fair way of going forward. The process is basically like this:
  1. file a bug proposing the change
  2. wait three weeks
  3. upload a package making the change, with another week delay
  4. you now have one more package to worry about
Easy right? It actually is! Process! It's magic! It will cure your babies and resurrect your cat!

So how did that go? It went well! The old maintainer was actually fine with the change because his team wasn't using the package anymore anyways. He asked to be kept as an uploader, which I was glad to oblige. (He replied a few months after the deadline, but I wasn't in a rush anyways, so that doesn't matter. It was polite for him to answer, even if, technically, I was already allowed to take it over.) What happened next is less shiny for me though. I totally forgot about the ITS, even after the maintainer reminded me of its existence. See, the thing is the ITS doesn't show up on my dashboard at all. So I totally forgot about it (yes, twice). In fact, the only reason I remembered it was that got into the process of formulating another ITS (1008753, trocla) and I was trying to figure out how to write the email. Then I remembered: "hey wait, I think I did this before!" followed by "oops, yes, I totally did this before and forgot for 9 months". So, not great. Also, the package is still not in a perfect shape. I was able to upload the upstream version that was pending 1.5.0 to clear out the ITS, basically. And then there's already two new upstream releases to upload, so I pushed 1.7.0 to experimental as well, for good measure. Unfortunately, I still can't enable tests because everything is on fire, as usual. But at least my kingdom is growing.

Appendix Just in case someone didn't notice the hyperbole, I'm not a monarchist promoting feudalism as a practice to manage a community. I do not intend to really "grow my kingdom" and I think the culture around "property" of "packages" is kind of absurd in Debian. I kind of wish it would go away. (Update: It has also been pointed out that I might have made Debian seem more confrontational than it actually is. And it's kind of true: most work and interactions in Debian actually go fine, it's only a minority of issues that degenerate into conflicts. It's just that they tend to take up a lot of space in the community, and I find that particularly draining. And I think think our "package ownership" culture is part of at least some of those problems.) Team maintenance, the LowNMU process, and low threshold adoption processes are all steps in the good direction, but they are all opt in. At least the package salvaging process is someone a little more ... uh... coercive? Or at least it allows the community to step in and do the right thing, in a sense. We'll see what happens with the coming wars around the recent tech committee decision, which are bound to touch on that topic. (Hint: our next drama is called "usrmerge".) Hopefully, LWN will make a brilliant article to sum it up for us so that I don't have to go through the inevitable debian-devel flamewar to figure it out. I already wrecked havoc on the #debian-devel IRC channel asking newbie questions so I won't stir that mud any further for now. (Update: LWN, of course, did make an article about usrmerge in Debian. I will read it soon and can then tell you know if it's brilliant, but they are typically spot on.)

Paul Wise: FLOSS Activities March 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review
  • Spam: reported 3 Debian bug reports and 53 Debian mailing list posts
  • Debian wiki: RecentChanges for the month
  • Debian BTS usertags: changes for the month
  • Debian screenshots:

Administration
  • Debian servers: investigate wiki mail delivery issue, restart backup director
  • Debian wiki: unblock IP addresses, approve accounts

Communication
  • Forward python-plac test failure issue upstream
  • Participate in Debian Project Leader election discussions
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The oci-python-sdk and plac work was sponsored. All other work was done on a volunteer basis.

31 March 2022

Matthew Garrett: ZTA doesn't solve all problems, but partial implementations solve fewer

Traditional network access controls work by assuming that something is trustworthy based on some other factor - for example, if a computer is on your office network, it's trustworthy because only trustworthy people should be able to gain physical access to plug something in. If you restrict access to your services to requests coming from trusted networks, then you can assert that it's coming from a trusted device.

Of course, this isn't necessarily true. A machine on your office network may be compromised. An attacker may obtain valid VPN credentials. Someone could leave a hostile device plugged in under a desk in a meeting room. Trust is being placed in devices that may not be trustworthy.

A Zero Trust Architecture (ZTA) is one where a device is granted no inherent trust. Instead, each access to a service is validated against some policy - if the policy is satisfied, the access is permitted. A typical implementation involves granting each device some sort of cryptographic identity (typically a TLS client certificate) and placing the protected services behind a proxy. The proxy verifies the device identity, queries another service to obtain the current device state (we'll come back to that in a moment), compares the state against a policy and either pass the request through to the service or reject it. Different services can have different policies (eg, you probably want a lax policy around whatever's hosting the documentation for how to fix your system if it's being refused access to something for being in the wrong state), and if you want you can also tie it to proof of user identity in some way.

From a user perspective, this is entirely transparent. The proxy is made available on the public internet, DNS for the services points to the proxy, and every time your users try to access the service they hit the proxy instead and (if everything's ok) gain access to it no matter which network they're on. There's no need to connect to a VPN first, and there's no worries about accidentally leaking information over the public internet instead of over a secure link.

It's also notable that traditional solutions tend to be all-or-nothing. If I have some services that are more sensitive than others, the only way I can really enforce this is by having multiple different VPNs and only granting access to sensitive services from specific VPNs. This obviously risks combinatorial explosion once I have more than a couple of policies, and it's a terrible user experience.

Overall, ZTA approaches provide more security and an improved user experience. So why are we still using VPNs? Primarily because this is all extremely difficult. Let's take a look at an extremely recent scenario. A device used by customer support technicians was compromised. The vendor in question has a solution that can tie authentication decisions to whether or not a device has a cryptographic identity. If this was in use, and if the cryptographic identity was tied to the device hardware (eg, by being generated in a TPM), the attacker would not simply be able to obtain the user credentials and log in from their own device. This is good - if the attacker wanted to maintain access to the service, they needed to stay on the device in question. This increases the probability of the monitoring tooling on the compromised device noticing them.

Unfortunately, the attacker simply disabled the monitoring tooling on the compromised device. If device state was being verified on each access then this would be noticed before too long - the last data received from the device would be flagged as too old, and the requests would no longer satisfy any reasonable access control policy. Instead, the device was assumed to be trustworthy simply because it could demonstrate its identity. There's an important point here: just because a device belongs to you doesn't mean it's a trustworthy device.

So, if ZTA approaches are so powerful and user-friendly, why aren't we all using one? There's a few problems, but the single biggest is that there's no standardised way to verify device state in any meaningful way. Remote Attestation can both prove device identity and the device boot state, but the only product on the market that does much with this is Microsoft's Device Health Attestation. DHA doesn't solve the broader problem of also reporting runtime state - it may be able to verify that endpoint monitoring was launched, but it doesn't make assertions about whether it's still running. Right now, people are left trying to scrape this information from whatever tooling they're running. The absence of any standardised approach to this problem means anyone who wants to deploy a strong ZTA has to integrate with whatever tooling they're already running, and that then increases the cost of migrating to any other tooling later.

But even device identity is hard! Knowing whether a machine should be given a certificate or not depends on knowing whether or not you own it, and inventory control is a surprisingly difficult problem in a lot of environments. It's not even just a matter of whether a machine should be given a certificate in the first place - if a machine is reported as lost or stolen, its trust should be revoked. Your inventory system needs to tie into your device state store in order to ensure that your proxies drop access.

And, worse, all of this depends on you being able to put stuff behind a proxy in the first place! If you're using third-party hosted services, that's a problem. In the absence of a proxy, trust decisions are probably made at login time. It's possible to tie user auth decisions to device identity and state (eg, a self-hosted SAML endpoint could do that before passing through to the actual ID provider), but that's still going to end up providing a bearer token of some sort that can potentially be exfiltrated, and will continue to be trusted even if the device state becomes invalid.

ZTA doesn't solve all problems, and there isn't a clear path to it doing so without significantly greater industry support. But a complete ZTA solution is significantly more powerful than a partial one. Verifying device identity is a step on the path to ZTA, but in the absence of device state verification it's only a step.

comment count unavailable comments

Russell Coker: AMT/MEBX on Debian

I ve just been playing with Intel s Active Management Technology (AMT) [1] which is also known as Management Engine Bios Extension (MEBX). Firstly a disclaimer, using this sort of technology gives remote access to your system at a level that allows in some ways overriding the OS. If this gets broken then you have big problems. Also all the code that matters is non-free. Please don t comment on this post saying that AMT is bad, take it as known that it has issues and that people are forced to use it anyway. I tested this out on a HP Z420 workstation. The first thing it to enable AMT via Intel MEBX , the default password is admin . On first use you are compelled to set a new password which must be 8+ characters containing upper and lower case, number, and punctuation characters. The Debian package amtterm (which needs the package libsoap-lite-perl ) has basic utilities for AMT. The amttool program connects to TCP port 16992 and the amtterm program connects to TCP port 16994. Note that these programs seem a little rough, you can get Perl errors (as opposed to deliberate help messages) if you enter bad command-line parameters. They basically work but could do with some improvement. If you use DHCP for the IP address the DHCP hostname will be DESKTOP-$AssetID and you can find the IP address by requesting an alert be sent to the sysadmin. Here are some examples of amttool usage:
# get AMT info
AMT_PASSWORD="$PASS" amttool $IP
# reset the system and redirect BIOS messages to serial over lan
AMT_PASSWORD="$PASS" amttool reset bios
# access serial over lan console
amtterm -p "$PASS" $IP
The following APT configuration enables the Ubuntu package wsmancli which had some features not in any Debian packages last time I checked.
deb http://us.archive.ubuntu.com/ubuntu/ bionic-updates universe
deb http://us.archive.ubuntu.com/ubuntu/ bionic universe
This Cyberciti article has information on accessing KVM over AMT [2], I haven t tried to do that yet.

Russell Coker: Links March 2022

Anarcat wrote a great blog post about switching from OpenNTP to Chrony which gives a good overview of how NTP works and how accurate the different versions are [1]. Bleeping Computer has an amusing article about criminals who copied a lot of data from NVidia servers including specs of their latest products [2], they are threatening to release all the data if NVidia doesn t stop crippling their GPUs to make them unsuitable for crypto currency mining. I don t support these criminals, but I think NVidia should allow people who buy hardware to use their property as they choose. If cryptocurrency miners buy all the NVidia products then NVidia still makes the sales, they could even auction them to make more money. NPR has a disturbing article about the way execution by lethal injection works in the US [3]. It seems that most people die in an extremely unpleasant way. It makes the North Korean execution by anti-aircraft gun seem civilised. The DirtyPipe vulnerability is the latest serious security issue in the Linux kernel [4]. The report of how it was discovered is very interesting and should be read by all sysadmins. SE Linux will not save you from this as the vulnerability allows writing to read-only files like /etc/passwd. Politico has an insightful analysis of Putin, it s not good news he wants to conquer all territory that had ever been part of a Russian empire at any time in history [5]. The Guardian has an informative article about the EU s attempts to debunk Russian propaganda about Covid19 [6]. Fortunately the sanctions are reducing Russia s ability to do such things now. The Guardian has in interesting article about a project to use literary analysis to predict wars [7]. Funded by the German military but funding was cut after it was proven to work. The Fact Act is a proposal by David Brin for political changes in the US to involve scientists and statisticians in an official advisory role in the legislative process [8], it s an idea with a lot of potential. Technology Review has an interesting interview with the leader of the NSA s Research Directorate [9]. In 2008 the EFF posted a long and informative article about the RIAA s war against music fans [10]. I had followed a lot of the news about this when it was happening, but I still learnt some things from this article that I hadn t known at the time. Also considering past legal battles in the context of the current situation is useful. As an aside all the music I want to listen to is now on YouTube and youtube-dl works really well for me. The 1952 edition of Psychiatry: Journal of Interpersonal Relations has an interesting article On Cooling the Mark Out [11] which starts about how criminal gangs engaged in fraud try to make their victims come to terms with the loss in a way that doesn t involve the police. But it goes on to cover ways of dealing with loss of status in general. The layout is hacky with words broken by hyphens in the middle of lines as it appears to have been scanned from paper, converted to MS-Word, and from there to PDF. But it s worth it. The Internet Heist by Cory Doctorow is an insightful series of 3 articles about the MPAA (MAFIAA) attempts to take over all TV distribution in the US [12]. Wired has an interesting exerpt from the book Spies, Lies, and Algorithms: The History and Future of American Intelligence , by Amy B. Zegart [13]. Interesting summary of the open source intelligence systems (which have nothing to do with open source as free software). But it would be interesting to have an open source intelligence organisation along similar lines to open source software. The guy who tracks billionaire s private jets is an example of this.

Next.

Previous.