Search Results: "spa"

14 August 2015

Dirk Eddelbuettel: Rblpapi: Connecting R to Bloomberg

big deal Whit, John and I are thrilled to announce Rblapi, a new CRAN package which connects R to the Bloomberg backends. Rebuilt from scratch using only the Bloomberg C++ API and the Rcpp and BH packages, it offers efficient and direct access from R to a truly vast number of financial data series, pricing tools and more. The package has been tested on Windows, OS X and Linux. As is standard for CRAN packages, binaries for Windows and OS X are provided (or will be once the builders caught up). Needless to say, a working Bloomberg installation is required to use the package. Please see the Rblapi package page for more details, including a large part of the introductory vignette document. As a teaser, here are just three of the core functions:
## Bloomberg Data Point Query
bdp(c("ESA Index", "SPY US Equity"), c("PX_LAST", "VOLUME"))
## Bloomberg Data Set Query
bds("GOOG US Equity", "TOP_20_HOLDERS_PUBLIC_FILINGS")
## Bloomberg Data History Query
bdh("SPY US Equity", c("PX_LAST", "VOLUME"), start.date=Sys.Date()-31)
## Get OHLCV bars (by default hourly and just six of them)
getBars("ES1 Index")
## Get Tick Data (by default last hour)
getTicks("ES1 Index")
Source code for the package is at the Rblpapi GitHub repo where issue tickets can be filed as well. The sibbling blp GitHub repo contains the Bloomberg code required to build and link the package (which is automated during the build of the CRAN package). Last but not least the Rblpapi package page has more details about the package.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Norbert Preining: QMapShack GPS and Maps on Linux

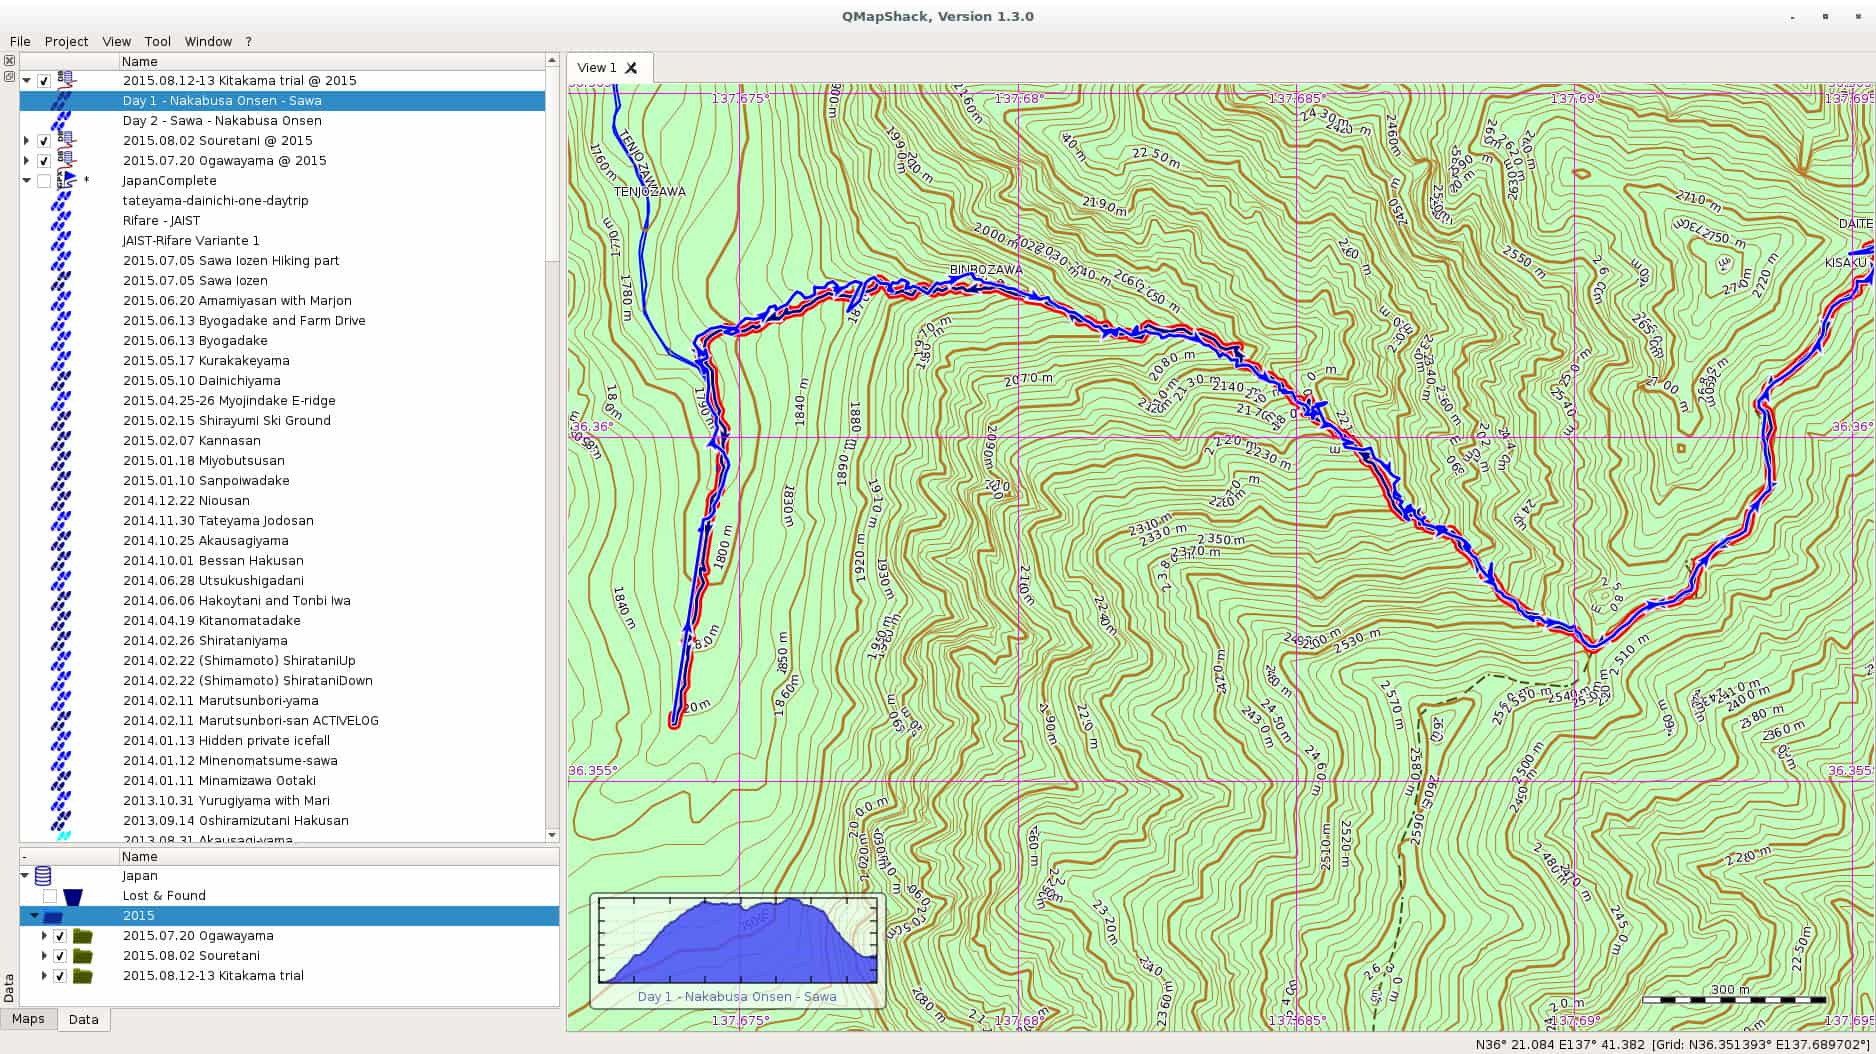
In one of the comments on my last post on Windows 10, a friendly reader from my home country pointed me at QMapShack as a replacement for QuoVadis. I have been using QuoVadis now for many many years, and it contains my mountaineering history all the way back. All the guiding work, all the track. QuoVadis is a great program, able to work with various commercial digital maps as well as GPS receivers. It only has one disadvantage, it doesn t work on Linux. QMapShack is very similar in the target audience, but very different in usage. The one big difference is of course the set of maps one can use with QMapShack. Fortunately, Garmin Maps are supported, and since all my maps regarding Japan are Garmin maps, I am now in the process to converting to QMapShack at least for my Japan GPS data. qmapshack Let us start with the program I was using since ages, and still are using, QuoVadis. QuoVadis is a great program, there is nothing to complain. It is extremely feature-rich, and above all it can work with many different maps. While working as mountain guide in Europe it was an essential tool for me. I could use the digital raster maps of Austria, Switzerland (SwissTOPO), Germany, France, Italy, as well as Garmin vector maps. For serious work as a professional it was indispensable for me. Unfortunately, it never worked on Linux. For some time I had a VirtualBox installation of Windows, but that was more a clutch than anything else. So for most of the GPS work I had to reboot my laptop to Windows, do my stuff there, and then switch back to Linux. QMapShack is far from as feature rich as QuoVadis, but as far as I see now, it does have enough features for me and my mountaineering in Japan. Dealing with GPS units is not a problem, this is the easy part. The difficult part are the digital maps. Fortunately, QMapShack supports Garmin vector maps, the only maps that are (as far as I know) available digitally for Japan. Getting used to QMapShack is a bit a challenge coming from QuoVadis, but the Wiki help pages allowed a quick start. Within short time I had maps set up. Next step was to download a data from my last weekend trip to Yarigadake, Kitakama-ridge (unfortunately we had to turn back due to rain). Connecting the unit and mounting it was already enough to show up in QMapShack, and allowed me to copy the tracks to my local database. Next I switched to Windows and exported some tracks from my Japan folder to a gpx file. After rebooting to Linux, I loaded the gpx file into QMapShack and without failure all the tracks and routes showed up, as it can be seen in the above screenshot (click on it to get a bigger version). Also the display of the Garmin map worked perfectly. Update: Please see the comment section for explanation of the necessary functions. QMapShack does provide similar functionality. Thanks to Oliver for pointing me at it! After some time of working there are a few functions from QuoVadis I am missing for now at QMapShack: Although these two functionalities are missing, all in all I am very happy for now with QMapShack. My next steps are: Finally, above all, I see a future where I do not need to reboot into Windows for doing my GPS work. For now I will import all the data into both applications, but if QMapShack holds its promises from the first day of usage, I am confident that this will not be necessary in future. Enjoy.

12 August 2015

Elena 'valhalla' Grandi: Printing a 2965 lines text file

Printing a 2965 lines text file

Let us image I have a reason https://people.debian.org/~anibal/ksp-dc15/ksp-dc15.html to print a text file that is 2965 lines long, is encoded in utf-8 (so a2ps and enscript don't work) and I don't want to destroy a whole forest for it.

I've started by using xelatex to get a nicely typeset A5 page with my file in a monospaced font: partecipants.tex

\documentclass[a5paper] article
\usepackage fontspec
\usepackage[left=1cm,right=1cm,top=0.8cm,bottom=1cm,foot=0.2cm] geometry
\usepackage listings

\lstset %
basicstyle=\ttfamily\scriptsize,
frame=none,
keepspaces=true,


\begin document
\lstinputlisting ksp-dc15.txt
\end document


This gets compiled into partecipants.pdf with


$ xelatex partecipants.tex


And resulted in 44 pages, 4 less than the 48 needed by a2ps, and printable on just 11 A4 sheets.

I wanted it to be easily manageable while walking around, taking notes into it while standing, so I decided to arrange it in booklet form:


$ pdfbook partecipants.pdf


The result, partecipants-book.pdf was printed (two sided, of course) folded and stitched in the middle.

I could have arranged it into signatures, but this would have required an additional sheet to bring the number of pages to a multiple of 16.

I know that there are electronic alternatives around, and I've also considered just carrying around the file and adding notes (to a copy?) with vim, but I'd trust a paper copy more.

Daniel Pocock: Recording live events like a pro (part 2: video)

In the first blog in this series, we looked at how to capture audio effectively for a range of different events. While recording audio appears less complicated than video, it remains fundamental to a good recording. For some types of event, like a speech or a debate, you can have quite a bad video with poor lighting and other defects but people will still be able to watch it if the audio is good. Therefore, if you haven't already looked at the previous blog, please do so now. As mentioned in the earlier blog, many people now have high quality equipment for recording both audio and video and a wide range of opportunities to use it, whether it is a talk at a conference, a wedding or making a Kickstarter video. The right camera for video recording The fundamental piece of equipment is the camera itself. You may have a DSLR camera that can record video or maybe you have a proper handheld video camera. The leading DSLR cameras, combined with a good lens, make higher quality recordings than many handheld video cameras. Unfortunately, although you pay good money to buy a very well engineered DSLR that could easily record many hours of video, most DSLRs are crippled to record a maximum of 30 minutes in one recording. This issue and some workarounds are discussed later in this blog. If you don't have any camera at all you need to think carefully about which type to buy. If you are only going to use it once you may want to consider renting or borrowing or asking for other people attending the event to bring whatever cameras they have to help make multiple recordings (the crowdsourcing solution). If you are a very keen photographer then you will probably have a preference for a DSLR. Accessories Don't just look at the cost of your camera and conclude that is all the budget you need. For professional quality video recording, you will almost certainly need some accessories. You may find they are overpriced at the retail store where you bought your camera, but you still need some of them, so have a look online.
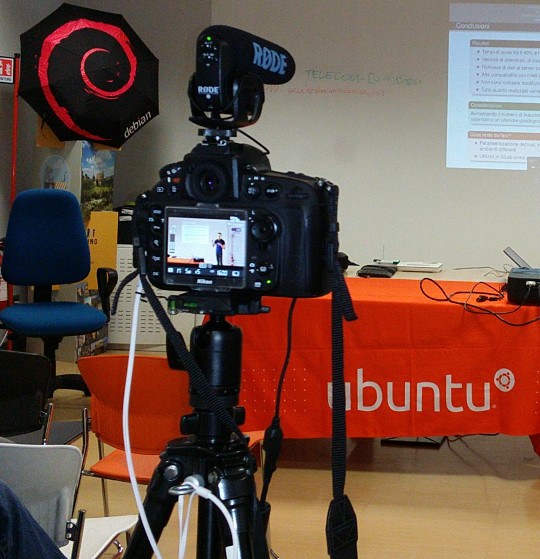
Recording a talk at a free software event with a Nikon D800 on a very basic tripod with Rode VideoMic Pro, headphones (white cable) and external power (black cable) If you want to capture audio with the camera and record it in the video file (discussed in more detail below), you will need to purchase a microphone that mounts on the camera. The built-in microphones on cameras are often quite bad, even on the most expensive cameras. If you are just using the built-in microphone for reference audio (to help with time synchronization when you combine different audio files with the video later) then the built-in microphone may be acceptable. Camera audio is discussed in more detail below. If your camera has a headphone socket, get some headphones for listening to the audio. Make sure you have multiple memory cards. Look carefully at the speed of the memory cards, slow ones are cheaper but they can't keep up with the speed of writing 1080p video. At a minimum, you should aim to buy memory cards that can handle one or two days worth of data for whatever it is you do. A tripod is essential for most types of video. If you use a particularly heavy camera or lens or if you are outdoors and it may be windy you will need a heavier tripod for stability. For video, it is very useful to have a tripod with a handle for panning left and right but if the camera will be stationary for the whole recording then the handle is not essential. Carrying at least one spare battery is another smart move. On one visit to the Inca Trail in Peru, we observed another member of our group hiking up and down the Andes with a brand new DSLR that they couldn't use because the battery was flat. For extended periods of recording, batteries will not be sufficient and you will need to purchase a mains power supply (PSU). These are available for most types of DSLR and video camera. The camera vendors typically design cameras with unusual power sockets so that you can only use a very specific and heavily overpriced PSU from the same company. Don't forget a surge protector too. There are various smartphone apps that allow you to remotely control the camera from the screen of your phone, such as the qDslrDashboard app. These often give a better preview than the screen built-in to the camera and may even allow you to use the touch screen to focus more quickly on a specific part of the picture. A regular USB cable is not suitable for this type of app, you need to buy a USB On-The-Go (OTG) cable.
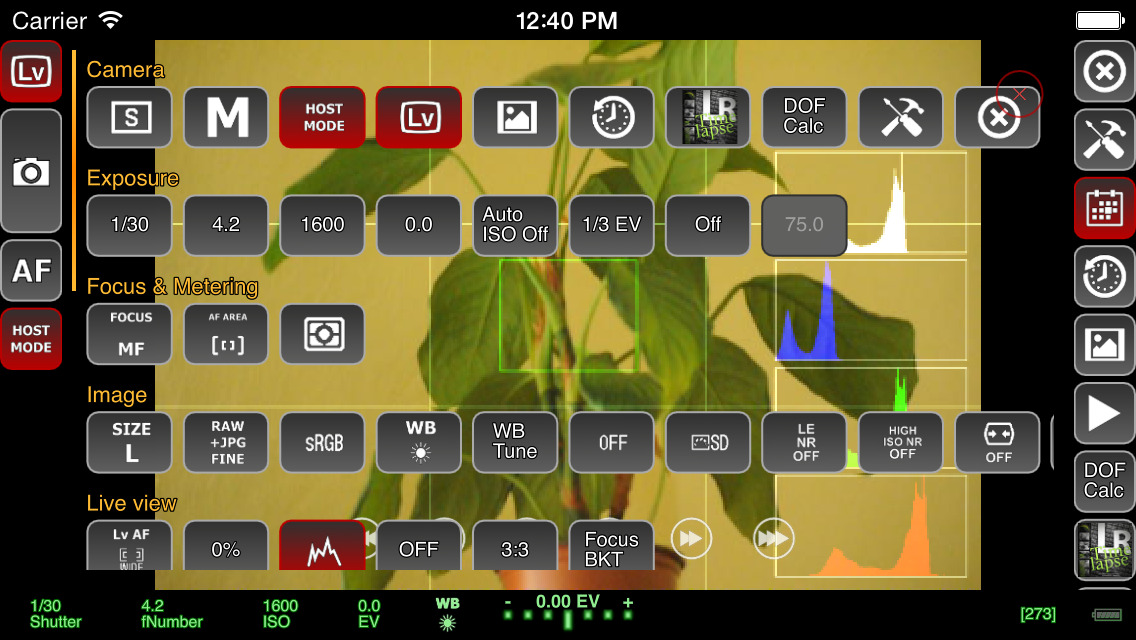
Screenshot of qDslrDashboard app on a smartphone, controlling a DSLR camera If you plan to copy the video from the camera to a computer at the event, you will need to make sure you have a fast memory card reader. The memory card readers in some laptops are quite slow and others can be quite fast so you may not need to buy an extra card reader. Camera audio Most cameras, including DSLRs, have a built-in microphone and a socket for connecting an external microphone. The built-in microphones obtain very poor quality sound. For many events, it is much better to have independent microphones, such as a lapel microphone attached to a smartphone or wireless transmitter. Those solutions are described in part one of this blog series. Nonetheless, there are still some benefits of capturing audio in the camera. The biggest benefit is the time synchronization: if you have audio recordings in other devices, you will need to align them with the video using post-production software. If the camera recorded an audio stream too, even if the quality is not very good, you can visualize the waveform on screen and use it to align the other audio recordings much more easily and precisely. If the camera will be very close to the people speaking then it may be acceptable to use a microphone mounted on the camera. This will be convenient for post-production because the audio will be synchronized with the video. It may still not be as good as a lapel microphone though, but the quality of these camera-mounted microphones is still far higher than the built-in microphones. I've been trying the Rode VideoMic Pro, it is definitely better than recording with the built-in microphone on the camera and also better than the built-in microphone on my phone. One problem that most people encounter is the sound of the lens autofocus mechanism being detected by the microphone. This occurs with both the built-in microphone and any other microphone you mount on the camera. A microphone mounted on top of the camera doesn't detect this noise with the same intensity as the built-in microphone but it is still present in the recordings. If using a camera-mounted microphone to detect the audio from an audience, you may need to have an omnidirectional microphone. Many camera-mounted microphones are directional and will not detect very much sound from the sides or behind the camera. When using any type of external microphone with the camera, it is recommend to disable automatic gain control (AGC) in the camera settings and then manually adjust the microphone sensitivity/volume level. Use headphones A final word on audio - most good cameras have an audio output socket. Connect headphones and wear them, to make sure you are always capturing audio. Otherwise, if the microphone's battery goes flat or if a wireless microphone goes out of range you may not notice. Choosing a lens The more light you get, the better. Bigger and more expensive lenses allow more light into the camera. Many of the normal lenses sold with a DSLR camera are acceptable but if it is a special occasion you may want to rent a more expensive lens for the day. If you already have a lens, it is a very good idea to test it in conditions similar to those you expect for the event you want to record. Recording duration limits Most DSLR cameras with video capability impose a 30 minute maximum recording duration This is basically the result of a friendly arrangement between movie studios and politicians to charge an extra tax on video recording technology and potentially make the movie studio bosses richer, supposedly justified by the fact that a tiny but exaggerated number of people use their cameras to record movies at the cinema. As a consequence, most DSLR manufacturers limit the duration of video recording so their product won't be subject to the tax, ensuring the retail price is lower and more attractive. On top of this, many DSLR cameras also have a 4GB file size limit if they use the FAT filesystem. Recording 1080p video at a high frame rate may hit the file size limit in 10 minutes, well before you encounter the 30 minute maximum recording duration. To deal with the file size issue, you can record at 720p instead of 1080p and use the frame rate 24fps. For events longer than 30 minutes or where you really want 1080p or a higher frame rate, there are some other options you can consider:
  • Buy or rent a proper video camera instead of using a DSLR camera
  • Using multiple cameras that can stop and be restarted at different times.
  • Manually stopping and restarting the camera if there are breaks in the event where it is safe to do so.
  • Use an app to control the camera and program it to immediately restart the recording each time it stops
  • Extract the raw output from the camera's HDMI socket and record into some other device or computer. There are several purpose-built devices
    that can be used this way with an embedded SSD for storage.
  • There are also some people distributing unofficial/alternative firmware images that remove the artificial 30 minute recording limit.
Camera settings There are many online tutorials and demonstration videos on YouTube that will help you optimize the camera settings for video. You may have already made recordings using the automatic mode. Adjusting some or all of the settings manually may help you create a more optimal recording. You will need to spend some time familiarizing yourself with the settings first. The first thing to check is white balance. This tells the camera the type of lighting in the location. If you set this incorrectly then the colours will be distorted. Many cameras have the ability to automatically set the white balance. For video, you may be able to change one or more settings that control the recording quality. These settings control the file compression ratio and image size. Typical image size settings are 720p and 1080p. Compression ratio may be controlled by a high/medium/low quality setting. Choosing the highest quality and biggest picture requires more space on the memory card and also means you reach the 4GB file size limit more quickly. A higher quality setting also implies a faster memory card is required, because the rate of megabytes per second written to the memory card is higher. Next you need to think about the frame rate. Events that involve fast moving subjects, such as sports, typically benefit from a higher frame rate. For other events it is quite acceptable to use 24 frames per second (fps). Higher frame rates also imply bigger file size and a requirement for a faster memory card. Once you have decided on the frame rate, the next thing to do is set the shutter speed. Use a shutter speed that is double the frame rate. For example, if using 24fps or 25fps, use a 1/50 shutter speed. The final two settings you need to adjust are the ISO and aperture. Set these based on the lighting conditions and extent to which the subjects are moving. For example, if the setting is dark or if you are trying to record fast moving subjects like athletes, vehicles or animals, use an ISO value of 800 or higher. Once you have chosen ISO, adjust the aperture to ensure the picture is sufficiently illuminated. Aperture also has a significant impact on the depth of field. Operating the camera: zoom and focus Many people use zoom lenses. It is not always necessary to change the zoom while recording a video, you can use software to zoom in and out on individual parts of the picture when editing it in post-production. If you do change the zoom while recording, it may be more difficult to maintain focus. Almost all lenses support manual focus (turning the focus ring by hand) and many support automatic focus. When shooting photographs with a DSLR, the mirror is down and the camera can use dedicated sensors for focus and light sensing. When shooting video, the mirror is up and the camera can not use the same focus sensors that are used in photography. Video recording uses a digital focussing algorithm based on contrast in the picture. If you take a lot of photos you are probably quite accustomed to the fast and precise autofocus for photography and you will notice that keeping a video in focus is more challenging. As mentioned already, one of the first things you can do to keep focus simple is to avoid zooming while recording. Record in a higher resolution than you require and then zoom with software later. Some people record using 4k resolution even when they only want to produce a 720p video, as they can digitally zoom in to different parts of the 4k recording without losing detail. If the subject is very stationary (people sitting at a desk for an interview is a typical example), you may be able to set the camera to manual focus and not change it at all while recording. If you choose to enable autofocus while recording, any built-in camera microphone or microphone mounted on the camera is likely to detect sounds from the motorized focus system. Ultimately, the autofocus mechanism is not accurate for all subjects and you may be unable to stop them moving around so you will need to change the focus manually while recording. It requires some practice to be able to do this quickly without overshooting the right focus. To make life more tricky, Nikon and Canon focus rings rotate in the opposite direction, so if you are proficient using one brand you may feel awkward if you ever have to use the other. A good way to practice this skill is to practice while in the car or on the train, pointing at different subjects outside the window and trying to stay in focus as you move from one subject to the next. Make a trial run Many events, from weddings right up to the Olympic Games opening ceremony, have a trial run the day before. One reason for that is to test the locations and settings of all the recording and broadcasting equipment. If a trial run isn't possible for your event, you may find some similar event to practice recording and test your equipment. For example, if you are planning to record a wedding, you could try and record a Sunday mass in the same church. Backup and duplicate the recordings before leaving the event If you only have one copy of the recordings and the equipment is stolen or damaged you may be very disappointed. Before your event, make a plan to duplicate the raw audio and video recordings so that several people can take copies away with them. Decide in advance who will be responsible for this, ensure there will be several portable hard disks and estimate how much time it will take to prepare the copies and factor this into the schedule. Conclusion All the products described can be easily purchased from online retailers. You may not need every accessory that is mentioned as it depends on the type of event you record. The total cost of buying or renting the necessary accessories may be as much as the cost of the camera itself so if you are new to this you may need to think carefully about making a budget with a spreadsheet to do it correctly. Becoming familiar with the camera controls and practicing the techniques for manual focus and zoom can take weeks or months. If you enjoy photography this can be time well spent but if you don't enjoy it then you may not want to commit the time necessary to make good quality video. Don't rule out options like renting equipment instead of buying it or crowdsourcing, asking several participants or friends to help make recordings with their own equipment. For many events, audio is far more indispensable than video and as emphasizing at the beginning of this article, it is recommended that you should be one hundred percent confident in your strategy for recording audio before you start planning to record video.

10 August 2015

Carl Chenet: Retweet, a simple bot to retweet tweets from a user

Follow me on Identi.ca or Twitter or Diaspora*diaspora-banner For a small project related to the french-speaking Hacker News-style website le Journal du hacker, I needed to retweet every tweets from a Twitter account to another one. So here it is : Retweet I wanted to keep it simple, stupid, and coded in Python if I needed to extend it myself for the projet Le Journal du hacker. logo-journal-du-hacker It was quite easy to reach these goals, but the project is also well documented and should be quite simple to install, configure and use. What about you? Do you also have this kind of needs? Don t hesitate to fork the project, report bugs, ask for feature requests and let us know in the comments of this post ;)

Daniel Pocock: Going 4K

I recently started using a 4K monitor. I've generally had a positive experience and thought I would share some comments about it. What can you do with 4K resolution?
  • View the entire London Underground map or Swiss railway map without having to zoom or scroll
  • Run a mail client like Thunderbird/Icedove and an IRC client side-by-side
  • Run Eclipse and the Android emulator side-by-side
  • Run Eclipse and some other program you are debugging side-by-side
  • When reading a PDF, show a whole page at a time but only using half the screen
Are there hardware issues? Originally the hardware was expensive and people would have to do things like using multiple cables to join their video card to their 4K screen. The latest generation of video cards and monitors don't have this problem. I chose to use NVIDIA's entry-level Quadro K420 card, the smallest and least expensive Quadro supporting 4K. The PC is a HP Z800 workstation. HP suggests they only certify the K420 with their latest workstations (e.g. Z840) but I have observed no problem using it in a Z800. The monitor is a 32" BenQ display. After reading comments from other 4K users, I felt that any monitor less than 30" would not help me get the most from the world of 4K. The monitor connects to the video card using a DisplayPort 1.2 cable that was in the box with the monitor. I've been able to get sound through the monitor but I found the volume is always a bit low and at one point sound stopped completely. What about software issues? Everything just appeared to work although the fonts are a bit smaller than what I'm used to. This appears to be related to DPI issues. DPI is not automatically detected and several applications have their own way of handling non-standard DPI. Discussion about this started on the debian-devel mailing list, given that non-standard DPI will be an issue with many newer monitors, handheld devices and more exotic displays such as televisions. Some web sites just don't look so good when the browser window is maximized to 4K resolution while others use the extra space really well. For example, using the AirBNB search, the maps show more detail but using another hotel booking site I found that it was still trying to render a map within a constant size region using less than ten percent of the page.

Matthias Klumpp: Akademy 2015

I am very late with this, but I still wanted to write a few words about Akademy 2015. First of all: It was an awesome conference! Meeting all the great people involved with KDE and seeing who I am working with (as in: face to face, not via email) was awesome. We had some very interesting discussions on a wide variety of topics, and also enjoyed quite some beer together. Particularly important to me was of course talking to Daniel Vr til who is working on XdgApp, and Aleix Pol of Muon Discover fame.
Also meeting with the other Kubuntu members was awesome I haven t seen some of them for about 3 years, and also met many cool people for the first time. My talk on AppStream/Limba went well, except that I got slightly confused by the timer showing that I had only 2 minutes left, after I had just completed the first half of my talk. It turned out that the timer was wrong  Another really nice aspect was to be able to get an insight into areas where I am usually not involved with, like visual design. It was really interesting to learn about the great work others are doing and to talk to people about their work and I also managed to scratch an itch in the Systemsettings application, where three categories had shown the same icon. Now Systemsettings looks like it is supposed to be, finally :-) The only thing I could maybe complain about was the weather, which was more Scotland/Wales like than Spanish but that didn t stop us at all, not even at the social event outside. So I actually don t complain  We also managed to discuss some new technical stuff, like AppStream for Kubuntu, and plenty of other things that I ll write about in a separate blog post. Generally, I got so many new impressions from this year s Akademy, that I could write a 10-pages long blogpost about it while still having to leave out things.

Kudos to the organizers of this Akademy, you did a fantastic job! I also want to thank the Ubuntu community for funding my flight, and the Kubuntu community for pushing me a little to attend :-). KDE is a great community with people driving the development of Free Software forward. The diversity of people, projects and ideas in KDE is a pleasure, and I am very happy to be part of this community. Akademy2015

Steve Kemp: A brief look at the weed file store

Now that I've got a citizen-ID, a pair of Finnish bank accounts, and have enrolled in a Finnish language-course (due to start next month) I guess I can go back to looking at object stores, and replicated filesystems. To recap my current favourite, despite the lack of documentation, is the Camlistore project which is written in Go. Looking around there are lots of interesting projects being written in Go, and so is my next one the seaweedfs, which despite its name is not a filesystem at all, but a store which is accessed via HTTP. Installation is simple, if you have a working go-lang environment:
go get github.com/chrislusf/seaweedfs/go/weed
Once that completes you'll find you have the executable bin/weed placed beneath your $GOPATH. This single binary is used for everything though it is worth noting that there are distinct roles: In our demo we'll have three hosts one, the master, two and three which are storage nodes. First of all we start the master:
root@one:~# mkdir /node.info
root@one:~# weed master -mdir /node.info -defaultReplication=001
Then on the storage nodes we start them up:
root@two:~# mkdir /data;
root@two:~# weed volume -dir=/data -max=1  -mserver=one.our.domain:9333
Then the second storage-node:
root@three:~# mkdir /data;
root@three:~# weed volume -dir=/data -max=1 -mserver=one.our.domain:9333
At this point we have a master to which we'll talk (on port :9333), and a pair of storage-nodes which will accept commands over :8080. We've configured replication such that all uploads will go to both volumes. (The -max=1 configuration ensures that each volume-store will only create one volume each. This is in the interest of simplicity.) Uploading content works in two phases: We'll do that like so:
laptop ~ $ curl -X POST http://one.our.domain:9333/dir/assign
 "fid":"1,06c3add5c3","url":"192.168.1.100:8080","publicUrl":"192.168.1.101:8080","count":1 
client ~ $ curl -X PUT -F file=@/etc/passwd  http://192.168.1.101:8080/1,06c3add5c3
 "name":"passwd","size":2137 
In the first command we call /dir/assign, and receive a JSON response which contains the IPs/ports of the storage-nodes, along with a "file ID", or fid. In the second command we pick one of the hosts at random (which are the IPs of our storage nodes) and make the upload using the given ID. If the upload succeeds it will be written to both volumes, which we can see directly by running strings on the files beneath /data on the two nodes. The next part is retrieving a file by ID, and we can do that by asking the master server where that ID lives:
client ~ $ curl http://one.our.domain:9333/dir/lookup?volumeId=1,06c3add5c3
 "volumeId":"1","locations":[
  "url":"192.168.1.100:8080","publicUrl":"192.168.1.100:8080" ,
  "url":"192.168.1.101:8080","publicUrl":"192.168.1.101:8080" 
] 
Or, if we prefer we could just fetch via the master - it will issue a redirect to one of the volumes that contains the file:
client ~$ curl http://one.our.domain:9333/1,06c3add5c3
<a href="http://192.168.1.100:8080/1,06c3add5c3">Moved Permanently</a>
If you follow redirections then it'll download, as you'd expect:
client ~ $ curl -L http://one.our.domain:9333/1,06c3add5c3
root:x:0:0:root:/root:/bin/bash
..
That's about all you need to know to decide if this is for you - in short uploads require two requests, one to claim an identifier, and one to use it. Downloads require that your storage-volumes be publicly accessible, and will probably require a proxy of some kind to make them visible on :80, or :443. A single "weed volume .." process, which runs as a volume-server can support multiple volumes, which are created on-demand, but I've explicitly preferred to limit them here. I'm not 100% sure yet whether it's a good idea to allow creation of multiple volumes or not. There are space implications, and you need to read about replication before you go too far down the rabbit-hole. There is the notion of "data centres", and "racks", such that you can pretend different IPs are different locations and ensure that data is replicated across them, or only within-them, but these choices will depend on your needs. Writing a thin middleware/shim to allow uploads to be atomic seems simple enough, and there are options to allow exporting the data from the volumes as .tar files, so I have no undue worries about data-storage. This system seems reliable, and it seems well designed, but people keep saying "I'm not using it in production because .. nobody else is" which is an unfortunate problem to have. Anyway, I like it. The biggest omission is really authentication. All files are public if you know their IDs, but at least they're not sequential ..

Mirco Bauer: Smuxi 1.0 "Finally" Release

And here we go again! We're proud to announce the new version of Smuxi, release 1.0 "Finally". During the development, 20 bug reports and 10 feature requests in 285 commits were worked on.

Finally 1.0 Smuxi is celebrating its 10th anniversary! 10 years ago, Mirco Bauer made the first commit to the Smuxi source code repository and is still very committed to it. He started the Gnosmirc project in 2005 when the only way a 24/7 "always-on" experience with IRC meant you had to use a console based IRC client like bitchx, irssi or epic combined with screen and SSH. This looks very practical at first and is a powerful Unix-ish way of accomplishing that job, but it has the big downside that it doesn't integrate with a desktop environment like GNOME. A bit later the Gnosmirc project was renamed to Smuxi when the new code architecture allowed other frontend implementations besides the GNOME one. The ncurses/STFL based text frontend was later implemented and is considered stable and useful enough for day to day use, but still has some rough edges. WinForms and WPF frontends also exist but need more work to reach a usable state. At this point Smuxi 1.0 contains all features that we could have imagined and even goes beyond with very advanced features like message patterns or language agnostic scripting.

Changes since Smuxi 0.11

Message Persistence One of the biggest drawbacks of the IRC protocol ever was that messages can't be retrieved from the IRC server because the IRC server is simply relaying messages to the connected clients. So, if an IRC client is freshly started and connects it starts to receive new messages, but all message you had received before are no longer available. This always made IRC in a way "volatile" unlike other communication systems like email where messages are relayed and stored on the client side. One common approach for IRC clients is to store log files in a text file. This is a simple feature and gives the user the possibility to read older conversations. Smuxi also supports text file logging like other IRC clients but it has a big user experience drawback as you need to open the file from the disk outside of the IRC client. In Smuxi 1.0 messages sent and received are now stored on the disk in a way they can automatically be retrieved/loaded when you restart Smuxi. It is like you have never closed Smuxi! This feature was already available in Smuxi for some time as a technical preview and it used the Db4o object database, but we were never happy about the performance neither with the stability so it always stayed an optional feature you need to enable. This year we tried a new message buffer backend using the famous SQLite database and it works much faster and stable as a rock. So finally we can enable this feature by default because it just works and enhanced your experience. We hope you enjoy it. Documentation of how you can change Smuxi message buffer backend and behavior can be found here. For instructions how to convert your existing db4o history to SQLite can be found in the "smuxi-message-buffer tool" section.

User Interface Enhancements
  • Synced message markers: the position of of the seen/unseen messages marker is pushed to the smuxi-server and remembered when the frontend reconnects. (Sebastian Poeplau)
  • Persistent message markers: the message marker position is also remembered across Smuxi(-server) restarts.
  • Message Counter: in addition to the highlight counter next to a chat new/unseen messages are also counted. This makes it easy to identify chats with much traffic.
  • Single application instance support. If you start Smuxi again from the menu it will bring the existing instance into the foreground. This makes the Ubuntu Messaging Menu much nicer.
  • The command/message entry is alignment with the messages. (Lex Berezhny)

Text Frontend Enhancements
  • The console background color can now be configured using: /config set STFL/Interface/TerminalBackgroundColor = #000000 (Ond ej Ho ek)
  • The text color contrast if nicks with the background is now ensured (Ond ej Ho ek) #1033
  • Messages containing images will not be skipped but their alternative text is shown instead (Ond ej Ho ek) #1035

New smuxi-message-buffer tool This is a new commandline tool that allows you to convert and export the message history of Smuxi message buffer files. This can be used to convert your existing Db4o history to SQLite like this for example:
for DB_DB4O in $HOME/.local/share/smuxi/buffers/*/*/*/*.db4o; do
    DB_SQLITE=$ DB_DB4O/.db4o/.sqlite3 
    smuxi-message-buffer convert $DB_DB4O $DB_SQLITE
done
Smuxi shouldn't be running when using this tool.

Scripting Enhancements

New Hook Points Smuxi 1.0 supports with the following new hook points:
  • engine/protocol-manager/on-presence-status-changed/ This hook point is raised when the presence status of a protocol manager changes. This happens for example when an IRC connection toggles the away state.
  • engine/session/on-event-message/ This hook point raises event messages that usually begin with "-!-". This can be useful to track state changes that are shown as a message without having a dedicated hook point for it.
  • engine/session/command-$cmd/ This hook point is raised on the engine side for commands, e.g. /some_command that isn't handled by the frontend or engine built-in commands. This is useful for commands that should be available for all frontends and isn't specific to the frontend environment.

New Plugins The following new plugins are supported by Smuxi 1.0:
  • topic-diff: Shows the word differences of the topic after topic changes. (meebey)
  • away-nick: Automatically appends and removes $AWAY_SUFFIX to/from the nick name when you go away using the /away command or by disconnecting all frontends from the smuxi-server. (meebey)
  • system-info: Shows system info. Includes system kernel version, distro name, and CPU vendor information. (AK0)
  • now-playing: This plugin is not new but was rewritten in Python to get rid of the spaghetti code monster which was written in Bash. (jamesaxl)

IRC Enhancements
  • NICKSERV support Notices from Nick/ChanServ are no longer shown on all channels as they like to send greeting messages and other spam which is annoying to see on all channels. #868
  • Automatic rejoin of channels protected with a key works as expected again
  • Connecting to irc.gitter.im is now supported. Gitter's IRCd implementation has a bug in the IRC protocol which is now tolerated.

Twitter Enhancements
  • The /search command shows tweets as live stream
  • Added /delete, /favorite and /unfavorite commands

Behind the Scenes
  • Re-licensed smuxi-common from GPLv2 to MIT/X11

Contributors Contributors to this release are the following people:
  • Mirco Bauer (199 commits)
  • Carlos Mart n Nieto (15 commits)
  • Andr s G. Aragoneses (14 commits)
  • Piotr Dr g (12 commits)
  • Ond ej Ho ek (11 commits)
  • Oliver Schneider (5 commits)
  • Calvin B (4 commits)
  • Victor Seva (3 commits)
  • Will Johansson (2 commits)
  • Sebastian Poeplau (2 commits)
  • Julian Taylor (2 commits)
  • James Axl (2 commits)
  • Daniel Mustieles (2 commits)
  • Christopher James Halse Rogers (2 commits)
  • . Uzun (1 commit)
  • Lex Berezhny (1 commit)
  • Kalle Kaitala (1 commit)
  • Jordi Mas (1 commit)
  • Joe Hansen (1 commit)
  • Jimmie Elvenmark (1 commit)
  • Dimitris Spingos (1 commit)
  • Dean Lee (1 commit)
  • Cl ment Bourgeois (1 commit)
  • Carlos Hernandez (1 commit)
Thank you very much for your contributions to Smuxi! Want this? Go here and grab it right now!

Posted Sun Aug 9 17:48:18 2015

Norbert Preining: Debian/TeX Live 2015.20150810-1

For those who are starving for some updates while the big gcc5 transitions brings the rest of Debian/sid to a halt, here is some fresh meat, a new TeX Live checkout. Nothing spectacular new here, just the usual big bunch of updates of and several new packages. Maybe worthwhile mentioning is that luasseq has been reincorporated into the TeX Live packages. Thanks to the maintainer for his work till now! Debian - TeX Live 2015 From the long list of changes let me pick one update and one new package: pgf has been updated to 3.0.1, which is just a small change in number, but incorporates 1.5 years of fixes, and the list of fixes is long. And a very interesting newcomer is pdfpagediff by C. V. Rad hakr ish nan. It allows visual comparison of two pdf files by overlaying them in a transparent way, making even slight changes in the layout immediately visible. Of course, these are not the only updates and newcomers, see the list below. Updated packages academicons, addlines, algorithms, archaic, babel, babel-estonian, biber, biblatex-source-division, bidi, bxjscls, chronology, cjk-ko, conteq, csplain, csquotes, curve2e, datatool, doclicense, dvips, eledmac, enotez, esami, eso-pic, etex-pkg, etoolbox, exsheets, fandol, fithesis, fontawesome, fontspec, forest, glossaries, greek-inputenc, jslectureplanner, kotex-oblivoir, kotex-utf, l3build, l3experimental, l3kernel, l3packages, latex, leadsheets, ledmac, lshort-english, luamplib, luasseq, luatexko, maths-symbols, media9, memoir, metrix, mhchem, minitoc, moderncv, modiagram, morefloats, mptopdf, msu-thesis, nameauth, ndsu-thesis, newpx, newtx, newtxsf, newtxtt, notes, ocgx2, pageslts, pdfpages, pdftex, pgf, phonrule, plain, polyglossia, pstricks, ptex, pxchfon, reflectgraphics, rsfso, sectionbox, siunitx, skrapport, standalone, tcolorbox, tetex, tex4ht, texfot, texinfo, texlive-scripts, todonotes, translations, tudscr, ucbthesis, unicode-math, xcharter, xgreek. New packages alertmessage, bewerbung, bidihl, bxpdfver, cloze, comicneue, copyedit, fcavtex, gradstudentresume, make4ht, mcf2graph, multiaudience, nmbib, pdfpagediff, quran, reledmac, roundrect, screenplay-pkg, shapes, tex4ebook. Enjoy.

9 August 2015

Hideki Yamane: xz multithreaded compression

$ dpkg -s liblzma5
Package: liblzma5
Status: install ok installed
(snip)
Version: 5.1.1alpha+20120614-2.1
$ time sudo cowbuilder --build fonts-horai-umefont_530-1.dsc
real 1m8.378s
user 1m0.084s
sys 0m3.244s
real 1m9.842s
user 1m0.964s
sys 0m3.856s
real 1m9.355s
user 1m0.824s
sys 0m3.380s

xz 5.2 supports multithread, with local build (remove --disable-thread option in debian/rules)

$ dpkg -s liblzma5
Package: liblzma5
Status: install ok installed
(snip)
Version: 5.2.1-0.1
real 1m7.946s
user 0m59.628s
sys 0m3.228s
real 1m8.794s
user 1m0.072s
sys 0m3.556s
real 1m7.580s
user 0m59.152s
sys 0m3.368s

Umm, not affected.

$ time xz -T 0 fonts-horai-umefont_530.orig.tar
real 0m15.488s
user 0m47.044s
sys 0m0.252s
$ time xz -T 1 fonts-horai-umefont_530.orig.tar
real 0m40.988s
user 0m40.804s
sys 0m0.124s
multithread itself is enabled.

Petter Reinholdtsen: First paper version of the Norwegian Free Culture book heading my way

Typesetting a book is harder than I hoped. As the translation is mostly done, and a volunteer proof reader was going to check the text on paper, it was time this summer to focus on formatting my translated docbook based version of the Free Culture book by Lawrence Lessig. I've been trying to get both docboox-xsl+fop and dblatex to give me a good looking PDF, but in the end I went with dblatex, because its Debian maintainer and upstream developer were responsive and very helpful in solving my formatting challenges. Last night, I finally managed to create a PDF that no longer made Lulu.com complain after uploading, and I ordered a text version of the book on paper. It is lacking a proper book cover and is not tagged with the correct ISBN number, but should give me an idea what the finished book will look like. Instead of using Lulu, I did consider printing the book using CreateSpace, but ended up using Lulu because it had smaller book size options (CreateSpace seem to lack pocket book with extended distribution). I looked for a similar service in Norway, but have not seen anything so far. Please let me know if I am missing out on something here. But I still struggle to decide the book size. Should I go for pocket book (4.25x6.875 inches / 10.8x17.5 cm) with 556 pages, Digest (5.5x8.5 inches / 14x21.6 cm) with 323 pages or US Trade (6x8 inches / 15.3x22.9 cm) with 280 pages? Fewer pager give a cheaper book, and a smaller book is easier to carry around. The test book I ordered was pocket book sized, to give me an idea how well that fit in my hand, but I suspect I will end up using a digest sized book in the end to bring the prize down further. My biggest challenge at the moment is making nice cover art. My inkscape skills are not yet up to the task of replicating the original cover in SVG format. I also need to figure out what to write about the book on the back (will most likely use the same text as the description on web based book stores). I would love help with this, if you are willing to license the art source and final version using the same CC license as the book. My artistic skills are not really up to the task. I plan to publish the book in both English and Norwegian and on paper, in PDF form as well as EPUB and MOBI format. The current status can as usual be found on github in the archive/ directory. So far I have spent all time on making the PDF version look good. Someone should probably do the same with the dbtoepub generated e-book. Help is definitely needed here, as I expect to run out of steem before I find time to improve the epub formatting. Please let me know via github if you find typos in the book or discover translations that should be improved. The final proof reading is being done right now, and I expect to publish the finished result in a few months.

8 August 2015

Matthew Garrett: Difficult social problems are still difficult problems

After less than a week of complaints, the TODO group have decided to pause development of their code of conduct. This seems to have been triggered by the public response to the changes I talked about here, which TODO appear to have been completely unprepared for.
While disappointing in a bunch of ways, this is probably the correct decision. TODO stumbled into this space with a poor understanding of the problems that they were trying to solve. Nikki Murray pointed out that the initial draft lacked several of the key components that help ensure less privileged groups can feel that their concerns are taken seriously. This was mostly rectified last week, but nobody involved appeared to be willing to stand behind those changes in a convincing way. This wasn't helped by almost all of this appearing to land on Github's plate, with the rest of the TODO group largely missing in action[1]. Where were Google in this? Yahoo? Facebook? Left facing an angry mob with nobody willing to make explicit statements of support, it's unsurprising that Github would try to back away from the situation.

But that doesn't remove their blame for being in the situation in the first place. The statement claims
We are consulting with stakeholders, community leaders, and legal professionals, which is great. It's also far too late. If an industry body wrote a new kernel from scratch and deployed it without any external review, then discovered that it didn't work and only then consulted any of the existing experts in the field, we'd never take them seriously again. But when an industry body turns up with a new social policy, fucks up spectacularly and then goes back to consult experts, it's expected that we give them a pass.

Why? Because we don't perceive social problems as difficult problems, and we assume that anybody can solve them by simply sitting down and talking for a few hours. When we find out that we've screwed up we throw our hands in the air and admit that this is all more difficult than we imagined, and we give up. We ignore the lessons that people have learned in the past. We ignore the existing work that's been done in the field. We ignore the people who work full time on helping solve these problems.

We wouldn't let an industry body with no experience of engineering build a bridge. We need to accept that social problems are outside our realm of expertise and defer to the people who are experts.

[1] The repository history shows the majority of substantive changes were from Github, with the initial work appearing to be mostly from Twitter.

comment count unavailable comments

Craig Small: Be careful with errno

I m getting close to releasing version 3.3.11 of procps. When it gets near that time, I generally browse again the Debian Bug Tracker for procps bugs. Bug number #733758 caught my eye. With the free command if you used the s option before the c option, the s option failed, seconds argument N failed where N was the number you typed in. The error should be for you trying to type letters for number of seconds. Seemed reasonably simple to test and simple to fix. Take me to the code The relevant code looks like this:
   case 's':
            flags  = FREE_REPEAT;
            args.repeat_interval = (1000000 * strtof(optarg, &amp;endptr));
            if (errno   optarg == endptr   (endptr &amp;&amp; *endptr))
                xerrx(EXIT_FAILURE, _("seconds argument  %s' failed"), optarg);
Seems pretty stock-standard sort of function. Use strtof() to convert the string into the float. You need to check both errno AND optarg == endptr because: At first I thought the logic was wrong, but tracing through it was fine. I then compiled free using the upstream git source, the program worked fine with s flag with no c flag. Doing a diff between the upstream HEAD and Debian s 3.3.10 source showed nothing obvious. I then shifted the upstream git to 3.3.10 too and re-compiled. The Debian source failed, the upstream parsed the s flag fine. I ran diff, no change. I ran md5sum, the hashes matched; what is going on here? I ll set when I want The man page says in the case of under/overflow ERANGE is stored in errno . What this means is if there isn t and under/overflow then errno is NOT set to 0, but its just not set at all. This is quite useful when you have a chain of functions and you just want to know something failed, but don t care what. Most of the time, you generally would have a Have I failed? test and then check errno for why. A typical example is socket calls where anything less than 0 means failure. You check the return value first and then errno. strtof() is one of those funny ones where most people check errno directly; its simpler than checking for +/- HUGE_VAL. You can see though that there are traps. What s the difference? OK, so a simple errno=0 above the call fixes it, but why would the Debian source tree have this failure and the upstream not? Even with the same code? The difference is how they are compiled. The upstream compiles free like this:
gcc -std=gnu99 -DHAVE_CONFIG_H -I. -include ./config.h -I./include -DLOCALEDIR=\"/usr/local/share/locale\" -Iproc -g -O2 -MT free.o -MD -MP -MF .deps/free.Tpo -c -o free.o free.c
mv -f .deps/free.Tpo .deps/free.Po
/bin/bash ./libtool --tag=CC --mode=link gcc -std=gnu99 -Iproc -g -O2 ./proc/libprocps.la -o free free.o strutils.o fileutils.o -ldl
libtool: link: gcc -std=gnu99 -Iproc -g -O2 -o .libs/free free.o strutils.o fileutils.o ./proc/.libs/libprocps.so -ldl
While Debian has some hardening flags:
gcc -std=gnu99 -DHAVE_CONFIG_H -I. -include ./config.h -I./include -DLOCALEDIR=\"/usr/share/locale\" -D_FORTIFY_SOURCE=2 -Iproc -g -O2 -fstack-protector-strong -Wformat -Werror=format-security -MT free.o -MD -MP -MF .deps/free.Tpo -c -o free.o free.c
mv -f .deps/free.Tpo .deps/free.Po
/bin/bash ./libtool --tag=CC --mode=link gcc -std=gnu99 -Iproc -g -O2 -fstack-protector-strong -Wformat -Werror=format-security ./proc/libprocps.la -Wl,-z,relro -o free free.o strutils.o fileutils.o -ldl
libtool: link: gcc -std=gnu99 -Iproc -g -O2 -fstack-protector-strong -Wformat -Werror=format-security -Wl,-z -Wl,relro -o .libs/free free.o strutils.o fileutils.o ./proc/.libs/libprocps.so -ldl
It s not the compiling of free itself that is doing it, but the library. Most likely something that is called before the strtof() is setting errno which this code then falls into. In fact if you run the upstream free linked to the Debian procps library it fails. Moral of the story is to set errno before the function is called if you are going to depend on it for checking if the function succeeded.

7 August 2015

Norbert Preining: Japanese-English dictionary for Kobo

Since ever the Kobo firmwares also allowed downloading of a bunch of dictionaries, most of which I don t need. As I am fluent in most languages I read and write, the only real dictionary I would like to see is a Japanese-English (I don t dare asking for a Japanese-German). Unfortunately, Kobo never shipped one. OTOH, starting with firmware 3.16.10 they ships two different English-Japanese dictionaries, one excellent Japanese-Japanese dictionary, but not one Japanese-English. So I took the liberty to write a script that allows everyone to enrich the shipped Japanese-Japanese dictionary with English definitions. Kobo Logo Till now I have used Tshering s excellent Japanese dictionary which was enriched with English definitions. It was based on the older Japanese-Japanese dictionary shipped with firmwares before 3.16.10. I didn t want to loose the more complete dictionary from the new firmware, so here is a script that updates the dictionary for you Prerequisites The script is neither fool-proof nor does everything by itself. Furthermore, it requires a set of programs. In details: Supported dictionaries At the moment the program can use the following two dictionaries as sources: Edict2 and Japanese3. Edict2 The Edict dictionary is a free dictionary which is the base of most other dictionaries. Created by the JMdict/EDICT Project it provides a very complete Japanese-English dictionary. To use the dict with the current program, one need to download the edict2.gz file and unpack it with gunzip edict2.gz. If you put it into the same directory as the Perl script, nothing else needs to be done, otherwise one can use the command line option --edict PATH-TO-EDICT to specify the location of the edict2 file. Japanese3 The Japanese3 is a dictionary application for iOS which provides another very complete Japanese-English dictionary. My feeling is that it is 90% and more based on Edict, so adding it will not buy you much, but still a bit (see below for how much!). If you have purchased this dictionary/application, and you manage to get access to your iOS device (via jailbreaking or some other tools), then you need to get the file Japanese3.db from the application folder, and then generate a file via sqlite3 as follows:
$ sqlite3 Japanese3.db
.output japanese3-data
select Entry, Furigana, Summary from entries;
If you save the generated file japanese3-data into the same directory as the Perl script, nothing else needs to be done, otherwise one can use the command line option --japanese3 PATH-TO-J3-DATA to specify the location of the Japanese3 data file. Command line options The program supports the following command line options: Note that in case you pass in the option --unpacked, the files should be properly named (encodings are a problem!). Furthermore, note that the unpacked directory contains lots of .gif and .html files that are actually gzip-compressed files, but lacking the .gz extension. If you want to unpack the dictionary, by advised that the file names in the Zip directory are already encoded in UTF-8, but normal programs (unzip, 7z) assume that they are encoded in some other encoding. Thus, if your are using UTF-8 locale, it is necessary to set LC_CTYPE to C to make sure that the encoding is used, as in
LC_CTYPE=C 7z x ...
Typical run In the following example we use both dict2 and Japanese3 dictionaries, and prefer Edict2:
$ perl enhance-dictionary.pl --dicts edict2 --dicts japanese3
Using the following dictionaries as source for translations: edict2 japanese3
loading edict2 ... done
loading Japanese3 data ... done
unpacking original dictionary ... done
loading dict files ... done
searching for words and updating ... done
total words 805521, matches: 130563 (edict: 123388, japanese3: 7175)
creating output html ... done
creating update dictionary in dicthtml-jaxxdjs-201508072201.zip ... done
$
Installing the dictionary After having created the enhanced dictionary, one can install the generated file as KOBO/.kobo/dicts/dicthtml-jaxxdjs.zip (where KOBO is the mount point of the eReader). The dictionary should be picked up automatically. And the next lookup should give you something like the following:
kobo-glohd-enhanced-ja-dict There is only one caveat: Syncing with Kobo will re-download the original dictionary and overwrite the enhanced one. There is at least one solution here, which I am employing, see this post on MobileRead. Download and development place I am using the github repository kobo-ja-dict-enhance to develop the program. Please report bugs, and feature requests there. The file for the last released version can be downloaded from here: enhance-dictionary.pl Future plans I am planning to get rid of the 7z dependency and use Archive::Zip for all the unpacking and packing. This would also allow to do everything in memory and thus make it faster. There is a branch on github with ongoing work on this matter. I also think about including translations for Hiragana words by providing the translations of all possible Kanji readings. Conclusions Even if Kobo does not provide us with a decent Japanese-English dictionary, adding at least a huge amount of translations to the current dictionary is now easily possible. For serious students of Japanese who are reading or starting to read Japanese eBooks, this will be of great help. Enjoy, and don t forget to give feedback, suggestions, and improvements either here or better via the Github page.

Christoph Egger: Systemd pitfalls

logind hangs If you just updated systemd and ssh to that host seems to hang, that's just a known Bug (Debian Bug). Don't panic. Wait for the logind timeout and restart logind. restart and stop;start One thing that confused me several times and still confuses people is systemctl restart doing more than systemctl stop ; systemctl start. You will notice the difference once you have a failed service. A restart will try to start the service again. Both stop and start however will just ignore it. Rumors have it this has changed post jessie however. sysvinit-wrapped services and stop While there are certainly bugs with sysvinit services in general (I found myself several times without a local resolver as unbound failed to be started, haven't managed to debug further), the stop behavior of wrapped services is just broken. systemctl stop will block until the sysv initscript finished. It will even note the result of the action in its state. However systemctl will return with exitcode 0 and not output anything on stdout/stderr. This has been reported as Debian Bug. zsh helper I found the following zshrc snipped quite helpful in dealing with non-reported systemctl failures. On root shells it will display a list of failed services as part of the prompt. This will give proper feedback whether your systemctl stop failed, it will give feedback if you still have type=simple services and if the sysv-init script or wrapper is broken.
precmd ()  
    if [[ $UID == 0 && $+commands[systemctl] != 0 ]]
    then
      use_systemd=true
      systemd_failed=" systemctl --state=failed   grep failed   cut -d \  -f 2   tr '\n' ' ' "
    fi
 
if [[ $UID == 0 && $+commands[systemctl] != 0 ]]
then
  PROMPT=$'% $fg[red]>>  $systemd_failed$reset_color% \n'
else
  PROMPT=""
fi
PROMPT+=whateveryourpromptis
zsh completion Speaking of zsh, there's one problem that bothers me a lot and I don't have any solution for. Tab-completing the service name for service is blazing fast. Tab-completing the service name for systemctl restart takes ages. People traced down to truckloads of dbus communication for the completion but no further fix is known (to me). type=simple services As described in length by Lucas Nussbaum type=simple services are actively harmful. Proper type=forking daemons are strictly superior (they provide feedback of finished initialization and success thereof) and type=notify services are so simple there's no excuse for not using them even for private one-off hacks. Even if you're language doesn't provide libsystemd-daemon bindings:
(defun sd-notify (event-string)
  (let ((socket (make-instance 'sb-bsd-sockets:local-socket :type :datagram))
        (name (posix-getenv "NOTIFY_SOCKET"))
        (bufferlen (length event-string)))
    (when name
      (sb-bsd-sockets:socket-connect socket name)
      (sb-bsd-sockets:socket-send socket event-string bufferlen))))
This is a stable API guaranteed to not break in the future and implemented in less than ten lines of code with just basic socket functions. And if your language has support it becomes actually trivial:
    try:
        import systemd
        systemd.daemon.notify("READY=1")
    except ImportError:
        pass
Note that in both cases there is no drawback at all on systemd-free setups. It has the overhead of checking the process' environment for NOTIFY_SOCKET or for the systemd package and behaves like a simple service otherwise. Actually the idea of separating the technical aspect (daemonizing) from the semantic aspect of signalizing "initialization finished, everything's fine" is a pretty good idea and hopefully has the potential to reduce the number of services signalizing the "everything's fine" too early. It could even be ported to non-systemd init systems easily given the API.

Christoph Egger: Systemd pitfalls

logind hangs If you just updated systemd and ssh to that host seems to hang, that's just a known Bug (Debian Bug #770135). Don't panic. Wait for the logind timeout and restart logind. restart and stop;start One thing that confused me several times and still confuses people is systemctl restart doing more than systemctl stop ; systemctl start. You will notice the difference once you have a failed service. A restart will try to start the service again. Both stop and start however will just ignore it. Rumors have it this has changed post jessie however. sysvinit-wrapped services and stop While there are certainly bugs with sysvinit services in general (I found myself several times without a local resolver as unbound failed to be started, haven't managed to debug further), the stop behavior of wrapped services is just broken. systemctl stop will block until the sysv initscript finished. It will even note the result of the action in its state. However systemctl will return with exitcode 0 and not output anything on stdout/stderr. This has been reported as Debian Bug #792045. zsh helper I found the following zshrc snipped quite helpful in dealing with non-reported systemctl failures. On root shells it will display a list of failed services as part of the prompt. This will give proper feedback whether your systemctl stop failed, it will give feedback if you still have type=simple services and if the sysv-init script or wrapper is broken.
precmd ()  
    if [[ $UID == 0 && $+commands[systemctl] != 0 ]]
    then
      use_systemd=true
      systemd_failed=" systemctl --state=failed   grep failed   cut -d \  -f 2   tr '\n' ' ' "
    fi
 
if [[ $UID == 0 && $+commands[systemctl] != 0 ]]
then
  PROMPT=$'% $fg[red]>>  $systemd_failed$reset_color% \n'
else
  PROMPT=""
fi
PROMPT+=whateveryourpromptis
zsh completion Speaking of zsh, there's one problem that bothers me a lot and I don't have any solution for. Tab-completing the service name for service is blazing fast. Tab-completing the service name for systemctl restart takes ages. People traced down to truckloads of dbus communication for the completion but no further fix is known (to me). type=simple services As described in length by Lucas Nussbaum type=simple services are actively harmful. Proper type=forking daemons are strictly superior (they provide feedback of finished initialization and success thereof) and type=notify services are so simple there's no excuse for not using them even for private one-off hacks. Even if you're language doesn't provide libsystemd-daemon bindings:
(defun sd-notify (event-string)
  (let ((socket (make-instance 'sb-bsd-sockets:local-socket :type :datagram))
        (name (posix-getenv "NOTIFY_SOCKET"))
        (bufferlen (length event-string)))
    (when name
      (sb-bsd-sockets:socket-connect socket name)
      (sb-bsd-sockets:socket-send socket event-string bufferlen))))
This is a stable API guaranteed to not break in the future and implemented in less than ten lines of code with just basic socket functions. And if your language has support it becomes actually trivial:
    try:
        import systemd
        systemd.daemon.notify("READY=1")
    except ImportError:
        pass
Note that in both cases there is no drawback at all on systemd-free setups. It has the overhead of checking the process' environment for NOTIFY_SOCKET or for the systemd package and behaves like a simple service otherwise. Actually the idea of separating the technical aspect (daemonizing) from the semantic aspect of signalizing "initialization finished, everything's fine" is a pretty good idea and hopefully has the potential to reduce the number of services signalizing the "everything's fine" too early. It could even be ported to non-systemd init systems easily given the API.

Neil McGovern: Forty five hours

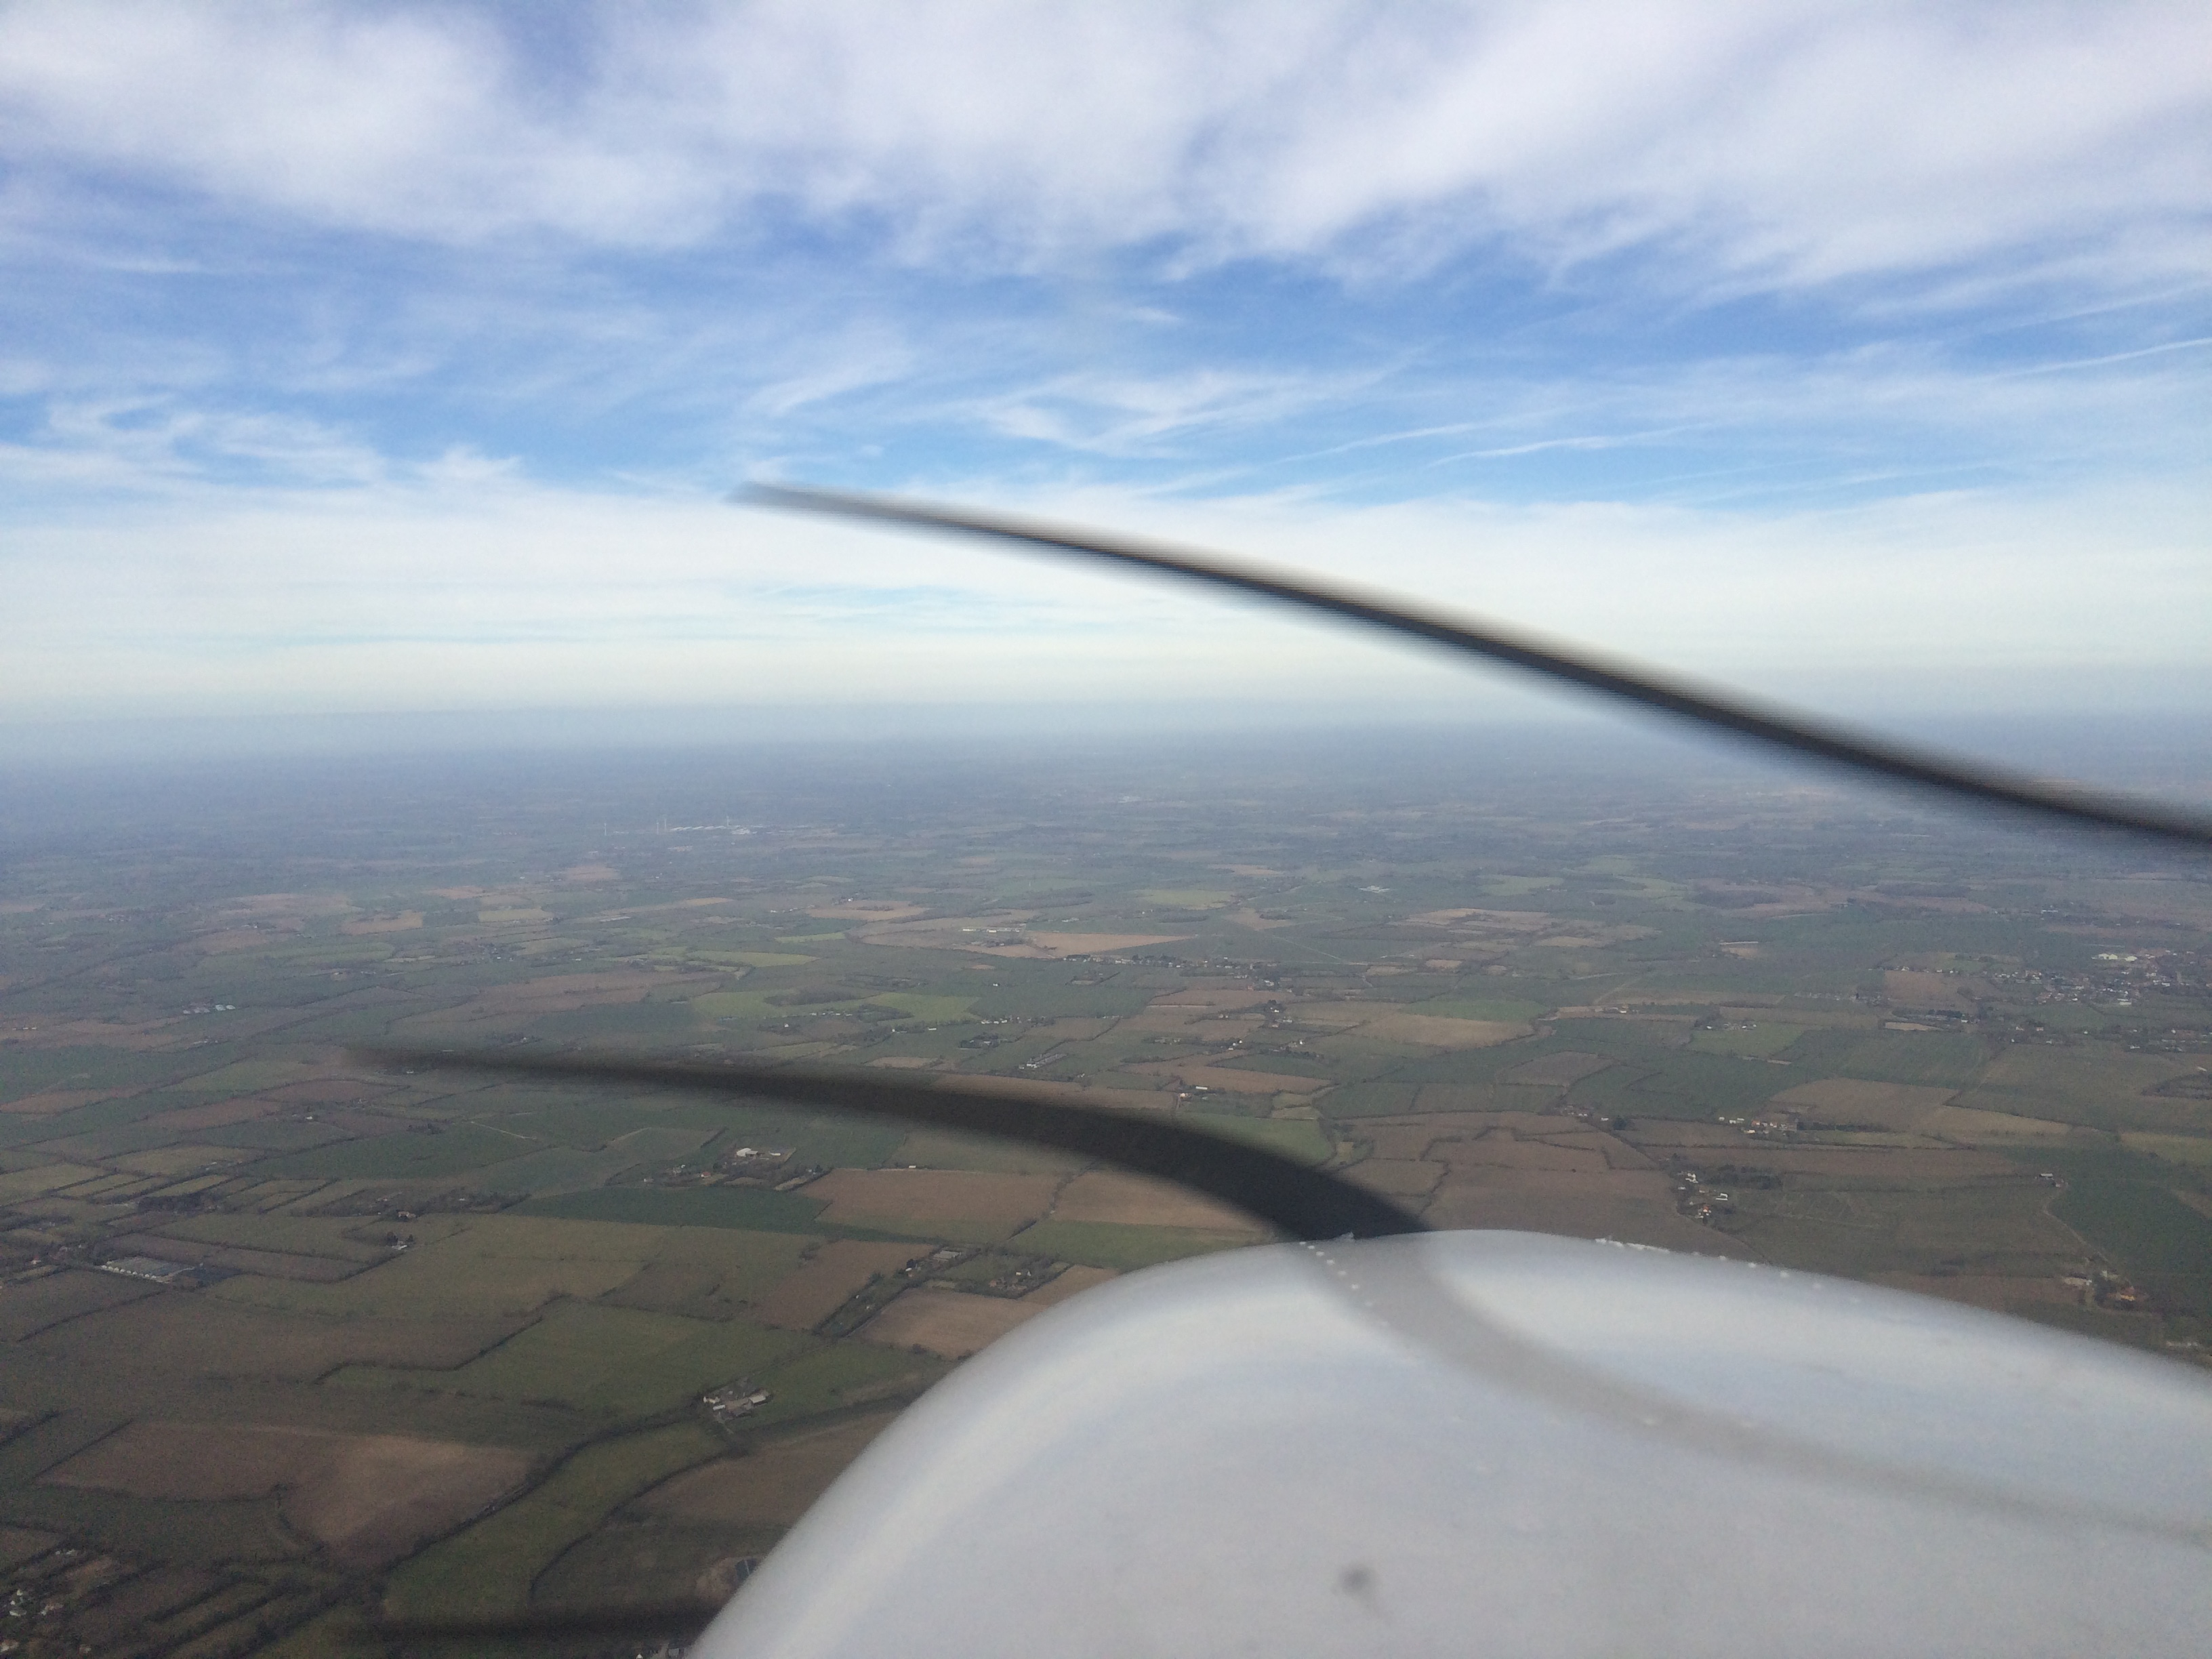
IMG_0330As some may know, since October 2013, I ve been studying to gain my Private Pilot Licence, and I finally achieved this goal. It s actually taken quite a bit more than 45 hours a total of around 60, but that does include a day trip to France (Le Touquet) and getting my night rating as well. This basically means I can fly single engine piston aeroplanes on my own, with passengers, as soon as my paperwork gets processed by the Civil Aviation Authority anyway. I ve been flying Cessna 172s from Cambridge Aero Club, where they have four of them, G-SHWK, G-UFCB, G-HERC and G-MEGS, as well as a Extra 200, G-GLOC. It s a great club, with fantastically maintained planes and great instructors, and Cambridge Airport has a full ATC service as well, so it s been useful to get that experience, especially as the UK s airspace is fairly contended with a lot of controlled and military airspace which needs permission to enter. As for what next, I need to work that out. When you get your licence, it s often described as a license to learn, so that s what I intend to do. Apart from popping over to France for lunch every now and again, I m probably going to have a go at aerobatics and farm strip flying, then probably look at my IMC rating. So, if it s a nice day, and you re around in Cambridge, let me know if you want a trip up in the skies!

6 August 2015

Christoph Egger

TinyTiny-RSS has some nice failure modes. And upstream support forums aren't really helpfull so when you search for your current problem, chances are that there is one mention of it on the web, in the forum, and the only thing happening there is people making fun of the reporter. Anyway. This installation has seen lots of error messages from the updater in the last several months:
Warning: Fatal error, unknown preferences key: ALLOW_DUPLICATE_POSTS (owner: 3) in /srv/www/tt-rss.faui2k9.de/root/classes/db/prefs.php on line 108
  
And, more recently, the android app stopped working with ERROR:JSON Parse failed.. Turns out both things are related. First thing I noticed was changing preferences in the web panel stopped working until you use the reset to Defaults option and then changed settings. Plugging wireshark in between showed what was going on (Note: API was displayed as enabled in Preferences/Preferences):
HTTP/1.1 200 OK
Server: nginx/1.8.0
Date: Thu, 06 Aug 2015 11:00:31 GMT
Content-Type: text/json
Transfer-Encoding: chunked
Connection: keep-alive
X-Powered-By: PHP/5.4.43
Content-Language: auto
Set-Cookie: [...]
Expires: Thu, 19 Nov 1981 08:52:00 GMT
Cache-Control: no-store, no-cache, must-revalidate, post-check=0, pre-check=0
Pragma: no-cache
Api-Content-Length: 234
ea

Warning: Fatal error, unknown preferences key: ENABLE_API_ACCESS (owner: 2) in /srv/www/tt-rss.faui2k9.de/root/classes/db/prefs.php on line 108
"seq":0,"status":1,"content": "error":"API_DISABLED" 0
Solution for fixing the Android app (and the logspam on the way as well) seems to be to reset the preferences and then configure tt-rss again (In the webapp, not in the android thing!). Also silences tt-rss update_daemon as well, yay! One last thing: someone out there who wants to explain to me how to fix
Fatal error: Query INSERT INTO ttrss_enclosures
                                                        (content_url, content_type, title, duration, post_id, width, height) VALUES
                                                        ('https://2.gravatar.com/avatar/e6d6ceb7764252af8da058e30cd8cb5f?s=96&d=identicon&r=G', '', '', '', '0', 0, 0) failed: ERROR:  insert or update on table "ttrss_enclosures" violates foreign key constraint "ttrss_enclosures_post_id_fkey"
DETAIL:  Key (post_id)=(0) is not present in table "ttrss_entries". in /srv/www/tt-rss.faui2k9.de/root/classes/db/pgsql.php on line 46
  

Christoph Egger: unbreaking tt-rss

TinyTiny-RSS has some nice failure modes. And upstream support forums aren't really helpfull so when you search for your current problem, chances are that there is one mention of it on the web, in the forum, and the only thing happening there is people making fun of the reporter. Anyway. This installation has seen lots of error messages from the updater in the last several months:
Warning: Fatal error, unknown preferences key: ALLOW_DUPLICATE_POSTS (owner: 3) in /srv/www/tt-rss.faui2k9.de/root/classes/db/prefs.php on line 108
  
And, more recently, the android app stopped working with ERROR:JSON Parse failed.. Turns out both things are related. First thing I noticed was changing preferences in the web panel stopped working until you use the reset to Defaults option and then changed settings. Plugging wireshark in between showed what was going on (Note: API was displayed as enabled in Preferences/Preferences):
HTTP/1.1 200 OK
Server: nginx/1.8.0
Date: Thu, 06 Aug 2015 11:00:31 GMT
Content-Type: text/json
Transfer-Encoding: chunked
Connection: keep-alive
X-Powered-By: PHP/5.4.43
Content-Language: auto
Set-Cookie: [...]
Expires: Thu, 19 Nov 1981 08:52:00 GMT
Cache-Control: no-store, no-cache, must-revalidate, post-check=0, pre-check=0
Pragma: no-cache
Api-Content-Length: 234
ea

Warning: Fatal error, unknown preferences key: ENABLE_API_ACCESS (owner: 2) in /srv/www/tt-rss.faui2k9.de/root/classes/db/prefs.php on line 108
"seq":0,"status":1,"content": "error":"API_DISABLED" 0
Solution for fixing the Android app (and the logspam on the way as well) seems to be to reset the preferences and then configure tt-rss again (In the webapp, not in the android thing!). Also silences tt-rss update_daemon as well, yay! One last thing: someone out there who wants to explain to me how to fix
Fatal error: Query INSERT INTO ttrss_enclosures
                                                        (content_url, content_type, title, duration, post_id, width, height) VALUES
                                                        ('https://2.gravatar.com/avatar/e6d6ceb7764252af8da058e30cd8cb5f?s=96&d=identicon&r=G', '', '', '', '0', 0, 0) failed: ERROR:  insert or update on table "ttrss_enclosures" violates foreign key constraint "ttrss_enclosures_post_id_fkey"
DETAIL:  Key (post_id)=(0) is not present in table "ttrss_entries". in /srv/www/tt-rss.faui2k9.de/root/classes/db/pgsql.php on line 46
  

Next.

Previous.