Search Results: "tar"

27 June 2017

Daniel Pocock: How did the world ever work without Facebook?

Almost every day, somebody tells me there is no way they can survive without some social media like Facebook or Twitter. Otherwise mature adults fearful that without these dubious services, they would have no human contact ever again, they would die of hunger and the sky would come crashing down too. It is particularly disturbing for me to hear this attitude from community activists and campaigners. These are people who aspire to change the world, but can you really change the system using the tools the system gives you? Revolutionaries like Gandhi and the Bolsheviks don't have a lot in common: but both of them changed the world and both of them did so by going against the system. Gandhi, of course, relied on non-violence while the Bolsheviks continued to rely on violence long after taking power. Neither of them needed social media but both are likely to be remembered far longer than any viral video clip you have seen recently. With US border guards asking visitors for their Facebook profiles and Mark Zuckerberg being a regular participant at secretive Bilderberg meetings, it should be clear that Facebook and conventional social media is not on your side, it's on theirs. Kettling has never been easier When street protests erupt in major cities such as London, the police build fences around the protesters, cutting them off from the rest of the world. They become an island in the middle of the city, like a construction site or broken down bus that everybody else goes around. The police then set about arresting one person at a time, taking their name and photograph and then slowly letting them leave in different directions. This strategy is called kettling. Facebook helps kettle activists in their arm chair. The police state can gather far more data about them, while their impact is even more muted than if they ventured out of their home. You are more likely to win the lottery than make a viral campaign Every week there is news about some social media campaign that has gone viral. Every day, marketing professionals, professional campaigners and motivated activists sit at their computer spending hours trying to replicate this phenomenon. Do the math: how many of these campaigns can really be viral success stories? Society can only absorb a small number of these campaigns at any one time. For most of the people trying to ignite such campaigns, their time and energy is wasted, much like money spent buying lottery tickets and with odds that are just as bad. It is far better to focus on the quality of your work in other ways than to waste any time on social media. If you do something that is truly extraordinary, then other people will pick it up and share it for you and that is how a viral campaign really begins. The time and effort you put into trying to force something to become viral is wasting the energy and concentration you need to make something that is worthy of really being viral. An earthquake and an escaped lion never needed to announce themselves on social media to become an instant hit. If your news isn't extraordinary enough for random people to spontaneously post, share and tweet it in the first place, how can it ever go far? The news media deliberately over-rates social media News media outlets, including TV, radio and print, gain a significant benefit crowd-sourcing live information, free of charge, from the public on social media. It is only logical that they will cheer on social media sites and give them regular attention. Have you noticed that whenever Facebook's publicity department makes an announcement, the media are quick to publish it ahead of more significant stories about social or economic issues that impact our lives? Why do you think the media puts Facebook up on a podium like this, ahead of all other industries, if the media aren't getting something out of it too? The tail doesn't wag the dog One particular example is the news media's fascination with Donald Trump's Twitter account. Some people have gone as far as suggesting that this billionaire could have simply parked his jet and spent the whole of 2016 at one of his golf courses sending tweets and he would have won the presidency anyway. Suggesting that Trump's campaign revolved entirely around Twitter is like suggesting the tail wags the dog. The reality is different: Trump has been a prominent public figure for decades, both in the business and entertainment world. During his presidential campaign, he had at least 220 major campaign rallies attended by over 1.2 million people in the real world. Without this real-world organization and history, the Twitter account would have been largely ignored like the majority of Twitter accounts. On the left of politics, the media have been just as quick to suggest that Bernie Sanders and Jeremy Corbyn have been supported by the "Facebook generation". This label is superficial and deceiving. The reality, again, is a grass roots movement that has attracted young people to attend local campaign meetings in pubs up and down the country. Getting people to get out and be active is key. Social media is incidental to their campaign, not indispensible. Real-world meetings, big or small, are immensely more powerful than a social media presence. Consider the Trump example again: if 100,000 people receive one of his tweets, how many even notice it in the non-stop stream of information we are bombarded with today? On the other hand, if 100,000 bellow out a racist slogan at one of his rallies, is there any doubt whether each and every one of those people is engaged with the campaign at that moment? If you could choose between 100 extra Twitter followers or 10 extra activists attending a meeting every month, which would you prefer? Do we need this new definition of a Friend? Facebook is redefining what it means to be a friend. Is somebody who takes pictures of you and insists on sharing them with hundreds of people, tagging your face for the benefit of biometric profiling systems, really a friend? If you want to find out what a real friend is and who your real friends really are, there is no better way to do so then blowing away your Facebook and Twitter account and waiting to see who contacts you personally about meeting up in the real world. If you look at a profile on Facebook or Twitter, one of the most prominent features is the number of friends or followers they have. Research suggests that humans can realistically cope with no more than about 150 stable relationships. Facebook, however, has turned Friending people into something like a computer game. This research is also given far more attention then it deserves though: the number of really meaningful friendships that one person can maintain is far smaller. Think about how many birthdays and spouse's names you can remember and those may be the number of real friendships you can manage well. In his book Busy, Tony Crabbe suggests between 10-20 friendships are in this category and you should spend all your time with these people rather than letting your time be spread thinly across superficial Facebook "friends". This same logic can be extrapolated to activism and marketing in its many forms: is it better for a campaigner or publicist to have fifty journalists following him on Twitter (where tweets are often lost in the blink of an eye) or three journalists who he meets for drinks from time to time? Facebook alternatives: the ultimate trap? Numerous free, open source projects have tried to offer an equivalent to Facebook and Twitter. GNU social, Diaspora and identi.ca are some of the more well known examples. Trying to persuade people to move from Facebook to one of these platforms rarely works. In most cases, Metcalfe's law suggests the size of Facebook will suck them back in like the gravity of a black hole. To help people really beat these monstrosities, the most effective strategy is to help them live without social media, whether it is proprietary or not. The best way to convince them may be to give it up yourself and let them see how much you enjoy life without it. Share your thoughts The FSFE community has recently been debating the use of propriety software and services. Please feel free to join the list and click here to reply on the thread.
Reproducible builds folks: Reproducible Builds: week 113 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday June 18 and Saturday June 24 2017: Upcoming and Past events Our next IRC meeting is scheduled for the 6th of July at 17:00 UTC with this agenda currently:
  1. Introductions
  2. Reproducible Builds Summit update
  3. NMU campaign for buster
  4. Press release: Debian is doing Reproducible Builds for Buster
  5. Reproducible Builds Branding & Logo
  6. should we become an SPI member
  7. Next meeting
  8. Any other business
On June 19th, Chris Lamb presented at LinuxCon China 2017 on Reproducible Builds. On June 23rd, Vagrant Cascadian held a Reproducible Builds question and answer session at Open Source Bridge. Reproducible work in other projects LEDE: firmware-utils and mtd-utils/mkfs.jffs2 now honor SOURCE_DATE_EPOCH. Toolchain development and fixes There was discussion on #782654 about packaging bazel for Debian. Dan Kegel wrote a patch to use ar determinitiscally for Homebrew, a package manager for MacOS. Dan Kegel worked on using SOURCE_DATE_EPOCH and other reproduciblity fixes in fpm, a multi plattform package builder. The Fedora Haskell team disabled parallel builds to achieve reproducible builds. Bernhard M. Wiedemann submitted many patches upstream: Packages fixed and bugs filed Patches submitted upstream: Other patches filed in Debian: Reviews of unreproducible packages 573 package reviews have been added, 154 have been updated and 9 have been removed in this week, adding to our knowledge about identified issues. 1 issue type has been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Version 83 was uploaded to unstable by Chris Lamb. It also moved the previous changes from experimental (to where they were uploaded) to unstable. It included contributions from previous weeks. You can read about these changes in our previous weeks' posts, or view the changelog directly (raw form). We plan to maintain a backport of this and future versions in stretch-backports. Ximin Luo also worked on better html-dir output for very very large diffs such as those for GCC. So far, this includes unreleased work on a PartialString data structure which will form a core part of a new and more intelligent recursive display algorithm. strip-nondeterminism development Versions 0.035-1 was uploaded to unstable from experimental by Chris Lamb. It included contributions from: Later in the week Mattia Rizzolo uploaded 0.035-2 with some improvements to the autopkgtest and to the general packaging. We currently don't plan to maintain a backport in stretch-backports like we did for jessie-backports. Please speak up if you think otherwise. reproducible-website development tests.reproducible-builds.org Misc. This week's edition was written by Ximin Luo, Holger Levsen, Bernhard M. Wiedemann, Mattia Rizzolo, Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Colin Watson: New address book

I ve had a kludgy mess of electronic address books for most of two decades, and have got rather fed up with it. My stack consisted of: The biggest practical problem with this was that I had the address book that was most convenient for me to add things to (Google Contacts) and the one I used when sending email, and no sensible way to merge them or move things between them. I also wasn t especially comfortable with having all my contact information in a proprietary web service. My goals for a replacement address book system were: I think I have all this now! New stack The obvious basic technology to use is CardDAV: it s fairly complex, admittedly, but lots of software supports it and one of my goals was not having to write my own thing. This meant I needed a CardDAV server, some way to sync the database to and from both Android and the system where I run mutt, and whatever query glue was necessary to get mutt to understand vCards. There are lots of different alternatives here, and if anything the problem was an embarrassment of choice. In the end I just decided to go for things that looked roughly the right shape for me and tried not to spend too much time in analysis paralysis. CardDAV server I went with Xandikos for the server, largely because I know Jelmer and have generally had pretty good experiences with their software, but also because using Git for history of the backend storage seems like something my future self will thank me for. It isn t packaged in stretch, but it s in Debian unstable, so I installed it from there. Rather than the standalone mode suggested on the web page, I decided to set it up in what felt like a more robust way using WSGI. I installed uwsgi, uwsgi-plugin-python3, and libapache2-mod-proxy-uwsgi, and created the following file in /etc/uwsgi/apps-available/xandikos.ini which I then symlinked into /etc/uwsgi/apps-enabled/xandikos.ini:
[uwsgi]
socket = 127.0.0.1:8801
uid = xandikos
gid = xandikos
umask = 022
master = true
cheaper = 2
processes = 4
plugin = python3
module = xandikos.wsgi:app
env = XANDIKOSPATH=/srv/xandikos/collections
The port number was arbitrary, as was the path. You need to create the xandikos user and group first (adduser --system --group --no-create-home --disabled-login xandikos). I created /srv/xandikos owned by xandikos:xandikos and mode 0700, and I recommend setting a umask as shown above since uwsgi s default umask is 000 (!). You should also run sudo -u xandikos xandikos -d /srv/xandikos/collections --autocreate and then Ctrl-c it after a short time (I think it would be nicer if there were a way to ask the WSGI wrapper to do this). For Apache setup, I kept it reasonably simple: I ran a2enmod proxy_uwsgi, used htpasswd to create /etc/apache2/xandikos.passwd with a username and password for myself, added a virtual host in /etc/apache2/sites-available/xandikos.conf, and enabled it with a2ensite xandikos:
<VirtualHost *:443>
        ServerName xandikos.example.org
        ServerAdmin me@example.org
        ErrorLog /var/log/apache2/xandikos-error.log
        TransferLog /var/log/apache2/xandikos-access.log
        <Location />
                ProxyPass "uwsgi://127.0.0.1:8801/"
                AuthType Basic
                AuthName "Xandikos"
                AuthBasicProvider file
                AuthUserFile "/etc/apache2/xandikos.passwd"
                Require valid-user
        </Location>
</VirtualHost>
Then service apache2 reload, set the new virtual host up with Let s Encrypt, reloaded again, and off we go. Android integration I installed DAVdroid from the Play Store: it cost a few pounds, but I was OK with that since it s GPLv3 and I m happy to help fund free software. I created two accounts, one for my existing Google Contacts database (and in fact calendaring as well, although I don t intend to switch over to self-hosting that just yet), and one for the new Xandikos instance. The Google setup was a bit fiddly because I have two-step verification turned on so I had to create an app-specific password. The Xandikos setup was straightforward: base URL, username, password, and done. Since I didn t completely trust the new setup yet, I followed what seemed like the most robust option from the DAVdroid contacts syncing documentation, and used the stock contacts app to export my Google Contacts account to a .vcf file and then import that into the appropriate DAVdroid account (which showed up automatically). This seemed straightforward and everything got pushed to Xandikos. There are some weird delays in syncing contacts that I don t entirely understand, but it all seems to get there in the end. mutt integration First off I needed to sync the contacts. (In fact I happen to run mutt on the same system where I run Xandikos at the moment, but I don t want to rely on that, and going through the CardDAV server means that I don t have to poke holes for myself using filesystem permissions.) I used vdirsyncer for this. In ~/.vdirsyncer/config:
[general]
status_path = "~/.vdirsyncer/status/"
[pair contacts]
a = "contacts_local"
b = "contacts_remote"
collections = ["from a", "from b"]
[storage contacts_local]
type = "filesystem"
path = "~/.contacts/"
fileext = ".vcf"
[storage contacts_remote]
type = "carddav"
url = "<Xandikos base URL>"
username = "<my username>"
password = "<my password>"
Running vdirsyncer discover and vdirsyncer sync then synced everything into ~/.contacts/. I added an hourly crontab entry to run vdirsyncer -v WARNING sync. Next, I needed a command-line address book tool based on this. khard looked about right and is in stretch, so I installed that. In ~/.config/khard/khard.conf (this is mostly just the example configuration, but I preferred to sort by first name since not all my contacts have neat first/last names):
[addressbooks]
[[contacts]]
path = ~/.contacts/<UUID of my contacts collection>/
[general]
debug = no
default_action = list
editor = vim
merge_editor = vimdiff
[contact table]
# display names by first or last name: first_name / last_name
display = first_name
# group by address book: yes / no
group_by_addressbook = no
# reverse table ordering: yes / no
reverse = no
# append nicknames to name column: yes / no
show_nicknames = no
# show uid table column: yes / no
show_uids = yes
# sort by first or last name: first_name / last_name
sort = first_name
[vcard]
# extend contacts with your own private objects
# these objects are stored with a leading "X-" before the object name in the vcard files
# every object label may only contain letters, digits and the - character
# example:
#   private_objects = Jabber, Skype, Twitter
private_objects = Jabber, Skype, Twitter
# preferred vcard version: 3.0 / 4.0
preferred_version = 3.0
# Look into source vcf files to speed up search queries: yes / no
search_in_source_files = no
# skip unparsable vcard files: yes / no
skip_unparsable = no
Now khard list shows all my contacts. So far so good. Apparently there are some awkward vCard compatibility issues with creating or modifying contacts from the khard end. I ve tried adding one address from ~/.mutt/aliases using khard and it seems to at least minimally work for me, but I haven t explored this very much yet. I had to install python3-vobject 0.9.4.1-1 from experimental to fix eventable/vobject#39 saving certain vCard files. Finally, mutt integration. I already had set query_command="lbdbq '%s'" in ~/.muttrc, and I wanted to keep that in place since I still wanted to use LDAP querying as well. I had to write a very small amount of code for this (perhaps I should contribute this to lbdb upstream?), in ~/.lbdb/modules/m_khard:
#! /bin/sh
m_khard_query ()  
    khard email --parsable --remove-first-line --search-in-source-files "$1"
 
My full ~/.lbdb/rc now reads as follows (you probably won t want the LDAP stuff, but I ve included it here for completeness):
MODULES_PATH="$MODULES_PATH $HOME/.lbdb/modules"
METHODS='m_muttalias m_khard m_ldap'
LDAP_NICKS='debian canonical'
Next steps I ve deleted one account from Google Contacts just to make sure that everything still works (e.g. I can still search for it when composing a new message), but I haven t yet deleted everything. I won t be adding anything new there though. I need to push everything from ~/.mutt/aliases into the new system. This is only about 30 contacts so shouldn t take too long. Overall this feels like a big improvement! It wasn t a trivial amount of setup for just me, but it means I have both better usability for myself and more independence from proprietary services, and I think I can add extra users with much less effort if I need to. Postscript A day later and I ve consolidated all my accounts from Google Contacts and ~/.mutt/aliases into the new system, with the exception of one group that I had defined as a mutt alias and need to work out what to do with. This all went smoothly. I ve filed the new lbdb module as #866178, and the python3-vobject bug as #866181.

Benjamin Mako Hill: Learning to Code in One s Own Language

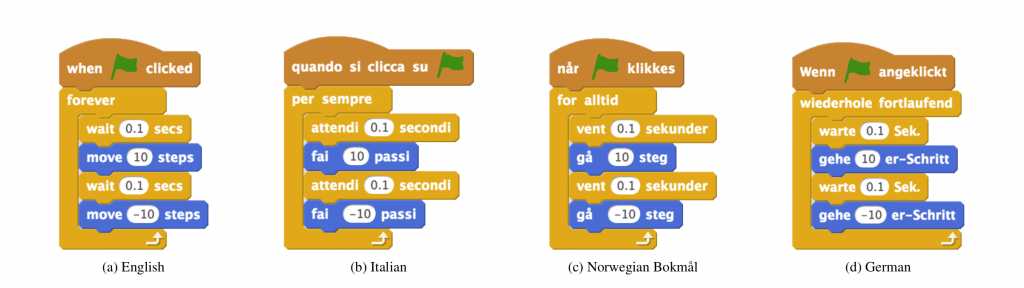
I recently published a paper with Sayamindu Dasgupta that provides evidence in support of the idea that kids can learn to code more quickly when they are programming in their own language. Millions of young people from around the world are learning to code. Often, during their learning experiences, these youth are using visual block-based programming languages like Scratch, App Inventor, and Code.org Studio. In block-based programming languages, coders manipulate visual, snap-together blocks that represent code constructs instead of textual symbols and commands that are found in more traditional programming languages. The textual symbols used in nearly all non-block-based programming languages are drawn from English consider if statements and for loops for common examples. Keywords in block-based languages, on the other hand, are often translated into different human languages. For example, depending on the language preference of the user, an identical set of computing instructions in Scratch can be represented in many different human languages:
Examples of a short piece of Scratch code shown in four different human languages: English, Italian, Norwegian Bokm l, and German.
Although my research with Sayamindu Dasgupta focuses on learning, both Sayamindu and I worked on local language technologies before coming back to academia. As a result, we were both interested in how the increasing translation of programming languages might be making it easier for non-English speaking kids to learn to code. After all, a large body of education research has shown that early-stage education is more effective when instruction is in the language that the learner speaks at home. Based on this research, we hypothesized that children learning to code with block-based programming languages translated to their mother-tongues will have better learning outcomes than children using the blocks in English. We sought to test this hypothesis in Scratch, an informal learning community built around a block-based programming language. We were helped by the fact that Scratch is translated into many languages and has a large number of learners from around the world. To measure learning, we built on some of our our own previous work and looked at learners cumulative block repertoires similar to a code vocabulary. By observing a learner s cumulative block repertoire over time, we can measure how quickly their code vocabulary is growing. Using this data, we compared the rate of growth of cumulative block repertoire between learners from non-English speaking countries using Scratch in English to learners from the same countries using Scratch in their local language. To identify non-English speakers, we considered Scratch users who reported themselves as coming from five primarily non-English speaking countries: Portugal, Italy, Brazil, Germany, and Norway. We chose these five countries because they each have one very widely spoken language that is not English and because Scratch is almost fully translated into that language. Even after controlling for a number of factors like social engagement on the Scratch website, user productivity, and time spent on projects, we found that learners from these countries who use Scratch in their local language have a higher rate of cumulative block repertoire growth than their counterparts using Scratch in English. This faster growth was despite having a lower initial block repertoire. The graph below visualizes our results for two prototypical learners who start with the same initial block repertoire: one learner who uses the English interface, and a second learner who uses their native language.
Summary of the results of our model for two prototypical individuals.
Our results are in line with what theories of education have to say about learning in one s own language. Our findings also represent good news for designers of block-based programming languages who have spent considerable amounts of effort in making their programming languages translatable. It s also good news for the volunteers who have spent many hours translating blocks and user interfaces. Although we find support for our hypothesis, we should stress that our findings are both limited and incomplete. For example, because we focus on estimating the differences between Scratch learners, our comparisons are between kids who all managed to successfully use Scratch. Before Scratch was translated, kids with little working knowledge of English or the Latin script might not have been able to use Scratch at all. Because of translation, many of these children are now able to learn to code.
This blog post and the work that it describes is a collaborative project with Sayamindu Dasgupta. Sayamindu also published a very similar version of the blog post in several places. Our paper is open access and you can read it here. The paper was published in the proceedings of the ACM Learning @ Scale Conference. We also recently gave a talk about this work at the International Communication Association s annual conference. We received support and feedback from members of the Scratch team at MIT (especially Mitch Resnick and Natalie Rusk), as well as from Nathan TeBlunthuis at the University of Washington. Financial support came from the US National Science Foundation.

26 June 2017

Alexander Wirt: Stretch Backports available

With the release of stretch we are pleased to open the doors for stretch-backports and jessie-backports-sloppy. \o/ As usual with a new release we will change a few things for the backports service.

What to upload where As a reminder, uploads to a release-backports pocket are to be taken from release + 1, uploads to a release-backports-sloppy pocket are to be taken from release + 2. Which means:
Source Distribution Backports Distribution Sloppy Distribution
buster stretch-backports jessie-backports-sloppy
stretch jessie-backports -

Deprecation of LTS support for backports We started supporting backports as long as there is LTS support as an experiment. Unfortunately it didn t worked, most maintainers didn t wanted to support oldoldstable-backports (squeeze) for the lifetime of LTS. So things started to rot in squeeze and most packages didn t received updates. After long discussions we decided to deprecate LTS support for backports. From now on squeeze-backports(-sloppy) is closed and will not receive any updates. Expect it to get removed from the mirrors and moved to archive in the near future.

BSA handling We - the backports team - didn t scale well in processing BSA requests. To get things better in the future we decided to change the process a little bit. If you upload a package which fixes security problems please fill out the BSA template and create a ticket in the rt tracker (see https://backports.debian.org/Contribute/#index3h2 for details).

Stretching the rules From time to time its necessary to not follow the backports rules, like a package needs to be in testing or a version needs to be in Debian. If you think you have one of those cases, please talk to us on the list before upload the package.

Thanks Thanks have to go out to all people making backports possible, and that includes up front the backporters themself who do upload the packages, track and update them on a regular basis, but also the buildd team making the autobuilding possible and the ftp masters for creating the suites in the first place. We wish you a happy stretch :) Alex, on behalf of the Backports Team

Jonathan Dowland: Coming in from the cold

I've been using a Mac day-to-day since around 2014, initially as a refreshing break from the disappointment I felt with GNOME3, but since then a few coincidences have kept me on the platform. Something happened earlier in the year that made me start to think about a move back to Linux on the desktop. My next work hardware refresh is due in March next year, which gives me about nine months to "un-plumb" myself from the Mac ecosystem. From the top of my head, here's the things I'm going to have to address: I think that's probably it: not a big list! Notably, I'm not locked into iTunes, which I avoid where possible; Apple's Photo app (formerly iPhoto) which is a bit of a disaster; nor Time Machine, which is excellent, but I have a backup system for other things in place that I can use.

25 June 2017

Andreas Bombe: PDP-8/e Replicated Introduction

I am creating a replica of the DEC PDP-8/e architecture in an FPGA from schematics of the original hardware. So how did I end up with a project like this? The story begins with me wanting to have a computer with one of those front panels that have many, many lights where you can really see, in real time, what the computer is doing while it is executing code. Not because I am nostalgic for a prior experience with any of those I was born a bit too late for that and my first computer as a kid was a Commodore 64. Now, the front panel era ended around 40 years ago with the advent of microprocessors and computers of that age and older that are complete and working are hard to find and not cheap. And even if you do, there s the issue of weight, size (complete systems with peripherals fill at least a rack) and power consumption. So what to do build myself a small one with modern technology of course. While there s many computer architectures of that era to choose from, the various PDP machines by DEC are significant and well known (and documented) due to their large numbers. The most important are probably the 12 bit PDP-8, the 16 bit PDP-11 and the 36 bit PDP-10. While the PDP-11 is enticing because of the possibility to run UNIX I wanted to start with something simpler, so I chose the PDP-8.
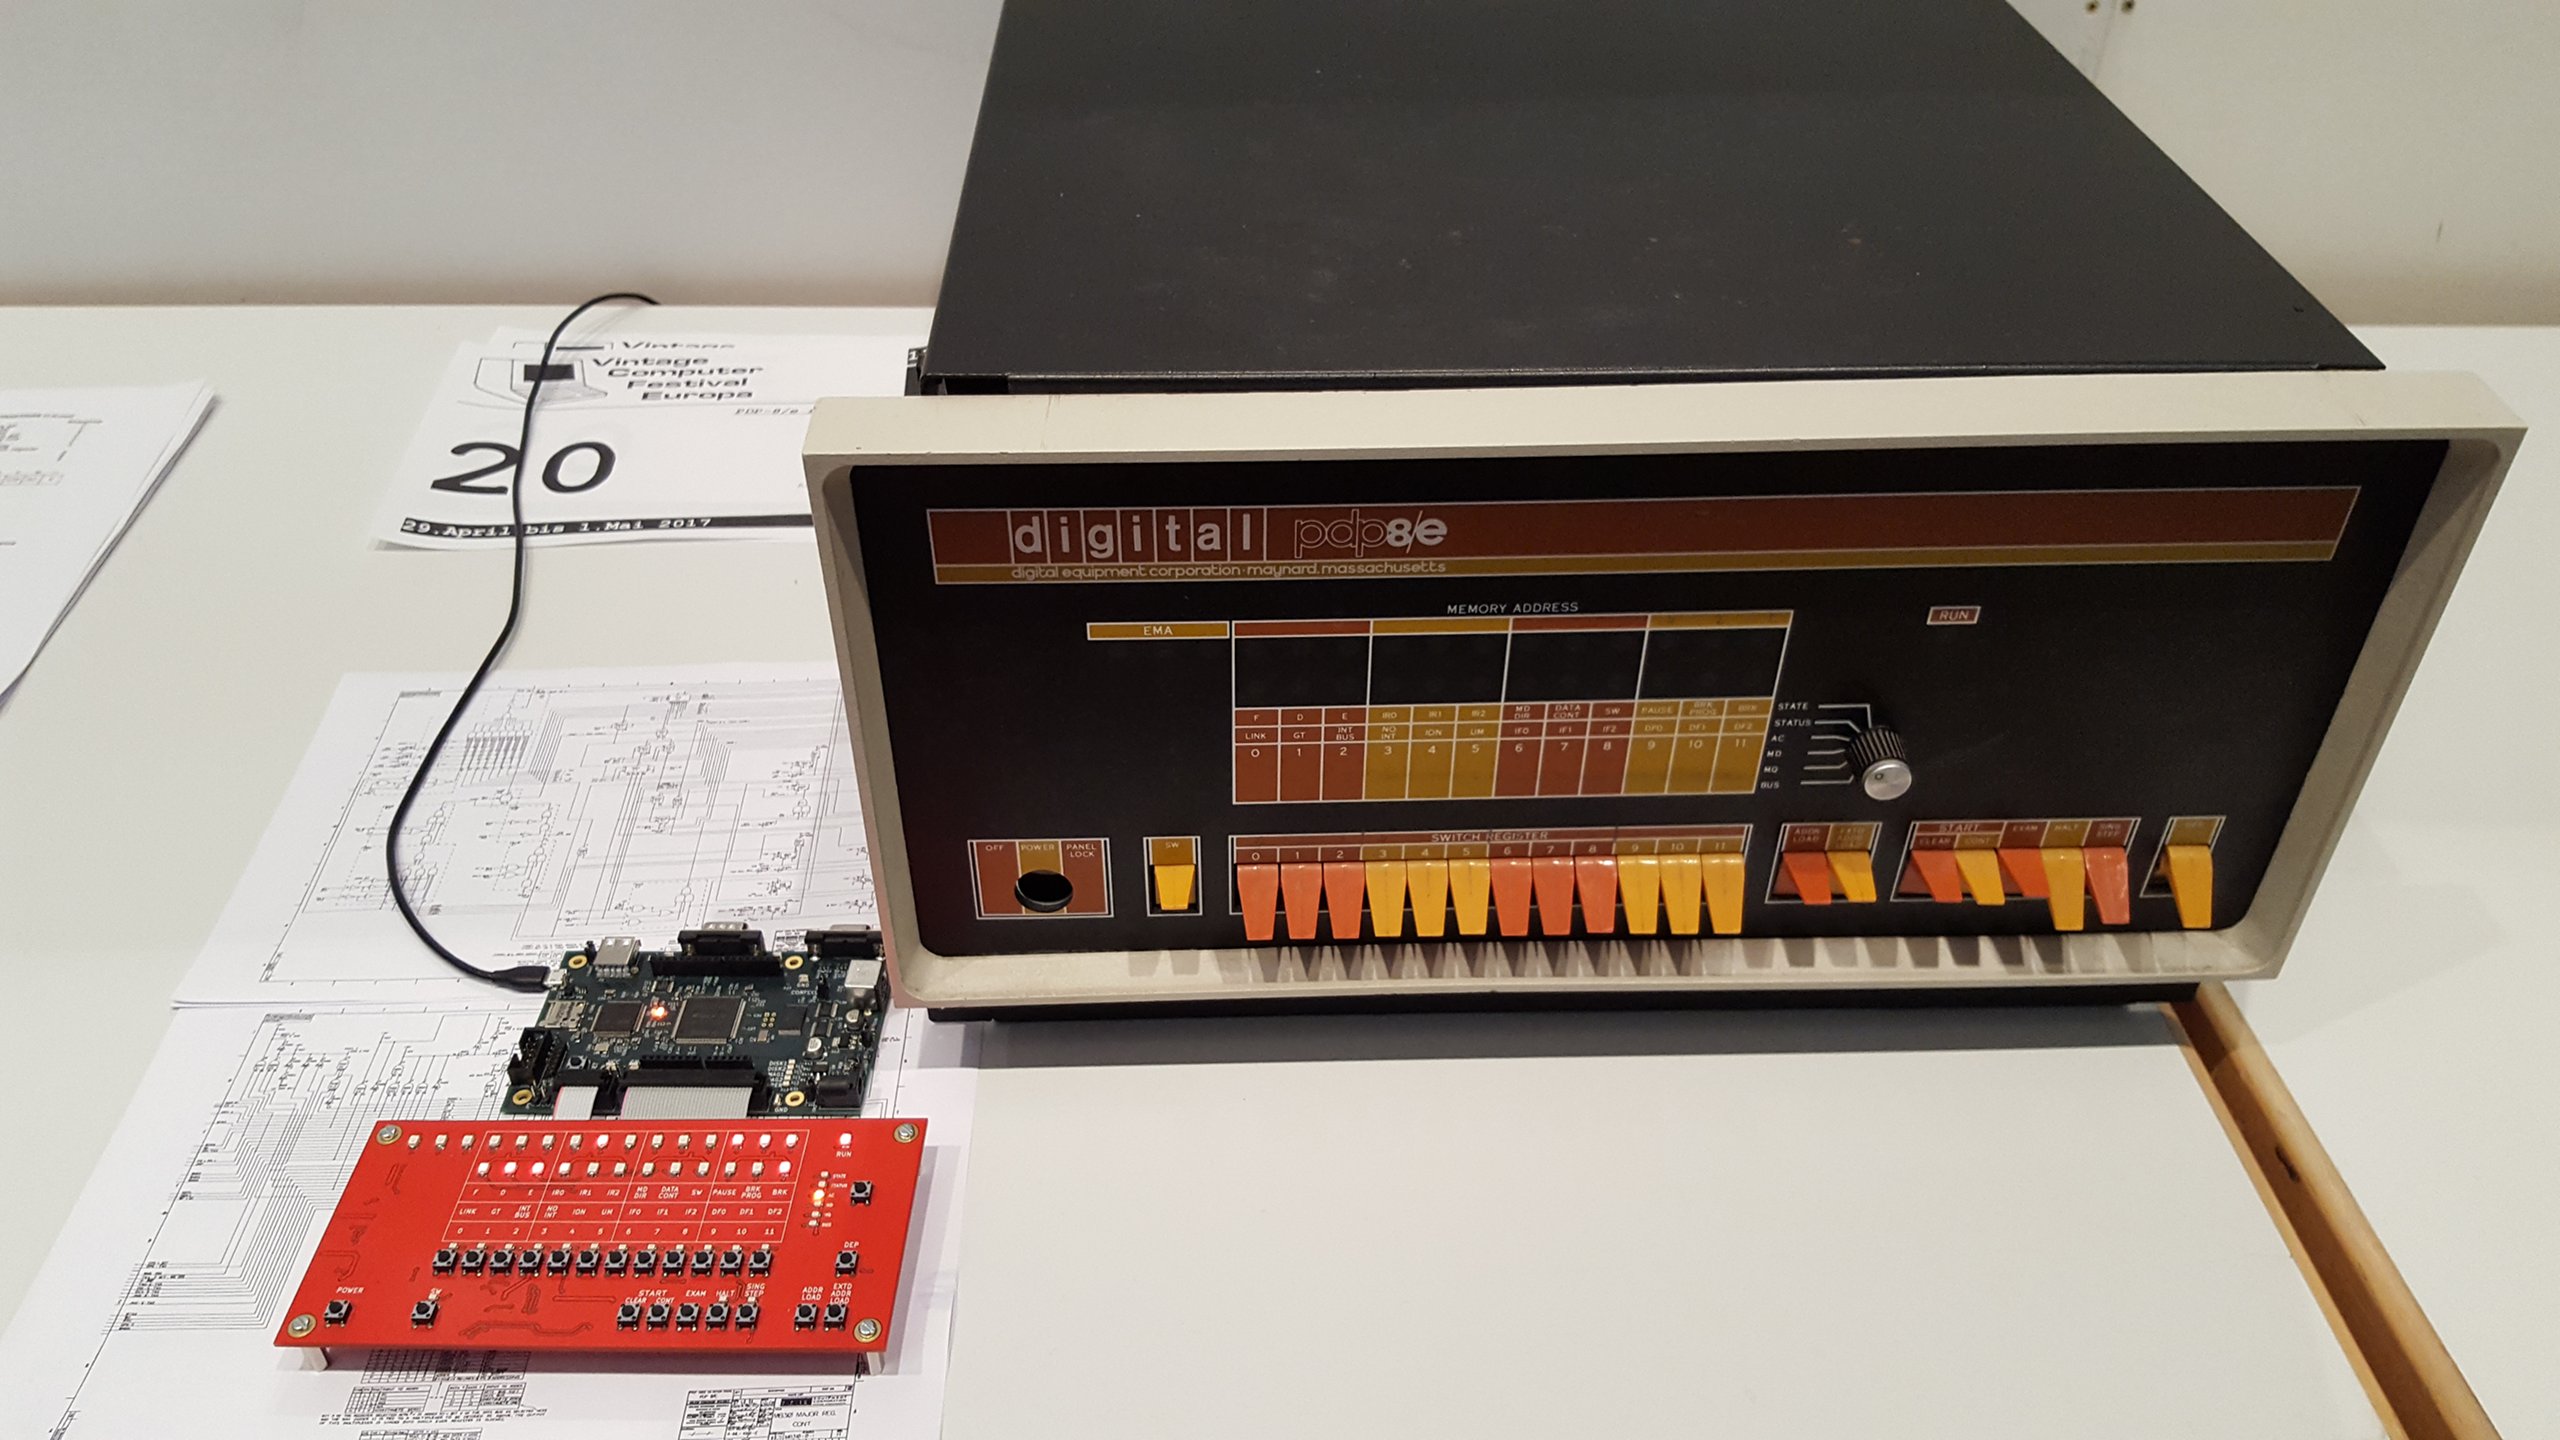
My implementation on display next to a real PDP-8/e at VCFe 18.0

The Original DEC started the PDP-8 line of computers programmed data processors designed as low cost machines in 1965. It is a quite minimalist 12 bit architecture based on the earlier PDP-5, and by minimalist I mean seriously minimal. If you are familiar with early 8 bit microprocessors like the 6502 or 8080 you will find them luxuriously equipped in comparison. The PDP-8 base architecture has a program counter (PC) and an accumulator (AC)1. That s it. There are no pointer or index registers2. There is no stack. It has addition and AND instructions but subtractions and OR operations have to be manually coded. The optional Extended Arithmetic Element adds the MQ register but that s really it for visible registers. The Wikipedia page on the PDP-8 has a good detailed description. Regarding technology, the PDP-8 series has been in production long enough to get the whole range of implementations from discrete transistor logic to microprocessors. The 8/e which I target was right in the middle, implemented in TTL logic where each IC contains multiple logic elements. This allowed the CPU itself (including timing generator) to fit on three large circuit boards plugged into a backplane. Complete systems would have at least another board for the front panel and multiple boards for the core memory, then additional boards for whatever options and peripherals were desired.

Design Choices and Comparisons I m not the only one who had the idea to build something like that, of course. Among the other modern PDP-8 implementations with a front panel, probably the most prominent project is the Spare Time Gizmos SBC6120 which is a PDP-8 single board computer built around the Harris/Intersil HD-6120 microprocessor, which implementes the PDP-8 architecture, combined with a nice front panel. Another is the PiDP-8/I, which is another nice front panel (modeled after the 8/i which has even more lights) driven by the simh simulator running under Linux on a Raspberry Pi. My goal is to get front panel lights that appear exactly like the real ones in operation. This necessitates driving the lights at full speed as they change with every instruction or even within instructions for some display selections. For example, if you run a tight loop that does nothing but increment AC while displaying that register, it would appear that all lights are lit at equal but less than full brightness. The reason is that the loop runs at such a high speed that even the most significant bit, which is blinking the slowest, is too fast to see flicker. Hence they are all effectively 50% on, just at different frequencies, and appear to be constantly light at the same brightness. This is where the other projects lack what I am looking for. The PiDP-8/I is a multiplexed display which updates at something like 30 Hz or 60 Hz, taking whatever value is current in the simulation software at the time. All the states the lights took inbetween are lost and consequently there is flickering where there shouldn t be. On the SBC6120 at least the address lines appear to update at full speed as these are the actual RAM address lines. However the used 6120 microprocessor does not have required data for the indicator display externally available. Instead, the SBC6120 runs an interrupt at 30 Hz to trap into its firmware/monitor program which then reads the current state and writes it to the front panel display, which is essentially just another peripheral. A different considerable problem with the SBC6120 is its use of the 6100 microprocessor family ICs, which are themselves long out of production and not trivial (or cheaply) to come by. Given that the way to go is to drive all lights in step with every cycle3, this can be done by a software running on a dedicated microcontroller which is how I started or by implementing a real CPU with all the needed outputs in an FPGA which is the project I am writing about. In the next post I give an overview of the hardware I built so far and some of the features that are yet to be implemented.

  1. With an associated link bit which is a little different from a carry bit in that it is treated as a thirteenth bit, i.e. it will be flipped rather than set when a carry occurs. [return]
  2. Although there are 8 specially treated memory addresses that will pre-increment when used in indirect addressing. [return]
  3. Basic cycles on the PDP-8/e are 1.4 s for memory modifying cycles and fast cycles of 1.2 s for everything else. Instructions can be one to three cycles long. [return]

Steinar H. Gunderson: Frame queue management in Nageru 1.6.1

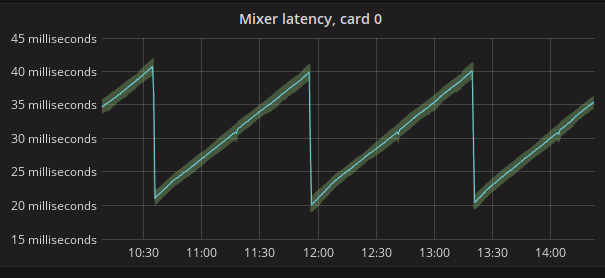
Nageru 1.6.1 is on its way, and what was intended to only be a release centered around monitoring improvements (more specifically a full set of native Prometheus] metrics) actually ended up getting a fairly substantial change to how Nageru manages its frame queues. To understand what's changing and why, it's useful to first understand the history of Nageru's queue management. Nageru 1.0.0 started out with a fairly simple scheme, but with some basics that are still relevant today: One of the input cards was deemed the master card, and whenever it delivers a frame, the master clock ticks and an output frame is produced. (There are some subtleties about dropped frames and/or the master card changing frame rates, but I'm going to ignore them, since they're not important to the discussion.) To this end, every card keeps a preallocated frame queue; when a card delivers a frame, it's put into the queue, and when the master clock ticks, it tries picking out one frame from each of the other card's queues to mix together. Note that mix here could be as simple as picking one input and throwing all the other ones away; the queueing algorithm doesn't care, it just feeds all of them to the theme and lets that run whatever GPU code it needs to match the user's preferences. The only thing that really keeps the queues bounded is that the frames in them are preallocated (in GPU memory), so if one queue gets longer than 16 frames, Nageru starts dropping it. But is 16 the right number? There are two conflicting demands here, ignoring memory usage: The 1.0.0 scheme does about as well as one could possibly hope in never dropping frames, but unfortunately, it can be pretty poor at latency. For instance, if your master card runs at 50 Hz and you have a 60 Hz card, the latter will eventually build up a delay of 16 * 16.7 ms = 266.7 ms clearly unacceptable, and rather unneeded. You could ask the user to specify a queue length, but the user probably doesn't know, and also shouldn't really have to care more knobs to twiddle are a bad thing, and even more so knobs the user is expected to twiddle. Thus, Nageru 1.2.0 introduced queue autotuning; it keeps a running estimate on how big the queue needs to be to avoid underruns, simply based on experience. If we've been dropping frames on a queue and then there's an underrun, the safe queue length is increased by one, and if the queue has been having excess frames for more than a thousand successive master clock ticks, we reduce it by one again. Whenever the queue has more than this safe number, we drop frames. This was simple, effective and largely fixed the problem. However, when adding metrics, I noticed a peculiar effect: Not all of my devices have equally good clocks. In particular, when setting up for 1080p50, my output card's internal clock (which assumes the role of the master clock when using HDMI/SDI output) seems to tick at about 49.9998 Hz, and my simple home camcorder delivers frames at about 49.9995 Hz. Over the course of an hour, this means it produces one more frame than you should have which should of course be dropped. Having an SDI setup with synchronized clocks (blackburst/tri-level) would of course fix this problem, but most people are not so lucky with their cameras, not to mention the price of PC graphics cards with SDI outputs! However, this happens very slowly, which means that for a significant amount of time, the two clocks will very nearly be in sync, and thus racing. Who ticks first is determined largely by luck in the jitter (normal is maybe 1ms, but occasionally, you'll see delayed delivery of as much as 10 ms), and this means that the 1000 frames estimate is likely to be thrown off, and the result is hundreds of dropped frames and underruns in that period. Once the clocks have diverged enough again, you're off the hook, but again, this isn't a good place to be. Thus, Nageru 1.6.1 change the algorithm around yet again, by incorporating more data to build an explicit jitter model. 1.5.0 was already timestamping each frame to be able to measure end-to-end latency precisely (now also exposed in Prometheus metrics), but from 1.6.1, they are actually used in the queueing algorithm. I ran several eight- to twelve-hour tests and simply stored all the event arrivals to a file, and then simulated a few different algorithms (including the old algorithm) to see how they fared in measures such as latency and number of drops/underruns. I won't go into the full details of the new queueing algorithm (see the commit if you're interested), but the gist is: Based on the last 5000 frames, it tries to estimate the maximum possible jitter for each input (ie., how late the frame could possibly be). Based on this as well as clock offsets, it determines whether it's really sure that there will be an input frame available on the next master tick even if it drops the queue, and then trims the queue to fit. The result is pretty satisfying; here's the end-to-end latency of my camera being sent through to the SDI output: As you can see, the latency goes up, up, up until Nageru figures it's now safe to drop a frame, and then does it in one clean drop event; no more hundreds on drops involved. There are very late frame arrivals involved in this run two extra frame drops, to be precise but the algorithm simply determines immediately that they are outliers, and drops them without letting them linger in the queue. (Immediate dropping is usually preferred to sticking around for a bit and then dropping it later, as it means you only get one disturbance event in your stream as opposed to two. Of course, you can only do it if you're reasonably sure it won't lead to more underruns later.) Nageru 1.6.1 will ship before Solskogen, as I intend to run it there :-) And there will probably be lovely premade Grafana dashboards from the Prometheus data. Although it would have been a lot nicer if Grafana were more packaging-friendly, so I could pick it up from stock Debian and run it on armhf. Hrmf. :-)

24 June 2017

Lisandro Dami n Nicanor P rez Meyer: Qt 5.7 submodules that didn't make it to Stretch but will be in testing

There are two Qt 5.7 submodules that we could not package in time for Strech but are/will be available in their 5.7 versions in testing. This are qtdeclarative-render2d-plugin and qtvirtualkeyboard.

declarative-render2d-plugin makes use of the Raster paint engine instead of OpenGL to render the contents of a scene graph, thus making it useful when Qt Quick2 applications are run in a system without OpenGL 2 enabled hardware. Using it might require tweaking Debian's /etc/X11/Xsession.d/90qt5-opengl. On Qt 5.9 and newer this plugin is merged in Qt GUI so there should be no need to perform any action on the user's behalf.

Debian's VirtualKeyboard currently has a gotcha: we are not building it with the embedded code it ships. Upstream ships 3rd party code but lacks a way to detect and use the system versions of them. See QTBUG-59594, patches are welcomed. Please note that we prefer patches sent directly upstream to the current dev revision, we will be happy to backport patches if necessary.
Yes, this means no hunspell, openwnn, pinyin, tcime nor lipi-toolkit/t9write support.


Ingo Juergensmann: Upgrade to Debian Stretch - GlusterFS fails to mount

Before I upgrade from Jessie to Stretch everything worked as a charme with glusterfs in Debian. But after I upgraded the first VM to Debian Stretch I discovered that glusterfs-client was unable to mount the storage on Jessie servers. I got this in glusterfs log:
[2017-06-24 12:51:53.240389] I [MSGID: 100030] [glusterfsd.c:2454:main] 0-/usr/sbin/glusterfs: Started running /usr/sbin/glusterfs version 3.8.8 (args: /usr/sbin/glusterfs --read-only --fuse-mountopts=nodev,noexec --volfile-server=192.168.254.254 --volfile-id=/le --fuse-mountopts=nodev,noexec /etc/letsencrypt.sh/certs)
[2017-06-24 12:51:54.534826] E [mount.c:318:fuse_mount_sys] 0-glusterfs-fuse: ret = -1

[2017-06-24 12:51:54.534896] I [mount.c:365:gf_fuse_mount] 0-glusterfs-fuse: direct mount failed (Invalid argument) errno 22, retry to mount via fusermount
[2017-06-24 12:51:56.668254] I [MSGID: 101190] [event-epoll.c:628:event_dispatch_epoll_worker] 0-epoll: Started thread with index 1
[2017-06-24 12:51:56.671649] E [glusterfsd-mgmt.c:1590:mgmt_getspec_cbk] 0-glusterfs: failed to get the 'volume file' from server
[2017-06-24 12:51:56.671669] E [glusterfsd-mgmt.c:1690:mgmt_getspec_cbk] 0-mgmt: failed to fetch volume file (key:/le)
[2017-06-24 12:51:57.014502] W [glusterfsd.c:1327:cleanup_and_exit] (-->/usr/lib/x86_64-linux-gnu/libgfrpc.so.0(rpc_clnt_handle_reply+0x90) [0x7fbea36c4a20] -->/usr/sbin/glusterfs(mgmt_getspec_cbk+0x494) [0x55fbbaed06f4] -->/usr/sbin/glusterfs(cleanup_and_exit+0x54) [0x55fbbaeca444] ) 0-: received signum (0), shutting down
[2017-06-24 12:51:57.014564] I [fuse-bridge.c:5794:fini] 0-fuse: Unmounting '/etc/letsencrypt.sh/certs'.
[2017-06-24 16:44:45.501056] I [MSGID: 100030] [glusterfsd.c:2454:main] 0-/usr/sbin/glusterfs: Started running /usr/sbin/glusterfs version 3.8.8 (args: /usr/sbin/glusterfs --read-only --fuse-mountopts=nodev,noexec --volfile-server=192.168.254.254 --volfile-id=/le --fuse-mountopts=nodev,noexec /etc/letsencrypt.sh/certs)
[2017-06-24 16:44:45.504038] E [mount.c:318:fuse_mount_sys] 0-glusterfs-fuse: ret = -1

[2017-06-24 16:44:45.504084] I [mount.c:365:gf_fuse_mount] 0-glusterfs-fuse: direct mount failed (Invalid argument) errno 22, retry to mount via fusermount
After some searches on the Internet I found Debian #858495, but no solution for my problem. Some search results recommended to set "option rpc-auth-allow-insecure on", but this didn't help. In the end I joined #gluster on Freenode and got some hints there:
JoeJulian ij__: debian breaks apart ipv4 and ipv6. You'll need to remove the ipv6 ::1 address from localhost in /etc/hosts or recombine your ip stack (it's a sysctl thing)
JoeJulian It has to do with the decisions made by the debian distro designers. All debian versions should have that problem. (yes, server side).
Removing ::1 from /etc/hosts and from lo interface did the trick and I could mount glusterfs storage from Jessie servers in my Stretch VMs again. However, when I upgraded the glusterfs storages to Stretch as well, this "workaround" didn't work anymore. Some more searching on the Internet made me found this posting on glusterfs mailing list:
We had seen a similar issue and Rajesh has provided a detailed explanation on why at [1]. I'd suggest you to not to change glusterd.vol but execute "gluster volume set <volname> transport.address-family inet" to allow Gluster to listen on IPv4 by default.
Setting this option instantly fixed my issues with mounting glusterfs storages. So, whatever is wrong with glusterfs in Debian, it seems to have something to do with IPv4 and IPv6. When disabling IPv6 in glusterfs, it works. I added information to #858495.
Kategorie:

23 June 2017

Joachim Breitner: The perils of live demonstrations

Yesterday, I was giving a talk at the The South SF Bay Haskell User Group about how implementing lock-step simulation is trivial in Haskell and how Chris Smith and me are using this to make CodeWorld even more attractive to students. I gave the talk before, at Compose::Conference in New York City earlier this year, so I felt well prepared. On the flight to the West Coast I slightly extended the slides, and as I was too cheap to buy in-flight WiFi, I tested them only locally. So I arrived at the offices of Target1 in Sunnyvale, got on the WiFi, uploaded my slides, which are in fact one large interactive CodeWorld program, and tried to run it. But I got a type error Turns out that the API of CodeWorld was changed just the day before:
commit 054c811b494746ec7304c3d495675046727ab114
Author: Chris Smith <cdsmith@gmail.com>
Date:   Wed Jun 21 23:53:53 2017 +0000
    Change dilated to take one parameter.
    
    Function is nearly unused, so I'm not concerned about breakage.
    This new version better aligns with standard educational usage,
    in which "dilation" means uniform scaling.  Taken as a separate
    operation, it commutes with rotation, and preserves similarity
    of shapes, neither of which is true of scaling in general.
Ok, that was quick to fix, and the CodeWorld server started to compile my code, and compiled, and aborted. It turned out that my program, presumably the larges CodeWorld interaction out there, hit the time limit of the compiler. Luckily, Chris Smith just arrived at the venue, and he emergency-bumped the compiler time limit. The program compiled and I could start my presentation. Unfortunately, the biggest blunder was still awaiting for me. I came to the slide where two instances of pong are played over a simulated network, and my point was that the two instances are perfectly in sync. Unfortunately, they were not. I guess it did support my point that lock-step simulation can easily go wrong, but it really left me out in the rain there, and I could not explain it I did not modify this code since New York, and there it worked flawless2. In the end, I could save my face a bit by running the real pong game against an attendee over the network, and no desynchronisation could be observed there. Today I dug into it and it took me a while, and it turned out that the problem was not in CodeWorld, or the lock-step simulation code discussed in our paper about it, but in the code in my presentation that simulated the delayed network messages; in some instances it would deliver the UI events in different order to the two simulated players, and hence cause them do something different. Phew.

  1. Yes, the retail giant. Turns out that they have a small but enthusiastic Haskell-using group in their IT department.
  2. I hope the video is going to be online soon, then you can check for yourself.

Elena 'valhalla' Grandi: On brokeness, the live installer and being nice to people

On brokeness, the live installer and being nice to people

This morning I've read this blog.einval.com/2017/06/22#tro.

I understand that somebody on the internet will always be trolling, but I just wanted to point out:

* that the installer in the old live images has been broken (for international users) for years
* that nobody cared enough to fix it, not even the people affected by it (the issue was reported as known in various forums, but for a long time nobody even opened an issue to let the *developers* know).

Compare this with the current situation, with people doing multiple tests as the (quite big number of) images were being built, and a fix released soon after for the issues found.

I'd say that this situation is great, and that instead of trolling around we should thank the people involved in this release for their great job.

Arturo Borrero Gonz lez: Backup router/switch configuration to a git repository

git Most routers/switches out there store their configuration in plain text, which is nice for backups. I m talking about Cisco, Juniper, HPE, etc. The configuration of our routers are being changed several times a day by the operators, and in this case we lacked some proper way of tracking these changes. Some of these routers come with their own mechanisms for doing backups, and depending on the model and version perhaps they include changes-tracking mechanisms as well. However, they mostly don t integrate well into our preferred version control system, which is git. After some internet searching, I found rancid, which is a suite for doing tasks like this. But it seemed rather complex and feature-full for what we required: simply fetch the plain text config and put it into a git repo. Worth noting that the most important drawback of not triggering the change-tracking from the router/switch is that we have to follow a polling approach: loggin into each device, get the plain text and the commit it to the repo (if changes detected). This can be hooked in cron, but as I said, we lost the sync behaviour and won t see any changes until the next cron is run. In most cases, we lost authorship information as well. But it was not important for us right now. In the future this is something that we will have to solve. Also, some routers/switches lack some basic SSH security improvements, like public-key authentication, so we end having to hard-code user/pass in our worker script. Since we have several devices of the same type, we just iterate over their names. For example, this is what we use for hp comware devices:
#!/bin/bash
# run this script by cron
USER="git"
PASSWORD="readonlyuser"
DEVICES="device1 device2 device3 device4"
FILE="flash:/startup.cfg"
GIT_DIR="myrepo"
GIT="/srv/git/$ GIT_DIR .git"
TMP_DIR="$(mktemp -d)"
if [ -z "$TMP_DIR" ] ; then
	echo "E: no temp dir created" >&2
	exit 1
fi
GIT_BIN="$(which git)"
if [ ! -x "$GIT_BIN" ] ; then
	echo "E: no git binary" >&2
	exit 1
fi
SCP_BIN="$(which scp)"
if [ ! -x "$SCP_BIN" ] ; then
	echo "E: no scp binary" >&2
	exit 1
fi
SSHPASS_BIN="$(which sshpass)"
if [ ! -x "$SSHPASS_BIN" ] ; then
	echo "E: no sshpass binary" >&2
	exit 1
fi
# clone git repo
cd $TMP_DIR
$GIT_BIN clone $GIT
cd $GIT_DIR
for device in $DEVICES; do
	mkdir -p $device
	cd $device
	# fetch cfg
	CONN="$ USER @$ device "
	$SSHPASS_BIN -p "$PASSWORD" $SCP_BIN $ CONN :$ FILE  .
	# commit
	$GIT_BIN add -A .
	$GIT_BIN commit -m "$ device : configuration change" \
		-m "A configuration change was detected" \
		--author="cron <cron@example.com>"
	$GIT_BIN push -f
	cd ..
done
# cleanup
rm -rf $TMP_DIR
You should create a read-only user git in the devices. And beware that each device model has the config file stored in a different place. For reference, in HP comware, the file to scp is flash:/startup.cfg. And you might try creating the user like this:
local-user git class manage
 password hash xxxxx
 service-type ssh
 authorization-attribute user-role security-audit
#
In Junos/Juniper, the file you should scp is /config/juniper.conf.gz and the script should gunzip the data before committing. For the read-only user, try is something like this:
system  
	[...]
	login  
		[...]
		class git  
			permissions maintenance;
			allow-commands scp.*;
		 
		user git  
			uid xxx;
			class git;
			authentication  
				encrypted-password "xxx";


The file to scp in HP procurve is /cfg/startup-config. And for the read-only user, try something like this:
aaa authorization group "git user" 1 match-command "scp.*" permit
aaa authentication local-user "git" group "git user" password sha1 "xxxxx"
What would be the ideal situation? Get the device controlled directly by git (i.e. commit > git hook > device update) or at least have the device to commit the changes by itself to git. I m open to suggestions :-)

22 June 2017

Steve McIntyre: -1, Trolling

Here's a nice comment I received by email this morning. I guess somebody was upset by my last post?
From: Tec Services <tecservices911@gmail.com>
Date: Wed, 21 Jun 2017 22:30:26 -0700
To: steve@einval.com
Subject: its time for you to retire from debian...unbelievable..your
         the quality guy and fucked up the installer!
i cant ever remember in the hostory of computing someone releasing an installer
that does not work!!
wtf!!!
you need to be retired...due to being retarded..
and that this was dedicated to ian...what a
disaster..you should be ashames..he is probably roling in his grave from shame
right now....
It's nice to be appreciated.

John Goerzen: First Experiences with Stretch

I ve done my first upgrades to Debian stretch at this point. The results have been overall good. On the laptop my kids use, I helped my 10-year-old do it, and it worked flawlessly. On my workstation, I got a kernel panic on boot. Hmm. Unfortunately, my system has to use the nv drivers, which leaves me with an 80 25 text console. It took some finagling (break=init in grub, then manually insmoding the appropriate stuff based on modules.dep for nouveau), but finally I got a console so I could see what was breaking. It appeared that init was crashing because it couldn t find liblz4. A little digging shows that liblz4 is in /usr, and /usr wasn t mounted. I ve filed the bug on systemd-sysv for this. I run root on ZFS, and further digging revealed that I had datasets named like this: This used to be fine. The mountpoint property of the usr dataset put it at /usr without incident. But it turns out that this won t work now, unless I set ZFS_INITRD_ADDITIONAL_DATASETS in /etc/default/zfs for some reason. So I renamed them so usr was under ROOT, and then the system booted. Then I ran samba not liking something in my bind interfaces line (to be fair, it did still say eth0 instead of br0). rpcbind was failing in postinst, though a reboot seems to have helped that. More annoying was that I had trouble logging into my system because resolv.conf was left empty (despite dns-* entries in /etc/network/interfaces and the presence of resolvconf). I eventually repaired that, and found that it kept removing my search line. Eventually I removed resolvconf. Then mariadb s postinst was silently failing. I eventually discovered it was sending info to syslog (odd), and /etc/init.d/apparmor teardown let it complete properly. It seems like there may have been an outdated /etc/apparmor.d/cache/usr.sbin.mysql out there for some reason. Then there was XFCE. I use it with xmonad, and the session startup was really wonky. I had to zap my sessions, my panel config, etc. and start anew. I am still not entirely sure I have it right, but I at do have a usable system now.

Norbert Preining: Signal handling in R

Recently I have been programming quite a lot in R, and today stumbled over the problem to implement a kind of monitoring loop in R. Typically that would be a infinite loop with sleep calls, but I wanted to allow for waking up from the sleep via sending UNIX style signals, in particular SIGINT. After some searching I found Beyond Exception Handling: Conditions and Restarts from the Advanced R book. But it didn t really help me a lot to program an interrupt handler.
My requirements were: Unfortunately it seems not to be possible to ignore interrupts at all from with the R code. The best one can do is install interrupt handlers and try to repeat the code which was executed while the interrupt happened. This is what I tried to implement with the following code below. I still have to digest the documentation about conditions and restarts, and play around a lot, but at least this is an initial working version.
workfun <- function()  
  i <- 1
  do_repeat <- FALSE
  while (TRUE)  
    message("begin of the loop")
    withRestarts(
       
        # do all the work here
        cat("Entering work part i =", i, "\n");
        Sys.sleep(10)
        i <- i + 1
        cat("finished work part\n")
       , 
      gotSIG = function()   
        message("interrupted while working, restarting work part")
        do_repeat <<- TRUE
        NULL
       
    )
    if (do_repeat)  
      cat("restarting work loop\n")
      do_repeat <- FALSE
      next
      else  
      cat("between work and sleep part\n")
     
    withRestarts(
       
        # do the sleep part here
        cat("Entering sleep part i =", i, "\n")
        Sys.sleep(10)
        i <- i + 1
        cat("finished sleep part\n")
       , 
      gotSIG = function()  
        message("got work to do, waking up!")
        NULL
       
    )
    message("end of the loop")
   
 
cat("Current process:", Sys.getpid(), "\n");
withCallingHandlers( 
    workfun()
   ,
  interrupt = function(e)  
    invokeRestart("gotSIG")
   )
While not perfect, I guess I have to live with this method for now.

21 June 2017

Reproducible builds folks: Reproducible Builds: week 112 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday June 11 and Saturday June 17 2017: Upcoming events Upstream patches and bugs filed Reviews of unreproducible packages 1 package review has been added, 19 have been updated and 2 have been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development tests.reproducible-builds.org As you might have noticed, Debian stretch was released last week. Since then, Mattia and Holger renamed our testing suite to stretch and added a buster suite so that we keep our historic results for stretch visible and can continue our development work as usual. In this sense, happy hacking on buster; may it become the best Debian release ever and hopefully the first reproducible one! Axel Beckert is currently in the process of setting up eight LeMaker HiKey960 boards. These boards were sponsored by Hewlett Packard Enterprise and will be hosted by the SOSETH students association at ETH Zurich. Thanks to everyone involved here and also thanks to Martin Michlmayr and Steve Geary who initiated getting these boards to us. Misc. This week's edition was written by Chris Lamb, Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

20 June 2017

Foteini Tsiami: Internationalization, part one

The first part of internationalizing a Greek application, is, of course, translating all the Greek text to English. I already knew how to open a user interface (.ui) file with Glade and how to translate/save it from there, and mail the result to the developers. If only it was that simple! I learned that the code of most open source software is kept on version control systems, which fortunately are a bit similar to Wikis, which I was familiar with, so I didn t have a lot of trouble understanding the concepts. Thanks to a very brief git crash course from my mentors, I was able to quickly start translating, committing, and even pushing back the updated files. The other tricky part was internationalizing the python source code. There Glade couldn t be used, a text editor like Pluma was needed. And the messages were part of the source code, so I had to be extra careful not to break the syntax. The English text then needed to be wrapped around _(), which does the gettext call which dynamically translates the messages into the user language. All this was very educative, but now that the first part of the internationalization, i.e. the Greek-to-English translations, are over, I think I ll take some time to read more about the tools that I used!

Norbert Preining: TeX Live 2017 hits Debian/unstable

Yesterday I uploaded the first packages of TeX Live 2017 to Debian/unstable, meaning that the new release cycle has started. Debian/stretch was released over the weekend, and this opened up unstable for new developments. The upload comprised the following packages: asymptote, cm-super, context, context-modules, texlive-base, texlive-bin, texlive-extra, texlive-extra, texlive-lang, texworks, xindy.
I mentioned already in a previous post the following changes: The last two changes are described together with other news (easy TEXMF tree management) in the TeX Live release post. These changes more or less sum up the new infra structure developments in TeX Live 2017. Since the last release to unstable (which happened in 2017-01-23) about half a year of package updates have accumulated, below is an approximate list of updates (not split into new/updated, though). Enjoy the brave new world of TeX Live 2017, and please report bugs to the BTS! Updated/new packages:
academicons, achemso, acmart, acro, actuarialangle, actuarialsymbol, adobemapping, alkalami, amiri, animate, aomart, apa6, apxproof, arabluatex, archaeologie, arsclassica, autoaligne, autobreak, autosp, axodraw2, babel, babel-azerbaijani, babel-english, babel-french, babel-indonesian, babel-japanese, babel-malay, babel-ukrainian, bangorexam, baskervaldx, baskervillef, bchart, beamer, beamerswitch, bgteubner, biblatex-abnt, biblatex-anonymous, biblatex-archaeology, biblatex-arthistory-bonn, biblatex-bookinother, biblatex-caspervector, biblatex-cheatsheet, biblatex-chem, biblatex-chicago, biblatex-claves, biblatex-enc, biblatex-fiwi, biblatex-gb7714-2015, biblatex-gost, biblatex-ieee, biblatex-iso690, biblatex-manuscripts-philology, biblatex-morenames, biblatex-nature, biblatex-opcit-booktitle, biblatex-oxref, biblatex-philosophy, biblatex-publist, biblatex-shortfields, biblatex-subseries, bibtexperllibs, bidi, biochemistry-colors, bookcover, boondox, bredzenie, breqn, bxbase, bxcalc, bxdvidriver, bxjalipsum, bxjaprnind, bxjscls, bxnewfont, bxorigcapt, bxpapersize, bxpdfver, cabin, callouts, chemfig, chemformula, chemmacros, chemschemex, childdoc, circuitikz, cje, cjhebrew, cjk-gs-integrate, cmpj, cochineal, combofont, context, conv-xkv, correctmathalign, covington, cquthesis, crimson, crossrefware, csbulletin, csplain, csquotes, css-colors, cstldoc, ctex, currency, cweb, datetime2-french, datetime2-german, datetime2-romanian, datetime2-ukrainian, dehyph-exptl, disser, docsurvey, dox, draftfigure, drawmatrix, dtk, dviinfox, easyformat, ebproof, elements, endheads, enotez, eqnalign, erewhon, eulerpx, expex, exsheets, factura, facture, fancyhdr, fbb, fei, fetamont, fibeamer, fithesis, fixme, fmtcount, fnspe, fontmfizz, fontools, fonts-churchslavonic, fontspec, footnotehyper, forest, gandhi, genealogytree, glossaries, glossaries-extra, gofonts, gotoh, graphics, graphics-def, graphics-pln, grayhints, gregoriotex, gtrlib-largetrees, gzt, halloweenmath, handout, hang, heuristica, hlist, hobby, hvfloat, hyperref, hyperxmp, ifptex, ijsra, japanese-otf-uptex, jlreq, jmlr, jsclasses, jslectureplanner, karnaugh-map, keyfloat, knowledge, komacv, koma-script, kotex-oblivoir, l3, l3build, ladder, langsci, latex, latex2e, latex2man, latex3, latexbug, latexindent, latexmk, latex-mr, leaflet, leipzig, libertine, libertinegc, libertinus, libertinust1math, lion-msc, lni, longdivision, lshort-chinese, ltb2bib, lualatex-math, lualibs, luamesh, luamplib, luaotfload, luapackageloader, luatexja, luatexko, lwarp, make4ht, marginnote, markdown, mathalfa, mathpunctspace, mathtools, mcexam, mcf2graph, media9, minidocument, modular, montserrat, morewrites, mpostinl, mptrees, mucproc, musixtex, mwcls, mweights, nameauth, newpx, newtx, newtxtt, nfssext-cfr, nlctdoc, novel, numspell, nwejm, oberdiek, ocgx2, oplotsymbl, optidef, oscola, overlays, pagecolor, pdflatexpicscale, pdfpages, pdfx, perfectcut, pgfplots, phonenumbers, phonrule, pkuthss, platex, platex-tools, polski, preview, program, proofread, prooftrees, pst-3dplot, pst-barcode, pst-eucl, pst-func, pst-ode, pst-pdf, pst-plot, pstricks, pstricks-add, pst-solides3d, pst-spinner, pst-tools, pst-tree, pst-vehicle, ptex2pdf, ptex-base, ptex-fontmaps, pxbase, pxchfon, pxrubrica, pythonhighlight, quran, ran_toks, reledmac, repere, resphilosophica, revquantum, rputover, rubik, rutitlepage, sansmathfonts, scratch, seealso, sesstime, siunitx, skdoc, songs, spectralsequences, stackengine, stage, sttools, studenthandouts, svg, tcolorbox, tex4ebook, tex4ht, texosquery, texproposal, thaienum, thalie, thesis-ekf, thuthesis, tikz-kalender, tikzmark, tikz-optics, tikz-palattice, tikzpeople, tikzsymbols, titlepic, tl17, tqft, tracklang, tudscr, tugboat-plain, turabian-formatting, txuprcal, typoaid, udesoftec, uhhassignment, ukrainian, ulthese, unamthesis, unfonts-core, unfonts-extra, unicode-math, uplatex, upmethodology, uptex-base, urcls, variablelm, varsfromjobname, visualtikz, xassoccnt, xcharter, xcntperchap, xecjk, xepersian, xetexko, xevlna, xgreek, xsavebox, xsim, ycbook.

19 June 2017

Jeremy Bicha: GNOME Tweak Tool 3.25.3

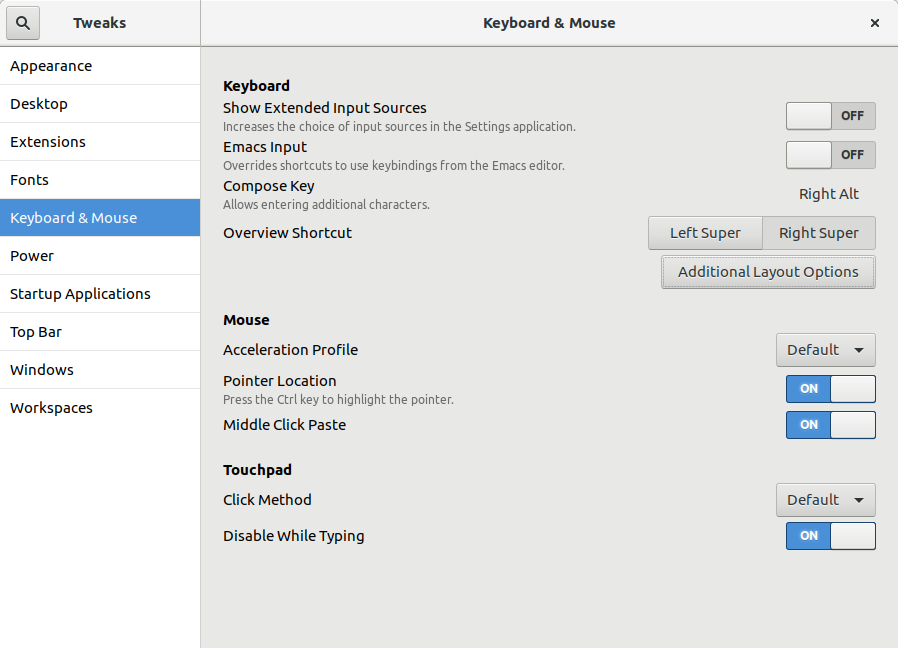
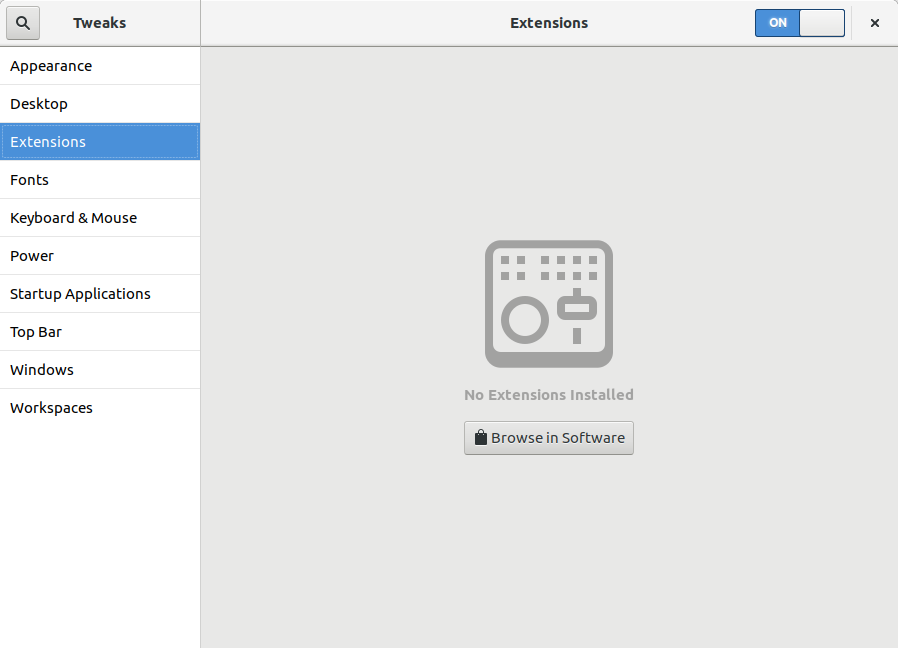
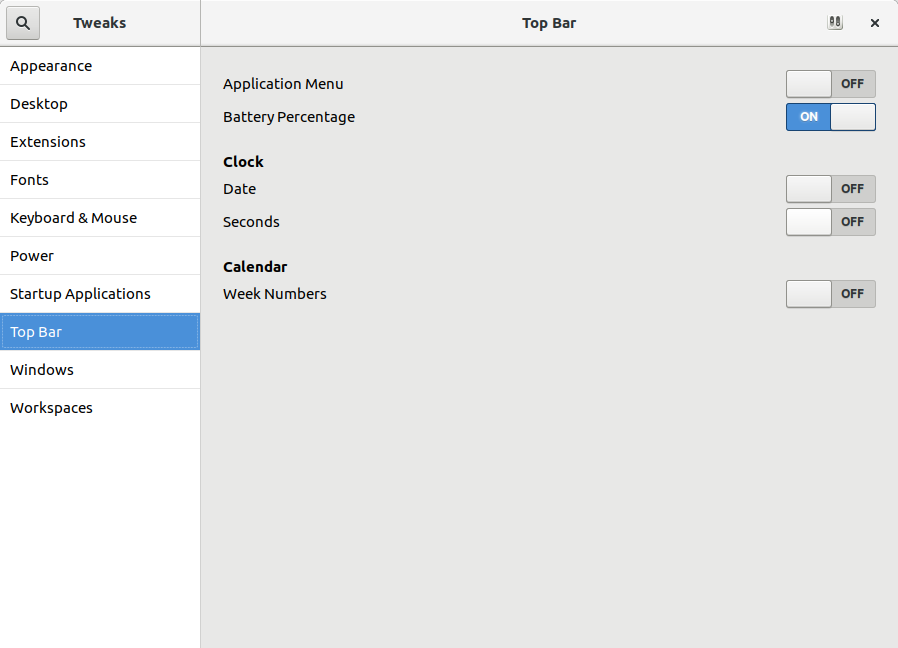
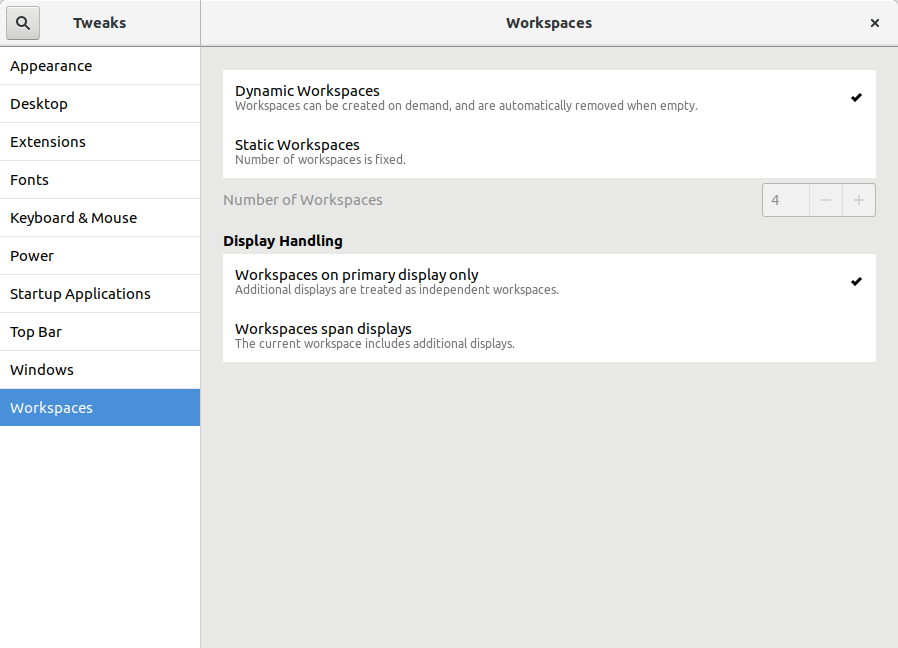
Today I released the second development snapshot (3.25.3) of what will be GNOME Tweak Tool 3.26. I consider the initial User Interface (UI) rework proposed by the GNOME Design Team to be complete now. Every page in Tweak Tool has been updated, either in this snapshot or the previous development snapshot. The hard part still remains: making the UI look as good as the mockups. Tweak Tool s backend makes this a bit more complicated than usual for an app like this. Here are a few visual highlights of this release. The Typing page has been moved into an Additional Layout Options dialog in the Keyboard & Mouse page. Also, the Compose Key option has been given its own dialog box. Florian M llner added content to the Extensions page that is shown if you don t have any GNOME Shell extensions installed yet. A hidden feature that GNOME has had for a long time is the ability to move the Application Menu from the GNOME top bar to a button in the app s title bar. This is easy to enable in Tweak Tool by turning off the Application Menu switch in the Top Bar page. This release improves how well that works, especially for Ubuntu users where the required hidden appmenu window button was probably not pre-configured. Some of the ComboBoxes have been replaced by ListBoxes. One example is on the Workspaces page where the new design allows for more information about the different options. The ListBoxes are also a lot easier to select than the smaller ComboBoxes were. For details of these and other changes, see the commit log or the NEWS file. GNOME Tweak Tool 3.26 will be released alongside GNOME 3.26 in mid-September.

Next.

Previous.