Search Results: "cas"

16 February 2015

Julien Danjou: Hacking Python AST: checking methods declaration

A few months ago, I wrote the definitive guide about Python method declaration, which had quite a good success. I still fight every day in OpenStack to have the developers declare their methods correctly in the patches they submit. Automation plan The thing is, I really dislike doing the same things over and over again. Furthermore, I'm not perfect either, and I miss a lot of these kind of problems in the reviews I made. So I decided to replace me by a program a more scalable and less error-prone version of my brain. In OpenStack, we rely on flake8 to do static analysis of our Python code in order to spot common programming mistakes. But we are really pedantic, so we wrote some extra hacking rules that we enforce on our code. To that end, we wrote a flake8 extension called hacking. I really like these rules, I even recommend to apply them in your own project. Though I might be biased or victim of Stockholm syndrome. Your call. Anyway, it's pretty clear that I need to add a check for method declaration in hacking. Let's write a flake8 extension! Typical error The typical error I spot is the following:
class Foo(object):
# self is not used, the method does not need
# to be bound, it should be declared static
def bar(self, a, b, c):
return a + b - c

That would be the correct version:
class Foo(object):
@staticmethod
def bar(a, b, c):
return a + b - c

This kind of mistake is not a show-stopper. It's just not optimized. Why you have to manually declare static or class methods might be a language issue, but I don't want to debate about Python misfeatures or design flaws. Strategy We could probably use some big magical regular expression to catch this problem. flake8 is based on the pep8 tool, which can do a line by line analysis of the code. But this method would make it very hard and error prone to detect this pattern. Though it's also possible to do an AST based analysis on on a per-file basis with pep8. So that's the method I pick as it's the most solid. AST analysis I won't dive deeply into Python AST and how it works. You can find plenty of sources on the Internet, and I even talk about it a bit in my book The Hacker's Guide to Python. To check correctly if all the methods in a Python file are correctly declared, we need to do the following: Flake8 plugin In order to register a new plugin in flake8 via hacking, we just need to add an entry in setup.cfg:
[entry_points]
flake8.extension =
[ ]
H904 = hacking.checks.other:StaticmethodChecker
H905 = hacking.checks.other:StaticmethodChecker

We register 2 hacking codes here. As you will notice later, we are actually going to add an extra check in our code for the same price. Stay tuned. The next step is to write the actual plugin. Since we are using an AST based check, the plugin needs to be a class following a certain signature:
@core.flake8ext
class StaticmethodChecker(object):
def __init__(self, tree, filename):
self.tree = tree

def run(self):
pass

So far, so good and pretty easy. We store the tree locally, then we just need to use it in run() and yield the problem we discover following pep8 expected signature, which is a tuple of (lineno, col_offset, error_string, code). This AST is made for walking The ast module provides the walk function, that allow to iterate easily on a tree. We'll use that to run through the AST. First, let's write a loop that ignores the statement that are not class definition.
@core.flake8ext
class StaticmethodChecker(object):
def __init__(self, tree, filename):
self.tree = tree

def run(self):
for stmt in ast.walk(self.tree):
# Ignore non-class
if not isinstance(stmt, ast.ClassDef):
continue

We still don't check for anything, but we know how to ignore statement that are not class definitions. The next step need to be to ignore what is not function definition. We just iterate over the attributes of the class definition.
for stmt in ast.walk(self.tree):
# Ignore non-class
if not isinstance(stmt, ast.ClassDef):
continue
# If it's a class, iterate over its body member to find methods
for body_item in stmt.body:
# Not a method, skip
if not isinstance(body_item, ast.FunctionDef):
continue

We're all set for checking the method, which is body_item. First, we need to check if it's already declared as static. If so, we don't have to do any further check and we can bail out.
for stmt in ast.walk(self.tree):
# Ignore non-class
if not isinstance(stmt, ast.ClassDef):
continue
# If it's a class, iterate over its body member to find methods
for body_item in stmt.body:
# Not a method, skip
if not isinstance(body_item, ast.FunctionDef):
continue
# Check that it has a decorator
for decorator in body_item.decorator_list:
if (isinstance(decorator, ast.Name)
and decorator.id == 'staticmethod'):
# It's a static function, it's OK
break
else:
# Function is not static, we do nothing for now
pass

Note that we use the special for/else form of Python, where the else is evaluated unless we used break to exit the for loop.
for stmt in ast.walk(self.tree):
# Ignore non-class
if not isinstance(stmt, ast.ClassDef):
continue
# If it's a class, iterate over its body member to find methods
for body_item in stmt.body:
# Not a method, skip
if not isinstance(body_item, ast.FunctionDef):
continue
# Check that it has a decorator
for decorator in body_item.decorator_list:
if (isinstance(decorator, ast.Name)
and decorator.id == 'staticmethod'):
# It's a static function, it's OK
break
else:
try:
first_arg = body_item.args.args[0]
except IndexError:
yield (
body_item.lineno,
body_item.col_offset,
"H905: method misses first argument",
"H905",
)
# Check next method
continue

We finally added some check! We grab the first argument from the method signature. Unless it fails, and in that case, we know there's a problem: you can't have a bound method without the self argument, therefore we raise the H905 code to signal a method that misses its first argument. Now you know why we registered this second pep8 code along with H904 in setup.cfg. We have here a good opportunity to kill two birds with one stone. The next step is to check if that first argument is used in the code of the method.
for stmt in ast.walk(self.tree):
# Ignore non-class
if not isinstance(stmt, ast.ClassDef):
continue
# If it's a class, iterate over its body member to find methods
for body_item in stmt.body:
# Not a method, skip
if not isinstance(body_item, ast.FunctionDef):
continue
# Check that it has a decorator
for decorator in body_item.decorator_list:
if (isinstance(decorator, ast.Name)
and decorator.id == 'staticmethod'):
# It's a static function, it's OK
break
else:
try:
first_arg = body_item.args.args[0]
except IndexError:
yield (
body_item.lineno,
body_item.col_offset,
"H905: method misses first argument",
"H905",
)
# Check next method
continue
for func_stmt in ast.walk(body_item):
if six.PY3:
if (isinstance(func_stmt, ast.Name)
and first_arg.arg == func_stmt.id):
# The first argument is used, it's OK
break
else:
if (func_stmt != first_arg
and isinstance(func_stmt, ast.Name)
and func_stmt.id == first_arg.id):
# The first argument is used, it's OK
break
else:
yield (
body_item.lineno,
body_item.col_offset,
"H904: method should be declared static",
"H904",
)

To that end, we iterate using ast.walk again and we look for the use of the same variable named (usually self, but if could be anything, like cls for @classmethod) in the body of the function. If not found, we finally yield the H904 error code. Otherwise, we're good. Conclusion I've submitted this patch to hacking, and, finger crossed, it might be merged one day. If it's not I'll create a new Python package with that check for flake8. The actual submitted code is a bit more complex to take into account the use of abc module and include some tests. As you may have notice, the code walks over the module AST definition several times. There might be a couple of optimization to browse the AST in only one pass, but I'm not sure it's worth it considering the actual usage of the tool. I'll let that as an exercise for the reader interested in contributing to OpenStack. Happy hacking!
The Hacker's Guide to Python
A book I wrote talking about designing Python applications, state of the art, advice to apply when building your application, various Python tips, etc. Interested? Check it out.

Vincent Sanders: To a child, often the box a toy came in is more appealing than the toy itself.

I think Allen Klein might not have been referring to me when he said that but I do seem to like creating boxes for my toys.

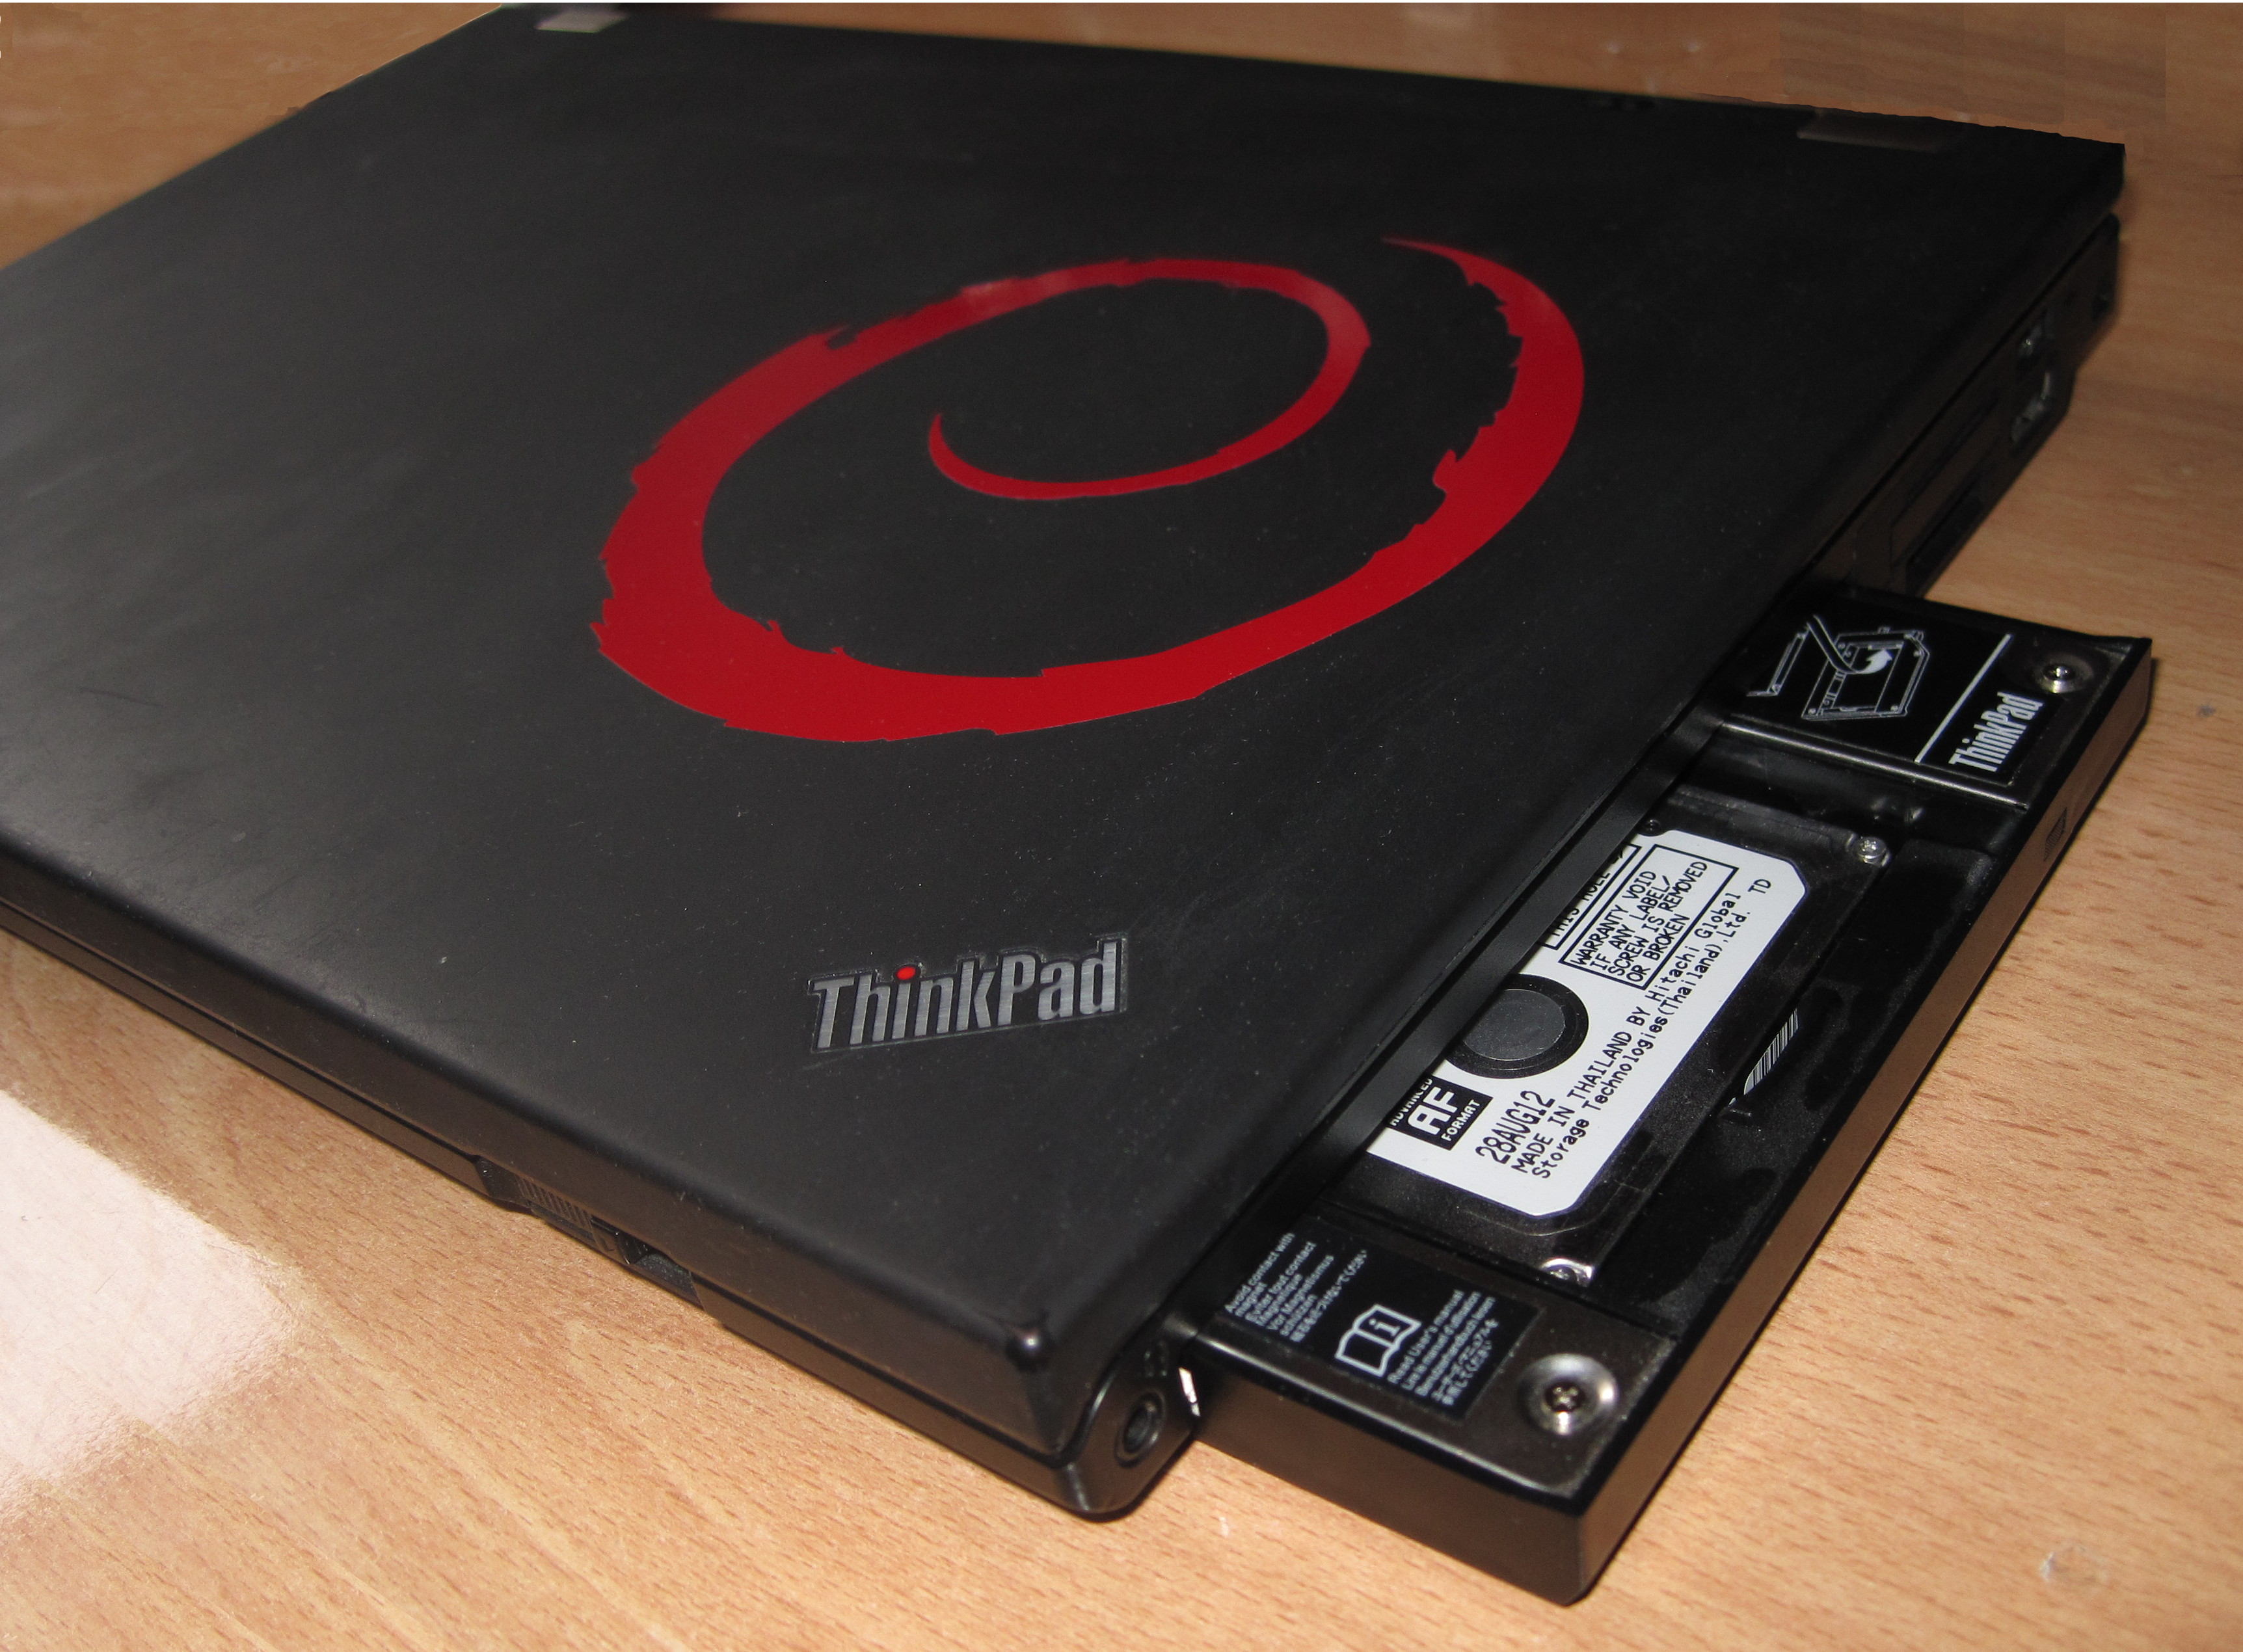
Lenovo laptop with ultrabay ejected
My Lenovo laptop has an Ultrabay, these are a way to easily swap optical and hard drives drives. They allow me to carry around additional storage and, providing I remembered to pack the drive, access optical media.
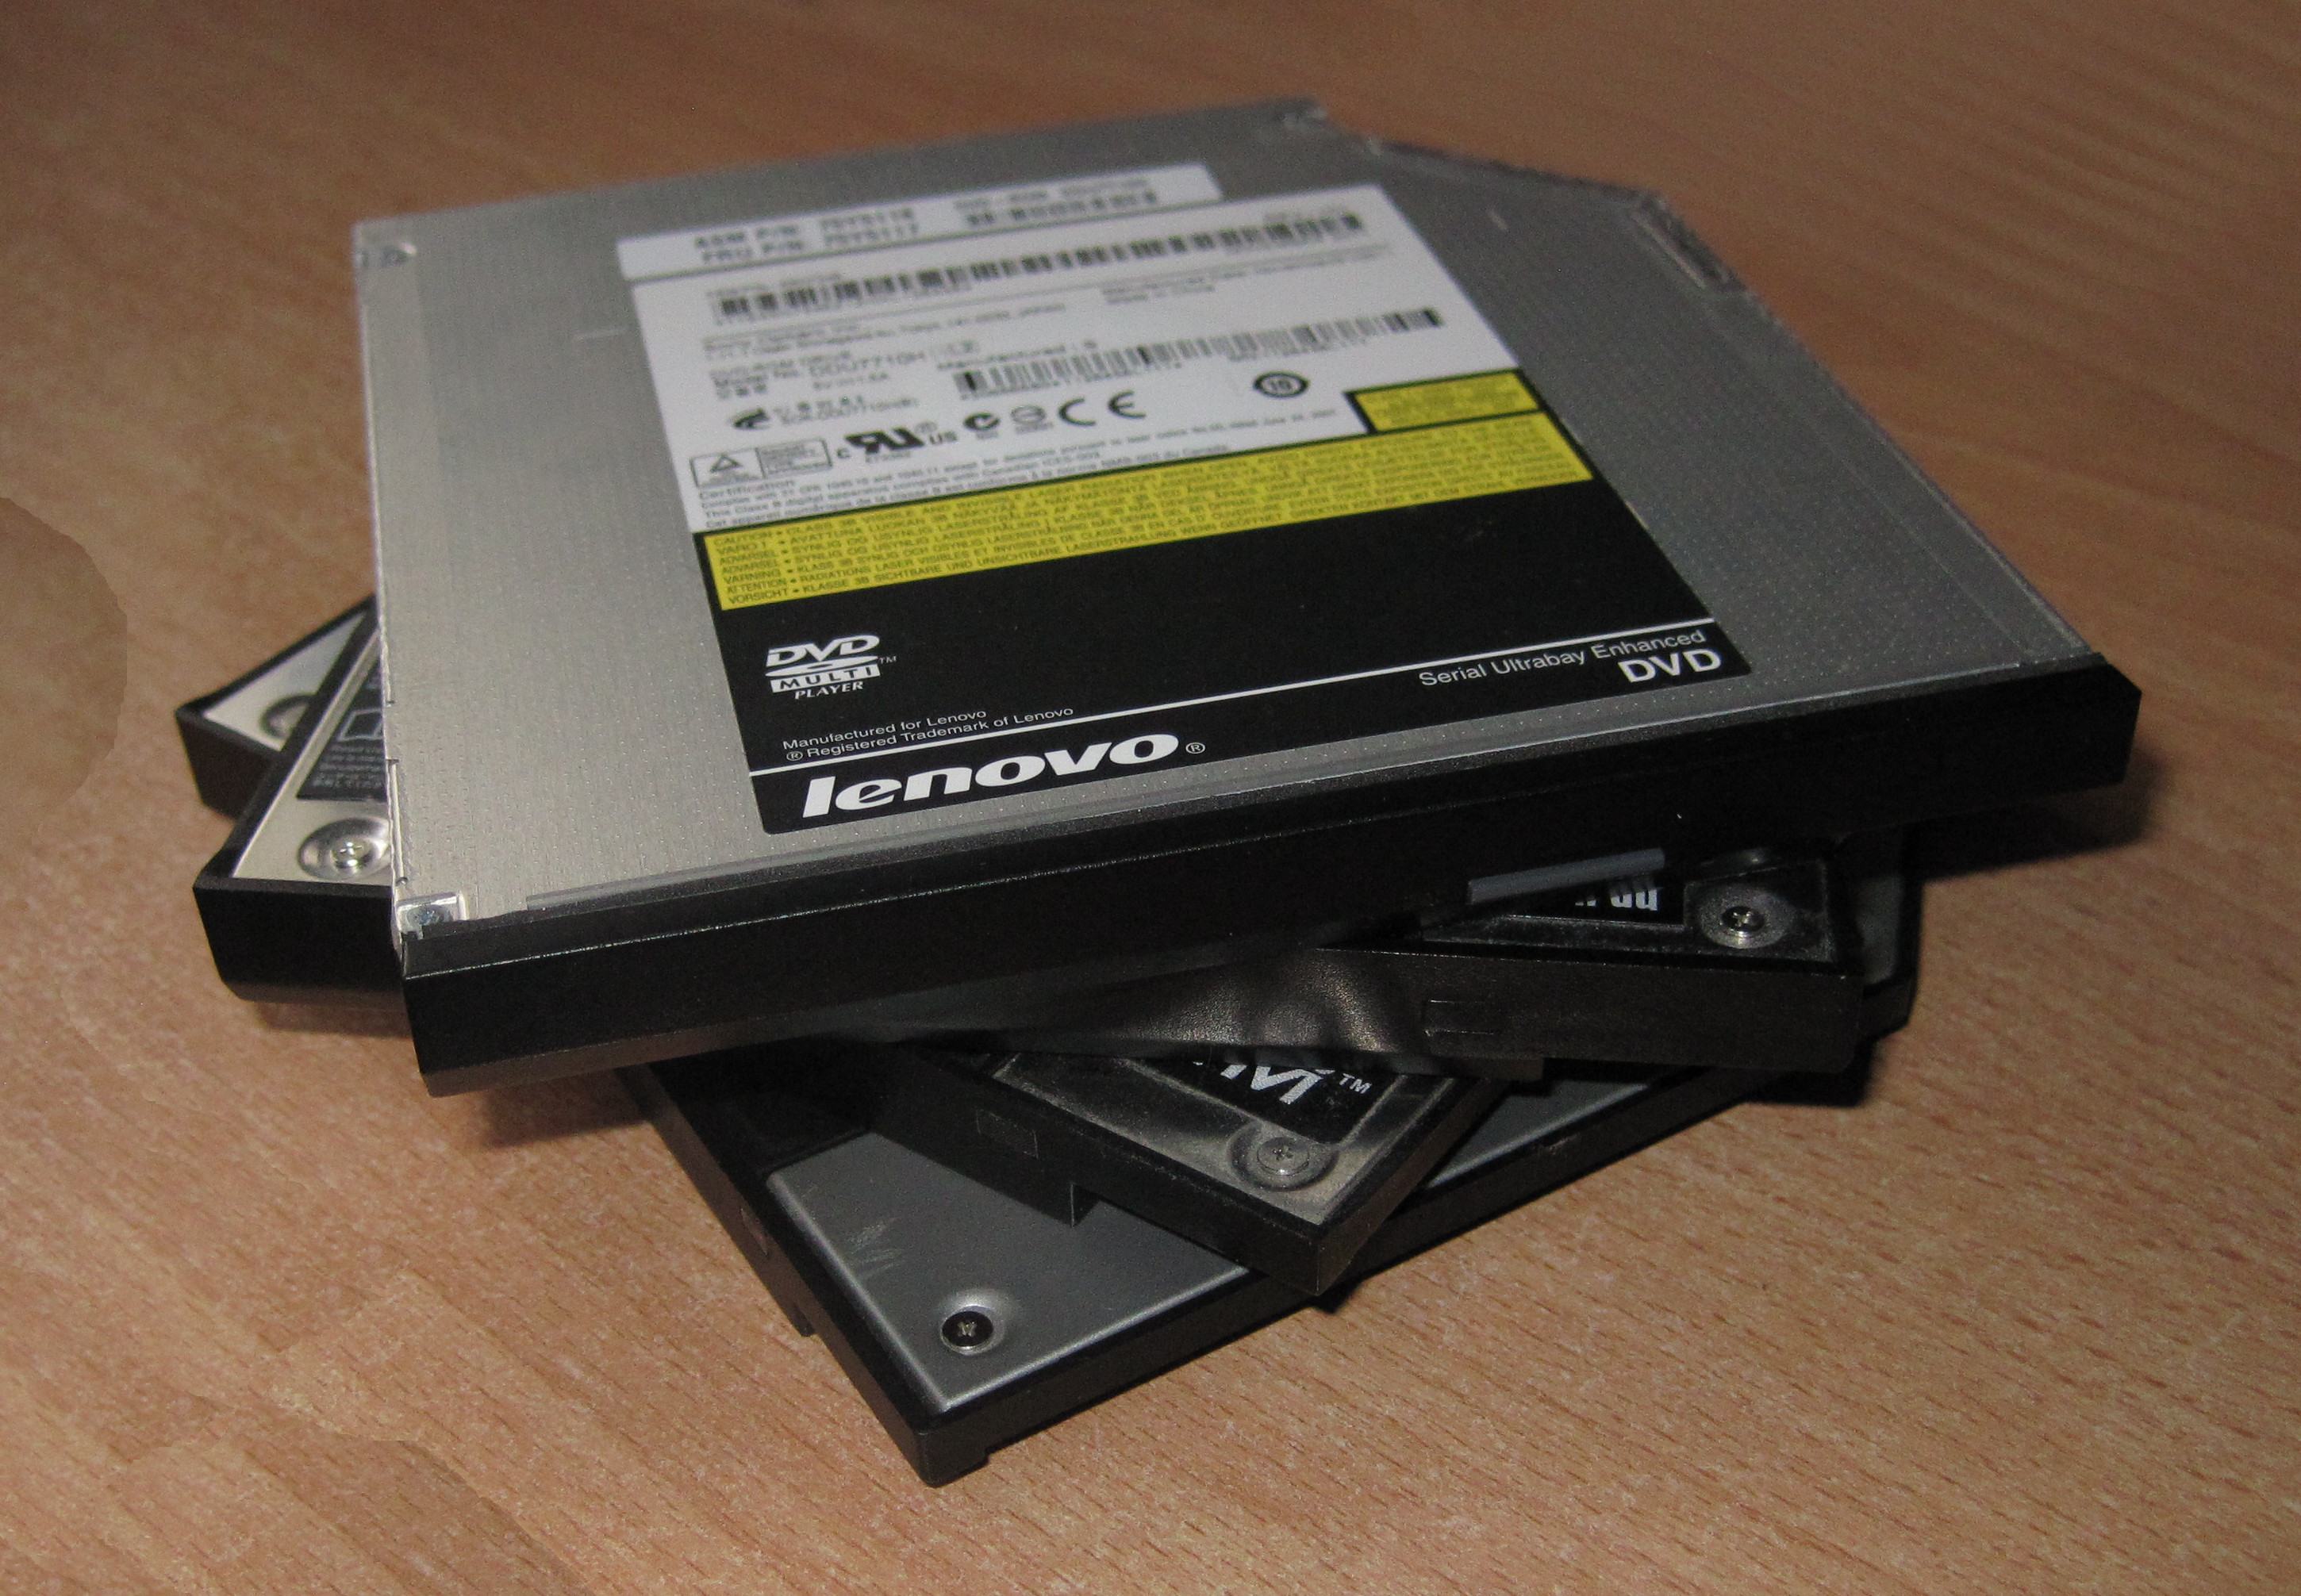
Over time I have acquired several additional hard drives housed in Ultrabay caddies. Generally I only need to access one at a time but increasingly I want to have more than one available.

Lenovo used to sell docking stations with multiple Ultrabays but since Series 3 was introduced this is no longer the case as the docks have been reduced to port replicators.

One solution is to buy a SATA to USB convertor which lets you use the drive externally. However once you have more than one drive this becomes somewhat untidy, not to mention all those unhoused drives on your desk become something of a hazard.

Recently after another close call I decided what I needed was a proper external enclosure to house all my drives. After some extensive googling I found nothing suitable ready to buy. Most normal people would give up at this point, I appear to be an abnormal person so I got the CAD package out.

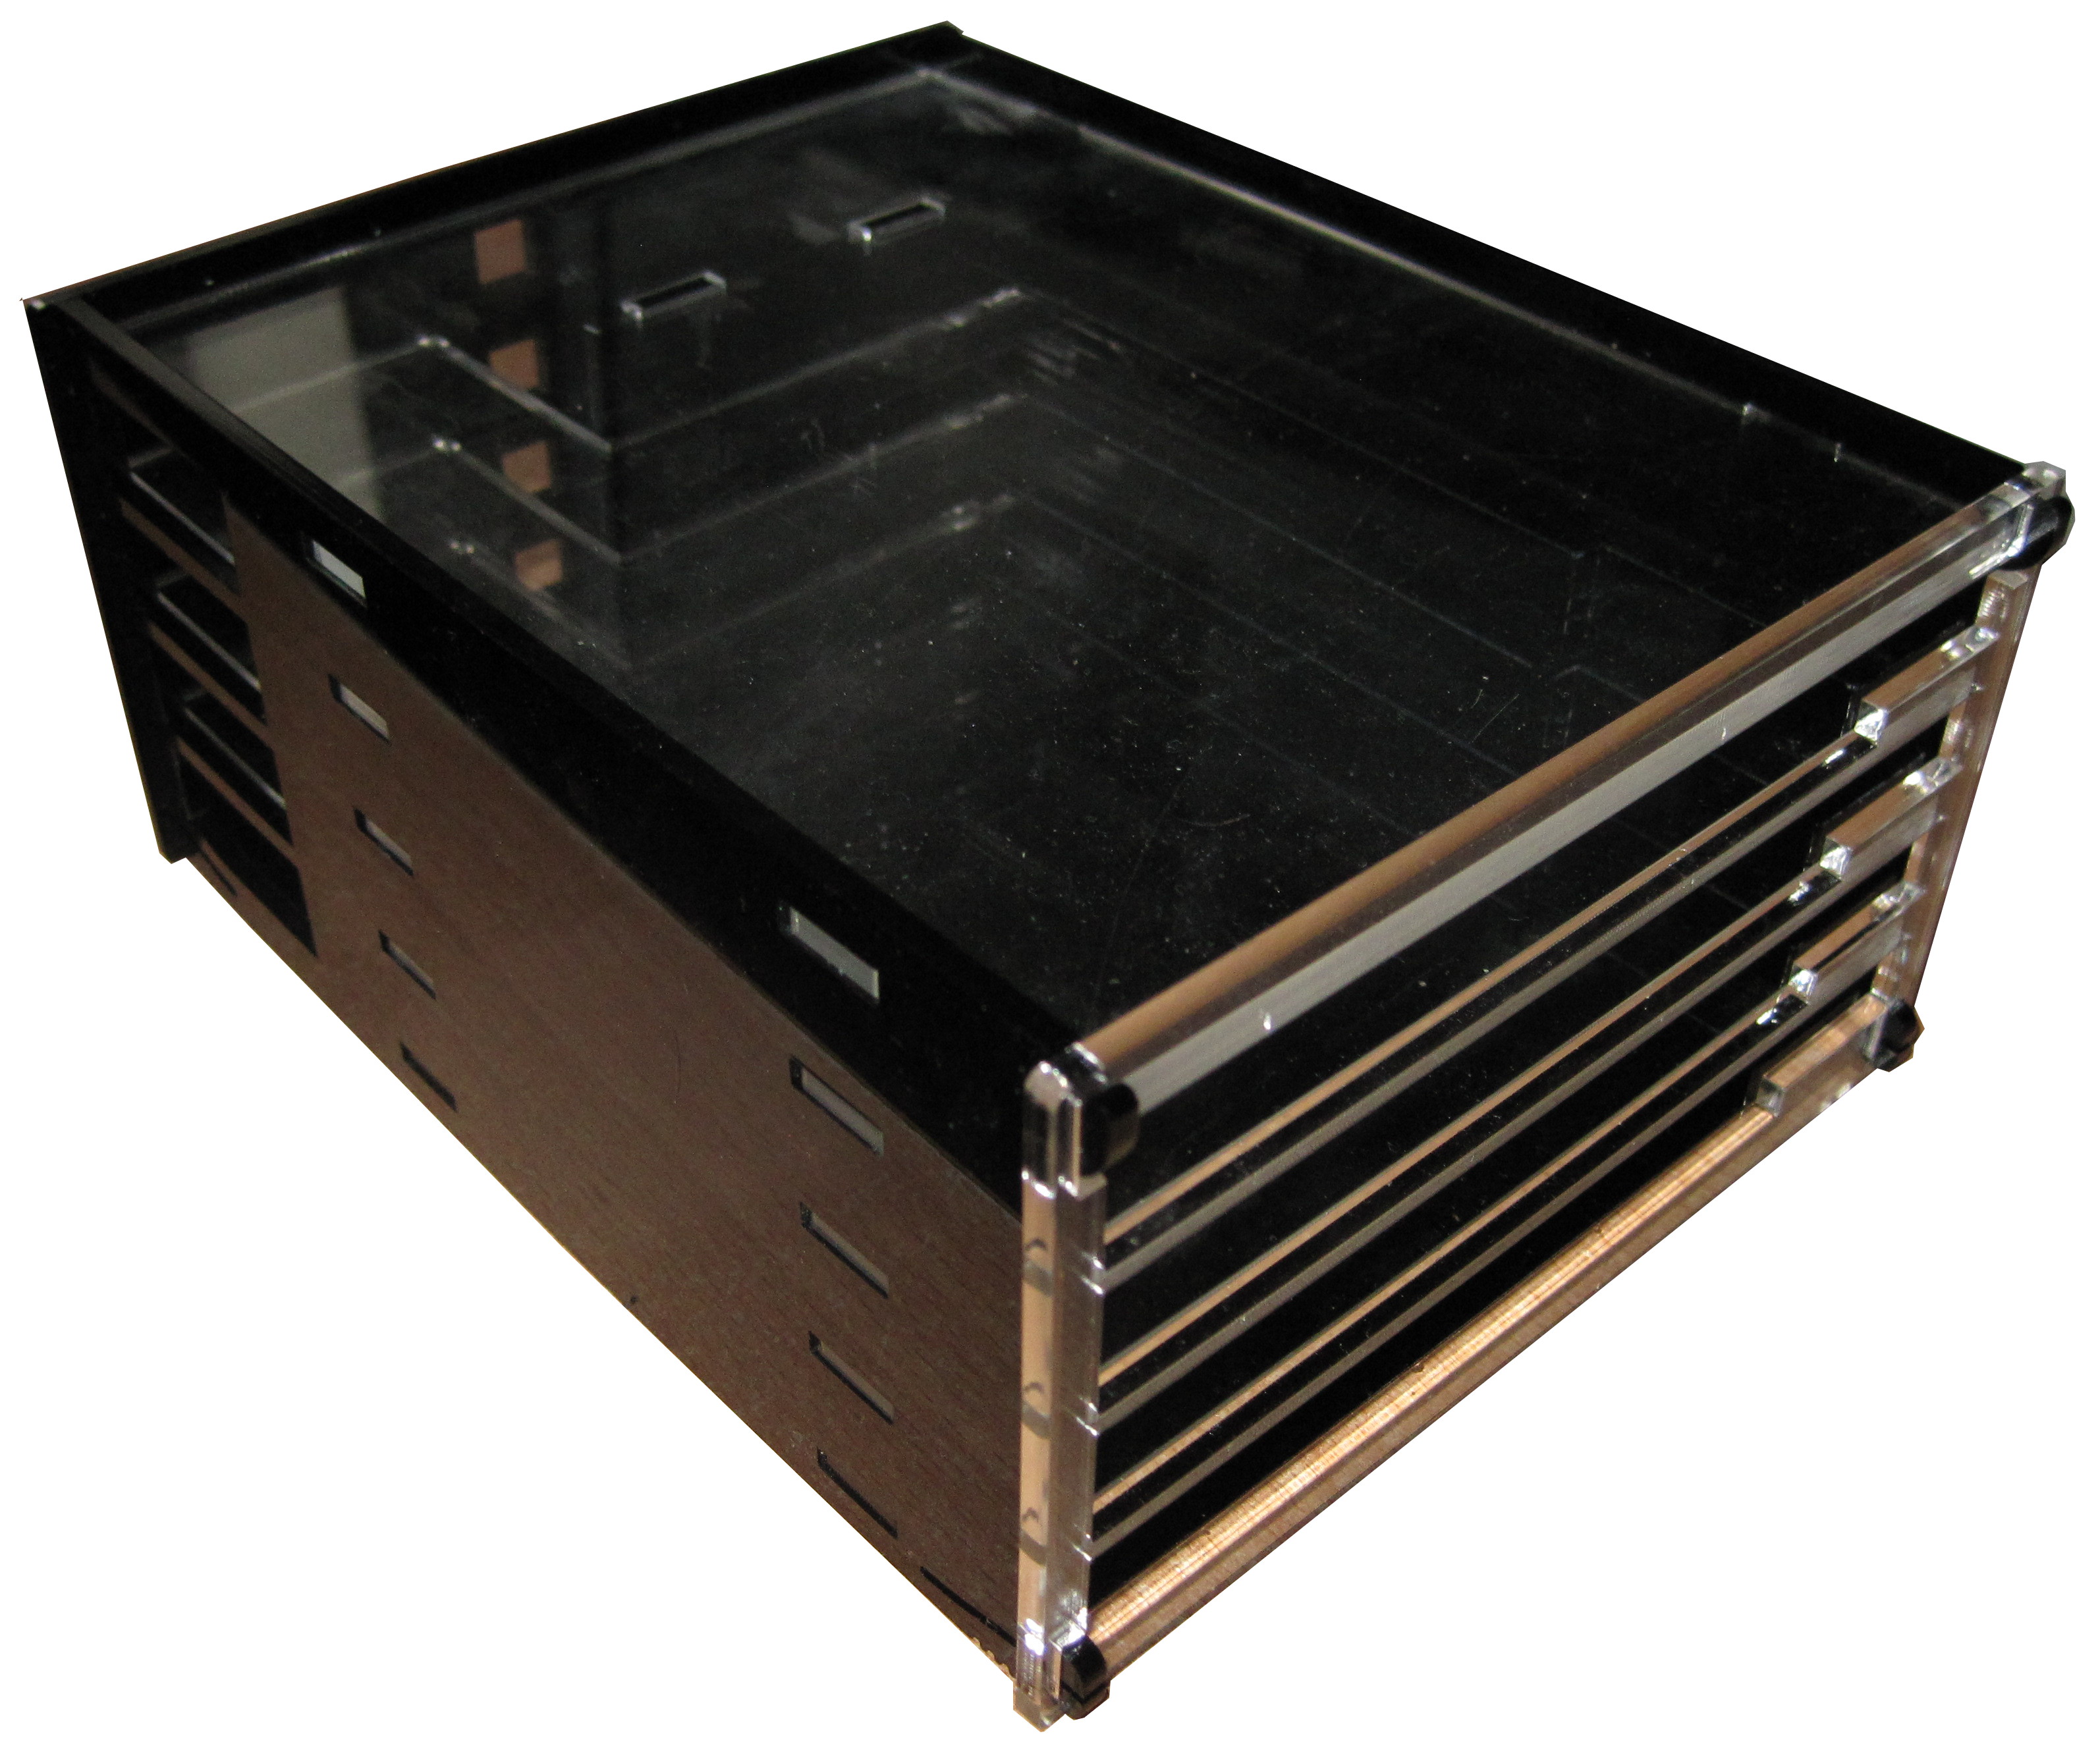
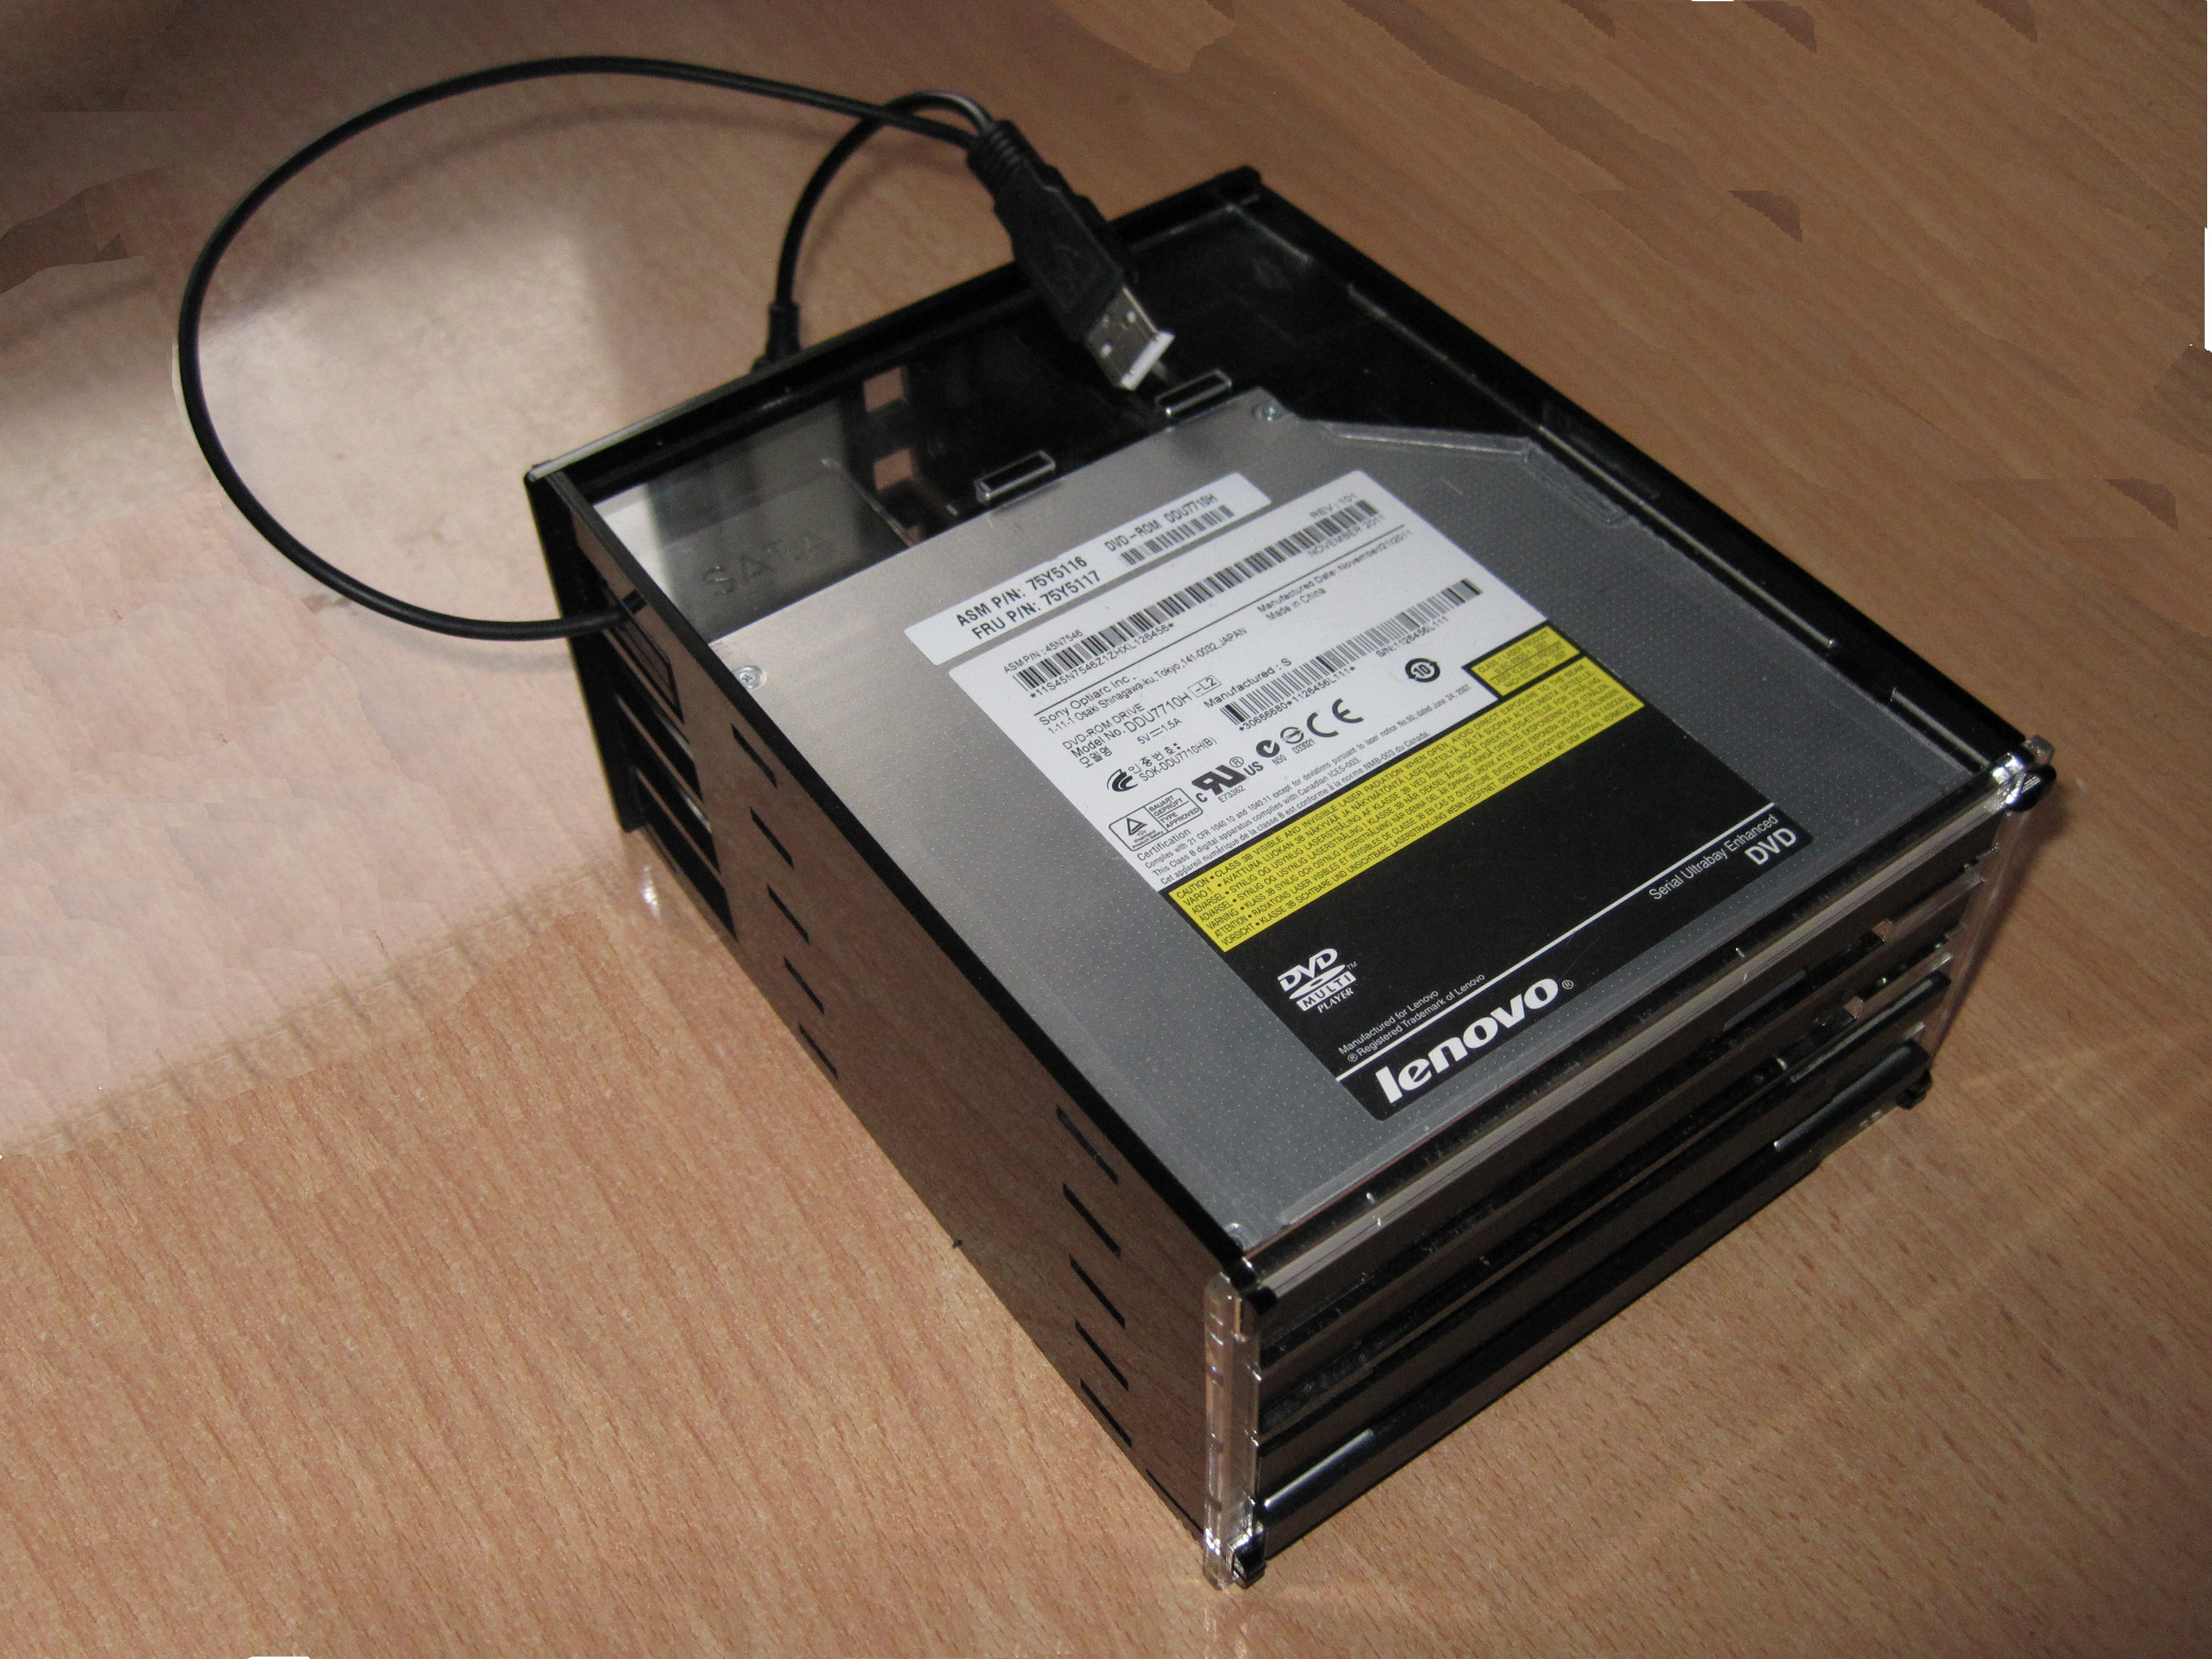
A few hours of design and a load of laser cutting later I came up with a four bay enclosure that now houses all my Ultrabay caddies.

The design was slightly evolved to accommodate the features of some older caddies and allow a pencil to be used to eject the drives (I put a square hole in the back)

The completed unit uses about 10 of plastic and takes 30 minutes to lasercut.

The only issue with the enclosure as manufactured is that Makespace ran out of black plastic stock and I had to use transparent to finish so it is not in classic black as lenovo intended.

As usual all the design files are publicly available from my design repo.

15 February 2015

Matthew Palmer: The Vicious Circle of Documentation

Ever worked at a company (or on a codebase, or whatever) where it seemed like, no matter what the question was, the answer was written down somewhere you could easily find it? Most people haven t, sadly, but they do exist, and I can assure you that it is an absolute pleasure. On the other hand, practically everyone has experienced completely undocumented systems and processes, where knowledge is shared by word-of-mouth, or lost every time someone quits. Why are there so many more undocumented systems than documented ones out there, and how can we cause more well-documented systems to exist? The answer isn t people are lazy , and the solution is simple though not easy.

Why Johnny Doesn t Read When someone needs to know something, they might go look for some documentation, or they might ask someone else or just guess wildly. The behaviour look for documentation is often reinforced negatively, by the result documentation doesn t exist . At the same time, the behaviours ask someone and guess wildly are positively reinforced, by the results I get my question answered and/or at least I can get on with my work . Over time, people optimise their behaviour by skipping the look for documentation step, and just go straight to asking other people (or guessing wildly).

Why Johnny Doesn t Write When someone writes documentation, they re hoping that people will read it and not have to ask them questions in order to be productive and do the right thing. Hence, the behaviour write documentation is negatively reinforced by the results I still get asked questions , and nobody does things the right way around here, dammit! Worse, though, is that there is very little positive reinforcement for the author: when someone does read the docs, and thus doesn t ask a question, the author almost certainly doesn t know they dodged a bullet. Similarly, when someone does things the right way, it s unlikely that anyone will notice. It s only the mistakes that catch the attention. Given that the experience of writing documentation tends to skew towards the negative, it s not surprising that eventually, the time spent writing documentation is reallocated to other, more utility-producing activities.

Death Spiral The combination of these two situations is self-reinforcing. While a suitably motivated reader might start by strictly looking for documentation, or an author initially be enthused to always fully documenting their work, over time the reflex will be for readers to just go ask someone, because there s never any documentation! , and for authors to not write documentation because nobody bothers to read what I write anyway! . It is important to recognise that this iterative feedback loop is the natural state of the reader/author ecosystem, resulting in something akin to thermodynamic entropy. To avoid the system descending into chaos, energy needs to be constantly applied to keep the system in order.

The Solution Effective methods for avoiding the vicious circle can be derived from the things that cause it. Change the forces that apply themselves to readers and authors, and they will behave differently. On the reader s side, the most effective way to encourage people to read documentation is for it to consistently exist. This means that those in control of a project or system mustn t consider something done until the documentation is in a good state. Patches shouldn t be landed, and releases shouldn t be made, unless the documentation is altered to match the functional changes being made. Yes, this requires discipline, which is just a form of energy application to prevent entropic decay. Writing documentation should be an explicit and well-understood part of somebody s job description. Whoever is responsible for documentation needs to be given the time to do it properly. Writing well takes time and mental energy, and that time needs to be factored into the plans. Never forget that skimping on documentation, like short-changing QA or customer support, is a false economy that will cost more in the long term than it saves in the short term. Even if the documentation exists, though, some people are going to tend towards asking people rather than consulting the documentation. This isn t a moral failing on their part, but only happens when they believe that asking someone is more beneficial to them than going to the documentation. To change the behaviour, you need to change the belief. You could change the belief by increasing the cost of asking. You could fire (or hellban) anyone who ever asks a question that is answered in the documentation. But you shouldn t. You could yell RTFM! at everyone who asks a question. Thankfully that s one acronym that s falling out of favour. Alternately, you can reduce the cost of getting the answer from the documentation. Possibly the largest single productivity boost for programmers, for example, has been the existence of Google. Whatever your problem, there s a pretty good chance that a search or two will find a solution. For your private documentation, you probably don t have the power of Google available, but decent full-text search systems are available. Use them. Finally, authors would benefit from more positive reinforcement. If you find good documentation, let the author know! It requires a lot of effort (comparatively) to look up an author s contact details and send them a nice e-mail. The like button is a more low-energy way of achieving a similar outcome you click the button, and the author gets a warm, fuzzy feeling. If your internal documentation system doesn t have some way to close the loop and let readers easily give authors a bit of kudos, fix it so it does. Heck, even if authors just know that a page they wrote was loaded N times in the past week, that s better than the current situation, in which deafening silence persists, punctuated by the occasional plaintive cry of Hey, do you know how to ? . Do you have any other ideas for how to encourage readers to read, and for authors to write?

14 February 2015

Wouter Verhelst: Docker

... is the new hype these days. Everyone seems to want to be part of it; even Microsoft wants to allow Docker to run on its platform. How they visualise that is slightly beyond me, seen as how Docker is mostly a case of "run a bunch of LXC instances", which by their definition can't happen on Windows. Presumably they'll just run a lot more VMs, then, which is a possible workaround. Or maybe Docker for Windows will be the same in concept, but not in implementation. I guess the future will tell. As I understand the premise, the idea of Docker is that getting software to run on "all" distributions is a Hard Problem[TM], so in a Docker thing you just define that this particular stuff is meant to run on top of this and this and that environment, and Docker then compartmentalises everything for you. It should make things easier to maintain, and that's a good thing. I'm not a fan. If the problem that Docker tries to fix is "making software run on all platforms is hard", then Docker's "solution" is "I give up, it's not possible". That's sad. Sure, having a platform which manages your virtualisation for you, without having to manually create virtual machines (or having to write software to do so) is great. And sure, compartmentalising software so that every application runs in its own space can help towards security, manageability, and a whole bunch of other advantages. But having an environment which says "if you want to run this applicaiton, I'll set up a chroot with distribution X for you; if you want to run this other application, I'll set up a chroot with distribution Y for you; and if you want to run yet this other application yere, I'll start doing a chroot with distribution Z for you" will, in the end, get you a situation where, if there's another bug in libc6 or libssl, you now have a nightmare trying to track down all the different versions in all the docker instances to make sure they're all fixed. And while it may work perfectly well on the open Internet, if you're on a corporate network with a paranoid firewall and proxy, downloading packages from public mirrors is harder than just creating a local mirror instead. Which you now have to do not only for your local distribution of choice, but also for the distributions of choice of all the developers of the software you're trying to use. Which may result in more work than just trying to massage the software in question to actually bloody well work, dammit. I'm sure Docker has a solution for some or all of the problems it introduces, and I'm not saying it doesn't work in practice. I'm sure it does fix some part of the "Making software run on all platforms is hard" problem, and so I might even end up using it at some point. But from an aesthetical point of view, I don't think Docker is a good system. I'm not very fond of giving up.

12 February 2015

Sven Hoexter: Out of the comfort zone: What I learned from my net-snmp backport on CentOS 5 and 6

This is a short roundup of things I learned after I've rolled out the stuff I wrote about here. Bugs and fighting with multiarch rpm/yum One oversight led me to not special case the perl-devel dependency on the net-snmp-devel package for CentOS 5, to depend on perl instead. That was easily fixed but afterwards a yum install net-snmp-devel still failed because it tried to install the stock CentOS 5 net-snmp-devel package and its dependencies. Closer investigation showed that it did so because I only provided x86_64 packages in our internal repository but it wanted to install i386 and x86_64 packages. Looking around this issue is documented in the Fedora Wiki. So the modern way to deal with it is to make the dependency architecture dependend with the
% ?_isa 
macro. That is evaluated at build time of the src.rpm and then the depedency is hardcoded together with the architecture. Compare
$ rpm -qRp net-snmp-devel-5.7.2-18.el6.x86_64.rpm grep perl
perl-devel(x86-64)
to
$ rpm -qRp net-snmp-devel-5.7.2-19.el5.centos.x86_64.rpm  grep perl
perl
As you can see it's missing for the el5 package and that's because it's too old, or more specific, rpm is too old to know about it. The workaround we use for now is to explicitly install only the x86_64 version of net-snmp-devel on CentOS 5 when required. That's a
yum install net-snmp-devel.x86_64
Another possible workaround is to remove i386 from your repository or just blacklist it in your yum configuration. I've read that's possible but did not try it. steal time still missing on CentOS 6 One of the motivations for this backport is support for steal time reporting via SNMP. For CentOS 5 that's solved with our net-snmp backport but for CentOS 6 we still do not see steal time. A short look around showed that it's also missing in top, vmstat and friends. Could it be a kernel issue? Since we're already running on the CentOS Xen hypervisor we gave the Linux 3.10.x packages a spin in a domU and now we also have steal time reporting. Yes, a kernel issue with the stock CentOS 6/RHEL 6 kernel. I'm not sure where and how to fill it since RedHat moved to KVM.

Sven Hoexter: Comparing apples and oranges: IPv6 adoption vs HTTP/2 adoption

I did not yet read the HTTP/2 draft but I've read the SPDY draft about 2.5 years ago. So I might be wrong here with my assumptions. We're now about 17 years into the IPv6 migration and still we do not have widespread IPv6 adoption on the client side. That's mostly an issue of CPE device rotation at the customer side and updating provisioning solutions. For the server side we're more or less done. Operating system support is there, commercial firewall and router vendors picked it up in the last ten years, datacenter providers are ready, so we're waiting for the users to put some pressure on providing a service via IPv6. Looking at HTTP/2 it's also a different protocol. The gap might be somewhat closer than the one between IPv4 and IPv6, but it's still huge. Now I'd bet that in the case of HTTP/2 we'll also see a really slow adoption, but this time it's not the client side that's holding back the adoption. For HTTP/2 I've no doubts about a fast adoption on the client side. Google and Mozilla are nowadays providing some kind of continues delivery of new features to the end user on a monthly basis (surprisingly that also works for mobile devices!). So the web browser near you will soon have a HTTP/2 implementation. Even Microsoft is switching to a new development model of rolling updates with Windows 10 and the Internet Explorer successor. But looking at the server side I doubt we'll have widespread HTTP/2 support within the next 5 years. Maybe in 10. But I doubt even that. With all those reverse proxies, interception devices for header enrichment at mobile carriers, application servers, self written HTTP implementations, load balancers and so on I doubt we'll have a fast and smooth migration ahead. But maybe we're all lucky and I'm wrong. I'd really love to be wrong here. Maybe we can provide working IPv4-IPv6 dual-stack setups for everyone in the meantime.

11 February 2015

John Goerzen: Reactions to Has modern Linux lost its way? and the value of simplicity

Apparently I touched a nerve with my recent post about the growing complexity of issues. There were quite a few good comments, which I ll mention here. It s provided me some clarity on the problem, in fact. I ll try to distill a few more thoughts here. The value of simplicity and predictability The best software, whether it s operating systems or anything else, is predictable. You read the documentation, or explore the interface, and you can make a logical prediction that when I do action X, the result will be Y. grep and cat are perfect examples of this. The more complex the rules in the software, the more hard it is for us to predict. It leads to bugs, and it leads to inadvertant security holes. Worse, it leads to people being unable to fix things themselves one of the key freedoms that Free Software is supposed to provide. The more complex software is, the fewer people will be able to fix it by themselves. Now, I want to clarify: I hear a lot of talk about ease of use. Gnome removes options in my print dialog box to make it easier to use. (This is why I do not use Gnome. It actually makes it harder to use, because now I have to go find some obscure way to just make the darn thing print.) A lot of people conflate ease of use with ease of learning, but in reality, I am talking about neither. I am talking about ease of analysis. The Linux command line may not have pointy-clicky icons, but at least at one time once you understood ls -l and how groups, users, and permission bits interacted, you could fairly easily conclude who had access to what on a system. Now we have a situation where the answer to this is quite unclear in terms of desktop environments (apparently some distros ship network-manager so that all users on the system share the wifi passwords they enter. A surprise, eh?) I don t mind reading a manpage to learn about something, so long as the manpage was written to inform. With this situation of dbus/cgmanager/polkit/etc, here s what it feels like. This, to me, is the crux of the problem: It feels like we are in a twisty maze, every passage looks alike, and our flashlight ran out of battieries in 2013. The manpages, to the extent they exist for things like cgmanager and polkit, describe the texture of the walls in our cavern, but don t give us a map to the cave. Therefore, we are each left to piece it together little bits at a time, but there are traps that keep moving around, so it s slow going. And it s a really big cave. Other user perceptions There are a lot of comments on the blog about this. It is clear that the problem is not specific to Debian. For instance: This stuff is really important, folks. People being able to maintain their own software, work with it themselves, etc. is one of the core reasons that Free Software exists in the first place. It is a fundamental value of our community. For decades, we have been struggling for survival, for relevance. When I started using Linux, it was both a question and an accomplishment to have a useable web browser on many platforms. (Netscape Navigator was closed source back then.) Now we have succeeded. We have GPL-licensed and BSD-licensed software running on everything from our smartphones to cars. But we are snatching defeat from the jaws of victory, because just as we are managing to remove the legal roadblocks that kept people from true mastery of their software, we are erecting technological ones that make the step into the Free Software world so much more difficult than it needs to be. We no longer have to craft Modelines for X, or compile a kernel with just the right drivers. This is progress. Our hardware is mostly auto-detected and our USB serial dongles work properly more often on Linux than on Windows. This is progress. Even our printers and scanners work pretty darn well. This is progress, too. But in the place of all these things, now we have userspace mucking it up. We have people with mysterious errors that can t be easily assisted by the elders in the community, because the elders are just as mystified. We have bugs crop up that would once have been shallow, but are now non-obvious. We are going to leave a sour taste in people s mouth, and stir repulsion instead of interest among those just checking it out. The ways out It s a nasty predicament, isn t it? What are your ways out of that cave without being eaten by a grue? Obviously the best bet is to get rid of the traps and the grues. Somehow the people that are working on this need to understand that elegance is a feature a darn important feature. Sadly I think this ship may have already sailed. Software diagnosis tools like Enrico Zini s seat-inspect idea can also help. If we have something like an ls for polkit that can reduce all the complexity to something more manageable, that s great. The next best thing is a good map good manpages, detailed logs, good error messages. If software would be more verbose about the permission errors, people could get a good clue about where to look. If manpages for software didn t just explain the cavern wall texture, but explain how this room relates to all the other nearby rooms, it would be tremendously helpful. At present, I am unsure if our problem is one of very poor documentation, or is so bad that good documentation like this is impossible because the underlying design is so complex it defies being documented in something smaller than a book (in which case, our ship has not just sailed but is taking on water). Counter-argument: progress One theme that came up often in the comments is that this is necessary for progress. To a certain extent, I buy that. I get why udev is important. I get why we want the DE software to interact well. But here s my thing: this already worked well in wheezy. Gnome, XFCE, and KDE software all could mount/unmount my drives. I am truly still unsure what problem all this solved. Yes, cloud companies have demanding requirements about security. I work for one. Making security more difficult to audit doesn t do me any favors, I can assure you. The systemd angle To my surprise, systemd came up quite often in the discussion, despite the fact that I mentioned I wasn t running systemd-sysv. It seems like the new desktop environemt ecosystem is the systemd ecosystem in a lot of people s minds. I m not certain this is justified; systemd was not my first choice, but as I said in an earlier blog post, jessie will still boot . A final note I still run Debian on all my personal boxes and I m not going to change. It does awesome things. For under $100, I built a music-playing system, with Raspberry Pis, fully synced throughout my house, using a little scripting and software. The same thing from Sonos would have cost thousands. I am passionate about this community and its values. Even when jessie releases with polkit and all the rest, I m still going to use it, because it is still a good distro from good people.

Daniel Leidert: Blogger RSS feed and category URLs with combined labels/tags

Run a blog on blogger.com? Maybe made it bilingual? Maybe blog on different topics? Wondering how the URL for an RSS feed for e.g. two labels looks like? Asking how to see all articles matching two tags (labels)? Finding a keyword under one or more labels? Many things are possible. I'll show a few examples below. Maybe that is even interesting for the planet Debian folks. I happen to blog mostly in English about Debian topics. But sometimes I also want to post something in German only (e.g. about German tax software). It is discouraged to put the latter on planet-debian. Instead it can be published in the language specific planet feed. So instead of adding new tags, one could easily combine two labels: the one for language of the feed and the one for Debian related posts (e.g. debian+english or debian+german). Therefor this post goes to the Debian planet. Search for combbined labels/tagsSay I want to view all postings related to the topics FOO and BAR. Then it is:

http://domain.tld/search/label/FOO+BAR OR
http://domain.tld/search/?q=label:FOO+label:BAR
Be aware that labels are case sensitive and that more labels can be added. The examples below will show all postings related to the topics debian and n54l and xbmc:

http://www.wgdd.de/search/label/debian+n54l+xbmc
http://www.wgdd.de/search/?q=label:debian+label:n54l+label:xbmc
It is also possible to search for all posts related to the topics FOO or BAR:

http://domain.tld/search/?q=label:FOO label:BAR
Say for example, you want to see all postings related to the topics logitech or toshiba, then it is:

http://www.wgdd.de/search/?q=label:logitech label:toshiba
Feed URLsTo get back to the first example lets say, the feed shall contain all posts related to the topics FOO and BAR. Then it is:

http://domain.tld/feeds/posts/default/-/FOO/BAR/ OR
http://domain.tld/feeds/posts/default?q=label:FOO+label:BAR
Respecitvely to show all feeds related to either of those topics use:

http://domain.tld/feeds/posts/default/?q=label:FOO label:BAR
To get a feed of the example topics as shown above then would be:

http://www.wgdd.de/feeds/posts/default/-/debian/n54l/xbmc/
http://www.wgdd.de/feeds/posts/default?q=label:debian+label:n54l+label:xbmc
http://www.wgdd.de/feeds/posts/default?q=label:logitech label:toshiba
Coming back to planet Debian, below is a solution for a multi-lingual planet contribution (if both planets would exist):

http://www.wgdd.de/feeds/posts/default?q=label:planet-debian+label:english
http://www.wgdd.de/feeds/posts/default?q=label:planet-debian+label:german
Advanced ...There is much more possible. I'll just show two more examples. AND and OR can be combined ...
http://www.wgdd.de/feeds/posts/default?q=label:debian+(label:logitech label:toshiba)
... and a keyword search can be added too:
http://www.wgdd.de/feeds/posts/default?q=stick+(label:debian+(label:logitech label:toshiba))
Links

Daniel Leidert: Issues with Server4You vServer running Debian Stable (Wheezy)

I recently acquired a vServer hosted by Server4You and decided to install a Debian Wheezy image. Usually I boot any device in backup mode and first install a fresh Debian copy using debootstrap over the provided image, to have a clean system. In this case I did not and I came across a few glitches I want to talk about. So hopefully, if you are running the same system image, it saves you some time to figure out, why the h*ll some things don't work as expected :) Cron jobs not runningI installed unattended-upgrades and adjusted all configuration files to enable unattended upgrades. But I never received any mail about an update although looking at the system, I saw updates waiting. I checked with
# run-parts --list /etc/cron.daily
and apt was not listed although /etc/cron.daily/apt was there. After spending some time to figure out, what was going on, I found the rather simple cause: Several scripts were missing the executable bit, thus did not run. So it seems, for whatever reason, the image authors have tempered with file permissions and of course, not by using dpkg-statoverride :( It was easy to fix the file permissions for everything beyond /etc/cron*, but that still leaves a very bad feeling, that there are more files that have been tempered with! I'm not speaking about customizations. That are easy to find using debsums. I'm speaking about file permissions and ownership.Now there seems no easy way to either check for changed permissions or ownership. The only solution I found is to get a list of all installed packages on the system, install them into a chroot environment and get all permission and ownership information from this very fresh system. Then compare file permissions/ownership of the installed system with this list. Not fun. init from testing / upstart on holdToday I've discovered, that apt-get wanted to update the init package. Of course I was curious, why unattended-upgrades didn't yet already do so. Turns out, init is only in testing/unstable and essential there. I purged it, but apt-get keeps bugging me to update/install this package. I really began to wonder, what is going on here, because this is a plain stable system:
  • no sources listed for backports, volatile, multimedia etc.
  • sources listed for testing and unstable
  • only packages from stable/stable-updates installed
  • sets APT::Default-Release "stable";
First I checked with aptitude:
# aptitude why init
Unable to find a reason to install init.
Ok, so why:
# apt-get dist-upgrade -u
Reading package lists... Done
Building dependency tree
Reading state information... Done
Calculating upgrade... Done
The following NEW packages will be installed:
init
0 upgraded, 1 newly installed, 0 to remove and 0 not upgraded.
Need to get 0 B/4674 B of archives.
After this operation, 29.7 kB of additional disk space will be used.
Do you want to continue [Y/n]?
JFTR: I see a stable system bugging me to install systemd for no obvious reason. The issue might be similar! I'm still investigating. (not reproducible anymore)Now I tried to debug this:
# apt-get -o  Debug::pkgProblemResolver="true" dist-upgrade -u
Reading package lists... Done
Building dependency tree
Reading state information... Done
Calculating upgrade... Starting
Starting 2
Investigating (0) upstart [ amd64 ] < 1.6.1-1 1.11-5 > ( admin )
Broken upstart:amd64 Conflicts on sysvinit [ amd64 ] < none -> 2.88dsf-41+deb7u1 2.88dsf-58 > ( admin )
Conflicts//Breaks against version 2.88dsf-58 for sysvinit but that is not InstVer, ignoring
Considering sysvinit:amd64 5102 as a solution to upstart:amd64 10102
Added sysvinit:amd64 to the remove list
Fixing upstart:amd64 via keep of sysvinit:amd64
Done
Done
The following NEW packages will be installed:
init
0 upgraded, 1 newly installed, 0 to remove and 0 not upgraded.
Need to get 0 B/4674 B of archives.
After this operation, 29.7 kB of additional disk space will be used.
Do you want to continue [Y/n]?
Eh, upstart?
# apt-cache policy upstart
upstart:
Installed: 1.6.1-1
Candidate: 1.6.1-1
Version table:
1.11-5 0
500 http://ftp.de.debian.org/debian/ testing/main amd64 Packages
500 http://ftp.de.debian.org/debian/ sid/main amd64 Packages
*** 1.6.1-1 0
990 http://ftp.de.debian.org/debian/ stable/main amd64 Packages
100 /var/lib/dpkg/status
# dpkg -l upstart
Desired=Unknown/Install/Remove/Purge/Hold
Status=Not/Inst/Conf-files/Unpacked/halF-conf/Half-inst/trig-aWait/Trig-pend
/ Err?=(none)/Reinst-required (Status,Err: uppercase=bad)
/ Name Version Architecture Description
+++-=============================-===================-===================-===============================================================
hi upstart 1.6.1-1 amd64 event-based init daemon
Ok, at least one package is at hold. This is another questionable customization, but in case easy to fix. But I still don't understand apt-get and the difference to aptitude behaviour? Can someone please enlighten me? Customized filesThis isn't really an issue, but just for completion: several files have been customized. debsums easily shows which ones:
# debsums -ac
I don't have the original list anymore - please check yourself

10 February 2015

Dirk Eddelbuettel: RPushbullet 0.2.0

A new releases of the RPushbullet package (interfacing the neat Pushbullet service) arrived on CRAN today. It brings several weeks of extensions, corrections and cleanups---with key contributions by Mike Birdgeneau and Henrik Bengtsson. RPushbullet now has support for channels (a reasonably new feature upstream). Setup, initialization and tests all got improved as well. Changes are summarized below based in the extract from the NEWS.Rd file.
Changes in version 0.2.0 (2015-02-07)
  • Added support for Pushbullet 'channels' (once again thanks to Mike Birdgeneau for the initial push on this)
  • Support for pushes was solidified: proper choices of either device, email or channel should work in all cases
  • S3 methods are now properly exports (thanks to Henrik Bengtsson)
  • File transfer mode has been improved / corrected (thanks to Mike Birdgeneau)
  • The regression test suite was expanded and robustified
  • This NEWS file was added. Better late than never.
Courtesy of CRANberries, there is also a diffstat report for this release. More details about the package are at the RPushbullet webpage and the RPushbullet GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

8 February 2015

Diego Escalante Urrelo: Link Pack #06

The story of Mel Blanc being saved by Bugs Bunny
Such a fantastic and romantic story. Mel Blanc, voice of half the Looney Tunes characters was in an car crash and hanging from a thread in a comma. And it took his characters to save him. It s a very interestingly edited podcast too:
( ) a crazy story about Mel nearly dying in a crash on Dead Man s Curve on Hollywood Boulevard and about the moment two weeks later when Bugs Bunny emerged from Mel s coma before Mel did. In fact, according to neurosurgeon Louis Conway who attended to Mel at the time, it seemed as though Bugs Bunny was trying to save his life.
The audacious rescue plan that might have saved space shuttle Columbia
This is probably the best documentary/kinda fiction article I have read in a long time. It s a long read going over the hypothetical, and nail bitting, plan to rescue the Columbia if it ever got in trouble. It s really intense, and something to sit down and read fully focused, book style.
But imagine an alternate timeline for the Columbia mission in which NASA quickly realized just how devastating the foam strike had been. Could the Columbia astronauts have been safely retrieved from orbit?
Ocean Gravity: Riding sea currents
Cool video of a sea diver running through seafloor currents, really cool and fascinating :). El chavo del ocho en el infierno
This one is in Spanish, and it s a funny take on El chavo del ocho and how it follows some classic models and myths of literature. Chespirito was very fond of classics, so this would make sense. But, of course, the whole article is written on a tongue in cheek style.
En El Chavo del Ocho, Bola os, o el Camus azteca, cre su propia versi n del mito de S sifo. El chavo y compa a est n condenados a empujar por una empinada colina todos los d as esta piedra enorme que siempre regresa, obligandolos al tormento del eterno retorno. La piedra de Quico es cuadrada, no rueda, se desliza. Es c mico, a pesar de tr gico.

Go for some more Link Pack, it s sugar free

Petter Reinholdtsen: Nagios module to check if the Frikanalen video stream is working

When running a TV station with both broadcast and web stream distribution, it is useful to know that the stream is working. As I am involved in the Norwegian open channel Frikanalen as part of my activity in the NUUG member organisation, I wrote a script to use mplayer to connect to a video stream, pick two images 35 seconds apart and compare them. If the images are missing or identical, something is probably wrong with the stream and an alarm should be triggered. The script is written as a Nagios plugin, allowing us to use Nagios to run the check regularly and sound the alarm when something is wrong. It is able to detect both a hanging and a broken video stream. I just uploaded the code for the script into the Frikanalen git repository on github. If you run a TV station with web streaming, perhaps you can find it useful too. Last year, the Frikanalen public TV station transformed into using only Linux based free software to administrate, schedule and distribute the TV content. The source code for the entire TV station is available from the Github project page. Everyone can use it to send their content on national TV, and we provide both a web GUI and a web API to add and schedule content. And thanks to last weeks developer gathering and following activity, we now have the schedule available as XMLTV too. Still a lot of work left to do, especially with the process to add videos and with the scheduling, so your contribution is most welcome. Perhaps you want to set up your own TV station?

Keith Packard: Altos1.6

AltOS 1.6 TeleDongle v3.0 support and bug fixes Bdale and I are pleased to announce the release of AltOS version 1.6. AltOS is the core of the software for all of the Altus Metrum products. It consists of firmware for our cc1111, STM32L151, STMF042, LPC11U14 and ATtiny85 based electronics and Java-based ground station software. This is a major release of AltOS, including support for our new TeleDongle v3.0 board and a selection of bug fixes AltOS Firmware TeleDongle v3.0 added along with some fixes Our updated ground station, TeleDongle v3.0, works just like the original TeleDongle, but is an all-new design: AltOS Bug Fixes We also fixed a few bugs in the firmware: AltosUI and TeleGPS applications A few minor new features are in this release Bug Fixes There are a bunch of minor bug fixes, including the usual collection of attempts to make stuff behave better on Windows platforms.

7 February 2015

Eddy Petri&#537;or: Using Gentoo to create a cross toolchain for the old NSLU2 systems (armv5te)

This is mostly written so I don't forget how to create a custom (Arm) toolchain the Gentoo way (in a Gentoo chroot).

I have been a Debian user since 2001, and I like it a lot. Yet I have had my share of problems with it, mostly because due to lack of time I have very little disposition to try to track unstable or testing, so I am forced to use stable.

This led me to be a fan of Russ Albery's backport script and to create a lot of local backports of packages that are already in unstable or testing.

But this does not help when packages are simply missing from Debian or when something like creating an arm uclibc based system that should be kept up to date, from a security PoV.

I have experience with Buildroot and I must say I like it a lot for creating custom root filesystems and even toolchains. It allows a lot of flexibility that binary distros like Debian don't offer, it does its designated work, creating root filesystems. But buildroot is not appropriate for a system that should be kept up to date, because it lacks a mechanism by which to be able to update to new versions of packages without recompiling the entire rootfs.

So I was hearing from the guys from the Linux Action Show (and Linux Unplugged - by the way, Jupiter Broadcast, why do I need scripts enabled from several sites just to see the links for the shows?) how Arch is great and all, that is a binary rolling release, and that you can customize packages by building your own packages from source using makepkg. I tried it, but Arm support is provided for some specific (modern) devices, my venerable Linksys NSLU2's (I have 2 of them) not being among them.

So I tried Arch in a chroot, then dropped it in favour of a Gentoo chroot since I was under the feeling running Arch from a chroot wasn't such a great idea and I don't want to install Arch on my SSD.

I used succesfully Gentoo in the past to create an arm-unknown-linux-gnueabi chroot back in 2008 and I always liked the idea of USE flags from Gentoo, so I knew I could do this.


So here it goes:


# create a local portage overlay - necessary for cross tools
export LP=/usr/local/portage
mkdir -p $LP/ metadata,profiles
echo 'mycross' > $LP/profiles/repo_name
echo 'masters = gentoo' > $LP/metadata/layout.conf
chown -R portage:portage $LP
echo 'PORTDIR_OVERLAY="'$LP' $ PORTDIR_OVERLAY "' >> /etc/portage/make.conf
unset LP

# install crossdev, setup for the desired target, build toolchain
emerge crossdev
crossdev --init-target -t arm-softfloat-linux-gnueabi -oO /usr/local/portage/mycross
crossdev -t arm-softfloat-linux-gnueabi


6 February 2015

Gunnar Wolf: On the number of attempts on brute-force login attacks

I would expect brute-force login attacks to be more common. And yes, at some point I got tired of ssh scans, and added rate-limiting firewall rules, even switched the daemon to a nonstandard port... But I have very seldom received an IMAP brute-force attack. I have received countless phishing scams on my users, and I know some of them have bitten because the scammers then use their passwords on my servers to send tons of spam. Activity is clearly atypical. Anyway, yesterday we got a brute-force attack on IMAP. A very childish atack, attempted from an IP in the largest ISP in Mexico, but using only usernames that would not belong in our culture (mosty English firstnames and some usual service account names). What I find interesting to see is that each login was attempted a limited (and different) amount of times: Four account names were attempted only once, eight were attempted twice, and so on following this pattern:
 1  
 2  
 3  
 4  
 5  
 6  
 7  
 8  
 9  
10  
11  
12  
13  
14  
15  
16  
17  
18  
19  
20  
21  
22  
(each dot represents four attempts) So... What's significant in all this? Very little, if anything at all. But for such a na ve login attack, it's interesting to see the number of attempted passwords per login varies so much. Yes, 273 (over of the total) did 22 requests, and another 200 were 18 and more. The rest... Fell quite shorter. In case you want to play with the data, you can grab the list of attempts with the number of requests. I filtered out all other data, as i was basically meaningless. This file is the result of:
  1. $ grep LOGIN /var/log/syslog.1
  2. grep FAILED.*201.163.94.42
  3. awk ' print $7 " " $8 '
  4. sort uniq -c
AttachmentSize
logins.txt27.97 KB

5 February 2015

Dirk Eddelbuettel: Introducing drat: Lightweight R Repositories

A new package of mine just got to CRAN in its very first version 0.0.1: drat. Its name stands for drat R Archive Template, and an introduction is provided at the drat page, the GitHub repository, and below. drat builds on a core strength of R: the ability to query multiple repositories. Just how one could always query, say, CRAN, BioConductor and OmegaHat---one can now adds drats of one or more other developers with ease. drat also builds on a core strength of GitHub. Every user automagically has a corresponding github.io address, and by appending drat we are getting a standardized URL. drat combines both strengths. So after an initial install.packages("drat") to get drat, you can just do either one of
library(drat)
addRepo("eddelbuettel")
or equally
drat:::add("eddelbuettel")
to register my drat. Now install.packages() will work using this new drat, as will update.packages(). The fact that the update mechanism works is a key strength: not only can you get a package, but you can gets its updates once its author replaces them into his drat. How does one do that? Easy! For a package foo_0.1.0.tar.gz we do
library(drat)
insertPackage("foo_0.1.0.tar.gz")
The default git repository locally is taken as the default ~/git/drat/ but can be overriden as both a local default (via options()) or directly on the command-line. Note that this also assumes that you a) have a gh-pages branch and b) have that branch as the currently active branch. Automating this / testing for this is left for a subsequent release. Also available is an alternative unexported short-hand function:
drat:::insert("foo_0.1.0.tar.gz", "/opt/myWork/git")
show here with the alternate use case of a local fileshare you can copy into and query from---something we do at work where we share packages only locally. The easiest way to obtain the corresponding file system layout may be to just fork the drat repository. So that is it. Two exported functions, and two unexported (potentially name-clobbering) shorthands. Now drat away! Courtesy of CRANberries, there is also a copy of the DESCRIPTION file for this initial release. More detailed information is on the drat page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 February 2015

Johannes Schauer: I became a Debian Developer

Thanks to akira for the confetti to celebrate the occasion!

Charles Plessy: News of the package mime-support.

The package mime-support is installed by default on Debian systems. It has two roles: first to provide the file /etc/mime.types that associates media types (formerly called MIME types) to suffixes of file names, and second to provide the mailcap system that associates media types with programs. I adopted this package at the end of the development cycle of Wheezy. Changes since Wheezy. The version distributed in Jessie brings a few additions in /etc/mime.types. Among them, application/vnd.debian.binary-package and text/vnd.debian.copyright, which as their name suggest describe two file formats designed by Debian. I registered these types to the IANA, which is more open to the addition of new types since the RFC 6838. The biggest change is the automatic extraction of the associations between programs and media types that are declared in the menu files in FreeDesktop format. Before, it was the maintainer of the Debian package who had to extract this information and translate it in mailcap format by hand. The automation is done via dpkg triggers. A big thank you to Kevin Ryde who gave me a precious help for the developments and corrections to the run-mailcap program, and to all the other contributors. Your help is always welcome! Security updates. In December, Debian has been contacted by Timothy D. Morgan, who found that an attacker could get run-mailcap to execute commands by inserting them in file names (CVE-2014-7209). This first security update for me went well, thanks to the help and instructions of Salvatore Bonaccorso from the Security team. The problem is solved in Wheezy, Jessie and Sid, as well as in Squeeze through its long term support. One of the consequences of this security update is that run-mailcap will systematically use the absolute path to the files to open. For harmless files, this is a bit ugly. This will perhaps be improved after Jessie is released. Future projects The file /etc/mime.types is kept up to date by hand; this is slow and inefficient. The package shared-mime-info contains similar information, that could be used to autogenerate this file, but that would require to parse a XML source that is quite complex. For the moment, I am considering to import Fedora's mailcap package, where the file /etc/mime.types is very well kept up to date. I have not yet decided how to do it, but maybe just by moving that file from one package to the other. In that case, we would have the mime-support package that would provide mailcap support, and the package whose source is Fedora's mailcap package who would provide /etc/mime.types. Perhaps it will be better to use clearer names, such as mailcap-support for the first and media-types for the second? Separating the two main functionalities of mime-support would have an interesting consequence: the possibility of not installing the support for the mailcap system, or to make it optional, and instead to use the FreeDesktop sytem (xdg-open), from the package xdg-utils. Something to keep in mind...

Vincent Bernat: Directory bookmarks with Zsh

There are numerous projects to implement directory bookmarks in your favorite shell. An inherent limitation of those implementations is they being only an enhanced cd command: you cannot use a bookmark in an arbitrary command. UPDATED: My initial implementation with Zsh was using dynamic named directories. I have been pointed on Twitter that there is a simpler way to implement bookmarks. The article has been updated to reflect that. As a side note, it is also possible to just use shell variables1. Zsh comes with a not well-known feature called static named directories. They are declared with the hash builtin and can be refered by prepending ~ to them:
$ hash -d -- -lldpd=/home/bernat/code/deezer/lldpd
$ echo ~-lldpd/README.md
/home/bernat/code/deezer/lldpd/README.md
$ head -n1 ~-lldpd/README.md
lldpd: implementation of IEEE 802.1ab (LLDP)
Because ~-lldpd is substituted during file name expansion, it is possible to use it in any command like a regular directory, like shown above. The - prefix is only here to avoid collision with home directories. Bookmarks are kept into a dedicated directory, $MARKPATH. Each bookmark is a symbolic link to the target directory: for example, ~-lldpd should be expanded to $MARKPATH/lldpd which points to the appropriate directory. Assuming that you have populated $MARKPATH with some links, here is how bookmarks are registered:
for link ($MARKPATH/*(N@))  
    hash -d -- -$ link:t =$ link:A 
 
You also automatically get completion and prompt expansion:
$ pwd
/home/bernat/code/deezer/lldpd/src/lib
$ echo $ (%):-%~ 
~-lldpd/src/lib
The last step is to manage bookmarks without adding or removing symbolic links manually. The following bookmark() function will display the existing bookmarks when called without arguments, will remove a bookmark when called with -d or add the current directory as a bookmark otherwise.
bookmark()  
    if (( $# == 0 )); then
        # When no arguments are provided, just display existing
        # bookmarks
        for link in $MARKPATH/*(N@); do
            local markname="$fg[green]$ link:t $reset_color"
            local markpath="$fg[blue]$ link:A $reset_color"
            printf "%-30s -> %s\n" $markname $markpath
        done
    else
        # Otherwise, we may want to add a bookmark or delete an
        # existing one.
        local -a delete
        zparseopts -D d=delete
        if (( $+delete[1] )); then
            # With  -d , we delete an existing bookmark
            command rm $MARKPATH/$1
        else
            # Otherwise, add a bookmark to the current
            # directory. The first argument is the bookmark
            # name.  .  is special and means the bookmark should
            # be named after the current directory.
            local name=$1
            [ $name == "." ] && name=$ PWD:t 
            ln -s $PWD $MARKPATH/$name
        fi
    fi
 
Find the complete version on GitHub.

Dynamic named directories Another (more complex) way to achieve the same thing is using dynamic named directories. I was initially using this solution but it is far more complex. This section is only here for historical reason. You can find the complete implementation in my GitHub repository. During file name expansion, a ~ followed by a string in square brackets is provided to the zsh_directory_name() function which will eventually reply with a directory name. This feature can be used to implement directory bookmarks:
$ cd ~[@lldpd]
$ pwd
/home/bernat/code/deezer/lldpd
$ echo ~[@lldpd]/README.md
/home/bernat/code/deezer/lldpd/README.md
$ head -n1 ~[@lldpd]/README.md
lldpd: implementation of IEEE 802.1ab (LLDP)
Like for static named directories, because ~[@lldpd] is substituted during file name expansion, it is possible to use it in any command like a regular directory.

Basic implementation Bookmarks are still kept into a dedicated directory, $MARKPATH and are still symbolic links. Here is how the core feature is implemented:
_bookmark_directory_name()  
    emulate -L zsh #  
    setopt extendedglob
    case $1 in
        n)
            [ [ $2 != ( #b)"@"(?*) ]] && return 1 #  
            typeset -ga reply
            reply=($ $ :-$MARKPATH/$match[1] :A ) #  
            return 0
            ;;
        *)
            return 1
            ;;
    esac
    return 0
 
add-zsh-hook zsh_directory_name _bookmark_directory_name
zsh_directory_name() is a function accepting hooks2: instead of defining it directly, we define another function and register it as a hook with add-zsh-hook. The hook is expected to handle different situations. The first one is to be able to transform a dynamic name into a regular directory name. In this case, the first parameter of the function is n and the second one is the dynamic name. In , the call to emulate will restore the pristine behaviour of Zsh and also ensure that any option set in the scope of the function will not have an impact outside. The function can then be reused safely in another environment. In , we check that the dynamic name starts with @ followed by at least one character. Otherwise, we declare we don t know how to handle it. Another hook will get the chance to do something. (#b) is a globbing flag. It activates backreferences for parenthesised groups. When a match is found, it is stored as an array, $match. In , we build the reply. We could have just returned $MARKPATH/$match[1] but to hide the symbolic link mechanism, we use the A modifier to ask Zsh to resolve symbolic links if possible. Zsh allows nested substitutions. It is therefore possible to use modifiers and flags on anything. $ :-$MARKPATH/$match[1] is a common trick to turn $MARKPATH/$match[1] into a parameter substitution and be able to apply the A modifier on it.

Completion Zsh is also able to ask for completion of a dynamic directory name. In this case, the completion system calls the hook function with c as the first argument.
_bookmark_directory_name()  
    # [...]
    case $1 in
        c)
            # Completion
            local expl
            local -a dirs
            dirs=($MARKPATH/*(N@:t)) #  
            dirs=("@"$ ^dirs ) #  
            _wanted dynamic-dirs expl 'bookmarked directory' compadd -S\] -a dirs
            return
            ;;
        # [...]
    esac
    # [...]
 
First, in , we create a list of possible bookmarks. In *(N@:t), N@ is a glob qualifier. N allows us to not return nothing if there is no match (otherwise, we would get an error) while @ only returns symbolic links. t is a modifier which will remove all leading pathname components. This is equivalent to use basename or $ something##*/ in POSIX shells but it plays nice with glob expressions. In , we just add @ before each bookmark name. If we have b1, b2 and b3 as bookmarks, $ ^dirs expands to b1,b2,b3 and therefore "@"$ ^dirs expands to the (@b1 @b2 @b3) array. The result is then feeded into the completion system.

Prompt expansion Many people put the name of the current directory in their prompt. It would be nice to have the bookmark name instead of the full name when we are below a bookmarked directory. That s also possible!
$ pwd
/home/bernat/code/deezer/lldpd/src/lib
$ echo $ (%):-%~ 
~[@lldpd]/src/lib
The prompt expansion system calls the hook function with d as first argument and the file name to transform.
_bookmark_directory_name()  
    # [...]
    case $1 in
        d)
            local link slink
            local -A links
            for link ($MARKPATH/*(N@))  
                links[$  #link:A $'\0'$ link:A ]=$ link:t  #  
             
            for slink ($ (@On)$ (k)links )  
                link=$ slink#*$'\0'  #  
                if [ [ $2 = ( #b)($ link )( /*) ]]; then
                    typeset -ga reply
                    reply=("@"$ links[$slink]  $(( $  #match[1]  )) )
                    return 0
                fi
             
            return 1
            ;;
        # [...]
    esac
    # [...]
 
OK. This is some black Zsh wizardry. Feel free to skip the explanation. This is a bit complex because we want to substitute the most specific bookmark, hence the need to sort bookmarks by their target lengths. In , the associative array $links is created by iterating on each symbolic link ($link) in the $MARKPATH directory. The goal is to map a target directory with the matching bookmark name. However, we need to iterate on this map from the longest to the shortest key. To achieve that, we prepend each key with its length. Remember, $ link:A is the absolute path with symbolic links resolved. So, $ #link:A is the length of this path. We concatenate the length of the target directory with the target directory name and use $'\0' as a separator because this is the only safe character for this purpose. The result is mapped to the bookmark name. The second loop is an iteration on the keys of the associative array $links (thanks to the use of the k parameter flag in $ (k)links ). Those keys are turned into an array (@ parameter flag) and sorted numerically in descending order (On parameter flag). Since the keys are directory names prefixed by their lengths, the first match will be the longest one. In , we extract the directory name from the key by removing the length and the null character at the beginning. Then, we check if the extracted directory name matches the file name we have been provided. Again, (#b) just activates backreferences. With extended globbing, we can use the or operator, . So, when either the file name matches exactly the directory name or is somewhere deeper, we create the reply which is an array whose first member is the bookmark name and the second member is the untranslated part of the file name.

Easy typing Typing ~[@ is cumbersome. Hopefully, Zsh line editor can be extended with additional bindings. The following snippet will substitute @@ (if typed without a pause) by ~[@:
vbe-insert-bookmark()  
    emulate -L zsh
    LBUFFER=$ LBUFFER "~[@"
 
zle -N vbe-insert-bookmark
bindkey '@@' vbe-insert-bookmark
In combination with the autocd option and completion, it is quite easy to jump to a bookmarked directory.

  1. For example:
    $ lldpd=/home/bernat/code/deezer/lldpd
    $ echo $lldpd/README.md
    /home/bernat/code/deezer/lldpd/README.md
    $ head -n1 $lldpd/README.md
    lldpd: implementation of IEEE 802.1ab (LLDP)
    
    The drawback is that you don t have a separate namespace for your bookmarks. You can still use a special prefix for that. Also, no prompt expansion.
  2. Other functions accepting hooks are chpwd() or precmd().

3 February 2015

Thomas Goirand: OpenStack packaging activity, November 2014 to January 2015

November 2014:
Sunday 2nd:
Travel from Moscow to Paris Monday 3rd to Sunday 8th:
Summit in Paris Monday 10th:
Uploaded python-rudolf to Sid (needed by Fuel)
Uploaded python-invoke and python-invocations (needed to run fabric s unit tests)
Uploaded python-requests-kerberos/0.5-2 fixing CVE-2014-8650: failure to handle mutual authentication. Asked the release team for unblock.
Uploaded openstack-pkg-tools version 19 fixing startup with systemd in Jessie (added RuntimeDirectory directive). Asked the release team for unblock.
Opened ticket to remove TripleO, Tuskar and Ironic packages from Jessie. I don t consider them ready for a Debian stable release, and there s no long term support from upstream.
Fixed Designate Juno dbsync process which prevented it from being installed.
Fixed Ironic Juno unowned files after purge (policy 6.8, 10.8): /var/lib/ironic/ cache, ironicdb (eg: purging these folders on purge) Thuesday 11:
Fixed nova-api CVE-2014-3708: Nova network DoS through API filtering in both the Juno and Icehouse release. Asked the release team to unblock the Icehouse version for Jessie. See: https://bugs.debian.org/769163
Uploaded Cinder with Duch debconf translation fix and pt.po
Uploaded python-django-pyscss with upstream patch for Django 1.7 support instead of the Debian one that I wrote 2 months ago. Asked the release team to unblock which they did. Wednesday 12:
Uploaded fix for horizon (see #769101) unowned files after purge (policy 6.8, 10.8). Now purging /usr/share/openstack-dashboard/openstack_dashboard on purge.
Uploaded Ironic with Duch translations of debconf
Uploaded Designate with Duch translations of Debconf screens
Uploaded openstack-trove with Duch translations of Debconf screens
Uploaded Tuskar with Duch translations of Debconf screens
Updated python-oslotest in Experimental to version 1.2.0 Thursday 13:
Uploaded new packages: python-oslo.middleware and python-oslo.concurrency.
Opened a new packaging branch for Nova Kilo, and updated (build-)depends.
Uploaded fix for Icehouse Cinder: delete volume failed due to unicode problems , and asked for unblock.
Uploaded new package: python-pygit2 and python-xmlbuilder, needed for fuel-agent-ci.
Uploaded sheepdog with Duch debconf translation.
Uploaded python-daemonize to Sid (in FTP master NEW queue).
Re-uploaded python-invoke after FTP master rejection (missing copyright information) Friday 14:
Uploaded liberasurecode & python-pyeclib to Sid, now in the FTP masters NEW queue waiting for approval. This will soon be needed by Swift. Monday 17:
Worked on the Cobbler packaging (all day long ) Tuesday 18:
Worked on backporting all of Fuel packages to Wheezy. Done with fuelclient already.
Uploaded ruby-cstruct and ruby-rethtool to Sid (needed by nailgun-agent) Wednesday 19:
Uploaded pyeclib again, with fixes for the build-depends. Package is still in the NEW queue anyway.
Built a Debian-based bootstrap hardware discovery image for Fuel, and it seems that it works already (to be checked )! \o/
To be added as packages in the ISO:
* nailgun-mcagents
* nailgun-net-check
* fuel-agent
* python-tasklib Thursday 20:
Uploaded python-tasklib to Sid (now in NEW queue )
Continued working on the discovery bootstrap ISO Friday 21:
Documented Sahara procedure in Debian in the official install-guide: https://review.openstack.org/136237
Fixed oslo.messaging so it doesn t use PROTOCOL_SSLv3 because its support has been removed from Debian (due to possible protocol downgrade attacks): https://review.openstack.org/136278 and uploaded fixed packages for Sid and Experimental.
Uploaded fixed Neutron packages for CVE-2014-7821 in both Sid and Experimental (eg: Icehouse and Juno) Monday 24:
Uploaded new package: python-os-client-config (in NEW queue)
Installed new Xen server to be used as my new Jenkins build machine
Moved the juno-wheezy VM to it
Finished to package python-pymysql and uploaded to Sid. It s now running all unit tests successfully! \o/ Tuesday 25:
Uploaded fix for openstack-debian-images to add the -o compat=1.0 option when building an image with Qemu > 1.0. Opened bug to the release team to have it unblocked.
Continued working on unit tests for fuel-nailgun. Wednesday 26:
Uploaded python-os-net-config to Sid (new package)
Worked briefly on python-cassandra-driver. It needs cassandra to be in, which is a LOT of work.
Found a (not useable) hack to run nailgun unit tests. It works, however, it doesn t seem like fuel-nailgun is designed to be able to use unix socket for the postgres connection in its unit tests.
Uploaded python-pykmip to Sid (new package)
Updated the Debian wheezy backport repository for libvirt to version 1.2.9 from official wheezy-backports. Removed policykit-1 and libusb from there too, as it broke stuff to use a backported version (X and usb were not useable on my Wheezy laptop when using it ). Thursday 27 & Friday 28:
Uploaded new Javascript packages or dependencies for Fuel: libjs-autonumeric, libjs-backbone-deep-model, libjs-backbone.stickit, libjs-cocktail, libjs-i18next, libjs-require-css, libjs-requirejs, libjs-requirejs-text Sunday 30:
Uploaded debian/copyright fixes for libjs-backbone-deep-model, libjs-backbone.stickit and libjs-cocktail after the packages were accepted by the FTP masters and they gave remarks about copyright. DECEMBER 2014 Monday 01:
Uploaded new Debian image to MOX, after I unerstood the issue was about the architecture field that I was wrongly filling. I ll be able to use that for Tempest checking on my dev account. Tuesday 02:
Uploaded python-q-text-as-data to Sid (new awesome package!)
Uploaded Horizon with some triggers mechanisms to start the compress when one of its JS depends is updated. That s very important for security!
Uploaded a fixed version of heat-cfntools to Sid (it was missing the /usr/lib/python* folder). Asked the release team for an unblock so it can reach Jessie.
Fixed unit tests in fuel-nailgun, thanks to a patch from Sebastian Kalinowski. Now all unit tests are passing but one (for which I opened a launchpad bug: tests are trying to write in /var/log/nailgun, which is impossible at package build time). Wednesday 03:
Uploaded fixed version of ruby-rethtool after FTP master s rejection and upstream correction of licensing files.
Uploaded fixed version of libjs-require-css after FTP master s rejection
Fixed (in Git only) python-sysv-ipc missing build-depends on dh-python as per bug opened by James Page (this is not so important, but I did it still).
Continued working on the tempest-ci scripts.
Added to the image-guide docs about openstack-debian-images: https://review.openstack.org/#/c/138743/ Thursday 04:
Uploaded new package: python-proliantutils. Send patch to upstream about an issue in indentation (mix-up with space and tabs) which made the package uninstallable with Python 3.4. Friday 05:
Worked on the package CI. Monday 07:
Worked on the package CI. All works now, up to all of the Tempest tests for Keystone. Now need to fix the neutron config. Thuesday 08:
Continued working on the CI. Wednesday 09:
Uploaded fix for FTBFS of python-tasklib (Closes: #772606)
Uploaded fix for libjerasure-deb missing dependency on libgf-complete-dev, package already unblocked and will migrate to Jessie.
Uploaded fix for Designate Juno fail to upgrade from Icehouse: this was due to the database_connection directive renamed to connection =.
Uploaded fix for Designate purge in Sid (Icehouse release of Designate).
Commited to git updates of the German debconf translation in both Icehouse and Juno.
Updated nova to use libvirtd as init script dependency instead of libvirt-bin (this was renamed in the libvirt-daemon-system package).
Do not touch the db connection directive if user didn t ask for db handling by the package. Thursday 10 to Saturday 13:
Finally understood the issues with systemd service files not being activated by default. Fixed openstack-pkg-tools, and uploaded version 20 to Sid, after the release team accepted the changes. Sunday 14:
Uploaded Juno 2014.2.1 to Experimental: ceilometer, cinder, glance, python-glance-store, heat, horizon, keystone Monday 15:
Finished uploading Juno 2014.2.1 to Experimental: Nova, Neutron, Sahara Tuesday 16:
Added crontab to flush tokens in Icehouse Keystone
Some more CI work Wednesday 17:
Uploaded keystone with systemd fix and crontab to flush the token table in Sid (eg: Icehouse).
Uploaded nova Icehouse with a bunch of fixes in Sid. Thursday 18:
Updated some issues in Nova Icehouse (Sid/Jessie) Friday 19:
Started building a new Jenkins instance for building Kilo packages Monday 22:
Finished building the new Jenkins instance for building Kilo packages, and rebuilt every packages there, using Jessie as a base. Tuesday 23:
Updated version for the following packages: oslo.utils, oslo.middleware, stevedore, oslo.concurency, pecan, oslo.concurrency, python-oslo.vmware, python-glance-store
Built so far: Ceilometer, Keystone, python-glanceclient, cinder, glance Wednesday 24:
Continued packaging Kilo beta 1. Updated: nova, designate, neutron
Uploaded python-tempest-lib to Debian Unstable (new package) Wednesday 31:
Continued packaging Kilo beta 1. Updated: heat JANUARY 2015 Thursday 01:
Continued packaging Kilo beta 1. Updated: ironic, openstack-trove, openstack-doc-tools, ceilometer Friday 02:
Finished packaging Kilo beta 1. Updated: Sahara, Murano, Murano-dashboard, Murano-agent Sunday 04:
Started testing Kilo beta 1. Fixed a few issues on default configuration for Ceilometer and Glance. Monday 05:
Fixed openstack-pkg-tools which failed to create PID files at boot time, Uploaded to Sid, asked the release team for unblock.
Uploaded ceilometer & cinder to Sid, rebuilt against openstack-pkg-tools 21.
Did more testing of Kilo beta 1, fixed a few more minor issues. Tuesday 06:
Uploaded glance, neutron, nova, designate, keystone, heat, trove to Sid, so that all sysv-rc init scripts are fixed with the new openstack-pkg-tools 21. Designate, heat, keystone and trove contains other minor fixes reported to the Debian BTS. Wednesday 07:
Asked the Debian release team (open bugs with debdiff as attachment) for unblocks of glance, neutron, nova, designate, keystone, heat, trove so they migrate to Jessie.
Fixed a few minor issues tracked in the Debian BTS on various packages. Thesday 08:
James Page from Canonical informed me that they are now using openstack-pkg-tools for maintaining their daemons in Nova, Cinder and Keystone in Ubuntu. That s an awesome news : more QA for both platforms.
James Page found out that dh_installinit *must* be called *after* the call of dh_systemd_enable, otherwise, daemons aren t started automatically at the first install of packages, as the unmask of systemd happens after the invoke-rc.d. Friday 09:
Did some QA checks on the latest upload. Fixed Heat which broke because using the wrong template name (glance instead of heat). Monday 12:
Started re-running the automated openstack-deploy scrip in Icehouse, Juno and Kilo. Found out the issue in Keystone wasn t fixed in Juno (but was fixed in other releases), and fixed it.
Removed the use of ssl.PROTOCOL_SSLv3 from heat (removed form Debian). Uploaded the fixed package to Sid.
All of openstack-deploy (debian/kilo branch) now works and succesfully installs OpenStack again. If dh_installinit is called before, we have:
# Automatically added by dh_installinit
if [ -x "/etc/init.d/keystone" ]; then
update-rc.d keystone defaults >/dev/null
fi
if [ -x "/etc/init.d/keystone" ]   [ -e "/etc/init/keystone.conf" ]; then
invoke-rc.d keystone start   true
fi
# End automatically added section
# Automatically added by dh_systemd_enable
# This will only remove masks created by d-s-h on package removal.
deb-systemd-helper unmask keystone.service >/dev/null   true
# was-enabled defaults to true, so new installations run enable.
if deb-systemd-helper --quiet was-enabled keystone.service; then
# Enables the unit on first installation, creates new
# symlinks on upgrades if the unit file has changed.
deb-systemd-helper enable keystone.service >/dev/null   true
else
# Update the statefile to add new symlinks (if any), which need to be
# cleaned up on purge. Also remove old symlinks.
deb-systemd-helper update-state keystone.service >/dev/null   true
fi
# End automatically added section
If it s called after dh_systemd_enable, we have:
# Automatically added by dh_systemd_enable
# This will only remove masks created by d-s-h on package removal.
deb-systemd-helper unmask keystone.service >/dev/null   true
# was-enabled defaults to true, so new installations run enable.
if deb-systemd-helper --quiet was-enabled keystone.service; then
# Enables the unit on first installation, creates new
# symlinks on upgrades if the unit file has changed.
deb-systemd-helper enable keystone.service >/dev/null   true
else
# Update the statefile to add new symlinks (if any), which need to be
# cleaned up on purge. Also remove old symlinks.
deb-systemd-helper update-state keystone.service >/dev/null   true
fi
# End automatically added section
# Automatically added by dh_installinit
if [ -x "/etc/init.d/keystone" ]; then
update-rc.d keystone defaults >/dev/null
fi
if [ -x "/etc/init.d/keystone" ]   [ -e "/etc/init/keystone.conf" ]; then
invoke-rc.d keystone start   true
fi
# End automatically added section
As a consequence, I have to re-upload version 22 of openstack-pkg-tools and also re-upload all OpenStack core packages to Debian Sid. Fixed a number of issues like:
* dbc_upgrade = true check which shouldn t have been there in postinst.
* <project>/configure_db default value is now always false
* db_sync and pkgos_dbc_postinst are now only done if <project>/configure_db is set to true.
Rebuilt all packages in Juno and Kilo with the above changes. Tuesday 13:
Opened unblock bugs for the release team to unblock all fixed packages.
Made more tests in Juno and Kilo to make sure the fixed bugs in Icehouse are fixed there too.
Fixed numerous issues in Trove (missing trove-conductor.conf, wrong trove-api init file, etc.). More work will be needed for it for both Icehouse and newer releases. Wednesday 14:
Did a doc meeting about debconf. Some doc contributors still want to kill the debconf / debian manual, and I have to not agree.
Made a new patch to better document the keystone install procedure:
Did some bug triaging in the doc about Debian.
Uploaded new versions of core packages to Experimental (eg: Juno) built against openstack-pkg-tools >= 22~, and some fixes forward ported from Icehouse: Keystone, Ceilometer, Cinder, Glance, Heat, Ironic, Murano, Neutron, Nova, Saraha and Murano-agent. All where rebuilt in Juno (Wheezy + Trusty) and Kilo (Jessie only) on my Jenkins. Thuesday 15:
Succesfully booted a live-build Debian live image containing mcollective and nailgun-agent as a Debian replacement for the hardware discovery / boostrap image of Fuel. Now, I need to find a way to use just a kernel + initramfs Friday 16 to Tuesday 20:
Worked on the packaging CI. Wednesday 21:
Fixed https://bugs.debian.org/775636 (Horizon failed to build due to a Moscow timezone change and wrong test). Uploaded to Sid, asked for unblock.
Fixed https://bugs.debian.org/775926: CVE-2015-1195: Glance still allows users to download and delete any file in glance-api server (applied upstream patch). Uploaded to Sid, asked for unblock. Uploaded Juno version to Experimental.
Uploaded openstack-trove with the remaining fixes, asked release team for unblock.
Uploaded python-glanceclient 0.15.0 (Juno) to Experimental because it fixes an issue with HTTPS. Added to it a patch from James Page not yet merged, which fixes unit test with Python 2.7.9 (7 failures otherwise).
Uploaded python-xstatic-d3 as it can t be installed anymore in Sid after a new version of d3 was uploaded. Thursday 22:
Uploaded python-xstatic-smart-table and libjs-angularjs-smart-table to Sid (new packages, now in NEW queue). Friday 23:
Ask for the removal of the below list of packages from Jessie:
python-xstatic
python-xstatic-angular
python-xstatic-angular-cookies
python-xstatic-angular-mock
python-xstatic-bootstrap-datepicker
python-xstatic-bootstrap-scss
python-xstatic-d3
python-xstatic-font-awesome
python-xstatic-hogan
python-xstatic-jasmine
python-xstatic-jquery
python-xstatic-jquery-migrate
python-xstatic-jquery-ui
python-xstatic-jquery.bootstrap.wizard
python-xstatic-jquery.quicksearch
python-xstatic-jquery.tablesorter
python-xstatic-jsencrypt
python-xstatic-qunit
python-xstatic-rickshaw
python-xstatic-spin
libjs-jsencrypt
libjs-spin.js
libjs-twitter-bootstrap-datepicker
libjs-twitter-bootstrap-wizard They are used only in OpenStack Horizon starting on 2014.2 (aka Juno), and Jessie is shipped with Icehouse, so it s IMO best to not carry the burden of maintaining these packages for the life of Jessie. Monday 26:
Enhanced and review requested changes for https://review.openstack.org/147296 (ie: Keystone install with more details about what the package does).
Finished testing network on the CI install. Now need to automate all. Tuesday 27:
Closed all bugs on the rabbitmq-server package (2 correction, one bug triage).
Uploaded a fix for the missing conntrack dependency in neutron-l3-agent.
Restarted working on CI setup of Juno after success with manual install in a Xen domU.
Uploaded fix to make sheepdog build reproducible (patch from the Debian BTS). Thursday 28:
Fixed and uploaded to Sid openstack-debian-images 2 bugs reported by Steve McIntire. Official Debian images for OpenStack are now available at:
http://cdimage.debian.org/cdimage/openstack/ \o/
Note that this is the weekly build of testing. We wont get Debian Stable images before Jessie is out.
Documented the new image thing here: http://docs.openstack.org/image-guide/content/ch_obtaining_images.html#debian-images as a new patch: https://review.openstack.org/#/c/151015/
Fixed my patch for keystone debconf doc at: https://review.openstack.org/#/c/147296/ Wednesday 29:
Continued working on packaging CI Thursday 30:
Fixed CVE on Neutron (Juno): L3 agent denial of service with radvd 2.0+
Fixed CVE on Glance (Icehouse + Juno): Glance user storage quota bypass. Asked release team for unblock.
Fixed the image-guide patch after review (ie: https://review.openstack.org/151015)

Next.

Previous.