Search Results: "reg"

28 December 2014

Ian Donnelly: New Release and Farewell to Planet Debian

Hi Everyone, So first I want to say, that I appreciate all the interest in our project from the folks who read our posts at Planet Debian. This will be our last post there for now, I hope you enjoyed the posts about my Google Summer of Code project and other info about Elektra we posted there. To stay informed about Elektra s releases, please subscribe to this RSS feed. Today I want to thank you all and tell you about the latest exciting Elektra news, our newest release 0.8.10! This new release brings many exciting updates and features, since I didn t to a post for Elektra 0.8.9, this post will cover changes and additions from Elektra 0.8.8 to 0.8.10. First of all, there is now a new gui for KDB! A big thanks goes out to Raffael Pancheri for developing this GUI! Once included in your Elektra build, this gui can be run using the command kdb qt-gui. It is very important to note that the gui is in version 0.0.2, meaning it is an alpha project and shouldn t be considered stable yet! This GUI is a convenient tool that lets you mount, unmount, search, import and export configurations. We are very excited about this tool and we hope it makes Elektra more accessible to all users. Check out the screenshot below to see this new GUI in action:
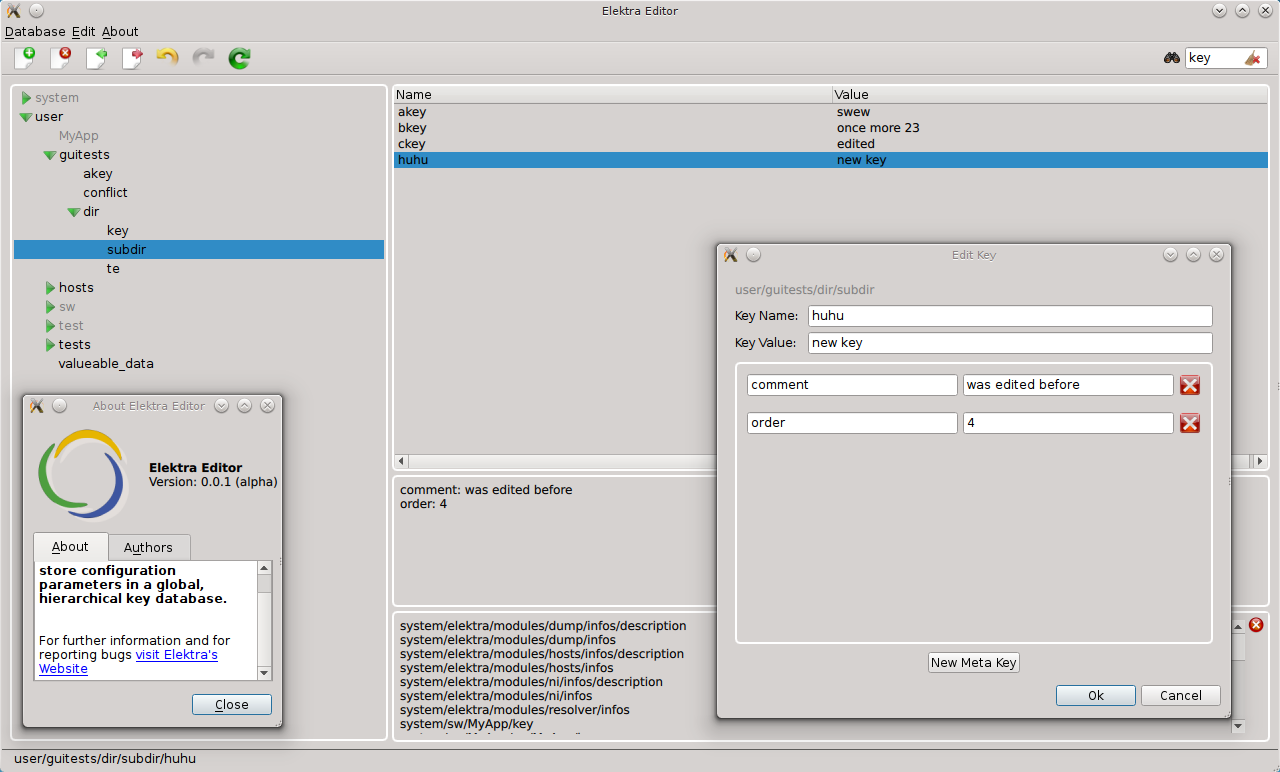
A screenshot of the new qt-gui tool

A few other new features are that Felix added support for multi-line into the ini plugin. Users are able to turn this feature on or off for each configuration. Additionally, Kai-Uwe added support for Windows 7 to Elektra! The Windows 7 port relies on a new resolver called wresolver which is a simpler version of the regular resolver which is compatible with Windows. Additionally, there is a new Java binding, so now Elektra is compatible with applications and plugins written in Java! On top of these features, a new hosts plugin and a new rename plugin have been written. The new hosts in conjunction with improvements to the ini plugin allows for multiple styles of comments (because some ini dialects allow ; and # to be used to differentiate comments) to be used and preserved in configuration files. Additionally, this new hosts plugin is compatible with and differentiates between ipv4 and ipv6 entries. There have also been a huge number of under-the-hood improvements, changes, and fixes; there have been so many in-fact that I am going to list them: There are many more new changes that I could not mention here. Please keep up-to-date with Elektra news and releases by subscribing to this RSS feed and following our news page on GitHub. As always feel free to comment on our posts and I will get back to you as soon as possible. Again, thanks for reading our blog, enjoy the new release! Sincerely,
Ian S. Donnelly P.S. Happy New Year to everybody!

26 December 2014

Vasudev Kamath: Notes: LXC How-To

LXC - Linux Containers allows us to run multiple isolated Linux system under same control host. This will be useful for testing application without changing our existing system. To create an LXC container we use the lxc-create command, it can accepts the template option, with which we can choose the OS we would like to run under the virtual isolated environment. On a Debian system I see following templates supported
[vasudev@rudra: ~/ ]% ls /usr/share/lxc/templates
lxc-alpine*    lxc-archlinux*  lxc-centos*  lxc-debian*    lxc-fedora*  lxc-openmandriva*  lxc-oracle*  lxc-sshd*    lxc-ubuntu-cloud*
lxc-altlinux*  lxc-busybox*    lxc-cirros*  lxc-download*  lxc-gentoo*  lxc-opensuse*      lxc-plamo*   lxc-ubuntu*
For my application testing I wanted to create a Debian container for my By default the template provided by lxc package creates Debian stable container. This can be changed by passing the option to debootstrap after -- as shown below.
sudo MIRROR=http://localhost:9999/debian lxc-create -t debian \
     -f   container.conf -n container-name -- -r sid
-r switch is used to specify the release, MIRROR environment variable is used to choose the required Debian mirror. I wanted to use my own local approx installation, so I can save some bandwidth. container.conf is the configuration file used for creating the LXC, in my case it contains basic information on how container networking should b setup. The configuration is basically taken from LXC Debian wiki
lxc.utsname = aptoffline-dev
lxc.network.type = veth
lxc.network.flags = up
lxc.network.link = br0.1
lxc.network.name = eth0
lxc.network.ipv4 = 192.168.3.2/24
lxc.network.veth.pair = vethvm1
I'm using VLAN setup described in Debian wiki: LXC VLAN Networking page. Below is my interfaces file.
iface eth0.1 inet manual
iface br0.1  inet manual
   bridge_ports eth0.1
   bridge_fd 0
   bridge_maxwait 0
Before launching the LXC make sure you run below command
sudo ifup eth0.1
sudo ifup br0.1
# Also give ip to bridge in same subnet as lxc.network.ipv4
sudo ip addr add 192.168.3.1/24 dev br0.1
I'm giving ip address to bridge so that I can communicate with container from my control host, once it comes up. Now start the container using below command
sudo lxc-start -n container -d -c tty8
We are starting lxc in daemon mode and attaching it to console tty8. If you want, you can drop -d and -c option to start lxc in foreground. But its better you start it in background and attach using lxc-console command shown below.
sudo lxc-console -n container -t tty8
You can detach from console using Ctrl+a q combination and let lxc execute in background. Its also possible to simply ssh into the running container since we have enabled networking. Stopping the container should be done using lxc-stop command, but without -k switch (kill) this command never returned. Even with timeout container is not stopped.
sudo lxc-stop -n container
-r can be used for reboot of container. Since I couldn't get clean shutdown I normally attach the console and issue a halt command in container itself. Not sure if this is the right way, but it gets the thing done. I consider Linux container as a better alternative for spawning a virtual Linux environment instead of running a full blown VM like Virtualbox or VMware.

25 December 2014

Dirk Eddelbuettel: rfoaas 0.0.4.20141225 -- not on CRAN

A new version of rfoaas was prepared for CRAN, but refused on the grounds of having been updated within 24 hours. Oh well. To recap, the rfoaas package provides an interface for R to the most excellent FOAAS service -- which provides a modern, scalable and RESTful web service for the frequent need to tell someone to eff off. And having seen the Christmas Eve (ie December 24) update, upstream immediatly and rather kindly added a new xmas(name, from) function -- so now we could do rfoaas::xmas("CRAN Maintainers") to wish the CRAN Maintainers a very Merry Christmas. So for once, there is no CRANberries report as the package is not on CRAN :-/ There is of course always GitHub. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russ Allbery: Review: Bad Pharma

Review: Bad Pharma, by Ben Goldacre
Publisher: Faber and Faber
Copyright: 2012, 2013
Printing: 2014
ISBN: 0-86547-806-6
Format: Trade paperback
Pages: 397
If you have previously read Bad Science by Ben Goldacre, it's doubtful you need me to do anything other than point out that he has a new book. Oh, and it's subtitled How Drug Companies Mislead Doctors and Harm Patients, and it's written with the same indignant determination, clear explanation, and appreciation for real science as Bad Science. If you haven't read Bad Science, I recommend it. You don't have to read it before Bad Pharma, but it's a more approachable start, and a funnier book. Bad Science opens with some obviously horrible examples, and slowly develops the tools required to analyze more advanced and deceptive quackery. Bad Pharma jumps straight into the deep end of statistical biases in data, how and why they're introduced, and why they undermine your health care. This is a more serious book than Bad Science, since it lacks the medical quackery that is so ludicrous it's funny. Everything in Bad Science is successfully sold to someone there are people who believe in candling but most readers of the book can laugh a bit that anyone would believe in such things before getting to the parts of the book where the quackery is widespread and kills people. Bad Pharma focuses on the mainstream pharmaceutical industry and the way that it distorts the scientific process, which leads to serious consequences quite quickly. Goldacre is more pointedly on a mission here than in his previous book. This is not just an expos . It includes detailed recommendations for how to make the drug evaluation process better, and some specific ethical recommendations for doctors to avoid being unduly influenced by drug company marketing. But before that, he provides the best detailed explanation of how the drug research and approval process is supposed to work that I've seen. There's also a lot of good information about how to detect trials and related studies that haven't been done properly, and how to separate marketing language from scientific evidence. Goldacre wisely does not get into all the details of how to do a trial properly, which would be way beyond the scope of this book, but he does provide valuable rules of thumb and red flags that indicate when someone is probably not doing the trial properly. A point that's both frustrating and enlightening, and made very well by this book, is that fixing many of the problems with the drug approval process is not that difficult. Fixing all of them would be exceedingly difficult, of course, since they involve humans, complex financial motivations, the effectiveness of propaganda, and talented people who are paid well to create favorable impressions for new drugs. But we could get quite significant benefits from a few straightforward enhancements of the existing drug approval process, such as requiring that all clinical trials be pre-registered and all trial results published as a prerequisite for any drug approval. Goldacre makes his case for these changes forcefully and persuasively, and with justified anger. The current situation is bad enough for people like me who are only potential patients with no urgent medical issues. For a practicing doctor like Goldacre, it's infuriating to be actively denied the information required to effectively save people's lives. Normally, I find books like this interesting, but depressing and frustratingly limited. It's easy to write books about abuses that currently exist, or the limitations of the current approach. It's much harder to do what Goldacre does here: clearly describe the goals and ideals of drug testing for the lay reader, detail how the current approaches fall short of that goals, and then propose practical and concrete ways to correct the situation. And keep the details interesting and entertaining enough that I enjoyed reading every page of a nearly 400 page book. This is not a book that will fill you with trust or enthusiasm for the medical establishment (anywhere in the world). But it's still oddly comforting: we do know how to do these things properly, and occasionally we even act on that knowledge. These problems are serious, but they should provoke outrage partly because they're correctable and yet aren't being corrected. And there are doctors like Goldacre who are trying to push medicine towards proper use of evidence, research, and knowledge, instead of commercial manipulation. Recommended if you have any interest at all in how medicine or scientific research is actually done, and what its pitfalls look like. Rating: 8 out of 10

Dirk Eddelbuettel: rfoaas 0.0.4.20141224

A new version of rfoaas is now on CRAN. The rfoaas package provides an interface for R to the most excellent FOAAS service -- which provides a modern, scalable and RESTful web service for the frequent need to tell someone to eff off. This is minor update, affecting only the rfoaas side without changes at the FOAAS backend side. We documented that the result may need an encoding update (at least on the World's leading consumer OS), and now provide a default value for from so that many services can be called argument-less, or at least with one argument less than before. Both of these were suggested by Richie Cotton via issue tickets at the GitHub repo. CRANberries also provides a diff to the previous release. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

24 December 2014

Chris Lamb: 8:20AM. Sunday, 22 December 2013

Running east into the sun, he hadn't seen another human for over half an hour. He navigates Westferry Circus and heads south, cutting from the road through to the riverside pathway. He keeps is breathing steady - no reason to hurry. The wind catches him from Westminster. It smells slightly salty but it's an ersatz attempt, nowhere near bracing enough to be a real sea breeze. Pressing on, the vacant citadel of Canary Wharf disappears behind him. But as the peninsula curves around, a man appears in the distance. Even half a mile away he looks out of place, or rather given the hour time. He's walking purposefully, but it doesn't feel the kind of route someone would be taking to work. He's not wearing quite enough clothes for the weather either, and homeless people are rarely made to feel welcome in the Docklands. His supermarket denim visibly flaps in the breeze. "Relaxed fit", they call it. When he gets within earshot the man cocks his head, not expecting to hear the regular cadence of approaching footsteps. He turns slightly to reveal he's cradling a large bottle of Coca-Cola, meekly wrapped in the swathing bands of two anonymously blue corner-shop plastic bags. The runner eyes the Coke greedily but can quickly see that it has already been opened, tainted. Although only a mouthful or so has gone, a brown froth sloshes against the top of the container. Amateur, he thinks. He'll regret that later. He looks back up to the man, who is now smiling at him. His left hand bccomes visible as he strides: a four-pack of Carling. The man laughs. "Oh, you and me mate are worlds apart!" the man shouts. It's immediately friendly. He starts to raise his Carling as but thinks better of it. It's momentarily awkward. "Worlds apart mate", the man continues. "Have a good one!" The runner smiles back. Only in time, the runner thinks. They both can't stop.

Gunnar Wolf: More on Debian as a social, quasi-familiar project

I have long wanted to echo Gregor's beautiful Debian Advent Calendar posts. Gregor is a dear project member and a dear friend to many of us Debianers, who has shown an amount of stamina and care for the project that inspires everybody; this year, after many harsh flamefests in the project (despite which we are moving at a great rate towards a great release!), many people have felt the need to echo how Debian even as often seen from the outside as a hostile mass of blabbering geeks is actually a great place to work together and to create a deep, strong social fabric And that's quite probably what binds the project together and ensures it will continue existing and excelling for a long time. As for the personal part: This year, my Debian involvement has once again reduced. Not because I care less about Debian, much to the contrary, but because I have taken several responsabilities which require my attention and time. Technically, I'm basically maintaining a couple of PHP-based packages I use for work (most prominently, Drupal7). I have stepped back of most of my DebConf responsabilities, although I stay (and will stay, as it's an area of the project I deeply enjoy doing) involved. And, of course, my current main area of involvement is keyring-maint (for which I have posted here several status updates). I have to say that we expected having a much harder time (read: Stronger opposition and discussions) regarding the expiry of 1024D keys. Of course, many people do have a hard time connecting anew to the web of trust, and we will still face quite a bit of work after January 1st, but the migration has been a mostly pleasant (although clearly intensive) work. Jonathan has just told me we are down to only 306 1024D keys in the keyring (which almost exactly matches the "200-300" I expected back at DC14). Anyway: People predicting doomsday scenarios for Debian do it because they are not familiar with how deep the project runs in us, how important it is socially, almost at a family level, to us that have been long involved in it. Debian is stronger than a technical or political discussion, no matter how harsh it is. And, as a personal thank-you: Gregor, your actions (the GDAC, the RC bug reports) inspire us to stay active, to do our volunteer work better, and remind us of how great is it to be a part of a global, distributed will to Do It Right. Thanks a lot!

Gregor Herrmann: GDAC 2014/24

the last year hasn't been an easy one for debian. we've seen lots of fights, unproductive discussions, & in general behaviour which contributed to what enrico in his brilliant blog post called the "stink in the kitchen". people's feelings were hurt, some became less active, others resigned from a specific position or retired completely. it happened to me as well that reading through threads full of trolling, aggressiveness, finger-pointing, unrespectful or abusive behaviour, etc. made me frustrated, or sad, or angry, or all kinds of other negative feelings. but then I usually told myself: this is not the debian project as I know it; this is only a small part a part which urgently needs improvement! ; but if we only look at it alone, our picture of debian at large is distorted. the much bigger part of the debian life I know doesn't happen on this handful of high-profile mailing lists; it happens on dozens of specialized mailing lists, in many small IRC channels, in the BTS, & in in-person meetings. & what I see there is most of the time constructive, collaborative, respectful communication, & committed, helpful, funny, awesome people. the idea of this advent calendar was to give examples of some of my recent experiences which demonstrate what the bright side of debian is in my opinion & what contributes to my fun in debian. with the aim of sharing my impression that the proverbial "stink" is, if we take a step back, only one piece of the bigger picture, & that we shouldn't let ourselves get demotivated by only staring at this puzzle piece. thanks to all the awesome contributors for polishing existing & adding new shiny puzzle pieces to our common picture every day! finally: thanks for reading this series of posts, & especially thank you to all who provided positive feedback this in turn motivated me to follow through! & now: back to work, & don't forget to help cleaning the kitchen :)
this posting is part of GDAC (gregoa's debian advent calendar), a project to show the bright side of debian & why it's fun for me to contribute.

23 December 2014

Gregor Herrmann: GDAC 2014/23

when I think about debian, one term that comes to my mind is "quality". of course it can be annoying when the ftp-masters REJECT a new package or when potential sponsors nit-pick on packaging details but in general this all leads to our excellent software quality. & yes, I've also seen less-than-excellent packages when working on RC bugs but I still believe that as a whole we strive to Do Things Right . - thanks to all mentors, QA people, ftp-masters, & diligent package maintainers!
this posting is part of GDAC (gregoa's debian advent calendar), a project to show the bright side of debian & why it's fun for me to contribute.

Dirk Eddelbuettel: RcppEigen 0.3.2.3.0

A new release of RcppEigen is now on CRAN, and will get to Debian shortly. This is thanks to a fabulous pull request by Yixuan Qiu who single-handedly managed to upgrade to the new minor release of Eigen -- after having expanded the unit tests a few weeks earlier in another pull request. The NEWS file entry follows.
Changes in RcppEigen version 0.3.2.3.0 (2014-12-22)
  • Updated to version 3.2.3 of Eigen
  • Added a number of additional unit tests for wrap, transform and sparse
  • Updated one of the examples
Courtesy of CRANberries, there is also a diffstat report for the most recent release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Michael Stapelberg: Debian Code Search: taming the latency tail

It s been a couple of weeks since I ve launched Debian Code Search Instant, so people have had the chance to use it for a while and that gives me plenty of data points to look at :-). For every query, I log the search term itself as well as the duration the query took to execute. That way, I can easily identify queries that take a long time and see why that is. There is a class of queries for which Debian Code Search (DCS) doesn t perform so well, and that s queries that consist of trigrams which are extremely common. Whenever DCS receives such a query, it needs to search through a lot of files. Note that it doesn t really matter if there are plenty of results or not it s the number of files that potentially contain a result which matters. One such query is arse (we get a lot of curse words). It consists of only two trigrams ( ars and rse ), which are extremely common in program source code. As a couple of examples, the terms parse , sparse , charset and coarse are all matched by that. As an aside, if you really want to search for just arse , use word boundaries, i.e. \barse\b , which also makes the query significantly faster. Fixing the overloaded frontend When DCS first received the query, arse would lead to our frontend server crashing. That was due to (intentionally) unoptimized code we were aggregating all search results from all 6 source backends in memory, sorted them, and then wrote them out to disk. I addressed this in commit d2922fe92 with the following measures:
  1. Instead of keeping the entire result in memory, just write the result to a temporary file on disk ( unsorted.json ) and store pointers into that file in memory, i.e. (offset, length) tuples. In order to sort the results, we also need to store the ranking and the path (to resolve ties and thereby guarantee a stable result order over multiple search queries). For grouping the results by source package, we need to keep the package name.
  2. If you think about it, you don t need the entire path in order to break a tie the hash is enough, as it defines an ordering. That ordering may be different, but any ordering is good enough for the purpose of merely breaking a tie in a deterministic way. I m using Go s hash/fnv, the only non-cryptographic (fast!) hash function that is included in Go s standard library.
  3. Since this was still leading to Out Of Memory errors, I decided to not store a copy of the package name in each search result, but rather use a pointer into a string pool containing all package names. The number of source package names is relatively small, in the order of 20,000, whereas the number of search results can be in the millions. Using the stringpool is a clear win the overhead in the case where #results < #srcpackages is negligible, but as soon as #results > #srcpackages, you save memory.
With all of that fixed, the query became at all possible, albeit with a runtime of around 20 minutes. Double Writing When running such a long-running query, I noticed that the query ran smooth for a while, but then it took multiple seconds without any visible progress at the end of the query before the results appeared. This was due to the frontend ranking the results and then converting unsorted.json into actual result pages. Since we provide results ordered by ranking, but also results grouped by source packages, it was writing every result twice to disk. What s even worse is that due to re-ordering, every read was essentially random (as opposed to sequential reads). What s even worse is that nobody will ever click through all the hundreds of thousands of result pages, so they are prepared entirely in vain. Therefore, with commit c744b236e I made the frontend generate these result pages on demand. This cut down the time for the ranking phase at the end of each query from 20-30 seconds (for big queries) to typically less than one second. Profiling/Monitoring After adding monitoring to each of the source-backends, I realized that during these long-running queries, the disk I/O and network I/O was nowhere near my expectations: each source-backend was sending only a low single-digit number of megabytes per second back to the frontend (typically somewhere between 1 MB/s and 3 MB/s). This didn t match up at all with the bandwidth I observed in earlier performance tests, so I used wget -O /dev/null to send a query and discard the result in order to get some theoretical performance numbers. Suddenly, I was getting more than 10 MB/s worth of results, maxing out the disks with a read rate of about 200 MB/s. So where is the bottleneck? I double-checked that neither the CPU on any of our VMs, nor the network between them was saturated. Note that as of this point, the CPU of the frontend was at roughly 70% (of one core), which didn t seem a lot to me. Then, I followed this excellent tutorial on profiling Go programs to see where the frontend is spending its time. Turns out, the biggest consumer of CPU time was the encoding/json Go package, which is used for deserializing results received from the backend and serializing them again before sending them to the client. Since I was curious about it for a while already, I decided to give cap n proto a try to replace JSON as serialization mechanism for communication between the source backends and the frontend. Switching to it (commit 8efd3b41) brought down the CPU load immensely, and made the query a bit faster. In addition, I killed the next biggest consumer: the lseek(2) syscall, which we used to call with SEEK_CUR and an offset of 0 so that it would tell us the current position. This was necessary in the first place because we don t know in advance how many bytes we re going to write when serializing a result to disk. The replacement is a neat little trick:
type countingWriter int64
func (c *countingWriter) Write(p []byte) (n int, err error)  
    *c += countingWriter(len(p))
    return len(p), nil
 
// [ ]
// Then, use an io.MultiWriter like this:
var written countingWriter
w := io.MultiWriter(s.tempFiles[backendidx], &written)
result.WriteJSON(w)
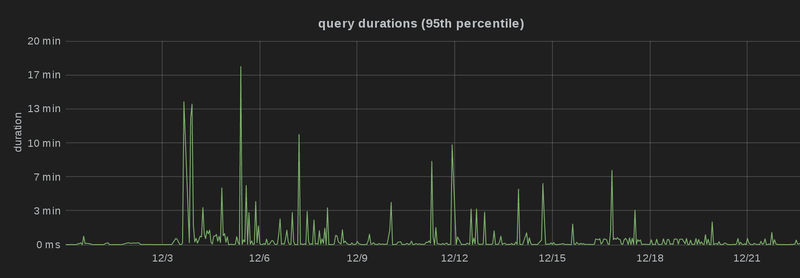
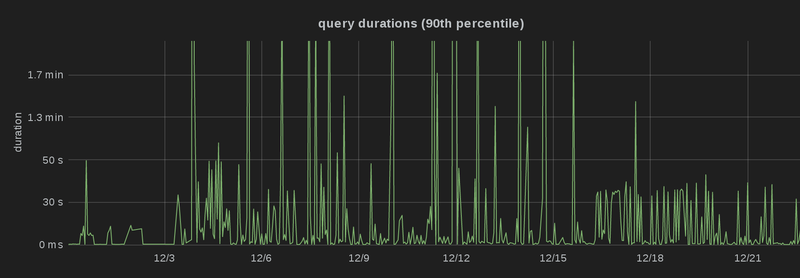
With some more profiling, the new bottleneck was suddenly the read(2) syscall, issued by the cap n proto deserialization, operating directly on the network connection buffer. strace revealed that crunching through the results of one source backend for a long query, read(2) was called about 250,000 times. By simply using a buffered reader (commit 684467ae), I could reduce that to about 2,000 times. Another bottleneck was the fact that for every processed result, the frontend needed to update the query state, which is shared amongst all goroutines (there is one goroutine for each source backend). All that parallelism isn t very effective if you need to synchronize the state updates in the end. So with commit 5d46a572, I refactored the state to be per-backend, so that locking is only necessary for the first couple of results, and the vast vast majority of results can be processed entirely without locking. This brought down the query time from 20 minutes to about 5 minutes, but I still wasn t happy with the bandwidth: the frontend was doing a bit over 10 MB/s of reads from all source backends combined, whereas with wget I could get around 40 MB/s with the same query. At this point, the CPU utilization was around 7% of one core on the frontend, and profiling didn t immediately reveal an obvious culprit. After a bit of experimenting (by commenting out code here and there ;-)), I figured out that the problem was that the frontend was still converting these results from capnproto buffers to JSON. While that doesn t take a lot of CPU time, it delays the network stream from the source-backend: once the local and remote TCP buffers are full, the source-backend will (intentionally!) not continue with its search, so that it doesn t run out of memory. I m still convinced that s a good idea, and in fact I was able to solve the problem in an elegant way: instead of writing JSON to disk and generating result pages on demand, we now write capnproto directly to disk (commit 466b7f3e) and convert it to JSON only before sending out the result pages. That decreases the overall CPU time since we only need to convert a small fraction of the results to JSON, but most importantly, the frontend is now not in the critical path anymore. It can directly pass the data through, and in fact it uses an io.TeeReader to do exactly that. Conclusion With all of these optimizations, we re now down to about 2.5 minutes for the search query arse , and the architecture of the system actually got simpler to reason about. Most importantly, though, the optimizations don t only play out for a single query, but for many different queries. I ve deployed the optimized version at the 15th of December 2014, and you can see that the 99th, 95th and 90th percentile latency dropped significantly, i.e. there are a lot fewer spikes than before, and more queries are processed faster, which is particularly obvious in the third graph (which is capped at 2 minutes):


22 December 2014

Gregor Herrmann: GDAC 2014/22

today I read about a nice & successful example that shows that a debian derivative works best by contributing back to debian & working on debian directly. - great to see again that debian is at the center of a whole ecosystem, & thanks to the grml team!
this posting is part of GDAC (gregoa's debian advent calendar), a project to show the bright side of debian & why it's fun for me to contribute.

Michael Prokop: Ten years of Grml

* On 22nd of October 2004 an event called OS04 took place in Seifenfabrik Graz/Austria and it marked the first official release of the Grml project. Grml was initially started by myself in 2003 I registered the domain on September 16, 2003 (so technically it would be 11 years already :)). It started with a boot-disk, first created by hand and then based on yard. On 4th of October 2004 we had a first presentation of grml 0.09 Codename Bughunter at Kunstlabor in Graz. I managed to talk a good friend and fellow student Martin Hecher into joining me. Soon after Michael Gebetsroither and Andreas Gredler joined and throughout the upcoming years further team members (Nico Golde, Daniel K. Gebhart, Mario Lang, Gerfried Fuchs, Matthias Kopfermann, Wolfgang Scheicher, Julius Plenz, Tobias Klauser, Marcel Wichern, Alexander Wirt, Timo Boettcher, Ulrich Dangel, Frank Terbeck, Alexander Steinb ck, Christian Hofstaedtler) and contributors (Hermann Thomas, Andreas Krennmair, Sven Guckes, Jogi Hofm ller, Moritz Augsburger, ) joined our efforts. Back in those days most efforts went into hardware detection, loading and setting up the according drivers and configurations, packaging software and fighting bugs with lots of reboots (working on our custom /linuxrc for the initrd wasn t always fun). Throughout the years virtualization became more broadly available, which is especially great for most of the testing you need to do when working on your own (meta) distribution. Once upon a time udev became available and solved most of the hardware detection issues for us. Nowadays X.org doesn t even need a xorg.conf file anymore (at least by default). We have to acknowledge that Linux grew up over the years quite a bit (and I m wondering how we ll look back at the systemd discussions in a few years). By having Debian Developers within the team we managed to push quite some work of us back to Debian (the distribution Grml was and still is based on), years before the Debian Derivatives initiative appeared. We never stopped contributing to Debian though and we also still benefit from the Debian Derivatives initiative, like sharing issues and ideas on DebConf meetings. On 28th of May 2009 I myself became an official Debian Developer. Over the years we moved from private self-hosted infrastructure to company-sponsored systems, migrated from Subversion (brr) to Mercurial (2006) to Git (2008). Our Zsh-related work became widely known as grml-zshrc. jenkins.grml.org managed to become a continuous integration/deployment/delivery home e.g. for the dpkg, fai, initramfs-tools, screen and zsh Debian packages. The underlying software for creating Debian packages in a CI/CD way became its own project known as jenkins-debian-glue in August 2011. In 2006 I started grml-debootstrap, which grew into a reliable method for installing plain Debian (nowadays even supporting installation as VM, and one of my customers does tens of deployments per day with grml-debootstrap in a fully automated fashion). So one of the biggest achievements of Grml is from my point of view that it managed to grow several active and successful sub-projects under its umbrella. Nowadays the Grml team consists of 3 Debian Developers Alexander Wirt (formorer), Evgeni Golov (Zhenech) and myself. We couldn t talk Frank Terbeck (ft) into becoming a DM/DD (yet?), but he s an active part of our Grml team nonetheless and does a terrific job with maintaining grml-zshrc as well as helping out in Debian s Zsh packaging (and being a Zsh upstream committer at the same time makes all of that even better :)). My personal conclusion for 10 years of Grml? Back in the days when I was a student Grml was my main personal pet and hobby. Grml grew into an open source project which wasn t known just in Graz/Austria, but especially throughout the German system administration scene. Since 2008 I m working self-employed and mainly working on open source stuff, so I m kind of living a dream, which I didn t even have when I started with Grml in 2003. Nowadays with running my own business and having my own family it s getting harder for me to consider it still a hobby though, instead it s more integrated and part of my business which I personally consider both good and bad at the same time (for various reasons). Thanks so much to anyone of you, who was (and possibly still is) part of the Grml journey! Let s hope for another 10 successful years! Thanks to Max Amanshauser and Christian Hofstaedtler for reading drafts of this.

Jonathan Dowland: Blade Runner: Alien Easter Egg?

A few weeks ago I went to see Blade Runner: The Final Cut in a one-off showing at the Tyneside Cinema. I've only watched the Final Cut once and that viewing was a bit compromised, so it was nice to see it properly, and on a massive screen with decent surround sound too. Whilst watching it I saw something that I thought might potentially have been a visual reference to Scott's earlier movie, Alien. When Deckard is climbing onto the roof of the Bradbury building, there's a decorative motif that to me, looks very Giger-esque, biomechanical, a bit like a chest-burster.
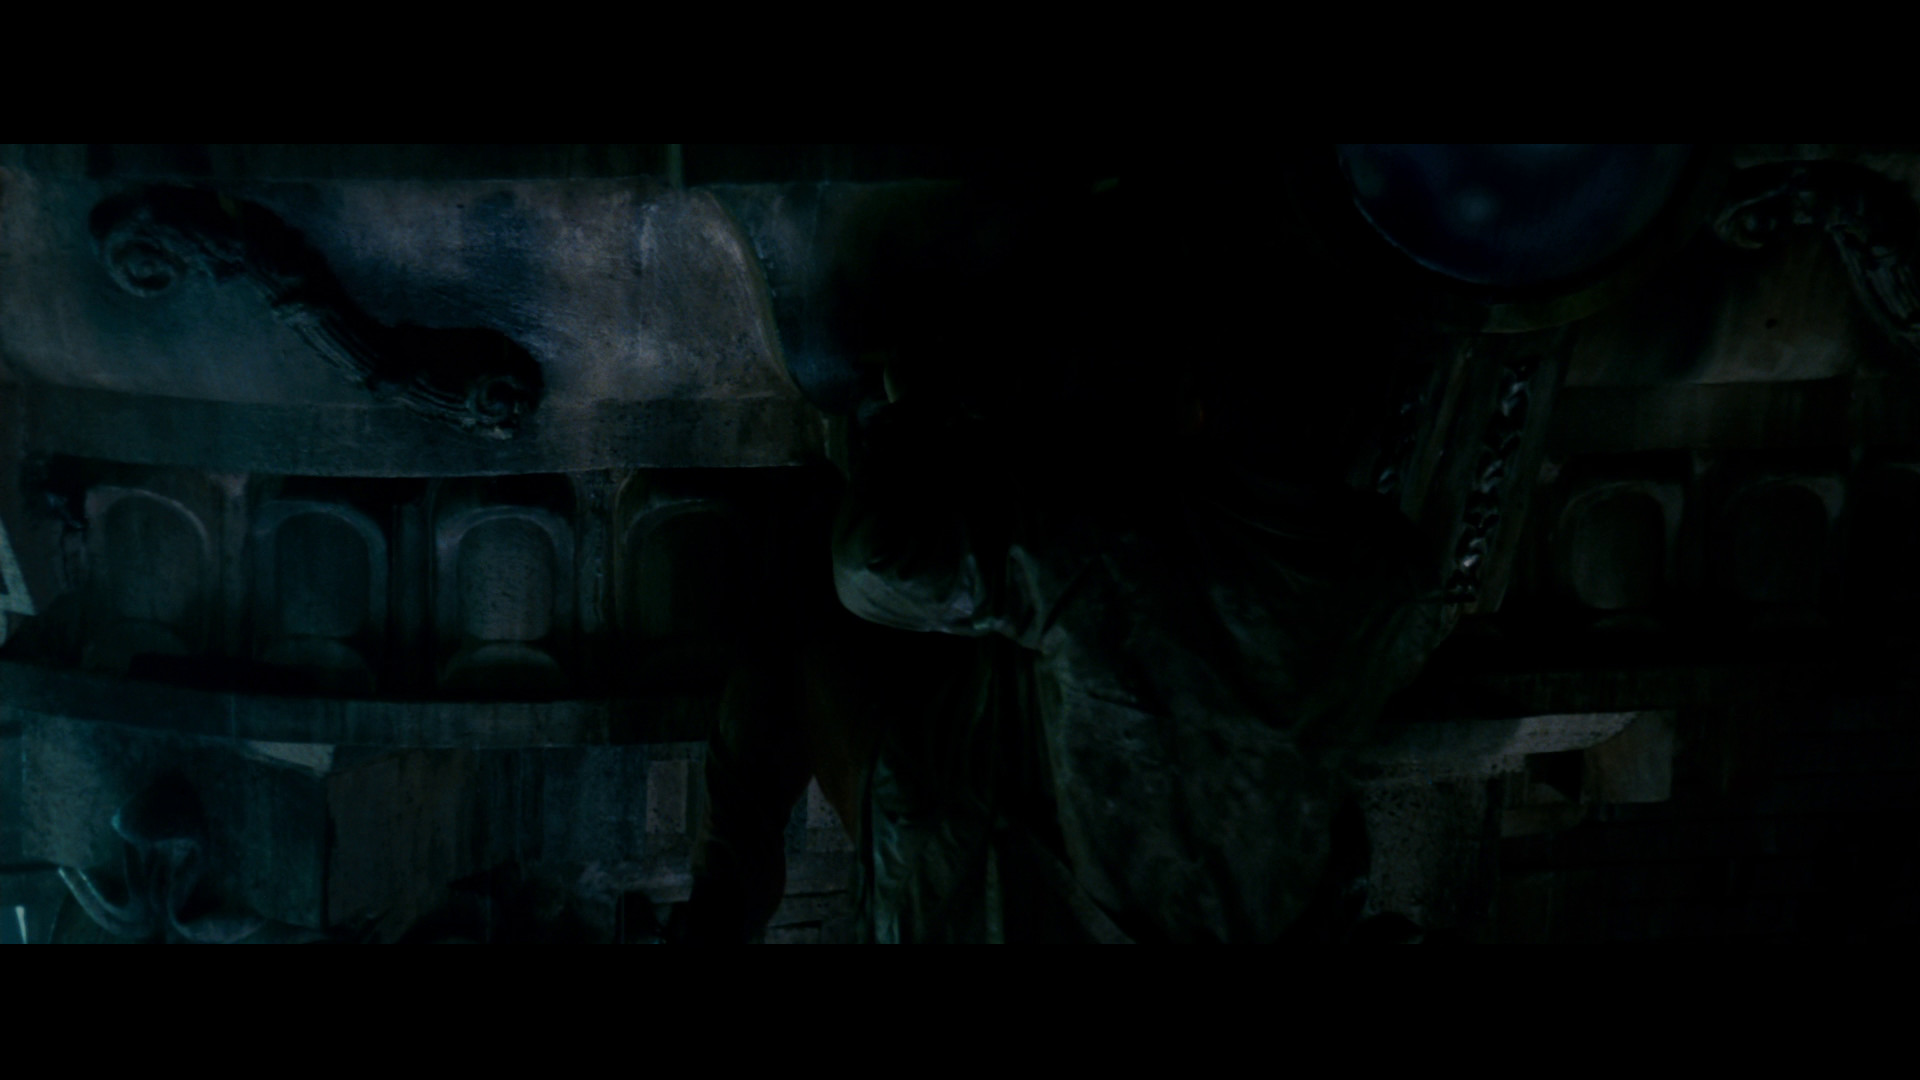
click for full frame click for full frame
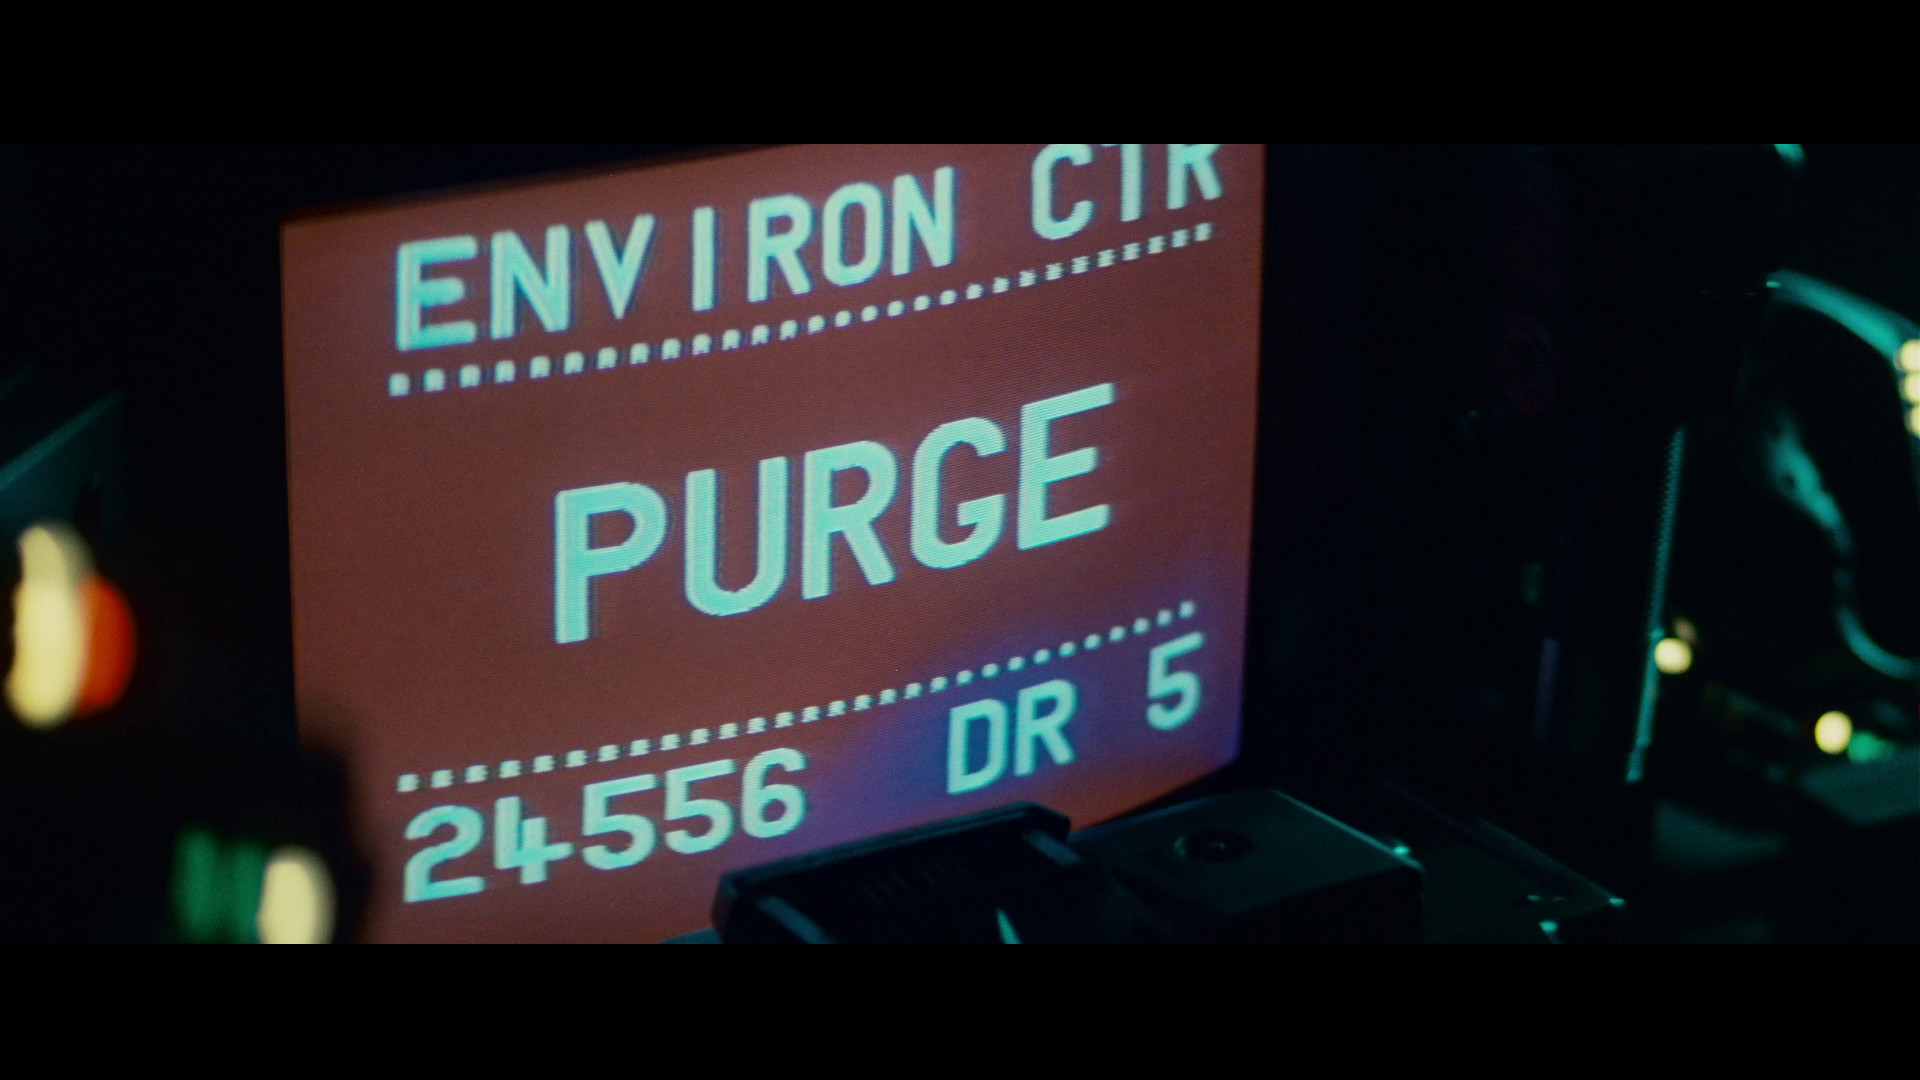
I went back and took a screenshot from the Blu Ray at the same point. What do you think? As it happens, whilst the inner regions of the building in the movie are the Bradbury building (or at least the entrance hall), I don't think the upper exterior shots are.
Purge Purge
There are a few other, well-known references to Alien in Blade Runner, although they are likely simply re-used effects rather than explicitly easter eggs. The display screen in Gaff's Spinner is re-used from the Narcissus (here's a comparison) and the ambience in Deckard's apartment also featured in the Nostromo's medical bay. Some enterprising person has put together a 12 hour session of that particular sound effect looping. There's a number of other comparisons and spots at this propsummit.com thread.

Dirk Eddelbuettel: BH release 1.55.0-1

A new release of BH, our package providing (a large part of the) Boost C++ libraries as a set of template headers for use by R, is now on CRAN. There are two changes. First, we upgraded to Boost 1.55. While Boost 1.57 is now current, I am playing it somewhat safe and conservative here by relying on what is the current version in Debian (and Ubuntu). I even started from the Debian tarball. This ensures we include nothing not in accordance with the Debian Free Software Guidelines (as they are a good proxy for what is acceptable to CRAN). The second change was the addition of Boost.Geometry as requested in issue ticket 5. This may be a good time to recall that best way to get in touch for desired additions in BH are the mailing list or the issue tracker at the GitHub repo. A brief summary of changes from the NEWS file (which we failed to update for the release; the text below is however now in the repo):
Changes in version 1.55.0-1 (2014-12-21)
Courtesy of CRANberries, there is also a (very long!) diffstat report for the most recent release. Comments and suggestions are welcome via the mailing list or the issue tracker at the GitHubGitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 December 2014

Gregor Herrmann: GDAC 2014/21

today I got two private mails from fellow DDs; both were personal messages & a pleasure to read. but what I also realized is that both emails were encrypted. which reminded me how hard it is to communicate securely with most people, & how easy it is with debian people. & this is something we can be proud of!
this posting is part of GDAC (gregoa's debian advent calendar), a project to show the bright side of debian & why it's fun for me to contribute.

Russ Allbery: Review: 2014 Hugos: Novelettes

Review: 2014 Hugos: Novelettes, edited by Loncon 3
Publisher: Loncon 3
Copyright: 2014
Format: Kindle
This is another weird "book review" covering the Hugo-nominated novelettes for the 2014 Hugos (given for works published in 2014) at Loncon 3, the 2014 Worldcon. The "editor" is the pool of attendees and supporting members who chose to nominate works, all of which had been previously edited by other editors in their original publication. I received all of these as part of the Hugo voter's packet for being a supporting member, but they all appear to be available for free on the Internet (at least at the time of this writing). "The Exchange Officers" by Brad Torgersen: An okay, if not particularly ground-breaking, military SF story, ruined for me by the ham-handed introduction of superficial jingoism. The protagonists are doing a tour as remote operators of humanoid battle suits in orbit: not a new premise, but a servicable one. Since this is military SF, they predictably have to defend a space installation against attackers. So we get a bit of drama, a bit of zero-g combat, and the fun of people learning how to remotely operate suits. You've probably read this before, but it passes the time reasonably well. Unfortunately, Torgersen decided to make the villains the Chinese military for no adequately-explained reason. (Well, I'm being kind; I suspect the reason is the standard yellow peril nonsense, but that's less generous.) So there is snide commentary about how only the military understand the Chinese threat and a fair bit of old-fashioned jingoism mixed in to the story, to its detriment. If you like this sort of thing, it's a typical example, although it escapes me why people thought it was exceptional enough to warrant nomination. (5) "The Lady Astronaut of Mars" by Mary Robinette Kowal: Once again, my clear favorite among the stories also won, which is a lovely pattern. Elma was the female astronaut in an alternate history in which manned space exploration continued to grow, leading to permanent settlement on Mars. She spent lots of time being photographed, being the smiling face of the space program, while her husband worked on the math and engineering of the launches. Now, she's an old woman, taking care of her failing and frail husband, her career behind her. Or so she thinks, before an offer that forces an impossible choice between space and staying with her husband for his final days. This is indeed the tear-jerker that it sounds like, but it's not as maudlin as it might sound. Kowal does an excellent job with Elma's characterization: she's no-nonsense, old enough to be confident in her opinions, and knows how to navigate through the world. The story is mixed with nostalgia and memories, including a reminder of just what Elma meant to others. It touches on heroism, symbolism, and the horrible choices around dying loved ones, but I thought it did so deftly and with grace. I was expecting the story to be too obvious, but I found I enjoyed the quotidian feel. It's not a story to read if you want to be surprised, but I loved the small touches. (9) "Opera Vita Aeterna" by Vox Day: Before the review, a note that I consider obligatory. The author of this story is an aggressively misogynistic white supremacist, well-known online for referring to black people as savages and arguing women should not be allowed to vote. To what extent you choose to take that into account when judging his fiction is up to you, but I don't think it should go unsaid. "Opera Vita Aeterna" is the story of a monastery in a typical fantasy world (at least as far as one can tell from this story; readers of Vox Day's fantasy series will probably know more background). At the start of the story, it gets an unexpected visit from an elf. Not just any elf, either, but one of the most powerful magicians of his society. He comes to the monastery out of curiousity about the god that the monks worship and stays for a project of illuminating their scriptures, while having theological debates with the abbot. This story is certainly not the offensive tirade that you might expect from its author. Its biggest problem is that nothing of substance happens in the story, either theologically or via more conventional action. It's a lot of description, a lot of talking, a lot of warmed-over Christian apologetics that dodges most of the hard problems, and a lot of assertions that the elf finds something of interest in this monastery. I can believe this could be the case, but Vox Day doesn't really show why. There is, at the end of the story, some actual drama, but I found it disappointing and pointless. It leads nowhere. The theology has the same problem: elves supposedly have no souls, which is should be the heart of a theological question or conflict Vox Day is constructing, but that conflict dies without any resolution. We know nothing more about the theology of this world at the end of the story than we do at the beginning. Some of the descriptions here aren't bad, and the atmosphere seems to want to develop into a story. But that development never happens, leaving the whole work feeling fundamentally pointless. (4) "The Truth of Fact, the Truth of Feelng" by Ted Chiang: This is another oddly-constructed story, although I think a bit more successful. It's a story in two interwoven parts. One is a fictional essay, told in a non-fiction style, about a man living in a future world with ubiquitous life recording and very efficient search software. Any part of one's life can be easily found and reviewed. The other is the story of a boy from a tribal culture during European colonialism. He learns to read and write, and from that a respect for written records, which come into conflict with the stories that the tribe elders tell about the past. The purpose of both of these stories is to question both the value and the implications of recording everything in a way that preserves and guarantees the facts instead of individual interpretations. The boy's story calls this into question; the narrator's story offers ambiguous support for its value and a deeper plea for giving people space to change. I found the style a bit difficult to get used to, since much of it did not feel like a story. But it grew on me as I read it, and the questions Chiang raises have stuck with me since. The problem of how and when to allow for change in others when we have perfect (or at least vastly improved) memory is both important and complicated, and this is one of the better presentations of the problem that I've seen. It's more of a think-y piece, and closer to non-fiction than a story, but I thought it was worth reading. (8) "The Waiting Stars" by Aliette de Bodard: I keep wanting to like de Bodard's space opera world of AIs and living ships, but it never quite works for me. I've read several stories set in this universe now, and it has some neat ideas, but I always struggle with the characters. This story at least doesn't have quite as much gruesome pregnancy as the previous ones (although there's still some). "The Waiting Stars" opens with a raid on a ship graveyard, an attempt to rescue and "reboot" an AI starship under the guidance of another Mind. This is intermixed with another story about a woman who was apparently rescued in childhood from birthing ship Minds and raised in a sort of foster institution. This feels like a flashback at first, but its interaction with the rest of the story is something more complicated. The conceptual trick de Bodard pulls here is thought-provoking, but once again I struggled to care about all of the characters. I also found the ending discouraging and unsatisfying, which didn't help. Someone who isn't me might really like this story, but it wasn't my thing. (6) Rating: 6 out of 10

20 December 2014

Gregor Herrmann: GDAC 2014/20

today seen on IRC: a maintainer was surprised & happy that their package had migrated to testing without having filed an unblock request. once again an example of the awesome work of the release team which pro-actively unblocked the package. a big thank you to the members of the release team!
this posting is part of GDAC (gregoa's debian advent calendar), a project to show the bright side of debian & why it's fun for me to contribute.

Dirk Eddelbuettel: digest 0.6.7

Release 0.6.7 of digest package is now on CRAN and in Debian. Jim Hester was at it again and added murmurHash. I cleaned up several sets of pedantic warnings in some of the source files, updated the test reference out, and that forms version 0.6.7. CRANberries provides the usual summary of changes to the previous version.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Rudy Godoy: Apache Phoenix for Cloudera CDH

Apache Phoenix is a relational database layer over HBase delivered as a client-embedded JDBC driver targeting low latency queries over HBase data. Apache Phoenix takes your SQL query, compiles it into a series of HBase scans, and orchestrates the running of those scans to produce regular JDBC result sets. What the above statement means for developers or data scientists is that you can talk SQL to your HBase cluster. Sounds good right? Setting up Phoenix on Cloudera CDH can be really frustrating and time-consuming. I wrapped-up references from across the web with my own findings to have both play nice. Building Apache Phoenix Because of dependency mismatch for the pre-built binaries, supporting Cloudera s CDH requires to build Phoenix using the versions that match the CDH deployment. The CDH version I used is CDH4.7.0. This guide applies for any version of CDH4+. Note: You can find CDH components version in the CDH Packaging and Tarball Information section for the Cloudera Release Guide . Current release information (CDH5.2.1) is available in this link. Preparing Phoenix build environment Phoenix can be built using maven or gradle. General instructions can be found in the Building Phoenix Project webpage. Before building Phoenix you need to have: Checkout correct Phoenix branch Phoenix has two major release versions: Clone the Phoenix git repository
git clone https://github.com/apache/phoenix.git
Work with the correct branch
git fetch origin
git checkout 3.2
Modify dependencies to match CDH Before building Phoenix, you will need to modify the dependencies to match the version of CDH you are trying to support. Edit phoenix/pom.xml and do the following changes: Add Cloudera s Maven repository
+  <repository>
+  <id>cloudera</id>
+  https://repository.cloudera.com/artifactory/cloudera-repos/
+  </repository>
Change component versions to match CDH s.
  
-  <hadoop-one.version>1.0.4</hadoop-one.version>
-  <hadoop-two.version>2.0.4-alpha</hadoop-two.version>
+  <hadoop-one.version>2.0.0-mr1-cdh4.7.0</hadoop-one.version>
+  <hadoop-two.version>2.0.0-cdh4.7.0</hadoop-two.version>
  <!-- Dependency versions -->
-  <hbase.version>0.94.19
+  <hbase.version>0.94.15-cdh4.7.0
  <commons-cli.version>1.2</commons-cli.version>
-  <hadoop.version>1.0.4
+  <hadoop.version>2.0.0-cdh4.7.0
  <pig.version>0.12.0</pig.version>
  <jackson.version>1.8.8</jackson.version>
  <antlr.version>3.5</antlr.version>
  <log4j.version>1.2.16</log4j.version>
  <slf4j-api.version>1.4.3.jar</slf4j-api.version>
  <slf4j-log4j.version>1.4.3</slf4j-log4j.version>
-  <protobuf-java.version>2.4.0</protobuf-java.version>
+  <protobuf-java.version>2.4.0a</protobuf-java.version>
  <commons-configuration.version>1.6</commons-configuration.version>
  <commons-io.version>2.1</commons-io.version>
  <commons-lang.version>2.5</commons-lang.version>
Change target version, only if you are building for Java 6. CDH4 is built for JRE 6.
  <artifactId>maven-compiler-plugin</artifactId>
  <version>3.0</version>
  <configuration>
-  <source>1.7</source>
-  <target>1.7</target>
+  <source>1.6</source>
+  <target>1.6</target>
  </configuration>
Phoenix building Once, you have made the changes you are set to build Phoenix. Our CDH4.7.0 cluster uses Hadoop 2, so make sure to activate the hadoop2 profile.
mvn package -DskipTests -Dhadoop.profile=2
If everything goes well, you should see the following result:
[INFO] ------------------------------------------------------------------------
[INFO] Reactor Summary:
[INFO]
[INFO] Apache Phoenix .................................... SUCCESS [2.729s]
[INFO] Phoenix Hadoop Compatibility ...................... SUCCESS [0.882s]
[INFO] Phoenix Core ...................................... SUCCESS [24.040s]
[INFO] Phoenix - Flume ................................... SUCCESS [1.679s]
[INFO] Phoenix - Pig ..................................... SUCCESS [1.741s]
[INFO] Phoenix Hadoop2 Compatibility ..................... SUCCESS [0.200s]
[INFO] Phoenix Assembly .................................. SUCCESS [30.176s]
[INFO] ------------------------------------------------------------------------
[INFO] BUILD SUCCESS
[INFO] ------------------------------------------------------------------------
[INFO] Total time: 1:02.186s
[INFO] Finished at: Mon Dec 15 13:18:48 PET 2014
[INFO] Final Memory: 45M/1330M
[INFO] ------------------------------------------------------------------------
Phoenix Server component deployment Since Phoenix is a JDBC layer on top of HBase a server component has to be deployed on every HBase node. The goal is to have Phoenix server component added to HBase classpath. You can achieve this goal either by copying the server component directly to HBase s lib directory, or copy the component to an alternative path then modify HBase classpath definition. For the first approach, do:
cp phoenix-assembly/target/phoenix-3.2.3-SNAPSHOT-server.jar /opt/cloudera/parcels/CDH/lib/hbase/lib/
Note: In this case CDH is a synlink to the current active CDH version. For the second approach, do:
cp phoenix-assembly/target/phoenix-3.2.3-SNAPSHOT-server.jar /opt/phoenix/
Then add the following line to /etc/hbase/conf/hbase-env.sh
/etc/hbase/conf/hbase-env.sh
export HBASE_CLASSPATH_PREFIX=/opt/phoenix/phoenix-3.2.3-SNAPSHOT-server.jar
Wether you ve used any of the methods, you have to restart HBase. If you are using Cloudera Manager, restart the HBase service. To validate that Phoenix is on HBase class path, do:
sudo -u hbase hbase classpath   tr ':' '\n'   grep phoenix
Phoenix server validation Phoenix provides a set of client tools that you can use to validate the server component functioning. However, since we are supporting CDH4.7.0 we ll need to make few changes to such utilities so they use the correct dependencies. phoenix/bin/sqlline.py: sqlline.py is a wrapper for the JDBC client, it provides a SQL console interface to HBase through Phoenix.
index f48e527..bf06148 100755
--- a/bin/sqlline.py
+++ b/bin/sqlline.py
@@ -53,7 +53,8 @@ colorSetting = "true"
 if os.name == 'nt':
  colorSetting = "false"
-java_cmd = 'java -cp "' + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
+extrajars="/opt/cloudera/parcels/CDH/lib/hadoop/lib/commons-collections-3.2.1.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-auth-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-common-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcerls/CDH/lib/oozie/libserver/hbase-0.94.15-cdh4.7.0.jar"
+java_cmd = 'java -cp ".' + os.pathsep + extrajars + os.pathsep + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
  '" -Dlog4j.configuration=file:' + \
  os.path.join(phoenix_utils.current_dir, "log4j.properties") + \
  " sqlline.SqlLine -d org.apache.phoenix.jdbc.PhoenixDriver \
phoenix/bin/psql.py: psql.py is a wrapper tool that can be used to create and populate HBase tables.
index 34a95df..b61fde4 100755
--- a/bin/psql.py
+++ b/bin/psql.py
@@ -34,7 +34,8 @@ else:
 # HBase configuration folder path (where hbase-site.xml reside) for
 # HBase/Phoenix client side property override
-java_cmd = 'java -cp "' + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
+extrajars="/opt/cloudera/parcels/CDH/lib/hadoop/lib/commons-collections-3.2.1.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-auth-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcels/CDH/lib/hadoop/hadoop-common-2.0.0-cdh4.7.0.jar:/opt/cloudera/parcerls/CDH/lib/oozie/libserver/hbase-0.94.15-cdh4.7.0.jar"
+java_cmd = 'java -cp ".' + os.pathsep + extrajars + os.pathsep + phoenix_utils.hbase_conf_path + os.pathsep + phoenix_utils.phoenix_client_jar + \
  '" -Dlog4j.configuration=file:' + \
  os.path.join(phoenix_utils.current_dir, "log4j.properties") + \
  " org.apache.phoenix.util.PhoenixRuntime " + args
After you have done such changes you can test connectivity by issuing the following commands:
./bin/sqlline.py zookeeper.local
Setting property: [isolation, TRANSACTION_READ_COMMITTED]
issuing: !connect jdbc:phoenix:zookeeper.local none none org.apache.phoenix.jdbc.PhoenixDriver
Connecting to jdbc:phoenix:zookeeper.local
14/12/16 19:26:10 WARN conf.Configuration: dfs.df.interval is deprecated. Instead, use fs.df.interval
14/12/16 19:26:10 WARN conf.Configuration: hadoop.native.lib is deprecated. Instead, use io.native.lib.available
14/12/16 19:26:10 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
14/12/16 19:26:10 WARN conf.Configuration: topology.script.number.args is deprecated. Instead, use net.topology.script.number.args
14/12/16 19:26:10 WARN conf.Configuration: dfs.umaskmode is deprecated. Instead, use fs.permissions.umask-mode
14/12/16 19:26:10 WARN conf.Configuration: topology.node.switch.mapping.impl is deprecated. Instead, use net.topology.node.switch.mapping.impl
14/12/16 19:26:11 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
14/12/16 19:26:11 WARN util.NativeCodeLoader: Unable to load native-hadoop library for your platform... using builtin-java classes where applicable
14/12/16 19:26:12 WARN conf.Configuration: fs.default.name is deprecated. Instead, use fs.defaultFS
Connected to: Phoenix (version 3.2)
Driver: PhoenixEmbeddedDriver (version 3.2)
Autocommit status: true
Transaction isolation: TRANSACTION_READ_COMMITTED
Building list of tables and columns for tab-completion (set fastconnect to true to skip)...
77/77 (100%) Done
Done
sqlline version 1.1.2
0: jdbc:phoenix:zookeeper.local>
Then, you can either issue SQL-commands or Phoenix-commands.
0: jdbc:phoenix:zookeeper.local> !tables
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+
  TABLE_CAT    TABLE_SCHEM    TABLE_NAME    TABLE_TYPE  
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+
  null    SYSTEM    CATALOG    SYSTEM TABLE   
  null    SYSTEM    SEQUENCE    SYSTEM TABLE   
  null    SYSTEM    STATS    SYSTEM TABLE   
  null    null    STOCK_SYMBOL    TABLE   
  null    null    WEB_STAT    TABLE   
+------------------------------------------+------------------------------------------+------------------------------------------+---------------------------+

Next.

Previous.