Search Results: "cas"

6 March 2015

Dirk Eddelbuettel: Rcpp 0.11.5

The new release 0.11.5 of Rcpp just reached the CRAN network for GNU R, and a Debian package has also been be uploaded. Rcpp has become the most popular way of enhancing GNU R with C++ code. As of today, 345 packages on CRAN depend on Rcpp for making analyses go faster and further; BioConductor adds another 41 packages, and casual searches on GitHub suggests dozens mores. This release continues the 0.11.* release cycle, adding another large number of small bug fixes, polishes and enhancements. Since the previous release in January, we incorporated a number of pull requests and changes from several contributors. This time, JJ deserves a special mention as he is responsible for a metric ton of the changes listed below, making Rcpp Attributes even more awesome. As always, you can follow the development via the GitHub repo and particularly the Issue tickets and Pull Requests. And any discussions, questions, ... regarding Rcpp are always welcome at the rcpp-devel mailing list. See below for a detailed list of changes extracted from the NEWS file.
Changes in Rcpp version 0.11.5 (2015-03-04)
  • Changes in Rcpp API:
    • An error handler for tinyformat was defined to prevent the assert() macro from spilling.
    • The Rcpp::warning function was added as a wrapper for Rf_warning.
    • The XPtr class was extended with new checked_get and release functions as well as improved behavior (throw an exception rather than crash) when a NULL external pointer is dereferenced.
    • R code is evaluated within an R_toplevelExec block to prevent user interrupts from bypassing C++ destructors on the stack.
    • The Rcpp::Environment constructor can now use a supplied parent environment.
    • The Rcpp::Function constructor can now use a supplied environment or namespace.
    • The attributes_hidden macro from R is used to shield internal functions; the R_ext/Visibility.h header is now included as well.
    • A Rcpp::print function was added as a wrapper around Rf_PrintValue.
  • Changes in Rcpp Attributes:
    • The pkg_types.h file is now included in RcppExports.cpp if it is present in either the inst/include or src.
    • sourceCpp was modified to allow includes of local files (e.g. #include "foo.hpp"). Implementation files (.cc; .cpp) corresponding to local includes are also automatically built if they exist.
    • The generated attributes code was simplified with respect to RNGScope and now uses RObject and its destructor rather than SEXP protect/unprotect.
    • Support addition of the rng parameter in Rcpp::export to suppress the otherwise automatic inclusion of RNGScope in generated code.
    • Attributes code was made more robust and can e.g. no longer recurse.
    • Version 3.2 of the Rtools is now correctly detected as well.
    • Allow 'R' to come immediately after '***' for defining embedded R code chunks in sourceCpp.
    • The attributes vignette has been updated with documentation on new features added over the past several releases.
  • Changes in Rcpp tests:
    • On Travis CI, all build dependencies are installed as binary .deb packages resulting in faster tests.
  • Thanks to CRANberries, you can also look at a diff to the previous release As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

    This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

    5 March 2015

    Ian Wienand: On VMware and GPL

    I do not believe any of the current reporting around the announced case has accurately described the issue; which I see as a much more subtle question of GPL use across API layers. Of course I don't know what the real issue is, because the case is sealed and I have no inside knowledge. I do have some knowledge of the vmkernel, however, and what I read does not match with what I know. An overview of ESXi is shown below overview of vmkernel and vmkapi There is no question that ESXi uses a lot of Linux kernel code and drivers. The question as I see it is more around the interface. The vmkernel provides a well-described API known as vmkapi. You can write drivers directly to this API; indeed some do. You can download a SDK. A lot of Linux code has been extracted into vmkLinux; this is a shim between Linux drivers and the vmkapi interface. The intent here is to provide an environment where almost unmodified Linux drivers can interface to the proprietary vmkernel. This means vendors don't have to write two drivers, they can re-use their Linux ones. Of course, large parts of various Linux sub-systems' API are embedded in here. But the intent is that this code is modified to communicate to the vmkernel via the exposed vmkapi layer. It is conceivable that you could write a vmkWindows or vmkOpenBSD and essentially provide a shim-wrapper for drivers from other operating systems too. vmkLinux and all the drivers are GPL, and released as such. I do not think there could be any argument there. But they interface to vmkapi which, as stated, is an available API but part of the proprietary kernel. So, as I see it, this is a much more subtle question than "did VMware copy-paste a bunch of Linux code into their kernel". It goes to where the GPL crosses API boundaries and what is considered a derived work. If nothing else, this enforcement increasing clarity around that point would be good for everyone I think.

    4 March 2015

    Zlatan Todori : Interviews with FLOSS developers: Paul Wise

    After starting with Joey Hess, we continue with Paul Wise. What makes his star to shine are many things such as being a DSA (Debian System Administrator), a helpful hand on mailings list, encouraging people to join Debian teams but most of all - he has encyclopedia knowledge on Debian as a whole which he gladly shares with anyone who asks (very fast response on IRC channels). It is almost impossible for any single person to count all Debian teams, work and places - to know most of those things, you can image the vast knowledge which Paul has. The legend says that his brain has better and faster search engine algorithm on Debian related queries than all other engines combined. So lets see what he has to share with world. me: Who are you? pabs: Paul Wise (pabs) and I have to say that I'm no-where near as knowledgeable as your intro suggests. me: How did you start programming? pabs: Messing around with fractals and graphics things in MS BASIC. me: How would you now advise others to start programming? pabs: Pick an issue in a tool you use, investigate how the tool works and how you can change it, fix that and contribute the change back to the project that created that tool. In the process you will learn skills, interact with the community and contribute to the project. me: Setup of your development machine? pabs: Lenovo Thinkpad with external monitor, Debian testing and some tweaks me What is your preferable language (for hacking)? Why? How do you compare it to other languages? pabs: I currently prefer Python for its readability. It still has some rough edges though the documentation covers them fairly well. I generally pick up new languages when working on projects written in them. Haskell is next on the horizon due to Nikki and the Robots. me: Describe your current most memorable situation as software developer/hacker? pabs: I had a great time creating fractals in BASIC, learning about the Mandelbrot set, L-systems and more. My days and nights of hacking on frhed (a GPLed hex editor for Windows) to help me cheat at Civilisation were pretty memorable. frhed led to my work on reverse engineering the CHM file format (a documentation format for Windows programs). A stand-out moment during my time with Debian was hacking on the derivates census patch generation code during the Debian UK BBQ weekend, surrounded by geeks playing Portal, cooking things, hacking on Debian and generally having a good time (thanks Steve!). me: Some memorable moments from Debian conferences? pabs: There are so many; meeting Debian folks, playing Mao once and then never again, late night games of werewolf, both delectably delicious and hideously disgusting cheeses, fried insects, day trips to beautiful landscapes, inspiring keynotes, exciting BoFs, secret IRC channels for planning surprise birthday parties, blue hair, wet air, blocks of fried cheese, a vast quantity of icecream, pants, geeks in the surf, volcanoes, hiking, a wonderful view, a uni-cycling stormtrooper & more. me: How do you see future of Debian development? pabs: I hope we will continue to exist and uphold our principles for the foreseeable future. I don't have any crystal balls though. me: You recently became member of Debian DSA - what is that like, what roles do you have and what tasks are in front of DSA? pabs: We wrote a bit of text about that for DPN recently. me: You have large knowledge on Debian and you share it with anyone who wants to know more. What motivates you to do so? pabs: I want the operating system I personally rely on to exist into the future, helping folks work on and join Debian can help with that. me: Why should developers and users join Debian community? What makes Debian a great and happy place? pabs: Every Debian contributor has different reasons for joining the community. Personally the Social Contract, the DFSG and the spirit and culture behind them are the main reason to be involved. I also like our many efforts towards technical excellence and correctness. Of course I've made a number of good friends over the years, especially as a result of attending DebConf every year since 2007. me: You are member of Debian publicity team which writes Debian news - do you need more people to join that team and how can they start? pabs: Since there is an infinite amount of work to do, pretty much every part of Debian always needs help, that includes the publicity team. We published a post about ways to help here. me: If someone wants to contribute to Debian in terms of packaging, can they do it anonymously (for example over Tor network, does Debian have .onion address)? pabs: Due to Debian's penchant for transparency it is harder but there are definitely package maintainers who have built up a reputation for good work under a pseudonym over the years and become Debian contributors as a result. I'm not aware of completely anonymous package maintainers but there are definitely people who file bugs using one-off pseudonyms, which is almost the same thing as anonymously. There are definitely Debian contributors and members who use Tor while contributing to Debian. In fact, as Debian is very highly dependent on OpenPGP and the best practices for OpenPGP include refreshing your keyring slowly over Tor, so probably quite a number of Debian contributors use Tor. As far as I know Debian itself does not run any Tor relays or onion services. me: What are places that non-packaging developers and people could join and help spread Debian even more? pabs: There are many ways to help Debian, including non-technical ones. Unfortunately our web page about helping Debian isn't quite up-to-date with all of them but a few more are to volunteer at DebConf, helo with artwork requests, speak about Debian at events or even come up with ideas for projects. Whatever skills you have, Debian can probably make use of them. If you aren't sure where to start, jump on the debian-mentors mailing list or IRC channel and we can probably guide you to the right place within Debian. Don't worry about not being skilled enough, everyone starts somewhere. me: How do you see Debian will manage webapps? pabs: Personally I prefer locally installed software, standard data formats and standard data transfer protocols to the wild webapps world but I understand they are becoming very popular to produce and use due to the ubiquity of the web browser platform. Antonio Terceiro is mentoring a project for this year's newcomer mentorship programs (outreachy/gsoc) that aims to improve support for installing web apps on Debian installations. I hope it succeeds as it could help make Debian more popular on servers and home servers in particular. me: How would you advise Debian (and other FLOSS users) to setup their machine in terms of security and anonymity? pabs: All technology has upsides and downsides. I would advise anyone to analyse their situation and protect themselves accordingly. For example if you have a bad memory, full disk encryption, which is based on pass-phrases might lead to data loss and physical security might be a better choice for protecting your data. The right choices around technology are very much a personal thing. me: Is it better to setup xmonad (because it is Haskell based WM) with small dependency chain or GNOME (because it is getting sandboxed apps) in term of security and privacy implications? pabs: Again, the right choices around technology are very much a personal thing. Due to the design of X11, both of these are approximately equivalent from a window-manager security properties point of view, that is to say, pretty bad. Wayland is one of the possible X11 successors and offers much better security properties. GNOME folks are working on switching to Wayland. Ultimately though it comes down to how each person uses their window manager and which software they run under it. me: Should Debian join Tor project as distro that installs Tor relays by default - should it offer that as option in installer in Debian 9? pabs: Running a Tor relay requires a reasonably fast and reliable Internet connection and should be a conscious decision on behalf of the sysadmin for a computer so Debian probably shouldn't install them by default. If tasksel gets support for installing tasks from Debian Pure Blends, then we could add a Tor relay task to the Debian Sanctuary Pure Blend. me: Have you ever considered joining initiatives such as FreedomBox? pabs: I was quite moved by Eben Moglen's talk at DebConf10 in New York and the resulting BoF. It seemed like a very ambitious project but I didn't really have the knowledge, skills or time to contribute yet. me: Are you a gamer? Valve Steam games are offered for free to Debian Developers - do you use steam and play Valve games? Your thoughts on Steam and non-free Linux gaming? pabs: I play computer games occasionally, all from Debian main or ones that I'm packaging. 0ad is my current go-to for a bit of gaming. I don't have any experience with Steam or non-free games on Linux. me: Is there something you would change in FLOSS ecosystem? pabs: Various folks have highlighted new and ongoing challenges for the FLOSS ecosystem in various places in recent years. Something that I would like to highlight that does not get talked about enough is the choices we make around our digital artefacts. This is the discussion around "preferred form for modification" or "source". The "source" for a particular digital artefact is a deliberate choice on behalf of the authors. Often generated files are distributed alongside the "source" without any instructions for reproducing the generated files from the "source". It sometimes happens that FLOSS contributors forget to distriute what they have chosen as "source", instead just distributing the generated files. This is a fairly well known issue but still happens. What isn't thought about quite as much is that the choice of "source" has consequences for future development possibilities of that "source". Some forms of "source" are more expressive than others, can be modified in a wider variety of ways and are better choices in general. Sometimes the consequences of choosing less expressive forms are mild and other times they are quite important. I hope more people will start to think about these choices. Some examples where, in my opinion, various people could have made better choices are listed in the mail I sent to the games team list last year. Another thing I would like to highlight is the work that organisations like Software Freedom Conservancy and Software in the Public Interest do to protect, defend, promote and support FLOSS projects. It is very important work that needs our interest and support. me: Can FLOSS world create great alternatives to Viber, Dropbox, WhatsUp, Facebook, Skype and other non-free services? pabs: I think that the FLOSS world has already created alternatives to all of those. The success of non-free services doesn't take these alternatives away but it does mean some of them are less useful because some of them are the kind of tools that become more useful with a larger amount of people using them. I don't know what it would take for the FLOSS alternatives to achieve similar success as network effects are hard to overcome. Hopefully mako is right and the network effects are overrated. me: Your thoughts and compare Cloud, IaaS, PaaS, SaaSS? To what should the FLOSS world pay more attention and energy? pabs: Initially I dismissed these as buzzwords and a threat to Free Software. These days I view them as potential opportunities for Free Software. Cloud-related technologies such as OpenStack and virtual machines can make private compute farm hardware more flexible and useful to their owners. IaaS providers can be used to run Debian more simply and cheaply and therefore bring Debian to more people than possible with hardware. PaaS providers can be used to run Free Software services. SaaSS can be based entirely on Free Software and respect users. Of course, just like running Free Software on hardware (proprietary or libre), cloud technology, IaaS, PaaS and SaaSS all come with downsides. The FLOSS world should aim to inform users of our software of these downsides. For example, the Debian installer could note that it is running on Intel CPUs with a proprietary BIOS and various proprietary software running, that it is running on a mobile phone with a locked bootloader, that it is running in a Xen VM on machines owned by Amazon. Free Software services could note they are running on Google App Engine etc. Free Software web browsers, chat clients etc could note when they are connecting to proprietary network services. All these notes could inform users about the downsides present in the particular situation encountered. There is also much work to be done making it easier to run Free Software on top of or use Free Software to connect to all manner of platforms from lowRISC to UEFI to VMware to Google App Engine to GitHub to Facebook. The more places Free Software can reach, the more people will be exposed to the philosophy behind it and the more potential there is for folks to join the community. While co-option of the FLOSS world is a dangerous certainty, co-option of proprietary platforms might be able to expand the reach of the philosophy behind Free Software. me: Your thoughts on Purism (the open hardware laptop initiative that got recently funded on CrowdSupply)? pabs: I don't know enough about that to comment but personally I am more interested in a laptop based on a libre CPU architecture. The RISC-V ISA and the lowRISC project seems to be one of the more promising possibilities at this point in time. me: Did you watch Citizenfour - comments on it? pabs: I've seen the trailer and look forward to watching it at some point, I read there might be a screening at DebConf15.

    2 March 2015

    Gergely Nagy: Distributed Version Control from another angle

    I've been using distributed version control systems for a good while, started with TLA back in 2001, when it was still a bunch of shell scripts and was simply called "Arch". I jumped the Git bandwagon quite early too, sometime around May 2005, I believe, though it was only something to test and play with on the side: I didn't migrate my projects over yet. There are many reasons why I preferred these over the systems I used in the past (RCS and CVS; never considered Subversion an option), most of those reasons have been discussed at length over the years, and there's no reason to do so again.The reason for this post, is because I read a blog post about why Git and the other DVCSes fall short. There are a number of things in that article that I find... well, lets just say misinformed. I'll try to explain why.But here's the rub
    I have wanted to have the full history while offline a grand total of maybe about six times. And this is merely going down over time as bandwidth gets ever more readily available. If you work as a field tech, or on a space station, or in a submarine or something, then okay, sure, this is a huge feature for you. But for the rest of us, I am going to assert that this is not the use case you need to optimize for when choosing a VCS.
    I'm neither a field tech, nor do I work on a space station or a submarine. Yet, having the full history available locally has been crucial for my work for at least the past six years. Initially, I worked offline primarily, because my internet connection was incredibly limited (slow, expensive and unreliable), yet, I had a habit of committing small changes often. I needed a full clone to work effectively, and conveniently. Throw-away branches and all that - I needed them local, I didn't have the resources to push them online every time I wanted a merge.But now that I have fast and reliable internet, why do I need the full history on my own computer? I do, because I do much more research than I do development. The vast majority of my work between 2010 and 2012 involved reading histories, cherry picking and so on. About six hours a day, I was reading the past. Having the full history locally is a terrific aid when your job involves digging through it.Between 2013 and 2014, the amount of history reading dropped significantly, but I still worked with long-lived branches a lot, branches where history matters, where having easy and fast access to them is indispensable. I still had to find changes based on content (not commit message, branch, date or anything - content) on a daily basis. Hitting the network for each and every search would have wasted not only tremendous bandwidth and processing power on the server, but also a significant amount of time.If you do more maintenance and research, or follow a good number of branches (or forks), with the intent to merge and cherry-pick actively from them, having all the histories available locally is a huge improvement. I'm happy to pay the price of "wasting" disk space to have this available. I couldn't work otherwise. Without full, local history, the things I did for syslog-ng would not have been possible. No maintenance, none of the features I implemented, none of the fixes I found. Why? Because I rely on the project's history to aid me in learning the whys, not just the hows.Thank you, but - perhaps unlike others - I like to learn from the past, and prefer doing it efficiently.Say goodbye to blobs (or your sanity (and sometimes both))
    You know what kind of external binary asset management system works really well? Subversion. Turns out it works tolerably for source control, too. Maybe you should take a look at it.
    Sure, some systems are better at managing binary assets. Git - and usually DVCSes - are terrible at it. There's nothing stopping anyone from using two systems: one for source, another for data. Mind you, I am extremely happy with git-annex. I disagree with Subversion being tolerable for source control. I'd turn this assertion around instead: You know what kind of system works really well for source code? Git. Turns out it works tolerably as an external binary assest management system, too. Maybe you should take a look at it.But then, I rarely need to work with blobs, so I'm likely not the best person to disagree here.Say goodbye to sane version synchronizationOkay, so this part of the article is ill-titled, I believe. Large repositories and version synchronisation are two different, not necessarily related topic. Granted DVCSes may not be the best fit for large repositories, but neither are centralised version control systems, based on my past experience. I had the misfortune of working with a roughly 3-4Gb (checked out) project, with extensive history, managed with a centralised version control system, without local history. It was terrible (and blame was so slow and expensive that we were told never to use it, because it crashed the server). While the system allowed us to have a reasonable overview over the whole project, but it utterly failed at allowing us to work at the component level. How do I see which version of component X we had in project release A? Or the version of component Y we had two weeks ago? Or what if we have component M, made up from components J and K, and belonging to component Z? Good luck managing that in a single repository.With TLA, we had configs, which were a bit cumbersome to use, but captured most of the essential parts of managing component bundling and hierarchical versioning far better than any other solution I've seen so far. I've yet to find an acceptable solution, but I'm convinced it will not have anything to do with centralised systems. You can't capture the delicate relations there.Say what again, I dare you, I double dare you
    All of the above might be almost tolerable if DVCSes were easier to use than traditional SCMs, but they aren t.
    I'm sorry, but have you tried managing a decently sized project, with a large history, built from multiple components with a traditional SCM? Because that is a colossal pain in the backside.Does Git's UI suck? Yes. But so did CVS's and Subversion's. If you rely on the command-line tools, you're going to feel the pain. That is why you use the IDE integration you surely have, which makes the most common tasks a breeze. That may sound like a git-apology, but remember, we did the same with every other version control system, because smart people prefer integration, and want the computer to work for them.
    And yet, when someone dares to say that Git is harder than other SCMs, they inevitably get yelled at, in what I can only assume is a combination of Stockholm syndrome and groupthink run amok by overdosing on five-hour energy buckets.
    If you feel the need to understand the innards of Git - then yes, it is harder than traditional SCMs. It is distributed, and different than what you're used to. If you do not have prior knowledge though, the difference in learning the internal working of Git and - say - Subversion all that different. And if you do not care how it works down below (and I dare say, a lot of developers should not, and do not care), then there is nothing to learn, apart from your IDE integration, which ain't different from a traditional SCM's.Mind you, I found it both interesting, and beneficial to learn Git's inner workings. Not only because it allowed me to make better use of my VCS, but because it taught me a bunch of things I could make use of elsewhere. I learned nothing from traditional SCMs.Do you hear the people sing, singing the song of angry men
    There is one last major argument that I hear all the time about why DVCSes are superior, which is that they somehow enable more democratic code development.
    The reason Git and other tools make code contribution easier is not GitHub pull requests (although, for drive-by contributions those are pretty useful too). The reason they make contribution easier is because you have your own copy of the full history. You can create your own branches easily, you can work with it as if you were the owner. For one-off contributions, that is no real advantage, I'll give you that. It takes more effort to fork & do a PR on GitHub, than to send a patch, I'll also agree with that.But once you start working with a project for more than a few patches, when you want to work with its history too, once you have long-lived branches, the local copy quickly becomes a great asset. Once you want to submit more than a few changes, you won't have to repeat a all steps. And not only that: since you have the full history, merging upstream changes (or just cherry picking from them), rebasing your work, and many other tasks become simpler.That is what it buys you, that is why it makes contribution easier. GitHub pull requests are an icing over the cake at best (and there are a good number of cases where the icing is completely unnecessary, because it doesn't go well with the cake).In closingIn closing, I'd like to highlight that different projects have different requirements. For example, I understand why Facebook, Google and a number of others use a single, huge repository. I happen to hate that setup, and would find working in such an environment horrible. But luckily, I don't work for those companies, and they don't listen to me, either, so everyone's happy. That does not mean I would go out and tell them they're wrong to use such a centralised, single-repository setup. For their use, in their situation, for their requirements, that may be the better option. For mine, not so much.In the end, what we need to realise is that there is no single tool that will fit all needs. There are tasks where Git is a terrible choice, but that does not make it terrible for all cases. Similarly, there are cases where Subversion is superior (I assume - I didn't have the misfortune of meeting with such a case).Instead of bashing the DVCS world, and assuming the Big Company use cases are all that matter, and that everyone uses the tools the same way, accept that some use it to achieve things you didn't think of, jobs you didn't consider.

    28 February 2015

    Ben Hutchings: Debian LTS work, February 2015

    This was my third month working on Debian LTS, and the first where I actually uploaded packages. I also worked on userland packages for the first time. In the middle of February I finished and uploaded a security update for the kernel package (linux-2.6 version 2.6.32-48squeeze11, DLA 155-1). I decided not to include the fix for CVE-2014-9419 and the large FPU/MMX/SSE/AVX state management changes it depends on, as they don't seem to be worth the risk. The old patch system used in linux-2.6 in squeeze still frustrates me, but I committed a script in the kernel subversion repository to simplify adding patches to it. This might be useful to any other LTS team members working on it. In the past week I uploaded security updates for cups (version 1.4.4-7+squeeze7, DLA 159-1) and sudo (1.7.4p4-2.squeeze.5, DLA 160-1). My work on the cups package was slowed down by its reliance on dpatch, which thankfully has been replaced in later versions. sudo is a more modern quilt/debhelper package, but upstream has an odd way of building manual pages. In the version used in squeeze the master format is Perl POD, while in wheezy it's mandoc, but in both cases the upstream source includes pre-generated manual pages and doesn't rebuild them by default. debian/rules is supposed to fix this but doesn't (#779363), so I had to regenerate 'by hand' and fold the changes into the respective patches. Finally, I started work on addressing the many remaining security issues in eglibc. Most of the patches applied to wheezy were usable with minimal adjustment, but I didn't have time left to perform any meaningful testing. I intend to upload what I've done to people.debian.org for testing by interested parties and then make an upload early in March (or let someone else on the LTS or glibc team do so). Update: I sent mail about the incomplete eglibc update to the debian-lts list.

    Zlatan Todori : Interviews with FLOSS developers: Joey Hess

    Edit: Now translated to Chinese. Thanks zhang wei! There is really hardly a better way to open a series of interviewing with developers behind Free Libre Open Source Software project, then with incredible mind such as Joey Hess. To write his contributions to Free software ecosystem, especially in Debian, would be a book by itself. His impact exceeds even his projects - people literally follow his blog posts to see what he is doing and how is he living. A hacker from cabin. If you really need to have a picture of true hacker, then Joey is the one. As this isn't a book I will just mention few projects that he has been behind - git-annex, ikiwiki, etckeeper, debian installer, parts of dpkg, debhelper, devscripts, taskel. So without further waiting here it is. Picture of Joey Hess me: Who are you? joeyh: I'm Joey -- https://joeyh.name/ me: How did you start programming? joeyh: Atari 130XE which came with BASIC and a boring word processor and not much else. No other friends had one, so the only way to get software was to type in demo programs from manual and then begin to change and write my own. So, the easy way to learn. Also some Logo in school. me: How would you now advise others to start programming? joeyh: Difficult question, it seems much harder to get an intimate understanding of things than when I started, and much harder to be motivated to program when there's so much stuff easily available. Maybe simple bare-metal systems like Arduino coupled with real-world interaction are the answer. I've recently been mentoring my nephew who is learning python and Python the Hard Way has gotten him far impressively fast. me: Setup of your development machine? joeyh: Lenovo laptop de-spywared with Debian unstable, xmonad, xfce, vim. me: Your thoughts on Purism (the open hardware laptop initiative that got recently funded on CrowdSupply)? joeyh: I don't know much about that one, but it seems that consumer level hardware has gotten so low quality, and so closed and untrustworthy that it makes sense to either build alternatives that are open, or pick out, as a community, the stuff we can adapt to our needs and concentrate on it. Several projects are trying, I hope they succeed. me: How do you see future of Debian development? joeyh: Well, I've mostly stopped worrying about it. If you look back at my presentations at the past 2 or 3 DebConfs, you'll find my best thoughts on the matter. me: You retired as Debian developer - do you intend sometime soon to come back and/or do you plan to join some other communities? joeyh: It would be glorious to come back, wouldn't it? But I don't think I will. Can't step in the same river twice, and all. Instead, Debian will probably have to put up with me as an annoying upstream author who doesn't ship tarballs, but does ship debian/ directories, and as a bug reporter who enjoys reporting amusing bugs like -0 NaN. I seem to have more time to spend in other online communities since I left Debian, but in a more diffuse way. Maybe that's just what it's like, to be involved in Free Software but not in the embrace of a big project like Debian. me: Some memorable moments from Debian conferences? joeyh: There are so many! Picnicing on berries and tamales at the Portland farmer's market right outside the venue; rainbows and bonfire in Switzerland after crazy busy days; impromptu pipe organ repair in a weird night venue in Edinburgh; walking through Porto Alegre at night with Ian Murdock and how humble he was about what he'd started; hacking all night in Spain; failing to sleep through midnight sun and incessent partying Finland; hanging out in the hotel lobby in Atlanta where we designed Build-Depends. me: Are you a gamer? Valve Steam games are offered for free to Debian Developers - do you use steam and play Valve games? joeyh: I've played through Half Life and Portal, but nethack has claimed more of my time. I mostly enjoy short, indie games, or games that tell us something new about the medium of games, A recent favorite was A Dark Room. But really, I have more pure fun playing real world Tabletop games with friends, like Carcassanne Discovery and Hive. In March, I am going to try to write a roguelike game in one week, in Haskell, for the Seven Day Roguelike Challenge and I'll be blogging about my progress daily. me: You are nowdays a Haskell hacker (git-annex) - what would you like to say about this language and how does it compare to Python, C, JavaScript, Ruby and Perl? joeyh: Not just git-annex; all my current projects are written in Haskell. I think it's amazing how much we expect programmers to keep in their heads while writing code. Is that buffer going to overflow? Is changing the value of that global variable going to break some other part of the code? Is that input sanitized yet? Did that interface change? Haskell solves some of these outright, but more, it makes you start noticing this kind of pervasive issue, and it provides ways to completely eliminate a class of problems from your code. For example http://joeyh.name/blog/entry/making_propellor_safer_with_GADTs_and_type_families/. The class of bugs I avoided there had never affected my code even once, but it was still worth preventing that whole class of bugs, so I don't have to worry about them ever again. me: Would you suggest Haskell as first language to learn especially for those that have an itch for mathematics? joeyh: I think that can work well. Or it can go other the way -- I had an affinity to mathematics when I was young, but it got knocked out of me in the way that happens to many people, and languages like perl and C don't do much to make you want to learn more about higher-order math. I've been picking up a bit more here and there via Haskell. me: How do you compare your productivity in Haskell compared to your Perl days? joeyh: It's very different; I'm a very different programmer now. I probably would bang out quick hacks more quickly when I was writing Perl. But, they tended to stay quick hacks. Now, I might take a little longer to get there, but the code seems a lot more solid, while also being more malleable to turn into larger or different programs. I'm also a lot more drawn toward writing software libraries. me: Can you describe your philosophy of life (you live in cabin, in forest, using a lot of solar power - many people are intrigued (including myself) what drives you towards that kind of life and how does it impact your overall quality of life and happiness. Looking the todays modern predator capitalistic society, in which you could easily earn more then $10.000 a month, you seem to be an anarchist and very humble human)? joeyh: I want to build worthwhile things that might last. Which is super hard in the world of software, both because it's hard to think far ahead at all, and because most jobs don't emphasize that kind of real value. I've been lucky and bootstrapped up to a point where I've been able to work full time on free software for years, and I'm willing to forgo a lot to continue that. Living in the woods without modern conveniences is great, because it's quiet and you can think as much as you like; the internet is just as close as it is anywhere else (maybe a bit slower); and when you've spent too much time quietly thinking you'll need to go chop wood, or haul water, or jump in the river to cool off, depending on the season. (Humble? Like most programmers, I am internally a flaming tower of ego...)
    Vote on Hacker News

    Gunnar Wolf: Welcome to the world, little ones!

    Welcome to the world, little ones!
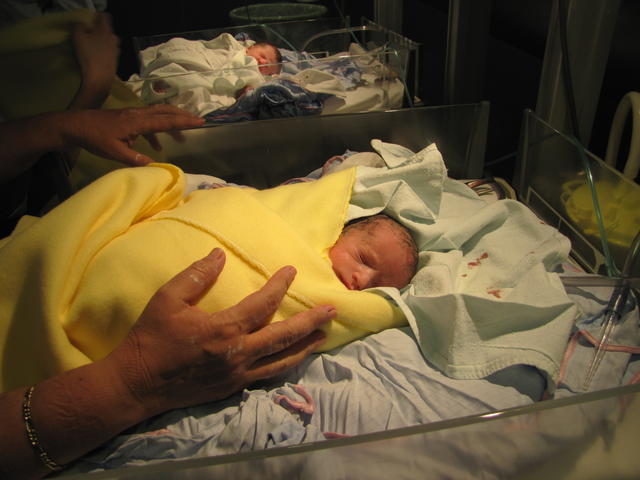
    Welcome little babies! Yesterday night, we entered the hospital. Nervous, heavy, and... Well, would we ever be ready? As ready as we could. A couple of hours later, Alan and Elena Wolf Daichman became individuals on their own right. As is often the case in the case of twins, they were brought to this world after a relatively short preparation (34 weeks, that's about 7.5 months). At 1.820 and 1.980Kg, they are considerably smaller than either of the parents... But we will be working on that! Regina is recovering from the operation, the babies are under observation. As far as we were told, they seem to be quite healthy, with just minor issues to work on during neonatal care. We are waiting for our doctors to come today and allow us to spend time with them. And as for us... It's a shocking change to finally see the so long expected babies. We are very very very happy... And the new reality is hard to grasp, to even begin understanding :) PS- Many people have told me that my blog often errors out under load. I expect it to happen today :) So, if you cannot do it here, there are many other ways to contact us. Use them! :)

    27 February 2015

    Dirk Eddelbuettel: RcppArmadillo 0.4.650.1.1 (and also 0.4.650.2.0)

    A new Armadillo release 4.650.1 was released by Conrad a few days ago. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. It turned out that this release had one shortcoming with respect to the C++11 RNG initializations in the R use case (where we need to protect the users from the C++98 RNG deemed unsuitable by the CRAN gatekeepers). And this lead to upstream release 4.650.1 which we wrapped into RcppArmadillo 0.4.650.1.1. As before this, was tested against all 107 reverse dependencies of RcppArmadillo on the CRAN repo. This version is now on CRAN, and was just uploaded to Debian. Its changes are summarized below based on the NEWS.Rd file.
    Changes in RcppArmadillo version 0.4.650.1.1 (2015-02-25)
    • Upgraded to Armadillo release Version 4.650.1 ("Intravenous Caffeine Injector")
      • added randg() for generating random values from gamma distributions (C++11 only)
      • added .head_rows() and .tail_rows() to submatrix views
      • added .head_cols() and .tail_cols() to submatrix views
      • expanded eigs_sym() to optionally calculate eigenvalues with smallest/largest algebraic values fixes for handling of sparse matrices
    • Applied small correction to main header file to set up C++11 RNG whether or not the alternate RNG (based on R, our default) is used
    Now, it turns out that another small fix was needed for the corner case of a submatrix within a submatrix, ie V.subvec(1,10).tail(5). I decided not to re-release this to CRAN given the CRAN Repository Policy preference for releases no more than every 1 2 months . But fear not, for we now have drat. I created a drat package repository in the RcppCore account (to not put a larger package into my main drat repository often used via a fork to initialize a drat). So now with these two simple commands
    ## if needed, first install 'drat' via:   install.packages("drat")
    drat:::add("RcppCore")
    update.packages()
    you will get the newest RcppArmadillo via this drat package repository. And course install.packages("RcppArmadillo") would also work, but takes longer to type :) Lastly, courtesy of CRANberries, there is also a diffstat report for the most recent CRAN release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

    This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

    26 February 2015

    EvolvisForge blog: tomcat7 init script is asynchronous

    TIL: the init script of tomcat7 in Debian is asynchronous. For some piece of software, our rollout (install and upgrade) process works like this: The first tomcat7 start here is just to unzip the *.war files. For some reason, people like to let tomcat7 do that. This failed today; there were two webapps. Manually unzipping it also did not work for some reason. Re-doing it, inserting a sleep 30 after the here , made it work. In a perfect world, initscripts only return when the service is running, so that the next one started in a nice sequential (not parallel!) init or manual start sequence can do what it needs to, assuming the previous command has fully finished. In this perfect world, those who do wish for faster startup times use a different init system, one that starts things in parallel, for example. Even there, dependencies will wish for the depended-on service to be fully running when they are started; even more so, since the delays between starting things seem to be less for that other init system. So, this is not about the init system, but about the init script; a change that would be a win-win for users of both init schemes. Update: Someone already contacted me with feedback: they suggested to wait until the shutdown port is listened on by tomcat7. We ll look at this later. In the meantime, we re trying to also get rid of the config (and logs) in webapps/ part
    PS: If someone is interested in an init script (Debian/LSB sysvinit, I made the effort to finally learn that some months before the other system came) that starts Wildfly (formerly known as JBoss AS) synchronously, waiting until all *.?ar files are fully deployed before returning (though with a timeout in case it won t ever finish), just ask (maybe it will become a dialogue, in which we can improve it together). (We have two versions of it, the more actively maintained one is in a secret internal project though, so I d have to merge it and ready it for publication though, plus the older one is AGPLv3, the newer one was relicenced to a BSDish licence.)

    25 February 2015

    Holger Levsen: 20150225-apparmor-user-stories

    Developing is a use case too For whatever reason Ulrike's blog post about AppArmor user stories and user tags was not syndicated to planet.d.o, despite it should have been and despite planet admins nicely having looked into it. Whatever... As you might have guessed by now, the user stories referred to in this blog post are about developers supporting AppArmor (a kernel module for restricting capabilities of processes) in their Debian packages. So if you're maintaining packages and have always been pondering to look into this apparmor thingy, go read that blog post! Hopefully the next post will "magically" appear on planet again ;-)

    Eddy Petrișor: Occasional Rsnapshot v1.3.0

    It is almost exactly 1 year and a half since I came up with the idea of having a way of making backups using Rsnapshot automatically triggered by my laptop when I have the backup media connected to my laptop. This could mean connecting a USB drive directly to the laptop or mounting a NFS/sshfs share in my home network. Today I tagged Occasional Rsnapshot the v1.3.0 version, the first released version that makes sure even when you connect your backup media occasionally, your Rsnapshot backups are done if and when it makes sense to do it, according to the rsnapshot.conf file and the status of the existing backups on the backup media.

    Quoting from the README, here is what Occasional Rsnapshot does:

    This is a tool that allows automatic backups using rsnapshot when the external backup drive or remote backup media is connected.

    Although the ideal setup would be to have periodic backups on a system that is always online, this is not always possible. But when the connection is done, the backup should start fairly quickly and should respect the daily/weekly/... schedules of rsnapshot so that it accurately represents history.

    In other words, if you backup to an external drive or to some network/internet connected storage that you don't expect to have always connected (which is is case with laptops) you can use occasional_rsnapshot to make sure your data is backed up when the backup storage is connected.

    occasional_rsnapshot is appropriate for:
    • laptops backing up on:
      • a NAS on the home LAN or
      • a remote or an internet hosted storage location
    • systems making backups online (storage mounted locally somehow)
    • systems doing backups on an external drive that is not always connected to the system
    The only caveat is that all of these must be mounted in the local file system tree somehow by any arbitrary tool, occasional_rsnapshot or rsnapshot do not care, as long as the files are mounted.

    So if you find yourself in a simillar situation, this script might help you to easily do backups in spite of the occasional availability of the backup media, instead of no backups at all. You can even trigger backups semi-automatically when you remember to or decide is time to backup, by simply pulging in your USB backup HDD.

    But how did I end up here, you might ask?

    In December 2012 I was asking about suggestions for backup solutions that would work for my very modest setup with Linux and Windows so I can backup my and my wife's system without worrying about loss of data.

    One month later I was explaining my concept of a backup solution that would not trust the backup server, and leave to the clients as much as possible the decision to start the backup at their desired time. I was also pondering on the problems I might encounter.

    From a security PoV, what I wanted was that:
    1. clients would be isolated from each other
    2. even in the case of a server compromise:
        • the data would not be accessible since they would be already encrypted before leaving the client
        • the clients could not be compromised


      The general concept was sane and supplemental security measures such as port knocking and initiation of backups only during specific time frames could be added.

      The problem I ran to was that when I set up this in my home network a sigle backup cycle would take more than a day, due to the fact that I wanted to do backup of all of my data and my server was a humble Linksys NSLU2 with a 3TB storage attached on USB.

      Even when the initial copy was done by attaching the USB media directly to the laptop, so the backup would only copy changed data, the backup with the HDD attached to the NSLU2 was not finished even after more than 6 hours.

      The bottleneck was the CPU speed and the USB speed. I tried even mounting the storage media over sshfs so the tiny xscale processor in the NSLU2 would not be bothered by any of the rsync computation. This proved to an exercise in futility, any attempt to put the NSLU2 anywhere in the loop resulted in an unacceptable and impractically long backup time.

      All these attempts, of course, took time, but that meant that I was aware I still didn't have appropriate backups and I wasn't getting closer to the desired result.

      So this brings us August 2013, when I realized I was trying to manually trigger Rsnapshot backups from time to time, but having to do all sorts of mental gymnastics and manual listing to evaluate if I needed to do monthly, weekly and daily backups or if weekly and daily was due.

      This had to stop.
      Triggering a backup should happen automatically as soon as the backup media is available, without any intervention from the user.
      I said.

      Then I came up with the basic concept for Occasional Rsnapshot: a very silent script that would be called from cron every 5 minutes, would check if the backup media is mounted, if is not, exit silently to not generate all sorts of noise in cron emails, but if mounted, compute which backup intervals should be triggered, and trigger them, if the appropriate amount of time passed since the most recent backup in that backup interval.

      Occasional Rsnapshot version v1.3.0 is the 8th and most recent release of the script. Even if I used Occasional Rsnapshot since the day 1, v1.3.0 is the first one I can recommend to others, without fearing they might lose data due to it.

      The backup media can be anything, starting from your regular USB mounted HDD, your sshfs mounted backup partition on the home NAS server to even a remote storage such as Amazon S3 online storage, and there are even brief instructions on how to do encrypted backups for the cases where you don't trust the remote storage.

      So if you think you might find anything that I described remotely interesting, I recommend downloading the latest release of Occasional Rsnapshot, go through the README and trying it out.

      Feedback and bug reports are welcome.
      Patches are welcomed with a 'thank you'.
      Pull requests are eagerly waited for :) .

      Andrew Cater: Cubietruck now running Debian :)

      Following a debootstrap build of sid on one machine to complete the cross-compilation of mainline u-boot, I managed to get vanilla Debian installed on my Cubietruck

      A USB-serial cable is a must for the install and for any subsequent major reconfiguration as the stock Debian installer does not have drivers for the video / audio. Various Cubietruck derivative distributions do - but the Sunxi kernel appears flaky

      All was fine for a few days, then I decided to try and configure the Wifi by hand configuring /etc/network/interfaces and wpasupplicant files. I managed to break the network connectivity by doing things in a hurry and typing blind. I'd put it into the appropriate closed metal case so was rather stuck.

      A friend carefully took the case apart by easing off the metal cover plates, removed two screws holding the whole thing together and precision drilled the metal cover plates on one side so that four screws can be undone and the entire inner part of the case can slide out as one while the other metal clover plate remains captive. He will follow this procedure with his two later.

      Very pleased with the way it's turned out. The WiFi driver has non-free firmware but I now have a tiny, silent machine, drawing about 3W tops and both interfaces are now working.


      Petter Reinholdtsen: The Norwegian open channel Frikanalen - 24x7 on the Internet

      The Norwegian nationwide open channel Frikanalen is still going strong. It allow everyone to send the video they want on national television. It is a TV station administrated completely using a web browser, running only Free Software, providing a REST api for administrators and members, and with distribution on the national DVB-T distribution network RiksTV. But only between 12:00 and 17:30 Norwegian time. This has finally changed, after many years with limited distribution. A few weeks ago, we set up a Ogg Theora stream via icecast to allow everyone with Internet access to check out the channel the rest of the day. This is presented on the Frikanalen web site now. And since a few days ago, the channel is also available via multicast on UNINETT, available for those using IPTV TVs and set-top boxes in the Norwegian National Research and Education network. If you want to see what is on the channel, point your media player to one of these sources. The first should work with most players and browsers, while as far as I know, the multicast UDP stream only work with VLC. The Ogg Theora / icecast stream is not working well, as the video and audio is slightly out of sync. We have not been able to figure out how to fix it. It is generated by recoding a internal MPEG transport stream with MPEG4 coded video (ie H.264) to Ogg Theora / Vorbis, and the result is less then stellar. If you have ideas how to fix it, please let us know on frikanalen (at) nuug.no. We currently use this with ffmpeg2theora 0.29:
      ./ffmpeg2theora.linux <OBE_gemini_URL.ts> -F 25 -x 720 -y 405 \
       --deinterlace --inputfps 25 -c 1 -H 48000 --keyint 8 --buf-delay 100 \
       --nosync -V 700 -o -   oggfwd video.nuug.no 8000 <pw> /frikanalen.ogv
      
      If you get the multicast UDP stream working, please let me know, as I am curious how far the multicast stream reach. It do not make it to my home network, nor any other commercially available network in Norway that I am aware of.

      24 February 2015

      EvolvisForge blog: Java , logging and the locale

      A coworker and I debugged a fascinating problem today. They had a tomcat7 installation with a couple of webapps, and one of the bundled libraries was logging in German. Everything else was logging in English (the webapps themselves, and the things the other bundled libraries did). We searched around a bit, and eventually found that the wrongly-logging library (something jaxb/jax-ws) was using, after unravelling another few layers of library bundling another library as convenience copy (gah, Java!), com.sun.xml.ws.resources.WsservletMessages which contains quite a few com.sun.istack.localization.Localizable members. Looking at the other classes in that package, in particular Localizer, showed that it defaults to the java.util.Locale.getDefault() value for the language. Which is set from the environment. Looking at /proc/pid-of-JVM-running-tomcat7/environ showed nothing, of course . The system locale was, properly, set to English. (We mostly use en_GB.UTF-8 for better paper sizes and the metric system (unless the person requesting the machine, or the admin creating it, still likes the system to speak German *shudder*), but that one still had en_US.UTF-8.) Browsing the documentation for java.util.Locale proved more fruitful: it also contains a setDefault method, which sets the new default locale JVM-wide. Turns out another of the webapps used that for some sort of internal localisation. Clearly, the containment of tomcat7 is incomplete in this case. Documenting for the larger net, in case someone else runs into this. It s not as if things like this would be showing up in the USA, where the majority of development appears to happen.

      23 February 2015

      Dirk Eddelbuettel: drat Tutorial: Publishing a package

      Introduction The drat package was released earlier this month, and described in a first blog post. I received some helpful feedback about what works and what doesn't. For example, Jenny Bryan pointed out that I was not making a clear enough distinction between the role of using drat to publish code, and using drat to receive/install code. Very fair point, and somewhat tricky as R aims to blur the line between being a user and developer of statistical analyses, and hence packages. Many of us are both. Both the main point is well taken, and this note aims to clarify this issue a little by focusing on the former. Another point make by Jenny concerns the double use of repository. And indeed, I conflated repository (in the sense of a GitHub code repository) with repository for a package store used by a package manager. The former, a GitHub repository, is something we use to implement a personal drat with: A GitHub repository happens to be uniquely identifiable just by its account name, and given an (optional) gh-pages branch also offers a stable and performant webserver we use to deliver packages for R. A (personal) code repository on the other hand is something we implement somewhere---possibly via drat which supports local directories, possibly on a network share, as well as anywhere web-accessible, e.g. via a GitHub repository. It is a little confusing, but I will aim to make the distinction clearer.

      Just once: Setting up a drat repository So let us for the remainder of this post assume the role of a code publisher. Assume you have a package you would like to make available, which may not be on CRAN and for which you would like to make installation by others easier via drat. The example below will use an interim version of drat which I pushed out yesterday (after fixing a bug noticed when pushing the very new RcppAPT package). For the following, all we assume (apart from having a package to publish) is that you have a drat directory setup within your git / GitHub repository. This is not an onerous restriction. First off, you don't have to use git or GitHub to publish via drat: local file stores and other web servers work just as well (and are documented). GitHub simply makes it easiest. Second, bootstrapping one is trivial: just fork my drat GitHub repository and then create a local clone of the fork. There is one additional requirement: you need a gh-pages branch. Using the fork-and-clone approach ensures this. Otherwise, if you know your way around git you already know how to create a gh-pages branch. Enough of the prerequisities. And on towards real fun. Let's ensure we are in the gh-pages branch:
      edd@max:~/git/drat(master)$ git checkout gh-pages
      Switched to branch 'gh-pages'
      Your branch is up-to-date with 'origin/gh-pages'.
      edd@max:~/git/drat(gh-pages)$ 

      Publish: Run one drat command to insert a package Now, let us assume you have a package to publish. In my case this was version 0.0.1.2 of drat itself as it contains a fix for the very command I am showing here. So if you want to run this, ensure you have this version of drat as the CRAN version is currently behind at release 0.0.1 (though I plan to correct that in the next few days). To publish an R package into a code repository created via drat running on a drat GitHub repository, just run insertPackage(packagefile) which we show here with the optional commit=TRUE. The path to the package can be absolute are relative; the easists is often to go up one directory from the sources to where R CMD build ... has created the package file.
      edd@max:~/git$ Rscript -e 'library(drat); insertPackage("drat_0.0.1.2.tar.gz", commit=TRUE)'
      [gh-pages 0d2093a] adding drat_0.0.1.2.tar.gz to drat
       3 files changed, 2 insertions(+), 2 deletions(-)
       create mode 100644 src/contrib/drat_0.0.1.2.tar.gz
      Counting objects: 7, done.
      Delta compression using up to 8 threads.
      Compressing objects: 100% (7/7), done.
      Writing objects: 100% (7/7), 7.37 KiB   0 bytes/s, done.
      Total 7 (delta 1), reused 0 (delta 0)
      To git@github.com:eddelbuettel/drat.git
         206d2fa..0d2093a  gh-pages -> gh-pages
      edd@max:~/git$ 
      You can equally well run this as insertPackage("drat_0.0.1.2.tar.gz"), then inspect the repo and only then run the git commands add, commit and push. Also note that future versions of drat will most likely support git operations directly by relying on the very promising git2r package. But this just affect package internals, the user-facing call of e.g. insertPackage("drat_0.0.1.2.tar.gz", commit=TRUE) will remain unchanged. And in a nutshell that really is all there is to it. With the newly drat-ed package pushed to your GitHub repository with a single function call), it is available via the automatically-provided gh-pages webserver access to anyone in the world. All they need to do is to point R's package management code (which is built into R itself and used for e.g._ CRAN and BioConductor R package repositories) to the new repo---and that is also just a single drat command. We showed this in the first blog post and may expand on it again in a follow-up. So in summary, that really is all there is to it. After a one-time setup / ensuring you are on the gh-pages branch, all it takes is a single function call from the drat package to publish your package to your drat GitHub repository.

      This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

      20 February 2015

      MJ Ray: Rebooting democracy? The case for a citizens constitutional convention.

      I m getting increasingly cynical about our largest organisations and their voting-centred approach to democracy. You vote once, for people rather than programmes, then you re meant to leave them to it for up to three years until they stand for reelection and in most systems, their actions aren t compared with what they said they d do in any way. I have this concern about Cooperatives UK too, but then its CEO publishes http://www.uk.coop/blog/ed-mayo/2015-02-18/rebooting-democracy-case-citizens-constitutional-convention and I think there may be hope for it yet. Well worth a read if you want to organise better groups.

      19 February 2015

      Matthew Garrett: It has been 0 days since the last significant security failure. It always will be.

      So blah blah Superfish blah blah trivial MITM everything's broken.

      Lenovo deserve criticism. The level of incompetence involved here is so staggering that it wouldn't be a gross injustice for the company to go under as a result[1]. But let's not pretend that this is some sort of isolated incident. As an industry, we don't care about user security. We will gladly ship products with known security failings and no plans to update them. We will produce devices that are locked down such that it's impossible for anybody else to fix our failures. We will hide behind vague denials, we will obfuscate the impact of flaws and we will deflect criticisms with announcements of new and shinier products that will make everything better.

      It'd be wonderful to say that this is limited to the proprietary software industry. I would love to be able to argue that we respect users more in the free software world. But there are too many cases that demonstrate otherwise, even where we should have the opportunity to prove the benefits of open development. An obvious example is the smartphone market. Hardware vendors will frequently fail to provide timely security updates, and will cease to update devices entirely after a very short period of time. Fortunately there's a huge community of people willing to produce updated firmware. Phone manufacturer is never going to fix the latest OpenSSL flaw? As long as your phone can be unlocked, there's a reasonable chance that there's an updated version on the internet.

      But this is let down by a kind of callous disregard for any deeper level of security. Almost every single third-party Android image is either unsigned or signed with the "test keys", a set of keys distributed with the Android source code. These keys are publicly available, and as such anybody can sign anything with them. If you configure your phone to allow you to install these images, anybody with physical access to your phone can replace your operating system. You've gained some level of security at the application level by giving up any real ability to trust your operating system.

      This is symptomatic of our entire ecosystem. We're happy to tell people to disable security features in order to install third-party software. We're happy to tell people to download and build source code without providing any meaningful way to verify that it hasn't been tampered with. Install methods for popular utilities often still start "curl sudo bash". This isn't good enough.

      We can laugh at proprietary vendors engaging in dreadful security practices. We can feel smug about giving users the tools to choose their own level of security. But until we're actually making it straightforward for users to choose freedom without giving up security, we're not providing something meaningfully better - we're just providing the same shit sandwich on different bread.

      [1] I don't see any way that they will, but it wouldn't upset me

      comment count unavailable comments

      17 February 2015

      Lucas Nussbaum: Some email organization tips and tricks

      I d like to share a few tips that were useful to strengthen my personal email organization. Most of what follows is probably not very new nor special, but hey, let s document it anyway. Many people have an inbox folder that just grow over time. It s actually similar to a twitter or RSS feed (except they probably agree that they are supposed to read more of their email feed ). When I send an email to them, it sometimes happen that they don t notice it, if the email arrives at a bad time. Of course, as long as they don t receive too many emails, and there aren t too many people relying on them, it might just work. But from time to time, it s super-painful for those interacting with them, when they miss an email and they need to be pinged again. So let s try not to be like them. :-) Tip #1: do Inbox Zero (or your own variant of it) Inbox Zero is an email management methodology inspired from David Allen s Getting Things Done book. It s best described in this video. The idea is to turn one s Inbox into an area that is only temporary storage, where every email will get processed at some point. Processing can mean deleting an email, archiving it, doing the action described in the email (and replying to it), etc. Put differently, it basically means implementing the Getting Things Done workflow on one s email. Tip #1.1: archive everything One of the time-consuming decisions in the original GTD workflow is to decide whether something should be eliminated (deleted) or stored for reference. Given that disk space is quite cheap, it s much easier to never decide about that, and just archive everything (by duplicating the email to an archive folder when it is received). To retrieve archived emails when needed, I then use notmuch within mutt to easily search through recent (< 2 year) archives. I use archivemail to archive older email in compressed mboxes from time to time, and grepmail to search through those mboxes when needed. I don t archive most Debian mailing lists though, as they are easy to fetch from master.d.o with the following script:
      #!/bin/sh
      rsync -vP master.debian.org:~debian/*/*$1/*$1.$ 2:-$(date +%Y%m) * .
      Then I can fetch a specific list archive with getlist devel 201502, or a set of archives with e.g. getlist devel 2014, or the current month with e.g. getlist devel. Note that to use grepmail on XZ-compressed archives, you need libmail-mbox-messageparser-perl version 1.5002-3 (only in unstable I was using a locally-patched version for ages, but finally made a patch last week, which Gregor kindly uploaded). Tip #1.2: split your inbox (Yes, this one looks obvious but I m always surprised at how many people don t do that.) Like me, you probably receive various kinds of emails: Splitting those into separate folders has several advantages: I ve seen some people splitting their inbox into too many folders. There s not much point in having a per-sender folder organization (unless there s really a recurring flow of emails from a specific person), as it increases the risk of missing an email. I use procmail to organize my email into folders. I know that there are several more modern alternatives, but I haven t looked at them since procmail does the job for me. Resulting organization I use one folder for my day-job email, one for my DPL email, one for all other email directed or Cced to me. Then, I have a few folders for automated notifications of stuff. My Debian mailing list folders are auto-managed by procmail s $MATCH:
      :0:
       * ^X-Mailing-List: <.*@lists\.debian\.org>
       * ^X-Mailing-List: <debian-\/[^@]*
       .ml.debian.$MATCH/
      Some other mailing lists are in they separate folders, and there s a catch-all folder for the remaining ones. Ah, and since I use feed2imap, I have folders for the RSS/Atom feeds I follow. I have two different commands to start mutt. One only shows a restricted number of (important) folders. The other one shows the full list of (non-empty) folders. This is a good trick to avoid spending time reading email when I am supposed to do something more important. :) As for many people probably, my own organization is loosely based on GTD and Inbox Zero. It sometimes happen that some emails stay in my Inbox for several days or weeks, but I very rarely have more than 20 or 30 emails in one of my main inbox folders. I also do reviews of the whole content of my main inbox folders once or twice a week, to ensure that I did not miss an email that could be acted on quickly. A last trick is that I have a special folder replies, where procmail copies emails that are replies to a mail I sent, but which do not Cc me. That s useful to work-around Debian s no Cc on reply to mailing list posts policy. I receive email using offlineimap (over SSH to my mail server), and send it using nullmailer (through a SSH tunnel). The main advantage of offlineimap over using IMAP directly in mutt is that using IMAP to a remote server feels much more sluggish. Another advantage is that I only need SSH access to get my full email setup to work. Tip #2: tracking sent emails Two recurring needs I had was: I developed a short script to address that. It scans the content of my Sent maildir and my archive maildirs, and, for each email address I use, displays (see example output in README) the list of emails sent with this address (one email per line). It also detects if an email was replied to ( R column after the date), and abbreviates common parts in email addresses (debian-project@lists.debian.org becomes d-project@l.d.o). It also generates a temporary maildir with symlinks to all emails, so that I can just open the maildir if needed.

      John Goerzen: Has Linux lost its way? comments prompt a Debian developer to revisit FreeBSD after 20 years

      I ll admit it. I have a soft spot for FreeBSD. FreeBSD was the first Unix I ran, and it was somewhere around 20 years ago that I did so, before I switched to Debian. Even then, I still used some of the FreeBSD Handbook to learn Linux, because Debian didn t have the great Reference that it does now. Anyhow, some comments in my recent posts ( Has modern Linux lost its way? and Reactions to that, and the value of simplicity), plus a latent desire to see how ZFS fares in FreeBSD, caused me to try it out. I installed it both in VirtualBox under Debian, and in an old 64-bit Thinkpad sitting in my basement that previously ran Debian. The results? A mixture of amazing and disappointing. I will say that I am quite glad that both exist; there is plenty of innovation happening everywhere and neat features exist everywhere, too. But I can also come right out and say that the statement that FreeBSD doesn t have issues like Linux does is false and misleading. In many cases, it s running the exact same stack. In others, it s better, but there are also others where it s worse. Perhaps this article might dispell a bit of the FUD surrounding jessie, while also showing off some of the nice things FreeBSD does. My conclusion: Both jessie and FreeBSD 10.1 are awesome Free operating systems, but both have their warts. This article is more about FreeBSD than Debian, but it will discuss a few of Debian s warts as well. The experience My initial reaction to FreeBSD was: wow, this feels so familiar. It reminds me of a commercial Unix, or maybe of Linux from a few years ago. A minimal, well-documented base system, everything pretty much in logical places in the filesystem, and solid memory management. I felt right at home. It was almost reassuring, even. Putting together a FreeBSD box is a lot of package installing and config file editing. The FreeBSD Handbook, describing how to install X, talks about editing this or that file for this or that feature. I like being able to learn directly how things fit together by doing this. But then you start remembering the reasons you didn t like Linux a few years ago, or the commercial Unixes: maybe it s that programs like apache are still not as well supported, or maybe it s that the default vi has this tendency to corrupt the terminal periodically, or perhaps it s that root s default shell is csh. Or perhaps it s that I have to do a lot of package installing and config file editing. It is not quite the learning experience it once was, either; now there are things like paste this XML file into some obscure polkit location to make your mouse work or something. Overall, there are some areas where FreeBSD kills it in a way no other OS does. It is unquestionably awesome in several areas. But there are a whole bunch of areas where it s about 80% as good as Linux, a number of areas (even polkit, dbus, and hal) where it s using the exact same stack Linux is (so all these comments about FreeBSD being so differently put together strike me as hollow), and frankly some areas that need a lot of work and make it hard to manage systems in a secure and stable way. The amazing Let s get this out there: I ve used ZFS too much to use any OS that doesn t support it or something like it. Right now, I m not aware of anything like ZFS that is generally stable and doesn t cost a fortune, so pretty much: if your Unix doesn t do ZFS, I m not interested. (btrfs isn t there yet, but will be awesome when it is.) That s why I picked FreeBSD for this, rather than NetBSD or OpenBSD. ZFS on FreeBSD is simply awesome. They have integreated it extremely well. The installer supports root on zfs, even encrypted root on zfs (though neither is a default). top on a FreeBSD system shows a line of ZFS ARC (cache) stats right alongside everything else. The ZFS defaults for maximum cache size, readahead, etc. auto-tune themselves at boot (unless overridden) based on the amount of RAM in a system and the system type. Seriously, these folks have thought of everything and it just reeks of solid. I haven t seen ZFS this well integrated outside the Solaris-type OSs. I have been using ZFSOnLinux for some time now, but it is just not as mature as ZFS on FreeBSD. ZoL, for instance, still has some memory tuning issues, and is not really suggested for 32-bit machines. FreeBSD just nails it. ZFS on FreeBSD even supports TRIM, which is not available in ZoL and I think fairly unique even among OpenZFS platforms. It also supports delegated administration of the filesystem, both to users and to jails on the system, seemingly very similar to Solaris zones. FreeBSD also supports beadm, which is like a similar tool on Solaris. This lets you basically use ZFS snapshots to make lightweight boot environments , so you can select which to boot into. This is useful, say, before doing upgrades. Then there are jails. Linux has tried so hard to get this right, and fallen on its face so many times, a person just wants to take pity sometimes. We ve had linux-vserver, openvz, lxc, and still none of them match what FreeBSD jails have done for a long time. Linux s current jail-du-jour is LXC, though it is extremely difficult to configure in a secure way. Even its author comments that you won t hear any of the LXC maintainers tell you that LXC is secure and that it pretty much requires AppArmor profiles to achieve reasonable security. These are still rather in flux, as I found out last time I tried LXC a few months ago. My confidence in LXC being as secure as, say, KVM or FreeBSD is simply very low. FreeBSD s jails are simple and well-documented where LXC is complex and hard to figure out. Its security is fairly transparent and easy to control and they just work well. I do think LXC is moving in the right direction and might even get there in a couple years, but I am quite skeptical that even Docker is getting the security completely right. The simply different People have been throwing around the word distribution with respect to FreeBSD, PC-BSD, etc. in recent years. There is an analogy there, but it s not perfect. In the Linux ecosystem, there is a kernel project, a libc project, a coreutils project, a udev project, a systemd/sysvinit/whatever project, etc. You get the idea. In FreeBSD, there is a base system project. This one project covers the kernel and the base userland. Some of what they use in the base system is code pulled in from elsewhere but maintained in their tree (ssh), some is completely homegrown (kernel), etc. But in the end, they have a nicely-integrated base system that always gets upgraded in sync. In the Linux world, the distribution makers are responsible for integrating the bits from everywhere into a coherent whole. FreeBSD is something of a toolkit to build up your system. Gentoo might be an analogy in the Linux side. On the other end of the spectrum, Ubuntu is a just install it and it works, tweak later sort of setup. Debian straddles the middle ground, offering both approaches in many cases. There are pros and cons to each approach. Generally, I don t think either one is better. They are just different. The not-quite-there I said that there are a lot of things in FreeBSD that are about 80% of where Linux is. Let me touch on them here. Its laptop support leaves something to be desired. I installed it on a few-years-old Thinkpad basically the best possible platform for working suspend in a Free OS. It has worked perfectly out of the box in Debian for years. In FreeBSD, suspend only works if it s in text mode. If X is running, the video gets corrupted and the system hangs. I have not tried to debug it further, but would also note that suspend on closed lid is not automatic in FreeBSD; the somewhat obscure instuctions tell you what policykit pkla file to edit to make suspend work in XFCE. (Incidentally, it also says what policykit file to edit to make the shutdown/restart options work). Its storage subsystem also has some surprising misses. Its rough version of LVM, LUKS, and md-raid is called GEOM. GEOM, however, supports only RAID0, RAID1, and RAID3. It does not support RAID5 or RAID6 in software RAID configurations! Linux s md-raid, by comparison, supports RAID0, RAID1, RAID4, RAID5, RAID6, etc. There seems to be a highly experimental RAID5 patchset floating around for many years, but it is certainly not integrated into the latest release kernel. The current documentation makes no mention of RAID5, although it seems that a dated logical volume manager supported it. In any case, RAID5 does not seem to be well-supported in software like it is in Linux. ZFS does have its raidz1 level, which is roughly the same as RAID5. However, that requires full use of ZFS. ZFS also does not support some common operations, like adding a single disk to an existing RAID5 group (which is possible with md-raid and many other implementations.) This is a ZFS limitation on all platforms. FreeBSD s filesystem support is rather a miss. They once had support for Linux ext* filesystems using the actual Linux code, but ripped it out because it was in GPL and rewrote it so it had a BSD license. The resulting driver really only works with ext2 filesystems, as it doesn t work with ext3/ext4 in many situations. Frankly I don t see why they bothered; they now have something that is BSD-licensed but only works with a filesystem so old nobody uses it anymore. There are only two FreeBSD filesystems that are really useable: UFS2 and ZFS. Virtualization under FreeBSD is also not all that present. Although it does support the VirtualBox Open Source Edition, this is not really a full-featured or fast enough virtualization environment for a server. Its other option is bhyve, which looks to be something of a Xen clone. bhyve, however, does not support Windows guests, and requires some hoops to even boot Linux guest installers. It will be several years at least before it reaches feature-parity with where KVM is today, I suspect. One can run FreeBSD as a guest under a number of different virtualization systems, but their instructions for making the mouse work best under VirtualBox did not work. There may have been some X.Org reshuffle in FreeBSD that wasn t taken into account. The installer can be nice and fast in some situations, but one wonders a little bit about QA. I had it lock up on my twice. Turns out this is a known bug reported 2 months ago with no activity, in which the installer attempts to use a package manger that it hasn t set up yet to install optional docs. I guess the devs aren t installing the docs in testing. There is nothing like Dropbox for FreeBSD. Apparently this is because FreeBSD has nothing like Linux s inotify. The Linux Dropbox does not work in FreeBSD s Linux mode. There are sketchy reports of people getting an OwnCloud client to work, but in something more akin to rsync rather than instant-sync mode, if they get it working at all. Some run Dropbox under wine, apparently. The desktop environments tend to need a lot more configuration work to get them going than on Linux. There s a lot of editing of polkit, hal, dbus, etc. config files mentioned in various places. So, not only does FreeBSD use a lot of the same components that cause confusion in Linux, it doesn t really configure them for you as much out of the box. FreeBSD doesn t support as many platforms as Linux. FreeBSD has only two platforms that are fully supported: i386 and amd64. But you ll see people refer to a list of other platforms that are supported , but they don t have security support, official releases, or even built packages. They includ arm, ia64, powerpc, and sparc64. The bad: package management Roughly 20 years ago, this was one of the things that pulled me to Debian. Perhaps I am spolied from running the distribution that has been the gold standard for package management for so long, but I find FreeBSD s package management even pkg-ng in 10.1-RELEASE to be lacking in a number of important ways. To start with, FreeBSD actually has two different package management systems: one for the base system, and one for what they call the ports/packages collection ( ports being the way to install from source, and packages being the way to install from binaries, but both related to the same tree.) For the base system, there is freebsd-update which can install patches and major upgrades. It also has a cron option to automate this. Sadly, it has no way of automatically indicating to a calling script whether a reboot is necessary. freebsd-update really manages less than a dozen packages though. The rest are managed by pkg. And pkg, it turns out, has a number of issues. The biggest: it can take a week to get security updates. The FreeBSD handbook explains pkg audit -F which will look at your installed packages (but NOT the ones in the base system) and alert you to packages that need to be updates, similar to a stripped-down version of Debian s debsecan. I discovered this myself, when pkg audit -F showed a vulnerability in xorg, but pkg upgrade showed my system was up-to-date. It is not documented in the Handbook, but people on the mailing list explained it to me. There are workarounds, but they can be laborious. If that s not bad enough, FreeBSD has no way to automatically install security patches for things in the packages collection. Debian has several (unattended-upgrades, cron-apt, etc.) There is pkg upgrade , but it upgrades everything on the system, which may be quite a bit more than you want to be upgraded. So: if you want to run Apache with PHP, and want it to just always apply security patches, FreeBSD packages are not up to the job like Debian s are. The pkg tool doesn t have very good error-handling. In fact, its error handling seems to be nonexistent at times. I noticed that some packages had failures during install time, but pkg ignored them and marked the package as correctly installed. I only noticed there was a problem because I happened to glance at the screen at the right moment during messages about hundreds of packages. In Debian, by contrast, if there are any failures, at the end of the run, you get a nice report of which packages failed, and an exit status to use in scripts. It also has another issue that Debian resolved about a decade ago: package scripts displaying messages that are important for the administrator, but showing so many of them that they scroll off the screen and are never seen. I submitted a bug report for this one also. Some of these things just make me question the design of pkg. If I can t trust it to accurately report if the installation succeeded, or show me the important info I need to see, then to what extent can I trust it? Then there is the question of testing of the ports/packages. It seems that, automated tests aside, basically everyone is running off the master branch of the ports/packages. That s like running Debian unstable on your servers. I am distinctly uncomfortable with this notion, though it seems FreeBSD people report it mostly works well. There are some other issues, too: FreeBSD ports make no distinction between development and runtime files like Debian s packages do. So, just by virtue of wanting to run a graphical desktop, you get all of the static libraries, include files, build scripts, etc for XOrg installed. For a package as concerned about licensing as FreeBSD, the packages collection does not have separate sections like Debian s main, contrib, and non-free. It s all in one big pot: BSD-license, GPL-license, proprietary without source license. There is /usr/local/share/licenses where you can look up a license for each package, but there is no way with FreeBSD, like there is with Debian, to say never even show me packages that aren t DFSG-free. This is useful, for instance, when running in a company to make sure you never install packages that are for personal use only or something. The bad: ABI stability I m used to being able to run binaries I compiled years ago on a modern system. This is generally possible in Linux, assuming you have the correct shared libraries available. In FreeBSD, this is explicitly NOT possible. After every major version upgrade, you must reinstall or recompile every binary on your system. This is not necessarily a showstopper for me, but it is a hassle for a lot of people. Update 2015-02-17: Some people in the comments are pointing out compat packages in the ports that may help with this situation. My comment was based on advice in the FreeBSD Handbook stating After a major version upgrade, all installed packages and ports need to be upgraded . I have not directly tried this, so if the Handbook is overstating the need, then this point may be in error. Conclusions As I said above, I found little validation to the comments that the Debian ecosystem is noticeably worse than the FreeBSD one. Debian has its warts too particularly with keeping software up-to-date. You can see that the two projects are designed around a different passion: FreeBSD s around the base system, and Debian s around an integrated whole system. It would be wrong to say that either of those is always better. FreeBSD s approach clearly produces some leading features, especially jails and ZFS integration. Yet Debian s approach also produces some leading features in the way of package management and security maintainability beyond the small base. My criticism of excessive complexity in the polkit/cgmanager/dbus area still stands. But to those people commenting that FreeBSD hasn t lost its way like Linux has, I would point out that FreeBSD mostly uses these same components also, and FreeBSD has excessive complexity in its ports/package system and system management tools. I think it s a draw. You pick the best for your use case. If you re looking for a platform to run a single custom app then perhaps all of the Debian package management benefits don t apply to you (you may not even need FreeBSD s packages, or just a few). The FreeBSD ZFS support or jails may well appeal. If you re looking to run a desktop environment, or a server with some application that needs a ton of PHP, Python, Perl, or C libraries, then Debian s package management and security handling may well be attractive. I am disappointed that Debian GNU/kFreeBSD will not be a release architecture in jessie. That project had the promise to provide a best of both worlds for those that want jails or tight ZFS integration.

      16 February 2015

      Matthew Garrett: Intel Boot Guard, Coreboot and user freedom

      PC World wrote an article on how the use of Intel Boot Guard by PC manufacturers is making it impossible for end-users to install replacement firmware such as Coreboot on their hardware. It's easy to interpret this as Intel acting to restrict competition in the firmware market, but the reality is actually a little more subtle than that.

      UEFI Secure Boot as a specification is still unbroken, which makes attacking the underlying firmware much more attractive. We've seen several presentations at security conferences lately that have demonstrated vulnerabilities that permit modification of the firmware itself. Once you can insert arbitrary code in the firmware, Secure Boot doesn't do a great deal to protect you - the firmware could be modified to boot unsigned code, or even to modify your signed bootloader such that it backdoors the kernel on the fly.

      But that's not all. Someone with physical access to your system could reflash your system. Even if you're paranoid enough that you X-ray your machine after every border crossing and verify that no additional components have been inserted, modified firmware could still be grabbing your disk encryption passphrase and stashing it somewhere for later examination.

      Intel Boot Guard is intended to protect against this scenario. When your CPU starts up, it reads some code out of flash and executes it. With Intel Boot Guard, the CPU verifies a signature on that code before executing it[1]. The hash of the public half of the signing key is flashed into fuses on the CPU. It is the system vendor that owns this key and chooses to flash it into the CPU, not Intel.

      This has genuine security benefits. It's no longer possible for an attacker to simply modify or replace the firmware - they have to find some other way to trick it into executing arbitrary code, and over time these will be closed off. But in the process, the system vendor has prevented the user from being able to make an informed choice to replace their system firmware.

      The usual argument here is that in an increasingly hostile environment, opt-in security isn't sufficient - it's the role of the vendor to ensure that users are as protected as possible by default, and in this case all that's sacrificed is the ability for a few hobbyists to replace their system firmware. But this is a false dichotomy - UEFI Secure Boot demonstrated that it was entirely possible to produce a security solution that provided security benefits and still gave the user ultimate control over the code that their machine would execute.

      To an extent the market will provide solutions to this. Vendors such as Purism will sell modern hardware without enabling Boot Guard. However, many people will buy hardware without consideration of this feature and only later become aware of what they've given up. It should never be necessary for someone to spend more money to purchase new hardware in order to obtain the freedom to run their choice of software. A future where users are obliged to run proprietary code because they can't afford another laptop is a dystopian one.

      Intel should be congratulated for taking steps to make it more difficult for attackers to compromise system firmware, but criticised for doing so in such a way that vendors are forced to choose between security and freedom. The ability to control the software that your system runs is fundamental to Free Software, and we must reject solutions that provide security at the expense of that ability. As an industry we should endeavour to identify solutions that provide both freedom and security and work with vendors to make those solutions available, and as a movement we should be doing a better job of articulating why this freedom is a fundamental part of users being able to place trust in their property.

      [1] It's slightly more complicated than that in reality, but the specifics really aren't that interesting.

      comment count unavailable comments

      Next.

      Previous.