Search Results: "will"

18 June 2017

Benjamin Mako Hill: The Community Data Science Collective Dataverse

I m pleased to announce the Community Data Science Collective Dataverse. Our dataverse is an archival repository for datasets created by the Community Data Science Collective. The dataverse won t replace work that collective members have been doing for years to document and distribute data from our research. What we hope it will do is get our data like our published manuscripts into the hands of folks in the forever business. Over the past few years, the Community Data Science Collective has published several papers where an important part of the contribution is a dataset. These include: Recently, we ve also begun producing replication datasets to go alongside our empirical papers. So far, this includes: In the case of each of the first groups of papers where the dataset was a part of the contribution, we uploaded code and data to a website we ve created. Of course, even if we do a wonderful job of keeping these websites maintained over time, eventually, our research group will cease to exist. When that happens, the data will eventually disappear as well. The text of our papers will be maintained long after we re gone in the journal or conference proceedings publisher s archival storage and in our universities institutional archives. But what about the data? Since the data is a core part perhaps the core part of the contribution of these papers, the data should be archived permanently as well. Toward that end, our group has created a dataverse. Our dataverse is a repository within the Harvard Dataverse where we have been uploading archival copies of datasets over the last six months. All five of the papers described above are uploaded already. The Scratch dataset, due to access control restrictions, isn t listed on the main page but it s online on the site. Moving forward, we ll be populating this new datasets we create as well as replication datasets for our future empirical papers. We re currently preparing several more. The primary point of the CDSC Dataverse is not to provide you with way to get our data although you re certainly welcome to use it that way and it might help make some of it more discoverable. The websites we ve created (like for the ones for redirects and for page protection) will continue to exist and be maintained. The Dataverse is insurance for if, and when, those websites go down to ensure that our data will still be accessible.
This post was also published on the Community Data Science Collective blog.

16 June 2017

Elena 'valhalla' Grandi: Travel piecepack v0.1

Travel piecepack v0.1

Immagine/fotosocial.gl-como.it/photos/valha

A www.piecepack.org/ set of generic board game pieces is nice to have around in case of a sudden spontaneous need of gaming, but carrying my full set www.trueelena.org/fantastic/fe takes some room, and is not going to fit in my daily bag.

I've been thinking for a while that an half-size set could be useful, and between yesterday and today I've actually managed to do the first version.

It's (2d) printed on both sides of a single sheet of heavy paper, laminated and then cut, comes with both the basic suites and the playing card expansion and fits in a mint tin divided by origami boxes.

It's just version 0.1 because there are a few issues: first of all I'm not happy with the manual way I used to draw the page: ideally it would have been programmatically generated from the same svg files as the 3d piecepack (with the ability to generate other expansions), but apparently reading paths from an svg and writing it in another svg is not supported in an easy way by the libraries I could find, and looking for it was starting to take much more time than just doing it by hand.

I also still have to assemble the dice; in the picture above I'm just using the ones from the 3d-printed set, but they are a bit too big and only four of them fit in the mint tin. I already have the faces printed, so this is going to be fixed in the next few days.

Source files are available in the same git repository as the 3d-printable piecepack git.trueelena.org/cgit.cgi/3d/, with the big limitation mentioned above; updates will also be pushed there, just don't hold your breath for it :)

15 June 2017

Jeremy Bicha: #newinstretch : Latest WebKitGTK+

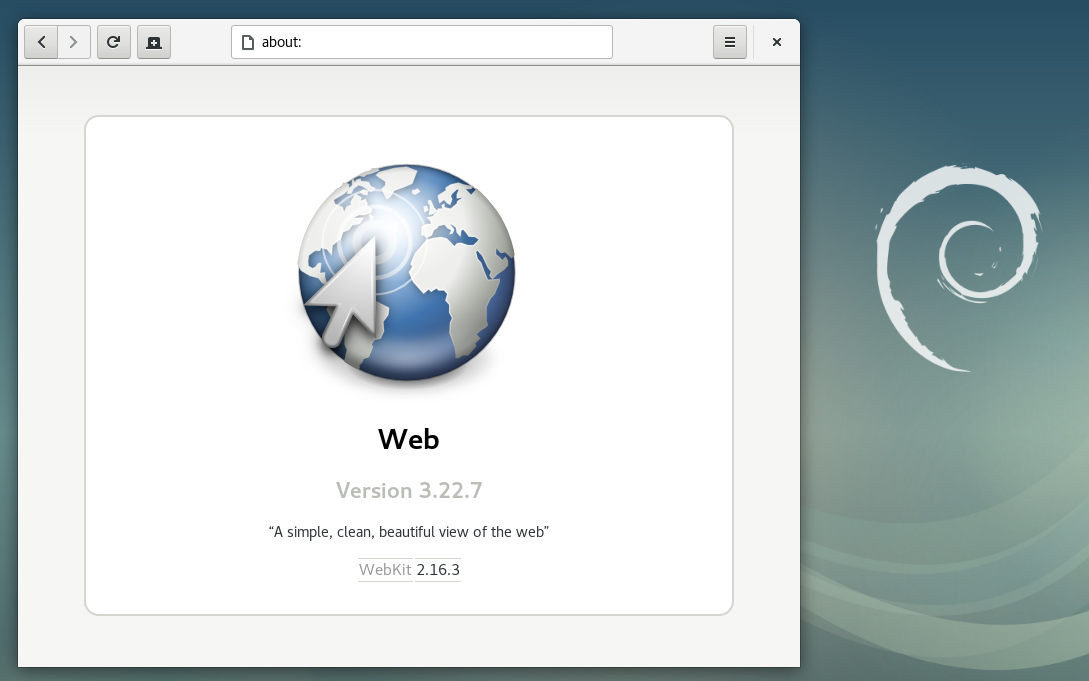
GNOME Web (Epiphany) in Debian 9 "Stretch" Debian 9 Stretch , the latest stable version of the venerable Linux distribution, will be released in a few days. I pushed a last-minute change to get the latest security and feature update of WebKitGTK+ (packaged as webkit2gtk 2.16.3) in before release. Carlos Garcia Campos discusses what s new in 2.16, but there are many, many more improvements since the 2.6 version in Debian 8. Like many things in Debian, this was a team effort from many people. Thank you to the WebKitGTK+ developers, WebKitGTK+ maintainers in Debian, Debian Release Managers, Debian Stable Release Managers, Debian Security Team, Ubuntu Security Team, and testers who all had some part in making this happen. As with Debian 8, there is no guaranteed security support for webkit2gtk for Debian 9. This time though, there is a chance of periodic security updates without needing to get the updates through backports. If you would like to help test the next proposed update, please contact me so that I can help coordinate this.

14 June 2017

Steve Kemp: Porting pfctl to Linux

If you have a bunch of machines running OpenBSD for firewalling purposes, which is pretty standard, you might start to use source-control to maintain the rulesets. You might go further, and use some kind of integration testing to deploy changes from your revision control system into production. Of course before you deploy any pf.conf file you need to test that the file contents are valid/correct. If your integration system doesn't run on OpenBSD though you have a couple of choices: I looked at this last year and got pretty far, but then got distracted. So the other day I picked it up again. It turns out that if you're patient it's not hard to use bison to generate some C code, then glue it together such that you can validate your firewall rules on a Linux system.
  deagol ~/pf.ctl $ ./pfctl ./pf.conf
  ./pf.conf:298: macro 'undefined_variable' not defined
  ./pf.conf:298: syntax error
Unfortunately I had to remove quite a lot of code to get the tool to compile, which means that while some failures like that above are caught others are missed. The example above reads:
vlans=" vlan1,vlan2 "
..
pass out on $vlans proto udp from $undefined_variable
Unfortunately the following line does not raise an error:
pass out on vlan12 inet proto tcp from <unknown> to $http_server port  80,443 
That comes about because looking up the value of the table named unknown just silently fails. In slowly removing more and more code to make it compile I lost the ability to keep track of table definitions - both their names and their values - Thus the fetching of a table by name has become a NOP, and a bogus name will result in no error. Now it is possible, with more care, that you could use a hashtable library, or similar, to simulate these things. But I kinda stalled, again. (Similar things happen with fetching a proto by name, I just hardcoded inet, gre, icmp, icmp6, etc. Things that I'd actually use.) Might be a fun project for somebody with some time anyway! Download the OpenBSD source, e.g. from a github mirror - yeah, yeah, but still. CVS? No thanks! - Then poke around beneath sbin/pfctl/. The main file you'll want to grab is parse.y, although you'll need to setup a bunch of headers too, and write yourself a Makefile. Here's a hint:
  deagol ~/pf.ctl $ tree
  .
    inc
      net
        pfvar.h
      queue.h
      sys
          _null.h
          refcnt.h
          tree.h
    Makefile
    parse.y
    pf.conf
    pfctl.h
    pfctl_parser.h
    y.tab.c
  3 directories, 11 files

Antoine Beaupr : Alioth moving toward pagure

Since 2003, the Debian project has been running a server called Alioth to host source code version control systems. The server will hit the end of life of the Debian LTS release (Wheezy) next year; that deadline raised some questions regarding the plans for the server over the coming years. Naturally, that led to a discussion regarding possible replacements. In response, the current Alioth maintainer, Alexander Wirt, announced a sprint to migrate to pagure, a free-software "Git-centered forge" written in Python for the Fedora project, which LWN covered last year. Alioth currently runs FusionForge, previously known as GForge, which is the free-software fork of the SourceForge code base when that service closed its source in 2001. Alioth hosts source code repositories, mainly Git and Subversion (SVN) and, like other "forge" sites, also offers forums, issue trackers, and mailing list services. While other alternatives are still being evaluated, a consensus has emerged on a migration plan from FusionForage to a more modern and minimal platform based on pagure.

Why not GitLab? While this may come as a surprise to some who would expect Debian to use the more popular GitLab project, the discussion and decision actually took place a while back. During a lengthy debate last year, Debian contributors discussed the relative merits of different code-hosting platforms, following the initiative of Debian Developer "Pirate" Praveen Arimbrathodiyil to package GitLab for Debian. At that time, Praveen also got a public GitLab instance running for Debian (gitlab.debian.net), which was sponsored by GitLab B.V. the commercial entity behind the GitLab project. The sponsorship was originally offered in 2015 by the GitLab CEO, presumably to counter a possible move to GitHub, as there was a discussion about creating a GitHub Organization for Debian at the time. The deployment of a Debian-specific GitLab instance then raised the question of the overlap with the already existing git.debian.org service, which is backed by Alioth's FusionForge deployment. It then seemed natural that the new GitLab instance would replace Alioth. But when Praveen directly proposed to move to GitLab, Wirt stepped in and explained that a migration plan was already in progress. The plan then was to migrate to a simpler gitolite-based setup, a decision that was apparently made in corridor discussions surrounding the Alioth Git replacement BoF held during Debconf 2015. The first objection raised by Wirt against GitLab was its "huge number of dependencies". Another issue Wirt identified was the "open core / enterprise model", preferring a "real open source system", an opinion which seems shared by other participants on the mailing list. Wirt backed his concerns with an hypothetical example:
Debian needs feature X but it is already in the enterprise version. We make a patch and, for commercial reasons, it never gets merged (they already sell it in the enterprise version). Which means we will have to fork the software and keep those patches forever. Been there done that. For me, that isn't acceptable.
This concern was further deepened when GitLab's Director of Strategic Partnerships, Eliran Mesika, explained the company's stewardship policy that explains how GitLab decides which features end up in the proprietary version. Praveen pointed out that:
[...] basically it boils down to features that they consider important for organizations with less than 100 developers may get accepted. I see that as a red flag for a big community like debian.
Since there are over 600 Debian Developers, the community seems to fall within the needs of "enterprise" users. The features the Debian community may need are, by definition, appropriate only to the "Enterprise Edition" (GitLab EE), the non-free version, and are therefore unlikely to end up in the "Community Edition" (GitLab CE), the free-software version. Interestingly, Mesika asked for clarification on which features were missing, explaining that GitLab is actually open to adding features to GitLab CE. The response from Debian Developer Holger Levsen was categorical: "It's not about a specific patch. Free GitLab and we can talk again." But beyond the practical and ethical concerns, some specific features Debian needs are currently only in GitLab EE. For example, debian.org systems use LDAP for authentication, which would obviously be useful in a GitLab deployment; GitLab CE supports basic LDAP authentication, but advanced features, like group or SSH-key synchronization, are only available in GitLab EE. Wirt also expressed concern about the Contributor License Agreement that GitLab B.V. requires contributors to sign when they send patches, which forces users to allow the release of their code under a non-free license. The debate then went on going through a exhaustive inventory of different free-software alternatives:
  • GitLab, a Ruby-based GitHub replacement, dual-licensed MIT/Commercial
  • Gogs, Go, MIT
  • Gitblit, Java, Apache-licensed
  • Kallithea, in Python, also supports Mercurial, GPLv3
  • and finally, pagure, also written Python, GPLv2
A feature comparison between each project was created in the Debian wiki as well. In the end, however, Praveen gave up on replacing Alioth with GitLab because of the controversy and moved on to support the pagure migration, which resolved the discussion in July 2016. More recently, Wirt admitted in an IRC conversation that "on the technical side I like GitLab a lot more than pagure" and that "as a user, GitLab is much nicer than pagure and it has those nice CI [continuous integration] features". However, as he explained in his blog "GitLab is Opencore, [and] that it is not entirely opensource. I don't think we should use software licensed under such a model for one of our core services" which leaves pagure as the only stable candidate. Other candidates were excluded on technical grounds, according to Wirt: Gogs "doesn't scale well" and a quick security check didn't yield satisfactory results; "Gitblit is Java" and Kallithea doesn't have support for accessing repositories over SSH (although there is a pending pull request to add the feature). In an email interview, Sid Sijbrandij, CEO of GitLab, did say that "we want to make sure that our open source edition can be used by open source projects". He gave examples of features liberated following requests by the community, such as branded login pages for the VLC project and GitLab Pages after popular demand. He stressed that "There are no artificial limits in our open source edition and some organizations use it with more than 20.000 users." So if the concern of the Debian community is that features may be missing from GitLab CE, there is definitely an opening from GitLab to add those features. If, however, the concern is purely ethical, it's hard to see how an agreement could be reached. As Sijbrandij put it:
On the mailinglist it seemed that some Debian maintainers do not agree with our open core business model and demand that there is no proprietary version. We respect that position but we don't think we can compete with the purely proprietary software like GitHub with this model.

Working toward a pagure migration The issue of Alioth maintenance came up again last month when Boyuan Yang asked what would happen to Alioth when support for Debian LTS (Wheezy) ends next year. Wirt brought up the pagure migration proposal and the community tried to make a plan for the migration. One of the issues raised was the question of the non-Git repositories hosted on Alioth, as pagure, like GitLab, only supports Git. Indeed, Ben Hutchings calculated that while 90% (\~19,000) of the repositories currently on Alioth are Git, there are 2,400 SVN repositories and a handful of Mercurial, Bazaar (bzr), Darcs, Arch, and even CVS repositories. As part of an informal survey, however, most packaging teams explained they either had already migrated away from SVN to Git or were in the process of doing so. The largest CVS user, the web site team, also explained it was progressively migrating to Git. Mattia Rizzolo then proposed that older repository services like SVN could continue running even if FusionForge goes down, as FusionForge is, after all, just a web interface to manage those back-end services. Repository creation would be disabled, but older repositories would stay operational until they migrate to Git. This would, effectively, mean the end of non-Git repository support for new projects in the Debian community, at least officially. Another issue is the creation of a Debian package for pagure. Ironically, while Praveen and other Debian maintainers have been working for 5 years to package GitLab for Debian, pagure isn't packaged yet. Antonio Terceiro, another Debian Developer, explained this isn't actually a large problem for debian.org services: "note that DSA [Debian System Administrator team] does not need/want the service software itself packaged, only its dependencies". Indeed, for Debian-specific code bases like ci.debian.net or tracker.debian.org, it may not make sense to have the overhead of maintaining Debian packages since those tools have limited use outside of the Debian project directly. While Debian derivatives and other distributions could reuse them, what usually happens is that other distributions roll their own software, like Ubuntu did with the Launchpad project. Still, Paul Wise, a member of the DSA team, reasoned that it was better, in the long term, to have Debian packages for debian.org services:
Personally I'm leaning towards the feeling that all configuration, code and dependencies for Debian services should be packaged and subjected to the usual Debian QA activities but I acknowledge that the current archive setup (testing migration plus backporting etc) doesn't necessarily make this easy.
Wise did say that "DSA doesn't have any hard rules/policy written down, just evaluation on a case-by-case basis" which probably means that pagure packaging will not be a blocker for deployment. The last pending issue is the question of the mailing lists hosted on Alioth, as pagure doesn't offer mailing list management (nor does GitLab). In fact, there are three different mailing list services for the Debian project: Wirt, with his "list-master hat" on, explained that the main mailing list service is "not really suited as a self-service" and expressed concern at the idea of migrating the large number mailing lists hosted on Alioth. Indeed, there are around 1,400 lists on Alioth while the main service has a set of 300 lists selected by the list masters. No solution for those mailing lists was found at the time of this writing. In the end, it seems like the Debian project has chosen pagure, the simpler, less featureful, but also less controversial, solution and will use the same hosting software as their fellow Linux distribution, Fedora. Wirt is also considering using FreeIPA for account management on top of pagure. The plan is to migrate away from FusionForge one bit at a time, and pagure is the solution for the first step: the Git repositories. Lists, other repositories, and additional features of FusionForge will be dealt with later on, but Wirt expects a plan to come out of the upcoming sprint. It will also be interesting to see how the interoperability promises of pagure will play out in the Debian world. Even though the federation features of pagure are still at the early stages, one can already clone issues and pull requests as Git repositories, which allows for a crude federation mechanism. In any case, given the long history and the wide variety of workflows in the Debian project, it is unlikely that a single tool will solve all problems. Alioth itself has significant overlap with other Debian services; not only does it handle mailing lists and forums, but it also has its own issue tracker that overlaps with the Debian bug tracking system (BTS). This is just the way things are in Debian: it is an old project with lots of moving part. As Jonathan Dowland put it: "The nature of the project is loosely-coupled, some redundancy, lots of legacy cruft, and sadly more than one way to do it." Hopefully, pagure will not become part of that "legacy redundant cruft". But at this point, the focus is on keeping the services running in a simpler, more maintainable way. The discussions between Debian and GitLab are still going on as we speak, but given how controversial the "open core" model used by GitLab is for the Debian community, pagure does seem like a more logical alternative.
Note: this article first appeared in the Linux Weekly News.

Sjoerd Simons: Debian Jessie on Raspberry Pi 2

Apart from being somewhat slow, one of the downsides of the original Raspberry Pi SoC was that it had an old ARM11 core which implements the ARMv6 architecture. This was particularly unfortunate as most common distributions (Debian, Ubuntu, Fedora, etc) standardized on the ARMv7-A architecture as a minimum for their ARM hardfloat ports. Which is one of the reasons for Raspbian and the various other RPI specific distributions. Happily, with the new Raspberry Pi 2 using Cortex-A7 Cores (which implement the ARMv7-A architecture) this issue is out of the way, which means that a a standard Debian hardfloat userland will run just fine. So the obvious first thing to do when an RPI 2 appeared on my desk was to put together a quick Debian Jessie image for it. The result of which can be found at: https://images.collabora.co.uk/rpi2/ Login as root with password debian (Obviously do change the password and create a normal user after booting). The image is 3G, so should fit on any SD card marketed as 4G or bigger. Using bmap-tools for flashing is recommended, otherwise you'll be waiting for 2.5G of zeros to be written to the card, which tends to be rather boring. Note that the image is really basic and will just get you to a login prompt on either serial or hdmi, batteries are very much not included, but can be apt-getted :). Technically, this image is simply a Debian Jessie debootstrap with a extra packages for hardware support. Unlike Raspbian the first partition (which contains the firmware & kernel files to boot the system) is mounted on /boot/firmware rather then on /boot. This is because the VideoCore expects the first partition to be a FAT filesystem, but mounting FAT on /boot really doesn't work right on Debian systems as it contains files managed by dpkg (e.g. the kernel package) which requires a POSIX compatible filesystem. Essentially the same reason why Debian is using /boot/efi for the ESP partition on Intel systems rather the mounting it on /boot directly. For reference, the RPI2 specific packages in this image are from https://repositories.collabora.co.uk/debian/ in the jessie distribution and rpi2 component (this repository is enabled by default on the image). The relevant packages there are: For the future, it would be nice to see the Raspberry Pi 2 support out of the box on Debian. For that to happen, the most important thing would be to have some mainline kernel support for this board (supporting multiplatform!) so it can be build as part of debians armmp kernel flavour. And ideally, having the firmware load a bootloader (such as u-boot) rather than a kernel directly to allow for a much more flexible boot sequence and support for using an initramfs (u-boot has some support for the original Raspberry Pi, so adding Raspberry Pi 2 support should hopefully not be too tricky) Update: An updated image (20150705) is available with the latest packages from Jessie and a GPG key that's not expired :).

Sjoerd Simons: Debian armhf VM on arm64 server

At Collabora one of the many things we do is build Debian derivatives/overlays for customers on a variety of architectures including 32 bit and 64 bit ARM systems. And just as Debian does, our OBS system builds on native systems rather than emulators. Luckily with the advent of ARM server systems some years ago building natively for those systems has been a lot less painful than it used to be. For 32 bit ARM we've been relying on Calxeda blade servers, however Calxeda unfortunately tanked ages ago and the hardware is starting to show its age (though luckily Debian Stretch does support it properly, so at least the software is still fresh). On the 64 bit ARM side, we're running on Gigabyte MP30-AR1 based servers which can run 32 bit arm code (As opposed to e.g. ThunderX based servers which can only run 64 bit code). As such running armhf VMs on them to act as build slaves seems a good choice, but setting that up is a bit more involved than it might appear. The first pitfall is that there is no standard bootloader or boot firmware available in Debian to boot on the "virt" machine emulated by qemu (I didn't want to use an emulation of a real machine). That also means there is nothing to pick the kernel inside the guest at boot nor something which can e.g. have the guest network boot, which means direct kernel booting needs to be used. The second pitfall was that the current Debian Stretch armhf kernel isn't built with support for the generic PCI host controller which the qemu virtual machine exposes, which means no storage and no network shows up in the guest. Hopefully that will get solved soonish (Debian bug 864726) and can be in a Stretch update, until then a custom kernel package is required using the patch attach to the bug report is required but I won't go into that any further in this post. So on the happy assumption that we have a kernel that works, the challenge left is to nicely manage direct kernel loading. Or more specifically, how ensure the hosts boots the kernel the guest has installed via the standard apt tools without having to copy kernels around between guest/host, which essentially comes down to exposing /boot from the guest to the host. The solution we picked is to use qemu's 9pfs support to share a folder from the host and use that as /boot of the guest. For the 9p folder the "mapped" security mode seems needed as the "none" mode seems to get confused by dpkg (Debian bug 864718). As we're using libvirt as our virtual machine manager the remainder of how to glue it all together will be mostly specific to that. First step is to install the system, mostly as normal. One can directly boot into the vmlinuz and initrd.gz provided by normal Stretch armhf netboot installer (downloaded into e.g /tmp). The setup overall is straight-forward with a few small tweaks: Apart from those tweaks the resulting example command is similar to the one that can be found in the virt-install man-page:
virt-install --name armhf-vm --arch armv7l --memory 512 \
  --disk /srv/armhf-vm.img,bus=virtio
  --filesystem /srv/armhf-vm-boot,virtio-boot,mode=mapped \
  --boot=kernel=/tmp/vmlinuz,initrd=/tmp/initrd.gz,kernel_args="console=ttyAMA0,root=/dev/vda1"

Run through the install as you'd normally would. Towards the end the installer will likely complain it can't figure out how to install a bootloader, which is fine. Just before ending the install/reboot, switch to the shell and copy the /boot/vmlinuz and /boot/initrd.img from the target system to the host in some fashion (e.g. chroot into /target and use scp from the installed system). This is required as the installer doesn't support 9p, but to boot the system an initramfs will be needed with the modules needed to mount the root fs, which is provided by the installed initramfs :). Once that's all moved around, the installer can be finished. Next, booting the installed system. For that adjust the libvirt config (e.g. using virsh edit and tuning the xml) to use the kernel and initramfs copied from the installer rather then the installer ones. Spool up the VM again and it should happily boot into a freshly installed Debian system. To finalize on the guest side /boot should be moved onto the shared 9pfs, the fstab entry for the new /boot should look something like:
virtio-boot /boot  9p trans=virtio,version=9p2000.L,x-systemd.automount 0 0

With that setup, it's just a matter of shuffling the files in /boot around to the new filesystem and the guest is done (make sure vmlinuz/initrd.img stay symlinks). Kernel upgrades will work as normal and visible to the host. Now on the host side there is one extra hoop to jump through, as the guest uses the 9p mapped security model symlinks in the guest will be normal files on the host containing the symlink target. To resolve that one, we've used libvirt's qemu hook support to setup a proper symlink before the guest is started. Below is the script we ended up using as an example (/etc/libvirt/hooks/qemu):
vm=$1
action=$2
bootdir=/srv/$ vm -boot
if [ $ action  != "prepare" ] ; then
  exit 0
fi
if [ ! -d $ bootdir  ] ; then
  exit 0
fi
ln -sf $(basename $(cat $ bootdir /vmlinuz))  $ bootdir /virtio-vmlinuz
ln -sf $(basename $(cat $ bootdir /initrd.img))  $ bootdir /virtio-initrd.img

With that in place, we can simply point the libvirt definition to use /srv/$ vm -boot/virtio- vmlinuz,initrd.img as the kernel/initramfs for the machine and it'll automatically get the latest kernel/initramfs as installed by the guest when the VM is started. Just one final rough edge remains, when doing reboot from the VM libvirt leaves qemu to handle that rather than restarting qemu. This unfortunately means a reboot won't pick up a new kernel if any, for now we've solved this by configuring libvirt to stop the VM on reboot instead. As we typically only reboot VMs on kernel (security) upgrades, while a bit tedious, this avoid rebooting with an older kernel/initramfs than intended.

Mike Gabriel: Ayatana Indicators

In the near future various upstream projects related to the Ubuntu desktop experience as we have known it so far may become only sporadically maintained or even fully unmaintained. Ubuntu will switch to the Gnome desktop environment with 18.04 LTS as its default desktop, maybe even earlier. The Application Indicators [1] brought into being by Canonical Ltd. will not be needed in Gnome (AFAIK) any more. We can expect the Application Indicator related projects become unmaintained upstream. (In fact I have recently been offered continuation of upstream maintenance of libdbusmenu). Historical Background This all started at Ubuntu Developer Summit 2012 when Canonical Ltd. announced Ubuntu to become the successor of Windows XP in business offices. The Unity Greeter received an Remote Login Service enhancement: since then it supports Remote Login to Windows Terminal Servers. The question came up, why Remote Login to Linux servers--maybe even Ubuntu machines--is not on the agenda. It turned out, that it wasn't even a discussable topic. At that time, I started looking into the Unity Greeter code, adding support for X2Go Logon into Unity Greeter. I never really stopped looking at the greeter code from time to time. Since then, it turned into some sort of a hobby... While looking into the Unity Greeter code over the past years and actually forking Unity Greeter as Arctica Greeter [2] in September 2015, I also started looking into the Application Indicators concept just recently. And I must say, the more I have been looking into it, the more I have started liking the concept behind Application Indicators. The basic idea is awesome. However, lately all indicators became more and more Ubuntu-centric and IMHO too polluted by code related to the just declared dead Ubuntu phablet project. Forking Application Indicators Saying all this, I recently forked Application Indicators as Ayatana Indicators. At the moment I represent upstream and Debian package maintainer in one person. Ideally, this is only temporary and more people join in. (I heard some Unity 7 maintainers think about switching to Ayatana Indicators for the now community maintained Unity 7). The goal is to provide Ayatana Indicators to all desktop environments generically, all that want to use them, either as default or optionally. Release-wise, the idea is to strictly differentiate between upstream and Debian downstream in the release cycles of the various related components. I hope, noone is too concerned about the choice of name, as the "Ayatana" word actually was first used for upstream efforts inside Ubuntu [3]. Using the Ayatana term for the indicator forks is meant as honouring the previously undertaken efforts. I have seen very good work, so far, while going through the indicators' code. The upstream code must not be distro-specific, but, of course, can be distro-aware. Contributions Welcome The Ayatana Indicators upstream project components are currently hosted on Github under the umbrella of the Arctica Project. Regarding Debian, first uploads have recently been accepted to Debian experimental. The Debian packages are maintained under the umbrella of the revived Ayatana Packagers team [4]. Meet you at the Ayatana Indicators BoF at DebConf 17 (hopefully) For DebConf 17 (yeah, I am going there, if all plans work out well!!!!) I have submitted a BoF on this topic (let's hope, it gets accepted...). I'd like to give a quick overview on the current status of above named efforts and reasonings behind my commitment to the work. Most of the time during that BoF I would like to get into discussion with desktop maintainers, possibly upstream developers, Ubuntu developers, etc. Anyone who sees an asset in the Indicators approach is welcome to share and contribute. References

Nicolas Dandrimont: DebConf 17 bursaries: update your status now!

TL;DR: if you applied for a DebConf 17 travel bursary, and you haven t accepted it yet, login to the DebConf website and update your status before June 20th or your bursary grant will be gone. *blows dust off the blog* As you might be aware, DebConf 17 is coming soon and it s gonna be the biggest DebConf in Montr al ever. Of course, what makes DebConf great is the people who come together to work on Debian, share their achievements, and help draft our cunning plans to take over the world. Also cheese. Lots and lots of cheese. To that end, the DebConf team had initially budgeted US$40,000 for travel grants ($30,000 for contributors, $10,000 for diversity and inclusion grants), allowing the bursaries team to bring people from all around the world who couldn t have made it to the conference. Our team of volunteers rated the 188 applications, we ve made a ranking (technically, two rankings : one on contribution grounds and one on D&I grounds), and we finally sent out a first round of grants last week. After the first round, the team made a new budget assessment, and thanks to the support of our outstanding sponsors, an extra $15,000 has been allocated for travel stipends during this week s team meeting, with the blessing of the DPL. We ve therefore been able to send a second round of grants today. Now, if you got a grant, you have two things to do : you need to accept your grant, and you need to update your requested amount. Both of those steps allow us to use our budget more wisely: having grants expire frees money up to get more people to the conference earlier. Having updated amounts gives us a better view of our overall budget. (You can only lower your requested amount, as we can t inflate our budget) Our system has sent mails to everyone, but it s easy enough to let that email slip (or to not receive it for some reason). It takes 30 seconds to look at the status of your request on the DebConf 17 website, and even less to do the few clicks needed for you to accept the grant. Please do so now! OK, it might take a few minutes if your SSO certificate has expired and you have to look up the docs to renew it. The deadline for the first round of travel grants (which went out last week) is June 20th. The deadline for the second round (which went out today) is June 24th. If somehow you can t login to the website before the deadline, the bursaries team has an email address you can use. We want to send out a third round of grants on June 25th, using the money people freed up: our current acceptance ratio is around 40%, and a lot of very strong applications have been deferred. We don t want them to wait up until July to get a definitive answer, so thanks for helping us! bient t Montr al !

Dirk Eddelbuettel: #7: C++14, R and Travis -- A useful hack

Welcome to the seventh post in the rarely relevant R ramblings series, or R4 for short. We took a short break as several conferences and other events interfered during the month of May, keeping us busy and away from this series. But we are back now with a short and useful hack I came up with this weekend. The topic is C++14, i.e. the newest formally approved language standard for C++, and its support in R and on Travis CI. With release R 3.4.0 of a few weeks ago, R now formally supports C++14. Which is great. But there be devils. A little known fact is that R hangs on to its configuration settings from its own compile time. That matters in cases such as the one we are looking at here: Travis CI. Travis is a tremendously useful and widely-deployed service, most commonly connected to GitHub driving "continuous integration" (the 'CI') testing after each commit. But Travis CI, for as useful as it is, is also maddingly conservative still forcing everybody to live and die by [Ubuntu 14.04]http://releases.ubuntu.com/14.04/). So while we all benefit from the fine work by Michael who faithfully provides Ubuntu binaries for distribution via CRAN (based on the Debian builds provided by yours truly), we are stuck with Ubuntu 14.04. Which means that while Michael can provide us with current R 3.4.0 it will be built on ancient Ubuntu 14.04. Why does this matter, you ask? Well, if you just try to turn the very C++14 support added to R 3.4.0 on in the binary running on Travis, you get this error:
** libs
Error in .shlib_internal(args) : 
  C++14 standard requested but CXX14 is not defined
And you get it whether or not you define CXX14 in the session. So R (in version 3.4.0) may want to use C++14 (because a package we submitted requests it), but having been built on the dreaded Ubuntu 14.04, it just can't oblige. Even when we supply a newer compiler. Because R hangs on to its compile-time settings rather than current environment variables. And that means no C++14 as its compile-time compiler was too ancient. Trust me, I tried: adding not only g++-6 (from a suitable repo) but also adding C++14 as the value for CXX_STD. Alas, no mas. The trick to overcome this is twofold, and fairly straightforward. First off, we just rely on the fact that g++ version 6 defaults to C++14. So by supplying g++-6, we are in the green. We have C++14 by default without requiring extra options. Sweet. The remainder is to tell R to not try to enable C++14 even though we are using it. How? By removing CXX_STD=C++14 on the fly and just for Travis. And this can be done easily with a small script configure which conditions on being on Travis by checking two environment variables:
#!/bin/bash
## Travis can let us run R 3.4.0 (from CRAN and the PPAs) but this R version
## does not know about C++14.  Even though we can select CXX_STD = C++14, R
## will fail as the version we use there was built in too old an environment,
## namely Ubuntu "trusty" 14.04.
##
## So we install g++-6 from another repo and rely on the fact that is
## defaults to C++14.  Sadly, we need R to not fail and hence, just on
## Travis, remove the C++14 instruction
if [[ "$ CI " == "true" ]]; then
    if [[ "$ TRAVIS " == "true" ]]; then 
        echo "** Overriding src/Makevars and removing C++14 on Travis only"
        sed -i 's CXX_STD = CXX14 ' src/Makevars
    fi
fi
I have deployed this now for two sets of builds in two distinct repositories for two "under-development" packages not yet on CRAN, and it just works. In case you turn on C++14 via SystemRequirements: in the file DESCRIPTION, you need to modify it here. So to sum up, there it is: C++14 with R 3.4.0 on Travis. Only takes a quick Travis-only modification.

13 June 2017

Reproducible builds folks: Reproducible Builds: week 111 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday June 4 and Saturday June 10 2017: Past and upcoming events On June 10th, Chris Lamb presented at the Hong Kong Open Source Conference 2017 on reproducible builds. Patches and bugs filed Reviews of unreproducible packages 7 package reviews have been added, 10 have been updated and 14 have been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: Two FTBFS issues of LEDE (exposed in our setup) were found and were fixed: diffoscope development tests.reproducible-builds.org: Alexander 'lynxis' Couzens made some changes for testing LEDE and OpenWrt: Hans-Christoph Steiner, for testing F-Droid: Daniel Shahaf, for testing Debian: Holger 'h01ger' Levsen, for testing Debian: Misc. This week's edition was written by Ximin Luo, Chris Lamb and Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Gunnar Wolf: Reporting progress on the translation infrastructure

Some days ago, I blogged asking for pointers to get started with the translation of Made with Creative Commons. Thank you all for your pointers and ideas! To the people that answered via private mail, via IRC, via comments on the blog. We have made quite a bit of progress so far; I want to test some things before actually sending a call for help. What do we have?
Git repository set up
I had already set up a repository at GitLab; right now, the contents are far from useful, they merely document what I have done so far. I have started talking with my Costa Rican friend Leo Arias, who is also interested in putting some muscle behind this translation, and we are both the admins to this project.
Talked with the authors
Sarah is quite enthusiastic about us making this! I asked her to hold a little bit before officially announcing there is work ongoing... I want to get bits of infrastructure ironed out first. Important Talking with her, she discussed the tools they used for authoring the book. It made me less of a purist :) Instead of starting from something "pristine", our master source will be the PDF export of the Google Docs document.
Markdown conversion
Given that translation tools work over the bits of plaintext, we want to work with the "plainest" rendition of the document, which is Markdown. I found that Pandoc does a very good approximation to what we need (that is, introduces very little "ugly" markup elements). Converting the ODT into Markdown is as easy as:
$ pandoc -f odt MadewithCreativeCommonsmostup-to-dateversion.odt -t markdown > MadewithCreativeCommonsmostup-to-dateversion.md
Of course, I want to fine-tune this as much as possible.
Producing a translatable .po file
I have used Gettext to translate user interfaces; it is a tool very well crafted for that task. Translating a book is quite different: How and where does it break and join? How are paragraphs "strung" together into chapters, parts, a book? That's a task for PO 4 Anything (po4a). As simple as this:
po4a-gettextize -f text -m MadewithCreativeCommonsmostup-to-dateversion.md -p MadewithCreativeCommonsmostup-to-dateversion.po -M utf-8
I tested the resulting file with my good ol' trusty poedit, and it works... Very nicely!
What is left to do?

Dirk Eddelbuettel: RcppMsgPack 0.1.1

A new package! Or at least new on CRAN as the very initial version 0.1.0 had been available via the ghrr drat for over a year. But now we have version 0.1.1 to announce as a CRAN package. RcppMspPack provides R with MessagePack header files for use via C++ (or C, if you must) packages such as RcppRedis. MessagePack itself is an efficient binary serialization format. It lets you exchange data among multiple languages like JSON. But it is faster and smaller. Small integers are encoded into a single byte, and typical short strings require only one extra byte in addition to the strings themselves. MessagePack is used by Redis and many other projects, and has bindings to just about any language. To use this package, simply add it to the LinkingTo: field in the DESCRIPTION field of your R package---and the R package infrastructure tools will then know how to set include flags correctly on all architectures supported by R. More information may be on the RcppMsgPack page. Issues and bugreports should go to the GitHub issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 June 2017

Sven Hoexter: UEFI PXE preseeded Debian installation on HPE DL120

We bought a bunch of very cheap low end HPE DL120 server. Enough to warrant a completely automated installation setup. Shouldn't be that much of a deal, right? Get dnsmasq up and running, feed it a preseed.cfg and be done with it. In practise it took us more hours then we expected. Setting up the hardware Our hosts are equipped with an additional 10G dual port NIC and we'd like to use this NIC for PXE booting. That's possible, but it requires you to switch to UEFI boot. Actually it enables you to boot from any available NIC. Setting up dnsmasq We decided to just use the packaged debian-installer from jessie and do some ugly things like overwritting files in /usr/lib via ansible later on. So first of all install debian-installer-8-netboot-amd64 and dnsmasq, then enroll our additional config for dnsmasq, ours looks like this:
domain=int.foobar.example
dhcp-range=192.168.0.240,192.168.0.242,255.255.255.0,1h
dhcp-boot=bootnetx64.efi
pxe-service=X86-64_EFI, "Boot UEFI PXE-64", bootnetx64.efi
enable-tftp
tftp-root=/usr/lib/debian-installer/images/8/amd64/text
dhcp-option=3,192.168.0.1
dhcp-host=00:c0:ff:ee:00:01,192.168.0.123,foobar-01
Now you've to link /usr/lib/debian-installer/images/8/amd64/text/bootnetx64.efi to /usr/lib/debian-installer/images/8/amd64/text/debian-installer/amd64/bootnetx64.efi. That got us of the ground and we had a working UEFI PXE boot that got us into debian-installer. Feeding d-i the preseed file Next we added some grub.cfg settings and parameterized some basic stuff to be handed over to d-i via the kernel command line. You'll find the correct grub.cfg in /usr/lib/debian-installer/images/8/amd64/text/debian-installer/amd64/grub/grub.cfg. We added the following two lines to automate the start of the installer:
set default="0"
set timeout=5
and our kernel command line looks like this:
 linux    /debian-installer/amd64/linux vga=788 --- auto=true interface=eth1 netcfg/dhcp_timeout=60 netcfg/choose_interface=eth1 priority=critical preseed/url=tftp://192.168.0.2/preseed.cfg quiet
Important points: preseeed.cfg, GPT and ESP One of the most painful points was the fight to find out the correct preseed values to install with GPT to create a ESP (EFI system partition) and use LVM for /. Relevant settings are:
# auto method must be lvm
d-i partman-auto/method string lvm
d-i partman-lvm/device_remove_lvm boolean true
d-i partman-md/device_remove_md boolean true
d-i partman-lvm/confirm boolean true
d-i partman-lvm/confirm_nooverwrite boolean true
d-i partman-basicfilesystems/no_swap boolean false
# Keep that one set to true so we end up with a UEFI enabled
# system. If set to false, /var/lib/partman/uefi_ignore will be touched
d-i partman-efi/non_efi_system boolean true
# enforce usage of GPT - a must have to use EFI!
d-i partman-basicfilesystems/choose_label string gpt
d-i partman-basicfilesystems/default_label string gpt
d-i partman-partitioning/choose_label string gpt
d-i partman-partitioning/default_label string gpt
d-i partman/choose_label string gpt
d-i partman/default_label string gpt
d-i partman-auto/choose_recipe select boot-root-all
d-i partman-auto/expert_recipe string \
boot-root-all :: \
538 538 1075 free \
$iflabel  gpt   \
$reusemethod    \
method  efi   \
format    \
. \
128 512 256 ext2 \
$defaultignore    \
method  format   format    \
use_filesystem    filesystem  ext2   \
mountpoint  /boot   \
. \
1024 4096 15360 ext4 \
$lvmok    \
method  format   format    \
use_filesystem    filesystem  ext4   \
mountpoint  /   \
. \
1024 4096 15360 ext4 \
$lvmok    \
method  format   format    \
use_filesystem    filesystem  ext4   \
mountpoint  /var   \
. \
1024 1024 -1 ext4 \
$lvmok    \
method  format   format    \
use_filesystem    filesystem  ext4   \
mountpoint  /var/lib   \
.
# This makes partman automatically partition without confirmation, provided
# that you told it what to do using one of the methods above.
d-i partman-partitioning/confirm_write_new_label boolean true
d-i partman/choose_partition select finish
d-i partman-md/confirm boolean true
d-i partman/confirm boolean true
d-i partman/confirm_nooverwrite boolean true
# This is fairly safe to set, it makes grub install automatically to the MBR
# if no other operating system is detected on the machine.
d-i grub-installer/only_debian boolean true
d-i grub-installer/with_other_os boolean true
d-i grub-installer/bootdev  string /dev/sda
I hope that helps to ease the processes to setup automated UEFI PXE installations for some other people out there still dealing with bare metal systems. Some settings took us some time to figure out, for example d-i partman-efi/non_efi_system boolean true required some searching on codesearch.d.n (amazing ressource if you're writing preseed files and need to find the correct templates) and reading scripts on git.d.o where you'll find the source for partman-* and grub-installer. Kudos Thanks especially to P.P. and M.K. to figure out all those details.

Craig Small: psmisc 23.0

I had to go check but it has been over 3 years since the last psmisc release back in February 2014. I really didn t think it had been that long ago. Anyhow, with no further delay, psmisc version 23.0 has been released today! Update: 23.1 is out now, removed some debug line out of killall and shipped two missing documents. This release is just a few feature update and minor bug fixes. The changelog lists them all, but these are the highlights. killall namespace filtering killall was not aware of namespaces, which meant if you wanted to kill all specified processes in the root namespace, it did that, but also all the child namespaces. So now it will only by default kill processes in its current PID namespace, and there is a new -n flag to specify 0 for all or a PID to use the namespace of. killall command name parsing This is similar to the bug sudo had where it didn t parse process names properly. A crafted process name meant killall missed it, even if you specified the username or tty. While I checked for procps having this problem (it didn t) I didn t check psmisc. Now killall and sudo use a similar parsing method as procps. New program: pslog Wanted to know what logs a process is writing to? pslog can help you here. It will report on what files in /var/log are opened by the specified process ID.
pslog 26475
Pid no 26475:
Log path: /opt/observium/logs/error_log
Log path: /var/log/apache2/other_vhosts_access.log
Log path: /opt/observium/logs/access_log
Finding psmisc psmisc will be available in your usual distributions shortly. The Debian packages are about to be uploaded and will be in the sid distribution soon. Other distributions I imagine will follow. For the source code, look in the GitLab repository or the Sourceforge file location.

9 June 2017

John Goerzen: Fixing the Problems with Docker Images

I recently wrote about the challenges in securing Docker container contents, and in particular with keeping up-to-date with security patches from all over the Internet. Today I want to fix that. Besides security, there is a second problem: the common way of running things in Docker pretends to provide a traditional POSIX API and environment, but really doesn t. This is a big deal. Before diving into that, I want to explain something: I have often heard it said the Docker provides single-process containers. This is unambiguously false in almost every case. Any time you have a shell script inside Docker that calls cp or even ls, you are running a second process. Web servers from Apache to whatever else use processes or threads of various types to service multiple connections at once. Many Docker containers are single-application, but a process is a core part of the POSIX API, and very little software would work if it was limited to a single process. So this is my little plea for more precise language. OK, soapbox mode off. Now then, in a traditional Linux environment, besides your application, there are other key components of the system. These are usually missing in Docker containers. So today, I will fix this also. In my docker-debian-base images, I have prepared a system that still has only 11MB RAM overhead, makes minimal changes on top of Debian, and yet provides a very complete environment and API. Here s what you get: The above goes into my minimal image. Additional images add layers on top of it, and here are some of the features they add: All of the above, including the optional features, has an 11MB overhead on start. Not bad for so much, right? From here, you can layer on top all your usual Dockery things. You can still run one application per container. But you can now make sure your disk doesn t fill up from logs, run your database vacuuming commands at will, have your blog download its RSS feeds every few minutes, etc all from within the container, as it should be. Furthermore, you don t have to reinvent the wheel, because Debian already ships with things to take care of a lot of this out of the box and now those tools will just work. There is some popular work done in this area already by phusion s baseimage-docker. However, I made my own for these reasons: Finally a word on the choice to use sysvinit. It would have been simpler to use systemd here, since it is the default in Debian these days. Unfortunately, systemd requires you to poke some holes in the Docker security model, as well as mount a cgroups filesystem from the host. I didn t consider this acceptable, and sysvinit ran without these workarounds, so I went with it. With all this, Docker becomes a viable replacement for KVM for various services on my internal networks. I ll be writing about that later.

Jonathan Dowland: Western Digital Hard Drive head parking

I stumbled across some information about pathological behaviour of Western Digital Green (and some Red) hard drives relating to drive-head parking when the device is idle. In some circumstances, a particular pattern of drive activity can result in the drive head being repeatedly parked and un-parked in short intervals, possibly* resulting in excess wear on the drive. Apparently* the drive head parking is recorded in the S.M.A.R.T. "Load Cycle Count" attribute. I have two WD Red drives in my NAS, one for live data and one for backup. The latter drive is basically unused most of the day until scheduled backup jobs kick in and those jobs are all clustered together. I already unmount the backup filesystems when the jobs are not active (I wrote about this in mount-on-demand backups). Inspecting the S.M.A.R.T. attributes was surprising:
drive power on hours load cycle count
regular 12143 348
backup 12191 13043
It certainly looks like my backup drive has a much higher load cycle count than you might expect for a mostly-idle drive. I checked the attributes again 24 hours later and the regular drive had incremented by a single cycle, whilst the backup drive went up by 56. There are some official tools from Western Digital that makes an adjustment to the idle timeouts for head parking on the drives. There's also an unofficial tool idle3tcl to do the same, which is packaged in Debian. The unofficial tool let you set and fetch a particular value from the drive firmware. I don't know for sure* that the official tool does exactly the same thing, and nothing else. One advantage of the unofficial tool is it lets you read the value as well as write it. I tried the unofficial tool to get the drive's default value, which was 0x8a, and bump it to the maximum of 0xff. I then tried the official tool then fetched the value again: interestingly the official tool had reset the value back to 0x8a. I haven't managed to assess the impact of these changes on the attrition rate yet because I need to perform a cold boot for the change to take effect and that isn't convenient just now. My plan is to try and disable the feature completely via the unofficial tool. If that rectifies the issue I will then investigate changing the power management settings by hand at backup start/end time, perhaps via hdparm. ( The problem with these kind of issues is there is precious little in the way of reliable documentation as to the real issue, real drive behaviour, etc. I've marked a few sections of this blog post with * asterisks to indicate where we are having to make informed guesses. )

8 June 2017

Norbert Preining: Running in the Kanazawa hills

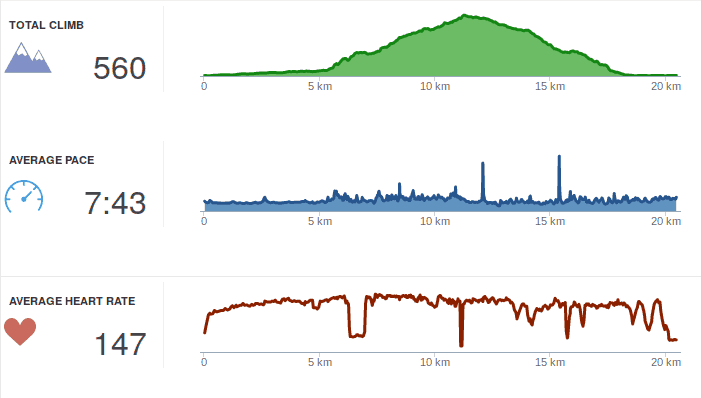
Sometimes I needed a short break from work, and usually I go a bit running. Normally I run between five and ten km, just around our flat. But yesterday I somehow thought it might be a good idea to run through the hills near by. I usually drive up there to a climbing spot or a cafe, so it will for sure not be that long. Well, my estimation was wrong
Turned out to be 20km and quite a trip up and down, in fact 560mH running up wasn t what I could actually do, so I walked the steeper parts. Due to the permanent rain the views weren t that great, but one gets a feeling how far it is back to town. I used my new fenix 5x for the run (was helpful with the built-in map, report later), so I got very detailed data from Garmin Connect. Not that I really understand what it is all for, but Garmin told me that I am overtraining and that I am not a good runner (due to vertical oscillation etc). I guess there is a whole lot to learn and improve. Anyway, I made it back alive, and the first thing I needed was loads of water to drink
Eriberto Mota: OpenVAS 9 from Kali Linux 2017.1 to Debian 9

The OpenVAS OpenVAS is a framework of several services and tools offering a comprehensive and powerful vulnerability scanning and vulnerability management solution. The framework is part of Greenbone Networks' commercial vulnerability management solution from which developments are contributed to the Open Source community since 2009. OpenVAS is composed of some elements, as OpenVAS-Cli, Greenbone Security Assistant, OpenVAS Scanner and OpenVAS Manager. The official OpenVAS homepage is http://www.openvas.org. From Kali Linux 2017.1 to Debian 9 Ok, this is a temporary solution. Now (June 2017), Debian 9 wasn't released yet and OpenVAS 9 is not available in Debian in good conditions (it is in Experimental but a bit problematic). I think that we will have OpenVAS in backports soon. The OpenVAS 9 from Kali is working perfect for Debian 9. So, to take advantage of this, adopt the following procedures:
1. Add a line to end of /etc/apt/sources.list file:

deb http://http.kali.org/kali kali-rolling main

2. Run:

# apt-get update
# apt-get install -t kali-rolling openvas

(if you want to simulate before install, add a -s option before -t)

3. Rermove or comment the previous line added to /etc/apt/sources.list file to avoid future problems in your Debian.

4. Run the following command to configure the OpenVAS and to download the initial database:

# openvas-setup

This step may take some time. Note that the initial password for user admin will be created and shown.

5. Finally, open a web browser and access the address https://127.0.0.1:9392 (use https!!!). Alternatively, you can call http://127.0.0.1 to be automagically redirected to https://127.0.0.1:9392.

The default user is admin and the password was shown in the last step. You will can change this password inside OpenVAS (menu Administration > Users > Edit User, which is an blue icon).

If your password was lost, you will be able to create a new administrative user via shell command. See the section "Some tips" below.

6. To see the packages installed from Kali Linux, use the command:

$ dpkg -l   grep kali
Some tips To create a new administrative user called test:
# openvasmd --create-user test --role Admin
To update the database (NVTs):
# openvasmd --update
# openvasmd --rebuild
# service openvas-scanner restart
To solve the message "Login failed. Waiting for OMP service to become available":
# openvas-start
To make OpenVAS listen all network interfaces, allowing one to call the service in a remote web browser (http://remote-server, port 80 only), edit the /lib/systemd/system/greenbone-security-assistant.service and change:
ExecStart=/usr/sbin/gsad --foreground --listen=127.0.0.1 --port=9392 --mlisten=127.0.0.1 --mport=9390

to

ExecStart=/usr/sbin/gsad --foreground --listen=0.0.0.0 --port=9392 --mlisten=127.0.0.1 --mport=9390
After the change, reload the configuration and restart the service:
# systemctl daemon-reload
# systemctl restart greenbone-security-assistant
Quick start for beginners If OpenVAS isn't familiar for you, I have a suggestion for a quick test. Firstly, download Ubuntu Server 8.04 from this page and install it inside a virtual machine, selecting all services as LAMP, SSH etc. I used the i386 version and VirtualBox. After this, use OpenVAS to scan the Ubuntu (menu Scans > Tasks > a pink icon with a magic wand in the upper left corner). After the scan, click over the blue bar where we will can see the word "Done". Enjoy!

7 June 2017

Alexander Wirt: Upcoming Alioth Sprint

As some of you already know we do need a replacement for alioth.debian.org. It is based on wheezy and a heavily modified version of Fusionforge. Unfortunately I am the last admin left for alioth and I am not really familiar with fusionforge. After some chatting with a bunch of people we decided that we should replace alioth with a stripped down version of new services. We want to start with the basic things, git and and identity provider. For git there are two candidates: gitlab and pagure. Gitlab is really nice, but has a big problem: it is Opencore, which that it is not entirely opensource. I don t think we should use software licensed under such a model for one of our core services. That brings us to the last candidate: pagure. Pagure is a nice project based on gitolite, it is developed by the fedora project which use it for all their repos. Pagure isn t packaged for Debian yet, but that is work in progress (#829046). If you can lend a helping hand to the packager, please do so. To get things started we will have a Alioth Sprint from 18th to 20th August 2017 in Hamburg, Germany. If you want to join us, add yourself to the wikipage. For further discussions I created a mailinglist on alioth. Please subscribe if you are interested in that topic.

Next.

Previous.