Search Results: "xam"

5 January 2013

Russ Allbery: Automated Perl testing

I started several coding projects today, but none of them reached an announcable conclusion, so this seems like a good day to write up my current discoveries in automated Perl testing modules. This post isn't about test frameworks like Test::More and friends, or even about helper modules (although I do recommend Test::Warn if you want to test warning code in your modules). It's not about writing functionality tests. Rather, it's about various CPAN modules that can be used almost identically in just about every Perl module distribution (and in some other places, like Perl scripts inside a larger package written in another language). You can drop a small driver script into your t directory and (mostly) run make test with no further customization. If you want to see the driver scripts for all of the below that I'm currently using, see the t directory of the Term::ANSIColor distribution. They'll slowly make their way into my other modules, and probably, despite the name of the package, rra-c-util, since that's my equivalent of gnulib and I have tools to synchronize shared code from that package. The driver script generally tests whether the module is installed, skips the test if not, and otherwise dispatches to the "test everything" routine in the module. Test::MinimumVersion: This tests that you're not accidentally using a newer Perl feature than you were expecting. It's very handy if you want to support backward compatibility to a particular version of Perl. It knows about features as far back as 5.004_05. It won't be able to catch everything, but it will catch some of the most obvious things. Test::Perl::Critic: This is sort of the thousand-pound gorilla. Test::Perl::Critic runs all of your code through perlcritic and reports any errors. You will probably need to combine this with a perlcriticrc file in your distribution that you configure it to use, since otherwise the person running the tests may have customized perlcritic. If you let it run perltidy to check for formatting problems, you'll also want a perltidyrc. See the driver script mentioned above for how I set that up. I usually configure this test to only run for me (by checking an environment variable) since the results vary a lot depending on what version of perlcritic is installed, and it's likely new versions will cause the test to start failing. If you use this, expect to need to add ## no critic annotations to your code. Test::Pod: Checks for syntax errors in your POD documentation so that you won't have those embarassing POD ERRORS sections. Note that the latest version of podlators turns syntax errors into fatal errors, so soon you won't have to worry as much about this. But if you'd been using this module all along, you wouldn't have to worry about the fact that pod2man may start faliing due to syntax errors you never fixed! Test::Pod::Coverage: Only of interest to module distributions, not ramdom scripts, this checks that every sub provided by your module has POD documentation. It understands various subs that don't need to be documented (such as the ones you provide to implement a tied class) and lets you mark some subs as not requiring documentation. Test::Pod::Spelling: Checks your POD documentation for spelling mistakes with a spell checker. (Note that perlcritic, and hence Test::Perl::Critic, can also do this, but I use this module separately since I think the output is more readable.) You will almost certainly want to make this test maintainer-only, since spell checkers and spelling dictionaries vary a lot. But it prevents a lot of embarassment when you read your documentation on search.cpan.org and find that obvious spelling error you never saw before. Test::Strict: Checks all Perl code to ensure that it compiles, checks whether it has use strict, and optionally checks whether it has use warnings. This is great; I use this even with packages that just have a few Perl utility scripts in a package otherwise written in C, since I previously kept releasing packages with helper scripts with obvious syntax errors since I didn't run them much. Another place it's useful is if you have internal Debian packages that wrap up Perl utility scripts; just create a small test suite with this module and run it from override_dh_auto_check and you won't ever release a package with scripts that won't run. You can also do test suite coverage testing with this module (and Devel::Cover), but that you'll want to mark maintainer-only since it takes a while. Test::Synopsis: Checks the code in the SYNOPSIS section of any POD documentation to ensure that it compiles. No more syntax errors in your example code in the documentation! All of these modules are, of course, packaged for Debian (thanks largely to the wonderful Perl packaging team!), and otherwise available on CPAN. There are a variety of others, of course; these are just the main ones that I've found personally useful. One final whine, however: all this wonderful Perl testing infrastructure desperately needs a common module and a common interface for providing a list of files to check. Every one of these modules reinvents that wheel, and most of them do it a slightly different way than all the others. Most of them check in either blib or lib (or sometimes both). Most of them also add t. Most of them don't include Makefile.PL, but some of them do. Almost none of them look in examples. Some have a simple way to add more files or directories; some don't. Some can be run from the t directory and still find things, but most of them can't. And of course the syntax is different in every case! Most of the work in my driver scripts is finding the right way to add a few additional directories to the scope of the testing, and in one annoying case (Test::Synopsis), I actually had to use Perl::Critic::Utils (for lack of a better module) to build a list of files to check instead of using the build-in file list, since the build-in file list required all module code be in lib. A module to abstract out all of this and provide a common interface would be easy to write. Most of the work would involve talking to all the authors of all these different modules and asking them to use it. If someone in the Perl community felt like doing that, it would make life so much easier for everyone.

4 January 2013

Richard Hartmann: Release Critical Bug report for Week 01

Another gaffe Sorry for pushing this on Saturday, couldn't manage to do it earlier. I'm just glad that other than running my script, updating UDD source (the stats below) and then copying that one line over to here, there's no coherent thought required to publish this. Another gist The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze release cycle?
Week Squeeze Wheezy Diff
43 284 (213+71) 468 (332+136) +184 (+119/+65)
44 261 (201+60) 408 (265+143) +147 (+64/+83)
45 261 (205+56) 425 (291+134) +164 (+86/+78)
46 271 (200+71) 401 (258+143) +130 (+58/+72)
47 283 (209+74) 366 (221+145) +83 (+12/+71)
48 256 (177+79) 378 (230+148) +122 (+53/+69)
49 256 (180+76) 360 (216+155) +104 (+36/+79)
50 204 (148+56) 339 (195+144) +135 (+47/+90)
51 178 (124+54) 323 (190+133) +145 (+66/+79)
52 115 (78+37) 289 (190+99) +174 (+112/+62)
1 93 (60+33) 287 (171+116) +194 (111/+83)
2 82 (46+36)
3 25 (15+10)
4 14 (8+6)
5 2 (0+2)
6 release!
Graphical overview of bug stats thanks to azhag:

David Welton: The Software Millionaire Next Door

I've been reading "The Millionaire Next Door" and have so far found it to be a pleasant book with a good message: don't waste your money on silly things and appearance (fancy suits, fancy cars, expensive boats, etc...), save what you do earn consistently and constantly, invest wisely, and so on. Wikipedia has a good summary:
http://en.wikipedia.org/wiki/The_Millionaire_Next_Door
One of the things I like about it is that it focuses on "ordinary" wealthy people, those with a million or more in the bank, but not the Warren Buffets or Bill Gates types that are extreme statistical outliers. There are plenty of people in the US who have done well by themselves by slowly but surely putting together enough money to be financially independent, without, however, being in the spotlight. As the book says, these are the kind of people who maybe own a local chain of businesses doing something fairly ordinary, but doing it well enough to succeed. They may very well not live in a fancy house, nor drive an expensive car, or otherwise outwardly draw much attention to themselves. The world of software does not revolve around "dressing for success" (you noticed?), but we do tend to focus on the "big winners". Gates, Jobs, Zuckerberg, Larry & Sergey, Larry Ellison, and so on are the stars of the show. Of course, the economics of software being what they are, instances of winner-take-all markets with one big fish and a lot of also-rans are not uncommon. However, that is not the only story, and I think it'd be interesting to know more about those in our industry who have accumulated significant wealth, yet are not the guys with more money than they could possibly ever spend on things that aren't, say, country-sized chunks of real-estate. I'm guessing they'd fall into these categories: It'd be very interesting to gather some actual data on this, although I'm not in a position to do so myself - I wouldn't even really know where to start. As I age, I think the third category has begun to seem appealing in many ways - I'm simply not cut out for the Big Company life, and I'm not interested in living in Silicon Valley and going "all in" on the latest startup - I already did that, and while it was fun and I don't regret it, it's not the kind of thing I'd want to do now that I'm married and have kids. Incidentally, this more relaxed, under the radar approach is exactly what is expoused in one of my favorite books of the past few years, Start Small, Stay Small. Edit : I finished reading the book and reviewed it here: http://davids-book-reviews.blogspot.com/

Thorsten Glaser: on the linguistic gender of hosts, with an xz reminder

Let s start a convention: bare-metal machines have the linguistic male gender ( der Computer , he needs to be rebooted), whereas VMs have the linguistic female gender ( die virtuelle Maschine , she runs better since the last upgrade of Linux-KVM), and neutral linguistic gender is used when you cannot or do not want or need to make such distinction.
This is, of course, entirely unrelated to human gender, but not unrelated to #debian-68k (on OFTC) discussions ;-) ObRant: DO NOT USE xz COMPRESSION LEVELS ABOVE 6! (For -7 we can make exceptions, for example in Debian *-dbg or *-source packages.) You may use -e if you absolutely need the better compression, but please think of the poor sods who have to create the archives. You must not use the highest compression levels -8 or -9 since they have absolutely insane memory requirements on compression and will still hinder machines with less RAM on decompression. (Using -e only affects CPU usage at compression time; decompression is exactly as fast and memory-consuming as without.) Furthermore, DO NOT CHOOSE A COMPRESSION LEVEL WITH A DICTIONARY SIZE MUCH LARGER THAN THE DATA TO COMPRESS, as that makes absolutely no sense and will rather worsen than improve compression. As a reminder, xz uses the following dictionary sizes: Decompression uses less than 1 MiB more than the dictionary size, but the dictionary must always be allocated wholly. (You re fine to use custom presets, but mind the RAM usage!) As a general rule, if you have something of up to 20 MiB to compress, -4 is fine, and -5 will only be better if you have similar data spread across the whole of the file instead of close to each other. When I make mksh distfiles, I instead put files close to each other that have related content, which improves compression much more nicely without penalising low-memory systems; for example, you could put documentation, Makefiles, scripts, m4(1) files, and C source code into groups before archiving, instead of doing it alphabetically. Another note on bzip2: its decompression is slow. I see no reason to use it any more, at all. Use gzip(1) if you care for compatibility or have an issue with xz not having a free copyright licence, and xz otherwise.

Julien Danjou: Integrating cl-irc and cl-async

Recently, I've started programming in Common Lisp. My idea here is to use cl-irc, an IRC library into an event loop. This can be really useful, for example to trigger action based on time, using timers. Creating a connection The first step is to create a basic cl-irc:connection object on our own. This can be achieved easily with this:
(require :cl-irc)

(defun connect (server)
(cl-irc:make-connection :connection-type 'cl-irc:connection
:client-stream t
:network-stream ?
:server-name server))

This will return a cl-irc:connection object, logging to stdout (:client-stream t) and having the server name server. Note that the server name could be any string. You probably noticed the ? I used as :network-stream value. This is not a real and working value: this should be a stream established to the IRC server you want to chat with. This is where we'll need to use cl-async:tcp-connect to establish a TCP connection. As you can read in this function's documentation, all we need to pass is the server address, two callbacks for read and general events, and the :stream option to get a stream rather than a socket. So you would do something like:
(require :cl-irc)
(require :cl-async)

(defun connection-socket-read (socket stream)
(format t "We should read the IRC message from ~a ~%" stream))

(defun connection-socket-event (ev)
(format t "Socket event: ~a~%" ev))

(defun connect (server &optional (port 6667))
(cl-irc:make-connection :connection-type 'cl-irc:connection
:client-stream t
:network-stream (as:tcp-connect server port
#'connection-socket-read
#'connection-socket-event
:stream t)
:server-name server))

(as:start-event-loop (lambda () (connect "irc.oftc.net")))

If you run this program, it will connect to the OFTC IRC server, and then notice you each time the server is sending you a message. Therefore our problem here is how we you treat the message read from the stream in connection-socket-read and handle them in the name of our connection object you used? We can't link both together at this point. We can't build a closure, because as the time we use as:tcp-connect we don't have the cl-irc:connection instance. Also we can't change easily the read-cb parameter of our network-stream established by as:tcp-connect, simply because cl-async doesn't use to do allow that. Building a closure So one solution here is to hack cl-irc:make-connection so we can build an cl-irc:connection instance without providing in advance the network-stream, allowing us to build a closure including the cl-irc:connection to read event for. This is what we're going to do in the connect function.
(require :cl-irc)
(require :cl-async)
(require :flexi-streams)

(defun connection-socket-read (connection)
(loop for message = (cl-irc::read-irc-message connection)
while message
do (cl-irc:irc-message-event connection message)))

(defun connection-socket-event (ev)
(format t "Socket event: ~a~%" ev))

(defun connect (server port nickname
&key
(username nil)
(realname nil)
(password nil))
;; Build an instance of cl-irc:connection, without any network/output stream
(let* ((connection (make-instance 'cl-irc:connection
:user username
:password password
:server-name server
:server-port port
:client-stream t))
;; Use as:tcp-connect to build our network stream, and build a
;; closure calling connection-socket-read' with our connection'
;; as arguments
(network-stream (as:tcp-connect server port
(lambda (socket stream)
(declare (ignore socket stream))
(connection-socket-read connection))
#'connection-socket-event
:stream t)))
;; Set the network stream on the connection
(setf (cl-irc:network-stream connection) network-stream)
;; Set the output stream on the connection
(setf (cl-irc:output-stream connection)
;; This is grabbed from cl-irc:make-connection
(flexi-streams:make-flexi-stream
network-stream
:element-type 'character
:external-format '(:utf8 :eol-style :crlf)))

;; Now handle the IRC protocol authentication pass
(unless (null password)
(cl-irc:pass connection password))
(cl-irc:nick connection nickname)
(cl-irc:user- connection (or username nickname) 0 (or realname nickname))
connection))

(as:start-event-loop (lambda () (connect "irc.oftc.net" 6667 "jd-blog")))

And here we are! If we run this, we're now using an event loop to run cl-irc. Each time the socket has something to read, the function connection-socket-read will be called on the non-blocking mode socket. If there's no message to be read, then the function will exit and the loop will continue to run. Using timers You can now modify the last line with this:
(defun say-hello (connection)
(cl-irc:privmsg connection "#jd-blog" "Hey I read your blog!")
(as:delay (lambda () (say-hello connection)) :time 60))

(as:start-event-loop (lambda ()
(let ((connection (connect "irc.oftc.net" 6667 "jd-blog")))
(cl-irc:join connection "#jd-blog")
(say-hello connection))))

This will connect to the IRC server, join a channel and then say the same sentence every minute. Challenge accomplished! And I'd like to thank Andrew Lyon, the author of cl-async, who has been incredibly helpful with my recent experimentations in this area.

Russ Allbery: cl2xhtml 1.10

cl2xhtml converts GNU ChangeLog files to XHTML for (hopefully) pretty web display. After making the most recent Term::ANSIColor release, I noticed that it didn't support the multi-author ChangeLog convention. This is not in the GNU standards, but it's become conventional to note changes by multiple authors with the syntax:
2013-01-03  Some Author <author@example.com>
            Another Person <person@example.com>
        * file.c: Some change.
cl2xhtml now understands that syntax, including with more than two authors, and turns it into a list of authors on the HTML page separated with commas and "and" as needed. You can get the latest version of cl2xhtml from my web tools page.

2 January 2013

Petter Reinholdtsen: New IRC channel for LEGO designers using Debian

During Christmas, I have worked a bit on the Debian support for LEGO Mindstorm NXT. My son and I have played a bit with my NXT set, and I discovered I had to build all the tools myself because none were already in Debian Squeeze. If Debian support for LEGO is something you care about, please join me on the IRC channel #debian-lego (server irc.debian.org). There is a lot that could be done to improve the Debian support for LEGO designers. For example both CAD software and Mindstorm compilers are missing. :) Update 2012-01-03: A project page including links to Lego related packages is now available.

Michael Stapelberg: WIT in Debian

I just uploaded wit-2.10a to Debian experimental (it has to pass the NEW queue first, though). WIT (Wiimms ISO Tools) is a set of command-line tools to manipulate Wii and GameCube ISO images and WBFS containers. It is useful (for me) to store backups of my Wii games on a USB hard disk drive. This saves me the optical disc juggling, doesn t wear off the discs as fast and gives faster load times. Here is an example session where I format one partition of the USB hard disk with WBFS and then copy my old WBFS image over to it:
$ wwt format -v --force /dev/sde3
wwt: Wiimms WBFS Tool v2.10a r0 x86_64 - Dirk Clemens - 2013-01-02
FORMAT BLOCK DEVICE /dev/sde3 [172 GiB, hss=512]
** 1 file formatted.
$ wwt add --part /dev/sde3 /media/sde1/wbfs/The\ Legend\ of\ Zelda\ Skyward\ Sword\ \[SOUP01\]/*.wbfs
*****  wwt: Wiimms WBFS Tool v2.10a r0 x86_64 - Dirk Clemens - 2013-01-02  *****
WBFSv1 #1/1 opened: /dev/sde3
 - ADD 1/1 [SOUP01] WBFS:/media/sde1/wbfs/The Legend of Zelda Skyward Sword [SOUP01]/SOUP01.wbfs/#0
* WBFS #1: 1 disc added.
wwt add --part /dev/sde3   0,02s user 7,66s system 2% cpu 5:02,68 total
$ wwt list
ID6     1/500 discs (4 GiB)
---------------------------------------------------------------------
SOUP01  The Legend of Zelda Skyward Sword
---------------------------------------------------------------------
Total: 1/500 discs, 4176 MiB ~ 4 GiB used, 171444 MiB ~ 167 GiB free.

1 January 2013

Craig Small: procps 3.3.6 and Mudlet 2.0

Mudlet - Graphical MUD clientYesterday was a busy Debian day for me with the release of not one but two packages. procps procps version 3.3.6 was released both as an upstream and a Debian package. While there were many bug fixes in this release, the main new feature for it was the top inspect feature. The top inspect feature allows you to run top in the normal way then you can inspect a specific process you have selected within top for more information. Examples of this include fuser or lsof type output to see what files or libraries are open but really the limit is how clever the operator is and how often you would need this information. Even scripts can be run off this feature if you have some customised or cooked output you need to see. Once the output is there, you can search for text. There will be a small hold-up with the Debian packages as the section for the library has been moved to libs, where it should be. At least I think that s why there is a delay. procps infrastructure procps currently has only an email list and a gitorious git repository. While this works most of the time, there are two main problems with this setup. The first is that the only two ways you can report bugs is send an email to the list or create a git merge request. The email has the problem with tracking and gathering history while the git sets the bar pretty high for reporting something has gone wrong. Second problem is there is no tarball file repository. gitorious does have the feature of downloading tarballs of the tag checkpoints, but this is the raw repository. When you make a tarball with make dist there are some generated files included in the tarball that don t appear in the gitorious ones, which means its not a simple for some as you expect. So I ll be creating a project for these two features soon. Not sure where they will be but I use sourceforge for both these for a few other projects so that might be where they end up. Mudlet Mudlet, the multi-user dungeon or MUD client, has finally made it to version 2.0! It looks a lot more stable and polished at least from the scripting side than the previous RC versions but has all the features that we ve come to expect with it. The most important thing is that the developers have finally put a line in the sand and said this is version 2.0 . The Debian package was uploaded yesterday and should be on its way to your local mirror soon.

Vincent Sanders: I don't drink coffee I take tea my dear, I like my toast done on one side...

Choices, options, selections if you rather. These are what set us all apart from our fellow man, perhaps it is only the appearance of free will and individuality but our world is full of choice.

In software it might be argued programming is nothing more than making thousands perhaps millions of choices which result in a list of instructions for a machine incapable of making decisions of its own.

On a more mundane level sometimes a programmer cannot make a choice suitable for all expected use cases and a user option is created. These options have become something of a cause for arguments within certain sections of the open source software community especially amongst the groups that influence the graphical user experience.

The discussion should be nuanced and varied (perhaps that is my age, or maybe I am more diplomatic than I thought?) but there seems to be little compromise on this discussion which (from an outsiders point of view) splits into two viewpoints:


The reductionist group is currently winning the argument in the popular graphical environments and seem to be removing functionality which requires user choice wherever they can find it. This results in the absurd "joke" that the UI will become a single button, which they are trying to remove.

Personally my view is that an option should be present only when an option cannot be satisfactorily selected by the computer and even then a default suitable for as many users as possible should be picked.

You may ask why I have raised this topic at all? well over the last few days I have been trying to fix the preferences selection for the GTK port of NetSurf. The NetSurf project follows my view on this subject pretty closely but being a browser its very difficult to do the right thing for everyone

NetSurf has numerous frontends for the core browser, I use the term frontend because in some places the toolkit and OS are conflated (windows, cocoa) and not in others (gtk). For each frontend NetSurf is a native application, this is an important distinction, the windows and widgets a user interfaces with are produced by that platforms toolkit.

Old NetSurf Preferences Dialog
This is a deliberate choice unlike other browsers which render their UI themselves as web content, this is a beguiling solution when the authors wish there to be a single browsing "experience" with a common look and feel. However NetSurf looks and feels like a native browser for each frontend, which is what the project decided it wanted to achieve.

Given this the gtk frontend (is it a Gnome application? not sure of the distinction TBH) has had no dedicated maintainer for some time it has suffered from a bad case of bitrot from both GTK library changes and general neglect.

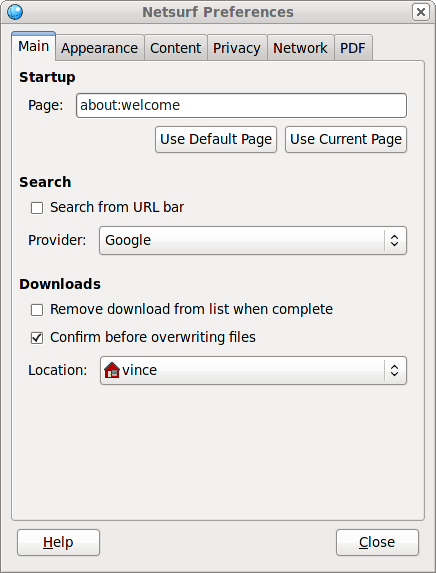
I have slowly been improving this situation, the browser can now be compiled with GTK version 2 (2.12 onwards) or 3, the menus and other UI elements have been translated for the supported languages and now the turn has come for the options dialog.

Oh, right, its "Preferences" not options, fair enough a common semantic throughout all applications does give a degree of homogeneousness but the word choice does seem to indicate the users control has been reduced. At this point I gained an education in just how unfriendly GTK and its tools have become towards the casual programmer.

The dialog I wanted to construct was a pretty standard tabbed layout which reflected the current options and allowed the user to change them in an obvious way. Given that I have constructed and equivalent interface in idiomatic manner for cocoa and windows I thought this would be straightforward, I was very wrong.

The interface construction tool is called glade which used to be the name of the UI "resource" file and interfaces. However the tool is still called glade but the interface is now GtkBuilder which has a different (but similar) XML based file format. Then we discover that despite it being an extensible file format the UI files are specifically versioned against the GTK library. Also why on earth can these resources not be compiled into my program? OK make them over-ridable perhaps. Generally it is yet another file to distribute and update in step with the executable.

New NetSurf Properties Dialog open on Main tab
New NetSurf Preferences
So because I want to support back to version 2.12 of GTK I do not get to use any of the features from 2.16 in my UI unless I load a different UI builder file...oh and GTK3? requires a completely different version of glade and the UI files which are incompatible with gtk 2. Once this was worked round with having multiple UI files I then moved on to the next issue.

The GTK model uses function callbacks on events, these are known as signals. Perfectly reasonable but because the ui files are loaded at runtime and not compiled in there must be a way for the GTKBuilder to map the textural signal names to function pointers.

The way the GTK developers have chosen to do this is to search the global function table which means any signal handler function symbol has also to be global which means unnecessary overhead for the ELF loader increasing load times.

This lookup should have been confined to a single object or even placed in an alternative section to avoid these issues, this would not have seemed especially challenging to implement as all callback handlers have to use a preprocessor to define already (G_MODULE_EXPORT).

Another thing that makes developing GTK applications worse is the documentation, this seems to be a continuous complaint about may open source projects, which is taciturn or simply missing in many cases. GTK seems to suffer dreadfully from having multiple API versions all subtly different resulting in a lot of work on the developers part to simply find what they want.

A specific example of this is the signals and under what circumstance they occur I wanted to update all the widgets with the current configuration state whenever the options window is shown (using gtk_widget_show()) so I figured that would be the "show" signal...right? nope, never did find the right one to use, ended up with "realize" which occurs once when the dialog is created, not what I wanted, but is at least consistent and works.

NetSurf with is Properties dialog open on the content tab
NetSurf with Preferences Dialog
Overall my impression of developing just one small dialog (60 widgets total exclusing labels and containers) for a GTK program is that the toolkit and its tooling is missing the facilities to make developers life easier when doing the drudge work that a good proportion of graphical program development.

It is not the case that one cannot do things, just that everything has to be done manually instead of having the tools do the work, and because of the documentation that tedium is magnified.

I did eventually reach the stage that the thought of writing the boilerplate to add another check button to enable "do not track" had me thinking "do they really need this or can I avoid the work?" perhaps that is why they are all reductionist?


Russ Allbery: Review: City of Diamond

Review: City of Diamond, by Jane Emerson
Publisher: DAW
Copyright: March 1996
ISBN: 0-88677-704-6
Format: Mass market
Pages: 624
The setting is deep into the star-faring future of humanity. Humans have settled many other worlds, thanks largely to technology from a race named the Curosa. There is a thriving network of settlement based around a sort of warp conduit network. But, standing apart from most human settlements, are three huge ships: the City of Opal, the City of Pearl, and the City of Diamond. Their inhabitants are devout members of the Redemptionist faith, a merging of Christian (primarily Catholic) belief and Curosa religion. Their ships are gifts from the now-departed Curosa, featuring drives unknown to the rest of humanity that allows them to ignore the normal transport network. They are meant to witness and spread their religion, but now, six centuries later, they primarily trade. Much of this is not apparent at the start. City of Diamond opens with Adrian Mercati, chosen heir of the current dying Protector, dodging people in what seems to be an oddly-organized city. Impudent, occasionally flippant, utterly charming, and in love with danger, he inherits the position of Protector shortly after we meet him. Emerson slowly reveals more of the nature of the ship while Adrian is shocking (and charming) the nobility and the church, and consorting with demons. Or, at least, one demon: Tal, an entirely human-appearing creature except for his eyes, who the Redemptionists claim is born without a soul. Slowly, it becomes clear that he's actually the offspring of an alien and a human, a mating of species whose children cannot socialize as human and behave in ways that seem like human sociopaths. Tal is no exception, but his interests align with Adrian's for the time. To those two viewpoint characters, Emerson adds four more: a low-rank administrator named Spider who works for Tal after Tal saved him from death by recycling, Adrian's politically-arranged bride-to-be from the rival (and even more religious) ship City of Opal, a guard from a French-descended slum on City of Opal, and a dangerously honorable and literal mercenary from an off-shoot culture of humanity that's now only a legend. This is a book that tends to sprawl. There's quite a lot going on, starting with the negotiations between City of Diamond and City of Opal to put to rest the remnants of a civil war and leading to the search for a legendary Curosa artifact on the planet they're both visiting. All of the characters have their own agendas, their own history, and their own goals, and are pursuing them in parallel and occasionally in opposition. Emerson takes the time to let all of this build. Despite that, there is very little in this book that drags or bores, and that's due primarily to the strength of the characters. Every one of the viewpoint characters is unique, bringing a different perspective to the story, and every one of them changes and grow over the course of the story. They also play off of each other in delightful ways. This is a book that makes full use of the fact that three characters make seven character interactions. For example, Tal by himself is logical but just slightly askew, Tal seen by Spider is uncomfortable and worrisome, Tal and Adrian is a dance of mutual amusement and respect, and Tal and Keylinn finding points of commonality is just delightful. I did wish that there was a bit more Keylinn and Tal and a bit less of Spider, but once Emerson built her world, introduced her characters, and got the story moving, there aren't many weak pieces. Part of the fun is figuring out the world background. There are almost no infodumps here; Emerson just starts telling stories of characters in the surroundings in which they find themselves, and the reader is left to piece things together from background description, the occasional explanation from one character to another, and parallels with long-standing SF tropes. It's not a puzzle book, but it is a book of where the reader is dropped as an alien into a fully-developed culture. In both that way and in the use of nobility, religion, and formal hierarchy against a starfaring backdrop, City of Diamond reminds me of the sort of classic space opera that led up to Star Wars but isn't seen as much these days. It's also funny. I was unsurprised to discover that Emerson is a pseudonym for Doris Egan, who (in addition to writing some other SF) is an occasional writer and producer for House. The humor isn't entirely obvious at the start, although Adrian frequently provokes a grin from the start of the book, but Tal's perceptive but obliviously blunt comments become more and more fun as the book progresses, and both Iolanthe (Adrian's bride) and Keylinn (the mercenary, sort of) are a delight. I want to see more of both of them, but sadly the book ends just as they (particularly Iolanthe) are hitting their strides. And that's the biggest problem with City of Diamond: it's a failed (or at least postponed) trilogy. As with Walter Jon Williams's Metropolitan and City on Fire, there were supposed to be more books, but apparently either the publisher lost interest or other projects took precedence. The story does come to something of a conclusion, but most of the major story arcs aren't resolved. Emerson is still bringing more guns onto the set late in the book. None of the villains truly get their just desserts, nor do most of the character arcs fully resolve, although friendships and more have formed satisfyingly by the end of the book. There is obviously far more to both these characters and this universe, including an entire ship that was never visited and an alien whose presence should prove startling. This is a great book: warm, funny, full of interesting characters, and with a nicely complex background universe. If it were complete in itself, or if the sequels had materialized, I would recommend it unreservedly. As is, you will have to weigh your dislike of unfinished stories against its stand-alone merits. But I enjoyed it a great deal. Rating: 7 out of 10

31 December 2012

Russ Allbery: Term::ANSIColor 4.01

It was too much to hope for that all that testing would catch everything in a 4.00 release, but it's ironic that the main bug was a bug in one of the test cases! BlueT - Matthew Lien - found that one of the tests malfunctioned when Test::Warn was not installed. Since I was cutting a new release anyway, I also improved the README somewhat and added POD documentation to the example script. You can get the latest version from the Term::ANSIColor distribution page.

Russell Coker: Modern Swap Use

A while ago I wrote a blog post debunking the idea that swap should be twice as large as RAM [1]. The issue of swap size has come up for discussion in a mailing list so it seems that it s worth another blog post. Swap Size In my previous post I suggested making swap space equal to RAM size for systems with less than 1G of RAM and half RAM size for systems with 2-4G of RAM with a maximum of 2G for any system. Generally it s better to have the kernel Oom handler kill a memory hungry process than to have the entire system go so slow that a hardware reset is needed. I wrote memlockd to lock the important system programs and the shared objects and data files they use into RAM to make it easier to recover from some bad paging situations [2], but even that won t always make it possible to login to a thrashing system in a reasonable amount of time. But it s not always good to reduce swap size. Sometimes if you don t have enough swap then performance sucks in situations where it would be OK if there was more swap. One factor in this regard is that pages mapped read-only from files are discarded when there is great memory pressure and no swap space to page-out the read-write pages. This can mean that you get thrashing among memory for executables and shared objects while there s lots of unused data pages in RAM that can t be paged out. One noteworthy corner case in this regard is Chromium which seems to take a lot of RAM if you have many tabs open for a long time. Another factor is that there is a reasonable amount of memory allocated which will almost never get used (EG all the X based workstations which have 6 gettys running on virtual consoles which will almost never be used). So a system which has a large amount of RAM relative to it s use (EG a single-user workstation with 8G of RAM) can still benefit from having a small amount of swap to allow larger caches. One workstation I run has 8G of RAM for a single user and typically has about 200M of the 1G swap space in use. It doesn t have enough swap to make much difference if really memory hungry programs are run, but having 4G of memory for cache instead of 3.8G might make a difference to system performance. So even systems which can run without using any swap can still be expected to give better performance if there is some swap space for programs that are very inactive. I have some systems with as much 4G of swap, but they are for corner cases where swap is allocated but there isn t a lot of paging going on. For example I have a workstation with 3G of RAM and 4G of swap for the benefit of Chromium. Hardware Developments Disk IO performance hasn t increased much when compared to increases in RAM size over the last ~15 years. A low-end 1988 era hard drive could sustain 512KB/s contiguous transfer rates and had random access times of about 28ms. A modern SATA disk will have contiguous transfer rates getting close to 200MB/s and random access times less than 4ms. So we are looking at about 400* the contiguous performance and about 10* the random access since 1988. In 1988 2MB was a lot of RAM for a PC, now no-one would buy a new PC with less than 4G so we are looking at something like 2000* the RAM size in the same period. When comparing with 1993 (when I first ran a Linux server 24*7) it was 4M of RAM, maybe 15ms random access, and maybe 1MB/s contiguous IO approximately double everything I had in 1988. But I ll use the numbers from 1988 because I m more certain of them even though I never ran an OS capable of proper memory management on the 1988 PC. In the most unrealistically ideal situation paging IO will be a factor of 5* more expensive now relatively than it was in 1988 (RAM size increase by a factor of 2000 divided by contiguous IO performance increase by a factor of 400). But in a more realistic situation (random IO) it will be 200* more expensive relatively than it was. In the early 90s a Linux system with swap use equal or greater than RAM could perform well (my recollection is that a system with 4M of RAM and 4M of active swap performed well and the same system with 8M of active swap was usable). But nowadays there s no chance of a system that has 4G of RAM and 4G of swap in active use being usable in any way unless you have some corner case of an application allocating RAM and not using it much. Note that 4G of RAM doesn t make a big system by today s standards, so it might be reasonable to compare 2M in 1988 to 8G or 16G today. But I think that assuming 4G of RAM for the purpose of comparison makes my point. Using Lots of Swap It is probably possible to have some background Chromium tabs using 4G of paged out RAM with good system performance. I ve had a system use 2G of swap for Chromium and perform well overall. There are surely many other ways that a user can launch processes that use a lot of memory and not use them actively. But this will probably require that the user know how the system works and alter their usage patterns. If you have a lot of swap in use and one application starts to run slowly you really don t want to flip to another application which would only make things worse. If you use tmpfs for /tmp then you need enough swap to store everything that is written to /tmp. There is no real upper limit to how much data that could be apart from the fact that applications and users generally don t want to write big data files that disappear on reboot. I generally only use a tmpfs for /tmp on servers. Programs that run on servers tend not to store a large amount of data in /tmp and that data is usually very temporary, unlike workstation users who store large video files in /tmp and leave them there until the next reboot. Are there any other common corner cases that allow using a lot of swap space without serious performance problems? My Swap Space Allocation When I setup Linux workstations for other people I generally use 1G of swap. For a system that often has multiple users (via the user-switch feature) I use 2G of swap if it only has 3G of RAM (I run many systems which are limited to 3G of RAM by their chipset). For systems that I personally use I generally allocate 4G of swap, this is to cater to excessive RAM use by Chromium and also because I test out random memory hungry programs and can t easily predict how much swap space will be needed a typical end-user desktop system is a lot more predictable than a workstation used for software development. For servers I generally allocate 512M of swap space. That s enough to page out things that aren t used and make space for cache memory. If that turns out to be inadequate then it s probably best to just let the watchdog daemon reboot the system.

30 December 2012

Iustin Pop: Interesting tool of the day: ghc-gc-tune

Courtesy of a recent Google+ post/Stack overflow answer, I stumbled upon ghc-gc-tune, a simple but nice tool which generates interesting graphs for Haskell programs. What is does is quite trivial: iterate over a range of arena and heap sizes, and run a specified program with those RTS options, then generate a graph comparing the performance (by default cpu time) across the combinations of the values. Note that for newer GHC versions, you'll need to link with -rtsopts to allow for the -A/-H custom sizes. The reason I mention it is that the graphs it generates can be quite interesting. For one of the Ganeti programs, hspace, run with the command line ./hspace --simu p,20,1t,96g,16,1 --disk-template drbd, it generates this graph: runtime graph with trivial usage This picture, if I read it correctly, says that this program is actually well behaved (well, +RTS -s says "3 MB total memory in use" with default options), and that the optimum sizes actually relate to the (L1? L2?) cache size. But note that the maximum difference is only about ~1.6 . By changing the parameters to hspace and make it allocate more memory (./hspace --simu p,20,1t,128g,256,32 --disk-template plain --tiered=1g,128m,1, ~52MB reported by +RTS -s), the graph changes significantly: runtime graph with 50mb usage Now we have somewhat the opposite situation: very small arena sizes are detrimental (and by a big factor, 4.5 ), large arena/heap sizes are OK-ish, and the sweet spot is around 2-4MB arena size with heap sizes up to 4MB. Now maybe these particular examples were not very elightening (and they were definitely not well-conducted tests, etc.), but they should allow some intuition into how the program behaves. Plus, the tool can also generate other plots, for example peak memory usage.

Russ Allbery: Term::ANSIColor 4.00

Term::ANSIColor is a Perl core module that provides a few different interfaces to get at the ANSI color and text attribute escape sequences. It can be used to, for example, print out bold text or colorize output. This is a major new feature release, incorporating patches sent to me by Kurt Starsinic and Stephen Thirlwall. Kurt Starsinic contributed support for 256-color emulators. These hang special extended sequences off the otherwise-unused 38 and 48 sequences, providing an alternative naming of the base 16 colors, 216 colors arranged in an RGB namespace, and 24 shades of grey. Those colors are now available via all the normal Term::ANSIColor interfaces. He also contributed a program to print out test data for 256-color emulators that I enhanced to print out test data for the basic and 16-color sets as well, which allowed me to get rid of the static test files in the distribution. Stephen Thirlwall contributed support for creating aliases for the standard colors via an environment variable. I extended his patch to also provide a coloralias() function interface. This feature probably won't be that widely used, but it allows a user to set up custom color names for applications that take color names from user configuration (which might be handy for doing things like using the Solarized color scheme), or to define an alias like "alert" or "warning" in one place and then use it throughout the code. With the new 256-color support, it may be useful to set up more human-readable aliases for some of the RGB colors. Since I was working on this project anyway, I also redid the whole module in the new Perl coding style that I've been experimenting, based on Damian Conway's Perl Best Practices, and added a ton of new tests. There are a lot of great CPAN modules out there to do automated tests of various aspects of Perl code, and most of them don't require much effort to use. I'll probably write a separate post about that later. That sort of comprehensive review of course uncovered a bunch of microbugs and lack of clarity in the code, which is now hopefully much improved. I'm pleased to report that the test suite achieves 100% code coverage as reported by Devel::Cover (and in fact there's a maintainer-only test to ensure that it stays that way). You can get the latest version from the Term::ANSIColor distribution page.

Dirk Eddelbuettel: RcppClassicExamples 0.1.1

Yesterday's initial upload of RcppClassicExamples was lacking a versioned Depends: to prevent builds on older versions of R. This has been added in a new upload 0.1.1. We also added a NEWS file (see below); no code changes were made.
Changes in version 0.1.1 (2012-12-30)
  • Added versioned Depends: in DESCRIPTION to not build under older versions of Rcpp and RcppClassic
Changes in version 0.1.0 (2012-12-27)
Thanks to CRANberries, you can also look at a diff to the previous release 0.1.0. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

29 December 2012

Dirk Eddelbuettel: RcppExamples 0.1.5 and RcppClassicExamples 0.1.0

The recent releases of Rcpp 0.10.2 and RcppClassic 0.9.3 had one more repercussion. On that dreaded OS, the linker no longer wanted to instantiate a symbol present in both packages; seems to me that the linker in the other two OSs is a little smarter. Anyway -- I didn't fight this but at long last moved all remnands of the long-deprecated older Rcpp API (which is still maintained by package RcppClassic) out of package RcppExamples and into a new package RcppClassicExamples. And the updated version 0.1.5 of the RcppExamples package appeared on CRAN and has now been joined by the initial version 0.1.0 of the new package RcppClassicExamples. No code changed were made; manual pages and descriptions where brushed up and that is about it. Thanks to CRANberries, you can also look at a diff to the previous release 0.1.4 of RcppExamples. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

Matthew Garrett: No, Linux won't be easy to run on a Microsoft Surface

The Microsoft Surface is a fairly attractive bit of tablet hardware, and as a result people have shown interest in running Linux on it. The immediate problem is that (like many ARM devices) it has a locked-down firmware that will only run signed binaries - unlike many other ARM devices, this is implemented using an existing standard (UEFI Secure Boot). Microsoft provide a signing service for UEFI binaries, so it's tempting to think that getting around this restriction would be as simple as taking an existing Linux bootloader, signing it and then booting. Unfortunately Microsoft's signing service signs binaries using a different key (the "Microsoft Windows UEFI Driver Publisher" key) to the one used to sign Windows, and the Surface doesn't carry that key. Booting Linux on these devices would involve finding a flaw in the firmware and using that to run arbitrary code.

Could this also be a problem on x86? In theory - Microsoft don't require that vendors carry the driver publisher key, and so a system could be Windows 8 certified and still not carry it. It's unlikely to occur in practice, though, since any third party expansion hardware will then fail on that device. As a result, anything with PCIe or Expresscard slots is effectively certain to have this key. If anyone finds any counterexamples, please let me know.

comment count unavailable comments

Russell Coker: Samsung Galaxy Camera a Quick Review

I recently had a chance to briefly play with the new Samsung Galaxy Camera [1]. The Galaxy Camera is an Android device with a 4.8 display (the same size as the Samsung Galaxy S3) that has a fairly capable camera (IE nothing like a typical phone camera). It runs Android 4.1 (Jelly Bean) and the camera has 21* zoom with a 16 megapixel sensor. Camera Features It seems that professional photographers are often annoyed when they see someone with a DSLR set in auto mode. It s widely regarded that auto mode is a waste of a good camera, although the better lenses used with DSLRs will usually give a better result than any compact camera even when it s in auto mode. The problem is that photography is quite complex, in an earlier post about digital cameras I summarised some of the technical issues related to cameras and even without any great detail it became a complex issue [2]. The Galaxy Camera has a reasonably friendly GUI for changing camera settings which even includes help on some of the terms, I expect that most people who use it will end up using most of the features which could make it a good training camera for someone who is going to move to a DSLR. A DSLR version of the Galaxy Camera could also be an interesting product. The camera also has modes such as Waterfall and Panorama , hopefully the settings for those would be exposed to the user so they could devise their own similar groups of settings. I ve seen the phone criticised for the lack of physical controls as the expert mode in software is inherently slower than manually turning dials on a DSLR. But it seems obvious to me that anyone who knows how to use the controls manually should be using a DSLR or bridge camera and anyone who doesn t already know how to do such things will be better suited by the software controls. It supports 120fps video at 720*480 resolution (with a file format stating that it s 30fps to give 1/4 speed) which could be useful. I used to have a LG Viewty smart-phone that did 120fps video but the resolution was too low to be useful. 720*480 is enough resolution to see some detail and has the potential for some interesting video, one use that I ve heard of is filming athletes to allow them to analyse their performance in slow motion. It also does 60fps video at 720p (1280*720) resolution. One down-side to the device is that the lens cover doesn t seem particularly sturdy. It s quite OK for a device that will be stored in a camera case but not so good for a device that will be used as a tablet. I didn t get to poke at the lens cover (people don t like it if you mess with their Christmas presents) but it s design is a couple of thin flaps that automatically retract when the camera is enabled which looks quite weak. I d like to see something solid which doesn t look like it will slide back if the device is treated as roughly as a phone. I think that the lack of a solid lens cover could be the one factor that prevents it from being used as a replacement for a smart phone. Apart from that a Galaxy Camera and a cheap GSM phone could perform all the functions of a high end phone such as the Galaxy S3 while also producing great pictures. It would probably make sense for retailers to bundle a cheap phone with a Galaxy Camera for this purpose. Tablet Features The device boasts WiFi Direct to allow multiple cameras and phones to talk to each other without a regular WiFi access point [3]. I didn t test this and I don t think it would be particularly useful to me, but it seems like a handy feature for less technical users. It can connect to the Internet via Wifi or 3G, supports automatic upload of pictures (it comes with Dropbox support by default like the Galaxy S3), and has a suite of photo and video editing software. I don t expect that any photo editing software that runs on an Android device would be much good (I think that you really need fine cursor control with a mouse and a high resolution screen), but it would probably be handy for sending out a first draft of photos. Most Android apps should just work, the exceptions being apps that rely on a camera that faces the user or full phone functionality. So the Galaxy Camera can do almost anything that an Android phone or tablet can do. Value The RRP for the Galaxy Camera is $599, that puts it in the same price range as a DSLR with a single lens. While that s not a bad price when compared to smart-phones (it s cheaper than the LTE version of the Galaxy S3 phone) it s still quite expensive for a camera that s not a DSLR. Fortunately Kogan is selling it for $469 and has free shipping at the moment [4]. This still makes it more expensive than some of Bridge Cameras which probably have significantly better optical features, but in terms of what the typical user can do with a camera the Galaxy Camera will probably give a much better result. The sensor in the Galaxy Camera is smaller than that in the Nokia 808 PureView [5] (1/2.3 vs 1/1.2 ) so the Nokia PureView should be able to take better pictures in some situations. Unfortunately the Nokia 808 doesn t run Android, I d probably own one if it did. Some of the reviews are rather harsh, the Verge has a harsh but fair review by Aaron Souppouris which makes a number of negative comparisons to cheaper cameras [6]. I really recommend reading Aaron s review as there s a lot of good information there. But I think that Aaron is missing some things, for example he criticises the inclusion of ebook software by saying that he wouldn t read a book on a camera. But the device is a small tablet computer which also has a compact camera included. I can easily imagine someone reading a book or playing Angry Birds on their camera/tablet while in transit to where they are will photograph something. I can also imagine a Galaxy Camera being a valuable tool for a journalist who wants to be able to write short articles and upload pictures and video when out of the office. Aaron concludes by suggesting that the Galaxy Camera is a $200 camera with $300 of editing features. I think of it as $200 in camera hardware with software that allows less skilled users to take full advantage of the hardware and the ability to do all the software/Internet things that you would do on a $450+ smart-phone. Would I Buy One? No. The Galaxy Camera is among other things a great toy, I d love to have one to play with but I can t spare $469 on one. Part of the reason for this is that my wife just bought a DSLR and is getting lessons from a professional photographer, so I really won t get better pictures from a Galaxy Camera. The DSLR on auto mode will allow me to take pictures that will usually be better than a Galaxy Camera can achieve (sometimes you just can t beat a good lens). For more demanding pictures my wife can tweak the DSLR. The 120fps video is a really nice feature, I don t know if my wife s DSLR can do that, but it s a toy feature not something I really need. I ve just bought a Galaxy S3 which is a great little tablet computer (most of the time it won t be used for phone calls). I don t need another 4.8 tablet so a significant part of the use of the Galaxy Camera doesn t apply to me. I recommend the Galaxy Camera to anyone who wants to take good photos but can t get a DSLR and lessons on how to use it properly. But if you would rather get a 35mm camera with interchangeable lenses that runs Android then it might be worth waiting. I expect that the Galaxy Camera will be a great success in the market (it s something you will love when you see it). That will drive the development of similar products, if Samsung doesn t release a 35mm Android camera soon then someone else will (for example Sony develops both high end cameras and Android phones). If my wife didn t have a DSLR then I d probably have bought a Galaxy Camera already. I will recommend it to my parents and many other people I know who want an OK camera and can benefit from a tablet, but don t know how to use a DSLR properly (or don t want to carry a bulky camera).

Steve Kemp: More polish for slaughter

A couple of days ago I made a new release of slaughter, to add a new primitive I was sorely missing:
if ( 1 != IdenticalContents( File1 => "/etc/foo" ,
                             File2 => "/etc/bar" ) )
 
   # do something because the file contents differ
 
This allows me to stop blindly over-writing files if they are identical already. As part of that work I figured I should be more "visible", so on that basis I've done two things: After sanity-checking my policies I'm confident I'm not leaking anything I wish to keep private - but there is some news being disclosed ;) Now that is done I think there shouldn't be any major slaughter-changes for the forseeable future; I'm managing about ten hosts with it now, and being perl it suits my needs. The transport system is flexible enough to suit most folk, and there are adequate facilities for making local additions without touching the core so if people do want to do new things they don't need me to make changes - hopefully. ObQuote: "Yippee-ki-yay" - Die Hard, the ultimate Christmas film.

Next.

Previous.