Search Results: "tar"

2 August 2017

Steve Kemp: So I did a thing, then another thing.

So I did start a project, to write a puppet-dashboard, it is functionally complete, but the next step is to allow me to raise alerts based on failing runs of puppet - in real-time. (i.e. Now that I have a dashboard I wish to not use it. I want to be alerted to failures, without having to remember to go look for them. Something puppet-dashboard can't do ..) In other news a while back I slipped in a casual note about having a brain scan done, here in sunny Helsinki. One of the cool things about that experience, in addition to being told I wasn't going to drop dead that particular day, was that the radiologist told me that I could pay 25 to get a copy of my brain data in DICOM format. I've not yet played with this very much, but I couldn't resist a brief animation:

Markus Koschany: PDFsam: How to upgrade a Maven application for Debian

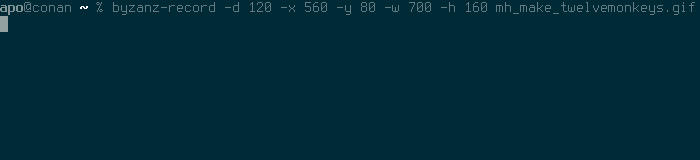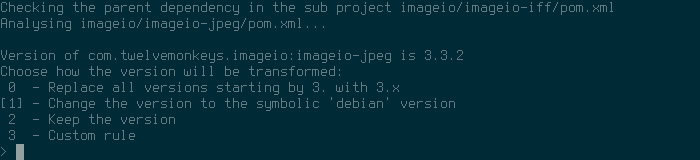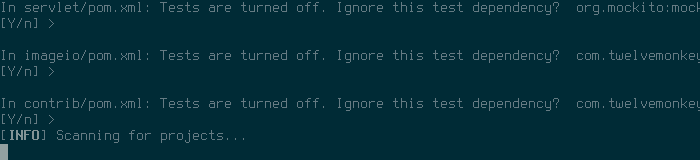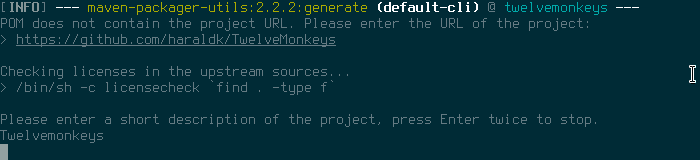
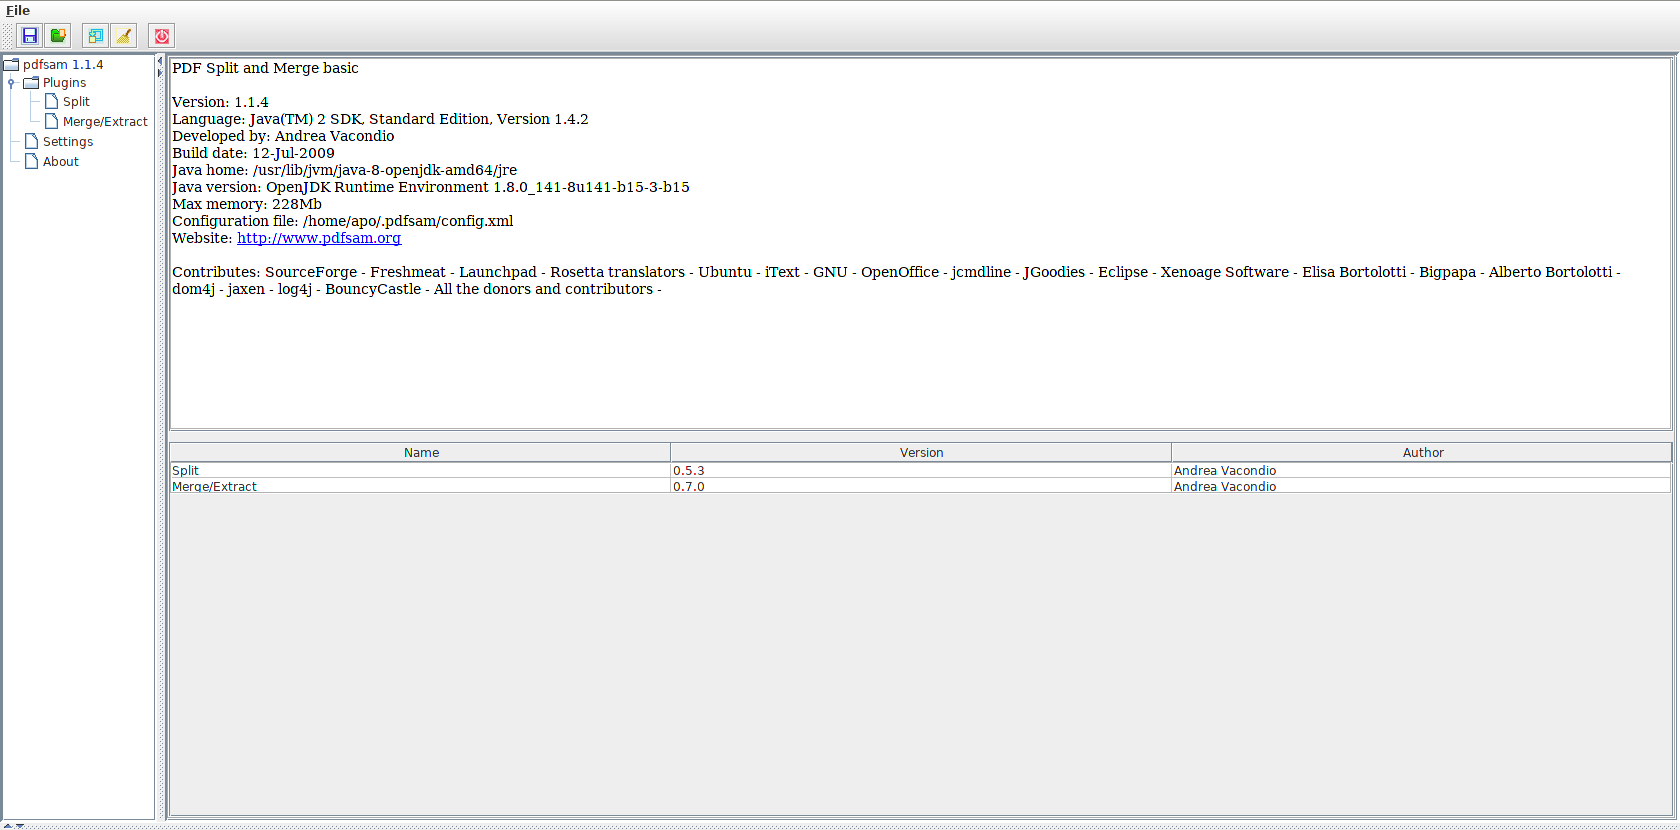
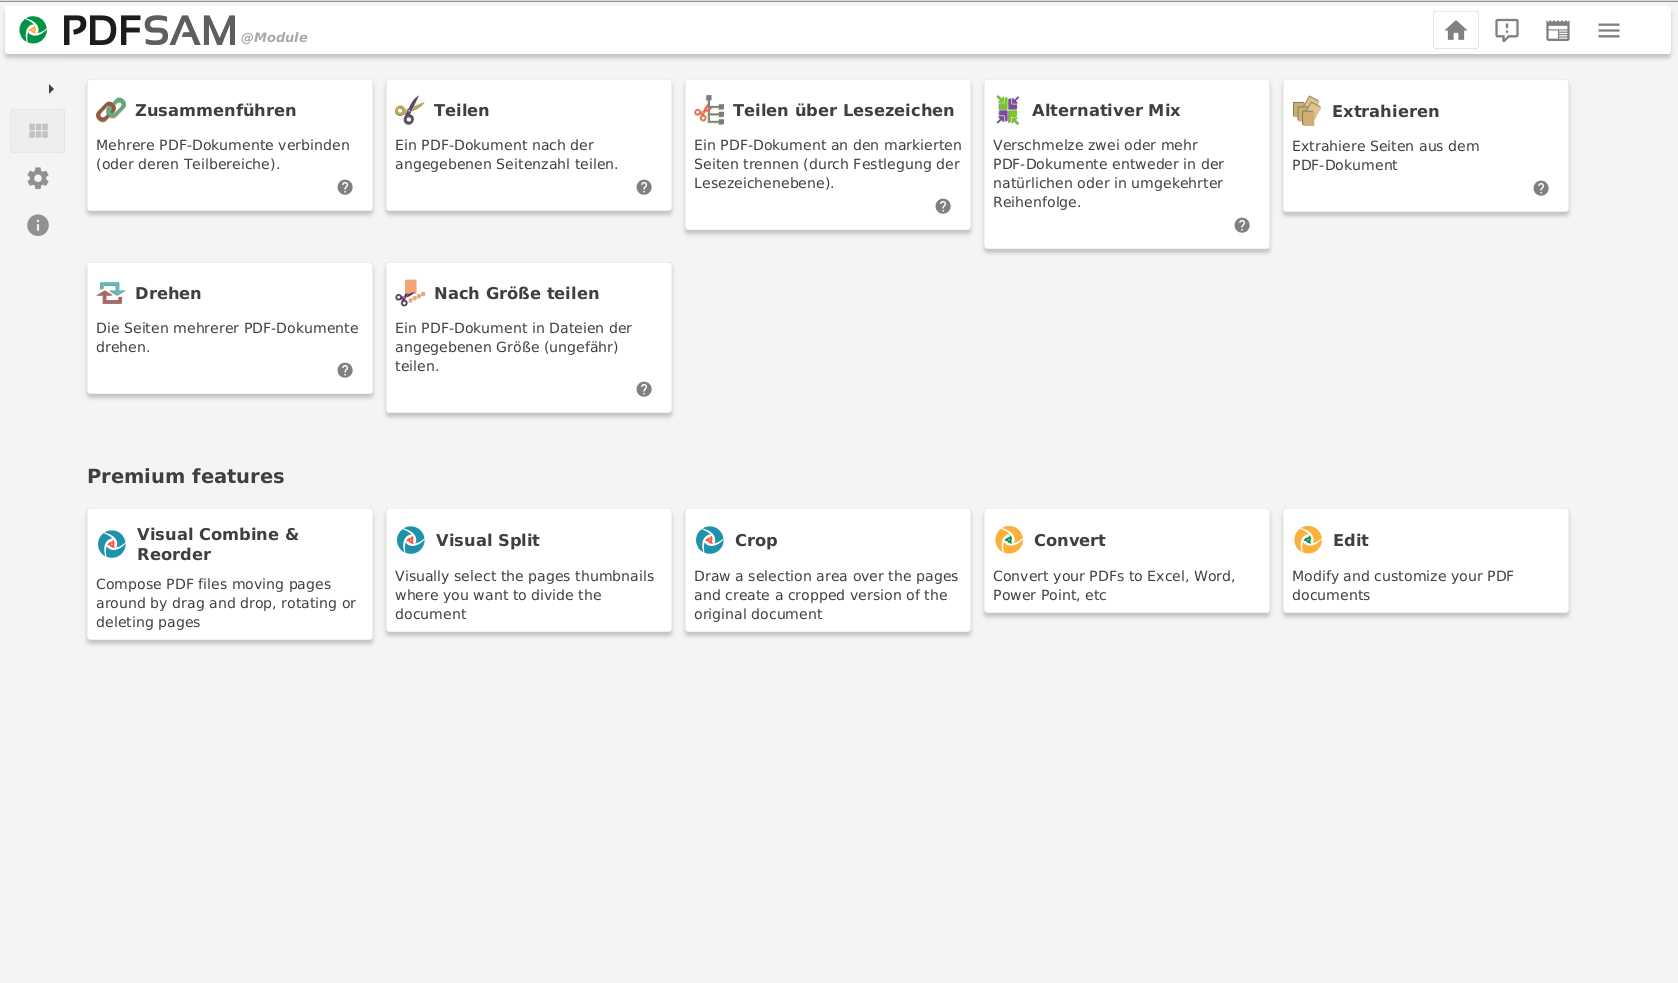
In the coming weeks and months I intend to write a mini series about packaging Java software for Debian. The following article basically starts in the middle of this journey because the PDFsam upgrade is still fresh in my mind. It requires some preexisting knowledge about build tools like Maven and some Java terminology. But do not fear. Hopefully it will make sense in the end when all pieces fall into place. A month ago I decided to upgrade PDFsam, a Java application to split, merge, extract, mix and rotate PDF documents. The current version 1.1.4 is already seven years old and uses Ant as its build system. Unfortunately up to now nobody was interested enough to invest the time to upgrade it to the latest version. A quick internet search unveils that the current sources can be found on github.com. Another brief look reveals we are dealing with a Maven project here because we can find a pom.xml file in the root directory and there is no sign of Ant s typical build.xml file anymore. Here are some general tips how to proceed from this point by using the PDFsam upgrade as an example. Find out how many new dependencies you really need The pom.xml file declares its dependencies in the <dependencies> section. It is good practice to inspect the pom.xml file and determine how much work will be required to upgrade the package. A seasoned Java packager will quickly find common dependencies like Hibernate or the Apache Commons libraries. Fortunately for you they are already packaged in Debian because a lot of projects depend on them. If you are unsure what is and what is not packaged for Debian, tracker.debian.org and codesearch.debian.net are useful tools to search for those packages. If in doubt just ask on debian-java@lists.debian.org. There is no automagical tool (yet) to find out what dependencies are really new (we talk about mh_make soon) but if you use the aforementioned tools and websites you will notice that in June 2017 one could not find the following artifacts: fontawesomefx, eventstudio, sejda-* and jackson-jr-objects. There are also jdepend and testFx but notice they are marked as <scope>test</scope> meaning they are only required if you would like to run upstream s test suite as well. For the sake of simplicity, it is best to ignore them for now and to focus on packaging only dependencies which are really needed to compile the application. Test dependencies can always be added later. This pom.xml investigation leads us to the following conclusion: PDFsam depends on Sejda, a PDF library. Basically Sejda is the product of a major refactoring that happened years ago and allows upstream to develop PDFsam faster and in multiple directions. For Debian packagers it is quite clear now that the upgrade of PDFsam is in reality more like packaging a completely new application. The inspection of Sejda s pom.xml file (another Maven project) reveals we also have to package imgscalr, Twelvemonkeys and SAMBox. We continue with these pom.xml analyses and end up with these new source packages: jackson-jr, libimgscalr-java, libsambox-java, libsejda-java, libsejda-injector-java, libsejda-io-java, libsejda-eventstudio-java, libtwelvemonkeys-java, fontawesomefx and libpdfbox2-java. Later I discovered that gettext-maven-plugin was also required. This was not obvious at first glance if you only check the pom.xml in the root directory but PDFsam and Sejda are multi-module projects! In this case every subdirectory (module) contains another pom.xml with additional information, so ideally you should check those too before you decide to start with your packaging. But don t worry it is often possible to ignore modules with a simple ignore rule inside your debian/*.poms file. The package will have less functionality but it can be still useful if you only need a subset of the modules. Of course in this case ignoring the gettext-maven-plugin artifact would result in a runtime error. C est la vie. A brief remark about Java package names: Java library packages must be named like libXXX-java. This is important for binary packages to avoid naming collisions. We are more tolerant when it comes to source package names but in general we recommend to use the exact same name as for the binary package. There are exceptions like prefixing source packages with their well known project name like jackson-XXX or jboss-XXX but this should only be used when there are already existing packages that use such a naming scheme. If in doubt, talk to us. mh_make or how to quickly generate an initial debian directory Packaging a Maven library is usually not very difficult even if it consists of multiple modules. The tricky part is to get the maven.rules, maven.IgnoreRules and your *.poms file right but debian/rules often only consists of a single dh line and the rest is finding the build-dependencies and adding them to debian/control. A small tool called mh_make, which is included in maven-debian-helper, can lend you a helping hand. The tool is not perfect yet. It requires that most build-dependencies are already installed on your local system, otherwise it won t create the initial debian directory and will only produce some unfinished (but in some cases still useful) files. A rule of thumb is to start with a package that does not depend on any other new dependency and requires the fewest build-dependencies. I have chosen libtwelvemonkeys-java because it was the simplest package and met the aforementioned criteria. Here is how mh_make looks like in action. (The animated GIF was created with Byzanz) First of all download the release tarball, unpack it and run mh_make inside the root directory. Ok, what is happening here? First you can choose a source and binary package name. Then disable the tests and don t run javadoc to create the documentation. This will simplify things a little. Tests and javadoc settings can be added later. Choose the version you want to package and then you can basically follow the default recommendations and confirm them by hitting the Enter key. Throughout the project we choose to transform the upstream version with the symbolic debian version. Remember that Java/Maven is version-centric. This will ensure that our Maven dependencies are always satisfied later and we can simply upgrade our Maven libraries and don t have to change the versions by hand in various pom.xml files; maven-debian-helper will automatically transform them for us to debian . Enable all modules. If you choose not to, you can select each module individually. Note that later on some of the required build-dependencies cannot be found because they are either not installed (libjmagick6-java) or they cannot be found in Debian s Maven repository under /usr/share/maven-repo. You can fix this by entering a substitution rule or, as I did in this case, you can just ignore these artifacts for now. They will be added to maven.IgnoreRules. In order to successfully compile your program you have to remove them from this file later again, create the correct substitution rule in maven.rules and add the missing build-dependencies to debian/control. For now we just want to quickly create our initial debian directory. If everything went as planned a complete debian directory should be visible in your root directory. The only thing left is to fix the substitution rule for the Servlet API 3.1. Add libservlet3.1-java to Build-Depends and the following rule to maven.rules: javax.servlet s/servlet-api/javax.servlet-api/ * s/.*/3.1/ * *
s/javax.servlet/javax.servlet.jsp/ s/jsp-api/javax.servlet.jsp-api/ * s/.*/2.3/ * * The maven.rules file consists of multiple rows separated by six columns. The values represent groupId, artifactId, type, version number and two fields which I never use.  You can just use an asterisk to match any value. Every value can be substituted. This is necessary when the value of upstream s pom.xml file differs from Debian s system packages. This happens frequently for API packages which are uploaded to Maven Central multiple times under a different groupId/artifactId but provide the same features. In this case the Twelvemonkeys pom requires an older API version but Debian is already at version 3.1. Note that we require a strict version number in this case because libservlet3.1-java does not use a symbolic debian version since we provide more than one Servlet API in the archive and this measure prevents conflicts. Thanks for reading this far. More articles about Java packaging will follow in the near future and hopefully they will clarify some terms and topics which could only be briefly mentioned in this post.

before

and after

1 August 2017

Thorsten Alteholz: My Debian Activities in July 2017

FTP assistant This month I am back to normal numbers and accepted 319 packages. I also kept the promise from last month and rejected 26 uploads. Debian LTS This was my thirty-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload went up to 23.5h. During that time I did LTS uploads of: I could also remove libtorrent-rasterbar and pspp from dla-needed.txt as the affected code was not in the Wheezy version or it was just a simple bug. Last but not least I also had a few days of frontdesk duties. Other stuff This month I uploaded a new version of entropybroker with a revised set of systemd service files. At the moment there is public instance of entropybroker running at eb.debian.net. Its entropy is fed by several Entropy Keys made by Simtec Electronics. Though it is public, it is not yet anonymous, so if you need some entropy please drop me a line. At the moment there are two consumers, but the buffers are still filled. I also uploaded several new packages, orcania, yder, hoel and ulfius. If everything works as expected, there will be soon an oauth2 server available in Debian. Last but not least my DOPOM of this month has been ptunnel.

Russ Allbery: Learning Rust

I'm obviously not spending much time writing here. It's been a rather busy month at work, and I've been doing other things on the weekend that aren't particularly interesting to write about. This past week, though, I took advantage of our semi-annual Hack Week to finally learn Rust. I have several co-workers who love the language and have been wanting to stretch my programming language knowledge a bit. I was also profoundly disappointed by Go, which has been touted as the new C-style systems language but which I think is awful. All the reasons why is a topic for another post, but the obnoxiously verbose error handling is probably my biggest complaint. (This is the worst property of C; why would you copy it?) Rust was a favorite of a few people who felt the same way I did about Go, which seemed promising. I made it through the first thirteen chapters of the second edition Rust book and wrote a not-entirely-trivial program (a tool to filter and search trace logs a Dropbox client) with a co-worker, and I think I'm in love with this language. It reminds me of everything I liked about Perl, except with all the weird bolted-on bits of Perl cleaned up and done properly, and with types. Despite having spent most of my career writing Perl and Python (and C, which is typed but not very well), I love strongly-typed languages. I just usually don't like the rest of the syntax of languages like Java and Go. Rust avoids the garbage collection nonsense (and huge performance issues), gives me the level of fine control that I am used to with C, but gets rid of memory allocation errors and provides a much richer type system and type matching. It feels a bit like an approachable Haskell, and I quickly found myself chaining iterators and pushing myself to write in a more functional style. The lifetime stuff in Rust can be frustrating, and there are a few limitations that can be hard to deal with (like iterating over one field of a struct while modifying another field of a struct, which comes up a lot and which is the sort of thing you have to avoid in Rust). But I like a language with a very picky compiler. And I love programming in a language where my first attempt is clunky and verbose, and then I think about the problem a bit and rewrite it in half as many lines of code, and then I sleep on it and come back and can delete half of the code again. I sadly don't have a lot of work projects right now where Rust is the right answer. I'm mostly maintaining existing code bases in Python, and Python is more accessible and more maintainable in most situations. But I now would love to find the time to rewrite a bunch of my personal C projects in Rust, and I'm watching for any new opportunity to use Rust. If you like new programming languages, but you don't have the time or inclination to live on the bleeding edge, Rust has gotten more stable and is at a good point to start. The documentation is fantastic, support for generating documentation is built into the language, the Rust book is a great teaching research, and Rust is available as Debian packages (so you don't have to do the horrifying curl bash nonsense in the official Rust documentation). Recommended, particularly for people who love Perl or functional languages (or functional Perl heavy on map and grep), want a more modern language with fewer odd corners, and want low-level control and native speed.

Russ Allbery: Review: The Fifth Season

Review: The Fifth Season, by N.K. Jemisin
Series: The Broken Earth #1
Publisher: Orbit
Copyright: 2015
ISBN: 0-316-22930-X
Format: Kindle
Pages: 497
The world of The Fifth Season is one of near-constant seismic activity. Volcanoes, massive earthquakes, and all the catastrophes that follow them are a constant threat. Civilization barely survives the turmoil, and only because of two things: strict cultural rules about how to handle a "fifth season" of heavy seismic activity and its aftermath (called stonelore), and the orogenes. Orogenes are humans (well, there is some debate about that) who have an organ that others don't, a biological ability to manipulate the seismic activity and the earth itself. They can protect others by damping down activity, smoothing faults, and redirecting seismic shock waves, but they can also destroy: pull earth out of shape, set off quakes, and create paths for magma to surface. And, to gather the power to manipulate the earth, they draw energy from everything around them, including from other people, often fatally. Orogenes are feared and hated by the typical person. The Stillness, the ironically-named continent on which this book is set, is very old and has had numerous civilizations destroyed by some seismic catastrophe. The landscape is scattered with useless or dangerous remnants of previous forgotten civilizations; the history, likewise, with only the stonelore and some muddled mythology available to most people. The current rulers have kept their empire for a surprising length of time, however, due mostly to the stable ground beneath their centrally-located capital. That stability comes from Fulcrum-trained orogenes, who are taken from their family as children and trained harshly to serve their society by suppressing or fixing dangerous seismic events. Fulcrum orogenes don't have an awful life (well, most of them; for some, it is pure torture), but they're effectively slaves, kept under the watchful eye of Guardians who have mysterious powers of their own. Against this background, The Fifth Season tells three interwoven stories. Essun lives in a small village (comm) at the start of the book, leading a quiet life, until one of her children is beaten to death by her husband following a seismic event that he thinks the child stopped. He's taken their other child and left. Essun, severely traumatized, heads after him to attempt a rescue, or at least revenge. Damaya is a child from another comm who is sold to the Guardians by her parents when she demonstrates orogenic ability, and who goes through Fulcrum training. And Syenite is a Fulcrum orogene, assigned to a field mission with a difficult but very senior orogene named Alabaster. All of these stories eventually interweave, and eventually reveal where they fit in the somewhat unobvious chronology of the story, but it takes some time to get there. It also takes some time for the primary characters to have much in the way of agency. Essun starts with the most, once she recovers her senses enough to start her hunt for revenge. Syenite is ambitious but junior, and Damaya is a child, trying to navigate an unknown world of student politics and strict rules. And all three of the main characters are orogenes, rogga when one is being insulting, and this world does not like orogenes. At all. The Fifth Season starts with an unusual narrative style: a conversational narrator who begins with some of the world background and some mysterious scenes that didn't make sense until much later in the book (late enough that I didn't remember them or make sense of them until I re-read them for this review). The book then focuses on Essun, whose scenes are written in second person present. Normally I think second person feels weirdly intrusive and off-putting, but once I got used to it here, I think it works as well as I've seen it work anywhere. I also see why Jemisin did it: Essun starts the story so traumatized that she's partly disassociating. First person wouldn't have worked, and the second-person voice gives that trauma some immediacy and emotional heft that would have been hard to achieve in third person. The story starts slowly, and builds slowly, as the world is introduced and Jemisin lays down the texture and history of the world. The world-building is ambitious in tracing down the ramifications of the seismic chaos and the implications of orogene ability (although it's best to think of it as pure magic, despite the minor science fiction trappings). But through that world-building, what this story is building is a deep, powerful, frustrated rage. The Fifth Season is an angry book. It's a book about outcasts, about slaves. About people who, even if they're succeeding within the parameters they're given, are channeled and stymied and controlled. It's a story about smiling, kind paternalism hiding lies, control, and abuse, about how hard it is to find enough space from the smothering destructiveness of a totalitarian culture to let yourself relax. It's a story about the horrible things people are willing to do to those they don't consider fully human, and all the ways in which safety, expediency, tradition, culture, and established social roles conspire to keep people within the box where they belong. And it's a story about how being constantly on edge, constantly dreading the next abuse, breaking under it, and being left wanting to burn the whole world to the ground. I struggled at the start of this book, but it grew on me, and by about halfway through it had me hooked completely. At first, Syenite's part of the story (the most traditionally told) was my favorite, but the coming-of-age stories of her and Damaya were overtaken by Essun's far more complex, cautious, and battle-weary tale. And I loved Jemisin's world-building. There's a lot of depth here, a lot of things going on that are unexplained but clearly important, and a restraint and maturity in how the world is revealed that makes it feel older and more layered than Jemisin's The Hundred Thousand Kingdoms. The major drawback of this book is that it is very much the first book of a series, and it doesn't so much have an ending as a hard stop. It's not quite a cliff-hanger, but it's nearly as unsatisfying as one. Most of the major questions of the book who the stone eaters are and what they want, and the fate of Essun's husband and child, just to name two are still unresolved at the end of the story. There is a bit of emotional closure, but not a true moment of catharsis for all of the rage. Hopefully that will be coming in a future book. This is a very unusual story, mixing fantasy and a sort of magic (orogeny) with some science fiction elements and a deep history. It's gritty, textured, emotional, and furious, and very much worth reading. I'm looking forward to the next book in the series. Followed by The Obelisk Gate. Rating: 8 out of 10

Junichi Uekawa: Playing with appengine python ndb.

Playing with appengine python ndb. Some interfaces changed from the old interface and I don't think I quite got the hang of it. The last time I was actively using it is when I was doing tokyodebian reservation system that I haven't touched for 3 years and started 8 years ago.

31 July 2017

Chris Lamb: Free software activities in July 2017

Here is my monthly update covering what I have been doing in the free software world during July 2017 (previous month): I also blogged about my recent lintian hacking and installation-birthday package.
Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most software is distributed pre-compiled to end users. The motivation behind the Reproducible Builds effort is to permit verification that no flaws have been introduced either maliciously or accidentally during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. (I have generously been awarded a grant from the Core Infrastructure Initiative to fund my work in this area.) This month I:
  • Assisted Mattia with a draft of an extensive status update to the debian-devel-announce mailing list. There were interesting follow-up discussions on Hacker News and Reddit.
  • Submitted the following patches to fix reproducibility-related toolchain issues within Debian:
  • I also submitted 5 patches to fix specific reproducibility issues in autopep8, castle-game-engine, grep, libcdio & tinymux.
  • Categorised a large number of packages and issues in the Reproducible Builds "notes" repository.
  • Worked on publishing our weekly reports. (#114 #115, #116 & #117)

I also made the following changes to our tooling:
diffoscope

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues.

  • comparators.xml:
    • Fix EPUB "missing file" tests; they ship a META-INF/container.xml file. [ ]
    • Misc style fixups. [ ]
  • APK files can also be identified as "DOS/MBR boot sector". (#868486)
  • comparators.sqlite: Simplify file detection by rewriting manual recognizes call with a Sqlite3Database.RE_FILE_TYPE definition. [ ]
  • comparators.directory:
    • Revert the removal of a try-except. (#868534)
    • Tidy module. [ ]

strip-nondeterminism

strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build.

  • Add missing File::Temp imports in the JAR and PNG handlers. This appears to have been exposed by lazily-loading handlers in #867982. (#868077)

buildinfo.debian.net

buildinfo.debian.net is my experiment into how to process, store and distribute .buildinfo files after the Debian archive software has processed them.

  • Avoid a race condition between check-and-creation of Buildinfo instances. [ ]


Debian My activities as the current Debian Project Leader are covered in my "Bits from the DPL emails to the debian-devel-announce mailing list.
Patches contributed
  • obs-studio: Remove annoying "click wrapper" on first startup. (#867756)
  • vim: Syntax highlighting for debian/copyright files. (#869965)
  • moin: Incorrect timezone offset applied due to "84600" typo. (#868463)
  • ssss: Add a simple autopkgtest. (#869645)
  • dch: Please bump $latest_bpo_dist to current stable release. (#867662)
  • python-kaitaistruct: Remove Markdown and homepage references from package long descriptions. (#869265)
  • album-data: Correct invalid Vcs-Git URI. (#869822)
  • pytest-sourceorder: Update Homepage field. (#869125)
I also made a very large number of contributions to the Lintian static analysis tool. To avoid duplication here, I have outlined them in a separate post.

Debian LTS

This month I have been paid to work 18 hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 1014-1 for libclamunrar, a library to add unrar support to the Clam anti-virus software to fix an arbitrary code execution vulnerability.
  • Issued DLA 1015-1 for the libgcrypt11 crypto library to fix a "sliding windows" information leak.
  • Issued DLA 1016-1 for radare2 (a reverse-engineering framework) to prevent a remote denial-of-service attack.
  • Issued DLA 1017-1 to fix a heap-based buffer over-read in the mpg123 audio library.
  • Issued DLA 1018-1 for the sqlite3 database engine to prevent a vulnerability that could be exploited via a specially-crafted database file.
  • Issued DLA 1019-1 to patch a cross-site scripting (XSS) exploit in phpldapadmin, a web-based interface for administering LDAP servers.
  • Issued DLA 1024-1 to prevent an information leak in nginx via a specially-crafted HTTP range.
  • Issued DLA 1028-1 for apache2 to prevent the leakage of potentially confidential information via providing Authorization Digest headers.
  • Issued DLA 1033-1 for the memcached in-memory object caching server to prevent a remote denial-of-service attack.

Uploads
  • redis:
    • 4:4.0.0-1 Upload new major upstream release to unstable.
    • 4:4.0.0-2 Make /usr/bin/redis-server in the primary package a symlink to /usr/bin/redis-check-rdb in the redis-tools package to prevent duplicate debug symbols that result in a package file collision. (#868551)
    • 4:4.0.0-3 Add -latomic to LDFLAGS to avoid a FTBFS on the mips & mipsel architectures.
    • 4:4.0.1-1 New upstream version. Install 00-RELEASENOTES as the upstream changelog.
    • 4:4.0.1-2 Skip non-deterministic tests that rely on timing. (#857855)
  • python-django:
    • 1:1.11.3-1 New upstream bugfix release. Check DEB_BUILD_PROFILES consistently, not DEB_BUILD_OPTIONS.
  • bfs:
    • 1.0.2-2 & 1.0.2-3 Use help2man to generate a manpage.
    • 1.0.2-4 Set hardening=+all for bindnow, etc.
    • 1.0.2-5 & 1.0.2-6 Don't use upstream's release target as it overrides our CFLAGS & install RELEASES.md as the upstream changelog.
    • 1.1-1 New upstream release.
  • libfiu:
    • 0.95-4 Apply patch from Steve Langasek to fix autopkgtests. (#869709)
  • python-daiquiri:
    • 1.0.1-1 Initial upload. (ITP)
    • 1.1.0-1 New upstream release.
    • 1.1.0-2 Tidy package long description.
    • 1.2.1-1 New upstream release.

I also reviewed and sponsored the uploads of gtts-token 1.1.1-1 and nlopt 2.4.2+dfsg-3.

Debian bugs filed
  • ITP: python-daiquiri Python library to easily setup basic logging functionality. (#867322)
  • twittering-mode: Correct incorrect time formatting due to "84600" typo. (#868479)

Russell Coker: Running a Tor Relay

I previously wrote about running my SE Linux Play Machine over Tor [1] which involved configuring ssh to use Tor. Since then I have installed a Tor hidden service for ssh on many systems I run for clients. The reason is that it is fairly common for them to allow a server to get a new IP address by DHCP or accidentally set their firewall to deny inbound connections. Without some sort of VPN this results in difficult phone calls talking non-technical people through the process of setting up a tunnel or discovering an IP address. While I can run my own VPN for them I don t want their infrastructure tied to mine and they don t want to pay for a 3rd party VPN service. Tor provides a free VPN service and works really well for this purpose. As I believe in giving back to the community I decided to run my own Tor relay. I have no plans to ever run a Tor Exit Node because that involves more legal problems than I am willing or able to deal with. A good overview of how Tor works is the EFF page about it [2]. The main point of a Middle Relay (or just Relay ) is that it only sends and receives encrypted data from other systems. As the Relay software (and the sysadmin if they choose to examine traffic) only sees encrypted data without any knowledge of the source or final destination the legal risk is negligible. Running a Tor relay is quite easy to do. The Tor project has a document on running relays [3], which basically involves changing 4 lines in the torrc file and restarting Tor. If you are running on Debian you should install the package tor-geoipdb to allow Tor to determine where connections come from (and to not whinge in the log files). ORPort [IPV6ADDR]:9001 If you want to use IPv6 then you need a line like the above with IPV6ADDR replaced by the address you want to use. Currently Tor only supports IPv6 for connections between Tor servers and only for the data transfer not the directory services. Data Transfer I currently have 2 systems running as Tor relays, both of them are well connected in a European DC and they are each transferring about 10GB of data per day which isn t a lot by server standards. I don t know if there is a sufficient number of relays around the world that the share of the load is small or if there is some geographic dispersion algorithm which determined that there are too many relays in operation in that region.

30 July 2017

Jose M. Calhariz: Crossgrading a complex Desktop and Debian Developer machine running Debian 9, for real.

After sometime without looking into this problem, I decided to do another try. I do not found a way to do a complex crossgrade of my desktop without massively removing packages. And there are bug and bug that require to edit the config scripts of the packages. So here is my another try to do a crossgrade of my desktop, this time for real.
apt-get update
apt-get upgrade
apt-get autoremove
apt-get clean
dpkg --list > original.dpkg
apt-get --download-only install dpkg:amd64 tar:amd64 apt:amd64 bash:amd64 dash:amd64 init:amd64 mawk:amd64
for pack32 in $(grep i386 original.dpkg   egrep "^ii "   awk ' print $2 ' ) ; do 
  echo $pack32 ; 
  apt-get --download-only install -y --allow-remove-essential $ pack32%:i386 :amd64 ; 
done
cd /var/cache/apt/archives/
dpkg --install libacl1_*amd64.deb libattr1_*_amd64.deb libapt-pkg5.0_*amd64.deb libbz2-1.0_*amd64.deb dpkg_*amd64.deb tar_*amd64.deb apt_*amd64.deb bash_*amd64.deb dash_*amd64.deb 
dpkg --install --skip-same-version *.deb
dpkg --configure --pending
dpkg --install --skip-same-version *.deb
dpkg --remove libcurl4-openssl-dev:i386
dpkg --configure --pending
dpkg --remove libkdesu5 kde-runtime
apt-get --fix-broken install
apt-get install  $(egrep "^ii"  ~/original.dpkg   grep -v ":i386"   grep -v "all"   grep -v "aiccu"   grep -v "acroread"   grep -v "flashplayer-mozilla"   grep -v "flash-player-properties"   awk ' print $2 ')
Reboot. Then the system failed to boot, missing lvm2 package. Boot with a live CD.
sudo -i
mount /dev/sdc2         /mnt
mount /dev/vg100/usr /mnt/usr
mount /dev/vg100/var /mnt/var
mount -o bind /proc    /mnt/proc
mount -o bind /sys     /mnt/sys
mount -o bind /dev/    /mnt/dev
mount -o bind /dev/pts  /mnt/dev/pts
chroot /mnt /bin/su -
apt-get install lvm2
exit
reboot
Still somethings do not work, like command fakeroot.
for pack32 in $(grep i386 original.dpkg    egrep "^ii "   awk ' print $2 ' ) ; do     
  echo $pack32 ;     
  if dpkg --status $pack32   grep -q "Multi-Arch: same" ; then       
    apt-get -y install $ pack32%:i386 :amd64 ;     
  fi ;   
done
for pack32 in $(grep i386 original.dpkg    egrep "^ii "   awk ' print $2 ' ) ; do     
  echo $pack32 ;     
  apt-get -y install $ pack32%:i386 :amd64 ;     
done
Now is time to find what still does not work and how to solve it.

29 July 2017

Antoine Beaupr : My free software activities, July 2017

Debian Long Term Support (LTS) This is my monthly working on Debian LTS. This time I worked on various hairy issues surrounding ca-certificates, unattended-upgrades, apache2 regressions, libmtp, tcpdump and ipsec-tools.

ca-certificates updates I've been working on the removal of the Wosign and StartCom certificates (Debian bug #858539) and, in general, the synchronisation of ca-certificates across suites (Debian bug #867461) since at least last march. I have made an attempt at summarizing the issue which led to a productive discussion and it seems that, in the end, the maintainer will take care of synchronizing information across suites. Guido was right in again raising the question of synchronizing NSS across all suites (Debian bug #824872) which itself raised the other question of how to test reverse dependencies. This brings me back to Debian bug #817286 which, basically proposed the idea of having "proposed updates" for security issues. The problem is while we can upload test packages to stable proposed-updates, we can't do the same in LTS because the suite is closed and we operate only on security packages. This issue came up before in other security upload and we need to think better about how to solve this.

unattended-upgrades Speaking of security upgrades brings me to the question of a bug (Debian bug #867169) that was filed against the wheezy version of unattended-upgrades, which showed that the package simply stopped working since the latest stable release, because wheezy became "oldoldstable". I first suggested using the "codename" but that appears to have been introduced only after wheezy. In the end, I proposed a simple update that would fix the configuration files and uploaded this as DLA-1032-1. This is thankfully fixed in later releases and will not require such hackery when jessie becomes LTS as well.

libmtp Next up is the work on the libmtp vulnerabilities (CVE-2017-9831 and CVE-2017-9832). As I described in my announcement, the work to backport the patch was huge, as upstream basically backported a whole library from the gphoto2 package to fix those issues (and probably many more). The lack of a test suite made it difficult to trust my own work, but given that I had no (negative) feedback, I figured it was okay to simply upload the result and that became DLA-1029-1.

tcpdump I then looked at reproducing CVE-2017-11108, a heap overflow triggered tcpdump would parse specifically STP packets. In Debian bug #867718, I described how to reproduce the issue across all suites and opened an issue upstream, given that the upstream maintainers hadn't responded responded in weeks according to notes in the RedHat Bugzilla issue. I eventually worked on a patch which I shared upstream, but that was rejected as they were already working on it in their embargoed repository. I can explain this confusion and duplication of work with:
  1. the original submitter didn't really contact security@tcpdump.org
  2. he did and they didn't reply, being just too busy
  3. they replied and he didn't relay that information back
I think #2 is most likely: the tcpdump.org folks are probably very busy with tons of reports like this. Still, I should probably have contacted security@tcpdump.org directly before starting my work, even though no harm was done because I didn't divulge issues that were already public. Since then, tcpdump has released 4.9.1 which fixes the issue, but then new CVEs came out that will require more work and probably another release. People looking into this issue must be certain to coordinate with the tcpdump security team before fixing the actual issues.

ipsec-tools Another package that didn't quite have a working solution is the ipsec-tools suite, in which the racoon daemon was vulnerable to a remotely-triggered DOS attack (CVE-2016-10396). I reviewed and fixed the upstream patch which introduced a regression. Unfortunately, there is no test suite or proof of concept to control the results. The reality is that ipsec-tools is really old, and should maybe simply be removed from Debian, in favor of strongswan. Upstream hasn't done a release in years and various distributions have patched up forks of those to keep it alive... I was happy, however, to know that a maintainer will take care of updating the various suites, including LTS, with my improved patch. So this fixes the issue for now, but I would strongly encourage users to switch away from ipsec-tools in the future.

apache2 Finally, I was bitten by the old DLA-841-1 upload I did all the way back in February, as it introduced a regression (Debian bug #858373). It turns out it was possible to segfault Apache workers with a trivial HTTP request, in certain (rather exotic, I might add) configurations (ErrorDocument 400 directive pointing to a cgid script in worker mode). Still, it was a serious regression and I found a part of the nasty long patch we worked on back then that was faulty, and introduced a small fix to correct that. The proposed package unfortunately didn't yield any feedback, and I can only assume it will work okay for people. The result is the DLA-841-2 upload which fixes the regression. I unfortunately didn't have time to work on the remaining CVEs affecting apache2 in LTS at the time of writing.

Triage I also did some miscellaneous triage by filing Debian bug #867477 for poppler in an effort to document better the pending issue. Next up was some minor work on eglibc issues. CVE-2017-8804 has a patch, but it's been disputed. since the main victim of this and the core of the vulnerability (rpcbind) has already been fixed, I am not sure this vulnerability is still a thing in LTS at all. I also looked at CVE-2014-9984, but the code is so different in wheezy that I wonder if LTS is affected at all. Unfortunately, the eglibc gymnastics are a little beyond me and I do not feel confident enough to just push those issues aside for now and let them open for others to look at.

Other free software work And of course, there's my usual monthly volunteer work. My ratio is a little better this time, having reached an about even ratio between paid and volunteer work, whereas this was 60% volunteer work in march.

Announcing ecdysis I recently published ecdysis, a set of template and code samples that I frequently reuse across project. This is probably the least pronounceable project name I have ever chosen, but this is somewhat on purpose. The goal of this project is not collaboration or to become a library: it's just a personal project which I share with the world as a curiosity. To quote the README file:
The name comes from what snakes and other animals do to "create a new snake": they shed their skin. This is not so appropriate for snakes, as it's just a way to rejuvenate their skin, but is especially relevant for anthropods since then "ecdysis" may be associated with a metamorphosis:
Ecdysis is the moulting of the cuticle in many invertebrates of the clade Ecdysozoa. Since the cuticle of these animals typically forms a largely inelastic exoskeleton, it is shed during growth and a new, larger covering is formed. The remnants of the old, empty exoskeleton are called exuviae. Wikipedia
So this project is metamorphosed into others when the documentation templates, code examples and so on are reused elsewhere. For that reason, the license is an unusally liberal (for me) MIT/Expat license. The name also has the nice property of being absolutely unpronounceable, which makes it unlikely to be copied but easy to search online.
It was an interesting exercise to go back into older projects and factor out interesting code. The process is not complete yet, as there are older projects I'm still curious in reviewing. A bunch of that code could also be factored into upstream project and maybe even the Python standard library. In short, this is stuff I keep on forgetting how to do: a proper setup.py config, some fancy argparse extensions and so on. Instead of having to remember where I had written that clever piece of code, I now shove it in the crazy chaotic project where I can find it again in the future.

Beets experiments Since I started using Subsonic (or Libresonic) to manage the music on my phone, album covers are suddenly way more interesting. But my collection so far has had limited album covers: my other media player (gmpc) would download those on the fly on its own and store them in its own database - not on the filesystem. I guess this could be considered to be a limitation of Subsonic, but I actually appreciate the separation of duty here. Garbage in, garbage out: the quality of Subsonic's rendering depends largely on how well setup your library and tags are. It turns out there is an amazing tool called beets to do exactly that kind of stuff. I originally discarded that "media library management system for obsessive-compulsive [OC] music geeks", trying to convince myself i was not an "OC music geek". Turns out I am. Oh well. Thanks to beets, I was able to download album covers for a lot of the albums in my collection. The only covers that are missing now are albums that are not correctly tagged and that beets couldn't automatically fix up. I still need to go through those and fix all those tags, but the first run did an impressive job at getting album covers. Then I got the next crazy idea: after a camping trip where we forgot (again) the lyrics to Georges Brassens, I figured I could start putting some lyrics on my ebook reader. "How hard can that be?" of course, being the start of another crazy project. A pull request and 3 days later, I had something that could turn a beets lyrics database into a Sphinx document which, in turn, can be turned into an ePUB. In the process, I probably got blocked from MusixMatch a hundred times, but it's done. Phew! The resulting e-book is about 8000 pages long, but is still surprisingly responsive. In the process, I also happened to do a partial benchmark of Python's bloom filter libraries. The biggest surprise there was the performance of the set builtin: for small items, it is basically as fast as a bloom filter. Of course, when the item size grows larger, its memory usage explodes, but in this case it turned out to be sufficient and bloom filter completely overkill and confusing. Oh, and thanks to those efforts, I got admitted in the beetbox organization on GitHub! I am not sure what I will do with that newfound power: I was just scratching an itch, really. But hopefully I'll be able to help here and there in the future as well.

Debian package maintenance I did some normal upkeep on a bunch of my packages this month, that were long overdue:
  • uploaded slop 6.3.47-1: major new upstream release
  • uploaded an NMU for maim 5.4.64-1.1: maim was broken by the slop release
  • uploaded pv 1.6.6-1: new upstream release
  • uploaded kedpm 1.0+deb8u1 to jessie (oldstable): one last security fix (Debian bug #860817, CVE-2017-8296) for that derelict password manager
  • uploaded charybdis 3.5.5-1: new minor upstream release, with optional support for mbedtls
  • filed Debian bug #866786 against cryptsetup to make the remote initramfs SSH-based unlocking support multiple devices: thanks to the maintainer, this now works flawlessly in buster and may be backported to stretch
  • expanded on Debian bug #805414 against gdm3 and Debian bug #845938 against pulseaudio, because I had trouble connecting my computer to this new Bluetooth speaker. turns out this is a known issue in Pulseaudio: whereas it releases ALSA devices, it doesn't release Bluetooth devices properly. Documented this more clearly in the wiki page
  • filed Debian bug #866790 regarding old stray Apparmor profiles that were lying around my system after an upgrade, which got me interested in Debian bug #830502 in turn
  • filed Debian bug #868728 against cups regarding a weird behavior I had interacting with a network printer. turns out the other workstation was misconfigured... why are printers still so hard?
  • filed Debian bug #870102 to automate sbuild schroots upgrades
  • after playing around with rash tried to complete the packaging (Debian bug #754972) of percol with this pull request upstream. this ended up to be way too much overhead and I reverted to my old normal history habits.

Robert McQueen: Welcome, Flathub!

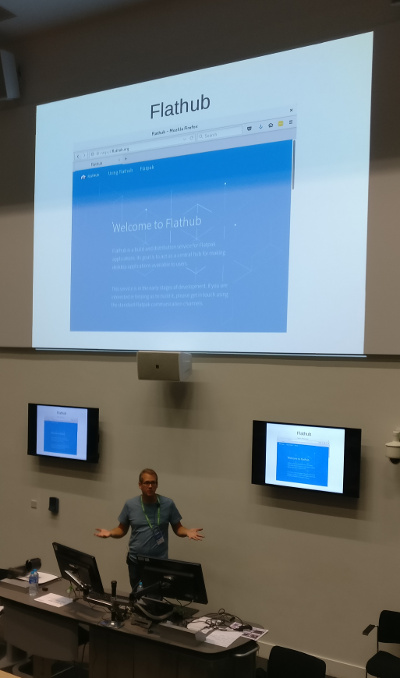
Alex Larsson talks about Flathub at GUADEC 2017At the Gtk+ hackfest in London earlier this year, we stole an afternoon from the toolkit folks (sorry!) to talk about Flatpak, and how we could establish a critical mass behind the Flatpak format. Bringing Linux container and sandboxing technology together with ostree, we ve got a technology which solves real world distribution, technical and security problems which have arguably held back the Linux desktop space and frustrated ISVs and app developers for nearly 20 years. The problem we need to solve, like any ecosystem, is one of users and developers without stuff you can easily get in Flatpak format, there won t be many users, and without many users, we won t have a strong or compelling incentive for developers to take their precious time to understand a new format and a new technology. As Alex Larsson said in his GUADEC talk yesterday: Decentralisation is good. Flatpak is a tool that is totally agnostic of who is publishing the software and where it comes from. For software freedom, that s an important thing because we want technology to empower users, rather than tell them what they can or can t do. Unfortunately, decentralisation makes for a terrible user experience. At present, the Flatpak webpage has a manually curated list of links to 10s of places where you can find different Flatpaks and add them to your system. You can t easily search and browse to find apps to try out so it s clear that if the current situation remains we re not going to be able to get a critical mass of users and developers around Flatpak. Enter Flathub. The idea is that by creating an obvious center of gravity for the Flatpak community to contribute and build their apps, users will have one place to go and find the best that the Linux app ecosystem has to offer. We can take care of the boring stuff like running a build service and empower Linux application developers to choose how and when their app gets out to their users. After the London hackfest we sketched out a minimum viable system Github, Buildbot and a few workers and got it going over the past few months, culminating in a mini-fundraiser to pay for the hosting of a production-ready setup. Thanks to the 20 individuals who supported our fundraiser, to Mythic Beasts who provided a server along with management, monitoring and heaps of bandwidth, and to Codethink and Scaleway who provide our ARM and Intel workers respectively. We inherit our core principles from the Flatpak project we want the Flatpak technology to succeed at alleviating the issues faced by app developers in targeting a diverse set of Linux platforms. None of this stops you from building and hosting your own Flatpak repos and we look forward to this being a wide and open playing field. We care about the success of the Linux desktop as a platform, so we are open to proprietary applications through Flatpak s extra data feature where the client machine downloads 3rd party binaries. They are correctly labeled as such in the AppStream, so will only be shown if you or your OS has configured GNOME Software to show you apps with proprietary licenses, respecting the user s preference. The new infrastructure is up and running and I put it into production on Thursday. We rebuilt the whole repository on the new system over the course of the week, signing everything with our new 4096-bit key stored on a Yubikey smartcard USB key. We have 66 apps at the moment, although Alex is working on bringing in the GNOME apps at present we hope those will be joined soon by the KDE apps, and Endless is planning to move over as many of our 3rd party Flatpaks as possible over the coming months. So, thanks again to Alex and the whole Flatpak community, and the individuals and the companies who supported making this a reality. You can add the repository and get downloading right away. Welcome to Flathub! Go forth and flatten  Flathub logo

Robert McQueen: Hello again!

Like all good blog posts, this one starts with an apology about not blogging for ages in my case it looks like it s been about 7 years which is definitely a new personal best (perhaps the equally or more remarkable thing is that I have diligently kept WordPress running in the meantime). In that time, as you might expect, a few things have happened, like I met a wonderful woman and fell in love and we have two wonderful children. I also decided to part ways with my first baby and leave my role as CTO & co-founder of Collabora. This was obviously a very tough decision it s a fantastic team where I met and made many life-long friends, and they are still going strong and doing awesome things with Open Source. However, shortly after that, in February last year, I was lucky enough to land what is basically a dream job working at Endless Computers as the VP of Deployment. As I m sure most readers know, Endless is building an OS to bring personal computing to millions of new users across the world. It s based on Free Software like GNOME, Debian, ostree and Flatpak, and the more successful Endless is, the more people who get access to education, technology and opportunity and the more FOSS users and developers there will be in the world. But in my role, I get to help define the product, understand our users and how technology might help them, take Open Source out to new people, solve commercial problems to get Endless OS out into the world, manage a fantastic team and work with bright people, learn from great managers and mentors, and still find time to squash bugs, review and write more code than I used to. Like any startup, we have a lot to do and not enough time to do it, so although there aren t quite enough days in the week, I m really happy! In any case, the main point of this blog post is that I m at GUADEC in Manchester right now, and I d like to blog about Flathub, but I thought it would be weird to just show up and say that after 7 years of silence without saying hello again.

Russell Coker: Apache Mesos on Debian

I decided to try packaging Mesos for Debian/Stretch. I had a spare system with a i7-930 CPU, 48G of RAM, and SSDs to use for building. The i7-930 isn t really fast by today s standards, but 48G of RAM and SSD storage mean that overall it s a decent build system faster than most systems I run (for myself and for clients) and probably faster than most systems used by Debian Developers for build purposes. There s a github issue about the lack of an upstream package for Debian/Stretch [1]. That upstream issue could probably be worked around by adding Jessie sources to the APT sources.list file, but a package for Stretch is what is needed anyway. Here is the documentation on building for Debian [2]. The list of packages it gives as build dependencies is incomplete, it also needs zlib1g-dev libapr1-dev libcurl4-nss-dev openjdk-8-jdk maven libsasl2-dev libsvn-dev. So BUILDING this software requires Java + Maven, Ruby, and Python along with autoconf, libtool, and all the usual Unix build tools. It also requires the FPM (Fucking Package Management) tool, I take the choice of name as an indication of the professionalism of the author. Building the software on my i7 system took 79 minutes which includes 76 minutes of CPU time (I didn t use the -j option to make). At the end of the build it turned out that I had mistakenly failed to install the Fucking Package Management gem and it aborted. At this stage I gave up on Mesos, the pain involved exceeds my interest in trying it out. How to do it Better One of the aims of Free Software is that bugs are more likely to get solved if many people look at them. There aren t many people who will devote 76 minutes of CPU time on a moderately fast system to investigate a single bug. To deal with this software should be prepared as components. An example of this is the SE Linux project which has 13 source modules in the latest release [3]. Of those 13 only 5 are really required. So anyone who wants to start on SE Linux from source (without considering a distribution like Debian or Fedora that has it packaged) can build the 5 most important ones. Also anyone who has an issue with SE Linux on their system can find the one source package that is relevant and study it with a short compile time. As an aside I ve been working on SE Linux since long before it was split into so many separate source packages and know the code well, but I still find the separation convenient I rarely need to work on more than a small subset of the code at one time. The requirement of Java, Ruby, and Python to build Mesos could be partly due to language interfaces to call Mesos interfaces from Ruby and Python. Ohe solution to that is to have the C libraries and header files to call Mesos and have separate packages that depend on those libraries and headers to provide the bindings for other languages. Another solution is to have autoconf detect that some languages aren t installed and just not try to compile bindings for them (this is one of the purposes of autoconf). The use of a tool like Fucking Package Management means that you don t get help from experts in the various distributions in making better packages. When there is a FOSS project with a debian subdirectory that makes barely functional packages then you will be likely to have an experienced Debian Developer offer a patch to improve it (I ve offered patches for such things on many occasions). When there is a FOSS project that uses a tool that is never used by Debian developers (or developers of Fedora and other distributions) then the only patches you will get will be from inexperienced people. A software build process should not download anything from the Internet. The source archive should contain everything that is needed and there should be dependencies for external software. Any downloads from the Internet need to be protected from MITM attacks which means that a responsible software developer has to read through the build system and make sure that appropriate PGP signature checks etc are performed. It could be that the files that the Mesos build downloaded from the Apache site had appropriate PGP checks performed but it would take me extra time and effort to verify this and I can t distribute software without being sure of this. Also reproducible builds are one of the latest things we aim for in the Debian project, this means we can t just download files from web sites because the next build might get a different version. Finally the fpm (Fucking Package Management) tool is a Ruby Gem that has to be installed with the gem install command. Any time you specify a gem install command you should include the -v option to ensure that everyone is using the same version of that gem, otherwise there is no guarantee that people who follow your documentation will get the same results. Also a quick Google search didn t indicate whether gem install checks PGP keys or verifies data integrity in other ways. If I m going to compile software for other people to use I m concerned about getting unexpected results with such things. A Google search indicates that Ruby people were worried about such things in 2013 but doesn t indicate whether they solved the problem properly.

Chris Lamb: More Lintian hacking

Lintian is static analysis tool for Debian packages, reporting on various errors, omissions and quality-assurance issues to the maintainer. I seem to have found myself hacking on it a bit more recently (see my previous installment). In particular, here's the code of mine which made for a total of 20 bugs closed that made it into the recent 2.5.52 release:
New tags
  • Check for the presence of an .asc signature in a .changes file if an upstream signing key is present. (#833585, tag)
  • Warn when dpkg-statoverride --add is called without a corresponding --list. (#652963, tag)
  • Check for years in debian/copyright that are later than the top entry in debian/changelog. (#807461, tag)
  • Trigger a warning when DEB_BUILD_OPTIONS is used instead of DEB_BUILD_MAINT_OPTIONS. (#833691, tag)
  • Look for "FIXME" and similar placeholders in various files in the debian directory. (#846009, tag)
  • Check for useless build-dependencies on dh-autoreconf or autotools-dev under Debhelper compatibility levels 10 or higher. (#844191, tag)
  • Emit a warning if GObject Introspection packages are missing dependencies on $ gir:Depends . (#860801, tag)
  • Check packages do not contain upstart configuration under /etc/init. (#825348, tag)
  • Emit a classification tag if maintainer scripts such as debian/postinst is an ELF binary. (tag)
  • Check for overly-generic manual pages such as README.3pm.gz. (#792846, tag)
  • Ensure that (non-ELF) maintainer scripts begin with #!. (#843428, tag)

Regression fixes
  • Ensure r-data-without-readme-source checks the source package, not the binary; README.source files are not installed in the latter. (#866322, tag)
  • Don't emit source-contains-prebuilt-ms-help-file for files generated by Halibut. (#867673, tag)
  • Add .yml to the list of file extensions to avoid false positives when emitting extra-license-file. (#856137, tag)
  • Append a regression test for enumerated lists in the "a) b) c) " style, which would previously trigger a "duplicate word" warning if the following paragraph began with an "a." (#844166, tag)

Documentation updates
  • Rename copyright-contains-dh-make-perl-boilerplate to copyright-contains-automatically-extracted-boilerplate as it can be generated by other tools such as dh-make-elpa. (#841832, tag)
  • Changes to new-package-should-not-package-python2-module (tag):
    • Upgrade from I: to W:. (#829744)
    • Clarify wording in description to make the justification clearer.
  • Clarify justification in debian-rules-parses-dpkg-parsechangelog. (#865882, tag)
  • Expand the rationale for the latest-debian-changelog-entry-without-new-date tag to mention possible implications for reproducible builds. (tag)
  • Update the source-contains-prebuilt-ms-help-file description; there exists free software to generate .chm files. (tag)
  • Append an example shell snippet to explain how to prevent init.d-script-sourcing-without-test. (tag)
  • Add a missing "contains" verb to the description of the debhelper-autoscript-in-maintainer-scripts tag. (tag)
  • Consistently use the same "Debian style" RFC822 date format for both "Mirror timestamp" and "Last updated" on the Lintian index page. (#828720)

Misc
  • Allow the use of suppress-tags=<tag>[,<tag>[,<tag>]] in ~/.lintianrc. (#764486)
  • Improve the support for "3.0 (git)" packages. However, they remain marked as unsupported-source-format as they are not accepted by the Debian archive. (#605999)
  • Apply patch from Dylan A ssi to also check for .RData files (not just .Rdata) when checking for the copyright status of R Project data files. (#868178, tag)
  • Match more Lena S derberg images. (#827941, tag)
  • Refactor a hard-coded list of possible upstream key locations to the common/signing-key-filenames Lintian::Data resource.

Norbert Preining: Gaming: The Long Dark

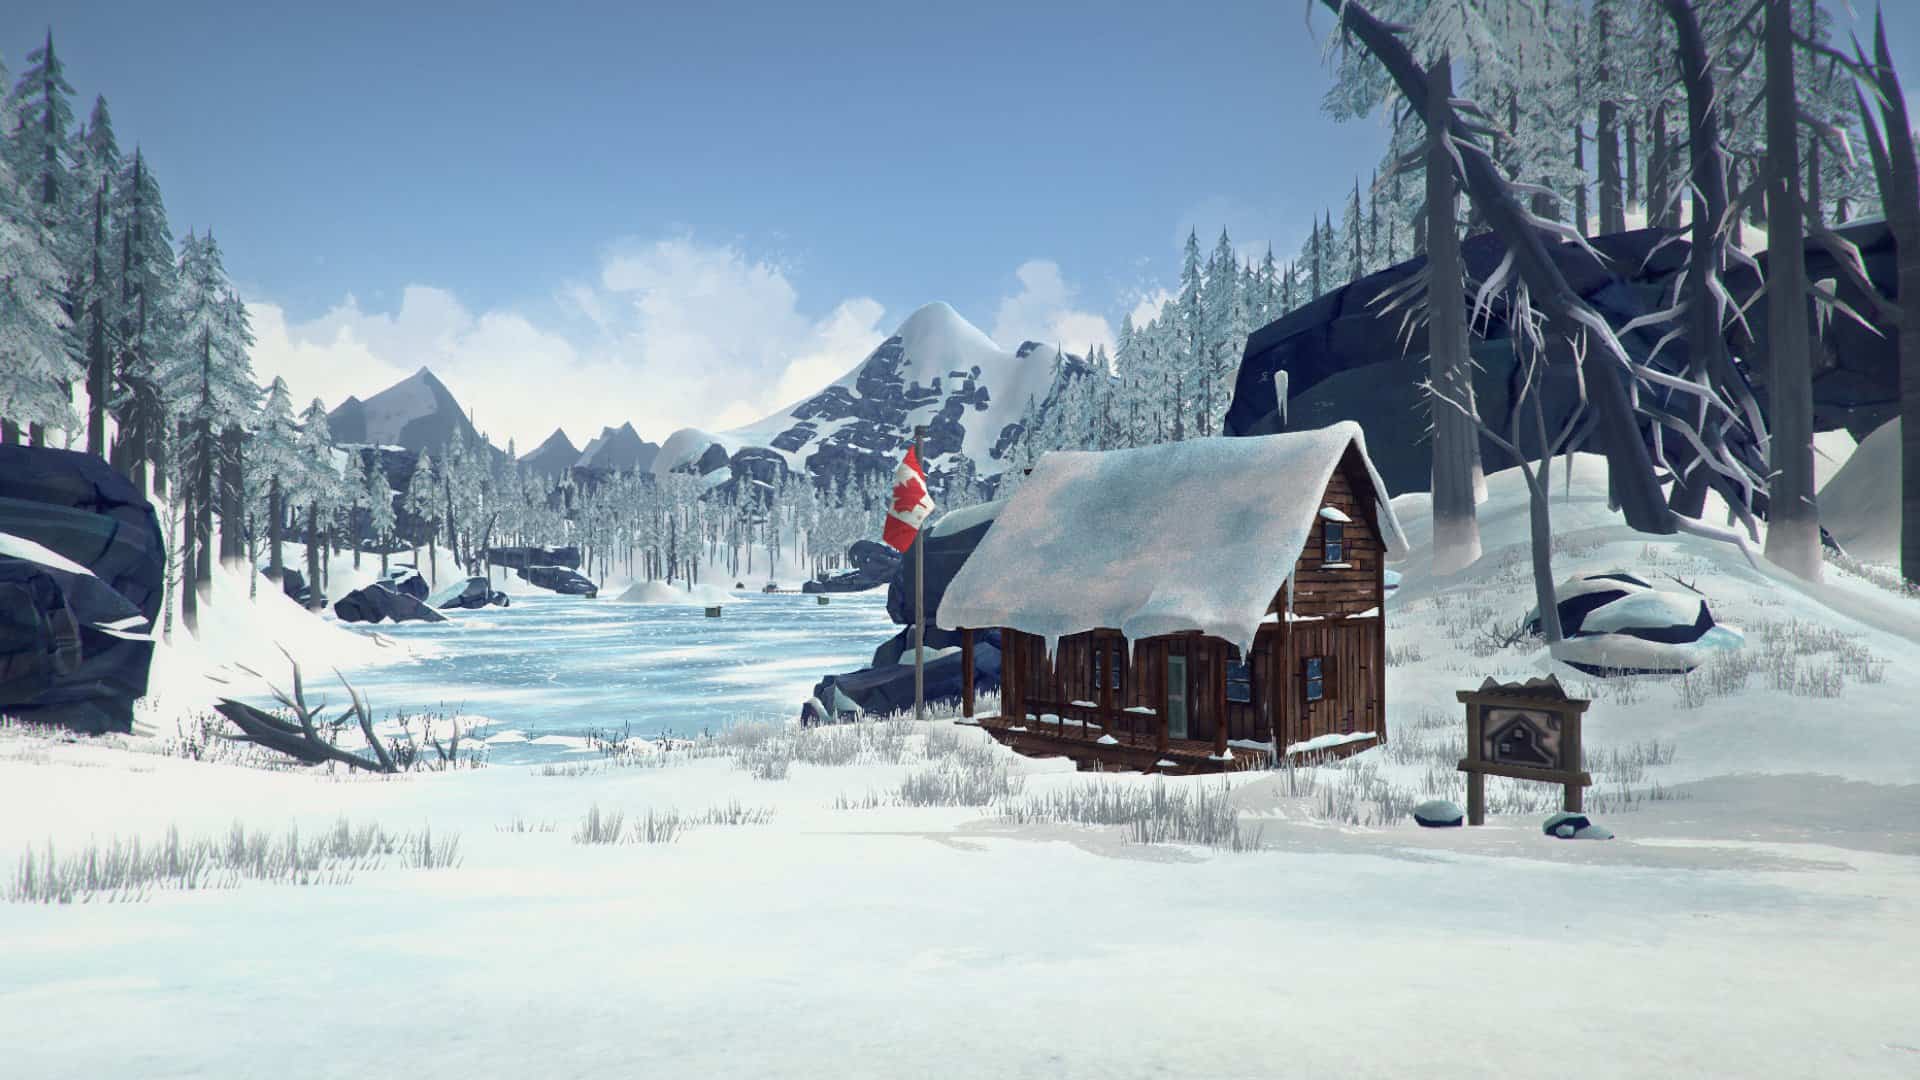
I normally don t play survival games or walking simulators, but The Long Dark by Hinterland Games, which I purchased back then when it was still in early access on Steam, took me into new realms. You are tossed out into the Canadian wilderness with hardly anything, and your only aim is to survive, find shelter, food, craft tools, hunt for food, explore. And while everything by now is Sandbox mode, on August 1st the first episode of Story mode is released. Best time to get the game! You will be greeted with some icy nights, but also with great vistas, relaxed evenings at a fire place, you will try to survive on moldy food and rotten energy bars, but also feast on the fireside while reading a good book. A real treat this game! Sandbox mode features five different areas to explore. Each one is large enough to spend weeks (in game time) wandering around. The easiest area to start with is Mystery Lake, with plenty of shelter (several huts) and abundance of resources. And just in case you are getting bored, all the areas are connected via tunnels or caves and one can wander of into the neighboring places. My home in Mystery Lake was always the Camp Office, the usual suspect. Nice views, fishing huts nearby to get fresh fish, lots of space. After managing to get from your starting place (which is arbitrary as far as I see) to one of the shelters, one starts collecting food, wood, savaging every accessible place for tools, weapons, burning material. And soon the backpack becomes to heavy, and one needs to store stuff and decide what to take. This is a very well done part of the game. The backpack is not limited by number of items, but you are limited in weight you can carry. That includes clothes (which can get quite heavy) and all the items in your backpack. In addition, the longer the day and the more tired you become, the less weight you can carry. And if the backpack starts getting too heavy you crawl to a very slow movement. There are many influences of the outside world on the player s condition: temperature, the wetness of your clothes, hunger, thirst, exhaustion, but also infections and bruises, all need to be taken care of, otherwise the end is coming faster than one wishes for. I have only two things to complain: First, if one walks outside, or runs outside, the own body temperature does not rise. This is unrealistically and should have been taken into account. The other thing is the difficulty: I have played weeks in game time in the easiest level, without any problem. But the moment I switched to the second level of difficulty (of 5!), I not even manage it for 2(!) days. Wolves, starvation, thirst, any of those kills me within an instant. I don t want to know how the hardest level feels, but it has a certain steep step here. The game takes a very realistic view onto the weather: Every day is different, sunny, foggy, blizzard, windy, often changing very quickly. It is wise to plan one s activities according to the weather, as it is very unforgiving. With beautifully crafted landscapes, loads of areas to explore, your own pride to survive for at least a few weeks, and lots of tools to find and craft and try out, this games, even while it is still in Sandbox mode, is a real feat. My absolute favorite since I have finished the Talos Principle and Portal series, absolutely recommendable!
28 July 2017

Steve Kemp: So I'm considering a new project

In the past there used to be a puppet-labs project called puppet-dashboard, which would let you see the state of your managed-nodes. Having even a very basic and simple "report user-interface" is pretty neat when you're pushing out a change, and you want to see it be applied across your fleet of hosts. There are some other neat features, such as allowing you to identify failures easily, and see nodes that haven't reported-in recently. This was spun out into a community-supported project which is largely stale: Having a dashboard is nice, but the current state of the software is less good. It turns out that the implementation is pretty simple though: The reporting node can thus receive real-time updates, and do what it wants with them. You can even sidestep the extra server if you wish: For example on my puppet-master I have this:
  root@master /var/lib/puppet/reports # ls   tail -n4
  smaug.dh.bytemark.co.uk
  ssh.steve.org.uk
  www.dns-api.com
  www.steve.org.uk
Inside each directory is a bunch of YAML files which describe the state of the host, and the recipes that were applied. Parsing those is pretty simple, the hardest part would be making a useful/attractive GUI. But happily we have the existing one to "inspire" us. I think I just need to write down a list of assumptions and see if they make sense. After all the existing installation(s) won't break, it's just a matter of deciding whether it is useful/worthwhile way to spend some time. Beyond that you might want to export data about the managed-nodes themselves. For example you might want a list of all the hosts which have "bash" installed on them. Or "All nodes with local user "steve"." I've written that stuff already, as it is very useful for auditing & etc. The hard part about that is that to get the extra data you'll need to include a puppet module to collect it. I suspect a new dashboard would be broadly interesting/useful but unless you have that extra detail it might not be so useful. You can't point to a slightly more modern installation and say "Yes this is worth migrating to". But if you have extra meta-data you can say: And that facility is very useful when you have shellshock, or similar knocking at your door. Anyway as a hacky start I wrote some code to parse reports, avoiding the magic object-fu that the YAML would usually invoke. The end result is this:
 root@master ~# dump-run www.steve.org.uk
 www.steve.org.uk
    Puppet Version: 4.8.2
    /var/lib/puppet/reports/www.steve.org.uk/201707291813.yaml
    Runtime: 2.16
    Status:changed
    Time:2017-07-29 18:13:04 +0000
    Resources
            total -> 176
            skipped -> 2
            failed -> 0
            changed -> 3
            out_of_sync -> 3
            scheduled -> 0
            corrective_change -> 3
    Changed Resources
            Ssh_authorized_key[skx@shelob-s-fi] /etc/puppet/code/environments/production/modules/ssh_keys/manifests/init.pp:17
            Ssh_authorized_key[skx@deagol-s-fi] /etc/puppet/code/environments/production/modules/ssh_keys/manifests/init.pp:22
            Ssh_authorized_key[steve@ssh.steve.org.uk-s-fi] /etc/puppet/code/environments/production/modules/ssh_keys/manifests/init.pp:27
    Skipped Resources
            Exec[clone sysadmin utils]
            Exec[update sysadmin utils]

Joachim Breitner: How is coinduction the dual of induction?

Earlier today, I demonstrated how to work with coinduction in the theorem provers Isabelle, Coq and Agda, with a very simple example. This reminded me of a discussion I had in Karlsruhe with my then colleague Denis Lohner: If coinduction is the dual of induction, why do the induction principles look so different? I like what we observed there, so I d like to share this. The following is mostly based on my naive understanding of coinduction based on what I observe in the implementation in Isabelle. I am sure that a different, more categorial presentation of datatypes (as initial resp. terminal objects in some category of algebras) makes the duality more obvious, but that does not necessarily help the working Isabelle user who wants to make sense of coninduction.

Inductive lists I will use the usual polymorphic list data type as an example. So on the one hand, we have normal, finite inductive lists:
datatype 'a list = nil   cons (hd : 'a) (tl : "'a list")
with the well-known induction principle that many of my readers know by heart (syntax slightly un-isabellized):
P nil   ( x xs. P xs   P (cons x xs))     xs. P xs

Coinductive lists In contrast, if we define our lists coinductively to get possibly infinite, Haskell-style lists, by writing
codatatype 'a llist = lnil   lcons (hd : 'a)  (tl : "'a llist")
we get the following coinduction principle:
(  xs ys.
    R xs ys'   (xs = lnil) = (ys = lnil)  
               (xs   lnil   ys'   lnil  
	         hd xs = hd ys   R (tl xs) (tl ys)))  
  (  xs ys. R xs ys   xs = ys)
This is less scary that it looks at first. It tell you if you give me a relation R between lists which implies that either both lists are empty or both lists are nonempty, and furthermore if both are non-empty, that they have the same head and tails related by R, then any two lists related by R are actually equal. If you think of the infinte list as a series of states of a computer program, then this is nothing else than a bisimulation. So we have two proof principles, both of which make intuitive sense. But how are they related? They look very different! In one, we have a predicate P, in the other a relation R, to point out just one difference.

Relation induction To see how they are dual to each other, we have to recognize that both these theorems are actually specializations of a more general (co)induction principle. The datatype declaration automatically creates a relator:
rel_list :: ('a   'b   bool)   'a list   'b list   bool
The definition of rel_list R xs ys is that xs and ys have the same shape (i.e. length), and that the corresponding elements are pairwise related by R. You might have defined this relation yourself at some time, and if so, you probably introduced it as an inductive predicate. So it is not surprising that the following induction principle characterizes this relation:
Q nil nil  
( x xs y ys. R x y   Q xs ys   Q (cons x xs) (cons y ys))  
( xs ys   rel_list R xs ys   Q xs ys)
Note how how similar this lemma is in shape to the normal induction for lists above! And indeed, if we choose Q xs ys (P xs xs = ys) and R x y (x = y), then we obtain exactly that. In that sense, the relation induction is a generalization of the normal induction.

Relation coinduction The same observation can be made in the coinductive world. Here, as well, the codatatype declaration introduces a function
rel_llist :: ('a   'b   bool)   'a llist   'b llist   bool
which relates lists of the same shape with related elements only that this one also relates infinite lists, and therefore is a coinductive relation. The corresponding rule for proof by coinduction is not surprising and should remind you of bisimulation, too:
( xs ys.
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))  
(  xs ys   R xs ys   rel_llist Q xs ys)
It is even more obvious that this is a generalization of the standard coinduction principle shown above: Just instantiate Q with equality, which turns rel_llist Q into equality on the lists, and you have the theorem above.

The duality With our induction and coinduction principle generalized to relations, suddenly a duality emerges: If you turn around the implication in the conclusion of one you get the conclusion of the other one. This is an example of cosomething is something with arrows reversed . But what about the premise(s) of the rules? What happens if we turn around the arrow here? Although slighty less immediate, it turns out that they are the same as well. To see that, we start with the premise of the coinduction rule, reverse the implication and then show that to be equivalent to the two premises of the induction rule:
( xs ys.
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))
=   case analysis (the other two cases are vacuously true)  
  ( xs ys.
    xs = lnil   ys = lnil  
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))
  ( xs ys.
    xs   lnil   ys   lnil
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))
=   simplification  
  ( xs ys.  xs = lnil   ys = lnil   R xs ys
  ( x xs y ys.  R (cons x xs) (cons y ys)   (Q x y   R xs ys))
=   more rewriting  
  R nil nil
  ( x xs y ys. Q x y   R xs ys   R (cons x xs) (cons y ys))

Conclusion The coinduction rule is not the direct dual of the induction rule, but both are specializations of more general, relational proof methods, where the duality is clearly present. More generally, this little excursion shows that it is often beneficial to think of types less as sets, and more as relations this way of thinking is surprisingly fruitful, and led to proofs of parametricity and free theorems and other nice things.

25 July 2017

Reproducible builds folks: Reproducible Builds: week 117 in Buster cycle

Here's what happened in the Reproducible Builds effort between Sunday July 16 and Saturday July 22 2017: Toolchain development Bernhard M. Wiedemann wrote a tool to automatically run through different sources of non-determinism, and report which of these caused irreproducibility. Dan Kegel's patches to fpm were merged. Bugs filed Patches submitted upstream: Patches filed in Debian: Reviews of unreproducible packages 73 package reviews have been added, 44 have been updated and 50 have been removed in this week, adding to our knowledge about identified issues. No issue types were updated. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development reprotest development Ximin also restarted the discussion with autopkgtest-devel about code reuse for reprotest. Santiago Torres began a series of patches to make reprotest more distro-agnostic, with the aim of making it usable on Arch Linux. Ximin reviewed these patches. Misc. This week's edition was written by Ximin Luo, Bernhard M. Wiedemann and Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Russell Coker: Forking Mon and DKIM with Mailing Lists

I have forked the Mon network/server monitoring system. Here is a link to the new project page [1]. There hasn t been an upstream release since 2010 and I think we need more frequent releases than that. I plan to merge as many useful monitoring scripts as possible and support them well. All Perl scripts will use strict and use other best practices. The first release of etbe-mon is essentially the same as the last release of the mon package in Debian. This is because I started work on the Debian package (almost all the systems I want to monitor run Debian) and as I had been accepted as a co-maintainer of the Debian package I put all my patches into Debian. It s probably not a common practice for someone to fork upstream of a package soon after becoming a comaintainer of the Debian package. But I believe that this is in the best interests of the users. I presume that there are other collections of patches out there and I hope to merge them so that everyone can get the benefits of features and bug fixes that have been separate due to a lack of upstream releases. Last time I checked mon wasn t in Fedora. I believe that mon has some unique features for simple monitoring that would be of benefit to Fedora users and would like to work with anyone who wants to maintain the package for Fedora. I am also interested in working with any other distributions of Linux and with non-Linux systems. While setting up the mailing list for etbemon I wrote an article about DKIM and mailing lists (primarily Mailman) [2]. This explains how to setup Mailman for correct operation with DKIM and also why that seems to be the only viable option.

Gunnar Wolf: Getting ready for DebConf17 in Montreal!


(image shamelessly copied from Noodles' Emptiness) This year I will only make it to DebConf, not to DebCamp. But, still, I am very very happy and excited as the travel date looms nearer! I have ordered some of the delicacies for the Cheese and Wine party, signed up for the public bicycle system of Montreal, and done a fair share of work with the Content Team; finally today we sent out the announcement for the schedule of talks. Of course, there are several issues yet to fix, and a lot of things to do before traveling... But, no doubt about this: It will be an intense week! Oh, one more thing while we are at it: The schedule as it was published today does not really look like we have organized stuff into tracks But we have! This will be soon fixed, adding some color-coding to make tracks clearer on the schedule. This year, I pushed for the Content Team to recover the notion of tracks as an organizative measure, and as something that delivers value to DebConf as a whole. Several months ago, I created a Wiki page for the DebConf tracks, asking interested people to sign up for them. We currently have the following tracks registered:
Blends
Andreas Tille
Debian Science
Michael Banck
Cloud and containers
Luca Filipozzi
Embedded
Pending
Systems administration, automation and orchestation
Pending
Security
Gunnar Wolf
We have two tracks still needing a track coordinator. Do note that most of the tasks mentioned by the Wiki have already been carried out; what a track coordinator will now do is to serve as some sort of moderator, maybe a recurring talkmeister, ensuring continuity and probably providing for some commentary, giving some unity to its sessions. So, the responsibilities for a track coordinator right now are quite similar to what is expected for video team volunteers but to a set of contiguous sessions. If you are interested in being the track coordinator/moderator for Embedded or for Systems administration, automation and orchestation or even to share the job with any of the other, registered, coordinators, please speak up! Mail content@debconf.org and update the table in the Wiki page. See you very soon in Montreal!

Next.

Previous.