Search Results: "ema"

11 June 2014

Daniel Pocock: Protest or Uber marketing stunt?

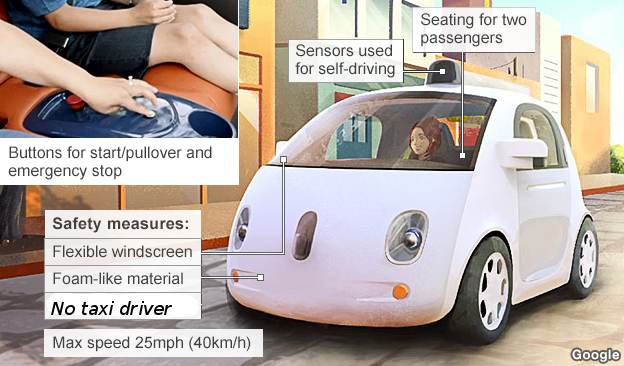
London's taxi "strike" today has been so successful that Uber claims to have had an 850% increase in new customer registrations this week. Well, that is a big success if you believe the strike may have been a guerrilla marketing tactic organised by Uber itself. No sympathy Personally, I have no sympathy for the taxi drivers. There is no city I have ever visited where I haven't encountered at least one taxi driver who tried to overcharge me. Honest drivers who give their customers value for money have less to fear from new technology than those who are unscrupulous. When I broke a leg a few years ago and was getting about on crutches for 6 weeks we decided to go out for dinner one night. This was the first time I went anywhere after having a long stint in hospital followed by a period of time I was confined to the house. The taxi driver deliberately skipped two turns leading directly to the restaurant, went another 1km past it and then followed a small street that winds back and forth and eventually demanded I pay him double what the fare should have been. This is exactly the type of abusive and despicable practice that is being eradicated by Uber's live GPS mapping technology. Although not every driver behaves so shamefully, this type of abuse of the weak or vulnerable is replicated in one way or another the world over. For example, in Melbourne, Australia, wheelchair taxis that have worked out they can make more money collecting families with suitcases at the airport leave genuine wheelchair users without a ride. Will Google be targeted next week? Google has just announced a step-change in plans to build their own self driving cars. Will Google offices around the world, including London be targetted by these crude blockades too? Political protest or anti-competitive mischief? Why were taxi drivers not arrested for their protest today? Given that the roads are the place where taxis and their competitors do business, can this blockade really be considered a political protest or is it an anti-competitive practice in blatant disregard of the law? Weapons of mass destruction Before even having breakfast you could probably find 10,000 cyclists in central London willing to sign a petition declaring taxis are a weapon of mass destruction. Once again, while there are honest drivers, there is a more than trivial number of taxi drivers who are a genuine danger to the lives of cyclists, scooters, motorcycles and occasionally pedestrians. I have personally experienced one of these thugs ramming my bicycle from behind (his hard-nosed insurer eventually paid up but without admitting liability). The police who attended the incident even told me they had seen so many accidents like this they wouldn't dare cycle themselves. The web is full of examples that appear to show malicious and criminal behavior by taxi drivers, thanks to Youtube and helmet cams: Will hotels protest about AirBNB? Now the taxi drivers have had their chance to cause mayhem, will hotel operators be next? What could they do though? Will they seek out AirBNB apartments and try to obstruct them somehow? Making mischief outside somebody's home is not a good way to make a point. Chances are, they would be prosecuted or served with restraining orders. So why do the taxi drivers get to jam up whole cities and get away with it? The Uber taxi meter loophole Will the courts decide that the Uber app is a taxi meter? This is actually a tough question. Even if courts rule against apps that perform live metering, Uber could simply remove all metering functions from the app itself and perform the metering calculations in the cloud. The app would just send start and finish locations to the cloud and the cloud would send a message back to the phone confirming the charge. The phone is then nothing more than a communication and positioning device. Remember the elevator man? When the automobile was first invented, laws were made requiring every car to be accompanied through public streets by a man carrying a flag. That job, like many others, no longer exists. elevator attendant In the good old days, every elevator had a man or woman who would sit on a stool and press buttons to operate the doors and motors. Some up-market department stores and hotels still have an elevator man to add a touch of nostalgia. The vast majority, however, have eliminated these jobs thanks to automatic elevators. Now, even aircraft can land automatically on a ship at sea. Look at all those people manning the deck in the video and contemplate how many of them might potentially be out of a job too in 50 years time as Terminator-style automated battleships patrol the seas. Technology, like the Terminator, is not going to stop.

10 June 2014

Steve Kemp: I did get a job

In my previous blog-post I mentioned, briefly, that I'd posted a couple of adverts on Reddit looking for work. To give more detail I did three things: The advertisement was set to be shown in /r/edinburgh (where I live), and /r/sysadmin (where I thought some people might look if they were struggling for help). The advertising on Reddit was painless to setup, and the traffic stats were interesting, but even though this worked out well I'm a little loathe to repeat the process - since the "non-sterling transaction fee" from my bank effectively doubled my budget. I received a few (private) emails and comments, along with the expected grammar corrections. The end result was that I received contact from an American company founder who seemed interested. He allowed me to write some code to solve a fun problem, appeared to enjoy the code I sent (Ruby code for dealing with (exim) email spam, that's as specific as I will be). The end result was a three month contract, which we obviously hope will lead to more permanent work. Anyway I thought this was an atypical route to find a work, and was about a million times nicer than working with recruiters, so .. consider this documentation! In other news it is now 10pm and I need to go to the gym and pub, in that order.

Steve Kemp: I'm still not a developer, but ..

Some coding updates: My templer static site generator has now been uploaded to CPAN, and is available as App::Templer. I've converted most of my Dockerfiles to work with docker 1.0.0, which is nice. I also hacked up a fun DNS-server for sharing JSON-encoded data, within a LAN or other environment: Finally I updated the blogspam-detecting site a little, on the back-end. The code is now running inside Docker containers which means I can redeploy more easily in the future. My blog post about looking for a job received some attention via a Reddit advert I posted to /r/edinburgh + /r/sysadmin, but thus far has mostly resulted in people wanting me to write code for them .. which is frustrating. For the moment I'm working on a fun challenge involving (email) spam-detection. That takes me back.

Russell Coker: Google Hardware Support

Ironically just 5 days after writing about how I choose Android devices for a long service life [1] my wife s Nexus 5 (with 32G of RAM (sorry Flash storage) to give it a long useful life) totally died. It reported itself as being fully charged and then 15 minutes later it was off and could not be revived. No combination of pushing the power button and connecting the power cable caused the screen to light up or any sound to be emitted. Google has a nice interactive support site for nexus devices that describes more ways of turning a phone on than any reasonable person could imagine. After trying to turn the phone on in various ways (plugged and unplugged etc) it gave me a link to get phone support. Clicking on that put me in the queue to RECEIVE a phone call and a minute later a lady who spoke English really well (which is unusual for telephone support) called me to talk me through the various options. Receiving a phone call is a much better experience than making a call. It meant that if the queue for phone support was long then I could do other things until the phone rings. It s impossible to be productive at other tasks while listening for hold music to stop and a person to start talking. The cost of doing this would be very tiny, while there would be some cost in hardware and software to have a web site that tells me how long I can expect to wait for a call a more basic implementation where I just submit my number and wait for a call would be very cheap to implement. The costs of calls from the US to Australia (and most places where people can afford a high end Android phone) are quite cheap for home users and are probably cheaper if you run a call center. If the average support call cost Google $1 and 3% of phones have support calls then that would be an extra cost of $0.03 per phone. I expect that almost everyone who buys a $450 phone would be happy to pay a lot more than $0.03 to avoid the possibility of listening to hold music! I received the phone call about a minute after requesting it, this was nice but I wonder how long I would have waited if I hadn t requested a call at 1AM Australian time (presumably during the day in a US call center). In any case getting a 1 minute response is great for any time of the day or night, lots of call centers can t do that. While the phone support is much better than most phone support, it would be nice if they added some extra options. I think it would be good to have webchat and SMS as options for support for the benefit of people who don t want to speak to strangers. This would be useful to a lot of people on the Autism Spectrum and probably others too. The phone call wasn t particularly productive, it merely confirmed that I had followed all the steps on the support website. Then I received an email telling me about the web site which was a waste of time as I d covered that in the phone call. I have just replied to their second email which asked for the IMEI of the phone to start the warranty return process. We could have saved more than 24 hours delay if this had been requested in the first email or the phone call. Google could have even requested the IMEI through the web site before starting the phone call. It would have been even easier if Google had included the device IMEI in the email they sent me to confirm the purchase as searching for old email is a lot easier than searching through my house for an old box. Another option for Google would be to just ask me for the Gmail account used for the purchase, as I only bought one Nexus 5 on that account they then have all the purchase details needed for a warranty claim. While the first call was a great experience the email support following that has been a waste of time. I m now wondering if they aim to delay the warranty process for a few days in the hope that the phone will just start working again.

9 June 2014

Konstantinos Margaritis: SIMD book, second update!

From the Indiegogo page: https://www.indiegogo.com/projects/simd-engines-comparative-reference-guide/x/4966960#activity
  • Added titlepage (simple, but will do the job)
  • Reorganized ALL instructions to include both unsigned/signed in the same entity
  • Added Saturated Addition, Subtraction and Saturated Subtraction
  • Added ARMv8 NEON instructions taken from ARM infocenter draft
  • Fixed some instructions (added 64-bit arithmetic for NEON)
  • Added some special addition/subtraction, like add/sub with carry(vmx/vsx), addsub(SSE3/AVX)
  • Added some in-vector sum additions, sum reductions but no descriptions yet
  • Added diagram for 8-bit addition/subtraction (still need lots more).
  • Removed VMX128, couldn't find enough information, an email to some IBM toolchain developers was left unanswered, so I guess noone really will really care if that engine is left out, if enough people insist on it, please also be kind enough to provide some documentation on it.

Dirk Eddelbuettel: Rcpp 0.11.2

A new minor release 0.11.2 of Rcpp is now on the CRAN network for GNU R, and binaries for Debian have also been uploaded. The release smoothes a few edges on both the Rcpp side itself, as well as on the interaction between Rcpp and R which since release 3.1.0 offers a few new features related to C++11. Kevin added a couple of neat extensions related to vectors, a new ListOf templated list class, as well as a new option to warn on implicit casts. We decided not to make this option the default as it may be too common in some packages. JJ took care of a few buglets related to the wonderful Rcpp Attributes. See the NEWS file section below for details, or the ChangeLog file in the package and on the Rcpp Changelog page. Note that the diffstat reported by CRANberries is very large as Kevin also committed a whitespace cleanup which touched almost all files. As before, we tested this release by building against all CRAN packages which depend upon Rcpp. In fact we did three such runs leading up to the release. Only one package was blacklisted (as I currently don't have CUDA set-up), two had what may be internal errors or tests which were too restrictive, sixteen suffered from missing packages or RGL devices --- but the remaining 202 packages all built and tested cleanly. Detailed results of those tests (and the scripts for it) are in the rcpp-logs repo GitHub. There are a number of other fixes, upgrades and other extensions detailed in NEWS file extract below, in the ChangeLog file in the package and on the Rcpp Changelog page.
Changes in Rcpp version 0.11.2 (2014-06-06
  • Changes in Rcpp API:
    • Implicit conversions, e.g. between NumericVector and IntegerVector, will now give warnings if you use #define RCPP_WARN_ON_COERCE before including the Rcpp headers.
    • Templated List containers, ListOf<T>, have been introduced. When subsetting such containers, the return is assumed to be of type T, allowing code such as ListOf<NumericVector> x; NumericVector y = x[0] + x[1] + x[2].
    • In a number of instances, returned results are protected and/or cast more carefully.
  • Changes in Rcpp Attributes
    • Trailing line comments are now stripped by the attributes parser. This allows the parser to handle C++ source files containing comments inline with function arguments.
    • The USE_CXX1X environment variable is now defined by the cpp11 plugin when R >= 3.1. Two additional plugins have been added for use with C++0x (eg when using g++ 4.6.* as on Windows) as well as C++1y for compilers beginning to support the next revision of the standard; additional fallback is provided for Windows.
    • compileAttributes() now also considers Imports: which may suppress a warning when running Rcpp.package.skeleton().
Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

8 June 2014

Bits from Debian: DebConf14 - Call for talks, BoFs and events

The Debian project is excited to announce that we are now accepting presentations, discussion sessions and tutorials for our DebConf14 conference which will take place in Portland State University, Oregon, USA from 23 to 31 August. Submitting an event To submit an event, first register as an attendee for DebConf14 in the conference management system. If you have any doubts or have problems with the registration process please check the Registration FAQ. After registering, go to the event submission page, or click on the Create an event option from the management system. Describe your submission in the web form. The most common event types are Lecture or Open Discussion (BoF). Please include a short title (to make it easy to produce a compact schedule) and an engaging description of the event. Tracks We will organize some talks into thematic tracks. If you have a proposal for a DebConf track, such as "Debian ARM", "Debian Infrastructure", or "Community Outreach" please contact talks@debconf.org. If you would like to be a track coordinator, please volunteer on the given mail address. Format of the events A regular session will be 45 minutes long, including time for questions. There will be a 15 minute breaks between events. Submissions are not limited to traditional talks: you could propose a performance, art installation, debate, or anything else. If you have any specific requirements for your event, please send an email to talks@debconf.org with the details of your requirements and be sure to mention your event title in the subject. Deadline While we ask speakers to submit their events before the deadline of 7 July 2014, 23:59:59 UTC, late submissions will continue to be accepted for scheduling until the end of DebConf. All attendees will have an opportunity to schedule ad-hoc events during DebConf itself if we have space for them. Very promising late submissions may be considered for inclusion in the main conference. Note that ad-hoc events have a much lower chance of video archiving, and streaming, so if you want these services it's better to get your submissions in early. DebConf official events will be broadcast live on the Internet when possible, and videos of the talks will be published on the web along with the presentation slides and papers. For private communication regarding your talk, or for more general ideas, or questions about the event and talks, please mail us We hope to you see you and share some good times with you this year in Portland during DebConf14!

7 June 2014

Vasudev Kamath: Exposing function in python module using entry_points, WSME in a Flask webapp

The heading might be ambiguous, but I couldn't figure out better heading so let me start by explaining what I'm trying to solve here.
Problem I have a python module which contains a function which I want to expose as a REST web service in a Flask application. I use WSME for Flask application, which actually needs signature of function in question and problem comes to picture because function to be exposed is foreign to Flask application, it resides in separate python module.
Solution While reading Julien Danjou's Hackers Guide To Python book I came across the setuptools entry_points concept which can be used to extend existing feature of a tool like plug-ins. So here I'm going to use this entry_points feature from setuptools to provide function in the module which can expose the signature of function[s] to be exposed through REST. Of course this means I need to modify module in question to write entry_points and function for giving out signature of function to be exposed. I will explain this with small example. I have a dummy module which provides a add function and a function which exposes the add functions signature.
def add(a, b):
    return a + b
def expose_rest_func():
    return [add, int, int, int]
This is stored in dummy/__init__.py file. I use pbr tool to package my python module. Below is content of setup.cfg file.
[metadata]
name = dummy
author = Vasudev Kamath
author-email = kamathvasudev@gmail.com
summary = Dummy module for testing purpose
version = 0.1
license = MIT
description-file =
  README.rst
requires-python = >= 2.7
[files]
packages =
  dummy
[entry_points] =
myapp.api.rest =
  rest = dummy:expose_rest_func
The special thing in above file is entry_points section, which defines function to be hooked into entry_point. In our case entry_point myapp.api.rest is used by our Flask application to interact with modules which expose them. The function which will be got accessing the entry_point is expose_rest_func which gives the function to be exposed its arg types and return types as a list. If we are looking at only supporting python3 it was sufficient to know function name only and use function annotations in function definition. Since I want to support both python2 and python3 this is out of question. Now, just run the following command in virtualenv to get the module installed.
PBR_VERSION=0.1 python setup.py sdist
pip install dist/dummy_module-0.1.tar.gz
Now if you want to see if the module is exposing entry_point or not just use entry_point_inspector tool after installing you will get a command called epi if you run it as follows you should note the dummy_module in its output
epi group list
+-----------------------------+
  Name                         
+-----------------------------+
  cliff.formatter.completion   
  cliff.formatter.list         
  cliff.formatter.show         
  console_scripts              
  distutils.commands           
  distutils.setup_keywords     
  egg_info.writers             
  epi.commands                 
  flake8.extension             
  setuptools.file_finders      
  setuptools.installation      
  myapp.api.rest               
  stevedore.example.formatter  
  stevedore.test.extension     
  wsme.protocols               
+-----------------------------+
So our entry_point is exposed now, we need to access it in our Flask application and expose the function using WSME. It is done by below code.
from wsmeext.flask import signature
import flask
import pkg_resources
def main():
   app = flask.Flask(__name__)
   app.config['DEBUG'] = True
   for entrypoint in pkg_resources.iter_entry_points('myapp.api.rest'):
       # Ugly but fix is only supporting python3
       func_signature = entrypoint.load()()
       app.route('/' + func_signature[0].__name__, methods=['POST'])(
           signature(func_signature[-1],
               *func_signature[1:-1])(func_signature[0]))
   app.run()
if __name__ == '__main__':
    main()
entry_point myapp.api.rest are iterated using the pkg_resources package provided by setuptools, when I load the entry_point I get back the function to be used which is called in same place to get function signature. Then I'm calling Flask and WSME decorator functions (yeah instead of decorating I'm using them directly over function to be exposed). The code looks bit ugly at the place where I'm accessing list using slices but I can't help it due to limitation of python2 with python3 there is new packing and unpacking stuff which makes code look bit more cooler see below.
from wsmeext.flask import signature
import flask
import pkg_resources
def main():
    app = flask.Flask(__name__)
    app.config['DEBUG'] = True
    for entrypoint in pkg_resources.iter_entry_points('silpa.api.rest'):
        func, *args, rettype = entrypoint.load()()
        app.route('/' + func.__name__, methods=['POST'])(
        signature(rettype, *args)(func_signature[0]))
    app.run()
if __name__ == '__main__':
    main()
You can access the service at http://localhost:5000/add depending on Accept header of HTTP you will get either XML or JSON response. If you access it from browser you will get XML response.
Usecase Now if you are wondering what is the reason behind this experience, this is for SILPA Project. I'm trying to implement REST service for all Indic language computing module. Since all these module are independent of SILPA which is a Flask web app I had to find a way to achieve this, and this is what I came up with.
Conclusion I'm not sure if there is any other approaches to achieve this, if there I would love to hear about them. You can write your comments and suggestion over email

Craig Small: A python utf gotcha

This one had me stumped for a while:
# -*- coding: utf-7 -*-
import datetime
from sqlalchemy import ForeignKey, Column
from sqlalchemy.types import Integer, Unicode, Boolean, DateTime
 
default_due_date = datetime.datetime.now() + datetime.timedelta(days=30)
Syntax error found on last line. Hmm, bring up a python interpreter and type the last line in with the imports. Works fine. It s the first line that is the problem, I typoed it and made it utf-7 not utf-8. I suppose it means that it is case-insenstive. Still, it wasn t too clear to me at least, what was going on.

6 June 2014

Gunnar Wolf: What defines an identity?

I must echo John Sullivan's post: GPG keysigning and government identification. John states some very important reasons for people everywhere to verify the identities of those parties they sign GPG keys with in a meaningful way, and that means, not just trusting government-issued IDs. As he says, It's not the Web of Amateur ID Checking. And I'll take the opportunity to expand, based on what some of us saw in Debian, on what this means. I know most people (even most people involved in Free Software development not everybody needs to join a globally-distributed, thousand-people-strong project such as Debian) are not that much into GPG, trust keyrings, or understand the value of a strong set of cross-signatures. I know many people have never been part of a key-signing party. I have been to several. And it was a very interesting experience. Fun, at the beginning at least, but quite tiring at the end. I was part of what could very well constitute the largest KSP ever in DebConf5 (Finland, 2005). Quite awe-inspiring We were over 200 people, all lined up with a printed list on one hand, our passport (or ID card for EU citizens) in the other. Actwally, we stood face to face, in a ribbon-like ring. And, after the basic explanation was given, it was time to check ID documents. And so it began. The rationale of this ring is that every person who signed up for the KSP would verify each of the others' identities. Were anything fishy to happen, somebody would surely raise a voice of alert. Of course, the interaction between every two people had to be quick More like a game than like a real check. "Hi, I'm #142 on the list. I checked, my ID is OK and my fingerprint is OK." "OK, I'm #35, I also printed the document and checked both my ID and my fingerprint are OK." The passport changes hands, the person in front of me takes the unique opportunity to look at a Mexican passport while I look at a Somewhere-y one. And all is fine and dandy. The first interactions do include some chatter while we grab up speed, so maybe a minute is spent Later on, we all get a bit tired, and things speed up a bit. But anyway, we were close to 200 people That means we surely spent over 120 minutes (2 full hours) checking ID documents. Of course, not all of the time under ideal lighting conditions. After two hours, nobody was checking anything anymore. But yes, as a group where we trust each other more than most social groups I have ever met, we did trust on others raising the alarm were anything fishy to happen. And we all finished happy and got home with a bucketload of signatures on. Yay! One year later, DebConf happened in Mexico. My friend Martin Krafft tested the system, perhaps cheerful and playful in his intent but the flaw in key signing parties such as the one I described he unveiled was huge: People join the KSP just because it's a social ritual, without putting any thought or judgement in it. And, by doing so, we ended up dilluting instead of strengthening our web of trust. Martin identified himself using an official-looking ID. According to his recount of the facts, he did start presenting a German ID and later switched to this other document. We could say it was a real ID from a fake country, or that it was a fake ID. It is up to each person to judge. But anyway, Martin brought his Transnational Republic ID document, and many tens of people agreed to sign his key based on it Or rather, based on it plus his outgoing, friendly personality. I did, at least, know perfectly well who he was, after knowing him for three years already. Many among us also did. Until he reached a very dilligent person, Manoj, that got disgusted by this experiment and loudly denounced it. Right, Manoj is known to have strong views, and using fake IDs is (or, at least, was) outside his definition of fair play. Some time after DebConf, a huge thread erupted questioning Martin's actions, as well as questioning what do we trust when we sign an identity document (a GPG key). So... We continued having traditional key signing parties for a couple of years, although more carefully and with more buzz regarding these issues. Until we finally decided to switch the protocol to a better one: One that ensures we do get some more talk and inter-personal recognition. We don't need everybody to cross-sign with everyone else A better trust comes from people chatting with each other and being able to actually pin-point who a person is, what do they do. And yes, at KSPs most people still require ID documents in order to cross-sign. Now... What do I think about this? First of all, if we have not ever talked for at least enough time for me to recognize you, don't be surprised: I won't sign your key or request you to sign mine (and note, I have quite a bad memory when it comes to faces and names). If it's the first conference (or social ocassion) we come together, I will most likely not look for key exchanges either. My personal way of verifying identities is by knowing the other person. So, no, I won't trust a government-issued ID. I know I will be signing some people based on something other than their name, but hey I know many people already who live pseudonymously, and if they choose for whatever reason to forgo their original name, their original name should not mean anything to me either. I know them by their pseudonym, and based on that pseudonym I will sign their identities. But... *sigh*, this post turned out quite long, and I'm not yet getting anywhere ;-) But what this means in the end is: We must stop and think what do we mean when we exchange signatures. We are not validating a person's worth. We are not validating that a government believes who they claim to be. We are validating we trust them to be identified with the (name,mail,affiliation) they are presenting us. And yes, our signature is much more than just a social rite It is a binding document. I don't know if a GPG signature is legally binding anywhere (I'm tempted to believe it is, as most jurisdictions do accept digital signatures, and the procedure is mathematically sound and criptographically strong), but it does have a high value for our project, and for many other projects in the Free Software world. So, wrapping up, I will also invite (just like John did) you to read the E-mail self-defense guide, published by the FSF in honor of today's Reset The Net effort.

5 June 2014

Thorsten Glaser: Dear FSF, stop recommending Enigmail.

Dear FSF, stop recommending Enigmail, please. It is broken, simple as that. Even if you switch everything HTML-related off, it still defaults to the latin9 (ISO-8859-15) encoding instead of UTF-8, and possibly some other nasties. Worse, it s based upon obsolete Thunderbird/Icedove technology, which is dead since the release of Firefox 17 and will only degrate over time. Side note: I was asked recently how much entropy is used while generating a PGP key using GnuPG on Windows , after having done the same for OpenSSL on Debian (and possibly almost all other OSes). I had to try to find out which was the actual code (GnuPG 2 with libgcrypt, it turns out), and it was not pretty. (You are hereby adviced to create a 600-byte file $ GNUPGHOME:-~/.gnupg /random_seed from a good source before even attempting to use GnuPG 2 for the first time. OK, you can run gpg -k once, to create the GNUPGHOME directory from a skeleton.)

Johannes Schauer: botch updates

My last update about ongoing development of botch, the bootstrap/build ordering tool chain, was four months ago and about several incremental updates. This post will be of similar nature. The most interesting news is probably the additional data that bootstrap.debian.net now provides. This is listed in the next section. All subsequent sections then list the changes under the hood that made the additions to bootstrap.debian.net possible.
bootstrap.debian.net The bootstrap.debian.net service used to have botch as a git submodule but now runs botch from its Debian package. This at least proves that the botch Debian package is mature enough to do useful stuff with it. In addition to the bootstrapping results by architecture, bootstrap.debian.net now also hosts the following additional services: Further improvements concern how dependency cycles are now presented in the html overviews. While before, vertices in a cycle where separated by commas as if they were simple package lists, vertices are now connected by unicode arrows. Dashed arrows indicate build dependencies while solid arrows indicate builds-from relationships. For what it's worth, installation set vertices now contain their installation set in their title attribute.

Debian package Botch has long depended on features of an unreleased version of dose3 which in turn depended on an unrelease version of libcudf. Both projects have recently made new releases so that I was now able to drop the dose3 git submodule and rely on the host system's dose3 version instead. This also made it possible to create a Debian package of botch which currently sits at Debian mentors. Writing the package also finally made me create a usable install target in the Makefile as well as adding stubs for the manpages of the 44 applications that botch currently ships. The actual content of these manpages still has to be written. The only documentation botch currently ships in the botch-doc package is an offline version of the wiki on gitorious. The new page ExamplesGraphs even includes pictures.

Cross By default, botch analyzes the native bootstrapping phase. That is, assume that the initial set of Essential:yes and build-essential packages magically exists and find out how to bootstrap the rest from there through native compilation. But part of the bootstrapping problem is also to create the set of Essential:yes and build-essential packages from nothing via cross compilation. Botch is unable to analyze the cross phase because too many packages cannot satisfy their crossbuild dependencies due to multiarch conflicts. This problem is only about the dependency metadata and not about whether a given source package actually crosscompiles fine in practice. Helmut Grohne has done great work with rebootstrap which is regularly run by jenkins.debian.net. He convinced me that we need an overview of what packages are blocking the analysis of the cross case and that it was useful to have a crossbuild order even if that was a fake order just to have a rough overview of the current situation in Debian Sid. I wrote a couple of scripts which would run dose-builddebcheck on a repository, analyze which packages fail to satisfy their crossbuild dependencies and why, fix those cases by adjusting package metadata accordingly and repeat until all relevant source packages satisfy their crossbuild dependencies. The result of this can then be used to identify the packages that need to be modified as well as to generate a crossbuild order. The fixes to the metadata are done in an automatic fashion and do not necessarily reflect the real fix that would solve the problem. Nevertheless, I ended up agreeing that it is better to have a slightly wrong overview than no overview at all.

Minimizing the dependency graph size Installation sets in the dependency graph are calculated independent from each other. If two binary packages provide A, then dependencies on A in different installation sets might choose different binary packages as providers of A. The same holds for disjunctive dependencies. If a package depends on A C and another package depends on C A then there is no coordination to choose C so to minimize the overall amount of vertices in the graph. I implemented two methods to minimize the impact of cases where the dependency solver has multiple options to satisfy a dependency through Provides and dependency disjunctions. The first method is inspired by Helmut Grohne. An algorithm goes through all disjunctive binary dependencies and removes all virtual packages, leaving only real packages. Of the remaining real packages, the first one is selected. For build dependencies, the algorithm drops all but the first package in every disjunction. This is also what sbuild does. Unfortunately this solution produces an unsatisfiable dependency situation in most cases. This is because oftentimes it is necessary to select the virtual disjunctive dependency because of a conflict relationship introduced by another package. The second method involves aspcud, a cudf solver which can optimize a solution by a criteria. This solution is based on an idea by Pietro Abate who implemented the basis for this idea back in 2012. In contrast to a usual cudf problem, binary packages now also depend on the source packages they build from. If we now ask aspcud to find an installation set for one of the base source packages (I chose src:build-essential) then it will return an installation set that includes source packages. As an optimization criteria the number of source packages in the installation set is minimized. This solution would be flawless if there were no conflicts between binary packages. Due to conflicts not all binary packages that must be coinstallable for this strategy to work can be coinstalled. The quick and dirty solution is to remove all conflicts before passing the cudf universe to aspcud. But this also means that the solution does sometimes not work in practice.

Test cases Botch now finally has a test target in its Makefile. The test target tests two code paths of the native.sh script and the cross.sh script. Running these two scripts covers testing most parts of botch. Given that I did lots of refactoring in the past weeks, the test cases greatly helped to assure that I didnt break anything in the process. I also added autopkgtests to the Debian packaging which test the same things as the test target but naturally run the installed version of botch instead. The autopkgtests were a great help in weeding out some lasts bugs which made botch depend on being executed from its source directory.

Python 3 Reading the suggestions in the Debian python policy I evaluated the possibility to use Python 3 for the Python scripts in botch. While I was at it I added transparent decompression for gzip, bz2 and xz based on the file magic, replaced python-apt with python-debian because of bug#748922 and added argparse argument parsing to all scripts. Unfortunately I had to find out that Python 3 support does not yet seem to be possible for botch for the following reasons:
  • no soap module for Python 3 in Debian (needed for bts access)
  • hash randomization is turned on by default in Python 3 and therefore the graph output of networkx is not deterministic anymore (bug#749710)
Thus I settled for changing the code such that it would be compatible with Python 2 as well as with Python 3. Because of the changed string handling and sys.stdout properties in Python 3 this proved to be tricky. On the other hand this showed me bugs in my code where I was wrongly relying on deterministic dictionary key traversal.

John Sullivan: GPG keysigning and government identification

Please stop recommending that checking government-issued ID is a good way to verify someone's identity before signing their GPG key. Have you been a US bartender before? Or held any other position where you've had to verify an ID? It's not an easy thing to do. People in those positions have books of valid IDs from different states. They have lights that show the security marks. They still get it wrong regularly. A very amateur fake ID, or borrowed real ID, will fool just about everyone in any informal context. What's even worse is that people have a habit of happily looking at passports from other countries than their own, and nodding knowingly. It's fun, but be honest, you have no idea what you're doing. How about just signing keys with people you would actually say you know well enough to trust? It's not the Web of Amateur ID Checking. ID checking is at best ineffective against the threats it's supposed to address, and is probably actually damaging to the Web of Trust because of the false sense of security. No idea what I'm talking about? Learn to encrypt your email by reading the FSF's new Email Self-Defense Guide, published in honor of today's Reset The Net effort.
John Sullivan: GPG keysigning and government identification

Please stop recommending that checking government-issued ID is a good way to verify someone's identity before signing their GPG key. Have you been a US bartender before? Or held any other position where you've had to verify an ID? It's not an easy thing to do. People in those positions have books of valid IDs from different states. They have lights that show the security marks. They still get it wrong regularly. A very amateur fake ID, or borrowed real ID, will fool just about everyone in any informal context. What's even worse is that people have a habit of happily looking at passports from other countries than their own, and nodding knowingly. It's fun, but be honest, you have no idea what you're doing. How about just signing keys with people you would actually say you know well enough to trust? It's not the Web of Amateur ID Checking. ID checking is at best ineffective against the threats it's supposed to address, and is probably actually damaging to the Web of Trust because of the false sense of security. No idea what I'm talking about? Learn to encrypt your email by reading the FSF's new Email Self-Defense Guide, published in honor of today's Reset The Net effort.

4 June 2014

Daniel Pocock: Trialing the xTuple/PostBooks next generation web UI

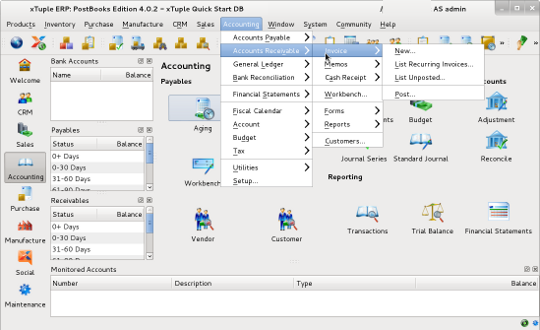
For some time I've been using PostBooks to keep track of finances. The traditional PostBooks system has a powerful Qt GUI. The xTuple team have been hard at work creating a shiny new web-based user interface. The traditional UI has no dedicated server - all users communicate directly with the PostgreSQL database where stored procedures and triggers ensure the correct logic is applied. The new model provides an xTuple application server that can handle requests from web users and potentially other third-party apps too. Who is it for? Some people may feel that the web UI is intended to appeal to mobile users. While it is useful for mobile and tablet devices, this is not strictly the aim, John has discussed this in a blog. One benefit of the web UI is that accountants and book-keepers do not need to have a copy of every exact PostBooks version that every client is using. Given that many people only need their accountant to look at their books for just a few hours at the end of each year, the ease of access with a web UI will make a big difference. Installing it quickly The xTuple Git repository provides a script to install the whole server quickly. Initially it just supported a single Ubuntu release, I just contributed some tweaks to generalize it for Debian wheezy and potentially other releases. It doesn't appear too difficult to generalize it further for Fedora or RHEL users. To get going, I recommend trying it in a fresh virtual machine, either in a server environment or desktop VirtualBox solution. The installation script will install various packages on the machine and mess about with the PostgreSQL setup so you will not want to run the automated setup script on any machine where you have existing databases. Once the virtual machine is setup, make sure sudo is installed and configured:
# apt-get install sudo
# visudo
and then run the install as your normal user:
git clone --recursive git://github.com/xtuple/xtuple.git
cd xtuple
git remote add XTUPLE git://github.com/xtuple/xtuple.git
git fetch XTUPLE
git checkout git describe --abbrev=0
chmod a+x scripts/install_xtuple.sh
scripts/install_xtuple.sh
If all goes well, 5-10 minutes later it is ready to run:
cd node-datasource
node main.js
The port numbers will appear on the screen and you can connect with a web browser. Trying it out Despite my comments above to the effect that this is not primarily aimed at mobile, the first and second device I tested with were both mobile devices, Samsung Galaxy S3 and a Samsung Galaxy Note 3. I feel the Note is far better for this type of application, primarily due to screen size and the fact that most of the forms in the application have fields that launch popup menus. It appears to work in both Chrome and Firefox on these devices. One handy feature is that the mobile device can dial numbers directly from the CRM address book, this is facilitated with the tel URI. My impression is that this is still a product that is in the final stages of development, although some people will be able to use it almost immediately. One significant thing to note is that the database schema is very stable due to the long history of the traditional xTuple/PostBooks products.

Russell Coker: Android Device Service Life

In recent years Android devices have been the most expensive things I ve purchased apart from airline tickets and other travel/holiday expenses. As they are expensive I d like to use them for as long as possible to get the most value for money. Also as I give my devices to relatives when they no longer work for me I d like to avoid having relatives hassling me about their phone not working as desired. So I ve been thinking about the features that I need to make it possible to use a phone or tablet for a long time. RAM The way Android works is that when an application in the foreground requests more memory background applications may be closed to free some memory. Android doesn t use swap by default, there is some documentation on how to enable it (and it s not difficult to figure out for anyone who has used Linux before) but generally it s not done. If you run a larger application the chances of apps closing in the background (causing delays when you switch back to them and possibly a loss of context if the app is buggy and doesn t preserve all state) are increased. As a general trend apps tend to get bigger to provide more features and also because users who own newer bigger devices don t complain as much about memory use. Also to make things worse new versions of Android tend to use more RAM. So a phone that runs well can suddenly start performing badly when you upgrade to a new version of Android (which incidentally usually can t be reversed) and upgrade to new versions of apps (which can t be reversed through the Google Play Store). The Sony Ericsson Xperia X10 was a very nice phone when it was released, it ran Android 2.1 very quickly. When I upgraded the Xperia X10s that my wife and I used to Android 2.3 (which was necessary to have the phone run as a Wifi access point) performance dropped considerably. The Android upgrade combined with newer larger apps means that those phones are barely usable now. 384M of RAM was plenty in early 2011 when I first used the Xperia X10 but it s not nearly enough now. Recently 2G of RAM has been the minimum for a mid-range or high-end phone. It seems difficult to imagine a new Android feature as compelling as the addition of Wifi access point support in Android 2.3 that would drive an upgrade to a future memory hogging version of the OS. It also seems difficult to imagine Android apps needing enough memory to destroy the performance of a phone with 2G of RAM. But then I couldn t imagine the 384M in an Xperia X10 becoming inadequate or the 512M in a Samsung Galaxy S becoming barely usable either. Storage Until fairly recently storage in an Android device was divided into USB attached storage (a VFAT filesystem that could be directly mounted on a PC) and a Linux filesystem that was used for all internal operations of the phone. On such devices it typically wasn t possible to change partition sizes without a lot more skill than most users possess and most of the storage space was reserved for USB attachment. If you only had a few Android apps and lots of photos, movies, etc then this worked well. But if you wanted to install larger Android apps then you would have big problems. Even with Android 4.x devices (which all seem to have a single filesystem) you can easily run out of space. Modern games often take several hundred megs of storage. Games that take 500M+ for the Android package install (which also requires the same amount of temporary space for installation and upgrade) are common. Sometimes games download data files after they have been installed for a total size approaching 2G (such as The Sims Freeplay). When I bought a Nexus 4 for my wife I got the version with 8G of storage because paying an extra $50 for the 16G version seemed unreasonable. 8G was fine for my wife, but when she got a new phone I gave the Nexus 4 to a relative who wanted to play The Sims and other big games. That relative isn t so happy about having a limited number of games on their phone and I have to fix it when storage space runs out and things start aborting (when storage runs out the Google App Store program aborts and uses lots of space for temporary files). I recently bought a tablet with 32G of storage and filled 16G on the first day (tablets are good for watching
TV and TV shows are big). Fortunately the tablet in question has a SD socket so that when space becomes a problem in a year or two I can buy an SD card and keep using it. An unfortunate recent decision by Google was to prevent apps from being run from a SD card. So even if you have a device with a SD socket you still need to have enough internal storage for all apps and their private data. At 500M+ for a modern game that means a device with 8G of storage (which includes space for the OS) will be lucky to get 8 games installed. If you want to use a phone to it s full capacity (playing various media files, games, etc) then it seems that the minimum storage capacity would be 8G of internal storage and a SD socket. For a device without an SD socket (such as the Nexus 5 with 16G or 32G of storage) your future use will be limited. 32G is probably enough for a phone given that you can recode movies to use less space (the FullHD screen on the Nexus 5 is nice but 720p movies will probably look good enough). But the larger screens of tablets demand better video quality so the Nexus tablets are probably a bad choice due to lack of storage space. Screen Size and Resolution I have previously written about the sizes of devices and how they may be used by people of various ages [1]. That should be of use for anyone who plans to use their old phone as an educational device for their children (which appears to be very common). But apart from that I can t think of any reason why size would suddenly make an old phone obsolete. Only young children will have their hands change size in any significant way. Resolution also shouldn t be a huge problem, the 480*854 screen on the Xperia X10 is fairly good for a 4 screen. While a higher resolution makes text more readable at a small size for most users the availability of a higher resolution screen isn t going to make their old phone obsolete. CPU The only Android devices I owned that appeared to develop CPU speed issues late in life were the Xperia X10 phones, and that might be more due to RAM limits and the OS upgrade. All the other devices were either obviously slow at purchase time or are still performing well now. CPU speed may make it difficult or impossible to play new games, but shouldn t affect other uses of a phone or tablet. Conclusion It seems to me that if you want to use an Android device for more than 2 years then storage capacity should be a major factor in choosing which device to purchase. It seems that lack of storage space is in many cases the main factor that makes older devices annoying or impossible to use.

2 June 2014

Francesca Ciceri: 100 bugs triaged: achievement unlocked

After two weeks working as OPW intern for Mozilla, it's time for a recap!
What exactly I've been doing in these two weeks? 100 bugs triaged: achievement unlocked! Yes, this is the thing I'm most proud of. I'm a bit cheating here, as strictly speaking, since the beginning of the internship I've triaged only 44 bugs.
But I've decided to count from the beginning of my activity on bugzilla, at the end of March, since I've started work on that as part of the small contribution required for applying to OPW.
Therefore, it's all OPW related :) Here's the grand total. Right now, I've decided to work on an average of 5 bugs a day: it's mostly triage and/or verification, which is quite fun.
It consists in trying to have a more complete and detailed bug report for the developers: asking the right questions to the reporter, ensuring that the bug is filed against the right product or component and all the information about platforms and version are correct. Or verifying that the bug isn't a duplicate, which involves doing some voodoo with Bugzilla quicksearch (I'm not so good with that yet, mostly because I'm not imaginative enough in the queries... but I'm getting better!) Sometimes triaging means reading lots of documentation (to be sure that something is a bug and not a feature) and checking meta-bugs and release notes to be able to pinpoint the time when something was introduced and the reasoning behind it.
That takes a lot of time, but it makes you discover some funny things, like the Mighty Bouncing Unicorn. And while I know it sounds a bit cruel, it's really good when you're verifying a fix and you find it's not totally ok, or that it triggered another bug.
I've been assured that feeling satisfied after that it's an essential part of the sadistic QA work. Writing FAQs for new triager This started as a personal project even before knowing I've been selected for OPW, and it's now part of my internship: I've been writing a first draft of FAQ for those who approach for the first time the Bug Triaging and Verifying work in Mozilla. It meant taking a whole lot of IRC logs and scan them for the most asked questions during bugdays, and you can find here my first draft. I'll send a RFC today about it on dev-quality mailing list and link it to the main Bugdays page. Lessons learned So, what I've learned in these two weeks? That I'm pretty good at figuring things alone, but I like to have feedback on what I'm working on.
That testing things is an art, and perfectionism is a big plus.
That there are such things as stupid questions, but you have to ask them nonetheless.
That people in the Mozilla community are quite friendly and not scary at all. Not even in video! :) Wishlist I've been thinking about this a lot, and I think I'd like to have They will probably become my next pet project.

Steve Kemp: Reflections on Lua-based email clients

Until recently I was very happy with my console mail client, Lumail, thinking I'd written it in a flexible manner, with lots of Lua-callable primitives. Now I'm beginning to suspect that I might have gone down the wrong path at some point. The user interface, at startup consists of a list of mailboxes. The intention being that you select a mailbox, and open it. That then takes you to a list of messages. (There is a cool and simple to use option to open the union of multiple mailboxes, which is something I use daily.) Now the list of mailboxes is sorted alphabetically, so the user interface looks something like this:
UI
Now the issue that triggered my rethink: Sure you think. It's just a list of strings. You could pass an array to a lua on_sort_maildirs function, and then use the returned array/table as teh display order. Simple. Simple until you realize the user might want to do more than operate solely on the list of strings. Perhaps they wish to put folders with unread messages at the top. At which point you need a "count_unread( maildir )" function. (Which does exist.) Anyway the realisation I had is that the CMaildir object, on the C++ side, isn't exposed to the Lua-side. So the (useful) member functions which should be exported/visible are not. Really what I'm trying to say is that I think I've implemented and exported useful Lua primitives, but actually many more parts of the implementation could be usefully exported - but are not, and that comes from the choice I made to expose "things" not "objects". If I'd exposed objects right from the start I'd have been in a better place. Oh well. I continued to toy with a basic GUI mail-client last week, but I've pretty much written that off as a useful way to spend my time. For the moment I'll leave email alone, I've done enough and despite niggles what I have is absolutely the best mail client for me. (It is a shame that Mutt is so heavyweight and hard to deal with, and that notmuch never really took off.)

1 June 2014

Russ Allbery: Spring haul post

Sorry about the lack of posting recently. Work has been rather problematic, and also very distracting, and on my time away from work I've been relaxing rather than writing. Didn't even get reviews written while on vacation. I am still hoping to catch up on reviews, however. In the meantime, I have been reading some, and buying more books. Here's a new haul list. Elizabeth Bear Steles of the Sky (sff)
Katherine Boo Behind the Beautiful Forevers (non-fiction)
John Chu The Water That Falls on You from Nowhere (sff)
Lewis Dartnell The Knowledge (non-fiction)
David Lochbaum, et al. Fukushima (non-fiction)
Ben Goldacre Bad Pharma (non-fiction)
Mira Grant Parasite (sff)
Thomas Olde Heuvelt The Ink Readers of Doi Saket (sff)
Mary Robinette Kowal The Lady Astronaut of Mars (sff)
Madeline Miller The Song of Achilles (historical)
Edmund S. Morgan American Slavery, American Freedom (non-fiction)
Richard Rhodes The Making of the Atomic Bomb (non-fiction)
Lee Smolin The Trouble with Physics (non-fiction)
Charles Stross Equoid (sff)
Charles Stross Neptune's Brood (sff) This is a bit of a grab-bag, including a variety of non-fiction that I had recommended to me by various people. I also picked up the remaining Hugo nominees for best novel that won't be in the voter packet, and the short fiction from Tor.com that was nominated and was available for free from Amazon for the Kindle. I read The Knowledge while I was on vacation, and it's in my large backlog of pending reviews.

30 May 2014

Jaldhar Vyas: OOH OOH Microagression!

Debian recently instituted a code of conduct which makes the astute observation that "a community in which people feel threatened is not a healthy community". So imagine my shock when I read Russell Cokers blog via Debian Planet, where commenting on a link from the intellectual powerhouse known as salon.com he said "The next logical step is to treat conservatism as a mental health problem." Being a conservative myself I immediately lost all my self-esteem and Dovecots SSL cert handling stopped working. What if I attend debconf and Coker uses his white privilege to sic Mental Health Services on me? I'm scared, so very scared and I don't know if I can continue not working on Debian Minix any longer. I demand that the Debian project, nay the world, should be OUTRAGED I'm talking spelling naughty words in hexadecimal levels of outrage and force this maniac to shut up before any more innocent flowers are brutalized by his "opinions."

Next.

Previous.
