No man s Sky (or as it s known in our house, "spaceship game") is a space
exploration/sandbox game that was originally released 10 years ago. Back then I
tried it on my brother s PS4 but I couldn t get into it. In 2022 it launched
for the Nintendo Switch1 and the game finally clicked for me.
I play it very casually. I mostly don t play at all, except sometimes when
there are time-limited expeditions running, which I find refreshing, and
usually have some exclusives as a reward for play.
One of the many things you can do in the game is collect star ships. I started
keeping a list of notable ones I ve found, and I ve decided to occasionally
blog about them.
The Horizon Vector NX is a small sporty ship that players on Nintendo Switch
could claim within the first month or so after it launched. The colour scheme
resembles the original neon switch controllers. Although the ship type occurs
naturally in the game in other configurations, I think differently-painted
wings are unique to this ship.
For most of the last 4 years, my copy of this ship was confined to the Switch,
until November 2024, when they added cross-save capability to the game. I was
then able to access the ship when playing on Linux (or Mac).
The game runs very well natively on Mac, flawlessly on Steam for Linux, but struggles on the origins switch. It s a marvel it runs there at all.
This post covers my friend Badri and my experiences in Brunei. Brunei officially Brunei Darussalam is a country in Southeast Asia, located on Borneo island. It is one of the few remaining absolute monarchies on Earth.
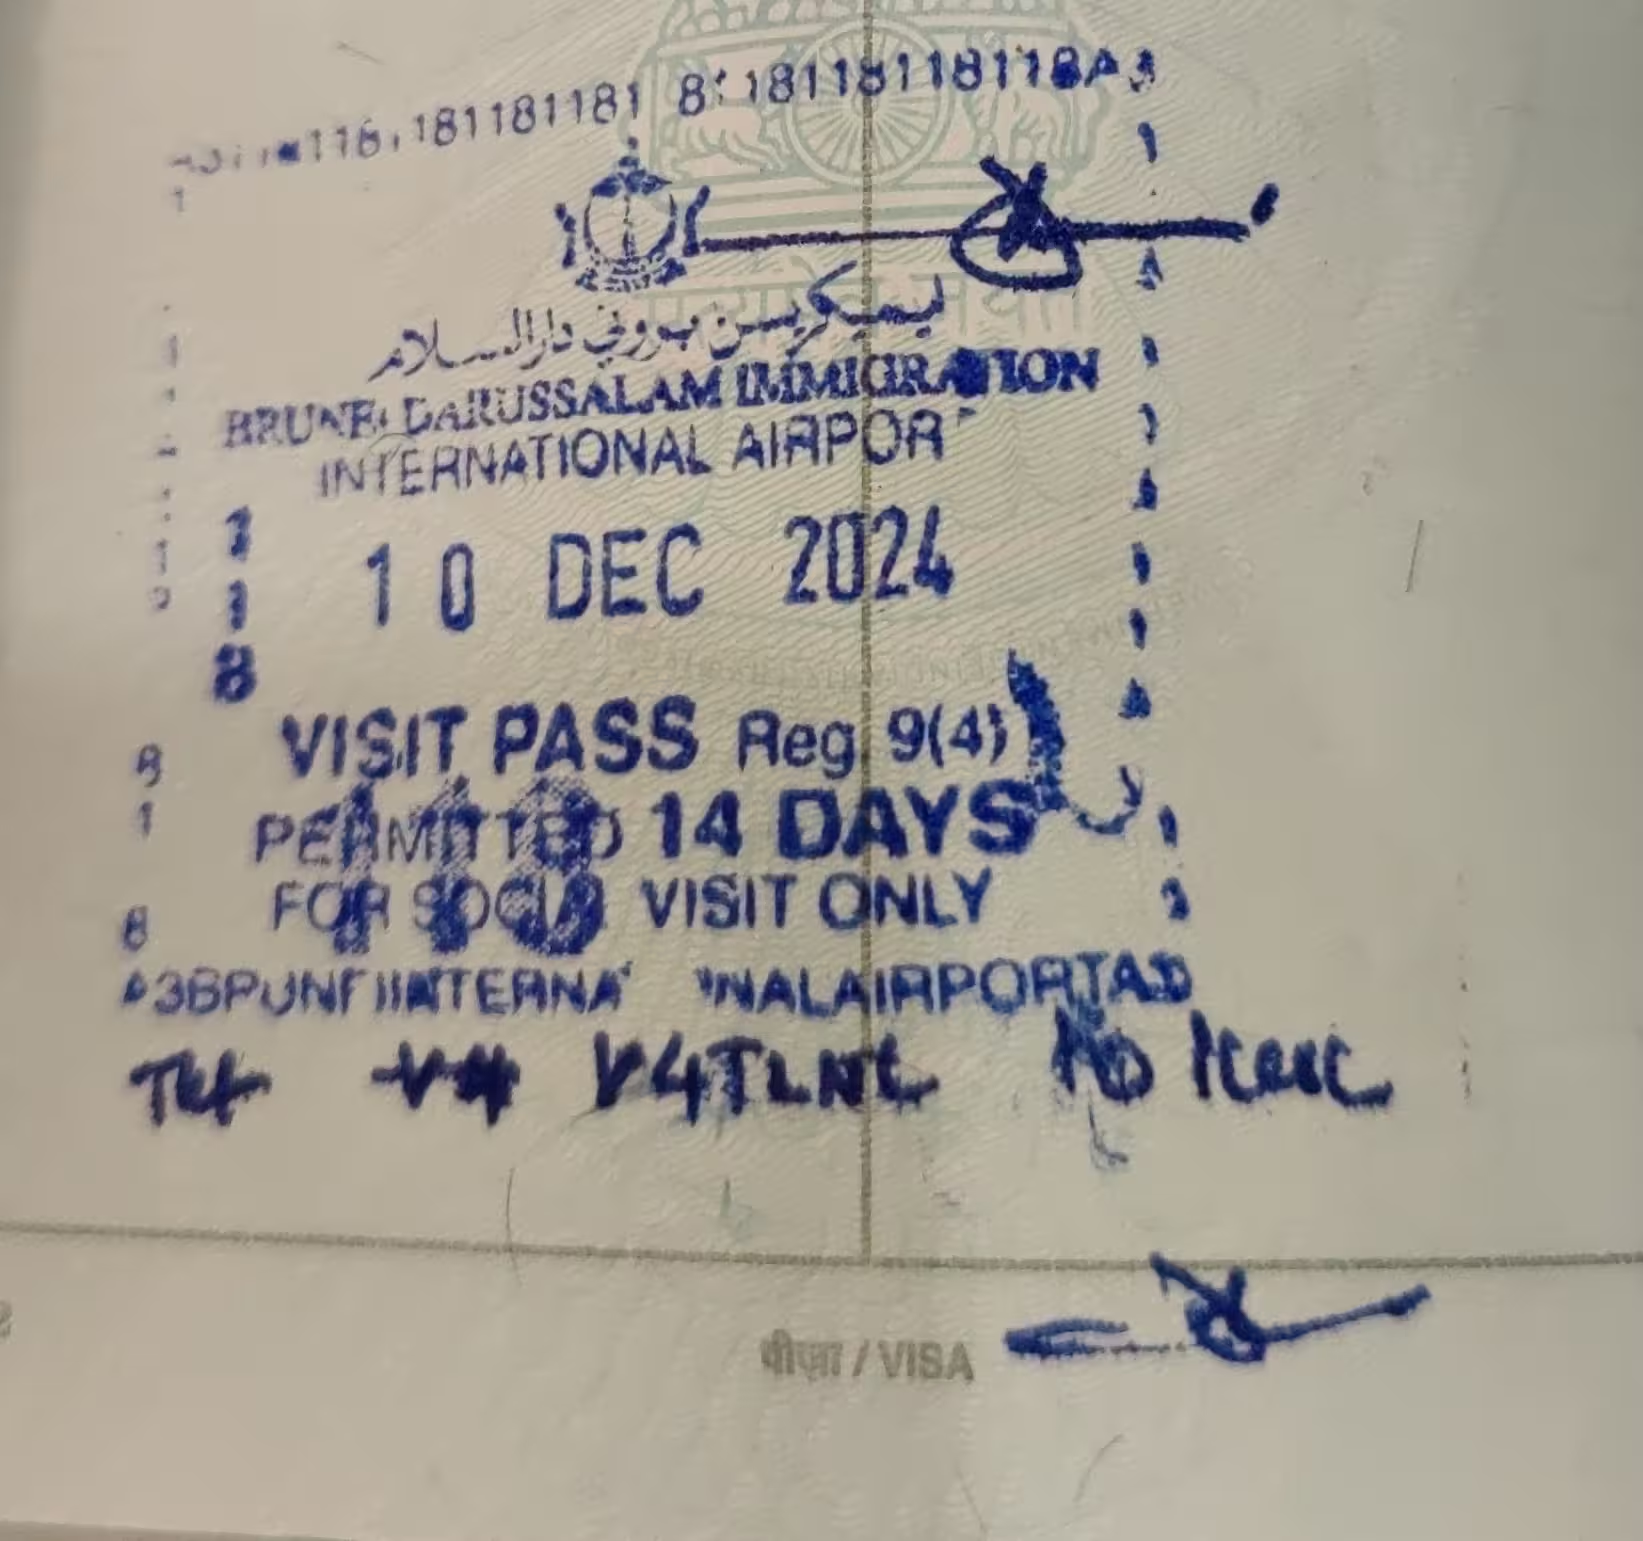
On the morning of the 10th of December 2024, Badri and I reached Brunei International Airport by taking a flight from Kuala Lumpur. Upon arrival at the airport, we had to go through the immigration, of course. However, I forgot to fill my arrival card, which I filled while I was in the queue for my immigration.
The immigration officer asked me how much cash I was carrying of each currency. After completing the formalities, the immigration officer stamped my passport and let me in. Take a look at Brunei s entry stamp in my passport.
Brunei entry stamp on my passport. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0.
We exchanged Singapore dollars to get some Brunei dollars at the airport. The Brunei dollar was pegged 1:1 with the Singapore dollar, meaning 1 Singapore dollar equals 1 Brunei dollar. The exchange rate we received at the airport was the same.
Our (pre-booked) accommodation was located near Gadong mall. So, we went to the information center at the airport to ask how to get there by public transport. However, the person at the information center told us that they didn t know the public transport routes and suggested we take a taxi instead.
We came out of the airport and came across an Indian with a mini bus. He offered to drop us at our accommodation for 10 Brunei dollars ( 630). As we were tired after a sleepless night, we didn t negotiate and took the offer. It felt a bit weird using the minibus as our private taxi.
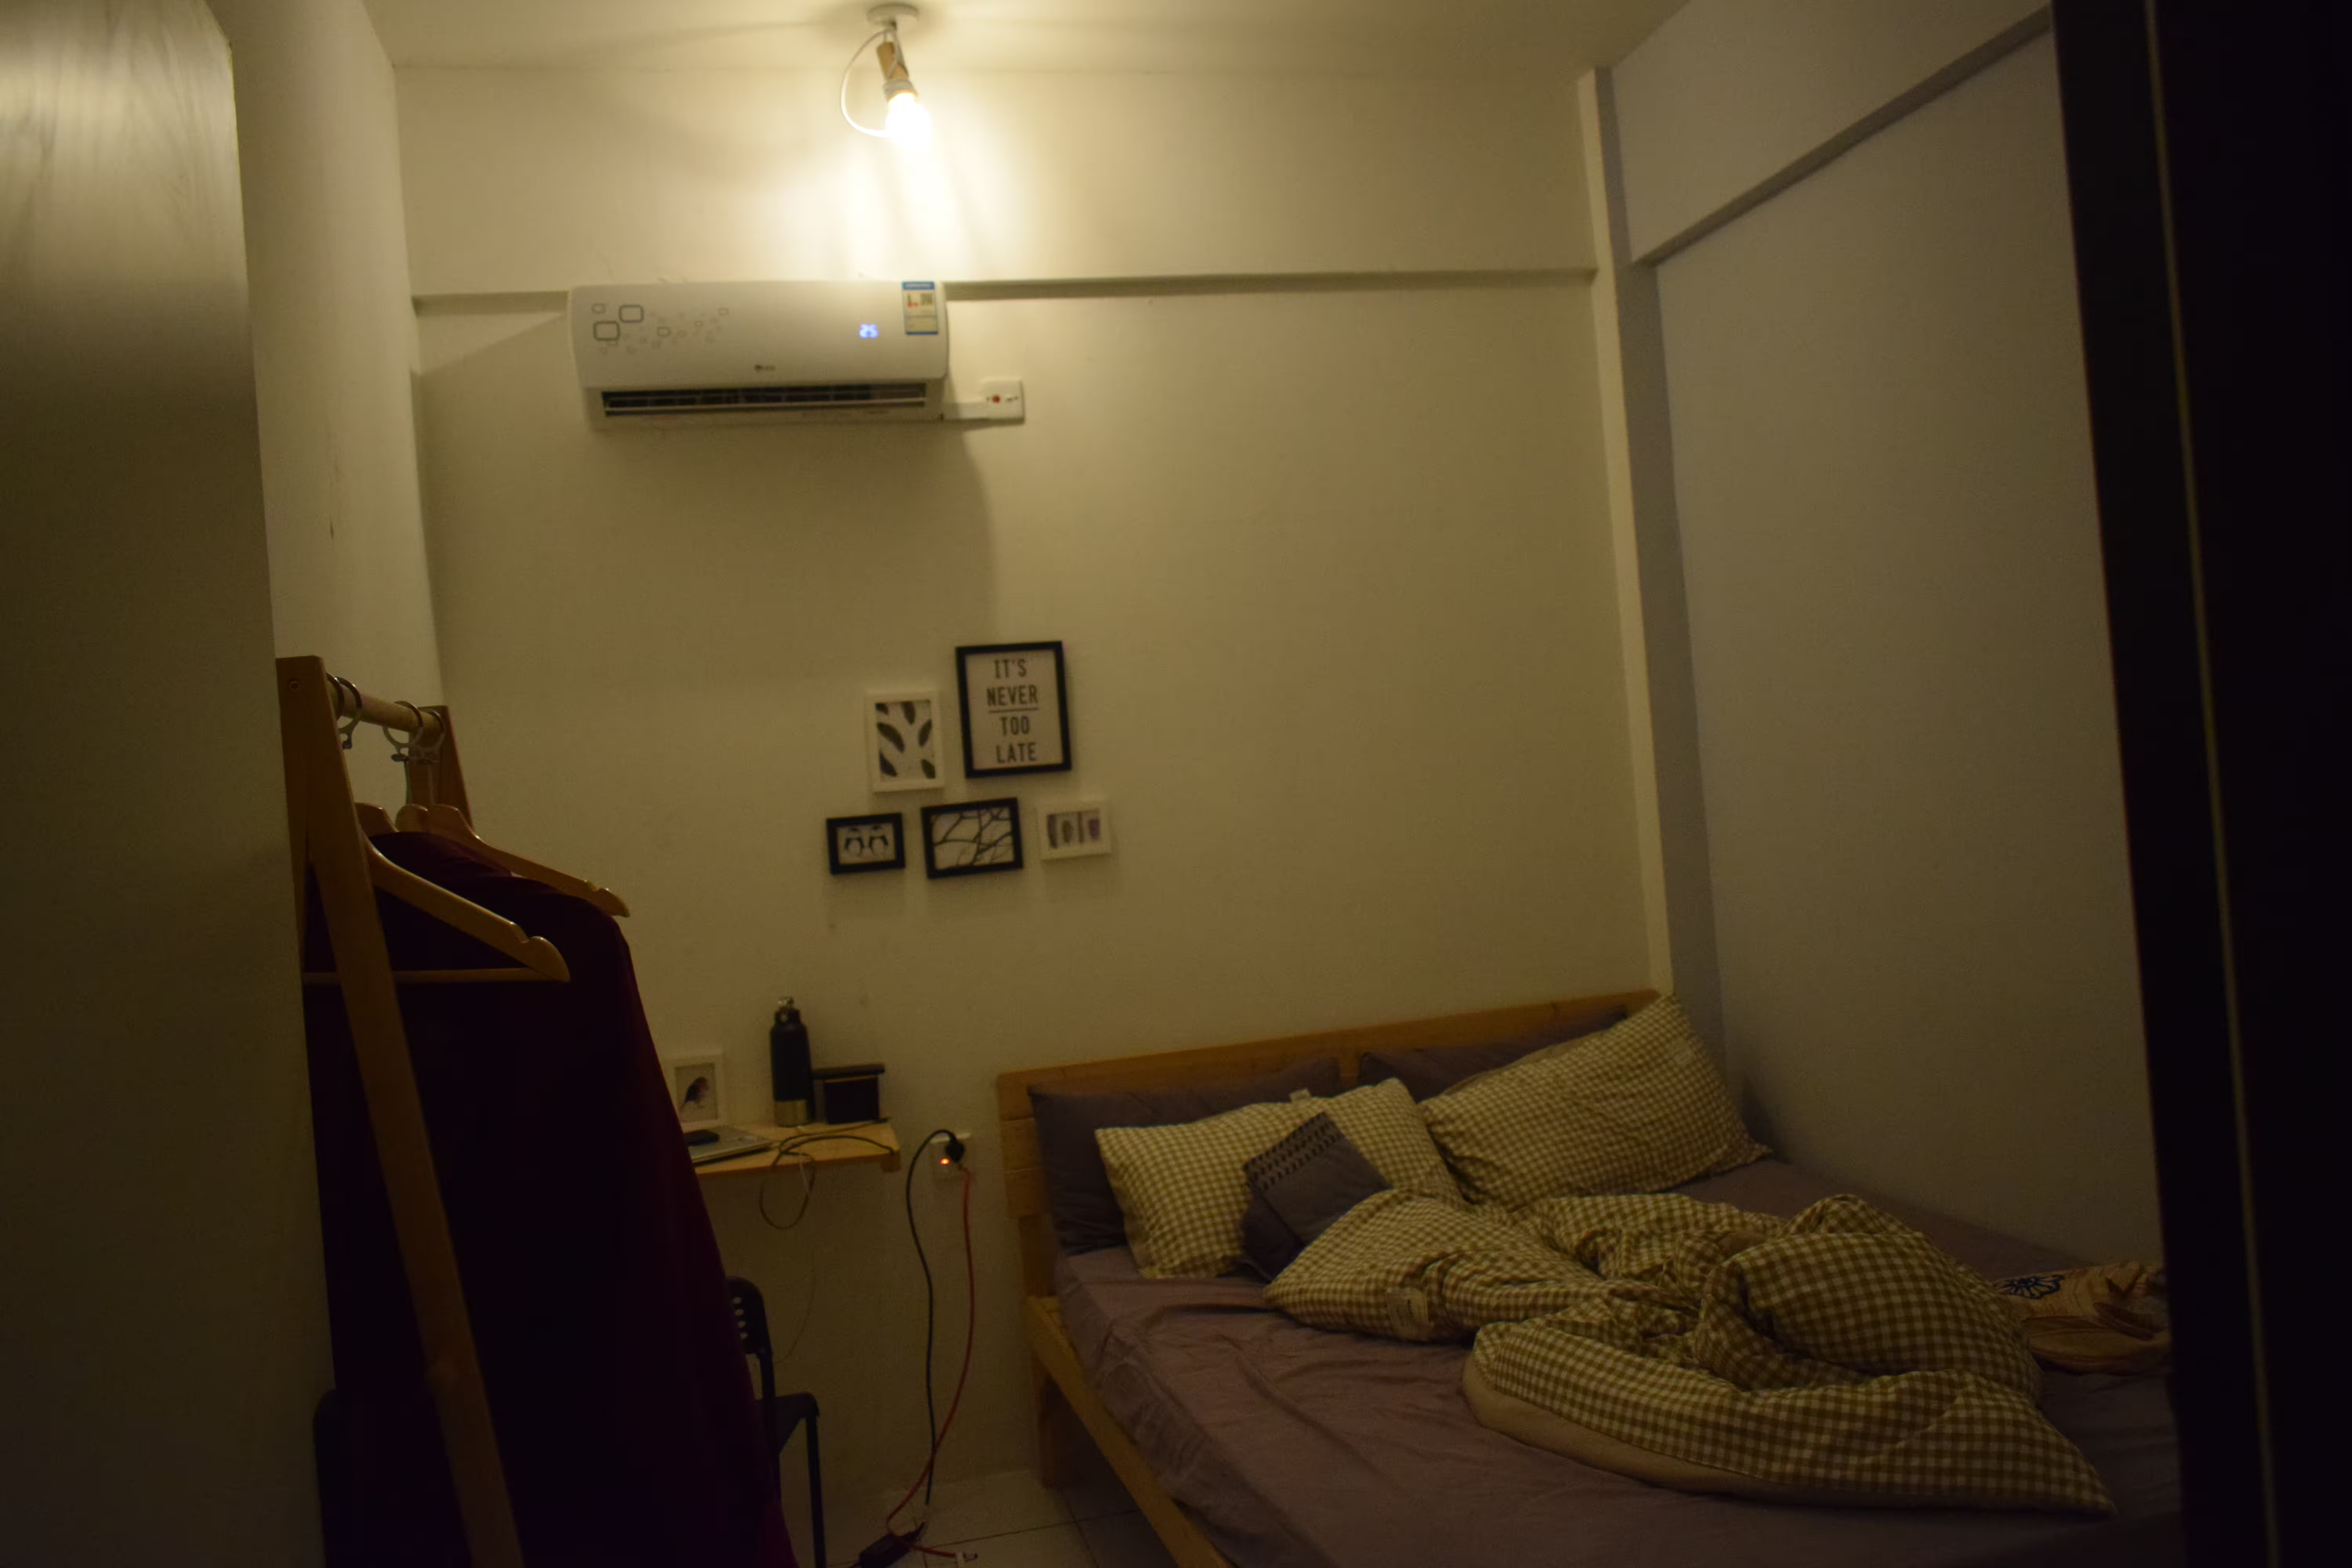
In around half-an-hour, we reach our accommodation. The place was more like a guest house than a hotel. In addition to the rooms, it had common space consisting of a hall, a kitchen and a balcony.
Our room in Brunei. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
Upon reaching the place, we paid for our room in cash, which was 66.70 Singapore dollars (4200 Indian rupees) for two nights. We reached before the check-in time, so we had to wait for our room to get ready before we entered.
The room had a double bed and also a place to hang clothes. We slept for a few hours before going out at night. We went into Gadong mall and had coffee at a caf named The Coffee Bean & Tea Leaf. The regular caffe latte I had here been 5.20 Brunei dollars. On another note, the snacks we got us from Kuala Lumpur covered us for the dinner.
The next day 11th of December 2024 we went to a nearby restaurant named Nadj for lunch. The owner was from Kerala. Here we ordered:
1 paneer pepper masala for 5 Brunei dollars (320 rupees)
1 Nasi goreng pattaya biasa for 4.50 Brunei dollars (290 rupees)
1 plain naan for 1.50 Brunei dollars (100 rupees)
1 butter naan for 1.80 Brunei dollars (115 rupees)
So, our lunch cost a total of 12.80 Brunei dollars (825 rupees). The naan was unusually thick, and didn t like the taste.
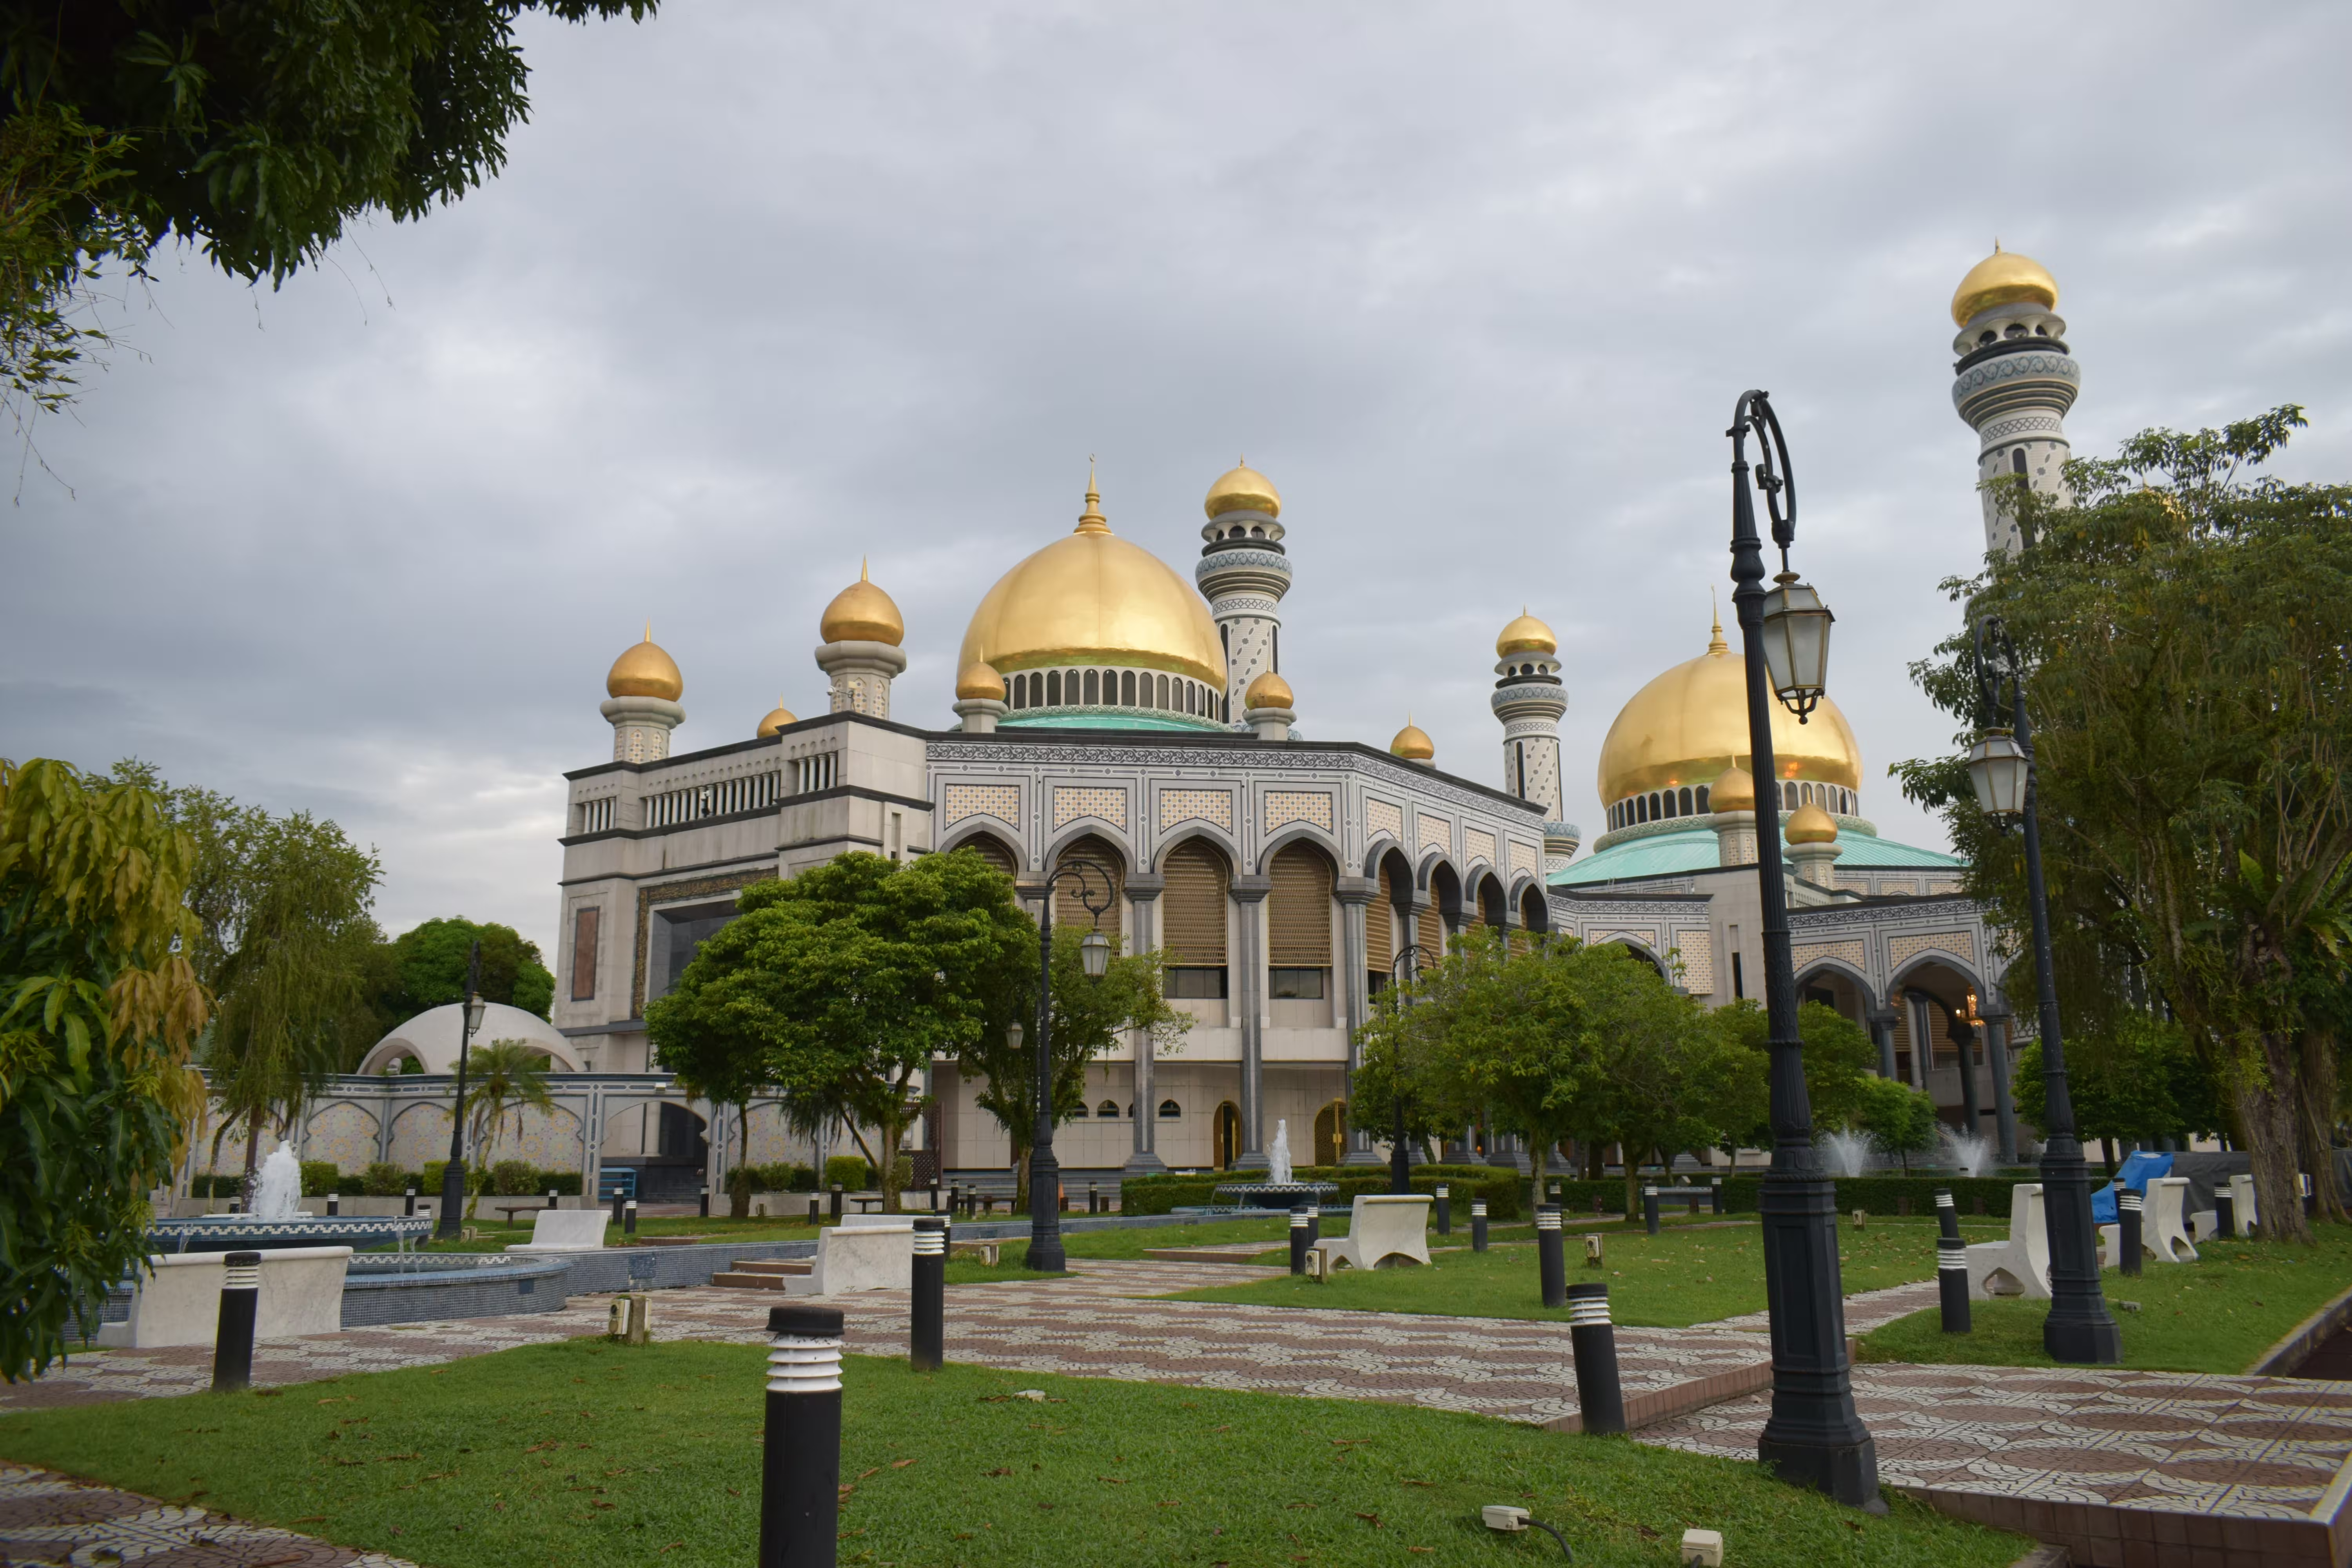
After the lunch, we planned to visit Brunei s famous Omar Ali Saifuddien Mosque. However, a minibus driver outside of Gadong Mall told us that the mosque would be closed in half-an-hour and suggested we visit the nearby Jame Asr Hassanil Bolkiah Mosque instead.
Jame Asr Hassanil Bolkiah Mosque. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
He dropped us there for 1 Brunei dollar per person. The person hailed from Uttar Pradesh and told us about bus routes in Hindi. Buses routes in Brunei were confusing, so the information he gave us was valuable.
It was evening, and we had an impression that the mosque and its premises were closed. However, soon enough, we stumbled across an open gate entering the mosque complex. We walked inside for some time, took pictures and exited. Walking in Bandar Seri Begawan wasn t pleasant, though. The pedestrian infrastructure wasn t good.
Then we walked back to our place and bought some souvenirs. For dinner and breakfast, we bought bread, fruits and eggs from local shops as we had a kitchen to cook for ourselves.
The guest house also had a washing machine (free of charge) which we wanted to use. However, they didn t have detergent. Therefore, we went outside to get some detergent. It was 8 o clock, and most of the shops were closed already. Others had had detergents in large sizes, the ones you would use if you lived there. We ended up getting a small packet at a supermarket.
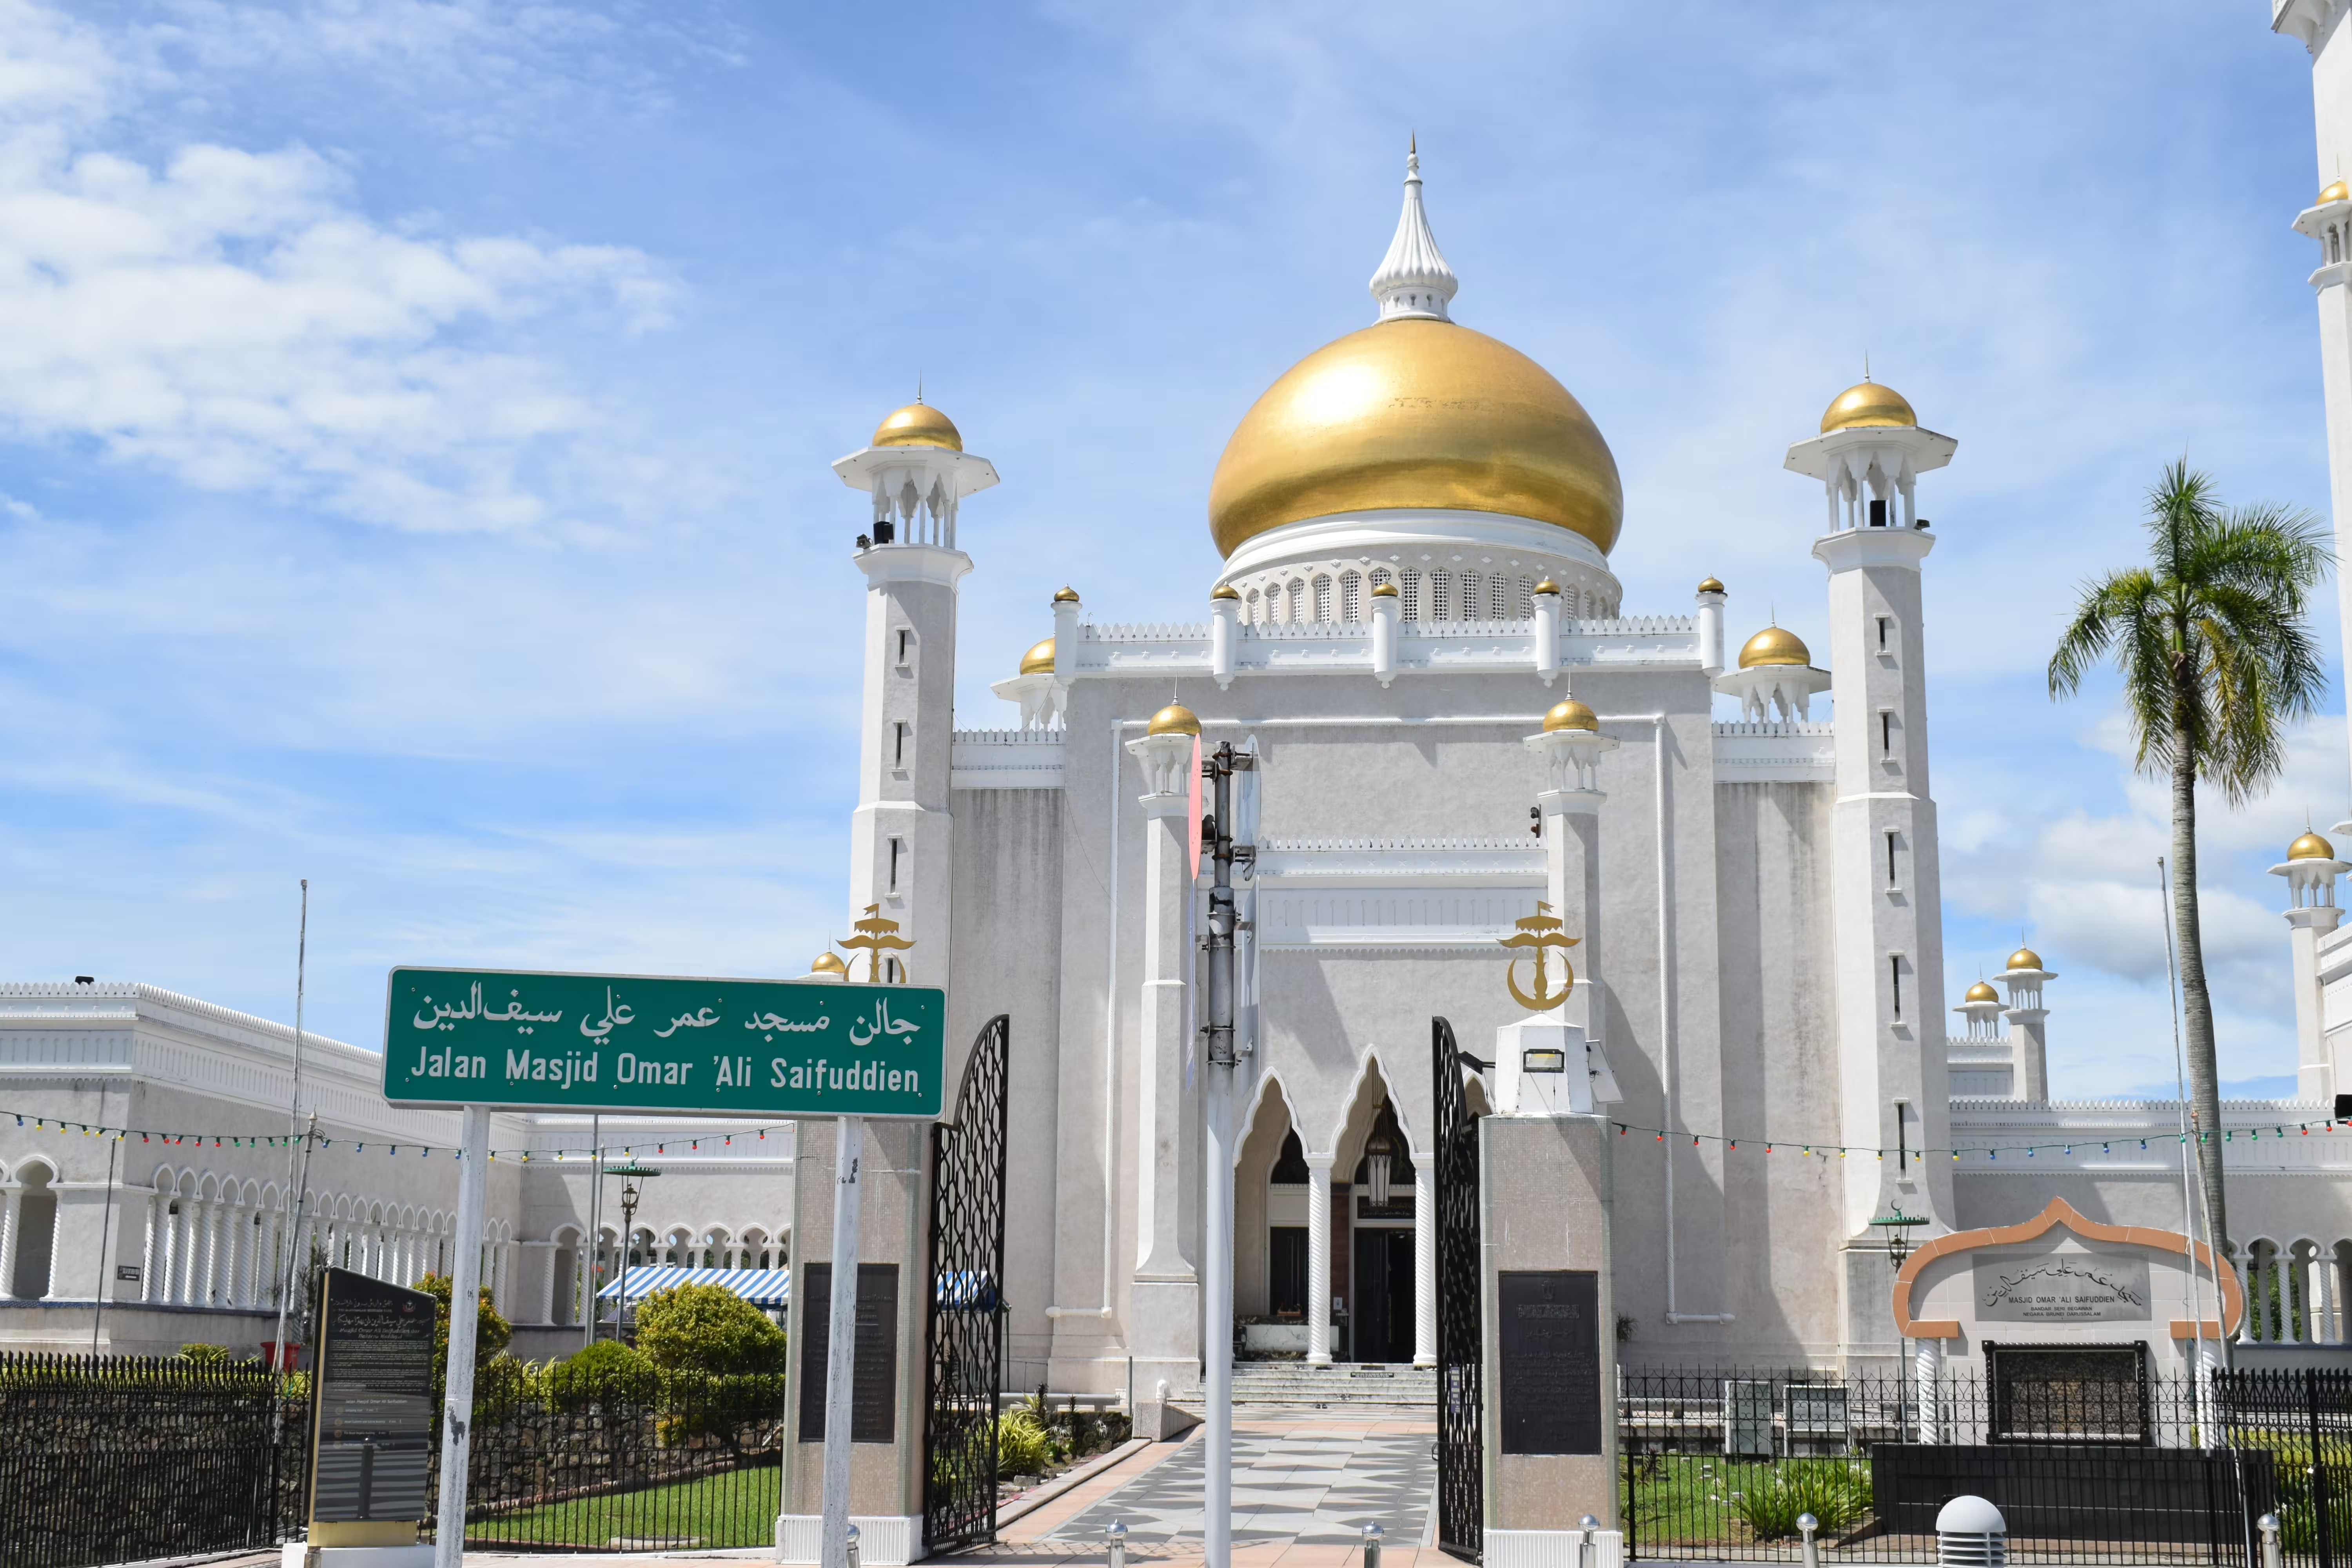
The next day 12th of December we had a flight to Ho Chi Minh City in Vietnam with a long layover in Kuala Lumpur. We had breakfast in the morning and took a bus to Omar Ali Saifuddien Mosque. The mosque was in prayer session, so it was closed for Muslims. Therefore, we just took pictures from the outside and took a bus for the airport.
Omar Ali Saifuddien Mosque. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
When the bus reached near the airport, the bus went straight rather than taking a left turn for the airport. Initially, I thought the bus would just take a turn and come back. However, the bus kept going away from the airport. Confused by this, I asked other passengers if the bus was going to the airport. The driver stopped the bus at Muara Town terminal 20 km from the airport. At this point, everyone alighted, except for us. The driver went to a nearby restaurant to have lunch.
I felt very uncomfortable stranded in a town which was 20 km from the airport. We had a lot of time, but I was still worried about missing our flight, as I didn t want to get stuck in Brunei. After waiting for 15 minutes, I went inside the restaurant and reminded the driver that we had a flight in a couple of hours and needed to go to the airport. He said he will leave soon.
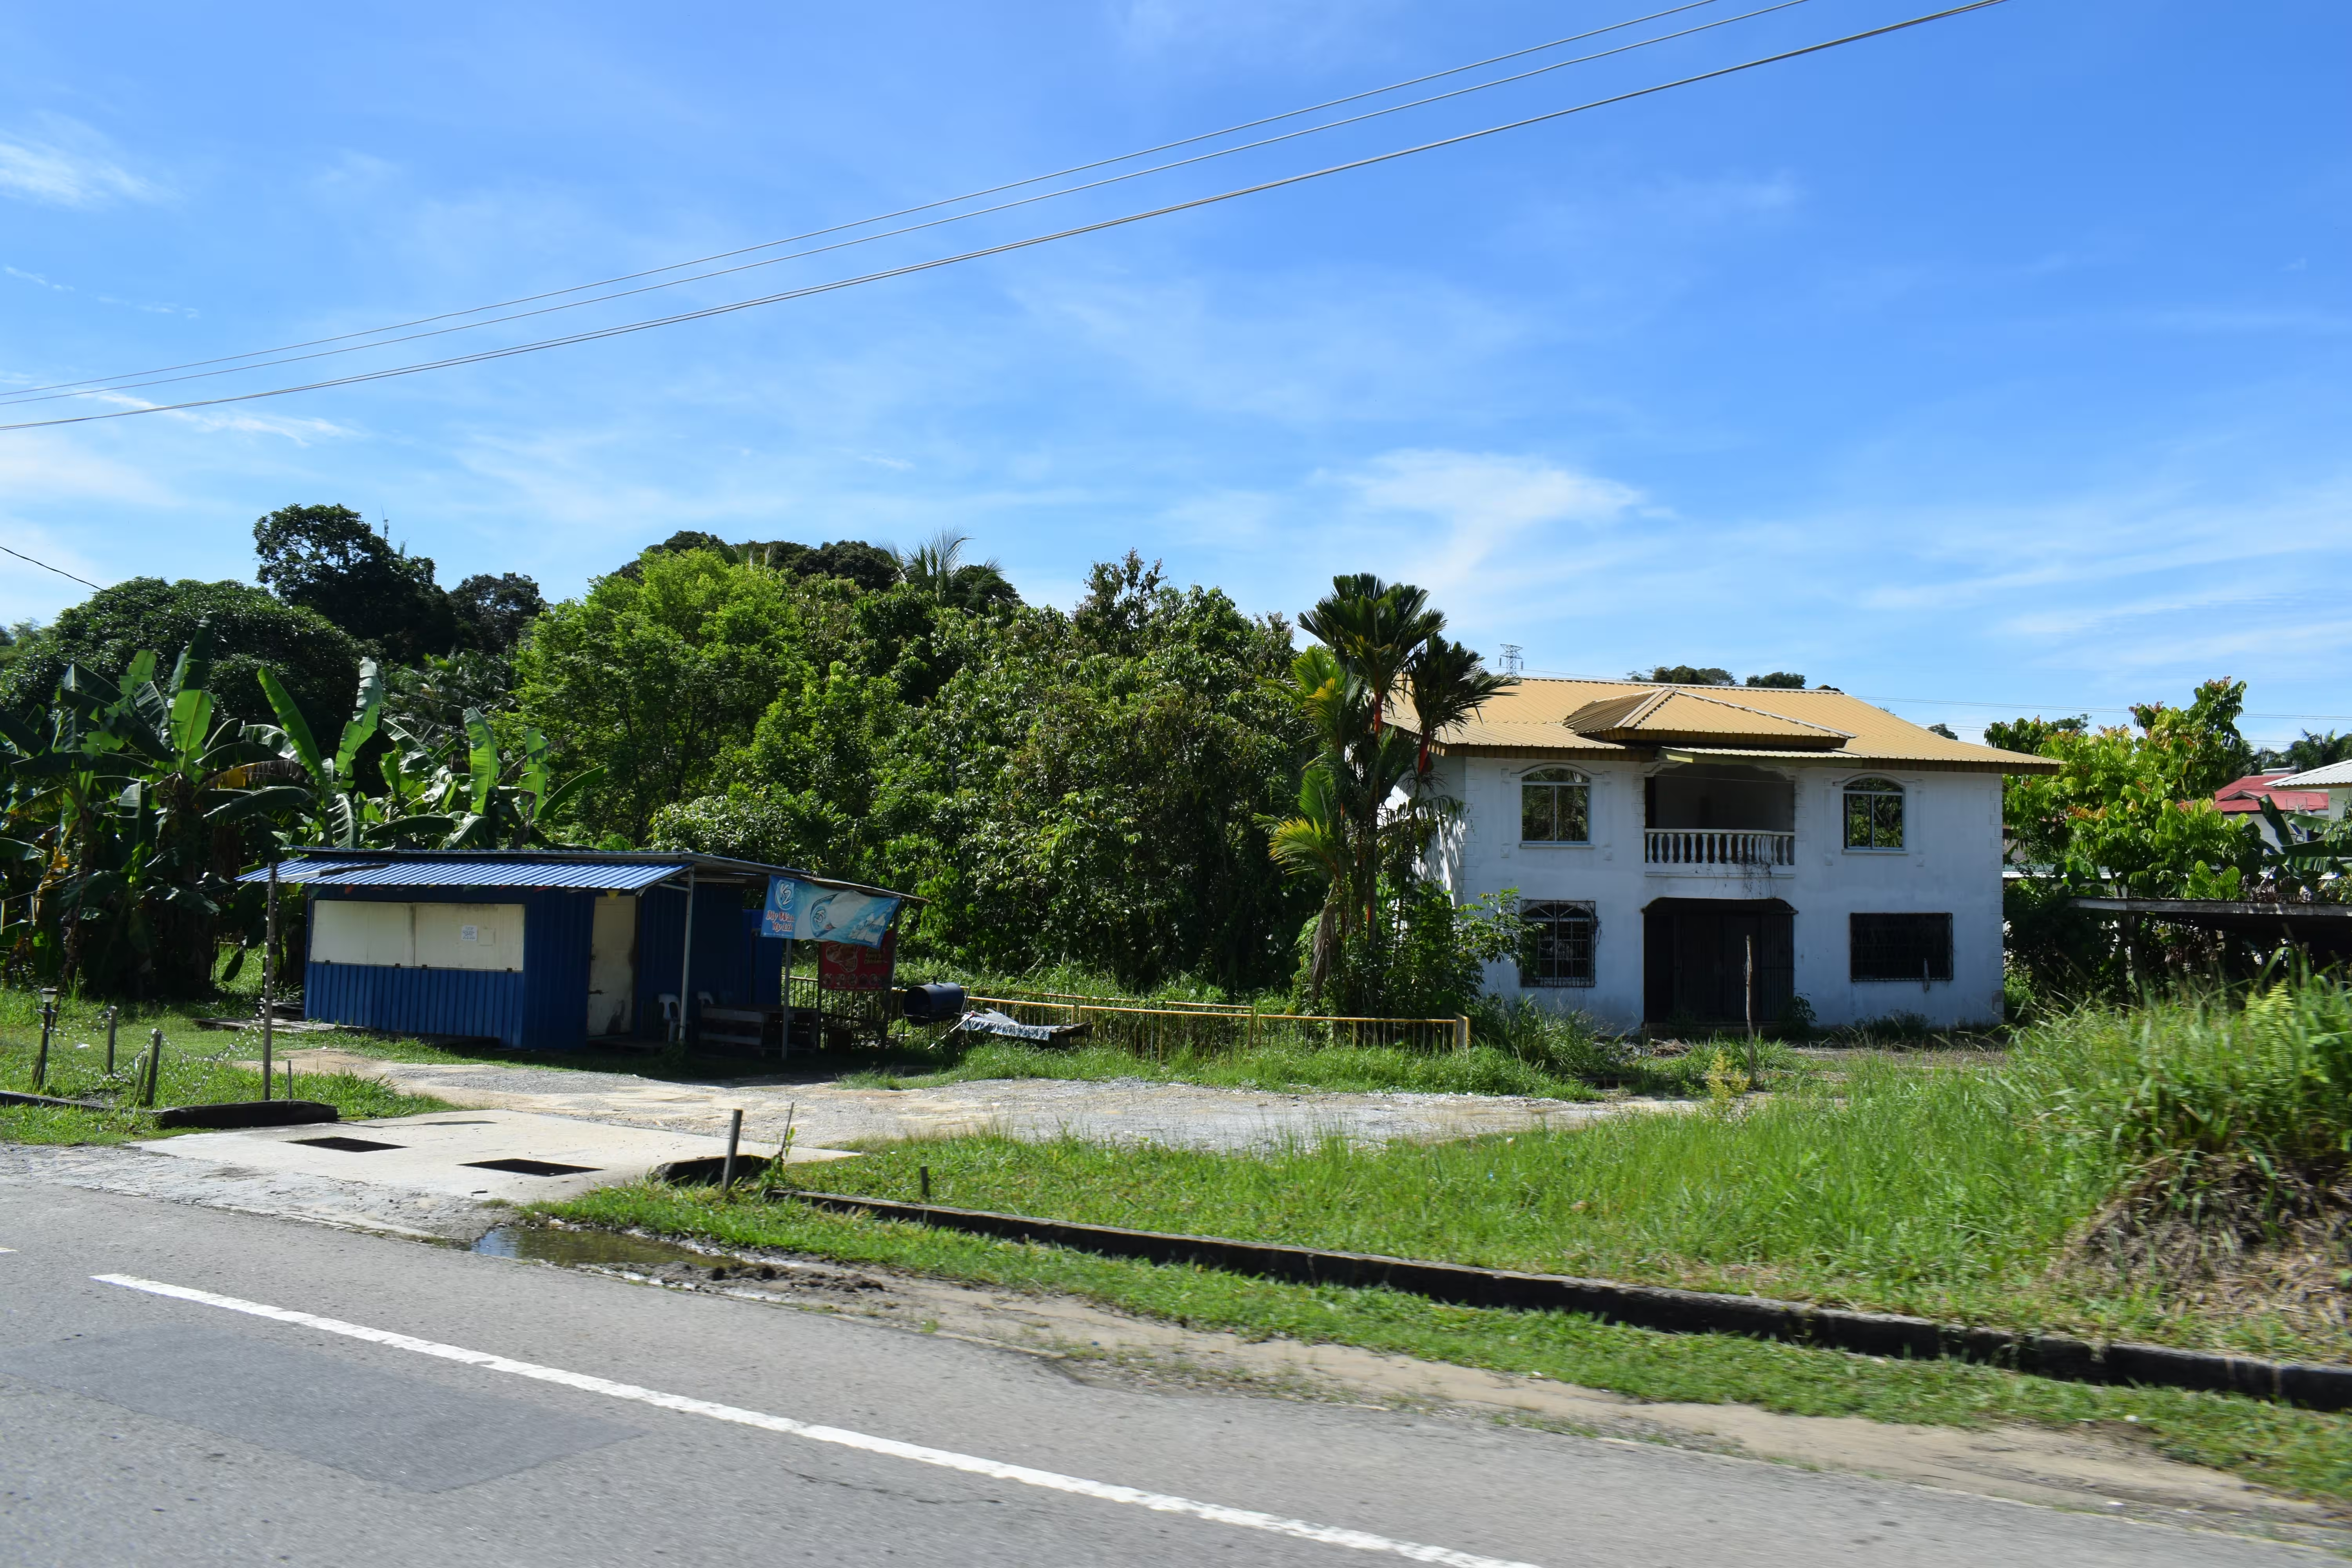
When he was done with his lunch, he drove us to the airport. It was incredibly frustrating. On a positive note, we saw countryside of Brunei that we would have seen otherwise. The bus ride cost us 1 Brunei dollar each.
A shot of Brunei s countryside. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0.
That s it for this one. Meet you in the next one. Stay tuned for the Vietnam post!
Introduction
I'm one of a Budgie Desktop user since 2020. (Budgie Desktop 10.5 or so)
Recently Budgie Desktop 10.10 had been available from
Debian experimental.
I've tried it and realized that not for me yet.
What is the requirement for desktop environment
Screen sharing with specifying the specific window/application for web meeting
Sharing keyboard input smoothly with deskflow
Switch focus with mouse movement
and ...
Is Budgie Desktop 10.10 suitable?
Short answer: No, not yet.
It seems that Budgie Desktop 10.10 (wayland) lost the functionality
- screen sharing with specifying the specific window/application for web meeting.
Of course, you can share your screen itself.
It also can't sharing keyboard input smoothly with deskflow.
Both of them seems that they are supported in GNOME? or KDE?.
In contrast to Budgie Desktop 10.9 (X11), Budgie Desktop 10.10 seems missing
effective wayland + xdg-desktop-portal support for them yet.
It might be supported in the future release, but it might be 11.x.
Conclusion
It was still too early to adopt Budgie Desktop (wayland) for me.
I'll stay with Budgie Desktop 10.9 for a while.
That said, it's unclear how long Budgie Desktop 10.9 will remain unstable and usable.
There might be a case that sticking to Budgie Desktop 10.9 might be problematic when other packages are updated.
When that happens, I'd like to reconsider this issue again.
The Debian LTS Team, funded by [Freexian s Debian LTS offering]
(https://www.freexian.com/lts/debian/), is pleased to report its activities for
December.
Activity summary
During the month of December, 18 contributors have been
paid to work on Debian LTS (links to individual
contributor reports are located below).
The team released 41 DLAs fixing 252 CVEs.
The team currently focuses on preparing security updates for Debian 11
bullseye , but also looks for contributing with updates for Debian 12
bookworm , Debian 13 trixie and even Debian unstable.
Notable security updates:
libsoup2.4 (DLA-4398-1),
prepared by Andreas Henrikson, fixing several vulnerabilities.
glib2.0 (DLA-4412-1),
published by Emilio Pozuelo Monfort, addressing multiple issues.
lasso (DLA-4397-1),
prepared by Sylvain Beucler, addressing multiple issues, including a critical
remote code execution (RCE) vulnerability
(CVE-2025-47151)
roundcube (DLA 4415-1),
prepared by Guilhem Moulin, fixing a cross-site-scripting (XSS)
(CVE-2025-68461)
and an information disclosure
(CVE-2025-68460)
vulnerabilities
mediawiki (DLA 4428-1),
published by Guilhem, fixing multiple vulnerabilities could lead to
information disclosure, denial of service or privilege escalation.
python-apt (DLA 4408-1), prepared by
Utkarsh Gupta, in coordination with the Debian Security Team and Julian
Andres Klode, the apt s maintainer.
libpng1.6 (DLA-4396-1),
published by Tobias Frost, completing the work started the previous month.
Notable non-security updates:
tzdata (DLA-4403-1),
prepared by Emilio, including the latest changes to the leap second list and
its expiry date, which was set for the end of December.
Contributions from outside the LTS Team:
Christoph Berg, co-maintainer of PostgreSQL in Debian, prepared a
postgresql-13 update, released as DLA-4420-1
The LTS Team has also contributed with updates to the latest Debian releases:
Andreas proposed trixie
and bookworm point updates for pgbouncer
Abhijith PA prepared a bookworm
point update for php-dompdf
Thorsten Alteholz prepared an unstable update and a
trixie point update for libcoap3
Thorsten prepared or completed different updates for unstable, trixie and
bookworm for packages related to cups: an
unstable update
of cups to fix several issues related to the latest security update, a
trixie point update for
libcupsfilters, and trixie and
bookworm point updates for cups-filter.
Version 0.0.25 of RcppSpdlog arrived
on CRAN right now, and will be
uploaded to Debian and built for r2u shortly along with a
minimal refresh of the documentation site. RcppSpdlog
bundles spdlog, a
wonderful header-only C++ logging library with all the bells and
whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn
more at the nice package
documention site.
This release fixes a minuscule cosmetic issue from the previous
release a week ago. We rely on two #defines that R sets to
signal to spdlog that we
are building in the R context (which matters for the R-specific logging
sink, and picks up something Gabi added upon my suggestion at
the very start of this package). But I use the same
#defines to now check in Rcpp that we are building with R and, in
this case, wrongly conclude R headers have already been installed so Rcpp (incorrectly) nags about that. The
solution is to add two #undefine and proceed as normal
(with Rcpp controlling and taking
care of R header includion too) and that is what we do here. All good
now, no nags from a false positive.
The NEWS entry for this release follows.
Changes in
RcppSpdlog version 0.0.25 (2026-01-15)
Ensure #define signaling R build (needed with spdlog)
is unset before including R headers to not falsely triggering message
from Rcpp
David Patterson does not need an introduction. Being the brain behind many
of the inventions that shaped the computing industry (repeatedly) over the
past 40 years, when he put forward an opinion article in Communications of
the ACM targeting the current day political waves in the USA, I could not
avoid choosing it to write this review.
Patterson worked for a a public university (University of California at
Berkeley) between 1976 and 2016, and in this article he argues how
government-funded academic research (GoFAR) allows for faster, more
effective and freer development than private sector-funded research would,
putting his own career milestones as an example of how public money that
went to his research has easily been amplified by a factor of 10,000:1 for
the country s economy, and 1,000:1 particularly for the government.
Patterson illustrates this quoting five of the home-run research projects
he started and pursued with government funding, eventually spinning them
off as successful startups:
RISC (Reduced Instruction Set Computing): Microprocessor
architecture that reduces the complexity and power consumption of CPUs,
yielding much smaller and more efficient processors.
RAID (Redundant Array of Inexpensive Disks): Patterson experimented
with a way to present a series of independent hard drive units as if they
were a single, larger one, leading to increases in capacity and
reliability beyond what the industry could provide in single drives, for
a fraction of the price.
NOW (Network Of Workstations): Introduced what we now know as
computer clusters (in contrast of large-scale massively multiprocessed
cache-coherent systems known as supercomputers ), which nowadays power
over 80% of the Top500 supercomputer list and are the computer platform
of choice of practically all data centers.
RAD Lab (Reliable Adaptive Distributed Systems Lab): Pursued the
technology for data centers to be self-healing and self-managing, testing
and pushing early cloud-scalability limits
ParLab (Parallel Computing Lab): Given the development of massively
parallel processing inside even simple microprocessors, this lab explores
how to improve designs of parallel software and hardware, presenting the
ground works that proved that inherently parallel GPUs were better than
CPUs at machine learning tasks. It also developed the RISC-V open
instruction set architecture.
Patterson identifies principles for the projects he has led, that are
specially compatible with the ways research works at universitary systems:
Multidisciplinary teams, demonstrative usable artifacts, seven- to ten-year
impact horizons, five-year sunset clauses (to create urgency and to lower
opportunity costs), physical proximity of collaborators, and leadership
followed on team success rather than individual recognition.
While it could be argued that it s easy to point at Patterson s work as a
success example while he is by far not the average academic, the points he
makes on how GoFAR research has been fundamental for the advance of
science and technology, but also of biology, medicine, and several other
fields are very clear.
Following up on my initial announcement about Debian Libre Live I am happy to report on continued progress and the release of Debian Libre Live version 13.3.0.
Since both this and the previous 13.2.0 release are based on the stable Debian trixie release, there really isn t a lot of major changes but instead incremental minor progress for the installation process. Repeated installations has a tendency to reveal bugs, and we have resolved the apt sources list confusion for Calamares-based installations and a couple of other nits. This release is more polished and we are not aware of any known remaining issues with them (unlike for earlier versions which were released with known problems), although we conservatively regard the project as still in beta. A Debian Libre Live logo is needed before marking this as stable, any graphically talented takers? (Please base it on the Debian SVG upstream logo image.)
We provide GNOME, KDE, and XFCE desktop images, as well as text-only standard image, which match the regular Debian Live images with non-free software on them, but also provide a slim variant which is merely 750MB compared to the 1.9GB standard image. The slim image can still start a debian installer, and can still boot into a minimal live text-based system.
The GNOME, KDE and XFCE desktop images feature the Calamares installer, and we have performed testing on a variety of machines. The standard and slim images does not have a installer from the running live system, but all images support a boot menu entry to start the installer.
With this release we also extend our arm64 support to two tested platforms. The current list of successfully installed and supported systems now include the following hardware:
This is a very limited set of machines, but the diversity in CPUs and architecture should hopefully reflect well on a wide variety of commonly available machines. Several of these machines are crippled (usually GPU or WiFI) without adding non-free software, complain at your hardware vendor and adapt your use-cases and future purchases.
The images are as follows, with SHA256SUM checksums and GnuPG signature on the 13.3.0 release page.
Two years of midsize electric sedan experience
This February (2026) marks a full 10 years since I started working for BMW, and a key employment bonus is the ability to drive a company car on special two-year leasing terms. Just before the new year 2026 started, I said goodbye to my latest company car. After driving the BMW i4, I switched to the BMW i5. In terms of power, it was a downgrade as I switched from the maximum power i4 M50 xDrive (all-wheel drive, 600 hp) to the i5 eDrive40 (rear-wheel drive, 340 hp). Did I regret that? Not for a single second! After driving 60,000 km in the last two years with the BMW i5, I was really sad to let it go -- it was the best car I have ever driven. Simple as that.
Read more (16 min remaining to read)
dh-python development, by Stefano Rivera
In Debian we build our Python packages with the help of a debhelper-compatible
tool, dh-python. Before starting the
3.14 transition (that would rebuild many packages) we landed some updates to
dh-python to fix bugs and add features. This started
a month of attention
on dh-python, iterating through several bug fixes, and a couple of unfortunate
regressions.
dh-python is used by almost all packages containing Python (over 5000). Most
of these are very simple, but some are complex and use dh-python in unexpected
ways. It s hard to avoid almost any change (including obvious bug fixes) from
causing some unexpected knock-on behaviour. There is a fair amount of complexity
in dh-python, and some rather clever code, which can make it tricky to work on.
All of this means that good QA is important. Stefano spent some time
adding type annotations
and specialized types to make it easier to see what the code is doing and catch
mistakes. This has already made work on dh-python easier.
Now that Debusine has built-in repositories
and debdiff support, Stefano could quickly test the effects of changes on many
other packages. After each big change, he could upload dh-python to
a repository,
rebuild e.g. 50 Python packages with it, and see what differences appeared in
the output. Reviewing the diffs is still a manual process, but can be improved.
Stefano did a small test
on what it would take to replace direct setuptools setup.py calls with
PEP-517 (pyproject-style) builds. There is
more work to do here.
Python 3.14 transition, by Stefano Rivera (et al.)
In December the transition to add
Python 3.14 as a supported version started in Debian unstable. To do this, we
update the list of supported versions in python3-defaults,
and then start rebuilding modules with C extensions from the leaves inwards.
This had already been tested in a PPA and Ubuntu, so many of the biggest
blocking compatibility issues with 3.14 had already been found and fixed. But
there are always new issues to discover.
Thanks to a number of people in the Debian Python team, we got through the first
bit of the transition fairly quickly. There are still a number of
open bugs
that need attention and many failed tests
blocking migration to testing.
Python 3.14.1 released just after we started the transition, and very soon
after, a follow-up 3.14.2 release came out to address a regression. We ran into
another regression in
Python 3.14.2.
Ruby 3.4 transition, by Lucas Kanashiro (et al.)
The Debian Ruby team just started the preparation to move the default Ruby
interpreter version to 3.4. At the moment, ruby3.4 source package is already
available in experimental, also ruby-defaults added support to
Ruby 3.4. Lucas rebuilt all reverse dependencies against this new version of the
interpreter and published the results here.
Lucas also reached out to some stakeholders to coordinate the work.
Next steps are: 1) announcing the results to the whole team and asking for help
to fix packages failing to build against the new interpreter; 2) file bugs
against packages FTBFSing against Ruby 3.4 which are not fixed yet; 3) once we
have a low number of build failures against Ruby 3.4, ask the Debian Release
team to start the transition in unstable.
Surviving scraper traffic in Debian CI, by Antonio Terceiro
Like most of the open web, Debian Continuous Integration
has been struggling for a while to keep up with the insatiable hunger from data
scrapers everywhere. Solving this involved a lot of trial and error; the final
result seems to be stable, and consists of two parts.
First, all Debian CI data pages, except the direct links to test log files
(such as those provided by the Release Team s testing migration excuses), now
require users to be authenticated before being accessed. This means that the
Debian CI data is no longer publicly browseable, which is a bit sad. However,
this is where we are now.
Additionally, there is now a fail2ban powered firewall-level access limitation
for clients that display an abusive access pattern. This went through several
iterations, with some of them unfortunately blocking legitimate Debian
contributors, but the current state seems to strike a good balance between
blocking scrapers and not blocking real users. Please get in touch with the team
on the #debci OFTC channel if you are affected by this.
A hybrid dependency solver for crossqa.debian.net, by Helmut Grohne
crossqa.debian.net continuously cross builds
packages from the Debian archive. Like Debian s native build infrastructure, it
uses dose-builddebcheck to determine whether a package s dependencies can be
satisfied before attempting a build. About one third of Debian s packages fail
this check, so understanding the reasons is key to improving cross building.
Unfortunately, dose-builddebcheck stops after reporting the first problem and
does not display additional ones.
To address this, a greedy solver implemented in Python now examines each
build-dependency individually and can report multiple causes. dose-builddebcheck
is still used as a fall-back when the greedy solver does not identify any
problems. The report for bazel-bootstrap
is a lengthy example.
rebootstrap, by Helmut Grohne
Due to the changes suggested by Loongson earlier, rebootstrap now adds
debhelper to its final installability test and builds a few more packages
required for installing it. It also now uses a variant of build-essential that
has been markedMulti-Arch: same
(see foundational work
from last year).
This in turn made the use of a non-default GCC version more difficult and
required more work to make it work for gcc-16 from experimental. Ongoing
archive changes temporarily regressed building fribidi and dash.
libselinux and groff have received patches for architecture specific changes
and libverto has been NMUed to remove the glib2.0 dependency.
Miscellaneous contributions
Stefano did some administrative work on debian.social and debian.net
instances and Debian reimbursements.
Stefano did routine updates of python-authlib, python-mitogen, xdot.
Stefano spent several hours discussing Debian s Python package layout with the
PyPA upstream community. Debian has ended up with a very different on-disk
installed Python layout than other distributions, and this continues to cause
some frustration in many communities that have to have special workarounds to
handle it. This ended up impacting cross builds as Helmut discovered.
Zulip is not yet in Debian (RFP in #800052),
but Rapha l helped on the French translation as he is experimenting with that
discussion platform.
Antonio performed several routine Salsa maintenance tasks, including
fixing salsa-nm-sync,
the service that synchronizes project members data from LDAP to Salsa, which had
been broken since salsa.debian.org was upgraded to
trixie .
Antonio deployed a new amd64 worker host for Debian CI.
Carles reviewed and submitted 14 Catalan translations using
po-debconf-manager.
Carles improved po-debconf-manager: added delete-package command,
show-information now uses properly formatted output (YAML), it now attaches
the translation on the bug reports for which a merge request has been opened too
long.
Carles investigated why some packages appeared in po-debconf-manager but not
in the Debian l10n list.
Turns out that some packages had debian/po/templates.pot (appearing in
po-debconf-manager) but not the POTFILES.in file as expected.
Created a script
to find out which packages were in this or similar situation and
reported bugs.
Carles tested and documented how to set
up voices (mbrola and festival) if using Orca speech synthesizer. Commented
a few issues and possible improvements in the debian-accessibility list.
Helmut sent patches for 48 cross build failures and initiated discussions on
how to deal with two non-trivial matters. Besides Python mentioned above,
CMake introduced a cmake_pkg_config builtin which is
not aware of the host architecture. He also
forwarded a Meson patch upstream.
Thorsten uploaded a new upstream version of cups to fix a nasty bug that was
introduced by the latest security update.
Colin used Debusine to coordinate transitions for astroid and pygments,
and wrote up the astroid case
on his blog.
Emilio helped with various transitions, and provided a build fix for opencv
for the ffmpeg 8 transition.
Emilio tested the GNOME updates for trixie proposed updates (gnome-shell,
mutter, glib2.0).
Santiago helped to review the status of how to test different build profiles
in parallel on the same pipeline, using the test-build-profiles job. This means,
for example, to simultaneously test build profiles such as nocheck and nodoc
for the same git tree. Finally, Santiago provided
MR !685
to fix the documentation.
Anupa prepared a bits post for Outreachy interns
announcement
along with T ssia Cam es Ara jo and worked on publicity team tasks.
Note: While I often post the reviews I write for Computing Reviews,
this is a shorter review requested to me by Manning. They kindly invited me
several months ago to be a reviewer for Python Workout, 2nd
edition;
after giving them my opinions, I am happy to widely recommend this book to
interested readers.
Python is relatively an easy programming language to learn, allowing you to
start coding pretty quickly. However, there s a significant gap between
being able to throw code in Python and truly mastering the language. To
write efficient, maintainable code that s easy for others to understand,
practice is essential. And that s often where many of us get stuck. This
book begins by stating that it is not designed to teach you Python ( )
but rather to improve your understanding of Python and how to use it to
solve problems.
The author s structure and writing style are very didactic. Each chapter
addresses a different aspect of the language: from the simplest (numbers,
strings, lists) to the most challenging for beginners (iterators and
generators), Lerner presents several problems for us to solve as examples,
emphasizing the less obvious details of each aspect.
I was invited as a reviewer in the preprint version of the book. I am now
very pleased to recommend it to all interested readers. The author presents
a pleasant and easy-to-read text, with a wealth of content that I am sure
will improve the Python skills of all its readers.
A recent article in The Atlantic makes the case that
very large language models effectively contain much of the works they're trained on.
This article is an attempt to popularize the insights in the recent academic paper
Extracting books from production language models from Ahmed et al.
The authors of the paper demonstrate convincingly that
well-known copyrighted textual material can be extracted from
the chatbot interfaces of popular commercial LLM services.
The Atlantic article cites a podcast quote about the Stable Diffusion AI image-generator model, saying "We took 100,000 gigabytes of images and compressed it to a two-gigabyte file that can re-create any of those and iterations of those".
By analogy, this suggests we might think of LLMs (which work on text, not the images handled by Stable Diffusion) as a form of lossy textual compression.
The entire text of Moby Dick, the canonical Big American Novel is merely 1.2MiB uncompressed (and less than 0.4MiB losslessly compressed with bzip2 -9).
It's not surprising to imagine that a model
with hundreds of billions of parameters might contain copies of these works.
Warning: The next paragraph contains fuzzy math with no real concrete engineering practice behind it!
Consider a hypothetical model with 100 billion parameters,
where each parameter is stored as a 16-bit floating point value.
The model weights would take 200 GB of storage.
If you were to fill the parameter space only with losslessly compressed copies of books like Moby Dick,
you could still fit half a million books, more than anyone can read in a lifetime.
And lossy compression is typically orders of magnitude less in size than lossless compression,
so we're talking about millions of works effectively encoded, with the acceptance of some
artifacts being injected in the output.
I first encountered this "compression" view of AI nearly three years ago, in Ted Chiang's insightful
ChatGPT is a Blurry JPEG of the Web.
I was suprised that The Atlantic article didn't cite Chiang's piece.
If you haven't read Ted Chiang, i strongly recommend his work,
and this piece is a great place to start.
Chiang aside, the more recent writing that focuses on the idea of
compressed works being "contained" in the model weights
seems to be used by people interested in wielding
some sort of copyright claims against the AI companies that maintain or provide access to these models.
There are many many problems with AI today, but attacking AI companies based on copyright concerns
seems similar to going after Al Capone for tax evasion.
We should be much more concerned with the effect these projects have on
cultural homogeneity,
mentalhealth,
laborrights,
privacy, and
socialcontrol
than whether they're violating copyright in some specific instance.
I just read this informative article on ANSI terminal security [1]. The author has written a tool named vt-houdini for testing for these issues [2]. They used to host an instance on their server but appear to have stopped it. When you run that tool you can ssh to the system in question and without needing a password you are connected and the server probes your terminal emulator for vulnerabilities. The versions of Kitty and Konsole in Debian/Trixie have just passed those tests on my system.
This will always be a potential security problem due to the purpose of a terminal emulator. A terminal emulator will often display untrusted data and often data which is known to come from hostile sources (EG logs of attempted attacks). So what could be done in this regard?
Memory Protection
Due to the complexity of terminal emulation there is the possibility of buffer overflows and other memory management issues that could be used to compromise the emulator.
The Fil-C compiler is an interesting project [3], it compiles existing C/C++ code with memory checks. It is reported to have no noticeable impact on the performance of the bash shell which sounds like a useful option to address some of these issues as shell security issues are connected to terminal security issues. The performance impact on a terminal emulator would be likely to be more noticeable. Also note that Fil-C compilation apparently requires compiling all libraries with it, this isn t a problem for bash as the only libraries it uses nowadays are libtinfo and libc. The kitty terminal emulator doesn t have many libraries but libpython is one of them, it s an essential part of Kitty and it is a complex library to compile in a different way. Konsole has about 160 libraries and it isn t plausible to recompile so many libraries at this time.
Choosing a terminal emulator that has a simpler design might help in this regard. Emulators that call libraries for 3D effects etc and native support for displaying in-line graphics have a much greater attack surface.
Access Control
A terminal emulator could be run in a container to prevent it from doing any damage if it is compromised. But the terminal emulator will have full control over the shell it runs and if the shell has access needed to allow commands like scp/rsync to do what is expected of them then that means that no useful level of containment is possible.
It would be possible to run a terminal emulator in a container for the purpose of connecting to an insecure or hostile system and not allow scp/rsync to/from any directory other than /tmp (or other directories to use for sharing files). You could run exec ssh $SERVER so the terminal emulator session ends when the ssh connection ends.
Conclusion
There aren t good solutions to the problems of terminal emulation security. But testing every terminal emulator with vt-houdini and fuzzing the popular ones would be a good start.
Qubes level isolation will help things in some situations, but if you need to connect to a server with privileged access to read log files containing potentially hostile data (which is a common sysadmin use case) then there aren t good options.
If you care about supporting open source software, and still use MySQL in 2026, you should switch to MariaDB like so many others have already done.
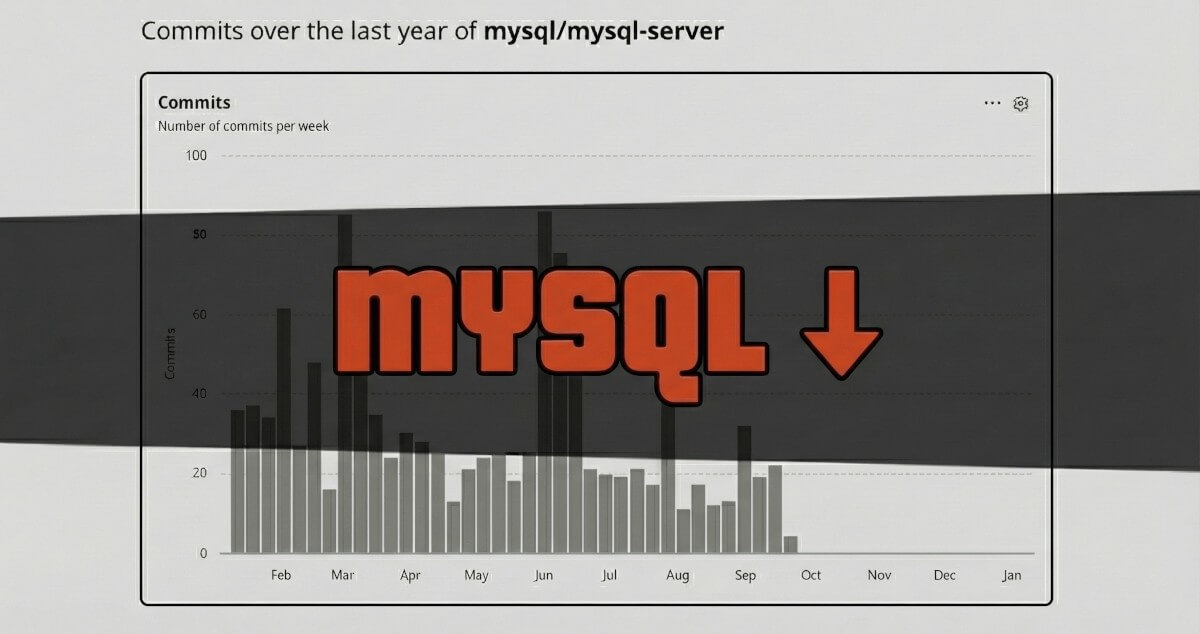
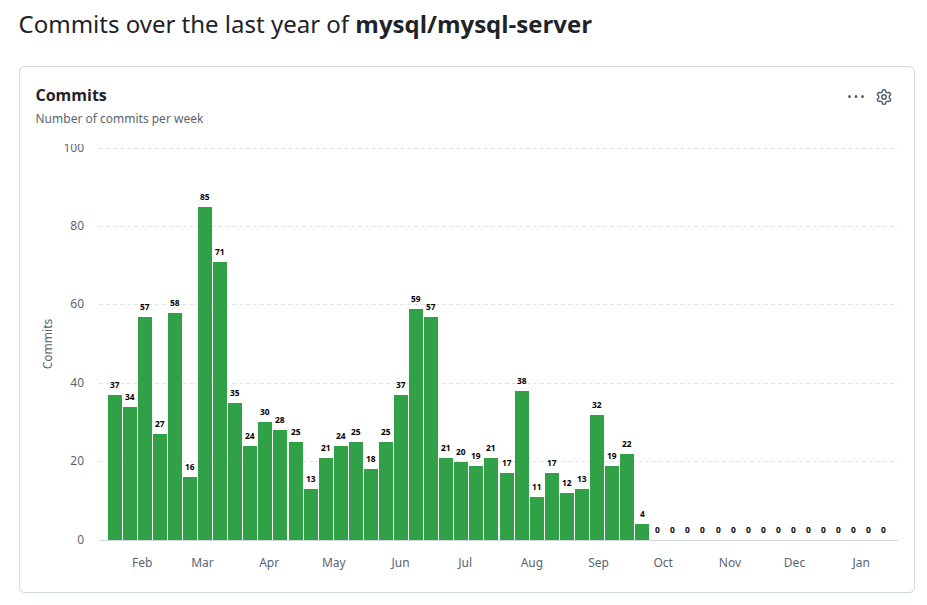
The number of git commits on github.com/mysql/mysql-server has been significantly declining in 2025. The screenshot below shows the state of git commits as of writing this in January 2026, and the picture should be alarming to anyone who cares about software being open source.
This is not surprising Oracle should not be trusted as the steward for open source projects
When Oracle acquired Sun Microsystems and MySQL along with it back in 2009, the European Commission almost blocked the deal due to concerns that Oracle s goal was just to stifle competition. The deal went through as Oracle made a commitment to keep MySQL going and not kill it, but (to nobody s surprise) Oracle has not been a good steward of MySQL as an open source project and the community around it has been withering away for years now. All development is done behind closed doors. The publicly visible bug tracker is not the real one Oracle staff actually uses for MySQL development, and the few people who try to contribute to MySQL just see their Pull Requests and patch submissions marked as received with mostly no feedback and then those changes may or may not be in the next MySQL release, often rewritten, and with only Oracle staff in the git author/committer fields. The real author only gets a small mention in a blog post. When I was the engineering manager for the core team working on RDS MySQL and RDS MariaDB at Amazon Web Services, I oversaw my engineers contributions to both MySQL and MariaDB (the latter being a fork of MySQL by the original MySQL author, Michael Widenius). All the software developers in my org disliked submitting code to MySQL due to how bad the reception by Oracle was to their contributions.
MariaDB is the stark opposite with all development taking place in real-time on github.com/mariadb/server, anyone being able to submit a Pull Request and get a review, all bugs being openly discussed at jira.mariadb.org and so forth, just like one would expect from a true open source project. MySQL is open source only by license (GPL v2), but not as a project.
MySQL s technical decline in recent years
Despite not being a good open source steward, Oracle should be given credit that it did keep the MySQL organization alive and allowed it to exist fairly independently and continue developing and releasing new MySQL versions well over a decade after the acquisition. I have no insight into how many customers they had, but I assume the MySQL business was fairly profitable and financially useful to Oracle, at least as long as it didn t gain too many features to threaten Oracle s own main database business.
I don t know why, perhaps because too many talented people had left the organization, but it seems that from a technical point of view MySQL clearly started to deteriorate from 2022 onward.
When MySQL 8.0.29 was released with the default ALTER TABLE method switched to run in-place, it had a lot of corner cases that didn t work, causing the database to crash and data to corrupt for many users. The issue wasn t fully fixed until a year later in MySQL 8.0.32. To many users annoyance Oracle announced the 8.0 series as evergreen and introduced features and changes in the minor releases, instead of just doing bugfixes and security fixes like users historically had learnt to expect from these x.y.Z maintenance releases.
There was no new major MySQL version for six years. After MySQL 8.0 in 2018 it wasn t until 2023 when MySQL 8.1 was released, and it was just a short-term preview release. The first actual new major release MySQL 8.4 LTS was released in 2024. Even though it was a new major release, many users got disappointed as it had barely any new features.
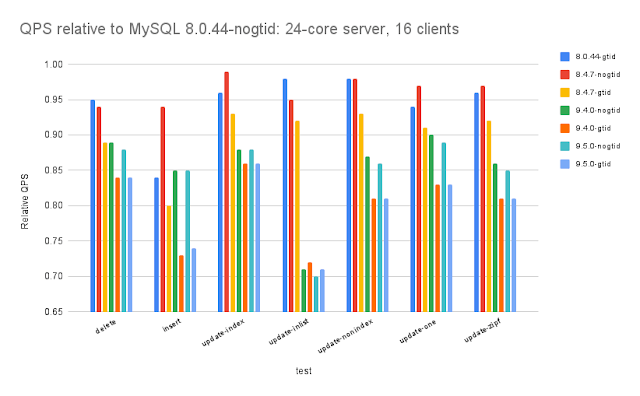
Many also reported degraded performance with newer MySQL versions, for example the benchmark by famous MySQL performance expert Mark Callaghan below shows that on write-heavy workloads MySQL 9.5 throughput is typically 15% less than in 8.0.
Due to newer MySQL versions deprecating many features, a lot of users also complained about significant struggles regarding both MySQL 5.7->8.0 and 8.0->8.4 upgrades. With few new features and heavy focus on code base cleanup and feature deprecation, it became obvious to many that Oracle had decided to just keep MySQL barely alive, and put all new relevant features (e.g. vector search) into Heatwave, Oracle s closed-source and cloud-only service for MySQL customers.
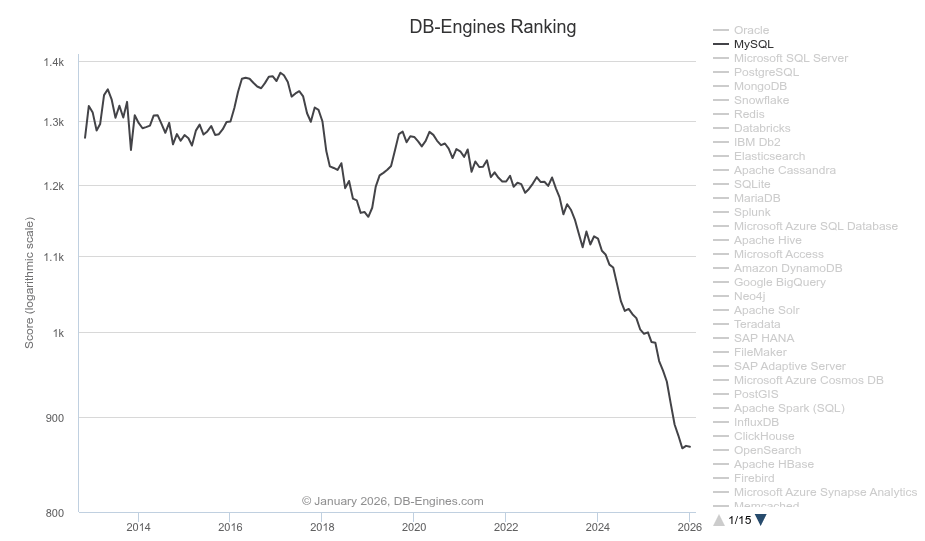
As it was evident that Oracle isn t investing in MySQL, Percona s Peter Zaitsev wrote Is Oracle Finally Killing MySQL in June 2024. At this time MySQL s popularity as ranked by DB-Engines had also started to tank hard, a trend that likely accelerates in 2026.
In September 2025 news reported that Oracle was reducing its workforce and that the MySQL staff was getting heavily reduced. Obviously this does not bode well for MySQL s future, and Peter Zaitsev posted already in November stats showing that the latest MySQL maintenance release contained fewer bug fixes than before.
Open source is more than ideology: it has very real effects on software security and sovereignty
Some say they don t care if MySQL is truly open source or not, or that they don t care if it has a future in coming years, as long as it still works now. I am afraid people thinking so are taking a huge risk. The database is often the most critical part of a software application stack, and any flaw or problem in operations, let alone a security issue, will have immediate consequences, and not caring will eventually get people fired or sued.
In open source problems are discussed openly, and the bigger the problem, the more people and companies will contribute to fixing it. Open source as a development methodology is similar to the scientific method with free flow of ideas that are constantly contested and only the ones with the most compelling evidence win. Not being open means more obscurity, more risk and more just trust us bro attitude.
This open vs. closed is very visible for example in how Oracle handles security issues. We can see that in 2025 alone MySQL published 123 CVEs about security issues, while MariaDB had 8. There were 117 CVEs that only affected MySQL and not MariaDB in 2025. I haven t read them all, but typically the CVEs hardly contain any real details. As an example, the most recent one CVE-2025-53067 states Easily exploitable vulnerability allows high privileged attacker with network access via multiple protocols to compromise MySQL Server. There is no information a security researcher or auditor could use to verify if any original issue actually existed, or if it was fixed, or if the fix was sufficient and fully mitigating the issue or not. MySQL users just have to take the word of Oracle that it is all good now. Handling security issues like this is in stark contrast to other open source projects, where all security issues and their code fixes are open for full scrutiny after the initial embargo is over and CVE made public.
There is also various forms of enshittification going on one would not see in a true open source project, and everything about MySQL as a software, documentation and website is pushing users to stop using the open source version and move to the closed MySQL versions, and in particular to Heatwave, which is not only closed-source but also results in Oracle fully controlling customer s databases contents.
Of course, some could say this is how Oracle makes money and is able to provide a better product. But stories on Reddit and elsewhere suggest that what is going on is more like Oracle milking hard the last remaining MySQL customers who are forced to pay more and more for getting less and less.
There are options and migrating is easy, just do it
A large part of MySQL users switched to MariaDB already in the mid-2010s, in particular everyone who had cared deeply about their database software staying truly open source. That included large installations such as Wikipedia, and Linux distributions such as Fedora and Debian. Because it s open source and there is no centralized machine collecting statistics, nobody knows what the exact market shares look like. There are however some application specific stats, such as that 57% of WordPress sites around the world run MariaDB, while the share for MySQL is 42%.
For anyone running a classic LAMP stack application such as WordPress, Drupal, Mediawiki, Nextcloud, or Magento, switching the old MySQL database to MariaDB is be straightforward. As MariaDB is a fork of MySQL and mostly backwards compatible with it, swapping out MySQL for MariaDB can be done without changing any of the existing connectors or database clients, as they will continue to work with MariaDB as if it was MySQL.
For those running custom applications and who have the freedom to make changes to how and what database is used, there are tens of mature and well-functioning open source databases to choose from, with PostgreSQL being the most popular general database. If your application was built from the start for MySQL, switching to PostgreSQL may however require a lot of work, and the MySQL/MariaDB architecture and storage engine InnoDB may still offer an edge in e.g. online services where high performance, scalability and solid replication features are of highest priority. For a quick and easy migration MariaDB is probably the best option.
Switching from MySQL to the Percona Server is also very easy, as it closely tracks all changes in MySQL and deviates from it only by a small number of improvements done by Percona. However, also precisely because of it being basically just a customized version of the MySQL Server, it s not a viable long-term solution for those trying to fully ditch the dependency on Oracle.
There are also several open source databases that have no common ancestry with MySQL, but strive to be MySQL-compatible. Thus most apps built for MySQL can simply switch to using them without needing SQL statements to be rewritten. One such database is TiDB, which has been designed from scratch specifically for highly scalable and large systems, and is so good that even Amazon s latest database solution DSQL was built borrowing many ideas from TiDB. However, TiDB only really shines with larger distributed setups, so for the vast majority of regular small- and mid-scale applications currently using MySQL, the most practical solution is probably to just switch to MariaDB, which on most Linux distributions can simply be installed by running apt/dnf/brew install mariadb-server.
Whatever you end up choosing, as long as it is not Oracle, you will be better off.
Team Rcpp is thrilled to share that an exciting new version 1.1.1 of
Rcpp is now on CRAN (and also
uploaded to Debian and already
built for r2u).
Having switchted to C++11 as the minimum standard in the
previous 1.1.0 release, this version takes full advantage of it and
removes a lot of conditional code catering to older standards
that no longer need to be supported. Consequently, the source tarball
shrinks by 39% from 3.11 mb to 1.88 mb. That is a big deal. (Size peaked
with Rcpp 1.0.12 two years ago at 3.43 mb; relative to its size we are
down 45% !!) Removing unused code also makes maintenance easier, and
quickens both compilation and installation in general.
This release continues as usual with the six-months January-July
cycle started with release
1.0.5 in July 2020. Interim snapshots are always available via the
r-universe page and
repo. We continue to strongly encourage the use of these development
released and their testing we tend to run our systems with them too.
Rcpp has long established itself
as the most popular way of enhancing R with C or C++ code. Right now,
3020 packages on CRAN depend on
Rcpp for making analytical code go
faster and further. On CRAN, 13.1% of all packages depend (directly) on
Rcpp, and 60.9% of all compiled
packages do. From the cloud mirror of CRAN (which is but a subset of all
CRAN downloads), Rcpp has been
downloaded 109.8 million times. The two published papers (also included
in the package as preprint vignettes) have, respectively, 2151 (JSS, 2011) and 405 (TAS, 2018)
citations, while the the book (Springer useR!,
2013) has another 715.
This time, I am not attempting to summarize the different changes.
The full list follows below and details all these changes, their
respective PRs and, if applicable, issue tickets. Big thanks from all of
us to all contributors!
Changes in
Rcpp release version 1.1.1 (2026-01-08)
Changes in Rcpp API:
An unused old R function for a compiler version check has been
removed after checking no known package uses it (Dirk in #1395)
A narrowing warning is avoided via a cast (Dirk in #1398)
Demangling checks have been simplified (I aki in #1401 addressing
#1400)
The treatment of signed zeros is now improved in the Sugar code
(I aki in #1404)
Preparations for phasing out use of Rf_error have
been made (I aki in #1407)
The long-deprecated function loadRcppModules() has
been removed (Dirk in #1416 closing #1415)
Some non-API includes from R were refactored to accommodate
R-devel changes (I aki in #1418 addressing
#1417)
An accessor to Rf_rnbeta has been removed (Dirk in
#1419 also
addressing #1420)
Code accessing non-API Rf_findVarInFrame now uses
R_getVarEx (Dirk in #1423 fixing #1421)
Code conditional on the R version now expects at least R 3.5.0;
older code has been removed (Dirk in #1426 fixing #1425)
The non-API ATTRIB entry point to the R API is no
longer used (Dirk in #1430 addressing
#1429)
The unwind-protect mechanism is now used unconditionally (Dirk in
#1437 closing
#1436)
Changes in Rcpp Attributes:
The OpenMP plugin has been generalized for different macOS compiler
installations (Kevin in #1414)
Changes in Rcpp Documentation:
Vignettes are now processed via a new "asis" processor adopted
from R.rsp (Dirk in #1394 fixing #1393)
R is now cited via its DOI (Dirk)
A (very) stale help page has been removed (Dirk in #1428 fixing #1427)
The main README.md was updated emphasizing r-universe in favor of
the local drat repos (Dirk in #1431)
Changes in Rcpp Deployment:
A temporary change in R-devel concerning NA part in complex
variables was accommodated, and then reverted (Dirk in #1399 fixing #1397)
The macOS CI runners now use macos-14 (Dirk in #1405)
A message is shown if R.h is included before Rcpp
headers as this can lead to errors (Dirk in #1411 closing #1410)
Old helper functions use message() to signal they
are not used, deprecation and removal to follow (Dirk in #1413 closing #1412)
Three tests were being silenced following #1413 (Dirk in #1422)
The heuristic whether to run all available tests was refined
(Dirk in #1434
addressing #1433)
Coverage has been tweaked via additional #nocov tags
(Dirk in #1435)
Non-release Changes:
Two interim non-releases 1.1.0.8.1 and .2 were made in order to
unblock CRAN due to changes in R-devel rather than Rcpp
Inspiration
In November I watched a short documentary about a guy who grew pearl oyster mushrooms in his backyard.
They used pallet boxes (half of a europallet, 60x80x20 cm) as box to keep the substrate the mycelium feeds on in.
Since I really enjoy (foraged) mushrooms and had the raw materials lying around, I opted to build it myself.
This also had the benefit of using what was available and not just consuming, i.e. buying a pallet box.
Preparing the raw materials
I had 4.5 m x ~ 25 cm wooden spruce planks at home. My plan was to cut those into 2 m segments, then trim the edges down to 20 cm and then cut them into handy pieces,
following the dimension of half a pallet box.
This is what they looked after cutting them with an electric chainsaw to around 2 m:
You can see that the edges are still not straight, because that's how they came out of the sawmill.
Once that was done I visited a family member that had a crosscut saw, a table saw and a band saw; all that I would need. First we trimmed the edges of the 2m planks
with the table saw so they were somewhat straight; then they were flipped and the other edge was cut straight, and their width cut down to 20 cm.
After moving them over to the crosscut saw dividing them into two 60 cm and one 80 cm was fairly easy. When cutting the 2m planks from the 4m ones I calculated with
extra offcuts, so I got little waste overall and could use the whole length to get my desired board.
This is what the cut pieces looked like:
Assembly
I packed up my planks, now nicely cut to size, and I went to a hardware shop and bought hinges and screws.
Assembly was fairly easy and fast: screw a hinge to a corner, hold the other plank onto the hinge so that the corners of both boards touch, and affix the hinge.
When this was done, the frame looked like this:
As last step I drilled 10mm holes more or less random in the middle of the box. This is where the mushrooms will grow out of later and can be harvested.
Closing thoughts
This was a fun project I finished in a day. The hinges have the benefit that they allow the box to
be folded up lenght-wise:
This allows for convenient storage. Since it's too cold outside right now, cultivation will have to wait
until spring. This also just needs mycelium one can just buy, and some material fungus digests.
They can also be fed coffee grounds, and harvest of the fruit body is possible circa every two weeks.
One of my holiday projects was to understand and gain more trust in how Debian binaries are built, and as the holidays are coming to an end, I d like to introduce a new research project called Debian Taco. I apparently need more holidays, because there are still more work to be done here, so at the end I ll summarize some pending work.
Debian Taco, or TacOS, is a GitSecDevOps rebuild of Debian GNU/Linux.
The Debian Taco project publish rebuilt binary packages, package repository metadata (InRelease, Packages, etc), container images, cloud images and live images.
All packages are built from pristine source packages in the Debian archive. Debian Taco does not modify any Debian source code nor add or remove any packages found in Debian.
No servers are involved! Everything is built in GitLab pipelines and results are published through modern GitDevOps mechanism like GitLab Pages and S3 object storage. You can fork the individual projects below on GitLab.com and you will have your own Debian-derived OS available for tweaking. (Of course, at some level, servers are always involved, so this claim is a bit of hyperbole.)
Goals
The goal of TacOS is to be bit-by-bit identical with official Debian GNU/Linux, and until that has been completed, publish diffoscope output with differences.
The idea is to further categorize all artifact differences into one of the following categories:
1) An obvious bug in Debian. For example, if a package does not build reproducible.
2) An obvious bug in TacOS. For example, if our build environment does not manage to build a package.
3) Something else. This would be input for further research and consideration. This category also include things where it isn t obvious if it is a bug in Debian or in TacOS. Known examples:
3A) Packages in TacOS are rebuilt the latest available source code, not the (potentially) older package that were used to build the Debian packages. This could lead to differences in the packages. These differences may be useful to analyze to identify supply-chain attacks. See some discussion about idempotent rebuilds.
Our packages are all built from source code, unless we have not yet managed to build something. In the latter situation, Debian Taco falls back and uses the official Debian artifact. This allows an incremental publication of Debian Taco that still is 100% complete without requiring that everything is rebuilt instantly. The goal is that everything should be rebuilt, and until that has been completed, publish a list of artifacts that we use verbatim from Debian.
Debian Taco Container Images
The Debian Taco Container Images project provide container images of Debian Taco for trixie, forky and sid on the amd64, arm64, ppc64el and riscv64 architectures.
These images allow quick and simple use of Debian Taco interactively, but makes it easy to deploy for container orchestration frameworks.
Debian Taco Cloud Images
The Debian Taco Cloud Images project provide cloud images of Debian Taco for trixie, forky and sid on the amd64, arm64, ppc64el and riscv64 architectures.
Launch and install Debian Taco for your cloud environment!
Debian Taco Live Images
The Debian Taco Live Images project provide live images of Debian Taco for trixie, forky and sid on the amd64 and arm64 architectures.
These images allows running Debian Taco on physical hardware (or virtual machines), and even installation for permanent use.
Debian Taco Build Images and Packages
Packages are built using debdistbuild, which was introduced in a blog about Build Debian in a GitLab Pipeline.
The first step is to prepare build images, which is done by the Debian Taco Build Images project. They are similar to the Debian Taco containers but have build-essential and debdistbuild installed on them.
Debdistbuild is launched in a per-architecture per-suite CI/CD project. Currently only trixie-amd64 is available. That project has built some essential early packages like base-files, debian-archive-keyring and hostname. They are stored in Git LFS backed by a S3 object storage. These packages were all built reproducibly. So this means Debian Taco is still 100% bit-by-bit identical to Debian, except for the renaming.
I ve yet to launch a more massive wide-scale package rebuild until some outstanding issues have been resolved. I earlier rebuilt around 7000 packages from Trixie on amd64, so I know that the method easily scales.
Remaining work
Where is the diffoscope package outputs and list of package differences? For another holiday! Clearly this is an important remaining work item.
Another important outstanding issue is how to orchestrate launching the build of all packages. Clearly a list of packages is needed, and some trigger mechanism to understand when new packages are added to Debian.
One goal was to build packages from the tag2upload browse.dgit.debian.org archive, before checking the Debian Archive. This ought to be really simple to implement, but other matters came first.
GitLab or Codeberg?
Everything is written using basic POSIX /bin/sh shell scripts. Debian Taco uses the GitLab CI/CD Pipeline mechanism together with a Hetzner S3 object storage to serve packages. The scripts have only weak reliance on GitLab-specific principles, and were designed with the intention to support other platforms. I believe reliance on a particular CI/CD platform is a limitation, so I d like to explore shipping Debian Taco through a Forgejo-based architecture, possibly via Codeberg as soon as I manage to deploy reliable Forgejo runners.
The important aspects that are required are:
1) Pipelines that can build and publish web sites similar to GitLab Pages. Codeberg has a pipeline mechanism. I ve successfully used Codeberg Pages to publish the OATH Toolkit homepage homepage. Glueing this together seems feasible.
2) Container Registry. It seems Forgejo supports a Container Registry but I ve not worked with it at Codeberg to understand if there are any limitations.
3) Package Registry. The Deban Taco live images are uploaded into a package registry, because they are too big for being served through GitLab Pages. It may be converted to using a Pages mechanism, or possibly through Release Artifacts if multi-GB artifacts are supported on other platforms.
I hope to continue this work and explaining more details in a series of posts, stay tuned!
About 6 months ago I got a Nissan LEAF ZE1 (2019 model) [1]. Generally it s going well and I m happy with most things about it.
One issue is that as there isn t a lot of weight in the front with the batteries in the centre of the car the front wheels slip easily when accelerating. It s a minor thing but a good reason for wanting AWD in an electric car.
When I got the car I got two charging devices, the one to charge from a regular 240V 10A power point (often referred to as a granny charger ) and a cable with a special EV charging connector on each end. The cable with an EV connector on each end is designed for charging that s faster than the granny charger but not as fast as the rapid chargers which have the cable connected to the supply so the cable temperature can be monitored and/or controlled. That cable can be used if you get a fast charger setup at your home (which I never plan to do) and apparently at some small hotels and other places with home-style EV charging. I m considering just selling that cable on ebay as I don t think I have any need to personally own a cable other than the granny charger .
The key fob for the LEAF has a battery installed, it s either CR2032 or CR2025 mine has CR2025. Some reports on the Internet suggest that you can stuff a CR2032 battery in anyway but that didn t work for me as the thickness of the battery stopped some of the contacts from making a good connection. I think I could have got it going by putting some metal in between but the batteries aren t expensive enough to make it worth the effort and risk. It would be nice if I could use batteries from my stockpile of CR2032 batteries that came from old PCs but I can afford to spend a few dollars on it.
My driveway is short and if I left the charger out it would be visible from the street and at risk of being stolen. I m thinking of chaining the charger to a tree and having some sort of waterproof enclosure for it so I don t have to go to the effort of taking it out of the boot every time I use it. Then I could also configure the car to only charge during the peak sunlight hours when the solar power my home feeds into the grid has a negative price (we have so much solar power that it s causing grid problems).
The cruise control is a pain to use, so much so that I haven t yet got it to work usefully ever. The features look good in the documentation but in practice it s not as good as the Kia one I ve used previously where I could just press one button to turn it on, another button to set the current speed as the cruise control speed, and then just have it work.
The electronic compass built in to the dash turned out to be surprisingly useful. I regret not gluing a compass to the dash of previous cars. One example is when I start google navigation for a journey and it says go South on street X and I need to know which direction is South so I don t start in the wrong direction. Another example is when I know that I m North of a major road that I need to take to get to my destination so I just need to go roughly South and that is enough to get me to a road I recognise.
In the past when there is a bird in the way I don t do anything different, I keep driving at the same speed and rely on the bird to see me and move out of the way. Birds have faster reactions than humans and have evolved to move at the speeds cars travel on all roads other than freeways, also birds that are on roads are usually ones that have an eye in each side of their head so they can t not see my car approaching. For decades this has worked, but recently a bird just stood on the road and got squashed. So I guess that I should honk when there s birds on the road.
Generally everything about the car is fine and I m happy to keep driving it.
Welcome to the December 2025 from the Reproducible Builds project!
Our monthly reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.
New orig-check service to validate Debian upstream tarballs
This month, Debian Developer Lucas Nussbaum announced the orig-check service, which attempts to automatically reproduce the generation upstream tarballs (ie. the original source component of a Debian source package), comparing that to the upstream tarball actually shipped with Debian.
As of the time of writing, it is possible for a Debian developer to upload a source archive that does not actually correspond to upstream s version. Whilst this is not inherently malicious (it typically indicates some tooling/process issue), the very possibility that a maintainer s version may differ potentially permits a maintainer to make (malicious) changes that would be misattributed to upstream.
This service therefore nicely complements the whatsrc.org service, which was reported in our reports for both April and August. The orig-check is dedicated to Lunar, who sadly passed away a year ago.
disorderfs updated to FUSE 3
disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues.
This month, however, Roland Clobus upgraded disorderfs* from FUSE 2 to FUSE 3 after its package automatically got removed from Debian testing. Some tests in Debian currently require disorderfs to make the Debian live images reproducible, although disorderfs is not a Debian-specific tool.
Luca Di Maio announced stampdalf, a filesystem timestamp preservation tool that wraps arbitrary commands and ensures filesystem timestamp reproducibility :
stampdalf allows you to run any command that modifies files in a directory tree, then automatically resets all timestamps back to their original values. Any new files created during command execution are set to [the UNIX epoch] or a custom timestamp via SOURCE_DATE_EPOCH.
The project s GitHub page helpfully reveals that the project is pronounced: stamp-dalf (stamp like time-stamp, dalf like Gandalf the wizard) as it s a wizard of time and stamps .)
Lastly, Reproducible Builds developer cen1 posted to our list announcing that early/experimental/alpha support for FreeBSD was added to rebuilderd. In their post, cen1 reports that the initial builds are in progress and look quite decent . cen1 also interestingly notes that since the upstream is currently not technically reproducible I had to relax the bit-for-bit identical requirement of rebuilderd [ ] I consider the pkg to be reproducible if the tar is content-identical (via diffoscope), ignoring timestamps and some of the manifest files. .
Most package managers also generate a lockfile, which records the exact set of resolved dependency versions. Lockfiles are used to reduce build times; to verify the integrity of resolved packages; and to support build reproducibility across environments and time. Despite these beneficial features, developers often struggle with their maintenance, usage, and interpretation. In this study, we unveil the major challenges related to lockfiles, such that future researchers and engineers can address them. [ ]
While existing studies primarily focus on software supply chain attacks prevention and detection methods, there is a need for a broad overview of attacks and comprehensive risk assessment for software supply chain security. This study conducts a systematic literature review to fill this gap. By analyzing 96 papers published between 2015-2023, we identified 19 distinct SSC attacks, including 6 novel attacks highlighted in recent studies. Additionally, we developed 25 specific security controls and established a precisely mapped taxonomy that transparently links each control to one or more specific attacks. [ ]
[Achieving] reproducibility at scale remains difficult, especially in Java, due to a range of non-deterministic factors and caveats in the build process. In this work, we focus on reproducibility in Java-based software, archetypal of enterprise applications. We introduce a conceptual framework for reproducible builds, we analyze a large dataset from Reproducible Central, and we develop a novel taxonomy of six root causes of unreproducibility. [ ]
Robert Stupp made a number of useful changes, fixing and reorganising the Groovy / Kotlin pages [][][] as well adding a note about potential non-deterministic behaviour to the JVM page [].
Upstream patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
I'm not hanging around on IRC a lot these days, but when I do I used
hexchat (and xchat before). Probably a bad habbit of clinging to what I got used
to for the past 25 years. But in the light of the planned removal of
GTK2, it
felt like it was time to look for an alternative.
Halloy looked interesting, albeit not packaged for
Debian. But upstream references a flatpak (another party I did not
join so far), good enough to give it a try.
Configuration ends up at ~/.var/app/org.squidowl.halloy/config/halloy/config.toml, which
I linked for convenience to ~/.halloy.toml.
Since I connect via ZNC in an odd old setup without
those virtual networks, but several accounts, and of course never bothered to replace the
self signed certificate, it requires some additional configuration to be able to connect.
Each account gets its own servers.<foo> block like this:
[servers.bnc-oftc]
nickname = "my-znc-user-for-this-network"
server = "sven.stormbind.net"
dangerously_accept_invalid_certs = true
password = "mypasssowrd"
port = 4711
use_tls = true
Halloy has also a small ZNC guide.
I'm growing old, so a bigger font size is useful. Be aware that font changes require
an application restart to take effect.
[font]
size = 16
family = "Noto Mono"
I also prefer the single-pane mode which could
be copy & pasted as documented.
Works good enough for now. hexchat was also the last none wayland application I've been using
(xlsclients output is finally empty).
As a little disclaimer, I usually review books or articles written in
English, and although I will offer this review to Computing Reviews as
usual, it is likely it will not be published. The title of this book in
Spanish is Inteligencia artificial: jugar o romper la baraja.
I was pointed at this book, published last October by Margarita Padilla
Garc a, a well known Free Software activist from Spain who has long worked
on analyzing (and shaping) aspects of socio-technological change. As other
books published by Traficantes de sue os, this
book is published as Open Access, under a CC BY-NC license, and can be
downloaded in
full. I
started casually looking at this book, with too long a backlog of material
to read, but soon realized I could just not put it down: it completely
captured me.
This book presents several aspects of Artificial Intelligence (AI), written
for a general, non-technical audience. Many books with a similar target
have been published, but this one is quite unique; first of all, it is
written in a personal, non-formal tone. Contrary to what s usual in my
reading, the author made the explicit decision not to fill the book with
references to her sources ( because searching on Internet, it s very easy
to find things ), making the book easier to read linearly a decision I
somewhat regret, but recognize helps develop the author s style.
The book has seven sections, dealing with different aspects of AI. They are
the Visions (historical framing of the development of AI); Spectacular
(why do we feel AI to be so disrupting, digging particularly into game
engines and search space); Strategies , explaining how multilayer neural
networks work and linking the various branches of historic AI together,
arriving at Natural Language Processing; On the inside , tackling
technical details such as algorithms, the importance of training data,
bias, discrimination; On the outside , presenting several example AI
implementations with socio-ethical implications; Philosophy , presenting
the works of Marx, Heidegger and Simondon in their relation with AI, work,
justice, ownership; and Doing , presenting aspects of social activism in
relation to AI. Each part ends with yet another personal note: Margarita
Padilla includes a letter to one of her friends related to said part.
Totalling 272 pages (A5, or roughly half-letter, format), this is a rather
small book. I read it probably over a week. So, while this book does not
provide lots of new information to me, the way how it was written, made it
a very pleasing experience, and it will surely influence the way I
understand or explain several concepts in this domain.
 No man s Sky (or as it s known in our house, "spaceship game") is a space
exploration/sandbox game that was originally released 10 years ago. Back then I
tried it on my brother s PS4 but I couldn t get into it. In 2022 it launched
for the Nintendo Switch1 and the game finally clicked for me.
I play it very casually. I mostly don t play at all, except sometimes when
there are time-limited expeditions running, which I find refreshing, and
usually have some exclusives as a reward for play.
One of the many things you can do in the game is collect star ships. I started
keeping a list of notable ones I ve found, and I ve decided to occasionally
blog about them.

 Brunei entry stamp on my passport. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0.
 Our room in Brunei. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
 Jame Asr Hassanil Bolkiah Mosque. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
 Omar Ali Saifuddien Mosque. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
 A shot of Brunei s countryside. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0.


 The Debian LTS Team, funded by [Freexian s Debian LTS offering]
(
 Version 0.0.25 of


 A recent article in The Atlantic makes the case that

 If you care about supporting open source software, and still use MySQL in 2026, you should switch to MariaDB like so many others have already done.
The number of git commits on
 Due to newer MySQL versions deprecating many features, a lot of users also complained about significant struggles regarding both MySQL 5.7->8.0 and 8.0->8.4 upgrades. With few new features and heavy focus on code base cleanup and feature deprecation, it became obvious to many that Oracle had decided to just keep MySQL barely alive, and put all new relevant features (e.g. vector search) into Heatwave, Oracle s closed-source and cloud-only service for MySQL customers.
As it was evident that Oracle isn t investing in MySQL, Percona s Peter Zaitsev wrote
 In September 2025
 Team Rcpp is thrilled to share that an exciting new version 1.1.1 of
Rcpp is now on
 You can see that the edges are still not straight, because that's how they came out of the sawmill.
Once that was done I visited a family member that had a crosscut saw, a table saw and a band saw; all that I would need. First we trimmed the edges of the 2m planks
with the table saw so they were somewhat straight; then they were flipped and the other edge was cut straight, and their width cut down to 20 cm.
After moving them over to the crosscut saw dividing them into two 60 cm and one 80 cm was fairly easy. When cutting the 2m planks from the 4m ones I calculated with
extra offcuts, so I got little waste overall and could use the whole length to get my desired board.
This is what the cut pieces looked like:
 Assembly
I packed up my planks, now nicely cut to size, and I went to a hardware shop and bought hinges and screws.
Assembly was fairly easy and fast: screw a hinge to a corner, hold the other plank onto the hinge so that the corners of both boards touch, and affix the hinge.

 When this was done, the frame looked like this:
 As last step I drilled 10mm holes more or less random in the middle of the box. This is where the mushrooms will grow out of later and can be harvested.
 Closing thoughts
This was a fun project I finished in a day. The hinges have the benefit that they allow the box to
be folded up lenght-wise:
 This allows for convenient storage. Since it's too cold outside right now, cultivation will have to wait
until spring. This also just needs mycelium one can just buy, and some material fungus digests.
They can also be fed coffee grounds, and harvest of the fruit body is possible circa every two weeks.