Search Results: "reg"

5 August 2025

Matthew Garrett: Cordoomceps - replacing an Amiga's brain with Doom

There's a lovely device called a pistorm, an adapter board that glues a Raspberry Pi GPIO bus to a Motorola 68000 bus. The intended use case is that you plug it into a 68000 device and then run an emulator that reads instructions from hardware (ROM or RAM) and emulates them. You're still limited by the ~7MHz bus that the hardware is running at, but you can run the instructions as fast as you want.

These days you're supposed to run a custom built OS on the Pi that just does 68000 emulation, but initially it ran Linux on the Pi and a userland 68000 emulator process. And, well, that got me thinking. The emulator takes 68000 instructions, emulates them, and then talks to the hardware to implement the effects of those instructions. What if we, well, just don't? What if we just run all of our code in Linux on an ARM core and then talk to the Amiga hardware?

We're going to ignore x86 here, because it's weird - but most hardware that wants software to be able to communicate with it maps itself into the same address space that RAM is in. You can write to a byte of RAM, or you can write to a piece of hardware that's effectively pretending to be RAM[1]. The Amiga wasn't unusual in this respect in the 80s, and to talk to the graphics hardware you speak to a special address range that gets sent to that hardware instead of to RAM. The CPU knows nothing about this. It just indicates it wants to write to an address, and then sends the data.

So, if we are the CPU, we can just indicate that we want to write to an address, and provide the data. And those addresses can correspond to the hardware. So, we can write to the RAM that belongs to the Amiga, and we can write to the hardware that isn't RAM but pretends to be. And that means we can run whatever we want on the Pi and then access Amiga hardware.

And, obviously, the thing we want to run is Doom, because that's what everyone runs in fucked up hardware situations.

Doom was Amiga kryptonite. Its entire graphical model was based on memory directly representing the contents of your display, and being able to modify that by just moving pixels around. This worked because at the time VGA displays supported having a memory layout where each pixel on your screen was represented by a byte in memory containing an 8 bit value that corresponded to a lookup table containing the RGB value for that pixel.

The Amiga was, well, not good at this. Back in the 80s, when the Amiga hardware was developed, memory was expensive. Dedicating that much RAM to the video hardware was unthinkable - the Amiga 1000 initially shipped with only 256K of RAM, and you could fill all of that with a sufficiently colourful picture. So instead of having the idea of each pixel being associated with a specific area of memory, the Amiga used bitmaps. A bitmap is an area of memory that represents the screen, but only represents one bit of the colour depth. If you have a black and white display, you only need one bitmap. If you want to display four colours, you need two. More colours, more bitmaps. And each bitmap is stored in an independent area of RAM. You never use more memory than you need to display the number of colours you want to.

But that means that each bitplane contains packed information - every byte of data in a bitplane contains the bit value for 8 different pixels, because each bitplane contains one bit of information per pixel. To update one pixel on screen, you need to read from every bitmap, update one bit, and write it back, and that's a lot of additional memory accesses. Doom, but on the Amiga, was slow not just because the CPU was slow, but because there was a lot of manipulation of data to turn it into the format the Amiga wanted and then push that over a fairly slow memory bus to have it displayed.

The CDTV was an aesthetically pleasing piece of hardware that absolutely sucked. It was an Amiga 500 in a hi-fi box with a caddy-loading CD drive, and it ran software that was just awful. There's no path to remediation here. No compelling apps were ever released. It's a terrible device. I love it. I bought one in 1996 because a local computer store had one and I pointed out that the company selling it had gone bankrupt some years earlier and literally nobody in my farming town was ever going to have any interest in buying a CD player that made a whirring noise when you turned it on because it had a fan and eventually they just sold it to me for not much money, and ever since then I wanted to have a CD player that ran Linux and well spoiler 30 years later I'm nearly there. That CDTV is going to be our test subject. We're going to try to get Doom running on it without executing any 68000 instructions.

We're facing two main problems here. The first is that all Amigas have a firmware ROM called Kickstart that runs at powerup. No matter how little you care about using any OS functionality, you can't start running your code until Kickstart has run. This means even documentation describing bare metal Amiga programming assumes that the hardware is already in the state that Kickstart left it in. This will become important later. The second is that we're going to need to actually write the code to use the Amiga hardware.

First, let's talk about Amiga graphics. We've already covered bitmaps, but for anyone used to modern hardware that's not the weirdest thing about what we're dealing with here. The CDTV's chipset supports a maximum of 64 colours in a mode called "Extra Half-Brite", or EHB, where you have 32 colours arbitrarily chosen from a palette and then 32 more colours that are identical but with half the intensity. For 64 colours we need 6 bitplanes, each of which can be located arbitrarily in the region of RAM accessible to the chipset ("chip RAM", distinguished from "fast ram" that's only accessible to the CPU). We tell the chipset where our bitplanes are and it displays them. Or, well, it does for a frame - after that the registers that pointed at our bitplanes no longer do, because when the hardware was DMAing through the bitplanes to display them it was incrementing those registers to point at the next address to DMA from. Which means that every frame we need to set those registers back.

Making sure you have code that's called every frame just to make your graphics work sounds intensely irritating, so Commodore gave us a way to avoid doing that. The chipset includes a coprocessor called "copper". Copper doesn't have a large set of features - in fact, it only has three. The first is that it can program chipset registers. The second is that it can wait for a specific point in screen scanout. The third (which we don't care about here) is that it can optionally skip an instruction if a certain point in screen scanout has already been reached. We can write a program (a "copper list") for the copper that tells it to program the chipset registers with the locations of our bitplanes and then wait until the end of the frame, at which point it will repeat the process. Now our bitplane pointers are always valid at the start of a frame.

Ok! We know how to display stuff. Now we just need to deal with not having 256 colours, and the whole "Doom expects pixels" thing. For the first of these, I stole code from ADoom, the only Amiga doom port I could easily find source for. This looks at the 256 colour palette loaded by Doom and calculates the closest approximation it can within the constraints of EHB. ADoom also includes a bunch of CPU-specific assembly optimisation for converting the "chunky" Doom graphic buffer into the "planar" Amiga bitplanes, none of which I used because (a) it's all for 68000 series CPUs and we're running on ARM, and (b) I have a quad core CPU running at 1.4GHz and I'm going to be pushing all the graphics over a 7.14MHz bus, the graphics mode conversion is not going to be the bottleneck here. Instead I just wrote a series of nested for loops that iterate through each pixel and update each bitplane and called it a day. The set of bitplanes I'm operating on here is allocated on the Linux side so I can read and write to them without being restricted by the speed of the Amiga bus (remember, each byte in each bitplane is going to be updated 8 times per frame, because it holds bits associated with 8 pixels), and then copied over to the Amiga's RAM once the frame is complete.

And, kind of astonishingly, this works! Once I'd figured out where I was going wrong with RGB ordering and which order the bitplanes go in, I had a recognisable copy of Doom running. Unfortunately there were weird graphical glitches - sometimes blocks would be entirely the wrong colour. It took me a while to figure out what was going on and then I felt stupid. Recording the screen and watching in slow motion revealed that the glitches often showed parts of two frames displaying at once. The Amiga hardware is taking responsibility for scanning out the frames, and the code on the Linux side isn't synchronised with it at all. That means I could update the bitplanes while the Amiga was scanning them out, resulting in a mashup of planes from two different Doom frames being used as one Amiga frame. One approach to avoid this would be to tie the Doom event loop to the Amiga, blocking my writes until the end of scanout. The other is to use double-buffering - have two sets of bitplanes, one being displayed and the other being written to. This consumes more RAM but since I'm not using the Amiga RAM for anything else that's not a problem. With this approach I have two copper lists, one for each set of bitplanes, and switch between them on each frame. This improved things a lot but not entirely, and there's still glitches when the palette is being updated (because there's only one set of colour registers), something Doom does rather a lot, so I'm going to need to implement proper synchronisation.

Except. This was only working if I ran a 68K emulator first in order to run Kickstart. If I tried accessing the hardware without doing that, things were in a weird state. I could update the colour registers, but accessing RAM didn't work - I could read stuff out, but anything I wrote vanished. Some more digging cleared that up. When you turn on a CPU it needs to start executing code from somewhere. On modern x86 systems it starts from a hardcoded address of 0xFFFFFFF0, which was traditionally a long way any RAM. The 68000 family instead reads its start address from address 0x00000004, which overlaps with where the Amiga chip RAM is. We can't write anything to RAM until we're executing code, and we can't execute code until we tell the CPU where the code is, which seems like a problem. This is solved on the Amiga by powering up in a state where the Kickstart ROM is "overlayed" onto address 0. The CPU reads the start address from the ROM, which causes it to jump into the ROM and start executing code there. Early on, the code tells the hardware to stop overlaying the ROM onto the low addresses, and now the RAM is available. This is poorly documented because it's not something you need to care if you execute Kickstart which every actual Amiga does and I'm only in this position because I've made poor life choices, but ok that explained things. To turn off the overlay you write to a register in one of the Complex Interface Adaptor (CIA) chips, and things start working like you'd expect.

Except, they don't. Writing to that register did nothing for me. I assumed that there was some other register I needed to write to first, and went to the extent of tracing every register access that occurred when running the emulator and replaying those in my code. Nope, still broken. What I finally discovered is that you need to pulse the reset line on the board before some of the hardware starts working - powering it up doesn't put you in a well defined state, but resetting it does.

So, I now have a slightly graphically glitchy copy of Doom running without any sound, displaying on an Amiga whose brain has been replaced with a parasitic Linux. Further updates will likely make things even worse. Code is, of course, available.

[1] This is why we had trouble with late era 32 bit systems and 4GB of RAM - a bunch of your hardware wanted to be in the same address space and so you couldn't put RAM there so you ended up with less than 4GB of RAM

comment count unavailable comments

Michael Ablassmeier: PVE 9.0 - Snapshots for LVM

The new Proxmox release advertises a new feature for easier snapshot handling of virtual machines whose disks are stored on LVM volumes, I wondered.. whats the deal..? To be able to use the new feature, you need to enable a special flag for the LVM volume group. This example shows the general workflow for a fresh setup. 1) Create the volume group with the snapshot-as-volume-chain feature turned on:
 pvesm add lvm lvmthick --content images --vgname lvm --snapshot-as-volume-chain 1
2) From this point on, you can create virtual machines right away, BUT those virtual machines disks must use the QCOW image format for their disk volumes. If you use the RAW format, you wont be able to create snapshots, still.
 VMID=401
 qm create $VMID --name vm-lvmthick
 qm set $VMID -scsi1 lvmthick:2,format=qcow2
So, why would it make sense to format the LVM volume as QCOW? Snapshots on LVM thick provisioned devices are, as everybody knows, a very I/O intensive task. Besides each snapshot, a special -cow Device is created that tracks the changed block regions and the original block data for each change to the active volume. This will waste quite some space within your volume group for each snapshot. Formatting the LVM volume as QCOW image, makes it possible to use the QCOW backing-image option for these devices, this is the way PVE 9 handles these kind of snapshots. Creating a snapshot looks like this:
 qm snapshot $VMID id
 snapshotting 'drive-scsi1' (lvmthick3:vm-401-disk-0.qcow2)
 Renamed "vm-401-disk-0.qcow2" to "snap_vm-401-disk-0_id.qcow2" in volume group "lvm"
 Rounding up size to full physical extent 1.00 GiB
 Logical volume "vm-401-disk-0.qcow2" created.
 Formatting '/dev/lvm/vm-401-disk-0.qcow2', fmt=qcow2 cluster_size=131072 extended_l2=on preallocation=metadata compression_type=zlib size=1073741824 backing_file=snap_vm-401-disk-0_id.qcow2 backing_fmt=qcow2 lazy_refcounts=off refcount_bits=16
So it will rename the current active disk and create another QCOW formatted LVM volume, but pointing it to the snapshot image using the backing_file option. Neat.

3 August 2025

Ben Hutchings: FOSS activity in July 2025

In July I attended DebCamp and DebConf in Brest, France. I very much enjoyed the opportunity to reconnect with other Debian contributors in person. I had a number of interesting and fruitful conversations there, besides the formally organised BoFs and talks. I also gave my own talk on What s new in the Linux kernel (and what s missing in Debian). Here s the usual categorisation of activity:

2 August 2025

Russell Coker: Server CPU Sockets

I am always looking for ways of increasing the compute power I have at a reasonable price. I am very happy with my HP z840 dual CPU workstation [1] that I m using as a server and my HP z640 single CPU workstation [2]. Both of them were available second hand at quite reasonable prices and could be cheaply upgraded to faster CPUs. But if I can get something a lot faster for a reasonable price then I ll definitely get it. Socket LGA2011-v3 The home server and home workstation I currently use have socket LGA2011-v3 [3] which supports the E5-2699A v4 CPU which gives a rating of 26,939 according to Passmark [4]. That Passmark score is quite decent, you can get CPUs using DDR4 RAM that go up to almost double that but it s a reasonable speed and it works in systems that are readily available at low prices. The z640 is regularly on sale for less than $400AU and the z840 is occasionally below $600. The Dell PowerEdge T430 is an ok dual-CPU tower server using the same socket. One thing that s not well known is that is it limited to something like 135W per CPU when run with two CPUs. So it will work correctly with a single E5-2697A v4 with 145W TDP (I ve tested that) but will refuse to boot with two of them. In my test system I tried replacing the 495W PSUs with 750W PSUs and it made no difference, the motherboard has the limit. With only a single CPU you only get 8/12 DIMM sockets and not all PCIe slots work. There are many second hand T430s on sale with only a single CPU presumably because the T330 sucks. My T430 works fine with a pair of E5-2683 v4 CPUs. The Dell PowerEdge T630 also takes the same CPUs but supports higher TDP than the T430. They also support 18*3.5 disks or 32*2.5 but they are noisy. I wouldn t buy one for home use. AMD There are some nice AMD CPUs manufactured around the same time and AMD has done a better job of making multiple CPUs that fit the same socket. The reason I don t generally use AMD CPUs is that they are used in a minority of the server grade systems so as I want ECC RAM and other server features I generally can t find AMD systems at a reasonable price on ebay etc. There are people who really want second hand server grade systems with AMD CPUs and outbid me. This is probably a region dependent issue, maybe if I was buying in the US I could get some nice workstations with AMD CPUs at low prices. Socket LGA1151 Socket LGA1151 [5] is used in the Dell PowerEdge T330. It only supports 2 memory channels and 4 DIMMs compared to the 4 channels and 8 DIMMs in LGA2011, and it also has a limit of 64G total RAM for most systems and 128G for some systems. By today s standards even 128G is a real limit for server use, DDR4 RDIMMs are about $1/GB and when spending $600+ on system and CPU upgrade you wouldn t want to spend less than $130 on RAM. The CPUs with decent performance for that socket like the i9-9900K aren t supported by the T330 (possibly they don t support ECC RAM). The CPUs that Dell supports perform very poorly. I suspect that Dell deliberately nerfed the T330 to drive sales of the T430. The Lenovo P330 uses socket LGA1151-2 but has the same issues of taking slow CPUs in addition to using UDIMMs which are significantly more expensive on the second hand market. Socket LGA2066 The next Intel socket after LGA2011-v3 is LGA2066 [6]. That is in The Dell Precision 5820 and HP Z4 G4. It takes an i9-10980XE for 32,404 on Passmark or a W-2295 for 30,906. The variant of the Dell 5820 that supports the i9 CPUs doesn t seem to support ECC RAM so it s not a proper workstation. The single thread performance difference between the W-2295 and the E5-2699A v4 is 2640 to 2055, a 28% increase for the W-2295. There are High Frequency Optimized cpus for socket LGA2011-v3 but they all deliver less than 2,300 on the Passmark single-thread tests which is much less than what you can get from socket LGA2066. The W-2295 costs $1000 on ebay and the E5-2699A v4 is readily available for under $400 and a few months ago I got a matched pair for a bit over $400. Note that getting a matched pair of Intel CPUs is a major pain [7]. Comparing sockets LGA2011-v3 and LGA2066 for a single-CPU system is a $300 system (HP x640) + $400 CPU (E5-2699A v4) vs $500 system (Dell Precision 5820) + $1000 CPU (W-2295), so more than twice the price for a 30% performance benefit on some tasks. The LGA2011-v3 and USB-C both launched in 2014 so LGA2011-v3 systems don t have USB-C sockets, a $20 USB-C PCIe card doesn t change the economics. Socket LGA3647 Socket LGA3647 [8] is used in the Dell PowerEdge T440. It supports 6 channels of DDR4 RAM which is a very nice feature for bigger systems. According to one Dell web page the best CPU Dell officially supports for this is the Xeon Gold 5120 which gives performance only slightly better than the E5-2683 v4 which has a low enough TDP that a T430 can run two of them. But according to another Dell web page they support 16 core CPUs which means performance better than a T430 but less than a HP z840. The T440 doesn t seem like a great system, if I got one cheap I could find a use for it but I wouldn t pay the prices that they go for on ebay. The Dell PowerEdge T640 has the same socket and is described as supporting up to 28 core CPUs. But I anticipate that it would be as loud as the T630 and it s also expensive. This socket is also used in the HP Z6 G4 which takes a W-3265 or Xeon Gold 6258R CPU for the high end options. The HP Z6 G4 systems on ebay are all above $1500 and the Xeon Gold 6258R is also over $1000 so while the Xeon Gold 6258R in a Z6 G4 will give 50% better performance on multithreaded operations than the systems I currently have it s costing almost 3* as much. It has 6 DIMM sockets which is a nice improvement over the 4 in the z640. The Z6 G4 takes a maximum of 768G of RAM with the optional extra CPU board (which is very expensive both new and on ebay) compared to my z840 which has 512G and half it s DIMM slots empty. The HP Z8 G4 has the same socket and takes up to 3TB of RAM if used with CPUs that support it (most CPUs only support 768G and you need a M variant to support more). The higher performance CPUs supported in the Z6 G4 and Z8 G4 don t have enough entries in the Passmark database to be accurate, but going from 22 cores in the E5-2699A v4 to 28 in the Xeon Platinum 8180 when using the same RAM technology doesn t seem like a huge benefit. The Z6 and Z8 G4 systems run DDR4 RAM at up to 2666 speed while the z640 and z840 only to 2400, a 10% increase in RAM speed is nice but not a huge difference. I don t think that any socket LGA3647 systems will ever be ones I want to buy. They don t offer much over LGA2011-v3 but are in newer and fancier systems that will go for significantly higher prices. DDR5 I think that DDR5 systems will be my next step up in tower server and workstation performance after the socket LGA2011-v3 systems. I don t think anything less will offer me enough of a benefit to justify a change. I also don t think that they will be in the price range I am willing to pay until well after DDR6 is released, some people are hoping for DDR6 to be released late this year but next year seems more likely. So maybe in 2027 there will be some nice DDR5 systems going cheap. CPU Benchmark Results Here are the benchmark results of CPUs I mentioned in this post according to passmark.com [9]. I didn t reference results of CPUs that only had 1 or 2 results posted as they aren t likely to be accurate.
CPU Single Thread Multi Thread TDP
E5-2683 v4 1,713 17,591 120W
Xeon Gold 5120 1,755 18,251 105W
i9-9900K 2,919 18,152 95W
E5-2697A v4 2,106 21,610 145W
E5-2699A v4 2,055 26,939 145W
W-3265 2,572 30,105 205W
W-2295 2,642 30,924 165W
i9-10980XE 2,662 32,397 165W
Xeon Gold 6258R 2,080 40,252 205W

1 August 2025

Sergio Cipriano: How I deployed this Website

How I deployed this Website I will describe the step-by-step process I followed to make this static website accessible on the Internet.

DNS I bought this domain on NameCheap and am using their DNS for now, where I created these records:
Record Type Host Value
A sergiocipriano.com 201.54.0.17
CNAME www sergiocipriano.com

Virtual Machine I am using Magalu Cloud for hosting my VM, since employees have free credits. Besides creating a VM with a public IP, I only needed to set up a Security Group with the following rules:
Type Protocol Port Direction CIDR
IPv4 / IPv6 TCP 80 IN Any IP
IPv4 / IPv6 TCP 443 IN Any IP

Firewall The first thing I did in the VM was enabling ufw (Uncomplicated Firewall). Enabling ufw without pre-allowing SSH is a common pitfall and can lock you out of your VM. I did this once :) A safe way to enable ufw:
$ sudo ufw allow OpenSSH      # or: sudo ufw allow 22/tcp
$ sudo ufw allow 'Nginx Full' # or: sudo ufw allow 80,443/tcp
$ sudo ufw enable
To check if everything is ok, run:
$ sudo ufw status verbose
Status: active
Logging: on (low)
Default: deny (incoming), allow (outgoing), disabled (routed)
New profiles: skip
To                           Action      From
--                           ------      ----
22/tcp (OpenSSH)             ALLOW IN    Anywhere                  
80,443/tcp (Nginx Full)      ALLOW IN    Anywhere                  
22/tcp (OpenSSH (v6))        ALLOW IN    Anywhere (v6)             
80,443/tcp (Nginx Full (v6)) ALLOW IN    Anywhere (v6) 

Reverse Proxy I'm using Nginx as the reverse proxy. Since I use the Debian package, I just needed to add this file:
/etc/nginx/sites-enabled/sergiocipriano.com
with this content:
server  
    listen 443 ssl;      # IPv4
    listen [::]:443 ssl; # IPv6
    server_name sergiocipriano.com www.sergiocipriano.com;
    root /path/to/website/sergiocipriano.com;
    index index.html;
    location /  
        try_files $uri /index.html;
     
 
server  
    listen 80;
    listen [::]:80;
    server_name sergiocipriano.com www.sergiocipriano.com;
    # Redirect all HTTP traffic to HTTPS
    return 301 https://$host$request_uri;
 

TLS It's really easy to setup TLS thanks to Let's Encrypt:
$ sudo apt-get install certbot python3-certbot-nginx
$ sudo certbot install --cert-name sergiocipriano.com
Saving debug log to /var/log/letsencrypt/letsencrypt.log
Deploying certificate
Successfully deployed certificate for sergiocipriano.com to /etc/nginx/sites-enabled/sergiocipriano.com
Successfully deployed certificate for www.sergiocipriano.com to /etc/nginx/sites-enabled/sergiocipriano.com
Certbot will edit the nginx configuration with the path to the certificate.

HTTP Security Headers I decided to use wapiti, which is a web application vulnerability scanner, and the report found this problems:
  1. CSP is not set
  2. X-Frame-Options is not set
  3. X-XSS-Protection is not set
  4. X-Content-Type-Options is not set
  5. Strict-Transport-Security is not set
I'll explain one by one:
  1. The Content-Security-Policy header prevents XSS and data injection by restricting sources of scripts, images, styles, etc.
  2. The X-Frame-Options header prevents a website from being embedded in iframes (clickjacking).
  3. The X-XSS-Protection header is deprecated. It is recommended that CSP is used instead of XSS filtering.
  4. The X-Content-Type-Options header stops MIME-type sniffing to prevent certain attacks.
  5. The Strict-Transport-Security header informs browsers that the host should only be accessed using HTTPS, and that any future attempts to access it using HTTP should automatically be upgraded to HTTPS. Additionally, on future connections to the host, the browser will not allow the user to bypass secure connection errors, such as an invalid certificate. HSTS identifies a host by its domain name only.
I added this security headers inside the HTTPS and HTTP server block, outside the location block, so they apply globally to all responses. Here's how the Nginx config look like:
add_header Content-Security-Policy "default-src 'self'; style-src 'self';" always;
add_header X-Frame-Options "DENY" always;
add_header X-Content-Type-Options "nosniff" always;
add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
I added always to ensure that nginx sends the header regardless of the response code. To add Content-Security-Policy header I had to move the css to a separate file, because browsers block inline styles under strict CSP unless you allow them explicitly. They're considered unsafe inline unless you move to a separate file and link it like this:
<link rel="stylesheet" href="./resources/header.css">

puer-robustus: My Google Summer of Code '25 at Debian

I ve participated in this year s Google Summer of Code (GSoC) program and have been working on the small (90h) autopkgtests for the rsync package project at Debian.

Writing my proposal Before you can start writing a proposal, you need to select an organization you want to work with. Since many organizations participate in GSoC, I ve used the following criteria to narrow things down for me:
  • Programming language familiarity: For me only Python (preferably) as well as shell and Go projects would have made sense. While learning another programming language is cool, I wouldn t be as effective and helpful to the project as someone who is proficient in the language already.
  • Standing of the organization: Some of the organizations participating in GSoC are well-known for the outstanding quality of the software they produce. Debian is one of them, but so is e.g. the Django Foundation or PostgreSQL. And my thinking was that the higher the quality of the organization, the more there is to learn for me as a GSoC student.
  • Mentor interactions: Apart from the advantage you get from mentor feedback when writing your proposal (more on that further below), it is also helpful to gauge how responsive/helpful your potential mentor is during the application phase. This is important since you will be working together for a period of at least 2 months; if the mentor-student communication doesn t work, the GSoC project is going to be difficult.
  • Free and Open-Source Software (FOSS) communication platforms: I generally believe that FOSS projects should be built on FOSS infrastructure. I personally won t run proprietary software when I want to contribute to FOSS in my spare time.
  • Be a user of the project: As Eric S. Raymond has pointed out in his seminal The Cathedral and the Bazaar 25 years ago
    Every good work of software starts by scratching a developer s personal itch.
Once I had some organizations in mind whose projects I d be interested in working on, I started writing proposals for them. Turns out, I started writing my proposals way too late: In the end I only managed to hand in a single one which is risky. Competition for the GSoC projects is fierce and the more quality (!) proposals you send out, the better your chances are at getting one. However, don t write proposals for the sake of it: Reviewers get way too many AI slop proposals already and you will not do yourself a favor with a low-quality proposal. Take the time to read the instructions/ideas/problem descriptions the project mentors have provided and follow their guidelines. Don t hesitate to reach out to project mentors: In my case, I ve asked Samuel Henrique a few clarification questions whereby the following (email) discussion has helped me greatly in improving my proposal. Once I ve finalized my proposal draft, I ve sent it to Samuel for a review, which again led to some improvements to the final proposal which I ve uploaded to the GSoC program webpage.

Community bonding period Once you get the information that you ve been accepted into the GSoC program (don t take it personally if you don t make it; this was my second attempt after not making the cut in 2024), get in touch with your prospective mentor ASAP. Agree upon a communication channel and some response times. Put yourself in the loop for project news and discussions whatever that means in the context of your organization: In Debian s case this boiled down to subscribing to a bunch of mailing lists and IRC channels. Also make sure to setup a functioning development environment if you haven t done so for writing the proposal already.

Payoneer setup The by far most annoying part of GSoC for me. But since you don t have a choice if you want to get the stipend, you will need to signup for an account at Payoneer. In this iteration of GSoC all participants got a personalized link to open a Payoneer account. When I tried to open an account by following this link, I got an email after the registration and email verification that my account is being blocked because Payoneer deems the email adress I gave a temporary one. Well, the email in question is most certainly anything but temporary, so I tried to get in touch with the Payoneer support - and ended up in an LLM-infused kafkaesque support hell. Emails are answered by an LLM which for me meant utterly off-topic replies and no help whatsoever. The Payoneer website offers a real-time chat, but it is yet another instance of a bullshit-spewing LLM bot. When I at last tried to call them (the support lines are not listed on the Payoneer website but were provided by the GSoC program), I kid you not, I was being told that their platform is currently suffering from technical problems and was hung up on. Only thanks to the swift and helpful support of the GSoC administrators (who get priority support from Payoneer) I was able to setup a Payoneer account in the end. Apart from showing no respect to customers, Payoneer is also ripping them off big time with fees (unless you get paid in USD). They charge you 2% for currency conversions to EUR on top of the FX spread they take. What worked for me to avoid all of those fees, was to open a USD account at Wise and have Payoneer transfer my GSoC stipend in USD to that account. Then I exchanged the USD to my local currency at Wise for significantly less than Payoneer would have charged me. Also make sure to close your Payoneer account after the end of GSoC to avoid their annual fee.

Project work With all this prelude out of the way, I can finally get to the actual work I ve been doing over the course of my GSoC project.

Background The upstream rsync project generally sees little development. Nonetheless, they released version 3.4.0 including some CVE fixes earlier this year. Unfortunately, their changes broke the -H flag. Now, Debian package maintainers need to apply those security fixes to the package versions in the Debian repositories; and those are typically a bit older. Which usually means that the patches cannot be applied as is but will need some amendments by the Debian maintainers. For these cases it is helpful to have autopkgtests defined, which check the package s functionality in an automated way upon every build. The question then is, why should the tests not be written upstream such that regressions are caught in the development rather than the distribution process? There s a lot to say on this question and it probably depends a lot on the package at hand, but for rsync the main benefits are twofold:
  1. The upstream project mocks the ssh connection over which rsync is most typically used. Mocking is better than nothing but not the real thing. In addition to being a more realisitic test scenario for the typical rsync use case, involving an ssh server in the test would automatically extend the overall resilience of Debian packages as now new versions of the openssh-server package in Debian benefit from the test cases in the rsync reverse dependency.
  2. The upstream rsync test framework is somewhat idiosyncratic and difficult to port to reimplementations of rsync. Given that the original rsync upstream sees little development, an extensive test suit further downstream can serve as a threshold for drop-in replacements for rsync.

Goal(s) At the start of the project, the Debian rsync package was just running (a part of) the upstream tests as autopkgtests. The relevant snippet from the build log for the rsync_3.4.1+ds1-3 package reads:
114s ------------------------------------------------------------
114s ----- overall results:
114s 36 passed
114s 7 skipped
Samuel and I agreed that it would be a good first milestone to make the skipped tests run. Afterwards, I should write some rsync test cases for local calls, i.e. without an ssh connection, effectively using rsync as a more powerful cp. And once that was done, I should extend the tests such that they run over an active ssh connection. With these milestones, I went to work.

Upstream tests Running the seven skipped upstream tests turned out to be fairly straightforward:
  • Two upstream tests concern access control lists and extended filesystem attributes. For these tests to run they rely on functionality provided by the acl and xattr Debian packages. Adding those to the Build-Depends list in the debian/control file of the rsync Debian package repo made them run.
  • Four upstream tests required root privileges to run. The autopkgtest tool knows the needs-root restriction for that reason. However, Samuel and I agreed that the tests should not exclusively run with root privileges. So, instead of just adding the restiction to the existing autopkgtest test, we created a new one which has the needs-root restriction and runs the upstream-tests-as-root script - which is nothing else than a symlink to the existing upstream-tests script.
The commits to implement these changes can be found in this merge request. The careful reader will have noticed that I only made 2 + 4 = 6 upstream test cases run out of 7: The leftover upstream test is checking the functionality of the --ctimes rsync option. In the context of Debian, the problem is that the Linux kernel doesn t have a syscall to set the creation time of a file. As long as that is the case, this test will always be skipped for the Debian package.

Local tests When it came to writing Debian specific test cases I started of a completely clean slate. Which is a blessing and a curse at the same time: You have full flexibility but also full responsibility. There were a few things to consider at this point in time:
  • Which language to write the tests in? The programming language I am most proficient in is Python. But testing a CLI tool in Python would have been weird: it would have meant that I d have to make repeated subprocess calls to run rsync and then read from the filesystem to get the file statistics I want to check. Samuel suggested I stick with shell scripts and make use of diffoscope - one of the main tools used and maintained by the Reproducible Builds project - to check whether the file contents and file metadata are as expected after rsync calls. Since I did not have good reasons to use bash, I ve decided to write the scripts to be POSIX compliant.
  • How to avoid boilerplate? If one makes use of a testing framework, which one? Writing the tests would involve quite a bit of boilerplate, mostly related to giving informative output on and during the test run, preparing the file structure we want to run rsync on, and cleaning the files up after the test has run. It would be very repetitive and in violation of DRY to have the code for this appear in every test. Good testing frameworks should provide convenience functions for these tasks. shunit2 comes with those functions, is packaged for Debian, and given that it is already being used in the curl project, I decided to go with it.
  • Do we use the same directory structure and files for every test or should every test have an individual setup? The tradeoff in this question being test isolation vs. idiosyncratic code. If every test has its own setup, it takes a) more work to write the test and b) more work to understand the differences between tests. However, one can be sure that changes to the setup in one test will have no side effects on other tests. In my opinion, this guarantee was worth the additional effort in writing/reading the tests.
Having made these decisions, I simply started writing tests and ran into issues very quickly.

rsync and subsecond mtime diffs When testing the rsync --times option, I observed a weird phenomenon: If the source and destination file have modification times which differ only in the nanoseconds, an rsync --times call will not synchronize the modification times. More details about this behavior and examples can be found in the upstream issue I raised. In the Debian tests we had to occasionally work around this by setting the timestamps explicitly with touch -d.
diffoscope regression In one test case, I was expecting a difference in the modification times but diffoscope would not report a diff. After a good amount of time spent on debugging the problem (my default, and usually correct, assumption is that something about my code is seriously broken if I run into issues like that), I was able to show that diffoscope only displayed this behavior in the version in the unstable suite, not on Debian stable (which I am running on my development machine). Since everything pointed to a regression in the diffoscope project and with diffoscope being written in Python, a language I am familiar with, I wanted to spend some time investigating (and hopefully fixing) the problem. Running git bisect on the diffoscope repo helped me in identifying the commit which introduced the regression: The commit contained an optimization via an early return for bit-by-bit identical files. Unfortunately, the early return also caused an explicitly requested metadata comparison (which could be different between the files) to be skipped. With a nicely diagnosed issue like that, I was able to go to a local hackerspace event, where people work on FOSS together for an evening every month. In a group, we were able to first, write a test which showcases the broken behavior in the latest diffoscope version, and second, make a fix to the code such that the same test passes going forward. All details can be found in this merge request.
shunit2 failures At some point I had a few autopkgtests setup and passing, but adding a new one would throw me totally inexplicable errors. After trying to isolate the problem as much as possible, it turns out that shunit2 doesn t play well together we the -e shell option. The project mentions this in the release notes for the 2.1.8 version1, but in my opinion a constraint this severe should be featured much more prominently, e.g. in the README.

Tests over an ssh connection The centrepiece of this project; everything else has in a way only been preparation for this. Obviously, the goal was to reuse the previously written local tests in some way. Not only because lazy me would have less work to do this way, but also because of a reduced long-term maintenance burden of one rather than two test sets. As it turns out, it is actually possible to accomplish that: The remote-tests script doesn t do much apart from starting an ssh server on localhost and running the local-tests script with the REMOTE environment variable set. The REMOTE environment variable changes the behavior of the local-tests script in such a way that it prepends "$REMOTE": to the destination of the rsync invocations. And given that we set REMOTE=rsync@localhost in the remote-tests script, local-tests copies the files to the exact same locations as before, just over ssh. The implementational details for this can be found in this merge request.

proposed-updates Most of my development work on the Debian rsync package took place during the Debian freeze as the release of Debian Trixie is just around the corner. This means that uploading by Debian Developers (DD) and Debian Maintainers (DM) to the unstable suite is discouraged as it makes migrating the packages to testing more difficult for the Debian release team. If DDs/DMs want to have the package version in unstable migrated to testing during the freeze they have to file an unblock request. Samuel has done this twice (1, 2) for my work for Trixie but has asked me to file the proposed-updates request for current stable (i.e. Debian Bookworm) myself after I ve backported my tests to bookworm.

Unfinished business To run the upstream tests which check access control list and extended file system attributes functionality, I ve added the acl and xattr packages to Build-Depends in debian/control. This, however, will only make the packages available at build time: If Debian users install the rsync package, the acl and xattr packages will not be installed alongside it. For that, the dependencies would have to be added to Depends or Suggests in debian/control. Depends is probably to strong of a relation since rsync clearly works well in practice without, but adding them to Suggests might be worthwhile. A decision on this would involve checking, what happens if rsync is called with the relevant options on a host machine which has those packages installed, but where the destination machine lacks them. Apart from the issue described above, the 15 tests I managed to write are are a drop in the water in light of the infinitude of rsync options and their combinations. Most glaringly, not all options of the --archive option are covered separately (which would help indicating what code path of rsync broke in a regression). To increase the likelihood of catching regressions with the autopkgtests, the test coverage should be extended in the future.

Conclusion Generally, I am happy with my contributions to Debian over the course of my small GSoC project: I ve created an extensible, easy to understand, and working autopkgtest setup for the Debian rsync package. There are two things which bother me, however:
  1. In hindsight, I probably shouldn t have gone with shunit2 as a testing framework. The fact that it behaves erratically with the -e flag is a serious drawback for a shell testing framework: You really don t want a shell command to fail silently and the test to continue running.
  2. As alluded to in the previous section, I m not particularly proud of the number of tests I managed to write.
On the other hand, finding and fixing the regression in diffoscope - while derailing me from the GSoC project itself - might have a redeeming quality.

DebConf25 By sheer luck I happened to work on a GSoC project at Debian over a time period during which the annual Debian conference would take place close enough to my place of residence. Samuel pointed the opportunity to attend DebConf out to me during the community bonding period and since I could make time for the event in my schedule, I signed up. DebConf was a great experience which - aside from gaining more knowledge about Debian development - allowed me to meet the actual people usually hidden behind email adresses and IRC nicks. I can wholeheartedly recommend attending a DebConf to every interested Debian user! For those who have missed this year s iteration of the conference, I can recommend the following recorded talks: While not featuring as a keynote speaker (understandably so as the newcomer to Debian community that I am), I could still contribute a bit to the conference program.

GSoC project presentation The Debian Outreach team has scheduled a session in which all GSoC and Outreachy students over the past year had the chance to present their work in a lightning talk. The session has been recorded and is available online, just like my slides and the source for them.

Debian install workshop Additionally, with so many Debian experts gathering in one place while KDE s End of 10 campaign is ongoing, I felt it natural to organize a Debian install workhop. In hindsight I can say that I underestimated how much work it would be, especially for me who does not speak a word of French. But although the turnout of people who wanted us to install Linux on their machines was disappointingly low, it was still worth it: Not only because the material in the repo can be helpful to others planning install workshops but also because it was nice to meet a) the person behind the Debian installer images and b) the local Brest/Finist re Linux user group as well as the motivated and helpful people at Infini.

Credits I want to thank the Open Source team at Google for organizing GSoC: The highly structured program with a one-to-one mentorship is a great avenue to start contributing to well established and at times intimidating FOSS projects. And as much as I disagree with Google s surveillance capitalist business model, I have to give it to them that the company at least takes its responsibility for FOSS (somewhat) seriously - unlike many other businesses which rely on FOSS and choose to freeride of it. Big thanks to the Debian community! I ve experienced nothing but friendliness in my interactions with the community. And lastly, the biggest thanks to my GSoC mentor Samuel Henrique. He has dealt patiently and competently with all my stupid newbie questions. His support enabled me to make - albeit small - contributions to Debian. It has been a pleasure to work with him during GSoC and I m looking forward to working together with him in the future.

  1. Obviously, I ve only read them after experiencing the problem.

31 July 2025

Matthew Garrett: Secure boot certificate rollover is real but probably won't hurt you

LWN wrote an article which opens with the assertion "Linux users who have Secure Boot enabled on their systems knowingly or unknowingly rely on a key from Microsoft that is set to expire in September". This is, depending on interpretation, either misleading or just plain wrong, but also there's not a good source of truth here, so.

First, how does secure boot signing work? Every system that supports UEFI secure boot ships with a set of trusted certificates in a database called "db". Any binary signed with a chain of certificates that chains to a root in db is trusted, unless either the binary (via hash) or an intermediate certificate is added to "dbx", a separate database of things whose trust has been revoked[1]. But, in general, the firmware doesn't care about the intermediate or the number of intermediates or whatever - as long as there's a valid chain back to a certificate that's in db, it's going to be happy.

That's the conceptual version. What about the real world one? Most x86 systems that implement UEFI secure boot have at least two root certificates in db - one called "Microsoft Windows Production PCA 2011", and one called "Microsoft Corporation UEFI CA 2011". The former is the root of a chain used to sign the Windows bootloader, and the latter is the root used to sign, well, everything else.

What is "everything else"? For people in the Linux ecosystem, the most obvious thing is the Shim bootloader that's used to bridge between the Microsoft root of trust and a given Linux distribution's root of trust[2]. But that's not the only third party code executed in the UEFI environment. Graphics cards, network cards, RAID and iSCSI cards and so on all tend to have their own unique initialisation process, and need board-specific drivers. Even if you added support for everything on the market to your system firmware, a system built last year wouldn't know how to drive a graphics card released this year. Cards need to provide their own drivers, and these drivers are stored in flash on the card so they can be updated. But since UEFI doesn't have any sandboxing environment, those drivers could do pretty much anything they wanted to. Someone could compromise the UEFI secure boot chain by just plugging in a card with a malicious driver on it, and have that hotpatch the bootloader and introduce a backdoor into your kernel.

This is avoided by enforcing secure boot for these drivers as well. Every plug-in card that carries its own driver has it signed by Microsoft, and up until now that's been a certificate chain going back to the same "Microsoft Corporation UEFI CA 2011" certificate used in signing Shim. This is important for reasons we'll get to.

The "Microsoft Windows Production PCA 2011" certificate expires in October 2026, and the "Microsoft Corporation UEFI CA 2011" one in June 2026. These dates are not that far in the future! Most of you have probably at some point tried to visit a website and got an error message telling you that the site's certificate had expired and that it's no longer trusted, and so it's natural to assume that the outcome of time's arrow marching past those expiry dates would be that systems will stop booting. Thankfully, that's not what's going to happen.

First up: if you grab a copy of the Shim currently shipped in Fedora and extract the certificates from it, you'll learn it's not directly signed with the "Microsoft Corporation UEFI CA 2011" certificate. Instead, it's signed with a "Microsoft Windows UEFI Driver Publisher" certificate that chains to the "Microsoft Corporation UEFI CA 2011" certificate. That's not unusual, intermediates are commonly used and rotated. But if we look more closely at that certificate, we learn that it was issued in 2023 and expired in 2024. Older versions of Shim were signed with older intermediates. A very large number of Linux systems are already booting certificates that have expired, and yet things keep working. Why?

Let's talk about time. In the ways we care about in this discussion, time is a social construct rather than a meaningful reality. There's no way for a computer to observe the state of the universe and know what time it is - it needs to be told. It has no idea whether that time is accurate or an elaborate fiction, and so it can't with any degree of certainty declare that a certificate is valid from an external frame of reference. The failure modes of getting this wrong are also extremely bad! If a system has a GPU that relies on an option ROM, and if you stop trusting the option ROM because either its certificate has genuinely expired or because your clock is wrong, you can't display any graphical output[3] and the user can't fix the clock and, well, crap.

The upshot is that nobody actually enforces these expiry dates - here's the reference code that disables it. In a year's time we'll have gone past the expiration date for "Microsoft Windows UEFI Driver Publisher" and everything will still be working, and a few months later "Microsoft Windows Production PCA 2011" will also expire and systems will keep booting Windows despite being signed with a now-expired certificate. This isn't a Y2K scenario where everything keeps working because people have done a huge amount of work - it's a situation where everything keeps working even if nobody does any work.

So, uh, what's the story here? Why is there any engineering effort going on at all? What's all this talk of new certificates? Why are there sensationalist pieces about how Linux is going to stop working on old computers or new computers or maybe all computers?

Microsoft will shortly start signing things with a new certificate that chains to a new root, and most systems don't trust that new root. System vendors are supplying updates[4] to their systems to add the new root to the set of trusted keys, and Microsoft has supplied a fallback that can be applied to all systems even without vendor support[5]. If something is signed purely with the new certificate then it won't boot on something that only trusts the old certificate (which shouldn't be a realistic scenario due to the above), but if something is signed purely with the old certificate then it won't boot on something that only trusts the new certificate.

How meaningful a risk is this? We don't have an explicit statement from Microsoft as yet as to what's going to happen here, but we expect that there'll be at least a period of time where Microsoft signs binaries with both the old and the new certificate, and in that case those objects should work just fine on both old and new computers. The problem arises if Microsoft stops signing things with the old certificate, at which point new releases will stop booting on systems that don't trust the new key (which, again, shouldn't happen). But even if that does turn out to be a problem, nothing is going to force Linux distributions to stop using existing Shims signed with the old certificate, and having a Shim signed with an old certificate does nothing to stop distributions signing new versions of grub and kernels. In an ideal world we have no reason to ever update Shim[6] and so we just keep on shipping one signed with two certs.

If there's a point in the future where Microsoft only signs with the new key, and if we were to somehow end up in a world where systems only trust the old key and not the new key[7], then those systems wouldn't boot with new graphics cards, wouldn't be able to run new versions of Windows, wouldn't be able to run any Linux distros that ship with a Shim signed only with the new certificate. That would be bad, but we have a mechanism to avoid it. On the other hand, systems that only trust the new certificate and not the old one would refuse to boot older Linux, wouldn't support old graphics cards, and also wouldn't boot old versions of Windows. Nobody wants that, and for the foreseeable future we're going to see new systems continue trusting the old certificate and old systems have updates that add the new certificate, and everything will just continue working exactly as it does now.

Conclusion: Outside some corner cases, the worst case is you might need to boot an old Linux to update your trusted keys to be able to install a new Linux, and no computer currently running Linux will break in any way whatsoever.

[1] (there's also a separate revocation mechanism called SBAT which I wrote about here, but it's not relevant in this scenario)

[2] Microsoft won't sign GPLed code for reasons I think are unreasonable, so having them sign grub was a non-starter, but also the point of Shim was to allow distributions to have something that doesn't change often and be able to sign their own bootloaders and kernels and so on without having to have Microsoft involved, which means grub and the kernel can be updated without having to ask Microsoft to sign anything and updates can be pushed without any additional delays

[3] It's been a long time since graphics cards booted directly into a state that provided any well-defined programming interface. Even back in 90s, cards didn't present VGA-compatible registers until card-specific code had been executed (hence DEC Alphas having an x86 emulator in their firmware to run the driver on the card). No driver? No video output.

[4] There's a UEFI-defined mechanism for updating the keys that doesn't require a full firmware update, and it'll work on all devices that use the same keys rather than being per-device

[5] Using the generic update without a vendor-specific update means it wouldn't be possible to issue further updates for the next key rollover, or any additional revocation updates, but I'm hoping to be retired by then and I hope all these computers will also be retired by then

[6] I said this in 2012 and it turned out to be wrong then so it's probably wrong now sorry, but at least SBAT means we can revoke vulnerable grubs without having to revoke Shim

[7] Which shouldn't happen! There's an update to add the new key that should work on all PCs, but there's always the chance of firmware bugs

comment count unavailable comments

Russell Coker: Links July 2025

Louis Rossman made an informative YouTube video about right to repair and the US military [1]. This is really important as it helps promote free software and open standards. The ACM has an insightful article about hidden controls [2]. We need EU regulations about hidden controls in safety critical systems like cars. This Daily WTF article has some interesting security implications for Windows [3]. Earth.com has an interesting article about the rubber hand illusion and how it works on Octopus [4]. For a long time I have been opposed to eating Octopus because I think they are too intelligent. The Washington Post has an insightful article about the future of spies when everything is tracked by technology [5]. Micah Lee wrote an informative guide to using Signal groups for activism [6]. David Brin wrote an insightful blog post about the phases of the ongoing US civil war [7]. Christian Kastner wrote an interesting blog post about using Glibc hardware capabilities to use different builds of a shared library for a range of CPU features [8]. David Brin wrote an insightful and interesting blog post comparing President Carter with the criminals in the Republican party [9].

29 July 2025

Christoph Berg: The Debian Conference 2025 in Brest

It's Sunday and I'm now sitting in the train from Brest to Paris where I will be changing to Germany, on the way back from the annual Debian conference. A full week of presentations, discussions, talks and socializing is laying behind me and my head is still spinning from the intensity.
Pollito and the gang of DebConf mascots wearing their conference badgesPollito and the gang of DebConf mascots wearing their conference badges (photo: Christoph Berg)
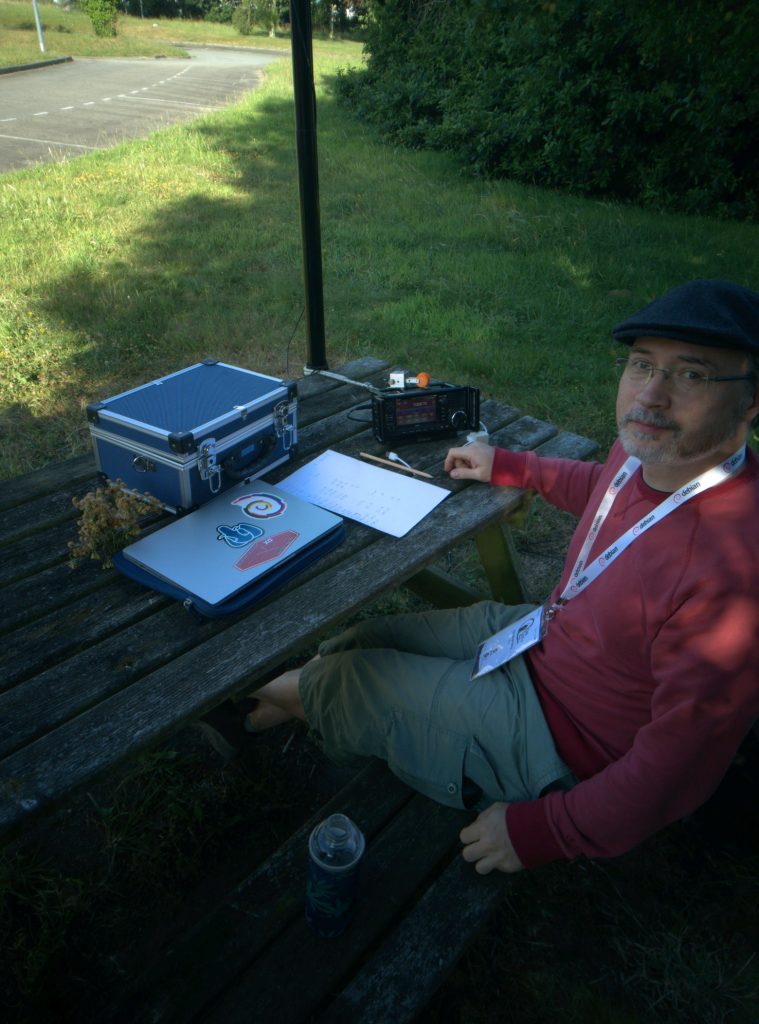
Sunday, July 13th It started last Sunday with traveling to the conference. I got on the Eurostar in Duisburg and we left on time, but even before reaching Cologne, the train was already one hour delayed for external reasons, collecting yet another hour between Aachen and Liege for its own technical problems. "The train driver is working on trying to fix the problem." My original schedule had well over two hours for changing train stations in Paris, but being that late, I missed the connection to Brest in Montparnasse. At least in the end, the total delay was only one hour when finally arriving at the destination. Due to the French julliet quatorze fireworks approaching, buses in Brest were rerouted, but I managed to catch the right bus to the conference venue, already meeting a few Debian people on the way. The conference was hosted at the IMT Atlantique Brest campus, giving the event a nice university touch. I arrived shortly after 10 in the evening and after settling down a bit, got on one of the "magic" buses for transportation to the camping site where half of the attendees where stationed. I shared a mobile home with three other Debianites, where I got a small room for myself. Monday, July 14th Next morning, we took the bus back to the venue with a small breakfast and the opening session where Enrico Zini invited me to come to his and Nicolas Dandrimont's session about Debian community governance and curation, which I gladly did. Many ideas about conflict moderation and community steering were floated around. I hope some of that can be put into effect to make flamewars on the mailing lists less heated and more directed. After that, I attended Olly Betts' "Stemming with Snowball" session, which is the stemmer used also in PostgreSQL. Text search is one of the areas in PostgreSQL that I never really looked closely at, including the integration into the postgresql-common package, so it was nice to get more information about that. In preparation for the conference, a few of us Ham radio operators in Debian had decided to bring some radio gear to DebConf this year in order to perhaps spark more interest for our hobby among the fellow geeks. In the afternoon after the talks, I found a quieter spot just outside of the main hall and set up a shortwave antenna by attaching a 10m mast to one of the park benches there. The 40m band was still pretty much closed, but I could work a few stations from England, just across the channel from Bretagne, answering questions from interested passing-by Debian people between the contacts. Over time, the band opened and more European stations got into the log.
F/DF7CB in Brest (photo: Evangelos Ribeiro Tzaras)
Tuesday, July 15th Tuesday started with Helmut Grohne's session about "Reviving (un)schroot". The schroot program has been Debian's standard way of managing build chroots for a long time, but it is more and more being regarded as obsolete with all kinds of newer containerization and virtualization technologies taking over. Since many bits of Debian infrastructure depend on schroot, and its user interface is still very useful, Helmut reimplemented it using Linux namespaces and the "unshare" systemcall. I had already worked with him at the Hamburg Minidebconf to replace the apt.postgresql.org buildd machinery with the new system, but we were not quite there yet (network isolation is nice, but we still sometimes need proper networking), so it was nice to see the effort is still progressing and I will give his new scripts a try when I'm back home. Next, Stefano Rivera and Colin Watson presented Debusine, a new package repository and workflow management system. It looks very promising for anyone running their own repository, so perhaps yet another bit of apt.postgresql.org infrastructure to replace in the future. After that, I went to the Debian LTS BoF session by Santiago Ruano Rinc n and Bastien Roucari s - Debian releases plus LTS is what we are covering with apt.postgresql.org. Then there were bits from the DPL (Debian Project Leader), and a session moderated by Stefano Rivera interesting to me as a member of the Debian Technical Committee on the future structure of the packages required for cross-building in Debian, a topic which had been brought to TC a while ago. I am happy that we could resolve the issue without having to issue a formal TC ruling as the involved parties (kernel, glibc, gcc and the cross-build people) found a promising way forward themselves. DebConf is really a good way to get such issues unstuck. Ten years ago at the 2015 Heidelberg DebConf, Enrico had given a seminal "Semi-serious stand-up comedy" talk, drawing parallels between the Debian Open Source community and the BDSM community - "People doing things consensually together". (Back then, the talk was announced as "probably unsuitable for people of all ages".) With his unique presentation style and witty insights, the session made a lasting impression on everyone attending. Now, ten years later (and he and many in the audience being ten years older), he gave an updated version of it. We are now looking forward to the sequel in 2035. The evening closed with the famous DebConf tradition of the Cheese & Wine party in a old fort next to the coast, just below the conference venue. Even when he's a fellow Debian Developer, Ham and also TC member, I had never met Paul Tagliamonte in person before, but we spent most of the evening together geeking out on all things Debian and Ham radio.
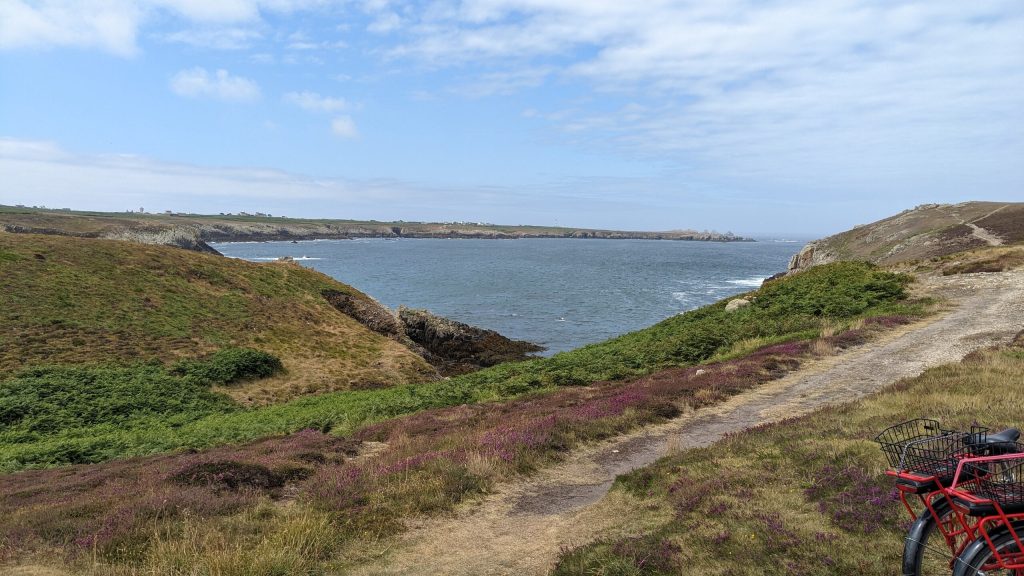
The northern coast of Ushant (photo: Christoph Berg)
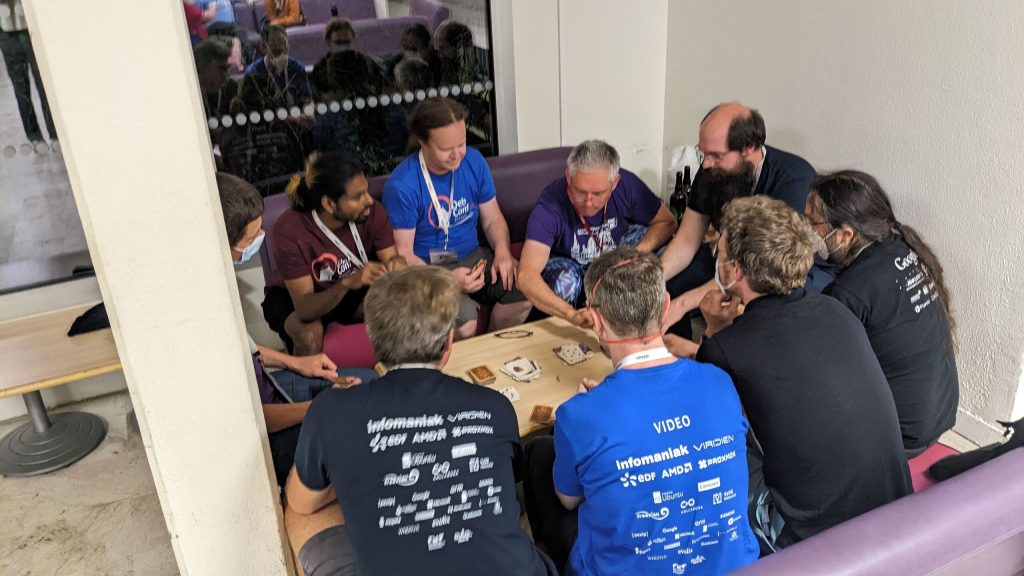
Wednesday, July 16th Wednesday already marked the end of the first half of the week, the day of the day trips. I had chosen to go to Ouessant island (Ushant in English) which marks the Western end of French mainland and hosts one of the lighthouses yielding the way into the English channel. The ferry trip included surprisingly big waves which left some participants seasick, but everyone recovered fast. After around one and a half hours we arrived, picked up the bicycles, and spent the rest of the day roaming the island. The weather forecast was originally very cloudy and 18 C, but over noon this turned into sunny and warm, so many got an unplanned sunburn. I enjoyed the trip very much - it made up for not having time visiting the city during the week. After returning, we spent the rest of the evening playing DebConf's standard game, Mao (spoiler alert: don't follow the link if you ever intend to play).
Having a nice day (photo: Christoph Berg)
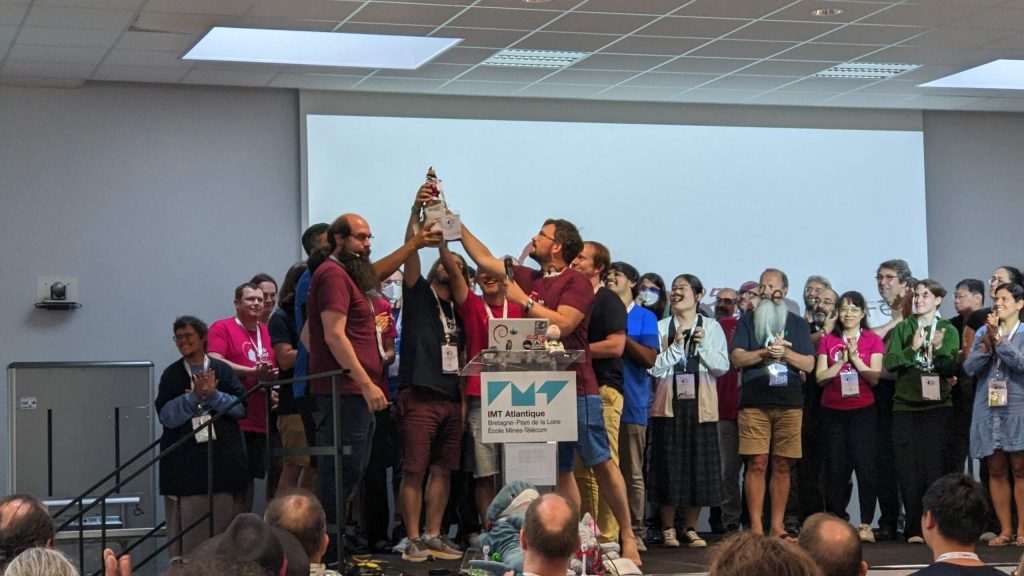
Thursday, July 17th The next day started with the traditional "Meet the Technical Committee" session. This year, we trimmed the usual slide deck down to remove the boring boilerplate parts, so after a very short introduction to the work of the committee by our chairman Matthew Vernon, we opened up the discussion with the audience, with seven (out of 8) TC members on stage. I think the format worked very well, with good input from attendees. Next up was "Don't fear the TPM" by Jonathan McDowell. A common misconception in the Free Software community is that the TPM is evil DRM hardware working against the user, but while it could be used in theory that way, the necessary TPM attestations seem to impossible to attain in practice, so that wouldn't happen anyway. Instead, it is a crypto coprocessor present in almost all modern computers that can be used to hold keys, for example to be used for SSH. It will also be interesting to research if we can make use of it for holding the Transparent Data Encryption keys for CYBERTEC's PostgreSQL Enterprise Edition. Aigars Mahinovs then directed everyone in place for the DebConf group picture, and Lucas Nussbaum started a discussion about archive-wide QA tasks in Debian, an area where I did a lot of work in the past and that still interests me. Antonio Terceiro and Paul Gevers followed up with techniques to track archive-wide rebuilding and testing of packages and in turn filing a lot of bugs to track the problems. The evening ended with the conference dinner, again in the fort close by the coast. DebConf is good for meeting new people, and I incidentally ran into another Chris, who happened to be one of the original maintainers of pgaccess, the pre-predecessor of today's pgadmin. I admit still missing this PostgreSQL frontend for its simplicity and ability to easily edit table data, but it disappeared around 2004. Friday, July 18th On Friday, I participated in discussion sessions around contributors.debian.org (PostgreSQL is planning to set up something similar) and the New Member process which I had helped to run and reform a decade or two ago. Agathe Porte (also a Ham radio operator, like so many others at the conference I had no idea of) then shared her work on rust-rewriting the slower parts of Lintian, the Debian package linter. Craig Small talked about "Free as in Bytes", the evolution of the Linux procps free command. Over the time and many kernel versions, the summary numbers printed became better and better, but there will probably never be a version that suits all use cases alike. Later over dinner, Craig (who is also a TC member) and I shared our experiences with these numbers and customers (not) understanding them. He pointed out that for PostgreSQL and looking at used memory in the presence of large shared memory buffers, USS (unique set size) and PSS (proportional set size) should be more realistic numbers than the standard RSS (resident set size) that the top utility is showing by default. Antonio Terceiro and Paul Gevers again joined to lead a session, now on ci.debian.net and autopkgtest, the test driver used for running tests on packages after then have been installed on a system. The PostgreSQL packages are heavily using this to make sure no regressions creep in even after builds have successfully completed and test re-runs are rescheduled periodically. The day ended with Bdale Garbee's electronics team BoF and Paul Tagliamonte and me setting up the radio station in the courtyard, again answering countless questions about ionospheric conditions and operating practice. Saturday, July 19th Saturday was the last conference day. In the first session, Nikos Tsipinakis and Federico Vaga from CERN announced that the LHC will be moving to Debian for the accelerator's frontend computers in their next "long shutdown" maintenance period in the next year. CentOS broke compatibility too often, and Debian trixie together with the extended LTS support will cover the time until the next long shutdown window in 2035, until when the computers should have all been replaced with newer processors covering higher x86_64 baseline versions. The audience was very delighted to hear that Debian is now also being used in this prestige project. Ben Hutchings then presented new Linux kernel features. Particularly interesting for me was the support for atomic writes spanning more than one filesystem block. When configured correctly, this would mean PostgreSQL didn't have to record full-page images in the WAL anymore, increasing throughput and performance. After that, the Debian ftp team discussed ways to improve review of new packages in the archive, and which of their processes could be relaxed with new US laws around Open Source and cryptography algorithms export. Emmanuel Arias led a session on Salsa CI, Debian's Gitlab instance and standard CI pipeline. (I think it's too slow, but the runners are not under their control.) Julian Klode then presented new features in APT, Debian's package manager. I like the new display format (and a tiny bit of that is also from me sending in wishlist bugs). In the last round of sessions this week, I then led the Ham radio BoF with an introduction into the hobby and how Debian can be used. Bdale mentioned that the sBitx family of SDR radios is natively running Debian, so stock packages can be used from the radio's touch display. We also briefly discussed his involvement in ARDC and the possibility to get grants from them for Ham radio projects. Finally, DebConf wrapped up with everyone gathering in the main auditorium and cheering the organizers for making the conference possible and passing Pollito, the DebConf mascot, to the next organizer team.
Pollito on stage (photo: Christoph Berg)
Sunday, July 20th Zoom back to the train: I made it through the Paris metro and I'm now on the Eurostar back to Germany. It has been an intense week with all the conference sessions and meeting all the people I had not seen so long. There are a lot of new ideas to follow up on both for my Debian and PostgreSQL work. Next year's DebConf will take place in Santa Fe, Argentina. I haven't yet decided if I will be going, but I can recommend the experience to everyone! The post The Debian Conference 2025 in Brest appeared first on CYBERTEC PostgreSQL Services & Support.

28 July 2025

Russ Allbery: Review: Cyteen

Review: Cyteen, by C.J. Cherryh
Series: Cyteen #1
Publisher: Warner Aspect
Copyright: 1988
Printing: September 1995
ISBN: 0-446-67127-4
Format: Trade paperback
Pages: 680
The main text below is an edited version of my original review of Cyteen written on 2012-01-03. Additional comments from my re-read are after the original review. I've reviewed several other C.J. Cherryh books somewhat negatively, which might give the impression I'm not a fan. That is an artifact of when I started reviewing. I first discovered Cherryh with Cyteen some 20 years ago, and it remains one of my favorite SF novels of all time. After finishing my reading for 2011, I was casting about for what to start next, saw Cyteen on my parents' shelves, and decided it was past time for my third reading, particularly given the recent release of a sequel, Regenesis. Cyteen is set in Cherryh's Alliance-Union universe following the Company Wars. It references several other books in that universe, most notably Forty Thousand in Gehenna but also Downbelow Station and others. It also has mentions of the Compact Space series (The Pride of Chanur and sequels). More generally, almost all of Cherryh's writing is loosely tied together by an overarching future history. One does not need to read any of those other books before reading Cyteen; this book will fill you in on all of the politics and history you need to know. I read Cyteen first and have never felt the lack. Cyteen was at one time split into three books for publishing reasons: The Betrayal, The Rebirth, and The Vindication. This is an awful way to think of the book. There are no internal pauses or reasonable volume breaks; Cyteen is a single coherent novel, and Cherryh has requested that it never be broken up that way again. If you happen to find all three portions as your reading copy, they contain all the same words and are serviceable if you remember it's a single novel under three covers, but I recommend against reading the portions in isolation. Human colonization of the galaxy started with slower-than-light travel sponsored by the private Sol Corporation. The inhabitants of the far-flung stations and the crews of the merchant ships that supplied them have formed their own separate cultures, but initially remained attached to Earth. That changed with the discovery of FTL travel and a botched attempt by Earth to reassert its authority. At the time of Cyteen, there are three human powers: distant Earth (which plays little role in this book), the merchanter Alliance, and Union. The planet Cyteen is one of only a few Earth-like worlds discovered by human expansion, and is the seat of government and the most powerful force in Union. This is primarily because of Reseune: the Cyteen lab that produces the azi. If Cyteen is about any one thing, it's about azi: genetically engineered human clones who are programmed via intensive psychological conditioning starting before birth. The conditioning uses a combination of drugs to make them receptive and "tape," specific patterns of instruction and sensory stimulation. They are designed for specific jobs or roles, they're conditioned to be obedient to regular humans, and they're not citizens. They are, in short, slaves. In a lot of books, that's as deep as the analysis would go. Azi are slaves, and slavery is certainly bad, so there would probably be a plot around azi overthrowing their conditioning, or around the protagonists trying to free them from servitude. But Cyteen is not any SF novel, and azi are considerably more complex and difficult than that analysis. We learn over the course of the book that the immensely powerful head of Reseune Labs, Ariane Emory, has a specific broader purpose in mind for the azi. One of the reasons why Reseune fought for and gained the role of legal protector of all azi in Union, regardless of where they were birthed, is so that Reseune could act to break any permanent dependence on azi as labor. And yet, they are slaves; one of the protagonists of Cyteen is an experimental azi, which makes him the permanent property of Reseune and puts him in constant jeopardy of being used as a political prisoner and lever of manipulation against those who care about him. Cyteen is a book about manipulation, about programming people, about what it means to have power over someone else's thoughts, and what one can do with that power. But it's also a book about connection and identity, about what makes up a personality, about what constitutes identity and how people construct the moral codes and values that they hold at their core. It's also a book about certainty. Azi are absolutely certain, and are capable of absolute trust, because that's part of their conditioning. Naturally-raised humans are not. This means humans can do things that azi can't, but the reverse is also true. The azi are not mindless slaves, nor are they mindlessly programmed, and several of the characters, both human and azi, find a lot of appeal in the core of certainty and deep self-knowledge of their own psychological rules that azis can have. Cyteen is a book about emotions, and logic, and where they come from and how to balance them. About whether emotional pain and uncertainty is beneficial or damaging, and about how one's experiences make up and alter one's identity. This is also a book about politics, both institutional and personal. It opens with Ariane Emory, Councilor for Science for five decades and the head of the ruling Union Expansionist party. She's powerful, brilliant, dangerously good at reading people, and dangerously willing to manipulate and control people for her own ends. What she wants, at the start of the book, is to completely clone a Special (the legal status given to the most brilliant minds of Union). This was attempted before and failed, but Ariane believes it's now possible, with a combination of tape, genetic engineering, and environmental control, to reproduce the brilliance of the original mind. To give Union another lifespan of work by their most brilliant thinkers. Jordan Warrick, another scientist at Reseune, has had a long-standing professional and personal feud with Ariane Emory. As the book opens, he is fighting to be transferred out from under her to the new research station that would be part of the Special cloning project, and he wants to bring his son Justin and Justin's companion azi Grant with them. Justin is a PR, a parental replicate, meaning he shares Jordan's genetic makeup but was not an attempt to reproduce the conditions of Jordan's rearing. Grant was raised as his brother. And both have, for reasons that are initially unclear, attracted the attention of Ariane, who may be using them as pawns. This is just the initial setup, and along with this should come a warning: the first 150 pages set up a very complex and dangerous political situation and build the tension that will carry the rest of the book, and they do this by, largely, torturing Justin and Grant. The viewpoint jumps around, but Justin and Grant are the primary protagonists for this first section of the book. While one feels sympathy for both of them, I have never, in my multiple readings of the book, particularly liked them. They're hard to like, as opposed to pity, during this setup; they have very little agency, are in way over their heads, are constantly making mistakes, and are essentially having their lives destroyed. Don't let this turn you off on the rest of the book. Cyteen takes a dramatic shift about 150 pages in. A new set of protagonists are introduced who are some of the most interesting, complex, and delightful protagonists in any SF novel I have read, and who are very much worth waiting for. While Justin has his moments later on (his life is so hard that his courage can be profoundly moving), it's not necessary to like him to love this book. That's one of the reasons why I so strongly dislike breaking it into three sections; that first section, which is mostly Justin and Grant, is not representative of the book. I can't talk too much more about the plot without risking spoiling it, but it's a beautiful, taut, and complex story that is full of my favorite things in both settings and protagonists. Cyteen is a book about brilliant people who think on their feet. Cherryh succeeds at showing this through what they do, which is rarely done as well as it is here. It's a book about remembering one's friends and remembering one's enemies, and waiting for the most effective moment to act, but it also achieves some remarkable transformations. About 150 pages in, you are likely to loathe almost everyone in Reseune; by the end of the book, you find yourself liking, or at least understanding, nearly everyone. This is extremely hard, and Cherryh pulls it off in most cases without even giving the people she's redeeming their own viewpoint sections. Other than perhaps George R.R. Martin I've not seen another author do this as well. And, more than anything else, Cyteen is a book with the most wonderful feeling of catharsis. I think this is one of the reasons why I adore this book and have difficulties with some of Cherryh's other works. She's always good at ramping up the tension and putting her characters in awful, untenable positions. Less frequently does she provide the emotional payoff of turning the tables, where you get to watch a protagonist do everything you've been wanting them to do for hundreds of pages, except even better and more delightfully than you would have come up with. Cyteen is one of the most emotionally satisfying books I've ever read. I could go on and on; there is just so much here that I love. Deep questions of ethics and self-control, presented in a way that one can see the consequences of both bad decisions and good ones and contrast them. Some of the best political negotiations in fiction. A wonderful look at friendship and loyalty from several directions. Two of the best semi-human protagonists I've seen, who one can see simultaneously as both wonderful friends and utterly non-human and who put nearly all of the androids in fiction to shame by being something trickier and more complex. A wonderful unfolding sense of power. A computer that can somewhat anticipate problems and somewhat can't, and that encapsulates much of what I love about semi-intelligent bases in science fiction. Cyteen has that rarest of properties of SF novels: Both the characters and the technology meld in a wonderful combination where neither could exist without the other, where the character issues are illuminated by the technology and the technology supports the characters. I have, for this book, two warnings. The first, as previously mentioned, is that the first 150 pages of setup is necessary but painful to read, and I never fully warmed to Justin and Grant throughout. I would not be surprised to hear that someone started this book but gave up on it after 50 or 100 pages. I do think it's worth sticking out the rocky beginning, though. Justin and Grant continue to be a little annoying, but there's so much other good stuff going on that it doesn't matter. The other warning is that part of the setup of the story involves the rape of an underage character. This is mostly off-camera, but the emotional consequences are significant (as they should be) and are frequently discussed throughout the book. There is also rather frank discussion of adolescent sexuality later in the book. I think both of these are relevant to the story and handled in a way that isn't gratuitous, but they made me uncomfortable and I don't have any past history with those topics. Those warnings notwithstanding, this is simply one of the best SF novels ever written. It uses technology to pose deep questions about human emotions, identity, and interactions, and it uses complex and interesting characters to take a close look at the impact of technology on lives. And it does this with a wonderfully taut, complicated plot that sustains its tension through all 680 pages, and with characters whom I absolutely love. I have no doubt that I'll be reading it for a fourth and fifth time some years down the road. Followed by Regenesis, although Cyteen stands well entirely on its own and there's no pressing need to read the sequel. Rating: 10 out of 10

Some additional thoughts after re-reading Cyteen in 2025: I touched on this briefly in my original review, but I was really struck during this re-read how much the azi are a commentary on and a complication of the role of androids in earlier science fiction. Asimov's Three Laws of Robotics were an attempt to control the risks of robots, but can also be read as turning robots into slaves. Azis make the slavery more explicit and disturbing by running the programming on a human biological platform, but they're more explicitly programmed and artificial than a lot of science fiction androids. Artificial beings and their relationship to humans have been a recurring theme of SF since Frankenstein, but I can't remember a novel that makes the comparison to humans this ambiguous and conflicted. The azi not only like being azi, they can describe why they prefer it. It's clear that Union made azi for many of the same reasons that humans enslave other humans, and that Ariane Emory is using them as machinery in a larger (and highly ethically questionable) plan, but Cherryh gets deeper into the emergent social complications and societal impact than most SF novels manage. Azi are apparently closer to humans than the famous SF examples such as Commander Data, but the deep differences are both more subtle and more profound. I've seen some reviewers who are disturbed by the lack of a clear moral stance by the protagonists against the creation of azi. I'm not sure what to think about that. It's clear the characters mostly like the society they've created, and the groups attempting to "free" azi from their "captivity" are portrayed as idiots who have no understanding of azi psychology. Emory says she doesn't want azi to be a permanent aspect of society but clearly has no intention of ending production any time soon. The book does seem oddly unaware that the production of azi is unethical per se and, unlike androids, has an obvious exit ramp: Continue cloning gene lines as needed to maintain a sufficient population for a growing industrial civilization, but raise the children as children rather than using azi programming. If Cherryh included some reason why that was infeasible, I didn't see it, and I don't think the characters directly confronted it. I don't think societies in books need to be ethical, or that Cherryh intended to defend this one. There are a lot of nasty moral traps that civilizations can fall into that make for interesting stories. But the lack of acknowledgment of the problem within the novel did seem odd this time around. The other part of this novel that was harder to read past in this re-read is the sexual ethics. There's a lot of adolescent sexuality in this book, and even apart from the rape scene which was more on-the-page than I had remembered and which is quite (intentionally) disturbing there is a whole lot of somewhat dubious consent. Maybe I've gotten older or just more discriminating, but it felt weirdly voyeuristic to know this much about the sex lives of characters who are, at several critical points in the story, just a bunch of kids. All that being said, and with the repeated warning that the first 150 pages of this novel are just not very good, there is still something magic about the last two-thirds of this book. It has competence porn featuring a precociously brilliant teenager who I really like, it has one of the more interesting non-AI programmed computer systems that I've read in SF, it has satisfying politics that feel like modern politics (media strategy and relationships and negotiated alliances, rather than brute force and ideology), and it has a truly excellent feeling of catharsis. The plot resolution is a bit too abrupt and a bit insufficiently explained (there's more in Regenesis), but even though this was my fourth time through this book, the pacing grabbed me again and I could barely put down the last part of the story. Ethics aside (and I realize that's quite the way to start a sentence), I find the azi stuff fascinating. I know the psychology in this book is not real and is hopelessly simplified compared to real psychology, but there's something in the discussions of value sets and flux and self-knowledge that grabs my interest and makes me want to ponder. I think it's the illusion of simplicity and control, the what-if premise of thought where core motivations and moral rules could be knowable instead of endlessly fluid the way they are in us humans. Cherryh's azi are some of the most intriguing androids in science fiction to me precisely because they don't start with computers and add the humanity in, but instead start with humanity and overlay a computer-like certainty of purpose that's fully self-aware. The result is more subtle and interesting than anything Star Trek managed. I was not quite as enamored with this book this time around, but it's still excellent once the story gets properly started. I still would recommend it, but I might add more warnings about the disturbing parts.

Re-read rating: 9 out of 10

27 July 2025

Russ Allbery: Review: The Dragon's Banker

Review: The Dragon's Banker, by Scott Warren
Publisher: Scott Warren
Copyright: September 2019
ISBN: 0-578-55292-2
Format: Kindle
Pages: 263
The Dragon's Banker is a self-published stand-alone fantasy novel, set in a secondary world with roughly Renaissance levels of technology and primarily alchemical magic. The version I read includes an unrelated novelette, "Forego Quest." I have the vague impression that this novel shares a world with other fantasy novels by the same author, but I have not read them and never felt like I was missing something important. Sailor Kelstern is a merchant banker. He earns his livelihood by financing caravans and sea voyages and taking a cut of the profits. He is not part of the primary banking houses of the city; instead, he has a small, personal business with a loyal staff that looks for opportunities the larger houses may have overlooked. As the story opens, he has fallen on hard times due in part to a spectacular falling-out with a previous client and is in desperate need of new opportunities. The jewel-bedecked Lady Arkelai and her quest for private banking services for her father, Lord Alkazarian, may be exactly what he needs. Or it may be a dangerous trap; Sailor has had disastrous past experience with nobles attempting to strong-arm him into their service. Unbeknownst to Sailor, Lord Alkazarian is even more dangerous than he first appears. He is sitting on a vast hoard of traditional riches whose value is endangered by the rise of new-fangled paper money. He is not at all happy about this development. He is also a dragon. I, and probably many other people who read this book, picked it up because it was recommended by Matt Levine as a fantasy about finance instead of the normal magical adventuring. I knew it was self-published going in, so I wasn't expecting polished writing. My hope was for interesting finance problems in a fantasy context, similar to the kind of things Matt Levine's newsletter is about: schemes for financing risky voyages, complications around competing ideas of money, macroeconomic risks from dragon hoards, complex derivatives, principal-agent problems, or something similar that goes beyond the (annoyingly superficial) treatment of finance in most fantasy novels. Unfortunately, what I got was a rather standard fantasy setting and a plot that revolves mostly around creative uses for magical devices, some conventional political skulduggery, and a lot of energetic but rather superficial business hustling. The protagonist is indeed a merchant banker who is in no way a conventional fantasy hero (one of the most taxing parts of Sailor's occasional visits to the dragon is the long hike down to the hoard, or rather the long climb back out), but the most complex financial instrument that appears in this book is straightforward short-selling. Alas. I was looking forward to the book that I hoped this was. Given my expectations, this was a disappointment. I kept waiting for the finances to get more complicated and interesting, and that kept not happening. Without that expectation, this is... okay, I guess. The writing is adequate but kind of stilted, presumably in an effort to make it sound slightly archaic, and has a strong self-published feel. Sailor is not a bad protagonist, but neither is he all that memorable. I did like some of the world-building, which has an attention to creative uses of bits of magic that readers who like gadget fantasy may appreciate. There are a lot of plot conveniences and coincidences, though, and very little of this is going to feel original to a long-time fantasy reader. Putting some of the complexity of real Renaissance banking and finance systems into a fantasy world is a great idea, but I've yet to read one that lived up to the potential of the premise. (Neal Stephenson's Baroque Cycle comes the closest; unfortunately, the non-economic parts of that over-long series are full of Stephenson's worst writing habits.) Part of the problem is doubtless that I am reasonably well-read in economics, so my standards are high. Maybe the average reader would be content with a few bits on the perils of investment, a simple treatment of trust in currency, and a mention or two of short-selling, which is what you get in this book. I am not altogether sorry that I read this, but I wouldn't recommend it. I encourage Matt Levine to read more genre fiction and find some novels with more interesting financial problems! "Forego Quest": This included novelette, on the other hand, was surprisingly good and raised my overall rating for the book by a full point. Arturus Kingson is the Chosen One. He is not the Chosen One of a single prophecy or set of prophecies; no, he's the Chosen One of, apparently, all of them, no matter how contradictory, and he wants absolutely nothing to do with any of them. Magical swords litter his path. He has so many scars and birthmarks that they look like a skin condition. Beautiful women approach him in bars. Mysterious cloaked strangers die dramatically in front of him. Owls try to get into his bedroom window. It's all very exhausting, since the universe absolutely refuses to take no for an answer. There isn't much more to the story than this, but Warren writes it in the first person with just the right tone of exasperated annoyance and gives Arturus a real problem to solve and enough of a plot to provide some structure. I'm usually not a fan of parody stories because too many of them feel like juvenile slapstick. This one is sarcastic instead, which is much more to my taste. "Forego Quest" goes on perhaps a bit too long, and the ending was not as successful as the rest of the book, but this was a lot of fun and made me laugh. (7) Rating: 6 out of 10

26 July 2025

Birger Schacht: My DebConf 25 review

DebConf 25 happened between 14th July and 19th July and I was there. It was my first DebConf (the big one, I was at a Mini DebConf in Hamburg a couple of years ago) and it was interesting. DebConf 25 happened at a Campus University at the outskirts of Brest and I was rather reluctant to go at first (EuroPython 25 was happening at the same time in Prague), but I decided to use the chance of DebConf happening in Europe, reachable by train from Vienna. We took the nighttrain to Paris, then found our way through the maze that is the Paris underground system and then got to Brest with the TGV. On our way to the Conference site we made a detour to a supermarket, which wasn t that easy because is was a national holiday in France and most of the shops were closed. But we weren t sure about the food situation at DebConf and we also wanted to get some beer. At the conference we were greeted by very friendly people at the badge station and the front desk and got our badges, swag and most important the keys to pretty nice rooms on the campus. Our rooms had a small private bathroom with a toilet and a shower and between the two rooms was a shared kitchen with a refrigerator and a microwave. All in all, the accommodation was simple but provided everything we needed and especially a space to have some privacy. During the next days I watched a lot of talks, met new people, caught up with old friends and also had a nice time with my travel buddies. There was a beach near the campus which I used nearly every day. It was mostly sunny except for the last day of the conference, which apparently was not common for the Brest area, so we got lucky regarding the weather. Landscape view of the sea at Dellec beach Given that we only arrived in the evening of the first day of DebConf, I missed the talk When Free Software Communities Unite: Tails, Tor, and the Fight for Privacy (recording), but I watched it on the way home and it was also covered by LWN. On Tuesday I started the day by visiting a talk about tag2upload (recording). The same day there was also an academic track and I watched the talk titled Integrating Knowledge Graphs into the Debian Ecosystem (recording) which presented a property graph showing relationships between various entities like packages, maintainers or bugs (there is a repository with parts of a paper, but not much other information). The speaker also mentioned the graphcast framework and the ontocast framework which sound interesting - we might have use for something liked this at $dayjob. In the afternoon there was a talk about the ArchWiki (recording) which gave a comprehensive insight in how the ArchWiki and the community behind it works. Right after that was a Debian Wiki BoF. There are various technical limitations with the current wiki software and there are not enough helping hands to maintain the service and do content curation. But the BoF had some nice results: there is now a new debian-wiki mailinglist, an IRC channel, a MediaWiki installation has been set up during DebConf, there are efforts to migrate the data and most importantly: and handful of people who want to maintain the service and organize the content of the wiki. I think the input from the ArchWiki folks gave some ideas how that team could operate. Tag at the wall at Dellec beach Wednesday was the day of the daytrip. I did not sign up for any of the trips and used the time to try out tag2upload, uploaded the latest labwc release to experimental and spent the rest of the day at the beach. Other noteworthy session I ve attended were the Don t fear the TPM talk (recording), which showed me a lot of stuff to try out, the session about lintian-ng (no recording), which is an experimental approach to make lintian faster, the review of the first year of wcurls existence (no recording yet) and the summary of Rust packaging in Debian (no recording yet). In between the sessions I started working on packaging wlr-sunclock (#1109230).
What did not work Vegan food. I might be spoiled by other conferences. Both at EuroPycon last year (definitely bigger, a lot more commercial) and at PyCon CZ 23 (similar in size, a lot more DIY) there was catering with explicitly vegan options. As I ve mentioned in the beginning, we went to a supermarket before we went to the conference and we had to go there one more time during the conference. I think there was a mixture between a total lack of awareness and a LOT of miscommunication. The breakfasts at the conference consisted of pastries and baguettes - I asked at the first day what the vegan options were and the answer was I don t know, maybe the baguette? and we were asked to only take as much baguette as the people who also got pastries. The lunch was prepared by the Restaurant associatif de Kern vent which is a canteen at the university campus. When we asked if there is vegan food, the people there said that there was only a vegetarian option so we only ate salad. Only later we heard via word of mouth that one has to explicitly ask for a vegan meal which was apparently prepared separatly and you had to find the right person that knows about it (I think thats very Debian-like ). But even then a person once got a vegetarian option offered as vegan food. One problem was also the missing / confusing labeling of the food. At the conference dinner there was apparently vegan food, but it was mixed with all the other food. There were some labels but with hundreds of hungry people around and caterers removing empty plates and dropping off plates with other stuff, everything gets mixed up. In the end we ate bread soaked in olive oil, until the olive oil got taken away by the catering people literally while we were dipping the bread in it. And when these issues were raised, some of the reactions can be summarized as You re holding it wrong which was really frustrating. The dinners at the conference hall were similar. At some point I had the impression that vegan and vegetarian was simply seen as the same thing. Dinner menu at the conference If the menus would be written like a debian/copyright file it would probably have looked like this:
Food: *
Diet: Vegan or Vegetarian
But the thing is that Vegan and Vegetarian cannot be mixed. Its similar to non compatible licenses. Once you mix vegan food with vegan food with vegetarian food it s not vegan anymore. Don t get me wrong, I know its hard to organize food for hundreds of people. But if you don t know what it means to provide a vegan option, just communicate the fact so people can look alternatives in advance. During the week some of the vegan people shared food, which was really nice and there were also a lot of non-vegan people who tried to help, organized extra food or simply listened to the hangry rants. Thanks for that!

Paris Saturday was the last day of DebConf and it was a rainy day. On Sunday morning we took the TGV back to Paris and then stayed there for one night because the next night train back to Vienna was on Monday. Luckily the weather was better in Paris. The first thing we did was to look up a vegan burger place. In the evening we strolled along the Seine and had a couple of beers at the Jardins du Trocad ro. Monday the rain also arrived in Paris and we mostly went from one cafe to the next, but also managed to visit Notre Dame.

Conclusio The next DebConf will be in Argentina and I think its likely that DebConf 27 will also not happen anywhere in trainvelling distance. But even if, I think the Mini DebConfs are more my style of happening (there is one planned in Hamburg next spring, and a couple of days ago I learned that there will be a Back to the Future musical show in Hamburg during that time). Nonetheless I had a nice time and I stumbled over some projects I might get more involved in. Thanks also to my travel buddies who put up with me

25 July 2025

Valhalla's Things: Roll Top Backpack, Handsewn

Posted on July 25, 2025
Tags: madeof:atoms, craft:sewing, FreeSoftWear
a backpack in a cream fabric with a short dark brown bottom; it closes by rolling down the top and is kept closed by a strap that feeds through two D-rings. I might be slightly insane? Or am I going to prove something about the nature and accessibility of sewing and MYOG1 as a hobby? I love my modular backpack, but it has a very modern look that is maybe not the best thing when otherwise dressed in historybounding dress, and it s also a bit bigger than I planned or needed it to be. So, when one of the shops I buy from had some waterproof cotton canvas on sale I failed my saving throw against temptations and bought a few meters, with the intent to make myself a backpack in a different style. It needs to be a backpack, because my back doesn t like asymmetrical bags2, and as far as I know 19th century backpacks weren t the most comfortable things, so I decided to go for a vaguely timeless roll top model that has the added advantage not to require a lot of hardware for the closure, just a few D-rings. Leather straps would look cool, but also require some tools that I still don t have, so I decided to look for some cotton webbing, and when I finally found some in 25 mm and 50 mm width I could finally start on the project. Except for one thing: thread. As much as I believe that regular n 50 cotton thread got a bad reputation from sellers who decided to cut quality in favour of profit, it is not up to the task of sewing a backpack. Nor that I d use regular sew-all poly thread either. I do have some of the thread I used for my other backpack, which would have been strong enough, but it s also in black, which isn t exactly the look I was aiming for on the natural / ecru colour of both the canvas and the webbing. I also misremembered it as only being available in that colour (it isn t), so I wasn t tempted into doing a full online order of technical materials just for that. On the other hand, I did have in my stash some strong thread I could trust for this job, in natural / ecru. There was only one problem: it was 33 2 Tex linen, and not suitable for the sewing machine. You can t handsew a backpack. Or can you? Of course it s going to be much slower, but I m still in a situation where I have more time and space for handsewing than I have for machine sewing. And as for strength, my perception is that for the same stitch length an handsewn backstitch is stronger than a machine lockstitch, or at least it is more effort to unpick (and thus harder to accidentally unravel if the thread breaks). And so I tried. And it worked. a needle coming straight up through layers of fabric and webbing, in the motion called stabbing. Having to backstitch everything instead of being able to use a running backstitch of course meant that it was slower than other sewing projects, and any time there were more than two layers of fabric I had to use the stabbing motion rather than the sewing one, which is even slower, but other than a few places with many layers of both fabric and webbing it wasn t hard. And to be fair, the seams were fewer and shorter than other sewing projects, and with the usual interruptions and uneven time availability it was done in less than a month, which is somewhat typical for one of my handsewn projects. the layers of the base pinned into the sides, trying to keep everything properly aligned especially on the corners in a way that would be very messy if fed as-is to a sewing machine. It may have been because of the pattern, but I think it s relevant that it was also easier than other backpacks I ve made, with significantly less cursing, even when doing seams that would have been quite fiddly when sewn by machine. I have to admit that now I m tempted to plan another backpack using the same pattern or a slight variation, sewn by machine in a different fabric, to see the difference in the time it takes and to check if the changes I think would make it easier to sew by machine are actually the right thing to do. But maybe I ll wait a bit, other projects are in the queue. The pattern is as usual online, released as #FreeSoftWear. Having used it for a while, I have to say that it is just the right size to fit all the things I usually carry, The fact that it only opens from the top means that finding things that have fallen to the very bottom involves a bit of rummaging, but not having to change a zipper every few years when (not if) it breaks is also very nice, so I m not sure which shape of backpack I prefer. the back of the backpack, showing the shoulder straps made with wide webbing that end in two D-rings, and a pattern of horizontal webbing sewn at 4 cm intervals to attach accessories. The soft back of course is an issue when the backpack is filled with small items, but the molle webbing is there exactly because I have plans to solve it, beside the trivial put something flat towards the back . As an object, I m happy with the result. As a project, it was way more than successful, exceeding all expectations, especially for something somewhat experimental like this one was.
  1. Make Your Own Gear, i.e. sewing or otherwise constructing outdoorish equipment.
  2. at least not if I fill them with stuff as I usually do with my backpack :D

23 July 2025

Dirk Eddelbuettel: qlcal 0.0.16 on CRAN: Regular Update

The sixteenth release of the qlcal package arrivied at CRAN today, once again following the QuantLib 1.39 release this morning. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases mainly synchronizes qlcal with the QuantLib release 1.39.

Changes in version 0.0.16 (2025-07-23)
  • Synchronized with QuantLib 1.39 released today
  • Calendar updates for Israel, minor utility functions update
  • Minor package maintenance updates

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Russell Coker: Annoying Wrongness on TV

One thing that annoys me on TV shows and movies is getting the details wrong. Yes it s fiction and yes some things can t be done correctly and in some situations correctly portraying things goes against the plot. But otherwise I think they should try to make it accurate. I was just watching The Americans (a generally good show that I recommend watching) and in Season 4 Episode 9 there s a close up of a glass of wine which clearly shows that the Tears of Wine effect is missing, the liquid in the glass obviously has the surface tension of water not of wine. When they run a show about spies then have to expect that the core audience will be the type of detail oriented people who notice these things. Having actors not actually drink alcohol on set is a standard practice, if they have to do 10 takes of someone drinking a glass of wine then that would be a problem if they actually drank real wine. But they could substitute real wine for the close up shots and of course just getting it right the first time is a good option. Some ridiculous inaccuracy we just need to deal with, like knives making a schwing sound when pulled out of scabbards and silenced guns usually still being quite loud (so many people are used to it being wrong). Organisations like the KGB had guns that were actually silent, but they generally looked obviously different to regular guns and had a much lower effective range. The gold coins shown on TV are another ridiculous thing. The sound of metal hitting something depends on how hard it is and how dense it is. Surely most people have heard the sounds of dropping steel nuts and ball bearings and the sound of dropping lead sinkers and knows that the sounds of items of similar size and shape differ greatly based on density and hardness. A modern coin made of copper, cupro-nickel (the current silver coins), or copper-aluminium (the current gold coins) sounds very different to a gold coin when dropped on a bench. For a show like The Witcher it wouldn t be difficult to make actual gold coins of a similar quality to iron age coin production, any jeweller could make the blanks and making stamps hard enough to press gold isn t an engineering challenge (stamping copper coins would be much more difficult). The coins used for the show could be sold to fans afterwards. Once coins are made they can t be just heaped up. Even if you are a sorcerer you probably couldn t fill a barrel a meter high with gold coins and not have it break from the weight and/or have the coins at the bottom cold welded. Gold coins are supposed to have a precise amount of gold and if you pile them up too high then the cold welding process will transfer gold between coins changing the value. If someone was going to have a significant quantity of gold stored then it would be in gold ingots with separators between layers to prevent cold welding. Movies tend not to show coins close up, I presume that s because they considered it too difficult to make coins and they just use some random coins from their own country. Another annoying thing is shows that don t match up the build dates of objects used. It s nice when they get it right like the movie Titanic featuring a M1911 pistol which is something that a rich person in 1912 would likely have. The series Carnival Row (which I recommend) has weapons that mostly match our WW1 era, everything that doesn t involve magic seems legit. One of the worst examples of this is the movie Anna (by Luc Besson which is mostly a recreation of his film Nikita but in the early 90s and with the KGB). That film features laptops with color screens and USB ports before USB was invented and when color screens weren t common on laptops, as an aside military spec laptops tend to have older designs than consumer spec ones. I ve mostly given up on hoping that movies will get hacking scenes that are any more accurate than knives making a schwing sound. But it shouldn t be that hard for them to find computer gear that was manufactured in the right year to use for the film. Why can t they hire experts on technology to check everything?

22 July 2025

David Bremner: Hibernate on the pocket reform 10/n

Context

Finally applying the pci reset series.
$ b4 am 20250715-pci-port-reset-v6-0-6f9cce94e7bb@oss.qualcomm.com
$ git am -3 v6_20250715_manivannan_sadhasivam_pci_add_support_for_resetting_the_root_ports_in_a_platform_specifi.mbx
There is quite a scary looking conflict between the last patch in the series and https://lore.kernel.org/r/1744940759-23823-1-git-send-email-shawn.lin@rock-chips.com which is now upstream (collabora) in rockchip-devel. I resolved the second basically by taking both, as it seemed like two independent sets of additions to the same parts of the file. The first it looks like Shawn's commit referenced above should prevail.
  • If anyone is curious about the (possibly incorrectly) rebased patches, they are at https://salsa.debian.org/bremner/collabora-rockchip-3588 (reform-patches is the default, and relevant branch).

testing
  • The new (6.16~rc7+) kernel boots
  • It successfully reboots
  • devices test passes, although the UBSAN warning / error is still there
 174.559032] UBSAN: array-index-out-of-bounds in net/mac80211/rc80211_minstrel_ht.c:409:33
[  174.559830] index 15 is out of range for type 'minstrel_rate_stats [10]'
[  174.560462] CPU: 7 UID: 0 PID: 213 Comm: kworker/u32:10 Tainted: G        WC OE       6.16.0-rc7+ #6 NONE
[  174.560470] Tainted: [W]=WARN, [C]=CRAP, [O]=OOT_MODULE, [E]=UNSIGNED_MODULE
[  174.560472] Hardware name: MNT Pocket Reform with RCORE RK3588 Module (DT)
[  174.560474] Workqueue: mt76 mt76u_tx_status_data [mt76_usb]
[  174.560489] Call trace:
[  174.560491]  show_stack+0x34/0x98 (C)
[  174.560501]  dump_stack_lvl+0x60/0x80
[  174.560508]  dump_stack+0x18/0x24
[  174.560514]  ubsan_epilogue+0x10/0x48
[  174.560520]  __ubsan_handle_out_of_bounds+0xa0/0xd0
[  174.560526]  minstrel_ht_tx_status+0x890/0xc68 [mac80211]
[  174.560633]  rate_control_tx_status+0xbc/0x180 [mac80211]
[  174.560730]  ieee80211_tx_status_ext+0x1d8/0x9a0 [mac80211]
[  174.560822]  mt76_tx_status_unlock+0x188/0x2a0 [mt76]
[  174.560844]  mt76x02_send_tx_status+0x130/0x4a0 [mt76x02_lib]
[  174.560860]  mt76x02_tx_status_data+0x64/0xa8 [mt76x02_lib]
[  174.560872]  mt76u_tx_status_data+0x84/0x120 [mt76_usb]
[  174.560879]  process_one_work+0x178/0x3c8
[  174.560885]  worker_thread+0x208/0x400
[  174.560890]  kthread+0x120/0x220
[  174.560894]  ret_from_fork+0x10/0x20
[  174.560898] ---[ end trace ]---
  • "platform" test still fails with
[   88.484072] rk_gmac-dwmac fe1b0000.ethernet end0: Link is Down
[   88.597026] rockchip-dw-pcie a40c00000.pcie: Failed to receive PME_TO_Ack
[   88.598523] PM: hibernation: hibernation debug: Waiting for 5 second(s).
[   94.667723] rockchip-dw-pcie a40c00000.pcie: Phy link never came up
[   94.668281] rockchip-dw-pcie a40c00000.pcie: fail to resume
[   94.668783] rockchip-dw-pcie a40c00000.pcie: PM: dpm_run_callback(): genpd_restore_noirq returns -110
[   94.669594] rockchip-dw-pcie a40c00000.pcie: PM: failed to restore noirq: error -110
[  120.035426] watchdog: CPU4: Watchdog detected hard LOCKUP on cpu 5
[  120.035978] Modules linked in: xt_CHECKSUM xt_tcpudp nft_chain_nat xt_MASQUERADE nf_nat nf_conntrack nf_defrag_ipv6 nf_defrag_ipv4 nft_compat bridge stp llc nf_tables aes_neon_bs aes_neon_blk ccm snd_seq_dummy snd_hrtimer snd_seq snd_seq_device dwmac_rk binfmt_misc mt76x2_common mt76x02_usb mt76_usb mt76x02_lib mt76 mac80211 libarc4 snd_soc_simple_card rockchip_saradc industrialio_triggered_buffer cfg80211 snd_soc_tlv320aic31xx rk805_pwrkey kfifo_buf reform2_lpc(OE) industrialio rockchip_thermal rfkill rockchip_rng hantro_vpu cdc_acm rockchip_rga v4l2_vp9 snd_soc_rockchip_i2s_tdm rockchip_vdec2 panthor videobuf2_dma_sg v4l2_jpeg drm_gpuvm v4l2_h264 drm_exec snd_soc_audio_graph_card snd_soc_simple_card_utils joydev evdev dm_mod nvme_fabrics efi_pstore configfs nfnetlink ip_tables x_tables autofs4 ext4 crc16 mbcache jbd2 btrfs blake2b_generic xor xor_neon raid6_pq mali_dp snd_soc_meson_axg_toddr snd_soc_meson_axg_fifo snd_soc_meson_codec_glue panfrost drm_shmem_helper gpu_sched ao_cec_g12a meson_vdec(C)
[  120.036066]  videobuf2_dma_contig hid_generic videobuf2_memops v4l2_mem2mem videobuf2_v4l2 videodev videobuf2_common mc dw_hdmi_i2s_audio meson_drm meson_canvas meson_dw_mipi_dsi meson_dw_hdmi usbhid hid mxsfb mux_mmio panel_edp imx_dcss ti_sn65dsi86 nwl_dsi mux_core pwm_imx27 xhci_plat_hcd xhci_hcd onboard_usb_dev snd_soc_hdmi_codec snd_soc_core micrel snd_pcm_dmaengine nvme snd_pcm nvme_core snd_timer snd nvme_keyring nvme_auth soundcore stmmac_platform stmmac pcs_xpcs phylink mdio_devres of_mdio sdhci_of_dwcmshc fixed_phy sdhci_pltfm phy_rockchip_usbdp dw_mmc_rockchip fwnode_mdio ehci_platform typec phy_rockchip_samsung_hdptx phy_rockchip_naneng_combphy rk808_regulator pwm_rockchip dwc3 dw_wdt libphy fan53555 ohci_platform sdhci ehci_hcd ulpi rtc_pcf8523 dw_mmc_pltfm udc_core ohci_hcd dw_mmc cqhci mdio_bus rockchip_dfi rockchipdrm dw_hdmi_qp analogix_dp i2c_rk3x usbcore phy_rockchip_inno_usb2 dw_mipi_dsi dw_mipi_dsi2 usb_common cpufreq_dt drm_dp_aux_bus [last unloaded: mt76x2u]
[  120.036150] Sending NMI from CPU 4 to CPUs 5:
  • The results are similar if I uncomment the unloading of the dwc3 module
set -x
echo platform >  /sys/power/pm_test
echo reboot > /sys/power/disk
sleep 2
rmmod mt76x2u
sleep 2
#rmmod dwc3
#sleep 2
echo disk >  /sys/power/state
sleep 2
#modprobe dwc3
#sleep 2
modprobe mt76x2u
  • Unsurprisingly, if I try an actual resume (instead of a "platform" test), I get the same messages about "Phy link never came up" and the system needs a hard reboot after trying to resume.
  • Barring inspiration, my next move will be to report my lack of success to the appropriate kernel mailing list(s).
previous episode

21 July 2025

Jonathan Dowland: Nine Inch Nails, Paris, 2025-07-07

On July 7th I did a quick one-day trip to Paris to watch Nine Inch Nails, who were performing one of their last shows for the European leg of the tour. I'd missed all the UK dates, which were announced after I was committed to a family holiday. The setup for these shows differs a lot from the norm. First, the support act was German-Iraqi techno DJ Boys Noize, who TR&AR had collaborated with on their soundtrack for the recent movie Challengers. BN did a 75-minute opening set:
Stripped down Set 1 Stripped down Set 1
The main gig was divided into four acts. Act 1 took place on a square "B Stage", situated in the middle of the main floor. Trent and 2-3 band members performed three stripped-down songs, with interpolations to other songs, alternative lyrics, and the like. I enjoyed this section more than I expected to.
Main stage lighting Main stage lighting
They then transition to the main stage for a six-song full-band set. The main stage was draped in layers of transparent curtains. One of the team was on-stage, walking around with a video camera, and the live camera footage was processed and projected onto the curtains in realtime. The visuals were truly fantastic. For the third act, Trent and Atticus returned to the B stage, to be joined by Boys Noize, who then performed four songs in a reworked, remixed, electronic dance format. This ended up being the highlight of the gig for me. I felt the reworkings breathed new life into some old songs.
remix Set 3 remix Set 3
Finally, back to the main stage to close out with a final seven songs. The traditional triad of closers was adjusted, substituting "The Hand That Feeds" for "The Perfect Drug"; a song that wasn't played at all from 1997 to 2018, and has now become a regular fixture. Several tapers recorded the show, and their recordings are up at nin.live. Overall it was great fun: I ended up flying via London and the airport time was a bit of a pain, but I did get a good start on my corrections. I was home the next afternoon. I'm trying not to think of the cost.

20 July 2025

Michael Prokop: What to expect from Debian/trixie #newintrixie

Trixie Banner, Copyright 2024 Elise Couper Update on 2025-07-28: added note about Debian 13/trixie support for OpenVox (thanks, Ben Ford!) Debian v13 with codename trixie is scheduled to be published as new stable release on 9th of August 2025. I was the driving force at several of my customers to be well prepared for the upcoming stable release (my efforts for trixie started in August 2024). On the one hand, to make sure packages we care about are available and actually make it into the release. On the other hand, to ensure there are no severe issues that make it into the release and to get proper and working upgrades. So far everything is looking pretty well and working fine, the efforts seemed to have payed off. :) As usual with major upgrades, there are some things to be aware of, and hereby I m starting my public notes on trixie that might be worth for other folks. My focus is primarily on server systems and looking at things from a sysadmin perspective. Further readings As usual start at the official Debian release notes, make sure to especially go through What s new in Debian 13 + issues to be aware of for trixie (strongly recommended read!). Package versions As a starting point, let s look at some selected packages and their versions in bookworm vs. trixie as of 2025-07-20 (mainly having amd64 in mind):
Package bookworm/v12 trixie/v13
ansible 2.14.3 2.19.0
apache 2.4.62 2.4.64
apt 2.6.1 3.0.3
bash 5.2.15 5.2.37
ceph 16.2.11 18.2.7
docker 20.10.24 26.1.5
dovecot 2.3.19 2.4.1
dpkg 1.21.22 1.22.21
emacs 28.2 30.1
gcc 12.2.0 14.2.0
git 2.39.5 2.47.2
golang 1.19 1.24
libc 2.36 2.41
linux kernel 6.1 6.12
llvm 14.0 19.0
lxc 5.0.2 6.0.4
mariadb 10.11 11.8
nginx 1.22.1 1.26.3
nodejs 18.13 20.19
openjdk 17.0 21.0
openssh 9.2p1 10.0p1
openssl 3.0 3.5
perl 5.36.0 5.40.1
php 8.2+93 8.4+96
podman 4.3.1 5.4.2
postfix 3.7.11 3.10.3
postgres 15 17
puppet 7.23.0 8.10.0
python3 3.11.2 3.13.5
qemu/kvm 7.2 10.0
rsync 3.2.7 3.4.1
ruby 3.1 3.3
rust 1.63.0 1.85.0
samba 4.17.12 4.22.3
systemd 252.36 257.7-1
unattended-upgrades 2.9.1 2.12
util-linux 2.38.1 2.41
vagrant 2.3.4 2.3.7
vim 9.0.1378 9.1.1230
zsh 5.9 5.9
Misc unsorted apt The new apt version 3.0 brings several new features, including: systemd systemd got upgraded from v252.36-1~deb12u1 to 257.7-1 and there are lots of changes. Be aware that systemd v257 has a new net.naming_scheme, v257 being PCI slot number is now read from firmware_node/sun sysfs file. The naming scheme based on devicetree aliases was extended to support aliases for individual interfaces of controllers with multiple ports. This might affect you, see e.g. #1092176 and #1107187, the Debian Wiki provides further useful information. There are new systemd tools available: The tools provided by systemd gained several new options: Debian s systemd ships new binary packages: Linux Kernel The trixie release ships a Linux kernel based on latest longterm version 6.12. As usual there are lots of changes in the kernel area, including better hardware support, and this might warrant a separate blog entry. To highlight some changes with Debian trixie: See Kernelnewbies.org for further changes between kernel versions. Configuration management For puppet users, Debian provides the puppet-agent (v8.10.0), puppetserver (v8.7.0) and puppetdb (v8.4.1) packages. Puppet s upstream does not provide packages for trixie, yet. Given how long it took them for Debian bookworm, and with their recent Plans for Open Source Puppet in 2025, it s unclear when (and whether at all) we might get something. As a result of upstream behavior, also the OpenVox project evolved, and they already provide Debian 13/trixie support (https://apt.voxpupuli.org/openvox8-release-debian13.deb). FYI: the AIO puppet-agent package for bookworm (v7.34.0-1bookworm) so far works fine for me on Debian/trixie. Be aware that due to the apt-key removal you need a recent version of the puppetlabs-apt for usage with trixie. The puppetlabs-ntp module isn t yet ready for trixie (regarding ntp/ntpsec), if you should depend on that. ansible is available and made it with version 2.19 into trixie. Prometheus stack Prometheus server was updated from v2.42.0 to v2.53, and all the exporters that got shipped with bookworm are still around (in more recent versions of course). Trixie gained some new exporters: Virtualization docker (v26.1.5), ganeti (v3.1.0), libvirt (v11.3.0, be aware of significant changes to libvirt packaging), lxc (v6.0.4), podman (v5.4.2), openstack (see openstack-team on Salsa), qemu/kvm (v10.0.2), xen (v4.20.0) are all still around. Proxmox already announced their PVE 9.0 BETA, being based on trixie and providing 6.14.8-1 kernel, QEMU 10.0.2, LXC 6.0.4, OpenZFS 2.3.3. Vagrant is available in version 2.3.7, but Vagrant upstream does not provide packages for trixie yet. Given that HashiCorp adopted the BSL, the future of vagrant in Debian is unclear. If you re relying on VirtualBox, be aware that upstream doesn t provide packages for trixie, yet. VirtualBox is available from Debian/unstable (version 7.1.12-dfsg-1 as of 2025-07-20), but not shipped with stable release since quite some time (due to lack of cooperation from upstream on security support for older releases, see #794466). Be aware that starting with Linux kernel 6.12, KVM initializes virtualization on module loading by default. This prevents VirtualBox VMs from starting. In order to avoid this, either add kvm.enable_virt_at_load=0 parameter into kernel command line or unload the corresponding kvm_intel / kvm_amd module. If you want to use Vagrant with VirtualBox on trixie, be aware that Debian s vagrant package as present in trixie doesn t support the VirtualBox package version 7.1 as present in Debian/unstable (manually patching vagrant s meta.rb and rebuilding the package without Breaks: virtualbox (>= 7.1) is known to be working). util-linux The are plenty of new options available in the tools provided by util-linux: Now no longer present in util-linux as of trixie: The following binaries got moved from util-linux to the util-linux-extra package: And the util-linux-extra package also provides new tools: OpenSSH OpenSSH was updated from v9.2p1 to 10.0p1-5, so if you re interested in all the changes, check out the release notes between those versions (9.3, 9.4, 9.5, 9.6, 9.7, 9.8, 9.9 + 10.0). Let s highlight some notable behavior changes in Debian: There are some notable new features: Thanks to everyone involved in the release, looking forward to trixie + and happy upgrading!
Let s continue with working towards Debian/forky. :)

18 July 2025

David Bremner: Hibernate on the pocket reform 8/n

Context

Sidequest: Fix patches continued
  • 1001-pci_dw_rockchip_enable_l0s_capability.patch doesn't apply cleanly either
  • b4 am 1744594051-209255-1-git-send-email-shawn.lin@rock-chips.com
  • This one has a usable blob index 21dc99c
  • git log --raw --all --find-object=21dc99c finds the patch already applied as 198e69cc4150aba1e7af740a2111ace6a267779e
  • 1002-v2-media_verisilicon_fix_av1_decoder_clock_frequency.patch applies cleanly

Build kernel with backported patches Back following the upstream bisect instructions from reform-debian-packages/README.md
$  apt-get install git gpg gpgv build-essential bc rsync kmod cpio bison flex libelf-dev libssl-dev debhelper libdw-dev
$ cp /boot/config-6.15.4-mnt-reform-arm64 .config
$ make olddefconfig
$ yes ''   make localmodconfig
$ make KBUILD_IMAGE=arch/arm64/boot/Image bindeb-pkg -j$(nproc)
One thing not documented there is that you need the pocket-reform dtb as well. Copy that file from reform-debian-packages, and update the relevant Makefile.
diff --git a/arch/arm64/boot/dts/rockchip/Makefile b/arch/arm64/boot/dts/rockchip/Makefile
index 26533be1dd86..83ef850cd113 100644
--- a/arch/arm64/boot/dts/rockchip/Makefile
+++ b/arch/arm64/boot/dts/rockchip/Makefile
@@ -163,6 +163,7 @@ dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-h96-max-v58.dtb
 dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-jaguar.dtb
 dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-jaguar-pre-ict-tester.dtbo
 dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-mnt-reform2.dtb
+dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-mnt-pocket-reform.dtb
 dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-nanopc-t6.dtb
 dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-nanopc-t6-lts.dtb
 dtb-$(CONFIG_ARCH_ROCKCHIP) += rk3588-ok3588-c.dtb
diff --git a/arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dts b/arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dts
new file mode 100644
index 000000000000..81533cedc200
  • With these changes I can boot in to 6.16~rc6, and log in the serial console, but the LCD display seems blank (but with some backlight power). That is probably related to the following warnings from device tree compilation
DTC     arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dtb
arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dts:1020.3-13: Warning (reg_format): /dsi@fde30000/panel:reg: property has invalid length (4 bytes) (#address-cells == 2, #size-cells == 1)
arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dtb: Warning (pci_device_reg): Failed prerequisite 'reg_format'
arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dtb: Warning (pci_device_bus_num): Failed prerequisite 'reg_format'
arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dtb: Warning (i2c_bus_reg): Failed prerequisite 'reg_format'
arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dtb: Warning (spi_bus_reg): Failed prerequisite 'reg_format'
arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dts:1018.8-1033.4: Warning (avoid_default_addr_size): /dsi@fde30000/panel: Relying on default #address-cells value
arch/arm64/boot/dts/rockchip/rk3588-mnt-pocket-reform.dts:1018.8-1033.4: Warning (avoid_default_addr_size): /dsi@fde30000/panel: Relying on default #size-cells value
  • The current source is on https://salsa.debian.org/bremner/collabora-rockchip-3588 The branch "reform-patches" is subject to rebase (and may make your computer explode).
  • For now I'm blocked on the panel, I suspect the dts file needs an update.
previous episode next episode

17 July 2025

Gunnar Wolf: About our proof-of-concept LLM tool for navigating Debian's manpages

So, for the first year, this year s DebConf had the DebConf Academic Track , that is, content for a one-day-long set of short sessions, for which of them there was a written article presenting the content often with a very academic format, but not necessarily. I hope that for future DebConfs we will continue to hold this track, and that we can help bridge the gap: to get people that are not usually from the academic / universitary prepare content that will be formally expressed and included in a long-lasting, indexed book of proceedings. We did have (informal) proceedings in many of the early DebConfs, and I m very happy to regain that, but with 20 years of better practices. Anyway, of course, I took the opportunity to join this experiment, and together with my Mexican colleague Tzolkin Gardu o who is finishing her PhD here in France (or should I say, second to her, as she is the true leading author of our work). And here you can see the paper we submitted to the DebConf Academic Track, which will be published soon: A retrieval-augmented-generation pipeline to help users query system-provided documentation The corresponding source code is all available at Tzolkin s repository in GitHub. So, what is it about, in shorter words and layman terms? Debian has lots of documentation, but lacks in discoverability. We targetted our venerable manpages: It is well known that manpages are relevant, well-organized documentation describing how to use each of the binaries we ship in Debian. Eric Raymond wrote in his well-known essay The Art of Unix Programming (2003) that the Unix cultural style is telegraphic but complete. It does not hold you by the hand, but it usualy points in the right direction. Our original intent was to digest all of the information in our manpages, but we narrowed it to only the first section of the manual due to the limitations of the hardware a good friend lent us to play with LLMs. We took four different base, redistributable (although, yes, non-DFSG-free) Large Language Models downloaded from HuggingFace (T5-small, MiniLM-L6-v2, BGE-small-en and Multilingual-e5-small), and trained them with the 34579 pages found inside /usr/share/man/man1 of all of the existing Debian packages. We did some interesting fine-tuning (for further details, please refer to the paper itself or to our GitHub repository. The idea is to present an interactive tool that udnerstand natural language queries, and answers with the specific manpage to which they better relate (I d like to say they answer best , but Tzolkin has repeatedly tried to correct my understanding of the resulting vectorial distances). I had prepared some images to present as interaction examples, but I ll wrap up this post with something even better So, this is what you would get with the following queries: We were happy to present like this. During DebCamp, however, I was able to devote some time to translating my client into a Web-accessible system. Do note that it s a bit brittle, and might break now and then. But you are welcome to play with it! Play with the Web interface for our RAG for Debian manuals! I find it worth sharing that, while we used quite a bit of GPU for the training (not too much a couple of nights on an old-although-powerful nVidia 1070 card lent to us by the Felipe Esquivel Fund for Science and Cultural Support), all querying takes place in the CPU, and I usually get between 0.1 and 0.3 seconds per query. My server s architecture is far from rock-solid, and it can break now and then but at least it should respawn upon failure And it should at least be available there for a couple of weeks into August. Anyway, this has been a very interesting journey getting my toes wet in the waters of LLM, and while current results are a bit crude, I think this can be made into an interesting tool for Debian exploration.
Next.

Previous.