Search Results: "andy"

15 May 2013

Daniel Kahn Gillmor: OpenPGP User ID Comments considered harmful

Most OpenPGP User IDs look like this:
Jane Q. Public <jane@example.org>
This is clean, clear, and unambiguous. However, some tools (gpg, enigmail among others) ask the user to provide a "Comment:" field when they are choosing a new User ID (e.g. when making a new key). These UI prompts are evil. The savvy user knows to avoid entering anything in this field, so that they can end up with a User ID like the one above. The user who provides something here (perhaps even something inconsequential like "I like strawberries", due to not being sure what should go in this little box) will instead end up with a User ID like:
Jane Q. Public (I like strawberries) <jane@example.org>
This is bad. This means that Jane is asking the people who certify her key+userid to certify whether she actually likes strawberries (how could they know? what if she changes her mind? should they revoke their certifications?) and anywhere that she is referred to by name will include this mention of strawberries. This is not Jane's identity, and it doesn't belong in an OpenPGP User ID packet. Furthermore, since User IDs are atomic, if Jane wants to change the comment field (but leave her name and e-mail address the same), she will instead need to create a new User ID, publish it, get everyone who has certified her old key+userid to certify the key+newuserid, and then revoke the old one. It is difficult already to help people understand and participate in the certification network that forms that backbone of OpenPGP's so-called "web of trust". These bogus comment fields make an already-difficult task harder. And all because of strawberries! Tools like enigmail and gpg should not expose the "Comment:" field to users who are generating keys or choosing new User IDs. If they feel it absolutely must be present for some weird corner case that 0.1% of their users will have, they could require that the user enters some sort of "expert mode" before prompting the user to do something that is likely to be a mistake. There is almost no legitimate reason for anyone to use this field. Let's go through some examples of this people use, taken from some examples i have lying around (identifying marks have been changed to protect the innocent who were duped by this bad UI choice, but you can probably find them on the public keyserver network if you want to hunt around):
domain repetition
John Q. Public (Debian) <johnqpublic@debian.org>
We know you're with debian already from the @debian.org address. If this is in contrast to your other address (johnqpublic@example.org) so that people know where to send you debian-related e-mail, this is still not necessary. Lest you think i'm just calling out debian developers, people with @ubuntu.com addresses and (Ubuntu) comments (as well as @example.edu addresses and (Example University) comments and @example.com addresses and (Example Corp) comments) are out there too.
nicknames already evident
John Q. Public (Johnny) <johnqpublic@example.net>
John Q. Public (wackydude) <wackydude@example.net>
Again, the information these comments are providing offers no clear disambiguation from the info already contained in the name and e-mail address, and just muddies the water about what the people who certify this identity should actually be trying to verify before they make their certification.
"Work"
John Q. Public (Work) <johnqpublic@example.com>
if John's correspondents know that he works for Example Corp, then "Work" isn't helpful to them, because they already know this as the address that they're writing to him with. If they don't know that, then they probably aren't writing to him at work, so they don't need this comment either. The same problem appears (for example) with literal comments of (School) next to their @example.edu address.
This is my nth try at this crazy system!
John Q. Public (This is my second key) <johnqpublic@example.com>
John Q. Public (This is my primary key) <johnqpublic@example.com>
John Q. Public (No wait really use this one) <johnqpublic@example.com>
OpenPGP is confusing, and it can be tricky to get it right. We all know :) This is still not part of John's identity. If you want to designate a key as your preferred key, keep it up-to-date, get people to certify it, and revoke or expire your old keys. People who care can look at the timestamps on your keys and tell which ones are the most recent ones. You do have a revocation certificate for your key handy just in case you lose it, right?
Don't use this key
John Q. Public (Old key, do not use) <johnqpublic@example.com>
John Q. Public (Please only use this through September 2004) <johnqpublic@example.com>
This kind of sentiment is better expressed by revoking the key in question or setting an expiration time on the key or User ID self-sig directly. This sentiment is not part of John's identity, and shouldn't be included as though it were.
"none"
John Q. Public (none) <johnqpublic@example.com>
sigh. This is clearly someone getting mixed up by the UI.
I use strong crypto!
John Q. Public (3092 bits of RSA) <johnqpublic@example.com>
This comment refers to the strength of the key material, or the algorithms preferred by the user. Since the User ID is associated with the key material already, people who care about this information can get it from the key directly. This is also not part of the user's actual identity.
"no comment"
John Q. Public (no comment) <johnqpublic@example.com>
This is actually not uncommon (some keyservers reply "too many matches!"). It shows that the user is witty and can think on their feet (at least once), but it is still not part of the user's identity.
But wait (i hear you say)! I have a special case that actually is a legitimate use of the comment field that cannot be expressed in OpenPGP in any other way! I'm sure that such cases exist. I've even seen one or two of them. The fact that one or two cases exist does not excuse the fact that that overwhelming majority of these comments in OpenPGP User IDs are a mistake, caused only by bad UI design that prompts people to put something (anything!) in the empty box (or on the command prompt, depending on your preference). And this mistake is one of the thousand papercuts that inhibits the robust growth of the OpenPGP certification network that some people call the "web of trust". Let's avoid them so we can focus on the other 999 papercuts. Please don't use comments in your OpenPGP User ID. And if you make a user interface for OpenPGP that prompts the user to decide on a new User ID, please don't include a prompt for "Comment" unless the user has already certified that they are really and truly a special special snowflake. Thanks!Tags: openpgp, ui

10 May 2013

Julien Danjou: Rant about Github pull-request workflow implementation

One of my recent innocent tweet about Gerrit vs Github triggered much more reponses and debate that I expected it to. I realize that it might be worth explaining a bit what I meant, in a text longer than 140 characters. <script async="async" charset="utf-8" src="http://platform.twitter.com/widgets.js"></script> The problems with Github pull-requests I always looked at Github from a distant eye, mainly because I always disliked their pull-request handling, and saw no value in the social hype it brings. Why? One click away isn't one click effort The pull-request system looks like an incredible easy way to contribute to any project hosted on Github. You're a click away to send your contribution to any software. But the problem is that any worthy contribution isn't an effort of a single click. Doing any proper and useful contribution to a software is never done right the first time. There's a dance you will have to play. A slowly rhythmed back and forth between you and the software maintainer or team. You'll have to dance it until your contribution is correct and can be merged. But as a software maintainer, not everybody is going to follow you on this choregraphy, and you'll end up with pull-request you'll never get finished unless you wrap things up yourself. So the gain in pull-requests here, isn't really bigger than a good bug report in most cases. This is where the social argument of Github isn't anymore. As soon as you're talking about projects bigger than a color theme for your favorite text editor, this feature is overrated. Contribution rework If you're lucky enough, your contributor will play along and follow you on this pull-request review process. You'll make suggestions, he will listen and will modify his pull-request to follow your advice. At this point, there's two technics he can use to please you. Technic #1: the Topping Github's pull-requests invite you to send an entire branch, eclipsing the fact that it is composed of several commits. The problem is that a lot of one-click-away contributors do not masterize Git and/or do not make efforts to build a logical patchset, and nothing warns them that their branch history is wrong. So they tend to change stuff around, commit, make a mistake, commit, fix this mistake, commit, etc. This kind of branch is composed of the whole brain's construction process of your contributor, and is a real pain to review. To the point I quite often give up. <figure> <figcaption> A typical case: 3 commits to build a 4 lines long file. </figcaption> </figure> Without Github, the old method that all software used, and that many software still use (e.g. Linux), is to send a patch set over e-mail (or any other medium like Gerrit). This method has one positive effect, that it forces the contributor to acknowledge the list of commits he is going to publish. So, if the contributor he has fixup commits in his history, they are going to be seen as first class citizen. And nobody is going to want to see that, neither your contributor, nor the software maintainers. Therefore, such a system tend to push contributors to write atomic, logical and self-contained patchset that can be more easily reviewed. Technic #2: the History Rewriter This is actually the good way to build a working and logical patchset using Git. Rewriting history and amending problematic patches using the famous git rebase --interactive trick. The problem is that if your contributor does this and then repush the branch composing your pull-request to Github, you will both lose the previous review done, each time. There's no history on the different versions of the branch that has been pushed. In the old alternative system like e-mail, no information is lost when reworked patches are resent, obviously. This is far better because it eases the following of the iterative discussions that the patch triggered. Of course, it would be possible for Github to enhance this and fix it, but currently it doesn't handle this use case correctly.. <figure> <figcaption> Exercise for the doubtful readers: good luck finding all revisions of my patch in the pull-request #157 of Hy.</figcaption> </figure> A quick look at OpenStack workflow It's not a secret for anyone that I've been contributing to OpenStack as a daily routine for the last 18 months. The more I contribute, the more I like the contribution workflow and process. It's already well and longly described on the wiki, so I'll summarize here my view and what I like about it. Gerrit To send a contribution to any OpenStack project, you need to pass via Gerrit. This is way simpler than doing a pull-request on Github actually, all you have to do is do your commit(s), and type git review. That's it. Your patch will be pushed to Gerrit and available for review. Gerrit allows other developers to review your patch, add comments anywhere on it, and score your patch up or down. You can build any rule you want for the score needed for a patch to be merged; OpenStack requires one positive scoring from two core developers before the patch is merged. Until a patch is validated, it can be reworked and amended locally using Git, and then resent using git review again. That simple. The historic and the different version of the patches are available, with the whole comments. Gerrit doesn't lose any historic information on your workflow. Finally, you'll notice that this is actually the same kind of workflow projects use when they work by patch sent over e-mail. Gerrit just build a single place to regroup and keep track of patchsets, which is really handy. It's also much easier for people to actually send patch using a command line tool than their MUA or git send-email. Gate testing Testing is mandatory for any patch sent to OpenStack. Unit tests and functionnals test are run for each version of each patch of the patchset sent. And until your patch passes all tests, it will be impossible to merge it. Yes, this implies that all patches in a patchset must be working commits and can be merged on their own, without the entire patchset going in! With such a restricution, it's impossible to have "fixup commits" merged in your project and pollute the history and the testability of the project. Once your patch is validated by core developers, the system checks that there is not any merge conflicts. If there's not, tests are re-run, since the branch you are pushing to might have changed, and if everything's fine, the patch is merged. This is an uncredible force for the quality of the project. This implies that no broken patchset can ever sneak in, and that the project pass always all tests. Conclusion: accessibility vs code review In the end, I think that one of the key of any development process, which is code review, is not well covered by Github pull-request system. It is, along with history integrity, damaged by the goal of making contributions easier. Choosing between these features is probably a trade-off that each project should do carefully, considering what are its core goals and the quality of code it want to reach. I tend to find that OpenStack found one of the best trade-off available using Gerrit and plugging testing automation via Jenkins on it, and I would probably recommend it for any project taking seriously code reviews and testing.

28 April 2013

Mart&iacute;n Ferrari: Moving my stuff away from home

TL;DR version: I want to get rid of the small server running at home, I tell you here about the service I've chosen, and why I like it. In following posts, I'll explain how did I set it up remotely. Disclaimer: I am in now way affiliated with the companies I mention here (except for Picasa, as I am a Google employee), and don't get any bonuses for this post. I am only sharing this because I think it might be useful information for other people.
Being a frequent migrant means possessions are a burden. In my previous place of residence (in France), I originally intended to only stay for 6 months, and so I arrived with just a couple of suitcases, and in the end that was enough for me to live for almost 2 years. The last time, on the other hand, I was removing my stuff completely from Argentina. I emptied my house, gave away some stuff, send some boxes to my parents' place, and carried the rest with me. That was a lot of stuff, but since the company was paying for the relocation, it was not much of a problem. Later I realised my mistake, and knowing that my time in Ireland is limited, I started to try and get rid of stuff I don't need. I know I will just sell or give away much of my stuff when I finally leave, but there are some things that are not so easy to part with. The main one being my home server, which hosts this website, my VCS repositories, pictures, and many other things I need to have on the net. This all used to be located in a home-made PC tucked in a data centre, co-located by a friendly company. But that computer died almost 2 years ago, and so canterville became abhean, and my stuff started being hosted with my aDSL connection. It worked well for some time, but now I realised I had to revert that change. With this in mind I set off to find a cheap place to host my stuff. I had a few requirements: I don't have that many photos, nor they are too big, but these requirements made it clear that most VPS offerings were not going to work for me. For some reason I fail to understand, local storage in VPS offerings is usually prohibitively expensive. This is OK for most use cases, but not for mine. A friend of mine, with a similar use case, is a happy VPS customer. He told me his trick: he only hosts in the server low-quality versions of the pictures, and keeps the originals (and back-ups) at home. This was a great idea, but with two fatal flaws: I want to only carry around a laptop and one or two external hard drives; and I want to have back-ups that are not physically with me. I was starting to think about hosting my files in Amazon s3 or something like that, since most dedicated servers are way too expensive. But then I heard about two French companies offering dirt-cheap servers: OVH and Online.net. Both of them offered small servers for about 12 a month, cheaper than most VPS offerings! Online seems to mainly cater to the French market, and for some silly reason, they charge a 50 set-up fee to customers outside of France. OVH, on the other hand, has many local branches, including an Irish one, so I went with them. The offering is a low-cost line called Kimsufi, and the smallest one is still very decent for a personal server: Once I had paid the fee for one month, it took a while for it to be activated (their payment system is pretty bad), but it finally was enabled about 24h later. Then the real fun started. On one hand, I was happy to see a wide selections of operating systems to choose from, including Debian stable and testing, and a web console with many functionalities, including some basic monitoring; but on the other hand, I realised that the installed image was not pristine, the online docs are not very good, and the web application is a bit buggy and really awkward to navigate. Having sub-par docs is not something I would usually care much about, but it made it a bit more difficult to me to understand some of the very cool functionalities their system offers (more on that in a bit), and more importantly, it made it clear to me that I won't trust their image: the procedures detailed there were not exactly best-practices, and they allow themselves to log-in as root into my server. I want to describe here what I think are their most interesting features, that made it possible to me to do risky operations, like encrypting the root partition, and setting up a firewall; and being able to fix problems that would usually require physical access. These are found in their web console: a hardware reset, and configurable netboot support with many offered images, including a rescue image based on Ubuntu and one that serves as a virtual KVM. (It is surprising that these servers don't have a serial console, but at least the kernel does not detect any). With these in hand, I didn't have to fear being locked out of my server for ever. Just set up a netboot image and hard-reboot the machine! Also, it made it very simple to install my system from scratch with debootstrap. The virtual KVM is a very interesting trick. It is a netboot image that runs some tests, and fires up a web browser. You get an email with the URL and a password to access it, and then you open a page that offers you what is basically a Qemu connected to a VNC server which will boot from your real hard drive. It is super slow, but that allows you to get console access to your server, which can be very handy to debug booting problems, unless it is some issue with the real hardware. It also offers the possibility of downloading an ISO image off the network and booting that, so it can be used to run a stock installer CD too. In another post I'll describe how I reinstalled my server remotely, and some of the pitfalls that I've encountered in the process.

26 April 2013

Ian Campbell: Generating Random MAC Addresses

Working with virtualisation I find myself occasionally needing to generate a random MAC address for use with a virtual machine. I have a stupid little local script which spits one out, which is all fine and dandy for my purposes. However this week one of my colleagues was writing a wiki page and needed to include instructions on how to set the MAC address on the Arndale board. He wanted to include a shell snippet to generate one and I suggested that there must be websites which will generate you a suitable address. But when I came to look we found that not a single one of the half a dozen site which I looked at handled the locally administered or multicast bits correctly, meaning that they would randomly generate either multicast addresses or addresses using assigned OUI (or both). Using a random OUI may not cause too much trouble in practice but using a multicast address is sure to lead to strange behaviour, and in any case it's kind of lame. So last night I sat down and wrote a quick hack cgi script to generate random addresses and tonight I deployed it at: http://www.hellion.org.uk/cgi-bin/randmac.pl. This is where the world and his dog leaves a comment pointing me to the existing service my searches missed...

25 April 2013

Julien Danjou: OpenStack Design Summit Havana, from a Ceilometer point of view

Last week was the OpenStack Design Summit in Portland, OR where we, developers, discussed and designed the new OpenStack release (Havana) coming up. The summit has been wonderful. It was my first OpenStack design summit -- even more as a PTL -- and bumping into various people I've never met so far and worked with online only was a real pleasure! <figure> <figcaption>Me and Nick ready to talk about Ceilometer new features.</figcaption> </figure> Nick Barcet from eNovance, our dear previous Ceilometer PTL, and myself, talked about Ceilometer and presented the work that bas been done for Grizzly, with some previews of what we'll like to see done for its Havana release. You can take a look at the slides if you're curious. Design sessions Ceilometer had his design sessions during the last days of the summit. We noted a lot of things and commented during the sessions in our Etherpads instances. The first session was a description of Ceilometer core architecture for interested people, and was a wonderful success considering that the room was packed. Our Doug Hellmann did a wonderful job introducing people to Ceilometer and answering question. <figure> <figcaption>Doug explaining Ceilometer architecture.</figcaption> </figure> The next session was about getting feedbacks from our users. We had a lot of surprise to discover wonderful real use-cases and deployments, like the CERN using Ceilometer and generating 2 GB of data per day! The following sessions ran on Thursday and were much more about new features discussion. A lot ot already existing blueprints were discussed and quickly validated during the first morning session. Then, Sandy Walsh introduced the architecture they use inside StackTach, so we can start thinking about getting things from it into Ceilometer. API improvements were discussed without surprises and with a good consensus on what needs to be done. The four following sessions that occupied a lot of the days were related to alarming. All were lead by Eoghan Glynn, from RedHat, who did an amazing job presenting the possible architectures with theirs pros and cons. Actually, all we had to do was to nod to his designs and acknowledge the plan on how to build this. That last two sessions were about discussing advanced models for billing where we got some interesting feedback from Daniel Dyer from HP, and then were a quick follow-up of the StackTach presentation from the morning session. Havana roadmap The list of blueprints targetting Havana is available and should be finished by next week. If you want to propose blueprints, you're free to do so and inform us about it so we can validate it. The same applies if you wish to implement one of them! API extension I do think the API version 2 is going to be heavily extended during this release cycle. We need more feature, like the group-by functionnality. Healthnmon In parallel of the design sessions, discussions took place in the unconference room with the Healthnmon developers to figure out a plan in order to merge some of their efforts into Ceilometer. They should provide a component to help Ceilometer supports more hypervisors than it currently does. Alarming Alarming is definitely going to be the next big project for Ceilometer. Today, Eoghan and I started building blueprints on alarming, centralized in a general blueprint. We know this is going to happen for real and very soon, thanks to the engagements of eNovance and RedHat who are commiting resources to this amazing project!

11 April 2013

Matthew Palmer: RSpec the easy way

Anyone that has a fondness for good ol RSpec knows that there s a fair number of matchers and predicates and whatnot involved. Life isn t helped by the recent (as of 2.11) decision to switch to using expect everywhere instead of should (apparently should will be going away entirely at some point in the future). There is a good looking RSpec cheatsheet out on the net, but it dates from 2006, and things have changed since then. We re using RSpec at work a lot at the moment, though, so our tech writer kindly updated it for the new-style syntax, gave it a nice blue tint, and put it out there for the world at large to use. Here is our updated RSpec cheatsheet for anyone who is interested. I can tell you for certain that a double-sided, laminated version of this sucker looks very nice, and is a handy addition to the desk-of-many-things.

24 March 2013

Ben Armstrong: Debugging the installer on Debian Live

I ve been using this process for debugging the installer while launched from a Debian Live desktop. Having a full live environment at your disposal during install is a boon to debugging because you don t have to work within the constraints normally imposed upon you by the limited debian-installer environment. Caveat: running debian-installer from the debian-installer-launcher still has one or two unresolved issues, so unless you re specifically working on live integration issues like I am, compare with a conventional d-i image install to gain the added confidence the install is the same in both environments. There are no longer active maintainers working on debian-installer-launcher and live-installer, and I think it s really important for wheezy to release with solid support for live installs, so I ve been using this setup to try to solve #702335. So far, progress is slow because I m new to this. If anyone is interested in collaborating in this work, give me a shout. I am SynrG @ irc.oftc.net and can be found on #debian-live and #debian-boot if you would like to drop in. Overview:
  1. Use images/lxde-desktop config from live-images.git and build your own image with live-build >=3.0.1-1. Just add -b hdd in auto/config before starting your build, as having a read/writable image is handy for this exercise.
  2. Boot the live medium. You may prefer to do this in a VM for convenience, having prepared a blank virtual disk image as your target in advance.
  3. Make any small changes you want to the installer before launching it. A quick hack I ve used is to sudo vi /usr/sbin/debian-installer-launcher and near the end on the line after prepare right before run , open a new line and add bash so an interactive shell will be opened after the installer is extracted but before it is launched. For larger changes (e.g. inclusion of updated udebs, etc.) add them to your live image configuration before building as described in live-manual.
  4. Open two root terminals and do debian-installer-launcher -t debug in one and tail -f /lib/live/installer/var/log/syslog in the other. If you ve added the hack from step 3, don t forget to exit the interactive shell after making changes. Now you can watch debug output as you go through the steps of the installer. If you like, you may append additional boot prompt parameters (e.g. preseeds) to the debian-installer-launcher command.
  5. During the install, you may modify other parts of the unpacked installer under /lib/live/installer (e.g. to add set -x to some scripts) prior to executing steps that would call them.

20 March 2013

Raphael Geissert: A bashism a week: substrings

Sometimes obtaining a substring in a shell script is needed. The bashism of this week comes handy as it allows one to obtain a substring by indicating the offset and even the length of the substring. This is the $ varname:offset:length bashism, also known as substring expansion.

The portable "replacements" are simple if the offset (and the length) are static. For example, the following code would print the substring of "foo" consisting of only the last two characters:
var=foo
# Replace the bashism $ var:1 with:
echo $ var#?

The length can then be limited with additional pattern-matching removal expansions:
var="portable code"
# Replace the bashism $ var:3:5 with the following code

# Offset is 3, so we use three ? (interrogation) characters:
part=$ var#???

# Length is 5, so we use five ? characters:
echo $ part%$ part#?????

As it can be seen, it is not impossible to replace a substring expansion.

The portable code becomes slightly more complex if the offset and/or the length are dynamic. I leave that as an exercise for the readers.

Feel free to post your code as a comment (use the <pre> tags, please) or in another public way. My own response is already scheduled to be published next week at the same time as usual.

Note: substring expansions can also be replaced with a wide variety of external commands. This is a pure-POSIX shell scripting example.

11 March 2013

Lars Wirzenius: Thinkpad X200s scroll wheel emulation

Daniel told me how to set up scroll wheel emulation on a Thinkpad. Presumably it works on other systems as well, but the magic numbers for xinput may be different. I wrote a script to set it up, and configure my GNOME session to run it upon login. The result: pressing the middle mouse button and moving the trackpoint up/down or left/right results in the applications receiving events as if a scroll wheel had been used. Very, very handy. Thanks, Daniel.
#!/bin/sh
set -eu
id=$(xinput list   sed -n '/TPPS\/2 IBM TrackPoint/s/.*id=\([0-9]\+\).*/\1/p')
emu=$(xinput list-props "$id"   
    sed -n '/Evdev Wheel Emulation (/s/.*(\([0-9]\+\)).*/\1/p')
but=$(xinput list-props "$id"   
    sed -n '/Evdev Wheel Emulation Button (/s/.*(\([0-9]\+\)).*/\1/p')
axs=$(xinput list-props "$id"   
    sed -n '/Evdev Wheel Emulation Axes (/s/.*(\([0-9]\+\)).*/\1/p')
xinput set-int-prop "$id" "$emu" 8 1
xinput set-int-prop "$id" "$but" 8 2
#xinput set-int-prop "$id" "$axs" 8 6 7 4 5

21 February 2013

Tanguy Ortolo: One archiver to rule them all: bsdtar

Package icon Sometimes, you have to use ZIP archives, or worse, RAR archives (curse them!), with one significant annoyance: zip, unzip, rar and unrar use a rather uncommon command line convention, compared to the usual tar, cpio and pax.This is where bsdtar and bsdcpio come handy: these two equivalent tools from FreeBSD do not directly implement any archive format, relying on libarchive to do that instead. That allows you to do thinks like:
% bsdtar -tf crap.rar
% bsdtar -xf crap.rar
% bsdtar --format zip -cf stuff.zip stuff
Too bad it does not have a -a option to automatically select the archive format as GNU tar does.

8 February 2013

Olivier Berger: RDF development in PHP with a PostGreSQL triple store thanks to the LibRDF OO wrapper for redland/librdf

Redland/librdf offers powerful features like being able to persist an RDF model to a relational database (only PostGreSQL seems to work on my setup with 1.0.16, but I may have misconfigured it). You can then do SPARQL queries over the model, and lots of other nice things. Unfortunately, the default PHP bindings are not really object-oriented, so the code isn t looking so good. But thanks to a gentleman named David Shea, there is an object-oriented library named LibRDF (case is sensitive), that helps write nice looking PHP. I discovered it via the blog post of Felix Ostrowski, who took over the maintenance of the LibRDF library (still the docs live on the original author s site). In his post, Felix illustrates how you may use it to parse Richard Cyganiak s FOAF profile. But the examples he gives don t illustrate the full potential of persistence of the RDF graph into the DB. Here s my contribution in 2 examples that will hopefully help : first, one that load Richard s FOAF to the DB, and one, that later retrieve the saved model and perform the same query (both pushed to my github clone of the library). There may be some problems with the use of librdf, including its availability, as it is not full PHP of course and I ve heard of memory management problems, but, depening on your needs, this may be quite handy for writing Linked Data applications.

6 February 2013

Biella Coleman: Edward Tufte was a phreak

It has been so very long since I have left a trace here. I guess moving to two new countries (Canada and Quebec), starting a new job, working on Anonymous, and finishing my first book was a bit much. I miss this space, not so much because what I write here is any good. But it a handy way for me to keep track of time and what I do and even think. My life feels like a blur at times and hopefully here I can see its rhythms and changes a little more clearly if I occasionally jot things down here. So I thought it would nice to start with something that I found surprising: famed information designer, Edward Tufte, a professor emeritus at Yale was a phone phreak (and there is a stellar new book on the topic by former phreak Phil Lapsley. He spoke about his technological exploration during a sad event, a memorial service in NYC which I attended for the hacker and activist Aaron Swartz. I had my wonderful RA transcribe the speech, so here it is [we may not have the right spelling for some of the individuals so please let us know of any mistakes]:
Edward Tufte s Speech From Aaron Swartz s Memorial
Speech starts 41:00 [video cuts out in beginning]
We would then meet over the years for a long talk every now and then, and my responsibility was to provide him with a reading list, a reading list for life and then about two years ago Quinn had Aaron come to Connecticut and he told me about the four and a half million downloads of scholarly articles and my first question is, Why isn t MIT celebrating this? .
[Video cuts out again]
Obviously helpful in my career there, he then became president of the Mellon foundation, he then retired from the Mellon foundation, but he was asked by the Mellon foundation to handle the problem of JSTOR and Aaron. So I wrote Bill Bullen(sp?) an email about it, I said first that Aaron was a treasure and then I told a personal story about how I had done some illegal hacking and been caught at it and what happened. In 1962, my housemate and I invented the first blue box, that s a device that allows for free, undetectable, unbillable long distance telephone calls. And we got this up and played around with it and the end of our research came when we concluded what was the longest long distance call ever made, which was from Palo Alto to New York time-of-day via Hawaii, well during our experimentation, AT&T, on the second day it turned out, had tapped our phone and uh but it wasn t until about 6 months later when I got a call from the gentleman, AJ Dodge, senior security person at AT&T and I said, I know what you re calling about. and so we met and he said You what you are doing is a crime that would , you know all that. But I knew it wasn t serious because he actually cared about the kind of engineering stuff and complained that the tone signals we were generating were not the standard because they record them and play them back in the network to see what numbers they we were that you were trying to reach, but they couldn t break though the noise of our signal. The upshot of it was that uh oh and he asked why we went off the air after about 3 months, because this was to make long distance telephone calls for free and I said this was because we regarded it as an engineering problem and we made the longest long distance call and so that was it. So the deal was, as I explained in my email to Bill Bullen, that we wouldn t try to sell this and we were told, I was told that crime significance would pay a great deal for this, we wouldn t do any more of it and that we would turn our equipment over to AT&T, and so they got a complete vacuum tube isolator kit for making long distance phone calls. But I was grateful for AJ Dodge and I must say, AT&T that they decided not to wreck my life. And so I told Bill Bullen that he had a great opportunity here, to not wreck somebody s life, course he thankfully did the right thing.
Aaron s unique quality was that he was marvelously and vigorously different. There is a scarcity of that. Perhaps we can be all a little more different too.
Thank you very much.

30 January 2013

Wouter Verhelst: HOWTO: create a PXE netboot debian-installer image with firmware files

Debian-installer is a great piece of software, which allows one to install the system in a variety of situations: manually, on a serial console, graphically, automatically, there are a number of scenarios it handles well. However, there is one issue: when installing Debian to a machine that requires firmware just to get at the network, getting things to work can be a hassle. There is a tarball containing the most-often required firmware blobs in order to be able to use the installer on such systems; but since they fail the DFSG, these cannot be part of Debian, for political reasons. To use them, you need to write the required firmware packages to a directory "/firmware" on a USB stick or similar, and put that in the system when asked. This is acceptable when you have just one system to install and have a USB stick handy; but if you have a lot of systems to install, or (as recently happened to me) you don't have a USB stick handy, then things become slightly more problematic. Luckily, there's an easy solution: you can update the initrd image so it contains the firmware packages already on it; when doing that, you don't need to deal with USB sticks anymore. Of course, using such an initrd image will cause the installer to automatically install all provided firmware packages, even if your hardware will function (at a basic level) without said firmware. Additionally, if you pass firmware packages to the installer in any way (through a USB stick, or through the method I'm about to describe, that makes no difference), and the installer determines that it might help to install one of these firmware packages, then the installed system will have them installed, and have the non-free repository enabled, which is not the default. Don't do this if you don't want that. Anyway, on to the actual procedure now: Tadaa! You've now created an initrd image that will not ask you for firmware images, instead just install them.

Raphael Geissert: A bashism a week: sleep

To delay execution of some commands in a shell script, the sleep command comes handy.
Even though many shells do not provide it as a built-in and the GNU sleep command is used, there are a couple of things to note:


This of course is regarding what is required by POSIX:2001; it only requires the sleep command to take an unsigned integer. FreeBSD's sleep command does accept fractions of seconds, for example.

Remember, if you rely on any non-standard behaviour or feature make sure you document it and, if feasible, check for it at run-time.

In this case, since the sleep command is not required to be a built-in, it does not matter what shell you specify in your script's shebang. Moreover, calling /bin/sleep doesn't guarantee you anything. The exception is if you specify a shell that has its own sleep built-in, then you could probably rely on it.

The easiest replacement for suffixes is calculating the desired amount of time in seconds. As for the second case, you may want to reconsider your use of a shell script.

29 January 2013

Daniel Kahn Gillmor: visualizing MIME structure

Better debugging tools can help us understand what's going on with MIME messages. A python scrap i wrote a couple years ago named printmimestructure has been very useful to me, so i thought i'd share it. It reads a message from stdin, and prints a visualisation of its structure, like this:
0 dkg@alice:~$ printmimestructure < 'Maildir/cur/1269025522.M338697P12023.monkey,S=6459,W=6963:2,Sa' 
 multipart/signed 6546 bytes
  text/plain inline 895 bytes
  application/pgp-signature inline [signature.asc] 836 bytes
0 dkg@alice:~$ 
You can fetch it with git if you like:
git clone git://lair.fifthhorseman.net/~dkg/printmimestructure
It feels silly to treat this ~30 line script as its own project, but i don't know of another simple tool that does this. If you know of one, or of something similar, i'd love to hear about it in the comments (or by sending me e-mail if you prefer). If it's useful for others, I'd be happy to contribute printmimestructure to a project of like-minded tools. Does such a project exist? Or if people think it would be handy to have in debian, i can also package it up, though that feels like it might be overkill. and oh yeah, as always: bug reports, suggestions, complaints, and patches are welcome :)Tags: debugging, mime, python

27 January 2013

Russell Coker: LCA 2012

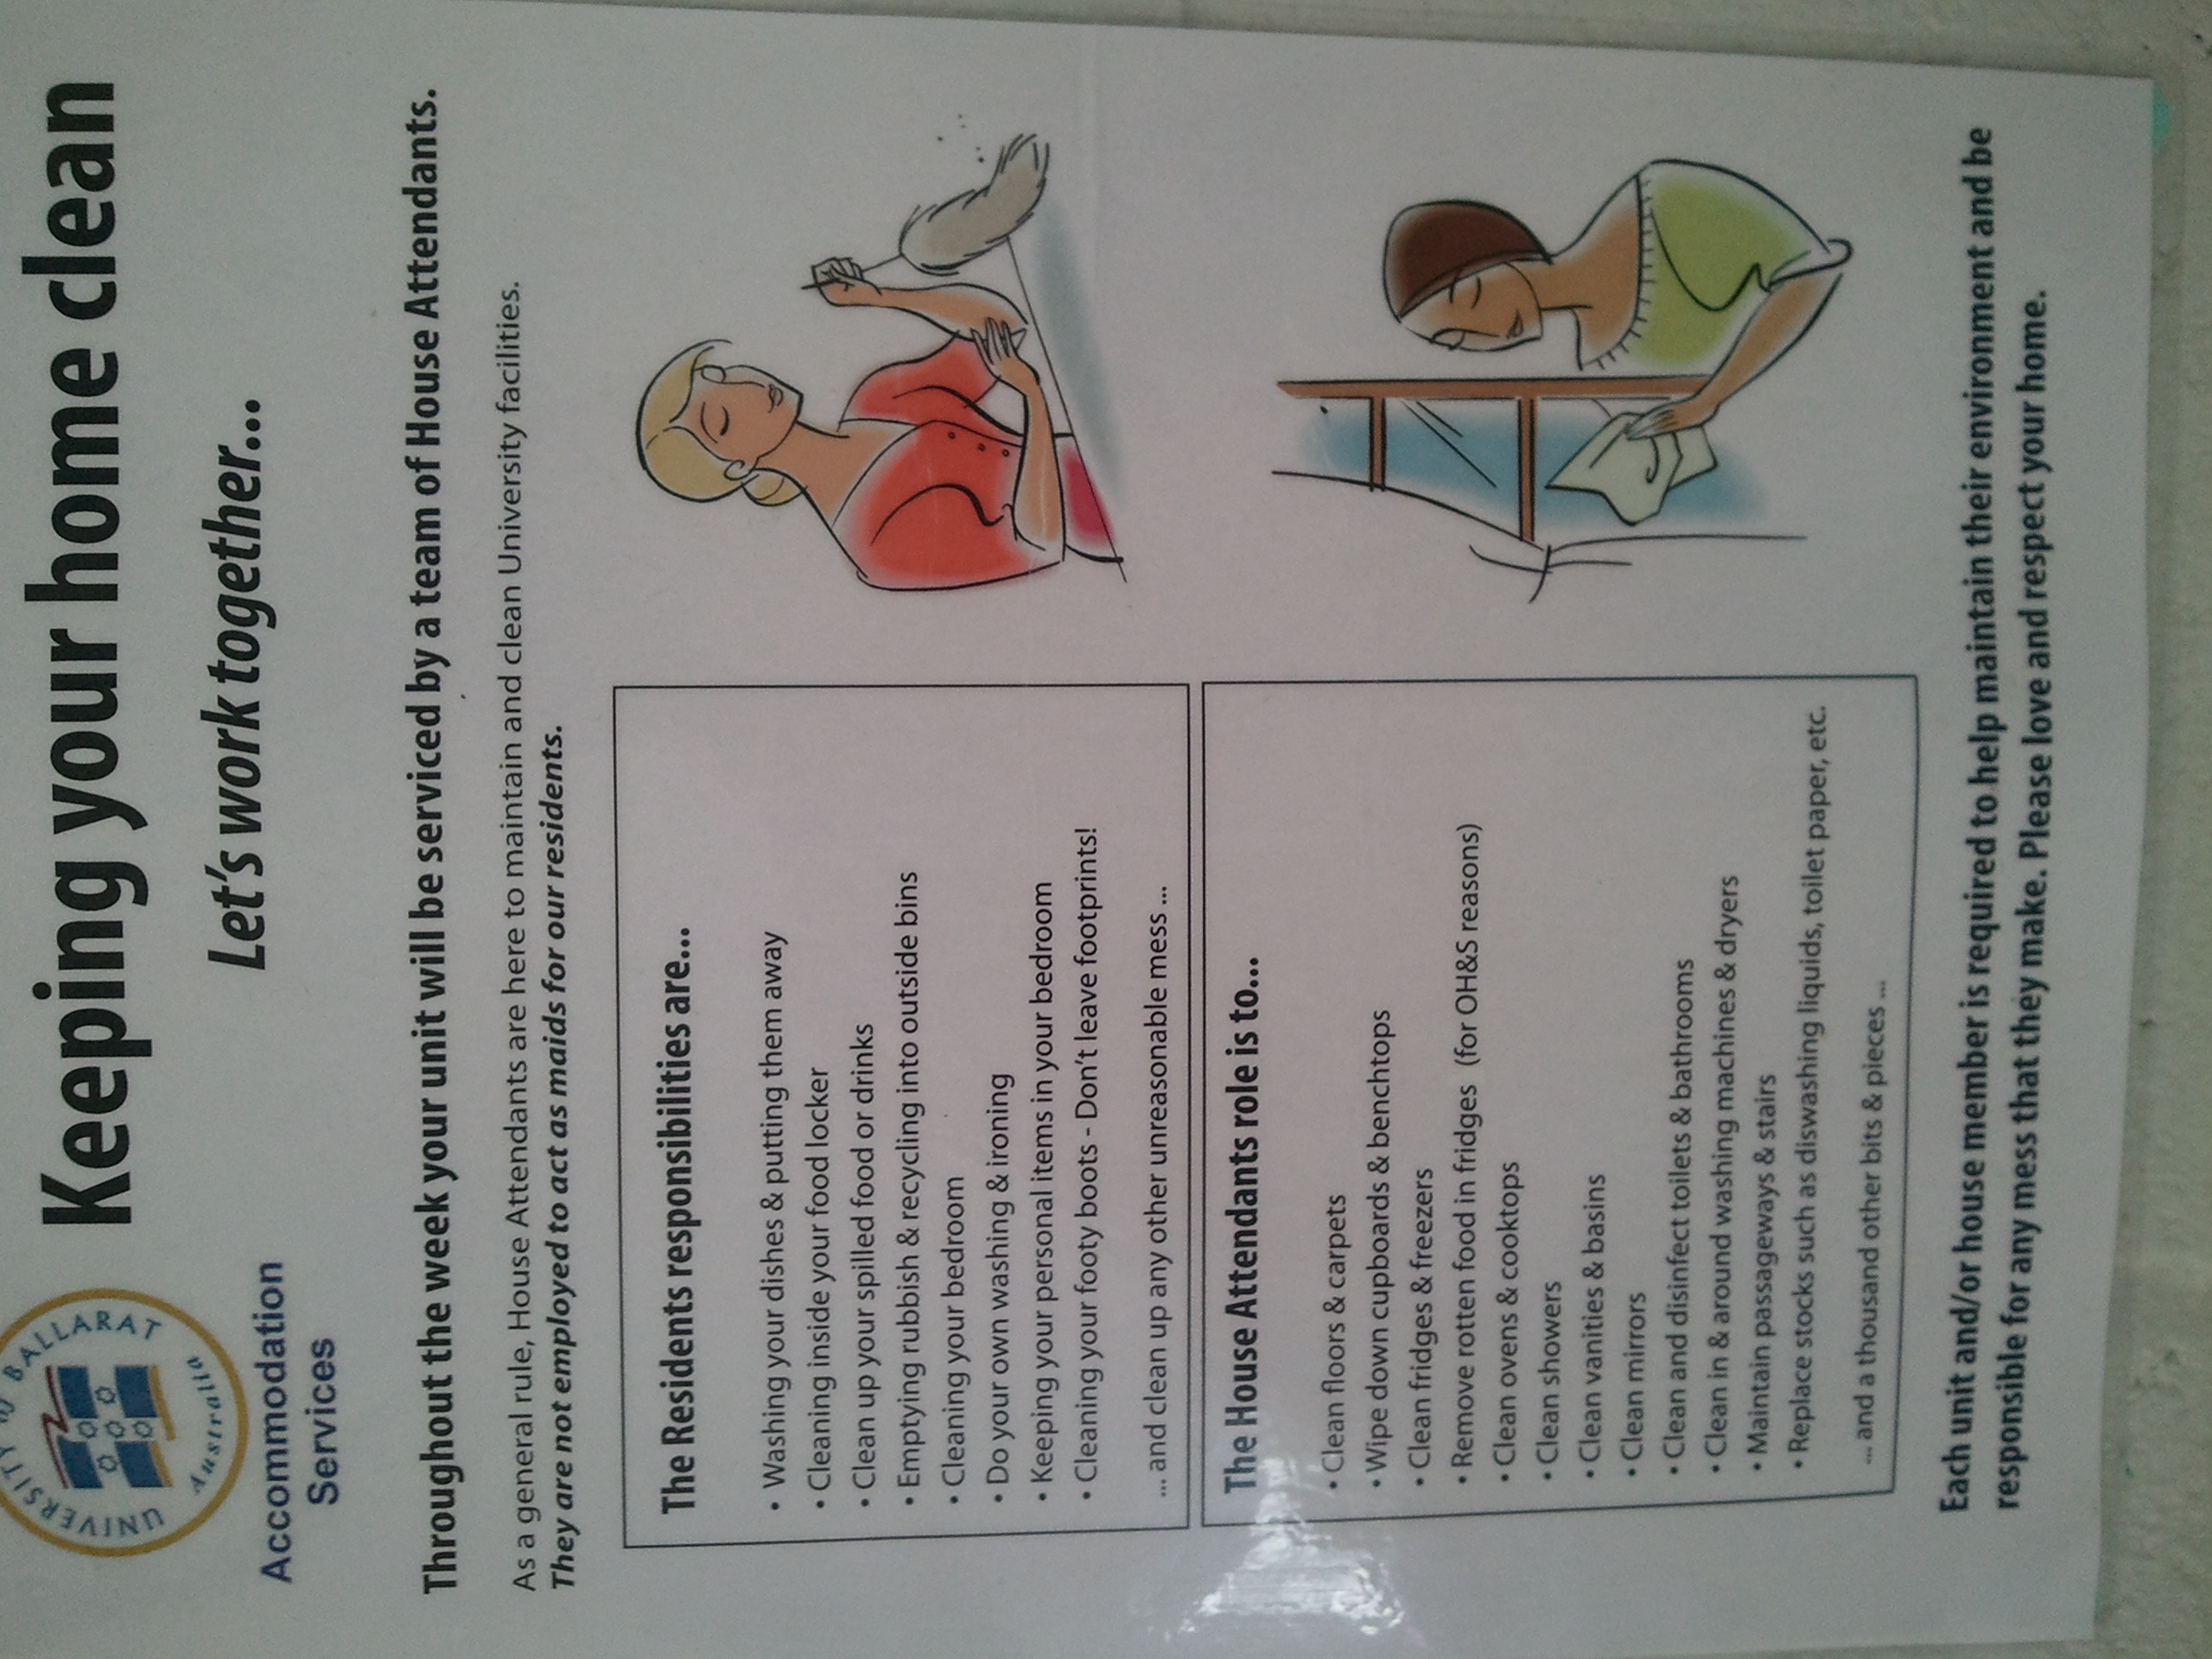
LCA 2013 [1] is starting so it seems like time to finish my write-up of LCA 2012. As usual it was a great conference, although I got sick immediately after getting there which reduced my ability to attend. Android A major unofficial theme of the conference was Android. Most delegates seemed to have Android phones, the Samsung Galaxy S and Galaxy Nexus seemed to be the most popular phones. Many delegates had two or more phones for development purposes. A large portion of the casual conversation at the conference concerned Android. There were a couple of really interesting talks about the Serval mesh networking project [2] which involves Android phones running in ad-hoc Wifi mode for long range communication without any official base station. Serval allows transferring messages, pictures, and voice calls. If you need to get longer range you can mount one phone in a convenient place and other phones will decide to use it as a relay there is no need to have a dedicated relay device (such as a mobile phone tower or Wifi access point). Serval is supposed to work with Wifi access points but due to Java not exposing some networking details to the higher levels of software the code that was available at the time of the conference didn t support networks other than a /24, which meant that the conference Wifi network didn t work with Serval. As an aside most people at the conference who installed Serval were using a development version that was newer than the version on the Android market. I can t remember what the extra features were though. Serval was designed for emergency situations, it can be installed on phones (and pushed to other phones via Wifi) in the field and allow communications when the infrastructure is broken. Also it s designed with some aim of circumventing censorship which among other things means that there are no facilities for tracking use. I think it would be really handy to be able to in some way track viewing of or interest in images that are transported via the mesh (maybe by something similar in concept to Google +1). Then in a crowd sourced environment people who take photos would be encouraged in their work by audience appreciation. One thing that interests me is the possibility of using Serval on a cruise ship. A cruise ship is an environment where mobile phone calls are unreasonably expensive, cabin phones aren t much use (who pays for a cruise and hangs out in their cabin?), and where there is usually a Wifi network installed. If a ship has a single bridged Wifi network that allows connecting to Wifi before authenticating for Internet access (which is probably the common case) then you could transport VOIP over that network without paying and without incurring any expense on the cruise company. One of the Serval developers assured me that this should be possible, of course a cruise ship with 3,000 passengers probably doesn t use a /24 for their Wifi so the current versions of Serval won t work At the geek my dinner event (a party where everyone brought $20 of food/drink which was cooked by volunteers) an artist showed me some art work that she created on her Samsung Galaxy Note (which was the biggest phone on sale at the time), it was very impressive. She recommended Picasso Mirror Draw, Sketch Free, Sketch Book Mobile Express, and Freenote as free graphical programs for Android. Samsung has a Noteworthy Project advertising campaign based on the artistic uses of the Galaxy Note which has some good videos of artists [3]. Chris Neugebauer and Paris Buttfield-Addison gave an informative and amusing talk about Android UI development (this link has the video) [4]. It s a pity that I missed seeing that one live but fortunately the video is of high quality. Accommodation picture of women cleaning As I ve become interested in Sociology I couldn t help but notice the pictures that accompanied the rules about cleaning the dormitory (which were displayed over the kitchen sink), it seems to imply that cleaning is only women s work. I wonder whether the people who created that poster deliberately chose pictures of women or whether they just chose the first available pictures from a collection of stock photos. Someone who was near my dorm room seemed to not realise how their alarm impacts other people. For the first two mornings I was woken repeatedly after 6AM by someone who was pressing the snooze button on their alarm. When sleeping in close proximity to other people the reasonable options involve some combination of having no loud alarm, immediately turning the alarm off and getting up (not pressing snooze to have it go off repeatedly), and setting the alarm for a time when almost everyone wants to get up (EG 1 hour before the first session). Networking Chris Neugebauer organised the Unprofessional Delegates Networking Session which was a great event. It was an event held at the same time as the Professional Delegates Networking Session with the difference being that you had to pay $5 for food and there was no free drink. A lot of great people attended the UPDNS so I m glad I don t pay for the PDNS. It seems that we won t have a UPDNS this year unfortunately. Conclusion LCA is always great fun and very educational. I recommend attending every year.

25 January 2013

Neil Williams: Hard drive death

My 1Tb laptop drive started misbehaving a few weeks ago, just spending a lot of time spinning when it should have been reading frequently changed files (like the browser cache). I was tempted to blame the browser at that point as no other packages appeared affected.

Wednesday night, a routine package upgrade on unstable brought in a bunch of qt4 updates which I wanted and a virtual box update that I didn't see much point in delaying ... 15 minutes later I couldn't work out why the virtualbox dkms task was still running, spotted it spinning in depmod and found some alarming messages in dmesg about short reads and errors reading from the hard drive. Hmm. The hard drive was out of control at this point, it quickly became apparent that no disc access was going to be possible and I couldn't get to a terminal to kill the current tasks, so I killed the power. The fsck which followed reboot showed more of the errors I'd seen in dmesg and fell back to the manual intervention stage. A few hours of confirming attempts to fix the errors, fsck finally finished. A short amount of usage showed that although fsck had finished, the drive was not happy and was starting to give short reads on other parts of the filesystem, resulting in ~40% of the filesystem appearing to be read-only when the rest was read-write. Somehow, I didn't think this was a welcome feature as the areas affected appeared to be quite random.

The drive in question was a replacement for the original 300Gb drive supplied with the ThinkPad, so a quick bit of switching of drives into a caddy and I could rsync my data off the large drive onto the smaller one. The rsync itself took a lot longer than it should have done because it got lots of short reads too. (Principally in /lib/modules/3.2.0-4/ and in the browser cache directories which had been the original symptom as well as most other places where one could have expected processes to have open files when the drive failed).

Now the 1Tb drive was a pig to fit into the Thinkpad originally because it was too big for the bay but I fitted it anyway. Yes, that was probably a mistake. It certainly meant that in order to fit it I had to not put the drive into the useful caddy provided by Lenovo which makes removal of the drive simple. Indeed the drive was wedged into the bay so tightly that it wasn't going to come out with normal levels of persuasion. This probably contributed to the failure of the drive, so live and learn.

With help from Andy Simpkins (it's always handy to have a hardware engineer on hand at times like this), the keyboard was lifted out, the case was dismantled and just enough room was made to get a screwdriver in behind the sata drive and lever it out of the bay. OK, rebuild laptop, put replacement drive into the caddy (because the smaller capacity drive is also a lot smaller in height than the 1Tb and therefore has plenty of clearance between it and the bay) and move on to the software recovery stage.

Hint: if this happens again, before turning off the broken system for the last time, just remember to download a recent Debian ISO to a USB stick - it saves having to ask someone else or find another machine to do the download. (Thanks Andy...)

OK, so after the usual complaints on reboot that there was no operating system, F12 got the boot order menu up and I was in Debian Installer Rescue Mode. Reinstalling grub failed initially for a few reasons:

  1. I'd deliberately not copied /dev /proc and /sys from the old harddrive but I'd also forgotten to create empty ones on the new drive...
  2. /etc/fstab helpfully referred to / as a UUID which no longer applied, so that had to be edited
  3. grub was confused and couldn't find the root filesystem

A few iterations later, I had a working /dev directory inside the /target chroot, bind mounted from the /dev outside the chroot, I was able to mount proc and sys, so grub was finally happy to reinstall itself and then update the initramfs setup for the new drive.

Reboot, another fsck, all appeared well. I was able to login via the terminal but not in X. Hmmm. Stop xdm, startx manually from the terminal, problems with /tmp/ - permission denied. Oops. Yes, it does help to create /tmp with the right permissions....

The final stage was to complete the dpkg --configure -a from the original failure. I've yet to reinstall the 3.2.0-4 kernel, so I'm back on 3.2.0-3 but that's OK.

So now I'm back on the original drive, albeit temporarily without any swap whatsoever (because I didn't partition the replacement drive to create /dev/sda5 before doing the copy) and now I remember the second reason I wanted to replace the original drive with the 1Tb drive - the original drive is as NOISY as hell. The whole edge of the laptop vibrates constantly, to the point that I can feel the vibration under the keys as I type. It's not that the drive is loose in the bay, it's just a constant vibration.

But, I have kept all my data and I have a usable laptop for the BSP this weekend. I will be looking at an SSD drive to replace this one though and having also found my old Acer laptop with power supply, I can now reference this entry when I transfer the system a second time.

22 January 2013

Julien Danjou: Extending Swift with middleware: example with ClamAV

In this article, I'm going to explain you how you can extend Swift, the OpenStack Object Storage project, so it performs extra action on files at upload or at download time. We're going to build an anti-virus filter inside Swift. The goal is to refuse uploaded data if they contain a virus. To help us with virus analyses, we'll use ClamAV. WSGI, paste and middleware
In a pipeline, a black cat can become a white cat with the help of some middleware.
To do our content analysis, the best place to hook in the Swift architecture is at the beginning of every request, on swift-proxy, before the file is actually stored on the cluster. Swift proxy uses, like many other OpenStack projects, paste to build his HTTP architecture. Paste uses WSGI and provides an architecture based on a pipeline. The pipeline is composed of a succession of middleware, ending with one application. Each middleware has the chance to look at the request or at the response, can modify it, and then pass it to the following middleware. The latest component of the pipeline is the real application, and in this case, the Swift proxy server. If you've already deployed Swift, you encountered a default pipeline in the swift-proxy.conf configuration file:
[pipeline:main]
pipeline = catch_errors healthcheck cache ratelimit tempauth proxy-logging proxy-server

This is a really basic pipeline with a few middleware. The first one catches error, the second one is in charge to return 200 OK response if you send a GET /healthcheck request on your proxy server. The third one is in charge of caching, the fourth one is used for rate limiting, the fifth for authentication, the sixth one for logging, and the final one is the actual proxy server, in charge of proxying the request to the account, container, or object servers (the others components of Swift). Of course, we could remove or add any of the middleware here at our convenience. Be aware that the order matters: for example, if you put healthcheck after tempauth, you won't be able to access the /healthcheck URL without being authenticated! ClamAV
If you don't know ClamAV, it's an antivirus engine designed for detecting trojans, viruses, malware and other malicious threats. Wwe're going to use it to scan every incoming file. To build the middleware, we'll use the Python binding pyclamd. The API is quite simple, see:
>>> import pyclamd
>>> pyclamd.init_unix_socket('/var/run/clamav/clamd.ctl')
>>> print pyclamd.scan_stream(pyclamd.EICAR)
'stream': 'Eicar-Test-Signature(44d88612fea8a8f36de82e1278abb02f:68)'
>>> print pyclamd.scan_stream("safe!")
None

Anatomy of a WSGI middleware Your WSGI middleware should consist of a callable object. Usually this is done with a class implementing the __call__ method. Here's a basic boilerplate:
class SwiftClamavMiddleware(object):
"""Middleware doing virus scan for Swift."""

def __init__(self, app, conf):
# app is the final application
self.app = app

def __call__(self, env, start_response):
return self.app(env, start_response)


def filter_factory(global_conf, **local_conf):
conf = global_conf.copy()
conf.update(local_conf)

def clamav_filter(app):
return SwiftClamavMiddleware(app, conf)
return clamav_filter

I'm not going to expand more on why this is built this way, but if you want to have more info on this kind of filter middleware, you can read their documentation on Paste. This middleware will just do nothing as it is. It's going to simply pass all requests it receives to the final application, and returns the result. Testing our basic middleware
Now is a really good time to add unit tests. I hope you didn't think we were going to write code without some tests, right? It's really easy to test a middleware, as we're going to use WebOb for that.
import unittest
from webob import Request


class FakeApp(object):
def __call__(self, env, start_response):
return Response(body="FAKE APP")(env, start_response)


class TestSwiftClamavMiddleware(unittest.TestCase):

def setUp(self):
self.app = SwiftClamavMiddleware(FakeApp(), )

def test_simple_request(self):
resp = Request.blank('/',
environ=
'REQUEST_METHOD': 'GET',
).get_response(self.app)
self.assertEqual(resp.body, "FAKE APP")

We create a FakeApp class, that represents a fake WSGI application. You could also use a real application, or write a fake application looking like the one you want to test. It'll require more time, but your tests will be closer to the reality. Here we write the simplest test we can for our middleware. We're just sending a GET / request to it, so it passes the request to the final application and returns the result. It is transparent, it does nothing. Now, with that solid base we'll able to add more features and test these features incrementally. Plugging ClamAV in With our base ready, we can start thinking about how to plug ClamAV in. What we want to check here, is the content of the file when it's uploaded. If we refer to the OpenStack object storage API , a file upload is done via a PUT request, so we're going to limit the check to that kind of requests. Obviously, more checks could be added, but we'll keep things simple here for the sake of comprehensibility. With WSGI, the content of the request is available in env['wsgi.input'] as an object implementing a file interface. We'll scan that stream with ClamAV to check for viruses.
import pyclamd
from webob import Response


class SwiftClamavMiddleware(object):
"""Middleware doing virus scan for Swift."""

def __init__(self, app, conf):
pyclamd.init_unix_socket('/var/run/clamav/clamd.ctl')
# app is the final application
self.app = app

def __call__(self, env, start_response):
if env['REQUEST_METHOD'] == "PUT":
# We have to read the whole content in memory because pyclamd
# forces us to, but this is a bad idea if the file is huge.
scan = pyclamd.scan_stream(env['wsgi.input'].read())
if scan:
return Response(status=403,
body="Virus %s detected" % scan['stream'],
content_type="text/plain")(env, start_response)
return self.app(env, start_response)


def filter_factory(global_conf, **local_conf):
conf = global_conf.copy()
conf.update(local_conf)

def clamav_filter(app):
return SwiftClamavMiddleware(app, conf)
return clamav_filter

That's it. We only check for PUT requests and if there's a virus in the file, we return a 403 Forbidden error with the name of the detected virus, bypassing entirely the rest of the middleware chain and the application handling. Then, we can simply test it.
import unittest
from cStringIO import StringIO
from webob import Request, Response


class FakeApp(object):
def __call__(self, env, start_response):
return Response(body="FAKE APP")(env, start_response)


class TestSwiftClamavMiddleware(unittest.TestCase):
def setUp(self):
self.app = SwiftClamavMiddleware(FakeApp(), )

def test_put_empty(self):
resp = Request.blank('/v1/account/container/object',
environ=
'REQUEST_METHOD': 'PUT',
).get_response(self.app)
self.assertEqual(resp.body, "FAKE APP")

def test_put_no_virus(self):
resp = Request.blank('/v1/account/container/object',
environ=
'REQUEST_METHOD': 'PUT',
'wsgi.input': StringIO('foobar')
).get_response(self.app)
self.assertEqual(resp.body, "FAKE APP")

def test_put_virus(self):
resp = Request.blank('/v1/account/container/object',
environ=
'REQUEST_METHOD': 'PUT',
'wsgi.input': StringIO(pyclamd.EICAR)
).get_response(self.app)
self.assertEqual(resp.status_code, 403)

The first test test_put_empty simulates an empty PUT request. The second one, test_put_no_virus simulates a regular PUT request but with a simple file containing no virus. Finally, the third and last test simulates the upload of a virus using the EICAR test file. This is a special test file that is recognized as a virus, even if it's not real one. Very handy for testing virus detection software! Configuring Swift proxy Our middleware is ready! We can configure Swift's proxy server to use it. We need to add the following lines to our swift-proxy.conf to teach it how to load the filter:
[filter:clamav]
paste.filter_factory = swiftclamav:clamav_filter

We'll assume that our Python modules is named swiftclamava here. Now that we've defined our filter and how to load it, we can use it in our pipeline:
[pipeline:main]
pipeline = catch_errors healthcheck cache ratelimit tempauth clamav proxy-logging proxy-server

Just before reaching the proxy-server, and after the user being authenticated, the content will be scanned for viruses. It's important here to put this after authentication for example, because otherwise we may scan content that will get rejected by the authtemp module, thus scanning for nothing! Beyond scanning And voil , we now have a simple middleware testing uploaded content and refusing infected files. We could enhance it with various other things, like configuration handling, but I'll let that as an exercise for the interested readers. We didn't exploited it here, but note that you can also manipulate request headers and modify them if needed. For example, we could have added a header X-Object-Meta-Scanned-By: ClamAV to indicates that the file has been scanned by ClamAV. You should now be able to build your own middleware doing whatever you want with uploaded data. Happy hacking!

13 January 2013

Neil Williams: Status of klibc on AArch64

With significant assistance from Steve McIntyre and some judicious delving into the ARM Information Centre, I've now got the assembly portions of klibc sorted (but untested) for AArch64 (arm64).

Andy & I started by copying the old ARM support as a new directory and one of the final steps was to remove a whole bunch of legacy code from the days before Thumb and all the #ifdef lines which went with it. Some files disappeared entirely. setjmp.S was the largest amount of work as the load&store multiple support of ARMv7 has gone in ARMv8, so the stmia mnemonic had to be expanded to multiple stp calls but that makes it more explicit, so it's not a bad thing.

Steve & I borrowed from the glibc AArch64 code from upstream by Marcus Shawcroft, simplifying the glibc macros for klibc and also got clues about what extra registers needed handling compared to ARMv7.

I've now got to look at some traditional cross-compilation issues because the Linaro AArch64 toolchain doesn't install to typical Debian cross-building paths and the build now moves past the AArch64-specific assembly and fails later when the C code gets the wrong include path and ends up including /usr/include/i386-linux-gnu/asm/byteorder.h with predictable results.

If someone has an AArch64 toolchain already set up, feel free to clone my modified klibc tree and let me know if there are subsequent build errors. Of course, if you fancy testing a build in the Foundation Model for ARMv8, that would be good too! (Report issues via github.)

Whilst I'm sorting out the toolchain, I've also been updating perl-cross-debian (which has also seen some more upstream testing and improvement).

11 January 2013

Julien Danjou: Overriding cl-json object encoding

CL-JSON provides an encoder for Lisp data structures and objects to JSON format. Unfortunately, in some case, its default encoding mechanism for CLOS objects isn't exactly doing the right thing. I'll show you how Common Lisp makes it easy to change that. Identifying the problem CL-JSON & CLOS CL-JSON mechanism encoding CLOS object is really neat. Let's see how it works for a simple case:
(defclass kitten ()
((tail :initarg :tail)))

(json:encode-json-to-string (make-instance 'kitten :tail 'black))

will produce:
 "tail":"black" 

Still using CL-JSON, we can also decode the JSON object to a CLOS object:
(slot-value
(json:with-decoder-simple-clos-semantics
(json:decode-json-from-string " \"tail\":\"black\" "))
:tail)

That code will return "black". Note that it's also possible to specify which class should be used when decoding objects, but that's beyond the purpose of this article. Postmodern Now, let's introduce Postmodern, a wonderful Common Lisp system providing access to the wonderful PostgreSQL database. It also provides a simple system to map rows in a database to CLOS classes, called DAO for Database access objects. With this, we can easily store our kitten into a table.
(defclass kitten ()
((tail :initarg :tail))
(:metaclass postmodern:dao-class))

If we try to encode this to JSON, it will produce the exact same result seen previously. The problem is what happens when one of our column has a NULL value. Postmodern encodes this using the :null symbol. So this code:
(defclass kitten ()
((tail :initarg :tail :col-type (or s-sql:db-null text)))
(:metaclass postmodern:dao-class))

(postmodern:deftable kitten
(postmodern:!dao-def))

(postmodern:connect-toplevel )

(postmodern:create-table 'kitten)

(json:encode-json-to-string
(postmodern:make-dao 'kitten))

will return:
" "tail":"null" "

Fail! The fact that the column is NULL is represented by the :null symbol. And CL-JSON encodes all symbols as string. This is not at all what we want here! Overriding encode-json CL-JSON provides and uses the encode-json method to encode all kind of object. It is defined as a generic function, and a lot of different methods are implemented to handle the different standard Common Lisp types. The one used for standard-object is defined liked that:
(defmethod encode-json ((o standard-object)
&optional (stream *json-output*))
"Write the JSON representation (Object) of the CLOS object O to
STREAM (or to *JSON-OUTPUT*)."
(with-object (stream)
(map-slots (stream-object-member-encoder stream) o)))

All we need to do here, is to create a new method for our kitten objects, that handles correctly the :null case.
(defclass kitten ()
((tail :initarg :tail :col-type (or s-sql:db-null text)))
(:metaclass postmodern:dao-class))

(export 'kitten)

;; Switch package just to define the new method
(in-package :json)
(defmethod encode-json ((o cl-user:kitten)
&optional (stream json:*json-output*))
"Write the JSON representation (Object) of the postmodern DAO CLOS object
O to STREAM (or to *JSON-OUTPUT*)."
(with-object (stream)
(map-slots (lambda (key value)
(as-object-member (key stream)
(encode-json (if (eq value :null) nil value) stream)))
o)))

;; Go back into our package
(in-package :cl-user)

(postmodern:deftable kitten
(postmodern:!dao-def))

(postmodern:connect-toplevel )

(postmodern:create-table 'kitten)

(json:encode-json-to-string
(postmodern:make-dao 'kitten))

With that new method, as soon as we encounter a :null symbol as a value for an object's slot, we replace it by nil. Now if we try to encode another kitten, we'll get:
 "tail":null 

which is far better for our JavaScript data consumers! In the end, I think that this kind of trick is feasible that easily because of the way CLOS provides its generic method implementation. The fact that methods don't belong to any class makes the extension of every program, library and class so much easier. Doing this in another language like Java would likely by impossible, and in Python it would unlikely be as clean as it is done in Common Lisp. The ability to teach any library about how it should handle your class just by defining a new method is really handy!

Next.

Previous.