Search Results: "cas"

19 April 2015

Laura Arjona: Six months selfhosting: my userop experiences

Note: In this post I mention some problems and ask questions (to myself, like thinking aloud ). The goal is not to get answers to those questions (I suppose that I will find them soon or later in the internet, manuals and so), but to show the kind of problems and questions that arise in my selfhosting adventures, which I suppose are common to other people trying to administer a home server with some web services. Am I an userop? Well I m something in the middle of (GNU/Linux) user and sysadmin: I have studied computer technical engineering but most of my experience has been in helpdesk, providing support for Windows users. I m running Debian in some LAMP boxes at work (without GUI) since 2008 or so, and in my desktops (with GUI) since 2010. I don t code nor package, but I don t mind trying to read code and understand it (or not). I know a bit of C, a bit of Python, of PHP, and enough Perl to open a Perl file and close it after two minutes, understanding that it s great, but too much for me :) I translate software, so I m not scared to clone a repository, edit files, commit or submit a patch. I m not scared of compiling a program (except if it s an Android app: I try to avoid setting up the development environment just to try some translation that I made but I built my Puma before it was the binary available for download or in F-Droid). In conclusion, I feel more like a GNU/Linux power user than a sysadmin . Sometimes just a user or even a newbie (for example, I don t know very well the Unix/Linux folder tree where are the wallpapers stored? Does it depend on the desktop that I use?). Anyway. I won t stop my free software + free networks digital life because I don t know many things. I bought a small server for home last September, and I wanted to try to selfhost some services, for me and for my family. I want to be a home sysadmin or something like that, so I joined the userops mailing list :) Here you have my experiences on selfhosting/being an userop until now. Mail I even didn t try to setup my mail server, because many people say it s a pain (although nice articles were published about how to do it, for example this series in ArsTechnica) and I need a static IP which is 14 /month more to my ISP, and Gandi, the place where I rented my domain name, provides mail, and they use Debian and Roundcube, and sponsor Debian too, so I decided to trust on them. So this is my strategy now, to try to keep mail under my control: MediaGoblin I ve setup two MediaGoblin instances (yes, two!). I managed to do it in Debian 7 stable (I think NodeJS npm was not needed then), but soon later I upgraded to Jessie so now it s even better. I installed Nginx and PostgreSQL via apt, to use them for both instances (and probably some more software later). One instance is public, and I use a Debian user, a PostgreSQL database, and it s running in http://media.larjona.net
I have requested an SSL cert to Gandi but I still didn t deployed it (lazy LArjona!!). The other instance is private, for family photos. I didn t know very well how much of my existing setup could reuse and how to keep both instances in case of downtimes or attack I know more or less the concept or chroot but I don t know how to deploy it in my machine. So I decided to use another Debian user, another PostgreSQL database, deploy MediaGoblin in a different folder, and create another virtual server in my Nginx to serve it. I managed to setup that virtual server to http-authenticate and to serve content via a different port, and use a self-signed SSL certificate (it s only for family, so it does not matter). I created another (unprivileged) Debian user with a password for the nginx authentication, and gave my family the URL in the form https://mediaprivate.larjona.net:PortNumber and the user and password (mediaprivate is a string, and PortNumber is a number). I think they don t use the instance too much, but at least I upload photos there from time to time and email the link instead of emailing the photos themselves (they don t use GPG either ). Upgrades I upgraded MediaGoblin from 0.7.1 to 0.8.0 successfully, I sent a report about how I did it to the mailing list. First I upgraded the public instance, when I figure out the process, I upgraded the second instance to test my instructions, and then, I sent the report with the instructions to the mailing list. Static site and LimeSurvey: the power of free software (with instructions) I wanted to act as a mirror of floss2013.libresoft.es and surveys.libresoft.es since they suffer a downtime and I participated in that project (not in the sysadmin part, but in the research and content creation). The static site floss2013.libresoft.es offered a zip with the whole website tree (since the website was licensed as AGPL), and I had access to the git repo holding the development copy of the website. So I just cloned the repository and setup another nginx virtual server in my machine, and tuned my DNS zone in Gandi website to serve floss2013.larjona.net from home. 10 minutes setup YAY! #inGitWeTrust #FreeSoftwareFTW :) For surveys.larjona.net I had to install a LimeSurvey instance. I knew how to do it because we use LimeSurvey at work, but at home I had Nginx instead of Apache, and PostgreSQL instead of MySQL. And no PHP I searched about how to install PHP in Nginx (I can use apt-get, nice!) and how to install LimeSurvey with Nginx and PostgreSQL (I had documentation about that, so I followed, and it worked). For making available the data (one survey and its results, so people can login as visitor to query and get statistics), I downloaded the LimeSurvey export dataset that we were providing in the static website, followed the replication instructions (hey, I wrote them!), and they worked #oleole! (And here, dear researchers, gets demonstrated that free software and free culture really empower your research and help spreading your results). Etherpad: not so easy, it seems! I m trying to install Etherpad-Lite, but I m suffering a bit. I think I did everything ok according to some guides but I get Bad Gateway and these kind of errors when trying to browse with Lynx in the host:
[error] 3615#0: *24 upstream timed out (110: Connection timed out) 
while reading response header from upstream, 
client: 127.0.0.1, 
server: pad.larjona.net, 
request: "GET / HTTP/1.0", 
upstream: "http://127.0.0.1:9001/", 
host: "pad.larjona.net"
2015/04/17 20:52:56 [error] 3615#0: *24 connect() failed 
(111: Connection refused) while connecting to upstream, 
client: 127.0.0.1, 
server: pad.larjona.net, 
request: "GET / HTTP/1.0", 
upstream: "http://[::1]:9001/", 
host: "pad.larjona.net"
I m not sure if I need to open some port in iptables, my router, or change my nginx configuration because the guides assume you re only serving one website in the port 80 (and I have several of them, now ), or what I ve spent three chunks of time (maybe ~2h each?) on this, in different days, and couldn t figure it out, so I decided to round-robin in my TODO list. Userops thoughts Debian brings peace of mind (for me) On one side, maintaining a Debian box it s quite easy, and the more software that it s packaged, the less time that I spend installing or upgrading. I like being in stable, I m in Jessie now (I migrated when it was frozen), but I ll stay in stable as much as I can. I like that I can use the software that I installed via apt-get for several services (nginx, PostgreSQL ). About the software that is not packaged (MediaGoblin, LimeSurvey, EtherPad, maybe others later), I wonder how dependencies and updates are handled. And maybe (probably) I have installed some components several times, one for each service (this sounds like a Windows box #grr). For example MediaGoblin uses PyPump. PyPump 0.5 is packaged in Debian Jessie. MediaGoblin uses PyPump 0.7+. What if PyPump 0.7+ gets, let s say, into Jessie-backports? Can I benefit from that? I know that MediaGoblin upgrade instructions includes upgrading the dependencies, but what about some security patch in one dependency? Should I upgrade the pip modules periodically? How to know if some upgrade is recommended because patches a vulnerability, or it s just new features (and maybe breaking my setup)? This kind of things are the peace of mind that Debian packaging brings to me: when some piece of software is packaged, I know maybe I need to care about proper setup and configuration, but later, it s kind-of-easy to maintain (since the Debian maintainers care about the rest). I don t mind about cloning a repo and compiling, I mind about later, or coexistance with other program/services. I trust in the MediaGoblin community and I m an active member (I m not developer, but hang on IRC, follow the mailing list, etc) but for example I don t know anything about the EtherPad project. And I don t feel like joining the community (I m already an active member in Debian, MediaGoblin, F-Droid, Pump.io, translator of LimeSurvey and many other small apps that I use, and in the future will use more services, like OwnCloud, XMPP ), joining the community of each software that I use is becoming not sustainable :s Free software is more than software I follow the userop mailing list, and it s becoming very technical. I mostly understand the problems (which are similar to the problems that I face: how to isolate different services, how to easily-configure them, how to make them installable by average user ) But I don t understand most of the solutions proposed, and I think that probably we need technical solutions, but in the meanwhile, some issues can be addressed not with software, but with other means: good documentation, community support, translations, beta-testers This is my conclusion until now. When a project is well documented, I think I can find my way to selfhost no matter if the software is packaged (or contained ) or not. MediaGoblin, and LimeSurvey, are well documented, and the user support channels are very responsive. I find lots of instructions that assume that you will use a whole machine for their service (and not for other things). And lots of documentation for the LAMP stack, but not for Nginx + PostgreSQL and Node instead of PHP So, for each particularity of my setup, I search the internet and try to pick good sources to help me do what I wanted to do. I m kind of privileged Some elements, not software related, to take into account as pre-requisites for succeed selfhosting services: These aspects are not present in a lot of people. If I look around to the computer users that I know (mostly Windows+Android, some GNU/Linux users, some Mac OSX users, some iOS users), I find that they search things like X does not work or they cannot write a proper search query in English. Or they trust some random person writing a recipe in their blog, without trying first to understand what the recipe does. Other people just say I m not a professional sysadmin, I ll just do what everybody does (aka use Google services or whatever). What if I try and I don t succeed? . Things like that. We may need some technical solutions (and hackers are thinking about that, and working on that). But I feel that we need (more) a huge group of beta-testers, dogfooding people, aventurers that try the half-cooked solutions and provide successful and unsuccessful experiences, to guide the research and make software technologies advance. I m not sure if I am an userop, but I feel part of that vanguard force , I want to be part of the future of free software and free networks. Comments? You can comment about this post on this pump.io thread.
Filed under: My experiences and opinion Tagged: Communities, Contributing to libre software, Debian, Developer motivations, English, free networks, Free Software, Freedom, innovation, MediaGoblin, Moving into free software, Project Management, selfhosting, sysadmin

18 April 2015

Neil McGovern: Taking office

Yesterday, my first term started as the Debian Project Leader. There s been a large number of emails congratulating me, and thanks to everyone who sent those. I d also like to thank Mehdi Dogguy and Gergely Nagy for running, and of course Lucas Nussbaum for his service over the past two years. Lucas also did a great handover, and so (I hope!) I m aware of most of the issues that are ongoing. As started previously, I ll keep my daily log of activities in /srv/leader/news/ on master.debian.org.

Russ Allbery: Review: The Long Way to a Small, Angry Planet

Review: The Long Way to a Small, Angry Planet, by Becky Chambers
Publisher: CreateSpace
Copyright: 2014
ISBN: 1-5004-5330-7
Format: Kindle
Pages: 503
The Wayfarer is a tunneling ship: one of the small, unremarked construction ships that help build the wormhole network used for interstellar transport. It's a working ship with a crew of eight (although most people would count seven and not count the AI). They don't all like each other particularly not the algaeist, who is remarkably unlikeable but they're used to each other. It's not a bad life, although a more professional attention to paperwork and procedure might help them land higher-paying jobs. That's where Rosemary Harper comes in. At the start of the book, she's joining the ship as their clerk: nervous, hopeful, uncertain, and not very experienced. But this is a way to get entirely away from her old life and, unbeknownst to the ship she's joining, her real name, identity, and anyone who would know her. Given that introduction, I was expecting this book to be primarily about Rosemary. What is she fleeing? Why did she change her identity? How will that past come to haunt her and the crew that she joined? But that's just the first place that Chambers surprised me. This isn't that book at all. It's something much quieter, more human, more expansive, and more joyful. For one, Chambers doesn't stick with Rosemary as a viewpoint character, either narratively or with the focus of the plot. The book may open with Rosemary and the captain, Ashby, as focal points, but that focus expands to include every member of the crew of the Wayfarer. We see each through others' eyes first, and then usually through their own, either in dialogue or directly. This is a true ensemble cast. Normally, for me, that's a drawback: large viewpoint casts tend to be either jarring or too sprawling, mixing people I want to read about with people I don't particularly care about. But Chambers avoids that almost entirely. I was occasionally a touch disappointed when the narrative focus shifted, but then I found myself engrossed in the backstory, hopes, and dreams of the next crew member, and the complex ways they interweave. Rosemary isn't the center of this story, but only because there's no single center. It's very hard to capture in a review what makes this book so special. The closest that I can come is that I like these people. They're individual, quirky, human (even the aliens; this is from more the Star Trek tradition of alien worldbuilding), complicated, and interesting, and it's very easy to care about them. Even characters I never expected to like. The Long Way to a Small, Angry Planet does have a plot, but it's not a fast-moving or completely coherent one. The ship tends to wander, even when the mission that gives rise to the title turns up. And there are a lot of coincidences here, which may bother you if you're reading for plot. At multiple points, the ship ends up in exactly the right place to trigger some revelation about the backstory of one of the crew members, even if the coincidence strains credulity. Similar to the algae-driven fuel system, some things one just has to shrug about and move past. On other fronts, though, I found The Long Way to be refreshingly willing to take a hard look at SF assumptions. This is not the typical space opera: humans are a relatively minor species in this galaxy, one that made rather a mess of their planet and are now refugees. They are treated with sympathy or pity; they're not somehow more flexible, adaptable, or interesting than the rest of the galaxy. More fascinatingly to me, humans are mostly pacifists, a cultural reaction to the dire path through history that brought them to their current exile. This is set against a backdrop of a vibrant variety of alien species, several of whom are present onboard the Wayfinder. The history and background of the other species are not, sadly, as well fleshed out as the humans, but each with at least a few twists that add interest to the story. But the true magic of this book, the thing that it has in overwhelming abundance, is heart. Not everyone in this book is a good person, but most of them are trying. I've rarely read a book full of so much empathy and willingness to reach out to others with open hands. And, even better, they're all nice in different ways. They bring their own unique personalities and approaches to their relationships, particularly the complex web of relationships that connects the crew. When bad things happen, and, despite the overall light tone, a few very bad things happen, the crew rallies like friends, or like chosen family. I have to say it again: I like these people. Usually, that's not a good sign for a book, since wholly likeable people don't generate enough drama. But this is one of the better-executed "protagonist versus nature" plots I've read. It successfully casts the difficulties of making a living at a hard and lonely and political job as the "nature" that provides the conflict. This is a rather unusual book. It's probably best classified as space opera, but it doesn't fit the normal pattern of space opera and it doesn't have enough drama. It's not a book about changing the universe; at the end of the book, the universe is in pretty much the same shape as we found it. It's not even about the character introduced in the first pages, or really that much about her dilemma. And it's certainly not a book about winning a cunning victory against your enemies. What it is, rather, is a book about friendships, about chosen families and how they form, about being on someone else's side, about banding together while still being yourself. It's about people making a living in a hard universe, together. It's full of heart, and I loved it. I'm unsurprised that The Long Way to a Small, Angry Planet had to be self-published via a Kickstarter campaign to find its audience. I'm also unsurprised that, once it got out there, it proved very popular and has now been picked up by a regular publisher. It's that sort of book. I believe it's currently out of print, at least in the US, as its new publisher spins up that process, but it should be back in print by late 2015. When that happens, I recommend it to your attention. It was the most emotionally satisfying book I've read so far this year. Rating: 9 out of 10

15 April 2015

Michal Čihař: Packaging python-gammu

After Monday release of separate Gammu and python-gammu, the obvious task was to get the new package to distributions. First I've started with Debian packages, what was quite easy as from quite complex CMake + Python package it is now purely CMake and it was mostly about removing stuff. Soon the updated Gammu package was uploaded to experimental. Once having that ready, I've also update the backports for Ubuntu and these are available in Gammu PPA. Creating new python-gammu package was a bit harder as this is the first Python 3 compatible package I've created, but it's now ready and sitting in the NEW queue. While working on python-gammu package, I've realized that some of the data used in testsuite are missing in the tarball. While not being critical, this is definitely not nice, so I've decided to release python-gammu 2.1 today. It also includes fixes for some corner cases found by coverity. For openSUSE the packaging was quite easy as well, stripping out unneeded parts of Gammu package went smoothly and it's now in hardware project, SR to Factory is pending. With python-gammu it turned out to be much harder as the testsuite had failed there with some strange error coming out of libdbi. After looking deeper into it, the problem is in new return type available in Git snapshot openSUSE is shipping. Fortunately producing fix was quite easy, so next Gammu upstream will handle that properly and package in hardware project is already patched. You can now use python-python-gammu from devel:languages:python and SR to Factory is pending as well.

Filed under: Debian English Gammu python-gammu SUSE Wammu 0 comments

Petter Reinholdtsen: Debian Edu interview: Shirish Agarwal

It was a surprise to me to learn that project to create a complete computer system for schools I've involved in, Debian Edu / Skolelinux, was being used in India. But apparently it is, and I managed to get an interview with one of the friends of the project there, Shirish Agarwal. Who are you, and how do you spend your days? My name is Shirish Agarwal. Based out of the educational and historical city of Pune, from the western state of Maharashtra, India. My bread comes from giving training, giving policy tips, installations on free software to mom and pop shops in different fields from Desktop publishing to retail shops as well as work with few software start-ups as well. How did you get in contact with the Skolelinux / Debian Edu project? It started innocently enough. I have been using Debian for a few years and in one local minidebconf / debutsav I was asked if there was anything for schools or education. I had worked / played with free educational softwares such as Gcompris and Stellarium for my many nieces and nephews so researched and found Debian Edu or Skolelinux as it was known then. Since then I have started using the various education meta-packages provided by the project. What do you see as the advantages of Skolelinux / Debian Edu? It's closest I have seen where a package full of educational software are packed, which are free and open (both literally and figuratively). Even if I take the simplest software which is gcompris, the number of activities therein are amazing. Another one of the softwares that I have liked for a long time is stellarium. Even pysycache is cool except for couple of issues I encountered #781841 and #781842. I prefer software installed on the system over web based solutions, as a web site can disappear any time but the software on disk has the possibility of a larger life span. Of course with both it's more a question if it has enough users who make it fun or sustainable or both for the developer per-se. What do you see as the disadvantages of Skolelinux / Debian Edu? I do see that the Debian Edu team seems to be short-handed and I think more efforts should be made to make it popular and ask and take help from people and the larger community wherever possible. I don't see any disadvantage to use Skolelinux apart from the fact that most apps. are generic which is good or bad how you see it. However, saying that I do acknowledge the fact that the canvas is pretty big and there are lot of interesting ideas that could be done but for reasons not known not done or if done I don't know about them. Let me share some of the ideas (these are more upstream based but still) I have had for a long time : 1. Classical maths question of two trains in opposing directions each running @x kmph/mph at y distance, when they will meet and how far would each travel and similar questions like these. The computer is a fantastic system where questions like these can be drawn, animated and the methodology and answers teased out in interactive manner. While sites such as the Ask Dr. Math FAQ on The Two Trains problem (as an example or point of inspiration) can be used there is lot more that can be done. I dunno if there is a free software which does something like this. The idea being a blend of objects + animation + interaction which does this. The whole interaction could be gamified with points or sounds or colourful celebration whenever the user gets even part of the question or/and methodology right. That would help reinforce good behaviour. This understanding could be used to share/showcase everything from how the first wheel came to be, to evolution to how astronomy started, psychics and everything in-between. One specific idea in the train part was having the Linux mascot on one train and the BSD or GNU mascot on the other train and they meeting somewhere in-between. Characters from blender movies could also be used. 2. Loads of crossword-puzzles with reference to subjects: We have enormous data sets in Wikipedia and Wikitionary. I don't think it should be a big job to design crossword puzzles. Using categories and sub-categories it should be doable to have Q&A single word answers from the existing data-sets. What would make it easy or hard could be the length of the word + existence of many or few vowels depending on the user's input. 3. Jigsaw puzzles - We already have a great software called palapeli with number of slicers making it pretty interesting. What needs to be done is to download large number of public domain and copyleft images, tease and use IPTC tags to categorise them into nature, history etc. and let it loose. This could turn to be really huge collection of images. One source could be taken from commons.wikimedia.org, others could be huge collection of royalty-free stock photos. Potential is immense. Apart from this, free software suffers in two directions, we lag both in development (of using new features per-se) and maintenance a lot. This is more so in educational software as these applications need to be timely and the opportunity cost of missing deadlines is immense. If we are able to solve issues of funding for development and maintenance of such software I don't see any big difficulties. I know of few start-ups in and around India who would love to develop and maintain such software if funding issues could be solved. Which free software do you use daily? That would be huge list. Some of the softwares are obviously apt, aptitude, debdelta, leafpad, the shell of course (zsh nowadays), quassel for IRC. In games I use shisen-sho while card-games are evenly between kpat and Aiselriot. In desktops it's a tie between gnome-flashback and mate. Which strategy do you believe is the right one to use to get schools to use free software? I think it should first start with using specific FOSS apps. in whatever environment they are. If it's MS-Windows or Mac so be it. Once they are habitual with the apps. and there is buy-in from the school management then it could be installed anywhere. Most of the people now understand the concept of a repository because of the various online stores so it isn't hard to convince on that front. What is harder is having enough people with technical skills and passion to service them. If you get buy-in from one or two teachers then ideas like above could also be asked to be done as a project as well. I think where we fall short more than anything is in marketing. For instance, Debian has this whole range of fonts in its archive but there isn't even a page where all those different fonts in the La Ipsum format could be tried out for newcomers. One of the issues faced constantly in installations is with updates and upgrades. People have this myth that each update and upgrade means the user interface will / has to change. I have seen this innumerable times. That perhaps is one of the reasons which browsers like Iceweasel / Firefox change user interfaces so much, not because it might be needed or be functional but because people believe that changed user interfaces are better. This, can easily be pointed with the user interfaces changed with almost every MS-Windows and Mac OS releases. The problems with Debian Edu for deployment are many. The biggest is the huge gap between what is taught in schools and what Debian Edu is aimed at. Me and my friends did teach on week-ends in a government school for around 2 years, and gathered some experience there. Some of the things we learnt/discovered there was :
  1. Most of the teachers are very territorial about their subjects and they do not want you to teach anything out of the portion/syllabus given.
  2. They want any activity on the system in accordance to whatever is in the syllabus.
  3. There are huge barriers both with the English language and at times with objects or whatever. An example, let's say in gcompris you have objects falling down and you have to name them and let's say the falling object is a hat or a fedora hat, this would not be as recognizable as say a Puneri Pagdi so there is need to inject local objects, words wherever possible. Especially for word-games there are so many hindi words which have become part of english vocabulary (for instance in parley), those could be made into a hinglish collection or something but that is something for upstream to do.

14 April 2015

Neil Williams: Extending an existing ARMMP initramfs

The actual use of this extension is still in development and the log files are not currently publicly visible, but it may still be useful for people to know the what and why The Debian ARMMP kernel can be used for multiple devices, just changing the DTB. I ve already done tests with this for Cubietruck and Beaglebone-Black, iMX.53 was one of the original test devices too. Whilst these tests can deploy a full image (there are examples of building such images in the vmdebootstrap package), it is a lot quicker to do simple tests of a kernel using a ramdisk. The default Debian initramfs has a focused objective but still forms a useful base for extension. In particular, I want to be able to test one initramfs on multiple boards (so multiple dtbs) with the same kernel image. I then want to be able, on selected boards, to mount a SATA drive or write an image to eMMC or a USB stick or whatever. LAVA (via the ongoing refactoring, not necessarily in the current dispatcher code) can automate such tests, e.g. to allow me to boot a Cubietruck into a standard Debian ARMMP armhf install on the SATA drive but using a modified (or updated) ARMMP kernel over TFTP without needing to install it on the device itself. That same kernel image can then be tested on multiple boards to see if the changes have benefitted one board at the expense of another. Automating all of that could be of a lot of benefit to the ARM kernel developers in Debian and outside Debian. So, the start point. Install Debian onto a Cubietruck in my case, with a SATA drive attached. All well and good so far, standard Debian Jessie ARMMP. (Cubietruck uses the LPAE kernel flavour but that won t matter for the initramfs.) Rather than building the initramfs manually, this provides a shortcut at some point I may investigate how to do this in QEMU but for now, it s just as quick to SSH onto the Cubietruck and update. I ve already written a little script to download the relevant linux-image package for ARMMP, unpack it and pull out the vmlinuz, the dtbs and a selected list of modules. The list is selective because TFTP has a 32Mb download limit and there are more modules than that. So I borrowed a snippet from the Xen folks (already shown previously here). The script is in a support repository for LAVA but can be used anywhere. (You ll need to edit the package name in the script to choose between ARMMP and ARMMP LPAE. Steps
  1. Get a working initramfs from an installed device running Debian ARMMP and copy some files for use later. Note: use the name of the symlink in the copy so that the file in /tmp/ is the actual file, using the name of the symlink as the filename. This is important later as it saves a step of having to make the (unnecessary) symlink inside the initramfs. Also, mkinitramfs, which built this initrd.img file in the first place, uses the same shared libraries as the main system, so copying these into the initramfs still works. (This is really useful when you get your ramdisk to support the attached secondary storage, allowing you to simply mount the original Debian install and fixup the initramfs by copying files off the main Debian install.) The relevant files are to support DNS lookup inside the initramfs which then allows a test to download a new image to put onto the attached media before rebooting into it.
    cp /boot/initrd.img-3.16.0-4-armmp-lpae /tmp/
    cp /lib/arm-linux-gnueabihf/libresolv.so.2 /tmp/
    cp /mnt/lib/arm-linux-gnueabihf/libnss_dns.so.2 /tmp/
    
    Copy these off the device for local adjustment:
    scp IP_ADDR:/tmp/FILE .
    
  2. Decompress the initrd.img:
    cp initrd.img-3.16.0-4-armmp-lpae initrd.img-3.16.0-4-armmp-lpae.gzip
    gunzip initrd.img-3.16.0-4-armmp-lpae.gzip
    
  3. Make a new empty directory
    mkdir initramfs
    cd initramfs
    
  4. Unpack:
    sudo cpio -id < initrd.img-3.16.0-4-armmp-lpae
    
  5. Remove the old modules (LAVA can add these later, allowing tests to use an updated build with updated modules):
    sudo rm -rf ./lib/modules/*
    
  6. Start to customise - need a script for udhcpc and two of the libraries from the installed system to allow the initramfs to do DNS lookups successfully.
    cp ../libresolv.so.2 ./lib/arm-linux-gnueabihf/
    cp ../libnss_dns.so.2 ./lib/arm-linux-gnueabihf/
    
  7. Copy the udhcpc default script into place:
    mkdir ./etc/udhcpc/
    sudo cp ../udhcpc.d ./etc/udhcpc/default.script
    sudo chmod 0755 ./etc/udhcpc/default.script
    
  8. Rebuild the cpio archive:
    find .   cpio -H newc -o > ../initrd.img-armmp.cpio
    
  9. Recompress:
    cd ..
    gzip initrd.img-armmp.cpio
    
  10. If using u-boot, add the UBoot header:
    mkimage -A arm -T ramdisk -C none -d initrd.img-armmp.cpio.gz initrd.img-armmp.cpio.gz.u-boot
    
  11. Checksum the final file so that you can check that against the LAVA logs.
    md5sum initrd.img-armmp.cpio.gz.u-boot
    
Each type of device will need a set of modules modprobed before tests can start. With the refactoring code, I can use an inline YAML and use dmesg -n 5 to reduce the kernel message noise. The actual module names here are just those for the Cubietruck but by having these only in the job submission, it makes it easier to test particular combinations and requirements.
- dmesg -n 5
- lava-test-case udevadm --shell udevadm hwdb --update
- lava-test-case depmod --shell depmod -a
- lava-test-case sata-mod --shell modprobe -a stmmac ahci_sunxi sd_mod sg ext4
- lava-test-case ifconfig --shell ifconfig eth0 up
- lava-test-case udhcpc --shell udhcpc
- dmesg -n 7
In due course, this will be added to the main LAVA documentation to allow others to keep the initramfs up to date and to support further test development.

13 April 2015

Mehdi Dogguy: DPL campaign 2015

This year's DPL campaign is over and voting period is also almost over. Many did not vote yet and they really should consider doing so. This is meant as a reminder for them. If you didn't have time to dig into debian-vote's archives and read questions/answers, here is the list with links to candidates' replies:

Compared to past years, we had a comparable number of questions. All questions did not start big threads as it used to be the case sometimes in the past :-) The good side of this is that we are trolling DPL candidates less than we used to do :-P

Now, if you still didn't vote, it is really time to do so. The voting period ends on Tuesday, April 14th, 23:59:59 UTC, 2015. You have only a few hours left!

Russ Allbery: Review: Zero Sum Game

Review: Zero Sum Game, by S.L. Huang
Series: Russell's Attic #1
Publisher: S.L. Huang
Copyright: 2014
ISBN: 0-9960700-1-X
Format: Kindle
Pages: 326
Cas Russell finds things for people, often involving some strategic violence. She belongs to that genre of action novel protagonists who have a rough code of ethics, but who don't exactly follow the law. Her friend Rio is much worse: a functioning sociopath with his own code of ethics, the derivation of which is a key plot point. When the book opens, Cas is on a mission to find a person and rescue them from a drug cartel not her normal mission, but her contact said she was referred by Rio. Oh, and Rio is currently hitting her in the face. This setup matches any number of present-day thrillers. The SFnal twist is that Cas is very good at numbers, in a completely unrealistic action hero way. (I found it unsurprising that Huang was inspired by the superhero genre; that's the right model to have in mind when reading about Cas.) She can calculate where bullets are going to go, knows just the right angle and velocity with which to throw things (and, even more notably, can get her body to do that), and, in one particularly memorable scene, sets up an eavesdropping sound concentrator by changing the angles of available random surfaces in the neighborhood, like trash cans. This ability is not without drawbacks. When she's not in a middle of a job, with something to focus on, she usually ends up drinking herself into a stupor to get her brain to stop working. But it's an extremely useful ability that requires the villains of this book go to great efforts to try to kill her. The plot starts out as fairly typical thriller material, involving threats and dire consequences to those Cas loves (or at least likes a lot) and an unfolding sense that this retrieval of a kidnapped woman is the tip of a very deep iceberg. The expected counterpart, a private investigator with a less casual attitude towards killing than Cas, shows up early on. (Rio does not play that role in the story. His role is much more complex.) But the superhero inspirations show up in the villains as well, in a twist that many on-line summaries spoil, but which I will leave unmentioned. Mostly, Zero Sum Game is a fast-moving story with lots of violence, lots of guns, shadowy conspiracies, and a hypercompetent protagonist. (Female, refreshingly, particularly since she doesn't fall in love with any of the other characters in the book.) It's a recipe for enjoyable brain candy, and I think that's the best attitude to bring to it. However, a couple of things set it apart for me. First, Cas spends quite a bit of time really thinking about her life and questioning her decisions, rather than just blithely enjoying her world of stress and violence. There's more introspection here than in the typical thriller plot, but she stops short of wallowing in angst and stays decisive. I liked that balance: a bit of inner discomfort, and a few hard ethical decisions, but not to the point of paralyzing her. Second, her relationship with Rio is something special. Rio himself is a character type that I've seen before in books like this, but I don't think I've seen the dynamic with a character like that handled this well before. I particularly liked that the focus of the book stayed on Cas, not on Rio, and the reader was encouraged to see that relationship as a reflection on Cas and her sense of internal ethics. Seeing Rio through Cas's eyes, and then seeing other characters react to him and react to their relationship, touched some chords that I really enjoyed reading. Unfortunately, the villains weren't as successful, at least for me. Partly this is a personal quirk: the nature of the threat posed (not revealed for about half the book) is a kind that I dislike reading about. It makes my skin crawl in a way that I don't enjoy. But, even putting that aside, the story ends on a very odd and disturbing anti-climax. It's clearly the first book of an ongoing series, and I hope later books will salvage this. (I certainly liked it well enough to read on.) But the ending left me unsettled and rather irritated at the author. Huang plays fair, and the ending is consistent with what we know by the end of the book, but I read this sort of action-thriller story for catharsis and the glory of competent people doing what they do well. I got deeply engrossed in this book and had a hard time putting it down. Both Cas and Rio are great characters, as are most of the supporting cast. I wish the ending wasn't quite as much of a letdown so that I could recommend it more strongly. But it's still a fun superhero thriller. If you're looking for something with unrealistic superpowers, a large helping of competence, and a high body count, this may be worth picking up. (And no, I don't know what the series title means. I know what the series title refers to, but I haven't yet figured out what connection it or the Axiom of Choice has to the plot.) Followed by Half Life. Rating: 7 out of 10

12 April 2015

Mark Brown: Acer Aspire E11

Recently I was in Seoul in the middle of three weeks of travel and my laptop died on me. Since I had some work that needed doing fairly urgently I took myself over to Yongsan Electronics Market and got myself a cheap replacement to tide myself over. What I ended up with was an Acer Aspire E11. There s a bunch of different models all with very similar plastics, I got one which has a N2940 SoC, 2G of RAM (upgraded to 4G in store), a 500G hard disk and no fans for just over 200000 Korean Won, or about $200. As you d expect at that price it s got shortcomings but overall I ve been extremely happy with it, it s worth looking at if you need something cheap. The keyboard in particular is probably the nicest I ve used 0n a laptop in a long time with a good, definite but not excessive click feel as you press. Battery life is about 5 hours as advertised which is not wonderful but basically fine for me most of the time, and while not exactly Retina it s clear with good viewing angles and generally pleasant to look at. Everything is plastic but feels very solid and robust, better than a lot of more expensive devices I ve used, and there s not much bezel around the screen which means it s the first laptop I ve had which has been comfortable to use in a standard economy seat on a plane. The biggest drawback is performance it s a little slow opening applications sometimes and kernel builds crawl with an x86 allmodconfig taking about one and three quarter hours. For e-mail and web browsing there s no problem at all, I did have to move from offlineimap to mbsync to get my mail to sync in a reasonable time but that s more to do with the performance of offlineimap than that of the system. Overall in use it feels like the Dell I was using from about 2008-2011 or so, comfortable in use outside of builds, and I do appreciate having a system with no fans. There were a couple of small tricks getting Debian installed this is the first system I ve seen with secure boot enabled by default which took me a few moments to work out (but is really good to see). Once that was disabled the install was smooth other than being bitten by Debian bug#778810 which meant I needed a manual fixup to actually get it to boot from the disk. It s also got a Broadcom WiFi module which means it doesn t work at all with mainline but it looked like that was on a standard mini PCI Express module so easily replaceable (I happened to have a USB dongle handy so haven t bothered) and the wired ethernet just worked. Like I say I ve been very happy with it, there s a bunch of other models with different specs for everything except the case (some touchscreen, some with small 32G eMMC drives) as well. Were it not for my need to do kernel builds I d probably be keeping it as my primary laptop.

Josselin Mouette: GNOME for system administrators - Jessie edition

The mini-Debconf Lyon 2015, in addition to being a great meeting to meet both friendly and new faces, has been the occasion for me to update and enrich the GNOME for system administrators course.

For those who couldn t be here, as well as those who were here and disappointed to see me cut through the last third for timing reasons, here are the slides:

Wouter Verhelst: LOADays 2015 talk done

I just uploaded my LOADays 2015 slides to slideshare. The talk seems to have been well received; I got a number of positive comments from some attendees, which is always nice. As an aside, during the talk I did a short demo of how to sign something from within Libreoffice using my eID card. Since the slides were made in Libreoffice Impress, the easiest thing to do was just to sign the slides themselves, which worked perfectly well. So, having uploaded, downloaded, and verified these slides, I can now say with 100% certainty that slideshare does not tamper with files you upload. They may reformat them so it's easier to view on a website, but if you click on the download link, you get the original, untampered version. At least that's the case if you sign documents, of course; it's always possible that they check for that and special-case such things. Would surprise me, though.

11 April 2015

Steve Kemp: Some things get moved, some things get doubled in size.

Relocation
We're about three months away from relocating from Edinburgh to Newcastle and some of the immediate panic has worn off. We've sold our sofa, our spare sofa, etc, etc. We've bought a used dining-table, chairs, and a small sofa, etc. We need to populate the second-bedroom as an actual bedroom, do some painting, & etc, but things are slowly getting done. I've registered myself as a landlord with the city council, so that I can rent the flat out without getting into trouble, and I'm in the process of discussing the income possabilities with a couple of agencies. We're still unsure of precisely which hospital, from the many choices, in Newcastle my wife will be stationed at. That's frustrating because she could be in the city proper, or outside it. So we need to know before we can find a place to rent there. Anyway moving? It'll be annoying, but we're making progress. Plus, how hard can it be?
VLAN Expansion
I previously had a /28 assigned for my own use, now I've doubled that to a /27 which gives me the ability to create more virtual machines and run some SSL on some websites. Using SNI I've actually got the ability to run SSL almost all sites. So I configured myself as a CA and generated a bunch of certificates for myself. (Annoyingly few tutorials on running a CA mentioned SNI so it took a few attempts to get the SAN working. But once I got the hang of it it was simple enough.) So if you have my certificate authority file installed you can browse many, many of my interesting websites over SSL.
SSL
I run a number of servers behind a reverse-proxy. At the moment the back-end is lighttpd. Now that I have SSL setup the incoming requests hit the proxy, get routed to lighttpd and all is well. Mostly. However redirections break. A request for:
  • https://lumail.org/docs
Gets rewritten to:
  • http://lumail.org/docs/
That is because lighttpd generates the redirection and it only sees the HTTP connection. It seems there is mod_extforward which should allow the server to be aware of the SSL - but it doesn't do so in a useful fashion. So right now most of my sites are SSL-enabled, but sometimes they'll flip to naked and unprotected. Annoying. I don't yet have a solution..

10 April 2015

Andrew Shadura: Kallithea 0.2 released

This post is almost a carbon copy of the Kallithea 0.2 release notes. Kallithea project have just released Kallithea 0.2. Kallithea is a Python-based GPLv3 source code management software for web-based hosting of Mercurial and Git repositories. This release brings many changes since 0.1. Notably, pull requests system have been improved, making contributing changes more robust. The visual appearance has also been refined: modern font-based symbolic icons from FontAwesome and GitHub Octicons have replaced the previously used bitmap icons, and revision graphs are now drawn with HiDPI display support. Kallithea now supports Mercurial 3.3 and Dulwich 0.9.9. Several fixes in the database code boosted performance significantly. We have also updated our Javascript libraries: jQuery, CodeMirror and Mergely. Javascript and CSS code have been cleaned up, with less and less code depending on Yahoo UI library. Since 0.1 we have discovered two security issues, so all users are strongly recommended to upgrade. For more details on these issues, please see our Security Notices page For more information, see https://kallithea-scm.org/ or http://docs.kallithea-scm.org/. The summary of the changes since 0.1 release is below. Bug fixes: Features and improvements: Changes (might influence workflows): Cleanup:

9 April 2015

Daniel Pocock: Never fly Etihad again?

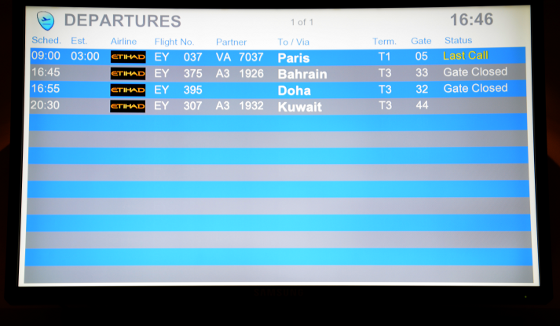
This is the first time we've flown out to Australia with Etihad and it may also be the last. We were due to fly back into Europe at CDG and head down to Lyon for the mini-DebConf this weekend. departure board, 18 hour delay for Paris Lets look at how our Etihad experience has worked out: 21:00 UTC Tuesday - waking up on Wednesday morning in Melbourne (UTC+10) 13:00 UTC Wednesday - leaving Melbourne about 11pm Wednesday night, a 12-13 hour flight to Abu Dhabi. We had heard about the air traffic control strikes in France (where we are going) and asked the airline if we should fly and they told us everything would be OK. 02:30 UTC Thursday - touchdown in Abu Dhabi, 6:30 am local time. Go to the transfer counter to ask for our boarding passes to CDG. At this stage, we were told that the connecting flight to CDG had been delayed 20 hours due to French strikes. As we are trying to reach Lyon for the mini-DebConf this weekend, we asked if we could leave Abu Dhabi on a 09:00 flight to Geneva. The Etihad staff told us to contact our travel agent (the flight was booked through Expedia) and for the next hour everybody's time was wasted making calls to Expedia who kept telling us to speak to Etihad. Whenever the Etihad customer service staff tried to speak to Expedia, the Expedia call center would hang up. Eventually, the Etihad staff told us that the deadline for putting us on the Geneva flight had passed and we would be stuck in Abu Dhabi for at least 20 hours. For flights to and from Europe, airlines have a responsibility to arrange hotels for passengers if there is a lengthy delay. If the airline is at fault, they must also pay some extra cash compensation but for a strike situation that is not applicable. Etihad has repeatedly fobbed us off. Initially we were given vouchers for Burger King or a pizza slice and told to hang around the transfer counter. By about 12:00 UTC (4pm local time, nine hours of waiting around the transfer counter) there was still no solution. One passenger was so upset that the airport security were called to speak to him and he was taken away. The airline staff kept giving excuses. Some passengers had been sent to a hotel but others left behind. I asked them again about our hotel and they kept trying to fob me off. Faced with the possibility that I would miss two nights of sleep and eight hours time difference coming into Europe, I continued asking the Etihad staff to own up to their responsibilities and they eventually offered us access to their airport lounge. We discovered some other passengers in the lounge too, including the passenger who had earlier been escorted away by security. This is unlike anything we've experienced with any other airline. At every opportunity (the check-in at Melbourne, or when the Geneva flight was boarding), the airline has failed to make arrangements that would have avoided cost and inconvenience. Assuming the flight goes ahead with a 20 hour delay, we will arrive in CDG some time Friday morning and not really sleep in a proper bed again until Friday night, about 70 hours after getting up in Melbourne on Wednesday morning. Thanks Etihad, you are a waking nightmare. The airline has been evasive about how they will deal with our onward travel from CDG to Lyon. We had booked a TGV train ticket already but it is not valid after such a long delay and it seems quite possible that trains will be busier than usual thanks to the air traffic control strike. So we don't even know if we will be loitering around a Paris airport or railway station for hours on Friday and nobody from the airline or Expedia really seems to care. Conclusion The only conclusion I can reach from this experience is that Etihad can't be trusted, certainly not for long journies such as Australia to Europe. Having flown through Singapore, Kuala Lumpur and Hong Kong, I know that air passengers have plenty of options available and there are many airlines that do go the extra mile to look after passengers especially on such long journeys. The airline missed opportunities to re-route us at every opportunity. It looks like they help some passengers (like those who did get to hotels) but leave many others high and dry just to stay within their budget.

7 April 2015

Wouter Verhelst: C11 function overloading

About four years ago, the ISO 9899:2011 "C11" standard was announced. At the time, I had a short look at (a draft version of) the standards document, and found a few interesting bits in there. Of course, however, due to it only very recently having been released, I did not have much hope of it being implemented to any reasonable amount anywhere yet. Which turned out to be the case. Even if that wasn't true, writing code that uses C11 features and expecting it to work just about anywhere else would have been a bad idea back then. We're several years down the line now, however, and now the standard has been implemented to a reasonable extent in most compilers. GCC claims its "support [for C11] is at a similar level of completeness to (...) C99 support" since GCC 4.9. Since my laptop has GCC 4.9, I looked at one feature in C11 that I have been wanting to use for a while: Generic selection.
#include <stdint.h>
#include <inttypes.h>
#include <stdio.h>
void say32(uint32_t i)  
    printf("32-bit variable: %" PRId32 "\n", i);
 
void say64(uint64_t i)  
    printf("64-bit variable: %" PRId64 "\n", i);
 
void sayother(int i)  
    printf("This is something else.\n");
 
#define say(X) _Generic((X), uint32_t: say32, uint64_t: say64, default: sayother)(X)
int main(void)  
    uint32_t v32 = 32;
    uint64_t v64 = 64;
    uint8_t v8 = 8;
    say(v32);
    say(v64);
    say(v8);
 
Output of the above:
32-bit variable: 32
64-bit variable: 64
This is something else.
or, "precompiler-assisted function overloading for C". Should be useful for things like:
#define ntoh(X) _Generic((X), int16_t: ntohs, uint16_t: ntohs, int32_t: ntohl, uint32_t: ntohl)(X)
#define hton(X) _Generic((X), int16_t: ntohs, uint16_t: htons, int32_t: ntohl, uint32_t: htonl)(X)
... and if one adds the ntohll found here, it can do 64 bit as well.

Wouter Verhelst: C11 operator overloading

C11 function overloading About four years ago, the ISO 9899:2011 "C11" standard was announced. At the time, I had a short look at (a draft version of) the standards document, and found a few interesting bits in there. Of course, however, due to it only very recently having been released, I did not have much hope of it being implemented to any reasonable amount anywhere yet. Which turned out to be the case. Even if that wasn't true, writing code that uses C11 features and expecting it to work just about anywhere else would have been a bad idea back then. We're several years down the line now, however, and now the standard has been implemented to a reasonable extent in most compilers. GCC claims its "support [for C11] is at a similar level of completeness to (...) C99 support" since GCC 4.9. Since my laptop has GCC 4.9, I looked at one feature in C11 that I have been wanting to use for a while: Generic selection.
#include <stdint.h>
#include <inttypes.h>
#include <stdio.h>
void say32(uint32_t i)  
    printf("32-bit variable: %" PRId32 "\n", i);
 
void say64(uint64_t i)  
    printf("64-bit variable: %" PRId64 "\n", i);
 
void sayother(int i)  
    printf("This is something else.\n");
 
#define say(X) _Generic((X), uint32_t: say32, uint64_t: say64, default: sayother)(X)
int main(void)  
    uint32_t v32 = 32;
    uint64_t v64 = 64;
    uint8_t v8 = 8;
    say(v32);
    say(v64);
    say(v8);
 
Output of the above:
32-bit variable: 32
64-bit variable: 64
This is something else.
or, "precompiler-assisted function overloading for C". Should be useful for things like:
#define ntoh(X) _Generic((X), int16_t: ntohs, uint16_t: ntohs, int32_t: ntohl, uint32_t: ntohl)(X)
#define hton(X) _Generic((X), int16_t: ntohs, uint16_t: htons, int32_t: ntohl, uint32_t: htonl)(X)
... and if one adds the ntohll found here, it can do 64 bit as well.

Lucas Nussbaum: Tentative systemd slides

I recently spent some time updating my systemd knowledge and decided to put together some slides that I ll use for a lecture. I m interested in feedback about things that are missing, unclear, etc. Available on slideshare, as PDF, and as LaTeX source.

Mike Hommey: Announcing git-cinnabar 0.2.0

Git-cinnabar is a git remote helper to interact with mercurial repositories. It allows to clone, pull and push from/to mercurial remote repositories, using git. Get it on github. What s new since 0.1.1? What to expect next? If you want to follow the improvements more closely, I encourage you to switch to the next branch. I won t push anything there that hasn t been extensively tested on the above mentioned repositories. And as always, please report any issue you run into.

6 April 2015

Daniel Leidert: Motion picture capturing: Debian + motion + Logitech C910

Woodpecker near the windowWinter time is a good time for some nature observation. Yesterday I had a woodpecker (picture) in front of my kitchen window. During the recent weeks there were long-tailed tits, a wren and other rarely seen birds. So I thought, it might be a good idea to capture some of these events :) I still own a Logitech C910 USB camera which allows HD video capturing up to 1080p. So I checked the web for some software that would begin video capturing in the case of motion detection and found motion, already available for Debian users. So I gave it a try. I tested all available resolutions of the camera together with the capturing results. I found that the resulting framerate of both the live stream and the captured video is highly depending on the resolution and some few configuration options. Below is a summary of my tests and the results I've achieved so far.

Logitech C910 HD cameraJust a bit of data regarding the camera. AFAIK it allows for fluent video streams up to 720p.
$ dmesg
[..]
usb 7-3: new high-speed USB device number 5 using ehci-pci
usb 7-3: New USB device found, idVendor=046d, idProduct=0821
usb 7-3: New USB device strings: Mfr=0, Product=0, SerialNumber=1
usb 7-3: SerialNumber: 91CF80A0
usb 7-3: current rate 0 is different from the runtime rate 16000
usb 7-3: current rate 0 is different from the runtime rate 32000
uvcvideo: Found UVC 1.00 device (046d:0821)
input: UVC Camera (046d:0821) as /devices/pci0000:00/0000:00:1a.7/usb7/7-3/7-3:1.2/input/input17

$ lsusb
[..]
Bus 007 Device 005: ID 046d:0821 Logitech, Inc. HD Webcam C910
[..]

$ v4l2-ctl -V -d /dev/video1
Format Video Capture:
Width/Height : 1280/720
Pixel Format : 'YUYV'
Field : None
Bytes per Line: 2560
Size Image : 1843200
Colorspace : SRGB
Also the uvcvideo kernel module is loaded and the user in question is part of the video group. Installation and startInstallation of the software is as easy as always:
apt-get install motion
It is possible to run the software as a service. But for testing, I copied /etc/motion/motion.conf to ~/.motion/motion.conf, fixed its permissions (you cannot copy the file as user - it's not world readable) and disabled the daemon mode.
daemon off
Note that in my case the correct device is /dev/video1 because the laptop has a built-in camera, that is /dev/video0. Also the target directory should be writeable by my user:
videodevice /dev/video1
target_dir ~/Videos
Then running motion from the command line ...
$ motion
[..]
[0] [NTC] [ALL] motion_startup: Motion 3.2.12+git20140228 Started
[..]
[1] [NTC] [ALL] motion_init: Thread 1 started , motion detection Enabled
[0] [NTC] [ALL] main: Thread 1 is device: /dev/video1 input -1
[1] [NTC] [VID] v4l2_get_capability:
------------------------
cap.driver: "uvcvideo"
cap.card: "UVC Camera (046d:0821)"
cap.bus_info: "usb-0000:00:1a.7-1"
cap.capabilities=0x84000001
------------------------
[1] [NTC] [VID] v4l2_get_capability: - VIDEO_CAPTURE
[1] [NTC] [VID] v4l2_get_capability: - STREAMING
[1] [NTC] [VID] v4l2_select_input: name = "Camera 1", type 0x00000002, status 00000000
[1] [NTC] [VID] v4l2_select_input: - CAMERA
[..]
[1] [NTC] [ALL] image_ring_resize: Resizing pre_capture buffer to 1 items
... will begin to capture motion detection events and also output a live stream. CTRL+C will stop it again. Live streamThe live stream is available by pointing the browser to localhost:8081. However, the stream seems to run at 1 fps (frames per second) and indeed does. The stream gets more quality by this configuration:
stream_motion on
stream_maxrate 100
The first option is responsible, that the stream only runs at one fps if there is no motion detection event. Otherwise the framerate increases to its maximum value, which is either the one given by stream_maxrate or the camera limit. The quality of the stream picture can be increased a bit further too by increasing the stream_quality value. Because I neither need the stream nor the control feed I disabled both:
stream_port 0
webcontrol_port 0
Picture capturingBy default there is video and picture capturing if a motion event is detected. I'm not interested in these pictures, so I turned them off:
output_pictures off
FYI: If you want a good picture quality, then the value of quality should very probably be increased. Video capturingThis is the really interesting part :) Of course if I will "shoot" some birds (with the camera), then a small image of say 320x240 pixels is not enough. The camera allows for a capture resolution up to 1920x1080 pixels (1080p). It is advertised for fluent video streams up to 720p (1280x720 pixels). So I tried the following resolutions: 320x240, 640x480, 800x600, 640x360 (360p), 1280x720 (720p) and 1920x1080 (1080p). These are easily configured by the width and height variables. For example the following configures motion for 1280x720 pixels (720p):
width 1280
height 720
The result was really disappointing. No event is captured with more then 20 fps. At higher resolutions the framerate drops even further and at the highest resolution of 1920x1080 pixels, the framerate is only two(!) fps. Also every created video runs much too fast and even faster by increasing the framerate variable. Of course its default value of 2 (fps) is not enough for fluent videos. AFAIK the C910 can run with 30 fps at 1280x720 pixels. So increasing the value of framerate, the maximum framerate recorded, is a must-do. (If you wanna test yourself, check the log output for the value following event_new_video FPS.)The solution to the issue, that videos are running too fast, however is to increase the pre_capture value, the number of pre-captured (buffered) pictures from before motion was detected. Even small values like 3..5 result in a distinctive improvement of the situation. Though increasing the value further didn't have any effect. So the values below should almost get the most out of the camera and result in videos in normal speed.
framerate 100
pre_capture 5
Videos in 1280x720 pixels are still captured with 10 fps and I don't know why. Running guvcview, the same camera allows for 30 fps in this resolution (even 60 fps in lower resolutions). However, even if the framerate could be higher, the resulting video runs fluently. Still the quality is just moderate (or to be honest, still disappointing). It looks "pixelated". Only static pictures are sharp. It took me a while to fix this too, because I first thought, the reason is the camera or missing hardware support. It is not :) The reason is, that ffmpeg is configured to produce a moderate(?)-quality video. The relevant variables are ffmpeg_bps and ffmpeg_variable_bitrate. I got the best results just changing the latter:
ffmpeg_variable_bitrate 2
Finally the resulting video quality is promising. I'll start with this configuration setting up an observation camera for the bird feeding ground.There is one more tweak for me. I got even better results by enabling the auto_brightness feature.
auto_brightness on
Complete configurationSo the complete configuration looks like this (only those options changed to the original config file)
daemon off
videodevice /dev/video1
width 1280
height 720
framerate 100
auto_brightness on
ffmpeg_variable_bitrate 2
target_dir /home/user/Videos
stream_port 0 #8081
stream_motion on
stream_maxrate 100
webcontrol_port 0 #8080
Links Continue with part II ...

Jonathan Carter: Squashfs Performance Testing

Experiments Last week I discovered The Fan Club s Experiments page. It reminds me of the Debian Experiments community on Google+. I like the concept of trying out all kinds of different things and reporting back to the community on how it works. I ve been meaning to do more of that myself so this is me jumping in and reporting back on something I ve been poking at this weekend. Introducing Squashfs Squashfs is a read-only compressed filesystem commonly used on embedded devices, Linux installation media and remote file systems (as is done in LTSP). Typically, a system like tmpfs, unionfs or aufs is mounted over this read-only system to make it usable as a root filesystem. It has plenty of other use cases too but for the purposes of this entry we ll stick with those use cases in mind. It supports gzip, lzo and xz(lzma) as compression back-ends. It also supports block sizes from 4K up to 1M. Compression technique as well as block size can have major effects on both performance and file size. In most cases the defaults will probably be sufficient, but if you want to find a good balance between performance and space saving, then you ll need some more insight. My Experiment: Test effects of squashfs compression methods and block sizes I m not the first person to have done some tests on squashfs performance and reported on it. Bernhard Wiedemann and the Squashfs LZMA project have posted some results before, and while very useful I want more information (especially compress/uncompress times). I was surprised to not find a more complete table elsewhere either. Even if such a table existed, I probably wouldn t be satisfied with it. Each squashfs is different and it makes a big difference whether it contains already compressed information or largely uncompressed information like clear text. I d rather be able to gather compression ratio/times for a specific image rather than for one that was used for testing purposes once-off. So, I put together a quick script that takes a squashfs image, extracts it to tmpfs, and then re-compressing it using it all the specified compression techniques and block sizes and then uncompressing those same images for their read speeds. My Testing Environment For this post, I will try out my script on the Ubuntu Desktop 14.04.2 LTS squashfs image. It s a complex image that contains a large mix of different kinds of files. I m extracting it to RAM since I want to avoid having disk performance as a significant factor. I m compressing the data back to SSD and extracting from there for read speed tests. The SSD seems fast enough not to have any significant effect on the tests. If you have a slow storage, the results of the larger images (with smaller block sizes) may be skewed unfavourably. As Bernhard mentioned on his post, testing the speed of your memory can also be useful, especially when testing on different kinds of systems and comparing the results:
# dd if=/dev/zero of=/dev/null bs=1M count=100000
104857600000 bytes (105 GB) copied, 4.90059 s, 21.4 GB/s
CPU is likely to be your biggest bottleneck by far when compressing. mksquashfs is SMP aware and will use all available cores by default. I m testing this on a dual core Core i7 laptop with hyper-threading (so squashfs will use 4 threads) and with 16GB RAM apparently transferring around 21GB/s. The results of the squashfs testing script will differ greatly based on the CPU cores, core speed, memory speed and storage speed of the computer you re running it on, so it shouldn t come as a surprise if you get different results than I did. If you don t have any significant bottleneck (like slow disks, slow CPU, running out of RAM, etc) then your results should more or less correspond in scale to mine for the same image. How to Run It Create a directory and place the filesystem you d like to test as filesystem.squashfs, then:
$ apt-get install squashfs-tools 
$ wget https://raw.githubusercontent.com/highvoltage/squashfs-experiments/master/test-mksquashfs.sh
$ bash test-mksquashfs.sh
With the default values in that file, you ll end up with 18 squashfs images taking up about 18GB of disk space. I keep all the results for inspection, but I ll probably adapt/fix the script to be more friendly to disk space usage some time. You should see output that look something like this, with all the resulting data in the ./results directory.
* Setting up...
- Testing gzip
  * Running a squashfs using compression gzip, blocksize 4096
  * Running a squashfs using compression gzip, blocksize 8192
  * Running a squashfs using compression gzip, blocksize 16384
  ...
- Testing lzo
  * Running a squashfs using compression lzo, blocksize 4096
  * Running a squashfs using compression lzo, blocksize 8192
  * Running a squashfs using compression lzo, blocksize 16384
  ...
- Testing xz
  * Running a squashfs using compression xz, blocksize 4096
  * Running a squashfs using compression xz, blocksize 8192
  * Running a squashfs using compression xz, blocksize 16384
  ...
* Testing uncompressing times...
  * Reading results/squashfs-gzip-131072.squashfs...
  * Reading results/squashfs-gzip-16384.squashfs...
  * Reading results/squashfs-gzip-32768.squashfs...
  ...
* Cleaning up...
On to the Results The report script will output the results into CSV. Here s the table with my results. Ratio is percentage of the size of the original uncompressed data, CTIME and UTIME is compression time and uncompress time for the entire image.
Filename Size Ratio CTIME UTIME
squashfs-gzip-4096.squashfs 1137016 39.66% 0m46.167s 0m37.220s
squashfs-gzip-8192.squashfs 1079596 37.67% 0m53.155s 0m35.508s
squashfs-gzip-16384.squashfs 1039076 36.27% 1m9.558s 0m26.988s
squashfs-gzip-32768.squashfs 1008268 35.20% 1m30.056s 0m30.599s
squashfs-gzip-65536.squashfs 987024 34.46% 1m51.281s 0m35.223s
squashfs-gzip-131072.squashfs 975708 34.07% 1m59.663s 0m22.878s
squashfs-gzip-262144.squashfs 970280 33.88% 2m13.246s 0m23.321s
squashfs-gzip-524288.squashfs 967704 33.79% 2m11.515s 0m24.865s
squashfs-gzip-1048576.squashfs 966580 33.75% 2m14.558s 0m28.029s
squashfs-lzo-4096.squashfs 1286776 44.88% 1m36.025s 0m22.179s
squashfs-lzo-8192.squashfs 1221920 42.64% 1m49.862s 0m21.690s
squashfs-lzo-16384.squashfs 1170636 40.86% 2m5.008s 0m20.831s
squashfs-lzo-32768.squashfs 1127432 39.36% 2m23.616s 0m20.597s
squashfs-lzo-65536.squashfs 1092788 38.15% 2m48.817s 0m21.164s
squashfs-lzo-131072.squashfs 1072208 37.43% 3m4.990s 0m20.563s
squashfs-lzo-262144.squashfs 1062544 37.10% 3m26.816s 0m15.708s
squashfs-lzo-524288.squashfs 1057780 36.93% 3m32.189s 0m16.166s
squashfs-lzo-1048576.squashfs 1055532 36.85% 3m42.566s 0m17.507s
squashfs-xz-4096.squashfs 1094880 38.19% 5m28.104s 2m21.373s
squashfs-xz-8192.squashfs 1002876 34.99% 5m15.148s 2m1.780s
squashfs-xz-16384.squashfs 937748 32.73% 5m11.683s 1m47.878s
squashfs-xz-32768.squashfs 888908 31.03% 5m17.207s 1m43.399s
squashfs-xz-65536.squashfs 852048 29.75% 5m27.819s 1m38.211s
squashfs-xz-131072.squashfs 823216 28.74% 5m42.993s 1m29.708s
squashfs-xz-262144.squashfs 799336 27.91% 6m30.575s 1m16.502s
squashfs-xz-524288.squashfs 778140 27.17% 6m58.455s 1m20.234s
squashfs-xz-1048576.squashfs 759244 26.51% 7m19.205s 1m28.721s
Some notes:

Next.

Previous.