Search Results: "tar"

25 August 2017

Steve Kemp: Interesting times debugging puppet

I recently upgraded a bunch of systems from Jessie to Stretch, and as a result of that one of my hosts has started showing me a lot of noise in an hourly cron-email:
Command line is not complete. Try option "help"
I've been ignoring these emails for the past while, but today I sat down to track down the source. It was obviously coming from facter, the system that puppet uses to gather information about hosts. Running facter -debug made that apparent:
 root@smaug ~ # facter --debug
 Found no suitable resolves of 1 for ec2_metadata
 value for ec2_metadata is still nil
 value for netmask_git is still nil
 value for ipaddress6_lo is still nil
 value for macaddress_lo is still nil
 value for ipaddress_master is still nil
 value for ipaddress6_master is still nil
 Command line is not complete. Try option "help"
 value for netmask_master is still nil
 value for ipaddress_skx_mail is still nil
 ..
There we see the issue, and it is obviously relating to our master interface. To cut a long-story short /usr/lib/ruby/vendor_ruby/facter/util/ip.rb contains some code which eventually runs this:
 ip link show $interface
That works on all other interfaces I have:
  $ ip link show git
  6: git: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UNKNOWN mode DEFAULT group default qlen 1000
But not on master:
  $ ip link show master
  Command line is not complete. Try option "help"
I ninja-edited the code from this:
  ethbond = regex.match(%x /sbin/ip link show '# interface ' )
to:
  ethbond = regex.match(%x /sbin/ip link show dev '# interface ' )
And suddenly puppet-runs without any errors. I'm not 100% sure if this is a bug bug, but it is something of a surprise anyway.
This host runs KVM guests, one of the guests is a puppet-master, with a local name master. Hence the name of the interface. Similarly the interface git is associated with the KVM guest behind git.steve.org.uk.

Reproducible builds folks: Reproducible Builds: Weekly report #121

Here's what happened in the Reproducible Builds effort between Sunday August 13 and Saturday August 19 2017: Reproducible Builds finally mandated by Debian Policy "Packages should build reproducibly" was merged into Debian policy! The added text is as follows and has been included into debian-policy 4.1.0.0:
Reproducibility
---------------
Packages should build reproducibly, which for the purposes of this
document [#]_ means that given
- a version of a source package unpacked at a given path;
- a set of versions of installed build dependencies;
- a set of environment variable values;
- a build architecture; and
- a host architecture,
repeatedly building the source package for the build architecture on
any machine of the host architecture with those versions of the build
dependencies installed and exactly those environment variable values
set will produce bit-for-bit identical binary packages.
It is recommended that packages produce bit-for-bit identical binaries
even if most environment variables and build paths are varied.  It is
intended for this stricter standard to replace the above when it is
easier for packages to meet it.
.. [#]
   This is Debian's precisification of the  reproducible-builds.org
   definition  _.
Reproducible work in other projects Bernhard M. Wiedemann's reproducibleopensuse scripts now work on Debian buster on the openSUSE Build Service with the latest versions of osc and obs-build. Toolchain development and fixes #872514 was opened on devscripts by Chris Lamb to add a reproducible-check program to report on the reproducibility status of installed packages. Packages reviewed and fixed, and bugs filed Upstream reports: Debian reports: Debian non-maintainer uploads: Reviews of unreproducible packages 47 package reviews have been added, 58 have been updated and 39 have been removed in this week, adding to our knowledge about identified issues. 4 issue types have been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Development continued in git, including the following contributions: disorderfs development Development continued in git, including the following contributions: reprotest development Development continued in git, including the following contributions: tests.reproducible-builds.org Mattia fixed the script which creates the HTML representation of our database scheme to not append .html twice to the filename. Misc. This week's edition was written by Ximin Luo, Chris Lamb and Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Dirk Eddelbuettel: BH 1.65.0-1

The BH package on CRAN was updated today to version 1.65.0. BH provides a sizeable portion of the Boost C++ libraries as a set of template headers for use by R, possibly with Rcpp as well as other packages. This release upgrades the version of Boost to the rather new upstream version Boost 1.65.0 released earlier this week, and adds two new libraries: align and sort. I had started the upgrade process a few days ago under release 1.64.0. Rigorous checking of reverse dependencies showed that mvnfast needed a small change (which was trivial: just seeding the RNG prior to running tests), which Matteo did in no time with a fresh CRAN upload. rstan is needing a bit more work but should be ready real soon now and we are awaiting a new version. And once I switched to the just release Boost 1.65.0 it became apparent that Cyclops no longer needs its embedded copy of Boost iterator---and Marc already made that change with yet another fresh CRAN upload. It is a true pleasure to work in such a responsive and collaborative community.

Changes in version 1.65.0-1 (2017-08-24)
  • Upgraded to Boost 1.64 and then 1.65 installed directly from upstream source with several minor tweaks (as before)
  • Fourth tweak corrects a misplaced curly brace (see the Boost ublas GitHub repo and its issue #40)
  • Added Boost align (as requested in #32)
  • Added Boost sort (as requested in #35)
  • Added Boost multiprecision by fixing a script typo (as requested in #42)
  • Updated Travis CI support via newer run.sh

Via CRANberries, there is a diffstat report relative to the previous release. Comments and suggestions are welcome via the mailing list or the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

24 August 2017

Michal &#268;iha&#345;: Taking over siphashc for Python

Since some time we're using siphash algorithm to speed up looking up strings in Weblate. Even though it is used by Python internally, it's not exposed in the standard library so several third party modules appeared in the PyPI. Out of all these siphashc or rather it's Python 3 fork siphashc3 seemed to perform best, so I've started to use that. However it turned out that none of them is in active maintenance anymore. The original version lacks Python 3 support, while the siphashc3 uses odd versioning which causes problems to some pip versions. After trying to get fix into siphashc3 without much of success, I've spoken to original author of siphashc and he has agreed to hand over maintainership to me. So it's new home is at https://github.com/WeblateOrg/siphashc and new release is already available on PyPI. Note: Originally we were using MD5 in Weblate, but siphash has shown to be faster and fits into 64-bits, what makes it easier to store and index in SQL databases as LONGINT.

Filed under: Debian English SUSE Weblate

Urvika Gola: Much awaited.. DebConf 17 in Montreal.

On 5th August I got a chance to attend, speak and experience DebConf 2017 at Montreal, Canada. The conference was stretch ed from 6 August to 12 August .
debconf_picture1Seasons of Debian Summer of Code & Winter of Outreachy
Pretty late for me to document my DebConf fun-learning-experiences, thanks to my delaying tactics.. I need to overcome.
But better late than ever, I had amazing time at DebConf. I got to meet and learn from my Outreachy Mentor, Daniel Pocock!
img_5634-e1503506917678.jpgPicture of Daniel and me captured by : Dorina Mosku
One thing about DebConf I loved was the amount of Diversity in Debian family! As a beginner, I got to get a big picture of what all projects are there. Daniel helped me a lot in getting started with packaging in Debian. I really appreciate the time he took out to guide me @DebConf and Pranav, remotely. One specific line I liked about Daniel s talk on Open Day, 5th August Free Communications with Free Software and Debian while talking about free RTC (Real Time Communication) is that, ..Instead of communication controlling the user, the user can control the communcation.. I talked about free RTC, my Project Lumicall and about my journey being an Outreachy Intern with Debian. I also covered my co-speaker s project work on Lumicall being a GSoC 2016 student.
IMG_0796Picture captured by Aigars Mahinovs
debconf_picture2Managing Debian s RTC services Daniel Pocock
Meeting the Outreachy family feels amaazzing! Karen Sandler, executive director of the Software Freedom Conservancy gave a talk on the Significance and Impact of Outreachy and Debian s support for the programme.
DG58B_gXUAA2GsAwith Karen Sandler and Outreachy alumini
DebConf 2017 has been a wonderful conference with the community being very welcoming and helpful

23 August 2017

Sylvestre Ledru: Rebuild of Debian using Clang 3.9, 4.0 and 5.0

tldr: The percentage of failure is decreasing, Clang support is improving but there is a long way to go. The goal of this initiative is to rebuild Debian using Clang as a compiler instead of gcc. I have been doing this analysis for the last 6 years. Recently, we rebuilt the archive of the Debian archive with Clang 3.9.1 (July 6th), 4.0.1 (July 6th) and 5.0 rc2 (August 20th). For various reasons, we didn't perform a rebuild since June 2016 with version 3.8. Therefor, we took the opportunity to do three over the last month. Now, the 3.9 & 4.0 results are impacted by a build failure when building all haskell packages (the -no-pie option in Clang doesn't exist - I introduced it in clang 5.0). Fixing this issue with 5.0 removed more than 860 failures. Also, for the same versions, a Qt compiler detection is considering that Clang is not a C++11 compiler because clang++, by default, defines __cplusplus as 199711L (-std=c++11 has to be added to define a correct __cplusplus). See https://bugreports.qt.io/browse/QTBUG-62535 for more information. Some discussions happened on the upstream mailing list about changing the default C++ dialect.
For example, with 4.0, this is causing 132 errors. With 5.0, probably thanks to a new Qt version, roughly the same number of packages are failing but because gcc just triggers a warning with the "nodiscard" attribute being incorrectly used when clang triggers an error. In parallel, ignoring the haskell build failures, the numbers sightly increased since last year even if the overall percentage decreased (new packages being uploaded in the archive).
VersionBuild failuresIgnoring haskell pkgs
3.81367 / 5.6%
3.92274 / 8.1%1618 / 5.8%
4.02311 / 8.3%1655 / 5.9%
5.01445 / 5.1%
In parallel, new warnings and errors showed up in Clang.
This is causing a new set of build failures (especially with the usage of -Werror). As few examples:
* Starting with 4.0, clang triggers an error ordered comparison between pointer and zero ('char *' and 'int').
* Similarly, with this version, -Wmain introduces a new warning which will trigger a warning when a bool literal is returned from main.
* clang also introduced a new warning called -Waddress-of-packed-member causing 5 new errors.
* With the same version, clang can trigger a new error when auto is used in function return type. Now, as a conclusion, having Debian being built with clang by default is still a long shot.
First, when Clang became usable for a general audience, gcc was lagging in term of warning and error detections. Now, gcc is in a much better position than it was, decreasing the interest to have clang replacing gcc. In parallel, most of the efforts in term of warnings
and mistake detections are currently done under the clang tidy umbrella, making them less intrusive as part of this initiative (but harder to use and to deploy).
As an example, the gcc warning -Wmisleading-indentation has been implemented under a clang-tidy checker.
Second, the very permissive license of clang has been a key factor for some operating systems to switch like the PS4, Mac OS X or FreeBSD. With Debian, the community is generally happy with the GPL.
Third, the performances are similar enough that it is not worth the work, except for some projects with very special needs. Last, despite that it is much easier to contribute to llvm/clang than gcc (not copyright assignment or actual review system for example), this isn't a big differentiator for most of the projects. Of course, I will continue to run and analysis these rebuilds as this is a great source of information for clang upstream developers to improve the compatibility with gcc and understand some impacts. However, until there is a big game changer, I will stop pursuing the goal of having Debian switching to clang instead of gcc. I will stop effort on the debile project (which was aiming to rebuild in the background packages).

Antoine Beaupr : The supposed decline of copyleft

At DebConf17, John Sullivan, the executive director of the FSF, gave a talk on the supposed decline of the use of copyleft licenses use free-software projects. In his presentation, Sullivan questioned the notion that permissive licenses, like the BSD or MIT licenses, are gaining ground at the expense of the traditionally dominant copyleft licenses from the FSF. While there does seem to be a rise in the use of permissive licenses, in general, there are several possible explanations for the phenomenon.

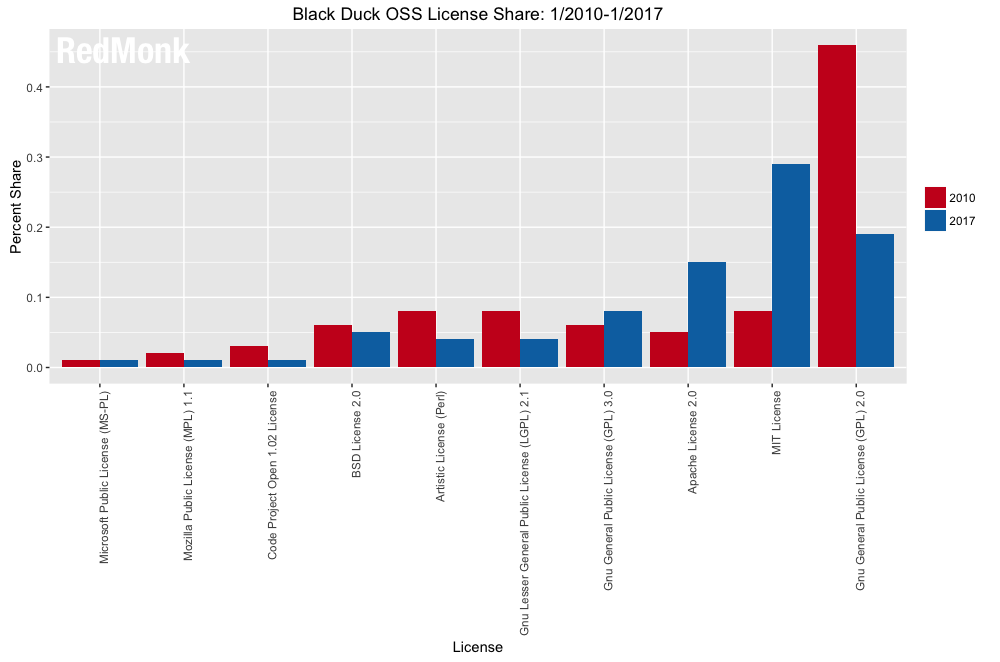
When the rumor mill starts Sullivan gave a recent example of the claim of the decline of copyleft in an article on Opensource.com by Jono Bacon from February 2017 that showed a histogram of license usage between 2010 and 2017 (seen below).
[Black Duck   histogram]
From that, Bacon elaborates possible reasons for the apparent decline of the GPL. The graphic used in the article was actually generated by Stephen O'Grady in a January article, The State Of Open Source Licensing, which said:
In Black Duck's sample, the most popular variant of the GPL version 2 is less than half as popular as it was (46% to 19%). Over the same span, the permissive MIT has gone from 8% share to 29%, while its permissive cousin the Apache License 2.0 jumped from 5% to 15%.
Sullivan, however, argued that the methodology used to create both articles was problematic. Neither contains original research: the graphs actually come from the Black Duck Software "KnowledgeBase" data, which was partly created from the old Ohloh web site now known as Open Hub. To show one problem with the data, Sullivan mentioned two free-software projects, GNU Bash and GNU Emacs, that had been showcased on the front page of Ohloh.net in 2012. On the site, Bash was (and still is) listed as GPLv2+, whereas it changed to GPLv3 in 2011. He also claimed that "Emacs was listed as licensed under GPLv3-only, which is a license Emacs has never had in its history", although I wasn't able to verify that information from the Internet archive. Basically, according to Sullivan, "the two projects featured on the front page of a site that was using [the Black Duck] data set were wrong". This, in turn, seriously brings into question the quality of the data:
I reported this problem and we'll continue to do that but when someone is not sharing the data set that they're using for other people to evaluate it and we see glimpses of it which are incorrect, that should give us a lot of hesitation about accepting any conclusion that comes out of it.
Reproducible observations are necessary to the establishment of solid theories in science. Sullivan didn't try to contact Black Duck to get access to the database, because he assumed (rightly, as it turned out) that he would need to "pay for the data under terms that forbid you to share that information with anybody else". So I wrote Black Duck myself to confirm this information. In an email interview, Patrick Carey from Black Duck confirmed its data set is proprietary. He believes, however, that through a "combination of human and automated techniques", Black Duck is "highly confident at the accuracy and completeness of the data in the KnowledgeBase". He did point out, however, that "the way we track the data may not necessarily be optimal for answering the question on license use trend" as "that would entail examination of new open source projects coming into existence each year and the licenses used by them". In other words, even according to Black Duck, its database may not be useful to establish the conclusions drawn by those articles. Carey did agree with those conclusions intuitively, however, saying that "there seems to be a shift toward Apache and MIT licenses in new projects, though I don't have data to back that up". He suggested that "an effective way to answer the trend question would be to analyze the new projects on GitHub over the last 5-10 years." Carey also suggested that "GitHub has become so dominant over the recent years that just looking at projects on GitHub would give you a reasonable sampling from which to draw conclusions".
[GitHub   graph]
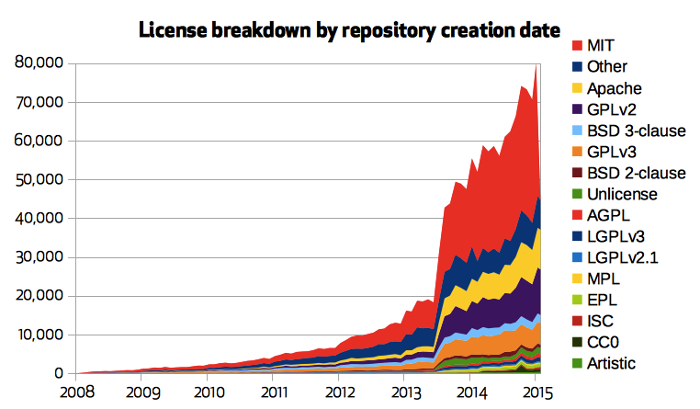
Indeed, GitHub published a report in 2015 that also seems to confirm MIT's popularity (45%), surpassing copyleft licenses (24%). The data is, however, not without its own limitations. For example, in the above graph going back to the inception of GitHub in 2008, we see a rather abnormal spike in 2013, which seems to correlate with the launch of the choosealicense.com site, described by GitHub as "our first pass at making open source licensing on GitHub easier". In his talk, Sullivan was critical of the initial version of the site which he described as biased toward permissive licenses. Because the GitHub project creation page links to the site, Sullivan explained that the site's bias could have actually influenced GitHub users' license choices. Following a talk from Sullivan at FOSDEM 2016, GitHub addressed the problem later that year by rewording parts of the front page to be more accurate, but that any change in license choice obviously doesn't show in the report produced in 2015 and won't affect choices users have already made. Therefore, there can be reasonable doubts that GitHub's subset of software projects may not actually be that representative of the larger free-software community.

In search of solid evidence So it seems we are missing good, reproducible results to confirm or dispel these claims. Sullivan explained that it is a difficult problem, if only in the way you select which projects to analyze: the impact of a MIT-licensed personal wiki will obviously be vastly different from, say, a GPL-licensed C compiler or kernel. We may want to distinguish between active and inactive projects. Then there is the problem of code duplication, both across publication platforms (a project may be published on GitHub and SourceForge for example) but also across projects (code may be copy-pasted between projects). We should think about how to evaluate the license of a given project: different files in the same code base regularly have different licenses often none at all. This is why having a clear, documented and publicly available data set and methodology is critical. Without this, the assumptions made are not clear and it is unreasonable to draw certain conclusions from the results. It turns out that some researchers did that kind of open research in 2016 in a paper called "The Debsources Dataset: Two Decades of Free and Open Source Software" [PDF] by Matthieu Caneill, Daniel M. Germ n, and Stefano Zacchiroli. The Debsources data set is the complete Debian source code that covers a large history of the Debian project and therefore includes thousands of free-software projects of different origins. According to the paper:
The long history of Debian creates a perfect subject to evaluate how FOSS licenses use has evolved over time, and the popularity of licenses currently in use.
Sullivan argued that the Debsources data set is interesting because of its quality: every package in Debian has been reviewed by multiple humans, including the original packager, but also by the FTP masters to ensure that the distribution can legally redistribute the software. The existence of a package in Debian provides a minimal "proof of use": unmaintained packages get removed from Debian on a regular basis and the mere fact that a piece of software gets packaged in Debian means at least some users found it important enough to work on packaging it. Debian packagers make specific efforts to avoid code duplication between packages in order to ease security maintenance. The data set covers a period longer than Black Duck's or GitHub's, as it goes all the way back to the Hamm 2.0 release in 1998. The data and how to reproduce it are freely available under a CC BY-SA 4.0 license.
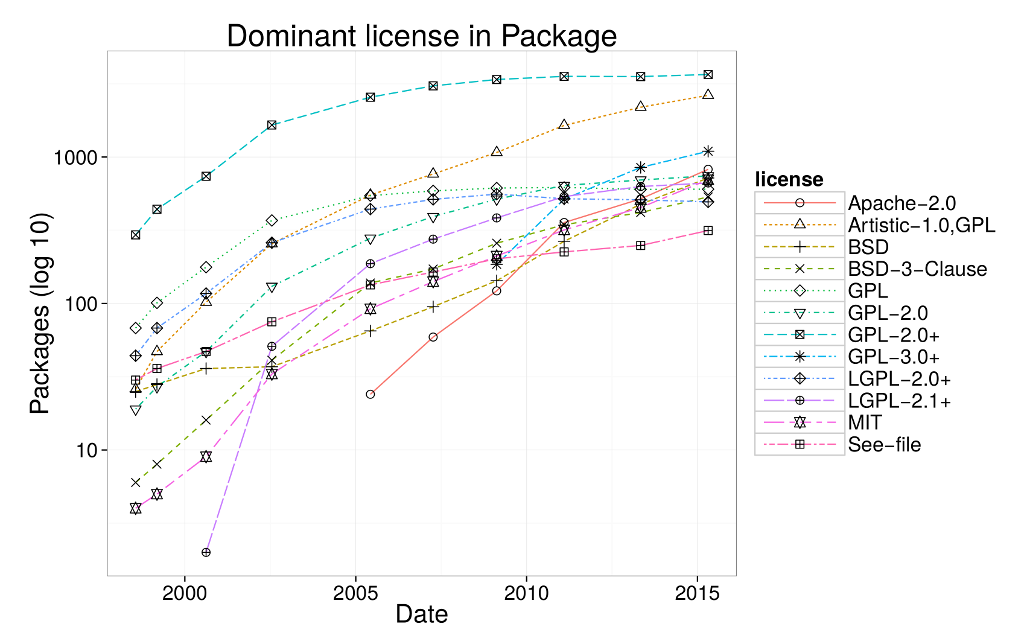
[Debsource   graph]
Sullivan presented the above graph from the research paper that showed the evolution of software license use in the Debian archive. Whereas previous graphs showed statistics in percentages, this one showed actual absolute numbers, where we can't actually distinguish a decline in copyleft licenses. To quote the paper again:
The top license is, once again, GPL-2.0+, followed by: Artistic-1.0/GPL dual-licensing (the licensing choice of Perl and most Perl libraries), GPL-3.0+, and Apache-2.0.
Indeed, looking at the graph, at most do we see a rise of the Apache and MIT licenses and no decline of the GPL per se, although its adoption does seem to slow down in recent years. We should also mention the possibility that Debian's data set has the opposite bias: toward GPL software. The Debian project is culturally quite different from the GitHub community and even the larger free-software ecosystem, naturally, which could explain the disparity in the results. We can only hope a similar analysis can be performed on the much larger Software Heritage data set eventually, which may give more representative results. The paper acknowledges this problem:
Debian is likely representative of enterprise use of FOSS as a base operating system, where stable, long-term and seldomly updated software products are desirable. Conversely Debian is unlikely representative of more dynamic FOSS environments (e.g., modern Web-development with micro libraries) where users, who are usually developers themselves, expect to receive library updates on a daily basis.
The Debsources research also shares methodology limitations with Black Duck: while Debian packages are reviewed before uploading and we can rely on the copyright information provided by Debian maintainers, the research also relies on automated tools (specifically FOSSology) to retrieve license information. Sullivan also warned against "ascribing reason to numbers": people may have different reasons for choosing a particular license. Developers may choose the MIT license because it has fewer words, for compatibility reasons, or simply because "their lawyers told them to". It may not imply an actual deliberate philosophical or ideological choice. Finally, he brought up the theory that the rise of non-copyleft licenses isn't necessarily at the detriment of the GPL. He explained that, even if there is an actual decline, it may not be much of a problem if there is an overall growth of free software to the detriment of proprietary software. He reminded the audience that non-copyleft licenses are still free software, according to the FSF and the Debian Free Software Guidelines, so their rise is still a positive outcome. Even if the GPL is a better tool to accomplish the goal of a free-software world, we can all acknowledge that the conversion of proprietary software to more permissive and certainly simpler licenses is definitely heading in the right direction.
[I would like to thank the DebConf organizers for providing meals for me during the conference.] Note: this article first appeared in the Linux Weekly News.

22 August 2017

Jonathan McDowell: Notes on upgrading from Jessie to Stretch

I upgraded my last major machine from Jessie to Stretch last week. That machine was the one running the most services, but I d made notes while updating various others to ensure it went smoothly. Below are the things I noted along the way, both for my own reference and in case they are of use to anyone else. Other than those points things were pretty smooth. Nice work by all those involved!

John Goerzen: The Eclipse

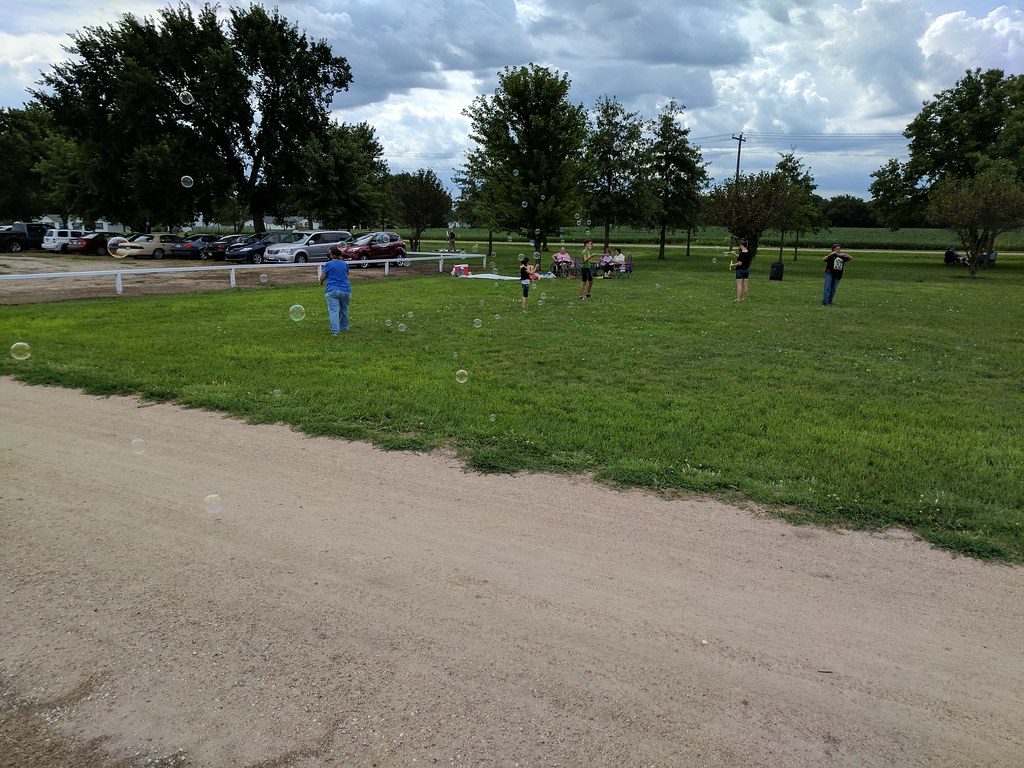
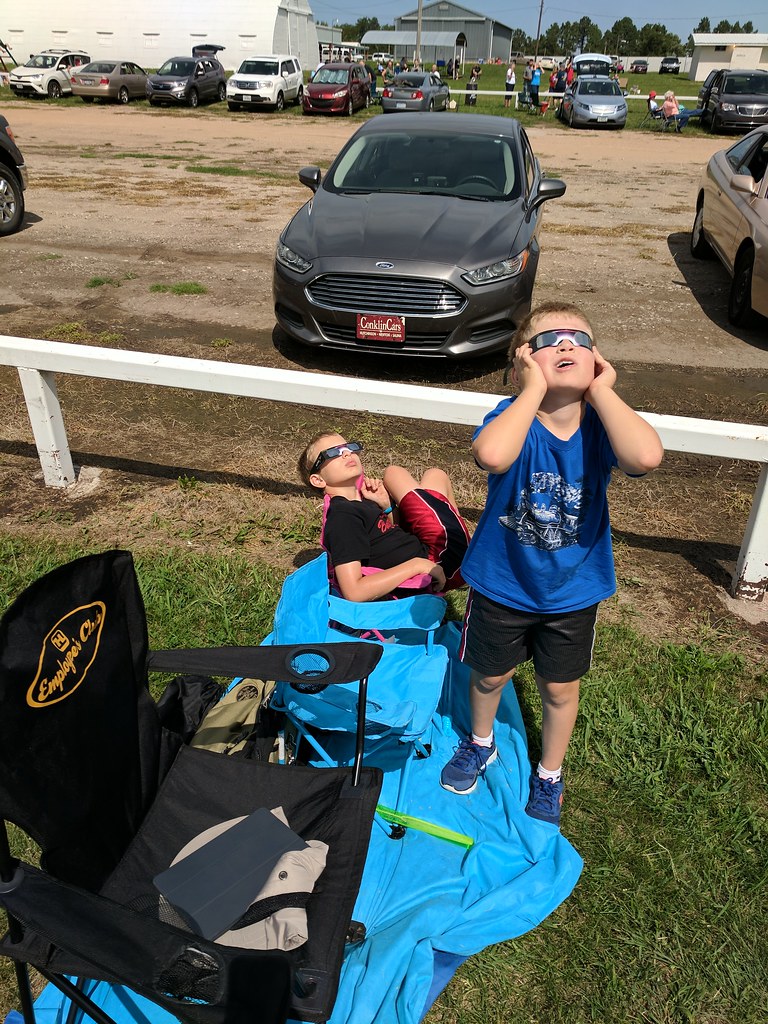
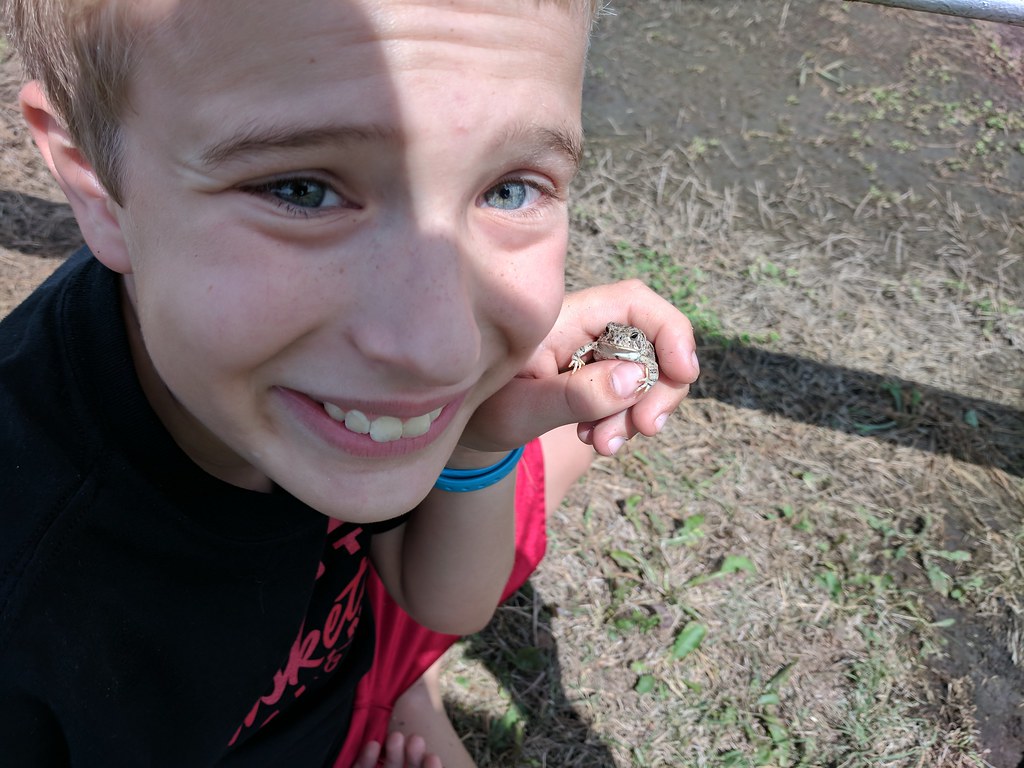
Highway US-81 in northern Kansas and southern Nebraska is normally a pleasant, sleepy sort of drive. It was upgraded to a 4-lane road not too long ago, but as far as 4-lane roads go, its traffic is typically light. For drives from Kansas to South Dakota, it makes a pleasant route. Yesterday was eclipse day. I strongly suspect that highway 81 had more traffic that day than it ever has before, or ever will again. For nearly the entire 3-hour drive to Geneva, NE, it was packed though mostly still moving at a good speed. And for our entire drive back, highway 81 and every other southbound road we used was so full it felt like rush hour in Dallas. (Well, not quite. Traffic was still moving.) I believe scenes like this were played out across the continent. I ve been taking a lot of photos, and writing about our new baby Martha lately. Now it s time to write a bit about some more adventures with Jacob and Oliver they re now in third and fifth grades in school. We had been planning to fly, and airports I called were either full, or were planning to park planes in the grass, or even shut down some runways to use for parking. The airport in the little town of Beatrice, NE (which I had visited twice before) was even going to have a temporary FAA control tower. At the last minute, due to some storm activity near home at departure time, we unloaded the plane and drove instead. The atmosphere at the fairgrounds in Geneva was festive. One family had brought bubbles for their kids and extras to share. IMG_20170821_113229 I had bought the boys a book about the eclipse, which they were reading before and during the event. They were both great, safe users of their eclipse glasses. IMG_20170821_124809 Jacob caught a toad, and played with it for awhile. He wanted to bring it home with us, but I convinced him to let me take a picture of him with his toad friend instead. IMG_20170821_124553 While we were waiting for totality, a number of buses from the local school district arrived. So by the time the big moment arrived, we could hear the distant roar of delight and applause from the school children gathered at the far end of the field, plus all the excitement nearby. Both boys were absolutely ecstatic to be witnessing it (and so was I!) Wow! Awesome! And simple cackles of delight were heard. On the drive home, they both kept talking about how amazing it was, and it was once in a lifetime. We enjoyed our eclipse neighbors the woman from San Antonio next to us, the surprise discovery of another family from just a few miles from us parked two cars down, even running into relatives at a restaurant on the way home. The applause from all around when it started and when it ended. And the feeling, which is hard to describe, of awe and amazement at the wonders of our world and our universe. There are many problems with the world right now, but somehow there s something right about people coming together from all over to enjoy it.

Daniel Silverstone: Building a USB descriptor table set

In order to proceed further on our USB/STM32 oddessy, we need to start to build a USB descriptor set for our first prototype piece of code. For this piece, we're going to put together a USB device which is vendor-specific class-wise and has a single configuration with a interface with a single endpoint which we're not going to actually implement anything of. What we're after is just to get the information presented to the computer so that lsusb can see it. To get these built, let's refer to information we discovered and recorded in a previous post about how descriptors go together.

Device descriptor Remembering that values which are > 1 byte in length are always stored little-endian, we can construct our device descriptor as:
Our device descriptor
Field Name Value Bytes
bLength 18 0x12
bDescriptorType DEVICE 0x01
bcdUSB USB 2.0 0x00 0x02
bDeviceClass 0 0x00
bDeviceSubClass 0 0x00
bDeviceProtocol 0 0x00
bMaxPacketSize 64 0x40
idVendor TEST 0xff 0xff
idProduct TEST 0xff 0xff
bcdDevice 0.0.1 0x01 0x00
iManufacturer 1 0x01
iProduct 2 0x02
iSerialNumber 3 0x03
bNumConfigurations 1 0x01
We're using the vendor ID and product id 0xffff because at this point we don't have any useful values for this (it costs $5,000 to register a vendor ID). This gives us a final byte array of:
0x12 0x01 0x00 0x02 0x00 0x00 0x00 0x40 (Early descriptor) 0xff 0xff 0xff 0xff 0x01 0x00 0x01 0x02 0x03 0x01 (and the rest)
We're reserving string ids 1, 2, and 3, for the manufacturer string, product name string, and serial number string respectively. I'm deliberately including them all so that we can see it all come out later in lsusb. If you feed the above hex sequence into a USB descriptor decoder then you can check my working.

Endpoint Descriptor We want a single configuration, which covers our one interface, with one endpoint in it. Let's start with the endpoint...
Our bulk IN endpoint
Field Name Value Bytes
bLength 7 0x07
bDescriptorType ENDPOINT 0x05
bEndpointAddress EP2IN 0x82
bmAttributes BULK 0x02
wMaxPacketSize 64 0x40 0x00
bInterval IGNORED 0x00
We're giving a single bulk IN endpoint, since that's the simplest thing to describe at this time. This endpoint will never be ready and so nothing will ever be read into the host. All that gives us:
0x07 0x05 0x82 0x02 0x40 0x00 0x00

Interface Descriptor The interface descriptor prefaces the endpoint set, and thanks to our simple single endpoint, and no plans for alternate interfaces, we can construct the interface simply as:
Our single simple interface
Field Name Value Bytes
bLength 9 0x09
bDescriptorType INTERFACE 0x04
bInterfaceNumber 1 0x01
bAlternateSetting 1 0x01
bNumEndpoints 1 0x01
bInterfaceClass 0 0x00
bInterfaceSubClass 0 0x00
bInterfaceProtocol 0 0x00
iInterface 5 0x05
All that gives us:
0x09 0x04 0x01 0x01 0x01 0x00 0x00 0x00 0x05

Configuration descriptor Finally we can put it all together and get the configuration descriptor...
Our sole configuration, encapsulating the interface and endpoint above
Field Name Value Bytes
bLength 9 0x09
bDescriptorType CONFIG 0x02
wTotalLength 9+9+7 0x19 0x00
bNumInterfaces 1 0x01
bConfigurationValue 1 0x01
iConfiguration 4 0x04
bmAttributes Bus powered, no wake 0x80
bMaxPower 500mA 0xfa
The wTotalLength field is interesting. It contains the configuration length, the interface length, and the endpoint length, hence 9 plus 9 plus 7 is 25. This gives:
0x09 0x02 0x19 0x00 0x01 0x01 0x04 0x80 0xfa

String descriptors We allowed ourselves a total of five strings, they were iManufacturer, iProduct, iSerial (from the device descriptor), iConfiguration (from the configuration descriptor), and iInterface (from the interface descriptor) respectively. Our string descriptors will therefore be:
String descriptor zero, en_GB only
Field Name Value Bytes
bLength 4 0x04
bDescriptorType STRING 0x03
wLangID[0] en_GB 0x09 0x08
0x04 0x03 0x09 0x08
...and...
String descriptor one, iManufacturer
Field Name Value Bytes
bLength 38 0x26
bDescriptorType STRING 0x03
bString "Rusty Manufacturer" ...
0x26 0x03 0x52 0x00 0x75 0x00 0x73 0x00 0x74 0x00 0x79 0x00 0x20 0x00 0x4d 0x00 0x61 0x00 0x6e 0x00 0x75 0x00 0x66 0x00 0x61 0x00 0x63 0x00 0x74 0x00 0x75 0x00 0x72 0x00 0x65 0x00 0x72 0x00
(You get the idea, there's no point me breaking down the rest of the string descriptors here, suffice it to say that the other strings are appropriate for the values they represent - namely product, serial, configuration, and interface.)

Putting it all together Given all the above, we have a device descriptor which is standalone, then a configuration descriptor which encompasses the interface and endpoint descriptors too. Finally we have a string descriptor table with six entries, the first is the language sets available, and the rest are our strings. In total we have:
    // Device descriptor
    const DEV_DESC: [u8; 18] =  
        0x12, 0x01, 0x00, 0x02, 0x00, 0x00, 0x00, 0x40,
        0xff, 0xff, 0xff, 0xff, 0x01, 0x00, 0x01, 0x02,
        0x03, 0x01
     ;
    // Configuration descriptor
    const CONF_DESC: [u8; 25] =  
        0x09, 0x02, 0x19, 0x00, 0x01, 0x01, 0x04, 0x80, 0xfa,
        0x09, 0x04, 0x01, 0x01, 0x01, 0x00, 0x00, 0x00, 0x05,
        0x07, 0x05, 0x82, 0x02, 0x40, 0x00, 0x00
     ;
    // String Descriptor zero
    const STR_DESC_0: [u8; 4] =  0x04, 0x03, 0x09, 0x08 ;
    // String Descriptor 1, "Rusty Manufacturer"
    const STR_DESC_1: [u8; 38] =  
        0x26, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x4d, 0x00,
        0x61, 0x00, 0x6e, 0x00, 0x75, 0x00, 0x66, 0x00,
        0x61, 0x00, 0x63, 0x00, 0x74, 0x00, 0x75, 0x00,
        0x72, 0x00, 0x65, 0x00, 0x72, 0x00
     ;
    // String Descriptor 2, "Rusty Product"
    const STR_DESC_2: [u8; 28] =  
        0x1c, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x50, 0x00,
        0x72, 0x00, 0x6f, 0x00, 0x64, 0x00, 0x75, 0x00,
        0x63, 0x00, 0x74, 0x00
     ;
    // String Descriptor 3, "123ABC"
    const STR_DESC_3: [u8; 14] =  
        0x0e, 0x03, 0x31, 0x00, 0x32, 0x00, 0x33, 0x00,
        0x41, 0x00, 0x42, 0x00, 0x43, 0x00
     ;
    // String Descriptor 4, "Rusty Configuration"
    const STR_DESC_4: [u8; 40] =  
        0x28, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x43, 0x00,
        0x6f, 0x00, 0x6e, 0x00, 0x66, 0x00, 0x69, 0x00,
        0x67, 0x00, 0x75, 0x00, 0x72, 0x00, 0x61, 0x00,
        0x74, 0x00, 0x69, 0x00, 0x6f, 0x00, 0x6e, 0x00
     ;
    // String Descriptor 5, "Rusty Interface"
    const STR_DESC_5: [u8; 32] =  
        0x20, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x49, 0x00,
        0x6e, 0x00, 0x74, 0x00, 0x65, 0x00, 0x72, 0x00,
        0x66, 0x00, 0x61, 0x00, 0x63, 0x00, 0x65, 0x00
     ;

With the above, we're a step closer to our first prototype which will hopefully be enumerable. Next time we'll look at beginning our prototype low level USB device stack mock-up.

21 August 2017

Carl Chenet: Remind people about your great content using social networks with Remindr

Each time I remind people about one of my best blog posts, I do have positive reviews and a peak of traffic on my blog. But as an IT guy, I hate (so much) manually (gosh!) posting reminders of my articles on both my Twitter account and my Mastodon account. So I wrote Remindr. Each time you launch it, it posts a content through both Mastodon and Twitter. You can attach an image for each message and using different languages is managed for your different content is managed. Under the hood, it s a self hosted (my instance just runs on my workstation) Python 3 application released under the GPLv3 license. Going further with Remindr How does exactly Remindr work? Remindr iterates through a list of messages in a file you write and extract one line for each execution of Remindr, adding a user-defined prefix and send them to both the Mastodon and Twitter social networks. Here is the format of the file:
o en Automatically Send Toots To The Mastodon Social Network https://carlchenet.com/automatically-send-toots-to-the-mastodon-social-network/ #Mastodon
x fr Sur Mastodon, cr er son compte de secours  ou tout perdre https://carlchenet.com/sur-mastodon-creer-son-compte-de-secours-ou-tout-perdre/ #Mastodon
x en Automatically boost cool toots on Mastodon with the Boost bot https://carlchenet.com/automatically-boost-cool-toots-on-mastodon-with-the-boost-bot/ #Mastodon
x en Cryptocurrencies On the New Social Network Mastodon #Mastodon #bitcoin #ethereum #monero
The first field only indicates if the line is the next one to be considered by Remindr, the o indicates the next line to be sent. The second field is the 2-letters code language your content is using, in my example en or fr. Next content on the line will compose the body of your messages to Mastodon and Twitter. So each time you launch Remindr, one of the lines of your file will be sent to Mastodon and Twitter. How easy to use is that? and finally You can help me developing tools for Mastodon and other social networks by donating anything through Liberaypay (also possible with cryptocurrencies). Any contribution will be appreciated. That s a big factor motivation
Donate You also may follow my account @carlchenet on Mastodon  Carl Chenet On Mastodon

20 August 2017

Vincent Bernat: IPv6 route lookup on Linux

TL;DR: With its implementation of IPv6 routing tables using radix trees, Linux offers subpar performance (450 ns for a full view 40,000 routes) compared to IPv4 (50 ns for a full view 500,000 routes) but fair memory usage (20 MiB for a full view).
In a previous article, we had a look at IPv4 route lookup on Linux. Let s see how different IPv6 is.

Lookup trie implementation Looking up a prefix in a routing table comes down to find the most specific entry matching the requested destination. A common structure for this task is the trie, a tree structure where each node has its parent as prefix. With IPv4, Linux uses a level-compressed trie (or LPC-trie), providing good performances with low memory usage. For IPv6, Linux uses a more classic radix tree (or Patricia trie). There are three reasons for not sharing:
  • The IPv6 implementation (introduced in Linux 2.1.8, 1996) predates the IPv4 implementation based on LPC-tries (in Linux 2.6.13, commit 19baf839ff4a).
  • The feature set is different. Notably, IPv6 supports source-specific routing1 (since Linux 2.1.120, 1998).
  • The IPv4 address space is denser than the IPv6 address space. Level-compression is therefore quite efficient with IPv4. This may not be the case with IPv6.
The trie in the below illustration encodes 6 prefixes: Radix tree For more in-depth explanation on the different ways to encode a routing table into a trie and a better understanding of radix trees, see the explanations for IPv4. The following figure shows the in-memory representation of the previous radix tree. Each node corresponds to a struct fib6_node. When a node has the RTN_RTINFO flag set, it embeds a pointer to a struct rt6_info containing information about the next-hop. Memory representation of a routing table The fib6_lookup_1() function walks the radix tree in two steps:
  1. walking down the tree to locate the potential candidate, and
  2. checking the candidate and, if needed, backtracking until a match.
Here is a slightly simplified version without source-specific routing:
static struct fib6_node *fib6_lookup_1(struct fib6_node *root,
                                       struct in6_addr  *addr)
 
    struct fib6_node *fn;
    __be32 dir;
    /* Step 1: locate potential candidate */
    fn = root;
    for (;;)  
        struct fib6_node *next;
        dir = addr_bit_set(addr, fn->fn_bit);
        next = dir ? fn->right : fn->left;
        if (next)  
            fn = next;
            continue;
         
        break;
     
    /* Step 2: check prefix and backtrack if needed */
    while (fn)  
        if (fn->fn_flags & RTN_RTINFO)  
            struct rt6key *key;
            key = fn->leaf->rt6i_dst;
            if (ipv6_prefix_equal(&key->addr, addr, key->plen))  
                if (fn->fn_flags & RTN_RTINFO)
                    return fn;
             
         
        if (fn->fn_flags & RTN_ROOT)
            break;
        fn = fn->parent;
     
    return NULL;
 

Caching While IPv4 lost its route cache in Linux 3.6 (commit 5e9965c15ba8), IPv6 still has a caching mechanism. However cache entries are directly put in the radix tree instead of a distinct structure. Since Linux 2.1.30 (1997) and until Linux 4.2 (commit 45e4fd26683c), almost any successful route lookup inserts a cache entry in the radix tree. For example, a router forwarding a ping between 2001:db8:1::1 and 2001:db8:3::1 would get those two cache entries:
$ ip -6 route show cache
2001:db8:1::1 dev r2-r1  metric 0
    cache
2001:db8:3::1 via 2001:db8:2::2 dev r2-r3  metric 0
    cache
These entries are cleaned up by the ip6_dst_gc() function controlled by the following parameters:
$ sysctl -a   grep -F net.ipv6.route
net.ipv6.route.gc_elasticity = 9
net.ipv6.route.gc_interval = 30
net.ipv6.route.gc_min_interval = 0
net.ipv6.route.gc_min_interval_ms = 500
net.ipv6.route.gc_thresh = 1024
net.ipv6.route.gc_timeout = 60
net.ipv6.route.max_size = 4096
net.ipv6.route.mtu_expires = 600
The garbage collector is triggered at most every 500 ms when there are more than 1024 entries or at least every 30 seconds. The garbage collection won t run for more than 60 seconds, except if there are more than 4096 routes. When running, it will first delete entries older than 30 seconds. If the number of cache entries is still greater than 4096, it will continue to delete more recent entries (but no more recent than 512 jiffies, which is the value of gc_elasticity) after a 500 ms pause. Starting from Linux 4.2 (commit 45e4fd26683c), only a PMTU exception would create a cache entry. A router doesn t have to handle those exceptions, so only hosts would get cache entries. And they should be pretty rare. Martin KaFai Lau explains:
Out of all IPv6 RTF_CACHE routes that are created, the percentage that has a different MTU is very small. In one of our end-user facing proxy server, only 1k out of 80k RTF_CACHE routes have a smaller MTU. For our DC traffic, there is no MTU exception.
Here is how a cache entry with a PMTU exception looks like:
$ ip -6 route show cache
2001:db8:1::50 via 2001:db8:1::13 dev out6  metric 0
    cache  expires 573sec mtu 1400 pref medium

Performance We consider three distinct scenarios:
Excerpt of an Internet full view
In this scenario, Linux acts as an edge router attached to the default-free zone. Currently, the size of such a routing table is a little bit above 40,000 routes.
/48 prefixes spread linearly with different densities
Linux acts as a core router inside a datacenter. Each customer or rack gets one or several /48 networks, which need to be routed around. With a density of 1, /48 subnets are contiguous.
/128 prefixes spread randomly in a fixed /108 subnet
Linux acts as a leaf router for a /64 subnet with hosts getting their IP using autoconfiguration. It is assumed all hosts share the same OUI and therefore, the first 40 bits are fixed. In this scenario, neighbor reachability information for the /64 subnet are converted into routes by some external process and redistributed among other routers sharing the same subnet2.

Route lookup performance With the help of a small kernel module, we can accurately benchmark3 the ip6_route_output_flags() function and correlate the results with the radix tree size: Maximum depth and lookup time Getting meaningful results is challenging due to the size of the address space. None of the scenarios have a fallback route and we only measure time for successful hits4. For the full view scenario, only the range from 2400::/16 to 2a06::/16 is scanned (it contains more than half of the routes). For the /128 scenario, the whole /108 subnet is scanned. For the /48 scenario, the range from the first /48 to the last one is scanned. For each range, 5000 addresses are picked semi-randomly. This operation is repeated until we get 5000 hits or until 1 million tests have been executed. The relation between the maximum depth and the lookup time is incomplete and I can t explain the difference of performance between the different densities of the /48 scenario. We can extract two important performance points:
  • With a full view, the lookup time is 450 ns. This is almost ten times the budget for forwarding at 10 Gbps which is about 50 ns.
  • With an almost empty routing table, the lookup time is 150 ns. This is still over the time budget for forwarding at 10 Gbps.
With IPv4, the lookup time for an almost empty table was 20 ns while the lookup time for a full view (500,000 routes) was a bit above 50 ns. How to explain such a difference? First, the maximum depth of the IPv4 LPC-trie with 500,000 routes was 6, while the maximum depth of the IPv6 radix tree for 40,000 routes is 40. Second, while both IPv4 s fib_lookup() and IPv6 s ip6_route_output_flags() functions have a fixed cost implied by the evaluation of routing rules, IPv4 has several optimizations when the rules are left unmodified5. Those optimizations are removed on the first modification. If we cancel those optimizations, the lookup time for IPv4 is impacted by about 30 ns. This still leaves a 100 ns difference with IPv6 to be explained. Let s compare how time is spent in each lookup function. Here is a CPU flamegraph for IPv4 s fib_lookup(): IPv4 route lookup flamegraph Only 50% of the time is spent in the actual route lookup. The remaining time is spent evaluating the routing rules (about 30 ns). This ratio is dependent on the number of routes we inserted (only 1000 in this example). It should be noted the fib_table_lookup() function is executed twice: once with the local routing table and once with the main routing table. The equivalent flamegraph for IPv6 s ip6_route_output_flags() is depicted below: IPv6 route lookup flamegraph Here is an approximate breakdown on the time spent:
  • 50% is spent in the route lookup in the main table,
  • 15% is spent in handling locking (IPv4 is using the more efficient RCU mechanism),
  • 5% is spent in the route lookup of the local table,
  • most of the remaining is spent in routing rule evaluation (about 100 ns)6.
Why does the evaluation of routing rules is less efficient with IPv6? Again, I don t have a definitive answer.

History The following graph shows the performance progression of route lookups through Linux history: IPv6 route lookup performance progression All kernels are compiled with GCC 4.9 (from Debian Jessie). This version is able to compile older kernels as well as current ones. The kernel configuration is the default one with CONFIG_SMP, CONFIG_IPV6, CONFIG_IPV6_MULTIPLE_TABLES and CONFIG_IPV6_SUBTREES options enabled. Some other unrelated options are enabled to be able to boot them in a virtual machine and run the benchmark. There are three notable performance changes:
  • In Linux 3.1, Eric Dumazet delays a bit the copy of route metrics to fix the undesirable sharing of route-specific metrics by all cache entries (commit 21efcfa0ff27). Each cache entry now gets its own metrics, which explains the performance hit for the non-/128 scenarios.
  • In Linux 3.9, Yoshifuji Hideaki removes the reference to the neighbor entry in struct rt6_info (commit 887c95cc1da5). This should have lead to a performance increase. The small regression may be due to cache-related issues.
  • In Linux 4.2, Martin KaFai Lau prevents the creation of cache entries for most route lookups. The most sensible performance improvement comes with commit 4b32b5ad31a6. The second one is from commit 45e4fd26683c, which effectively removes creation of cache entries, except for PMTU exceptions.

Insertion performance Another interesting performance-related metric is the insertion time. Linux is able to insert a full view in less than two seconds. For some reason, the insertion time is not linear above 50,000 routes and climbs very fast to 60 seconds for 500,000 routes. Insertion time Despite its more complex insertion logic, the IPv4 subsystem is able to insert 2 million routes in less than 10 seconds.

Memory usage Radix tree nodes (struct fib6_node) and routing information (struct rt6_info) are allocated with the slab allocator7. It is therefore possible to extract the information from /proc/slabinfo when the kernel is booted with the slab_nomerge flag:
# sed -ne 2p -e '/^ip6_dst/p' -e '/^fib6_nodes/p' /proc/slabinfo   cut -f1 -d:
   name            <active_objs> <num_objs> <objsize> <objperslab> <pagesperslab>
fib6_nodes         76101  76104     64   63    1
ip6_dst_cache      40090  40090    384   10    1
In the above example, the used memory is 76104 64+40090 384 bytes (about 20 MiB). The number of struct rt6_info matches the number of routes while the number of nodes is roughly twice the number of routes: Nodes The memory usage is therefore quite predictable and reasonable, as even a small single-board computer can support several full views (20 MiB for each): Memory usage The LPC-trie used for IPv4 is more efficient: when 512 MiB of memory is needed for IPv6 to store 1 million routes, only 128 MiB are needed for IPv4. The difference is mainly due to the size of struct rt6_info (336 bytes) compared to the size of IPv4 s struct fib_alias (48 bytes): IPv4 puts most information about next-hops in struct fib_info structures that are shared with many entries.

Conclusion The takeaways from this article are:
  • upgrade to Linux 4.2 or more recent to avoid excessive caching,
  • route lookups are noticeably slower compared to IPv4 (by an order of magnitude),
  • CONFIG_IPV6_MULTIPLE_TABLES option incurs a fixed penalty of 100 ns by lookup,
  • memory usage is fair (20 MiB for 40,000 routes).
Compared to IPv4, IPv6 in Linux doesn t foster the same interest, notably in term of optimizations. Hopefully, things are changing as its adoption and use at scale are increasing.

  1. For a given destination prefix, it s possible to attach source-specific prefixes:
    ip -6 route add 2001:db8:1::/64 \
      from 2001:db8:3::/64 \
      via fe80::1 \
      dev eth0
    
    Lookup is first done on the destination address, then on the source address.
  2. This is quite different of the classic scenario where Linux acts as a gateway for a /64 subnet. In this case, the neighbor subsystem stores the reachability information for each host and the routing table only contains a single /64 prefix.
  3. The measurements are done in a virtual machine with one vCPU and no neighbors. The host is an Intel Core i5-4670K running at 3.7 GHz during the experiment (CPU governor set to performance). The benchmark is single-threaded. Many lookups are performed and the result reported is the median value. Timings of individual runs are computed from the TSC.
  4. Most of the packets in the network are expected to be routed to a destination. However, this also means the backtracking code path is not used in the /128 and /48 scenarios. Having a fallback route gives far different results and make it difficult to ensure we explore the address space correctly.
  5. The exact same optimizations could be applied for IPv6. Nobody did it yet.
  6. Compiling out table support effectively removes those last 100 ns.
  7. There is also per-CPU pointers allocated directly (4 bytes per entry per CPU on a 64-bit architecture). We ignore this detail.

19 August 2017

Sean Whitton: Debian Policy call for participation -- August 2017

At the Debian Policy BoF at DebConf17, Solveig suggested that we could post summaries of recent activity in policy bugs to Planet Debian, as a kind of call for participation. Russ Allbery had written a script to generate such a summary some time ago, but it couldn t handle the usertags the policy team uses to progress bugs through the policy changes process. Today I enhanced the script to handle usertags and I m pleased to be able to post a summary of our bugs. Consensus has been reached and help is needed to write a patch #172436 BROWSER and sensible-browser standardization #273093 document interactions of multiple clashing package diversions #299007 Transitioning perms of /usr/local #314808 Web applications should use /usr/share/package, not /usr/share/doc/ #425523 Describe error unwind when unpacking a package fails #452393 Clarify difference between required and important priorities #476810 Please clarify 12.5, Copyright information #484673 file permissions for files potentially including credential informa #491318 init scripts should support start/stop/restart/force-reload - why #556015 Clarify requirements for linked doc directories #568313 Suggestion: forbid the use of dpkg-statoverride when uid and gid ar #578597 Recommend usage of dpkg-buildflags to initialize CFLAGS and al. #582109 document triggers where appropriate #587279 Clarify restrictions on main to non-free dependencies #587991 perl-policy: /etc/perl missing from Module Path #592610 Clarify when Conflicts + Replaces et al are appropriate #613046 please update example in 4.9.1 (debian/rules and DEB_BUILD_OPTIONS) #614807 Please document autobuilder-imposed build-dependency alternative re #616462 clarify wording of parenthetical in section 2.2.1 #628515 recommending verbose build logs #661928 recipe for determining shlib package name #664257 document Architecture name definitions #682347 mark editor virtual package name as obsolete #683222 say explicitly that debian/changelog is required in source packages #685506 copyright-format: new Files-Excluded field #685746 debian-policy Consider clarifying the use of recommends #688251 Built-Using description too aggressive #757760 please document build profiles #759316 Document the use of /etc/default for cron jobs #761219 document versioned Provides #767839 Linking documentation of arch:any package to arch:all #770440 policy should mention systemd timers #773557 Avoid unsafe RPATH/RUNPATH #780725 PATH used for building is not specified #793499 The Installed-Size algorithm is out-of-date #810381 Update wording of 5.6.26 VCS-* fields to recommend encryption #823256 Update maintscript arguments with dpkg >= 1.18.5 #833401 virtual packages: dbus-session-bus, dbus-default-session-bus #835451 Building as root should be discouraged #838777 Policy 11.8.4 for x-window-manager needs update for freedesktop menus #845715 Please document that packages are not allowed to write outside thei #853779 Clarify requirements about update-rc.d and invoke-rc.d usage in mai Wording proposed, awaiting review from anyone and/or seconds by DDs #542288 Versions for native packages, NMU s, and binary only uploads #582109 document triggers where appropriate #630174 forbid installation into /lib64 #645696 [copyright-format] clearer definitions and more consistent License: #648271 11.8.3 Packages providing a terminal emulator says xterm passes - #649530 [copyright-format] clearer definitions and more consistent License: #662998 stripping static libraries #732445 debian-policy should encourage verification of upstream cryptograph #737796 copyright-format: support Files: paragraph with both abbreviated na #756835 Extension of the syntax of the Packages-List field. #786470 [copyright-format] Add an optional License-Grant field #835451 Building as root should be discouraged #844431 Packages should be reproducible #845255 Include best practices for packaging database applications #850729 Documenting special version number suffixes Merged for the next release #587279 Clarify restrictions on main to non-free dependencies #616462 clarify wording of parenthetical in section 2.2.1 #732445 debian-policy should encourage verification of upstream cryptograph #844431 Packages should be reproducible

Arturo Borrero Gonz lez: Running Suricata 4.0 with Debian Stretch

debian-suricata logo Do you know what s happening in the wires of your network? There is a major FLOSS player in the field of real time intrusion detection (IDS), inline intrusion prevention (IPS) and network security monitoring (NSM). I m talking about Suricata, a mature, fast and robust network threat detection engine. Suricata is a community driven project, supported by the Open InfoSec Foundation (OISF). For those who doesn t know how Suricata works, it usually runs by loading a set of pre-defined rules for matching different network protocols and flow behaviours. In this regards, Suricata has been always ruleset-compatible with the other famous IDS: snort. The last major release of Suricata is 4.0.0, and I m uploading the package for Debian stretch-backports as I write this line. This means the updated package should be available for general usage after the usual buildds processing ends inside the Debian archive. You might be wondering, How to start using Suricata 4.0 with Debian Stretch? First, I would recommend reading the docs. Please checkout: My recommendation is to run Suricata from stretch-backports or from testing, and just installing the package should be enough to get the environment up and running:
% sudo aptitude install suricata
You can check that the installation was good:
% sudo systemctl status suricata
  suricata.service - Suricata IDS/IDP daemon
   Loaded: loaded (/lib/systemd/system/suricata.service; enabled; vendor preset: enabled)
   Active: active (running) since Sat 2017-08-19 12:50:49 CEST; 44min ago
     Docs: man:suricata(8)
           man:suricatasc(8)
           https://redmine.openinfosecfoundation.org/projects/suricata/wiki
 Main PID: 1101 (Suricata-Main)
    Tasks: 8 (limit: 4915)
   CGroup: /system.slice/suricata.service
            1101 /usr/bin/suricata -D --af-packet -c /etc/suricata/suricata.yaml --pidfile /var/run/suricata.pid
ago 19 12:50:44 nostromo systemd[1]: Starting Suricata IDS/IDP daemon...
ago 19 12:50:47 nostromo suricata[1032]: 19/8/2017 -- 12:50:47 - <Notice> - This is Suricata version 4.0.0 RELEASE
ago 19 12:50:49 nostromo systemd[1]: Started Suricata IDS/IDP daemon.
You can interact with Suricata using the suricatasc tool:
% sudo suricatasc -c uptime
 "message": 3892, "return": "OK" 
And start inspecting the generated logs at /var/log/suricata/ The default configuration, in file /etc/suricata/suricata.yaml, comes with some preconfigured values. For a proper integration into your enviroment, you should tune the configuration file, define your networks, network interfaces, running modes, and so on (refer to the upstream documentation for this). In my case, I tested suricata by inspecting the traffic of my laptop. After installation, I only had to switch the network interface:
[...]
# Linux high speed capture support
af-packet:
  - interface: wlan0
[...]
After a restart, I started seeing some alerts:
% sudo systemctl restart suricata
% sudo tail -f /var/log/suricata/fast.log
08/19/2017-14:03:04.025898  [**] [1:2012648:3] ET POLICY Dropbox Client Broadcasting [**] \
	[Classification: Potential Corporate Privacy Violation] [Priority: 1]  UDP  192.168.1.36:17500 -> 255.255.255.255:17500
One of the main things when running Suricata is to keep your ruleset up-to-dated. In Debian, we have the suricata-oinkmaster package which comes with some handy options to automate your ruleset updates using the Oinkmaster software. Please note that this is a Debian-specific glue to integrate and automate Suricata with Oinkmaster. To get this funcionality, simply install the package:
% sudo aptitude install suricata-oinkmaster
A daily cron-job will be enabled. Check suricata-oinkmaster-updater(8) for more info. By the way, Did you know that Suricata can easily handle big loads of traffic? (i.e, 10Gbps). And I heard some scaling works are in mind to reach 100Gpbs. I have been in charge of the Suricata package in Debian for a while, several years already, with the help of some other DD hackers: Pierre Chifflier (pollux) and Sascha Steinbiss (satta), among others. Due to this work, I believe the package is really well integrated into Debian, ready to use and with some powerful features. And, of course, we are open to suggestions and bug reports. So, this is it, another great stuff you can do with Debian :-)

18 August 2017

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, July 2017

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In July, about 181 work hours have been dispatched among 11 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours increased slightly with two new sponsors: Leibniz Rechenzentrum (silver sponsor) and Catalyst IT Ltd (bronze sponsor). The security tracker currently lists 74 packages with a known CVE and the dla-needed.txt file 64. The number of packages with open issues increased of almost 50% compared to last month. Hopefully this backlog will get cleared up when the unused hours will actually be done. In any case, this evolution is worth watching. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Albiona Hoti: CoderGals Prizren Hackathon

CoderGals Hackathon started tonight!

Mike Gabriel: @DebConf17: Ad-hoc BoF: Bits from the Debian+Ubuntu MATE Packaging Team

On Tuesday, late afternoon, at DebConf17, I offered an ad-hoc BoF about the current status of the MATE Desktop packaging efforts in Debian and Ubuntu. I need to get this written down, before DebConf17 feels too far away... Unfortunately, I scheduled that BoF with Joey Hess's talk about his post-Debian life, which attracted many people. So, only a small group of people came together to share and discuss about the current status of MATE in Debian and Ubuntu. Ongoing efforts around MATE in Debian and Ubuntu A quick summary of ongoing efforts was provided and also a collection of URLs for reporting bugs, looking up packaging status, etc. was listed: Cross-Distro Packaging Workflow The workflow of Debian and Ubuntu packaging in the MATE Packaging Team was described in detail (basically, all packages go through Debian, only exception being freeze states of this or that distro) and the benefit of the close cooperation between the two projects underlined. We reduce the packaging effort tremendously by working very closely together. In the past, we (Martin Wimpress and myself) also invited the people from Linux Mint to join our cross-distro packaging efforts, but so far to no avail. Also the packaging for the Parrot Security OS has recently been integrated in our packaging Git repository. Requested / Upcoming Improvements From people attending the BoF, I got these main inputs, which I hope to accomplish with the help of all, for Debian buster: Another project that I will also work on for Debian buster is proper Ayatana Indicator support for Debian's MATE Desktop. Credits Thanks to all the people attending the BoF for your sharings and input. Feel invited to contribute to our team's effort in improving the user experience of the MATE Destkop Environment in Debian (and Ubuntu, and ...). Also a big thanks to the people already on the team for bringing MATE in Debian to where it is now. Good work, folks!

17 August 2017

Sean Whitton: DebCamp/DebConf17: reports on sprints and BoFs

In addition to my personal reflections on DebCamp/DebConf17, here is a brief summary of the activities that I had a hand in co-ordinating. I won t discuss here many other small items of work and valuable conversations that I had during the two weeks; hopefully the fruits of these will show themselves in my uploads to the archive over the next year. Debian Policy sprint & BoF Debian Emacs Team meeting/sprint Unfortunately we didn t make any significant progress towards converting all addons to use dh_elpa, as the work is not that much fun. Might be worth a more focused sprint next year. Report on team website Git for Debian packaging BoF & follow-up conversations The BoF was far more about dgit than I had wanted; however, I think that this was mostly because people had questions about dgit, rather than any unintended lecturing by me. I believe that several people came away from DebConf thinking that starting to use dgit would improve Debian for themselves and for users of their packages.

Sean Whitton: I went all the way to Montr al for DebConf17, and all I got was a new MUA

This year s group photo (by Aigars Mahinovs). I really like the tagline
On Sunday night I got back from Montr al, where I attended both DebCamp17 and DebConf17. It was a wonderful two weeks. All I really did was work on Debian for roughly eight hours per day, interspersed with getting to know both people I ve been working with since I first began contributing to Debian in late 2015, and people I didn t yet know. But this was all I really needed to be doing. There was no need to engage in distracting myself. I enjoyed the first week more. There were sufficiently few people present that you could know at least all of their faces, and interesting-sounding talks didn t interrupt making progress on one s own work or unblocking other people s work. In the second week it was great to meet people who were only present for the second week, but it felt more like regular Debian, in that I was often waiting on other people or they were waiting on me. While I spent one morning actually writing fresh code, and I did a fair amount of pure packaging work, the majority of my time was poured into (i) Debian Policy; (ii) discussions within the Emacs team; and (iii) discussions about dgit. This was as I expected. During DebConf, it s not that useful to seclude oneself and sufficiently reacquaint oneself with a codebase that one can start producing patches, because that can be done anywhere in the world, without everyone else around. It s far more useful to bring different people together to get projects unblocked. I did some of that for my own work, and also tried to help other people s, including those who weren t able to attend the conference. In my ordinary life, taking a step back from the methods by which I protect my PGP keys and other personal data, I can appear to myself as a paranoid extremist, or some kind of data hoarder. It was comforting to find at DebConf plenty of people who go way further than me: multiple user accounts on their laptop, with separate X servers, for tasks of different security levels; PGP keys on smartcards; refusal to sign my PGP key based on government-issued ID alone; use of Qubes OS. One thing that did surprise me was to find myself in a minority for using the GNOME desktop; I had previously assumed that most people deep in Debian development didn t bother with tiling window managers. Turns out they are enthusiastic to talk about the trade-offs between window managers while riding the subway train back to our accommodation at midnight who knew such people existed? I was pleased to find them. One evening, I received a tag-teamed live tutorial in using i3 s core keybindings, and the next morning GNOME seemed deeply inelegant. The insinuation began, but I was immediately embroiled in inner struggle over the fact that i3 is a very popular tiling window manager, so it wouldn t be very cool if I were to start using it. This difficulty was compounded when I learned that the Haskell team lead still uses xmonad. The struggle continues. I hope that I ve been influenced by the highly non-judgemental and tolerant attitudes of the attendees of the conference. While most people at the conference were pretty ordinary aside from wanting to talk about the details of Debian packaging and processes! there were several people who rather visibly rejected social norms about how to present themselves. Around these people there was nothing of the usual tension. Further, in contrast with my environment as a graduate student, everyone was extremely relaxed about how everyone was spending their time. People drinking beer in the evenings were sitting at tables where other people were continuing to silently work on Debian. It is nice to have my experience in Montr al as a reference to check my own judgemental tendencies. I came away with a lot more than a new MUA: a certainty that I want to try to get to next year s conference; friends; a real life community behind what was hitherto mostly a hobby; a long list of tasks and the belief that I can accomplish them; a list of PGP fingerprints to sign; a new perspective on the arguments that occur on Debian mailing lists; an awareness of the risk of unconsciously manipulating other community members into getting work done. With regard to the MUA, I should say that I did not waste a lot of DebConf time messing with its configuration. I had actually worked out a notmuch configuration some months ago, but couldn t use it because I couldn t figure out how to incorporate my old mail archives into its index. Fortunately notmuch s maintainer is also on the Emacs team he was able to confirm that the crazy solution I d come up with was not likely to break notmuch s operating assumptions, and so I was able to spend about half an hour copying and pasting the configuration and scripts I d previously developed into my homedir, and then start using notmuch for the remainder of the conference. The main reason for wanting to use notmuch was to handle Debian mailing list volume more effectively than I m able to with mutt, so I was very happy to have the opportunity to pester David with newbie questions. Many, many thanks to all the volunteers whose efforts made DebCamp17 and DebConf17 possible.

Julian Andres Klode: Why TUF does not shine (for APT repositories)

In DebConf17 there was a talk about The Update Framework, short TUF. TUF claims to be a plug-in solution to software updates, but while it has the same practical level of security as apt, it also has the same shortcomings, including no way to effectively revoke keys. TUF divides signing responsibilities into roles: A root role, a targets rule (signing stuff to download), a snapshots rule (signing meta data), and a time stamp rule (signing a time stamp file). There also is a mirror role for signing a list of mirrors, but we can ignore that for now. It strongly recommends that all keys except for timestamp and mirrors are kept offline, which is not applicable for APT repositories Ubuntu updates the repository every 30 minutes, imagine doing that with offline keys. An insane proposal. In APT repositories, we effectively only have a snapshots rule the only thing we sign are Release files, and trust is then chained down by hashes (Release files hashes Packages index files, and they have hashes of individual packages). The keys used to sign repositories are online keys, after all, all the metadata files change every 30 minutes (Ubuntu) or 6 hours (Debian) it s impossible to sign them by hand. The timestamp role is replaced by a field in the Release file specifying until when the Release file is considered valid. Let s check the attacks TUF protects again: As we can see, APT addresses all attacks TUF addresses. But both do not handle key revocation. So, if a key & mirror gets compromised (or just key and the mirror is MITMed), we cannot inform the user that the key has been compromised and block updates from the compromised repository. I just wrote up a proposal to allow APT to query for revoked keys from a different host with a key revocation list (KRL) file that is signed by different keys than the repository. This would solve the problem of key revocation easily even if the repository host is MITMed or compromised, we can still revoke the keys signing the repository from a different location.
Filed under: Debian, Ubuntu

Next.

Previous.