Search Results: "nate"

29 December 2013

Russ Allbery: Review: The Incrementalists

Review: The Incrementalists, by Steven Brust & Skyler White
Publisher: Tor
Copyright: September 2013
ISBN: 0-7653-3422-4
Format: Hardcover
Pages: 304
The Incrementalists are a secret society that has been in continuous existence for forty thousand years. The members are immortal... sort of (more on that in a moment). They are extremely good at determining what signals, triggers, and actions have the most impact on people, and adept at using those triggers to influence people's behavior. And they're making the world better. Not in any huge, noticeable way, just a little bit, here and there. Incrementally. Brust and White completely had me with this concept. There are several SF novels about immortals, but (apart from the vampire subgenre) they mostly stay underground and find ways to survive without trying to change the surrounding human society. I love the idea of small, incremental changes, and I was looking forward to reading a book about how that would work. How do they choose what to do? How do they find the right place to push? What long-term goals would such an organization pursue, and what governance structure would they use? I'm still wondering about most of those things, sadly, since that isn't what this novel is about at all. I should be fair: a few of those questions hover in the background. There are some political arguments (that parallel arguments on Brust's blog), and a tiny bit about governance. But mostly this is a sort of romance, a fight over identity, and an extensive exploration of the mental "garden" that the Incrementalists use and build to hold their memories and share information with each other. The story revolves around two Incrementalists: Phil, who is one of the leaders and has one of the longest continuous identities of any of the group, and Renee, a new recruit by Phil who picks up the memories and capabilities (sort of) of the recently-deceased Incrementalist Celeste. Phil is the long-term insider, although a fairly laid-back one. Renee is the outsider, the one to which the story is happening at the beginning, who is taught how the Incrementalists' system works. The Incrementalists is told in alternating first-person viewpoint sections by Phil and Renee (making me wonder if the characters were each written by one of the authors). Once I got past my disappointment over this book not being quite what I wanted, the identity puzzles that Brust and White play with here caught my attention. The underlying "magic" of the Incrementalists is based on the "memory palace" concept of storing memories via visualizations, but takes it into something akin to personal alternate worlds. Their immortality isn't through physical immortality, but rather the ability to store their memories and personality in their garden, which is their term for the memory palace, and then have it imposed on someone else: a combination of reincarnation, mental takeover, and mental merging. This makes for complex interpersonal relationships and complex interactions between memory, belief, and identity, not to mention some major ethical issues, which come to a head in Phil and Renee's relationship and Celeste's lingering meddling. I think Brust and White are digging into some interesting questions of character here. There's a lot of emphasis in The Incrementalists on the ease with which people can be manipulated, and the Incrementalists themselves are far from immune. Choice and personal definition are both questionable concepts given how much influence other people have, how many vulnerabilities everyone carries with them, and how much one's opinions are governed by one's life history. That makes identity complex, and raises the question of whether one can truly define oneself. But, while all these ideas are raised, I think The Incrementalists dances around them more than engages them directly. It's similar to the background hook: yes, these people are slowly improving the world, and we see a little bit of that (and a little bit of them manipulating people for their own convenience), but the story doesn't fully engage with the idea. There's a romance, a few arguments, some tension, some world-building, but I don't feel like this book ever fully committed to any of them. One of the occasional failure modes of Brust for me is insufficient explanation and insufficient clarity, and I hit that here. My final impression of The Incrementalists is interesting, enjoyable, but vaguely disappointing. It's still a good story with some interesting characters and nice use of the memory palace concept, and I liked Renee throughout (although I think the development of the love story is disturbingly easy and a little weird). But I can't strongly recommend it, and I'm not sure if it's worth seeking out. Rating: 7 out of 10

28 December 2013

Keith Packard: Present-redirect-lifetimes

Object Lifetimes under Present Redirection Present extension redirection passes responsibility for showing application contents from the X server to the compositing manager. This eliminates an extra copy to the composite extension window buffer and also allows the application contents to be shown in the right frame. (Currently, the copy from application buffer to window buffer is synchronized to the application-specified frame, and then a Damage event is delivered to the compositing manager which constructs the screen image using the window buffer and presents that to the screen at least one frame later, which generally adds another frame of delay for the application.) The redirection operation itself is simple just wrap the PresentPixmap request up into an event and send it to the compositing manager. However, the pixmap to be presented is allocated by the application, and hence may disappear at any time. We need to carefully control the lifetime of the pixmap ID and the specific frame contents of the pixmap so that the compositing manager can reliably construct complete frames. We ll separately discuss the lifetime of the specific frame contents from that of the pixmap itself. By the frame contents , I mean the image, as a set of pixel values in the pixmap, to be presented for a specific frame. Present Pixmap contents lifetime After the application is finished constructing a particular frame in a pixmap, it passes the pixmap to the X server with PresentPixmap. With non-redirected Present, the X server is responsible for generating a PresentIdleNotify event once the server is finished using the contents. There are three different cases that the server handles, matching the three different PresentCompleteModes:
  1. Copy. The pixmap contents are not needed after the copy operation has been performed. Hence, the PresentIdleNotify event is generated when the target vblank time has been reached, right after the X server calls CopyArea
  2. Flip. The pixmap is being used for scanout, and so the X server won t be done using it until some other scanout buffer is selected. This can happen as a result of window reconfiguration which makes the displayed window no longer full-screen, but the usual case is when the application presents a subsequent frame for display, and the new frame replaces the old. Thus, the PresentIdleNotify event generally occurs when the target vblank time for the subsequent frame has been reached, right after the subsequent frame s pixmap has been selected for scanout.
  3. Skip. The pixmap contents will never be used, and the X server figures this out when a subsequent frame is delivered with a matching target vblank time. This happens when the subsequent Present operation is queued by the X server.
In the Redirect case, the X server cannot tell when the compositing manager is finished with the pixmap. The same three cases as above apply here, but the results are slightly different:
  1. Composite. The pixmap is being used as a part of the screen image and must be composited with other window pixmaps. In this case, the compositing manager will need to hold onto the pixmap until a subsequent pixmap is provided by the application. Thus, the pixmap will remain needed by the compositing manager until it receives a subsequent PresentRedirectNotify for the same window.
  2. Flip. The compositing manager is free to take the application pixmap and use it directly in a subsequent PresentPixmap operation and let the X server flip to it; this provides a simple way of avoiding an extra copy while not needing to fuss around with unredirecting windows. In this case, the X server will need the pixmap contents until a new scanout pixmap is provided, and the compositing manager will also need the pixmap in case the contents are needed to help construct a subsequent frame.
  3. Skip. In this case, the compositing manager notices that the window s pixmap has been replaced before it was ever used.
In case 2, the X server and the compositing manager will need to agree on when the PresentIdleNotify event should be delivered. In the other two cases, the compositing manager itself will be in charge of that. To let the compositing manager control when the event is delivered, the X server will count the number of PresentPixmap redirection events sent, and the compositing manager will deliver matching PresentIdle requests. PresentIdle
 
    PresentIdle
    pixmap: PIXMAP
 
Errors: Pixmap, Match
Informs the server that the Pixmap passed in a PresentRedirectNotify event is no longer needed by the client. Each PresentRedirectNotify event must be matched by a PresentIdle request for the originating client to receive a PresentIdleNotify event. PresentRedirect pixmap ID lifetimes A compositing manager will want to know the lifetime of the pixmaps delivered in PresentRedirectNotify events to clean up whatever local data it has associated with it. For instance, GL compositing managers will construct textures for each pixmap that need to be destroyed when the pixmap disappears. Some kind of PixmapDestroyNotify event is necessary for this; the alternative is for the compositing manager to constantly query the X server to see if the pixmap IDs it is using are still valid, and even that isn t reliable as the application may re-use pixmap IDs for a new pixmap. It seems like this PixmapDestroyNotify event belongs in the XFixes extension it s a general mechanism that doesn t directly relate to Present. XFixes doesn t currently have any Generic Events associated, but adding that should be fairly straightforward. And then, have the Present extension automatically select for PixmapDestroyNotify events when it delivers the pixmap in a PresentRedirectNotify event so that the client is ensured of receiving the associated PixmapDestroyNotify event. One remaining question I have is whether this is sufficient, or if the compositing manager needs a stable pixmap ID which lives beyond the life of the application pixmap ID. If so, the solution would be to have the X server allocate an internal ID for the pixmap and pass that to the client somehow; presumably in addition to the original pixmap ID. XFixesPixmapSelectInput
XFIXESEVENTID   XID  
    Defines a unique event delivery target for Present
    events. Multiple event IDs can be allocated to provide
    multiple distinct event delivery contexts.
PIXMAPEVENTS   XFixesPixmapDestroyNotify  
 
    XFixesPixmapSelectInput
    eventid: XFIXESEVENTID
    pixmap: PIXMAP
    events: SETofPIXMAPEVENTS
 
Errors: Pixmap, Value
Changes the set of events to be delivered for the target pixmap. A Value error is sent if events contains invalid event selections. XFixesPixmapDestroyNotify
 
    XFixesPixmapDestroyNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        XFixes extension request number
    sequence-number: CARD16
    length: CARD32          0
    evtype: CARD16          XFixes_PixmapDestroyNotify
    eventID: XFIXESEVENTID
    pixmap: pixmap
 
This event is delivered to all clients selecting for it on pixmap when the pixmap ID is destroyed by a client. Note that the pixmap may still be referenced by other objects within the X server, as a window background, GC tile or stipple or Picture drawable (among others), but this event serves to notify the selecting client that the ID is no longer associated with the underlying pixmap.

25 December 2013

Michael Stapelberg: Hosting for Debian Code Search provided by Rackspace

For a number of weeks now, I have been forwarding traffic being sent to codesearch.debian.net to an instance of Debian Code Search running at Rackspace s public cloud offering. I feel like it s overdue to announce how they have been supporting the project and what that means. Context First of all, let s provide some context. Debian Code Search was launched in November 2012, hosted entirely on my private server. Since DebConf 13, I am in contact with DSA in order to get Code Search running on a DSA-provided machine and make it an official Debian service. Code Search runs best on flash storage, and only with adequate resources can we enable some use cases (e.g. package-level results) and make sure the existing use cases work at all (we currently have timeouts for some queries). Unfortunately, flash storage is scarce in Debian, hence we couldn t get any for Code Search. At some point, I got the suggestion to ask Rackspace for help, since they are quite friendly to the Open Source community. They agreed to help us out with a generous amount of resources in their public cloud offering! This means I can run Code Search at Rackspace the way it is meant to be run: with the index sharded onto 6 different machines and the source code being searched on fast flash storage. Concerns Now, when using third-party infrastructure, there are always two big concerns: proprietary infrastructure and vendor lock-in. As for the proprietary aspect, Rackspace s public cloud offering is based on OpenStack, which is FOSS. Granted, they have a couple of extensions that are not (yet?) released in OpenStack, but those are minor details and any automation that we use can trivially be ported to any other OpenStack offering. Who knows, maybe in the future we use OpenStack in Debian, too? Given the OpenStack situation, I am not concerned about vendor lock-in. However, to specifically address this concern and err on the side of caution, attention will be paid to keep Code Search able to run on non-cloud infrastructure, such that we can run our own instance on DSA-provided hardware. My current intention is that this instance will be the fall-back that we can use should there ever be problems with Rackspace. So far, however, I am very happy with Rackspace s stability. Future There are a number of improvements waiting: for users in the United States, traffic first goes to my server in Europe and then back to Rackspace in the US. Eventually, we should get rid of this indirection. Perhaps we can also spin up another instance in Europe eventually. Furthermore, Rackspace recently announced new available hardware, which we are not yet making use of. I expect a big speed-up, but will have to do some careful benchmarking. Also, I have some interesting performance data, which will be shared in subsequent blog posts. Stay tuned :). Conclusion I d like to thank Rackspace very much for their generous support of the Debian project and Code Search in particular. I hope you look forward to the upcoming posts with more details. Also, to be perfectly clear about it: I also thank DSA for their help, and hope they will continue working with me to have our independent (yet slower) instance of Code Search running on Debian hardware.

24 December 2013

Andrea Veri: Manage passwords with pass

Fighting with passwords have always been one of my favorite battles in the past and unfortunately the former always won. I never liked using the root user that much for administering a machine and made a massive use of sudo, I won t list all the benefits of using sudo, but the following wiki page has a pretty nice overview of them. Said that, when using sudo it s definitely ideal to combine a strong password that is also easy to remember and type again when prompted. Sadly strong passwords that are also easy to remember can be considered an oxymoron. How hard would it be to recall a 30+ chars long password? Honestly that would be close to impossible for an human being but what if a little software available on the major GNU/Linux distributions could handle that for us? That s where pass comes handy, but what is pass? from the pass manpage itself:
pass is a very simple password store that keeps passwords inside gpg2(1) encrypted files inside a simple directory tree residing at ~/.password-store. The pass utility provides a series of commands for manipulating the password store, allowing the user to add, remove, edit, synchronize, generate, and manipulate passwords.
I m sure that a lot of you guys have been looking for a tool like this one for ages: pass allows you to generate very strong passwords with pwgen, GPG encrypt them with your GPG Key, store them safely on your disk and make them available whenever you need them with a single command. But let s move to the practice, give the following steps a try and enjoy how powerful your pass setup will be. First setup 1. Install the software:
yum/apt-get install pass

2. Generate a GPG Key if you don t have one already, a detailed guide can be found here. 3. Initialize your passwords storage. (GPGKEYID can be retrieved by running gpg list-keys and then looking for a line similar to this one: pub 4096R/B3A6223D 2012-06-25)
pass init GPGKEYID

4. Generate your first password and call it sudo_password given you are going to make use of it as your brand new sudo password. (we want it at least 30+ chars long)
pass generate sudo_password 30

5. (Optional) Create as much passwords as you need and make sure to save them with unique names, that way you will be able to identify what a password is used for easily.
pass generate gmail_password 30

Additional maintenance commands on your password database 1. Look at the existing passwords on your database.
pass ls

Result:
Password Store
  gmail_password
  sudo_password
  root_password

2. Manually edit a password.
pass edit password_name

3. Remove a password from your database.
pass rm password_name

4. Copy a password on your clipboard and paste it.
pass -c password_name

Are you wondering if pass supports a VCS? Yeah, it does, it currently allows you to manage your passwords database with Git, so that each applied change to the database will be tracked through a VCS so that you won t forget when and how you updated a specific password.

Dirk Eddelbuettel: RcppZiggurat 0.1.0 (and 0.1.1): Faster N(0,1) RNGs

Over the last few weeks I have been working on getting the Ziggurat normal random number generator updated and available in R. The Ziggurat generator provides a pretty unique combination of speed and good statistical properties for (standard) normal random numbers (as opposed to uniform draws as is commonn for most RNGs). Generation of N(0,1) draws may not by itself be the dominant slowdown in a simulation, yet when large number of draws are required it may be helpful to have a generator that is faster than the defaults in R (which have excellent properties, but not the fastest speed). A first release 0.0.1 went to CRAN a couple of weeks ago. This was followed up by a more thorough release 0.1.0 this last weekend which, as it happens, needed a minor follow-up 0.1.1 to clean up some dependencies on the right R version, as well as vignette building procedures. I added a web page about RcppZiggurat to group together some basic information, but the single best starting point may be the detailed pdf vignette included in the package. Courtesy of CRANberries, there are diffstat reports for the most recent release as well as for the preceding release two days earlier. More detailed information is on the RcppZiggurat page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

23 December 2013

Russ Allbery: Review: The Death of Bees

Review: The Death of Bees, by Lisa O'Donnell
Publisher: HarperCollins
Copyright: 2012
Printing: 2013
ISBN: 0-06-220984-1
Format: Hardcover
Pages: 309
This is the first definite hit from my Powell's Indiespensable subscription, and a good example of why I subscribe. I never would have read or even heard of this book without it, and I thoroughly enjoyed it. Marnie and Nellie are sisters living in a housing estate in Glasgow's Maryhill district. Neither of their parents ever held regular jobs, although one does quickly learn their father had been earning money distributing drugs. The story opens, rather shockingly, with the death of both parents: their father smothered in his bed, and their mother, a day later, after refusing to notify anyone of their father's death, by hanging herself in the garden shed. In fear of being taken by social services and then separated, particularly given Nellie's unusual way of interacting with the world (she talks, and writes, like a woman in the 1950s trying to sound high-class), the girls bury both bodies in the back garden and tell everyone their parents just went on an unannounced trip without them. It wouldn't be the first time. Marnie is 15 and a year away from being legally an adult, at which point she can take custody of Nellie (who is 12) and keep them together. In the meantime, they just have to keep their parents' deaths secret and figure out how to keep food on the table and social services away. Their next-door neighbor is a formerly-closeted older gay man named Lennie who is known as the neighborhood pervert after he was arrested getting a blow job from an underage male prostitute. Both girls are quite understandably suspicious of him, but he's also the first person to notice that something is wrong and to start trying to help. The book is told in many short chapters, each written by one of Marnie, Nellie, or Lennie in their own voice. You might have guessed from the plot summary that this book needs a few warnings, but I want to emphasize that more. This is a book that opens with decaying corpses, including a few rather-too-vivid images from its transport and from Marnie's later (unnamed) post-traumatic stress. Marnie is quite sexually active, and both girls have had a nasty background full of things that I preferred not to think too much about. Most of the worst bits are only alluded to and are kept off-camera, but there's still quite a lot of background nastiness and desperation here. The Death of Bees is blunt and forthright to the point that it repeatedly made me cringe, and that sort of thing usually doesn't bother me in books. That said, this is not a horror novel, even though it contains horror. You could describe it as darkly comic, although none of the comedy is the sort that makes one laugh, except perhaps in startled surprise. The adjectives that come to mind are fierce, compassionate, empathetic, tough, and courageous. The author is completely on the side of the three protagonists, all of whom are deeply hurt in their own ways but all of whom are trying as hard as they can to support each other. I have rarely read a book that made me care as much about the characters. It's the kind of story that makes one want to passionately defend them, particularly once the one real villain, in the form of a do-gooding outsider, makes his appearance. And the reader and the author aren't alone. One of the things I loved about this book is that it doesn't artificially isolate the characters. Marnie has friends, and while Marnie doesn't always notice for Marnie, this is just her life, and many things of significance to the reader are just more of daily life for her this book is full of unexpected acts of small kindness. The surrounding characters are themselves all dealing with their own troubles and not in a great position to help anyone, and yet somehow they manage. Even Nellie, who has a great deal of difficulty interacting with other people her own age, gets unexpected help from people she thinks can't stand her. I think it's very telling that about the only character here who is entirely unsympathetic is the one who claims to be the most moral and virtuous. Unfortunately, from my perspective, this book has one major flaw: the ending. Thankfully, the ending isn't bad; if it were, it would have completely destroyed my enjoyment of the book. By the time one gets through this story, having something bad happen to these girls would break your heart. The ending does deliver the necessary catharsis, but it is far, far too short. O'Donnell builds up tension mercilessly, pushing the story down a path that's clearly desperately wrong for both of the girls, and doesn't let the story climax happen until about ten pages from the end. We get all of a page or two of denouement, and then the novel is over. I am, admittedly, a "Scouring of the Shire" sort of person. I like long denouements, particularly if I've gone through hell with the characters. I like getting to spend some happy time with them. But even for those who don't enjoy that as much as I do, I think this ending was too short. O'Donnell does an amazing job building sympathy and empathy throughout the story, and I didn't want to have to fill in all of the happily ever after from my own imagination. Maybe it would have been hard to do without getting too sentimental or without dulling some of the sharp edges of the story, but I would have really appreciated another ten pages. As is, it felt like the novel abruptly and unceremoniously dumped me out on the ground. But, that aside, this is an excellent character story. It's one that I would be careful about recommending; parts of it are extremely dark and nasty, and you have to take Marnie on her own terms for the story to work. But it's beautifully written and thoroughly engaging, and I'm very glad to have read it. Rating: 8 out of 10

Russell Coker: The Nexus 5

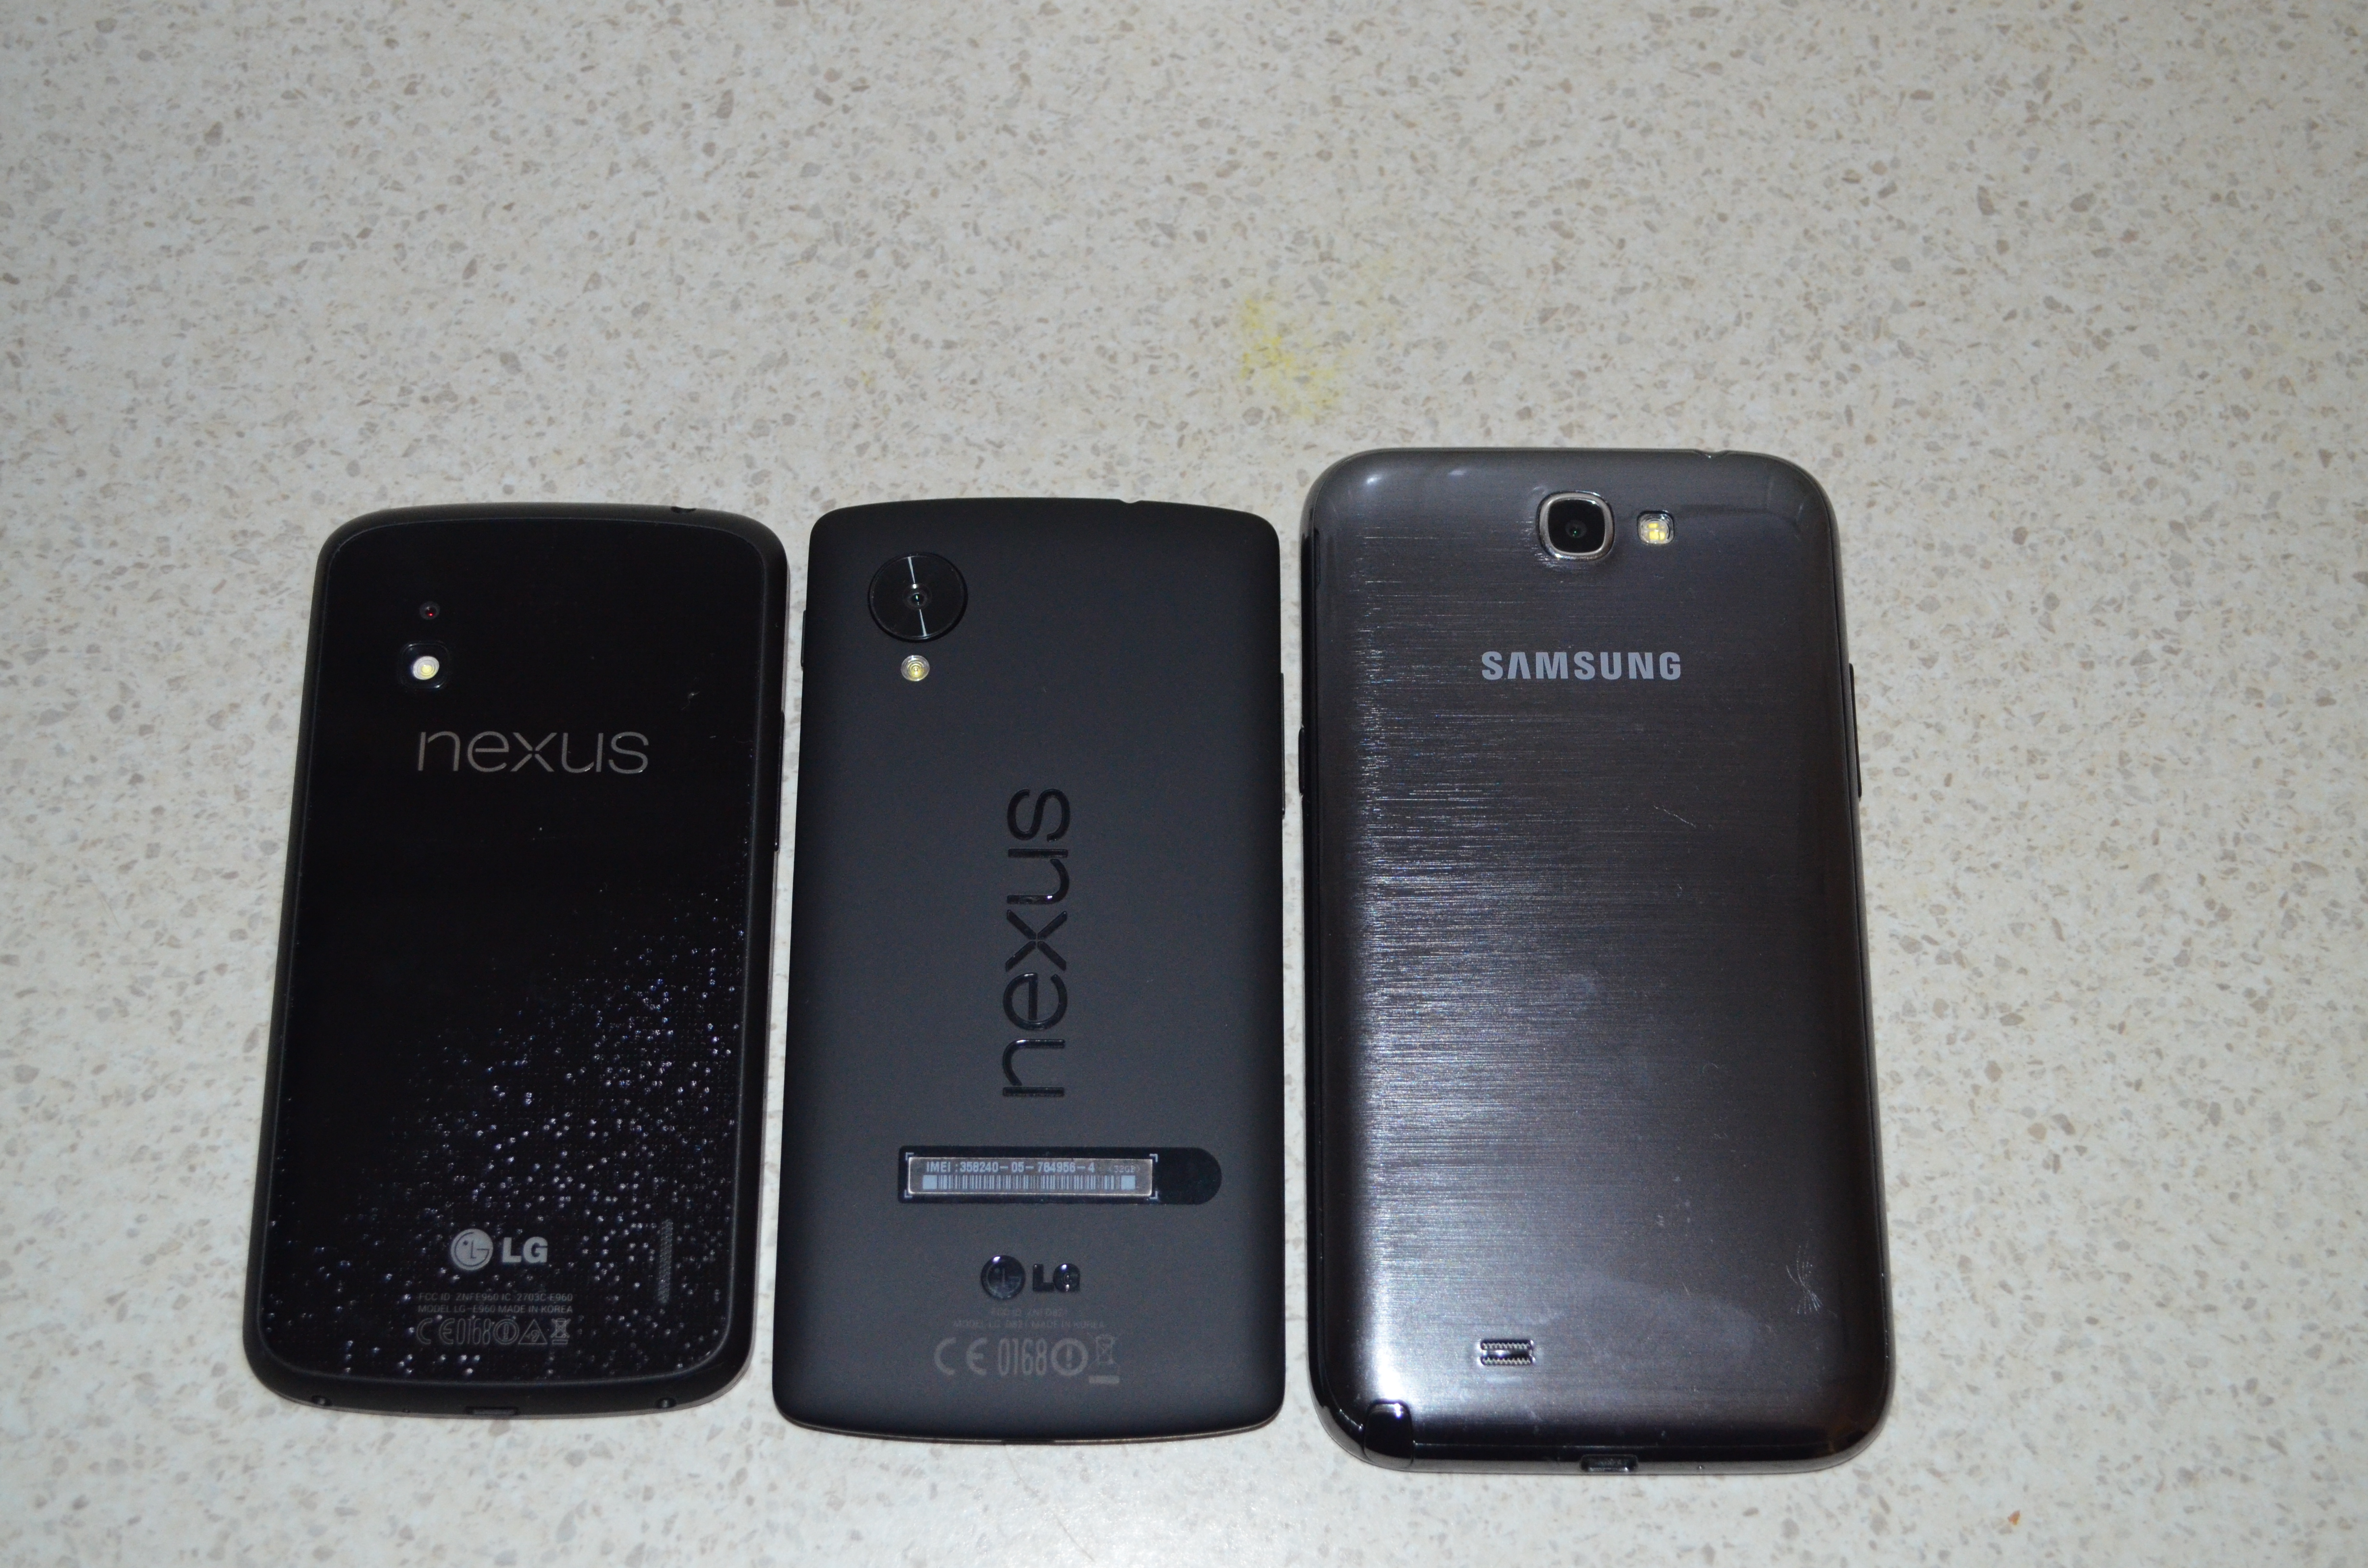
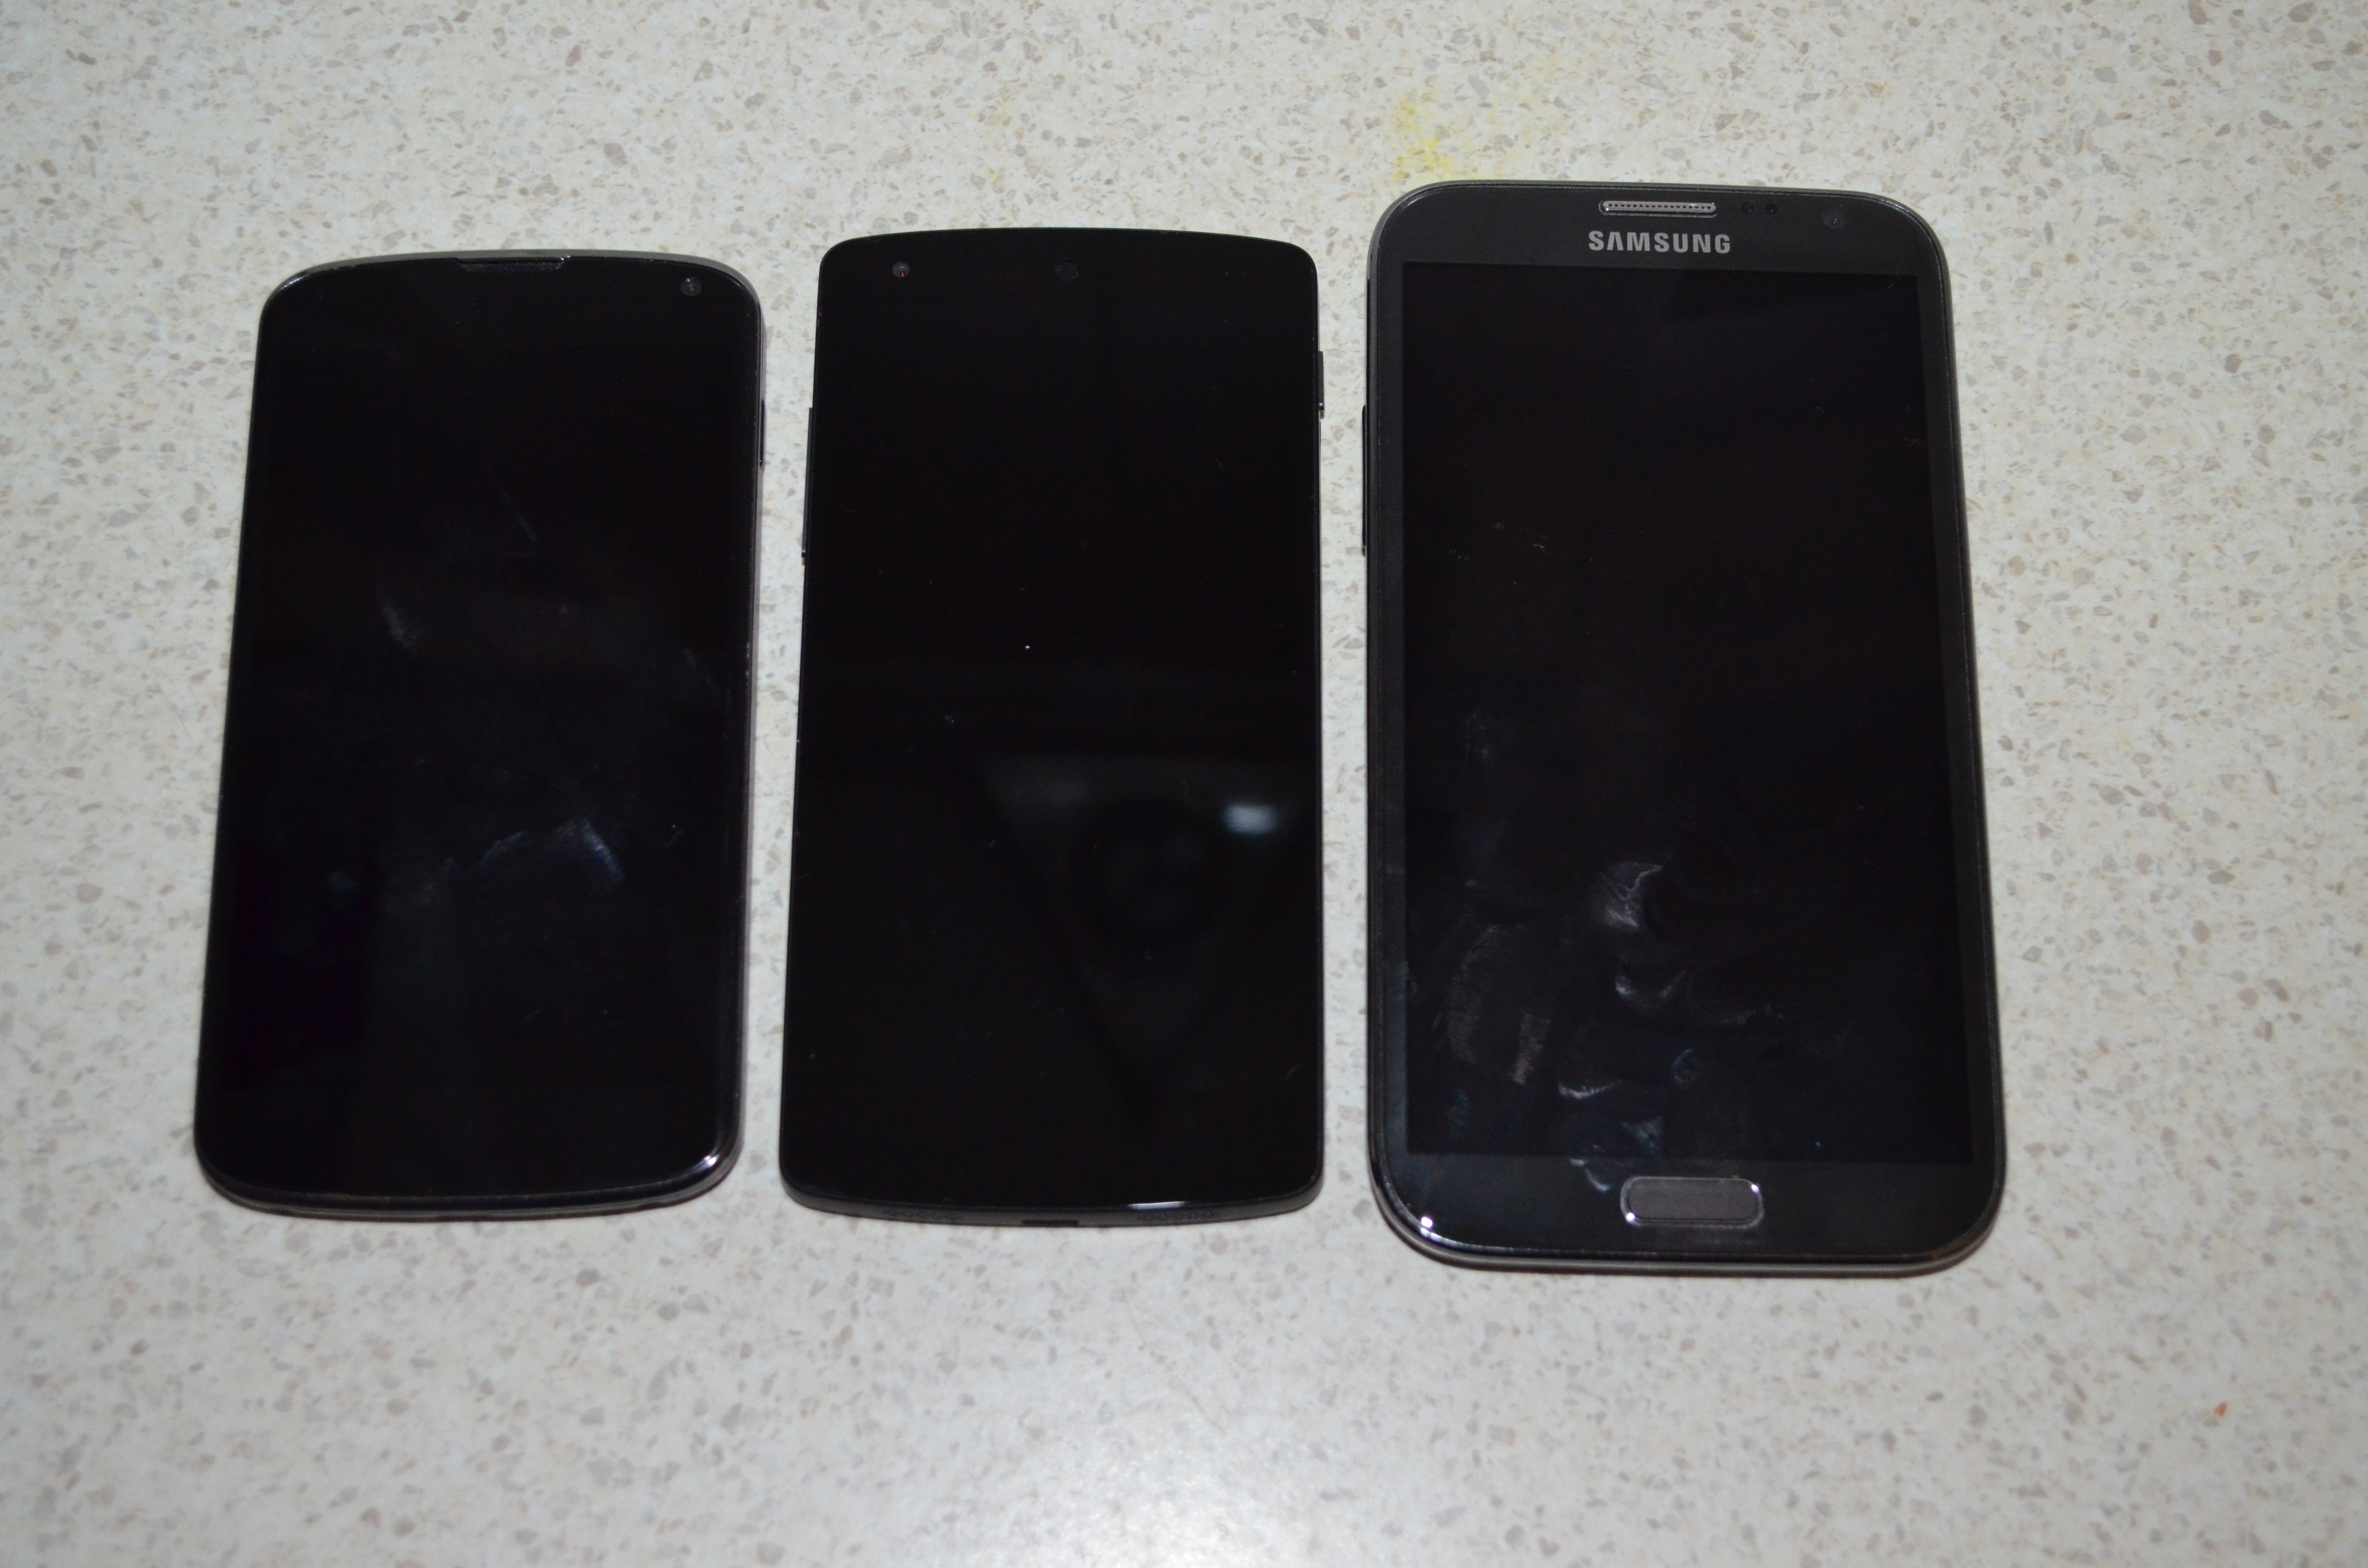
The Nexus 5 is the latest Android phone to be endorsed by Google (and manufactured by LG). It s getting good reviews and the price is good for the specs. I just bought one for my wife, I got her the 32G version because when I bought her a Nexus 4 at the start of the year [1] I chose the 8G version and regretted it ever since. The size of apps is always increasing (some Android games need more than 1G of storage) and higher resolution screens drives the use of high resolution video. Appearance back of Nexus 4, Nexus 5, and Samsung Galaxy Note 2front of Nexus 4, Nexus 5, and Samsung Galaxy Note 2 Above I have pictures of the Nexus 4, the Nexus 5, and the Samsung Galaxy Note 2. The photo of the phone backs captures part of the sparkling pattern on the back of the Nexus 4 and it looks much better in real life (IMHO) because it shimmers as you move the phone. The Nexus 4 looks so good that there s even a transparent case specifically designed to show off the rear panel [2]. It doesn t seem likely that anyone will design such a transparent case for the Nexus 5, it s a good phone to cover up IMHO. The Note 2 isn t the most attractive phone, but I think it has a streamlined elegance of being optimised for it s function. The Nexus 5 has it s camera sticking out, it would be better if they had just made the entire phone thicker and given it a bigger battery but for people who don t want good battery life I guess it s a way of providing a better focal length without making the phone thicker. Sticking the IMEI number on the back of the phone will be useful on rare occasions (and might be a security issue on more occasions) but it definitely makes the phone less attractive. Full HD The quality of the Full HD (1920*1080) display is obvious. The text is slightly clearer when viewing maps and the graphics in Ingress look nicer. Before I used the Nexus 5 I didn t think that there would be any benefit in having such a high resolution in a phone but now I realise that I was wrong. The higher resolution is clearly better. Chris Chavez wrote an article for Phandroid about a rumored Samsung phone with a 2560*1440 display [3]. If such a device had a 6.6 display (IE a new version of the Galaxy Mega) then it would have the same dot-pitch as the Nexus 5. If such a device had a 5.5 display (like the Galaxy Note 3) then it would have a 15% greater DPI than the Nexus 5. It seems that a higher DPI provides a real benefit and this is probably the biggest reason to choose the Nexus 5 over the Nexus 4 and most other Android devices. Comparing with the Nexus 4 The Nexus 5 has the same amount of RAM (2G), a slightly larger display (4.95 vs 4.7 ), higher resolution (a big deal), faster CPU and GPU, and optical zoom. Faster CPU isn t usually going to be a big deal (apart from the fact that more CPU power is needed as well as more GPU power to drive the higher resolution display). The Nexus 5 can come with 16G or 32G of storage while the Nexus 4 has options of 8G and 16G. If you want more than 16G of storage then that s a real benefit for the Nexus 5, but if you only need 16G then it s not an issue. It seems that when playing Ingress on a Nexus 5 it s more likely that running another program (such as Google Hangouts) will cause Ingress to be reloaded than it does on a Nexus 4 or a Galaxy Note 2. While I haven t done a good comparison of the Nexus 4 and the Nexus 5 in this regard I ve compared the Galaxy Note 2 and the Nexus 5 well. My Galaxy Note 2 (which has many daemons running) is much less likely to cause a reload of Ingress (IE have run low on memory and terminated Ingress) than the Nexus 5 my wife is using (which has very little running). So it seems that the OS build on the Nexus 5 uses more memory than the Galaxy Note 2. The Nexus 5 has Gorilla Glass 3 vs Gorilla Glass 2 on the Nexus 4. As my older Android phones with Gorilla Glass 1 (Galaxy S and Sony Ericsson Xperia X10i) didn t get any scratches that matter I don t think this is a benefit for me. Maybe if I lived near a beach I d care more about this. I think that the most significant benefit of the Nexus 5 over the Nexus 4 is the higher resolution display. The optical zoom should provide a theoretical benefit when taking photos, whether that results in better pictures in practice would probably depend on how you hold your phone, the available light, and other factors. I think that if it was possible to buy a Nexus 4 at a sensible price (IE something less than the $250 that Google last charged) then for most people the Nexus 4 would be a better choice than the Nexus 5. But as ebay is full of Nexus 4 phones selling for a higher prices than the Nexus 5 it seems that buying a Nexus 5 is the only option. The range of phones that Kogan sells [4] doesn t have anything for the same price that compares on features. Heat The heat produced by the Nexus 5 is significant and noticable. After some light Ingress playing on a cold day my Galaxy Note 2 with a gel case (that keeps it warm) reported itself as having a battery temperature of 34C. My wife s Nexus 5 reported a temperature of 43C. While the thermometer in the phone might not be the most accurate I don t think there was an accuracy problem, holding my wife s phone was unpleasant and felt like it could burn my hand if I held it tight (40C is the minimum temperature for burns). It seems that a Nexus 5 isn t a good choice if you want to play Ingress in a warm part of the world (EG most of Australia in summer). Also heat dissipated is directly proportional to power use which is going to be a problem for a phone that doesn t permit replacing it s battery. Conclusion I m quite disappointed with the Nexus 5. I expected it to be at least as good as the Nexus 4 in every way and better in many ways. Instead it s not always as good as the Nexus 4 and the ways that it is better won t necessarily provide benefits for everyone. The heat and power use problems are really going to hurt the use of it. But I guess we can always hope that Google release a new Android build that reduces the power use, they might even have a new build that uses less RAM too. I would not consider getting a Nexus 5 for my own use. For my use the Note 2 is clearly more suitable, the larger screen more than compensates for the clarity that the Nexus 5 gets from it s high resolution display. Also I REALLY like having a hardware home button. I ll probably get a Note 3 when the price drops, I m not interested in paying $649 for a phone and I m also not interested in replacing a phone that s less than a year old. So maybe I ll get a Note 3 in the second half of next year.

20 December 2013

Christoph Egger

Greetings from the FAU Security Team (FAUST), the Uni Erlangen CTF group. We were participating in the RuCTFe competition and made it to 4th place. Following is my write-up on the nsaless service, the main crypto challenge in the competition. nsaless is a nodejs webservice providing a short message service. People can post messages and their followers receive the message encrypted to their individual RSA key.

About the gameserver protocol
The gameserver created groups of 8 users on the service 7 were just following the first user (and authorized by the first user to do so) while the first user sent a tweet containing the flag. The service used 512bit RSA with 7 as public exponent. While RSA512 is certainly weak, it's strong enough to make it unfeasible to break directly.

Attacking RSA
There are some known attacks against RSA with small exponents if no proper padding is done. The most straightforward version just takes the e-th root of the cipher-text and, if the clear message was small enough, outputs that root as plain-text. As the flag was long enough to make this attack impossible, we need a somewhat improved Attack.

H stad's Broadcast Attack
Reminder:
  • In RSA, given a plain-text A, the sender computes A mod N to build the cipher-text B.
  • Given simultaneous congruences we can efficiently compute a x such that x satisfies all congruences using the Chinese remainder theorem.
For NSAless we actually get several such B for different N (each belonging to different users receiving the tweet because they follow the poster). This effectively means we get A in mod N for different N. Using the Chinese remainder theorem we can now compute a x A mod N . If we use at least e different B for this we are guaranteed that x actually equals A (in ): A needs to be smaller than N for all N used (otherwise we lose information during encryption), therefore A needs to be smaller than N . Computing now the e-th root of x we get the plain-text A the flag.

Fix
Fixing your service is easy enough, just increase e to an suitable number > 8. At the end of the contest 5 Teams had fixed this vulnerability by either using 17 or 65537.

EXPLOIT
The basic exploit is shown below. Unfortunately it needs to retrieve all tweets for all users the compute the flags which just takes too long to be feasible (at least at the end of the competition where tons of users already existed) so you would need some caching to make it actually work. Would have been a great idea to have users expire after an hour or two in the service!
#!/usr/bin/python
import httplib
import urllib
import re
import json
import pprint
import gmpy
import sys
userparse_re = re.compile('<a [^>]*>([^<]*)</a></div>\s*<div>([^<]*)</div>')
tweetparse_re = re.compile("<div id='last_tweet'>([0-9]+)</div>")
followingparse_re = re.compile('<div><a href="/[0-9]+">([0-9]+)</a></div>')
def my_parse_number(number):
    string = "%x" % number
    if len(string) != 64:
        return ""
    erg = []
    while string != '':
        erg = erg + [chr(int(string[:2], 16))]
        string = string[2:]
    return ''.join(erg)
def extended_gcd(a, b):
    x,y = 0, 1
    lastx, lasty = 1, 0
    while b:
        a, (q, b) = b, divmod(a,b)
        x, lastx = lastx-q*x, x
        y, lasty = lasty-q*y, y
    return (lastx, lasty, a)
def chinese_remainder_theorem(items):
  N = 1
  for a, n in items:
    N *= n
  result = 0
  for a, n in items:
    m = N/n
    r, s, d = extended_gcd(n, m)
    if d != 1:
      raise "Input not pairwise co-prime"
    result += a*s*m
  return result % N, N
def get_tweet(uid):
    try:
        conn = httplib.HTTPConnection("%s:48879" % sys.argv[1], timeout=60)
        conn.request("GET", "/%s" % uid)
        r1 = conn.getresponse()
        data = r1.read()
        tweet = re.findall(tweetparse_re, data)
        if len(tweet) != 1:
            return None
        followers = re.findall(followingparse_re, data)
        return tweet[0], followers
    except:
        return None
def get_users():
    conn = httplib.HTTPConnection("%s:48879" % sys.argv[1], timeout=60)
    conn.request("GET", "/users")
    r1 = conn.getresponse()
    data1 = r1.read(1024 * 1024)
    data = dict()
    for i in re.findall(userparse_re, data1)[:100]:
        userinfo = get_tweet(i[0])
        if userinfo != None:
            data[i[0]] = (json.loads(i[1].replace('&quot;', '"'))['n'], userinfo)
    return data
users = get_users()
allusers = users.keys()
masters = [ user for user in allusers if len(users[user][1][1]) > 0 ]
for test in masters:
    try:
        followers = users[test][1][1]
        data = []
        for fol in followers:
            n = int(users[fol][0])
            tweet = int(users[fol][1][0])
            data = data + [(tweet, n)]
        x, n = chinese_remainder_theorem(data)
        realnum = gmpy.mpz(x).root(7)[0].digits()
        print my_parse_number(int(realnum))
    except:
        pass

Dirk Eddelbuettel: New RcppEigen release 0.3.2.0.1 -- and a new maintainer

In a recent email to the Rcpp and lme4 mailing lists, Doug Bates announced that was turning away from R, Rcpp, lme4 and hence also RcppEigen for which he had been both the primary author and maintainer. This is huge loss for the R community. I have known Doug since the 1990s. He has been a fairly central figure around R during all those years in which I got more and more involved with R. I have learned a lot from him, and enjoyed the work together---initially on the Debian R package (which I took over from him), and all the way to joint work on Rcpp and RcppEigen, including our JSS paper. I am certain to miss him around R. Now, in order to keep RcppEigen viable within CRAN and the R ecosystem, I have offered to maintain it. A first new upload is now on CRAN (and I also uploaded it to Debian where I started to maintain it too as a depedency for lme4). I have also started to make a few minor changes such as tightening Suggests: a little, and editing a few descriptive files. Details are in the Github repo. Questions, comments etc about RcppEigen should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 December 2013

Keith Packard: Altos1.3

AltOS 1.3 TeleMega and EasyMini support Bdale and I are pleased to announce the release of AltOS version 1.3. AltOS is the core of the software for all of the Altus Metrum products. It consists of firmware for our cc1111, STM32L151, LPC11U14 and ATtiny85 based electronics and Java-based ground station software. This is a major release of AltOS as it includes support for both of our brand new flight computers, TeleMega and EasyMini. AltOS Firmware New hardware, new features and fixes Our new advanced flight computer, TeleMega, required a lot of new firmware features, including: Our new easy-to-use flight computer, EasyMini also uses a new processor, the LPC11U14, which is an ARM Cortex-M0 part. For our existing cc1111 devices, there are some minor bug fixes for the flight software, so you should plan on re-flashing flight units at some point. However, there aren t any incompatible changes, so you don t have to do it all at once. Bug fixes: AltosUI Redesigned for TeleMega and EasyMini support AltosUI has also seen quite a bit of work for the 1.3 release, but almost all of that was a massive internal restructuring necessary to support flight computers with a wide range of sensors. From the user s perspective, it s pretty similar with a few changes:

18 December 2013

Daniel Pocock: Embedding Python in multi-threaded C++ applications

Embedding Python into other applications to provide a scripting mechanism is a popular practice. Ganglia can run user-supplied Python scripts for metric collection and the Blender project does it too, allowing users to develop custom tools and use script code to direct their animations. There are various reasons people choose Python:
  • Modern, object orientated style of programming
  • Interpreted language (no need to compile things, just edit and run the code)
  • Python has a vast array of modules providing many features such as database and network access, data processing, etc
The bottom line is that the application developer who chooses to embed Python in their existing application can benefit from the product of all this existing code multiplied by the imagination of their users. Enter repro repro is the SIP proxy of the reSIProcate project. reSIProcate is an advanced SIP implementation developed in C++. repro is a multi-threaded process. repro's most serious competitor is the Kamailio SIP proxy. Kamailio has its own bespoke scripting language that it has inherited from the SIP Express Router (SER) family of projects. repro has always been far more rigid in its capabilities than Kamailio. On the other hand, while Kamailio has given users great flexibility, it has also come at a cost: users can easily build configurations that are not valid or may not do what they really intend if they don't understand the intricacies of the SIP protocol. Here is an example of the Kamailio configuration script (from Daniel's excellent blog about building a Skype-like service in less than an hour) Kamailio also has a wide array of plugins for things like database and LDAP access. repro only had embedded bdb and MySQL support. Embedding Python into repro appears to be a quick way to fill many of these gaps and allow users to combine the power of the reSIProcate stack with their own custom routing logic. On the other hand, it is not simply copying the Kamailio scripting solution: rather, it provides a distinctive alternative. Starting the integration Embedding Python is such a popular practice that there is even dedicated documentation on the subject. As well as looking there, I also looked over the example provided by the embedded Python module for Ganglia. Looking over the Ganglia mod_python code I noticed a lot of boilerplate code for reference counting and other tedious activities. Given that reSIProcate is C++ code, I thought I would look for a C++ solution to this and I came across PyCXX. PyCXX is licensed under BSD-like terms similar to reSIProcate itself so it is a good fit. There is also the alternative Boost.Python API, however, reSIProcate has been built without Boost dependencies so I decided to stick with PyCXX. I looked over the PyCXX examples and the documentation and was able to complete a first cut of the embedded Python scripting feature very quickly. Using PyCXX One unusual thing I noticed about PyCXX is that the Debian package, python-cxx-dev does not provide any shared library. Instead, some uncompiled source files are provided and each project using PyCXX must compile them and link them statically itself. Here is how I do that in the Makefile.am for pyroute in repro:
AM_CXXFLAGS = -I $(top_srcdir)
reproplugin_LTLIBRARIES = libpyroute.la
libpyroute_la_SOURCES = PyRoutePlugin.cxx
libpyroute_la_SOURCES += PyRouteWorker.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxxextensions.c
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxx_extensions.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxxsupport.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/../IndirectPythonInterface.cxx
libpyroute_la_CPPFLAGS = $(DEPS_PYTHON_CFLAGS)
libpyroute_la_LDFLAGS = -module -avoid-version
libpyroute_la_LDFLAGS += $(DEPS_PYTHON_LIBS)
EXTRA_DIST = example.py
noinst_HEADERS = PyRouteWorker.hxx
noinst_HEADERS += PyThreadSupport.hxx
The value PYCXX_SRCDIR must be provided on the configure command line. On Debian, it is /usr/share/python2.7/CXX/Python2 Going multi-threaded My initial implementation simply invoked the Python method from the main routing thread of the repro SIP proxy. This meant that it would only be suitable for executing functions that complete quickly, ruling out the use of any Python scripts that talk to network servers or other slow activities. When the proxy becomes heavily loaded, it is important that it can complete many tasks asynchronously, such as forwarding chat messages between users in real-time. Therefore, it was essential to extend the solution to run the Python scripts in a pool of worker threads. At this point, I had an initial feeling that there may be danger in just calling the Python methods from some other random threads started by my own code. I went to see the manual and I came across this specific documentation about the subject. It looks quite easy, just wrap the call to the user-supplied Python code in something like this:
PyGILState_STATE gstate;
gstate = PyGILState_Ensure();
/* Perform Python actions here. */
result = CallSomeFunction();
/* evaluate result or handle exception */
/* Release the thread. No Python API allowed beyond this point. */
PyGILState_Release(gstate);
Unfortunately, I found that this would not work and that one of two problems occur when using this code:
  • The thread blocks on the call to PyGILState_Ensure()
  • The program crashes with a segmentation fault when the call to a Python method was invoked
Exactly which of these outcomes I experienced seemed to depend on whether I tried to explicitly call PyEval_ReleaseThread() from the main thread after doing the Py_Initialize() and other setup tasks. I tried various permutations of using PyGILState_Ensure()PyGILState_Release() and/or PyEval_SaveThread()/PyEval_ReleaseThread() but I always had one of the same problems. The next thing that occurred to me is that maybe PyCXX provides some framework for thread integration: I had a look through the code and couldn't find any reference to the threading functionality from the C API. I went looking for more articles and mailing list discussions and found implementation notes such as this one in Linux Journal and this wiki from the Blender developers. Most of them just appeared to be repeating what was in the manual, with a few subtle differences, but none of this provided an immediate solution. Eventually, I discovered this other blog about concurrency with embedded Python and it suggests something not highlighted in any of the other resources: calling PyThreadState_New(m_interpreterState) in each thread after it starts and before it does anything else. Combining this with the use of PyEval_SaveThread()/PyEval_ReleaseThread() fixed the problem: the use of PyThreadState_New() was not otherwise mentioned in the relevant section of the Python guide. I decided to take this solution a step further and create a convenient C++ class to encapsulate the logic, you can see this in PyThreadSupport.hxx:
class PyExternalUser
 
   public:
      PyExternalUser(PyInterpreterState* interpreterState)
       : mInterpreterState(interpreterState),
         mThreadState(PyThreadState_New(mInterpreterState))  ;
   class Use
    
      public:
         Use(PyExternalUser& user)
          : mUser(user)
           PyEval_RestoreThread(mUser.getThreadState());  ;
         ~Use()   mUser.setThreadState(PyEval_SaveThread());  ;
      private:
         PyExternalUser& mUser;
    ;
   friend class Use;
   protected:
      PyThreadState* getThreadState()   return mThreadState;  ;
      void setThreadState(PyThreadState* threadState)   mThreadState = threadState;  ;
   private:
      PyInterpreterState* mInterpreterState;
      PyThreadState* mThreadState;
 ;
and the way to use it is demonstrated in the PyRouteWorker class. Observe how PyExternalUser::Use is instantiated in the PyRouteWorker::process() method: when it goes out of scope (either due to a normal return, an error or an exception) the necessary call to PyEval_SaveThread() is made in the PyExternalUser::Use::~Use() destructor. Using other Python modules and DSO problems All of the above worked for basic Python such as this trivial example script:
def on_load():
    '''Do initialisation when module loads'''
    print 'example: on_load invoked'
def provide_route(method, request_uri, headers):
    '''Process a request URI and return the target URI(s)'''
    print 'example: method = ' + method
    print 'example: request_uri = ' + request_uri
    print 'example: From = ' + headers["From"]
    print 'example: To = ' + headers["To"]
    routes = list()
    routes.append('sip:bob@example.org')
    routes.append('sip:alice@example.org')
    return routes
However, it needs a more credible and useful test: using the python-ldap module to try and query an LDAP server appears like a good choice. Upon trying to use import ldap in the Python script, repro would refuse to load the Python script, choking on an error like this:
Traceback (most recent call last):
  File "/usr/lib/python2.7/dist-packages/ldap/__init__.py", line 22, in 
    import _ldap
ImportError: /usr/lib/python2.7/dist-packages/_ldap.so: undefined symbol: PyExc_SystemError
I looked at the file _ldap.so and discovered that it is linked with the LDAP libraries but not explicitly linked to any version of the Python runtime libraries. It expects the application hosting it to provide the Python symbols globally. In my own implementation, my embedded Python encapsulation code is provide as a DSO plugin, similar to the way plugins are loaded in Ganglia or Apache. The DSO links to Python: the DSO is loaded by a dlopen() call from the main process. The main repro binary has no direct link to Python libraries. Adding RTLD_GLOBAL to the top-level dlopen() call for loading the plugin is one way to ensure the Python symbols are made available to the Python modules loaded indirectly by the Python interpreter. This solution may be suitable for applications that don't mix and match many different components. Doing something useful with it Now it was all working nicely, I took a boilerplate LDAP Python example and used it for making a trivial script that converts sip:user@example.org to something like sip:9001@pbx.example.org, assuming that 9001 is the telephoneNumber associated with the user@ email address in LDAP. It is surprisingly simple and easily adaptable to local requirements depending upon the local LDAP structures:
import ldap
from urlparse import urlparse
def on_load():
    '''Do initialisation when module loads'''
    #print 'ldap router: on_load invoked'
def provide_route(method, request_uri, headers):
    '''Process a request URI and return the target URI(s)'''
    #print 'ldap router: request_uri = ' + request_uri
    _request_uri = urlparse(request_uri)
    routes = list()
    
    # Basic LDAP server parameters:
    server_uri = 'ldaps://ldap.example.org'
    base_dn = "dc=example,dc=org"
    # this domain will be appended to the phone numbers when creating
    # the target URI:
    phone_domain = 'pbx.example.org'
    # urlparse is not great for "sip:" URIs,
    # the user@host portion is in the 'path' element:
    filter = "(&(objectClass=inetOrgPerson)(mail=%s))" % _request_uri.path
    #print "Using filter: %s" % filter
    try:
        con = ldap.initialize(server_uri)
        scope = ldap.SCOPE_SUBTREE
        retrieve_attributes = None
        result_id = con.search(base_dn, scope, filter, retrieve_attributes)
        result_set = []
        while 1:
            timeout = 1
            result_type, result_data = con.result(result_id, 0, None)
            if (result_data == []):
                break
            else:
                if result_type == ldap.RES_SEARCH_ENTRY:
                    result_set.append(result_data)
        if len(result_set) == 0:
            #print "No Results."
            return routes
        for i in range(len(result_set)):
            for entry in result_set[i]:
                if entry[1].has_key('telephoneNumber'):
                    phone = entry[1]['telephoneNumber'][0]
                    routes.append('sip:' + phone + '@' + phone_domain)
    except ldap.LDAPError, error_message:
        print "Couldn't Connect. %s " % error_message
    return routes
Embedded Python opens up a world of possibilities After Ganglia 3.1.0 introduced an embedded Python scripting facility, dozens of new modules started appearing in github. Python scripting lowers the barrier for new contributors to a project and makes it much easier to fine tune free software projects to meet local requirements: hopefully we will see similar trends with the repro SIP proxy and other projects that choose Python. The code is committed here in the reSIProcate repository. These features will appear in the next beta release of reSIProcate and Debian packages will be available in unstable in a few days.

Ingo Juergensmann: Debian donation to m68k arrived

The Debian m68k port has been entitled by the DPL to receive a donation of five memory expansion cards for the m68k autobuilders. The cards arrived two weeks ago and are now being shipped to the appropriate buildd admins. Adding those 256 MB memory expansion will have a huge effect to the m68k buildds, because most of them are Amigas that are currently running with "just" 128 MB. The problem with those expansion cards is to make use of them. Sounds strange but this is the story behind it.... Those memory expansion cards, namely it is the BigRamPlus from Individual Computers, are Zorro III bus cards, which has some speed limitations. The Amiga memory model is best described in the Amiga Hardware Reference Manual. For Zorro III based Amigas this is described in the section "A3000 memory map", where you can see that the memory model is divided into different address space. The most important address space is the "Coprocessor Slot Expansion" space, starting at $0800 0000. This is where the memory on the CPU accelerator cards will be found and which runs at full CPU speed. The BigRamPlus, however, is located within "Zorro III Expansion" address space at $1000 0000 and will have transfer rates of about 13 MB/s. Then again there's still the motherboard expansion memory and others like Zorro II expansion memory. Unfortunately the current kernel does not support SPARSEMEM on m68k, but is using DISCONTIGMEM as Geert Uytterhoven explained. In short: we need SPARSEMEM support to easily make use of all available memory chunks that can be found. To make it a little more difficult, Amigas do use some kind of memory priority. Memory on accelerator cards usually has a priority of 40, motherboard expansion memory has a priority of, let's say, 20 and chip memory a pri of 0. This priority usually is equivalent to speed of memory. So, we want to have the kernel loaded to accelerator memory, of course. Basically we could do that by using a memfile and define the different memory chunks in the appropriate priority list like this one:
2097152
0x08000000 67108864
0x07400000 12582912
0x05000000 268435424
Would be an easy solution, right? Except that this doesn't work out. Currently the kernel will be loaded into the first memory chunk that is defined and ignore all memory chunks before that address space. As you can see 0x07400000 and 0x05000000 would be ignored because of this. Getting confused? No problem! It will get worse! ;) There's another method of accessing memory for Amigas: it's called z2ram and will use Zorro II as, let's say, swapping area. But maybe you guessed it: z2ram does not work for Zorro III memory (yet). So, this won't work either. Geert suggested to use that Zorro III memory as mtd device and finally this worked out! You'll need these modules in your kernel:
CONFIG_MTD=m
CONFIG_MTD_CMDLINE_PARTS=m
CONFIG_MTD_BLKDEVS=m
CONFIG_MTD_SWAP=m
CONFIG_MTD_MAP_BANK_WIDTH_1=y
CONFIG_MTD_MAP_BANK_WIDTH_2=y
CONFIG_MTD_MAP_BANK_WIDTH_4=y
CONFIG_MTD_CFI_I1=y
CONFIG_MTD_CFI_I2=y
CONFIG_MTD_SLRAM=m
CONFIG_MTD_PHRAM=m
Then you just need to create the mtd device and configure it as swap space:
/sbin/modprobe phram phram=bigram0,0x50000000,0xfffffe0
/sbin/modprobe mtdblock
/sbin/mkswap /dev/mtdblock0
/sbin/swapon -p 5 /dev/mtdblock0
And then you're done:
# swapon -s
Filename Type Size Used Priority
/dev/sda3 partition 205932 8 1
/dev/sdb3 partition 875536 16 1
/dev/mtdblock0 partition 262136 53952 5
To make it even worse (yes, there's still room for that! ;)) you can put two memory expansion cards into one box:
# lszorro -v
00: MacroSystems USA Warp Engine 40xx [Accelerator, SCSI Host Adapter and RAM Expansion]
40000000 (512K) 01: Unknown device 0e3b:20:00
50000000 (256M) 02: Village Tronic Picasso II/II+ RAM [Graphics Card]
00200000 (2M) 03: Village Tronic Picasso II/II+ [Graphics Card]
00e90000 (64K) 04: Hydra Systems Amiganet [Ethernet Card]
00ea0000 (64K) 05: Unknown device 0e3b:20:00
60000000 (256M)
The two "Unknown device" entries are the two BigRamPlus cards. As you can see card #1 starts at 0x50000000 and card #2 starts at 0x60000000. Unfortunately the phram kernel module can be loaded twice with different start addresses, but the idea to start at 0x50000000 with a size of 512M won't work either as there seems to be a reserved 0x20 bytes a range at the beginning of each card. Anyway... So, to make a very long and weird story short: the donated memory cards from Debian can now be used as additional and fast swap space for the buildds as long as it takes to get SPARSEMEM support working. Thanks again for donating the money for those memory expansion cards for the good old m68k port. Once done SPARSEMEM support in the m68k will benefit not only these cards in Amigas but Ataris as well.
Kategorie:

Antoine Beaupr : Password reset of Speedstream 5200 modems

After an extended downtime on my ADSL uplink at home during a nice snowstorm, I got curious and wanted to find out the SNR (Signal to Noise Ratio) I had on my line, to try to explain why it was down. It turned out it was more complicated than I thought, because the modem was locked down by Bell Canada (even though I am not a customer). There was a Windows utility, but since I haven't been running this pathetic operating system in years, I had to find an alternative. Fortunately, the author of that utility posted a description of the packet format used for the password reset, and here I was trying to send raw ethernet frames using Linux (for testing and, why not!) and FreeBSD (because I use FreeBSD for routing, because I dislike iptables). The result is this somewhat poorly written C program, available in this git repository. It uses raw sockets in Linux but the BPF (Berkeley Packet Filter) in FreeBSD, as their interface is a little broken for raw sockets. See the README file for more information. Enjoy.

Daniel Kahn Gillmor: automatically have uscan check signatures

If you maintain software in debian, one of your regular maintenance tasks is checking for new upstream versions, reviewing them, and preparing them for debian if appropriate. One of those steps is often to verify the cryptographic signature on the upstream source archive. At the moment, most maintainers do the cryptographic check manually, or maybe even don't bother to do it at all. For the common case of detached OpenPGP signatures, though, uscan can now do it for you automatically (as of devscripts version 2.13.3). You just need to tell uscan what keys you expect upstream to be signing with, and how to find the detached signature. So, for example, Damien Miller recently announced his new key that he will be using to sign OpenSSH releases (his new key has OpenPGP fingerprint 59C2 118E D206 D927 E667 EBE3 D3E5 F56B 6D92 0D30 -- you can verify it has been cross-signed by his older key, and his older key has been revoked with the indication that it was superceded by this one). Having done a reasonable verification of Damien's key, if i was the openssh package maintainer, i'd do the following:

cd ~/src/openssh/
gpg --export '59C2 118E D206 D927 E667  EBE3 D3E5 F56B 6D92 0D30' >> debian/upstream-signing-key.pgp
And then upon noticing that the signature files are named with a simple .asc suffix on the upstream distribution site, we can use the following pgpsigurlmangle option in debian/watch:
version=3
opts=pgpsigurlmangle=s/$/.asc/ ftp://ftp.openbsd.org/pub/OpenBSD/OpenSSH/portable/openssh-(.*)\.tar\.gz 
I've filed this specific example as debian bug #732441. If you notice a package with upstream signatures that aren't currently being checked by uscan (or if you are upstream, you sign your packages, and you want your debian maintainer to verify them), you can file similar bugs. Or, if you maintain a package for debian, you can just fix up your package so that this check is there on the next upload. If you maintain a package whose upstream doesn't sign their releases, ask them why not -- wouldn't upstream prefer that their downstream users can verify that each release wasn't tampered with? Of course, none of these checks take the the place of the real work of a debian package maintainer: reviewing the code and the changelogs, thinking about what changes have happened, and how they fit into the broader distribution. But it helps to automate one of the basic safeguards we should all be using. Let's eliminate the possibility that the file was tampered with at the upstream distribution mirror or while in transit over the network. That way, the maintainer's time and energy can be spent where they're more needed.Tags: crypto, devscripts, openpgp, package maintenance, signatures, uscan

16 December 2013

Erich Schubert: Java Hotspot Compiler - a heavily underappreciated technology

When I had my first contacts with Java, probably around Java 1.1 or Java 1.2, it felt all clumsy and slow. And this is still the reputation that Java has to many developers: bloated source code and slow performance.
The last years I've worked a lot with Java; it would not have been my personal first choice, but as this is usually the language the students know best, it was the best choice for this project, the data mining framework ELKI.
I've learned a lot on Java since, also on debugging and optimizing Java code. ELKI contains a number of tasks that require a good number chrunching performance; something where Java particularly had the reputation of being slow.
I must say, this is not entirely fair. Sure, the pure matrix multiplication performance of Java is not up to Fortran (BLAS libraries are usually implemented in Fortran, and many tools such as R or NumPy will use them for the heavy lifting). But there are other tasks than matrix multiplication, too!
There is a number of things where Java could be improved a lot. Some of this will be coming with Java 8, others is still missing. I'd particularly like to see native BLAS support and multi-valued on-stack returns (to allow intrinsic sincos, for example).

In this post, I want to emphasize that usually the Hotspot compiler does an excellent job.
A few years ago, I have always been laughing at those that claimed "Java code can even be faster than C code"; because the Java JVM is written in C. Having had a deeper look at what the hotspot compiler does, I'm now saying: I'm not surprised that quite often, reasonably good Java code outperforms reasonably good C code.
In fact, I'd love to see a "hotspot" optimizer for C.
So what is it what makes Hotspot so fast? In my opinion, the key ingredient to hotspot performance is aggressive inlining. And this is exactly why "reasonably well written" Java code can be faster than C code written at a similar level.
Let me explain this at an example. Assuming we want to compute a pariwise distance matrix; but we want the code to be able to support arbitrary distance functions. The code will roughly look like this (not heavily optimized):
for (int i = 0; i < size; i++)  
  for (int j = i + 1; j < size; j++)  
    matrix[i][j] = computeDistance(data[i], data[j]);
   
 
In C, if you want to be able to choose computeDistance at runtime, you would likely make it a function pointer, or in C++ use e.g. boost::function or a virtual method. In Java, you would use an interface method instead, i.e. distanceFunction.distance().
In C, your compiler will most likely emit a jmp *%eax instruction to jump to the method to compute the distance; with virtual methods in C++, it would load the target method from the vtable and then jmp there. Technically, it will likely be a "register-indirect absolute jump". Java will, however, try to inline this code at runtime, i.e. it will often insert the actual distance function used at the location of this call.
Why does this make a difference? CPUs have become quite good at speculative execution, prefetching and caching. Yet, it can still pay off to save those jmps as far as I can tell; and if it is just to allow the CPU to apply these techniques to predict another branch better. But there is also a second effect: the hotspot compiler will be optimizing the inlined version of the code, whereas the C compiler has to optimize the two functions independently (as it cannot know they will be only used in this combination).
Hotspot can be quite aggressive there. It will even inline and optimize when it is not 100% sure that these assumptions are correct. It will just add simple tests (e.g. adding some type checks) and jump back to the interpreter/compiler when these assumptions fail and then reoptimize again.
You can see the inlining effect in Java when you use the -Xcomp flag, telling the Java VM to compile everything at load time. It cannot do as much speculative inlining there, as it does not know which method will be called and which class will be seen. Instead, it will have to compile the code using virtual method invocations, just like C++ would use for executing this. Except that in Java, every single method will be virtual (in C++, you have to be explicit). You will likely see a substantial performance drop when using this flag, it is not recommended to use. Instead, let hotspot perform its inlining magic. It will inline a lot by default - in particular tiny methods such as getters and setters.
I'd love to see something similar in C or C++. There are some optimizations that can only be done at runtime, not at compile time. Maybe not even at linking time; but only with runtime type information, and that may also change over time (e.g. the user first computes a distance matrix for Euclidean distance, then for Manhattan distance).

Don't get me wrong. I'm not saying Java is perfect. There are a lot of common mistakes, such as using java.util.Collections for primitive types, which comes at a massive memory cost and garbage collection overhead. The first thing to debug when optimizing Java applications is to check for memory usage overhead. But all in all, good Java code can indeed perform well, and may even outperform C code, due to the inlining optimization I just discussed; in particular on large projects where you cannot fine-tune inlining in C anymore.

Sometimes, Hotspot may also fail. Which is largely why I've been investigating these issues recently. In ELKI 0.6.0 I'm facing a severe performance regression with linear scans (which is actually the simpler codepath, not using indexes but using a simple loop as seen above). I had this with 0.5.0 before, but back then I was able to revert back to an earlier version that still performed good (even though the code was much more redundant). This time, I would have had to revert a larger refactoring that I wanted to keep, unfortunately.
Because the regression was quite severe - from 600 seconds to 1500-2500 seconds (still clearly better than -Xcomp) - I first assumed I was facing an actual programming bug. Careful inspection down to the assembler code produced by the hotspot VM did not reveal any such error. Then I tried Java 8, and the regression was gone.
So apparently, it is not a programming error, but Java 7 failed at optimizing it remotely as good as it did with the previous ELKI version!
If you are an Java guru, interested at tracking down this regression, feel free to contact me. It's in an open source project, ELKI. I'd be happy to have good performance even for linear-scans, and Java 7. But I don't want to waste any more hours on this, but instead plan to move on to Java 8 for other reasons (lambda expressions, which will greatly reduce the amount of glue coded needed), too. Plus, Java 8 is faster in my benchmarks.

Dirk Eddelbuettel: RProtoBuf 0.3.2

A new version 0.3.2 of RProtoBuf, is now on CRAN. RProtoBuf provides GNU R bindings for the Google Protobuf data encoding library used and released by Google. As for the last few releases, Murray took charge of most changes. The NEWS file entry follows:
Changes in RProtoBuf version 0.3.2 (2013-12-15)
  • Fixed a bug that erroneously prevented users from setting raw byte fields in protocol buffers under certain circumstances.
  • Give a user friendly error message when seting an extension to a message of the wrong type instead of causing a C++ check failure that terminates the Rsession.
  • Change object table lookup slightly to allow users to use the <<- operator in code using RProtoBuf without hitting a stop() error in the lookup routine.
  • Add missing enum_type method and improve show method for EnumValueDescriptors.
  • Improve documentation and tests for all of the above.
  • Rewrote tests/ script calling RUnit tests
CRANberries also provides a diff to the previous release 0.3.1. More information is at the RProtoBuf page which has a draft package vignette, a 'quick' overview vignette and a unit test summary vignette. Questions, comments etc should go to the rprotobuf mailing list off the RProtoBuf page at R-Forge.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Craig Sanders: shopping online whinge of the day

There are numerous benefits to shopping online you can order stuff and pay for it from the comfort of your own home and it ll arrive on your doorstep in just a few days. wonderful, and so many words have been written about the benefits over the years that there s no need to belabour the point, But there are some things about it that really suck and make me NOT want to order stuff online most of the time my distaste for the privacy and delivery problems is enough to dissauade me from buying anything, helped by the fact that I live a fairly non-consumerist lifestyle (and for a geek, I have an almost non-existent gadget-fetish) but occasionally I want or need something that isn t available locally or which my ill-health makes impractical to buy in person (i ve been effectively housebound or in hospital for most of the year) so here are the things that piss me off most about shopping online.
  1. Loss of anonymity and privacy. You can walk into any shop and pay cash for whatever you want, they don t need to know who you are or where you live, and they don t get to accidentally add you to a mailing list against your express wishes oh, we didn t realise that when you said DO NOT SPAM ME, you actually meant DO NOT SPAM ME we ll just keep spamming you for another six months until we get around to processing your removal request . partial solution: use a different email address with each online shop. boycott the shop and destroy the address if they spam. what sucks is that this is actually necessary. it doesn t matter how loudly I say DO NOT SPAM ME. DO NOT ADD ME TO ANY MAILING LISTS. DO NOT ASK ME TO COMPLETE A SURVEY. DO NOT CONTACT ME FOR ANY REASON NOT DIRECTLY RELATED TO DELIVERING MY ORDER. MY PERSONAL INFORMATION IS PROVIDED SOLELY SO THAT YOU CAN SHIP MY ORDER TO ME AND MAY NOT BE USED FOR ANY OTHER PURPOSE. FAILURE TO RESPECT MY PRIVACY WILL RESULT IN IMMEDIATE AND PERMANENT BOYCOTT (yes, that IS the text I use in the comments/instructions field of every order I place), marketing vermin will decide that I really want their spam after all because their spam is super interesting and important and isn t really spam at all.
  2. nosy demands for unneccessary information. OK, they need your addresss to ship your parcel but they don t need your phone number, and they don t need to tie your order to your facebook or other bullshit social-spam account. most online order forms have phone number as a required field. Fortunately, they usually accept 0000000 or some other bogus non-phone number as a valid number .if not, i give them their own phone number.
  3. the thing that really shits me the most about online shopping is that both couriers and australia post suck. the lazy fuckers usually don t even bother attempting to deliver to residential addressess. at best, they just stick a non-delivery card in your letterbox without even attempting to knock on the door ..and sometimes they don t even bother doing that. the delivery driver just files a bogus failed to deliver or recipient refused delivery with their office.
i ve made four online purchases in the last month and a half. only one of them was delivered correctly to my door, even though I was sitting at my desk in the front room of the house, a few feet from my front door, and regularly monitoring the parcel s tracking web page so I knew it was arriving. parcel 1 (Nov 16): DHL from NZ to AU. delivered perfectly. delivered in about two days for $17. order value: around $35. parcel 2 (Nov 20): Aust Post from WA to Vic, Express Post (costs a few bucks more than standard post). order value: around $80. lazy driver didn t bother to attempt delivery. left card in letter box. i had to pick it up 2 days later from a post office the next suburb over (it wasn t there yet on the first attempt to pick up, the next day). Aust Post offered to maybe put me in touch with their re-delivery people who might possibly be able to re-deliver the parcel next week sometime maybe, if they felt like it. knowing that I had another hospital appt the next week, I declined (if i hadn t, it would have been an absolute certainty that they would try to deliver it while i was out). parcel 3 (nov 29): DHL from NZ to AU. order value: around $85. lazy courier didn t even bother to leave a card, just logged it as Recipient refused delivery . This refused delivery lie infuriated me when i saw it on the tracking page so i phoned and yelled at them a lot. DHL delivered it later the same day. if they hadn t I would have had to get myself over to the other side of town during business hours and pick it up from their South Melbourne depot. parcel 4 (today, Dec 16): Aust Post from NSW to Vic, Express Post . order value: around $160. lazy driver didn t even bother to leave a card, just logged it as Attempted delivery being carded to Australia Post outlet . Complete bullshit. There was no delivery attempt, not even a card in the letterbox, let alone a knock on the door with my parcel. Rang Aust Post on 8847 9045 (a phone number curiously absent from their tracking page, but which I had written down after their failure to deliver on Nov 20) and complained. they claim that they will try to deliver it today. i ll believe it when I see it. UPDATE @4.30pm: no, it s not going to be delivered today. they say they might choose to deliver it tomorrow or sometime in the future, if the delivery center manager feels like it. i told them that this is not an option my parcel WILL be delivered, it is what they were paid to do so it is what they ARE going to do. btw, the tracking page says that they attempted delivery at 12.15 today (they didn t not even a card in the letterbox), but the tracking page wasn t updated with that until about 2.30pm. by a complete non-coincidence their delivery center allegedly closes at 2pm, so it s impossible to complain about non-delivery in time for the complaint to do any good. Score so far: DHL 50% delivery rate. Aust Post: 100% failure rate. Annoyance Rate: extremely high. Desire to repeat the experience: non-existent. The Australia Post delivery problems are particularly annoying. I ve always thought of the network of local post offices to be a huge advantage for parcel delivery if i m not home, my parcel will go to a local post office and I can pick it up from there. And this is a great advantage. I used to take advantage of it when I was well enough to work. In fact, I d insist on delivery by Aust. Post rather than by a courier for exactly this reason, a local post office is far more convenient than some courier s depot on the other side of town or out in some far outer-suburban hellhole. But when it s used as an excuse to not even bother attempting delivery, it sucks. I m not well, and I should have been lying in bed reading or sleeping today, not wasting what little energy I have waiting for a parcel that never arrived and I certainly shouldn t have to phone Aust Post or DHL to yell at them for failing to do the job that they have been paid to do. shopping online whinge of the day is a post from: Errata

15 December 2013

Alessandro Ghedini: Building Debian packages using Linux namespaces

In the past few days I have been messing around with Linux namespaces, and developed a little tool (pflask) that automates the creation of simple Linux containers based on them (a sort of chroot(8) on steroids if you will). While the whole raison d' tre behind this project was "just because", and many more mature solutions exist, I decided that it'd be nice to find an actual use case for this (otherwise I tend to lose interest pretty quickly) so I wrote a lil (and rather dumb) pbuilder clone that uses pflask instead of chroot. The nice thing about pflask is that, differently from e.g. LXC, it doesn't need any pre-configuration and can be used directly on a vanilla debootstrap(8)ed Debian system:
$ sudo mkdir -p /var/cache/pflask
$ sudo debootstrap --variant=buildd $DIST /var/cache/pflask/base-$DIST-$ARCH
Where $DIST and $ARCH are e.g. unstable and amd64. Once that's done just run pflask-debuild on the package sources:
$ apt-get source somepackage
$ cd somepackage-XYX
$ pflask-debuild
The script will take care of creating a new container, chroot(2)ing into it, installing all the required dependencies, building and signing the package (it also runs lintian!). The main difference from pbuilder is that pflask will mount a copy-on-write filesystem (using AuFS) on the / of the container so that any modification (e.g. installation of packages) can be easily discarded once the container terminates (similarly to what cowbuilder(8) does, modulo the hardlinks hack). Additionally, thanks to the mount namespace created inside the container, all of this will be isolated from the host system and other containers, so that multiple packages can be built simultaneously on the same base debootstrapped directory. Another possibility would be that of disabling the network inside the container using a network namespace, in order to prevent the package build system from downloading stuff from Internet while at the same time maintaining the network active on the host system, but I haven't done any experiment in this direction yet. Note though that all of this is rather crude and experimental, but as a little hack it seems to work rather well (YMMV).

Russell Coker: Dell PowerEdge T110

In June 2008 I received a Dell PowerEdge T105 server to run in my home for a client [1]. That system has run well for over 5 years for the purposes of my client and also as my own home fileserver and as a workstation. But now it s getting a bit old, while it was still basically working the cooling fans were getting noisy, faster systems are available, and it was crashing occasionally which could have been due to hardware or software. On the 7th of November I got a new Dell PowerEdge T110. It s got a i3-3220 CPU (speed of 4218 according to cpubenchmark.net) which is a lot better than the AMD 1212 (speed of 982). It takes up to 4*3.5 SATA disks (as opposed to 2 disks) and has more options for memory expansion. Next time I run out of disk space I ll add another RAID-1 pair of disks instead of buying new disks. Generally this system is much the same as the one it replaces. It s a cheap server which unfortunately lacks sound hardware and usable video hardware. Sound is a problem I already solved with USB speakers but for the new system I bought a PCIe video card. Fortunately the system has PCIe*16 sockets (which apparently only have PCIe*8 wires) which avoids the problem I had in the past trying to obtain a suitable video card. The crashes turned out to be due to BTRFS and now that I ve made some tweaks everything is running well. I ll probably buy another Dell PowerEdge in about 5 years time.

14 December 2013

Dirk Eddelbuettel: RcppDE 0.1.2

A maintenance release (now at version 0.1.2) of my RcppDE package (previously described in these two posts) is now CRAN. More details about the package are available in the vignette also included in the RcppDE R package. Changes were minimal and driven mostly by some CRAN Policy changes which now prefer vignette sources files in (top-level) directory vignettes/ Courtesy of CRANberries, there is also a diffstat report for the most recent release. Current and previous releases are available here as well as on CRAN.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.