Search Results: "will"

22 August 2017

John Goerzen: The Eclipse

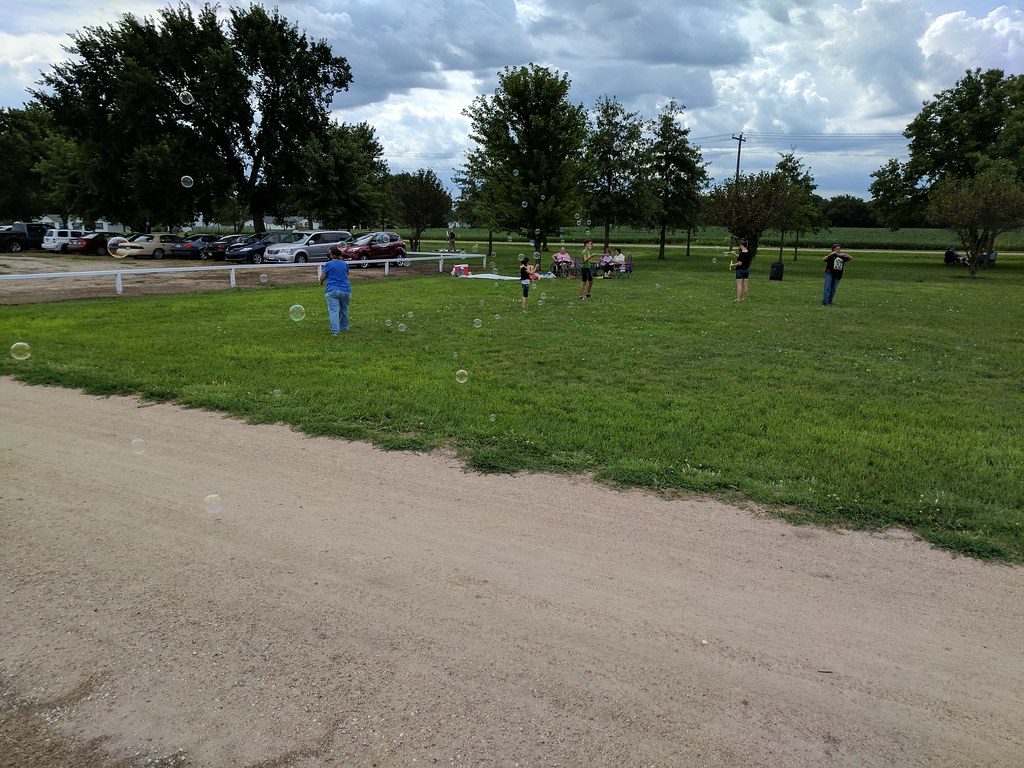
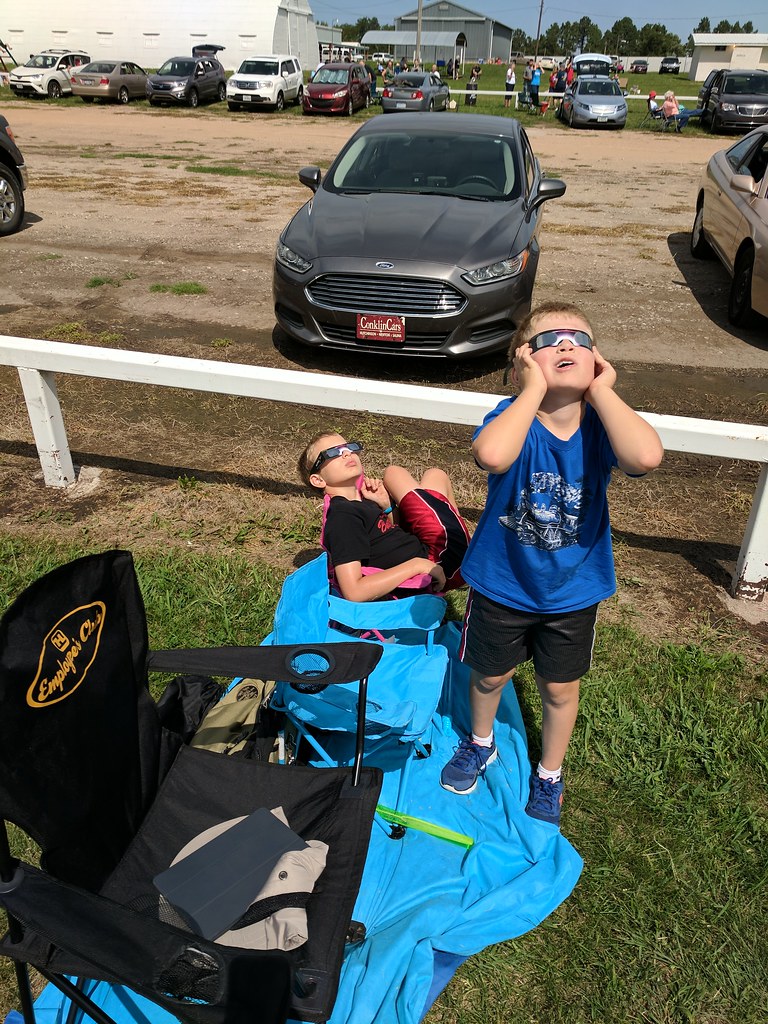
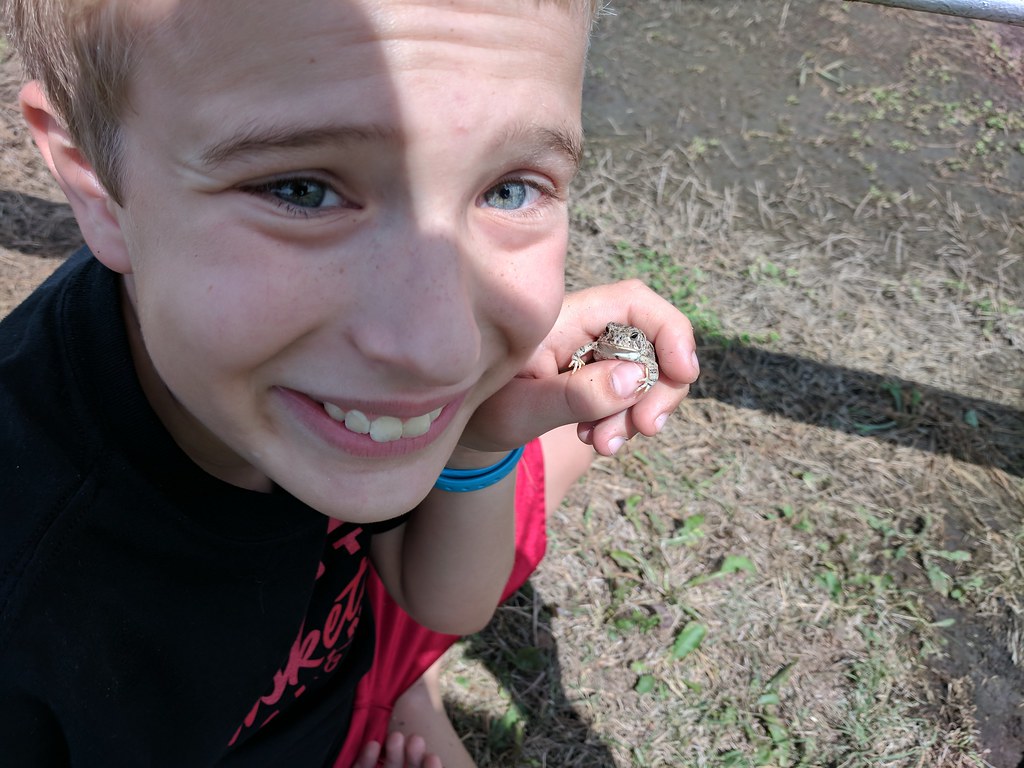
Highway US-81 in northern Kansas and southern Nebraska is normally a pleasant, sleepy sort of drive. It was upgraded to a 4-lane road not too long ago, but as far as 4-lane roads go, its traffic is typically light. For drives from Kansas to South Dakota, it makes a pleasant route. Yesterday was eclipse day. I strongly suspect that highway 81 had more traffic that day than it ever has before, or ever will again. For nearly the entire 3-hour drive to Geneva, NE, it was packed though mostly still moving at a good speed. And for our entire drive back, highway 81 and every other southbound road we used was so full it felt like rush hour in Dallas. (Well, not quite. Traffic was still moving.) I believe scenes like this were played out across the continent. I ve been taking a lot of photos, and writing about our new baby Martha lately. Now it s time to write a bit about some more adventures with Jacob and Oliver they re now in third and fifth grades in school. We had been planning to fly, and airports I called were either full, or were planning to park planes in the grass, or even shut down some runways to use for parking. The airport in the little town of Beatrice, NE (which I had visited twice before) was even going to have a temporary FAA control tower. At the last minute, due to some storm activity near home at departure time, we unloaded the plane and drove instead. The atmosphere at the fairgrounds in Geneva was festive. One family had brought bubbles for their kids and extras to share. IMG_20170821_113229 I had bought the boys a book about the eclipse, which they were reading before and during the event. They were both great, safe users of their eclipse glasses. IMG_20170821_124809 Jacob caught a toad, and played with it for awhile. He wanted to bring it home with us, but I convinced him to let me take a picture of him with his toad friend instead. IMG_20170821_124553 While we were waiting for totality, a number of buses from the local school district arrived. So by the time the big moment arrived, we could hear the distant roar of delight and applause from the school children gathered at the far end of the field, plus all the excitement nearby. Both boys were absolutely ecstatic to be witnessing it (and so was I!) Wow! Awesome! And simple cackles of delight were heard. On the drive home, they both kept talking about how amazing it was, and it was once in a lifetime. We enjoyed our eclipse neighbors the woman from San Antonio next to us, the surprise discovery of another family from just a few miles from us parked two cars down, even running into relatives at a restaurant on the way home. The applause from all around when it started and when it ended. And the feeling, which is hard to describe, of awe and amazement at the wonders of our world and our universe. There are many problems with the world right now, but somehow there s something right about people coming together from all over to enjoy it.
Daniel Silverstone: Building a USB descriptor table set

In order to proceed further on our USB/STM32 oddessy, we need to start to build a USB descriptor set for our first prototype piece of code. For this piece, we're going to put together a USB device which is vendor-specific class-wise and has a single configuration with a interface with a single endpoint which we're not going to actually implement anything of. What we're after is just to get the information presented to the computer so that lsusb can see it. To get these built, let's refer to information we discovered and recorded in a previous post about how descriptors go together.
Device descriptor Remembering that values which are > 1 byte in length are always stored little-endian, we can construct our device descriptor as:
Our device descriptor
Field Name Value Bytes
bLength 18 0x12
bDescriptorType DEVICE 0x01
bcdUSB USB 2.0 0x00 0x02
bDeviceClass 0 0x00
bDeviceSubClass 0 0x00
bDeviceProtocol 0 0x00
bMaxPacketSize 64 0x40
idVendor TEST 0xff 0xff
idProduct TEST 0xff 0xff
bcdDevice 0.0.1 0x01 0x00
iManufacturer 1 0x01
iProduct 2 0x02
iSerialNumber 3 0x03
bNumConfigurations 1 0x01
We're using the vendor ID and product id 0xffff because at this point we don't have any useful values for this (it costs $5,000 to register a vendor ID). This gives us a final byte array of:
0x12 0x01 0x00 0x02 0x00 0x00 0x00 0x40 (Early descriptor) 0xff 0xff 0xff 0xff 0x01 0x00 0x01 0x02 0x03 0x01 (and the rest)
We're reserving string ids 1, 2, and 3, for the manufacturer string, product name string, and serial number string respectively. I'm deliberately including them all so that we can see it all come out later in lsusb. If you feed the above hex sequence into a USB descriptor decoder then you can check my working.

Endpoint Descriptor We want a single configuration, which covers our one interface, with one endpoint in it. Let's start with the endpoint...
Our bulk IN endpoint
Field Name Value Bytes
bLength 7 0x07
bDescriptorType ENDPOINT 0x05
bEndpointAddress EP2IN 0x82
bmAttributes BULK 0x02
wMaxPacketSize 64 0x40 0x00
bInterval IGNORED 0x00
We're giving a single bulk IN endpoint, since that's the simplest thing to describe at this time. This endpoint will never be ready and so nothing will ever be read into the host. All that gives us:
0x07 0x05 0x82 0x02 0x40 0x00 0x00

Interface Descriptor The interface descriptor prefaces the endpoint set, and thanks to our simple single endpoint, and no plans for alternate interfaces, we can construct the interface simply as:
Our single simple interface
Field Name Value Bytes
bLength 9 0x09
bDescriptorType INTERFACE 0x04
bInterfaceNumber 1 0x01
bAlternateSetting 1 0x01
bNumEndpoints 1 0x01
bInterfaceClass 0 0x00
bInterfaceSubClass 0 0x00
bInterfaceProtocol 0 0x00
iInterface 5 0x05
All that gives us:
0x09 0x04 0x01 0x01 0x01 0x00 0x00 0x00 0x05

Configuration descriptor Finally we can put it all together and get the configuration descriptor...
Our sole configuration, encapsulating the interface and endpoint above
Field Name Value Bytes
bLength 9 0x09
bDescriptorType CONFIG 0x02
wTotalLength 9+9+7 0x19 0x00
bNumInterfaces 1 0x01
bConfigurationValue 1 0x01
iConfiguration 4 0x04
bmAttributes Bus powered, no wake 0x80
bMaxPower 500mA 0xfa
The wTotalLength field is interesting. It contains the configuration length, the interface length, and the endpoint length, hence 9 plus 9 plus 7 is 25. This gives:
0x09 0x02 0x19 0x00 0x01 0x01 0x04 0x80 0xfa

String descriptors We allowed ourselves a total of five strings, they were iManufacturer, iProduct, iSerial (from the device descriptor), iConfiguration (from the configuration descriptor), and iInterface (from the interface descriptor) respectively. Our string descriptors will therefore be:
String descriptor zero, en_GB only
Field Name Value Bytes
bLength 4 0x04
bDescriptorType STRING 0x03
wLangID[0] en_GB 0x09 0x08
0x04 0x03 0x09 0x08
...and...
String descriptor one, iManufacturer
Field Name Value Bytes
bLength 38 0x26
bDescriptorType STRING 0x03
bString "Rusty Manufacturer" ...
0x26 0x03 0x52 0x00 0x75 0x00 0x73 0x00 0x74 0x00 0x79 0x00 0x20 0x00 0x4d 0x00 0x61 0x00 0x6e 0x00 0x75 0x00 0x66 0x00 0x61 0x00 0x63 0x00 0x74 0x00 0x75 0x00 0x72 0x00 0x65 0x00 0x72 0x00
(You get the idea, there's no point me breaking down the rest of the string descriptors here, suffice it to say that the other strings are appropriate for the values they represent - namely product, serial, configuration, and interface.)

Putting it all together Given all the above, we have a device descriptor which is standalone, then a configuration descriptor which encompasses the interface and endpoint descriptors too. Finally we have a string descriptor table with six entries, the first is the language sets available, and the rest are our strings. In total we have:
    // Device descriptor
    const DEV_DESC: [u8; 18] =  
        0x12, 0x01, 0x00, 0x02, 0x00, 0x00, 0x00, 0x40,
        0xff, 0xff, 0xff, 0xff, 0x01, 0x00, 0x01, 0x02,
        0x03, 0x01
     ;
    // Configuration descriptor
    const CONF_DESC: [u8; 25] =  
        0x09, 0x02, 0x19, 0x00, 0x01, 0x01, 0x04, 0x80, 0xfa,
        0x09, 0x04, 0x01, 0x01, 0x01, 0x00, 0x00, 0x00, 0x05,
        0x07, 0x05, 0x82, 0x02, 0x40, 0x00, 0x00
     ;
    // String Descriptor zero
    const STR_DESC_0: [u8; 4] =  0x04, 0x03, 0x09, 0x08 ;
    // String Descriptor 1, "Rusty Manufacturer"
    const STR_DESC_1: [u8; 38] =  
        0x26, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x4d, 0x00,
        0x61, 0x00, 0x6e, 0x00, 0x75, 0x00, 0x66, 0x00,
        0x61, 0x00, 0x63, 0x00, 0x74, 0x00, 0x75, 0x00,
        0x72, 0x00, 0x65, 0x00, 0x72, 0x00
     ;
    // String Descriptor 2, "Rusty Product"
    const STR_DESC_2: [u8; 28] =  
        0x1c, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x50, 0x00,
        0x72, 0x00, 0x6f, 0x00, 0x64, 0x00, 0x75, 0x00,
        0x63, 0x00, 0x74, 0x00
     ;
    // String Descriptor 3, "123ABC"
    const STR_DESC_3: [u8; 14] =  
        0x0e, 0x03, 0x31, 0x00, 0x32, 0x00, 0x33, 0x00,
        0x41, 0x00, 0x42, 0x00, 0x43, 0x00
     ;
    // String Descriptor 4, "Rusty Configuration"
    const STR_DESC_4: [u8; 40] =  
        0x28, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x43, 0x00,
        0x6f, 0x00, 0x6e, 0x00, 0x66, 0x00, 0x69, 0x00,
        0x67, 0x00, 0x75, 0x00, 0x72, 0x00, 0x61, 0x00,
        0x74, 0x00, 0x69, 0x00, 0x6f, 0x00, 0x6e, 0x00
     ;
    // String Descriptor 5, "Rusty Interface"
    const STR_DESC_5: [u8; 32] =  
        0x20, 0x03, 0x52, 0x00, 0x75, 0x00, 0x73, 0x00,
        0x74, 0x00, 0x79, 0x00, 0x20, 0x00, 0x49, 0x00,
        0x6e, 0x00, 0x74, 0x00, 0x65, 0x00, 0x72, 0x00,
        0x66, 0x00, 0x61, 0x00, 0x63, 0x00, 0x65, 0x00
     ;
With the above, we're a step closer to our first prototype which will hopefully be enumerable. Next time we'll look at beginning our prototype low level USB device stack mock-up.

21 August 2017

Carl Chenet: Remind people about your great content using social networks with Remindr

Each time I remind people about one of my best blog posts, I do have positive reviews and a peak of traffic on my blog. But as an IT guy, I hate (so much) manually (gosh!) posting reminders of my articles on both my Twitter account and my Mastodon account. So I wrote Remindr. Each time you launch it, it posts a content through both Mastodon and Twitter. You can attach an image for each message and using different languages is managed for your different content is managed. Under the hood, it s a self hosted (my instance just runs on my workstation) Python 3 application released under the GPLv3 license. Going further with Remindr How does exactly Remindr work? Remindr iterates through a list of messages in a file you write and extract one line for each execution of Remindr, adding a user-defined prefix and send them to both the Mastodon and Twitter social networks. Here is the format of the file:
o en Automatically Send Toots To The Mastodon Social Network https://carlchenet.com/automatically-send-toots-to-the-mastodon-social-network/ #Mastodon
x fr Sur Mastodon, cr er son compte de secours  ou tout perdre https://carlchenet.com/sur-mastodon-creer-son-compte-de-secours-ou-tout-perdre/ #Mastodon
x en Automatically boost cool toots on Mastodon with the Boost bot https://carlchenet.com/automatically-boost-cool-toots-on-mastodon-with-the-boost-bot/ #Mastodon
x en Cryptocurrencies On the New Social Network Mastodon #Mastodon #bitcoin #ethereum #monero
The first field only indicates if the line is the next one to be considered by Remindr, the o indicates the next line to be sent. The second field is the 2-letters code language your content is using, in my example en or fr. Next content on the line will compose the body of your messages to Mastodon and Twitter. So each time you launch Remindr, one of the lines of your file will be sent to Mastodon and Twitter. How easy to use is that? and finally You can help me developing tools for Mastodon and other social networks by donating anything through Liberaypay (also possible with cryptocurrencies). Any contribution will be appreciated. That s a big factor motivation
Donate You also may follow my account @carlchenet on Mastodon  Carl Chenet On Mastodon

20 August 2017

Steinar H. Gunderson: Random codec notes

Post-Solskogen, there hasn't been all that many commits in the main Nageru repository, but that doesn't mean the project is standing still. In particular, I've been working with NVIDIA to shake out a crash bug in their drivers (which in itself uncovered some interesting debugging techniques, although in the end, the bug turned out just to be uncovered by the boring standard technique of analyzing crash dumps and writing a minimal program to reproduce). But I've also been looking at intraframe codecs; my sort-of plan was to go to VideoLAN Dev Days to present my findings, but unfortunately, there seems to be a schedule conflict, so instead, you can have some scattered random notes: Work in progress :-) Maybe something more coherent will come out eventually. Edit: Forgot about TF switching!

Dirk Eddelbuettel: RcppArmadillo 0.7.960.1.1

armadillo image On the heels of the very recent bi-monthly RcppArmadillo release comes a quick bug-fix release 0.7.960.1.1 which just got onto CRAN (and I will ship a build to Debian in a moment). There were three distinct issues I addressed in three quick pull requests: Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language--and is widely used by (currently) 382 other packages on CRAN---an increase of 52 since the CRAN release in June! Changes in this release relative to the previous CRAN release are as follows:

Changes in RcppArmadillo version 0.7.960.1.1 (2017-08-20)
  • Added improved check for inherited S4 matrix classes (#162 fixing #161)
  • Changed fastLm C++ function to fastLm_impl to not clash with R method (#164 fixing #163)
  • Added OpenMP check for configure (#166 fixing #165)

Courtesy of CRANberries, there is a diffstat report. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Vincent Bernat: IPv6 route lookup on Linux

TL;DR: With its implementation of IPv6 routing tables using radix trees, Linux offers subpar performance (450 ns for a full view 40,000 routes) compared to IPv4 (50 ns for a full view 500,000 routes) but fair memory usage (20 MiB for a full view).
In a previous article, we had a look at IPv4 route lookup on Linux. Let s see how different IPv6 is.

Lookup trie implementation Looking up a prefix in a routing table comes down to find the most specific entry matching the requested destination. A common structure for this task is the trie, a tree structure where each node has its parent as prefix. With IPv4, Linux uses a level-compressed trie (or LPC-trie), providing good performances with low memory usage. For IPv6, Linux uses a more classic radix tree (or Patricia trie). There are three reasons for not sharing:
  • The IPv6 implementation (introduced in Linux 2.1.8, 1996) predates the IPv4 implementation based on LPC-tries (in Linux 2.6.13, commit 19baf839ff4a).
  • The feature set is different. Notably, IPv6 supports source-specific routing1 (since Linux 2.1.120, 1998).
  • The IPv4 address space is denser than the IPv6 address space. Level-compression is therefore quite efficient with IPv4. This may not be the case with IPv6.
The trie in the below illustration encodes 6 prefixes: Radix tree For more in-depth explanation on the different ways to encode a routing table into a trie and a better understanding of radix trees, see the explanations for IPv4. The following figure shows the in-memory representation of the previous radix tree. Each node corresponds to a struct fib6_node. When a node has the RTN_RTINFO flag set, it embeds a pointer to a struct rt6_info containing information about the next-hop. Memory representation of a routing table The fib6_lookup_1() function walks the radix tree in two steps:
  1. walking down the tree to locate the potential candidate, and
  2. checking the candidate and, if needed, backtracking until a match.
Here is a slightly simplified version without source-specific routing:
static struct fib6_node *fib6_lookup_1(struct fib6_node *root,
                                       struct in6_addr  *addr)
 
    struct fib6_node *fn;
    __be32 dir;
    /* Step 1: locate potential candidate */
    fn = root;
    for (;;)  
        struct fib6_node *next;
        dir = addr_bit_set(addr, fn->fn_bit);
        next = dir ? fn->right : fn->left;
        if (next)  
            fn = next;
            continue;
         
        break;
     
    /* Step 2: check prefix and backtrack if needed */
    while (fn)  
        if (fn->fn_flags & RTN_RTINFO)  
            struct rt6key *key;
            key = fn->leaf->rt6i_dst;
            if (ipv6_prefix_equal(&key->addr, addr, key->plen))  
                if (fn->fn_flags & RTN_RTINFO)
                    return fn;
             
         
        if (fn->fn_flags & RTN_ROOT)
            break;
        fn = fn->parent;
     
    return NULL;
 

Caching While IPv4 lost its route cache in Linux 3.6 (commit 5e9965c15ba8), IPv6 still has a caching mechanism. However cache entries are directly put in the radix tree instead of a distinct structure. Since Linux 2.1.30 (1997) and until Linux 4.2 (commit 45e4fd26683c), almost any successful route lookup inserts a cache entry in the radix tree. For example, a router forwarding a ping between 2001:db8:1::1 and 2001:db8:3::1 would get those two cache entries:
$ ip -6 route show cache
2001:db8:1::1 dev r2-r1  metric 0
    cache
2001:db8:3::1 via 2001:db8:2::2 dev r2-r3  metric 0
    cache
These entries are cleaned up by the ip6_dst_gc() function controlled by the following parameters:
$ sysctl -a   grep -F net.ipv6.route
net.ipv6.route.gc_elasticity = 9
net.ipv6.route.gc_interval = 30
net.ipv6.route.gc_min_interval = 0
net.ipv6.route.gc_min_interval_ms = 500
net.ipv6.route.gc_thresh = 1024
net.ipv6.route.gc_timeout = 60
net.ipv6.route.max_size = 4096
net.ipv6.route.mtu_expires = 600
The garbage collector is triggered at most every 500 ms when there are more than 1024 entries or at least every 30 seconds. The garbage collection won t run for more than 60 seconds, except if there are more than 4096 routes. When running, it will first delete entries older than 30 seconds. If the number of cache entries is still greater than 4096, it will continue to delete more recent entries (but no more recent than 512 jiffies, which is the value of gc_elasticity) after a 500 ms pause. Starting from Linux 4.2 (commit 45e4fd26683c), only a PMTU exception would create a cache entry. A router doesn t have to handle those exceptions, so only hosts would get cache entries. And they should be pretty rare. Martin KaFai Lau explains:
Out of all IPv6 RTF_CACHE routes that are created, the percentage that has a different MTU is very small. In one of our end-user facing proxy server, only 1k out of 80k RTF_CACHE routes have a smaller MTU. For our DC traffic, there is no MTU exception.
Here is how a cache entry with a PMTU exception looks like:
$ ip -6 route show cache
2001:db8:1::50 via 2001:db8:1::13 dev out6  metric 0
    cache  expires 573sec mtu 1400 pref medium

Performance We consider three distinct scenarios:
Excerpt of an Internet full view
In this scenario, Linux acts as an edge router attached to the default-free zone. Currently, the size of such a routing table is a little bit above 40,000 routes.
/48 prefixes spread linearly with different densities
Linux acts as a core router inside a datacenter. Each customer or rack gets one or several /48 networks, which need to be routed around. With a density of 1, /48 subnets are contiguous.
/128 prefixes spread randomly in a fixed /108 subnet
Linux acts as a leaf router for a /64 subnet with hosts getting their IP using autoconfiguration. It is assumed all hosts share the same OUI and therefore, the first 40 bits are fixed. In this scenario, neighbor reachability information for the /64 subnet are converted into routes by some external process and redistributed among other routers sharing the same subnet2.

Route lookup performance With the help of a small kernel module, we can accurately benchmark3 the ip6_route_output_flags() function and correlate the results with the radix tree size: Maximum depth and lookup time Getting meaningful results is challenging due to the size of the address space. None of the scenarios have a fallback route and we only measure time for successful hits4. For the full view scenario, only the range from 2400::/16 to 2a06::/16 is scanned (it contains more than half of the routes). For the /128 scenario, the whole /108 subnet is scanned. For the /48 scenario, the range from the first /48 to the last one is scanned. For each range, 5000 addresses are picked semi-randomly. This operation is repeated until we get 5000 hits or until 1 million tests have been executed. The relation between the maximum depth and the lookup time is incomplete and I can t explain the difference of performance between the different densities of the /48 scenario. We can extract two important performance points:
  • With a full view, the lookup time is 450 ns. This is almost ten times the budget for forwarding at 10 Gbps which is about 50 ns.
  • With an almost empty routing table, the lookup time is 150 ns. This is still over the time budget for forwarding at 10 Gbps.
With IPv4, the lookup time for an almost empty table was 20 ns while the lookup time for a full view (500,000 routes) was a bit above 50 ns. How to explain such a difference? First, the maximum depth of the IPv4 LPC-trie with 500,000 routes was 6, while the maximum depth of the IPv6 radix tree for 40,000 routes is 40. Second, while both IPv4 s fib_lookup() and IPv6 s ip6_route_output_flags() functions have a fixed cost implied by the evaluation of routing rules, IPv4 has several optimizations when the rules are left unmodified5. Those optimizations are removed on the first modification. If we cancel those optimizations, the lookup time for IPv4 is impacted by about 30 ns. This still leaves a 100 ns difference with IPv6 to be explained. Let s compare how time is spent in each lookup function. Here is a CPU flamegraph for IPv4 s fib_lookup(): IPv4 route lookup flamegraph Only 50% of the time is spent in the actual route lookup. The remaining time is spent evaluating the routing rules (about 30 ns). This ratio is dependent on the number of routes we inserted (only 1000 in this example). It should be noted the fib_table_lookup() function is executed twice: once with the local routing table and once with the main routing table. The equivalent flamegraph for IPv6 s ip6_route_output_flags() is depicted below: IPv6 route lookup flamegraph Here is an approximate breakdown on the time spent:
  • 50% is spent in the route lookup in the main table,
  • 15% is spent in handling locking (IPv4 is using the more efficient RCU mechanism),
  • 5% is spent in the route lookup of the local table,
  • most of the remaining is spent in routing rule evaluation (about 100 ns)6.
Why does the evaluation of routing rules is less efficient with IPv6? Again, I don t have a definitive answer.

History The following graph shows the performance progression of route lookups through Linux history: IPv6 route lookup performance progression All kernels are compiled with GCC 4.9 (from Debian Jessie). This version is able to compile older kernels as well as current ones. The kernel configuration is the default one with CONFIG_SMP, CONFIG_IPV6, CONFIG_IPV6_MULTIPLE_TABLES and CONFIG_IPV6_SUBTREES options enabled. Some other unrelated options are enabled to be able to boot them in a virtual machine and run the benchmark. There are three notable performance changes:
  • In Linux 3.1, Eric Dumazet delays a bit the copy of route metrics to fix the undesirable sharing of route-specific metrics by all cache entries (commit 21efcfa0ff27). Each cache entry now gets its own metrics, which explains the performance hit for the non-/128 scenarios.
  • In Linux 3.9, Yoshifuji Hideaki removes the reference to the neighbor entry in struct rt6_info (commit 887c95cc1da5). This should have lead to a performance increase. The small regression may be due to cache-related issues.
  • In Linux 4.2, Martin KaFai Lau prevents the creation of cache entries for most route lookups. The most sensible performance improvement comes with commit 4b32b5ad31a6. The second one is from commit 45e4fd26683c, which effectively removes creation of cache entries, except for PMTU exceptions.

Insertion performance Another interesting performance-related metric is the insertion time. Linux is able to insert a full view in less than two seconds. For some reason, the insertion time is not linear above 50,000 routes and climbs very fast to 60 seconds for 500,000 routes. Insertion time Despite its more complex insertion logic, the IPv4 subsystem is able to insert 2 million routes in less than 10 seconds.

Memory usage Radix tree nodes (struct fib6_node) and routing information (struct rt6_info) are allocated with the slab allocator7. It is therefore possible to extract the information from /proc/slabinfo when the kernel is booted with the slab_nomerge flag:
# sed -ne 2p -e '/^ip6_dst/p' -e '/^fib6_nodes/p' /proc/slabinfo   cut -f1 -d:
   name            <active_objs> <num_objs> <objsize> <objperslab> <pagesperslab>
fib6_nodes         76101  76104     64   63    1
ip6_dst_cache      40090  40090    384   10    1
In the above example, the used memory is 76104 64+40090 384 bytes (about 20 MiB). The number of struct rt6_info matches the number of routes while the number of nodes is roughly twice the number of routes: Nodes The memory usage is therefore quite predictable and reasonable, as even a small single-board computer can support several full views (20 MiB for each): Memory usage The LPC-trie used for IPv4 is more efficient: when 512 MiB of memory is needed for IPv6 to store 1 million routes, only 128 MiB are needed for IPv4. The difference is mainly due to the size of struct rt6_info (336 bytes) compared to the size of IPv4 s struct fib_alias (48 bytes): IPv4 puts most information about next-hops in struct fib_info structures that are shared with many entries.

Conclusion The takeaways from this article are:
  • upgrade to Linux 4.2 or more recent to avoid excessive caching,
  • route lookups are noticeably slower compared to IPv4 (by an order of magnitude),
  • CONFIG_IPV6_MULTIPLE_TABLES option incurs a fixed penalty of 100 ns by lookup,
  • memory usage is fair (20 MiB for 40,000 routes).
Compared to IPv4, IPv6 in Linux doesn t foster the same interest, notably in term of optimizations. Hopefully, things are changing as its adoption and use at scale are increasing.

  1. For a given destination prefix, it s possible to attach source-specific prefixes:
    ip -6 route add 2001:db8:1::/64 \
      from 2001:db8:3::/64 \
      via fe80::1 \
      dev eth0
    
    Lookup is first done on the destination address, then on the source address.
  2. This is quite different of the classic scenario where Linux acts as a gateway for a /64 subnet. In this case, the neighbor subsystem stores the reachability information for each host and the routing table only contains a single /64 prefix.
  3. The measurements are done in a virtual machine with one vCPU and no neighbors. The host is an Intel Core i5-4670K running at 3.7 GHz during the experiment (CPU governor set to performance). The benchmark is single-threaded. Many lookups are performed and the result reported is the median value. Timings of individual runs are computed from the TSC.
  4. Most of the packets in the network are expected to be routed to a destination. However, this also means the backtracking code path is not used in the /128 and /48 scenarios. Having a fallback route gives far different results and make it difficult to ensure we explore the address space correctly.
  5. The exact same optimizations could be applied for IPv6. Nobody did it yet.
  6. Compiling out table support effectively removes those last 100 ns.
  7. There is also per-CPU pointers allocated directly (4 bytes per entry per CPU on a 64-bit architecture). We ignore this detail.

19 August 2017

Holger Levsen: 20170819-lasercutter-sprint

laser-cutter sprint So I'm overcoming my jetlag after DebConf17 by helping to make the Alioth sprint happen, and while it's good to witness work on the upcoming git.debian.org replacement, I'm rather minding my own business instead of getting involved And so I got interested in this laser cutter, which since two months has been set up in the CCCHH hackerspace and which is nicely documentend (and set up), so I managed to learn how to do my first baby steps with the laser cutter in one evening: Basically there is a hosted web application named 'LaserWeb4' for which a pre-configuration exists, so that one only needs to load an image, scale and position it and tune the laser settings a bit. The laser itself is inside a cage, which has a physical safety switch which will turn off the laser if the cage is opened. Obviously the setup is a lot more complex and there are many parameters to tune, and I basically just learned one thing, which is "printing images on wood", but "printing images on a laptop cover" should be pretty similar and something to learn in the future ;-) And now I'm even teaching weasel how to use this thing (and he already made interesting new mistakes) and it looks like Ganneff & formorer are next. Fun fun fun! Oh, and the Alioth sprint also seems to be quite productive, but I'll leave reporting about this to others.

Vasudev Kamath: Writing a UDP Broadcast Receiver as Python Iterator

I had to write a small Python application to listen for some broadcast message and process the message. This broadcast messages are actually sort of discovery messages to find some peers in a network. Writing a simple UDP Server to listen on a particular port was easy; but while designing an application I was wondering how can I plugin this server into my main code. There are 2 possibility
  1. Use threading module of python to send the server code in back ground and give it a callback to communicate the data to main thread.
  2. Periodically read some messages from server code and then dispose of server.
I didn't like first approach because I need to pass a callback function and I some how will end up complicating code. Second approach sounded sane but I did want to make server more like iterator. I searched around to see if some one has attempted to write something similar, but did not find anything useful (may be my Googling skills aren't good enough). Anyway so I thought what is wrong in trying?. If it works then I'll be happy that I did something different :-). The first thing for making iterator in Python is having function __iter__ and __next__ defined in your class. For Python 2 iterator protocol wanted next to be defined instead of __next__. So for portable code you can define a next function which in return calls __next__. So here is my first shot at writing BroadCastReceiver class.
from socket import socket, AF_INET, SOCK_DGRAM
class BroadCastReceiver:
    def __init__(self, port, msg_len=8192):
        self.sock = socket(AF_INET, SOCK_DGRAM)
        self.sock.setsockopt(SOL_SOCKET, SO_REUSEADDR, 1)
        self.sock.bind(('', port))
        self.msg_len = msg_len
    def __iter__(self):
             return self
    def __next__(self):
             try:
                 addr, data = self.sock.recvfrom(self.msg_len)
                 return addr, data
             except Exception as e:
                 print("Got exception trying to recv %s" % e)
                 raise StopIteration
This version of code can be used in a for loop to read from socket UDP broadcasts. One problem will be that if no packet is received which might be due to disconnected network the loop will just block forever. So I had to modify the code slightly to add timeout parameter. So changed portion of code is below.
...
    def __init__(self, port, msg_len=8192, timeout=15):
        self.sock = socket(AF_INET, SOCK_DGRAM)
        self.sock.setsockopt(SOL_SOCKET, SO_REUSEADDR, 1)
        self.sock.settimeout(timeout)
        self.sock.msg_len = msg_len
        self.sock.bind(('', port))
 ...
So now if network is disconnected or no packet was received for timeout period we get a socket.timeout exception due to which StopIteration will be raised causing the for loop using server as iterator to exit. This avoids us just blocking our periodic code run forever when network is disconnected or no messages are received for long time. (may be due to connected to wrong network). Now every thing looks fine but only part is if we create the server object each time our periodic code is called we will have binding issue as we did not properly close the socket once iterator has stopped. So I added socket closing code in __del__ function for the class. __del__ will be called when garbage collector try to recollect object when it goes out of scope.
...
    def __del__(self):
        self.sock.close()
So the server can be used in for loop or by passing the object of server to next built-in function. Here are 2 examples.
r = BroadCastReceiver(5000, timeout=10)
count = 0
for (address, data) in r:
    print('Got packet from %s: %s' % address, data)
    count += 1
    # do whatever you want with data
    if count > 10:
        break
Here we use an counter variable to track iteration and after some iteration we exit for loop. Another way is use for loop with range of iteration like below.
r = BroadCastReceiver(5000,  timeout=10)
for i in range(20):
    try:
        address, data = next(r)
        # do whatever you want with data
    except:
        break
Here an additional try block was needed inside the for loop to card call to next, this is to handle the timeout or other exception and exit the loop. In first case this is not needed as StopIteration is understood by for. Both use cases I described above are mostly useful when it is not critical to handle each and every packet (mostly peer discovery) and packets will always be sent. So if we miss some peers in one iteration we will still catch them in next iteration. We just need to make sure we provide big enough counter to catch most peers in each iteration. If its critical to receive each packet we can safely send this iterating logic to a separate thread which keeps receiving packets and process data as needed. For now I tried this pattern mostly with UDP protocol but I'm sure with some modification this can be used with TCP as well. I'll be happy to get feed back from Pythonistas out there on what you think of this approach. :-)
Update I got a suggestion from Ryan Nowakowski to make the server object as context manager and close the socket in __exit__ as it can't be guaranteed that __del__ will be called for objects which exists during interpreter exits. So I slightly modified the class to add __enter__ and __exit__ method like below and removed __del__
...
    def __enter__(self):
        return self
    def __exit__(self, exc_type, exc_value, traceback):
        self.sock.close()
Usage pattern is slightly modified because of this and we need to use with statement while creating object.
with BroadCastReceiver(2000) as r:
    # use server object as you wish
    ...
It is also possible to cleanly close socket without adding context manager that is adding finally statement to our try and except block in __next__. The modified code without adding context manager looks like below.
def __next__(self):
    try:
        addr, data = self.sock.recvfrom(self.msg_len)
        return addr, data
    except Exception as e:
        print("Got exception trying to recv %s" % e)
        raise StopIteration
    finally:
        self.sock.close()
When we raise StopIteration again from except block, it will be temporarily saved and finally block is executed which will now close the socket.

Olivier Gr goire: Conclusion Google Summer of Code 2017 with GNU

alt text alt text alt text

GNU Ring project with GNU organisation

1. Me Before getting into the thick of my project, let me present myself:
I am Olivier Gr goire (Gasuleg), and I study IT engineering at cole de Technologie Sup rieure in Montreal.
I am a technician in electronics, and I study now computing sciences.
I applied to GSoC because I love the concept of the project that I worked on and I really wanted to be part of it.

2. My Project During this GSoC, I worked on the GNU Ring project.
What is ring?
  • A telephone: a simple tool to connect, communicate and share.
  • A teleconferencing tool: easily join calls to create conferences with multiple participants.
  • A media sharing tool: Ring supports a variety of video input options, including mutliple cameras and image and video files, and the selection of audio inputs and outputs; all this is supported by multiple high quality audio and video codecs.
  • A messenger: send text messeges during calls or out of calls (as long as your peer is connected).
  • A building block for your IoT project: re-use the universal communications technology of Ring with its portable library on your system of choice.
    ring.cx
What I need to do?
This project is, at the moment, unstable due to a lack of automated tests. Only a part of the code is tested. I need to improve this.
To do that, I need to:
  • Research and test automation strategies that integrate the compilation system and Jenkins verification like the SIP tests
  • Implement some unit tests to check the components
See more in my proposal!

3. The Code Links to my work
Here are the links to the code I was working on all throughout the Google Summer of Code:
Patch Status
Black box testing sip Merged
New unit test: smartools Merged
New unit test:account_factory Merged
New unit test: util classes On Review
New unit test: archiver, conference, preferences On Review
New unit test: dring, threadloop On Review
Documentation On Review
Refactoring + video_input unit test Abandoned


How to use the code?
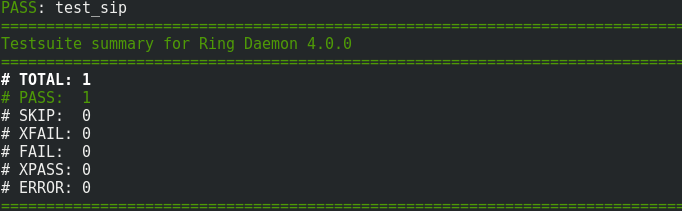
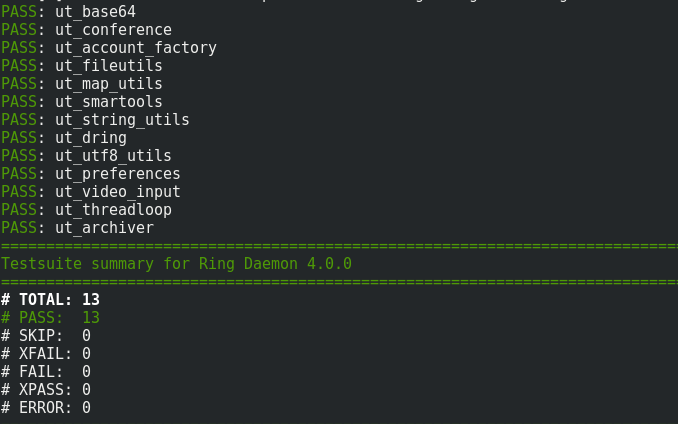
Follow the instructions to build the daemon and instead of doing make , do make check . You will see something composed of:

  • Test automation strategies
    alt text
  • Unit test alt text
Some explanations of the code
The tests are based on CPPunit framework.
I created some Black box testing to do some calls using SIP protocol. To do that, I created scenarios using SIPp .
I also create a lot of unit tests.
Difficulties encountered
My project was a little bit difficult to setup because I never touch autotools before that.
The sip tests were not really difficult to create. SIPp is really easy to use.
The unit test part was more tricky. It s really easier to do the tests before coding like the Test-driven_development said. Here the code is already written and I need to test it. So, I needed to create tests based on the code and not what he needed to do. Also, I got some issues with classes who were really linked together so I couldn t make unit test with it.

4. What s next?
  • Merge all the patchs
  • Add gcov to know the code coverage
  • Increase the code coverage

5. Thanks I would like to thank the following:
  • The Google Summer of Code organisation, for this wonderful experience.
  • GNU, for accepting my project proposal and letting me embark on this fantastic adventure.
  • My mentor, Mr Guillaume Roguez, and all the ring team, for being there to help me.

Arturo Borrero Gonz lez: Running Suricata 4.0 with Debian Stretch

debian-suricata logo Do you know what s happening in the wires of your network? There is a major FLOSS player in the field of real time intrusion detection (IDS), inline intrusion prevention (IPS) and network security monitoring (NSM). I m talking about Suricata, a mature, fast and robust network threat detection engine. Suricata is a community driven project, supported by the Open InfoSec Foundation (OISF). For those who doesn t know how Suricata works, it usually runs by loading a set of pre-defined rules for matching different network protocols and flow behaviours. In this regards, Suricata has been always ruleset-compatible with the other famous IDS: snort. The last major release of Suricata is 4.0.0, and I m uploading the package for Debian stretch-backports as I write this line. This means the updated package should be available for general usage after the usual buildds processing ends inside the Debian archive. You might be wondering, How to start using Suricata 4.0 with Debian Stretch? First, I would recommend reading the docs. Please checkout: My recommendation is to run Suricata from stretch-backports or from testing, and just installing the package should be enough to get the environment up and running:
% sudo aptitude install suricata
You can check that the installation was good:
% sudo systemctl status suricata
  suricata.service - Suricata IDS/IDP daemon
   Loaded: loaded (/lib/systemd/system/suricata.service; enabled; vendor preset: enabled)
   Active: active (running) since Sat 2017-08-19 12:50:49 CEST; 44min ago
     Docs: man:suricata(8)
           man:suricatasc(8)
           https://redmine.openinfosecfoundation.org/projects/suricata/wiki
 Main PID: 1101 (Suricata-Main)
    Tasks: 8 (limit: 4915)
   CGroup: /system.slice/suricata.service
            1101 /usr/bin/suricata -D --af-packet -c /etc/suricata/suricata.yaml --pidfile /var/run/suricata.pid
ago 19 12:50:44 nostromo systemd[1]: Starting Suricata IDS/IDP daemon...
ago 19 12:50:47 nostromo suricata[1032]: 19/8/2017 -- 12:50:47 - <Notice> - This is Suricata version 4.0.0 RELEASE
ago 19 12:50:49 nostromo systemd[1]: Started Suricata IDS/IDP daemon.
You can interact with Suricata using the suricatasc tool:
% sudo suricatasc -c uptime
 "message": 3892, "return": "OK" 
And start inspecting the generated logs at /var/log/suricata/ The default configuration, in file /etc/suricata/suricata.yaml, comes with some preconfigured values. For a proper integration into your enviroment, you should tune the configuration file, define your networks, network interfaces, running modes, and so on (refer to the upstream documentation for this). In my case, I tested suricata by inspecting the traffic of my laptop. After installation, I only had to switch the network interface:
[...]
# Linux high speed capture support
af-packet:
  - interface: wlan0
[...]
After a restart, I started seeing some alerts:
% sudo systemctl restart suricata
% sudo tail -f /var/log/suricata/fast.log
08/19/2017-14:03:04.025898  [**] [1:2012648:3] ET POLICY Dropbox Client Broadcasting [**] \
	[Classification: Potential Corporate Privacy Violation] [Priority: 1]  UDP  192.168.1.36:17500 -> 255.255.255.255:17500
One of the main things when running Suricata is to keep your ruleset up-to-dated. In Debian, we have the suricata-oinkmaster package which comes with some handy options to automate your ruleset updates using the Oinkmaster software. Please note that this is a Debian-specific glue to integrate and automate Suricata with Oinkmaster. To get this funcionality, simply install the package:
% sudo aptitude install suricata-oinkmaster
A daily cron-job will be enabled. Check suricata-oinkmaster-updater(8) for more info. By the way, Did you know that Suricata can easily handle big loads of traffic? (i.e, 10Gbps). And I heard some scaling works are in mind to reach 100Gpbs. I have been in charge of the Suricata package in Debian for a while, several years already, with the help of some other DD hackers: Pierre Chifflier (pollux) and Sascha Steinbiss (satta), among others. Due to this work, I believe the package is really well integrated into Debian, ready to use and with some powerful features. And, of course, we are open to suggestions and bug reports. So, this is it, another great stuff you can do with Debian :-)

18 August 2017

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, July 2017

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In July, about 181 work hours have been dispatched among 11 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours increased slightly with two new sponsors: Leibniz Rechenzentrum (silver sponsor) and Catalyst IT Ltd (bronze sponsor). The security tracker currently lists 74 packages with a known CVE and the dla-needed.txt file 64. The number of packages with open issues increased of almost 50% compared to last month. Hopefully this backlog will get cleared up when the unused hours will actually be done. In any case, this evolution is worth watching. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Mike Gabriel: @DebConf17: Ad-hoc BoF: Bits from the Debian+Ubuntu MATE Packaging Team

On Tuesday, late afternoon, at DebConf17, I offered an ad-hoc BoF about the current status of the MATE Desktop packaging efforts in Debian and Ubuntu. I need to get this written down, before DebConf17 feels too far away... Unfortunately, I scheduled that BoF with Joey Hess's talk about his post-Debian life, which attracted many people. So, only a small group of people came together to share and discuss about the current status of MATE in Debian and Ubuntu. Ongoing efforts around MATE in Debian and Ubuntu A quick summary of ongoing efforts was provided and also a collection of URLs for reporting bugs, looking up packaging status, etc. was listed: Cross-Distro Packaging Workflow The workflow of Debian and Ubuntu packaging in the MATE Packaging Team was described in detail (basically, all packages go through Debian, only exception being freeze states of this or that distro) and the benefit of the close cooperation between the two projects underlined. We reduce the packaging effort tremendously by working very closely together. In the past, we (Martin Wimpress and myself) also invited the people from Linux Mint to join our cross-distro packaging efforts, but so far to no avail. Also the packaging for the Parrot Security OS has recently been integrated in our packaging Git repository. Requested / Upcoming Improvements From people attending the BoF, I got these main inputs, which I hope to accomplish with the help of all, for Debian buster: Another project that I will also work on for Debian buster is proper Ayatana Indicator support for Debian's MATE Desktop. Credits Thanks to all the people attending the BoF for your sharings and input. Feel invited to contribute to our team's effort in improving the user experience of the MATE Destkop Environment in Debian (and Ubuntu, and ...). Also a big thanks to the people already on the team for bringing MATE in Debian to where it is now. Good work, folks!

Dirk Eddelbuettel: RcppArmadillo 0.7.960.1.0

armadillo image The bi-monthly RcppArmadillo release is out with a new version 0.7.960.1.0 which is now on CRAN, and will get to Debian in due course. And it is a big one. Lots of nice upstream changes from Armadillo, and lots of work on our end as the Google Summer of Code project by Binxiang Ni, plus a few smaller enhancements -- see below for details. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language--and is widely used by (currently) 379 other packages on CRAN---an increase of 49 since the last CRAN release in June! Changes in this release relative to the previous CRAN release are as follows:

Changes in RcppArmadillo version 0.7.960.1.0 (2017-08-11)
  • Upgraded to Armadillo release 7.960.1 (Northern Banana Republic Deluxe)
    • faster randn() when using OpenMP (NB: usually omitted when used fromR)
    • faster gmm_diag class, for Gaussian mixture models with diagonal covariance matrices
    • added .sum_log_p() to the gmm_diag class
    • added gmm_full class, for Gaussian mixture models with full covariance matrices
    • expanded .each_slice() to optionally use OpenMP for multi-threaded execution
  • Upgraded to Armadillo release 7.950.0 (Northern Banana Republic)
    • expanded accu() and sum() to use OpenMP for processing expressions with computationally expensive element-wise functions
    • expanded trimatu() and trimatl() to allow specification of the diagonal which delineates the boundary of the triangular part
  • Enhanced support for sparse matrices (Binxiang Ni as part of Google Summer of Code 2017)
    • Add support for dtCMatrix and dsCMatrix (#135)
    • Add conversion and unit tests for dgT, dtT and dsTMatrix (#136)
    • Add conversion and unit tests for dgR, dtR and dsRMatrix (#139)
    • Add conversion and unit tests for pMatrix and ddiMatrix (#140)
    • Rewrite conversion for dgT, dtT and dsTMatrix, and add file-based tests (#142)
    • Add conversion and unit tests for indMatrix (#144)
    • Rewrite conversion for ddiMatrix (#145)
    • Add a warning message for matrices that cannot be converted (#147)
    • Add new vignette for sparse matrix support (#152; Dirk in #153)
    • Add support for sparse matrix conversion from Python SciPy (#158 addressing #141)
  • Optional return of row or column vectors in collapsed form if appropriate #define is set (Serguei Sokol in #151 and #154)
  • Correct speye() for non-symmetric cases (Qiang Kou in #150 closing #149).
  • Ensure tests using Scientific Python and reticulate are properly conditioned on the packages being present.
  • Added .aspell/ directory with small local directory now supported by R-devel.

Courtesy of CRANberries, there is a diffstat report. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

17 August 2017

Sean Whitton: DebCamp/DebConf17: reports on sprints and BoFs

In addition to my personal reflections on DebCamp/DebConf17, here is a brief summary of the activities that I had a hand in co-ordinating. I won t discuss here many other small items of work and valuable conversations that I had during the two weeks; hopefully the fruits of these will show themselves in my uploads to the archive over the next year. Debian Policy sprint & BoF Debian Emacs Team meeting/sprint Unfortunately we didn t make any significant progress towards converting all addons to use dh_elpa, as the work is not that much fun. Might be worth a more focused sprint next year. Report on team website Git for Debian packaging BoF & follow-up conversations The BoF was far more about dgit than I had wanted; however, I think that this was mostly because people had questions about dgit, rather than any unintended lecturing by me. I believe that several people came away from DebConf thinking that starting to use dgit would improve Debian for themselves and for users of their packages.

Reproducible builds folks: Reproducible Builds: Weekly report #120

Here's what happened in the Reproducible Builds effort between Sunday 6th and Saturday 12th August 2017: Notes about reviews of unreproducible packages 13 package reviews have been added, 7 have been updated and 34 have been removed in this week, adding to our knowledge about identified issues. Packages reviewed and fixed, and reproducibility related bugs filed Upstream packages: Other bugs filed diffoscope development trydiffoscope development tests.reproducible-builds.org Misc. This week's edition was written by Chris Lamb & Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Shirish Agarwal: Composers are not given due recognition

Update Some youtube links are not viewable or even seen on planet.debian.org. Seems p.d.o. tries its best to remove external links, sorry for the breakage. Beware some youtube-links would be shared in this entry, sorry couldn t find a better/easier media platform to work with. If anyone knows any other platform or wants to suggest, feel free to either mail me or let me know in comments. I want to start today s sharing with a picture of Ganesha I saw today. It is and was public art hence sharing it without an issue. Sketch of Ganesha/Ganapati This is starting of festivities time in India and Ganesha or Ganpati is looked up as a good omen in India. The festival of Ganesh Chaturthi would be starting on the 25th of August and is a sight to behold. Just like Rio has its carnival, Ganesh Chaturthi is also a carnival. We also have parades where people come with Pandals (or temporary structures) The mythology says he has a sweet tooth (hence lot of distribution of sweets, especially modak) and anything which might be troubling people, he creates solutions for them. Here is one video of how people celebrate his immersion in India. This is from my home-town few years ago, every year the madness and the celebrations are becoming more and more. People from far off come to see how we celebrate and see how different people make their Pandals. While some are with music, others are with social messages. Usually people start going to see these structures after dusk and return home way after midnight or early morning. I hope to do this endeavour after many years. One is drunk from hearing all sorts of different kids of music, decoration, messages, a feast and a strain to all the senses. Ganesha immersion celebrations https://www.youtube.com/watch?v=hjWfpGUryho If one is interested one can find more info. at https://en.wikipedia.org/wiki/Ganesh_Chaturthi After quite a bit of time, I wrote an article about various foss internships which I knew besides GSOC over the years. I finally penned them down at https://itsfoss.com/best-open-source-internships/ Interestingly, I was amazed to see that all FOSS U.S. projects (outside of GSOC) are for students who are either living or studying in U.S. and have a student work visa (which from private discussions I came to know is lot harder to get nowadays than before). Except for the National Science Foundation (NSF) which probably has U.S. defence relations and hence they might be sensitive, I fail to understand other institutes preferences for only getting people from the U.S. and hence having a lesser talent pool of people. This also affects the growth of the projects themselves. Just think how limited Debian would have been if it had decided to only have people from only any one community develop it. Dunno if this is due to the present President Trump or these policies had been there before. It would be nice and interesting if people in the know can share. What has also been interesting to watch is Mr. Trump blaming low-cost manufacturing centres like India and China when as far as I recall, lot of manufacturing, specifically auto-mobiles manufacturing was shifted out of the U.S. to Ireland and other places years before which are relatively high-cost places (at least compared to India). I *believe* the change was as early as in 1980 s itself where India was insulated and had a limited market for everything (similar to Russian communism as shown in popular media but not so bad.) Interestingly, it took almost a month for the perl 2.56 to make the transition smoothly. It took quite a bit of time for all the components to work together and be installable. Also saw this few days back http://fortune.com/2017/04/12/auto-industry-decline/ While Tesla is expensive even by American standards the idea of lesser parts, lesser complexity and hence lower costs to use, maintain is good. I do hope that he and his team or any of the competitors do overcome the significant challenges. Any significant improvement in battery technology is bound to have huge impact in almost everything that is used in 21st century. Two recent articles tell me the future may become present very quickly. https://www.purdue.edu/newsroom/releases/2017/Q2/instantly-rechargeable-battery-could-change-the-future-of-electric-and-hybrid-automobiles.html Toyota could finally start mass producing electric cars thanks to China I do hope to see EV being prevalent before the next decade is over otherwise we don t have any hope due to climate change. As for my health, I am much better than before. Just to share some stats, before my illness for lack of better word, I was 120 kgs. , when I was kept in the hospital for about 2-2.5 weeks I came down to 95 kgs. and now back upto 108 kgs. Do go for exercising every other day and trying to get back the strength, stamina and increasing a bit of both. Doctors have given me another 4-5 months after which a brain scan will reveal if there are any remaining blood clots in the brain or not. Lastly, while it has become somewhat of a sensitive issue to love Muslims or to talk about their work in any field in the current political climate, there are 4-5 music pieces I listen whenever I can, especially before going to bed. While almost all the pieces have been sung and written by Muslims, sadly I don t know who the composers of these beautiful songs are. While it is much easier to get the names of the singer and the lyricist, one of the more important roles in my view is the composer or/and music arranger. Without them, the songs would not have the same haunting quality that the songs have. While I have been lucky to find the names of the composer/music arranger for the pieces below but this is not the case if and when the songs comes on television. I do remember in old times at least on Radio they used to mention about who has given the music as well, dunno in modern times. I am sharing the songs, and hopefully will also share the translations if I find on the web, please see the lyrics. The numbering is for convenience only and am torn in these 4-5 songs which is the best. Just to share these are all sufi love songs except the last one which I am sharing. 1. Lyrical song https://www.youtube.com/watch?v=ehqN6oTpmb8 Translation with video of song http://www.bollynook.com/en/lyrics/6443/aaj-din-chadheya/ While there probably are stories with each song, I was lucky to find the story about this one. The lyrics of the song are actually a love lost Punjabi poet who writes in the memory of his beloved to which he could not marry and he pens those when standing in line for his liquor. The story goes on that he marries a girl later in life who bears a resemblance to his beloved whom he couldn t forget till his dying day. 2. Lyrical song https://www.youtube.com/watch?v=uTC_2c83qn0 The same song has been sung by different people and I love them all the more for it. Another video https://www.youtube.com/watch?v=3G7Qg4LJ7WE Another video https://www.youtube.com/watch?v=kOsvNuR3m5Y Translation http://www.bollynook.com/en/lyrics/10703/o-re-piya/ 3. Lyrical song https://www.youtube.com/watch?v=qG7Kms_YA5Q The translation http://www.filmyquotes.com/songs/885 The translation of the song is a bit crude but then translations are supposed to be crude  Anyways, the above song is what would be called a perfect Sufi song. I hope people enjoy the longing and the silence which follows this piece. Another classic one 4. Lyrical song https://www.youtube.com/watch?v=Ube5XhN_lpM English translation http://www.ardhamy.com/song/aye-dil-e-naadan While the song is from the movie Razia Sultana and was a flop as the movie was about Race and controversial then as it probably would be now. As seen in the other songs of the same genre, it has strands of longing, loneliness as seen of the above. 5. Lyrical song https://www.youtube.com/watch?v=tv242qOnHJA This one is not a sufi song but I love all the women and the girls and the way they enhanced the song. I dunno how much they must have practised as it s a very fast and peppy song and doesn t give time to the singer to breathe except for that one section which has a bit of Carnatic music. At the very end I would like to share http://www.globalrhythm.net/ I have found some interesting sounds on the site. Hope the site enriches you as well. FWIW I have no links with the site except as somebody who likes to diversify his music listening. Lastly, for a long period of time, I had been hearing the criticism, especially for FOSS games that they don t have AAA quality assets. Recently I came across a game called Starship Theory (sadly its only for MS-Windows) Game video https://www.youtube.com/watch?v=imaL2pjNURg You look at the game and see the number of videos the guy has made. What FOSS game developers can learn from this, you don t need high-end 2.5/3d models, clipart will do but need depth in gameplay which can make FOSS games be popular and also earn a pretty bundle. I do hope some FOSS game upstream developers take note and use that game s inspiration to bring more depth. That doesn t mean games like 0ad are not liked by people but it takes huge amount of time and resources. 0ad video https://www.youtube.com/watch?v=DHx5XBtypcQ Hope you have a good time with all the ideas, anecdotes and videos I shared above.
Filed under: Miscellenous Tagged: #FOSS Internships, #Ganesh Chaturthi, #Ganeshji, #planet-debian, #Sufi Bollywood Music, FOSS, FOSS games, politics

Bits from Debian: Work on Debian for mobile devices continues

Work on Debian for mobile devices, i.e. telephones, tablets, and handheld computers, continues. During the recent DebConf17 in Montr al, Canada, more than 50 people had a meeting to reconsider opportunities and challenges for Debian on mobile devices. A number of devices were shown at DebConf: photo of Samsung, Pyra, N900, ZeroPhone, GnuK, and PocketCHIP - click to enlarge The photo (click to enlarge) shows all four devices, together with a Nokia N900, which was the first Linux-based smartphone by Nokia, running Debian-based Maemo and a completely unrelated Gnuk cryptographic token, which just sneaked into the setting. If you like to participate, please

16 August 2017

Simon McVittie: DebConf 17: Flatpak and Debian

The indoor garden at Coll ge de Maisonneuve, the DebConf 17 venue
Decorative photo of the indoor garden
I'm currently at DebConf 17 in Montr al, back at DebConf for the first time in 10 years (last time was DebConf 7 in Edinburgh). It's great to put names to faces and meet more of my co-developers in person! On Monday I gave a talk entitled A Debian maintainer's guide to Flatpak , aiming to introduce Debian developers to Flatpak, and show how Flatpak and Debian (and Debian derivatives like SteamOS) can help each other. It seems to have been quite well received, with people generally positive about the idea of using Flatpak to deliver backports and faster-moving leaf packages (games!) onto the stable base platform that Debian is so good at providing. A video of the talk is available from the Debian Meetings Archive. I've also put up my slides in the DebConf git-annex repository, with some small edits to link to more source code: A Debian maintainer's guide to Flatpak. Source code for the slides is also available from Collabora's git server. The next step is to take my proof-of-concept for building Flatpak runtimes and apps from Debian and SteamOS packages, flatdeb, get it a bit more production-ready, and perhaps start publishing some sample runtimes from a cron job on a Debian or Collabora server. (By the way, if you downloaded that source right after my talk, please update - I've now pushed some late changes that were necessary to fix the 3D drivers for my OpenArena demo.) I don't think Debian will be going quite as far as Endless any time soon: as Cosimo outlined in the talk right before mine, they deploy their Debian derivative as an immutable base OS with libOSTree, with all the user-installable modules above that coming from Flatpak. That model is certainly an interesting thing to think about for Debian derivatives, though: at Collabora we work on a lot of appliance-like embedded Debian derivatives, with a lot of flexibility during development but very limited state on deployed systems, and Endless' approach seems a perfect fit for those situations. [Edited 2017-08-16 to fix the link for the slides, and add links for the video]

Ross Gammon: My Debian & Ubuntu work from April to mid-August 2017

Okay, so I have been slack with my blogging again. I have been travelling around Europe with work quite a bit, had a short holiday over Easter in Denmark, and also had 3 weeks of Summer Holiday in Germany. Debian
  • Tidied up the packaging and tried building the latest version of libdrumstick, but tests had been added to the package by upstream which were failing. I still need to get back and investigate that.
  • Updated node-seq (targeted at experimental due to the Debian Stretch release freeze) and asked for sponsorship (as I did not have DM rights for it yet).
  • Uploaded the latest version of abcmidi (also to experimental), and again.
  • Updated node-tmp to the latest version and uploaded to experimental.
  • Worked some more on bluebird RFP, but getting errors when running tests. I still haven t gone back to investigate that.
  • Updated node-coffeeify to the latest version and uploaded to experimental.
  • Uploaded the latest version of node-os-tmpdir (also to experimental).
  • Uploaded the latest version of node-concat-stream (also to experimental).
  • After encouragement from several Debian Developers, I applied to become a full Debian Developer. Over the summer months I worked with Santiago as my Application Manager and answered questions about working in the Debian Project.
  • A web vulnerability was identified in node-concat-stream, so I prepared a fix to the version in unstable, uploaded it to unstable, and submitted a unblock request bug so that it would be fixed in the coming Debian Stretch release.
  • Debian 10 (Stretch) was released! Yay!
  • Moved abcmidi from experimental to unstable, adding an autopkgtest at the same time.
  • Moved node-concat-stream from experimental to unstable. During the process I had to take care of the intermediate upload to stretch (on a separate branch) because of the freeze.
  • Moved node-tmp to unstable from experimental.
  • Moved node-os-tmpdir from experimental to unstable.
  • Filed a removal bug for creepy, which seems to be unmaintained upstream these days. Sent my unfinished Qt4 to Qt5 porting patches upstream just in case!
  • Uploaded node-object-inspect to experimental to check the reverse dependencies, then moved it to unstable. Then a new upstream version came out which is now in experimental waiting for a retest of reverse dependencies.
  • Uploaded the latest version of gramps (4.2.6).
  • Uploaded a new version of node-cross-spawn to experimental.
  • Discovered that I had successfully completed the DD application process and I was now a Debian Developer. I celebrated by uploading the Debian Multimedia Blends package to the NEW queue, which I was not able to do before!
  • Tweaked and uploaded the node-seq package (with an RC fix) which had been sitting there because I did not have DM rights to the package. It is not an important package anyhow, as it is just one of the many dependencies that need to be packaged for Browserify.
  • Packaged and uploaded the latest node-isarray directly to unstable, as the changes seemed harmless.
  • Prepared and uploaded the latest node-js-yaml to experimental.
  • Did an update to the Node packaging Manual now that we are allowed to use node as the executable in Debian instead of nodejs which caused us to do a lot of patching in the past to get node packages working in Debian.
Ubuntu
  • Did a freeze exception bug for ubuntustudio-controls, but we did not manage to get it sponsored before the Ubuntu Studio Zesty 17.04 release.
  • Investigated why Ardour was not migrating from zesty-proposed, but I couldn t be sure of what was holding it up. After getting some help from the Developer s mailing list, I prepared no change rebuild of pd-aubio which was sponsored by Steve Langasek after a little tweak. This did the trick.
  • Wrote to the Ubuntu Studio list asking for support for testing the Ubuntu Studio Zesty release, as I would be on holiday in the lead up to the release. When I got back, I found the release had gone smoothly. Thanks team!
  • Worked on some blueprints for the next Ubuntu Studio Artful release.
  • As Set no longer has enough spare time to work on Ubuntu Studio, we had a meeting on IRC to decide what to do. We decided that we should set up a Council like Xubuntu have. I drafted an announcement, but we still have not gone live with it yet. Maybe someone will have read this far and give us a push (or help).
  • Did a quick test of Len s ubuntustudio-controls re-write (at least the GUI bits). We better get a move on if we want this to be part of Artful!
  • Tested ISO for Ubuntu Studio Xenial 16.04.3 point release, and updated the release notes.
  • Started working on a merge of Qjackctl using git-ubuntu for the first time. Had some issues getting going, so I asked the authors for some advice.

15 August 2017

Lisandro Dami n Nicanor P rez Meyer: Qt 4 removal in Debian testing (Buster)/unstable

We have been announcing it: we are going to remove Qt 4 during the Buster cycle.

Or at least that's the best outcome we can expect. Removing a very highly used library is hard, as Qt4's Webkit has proved. Qt 4 is long dead upstream and we have already started to need to patch it with untested patches as in the OpenSSL 1.1 case (will be in experimental in a few hours after this post).

We will try to put as less effort as possible in keeping it alive meaning that from now on if we need to patch it to make it support a newer lib or alike we will simply remove its support if possible. Using the OpenSSL case as an example, if we need to support any version > 1.1 we will simply remove the SSL support. That means things will break.

So, if you depend on FLOSS which is still based on Qt 4 be sure to try to port it. If you depend on a proprietary vendor software which uses Qt 4 then you better start telling them it's really time to update it. Really.

We will soon start filing bugs against packages using Qt 4. I'll update this blog post later to add that info.

For the Qt/KDE team, Lisandro.

Next.

Previous.