Search Results: "spa"

11 February 2016

Bits from Debian: Tails installer is now in Debian

Tails (The amnesic incognito live system) is a live OS based on Debian GNU/Linux which aims at preserving the user's privacy and anonymity by using the Internet anonymously and circumventing censorship. Installed on a USB device, it is configured to leave no trace on the computer you are using unless asked explicitly. Tails Logo As of today, the people the most needy for digital security are not computer experts. Being able to get started easily with a new tool is critical to its adoption, and even more in high-risk and stressful environments. That's why we wanted to make it faster, simpler, and more secure to install Tails for new users. One of the components of Tails, the Tails Installer is now in Debian thanks to the Debian Privacy Tools Maintainers Team. Tails Installer is a graphical tool to install or upgrade Tails on a USB stick from an ISO image. It aims at making it easier and faster to get Tails up and running. The previous process for getting started with Tails was very complex and was problematic for less tech-savvy users. It required starting Tails three times, and copying the full ISO image onto a USB stick twice before having a fully functional Tails USB stick with persistence enabled. This can now be done simply by installing Tails Installer in your existing Debian system, using sid, stretch or jessie-backports, plugging a USB stick and choosing if one wants to update the USB stick or to install Tails using a previously downloaded ISO image. Tails Installer also helps Tails users to create an encrypted persistent storage for personal files and settings in the rest of the available space.
9 February 2016

Jose M. Calhariz: A Selection of Talks from FOSDEM 2016

It's that time of the year where I go to FOSDEM (Free and Open Source Software Developers' European Meeting). The keynotes and the maintracks are very good, with good presentations and contents. It's very dificult to choose what talks to see, what talks to see later in video and what talks to loose. What I leave here is my selection of talks. This selection is representative of my tastes, not of the quality of the presentations. I will give links for material that is available now. I will do periodic updates when the new material is available: video or slides.

Joachim Breitner: GHC performance is rather stable

Johannes Bechberger, while working on his Bachelor s thesis supervised by my colleague Andreas Zwinkau, has developed a performance benchmark runner and results visualizer called temci , and used GHC as a guinea pig. You can read his elaborate analysis on his blog. This is particularly interesting given recent discussions about GHC itself becoming slower and slower, as for example observed by Johannes Waldmann and Anthony Cowley. Johannes Bechberger s take-away is that, at least for the programs at hand (which were taken from the The Computer Language Benchmarks Game, there are hardly any changes worth mentioning, as most of the observed effects are less than a standard deviation and hence insignificant. He tries hard to distill some useful conclusions from the data; the one he finds are: If you are interested, please head over to Johannes s post and look at the gory details of the analysis and give him feedback on that. Also, maybe his tool temci is something you want to try out? Personally, I find it dissatisfying to learn so little from so much work, but as he writes: It s so easy to lie with statistics. , and I might add lie to yourself , e.g. by ignoring good advise about standard deviations and significance. I m sure my tool gipeda (which powers perf.haskell.org) is guilty of that sin. Maybe a different selection of test programs would yield more insight; the benchmark s games programs are too small and hand-optimized, the nofib programs are plain old and the fibon collection has bitrotted. I would love to see a curated, collection of real-world programs, bundled with all dependencies and frozen to allow meaningful comparisons, but updated to a new, clearly marked revision, on a maybe bi-yearly basis maybe Haskell-SPEC-2016 if that were not a trademark infringement.

8 February 2016

Joachim Breitner: Protecting static content with mod_rewrite

Since fourteen years, I have been photographing digitally and putting the pictures on my webpage. Back then, online privacy was not a big deal, but things have changed, and I had to at least mildly protect the innocent. In particular, I wanted to prevent search engines from accessing some of my pictures. As I did not want my friends and family having to create an account and remember a password, I set up an OpenID based scheme five years ago. This way, they could use any of their OpenID enabled account, e.g. their Google Mail account, to log in, without disclosing any data to me. As my photo album consists of just static files, I created two copies on the server: the real one with everything, and a bunch of symbolic links representing the publicly visible parts. I then used mod_auth_openid to prevent access to the protected files, unless the users logged in. I never got around of actually limiting who could log in, so strangers were still able to see all photos, but at least search engine spiders were locked out. But, very unfortunately, OpenID did never really catch on, Google even stopped being a provider, and other promising decentralized authentication schemes like Mozilla Persona are also phased out. So I needed an alternative. A very simply scheme would be a single password that my friends and family can get from me and that unlocks the pictures. I could have done that using HTTP Auth, but that is not very user-friendly, and the login does not persist (at least not without the help of the browser). Instead, I wanted something that involves a simple HTTP form. But I also wanted to avoid server-side programming, for performance and security reasons. I love serving static files whenever it is feasible. Then I found that mod_rewrite, Apache s all-around-tool for URL rewriting and request mangling, supports reading and writing cookies! So I came up with a scheme that implements the whole login logic in the Apache server configuration. I d like to describe this setup here, in case someone finds it inspiring. I created a login.html with a simple HTML form:
<form method="GET" action="/bilder/login.html">
 <div style="text-align:center">
  <input name="password" placeholder="Password" />
  <button type="submit">Sign-In</button>
 </div>
</form>
It sends the user to the same page again, putting the password into the query string, hence the method="GET" mod_rewrite unfortunately cannot read the parameters of a POST request. The Apache configuration is as follows:
RewriteMap public "dbm:/var/www/joachim-breitner.de/bilder/publicfiles.dbm"
<Directory /var/www/joachim-breitner.de/bilder>
 RewriteEngine On
 # This is a GET request, trying to set a password.
 RewriteCond % QUERY_STRING  password=correcthorsebatterystaple
 RewriteRule ^login.html /bilder/loggedin.html [L,R,QSD,CO=bilderhp:correcthorsebatterystaple:www.joachim-breitner.de:2000000:/bilder]
 # This is a GET request, trying to set a wrong password.
 RewriteCond % QUERY_STRING  password=
 RewriteRule ^login.html /bilder/notloggedin.html [L,R,QSD]
 # No point in loggin in if there is already the right password
 RewriteCond % HTTP:Cookie  bilderhp=correcthorsebatterystaple
 RewriteRule ^login.html /bilder/loggedin.html [L,R]
 # If protected file is requested, check for cookie.
 # If no cookie present, redirect pictures to replacement picture
 RewriteCond % HTTP:Cookie  !bilderhp=correcthorsebatterystaple
 RewriteCond $ public:$0 private  private
 RewriteRule ^.*\.(png jpg)$ /bilder/pleaselogin.png [L]
 RewriteCond % HTTP:Cookie  !bilderhp=correcthorsebatterystaple
 RewriteCond $ public:$0 private  private
 RewriteRule ^.+$ /bilder/login.html [L,R]
</Directory>
The publicfiles.dbm file is generated from a text file with lines like
login.html.en 1
login.html.de 1
pleaselogin.png 1
thumbs/20030920165701_thumb.jpg 1
thumbs/20080813225123_thumb.jpg 1
...
using
/usr/sbin/httxt2dbm -i publicfiles.txt -o publicfiles.dbm
and whitelists all files that are visible without login. Make sure it contains the login page, otherwise you ll get a redirect circle. The other directives in the above configure fulfill these tasks: And that s it! No resource-hogging web frameworks, not security-dubious scripting languages, and a dead-simple way to authenticate. Oh, and if you believe you know me well enough to be allowed to see all photos: The real password is not correcthorsebatterystaple; just ask me what it is.

7 February 2016

Joey Hess: letsencrypt support in propellor

I've integrated letsencrypt into propellor today. I'm using the reference letsencrypt client. While I've seen complaints that it has a lot of dependencies and is too complicated, it seemed to only need to pull in a few packages, and use only a few megabytes of disk space, and it has fewer options than ls does. So seems fine. (Although it would be nice to have some alternatives packaged in Debian.) I ended up implementing this:
letsEncrypt :: AgreeTOS -> Domain -> WebRoot -> Property NoInfo
This property just makes the certificate available, it does not configure the web server to use it. This avoids relying on the letsencrypt client's apache config munging, which is probably useful for many people, but not those of us using configuration management systems. And so avoids most of the complicated magic that the letsencrypt client has a reputation for. Instead, any property that wants to use the certificate can just use leteencrypt to get it and set up the server when it makes a change to the certificate:
letsEncrypt (LetsEncrypt.AgreeTOS (Just "me@my.domain")) "example.com" "/var/www"
     onChange  setupthewebserver
(Took me a while to notice I could use onChange like that, and so divorce the cert generation/renewal from the server setup. onChange is awesome! This blog post has been updated accordingly.) In practice, the http site has to be brought up first, and then letsencrypt run, and then the cert installed and the https site brought up using it. That dance is automated by this property:
Apache.httpsVirtualHost "example.com" "/var/www"
    (LetsEncrypt.AgreeTOS (Just "me@my.domain"))
That's about as simple a configuration as I can imagine for such a website!
The two parts of letsencrypt that are complicated are not the fault of the client really. Those are renewal and rate limiting. I'm currently rate limited for the next week because I asked letsencrypt for several certificates for a domain, as I was learning how to use it and integrating it into propellor. So I've not quite managed to fully test everything. That's annoying. I also worry that rate limiting could hit at an inopportune time once I'm relying on letsencrypt. It's especially problimatic that it only allows 5 certs for subdomains of a given domain per week. What if I use a lot of subdomains? Renewal is complicated mostly because there's no good way to test it. You set up your cron job, or whatever, and wait three months, and hopefully it worked. Just as likely, you got something wrong, and your website breaks. Maybe letsencrypt could offer certificates that will only last an hour, or a day, for use when testing renewal. Also, what if something goes wrong with renewal? Perhaps letsencrypt.org is not available when your certificate needs to be renewed. What I've done in propellor to handle renewal is, it runs letsencrypt every time, with the --keep-until-expiring option. If this fails, propellor will report a failure. As long as propellor is run periodically by a cron job, this should result in multiple failure reports being sent (for 30 days I think) before a cert expires without getting renewed. But, I have not been able to test this.

6 February 2016

Dimitri John Ledkov: Blogging about Let's encrypt over HTTP

So let's encrypt thing started. And it can do challenges over http (serving text files) and over dns (serving .txt records).

My "infrastructure" is fairly modest. I've seen too many of my email accounts getting swamped with spam, and or companies going bust. So I got my own domain name surgut.co.uk. However, I don't have money or time to run my own services. So I've signed up for the Google Apps account for my domain to do email, blogging, etc.

Then later i got the libnih.la domain to host API docs for the mentioned library. In the world of .io startups, I thought it's an incredibly funny domain name.

But I also have a VPS to host static files on ad-hoc basis, run VPN, and an irc bouncer. My irc bouncer is ZNC and I used a self-signed certificate there, thus i had "ignore" ssl errors in all of my irc clients... which kind of defeats the purposes somewhat.

I run my VPS on i386 (to save on memory usage) and on Ubuntu 14.04 LTS managed with Landscape. And my little services are just configured by hand there (not using juju).

My first attempt at getting on the let's encrypt bandwagon was to use the official client. By fetching debs from xenial, and installing that on LTS. But the package/script there is huge, has support for things I don't need, and wants dependencies I don't have on 14.04 LTS.

However I found a minimalist implementation letsencrypt.sh implemented in shell, with openssl and curl. It was trivial to get dependencies for and configure. Specified a domains text file, and that was it. And well, added sym links in my NGINX config to serve the challenges directory & a hook to deploy certificate to znc and restart that. I've added a cronjob to renew the certs too. Thinking about it, it's not complete as I'm not sure if NGINX will pick up certificate change and/or if it will need to be reloaded. I shall test that, once my cert expires.

Tweaking config for NGINX was easy. And I was like, let's see how good it is. I pointed https://www.ssllabs.com/ssltest/ at my https://x4d.surgut.co.uk/ and I got a "C" rating. No forward secrecy, vulnerable to down grade attacks, BEAST, POODLE and stuff like that. I went googling for all types of NGINX configs and eventually found website with "best known practices" https://cipherli.st/ However, even that only got me to "B" rating, as it still has Diffie-Hellman things that ssltest caps at "B" rating. So I disabled those too. I've ended up with this gibberish:

ssl_protocols TLSv1 TLSv1.1 TLSv1.2;
ssl_prefer_server_ciphers on;
ssl_ciphers "EECDH+AESGCM:AES256+EECDH";
ssl_ecdh_curve secp384r1; # Requires nginx >= 1.1.0
ssl_session_cache shared:SSL:10m;
#ssl_session_tickets off; # Requires nginx >= 1.5.9
ssl_stapling on; # Requires nginx >= 1.3.7
ssl_stapling_verify on; # Requires nginx => 1.3.7
#resolver $DNS-IP-1 $DNS-IP-2 valid=300s;
#resolver_timeout 5s;
add_header Strict-Transport-Security "max-age=63072000; includeSubdomains; preload";
add_header X-Frame-Options DENY;
add_header X-Content-Type-Options nosniff;

I call it gibberish, because IMHO, I shouldn't need to specify any of the above... Anyway I got my A+ rating.

However, security is as best as the weakest link. I'm still serving things over HTTP, maybe I should disable that. And I'm yet to check how "good" the TLS is on my znc. Or if I need to further harden my sshd configuration.

This has filled a big gap in my infrastructure. However a few things remain served over HTTP only.

http://blog.surgut.co.uk is hosted by an Alphabet's / Google's Blogger service. Which I would want to be served over HTTPS.

http://libnih.la is hosted by GitHub Inc service. Which I would want to be served over HTTPS.

I do not want to manage those services, experience load / spammers / DDoS attacks etc. But I am happy to sign CSRs with let's encrypt and deploy certs over to those companies. Or allow them to self-obtain certificates from let's encrypt on my behalf. I used gandi.net as my domain names provider, which offers an RPC API to manage domains and their zones files, thus e.g. I can also generate an API token for those companies to respond with a dns-01 challenge from let's encrypt.

One step at a time I guess.

The postings on this site are my own and don't necessarily represent any past/present/future employers' positions, strategies, or opinions.

Andrew Shadura: Community time at Collabora

I haven t yet blogged about this (as normally I don t blog often), but I joined Collabora in June last year. Since then, I had an opportunity to work with OpenEmbedded again, write a kernel patch, learn lots of things about systemd (in particular, how to stop worrying about it taking over the world and so on), and do lots of other things. As one would expect when working for a free software consultancy, our customers do understand the value of the community and contributing back to it, and so does the customer for the project I m working on. In fact, our customer insists we keep the number of locally applied patches to, for example, Linux kernel, to minimum, submitting as much as possible upstream. However, apart from the upstreaming work which may be done for the customer, Collabora encourages us, the engineers, to spend up to two hours weekly for upstreaming on top of what customers need, and up to five days yearly as paid Community days. These community days may be spent working on the code or doing volunteering at free software events or even speaking at conferences. Even though on this project I have already been paid for contributing to the free software project which I maintained in my free time previously (ifupdown), paid community time is a great opportunity to contribute to the projects I m interested in, and if the projects I m interested in coincide with the projects I m working with, I effectively can spend even more time on them. A bit unfortunately for me, I haven t spent enough time last year to plan my community days, so I used most of them in the last weeks of the calendar year, and I used them (and some of my upstreaming hours) on something that benefitted both free software community and Collabora. I m talking about SparkleShare, a cross-platform Git-based file synchronisation solution written in C#. SparkleShare provides an easy to use interface for Git, or, actually, it makes it possible to not use any Git interface at all, as it monitors the working directory using inotify and commits stuff right after it changes. It automatically handles conflicts even for binary files, even though I have to admit its handling could still be improved. At Collabora, we use SparkleShare to store all sorts of internal documents, and it s being used by users not familiar with command line interfaces too. Unfortunately, the version we recently had in Debian had a couple of very annoying bugs, making it a great pain to use it: it would not notice edits in local files, or not notice new commits being pushed to the server, and that led to individual users edits being lost sometimes. Not cool, especially when the document has to be sent to the customer in a couple of minutes. The new versions, 1.4 (and recently released 1.5) was reported as being much better and also fixing some crashes, but it also used GTK+ 3 and some libraries not yet packaged for Debian. Thanh Tung Nguyen packaged these packages (and a newer SparkleShare) for Ubuntu and published them in his PPA, but they required some work to be fit for Debian. I have never touched Mono packages before in my life, so I had to learn a lot. Some time was spent talking to upstream about fixing their copyright statements (they had none in the code, and only one author was mentioned in configure.ac, and nowhere else in the source), a bit more time went into adjusting and updating the patches to the current source code version. Then, of course, waiting the packages to go through NEW. Fixing parallel build issues, waiting for buildds to all build dependencies for at least one architecture But then, finally, on 19th of January I had the updated SparkleShare in Debian. As you may have already guessed, this blog post has been sponsored by Collabora, the first of my employers to encourage require me to work on free software in my paid time :)

Neil Williams: lava.debian.net

With thanks to Iain Learmonth for the hardware, there is now a Debian instance of LAVA available for use and the Debian wiki page has been updated. LAVA is a continuous integration system for deploying operating systems onto physical and virtual hardware for running tests. Tests can be simple boot testing, bootloader testing and system level testing. Extra hardware may be required for some system tests. Results are tracked over time and data can be exported for further analysis. LAVA has a long history of supporting continuous integration of the Linux kernel on ARM devices (ARMv7 & ARMv8). So if you are testing a Linux kernel image on armhf or arm64 devices, you will find a lot of similar tests already running on the other LAVA instances. The Debian LAVA instance seeks to widen that testing in a couple of ways: This instance relies on the latest changes in lava-server and lava-dispatcher. The 2016.2 release has now deprecated the old, complex dispatcher and a whole new pipeline design is available. The Debian LAVA instance is running 2015.12 at the moment, I ll upgrade to 2016.2 once the packages migrate into testing in a few days and I can do a backport to jessie. What can LAVA do for Debian? ARMMP kernel testing Unreleased builds, experimental initramfs testing this is the core of what LAVA is already doing behind the scenes of sites like http://kernelci.org/. U-Boot ARM testing This is what fully automated LAVA labs have not been able to deliver in the past, at least without a usable SD Mux What s next LOTS. This post actually got published early (distracted by the rugby) I ll update things more in a later post. Contact me if you want to get involved, I ll provide more information on how to use the instance and how to contribute to the testing in due course.

5 February 2016

Bernd Zeimetz: bzed-letsencrypt puppet module

With the announcement of the Let s Encrypt dns-01 challenge support we finally had a way to retrieve certificates for those hosts where http challenges won t work. Also it allows to centralize the signing procedure to avoid the installation and maintenance of letsencrypt clients on all hosts. For an implementation I had the following requirements in my mind: After reading trough the source code of various letsencrypt client implementations I decided to use letsencrypt.sh. Mainly because its dependencies are available pretty much everywhere and adding the necessary hook is as simple as writing some lines of code in your favourite (scripting) language. My second favourite was lego, but I wanted to avoid shipping binaries with puppet, so golang was not an option. It took me some days to find enough spare time to write the necessary puppet code, but finally I managed to release a working module today. It is still not perfect, but the basic tasks are implemented and the whole key/csr/signing chain works pretty well. And if your hook can handle it, http-01 challenges are possible, too! Please give the module a try and send patches if you would like to help to improve it!

Jose M. Calhariz: Preview of amanda 3.3.8-1

While I sort out a sponsor, my sponsor is very busy, here is a preview of the new packages. So anyone can install and test them on jessie. The source of the packages is in collab-maint.The debs files for jessie are here: amanda-common_3.3.8-1_cal0_i386.deb amanda-server_3.3.8-1_cal0_i386.deb amanda-client_3.3.8-1_cal0_i386.deb Here comes the changelog:
amanda (1:3.3.8-1~cal0) unstable; urgency=low
  * New Upstream version
    * Changes for 3.3.8
      * s3 devices
          New NEARLINE S3-STORAGE-CLASS for Google storage.
          New AWS4 STORAGE-API
      * amcryptsimple
          Works with newer gpg2.
      * amgtar
          Default SPARSE value is NO if tar < 1.28.
          Because a bug in tar with some filesystem.
      * amstar
          support include in backup mode.
      * ampgsql
          Add FULL-WAL property.
      * Many bugs fix.
    * Changes for 3.3.7p1
      * Fix build in 3.3.7
    * Changes for 3.3.7
      * amvault
          new --no-interactivity argument.
          new --src-labelstr argument.
      * amdump
          compute crc32 of the streams and write them to the debug files.
      * chg-robot
          Add a BROKEN-DRIVE-LOADED-SLOT property.
      * Many bugs fix.
  * Refreshed patches.
  * Dropped patches that were applied by the upstream: fix-misc-typos,
    automake-add-missing, fix-amcheck-M.patch,
    fix-device-src_rait-device.c, fix-amreport-perl_Amanda_Report_human.pm
  * Change the email of the maintainer.
  * "wrap-and-sort -at" all control files.
  * swig is a new build depend.
  * Bump standard version to 3.9.6, no changes needed.
  * Replace deprecated dependency perl5 by perl, (Closes: #808209), thank
    you Gregor Herrmann for the NMU.
 -- Jose M Calhariz <jose@calhariz.com>  Tue, 02 Feb 2016 19:56:12 +0000

Ben Hutchings: Debian LTS work, January 2016

In January I carried over 10 hours from December and was assigned another 15 hours of work by Freexian's Debian LTS initiative. I worked a total of 15 hours. I had a few days on 'front desk' at the start of the month, as my week in that role spanned the new year. I fixed a regression in the kernel that was introduced to all stable suites in December. I uploaded this along with some minor security fixes, and issued DLA 378-1. I finished backporting and testing fixes to sudo for CVE-2015-5602. I uploaded an update and issued DLA 382-1, which was followed by DSA 3440-1 for wheezy and jessie. I finished backporting and testing fixes to Claws Mail for CVE-2015-8614 and CVE-2015-8708. I uploaded an update and issued DLA 383-1. This was followed by DSA 3452-1 for wheezy and jessie, although the issues are less serious there. I also apent a little time on InspIRCd, though this isn't a package that Freexian's customers care about and it seems to have been broken in squeeze for several years due to a latent bug in the build system. I had already backported the security fix by the time I discovered this, so I went ahead with an update fixing that regression as well, and issued DLA 384-1. Finally, I diagnosed the regression in the update to isc-dhcp in DLA 385-1.

4 February 2016

Russell Coker: Unikernels

At LCA I attended a talk about Unikernels. Here are the reasons why I think that they are a bad idea: Single Address Space According to the Unikernel Wikipedia page [1] a significant criteria for a Unikernel system is that it has a single address space. This gives performance benefits as there is no need to change CPU memory mappings when making system calls. But the disadvantage is that any code in the application/kernel can access any other code directly. In a typical modern OS (Linux, BSD, Windows, etc) every application has a separate address space and there are separate memory regions for code and data. While an application can request the ability to modify it s own executable code in some situations (if the OS is configured to allow that) it won t happen by default. In MS-DOS and in a Unikernel system all code has read/write/execute access to all memory. MS-DOS was the least reliable OS that I ever used. It was unreliable because it performed tasks that were more complex than CP/M but had no memory protection so any bug in any code was likely to cause a system crash. The crash could be delayed by some time (EG corrupting data structures that are only rarely accessed) which would make it very difficult to fix. It would be possible to have a Unikernel system with non-modifyable executable areas and non-executable data areas and it is conceivable that a virtual machine system like Xen could enforce that. But that still wouldn t solve the problem of all code being able to write to all data. On a Linux system when an application writes to the wrong address there is a reasonable probability that it will not have write access and you will immediately get a SEGV which is logged and informs the sysadmin of the address of the crash. When Linux applications have bugs that are difficult to diagnose (EG buffer overruns that happen in production and can t be reproduced in a test environment) there are a variety of ways of debugging them. Tools such as Valgrind can analyse memory access and tell the developers which code had a bug and what the bug does. It s theoretically possible to link something like Valgrind into a Unikernel, but the lack of multiple processes would make it difficult to manage. Debugging A full Unix environment has a rich array of debugging tools, strace, ltrace, gdb, valgrind and more. If there are performance problems then tools like sysstat, sar, iostat, top, iotop, and more. I don t know which of those tools I might need to debug problems at some future time. I don t think that any Internet facing service can be expected to be reliable enough that it will never need any sort of debugging. Service Complexity It s very rare for a server to have only a single process performing the essential tasks. It s not uncommon to have a web server running CGI-BIN scripts or calling shell scripts from PHP code as part of the essential service. Also many Unix daemons are not written to run as a single process, at least threading is required and many daemons require multiple processes. It s also very common for the design of a daemon to rely on a cron job to clean up temporary files etc. It is possible to build the functionality of cron into a Unikernel, but that means more potential bugs and more time spent not actually developing the core application. One could argue that there are design benefits to writing simple servers that don t require multiple programs. But most programmers aren t used to doing that and in many cases it would result in a less efficient result. One can also argue that a Finite State Machine design is the best way to deal with many problems that are usually solved by multi-threading or multiple processes. But most programmers are better at writing threaded code so forcing programmers to use a FSM design doesn t seem like a good idea for security. Management The typical server programs rely on cron jobs to rotate log files and monitoring software to inspect the state of the system for the purposes of graphing performance and flagging potential problems. It would be possible to compile the functionality of something like the Nagios NRPE into a Unikernel if you want to have your monitoring code running in the kernel. I ve seen something very similar implemented in the past, the CA Unicenter monitoring system on Solaris used to have a kernel module for monitoring (I don t know why). My experience was that Unicenter caused many kernel panics and more downtime than all other problems combined. It would not be difficult to write better code than the typical CA employee, but writing code that is good enough to have a monitoring system running in the kernel on a single-threaded system is asking a lot. One of the claimed benefits of a Unikernel was that it s supposedly risky to allow ssh access. The recent ssh security issue was an attack against the ssh client if it connected to a hostile server. If you had a ssh server only accepting connections from management workstations (a reasonably common configuration for running servers) and only allowed the ssh clients to connect to servers related to work (an uncommon configuration that s not difficult to implement) then there wouldn t be any problems in this regard. I think that I m a good programmer, but I don t think that I can write server code that s likely to be more secure than sshd. On Designing It Yourself One thing that everyone who has any experience in security has witnessed is that people who design their own encryption inevitably do it badly. The people who are experts in cryptology don t design their own custom algorithm because they know that encryption algorithms need significant review before they can be trusted. The people who know how to do it well know that they can t do it well on their own. The people who know little just go ahead and do it. I think that the same thing applies to operating systems. I ve contributed a few patches to the Linux kernel and spent a lot of time working on SE Linux (including maintaining out of tree kernel patches) and know how hard it is to do it properly. Even though I m a good programmer I know better than to think I could just build my own kernel and expect it to be secure. I think that the Unikernel people haven t learned this.

2 February 2016

Dirk Eddelbuettel: Like peanut butter and jelly: x13binary and seasonal

This post was written by Dirk Eddelbuettel and Christoph Sax and will be posted on both author's respective blogs. The seasonal package by Christoph Sax brings a very featureful and expressive interface for working with seasonal data to the R environment. It uses the standard tool of the trade: X-13ARIMA-SEATS. This powerful program is provided by the statisticians of the US Census Bureau based on their earlier work (named X-11 and X-12-ARIMA) as well as the TRAMO/SEATS program by the Bank of Spain. X-13ARIMA-SEATS is probably the best known tool for de-seasonalization of timeseries, and used by statistical offices around the world. Sadly, it also has a steep learning curve. One interacts with a basic command-line tool which users have to download, install and properly reference (by environment variables or related means). Each model specification has to be prepared in a special 'spec' file that uses its own, cumbersome syntax. As seasonal provides all the required functionality to use X-13ARIMA-SEATS from R --- see the very nice seasonal demo site --- it still required the user to manually deal with the X-13ARIMA-SEATS installation. So we decided to do something about this. A pair of GitHub repositories provide both the underlying binary in a per-operating system form (see x13prebuilt) as well as a ready-to- use R package (see x13binary) which uses the former to provide binaries for R. And the latter is now on CRAN as package x13binary ready to be used on Windows, OS-X or Linux. And the seasonal package (in version 1.2.0 -- now on CRAN -- or later) automatically makes use of it. Installing seasaonal and x13binary in R is now as easy as:

install.packages("seasonal")
which opens the door for effortless deployment of powerful deasonalization. By default, the principal function of the package employs a number of automated techniques that work well in most circumstances. For example, the following code produces a seasonal adjustment of the latest data of US retail sales (by the Census Bureau) downloaded from Quandl:
library(seasonal) 
library(Quandl)   ## not needed for seasonal but has some niceties for Quandl data
rs <- Quandl(code="USCENSUS/BI_MARTS_44000_SM", type="ts")/1e3
m1 <- seas(rs)
plot(m1, main = "Retail Trade: U.S. Total Sales", ylab = "USD (in Billions)")
This tests for log-transformation, performs an automated ARIMA model search, applies outlier detection, tests and adjusts for trading day and easter effects, and invokes the SEATS method to perform seasonal adjustment. And this is how the adjusted series looks like:
Of course, you can access all available options of X-13ARIMA-SEATS as well. Here is an example where we adjust the latest data for Chinese exports (as tallied by the US FED), taking into account the different effects of Chinese New Year before, during and after the holiday:
xp <- Quandl(code="FRED/VALEXPCNM052N", type="ts")/1e9
m2 <- seas(window(xp, start = 2000),
          xreg = cbind(genhol(cny, start = -7, end = -1, center = "calendar"), 
                       genhol(cny, start = 0, end = 7, center = "calendar"), 
                       genhol(cny, start = 8, end = 21, center = "calendar")
          ),
          regression.aictest = c("td", "user"),
          regression.usertype = "holiday")
plot(m2, main = "Goods, Value of Exports for China", ylab = "USD (in Billions)")
which generates the following chart demonstrating a recent flattening in export activity measured in USD.
We hope this simple examples illustrates both how powerful a tool X-13ARIMA-SEATS is, but also just how easy it is to use X-13ARIMA-SEATS from R now that we provide the x13binary package automating its installation.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Norbert Preining: Gaming: The Talos Principle Road to Gehenna

After finishing the Talos Principle I immediately started to play the extension Road to Gehenna, but was derailed near completion by the incredible Portal Stories: Mel. Now that I finally managed to escape from the test chambers my attention returned to the Road to Gehenna. As with the pair Portal 2 and Portal Stories: Mel, the challenges are going up considerably from the original Talos Principle to the Road to Gehenna. Checking the hours of game play it took me about 24h through all the riddles in Road to Gehenna, but I have to admit, I had some riddles where I needed to cheat. road-to-gehenna.jpg The Road to Gehenna does not bring much new game play elements, but loads of new riddles. And the best of all, playable on Linux! And as with the original game, the graphics are really well done, while still be playable on my Vaio Pro laptop with Intel integrated graphic card a plus that is rare in the world of computer games where everyone is expected to have a high-end nVidia or Radeon card. Ok, there is not much action going on where quick graphic computations are necessary, still the impression of the game is great.
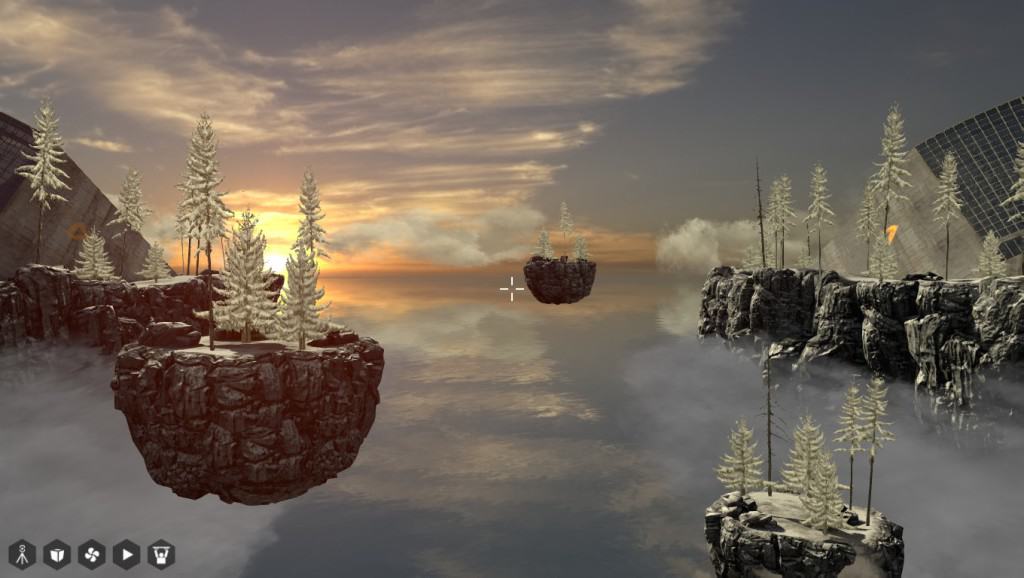
gehenna1 The riddles contain the well known elements (connectors, boxes, jammer, etc), but the settings are often spectacular, sometimes very small and narrow, just a few moves if done in the right order, sometimes like wide open fields with lots of space to explore. Transportation between various islands suspended in the air is with vents, giving you a lot of nice flight time!
gehenna2 If one searches a lot, or uses a bit of cheating, one can find good old friends from the Portal series, burried in the sand in one of the world. This is not the only easter egg hidden in the game, there are actually a lot, some of which I have not seen but only read about afterwards. Guess I need to replay the whole game.
gehenna3 Coming back to the riddles, I really believe that the makers have been ingenious in using the few items at hand to create challenging and surprising riddles. As it is so often, many of the riddles look completely impossible at first glance, and often even after staring at them for tens and tens of minutes. Until (and if) one has the the a-ha effect and understands the trick. This often still needs a lot of handwork and trial-error rounds, but all in all the game is well balanced. What is a bit a pain similar to the original game are collecting the stars to reach the hidden world and free the admin. There the developers overdid it in my opinion, with some rather absurd and complicated stars.
gehenna4 The end of the game, ascension of the messengers, is rather unspectacular. A short discussion on who remains and then a big closing scene with the messenger being beamed up a la Starship Enterprise, and a closing black screen. But well, the fun was with the riddles.
gehenna5 All in all an extension that is well worth the investment if one enjoyed the original Talos, and is looking for rather challenging riddles. Now that I have finished all the Portal and Talos titles, I am hard thinking of what is next looking into Braid Enjoy!

Russell Coker: Compatibility and a Linux Community Server

Compatibility/interoperability is a good thing. It s generally good for systems on the Internet to be capable of communicating with as many systems as possible. Unfortunately it s not always possible as new features sometimes break compatibility with older systems. Sometimes you have systems that are simply broken, for example all the systems with firewalls that block ICMP so that connections hang when the packet size gets too big. Sometimes to take advantage of new features you have to potentially trigger issues with broken systems. I recently added support for IPv6 to the Linux Users of Victoria server. I think that adding IPv6 support is a good thing due to the lack of IPv4 addresses even though there are hardly any systems that are unable to access IPv4. One of the benefits of this for club members is that it s a platform they can use for testing IPv6 connectivity with a friendly sysadmin to help them diagnose problems. I recently notified a member by email that the callback that their mail server used as an anti-spam measure didn t work with IPv6 and was causing mail to be incorrectly rejected. It s obviously a benefit for that user to have the problem with a small local server than with something like Gmail. In spite of the fact that at least one user had problems and others potentially had problems I think it s clear that adding IPv6 support was the correct thing to do. SSL Issues Ben wrote a good post about SSL security [1] which links to a test suite for SSL servers [2]. I tested the LUV web site and got A-. This blog post describes how to setup PFS (Perfect Forward Secrecy) [3], after following it s advice I got a score of B! From the comments on this blog post about RC4 etc [4] it seems that the only way to have PFS and not be vulnerable to other issues is to require TLS 1.2. So the issue is what systems can t use TLS 1.2. TLS 1.2 Support in Browsers This Wikipedia page has information on SSL support in various web browsers [5]. If we require TLS 1.2 we break support of the following browsers: The default Android browser before Android 5.0. Admittedly that browser always sucked badly and probably has lots of other security issues and there are alternate browsers. One problem is that many people who install better browsers on Android devices (such as Chrome) will still have their OS configured to use the default browser for URLs opened by other programs (EG email and IM). Chrome versions before 30 didn t support it. But version 30 was released in 2013 and Google does a good job of forcing upgrades. A Debian/Wheezy system I run is now displaying warnings from the google-chrome package saying that Wheezy is too old and won t be supported for long! Firefox before version 27 didn t support it (the Wikipedia page is unclear about versions 27-31). 27 was released in 2014. Debian/Wheezy has version 38, Debian/Squeeze has Iceweasel 3.5.16 which doesn t support it. I think it is reasonable to assume that anyone who s still using Squeeze is using it for a server given it s age and the fact that LTS is based on packages related to being a server. IE version 11 supports it and runs on Windows 7+ (all supported versions of Windows). IE 10 doesn t support it and runs on Windows 7 and Windows 8. Are the free upgrades from Windows 7 to Windows 10 going to solve this problem? Do we want to support Windows 7 systems that haven t been upgraded to the latest IE? Do we want to support versions of Windows that MS doesn t support? Windows mobile doesn t have enough users to care about. Opera supports it from version 17. This is noteworthy because Opera used to be good for devices running older versions of Android that aren t supported by Chrome. Safari supported it from iOS version 5, I think that s a solved problem given the way Apple makes it easy for users to upgrade and strongly encourages them to do so. Log Analysis For many servers the correct thing to do before even discussing the issue is to look at the logs and see how many people use the various browsers. One problem with that approach on a Linux community site is that the people who visit the site most often will be more likely to use recent Linux browsers but older Windows systems will be more common among people visiting the site for the first time. Another issue is that there isn t an easy way of determining who is a serious user, unlike for example a shopping site where one could search for log entries about sales. I did a quick search of the Apache logs and found many entries about browsers that purport to be IE6 and other versions of IE before 11. But most of those log entries were from other countries, while some people from other countries visit the club web site it s not very common. Most access from outside Australia would be from bots, and the bots probably fake their user agent. Should We Do It? Is breaking support for Debian/Squeeze, the built in Android browser on Android <5.0, and Windows 7 and 8 systems that haven t upgraded IE as a web browsing platform a reasonable trade-off for implementing the best SSL security features? For the LUV server as a stand-alone issue the answer would be no as the only really secret data there is accessed via ssh. For a general web infrastructure issue it seems that the answer might be yes. I think that it benefits the community to allow members to test against server configurations that will become more popular in the future. After implementing changes in the server I can advise club members (and general community members) about how to configure their servers for similar results. Does this outweigh the problems caused by some potential users of ancient systems? I m blogging about this because I think that the issues of configuration of community servers have a greater scope than my local LUG. I welcome comments about these issues, as well as about the SSL compatibility issues.

1 February 2016

Lunar: Reproducible builds: week 40 in Stretch cycle

What happened in the reproducible builds effort between January 24th and January 30th:

Media coverage Holger Levsen was interviewed by the FOSDEM team to introduce his talk on Sunday 31st.

Toolchain fixes Jonas Smedegaard uploaded d-shlibs/0.63 which makes the order of dependencies generated by d-devlibdeps stable accross locales. Original patch by Reiner Herrmann.

Packages fixed The following 53 packages have become reproducible due to changes in their build dependencies: appstream-glib, aptitude, arbtt, btrfs-tools, cinnamon-settings-daemon, cppcheck, debian-security-support, easytag, gitit, gnash, gnome-control-center, gnome-keyring, gnome-shell, gnome-software, graphite2, gtk+2.0, gupnp, gvfs, gyp, hgview, htmlcxx, i3status, imms, irker, jmapviewer, katarakt, kmod, lastpass-cli, libaccounts-glib, libam7xxx, libldm, libopenobex, libsecret, linthesia, mate-session-manager, mpris-remote, network-manager, paprefs, php-opencloud, pisa, pyacidobasic, python-pymzml, python-pyscss, qtquick1-opensource-src, rdkit, ruby-rails-html-sanitizer, shellex, slony1-2, spacezero, spamprobe, sugar-toolkit-gtk3, tachyon, tgt. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them:
  • gnubg/1.05.000-4 by Russ Allbery.
  • grcompiler/4.2-6 by Hideki Yamane.
  • sdlgfx/2.0.25-5 fix by Felix Geyer, uploaded by Gianfranco Costamagna.
Patches submitted which have not made their way to the archive yet:
  • #812876 on glib2.0 by Lunar: ensure that functions are sorted using the C locale when giotypefuncs.c is generated.

diffoscope development diffoscope 48 was released on January 26th. It fixes several issues introduced by the retrieval of extra symbols from Debian debug packages. It also restores compatibility with older versions of binutils which does not support readelf --decompress.

strip-nondeterminism development strip-nondeterminism 0.015-1 was uploaded on January 27th. It fixes handling of signed JAR files which are now going to be ignored to keep the signatures intact.

Package reviews 54 reviews have been removed, 36 added and 17 updated in the previous week. 30 new FTBFS bugs have been submitted by Chris Lamb, Michael Tautschnig, Mattia Rizzolo, Tobias Frost.

Misc. Alexander Couzens and Bryan Newbold have been busy fixing more issues in OpenWrt. Version 1.6.3 of FreeBSD's package manager pkg(8) now supports SOURCE_DATE_EPOCH. Ross Karchner did a lightning talk about reproducible builds at his work place and shared the slides.

Ritesh Raj Sarraf: State of Email Clients on Linux Based Platforms

I've been trying to catch up on my reading list (Thanks to rss2email, now I can hold the list longer, than just marking all as read). And one item from last year's end worth spending time was Thunderbird. Thunderbird has been the email client of choice for many users. The main reason for it being popular has been, in my opinion, it being cross platform. Because that allows users an easy migration path across platforms. It also bring persistence, in terms of features and workflows, to the end users. Perhaps that must have been an important reason for many distributions (Ubuntu) and service providers to promote it as the default email client. A Windows/Mac user migrating to Ubuntu will have a lot better experience if they see familiar tools, and their data and workflows being intact. Mozilla must have executed its plan pretty well, to have been able to get it rolling so far. Because other attempts elsewhere (KDE4 Windows) weren't so easy. Part of the reason maybe that any time a new disruptive update is rolled on (KDE4, GNOME3), a lot many frustrated users are born. It is not that people don't want change. Its just that no one likes to see things break. But unfortunately, in Free Software / Open Source world, that is taken lightly. That's one reason why it takes Mozilla so so so long to implement Maildir in TB, when others (Evolution) have had it for so long. So, recently, Mozilla announced its plans to drop Thunderbird development. It is not something new. Anyone using TB knows how long it has been in Maintenance/ESR mode. What was interesting on LWN was the comments. People talked a lot about DE Native Email clients - Kmail, Sylpheed. TUI Clients and these days Browser based clients. Surprisingly, not much was talked about Evolution. My recent move to GNOME has made me look into letting go of old tools/workflows, and try to embrace newer ones. Of them has been GNOME itself. Changing workflows for email was difficult and frustrating. But knowing that TB doesn't have a bright future, it was important to look for alternatives. Just having waited for Maildir and GTK3 port of TB for so long, was enough. On GNOME, Evolution, may give an initial impression of being in Maintenance mode. Especially given that most GNOME apps are now moving to the new UI, which is more touch friendly. And also, because there were other efforts to have another email client on GNOME, I think it is Yorba. But even in its current form, Evolution is a pretty impressive email client Personal Information Management tool. It already is ported to GTK3. Which implies it is capable of responding to Touch events. It sure could have a revised Touch UI, like what is happening with other GNOME Apps. But I'm happy that it has been defered for now. Revising Evolution won't be an easy task, and knowing that GNOME too is understaffed, breaking a perfectly working tool won't be a good idea. My intent with this blog post is to give credit to my favorite GNOME application, i.e. Evolution. So next time you are looking for an email client alternative, give Evolution a try. Today, it already does:
  • Touch UI
  • Maildir
  • Microsoft Exchange
  • GTK3
  • Addressbook, Notes, Tasks, Calendar - Most Standards Based and Google Services compatible
  • RSS Feed Manager
  • And many more that I may not have been using
The only missing piece is being cross-platform. But given the trend, and available resources, I think that path is not worthy of trying. Keep It Simple. Support one platform and support it well.

Categories:

Keywords:

Like:

Russ Allbery: Review: Oathblood

Review: Oathblood, by Mercedes Lackey
Series: Vows and Honor #3
Publisher: DAW
Copyright: April 1998
ISBN: 0-88677-773-9
Format: Mass market
Pages: 394
I have this story collection listed as the third book in the Vows and Honor series, but as mentioned in the review of The Oathbound, it's more complicated than that. This book has the first Tarma and Kethry story, which is not found in The Oathbound, and two of the better stories from that volume. This is probably the place to start for the series; you're not missing that much from the rest of that book. However, the last three stories ("Wings of Fire," "Spring Plowing at Forst Reach," and "Oathblood") have significant spoilers for Oathbreakers. Therefore, if you care about both avoiding spoilers and reading this series, my recommended reading order is to ignore The Oathbound entirely, read Oathblood up to but not including "Wings of Fire," read Oathbreakers, and then come back here for the last two stories. "Sword-sworn": This is the very first Tarma and Kethry story and hence where this series actually begins. As Lackey notes in her introduction, it's a pretty stock "rape and revenge" story, which is not something I particularly enjoy. Marion Zimmer Bradley liked it well enough to accept it anyway, and I can sort of see why: the dynamic between the two characters sparkles in a few places, and the Shin'a'in world-building isn't bad. The plot, though, is very predictable and not very notable. There isn't much here that you'd be surprised by if you'd read references to these events in later stories. And there's no explanation of a few things one might be curious about, such as where Need came from. (6) "Turnabout": This is one of the two stories also found in The Oathbound. Merchants are plagued by bandits who manage to see through ruses and always catch their guards by surprise (with a particularly nasty bit of rape and murder in one case Tarma and Kethry stories have quite a lot of that). That's enough to get the duo to take the job of luring out the bandits and dealing with them, using a nice bit of magical disguise. This story is also a song on one of the Vows and Honor albums from Firebird (which I also have). It was one of my favorites of Lackey's songs, so I want to like the story (and used to like it a great deal). Unfortunately, the very nasty bit of revenge that the supposed heroes take at the end of the story completely destroyed my enjoyment of it on re-reading. It's essentially a glorification of prison rape, which is a trope that I no longer have any patience for. (4) "The Making of a Legend": In order to explain the differences between the song based on "Turnabout" and the actual story, Lackey invented a bard, Leslac, who loves writing songs about Tarma and Kethry and regularly gets the details wrong, mostly by advertising them as moral crusaders for women instead of mercenaries who want to get paid, much to their deep annoyance. This is his debut in an actual story, featuring an incident that's delightfully contrary to Leslac's expectations. It's a slight story, but I thought it was fun. (6) "Keys": Another story from The Oathbound, this is a locked-room mystery with a bit of magical sleuthing. Kethry attempts to prove that a woman did not murder her husband while Tarma serves as her champion in a (rather broken) version of trial by combat. I think the version here is better than the edited version in The Oathbound, and it's a fairly enjoyable bit of sleuthing. (7) "A Woman's Weapon": I would call this the typical Tarma and Kethry story (except that, for a change, it's missing the rape): they stumble across some sort of serious injustice and put things to right with some hard thinking and a bit of poetic justice. In this case, it's a tannery that's poisoning the land, and a master tanner who can't put a stop to his rival. Competent although not particularly memorable. (6) "The Talisman": A rather depressing little story about a mage who wants shortcuts and a magic talisman that isn't what it appears to be. Not one of my favorites, in part because it has some common Tarma and Kethry problems: unnecessary death, a feeling that the world is very dangerous and that mistakes are fatal, and narrative presentation of the people who die from their stupidity as deserving it. I couldn't shake the feeling that there was probably some better way of resolving this if people had just communicated a bit better. (5) "A Tale of Heroes": Back to the rape, unfortunately, plus a bit of very convenient match-making that I found extremely dubious. For all that Lackey's introduction paints this as a story of empowering people to follow their own paths, the chambermaid of this story didn't seem to have many more choices in her life after meeting Tarma and Kethry than before, even if her physical situation was better. I did like the touch of Tarma and Kethry not being the heroes and victors in the significant magical problem they stumble across, though, and it's a warm-hearted story if you ignore the effects of trauma as much as the story ignores them. (6) "Friendly Fire": An amusing short story about the power of bad luck and Murphy's Law. It hit one of my pet peeves at one point, where Lackey tries to distort the words of someone with a cold and just makes the dialogue irritating to read, but otherwise a lot of fun. (7) "Wings of Fire": I love the Hawkbrothers, so it's always fun when they show up. The villain of this piece is way over the top and leaves much to be desired, but the guest-starring Hawkbrother mostly makes up for it. Once again, Tarma and Kethry get out of a tight spot by thinking harder instead of by having more power, although the villain makes that rather easy via overconfidence. Once again, though, the poetic justice that Lackey's protagonists enjoy leaves a bad taste in my mouth, although it's not quite as bad here as some other stories. (6) "Spring Planting at Forst Reach": On one level, this is a rather prosaic story about training horses (based on Lackey's experience and reading, so a bit better than typical fantasy horse stories). But it's set at Forst Reach, Vanyel's home, some years after Vanyel. I like those people and their gruff approach to life, and it meshes well with Tarma and Kethry's approach. If you enjoy the two showing off their skills and wowing people with new ideas, you'll have fun with this. (7) "Oathblood": As you might guess from the matching title, this novella is the heart of the book and about a quarter of its length. We get to see Kethry's kids, see more of their life in their second (post-Oathbreakers) career, and then get a rather good adventure story of resourceful and thoughtful youngsters, with a nice touch of immature but deeply-meant loyalty. I didn't enjoy it as much as I would have without one of the tactics the kids use to get out of trouble, but my dislike for reading about other people's bowel troubles is partly a personal quirk. This is a pretty typical Lackey story of resourcefulness and courage; if you like this series in general, you'll probably enjoy this one. (7) Rating: 7 out of 10

Junichi Uekawa: Been playing with user namespaces.

Been playing with user namespaces. But it seems we lack documentation, and moreover, it lacks coherent design as an API, probably because we are playing whack a mole on new holes as they are discovered. As for the naming, seems to be called 'userns' in patch sets. The API is unshare(CLONE_NEWUSER) with bunch of files in proc such as /proc/self/uid_map,gid_map. CAP_SETGID seems also be related but not sure if it's doing anything.

31 January 2016

Sean Whitton: Clean forks for GitHub pull requests

As I understand it, having a GitHub profile as a portfolio has become an essential element in applying for entry-level computer programming jobs insightfully, a friend of mine draws a comparison with the rise of unpaid internships in other fields. Something about GitHub that gets in the way of maintaining a presentable portfolio is that forks of other people s repositories made just to submit a pull request can crowd out repositories showcasing one s work. Sometimes pull requests can take months to be responded to by upstream maintainers, leaving unimpressive repositories sitting around on one s profile for all that time. The following Python script, clean-github-pr.py, forks a repository and then sets various attributes of it to make it as obvious as GitHub allows that it s just a temporary fork made in order to submit a pull request. Invoke it like this:
$ clean-github-pr.py upstream-owner/repo-to-fork
You will need the PyGitHub python library, which on a Debian Stretch system can be installed with apt-get install python-github.
#!/usr/bin/python
# clean-github-pr --- Create tidy repositories for pull requests
#
# Copyright (C) 2016  Sean Whitton
#
# clean-github-pr is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# clean-github-pr is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with clean-github-pr.  If not, see <http://www.gnu.org/licenses/>.
import github
import sys
import time
import tempfile
import shutil
import subprocess
import os
CREDS_FILE = os.getenv("HOME") + "/.cache/clean-github-pr-creds"
def main():
    # check arguments
    if len(sys.argv) != 2:
        print sys.argv[0] + ": usage: " + sys.argv[0] + " USER/REPO"
        sys.exit(1)
    # check creds file
    try:
        f = open(CREDS_FILE, 'r')
    except IOError:
        print sys.argv[0] + ": please put your github username and password, separated by a colon, in the file ~/.cache/clean-github-pr-creds"
        sys.exit(1)
    # just to be sure
    os.chmod(CREDS_FILE, 0600)
    # make the fork
    creds = f.readline()
    username = creds.split(":")[0]
    pword = creds.split(":")[1].strip()
    g = github.Github(username, pword)
    u = g.get_user()
    source = sys.argv[1]
    fork = sys.argv[1].split("/")[1]
    print "forking repo " + source
    u.create_fork(g.get_repo(source))
    while True:
        try:
            r = u.get_repo(fork)
        except github.UnknownObjectException:
            print "still waiting"
            time.sleep(5)
        else:
            break
    # set up & push github branch
    user_work_dir = os.getcwd()
    work_area = tempfile.mkdtemp()
    os.chdir(work_area)
    subprocess.call(["git", "clone", "https://github.com/" + username + "/" + fork])
    os.chdir(work_area + "/" + fork)
    subprocess.call(["git", "checkout", "--orphan", "github"])
    subprocess.call(["git", "rm", "-rf", "."])
    with open("README.md", 'w') as f:
        f.write("This repository is just a fork made in order to submit a pull request; please ignore.")
    subprocess.call(["git", "add", "README.md"])
    subprocess.call(["git", "commit", "-m", "fork for a pull request; please ignore"])
    subprocess.call(["git", "push", "origin", "github"])
    os.chdir(user_work_dir)
    shutil.rmtree(work_area)
    # set clean repository settings
    r.edit(fork,
           has_wiki=False,
           description="Fork for a pull request; please ignore",
           homepage="",
           has_issues=False,
           has_downloads=False,
           default_branch="github")
if __name__ == "__main__":
    main()
If you have any suggestions for clean-github-pr.py, please send me a patch or a pull request against the version in my dotfiles repository.

Next.

Previous.