Search Results: "reg"

26 July 2015

Lunar: Reproducible builds: week 12 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Eric Dorlan uploaded automake-1.15/1:1.15-2 which makes the output of mdate-sh deterministic. Original patch by Reiner Herrmann. Kenneth J. Pronovici uploaded epydoc/3.0.1+dfsg-8 which now honors SOURCE_DATE_EPOCH. Original patch by Reiner Herrmann. Chris Lamb submitted a patch to dh-python to make the order of the generated maintainer scripts deterministic. Chris also offered a fix for a source of non-determinism in dpkg-shlibdeps when packages have alternative dependencies. Dhole provided a patch to add support for SOURCE_DATE_EPOCH to gettext. Packages fixed The following 78 packages became reproducible in our setup due to changes in their build dependencies: chemical-mime-data, clojure-contrib, cobertura-maven-plugin, cpm, davical, debian-security-support, dfc, diction, dvdwizard, galternatives, gentlyweb-utils, gifticlib, gmtkbabel, gnuplot-mode, gplanarity, gpodder, gtg-trace, gyoto, highlight.js, htp, ibus-table, impressive, jags, jansi-native, jnr-constants, jthread, jwm, khronos-api, latex-coffee-stains, latex-make, latex2rtf, latexdiff, libcrcutil, libdc0, libdc1394-22, libidn2-0, libint, libjava-jdbc-clojure, libkryo-java, libphone-ui-shr, libpicocontainer-java, libraw1394, librostlab-blast, librostlab, libshevek, libstxxl, libtools-logging-clojure, libtools-macro-clojure, litl, londonlaw, ltsp, macsyfinder, mapnik, maven-compiler-plugin, mc, microdc2, miniupnpd, monajat, navit, pdmenu, pirl, plm, scikit-learn, snp-sites, sra-sdk, sunpinyin, tilda, vdr-plugin-dvd, vdr-plugin-epgsearch, vdr-plugin-remote, vdr-plugin-spider, vdr-plugin-streamdev, vdr-plugin-sudoku, vdr-plugin-xineliboutput, veromix, voxbo, xaos, xbae. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net The statistics on the main page of reproducible.debian.net are now updated every five minutes. A random unreviewed package is suggested in the look at a package form on every build. (h01ger) A new package set based new on the Core Internet Infrastructure census has been added. (h01ger) Testing of FreeBSD has started, though no results yet. More details have been posted to the freebsd-hackers mailing list. The build is run on a new virtual machine running FreeBSD 10.1 with 3 cores and 6 GB of RAM, also sponsored by Profitbricks. strip-nondeterminism development Andrew Ayer released version 0.009 of strip-nondeterminism. The new version will strip locales from Javadoc, include the name of files causing errors, and ignore unhandled (but rare) zip64 archives. debbindiff development Lunar continued its major refactoring to enhance code reuse and pave the way to fuzzy-matching and parallel processing. Most file comparators have now been converted to the new class hierarchy. In order to support for archive formats, work has started on packaging Python bindings for libarchive. While getting support for more archive formats with a common interface is very nice, libarchive is a stream oriented library and might have bad performance with how debbindiff currently works. Time will tell if better solutions need to be found. Documentation update Lunar started a Reproducible builds HOWTO intended to explain the different aspects of making software build reproducibly to the different audiences that might have to get involved like software authors, producers of binary packages, and distributors. Package reviews 17 obsolete reviews have been removed, 212 added and 46 updated this week. 15 new bugs for packages failing to build from sources have been reported by Chris West (Faux), and Mattia Rizzolo. Presentations Lunar presented Debian efforts and some recipes on making software build reproducibly at Libre Software Meeting 2015. Slides and a video recording are available. Misc. h01ger, dkg, and Lunar attended a Core Infrastructure Initiative meeting. The progress and tools mode for the Debian efforts were shown. Several discussions also helped getting a better understanding of the needs of other free software projects regarding reproducible builds. The idea of a global append only log, similar to the logs used for Certificate Transparency, came up on multiple occasions. Using such append only logs for keeping records of sources and build results has gotten the name Binary Transparency Logs . They would at least help identifying a compromised software signing key. Whether the benefits in using such logs justify the costs need more research.

Dirk Eddelbuettel: RcppZiggurat 0.1.3: Faster Random Normal Draws

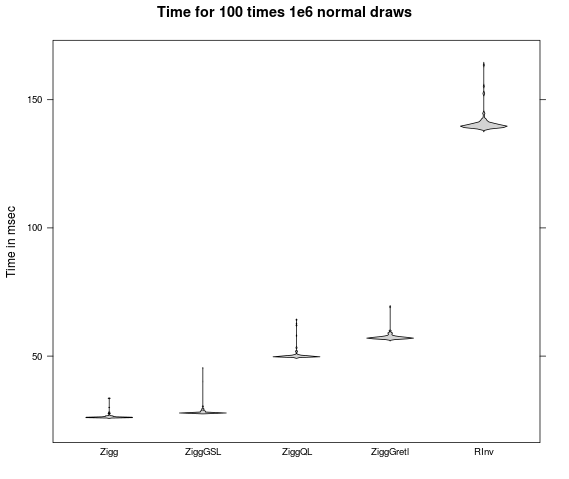
ziggurats After a slight hiatus since the last release in early 2014, we are delighted to announce a new release of RcppZiggurat which is now on the CRAN network for R. The RcppZiggurat package updates the code for the Ziggurat generator which provides very fast draws from a Normal distribution. The package provides a simple C++ wrapper class for the generator improving on the very basic macros, and permits comparison among several existing Ziggurat implementations. This can be seen in the figure where Ziggurat from this package dominates accessing the implementations from the GSL, QuantLib and Gretl---all of which are still way faster than the default Normal generator in R (which is of course of higher code complexity). This release contains a few internal cleanups relative to the last release. It was triggered by a very helpful email from Brian Ripley who notices compiler warnings on the Solaris platform due to my incorrect use of on integer variables. The NEWS file entry below lists all changes.
Changes in version 0.1.3 (2015-07-25)
  • Use the SHR3 generator for the default implementation just like Leong et al do, making our default implementation identical to theirs (but 32- and 64-bit compatible)
  • Switched generators from float to double ensuring that results are identical on 32- and 64-bit platforms
  • Simplified builds with respect to GSL use via the RcppGSL package; added a seed setter for the GSL variant
  • Corrected use of fabs() to abs() on integer variables, with a grateful nod to Brian Ripley for the hint (based on CRAN checks on the beloved Slowlaris machines)
  • Accelerated Travis CI tests by relying exclusively on r-cran-* packages from the PPAs by Michael Rutter and myself
  • Updated DESCRIPTION and NAMESPACE according to current best practices, and R-devel CMD check --as-cran checks
Courtesy of CRANberries, there is also a diffstat report for the most recent release. More information is on the RcppZiggurat page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

25 July 2015

Dirk Eddelbuettel: Rcpp 0.12.0: Now with more Big Data!

big-data image A new release 0.12.0 of Rcpp arrived on the CRAN network for GNU R this morning, and I also pushed a Debian package upload. Rcpp has become the most popular way of enhancing GNU R with C++ code. As of today, 423 packages on CRAN depend on Rcpp for making analyses go faster and further. Note that this is 60 more packages since the last release in May! Also, BioConductor adds another 57 packages, and casual searches on GitHub suggests many more. And according to Andrie De Vries, Rcpp has now page rank of one on CRAN as well! And with this release, Rcpp also becomes ready for Big Data, or, as they call it in Texas, Data. Thanks to a lot of work and several pull requests by Qiang Kou, support for R_xlen_t has been added. That means we can now do stunts like
R> library(Rcpp)
R> big <- 2^31-1
R> bigM <- rep(NA, big)
R> bigM2 <- c(bigM, bigM)
R> cppFunction("double getSz(LogicalVector x)   return x.length();  ")
R> getSz(bigM)
[1] 2147483647
R> getSz(bigM2)
[1] 4294967294
R>
where prior versions of Rcpp would just have said
> getSz(bigM2)
Error in getSz(bigM2) :
  long vectors not supported yet: ../../src/include/Rinlinedfuns.h:137
>
which is clearly not Texas-style. Another wellcome change, also thanks to Qiang Kou, adds encoding support for strings. A lot of other things got polished. We are still improving exception handling as we still get the odd curveballs in a corner cases. Matt Dziubinski corrected the var() computation to use the proper two-pass method and added better support for lambda functions in Sugar expression using sapply(), Qiang Kou added more pull requests mostly for string initialization, and Romain added a pull request which made data frame creation a little more robust, and JJ was his usual self in tirelessly looking after all aspects of Rcpp Attributes. As always, you can follow the development via the GitHub repo and particularly the Issue tickets and Pull Requests. And any discussions, questions, ... regarding Rcpp are always welcome at the rcpp-devel mailing list. Last but not least, we are also extremely pleased to annouce that Qiang Kou has joined us in the Rcpp-Core team. We are looking forward to a lot more awesome! See below for a detailed list of changes extracted from the NEWS file.
Changes in Rcpp version 0.12.0 (2015-07-24)
  • Changes in Rcpp API:
    • Rcpp_eval() no longer uses R_ToplevelExec when evaluating R expressions; this should resolve errors where calling handlers (e.g. through suppressMessages()) were not properly respected.
    • All internal length variables have been changed from R_len_t to R_xlen_t to support vectors longer than 2^31-1 elements (via pull request 303 by Qiang Kou).
    • The sugar function sapply now supports lambda functions (addressing issue 213 thanks to Matt Dziubinski)
    • The var sugar function now uses a more robust two-pass method, supports complex numbers, with new unit tests added (via pull request 320 by Matt Dziubinski)
    • String constructors now allow encodings (via pull request 310 by Qiang Kou)
    • String objects are preserving the underlying SEXP objects better, and are more careful about initializations (via pull requests 322 and 329 by Qiang Kou)
    • DataFrame constructors are now a little more careful (via pull request 301 by Romain Francois)
    • For R 3.2.0 or newer, Rf_installChar() is used instead of Rf_install(CHAR()) (via pull request 332).
  • Changes in Rcpp Attributes:
    • Use more robust method of ensuring unique paths for generated shared libraries.
    • The evalCpp function now also supports the plugins argument.
    • Correctly handle signature termination characters (' ' or ';') contained in quotes.
  • Changes in Rcpp Documentation:
    • The Rcpp-FAQ vignette was once again updated with respect to OS X issues and Fortran libraries needed for e.g. RcppArmadillo.
    • The included Rcpp.bib bibtex file (which is also used by other Rcpp* packages) was updated with respect to its CRAN references.
Thanks to CRANberries, you can also look at a diff to the previous release As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

23 July 2015

Daniel Pocock: Unpaid work training Google's spam filters

This week, there has been increased discussion about the pain of spam filtering by large companies, especially Google. It started with Google's announcement that they are offering a service for email senders to know if their messages are wrongly classified as spam. Two particular things caught my attention: the statement that less than 0.05% of genuine email goes to the spam folder by mistake and the statement that this new tool to understand misclassification is only available to "help qualified high-volume senders". From there, discussion has proceeded with Linus Torvalds blogging about his own experience of Google misclassifying patches from Linux contributors as spam and that has been widely reported in places like Slashdot and The Register. Personally, I've observed much the same thing from the other perspective. While Torvalds complains that he isn't receiving email, I've observed that my own emails are not always received when the recipient is a Gmail address. It seems that Google expects their users work a little bit every day going through every message in the spam folder and explicitly clicking the "Not Spam" button: so that Google can improve their proprietary algorithms for classifying mail. If you just read or reply to a message in the folder without clicking the button, or if you don't do this for every message, including mailing list posts and other trivial notifications that are not actually spam, more important messages from the same senders will also continue to be misclassified. If you are not willing to volunteer your time to do this, or if you are simply one of those people who has better things to do, Google's Gmail service is going to have a corrosive effect on your relationships. A few months ago, we visited Australia and I sent emails to many people who I wanted to catch up with, including invitations to a family event. Some people received the emails in their inboxes yet other people didn't see them because the systems at Google (and other companies, notably Hotmail) put them in a spam folder. The rate at which this appeared to happen was definitely higher than the 0.05% quoted in the Google article above. Maybe the Google spam filters noticed that I haven't sent email to some members of the extended family for a long time and this triggered the spam algorithm? Yet it was at that very moment that we were visiting Australia that email needs to work reliably with that type of contact as we don't fly out there every year. A little bit earlier in the year, I was corresponding with a few students who were applying for Google Summer of Code. Some of them also observed the same thing, they sent me an email and didn't receive my response until they were looking in their spam folder a few days later. Last year I know a GSoC mentor who lost track of a student for over a week because of Google silently discarding chat messages, so it appears Google has not just shot themselves in the foot, they managed to shoot their foot twice. What is remarkable is that in both cases, the email problems and the XMPP problems, Google doesn't send any error back to the sender so that they know their message didn't get through. Instead, it is silently discarded or left in a spam folder. This is the most corrosive form of communication problem as more time can pass before anybody realizes that something went wrong. After it happens a few times, people lose a lot of confidence in the technology itself and try other means of communication which may be more expensive, more synchronous and time intensive or less private. When I discussed these issues with friends, some people replied by telling me I should send them things through Facebook or WhatsApp, but each of those services has a higher privacy cost and there are also many other people who don't use either of those services. This tends to fragment communications even more as people who use Facebook end up communicating with other people who use Facebook and excluding all the people who don't have time for Facebook. On top of that, it creates more tedious effort going to three or four different places to check for messages. Despite all of this, the suggestion that Google's only response is to build a service to "help qualified high-volume senders" get their messages through leaves me feeling that things will get worse before they start to get better. There is no mention in the Google announcement about what they will offer to help the average person eliminate these problems, other than to stop using Gmail or spend unpaid time meticulously training the Google spam filter and hoping everybody else does the same thing. Some more observations on the issue Many spam filtering programs used in corporate networks, such as SpamAssassin, add headers to each email to suggest why it was classified as spam. Google's systems don't appear to give any such feedback to their users or message senders though, just a very basic set of recommendations for running a mail server. Many chat protocols work with an explicit opt-in. Before you can exchange messages with somebody, you must add each other to your buddy lists. Once you do this, virtually all messages get through without filtering. Could this concept be adapted to email, maybe giving users a summary of messages from people they don't have in their contact list and asking them to explicitly accept or reject each contact? If a message spends more than a week in the spam folder and Google detects that the user isn't ever looking in the spam folder, should Google send a bounce message back to the sender to indicate that Google refused to deliver it to the inbox? I've personally heard that misclassification occurs with mailing list posts as well as private messages.

22 July 2015

Cyril Brulebois: D-I Stretch Alpha 1

Time for a quick recap of the beginning of the Stretch release cycle as far as the Debian Installer is concerned: (On a related note, I ve started tweeting rather regularly about my actions, wins & fails, using the #DebianInstaller hashtag. I might try and aggregate my tweets as @CyrilBrulebois into more regular blog posts, time permitting.) Executive summary: D-I Stretch Alpha 1 is released, time to stretch a bit! Stretching cat (Credit: rferran on openclipart)

21 July 2015

Jonathan McDowell: Recovering a DGN3500 via JTAG

Back in 2010 when I needed an ADSL2 router in the US I bought a Netgear DGN3500. It did what I wanted out of the box and being based on a MIPS AR9 (ARX100) it seemed likely OpenWRT support might happen. Long story short I managed to overwrite u-boot (the bootloader) while flashing a test image I d built. I ended up buying a new router (same model) to get my internet connection back ASAP and never getting around to fully fixing the broken one. Until yesterday. Below is how I fixed it; both for my own future reference and in case it s of use any any other unfortunate soul. The device has clear points for serial and JTAG and it was easy enough (even with my basic soldering skills) to put a proper header on. The tricky bit is that the flash is connected via SPI, so it s not just a matter of attaching JTAG, doing a scan and reflashing from the JTAG tool. I ended up doing RAM initialisation, then copying a RAM copy of u-boot in and then using that to reflash. There may well have been a better way, but this worked for me. For reference the failure mode I saw was an infinitely repeating:

ROM VER: 1.1.3
CFG 05
My JTAG device is a Bus Pirate v3b which is much better than the parallel port JTAG device I built the first time I wanted to do something similar. I put the latest firmware (6.1) on it. All of this was done from my laptop, which runs Debian testing (stretch). I used the OpenOCD 0.9.0-1+b1 package from there. Daniel Schwierzeck has some OpenOCD scripts which include a target definition for the ARX100. I added a board definition for the DGN3500 (I ve also send Daniel a patch to add this to his repo). I tied all of this together with an openocd.cfg that contained:
source [find interface/buspirate.cfg]
buspirate_port /dev/ttyUSB1
buspirate_vreg 0
buspirate_mode normal
buspirate_pullup 0
reset_config trst_only
source [find openocd-scripts/target/arx100.cfg]
source [find openocd-scripts/board/dgn3500.cfg]
gdb_flash_program enable
gdb_memory_map enable
gdb_breakpoint_override hard
I was then able to power on the router and type dgn3500_ramboot into the OpenOCD session. This fetched my RAM copy of u-boot from dgn3500_ram/u-boot.bin, copied it into the router s memory and started it running. From there I had a u-boot environment with access to the flash commands and was able to restore the original Netgear image (and once I was sure that was working ok I subsequently upgraded to the Barrier Breaker OpenWRT image).

20 July 2015

Daniel Pocock: RTC status on Debian, Ubuntu and Fedora

Zoltan (Zoltanh721) recently blogged about WebRTC for the Fedora community and Fedora desktop. https://fedrtc.org has been running for a while now and this has given many people a chance to get a taste of regular SIP and WebRTC-based SIP. As suggested in Zoltan's blog, it has convenient integration with Fedora SSO and as the source code is available, people are welcome to see how it was built and use it for other projects. Issues with Chrome/Chromium on Linux If you tried any of FedRTC.org, rtc.debian.org or meet.jit.si using Chrome/Chromium on Linux, you may have found that the call appears to be connected but there is no media. This is a bug and the Chromium developers are on to it. You can work around this by trying an older version of Chromium (it still works with v37 from Debian wheezy) or Firefox/Iceweasel. WebRTC is not everything WebRTC offers many great possibilities for people to quickly build and deploy RTC services to a large user base, especially when using components like JSCommunicator or the DruCall WebRTC plugin for Drupal. However, it is not a silver bullet. For example, there remain concerns about how to receive incoming calls. How do you know which browser tab is ringing when you have many tabs open at once? This may require greater browser/desktop integration and that has security implications for JavaScript. Whether users on battery-powered devices can really leave JavaScript running for extended periods of time waiting for incoming calls is another issue, especially when you consider that many web sites contain some JavaScript that is less than efficient. Native applications and mobile apps like Lumicall continue to offer the most optimized solution for each platform although WebRTC currently offers the most convenient way for people to place a Call me link on their web site or portal. Deploy it yourself The RTC Quick Start Guide offers step-by-step instructions and a thorough discussion of the architecture for people to start deploying RTC and WebRTC on their own servers using standard packages on many of the most popular Linux distributions, including Debian, Ubuntu, RHEL, CentOS and Fedora.

Ritesh Raj Sarraf: Micro DD meetup

A couple of us DDs met here on the weekend. It is always a fun time, being part of these meetings. We talked briefly about the status of Cross Compilation in Debian, on the tools that simplify the process. Next we touched upon licensing, discussing the benefits of particular licenses (BSD, Apache, GPL) from the point of view of the consumer. The consumer being an individual just wanting to use/improve software, to a consumer who's building a (free / non-free) product on top of it. I think the overall conclusion was that there are 2 major licenses at a high level: Ones those allow you take the code and not give back, and the others which allow you to take code only if you are ready to share the enhancements back and forward. Next we briefly touched upon systemd. Given that I recently spent a good amount of time talking to the systemd maintainer while fixing bugs in my software, it was natural for me to steer that topic. At the end, more people are now enthused to learn the paradigm shift. The other topic where we spent time was on Containers. It is impressive to see how quick, and how many, products have now spun out of cgroups. The topic moved to cgroups, thanks to systemd, one of the prime consumers of cgroups. While demonstrating the functionalities of Linux Containers (LXC), I realized that systemd has a tool in place to serve the same use case. So, once back home, I spent some time figuring out the possibility to replace my lxc setup, with that of systemd-nspawn. Apart from a minor bug, almost everything else seems to work find with systemd-nspawn. So, following is the config detail of my container, as used in lxc. And to replace lxc, I need to fill is almost all of it with systemd-nspawn.
rrs@learner:~$ sudo cat /var/lib/lxc/deb-template/config
# Template used to create this container: /usr/share/lxc/templates/lxc-debian
# Parameters passed to the template:
# For additional config options, please look at lxc.container.conf(5)
# CPU
lxc.cgroup.cpuset.cpus = 0,1
lxc.cgroup.cpu.shares = 1234
# Mem
lxc.cgroup.memory.limit_in_bytes = 2000M
lxc.cgroup.memory.soft_limit_in_bytes = 1500M
# Network
lxc.network.type = veth
lxc.network.hwaddr = 00:16:3e:0c:c5:d4
lxc.network.flags = up
lxc.network.link = lxcbr0
# Root file system
lxc.rootfs = /var/lib/lxc/deb-template/rootfs
# Common configuration
lxc.include = /usr/share/lxc/config/debian.common.conf
# Container specific configuration
lxc.mount = /var/lib/lxc/deb-template/fstab
lxc.utsname = deb-template
lxc.arch = amd64
# For apt
lxc.mount.entry = /var/cache/apt/archives var/cache/apt/archives none defaults,bind 0 0
lxc.mount.entry = /var/tmp/lxc var/tmp/lxc none defaults,bind 0 0
2015-07-20 / 16:28:58         
The equivalent of the above, in systemd-nspawn is:
sudo systemd-nspawn -n -b --machine deb-template --network-bridge=lxcbr0 --bind /var/cache/apt/archives/
The only missing bit is CPU and Memory, which I'm yet to try, is documented as doable with the systemctl --property= interface
      --property=
           Set a unit property on the scope unit to register for the machine. This only
           applies if the machine is run in its own scope unit, i.e. if --keep-unit is not
           used. Takes unit property assignments in the same format as systemctl
           set-property. This is useful to set memory limits and similar for machines.
With all this in place, using containers under systemd is a breeze.
rrs@learner:~/Community/Packaging/multipath-tools (experimental)$ sudo machinectl list
MACHINE      CLASS     SERVICE
deb-template container nspawn
1 machines listed.
2015-07-20 / 16:44:07         
rrs@learner:~/Community/Packaging/multipath-tools (experimental)$ sudo machinectl status deb-template
deb-template
           Since: Mon 2015-07-20 16:13:58 IST; 30min ago
          Leader: 9064 (systemd)
         Service: nspawn; class container
            Root: /var/lib/lxc/deb-template/rootfs
           Iface: lxcbr0
         Address: 172.16.10.12
                  fe80::706d:e4ff:fec5:bfc8%3
              OS: Debian GNU/Linux stretch/sid
            Unit: machine-deb\x2dtemplate.scope
                   9064 /lib/systemd/systemd --system --deserialize 14
                   system.slice
                     systemd-journald.service
                       9092 /lib/systemd/systemd-journald
                     ssh.service
                       9160 /usr/sbin/sshd -D
                     console-getty.service
                       9166 /bin/login --     
                       9171 -bash
                       9226 dhclient host0
Jul 20 16:13:58 learner systemd[1]: Started Container deb-template.
Jul 20 16:13:58 learner systemd[1]: Starting Container deb-template.
2015-07-20 / 16:44:15         

Categories:

Keywords:

Like:

19 July 2015

Gregor Herrmann: RC bugs 2015/17-29

after the release is before the release. or: long time no RC bug report. after the jessie release I spent most of my Debian time on work in the Debian Perl Group. we tried to get down the list of new upstream releases (from over 500 to currently 379; unfortunately the CPAN never sleeps), we were & still are busy preparing for the Perl 5.22 transition (e.g. we uploaded something between 300 & 400 packages to deal with Module::Build & CGI.pm being removed from perl core; only team-maintained packages so far), & we had a pleasant & productive sprint in Barcelona in May. & I also tried to fix some of the RC bugs in our packages which popped up over the previous months. yesterday & today I finally found some time to help with the GCC 5 transition, mostly by making QA or Non-Maintainer Uploads with patches that already were in the BTS. a big thanks especially to the team at HP which provided a couple dozens patches! & here's the list of RC bugs I've worked on in the last 3 months:

18 July 2015

Niels Thykier: Performance tuning of lintian

For quite a while, Lintian has been able to create performance logs (--perf-debug --perf-output perf.log) that help diagnose where lintian spends most of its runtime. I decided to make lintian output these logs on lintian.debian.org to help us spot performance issues, though I have not been very good at analysing them regularly. At the beginning of the month, I finally got around to look a bit into one of them. My findings on IRC triggered Mattia Rizzolo to create this following graph. It shows the accumulated runtime of each check/collection measured in seconds. Find these findings, we set out to solve some of the issues. This lead to the following changes in 2.5.33 (in no particular order): Legend: S: run single threaded (1:1 performance improvement). P: run in parallel. Overall, I doubt the changes will give a revolutionary change in speed, but it should improve the 3rd, 4th and 5th slowest parts in Lintian. Beyond runtime performance, we got a few memory optimisations in the pipeline for Lintian 2.5.34: Combined these 6 commits reduce memory consumption in caches by ~33% compared to 2.5.33, when lintian processes itself. In absolute numbers, we are talking about a drop from 12.53MB to 8.48MB. The mileages can certainly vary depending on the package (mscgen only saw an ~25% improvement). Nevertheless, I was happy to list #715035 as being closed in 2.5.34. :)
Filed under: Debian, Lintian

17 July 2015

Dirk Eddelbuettel: RcppRedis 0.1.5

Another small update to RcppRedis arrived on CRAN this morning. The fix I made a few days ago addressing a unit test setup (for the rredis package loaded only for a comparison) didn't quite work out.
Changes in version 0.1.5 (2015-07-17)
  • Another minor fix to unit test setup for rredis.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. More information is on the RcppRedis page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RcppTOML 0.0.4

We introduced RcppTOML in April with the initial CRAN release 0.0.3. It permits R to read the (absolutely awesome) TOML format which is simply fabulous for configuration files. A new version appeared on CRAN yesterday. We had observed a somewhat rare segfault in our production use which came down me dereferencing a list iterator which checking length first. Ooops. As usual, a few other changes were made as, mostly to stay on the good side of R CMD check --as-cran for the development version of R. Courtesy of CRANberries, there is also a diffstat report for this release More information is on the RcppRedis page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

16 July 2015

Dirk Eddelbuettel: RcppEigen 0.3.2.5.0

A new release of RcppEigen arrived on CRAN and in Debian yesterday. It synchronizes the Eigen code with the 3.2.5 upstream release. Once again, Yixuan Qiu did most of the heavy lifting in one very nice pull request, and I added some minor updates to keep R CMD check --as-cran happy. The NEWS file entry follows.
Changes in RcppEigen version 0.3.2.5.0 (2015-07-11)
  • Updated to version 3.2.5 of Eigen
  • Fixed some incorrect error messages stemming from Eigen code.
  • Updated package to current R CMD check standards.
Courtesy of CRANberries, there is also a diffstat report for the most recent release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

14 July 2015

Matthew Palmer: Why DANE isn't going to win

In a comment to my previous post, Daniele asked the entirely reasonable question,
Would you like to comment on why you think that DNSSEC+DANE are not a possible and much better alternative?
Where DANE fails to be a feasible alternative to the current system is that it is not widely acknowledged to be superior in every possible way . A weak demonstration of this is that no browser has implemented DANE support, and very few other TLS-using applications have, either. The only thing I use which has DANE support that I m aware of is Postfix and SMTP is an application in which the limitations of DANE have far less impact. My understanding of the limitations of DANE, for large-scale deployment, are enumerated below.

DNS Is Awful Quoting Google security engineer Adam Langley:
But many (~4% in past tests) of users can t resolve a TXT record when they can resolve an A record for the same name. In practice, consumer DNS is hijacked by many devices that do a poor job of implementing DNS.
Consider that TXT records are far, far older than TLSA records. It seems likely that TLSA records would fail to be retrieved greater than 4% of the time. Extrapolate to the likely failure rate for lookup of TLSA records would be, and imagine what that would do to the reliability of DANE verification. It would either be completely unworkable, or else would cause a whole new round of just click through the security error training. Ugh. This also impacts DNSSEC itself. Lots of recursive resolvers don t validate DNSSEC, and some providers mangle DNS responses in some way, which breaks DNSSEC. Since OSes don t support DNSSEC validation by default (for example, by having the name resolution APIs indicate DNSSEC validation status), browsers would essentially have to ship their own validating resolver code. Some people have concerns around the single point of control for DNS records, too. While the weakest link nature of the CA model is terribad, there is a significant body of opinion that replacing it with a single, minimally-accountable organisation like ICANN isn t a great trade. Finally, performance is also a concern. Having to go out-of-band to retrieve TLSA records delays page generation, and nobody likes slow page loads.

DNSSEC Is Awful Lots of people don t like DNSSEC, for all sorts of reasons. While I don t think it is quite as bad as people make out (I ve deployed it for most zones I manage, there are some legitimate issues that mean browser vendors aren t willing to rely on DNSSEC. 1024 bit RSA keys are quite common throughout the DNSSEC system. Getting rid of 1024 bit keys in the PKI has been a long-running effort; doing the same for DNSSEC is likely to take quite a while. Yes, rapid rotation is possible, by splitting key-signing and zone-signing (a good design choice), but since it can t be enforced, it s entirely likely that long-lived 1024 bit keys for signing DNSSEC zones is the rule, rather than exception.

DNS Providers are Awful While we all poke fun at CAs who get compromised, consider how often someone s DNS control panel gets compromised. Now ponder the fact that, if DANE is supported, TLSA records can be manipulated in that DNS control panel. Those records would then automatically be DNSSEC signed by the DNS provider and served up to anyone who comes along. Ouch. In theory, of course, you should choose a suitably secure DNS provider, to prevent this problem. Given that there are regular hijackings of high-profile domains (which, presumably, the owners of those domains would also want to prevent), there is something in the DNS service provider market which prevents optimal consumer behaviour. Market for lemons, perchance?

Conclusion None of these problems are unsolvable, although none are trivial. I like DANE as a concept, and I d really, really like to see it succeed. However, the problems I ve listed above are all reasonable objections, made by people who have their hands in browser codebases, and so unless they re fixed, I don t see that anyone s going to be able to rely on DANE on the Internet for a long, long time to come.

13 July 2015

Dirk Eddelbuettel: RcppGSL 0.2.5

A new version of RcppGSL arrived on CRAN a couple of days ago. This package provides an interface from R to the GNU GSL using our Rcpp package. In the course of preparation for the higher-performance R via C++ course I gave in Zuerich last month, I overhauled this package, its embedded package (!!) showing how to build a package which uses R, C++ and the GSL (and which can serve as a fine example of how to build and R and C++ package using an external library), and also overhauled the vignette which discusses all these aspect. All examples now consistently use Rcpp Attributes. The NEWS file entries follows below:
Changes in version 0.2.5 (2015-07-05)
  • The colnorm function in the included example package was rewritten to use Rcpp Attributes, the example package was updated and its version number increased to 0.0.3.
  • The unit tests also use the updated version of the example package.
  • The package, and the included example package, were updated throughout to conform to the current R CMD check standards.
  • The RcppGSL-intro vignette was updated throughout.
  • The Travis CI integration now uses r-cran-* packages which leads to faster tests.
Courtesy of CRANberries, a summary of changes to the most recent release is available. More information is on the RcppGSL page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 July 2015

Lunar: Reproducible builds: week 11 in Stretch cycle

Debian is undertaking a huge effort to develop a reproducible builds system. I'd like to thank you for that. This could be Debian's most important project, with how badly computer security has been going.

PerniciousPunk in Reddit's Ask me anything! to Neil McGovern, DPL. What happened in the reproducible builds effort this week: Toolchain fixes More tools are getting patched to use the value of the SOURCE_DATE_EPOCH environment variable as the current time:

In the reproducible experimental toolchain which have been uploaded: Johannes Schauer followed up on making sbuild build path deterministic with several ideas. Packages fixed The following 311 packages became reproducible due to changes in their build dependencies : 4ti2, alot, angband, appstream-glib, argvalidate, armada-backlight, ascii, ask, astroquery, atheist, aubio, autorevision, awesome-extra, bibtool, boot-info-script, bpython, brian, btrfs-tools, bugs-everywhere, capnproto, cbm, ccfits, cddlib, cflow, cfourcc, cgit, chaussette, checkbox-ng, cinnamon-settings-daemon, clfswm, clipper, compton, cppcheck, crmsh, cupt, cutechess, d-itg, dahdi-tools, dapl, darnwdl, dbusada, debian-security-support, debomatic, dime, dipy, dnsruby, doctrine, drmips, dsc-statistics, dune-common, dune-istl, dune-localfunctions, easytag, ent, epr-api, esajpip, eyed3, fastjet, fatresize, fflas-ffpack, flann, flex, flint, fltk1.3, fonts-dustin, fonts-play, fonts-uralic, freecontact, freedoom, gap-guava, gap-scscp, genometools, geogebra, git-reintegrate, git-remote-bzr, git-remote-hg, gitmagic, givaro, gnash, gocr, gorm.app, gprbuild, grapefruit, greed, gtkspellmm, gummiboot, gyp, heat-cfntools, herold, htp, httpfs2, i3status, imagetooth, imapcopy, imaprowl, irker, jansson, jmapviewer, jsdoc-toolkit, jwm, katarakt, khronos-opencl-man, khronos-opengl-man4, lastpass-cli, lava-coordinator, lava-tool, lavapdu, letterize, lhapdf, libam7xxx, libburn, libccrtp, libclaw, libcommoncpp2, libdaemon, libdbusmenu-qt, libdc0, libevhtp, libexosip2, libfreenect, libgwenhywfar, libhmsbeagle, libitpp, libldm, libmodbus, libmtp, libmwaw, libnfo, libpam-abl, libphysfs, libplayer, libqb, libsecret, libserial, libsidplayfp, libtime-y2038-perl, libxr, lift, linbox, linthesia, livestreamer, lizardfs, lmdb, log4c, logbook, lrslib, lvtk, m-tx, mailman-api, matroxset, miniupnpd, mknbi, monkeysign, mpi4py, mpmath, mpqc, mpris-remote, musicbrainzngs, network-manager, nifticlib, obfsproxy, ogre-1.9, opal, openchange, opensc, packaging-tutorial, padevchooser, pajeng, paprefs, pavumeter, pcl, pdmenu, pepper, perroquet, pgrouting, pixz, pngcheck, po4a, powerline, probabel, profitbricks-client, prosody, pstreams, pyacidobasic, pyepr, pymilter, pytest, python-amqp, python-apt, python-carrot, python-django, python-ethtool, python-mock, python-odf, python-pathtools, python-pskc, python-psutil, python-pypump, python-repoze.tm2, python-repoze.what, qdjango, qpid-proton, qsapecng, radare2, reclass, repsnapper, resource-agents, rgain, rttool, ruby-aggregate, ruby-albino, ruby-archive-tar-minitar, ruby-bcat, ruby-blankslate, ruby-coffee-script, ruby-colored, ruby-dbd-mysql, ruby-dbd-odbc, ruby-dbd-pg, ruby-dbd-sqlite3, ruby-dbi, ruby-dirty-memoize, ruby-encryptor, ruby-erubis, ruby-fast-xs, ruby-fusefs, ruby-gd, ruby-git, ruby-globalhotkeys, ruby-god, ruby-hike, ruby-hmac, ruby-integration, ruby-jnunemaker-matchy, ruby-memoize, ruby-merb-core, ruby-merb-haml, ruby-merb-helpers, ruby-metaid, ruby-mina, ruby-net-irc, ruby-net-netrc, ruby-odbc, ruby-ole, ruby-packet, ruby-parseconfig, ruby-platform, ruby-plist, ruby-popen4, ruby-rchardet, ruby-romkan, ruby-ronn, ruby-rubyforge, ruby-rubytorrent, ruby-samuel, ruby-shoulda-matchers, ruby-sourcify, ruby-test-spec, ruby-validatable, ruby-wirble, ruby-xml-simple, ruby-zoom, rumor, rurple-ng, ryu, sam2p, scikit-learn, serd, shellex, shorewall-doc, shunit2, simbody, simplejson, smcroute, soqt, sord, spacezero, spamassassin-heatu, spamprobe, sphinxcontrib-youtube, splitpatch, sratom, stompserver, syncevolution, tgt, ticgit, tinyproxy, tor, tox, transmissionrpc, tweeper, udpcast, units-filter, viennacl, visp, vite, vmfs-tools, waffle, waitress, wavtool-pl, webkit2pdf, wfmath, wit, wreport, x11proto-input, xbae, xdg-utils, xdotool, xsystem35, yapsy, yaz. Please note that some packages in the above list are falsely reproducible. In the experimental toolchain, debhelper exported TZ=UTC and this made packages capturing the current date (without the time) reproducible in the current test environment. The following packages became reproducible after getting fixed: Ben Hutchings upstreamed several patches to fix Linux reproducibility issues which were quickly merged. Some uploads fixed some reproducibility issues but not all of them: Uploads that should fix packages not in main: Patches submitted which have not made their way to the archive yet: reproducible.debian.net A new package set has been added for lua maintainers. (h01ger) tracker.debian.org now only shows reproducibility issues for unstable. Holger and Mattia worked on several bugfixes and enhancements: finished initial test setup for NetBSD, rewriting more shell scripts in Python, saving UDD requests, and more debbindiff development Reiner Herrmann fixed text comparison of files with different encoding. Documentation update Juan Picca added to the commands needed for a local test chroot installation of the locales-all package. Package reviews 286 obsolete reviews have been removed, 278 added and 243 updated this week. 43 new bugs for packages failing to build from sources have been filled by Chris West (Faux), Mattia Rizzolo, and h01ger. The following new issues have been added: timestamps_in_manpages_generated_by_ronn, timestamps_in_documentation_generated_by_org_mode, and timestamps_in_pdf_generated_by_matplotlib. Misc. Reiner Herrmann has submitted patches for OpenWrt. Chris Lamb cleaned up some code and removed cruft in the misc.git repository. Mattia Rizzolo updated the prebuilder script to match what is currently done on reproducible.debian.net.

Dirk Eddelbuettel: RcppRedis 0.1.4

A small update to RcppRedis arrived on CRAN a few days ago. One of the unit tests failed as we (still) initialized the rredis package (loaded only for a comparison) in a form long-internalized by Bryan Lewis, its author. No actual changes to functionality were; the only other changes is cosmetic and in response a R CMD check requirement where the curl binary seemingly fails to follow redirects so we removed the (official !) redis.io URL.
Changes in version 0.1.4 (2015-07-04)
  • Minor update to unit test setup for rredis.
  • No longer list URLs to Redis as automated CRAN tests for URL validity choke on redirects.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. More information is on the RcppRedis page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 July 2015

Dirk Eddelbuettel: random 0.2.5

A few days ago and while we were traveling, an updated release of our random package for truly (hardware-based) random numbers as provided by random.org arrived on CRAN. Brian Ripley had pointed out to us that some of the curl implementations (which must now be used as https is mandatory at random.org) did not follow redirects. Which was bad luck, given that I had used a shortform https://random.org as opposed to the fuller-length https://wwwrandom.org variant providing the service. This has been rectified, and we used the opportunity to also update the DESCRIPTION and NAMESPACE file as R CMD check --as-cran now mandates more explicit imports. Courtesy of CRANberries comes a diffstat report for this release. Current and previous releases are available here as well as on CRAN.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

10 July 2015

Chris Lamb: Where's the principled opposition to the "WhatsApp ban"?

The Independent reports that David Cameron wishes to ban the instant messaging application WhatsApp due its use of end-to-end encryption. That we might merely be pawns in manoeuvring for some future political compromise (or merely susceptible to cheap clickbait) should be cause for some concern, but what should worry us more is that if it takes scare stories about WhatsApp for our culture to awaken on the issues of privacy and civil liberties, then the central argument against surveillance was lost a long time ago. However, the situation worsens once you analyse the disapproval in more detail. One is immediately struck by a predominant narrative of technical considerations; a ban would be "unworkable" or "impractical". A robust defence of personal liberty or a warning about the insidious nature of chilling effects? Perhaps a prescient John Locke quote to underscore the case? No. An encryption ban would "cause security problems." The argument proceeds in a tediously predictable fashion: it was already difficult to keep track whether one should ipso facto be in favour of measures that benefit the economy, but we are suddenly co-opted as technocrats to consider the "damage" it could to do the recovery or the impact on a now-victimised financial sector. The coup-de-gr ce finally appeals to our already inflated self-regard and narcissism: someone could "steal your identity." Perhaps even more disappointing is the reaction from more technically-minded circles who, frankly, should know better. Here, they give the outward impression of metaphorically stockpiling copies of the GnuPG source code in their bunkers, perhaps believing the shallow techno-utopianist worldview that all social and cultural problems can probably be solved with Twitter and a JavaScript intepreter. The tragedy here is that I suspect that this isn't what the vast majority of people really believe. Given a hypothetical ban that could, somehow, bypass all of the stated concerns, I'm pretty upbeat and confident that most people would remain uncomfortable with it on some level. So what, exactly, does it take for us to oppose this kind of intervention on enduring principled grounds instead of transient and circumventable practical ones? Is the problem just a lack of vocabulary to discuss these issues on a social scale? A lack of courage? Whilst it's certainly easier to dissect illiberal measures on technical merit than to make an impassioned case for abstract freedoms, every time we gleefully cackle "it won't work" we are, in essence, conceding the central argument to the authoritarian and the censorious. If one is right but for the wrong reasons, were we even right to begin with?

Gunnar Wolf: Finishing the course on "Free Software and Open Standards"

A couple of months ago, I was invited to give the starting course for the Masters degree in Free Software in the Universidad Andina Sim n Bol var university. UASB is a multinational university, with campuses in (at least) Ecuador, Chile, Bolivia and Colombia; I was doubtful at first regarding the seriousness of this proposal and the viability of the program, but time made my doubts disappear. Bolivia is going through an interesting process, as they have one of the strongest worded government mandates for migration to free software for the public administration in the next couple of years; this migration has prompted the interest of many professionals in the country. In particular, we have over 40 registered people for this Masters degree. Studying a Masters degree is a long-term commitment which signifies a big time investment, and although many of the student are quite new to the idea of free software, they are willing to spend this time (and money, as the university is privately owned and charges for its enrollment). I gave this class together with Alejandro Miranda (a.k.a. @pooka), as we have a very good pair-teaching dynamics; we had already given many conferences together, but this is the first time we had the opportunity to share a whole course and the experience was very good. We have read the students' logs, and many of them clearly agree with this. I had to skip two of the (ten) lessons, as I travelled from Mexico to Argentina halfway through it (of course, we brought the babies to meet my wife's family and friends!), so we had also the honor of having Esteban Lima fill in for those sessions. I am very happy and grateful that the University took care to record our presentations and intend to record and put online all of the classes; as we were the first in the program, there were some understandable hiccups and some sessions were lost, but most are available. Here they are, in case you are interested in refering to them:
Topic Video (my server) Video (Youtube)
Introduction to free software Watch Watch
History Watch Watch
Free culture N/A N/A
The effects of free software Watch Watch
Free software and open standards related to technologic soverignity Watch Watch
The free software ecosystem Watch Watch
Free software implementation in Bolivia Watch Watch
Introduction to intelectual property: Copyright, patents, trademarks, etc. Watch Watch
Who is "the community" and why do we speak about it? Watch Watch
Current status and challenges for the movement N/A N/A
We have yet another video file (which I have not fully followed through) titled ADSIB - Migration plan. It can also be downloaded from my server or watched online at Youtube. All in all: This was a great opportunity and a joy to do. I think the material we used and developed fit well what was expected from us, and we had fun giving somewhat heterodox readings on our movement.

Next.

Previous.