Search Results: "xam"

7 May 2025

Jonathan Dowland: procmail versus exim filters

I ve been using Procmail to filter mail for a long time. Reading Antoine s blog post procmail considered harmful, I felt motivated (and shamed) into migrating to something else. Luckily, Enrico's shared a detailed roadmap for moving to Sieve, in particular Dovecot's Sieve implementation (which provides "pipe" and "filter" extensions). My MTA is Exim, and for my first foray into this, I didn't want to change that1. Exim provides two filtering languages for users: an implementation of Sieve, and its own filter language. Requirements A good first step is to look at what I'm using Procmail for:
  1. I invoke external mail filters: processes which read the mail and emit a possibly altered mail (headers added, etc.). In particular, crm114 (which has worked remarkably well for me) to classify mail as spam or not, and dsafilter, to mark up Debian Security Advisories
  2. I file messages into different folders depending on the outcome of the above filters
  3. I drop mail ("killfile") some sender addresses (persistent pests on mailing lists); and mails containing certain hosts in the References header (as an imperfect way of dropping mailing list threads which are replies to someone I've killfiled); and mail encoded in a character set for a language I can't read (Russian, Korean, etc.), and several other simple static rules
  4. I move mailing list mail into folders, semi-automatically (see list filtering)
  5. I strip "tagged" subjects for some mailing lists: i.e., incoming mail has subjects like "[cs-historic-committee] help moving several tons of IBM360", and I don't want the "[cs-historic-committee]" bit.
  6. I file a copy of some messages, the name of which is partly derived from the current calendar year
Exim Filters I want to continue to do (1), which rules out Exim's implementation of Sieve, which does not support invoking external programs. Exim's own filter language has a pipe function that might do what I need, so let's look at how to achieve the above with Exim Filters. autolists Here's an autolist recipe for Debian's mailing lists, in Exim filter language. Contrast with the Procmail in list filtering:
if $header_list-id matches "(debian.*)\.lists\.debian\.org"
then
  save Maildir/l/$1/
  finish
endif
Hands down, the exim filter is nicer (although some of the rules on escape characters in exim filters, not demonstrated here, are byzantine). killfile An ideal chunk of configuration for kill-filing a list of addresses is light on boiler plate, and easy to add more addresses to in the future. This is the best I could come up with:
if foranyaddress "someone@example.org,\
                  another@example.net,\
                  especially-bad.example.com,\
                 "
   ($reply_address contains $thisaddress
    or $header_references contains $thisaddress)
then finish endif
I won't bother sharing the equivalent Procmail but it's pretty comparable: the exim filter is no great improvement. It would be lovely if the list of addresses could be stored elsewhere, such as a simple text file, one line per address, or even a database. Exim's own configuration language (distinct from this filter language) has some nice mechanisms for reading lists of things like addresses from files or databases. Sadly it seems the filter language lacks anything similar. external filters With Procmail, I pass the mail to an external program, and then read the output of that program back, as the new content of the mail, which continues to be filtered: subsequent filter rules inspect the headers to see what the outcome of the filter was (is it spam?) and to decide what to do accordingly. Crucially, we also check the return status of the filter, to handle the case when it fails. With Exim filters, we can use pipe to invoke an external program:
pipe "$home/mail/mailreaver.crm -u $home/mail/"
However, this is not a filter: the mail is sent to the external program, and the exim filter's job is complete. We can't write further filter rules to continue to process the mail: the external program would have to do that; and we have no way of handling errors. Here's Exim's documentation on what happens when the external command fails:
Most non-zero codes are treated by Exim as indicating a failure of the pipe. This is treated as a delivery failure, causing the message to be returned to its sender.
That is definitely not what I want: if the filter broke (even temporarily), Exim would seemingly generate a bounce to the sender address, which could be anything, and I wouldn't have a copy of the message. The documentation goes on to say that some shell return codes (defaulting to 73 and 75) cause Exim to treat it as a temporary error, spool the mail and retry later on. That's a much better behaviour for my use-case. Having said that, on the rare occasions I've broken the filter, the thing which made me notice most quickly was spam hitting my inbox, which my Procmail recipe achieves. removing subject tagging Here, Exim's filter language gets unstuck. There is no way to add or alter headers for a message in a user filter. Exim uses the same filter language for system-wide message filtering, and in that context, it has some extra functions: headers add <string>, headers remove <string>, but (for reasons I don't know) these are not available for user filters. copy mail to archive folder I can't see a way to derive a folder name from the calendar year. next steps Exim Sieve implementation and its filter language are ruled out as Procmail replacements because they can't do at least two of the things I need to do. However, based on Enrico's write-up, it looks like Dovecot's Sieve implementation probably can. I was also recommended maildrop, which I might look at if Dovecot Sieve doesn't pan out.

  1. I should revisit this requirement because I could probably reconfigure exim to run my spam classifier at the system level, obviating the need to do it in a user filter, and also raising the opportunity to do smtp-time rejection based on the outcome

5 May 2025

Sergio Talens-Oliag: Argo CD Usage Examples

As a followup of my post about the use of argocd-autopilot I m going to deploy various applications to the cluster using Argo CD from the same repository we used on the previous post. For our examples we are going to test a solution to the problem we had when we updated a ConfigMap used by the argocd-server (the resource was updated but the application Pod was not because there was no change on the argocd-server deployment); our original fix was to kill the pod manually, but the manual operation is something we want to avoid. The proposed solution to this kind of issues on the helm documentation is to add annotations to the Deployments with values that are a hash of the ConfigMaps or Secrets used by them, this way if a file is updated the annotation is also updated and when the Deployment changes are applied a roll out of the pods is triggered. On this post we will install a couple of controllers and an application to show how we can handle Secrets with argocd and solve the issue with updates on ConfigMaps and Secrets, to do it we will execute the following tasks:
  1. Deploy the Reloader controller to our cluster. It is a tool that watches changes in ConfigMaps and Secrets and does rolling upgrades on the Pods that use them from Deployment, StatefulSet, DaemonSet or DeploymentConfig objects when they are updated (by default we have to add some annotations to the objects to make things work).
  2. Deploy a simple application that can use ConfigMaps and Secrets and test that the Reloader controller does its job when we add or update a ConfigMap.
  3. Install the Sealed Secrets controller to manage secrets inside our cluster, use it to add a secret to our sample application and see that the application is reloaded automatically.

Creating the test project for argocd-autopilotAs we did our installation using argocd-autopilot we will use its structure to manage the applications. The first thing to do is to create a project (we will name it test) as follows:
  argocd-autopilot project create test
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 18, done.
Counting objects: 100% (18/18), done.
Compressing objects: 100% (16/16), done.
Total 18 (delta 1), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO pushing new project manifest to repo
INFO project created: 'test'
Now that the test project is available we will use it on our argocd-autopilot invocations when creating applications.

Installing the reloader controllerTo add the reloader application to the test project as a kustomize application and deploy it on the tools namespace with argocd-autopilot we do the following:
  argocd-autopilot app create reloader \
    --app 'github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2' \
    --project test --type kustomize --dest-namespace tools
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 19, done.
Counting objects: 100% (19/19), done.
Compressing objects: 100% (18/18), done.
Total 19 (delta 2), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO created 'application namespace' file at '/bootstrap/cluster-resources/in-cluster/tools-ns.yaml'
INFO committing changes to gitops repo...
INFO installed application: reloader
That command creates four files on the argocd repository:
  1. One to create the tools namespace:
    bootstrap/cluster-resources/in-cluster/tools-ns.yaml
    apiVersion: v1
    kind: Namespace
    metadata:
      annotations:
        argocd.argoproj.io/sync-options: Prune=false
      creationTimestamp: null
      name: tools
    spec:  
    status:  
  2. Another to include the reloader base application from the upstream repository:
    apps/reloader/base/kustomization.yaml
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    resources:
    - github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2
  3. The kustomization.yaml file for the test project (by default it includes the same configuration used on the base definition, but we could make other changes if needed):
    apps/reloader/overlays/test/kustomization.yaml
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    namespace: tools
    resources:
    - ../../base
  4. The config.json file used to define the application on argocd for the test project (it points to the folder that includes the previous kustomization.yaml file):
    apps/reloader/overlays/test/config.json
     
      "appName": "reloader",
      "userGivenName": "reloader",
      "destNamespace": "tools",
      "destServer": "https://kubernetes.default.svc",
      "srcPath": "apps/reloader/overlays/test",
      "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
      "srcTargetRevision": "",
      "labels": null,
      "annotations": null
     
We can check that the application is working using the argocd command line application:
  argocd app get argocd/test-reloader -o tree
Name:               argocd/test-reloader
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          tools
URL:                https://argocd.lo.mixinet.net:8443/applications/test-reloader
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/reloader/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (2893b56)
Health Status:      Healthy
KIND/NAME                                          STATUS  HEALTH   MESSAGE
ClusterRole/reloader-reloader-role                 Synced
ClusterRoleBinding/reloader-reloader-role-binding  Synced
ServiceAccount/reloader-reloader                   Synced           serviceaccount/reloader-reloader created
Deployment/reloader-reloader                       Synced  Healthy  deployment.apps/reloader-reloader created
 ReplicaSet/reloader-reloader-5b6dcc7b6f                  Healthy
   Pod/reloader-reloader-5b6dcc7b6f-vwjcx                 Healthy

Adding flags to the reloader serverThe runtime configuration flags for the reloader server are described on the project README.md file, in our case we want to adjust three values:
  • We want to enable the option to reload a workload when a ConfigMap or Secret is created,
  • We want to enable the option to reload a workload when a ConfigMap or Secret is deleted,
  • We want to use the annotations strategy for reloads, as it is the recommended mode of operation when using argocd.
To pass them we edit the apps/reloader/overlays/test/kustomization.yaml file to patch the pod container template, the text added is the following:
patches:
# Add flags to reload workloads when ConfigMaps or Secrets are created or deleted
- target:
    kind: Deployment
    name: reloader-reloader
  patch:  -
    - op: add
      path: /spec/template/spec/containers/0/args
      value:
        - '--reload-on-create=true'
        - '--reload-on-delete=true'
        - '--reload-strategy=annotations'
After committing and pushing the updated file the system launches the application with the new options.

The dummyhttp applicationTo do a quick test we are going to deploy the dummyhttp web server using an image generated using the following Dockerfile:
# Image to run the dummyhttp application <https://github.com/svenstaro/dummyhttp>
# This arg could be passed by the container build command (used with mirrors)
ARG OCI_REGISTRY_PREFIX
# Latest tested version of alpine
FROM $ OCI_REGISTRY_PREFIX alpine:3.21.3
# Tool versions
ARG DUMMYHTTP_VERS=1.1.1
# Download binary
RUN ARCH="$(apk --print-arch)" && \
  VERS="$DUMMYHTTP_VERS" && \
  URL="https://github.com/svenstaro/dummyhttp/releases/download/v$VERS/dummyhttp-$VERS-$ARCH-unknown-linux-musl" && \
  wget "$URL" -O "/tmp/dummyhttp" && \
  install /tmp/dummyhttp /usr/local/bin && \
  rm -f /tmp/dummyhttp
# Set the entrypoint to /usr/local/bin/dummyhttp
ENTRYPOINT [ "/usr/local/bin/dummyhttp" ]
The kustomize base application is available on a monorepo that contains the following files:
  1. A Deployment definition that uses the previous image but uses /bin/sh -c as its entrypoint (command in the k8s Pod terminology) and passes as its argument a string that runs the eval command to be able to expand environment variables passed to the pod (the definition includes two optional variables, one taken from a ConfigMap and another one from a Secret):
    apiVersion: apps/v1
    kind: Deployment
    metadata:
      name: dummyhttp
      labels:
        app: dummyhttp
    spec:
      selector:
        matchLabels:
          app: dummyhttp
      template:
        metadata:
          labels:
            app: dummyhttp
        spec:
          containers:
          - name: dummyhttp
            image: forgejo.mixinet.net/oci/dummyhttp:1.0.0
            command: [ "/bin/sh", "-c" ]
            args:
            - 'eval dummyhttp -b \" \\\"c\\\": \\\"$CM_VAR\\\", \\\"s\\\": \\\"$SECRET_VAR\\\" \"'
            ports:
            - containerPort: 8080
            env:
            - name: CM_VAR
              valueFrom:
                configMapKeyRef:
                  name: dummyhttp-configmap
                  key: CM_VAR
                  optional: true
            - name: SECRET_VAR
              valueFrom:
                secretKeyRef:
                  name: dummyhttp-secret
                  key: SECRET_VAR
                  optional: true
  2. A Service that publishes the previous Deployment (the only relevant thing to mention is that the web server uses the port 8080 by default):
    apiVersion: v1
    kind: Service
    metadata:
      name: dummyhttp
    spec:
      selector:
        app: dummyhttp
      ports:
      - name: http
        port: 80
        targetPort: 8080
  3. An Ingress definition to allow access to the application from the outside:
    apiVersion: networking.k8s.io/v1
    kind: Ingress
    metadata:
      name: dummyhttp
      annotations:
        traefik.ingress.kubernetes.io/router.tls: "true"
    spec:
      rules:
        - host: dummyhttp.localhost.mixinet.net
          http:
            paths:
              - path: /
                pathType: Prefix
                backend:
                  service:
                    name: dummyhttp
                    port:
                      number: 80
  4. And the kustomization.yaml file that includes the previous files:
    apiVersion: kustomize.config.k8s.io/v1beta1
    kind: Kustomization
    resources:
    - deployment.yaml
    - service.yaml
    - ingress.yaml

Deploying the dummyhttp application from argocdWe could create the dummyhttp application using the argocd-autopilot command as we ve done on the reloader case, but we are going to do it manually to show how simple it is. First we ve created the apps/dummyhttp/base/kustomization.yaml file to include the application from the previous repository:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
  - https://forgejo.mixinet.net/blogops/argocd-applications.git//dummyhttp/?ref=dummyhttp-v1.0.0
As a second step we create the apps/dummyhttp/overlays/test/kustomization.yaml file to include the previous file:
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
- ../../base
And finally we add the apps/dummyhttp/overlays/test/config.json file to configure the application as the ApplicationSet defined by argocd-autopilot expects:
 
  "appName": "dummyhttp",
  "userGivenName": "dummyhttp",
  "destNamespace": "default",
  "destServer": "https://kubernetes.default.svc",
  "srcPath": "apps/dummyhttp/overlays/test",
  "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
  "srcTargetRevision": "",
  "labels": null,
  "annotations": null
 
Once we have the three files we commit and push the changes and argocd deploys the application; we can check that things are working using curl:
  curl -s https://dummyhttp.lo.mixinet.net:8443/   jq -M .
 
  "c": "",
  "s": ""
 

Patching the applicationNow we will add patches to the apps/dummyhttp/overlays/test/kustomization.yaml file:
  • One to add annotations for reloader (one to enable it and another one to set the roll out strategy to restart to avoid touching the deployments, as that can generate issues with argocd).
  • Another to change the ingress hostname (not really needed, but something quite reasonable for a specific project).
The file diff is as follows:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,3 +2,22 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+patches:
+# Add reloader annotations
+- target:
+    kind: Deployment
+    name: dummyhttp
+  patch:  -
+    - op: add
+      path: /metadata/annotations
+      value:
+        reloader.stakater.com/auto: "true"
+        reloader.stakater.com/rollout-strategy: "restart"
+# Change the ingress host name
+- target:
+    kind: Ingress
+    name: dummyhttp
+  patch:  -
+    - op: replace
+      path: /spec/rules/0/host
+      value: test-dummyhttp.lo.mixinet.net
After committing and pushing the changes we can use the argocd cli to check the status of the application:
  argocd app get argocd/test-dummyhttp -o tree
Name:               argocd/test-dummyhttp
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          default
URL:                https://argocd.lo.mixinet.net:8443/applications/test-dummyhttp
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/dummyhttp/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (fbc6031)
Health Status:      Healthy
KIND/NAME                           STATUS  HEALTH   MESSAGE
Deployment/dummyhttp                Synced  Healthy  deployment.apps/dummyhttp configured
 ReplicaSet/dummyhttp-55569589bc           Healthy
   Pod/dummyhttp-55569589bc-qhnfk          Healthy
Ingress/dummyhttp                   Synced  Healthy  ingress.networking.k8s.io/dummyhttp configured
Service/dummyhttp                   Synced  Healthy  service/dummyhttp unchanged
 Endpoints/dummyhttp
 EndpointSlice/dummyhttp-x57bl
As we can see, the Deployment and Ingress where updated, but the Service is unchanged. To validate that the ingress is using the new hostname we can use curl:
  curl -s https://dummyhttp.lo.mixinet.net:8443/
404 page not found
  curl -s https://test-dummyhttp.lo.mixinet.net:8443/
 "c": "", "s": "" 

Adding a ConfigMapNow that the system is adjusted to reload the application when the ConfigMap or Secret is created, deleted or updated we are ready to add one file and see how the system reacts. We modify the apps/dummyhttp/overlays/test/kustomization.yaml file to create the ConfigMap using the configMapGenerator as follows:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,6 +2,14 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+# Add the config map
+configMapGenerator:
+- name: dummyhttp-configmap
+  literals:
+  - CM_VAR="Default Test Value"
+  behavior: create
+  options:
+    disableNameSuffixHash: true
 patches:
 # Add reloader annotations
 - target:
After committing and pushing the changes we can see that the ConfigMap is available, the pod has been deleted and started again and the curl output includes the new value:
  kubectl get configmaps,pods
NAME                             READY   STATUS        RESTARTS   AGE
configmap/dummyhttp-configmap   1      11s
configmap/kube-root-ca.crt      1      4d7h
NAME                            DATA   AGE
pod/dummyhttp-779c96c44b-pjq4d   1/1     Running       0          11s
pod/dummyhttp-fc964557f-jvpkx    1/1     Terminating   0          2m42s
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": ""
 

Using helm with argocd-autopilotRight now there is no direct support in argocd-autopilot to manage applications using helm (see the issue #38 on the project), but we want to use a chart in our next example. There are multiple ways to add the support, but the simplest one that allows us to keep using argocd-autopilot is to use kustomize applications that call helm as described here. The only thing needed before being able to use the approach is to add the kustomize.buildOptions flag to the argocd-cm on the bootstrap/argo-cd/kustomization.yaml file, its contents now are follows:
bootstrap/argo-cd/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
configMapGenerator:
- behavior: merge
  literals:
  # Enable helm usage from kustomize (see https://github.com/argoproj/argo-cd/issues/2789#issuecomment-960271294)
  - kustomize.buildOptions="--enable-helm"
  -  
    repository.credentials=- passwordSecret:
        key: git_token
        name: autopilot-secret
      url: https://forgejo.mixinet.net/
      usernameSecret:
        key: git_username
        name: autopilot-secret
  name: argocd-cm
  # Disable TLS for the Argo Server (see https://argo-cd.readthedocs.io/en/stable/operator-manual/ingress/#traefik-v30)
- behavior: merge
  literals:
  - "server.insecure=true"
  name: argocd-cmd-params-cm
kind: Kustomization
namespace: argocd
resources:
- github.com/argoproj-labs/argocd-autopilot/manifests/base?ref=v0.4.19
- ingress_route.yaml
On the following section we will explain how the application is defined to make things work.

Installing the sealed-secrets controllerTo manage secrets in our cluster we are going to use the sealed-secrets controller and to install it we are going to use its chart. As we mentioned on the previous section, the idea is to create a kustomize application and use that to deploy the chart, but we are going to create the files manually, as we are not going import the base kustomization files from a remote repository. As there is no clear way to override helm Chart values using overlays we are going to use a generator to create the helm configuration from an external resource and include it from our overlays (the idea has been taken from this repository, which was referenced from a comment on the kustomize issue #38 mentioned earlier).

The sealed-secrets applicationWe have created the following files and folders manually:
apps/sealed-secrets/
  helm
    chart.yaml
    kustomization.yaml
  overlays
      test
          config.json
          kustomization.yaml
          values.yaml
The helm folder contains the generator template that will be included from our overlays. The kustomization.yaml includes the chart.yaml as a resource:
apps/sealed-secrets/helm/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
resources:
- chart.yaml
And the chart.yaml file defines the HelmChartInflationGenerator:
apps/sealed-secrets/helm/chart.yaml
apiVersion: builtin
kind: HelmChartInflationGenerator
metadata:
  name: sealed-secrets
releaseName: sealed-secrets
name: sealed-secrets
namespace: kube-system
repo: https://bitnami-labs.github.io/sealed-secrets
version: 2.17.2
includeCRDs: true
# Add common values to all argo-cd projects inline
valuesInline:
  fullnameOverride: sealed-secrets-controller
# Load a values.yaml file from the same directory that uses this generator
valuesFile: values.yaml
For this chart the template adjusts the namespace to kube-system and adds the fullnameOverride on the valuesInline key because we want to use those settings on all the projects (they are the values expected by the kubeseal command line application, so we adjust them to avoid the need to add additional parameters to it). We adjust global values as inline to be able to use a the valuesFile from our overlays; as we are using a generator the path is relative to the folder that contains the kustomization.yaml file that calls it, in our case we will need to have a values.yaml file on each overlay folder (if we don t want to overwrite any values for a project we can create an empty file, but it has to exist). Finally, our overlay folder contains three files, a kustomization.yaml file that includes the generator from the helm folder, the values.yaml file needed by the chart and the config.json file used by argocd-autopilot to install the application. The kustomization.yaml file contents are:
apps/sealed-secrets/overlays/test/kustomization.yaml
apiVersion: kustomize.config.k8s.io/v1beta1
kind: Kustomization
# Uncomment if you want to add additional resources using kustomize
#resources:
#- ../../base
generators:
- ../../helm
The values.yaml file enables the ingress for the application and adjusts its hostname:
apps/sealed-secrets/overlays/test/values.yaml
ingress:
  enabled: true
  hostname: test-sealed-secrets.lo.mixinet.net
And the config.json file is similar to the ones used with the other applications we have installed:
apps/sealed-secrets/overlays/test/config.json
 
  "appName": "sealed-secrets",
  "userGivenName": "sealed-secrets",
  "destNamespace": "kube-system",
  "destServer": "https://kubernetes.default.svc",
  "srcPath": "apps/sealed-secrets/overlays/test",
  "srcRepoURL": "https://forgejo.mixinet.net/blogops/argocd.git",
  "srcTargetRevision": "",
  "labels": null,
  "annotations": null
 
Once we commit and push the files the sealed-secrets application is installed in our cluster, we can check it using curl to get the public certificate used by it:
  curl -s https://test-sealed-secrets.lo.mixinet.net:8443/v1/cert.pem
-----BEGIN CERTIFICATE-----
[...]
-----END CERTIFICATE-----

The dummyhttp-secretTo create sealed secrets we need to install the kubeseal tool:
  arkade get kubeseal
Now we create a local version of the dummyhttp-secret that contains some value on the SECRET_VAR key (the easiest way for doing it is to use kubectl):
  echo -n "Boo"   kubectl create secret generic dummyhttp-secret \
    --dry-run=client --from-file=SECRET_VAR=/dev/stdin -o yaml \
    >/tmp/dummyhttp-secret.yaml
The secret definition in yaml format is:
apiVersion: v1
data:
  SECRET_VAR: Qm9v
kind: Secret
metadata:
  creationTimestamp: null
  name: dummyhttp-secret
To create a sealed version using the kubeseal tool we can do the following:
  kubeseal -f /tmp/dummyhttp-secret.yaml -w /tmp/dummyhttp-sealed-secret.yaml
That invocation needs to have access to the cluster to do its job and in our case it works because we modified the chart to use the kube-system namespace and set the controller name to sealed-secrets-controller as the tool expects. If we need to create the secrets without credentials we can connect to the ingress address we added to retrieve the public key:
  kubeseal -f /tmp/dummyhttp-secret.yaml -w /tmp/dummyhttp-sealed-secret.yaml \
    --cert https://test-sealed-secrets.lo.mixinet.net:8443/v1/cert.pem
Or, if we don t have access to the ingress address, we can save the certificate on a file and use it instead of the URL. The sealed version of the secret looks like this:
apiVersion: bitnami.com/v1alpha1
kind: SealedSecret
metadata:
  creationTimestamp: null
  name: dummyhttp-secret
  namespace: default
spec:
  encryptedData:
    SECRET_VAR: [...]
  template:
    metadata:
      creationTimestamp: null
      name: dummyhttp-secret
      namespace: default
This file can be deployed to the cluster to create the secret (in our case we will add it to the argocd application), but before doing that we are going to check the output of our dummyhttp service and get the list of Secrets and SealedSecrets in the default namespace:
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": ""
 
  kubectl get sealedsecrets,secrets
No resources found in default namespace.
Now we add the SealedSecret to the dummyapp copying the file and adding it to the kustomization.yaml file:
--- a/apps/dummyhttp/overlays/test/kustomization.yaml
+++ b/apps/dummyhttp/overlays/test/kustomization.yaml
@@ -2,6 +2,7 @@ apiVersion: kustomize.config.k8s.io/v1beta1
 kind: Kustomization
 resources:
 - ../../base
+- dummyhttp-sealed-secret.yaml
 # Create the config map value
 configMapGenerator:
 - name: dummyhttp-configmap
Once we commit and push the files Argo CD creates the SealedSecret and the controller generates the Secret:
  kubectl apply -f /tmp/dummyhttp-sealed-secret.yaml
sealedsecret.bitnami.com/dummyhttp-secret created
  kubectl get sealedsecrets,secrets
NAME                                        STATUS   SYNCED   AGE
sealedsecret.bitnami.com/dummyhttp-secret            True     3s
NAME                      TYPE     DATA   AGE
secret/dummyhttp-secret   Opaque   1      3s
If we check the command output we can see the new value of the secret:
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .
 
  "c": "Default Test Value",
  "s": "Boo"
 

Using sealed-secrets in production clustersIf you plan to use sealed-secrets look into its documentation to understand how it manages the private keys, how to backup things and keep in mind that, as the documentation explains, you can rotate your sealed version of the secrets, but that doesn t change the actual secrets. If you want to rotate your secrets you have to update them and commit the sealed version of the updates (as the controller also rotates the encryption keys your new sealed version will also be using a newer key, so you will be doing both things at the same time).

Final remarksOn this post we have seen how to deploy applications using the argocd-autopilot model, including the use of helm charts inside kustomize applications and how to install and use the sealed-secrets controller. It has been interesting and I ve learnt a lot about argocd in the process, but I believe that if I ever want to use it in production I will also review the native helm support in argocd using a separate repository to manage the applications, at least to be able to compare it to the model explained here.

4 May 2025

Dirk Eddelbuettel: #47: r2u at its Third Birthday

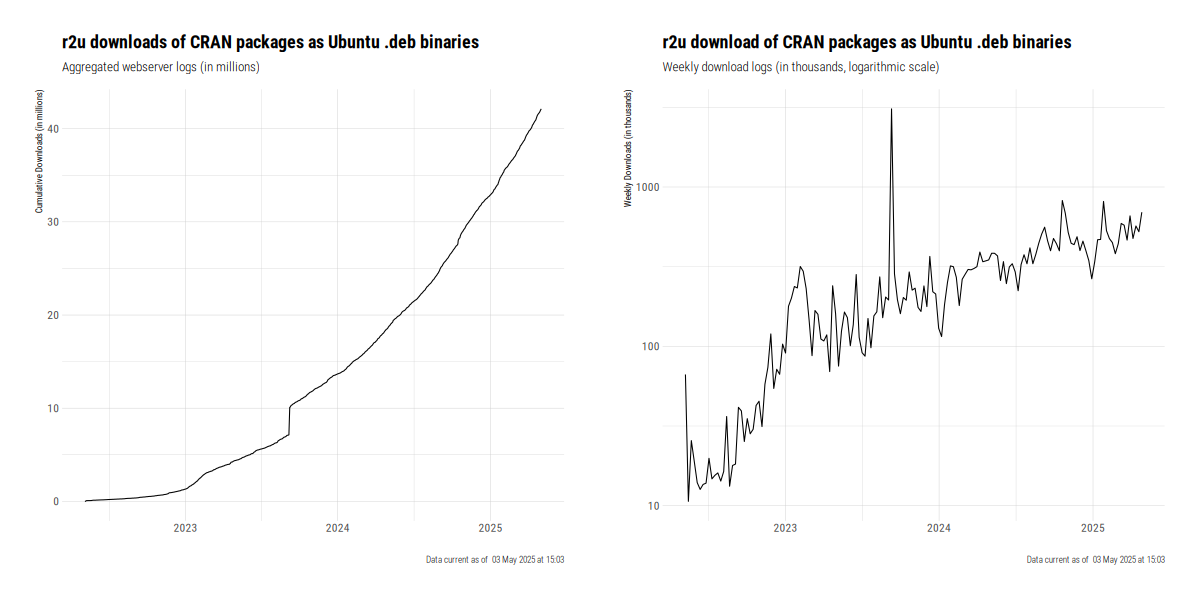
Welcome to post 47 in the $R^4 series! r2u provides Ubuntu binaries for all CRAN packages for the R system. It started three years ago, and offers for Linux users on Ubuntu what windows and macOS users already experience: fast, easy and reliable installation of binary packages. But by integrating with the system package manager (which is something that cannot be done on those other operating systems) we can fully and completely integrate it with underlying system. External libraries are resolved as shared libraries and handled by the system package manager. This offers fully automatic installation both at the initial installation and all subsequent upgrades. R users just say, e.g., install.packages("sf") and spatial libraries proj, gdal, geotiff (as well as several others) are automatically installed as dependencies in the correct versions. And they remain installed along with sf as the system manager now knows of the dependency. Work on r2u began as a quick weekend experiment in March 2022, and by May 4 a first release was marked in the NEWS file after a few brave alpha testers kicked tires quite happily. This makes today the third anniversary of that first release, and marks a good time to review where we are. This short post does this, and stresses three aspects: overall usage, current versions, and new developments.

Steadily Growing Usage at 42 Million Packages Shipped r2u ships from two sites. Its main repository is at the University of Illinois campus providing ample and heavily redundant bandwidth. We remain very grateful for the sponsorship from Atlas. It also still ships from my own server though that may be discontinued or could be spotty as it is on retail fiber connectivity. As we have access to the both sets of server logs, we can tabulate and chart usage. As of yesterday, total downloads were north of 42 million with current weekly averages around 500 thousand. These are quite staggering numbers for what started as a small hobby project, and are quite humbling. Usage is driven by deployment in continuous integration (as for example the Ubuntu-use at GitHub makes this both an easy and obvious choice), cloud computing (as it is easy to spin up Ubuntu instances, it is as easy to add r2u via four simple commands or one short script), explorative use (for example on Google Colab) or of course in general laptop, desktop, or server settings.

Current Versions Since r2u began, we added two Ubuntu LTS releases, three annual R releases as well as multiple BioConductor releases. BioConductor support is on a best-efforts basis motivated primarily to support the CRAN packages having dependencies. It has grown to around 500 packages and includes the top-250 by usage. Right now, current versions R 4.5.0 and BioConductor 3.21, both released last month, are supported.

New Development: arm64 A recent change is the support of the arm64 platform. As discussed in the introductory post, it is a popular and increasingly common CPU choice seen anywhere from the Raspberry Pi 5 and it Cortex CPU to in-house cloud computing platforms (called, respectively, Graviton at AWS and Axiom at GCS), general server use via Ampere CPUs, Cortex-based laptops that start to appears and last but not least on the popular M1 to M4-based macOS machines. (For macOS, one key appeal is in use of lighterweight Docker use as these M1 to M4 cpus can run arm64-based containers without a translation layer making it an attractive choice.) This is currently supported only for the noble aka 24.04 release. GitHub Actions, where we compile these packages, now also supports jammy aka 22.04 but it may not be worth it to expand there as the current latest release is available. We have not yet added BioConductor support but may do so. Drop us a line (maybe via an issue) if this of interest. With the provision of arm64 binaries, we also started to make heavier use of GitHub Actions. The BioConductor 3.21 release binaries were also created there. This makes the provision more transparent as well as the configuration repo as well as the two builder repos (arm64, bioc) are public, as is of course the main r2u repo.

Summing Up This short post summarised the current state of r2u along with some recent news. If you are curious, head over to the r2u site and try it, for example in a rocker/r2u container.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

3 May 2025

Russ Allbery: Review: Paper Soldiers

Review: Paper Soldiers, by Saleha Mohsin
Publisher: Portfolio
Copyright: 2024
ISBN: 0-593-53912-5
Format: Kindle
Pages: 250
The subtitle of Paper Soldiers is "How the Weaponization of the Dollar Changed the World Order," which may give you the impression that this book is about US use of the dollar system for political purposes such as sanctions. Do not be fooled like I was; this subtitle is, at best, deceptive. Coverage of the weaponization of the dollar is superficial and limited to a few chapters. This book is, instead, a history of the strong dollar policy told via a collection of hagiographies of US Treasury Secretaries and written with all of the skeptical cynicism of a poleaxed fawn. There is going to be some grumbling about the state of journalism in this review. Per the author's note, Saleha Mohsin is the Bloomberg News beat reporter for the US Department of the Treasury. That is, sadly, exactly what this book reads like: routine beat reporting. Mohsin asked current and former Treasury officials what they were thinking at various points in history and then wrote down their answers without, so far as I can tell, considering any contradictory evidence or wondering whether they were telling the truth. Paper Soldiers does contain extensive notes (those plus the index fill about forty pages), so I guess you could do the cross-checking yourself, although apparently most of the interviews for this book were "on background" and are therefore unattributed. (Is this weird? I feel like this is weird.) Mohsin adds a bit of utterly conventional and uncritical economic framing and casts the whole project in the sort of slightly breathless and dramatized prose style that infests routine news stories in the US. I find this style of book unbelievably frustrating because it represents such a wasted opportunity. To me, the point of book-length journalism is precisely to not write in this style. When you're trying to crank out two or three articles a week covering current events, I understand why there isn't always space or time to go deep into background, skepticism, and contrary opinions. But when you expand that material into a book, surely the whole point is to take the time to do some real reporting. Dig into what people told you, see if they're lying, talk to the people who disagree with them, question the conventional assumptions, and show your work on the page so that the reader is smarter after finishing your book than they were before they started. International political economics is not a sequence of objective facts. It's a set of decisions made in pursuit of economic and political theories that are disputed and arguable, and I think you owe the reader some sense of the argument and, ideally, some defensible position on the merits that is more than a transcription of your interviews. This is... not that.
It's a power loop that the United States still enjoys today: trust in America's dollar (and its democratic government) allows for cheap debt financing, which buys health care built on the most advanced research and development and inventions like airplanes and the iPhone. All of this is propelled by free market innovation and the superpowered strength to keep the nation safe from foreign threats. That investment boosts the nation's economic, military, and technological prowess, making its economy (and the dollar) even more attractive.
Let me be precise about my criticism. I am not saying that every contention in the above excerpt is wrong. Some of them are probably correct; more of them are at least arguable. This book is strictly about the era after Bretton Woods, so using airplanes as an example invention is a bizarre choice, but sure, whatever, I get the point. My criticism is that paragraphs like this, as written in this book, are not introductions to deeper discussions that question or defend that model of economic and political power. They are simple assertions that stand entirely unsupported. Mohsin routinely writes paragraphs like the above as if they are self-evident, and then immediately moves on to the next anecdote about Treasury dollar policy. Take, for example, the role of the US dollar as the world's reserve currency, which roughly means that most international transactions are conducted in dollars and numerous countries and organizations around the world hold large deposits in dollars instead of in their native currency. The conventional wisdom holds that this is a great boon to the US economy, but there are also substantive critiques and questions about that conventional wisdom. You would never know that from this book; Mohsin asserts the conventional wisdom about reserve currencies without so much as a hint that anyone might disagree. For example, one common argument, repeated several times by Mohsin, is that the US can only get away with the amount of deficit spending and cheap borrowing that it does because the dollar is the world's reserve currency. Consider two other countries whose currencies are clearly not the international reserve currency: Japan and the United Kingdom. The current US debt to GDP ratio is about 125% and the current interest rate on US 10-year bonds is about 4.2%. The current Japanese debt to GDP ratio is about 260% and the current interest rate on Japanese 10-year bonds is about 1.2%. The current UK debt to GDP ratio is 160% and the current interest rate on UK 10-year bonds is 4.5%. Are you seeing the dramatic effects of the role of the dollar as reserve currency? Me either. Again, I am not saying that this is a decisive counter-argument. I am not an economist; I'm just some random guy on the Internet who finds macroeconomics interesting and reads a few newsletters. I know the Japanese bond market is unusual in ways I'm not accounting for. There may well be compelling arguments for why reserve currency status matters immensely for US borrowing capacity. My point is not that Mohsin is wrong; my point is that you have to convince me and she doesn't even try. Nowhere in this book is a serious effort to view conventional wisdom with skepticism or confront it with opposing arguments. Instead, this book is full of blithe assertions that happen to support the narrative the author was fed by a bunch of former Treasury officials and does not appear to question in any way. I want books like this to increase my understanding of the world. To do that, they need to show me multiple sides of debates and teach me how to evaluate evidence, not simply reinforce a superficial conventional wisdom. It doesn't help that whatever fact-checking process this book went through left some glaring errors. For example, on the Plaza Accord:
With their central banks working in concert, enough dollars were purchased on the open market to weaken the currency, making American goods more affordable for foreign buyers.
I don't know what happened after the Plaza Accord (I read books like this to find out!), but clearly it wasn't that. This is utter nonsense. Buying dollars on the open market would increase the value of the dollar, not weaken it; this is basic supply and demand that you learn in the first week of a college economics class. This is the type of error that makes me question all the other claims in the book that I can't easily check. Mohsin does offer a more credible explanation of the importance of a reserve currency late in the book, although it's not clear to me that she realizes it: The widespread use of the US dollar gives US government sanctions vast international reach, allowing the US to punish and coerce its enemies through the threat of denying them access to the international financial system. Now we're getting somewhere! This is a more believable argument than a small and possibly imaginary effect on government borrowing costs. It is clear why a bellicose US government, particularly one led by advocates of a unitary executive theory that elevates the US president to a status of near-emperor, want to turn the dollar into a weapon of international control. It's much less obvious how comfortable the rest of the world should be with that concentration of power. This would be a fascinating topic for a journalistic non-fiction book. Some reporter should dive deep into the mechanics of sanctions and ask serious questions about the moral, practical, and diplomatic consequences of this aggressive wielding of US power. One could give it a title like Paper Soldiers that reflected the use of banks and paper currency as foot soldiers enforcing imperious dictates on the rest of the world. Alas, apart from a brief section in which the US scared other countries away from questioning the dollar, Mohsin does not tug at this thread. Maybe someone should write that book someday. As you will have gathered by now, I think this is a bad book and I do not recommend that you read it. Its worst flaw is one that it shares with far too much mainstream US print and TV journalism: the utter credulity of the author. I have the old-fashioned belief that a journalist should be more than a transcriptionist for powerful people. They should be skeptical, they should assume public figures may be lying, they should look for ulterior motives, and they should try to bring the reader closer to some objective truths about the world, wherever they may lie. I have no solution for this degradation of journalism. I'm not even sure that it's a change. There were always reporters eager to transcribe the voice of power into the newspaper, and if we remember the history of journalism differently, that may be because we have elevated the rare exceptions and forgotten the average. But after watching too many journalists I once respected start parroting every piece of nonsense someone tells them, from NFTs to UFOs to the existential threat of AI, I've concluded that the least I can do as a reader is to stop rewarding reporters who cannot approach powerful subjects with skepticism, suspicion, and critical research. I failed in this case, but perhaps I can serve as a warning to others. Rating: 3 out of 10

2 May 2025

Jonathan Dowland: Korg Minilogue XD

I didn't buy the Arturia Microfreak or the Behringer Model-D; I bought a Korg Minilogue XD.
Korg Minilogue XD, and Zoom R8 Korg Minilogue XD, and Zoom R8
I wanted an all-in-one unit which meant a built-in keyboard. I was keen on analogue oscillators, partly for the sound, but mostly to ensure that most of the controls were immediately accessible. The Minilogue-XD has two analogue oscillators and an analogue filter. It also has some useful, pure digital stuff: post-effects (chorus, flanger, echo, etc.); and a third, digital oscillator. The digital oscillator is programmable. There's an SDK, shared between the Minilogue-XD and some other Korg synths (at least the Prologue and NTS-1). There's a cottage industry of independent musicians writing and selling digital patches, e.g. STRING User Oscillator. Here's an example of a drone programmed using the SDK for the NTS-1:
Eventually I expect to have fun exploring the SDK, but for now I'm keeping it firmly away from computers (hence the Zoom R8 multitrack recorder in the above image: more on that in a future blog post). The Korg has been gathering dust whilst I was writing up, but now I hope to find some time to play.

1 May 2025

Ian Jackson: Free Software, internal politics, and governance

There is a thread of opinion in some Free Software communities, that we shouldn t be doing politics , and instead should just focus on technology. But that s impossible. This approach is naive, harmful, and, ultimately, self-defeating, even on its own narrow terms. Today I m talking about small-p politics In this article I m using politics in the very wide sense: us humans managing our disagreements with each other. I m not going to talk about culture wars, woke, racism, trans rights, and so on. I am not going to talk about how Free Software has always had explicitly political goals; or how it s impossible to be neutral because choosing not to take a stand is itself to take a stand. Those issues are all are important and Free Software definitely must engage with them. Many of the points I make are applicable there too. But those are not my focus today. Today I m talking in more general terms about politics, power, and governance. Many people working together always entails politics Computers are incredibly complicated nowadays. Making software is a joint enterprise. Even if an individual program has only a single maintainer, it fits into an ecosystem of other software, maintained by countless other developers. Larger projects can have thousands of maintainers and hundreds of thousands of contributors. Humans don t always agree about everything. This is natural. Indeed, it s healthy: to write the best code, we need a wide range of knowledge and experience. When we can t come to agreement, we need a way to deal with that: a way that lets us still make progress, but also leaves us able to work together afterwards. A way that feels OK for everyone. Providing a framework for disagreement is the job of a governance system. The rules say which people make which decisions, who must be consulted, how the decisions are made, and, how, if any, they can be reviewed. This is all politics. Consensus is great but always requiring it is harmful Ideally a discussion will converge to a synthesis that satisfies everyone, or at least a consensus. When consensus can t be achieved, we can hope for compromise: something everyone can live with. Compromise is achieved through negotiation. If every decision requires consensus, then the proponents of any wide-ranging improvement have an almost insurmountable hurdle: those who are favoured by the status quo and find it convenient can always object. So there will never be consensus for change. If there is any objection at all, no matter how ill-founded, the status quo will always win. This is where governance comes in. Governance is like backups: we need to practice it Governance processes are the backstop for when discussions, and then negotiations, fail, and people still don t see eye to eye. In a healthy community, everyone needs to know how the governance works and what the rules are. The participants need to accept the system s legitimacy. Everyone, including the losing side, must be prepared to accept and implement (or, at least not obstruct) whatever the decision is, and hopefully live with it and stay around. That means we need to practice our governance processes. We can t just leave them for the day we have a huge and controversial decision to make. If we do that, then when it comes to the crunch we ll have toxic rows where no-one can agree the rules; where determined people bend the rules to fit their outcome; and where afterwards people feel like the whole thing was horrible and unfair. So our decisionmaking bodies and roles need to be making decisions, as a matter of routine, and we need to get used to that. First-line decisionmaking bodies should be making decisions frequently. Last-line appeal mechanisms (large-scale votes, for example) are naturally going to be exercised more rarely, but they must happen, be seen as legitimate, and their outcomes must be implemented in full. Governance should usually be routine and boring When governance is working well it s quite boring. People offer their input, and are heard. Angles are debated, and concerns are addressed. If agreement still isn t reached, the committee, or elected leader, makes a decision. Hopefully everyone thinks the leadership is legitimate, and that it properly considered and heard their arguments, and made the decision for good reasons. Hopefully the losing side can still get their work done (and make their own computer work the way they want); so while they will be disappointed, they can live with the outcome. Many human institutions manage this most of the time. It does take some knowledge about principles of governance, and ideally some experience. Governance means deciding, not just mediating By making decisions I mean exercising their authority to rule on an actual disagreement: one that wasn t resolved by debate or negotiation. Governance processes by definition involve deciding, not just mediating. It s not governance if we re advising or cajoling: in that case, we re back to demanding consensus. Governance is necessary precisely when consensus is not achieved. If the governance systems are to mean anything, they must be able to (over)rule; that means (over)ruling must be normal and accepted. Otherwise, when the we need to overrule, we ll find that we can t, because we lack the collective practice. To be legitimate (and seen as legitimate) decisions must usually be made based on the merits, not on participants status, and not only on process questions. On the autonomy of the programmer Many programmers seem to find the very concept of governance, and binding decisionmaking, deeply uncomfortable. Ultimately, it means sometimes overruling someone s technical decision. As programmers and maintainers we naturally see how this erodes our autonomy. But we have all seen projects where the maintainers are unpleasant, obstinate, or destructive. We have all found this frustrating. Software is all interconnected, and one programmer s bad decisions can cause problems for many of the rest of us. We exasperate, why won t they just do the right thing . This is futile. People have never just ed and they re not going to start just ing now. So often the boot is on the other foot. More broadly, as software developers, we have a responsibility to our users, and a duty to write code that does good rather than ill in the world. We ought to be accountable. (And not just to capitalist bosses!) Governance mechanisms are the answer. (No, forking anything but the smallest project is very rarely a practical answer.) Mitigate the consequences of decisions retain flexibility In software, it is often possible to soften the bad social effects of a controversial decision, by retaining flexibility. With a bit of extra work, we can often provide hooks, non-default configuration options, or plugin arrangements. If we can convert the question from how will the software always behave into merely what should the default be , we can often save ourselves a lot of drama. So it is often worth keeping even suboptimal or untidy features or options, if people want to use them and are willing to maintain them. There is a tradeoff here, of course. But Free Software projects often significantly under-value the social benefits of keeping everyone happy. Wrestling software even crusty or buggy software is a lot more fun than having unpleasant arguments. But don t do decisionmaking like a corporation Many programmers experience of formal decisionmaking is from their boss at work. But corporations are often a very bad example. They typically don t have as much trouble actually making decisions, but the actual decisions are often terrible, and not just because corporations goals are often bad. You get to be a decisionmaker in a corporation by spouting plausible nonsense, sounding confident, buttering up the even-more-vacuous people further up the chain, and sometimes by sabotaging your rivals. Corporate senior managers are hardly ever held accountable typically the effects of their tenure are only properly felt well after they ve left to mess up somewhere else. We should select our leaders more wisely, and base decisions on substance. If you won t do politics, politics will do you As a participant in a project, or a society, you can of course opt out of getting involved in politics. You can opt out of learning how to do politics generally, and opt out of understanding your project s governance structures. You can opt out of making judgements about disputed questions, and tell yourself there s merit on both sides . You can hate politicians indiscriminately, and criticise anyone you see doing politics. If you do this, then you are abdicating your decisionmaking authority, to those who are the most effective manipulators, or the most committed to getting their way. You re tacitly supporting the existing power bases. You re ceding power to the best liars, to those with the least scruples, and to the people who are most motivated by dominance. This is precisely the opposite of what you wanted. If enough people won t do politics, and hate anyone who does, your discussion spaces will be reduced to a battleground of only the hardiest and the most toxic. If you don t see the politics, it s still happening If your governance systems don t work, then there is no effective redress against bad or even malicious decisions. Your roleholders and subteams are unaccountable power centres. Power radically distorts every human relationship, and it takes great strength of character for an unaccountable power centre not to eventually become an unaccountable toxic cabal. So if you have a reasonable sized community, but don t see your formal governance systems working people debating things, votes, leadership making explicit decisions that doesn t mean everything is fine, and all the decisions are great, and there s no politics happening. It just means that most of your community have given up on the official process. It also probably means that some parts of your project have formed toxic and unaccountable cabals. Those who won t put up with that will leave. The same is true if the only governance actions that ever happen are massive drama. That means that only the most determined victim of a bad decision, will even consider using such a process. Conclusions

comment count unavailable comments

Guido G nther: Free Software Activities April 2025

Another short status update of what happened on my side last month. Notable might be the Cell Broadcast support for Qualcomm SoCs, the rest is smaller fixes and QoL improvements. phosh phoc phosh-mobile-settings pfs feedbackd feedbackd-device-themes gmobile Debian git-buildpackage wlroots ModemManager Libqmi gnome-clocks gnome-calls qmi-parse-kernel-dump xwayland-run osmo-cbc phosh-nightly Blog posts Bugs Reviews This is not code by me but reviews on other peoples code. The list is (as usual) slightly incomplete. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread

25 April 2025

Simon Josefsson: GitLab Runner with Rootless Privilege-less Capability-less Podman on riscv64

I host my own GitLab CI/CD runners, and find that having coverage on the riscv64 CPU architecture is useful for testing things. The HiFive Premier P550 seems to be a common hardware choice. The P550 is possible to purchase online. You also need a (mini-)ATX chassi, power supply (~500W is more than sufficient), PCI-to-M2 converter and a NVMe storage device. Total cost per machine was around $8k/ 8k for me. Assembly was simple: bolt everything, connect ATX power, connect cables for the front-panel, USB and and Audio. Be sure to toggle the physical power switch on the P550 before you close the box. Front-panel power button will start your machine. There is a P550 user manual available. Below I will guide you to install the GitLab Runner on the pre-installed Ubuntu 24.04 that ships with the P550, and configure it to use Podman in root-less mode and without the --privileged flag, without any additional capabilities like SYS_ADMIN. Presumably you want to migrate to some other OS instead; hey Trisquel 13 riscv64 I m waiting for you! I wouldn t recommend using this machine for anything sensitive, there is an awful lot of non-free and/or vendor-specific software installed, and the hardware itself is young. I am not aware of any riscv64 hardware that can run a libre OS, all of them appear to require non-free blobs and usually a non-mainline kernel.
apt-get install minicom
minicom -o -D /dev/ttyUSB3
#cmd: ifconfig
inet 192.168.0.2 netmask: 255.255.240.0
gatway 192.168.0.1
SOM_Mac0: 8c:00:00:00:00:00
SOM_Mac1: 8c:00:00:00:00:00
MCU_Mac: 8c:00:00:00:00:00
#cmd: setmac 0 CA:FE:42:17:23:00
The MAC setting will be valid after rebooting the carrier board!!!
MAC[0] addr set to CA:FE:42:17:23:00(ca:fe:42:17:23:0)
#cmd: setmac 1 CA:FE:42:17:23:01
The MAC setting will be valid after rebooting the carrier board!!!
MAC[1] addr set to CA:FE:42:17:23:01(ca:fe:42:17:23:1)
#cmd: setmac 2 CA:FE:42:17:23:02
The MAC setting will be valid after rebooting the carrier board!!!
MAC[2] addr set to CA:FE:42:17:23:02(ca:fe:42:17:23:2)
#cmd:
apt-get install openocd
wget https://raw.githubusercontent.com/sifiveinc/hifive-premier-p550-tools/refs/heads/master/mcu-firmware/stm32_openocd.cfg
echo 'acc115d283ff8533d6ae5226565478d0128923c8a479a768d806487378c5f6c3 stm32_openocd.cfg' sha256sum -c
openocd -f stm32_openocd.cfg &
telnet localhost 4444
...
echo 'ssh-ed25519 AAA...' > ~/.ssh/authorized_keys
sed -i 's;^#PasswordAuthentication.*;PasswordAuthentication no;' /etc/ssh/sshd_config
service ssh restart
parted /dev/nvme0n1 print
blkdiscard /dev/nvme0n1
parted /dev/nvme0n1 mklabel gpt
parted /dev/nvme0n1 mkpart jas-p550-nvm-02 ext2 1MiB 100% align-check optimal 1
parted /dev/nvme0n1 set 1 lvm on
partprobe /dev/nvme0n1
pvcreate /dev/nvme0n1p1
vgcreate vg0 /dev/nvme0n1p1
lvcreate -L 400G -n glr vg0
mkfs.ext4 -L glr /dev/mapper/vg0-glr
Now with a reasonable setup ready, let s install the GitLab Runner. The following is adapted from gitlab-runner s official installation instructions documentation. The normal installation flow doesn t work because they don t publish riscv64 apt repositories, so you will have to perform upgrades manually.
# wget https://s3.dualstack.us-east-1.amazonaws.com/gitlab-runner-downloads/latest/deb/gitlab-runner_riscv64.deb
# wget https://s3.dualstack.us-east-1.amazonaws.com/gitlab-runner-downloads/latest/deb/gitlab-runner-helper-images.deb
wget https://gitlab-runner-downloads.s3.amazonaws.com/v17.11.0/deb/gitlab-runner_riscv64.deb
wget https://gitlab-runner-downloads.s3.amazonaws.com/v17.11.0/deb/gitlab-runner-helper-images.deb
echo '68a4c2a4b5988a5a5bae019c8b82b6e340376c1b2190228df657164c534bc3c3 gitlab-runner-helper-images.deb' sha256sum -c
echo 'ee37dc76d3c5b52e4ba35cf8703813f54f536f75cfc208387f5aa1686add7a8c gitlab-runner_riscv64.deb' sha256sum -c
dpkg -i gitlab-runner-helper-images.deb gitlab-runner_riscv64.deb
Remember the NVMe device? Let s not forget to use it, to avoid wear and tear of the internal MMC root disk. Do this now before any files in /home/gitlab-runner appears, or you have to move them manually.
gitlab-runner stop
echo 'LABEL=glr /home/gitlab-runner ext4 defaults,noatime 0 1' >> /etc/fstab
systemctl daemon-reload
mount /home/gitlab-runner
Next install gitlab-runner and configure it. Replace token glrt-REPLACEME below with the registration token you get from your GitLab project s Settings -> CI/CD -> Runners -> New project runner. I used the tags riscv64 and a runner description of the hostname.
gitlab-runner register --non-interactive --url https://gitlab.com --token glrt-REPLACEME --name $(hostname) --executor docker --docker-image debian:stable
We install and configure gitlab-runner to use podman, and to use non-root user.
apt-get install podman
gitlab-runner stop
usermod --add-subuids 100000-165535 --add-subgids 100000-165535 gitlab-runner
You need to run some commands as the gitlab-runner user, but unfortunately some interaction between sudo/su and pam_systemd makes this harder than it should be. So you have to setup SSH for the user and login via SSH to run the commands. Does anyone know of a better way to do this?
# on the p550:
cp -a /root/.ssh/ /home/gitlab-runner/
chown -R gitlab-runner:gitlab-runner /home/gitlab-runner/.ssh/
# on your laptop:
ssh gitlab-runner@jas-p550-01
systemctl --user --now enable podman.socket
systemctl --user --now start podman.socket
loginctl enable-linger gitlab-runner gitlab-runner
systemctl status --user podman.socket
We modify /etc/gitlab-runner/config.toml as follows, replace 997 with the user id shown by systemctl status above. See feature flags documentation for more documentation.
...
[[runners]]
environment = ["FF_NETWORK_PER_BUILD=1", "FF_USE_FASTZIP=1"]
...
[runners.docker]
host = "unix:///run/user/997/podman/podman.sock"
Note that unlike the documentation I do not add the privileged = true parameter here. I will come back to this later. Restart the system to confirm that pushing a .gitlab-ci.yml with a job that uses the riscv64 tag like the following works properly.
dump-env-details-riscv64:
stage: build
image: riscv64/debian:testing
tags: [ riscv64 ]
script:
- set
Your gitlab-runner should now be receiving jobs and running them in rootless podman. You may view the log using journalctl as follows:
journalctl --follow _SYSTEMD_UNIT=gitlab-runner.service
To stop the graphical environment and disable some unnecessary services, you can use:
systemctl set-default multi-user.target
systemctl disable openvpn cups cups-browsed sssd colord
At this point, things were working fine and I was running many successful builds. Now starts the fun part with operational aspects! I had a problem when running buildah to build a new container from within a job, and noticed that aardvark-dns was crashing. You can use the Debian aardvark-dns binary instead.
wget http://ftp.de.debian.org/debian/pool/main/a/aardvark-dns/aardvark-dns_1.14.0-3_riscv64.deb
echo 'df33117b6069ac84d3e97dba2c59ba53775207dbaa1b123c3f87b3f312d2f87a aardvark-dns_1.14.0-3_riscv64.deb' sha256sum -c
mkdir t
cd t
dpkg -x ../aardvark-dns_1.14.0-3_riscv64.deb .
mv /usr/lib/podman/aardvark-dns /usr/lib/podman/aardvark-dns.ubuntu
mv usr/lib/podman/aardvark-dns /usr/lib/podman/aardvark-dns.debian
My setup uses podman in rootless mode without passing the privileged parameter or any add-cap parameters to add non-default capabilities. This is sufficient for most builds. However if you try to create container using buildah from within a job, you may see errors like this:
Writing manifest to image destination
Error: mounting new container: mounting build container "8bf1ec03d967eae87095906d8544f51309363ddf28c60462d16d73a0a7279ce1": creating overlay mount to /var/lib/containers/storage/overlay/23785e20a8bac468dbf028bf524274c91fbd70dae195a6cdb10241c345346e6f/merged, mount_data="lowerdir=/var/lib/containers/storage/overlay/l/I3TWYVYTRZ4KVYCT6FJKHR3WHW,upperdir=/var/lib/containers/storage/overlay/23785e20a8bac468dbf028bf524274c91fbd70dae195a6cdb10241c345346e6f/diff,workdir=/var/lib/containers/storage/overlay/23785e20a8bac468dbf028bf524274c91fbd70dae195a6cdb10241c345346e6f/work,volatile": using mount program /usr/bin/fuse-overlayfs: unknown argument ignored: lazytime
fuse: device not found, try 'modprobe fuse' first
fuse-overlayfs: cannot mount: No such file or directory
: exit status 1
According to GitLab runner security considerations, you should not enable the privileged = true parameter, and the alternative appears to run Podman as root with privileged=false. Indeed setting privileged=true as in the following example solves the problem, and I suppose running podman as root would too.
[[runners]]
[runners.docker]
privileged = true
Can we do better? After some experimentation, and reading open issues with suggested capabilities and configuration snippets, I ended up with the following configuration. It runs podman in rootless mode (as the gitlab-runner user) without --privileged, but add the CAP_SYS_ADMIN capability and exposes the /dev/fuse device. Still, this is running as non-root user on the machine, so I think it is an improvement compared to using --privileged and also compared to running podman as root.
[[runners]]
[runners.docker]
privileged = false
cap_add = ["SYS_ADMIN"]
devices = ["/dev/fuse"]
Still I worry about the security properties of such a setup, so I only enable these settings for a separately configured runner instance that I use when I need this docker-in-docker (oh, I meant buildah-in-podman) functionality. I found one article discussing Rootless Podman without the privileged flag that suggest isolation=chroot but I have yet to make this work. Suggestions for improvement are welcome. Happy Riscv64 Building! Update 2025-05-05: I was able to make it work without the SYS_ADMIN capability too, with a GitLab /etc/gitlab-runner/config.toml like the following:
[[runners]]
  [runners.docker]
    privileged = false
    devices = ["/dev/fuse"]
And passing --isolation chroot to Buildah like this:
buildah build --isolation chroot -t $CI_REGISTRY_IMAGE:name image/
I ve updated the blog title to add the word capability-less as well. I ve confirmed that the same recipe works on podman on a ppc64el platform too. Remaining loop-holes are escaping from the chroot into the non-root gitlab-runner user, and escalating that privilege to root. The /dev/fuse and sub-uid/gid may be privilege escalation vectors here, otherwise I believe you ve found a serious software security issue rather than a configuration mistake.

23 April 2025

Dirk Eddelbuettel: qlcal 0.0.15 on CRAN: Calendar Updates

The fifteenth release of the qlcal package arrivied at CRAN today, following the QuantLib 1.38 release this morning. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases synchronizes qlcal with the QuantLib release 1.38.

Changes in version 0.0.15 (2025-04-23)
  • Synchronized with QuantLib 1.38 released today
  • Calendar updates for China, Hongkong, Thailand
  • Minor continuous integration update

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dirk Eddelbuettel: RInside 0.2.19 on CRAN: Mostly Maintenance

A new release 0.2.19 of RInside arrived on CRAN and in Debian today. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by Rcpp. This release fixes a minor bug that got tickled (after a decade and a half RInside) by environment variables (which we parse at compile time and encode in a C/C++ header file as constants) built using double quotes. CRAN currently needs that on one or two platforms, and RInside was erroring. This has been addressed. In the two years since the last release we also received two kind PRs updating the Qt examples to Qt6. And as always we also updated a few other things around the package. The list of changes since the last release:

Changes in RInside version 0.2.19 (2025-04-22)
  • The qt example now supports Qt6 (Joris Goosen in #54 closing #53)
  • CMake support was refined for more recent versions (Joris Goosen in #55)
  • The sandboxed-server example now states more clearly that RINSIDE_CALLBACKS needs to be defined
  • More routine update to package and continuous integration.
  • Some now-obsolete checks for C++11 have been removed
  • When parsing environment variables, use of double quotes is now supported

My CRANberries also provide a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page, or to issues tickets at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

22 April 2025

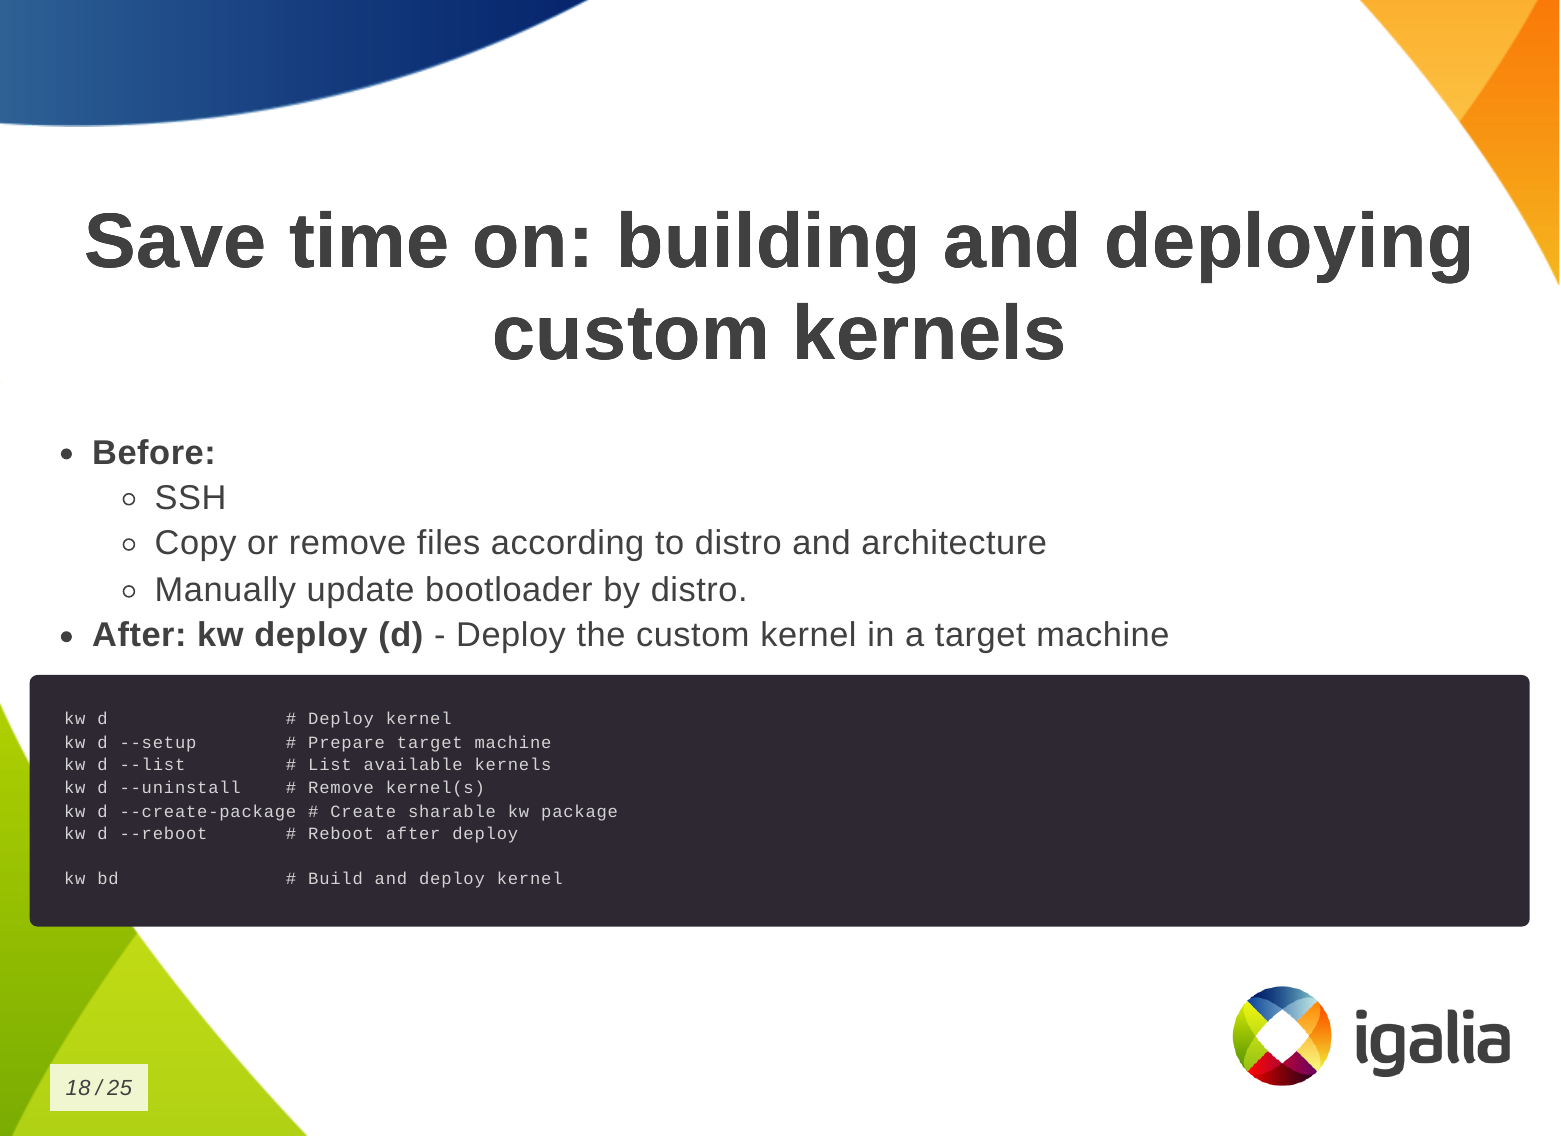
Melissa Wen: 2025 FOSDEM: Don't let your motivation go, save time with kworkflow

2025 was my first year at FOSDEM, and I can say it was an incredible experience where I met many colleagues from Igalia who live around the world, and also many friends from the Linux display stack who are part of my daily work and contributions to DRM/KMS. In addition, I met new faces and recognized others with whom I had interacted on some online forums and we had good and long conversations. During FOSDEM 2025 I had the opportunity to present about kworkflow in the kernel devroom. Kworkflow is a set of tools that help kernel developers with their routine tasks and it is the tool I use for my development tasks. In short, every contribution I make to the Linux kernel is assisted by kworkflow. The goal of my presentation was to spread the word about kworkflow. I aimed to show how the suite consolidates good practices and recommendations of the kernel workflow in short commands. These commands are easily configurable and memorized for your current work setup, or for your multiple setups. For me, Kworkflow is a tool that accommodates the needs of different agents in the Linux kernel community. Active developers and maintainers are the main target audience for kworkflow, but it is also inviting for users and user-space developers who just want to report a problem and validate a solution without needing to know every detail of the kernel development workflow. Something I didn t emphasize during the presentation but would like to correct this flaw here is that the main author and developer of kworkflow is my colleague at Igalia, Rodrigo Siqueira. Being honest, my contributions are mostly on requesting and validating new features, fixing bugs, and sharing scripts to increase feature coverage. So, the video and slide deck of my FOSDEM presentation are available for download here. And, as usual, you will find in this blog post the script of this presentation and more detailed explanation of the demo presented there.

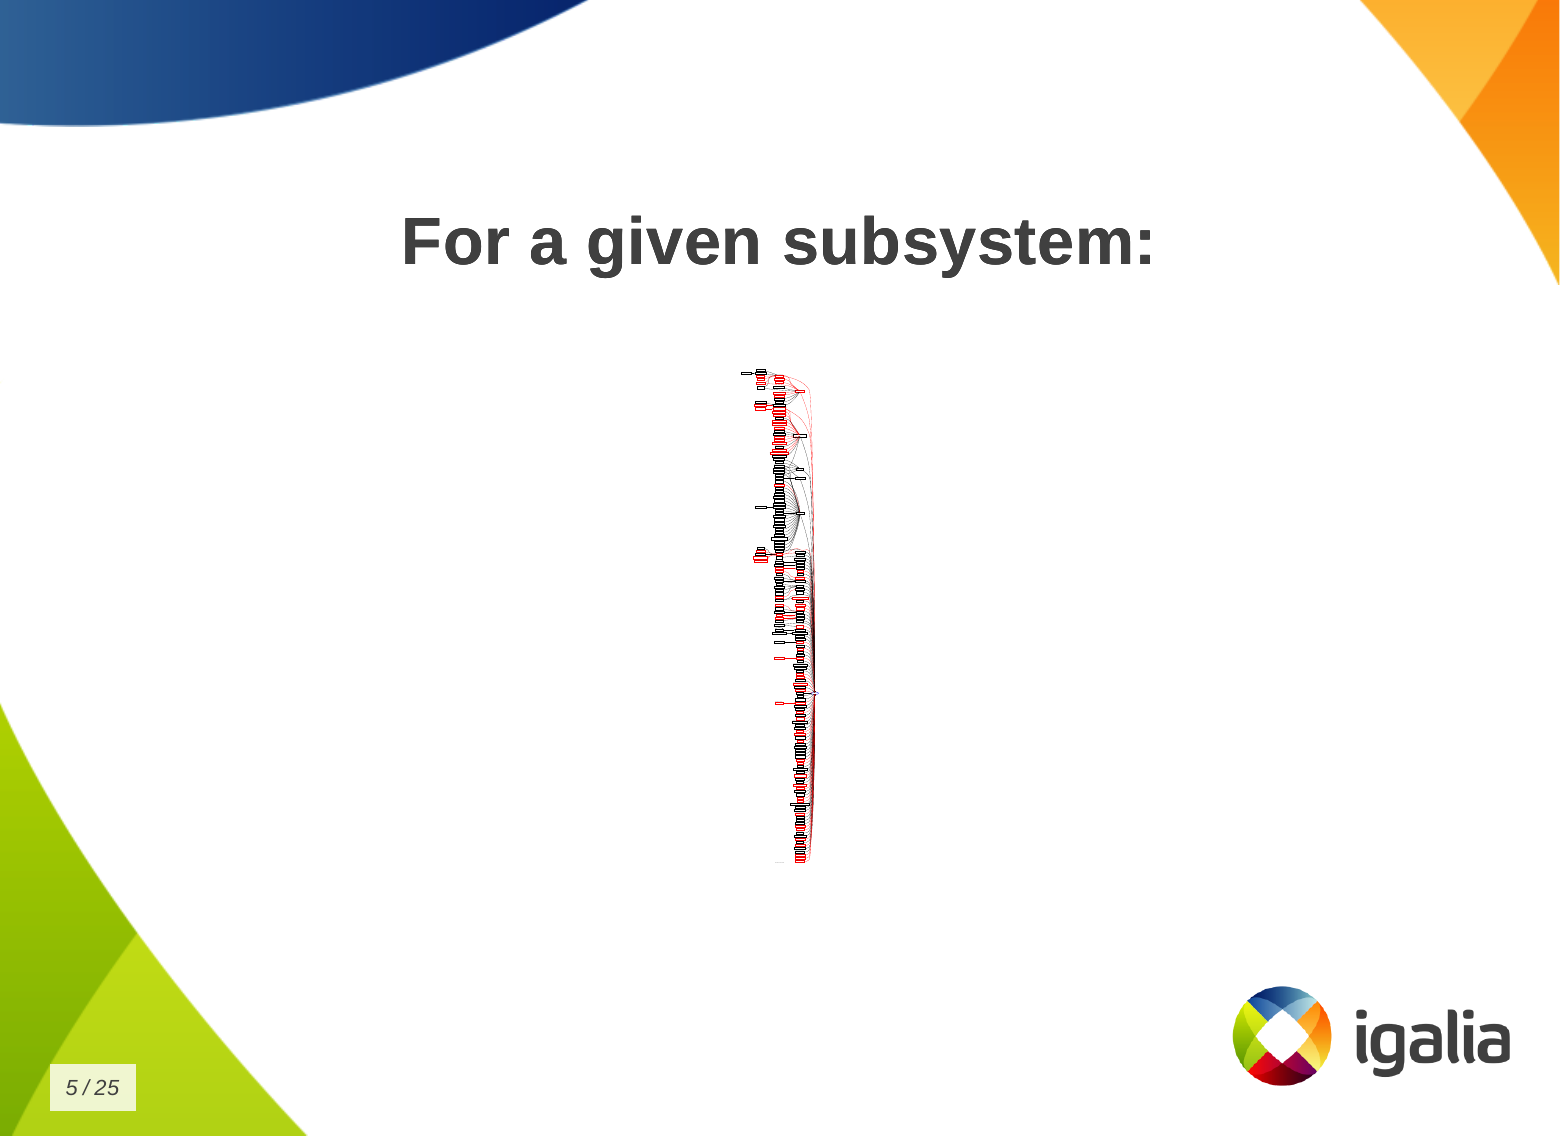
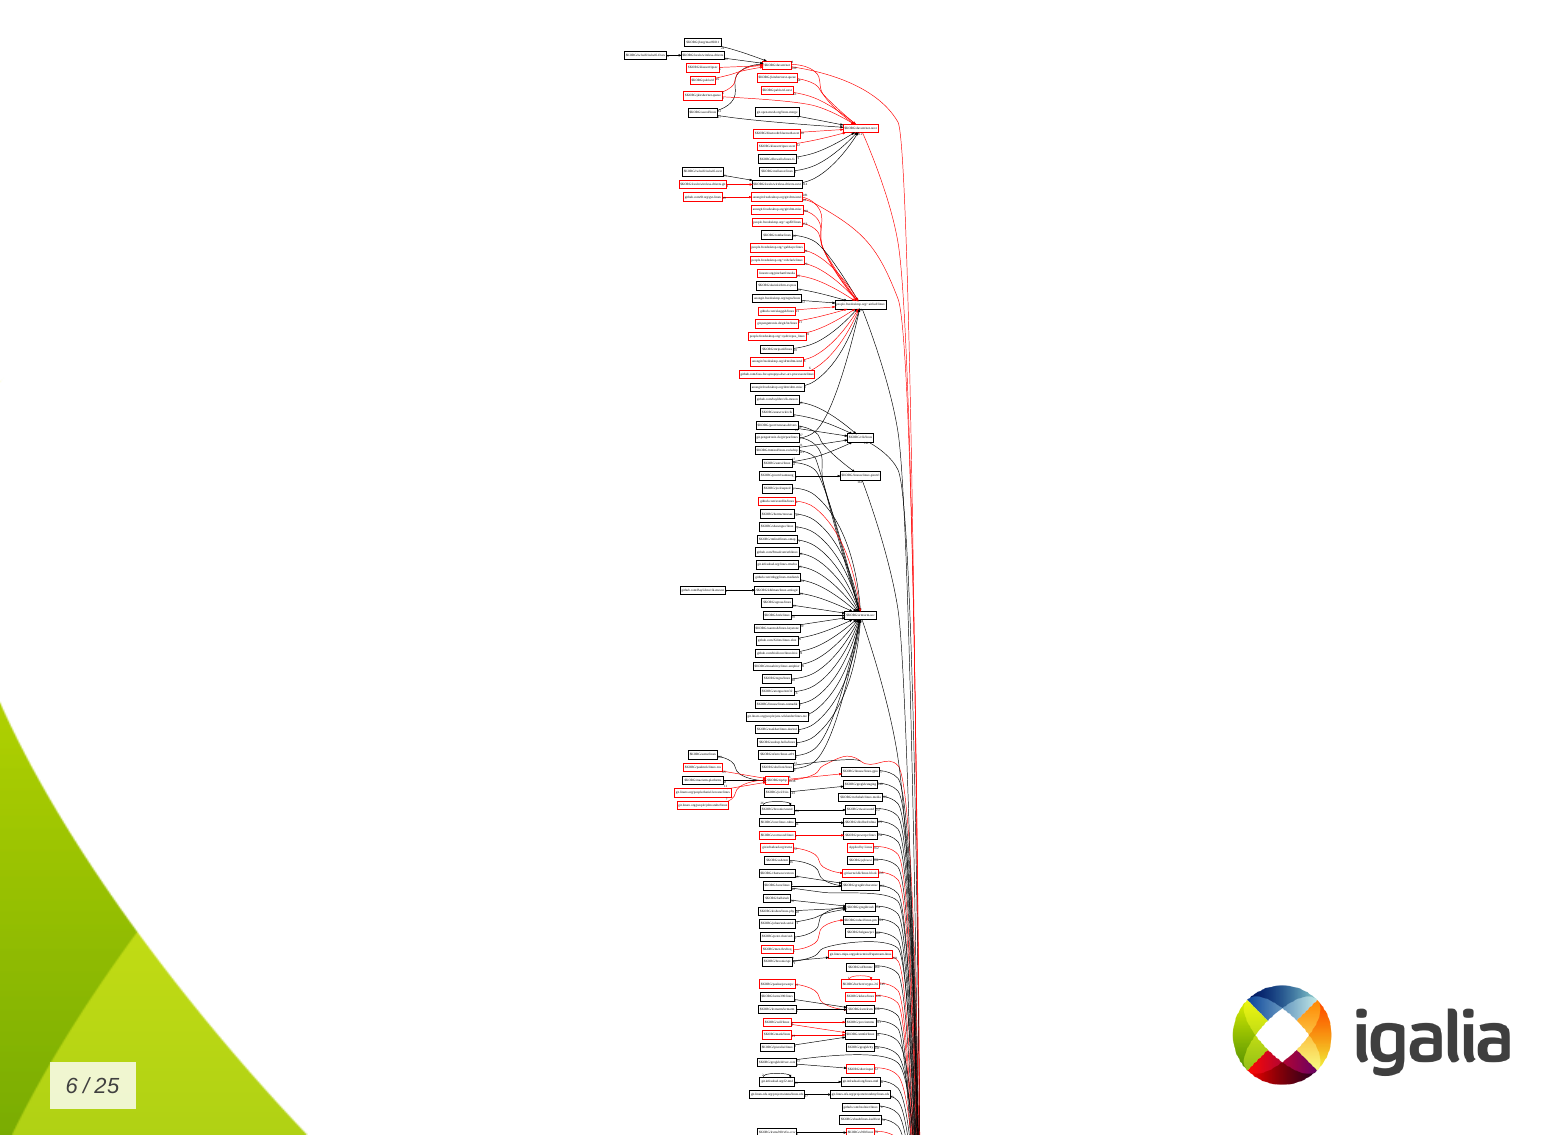
Kworkflow at FOSDEM 2025: Speaker Notes and Demo Hi, I m Melissa, a GPU kernel driver developer at Igalia and today I ll be giving a very inclusive talk to not let your motivation go by saving time with kworkflow. So, you re a kernel developer, or you want to be a kernel developer, or you don t want to be a kernel developer. But you re all united by a single need: you need to validate a custom kernel with just one change, and you need to verify that it fixes or improves something in the kernel. And that s a given change for a given distribution, or for a given device, or for a given subsystem Look to this diagram and try to figure out the number of subsystems and related work trees you can handle in the kernel. So, whether you are a kernel developer or not, at some point you may come across this type of situation: There is a userspace developer who wants to report a kernel issue and says:
  • Oh, there is a problem in your driver that can only be reproduced by running this specific distribution. And the kernel developer asks:
  • Oh, have you checked if this issue is still present in the latest kernel version of this branch?
But the userspace developer has never compiled and installed a custom kernel before. So they have to read a lot of tutorials and kernel documentation to create a kernel compilation and deployment script. Finally, the reporter managed to compile and deploy a custom kernel and reports:
  • Sorry for the delay, this is the first time I have installed a custom kernel. I am not sure if I did it right, but the issue is still present in the kernel of the branch you pointed out.
And then, the kernel developer needs to reproduce this issue on their side, but they have never worked with this distribution, so they just created a new script, but the same script created by the reporter. What s the problem of this situation? The problem is that you keep creating new scripts! Every time you change distribution, change architecture, change hardware, change project - even in the same company - the development setup may change when you switch to a different project, you create another script for your new kernel development workflow! You know, you have a lot of babies, you have a collection of my precious scripts , like Sm agol (Lord of the Rings) with the precious ring. Instead of creating and accumulating scripts, save yourself time with kworkflow. Here is a typical script that many of you may have. This is a Raspberry Pi 4 script and contains everything you need to memorize to compile and deploy a kernel on your Raspberry Pi 4. With kworkflow, you only need to memorize two commands, and those commands are not specific to Raspberry Pi. They are the same commands to different architecture, kernel configuration, target device.
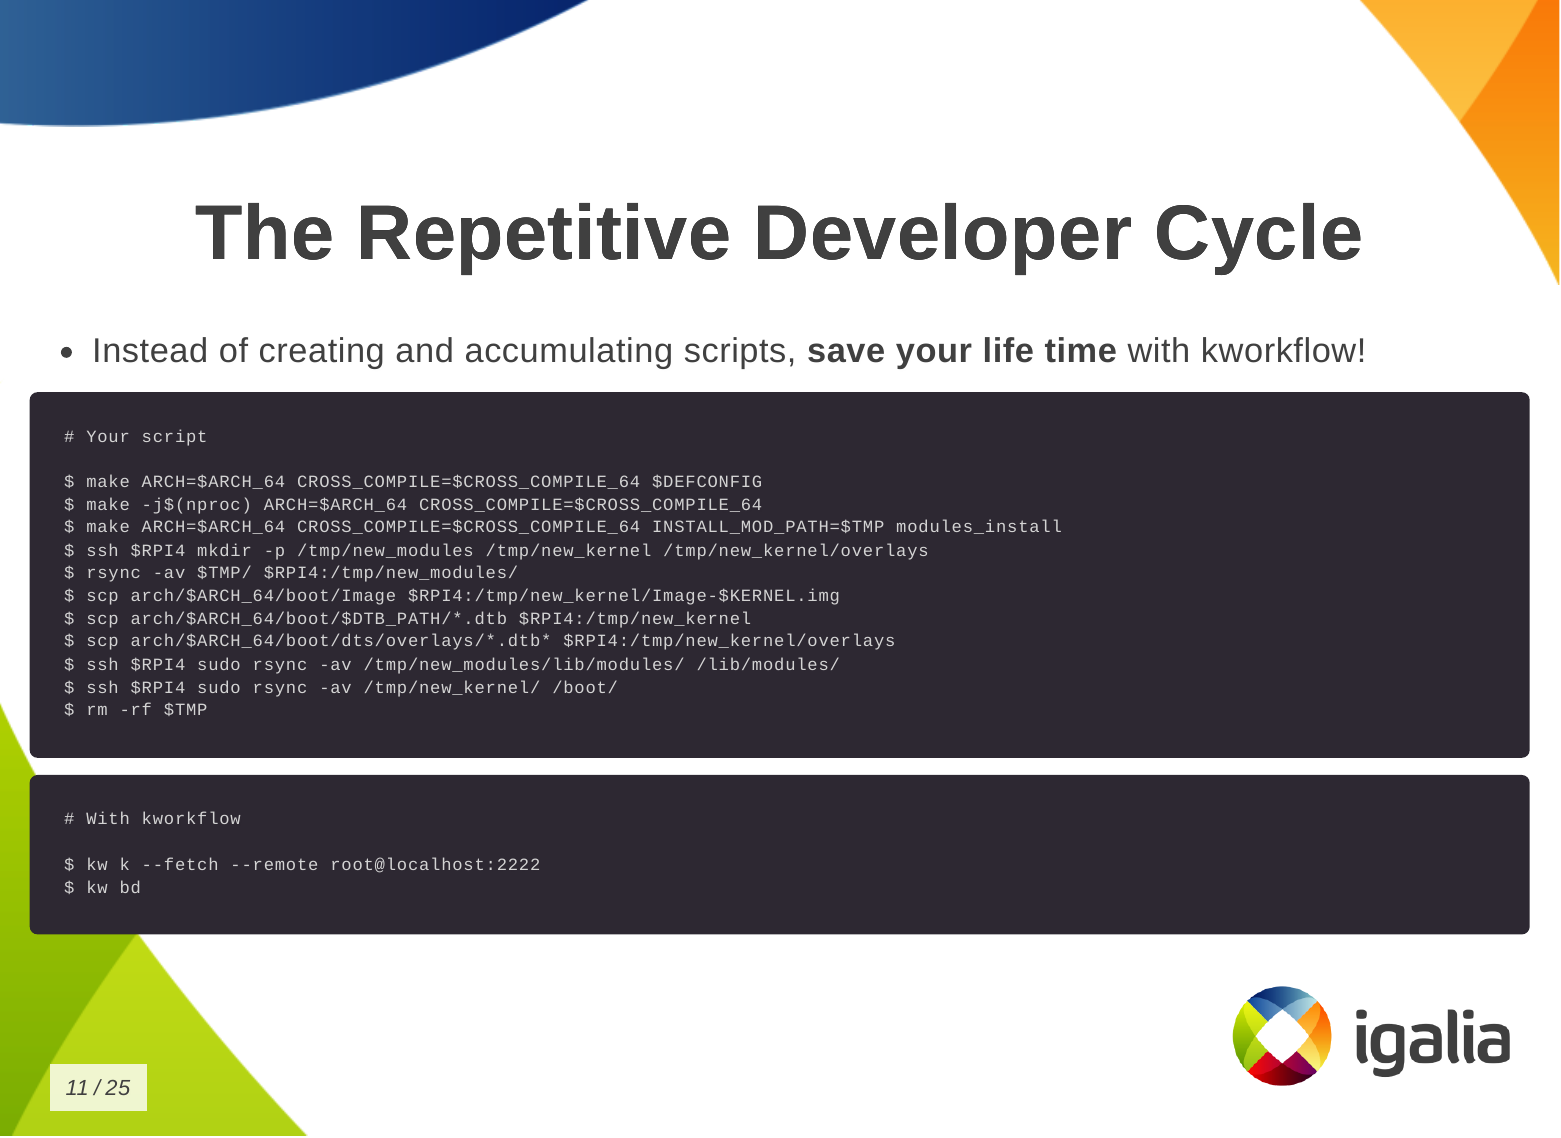
What is kworkflow? Kworkflow is a collection of tools and software combined to:
  • Optimize Linux kernel development workflow.
  • Reduce time spent on repetitive tasks, since we are spending our lives compiling kernels.
  • Standardize best practices.
  • Ensure reliable data exchange across kernel workflow. For example: two people describe the same setup, but they are not seeing the same thing, kworkflow can ensure both are actually with the same kernel, modules and options enabled.
I don t know if you will get this analogy, but kworkflow is for me a megazord of scripts. You are combining all of your scripts to create a very powerful tool.
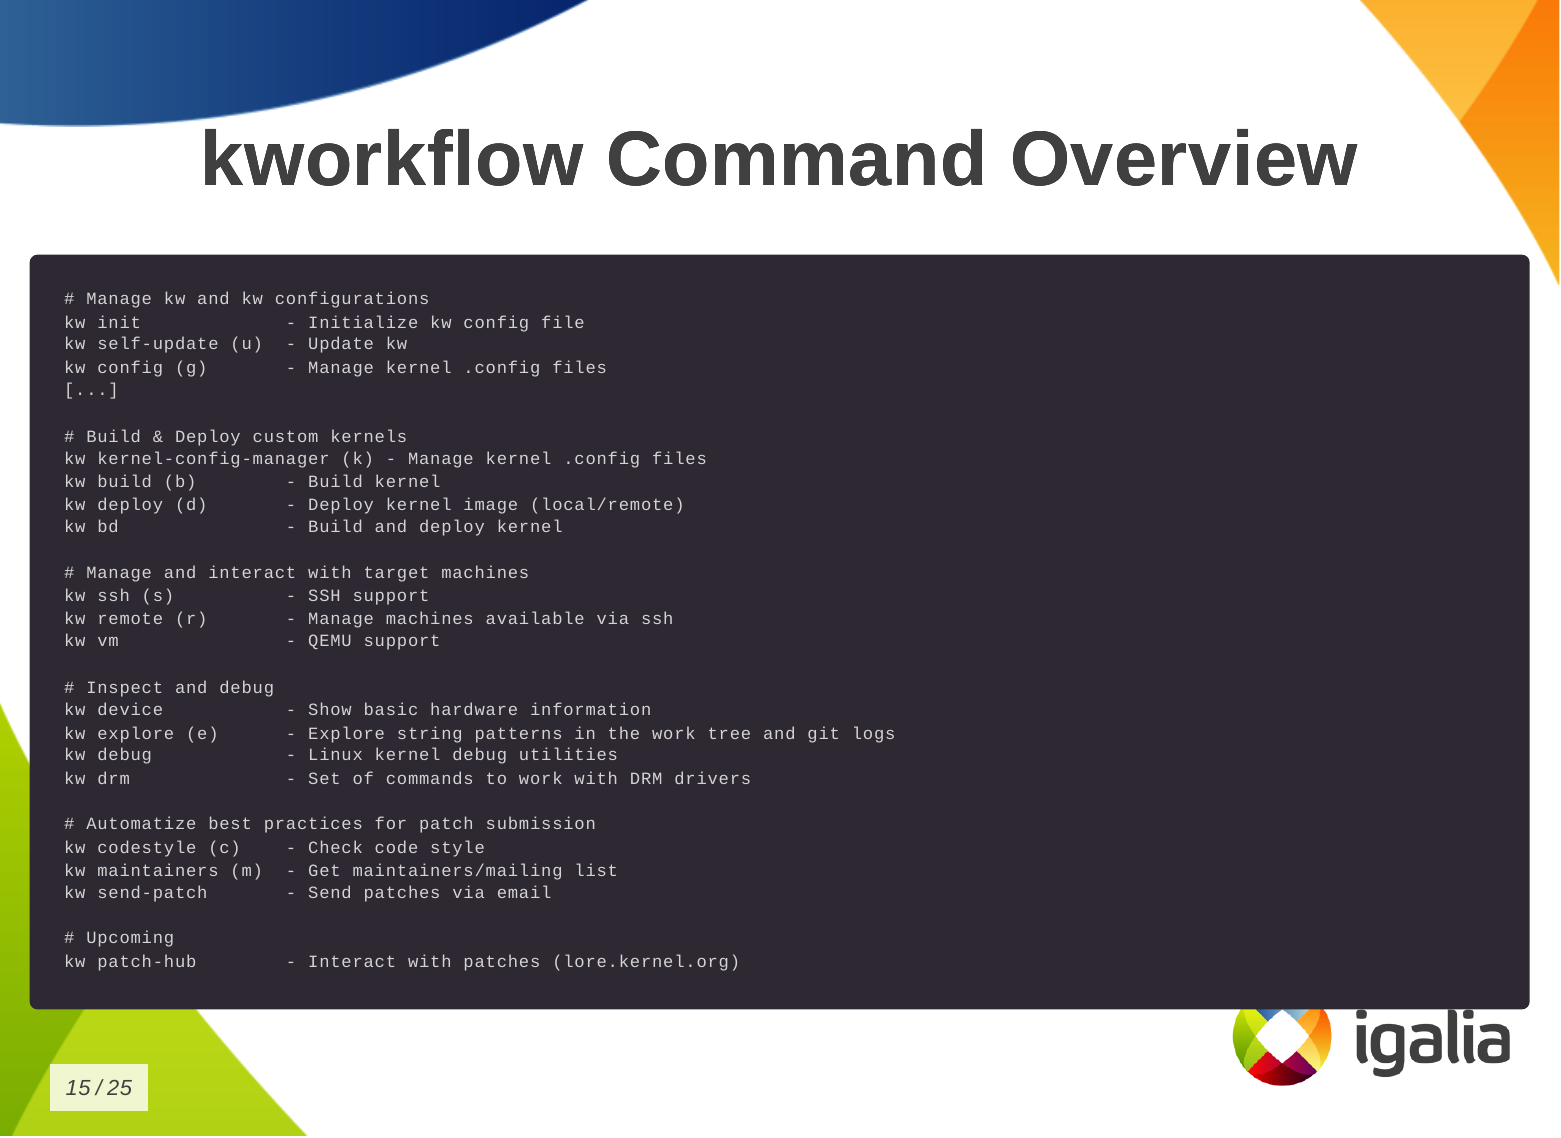
What is the main feature of kworflow? There are many, but these are the most important for me:
  • Build & deploy custom kernels across devices & distros.
  • Handle cross-compilation seamlessly.
  • Manage multiple architecture, settings and target devices in the same work tree.
  • Organize kernel configuration files.
  • Facilitate remote debugging & code inspection.
  • Standardize Linux kernel patch submission guidelines. You don t need to double check documentantion neither Greg needs to tell you that you are not following Linux kernel guidelines.
  • Upcoming: Interface to bookmark, apply and reviewed-by patches from mailing lists (lore.kernel.org).
This is the list of commands you can run with kworkflow. The first subset is to configure your tool for various situations you may face in your daily tasks.
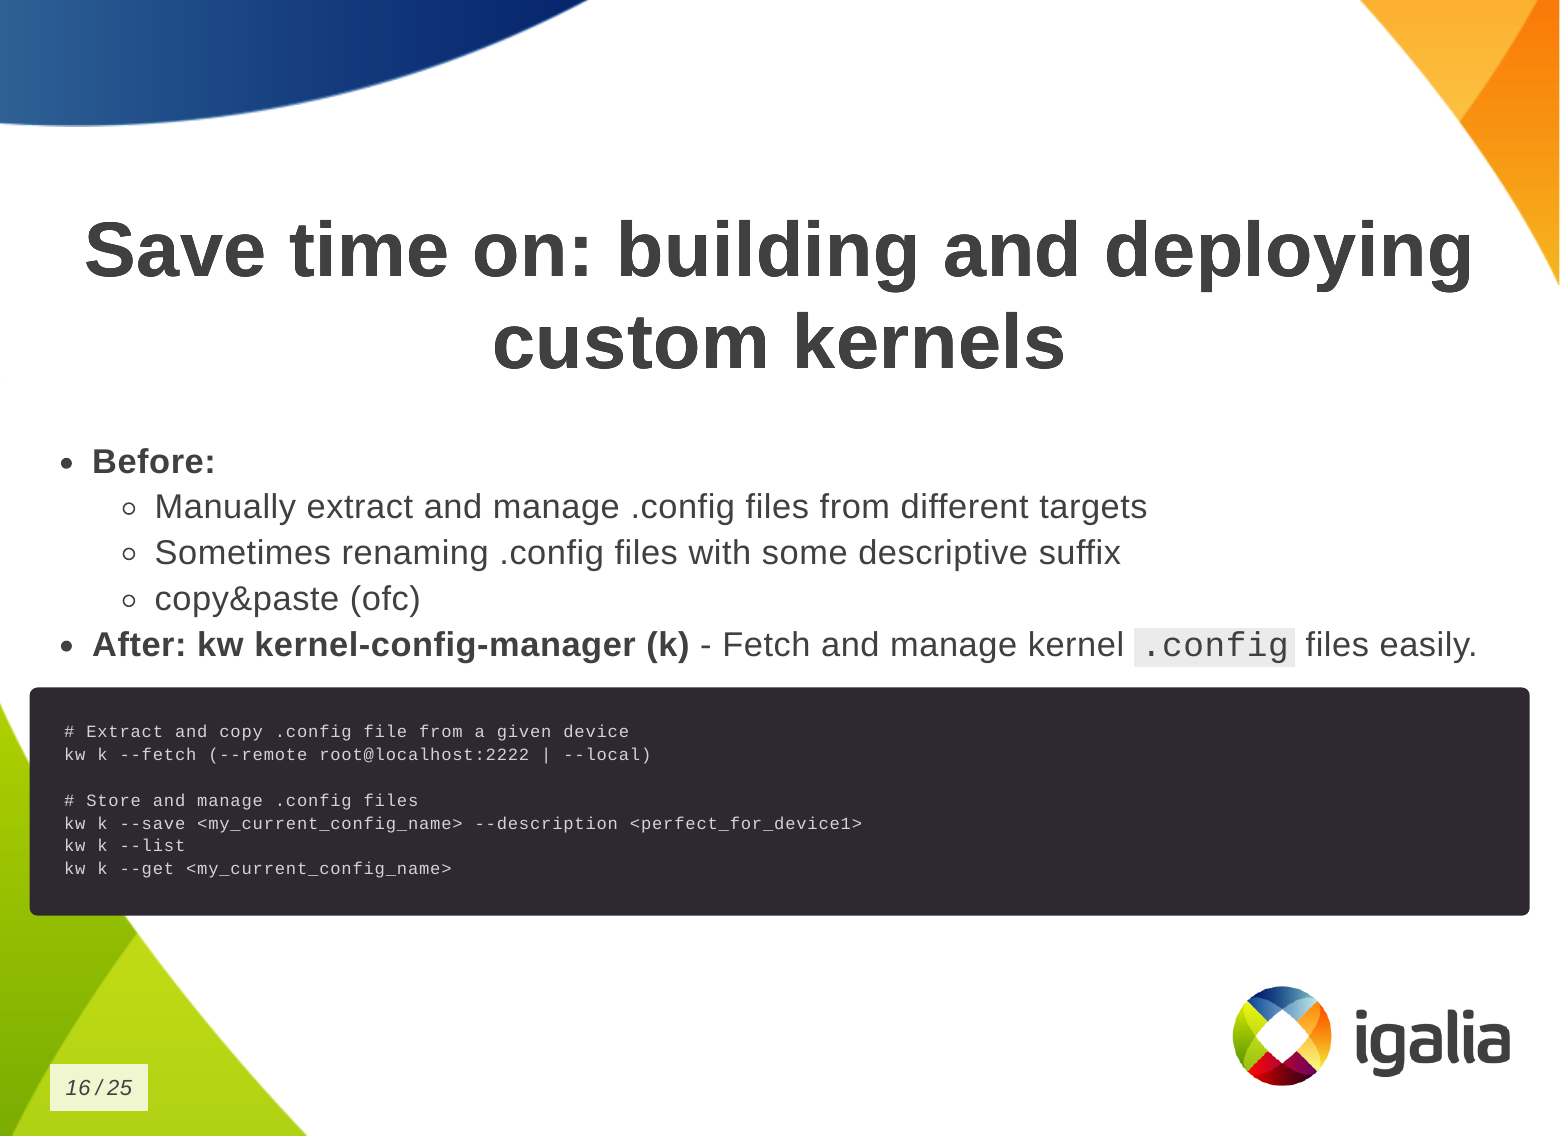
# Manage kw and kw configurations
kw init             - Initialize kw config file
kw self-update (u)  - Update kw
kw config (g)       - Manage kernel .config files
The second subset is to build and deploy custom kernels.
# Build & Deploy custom kernels
kw kernel-config-manager (k) - Manage kernel .config files
kw build (b)        - Build kernel
kw deploy (d)       - Deploy kernel image (local/remote)
kw bd               - Build and deploy kernel
We have some tools to manage and interact with target machines.
# Manage and interact with target machines
kw ssh (s)          - SSH support
kw remote (r)       - Manage machines available via ssh
kw vm               - QEMU support
To inspect and debug a kernel.
# Inspect and debug
kw device           - Show basic hardware information
kw explore (e)      - Explore string patterns in the work tree and git logs
kw debug            - Linux kernel debug utilities
kw drm              - Set of commands to work with DRM drivers
To automatize best practices for patch submission like codestyle, maintainers and the correct list of recipients and mailing lists of this change, to ensure we are sending the patch to who is interested in it.
# Automatize best practices for patch submission
kw codestyle (c)    - Check code style
kw maintainers (m)  - Get maintainers/mailing list
kw send-patch       - Send patches via email
And the last one, the upcoming patch hub.
# Upcoming
kw patch-hub        - Interact with patches (lore.kernel.org)

How can you save time with Kworkflow? So how can you save time building and deploying a custom kernel? First, you need a .config file.
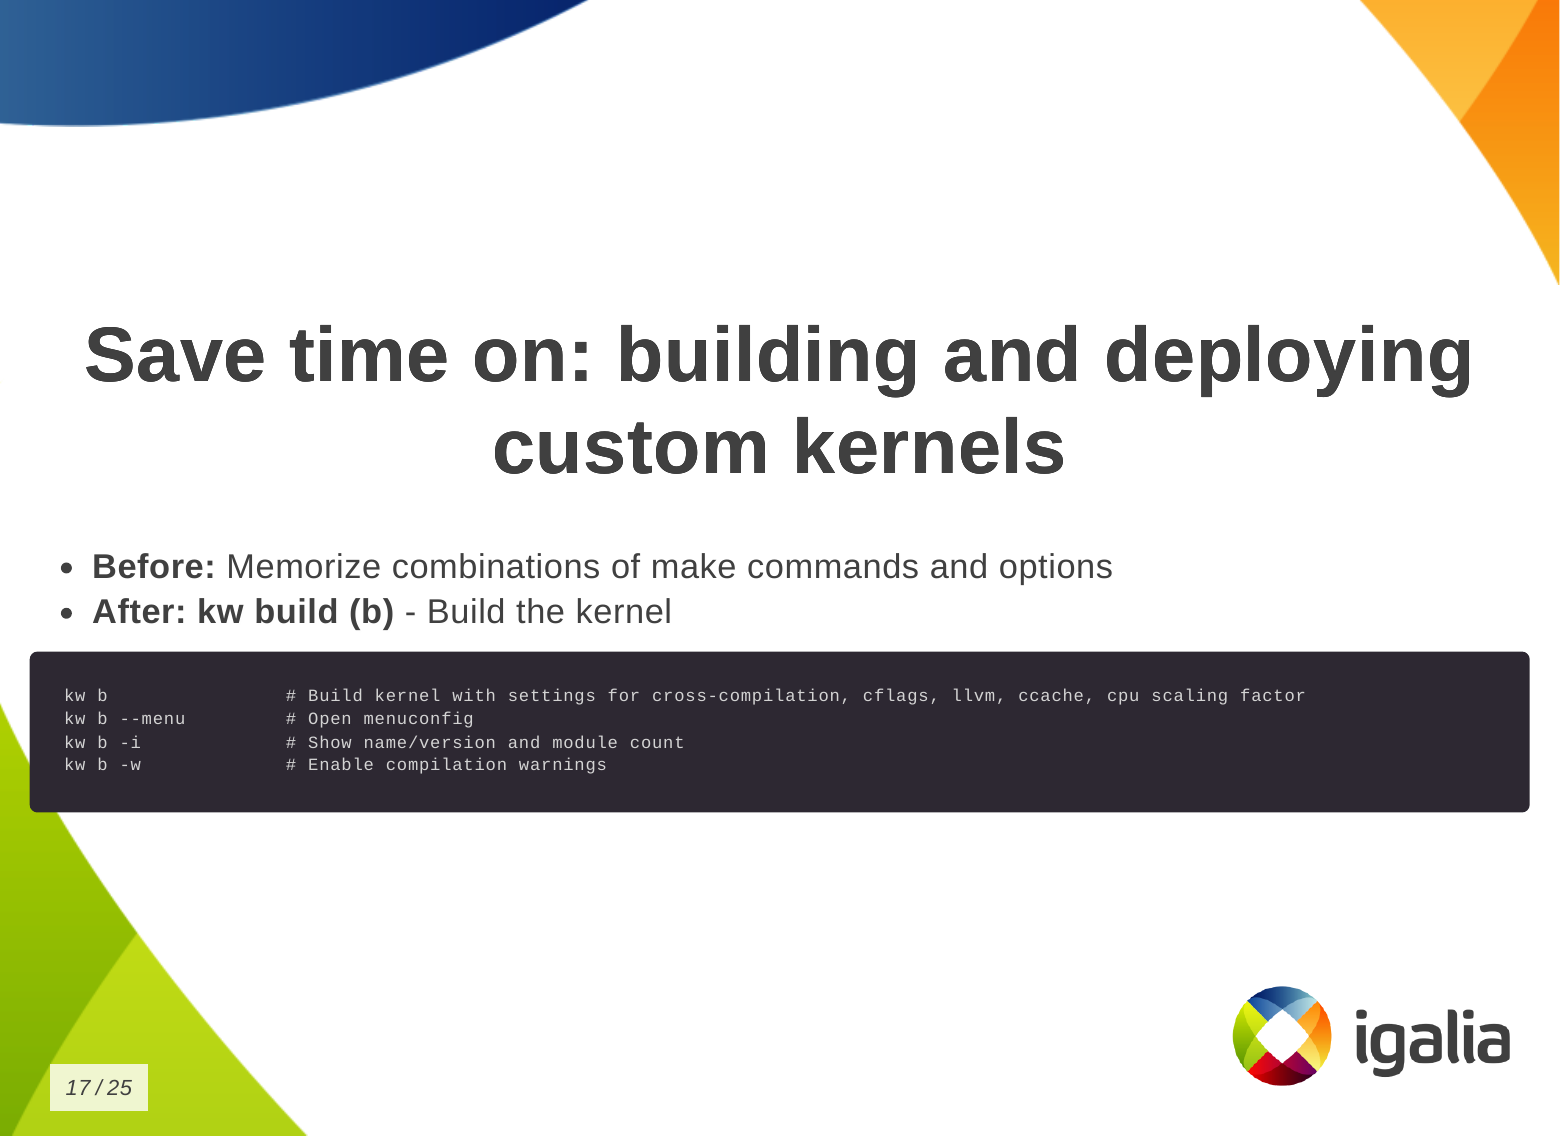
  • Without kworkflow: You may be manually extracting and managing .config files from different targets and saving them with different suffixes to link the kernel to the target device or distribution, or any descriptive suffix to help identify which is which. Or even copying and pasting from somewhere.
  • With kworkflow: you can use the kernel-config-manager command, or simply kw k, to store, describe and retrieve a specific .config file very easily, according to your current needs.
Then you want to build the kernel:
  • Without kworkflow: You are probably now memorizing a combination of commands and options.
  • With kworkflow: you just need kw b (kw build) to build the kernel with the correct settings for cross-compilation, compilation warnings, cflags, etc. It also shows some information about the kernel, like number of modules.
Finally, to deploy the kernel in a target machine.
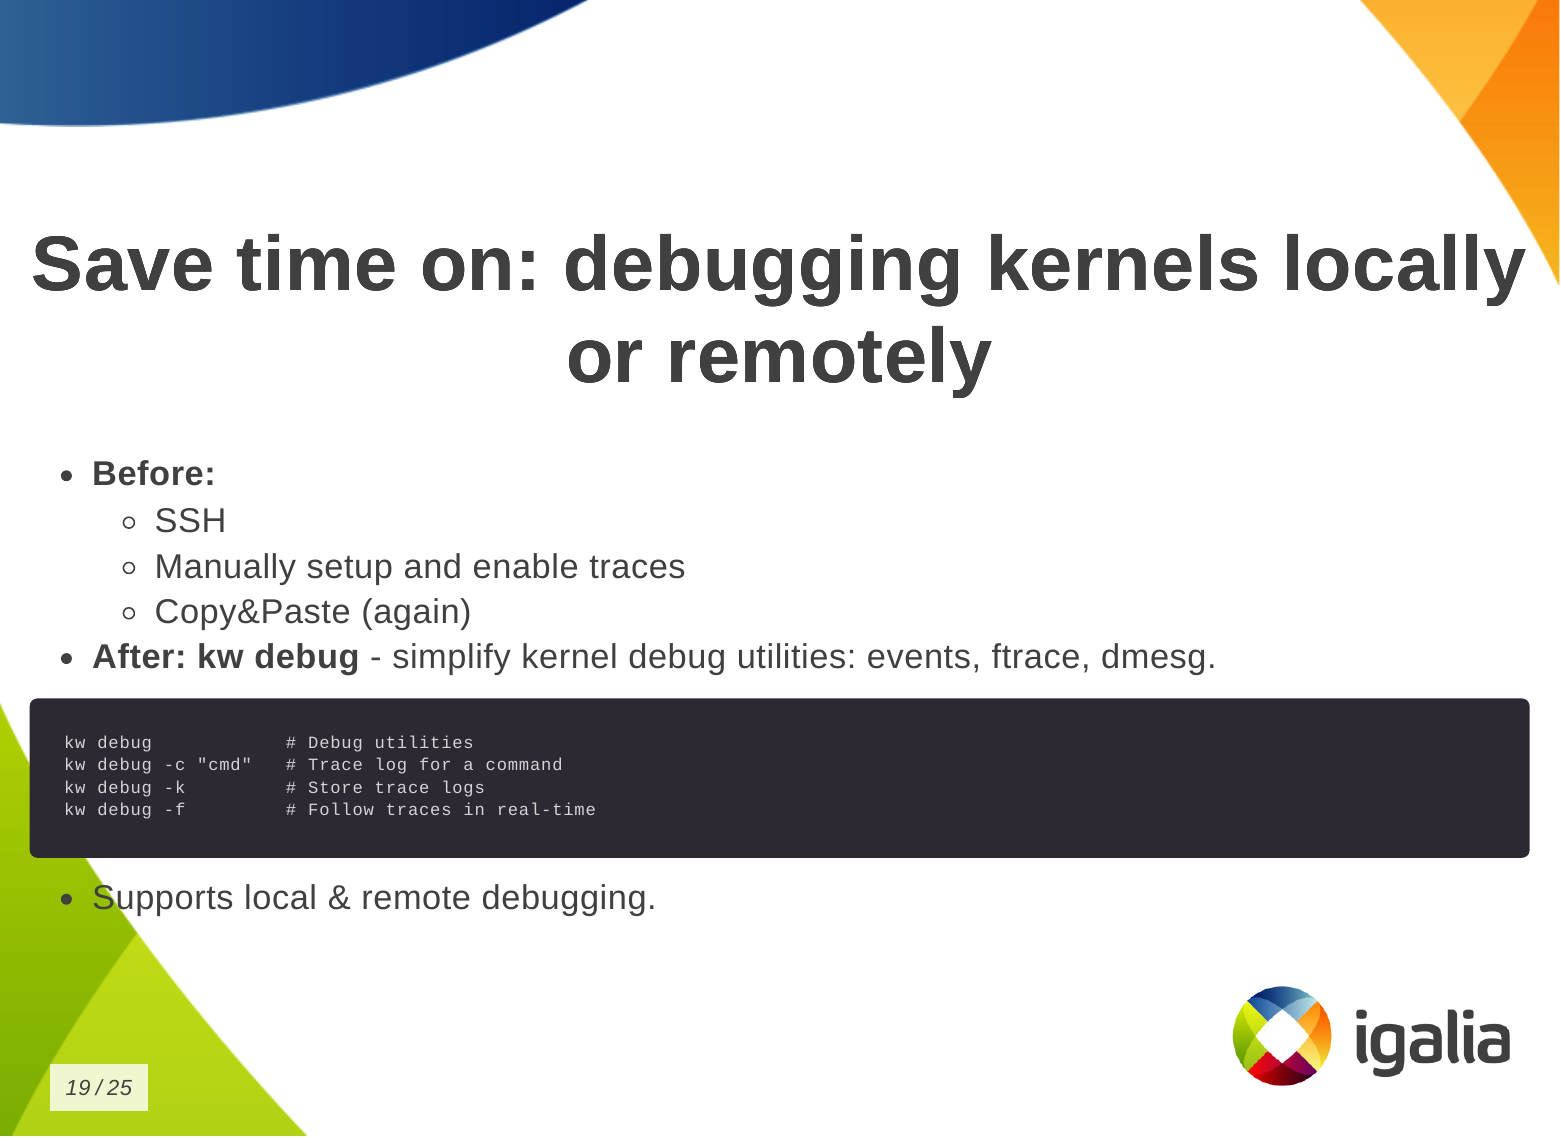
  • Without kworkflow: You might be doing things like: SSH connecting to the remote machine, copying and removing files according to distributions and architecture, and manually updating the bootloader for the target distribution.
  • With kworkflow: you just need kw d which does a lot of things for you, like: deploying the kernel, preparing the target machine for the new installation, listing available kernels and uninstall them, creating a tarball, rebooting the machine after deploying the kernel, etc.
You can also save time on debugging kernels locally or remotely.
  • Without kworkflow: you do: ssh, manual setup and traces enablement, copy&paste logs.
  • With kworkflow: more straighforward access to debug utilities: events, trace, dmesg.
You can save time on managing multiple kernel images in the same work tree.
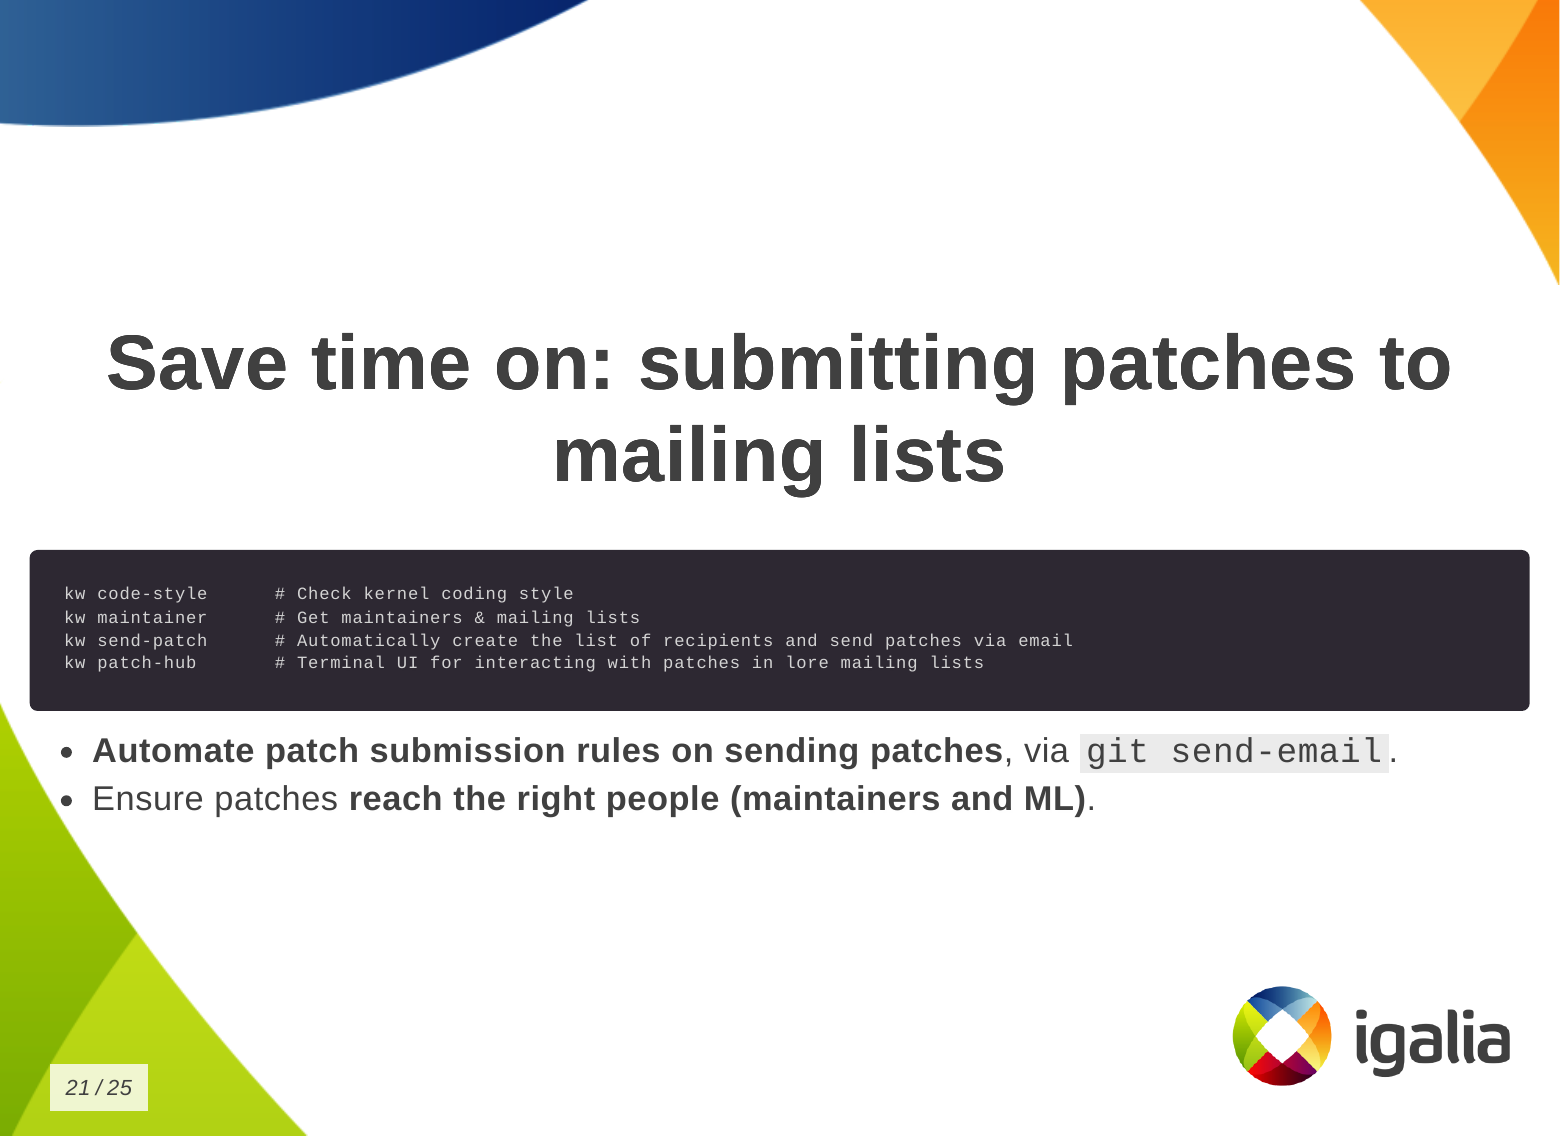
  • Without kworkflow: now you can be cloning multiple times the same repository so you don t lose compiled files when changing kernel configuration or compilation options and manually managing build and deployment scripts.
  • With kworkflow: you can use kw env to isolate multiple contexts in the same worktree as environments, so you can keep different configurations in the same worktree and switch between them easily without losing anything from the last time you worked in a specific context.
Finally, you can save time when submitting kernel patches. In kworkflow, you can find everything you need to wrap your changes in patch format and submit them to the right list of recipients, those who can review, comment on, and accept your changes. This is a demo that the lead developer of the kw patch-hub feature sent me. With this feature, you will be able to check out a series on a specific mailing list, bookmark those patches in the kernel for validation, and when you are satisfied with the proposed changes, you can automatically submit a reviewed-by for that whole series to the mailing list.
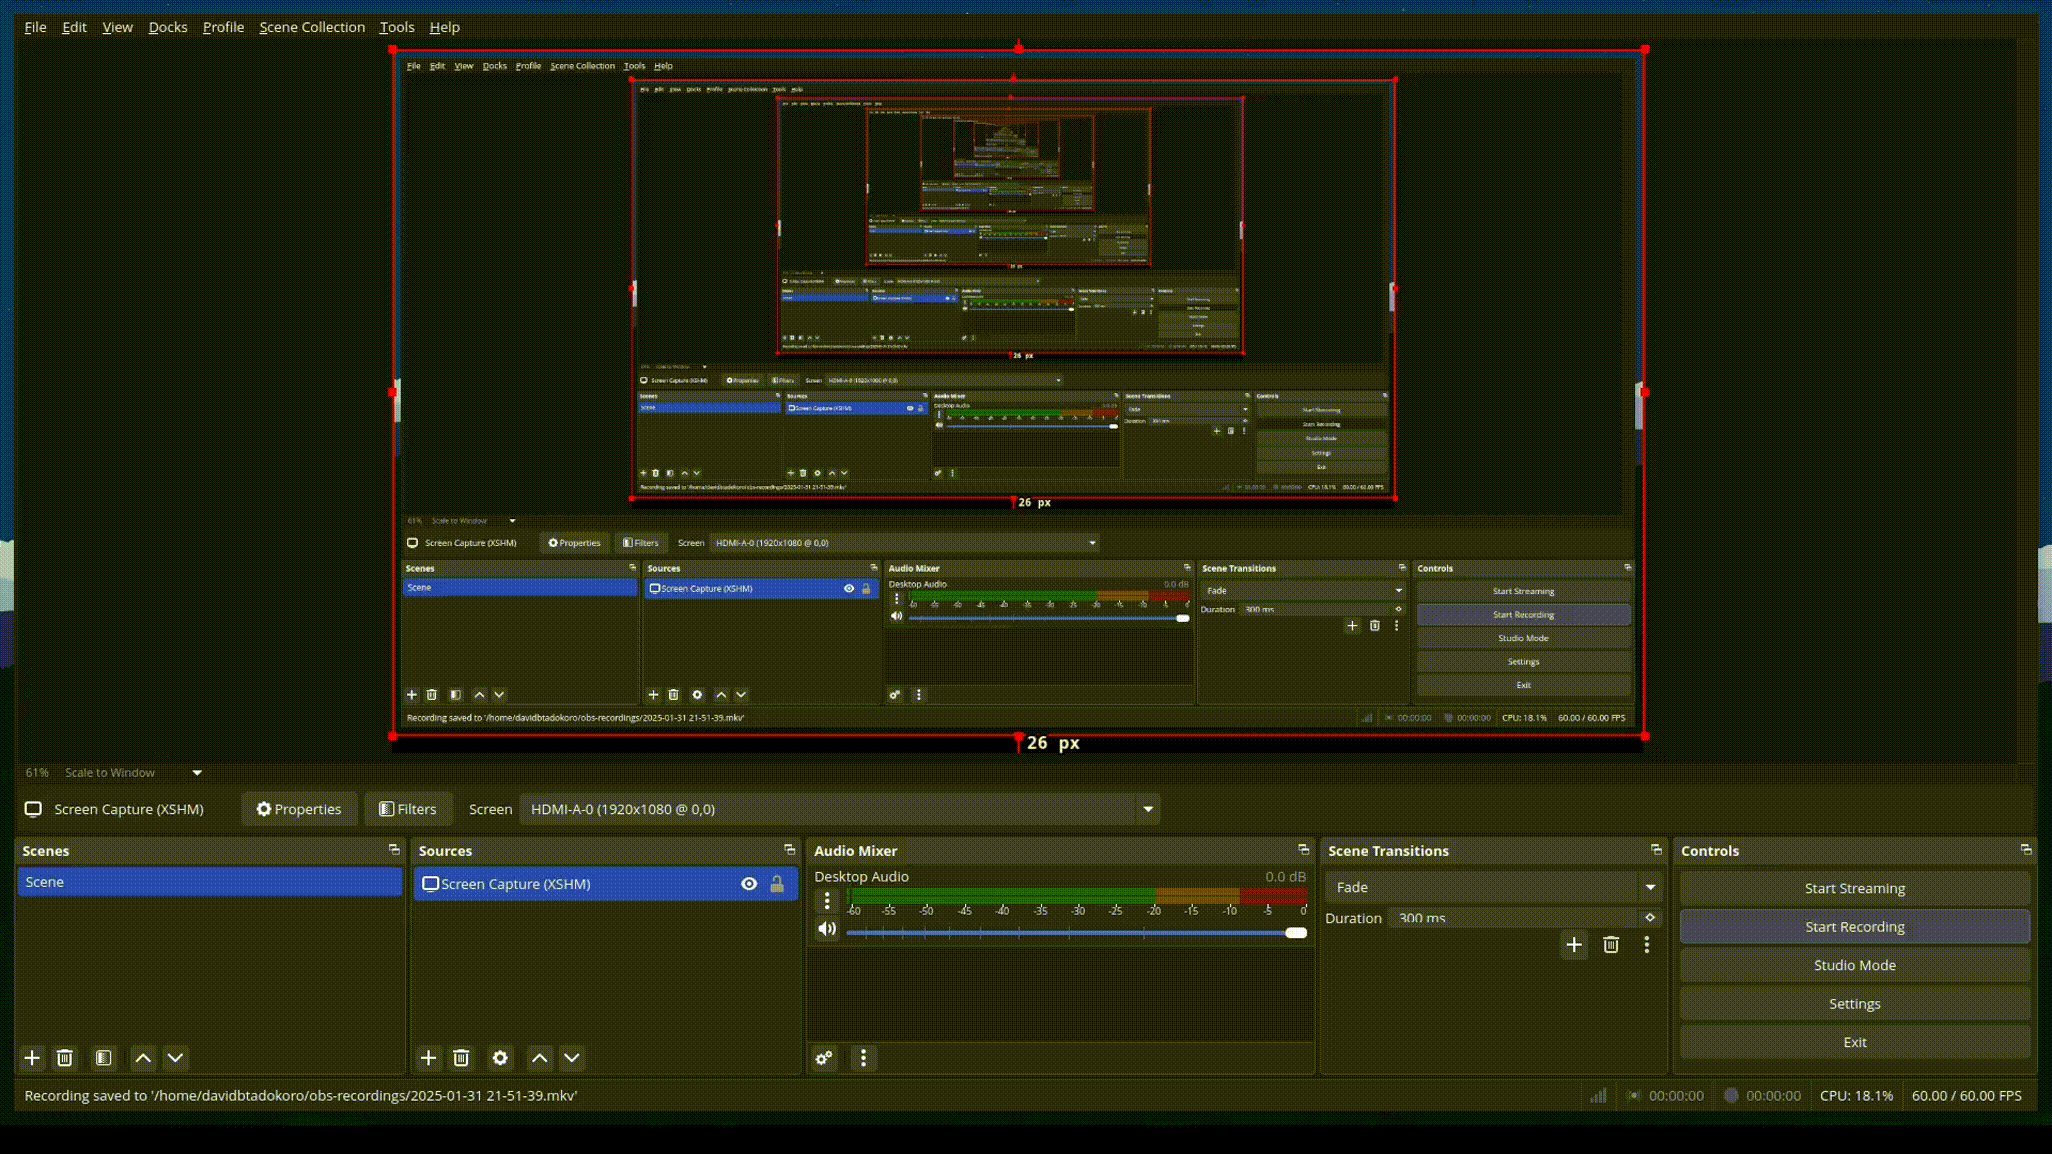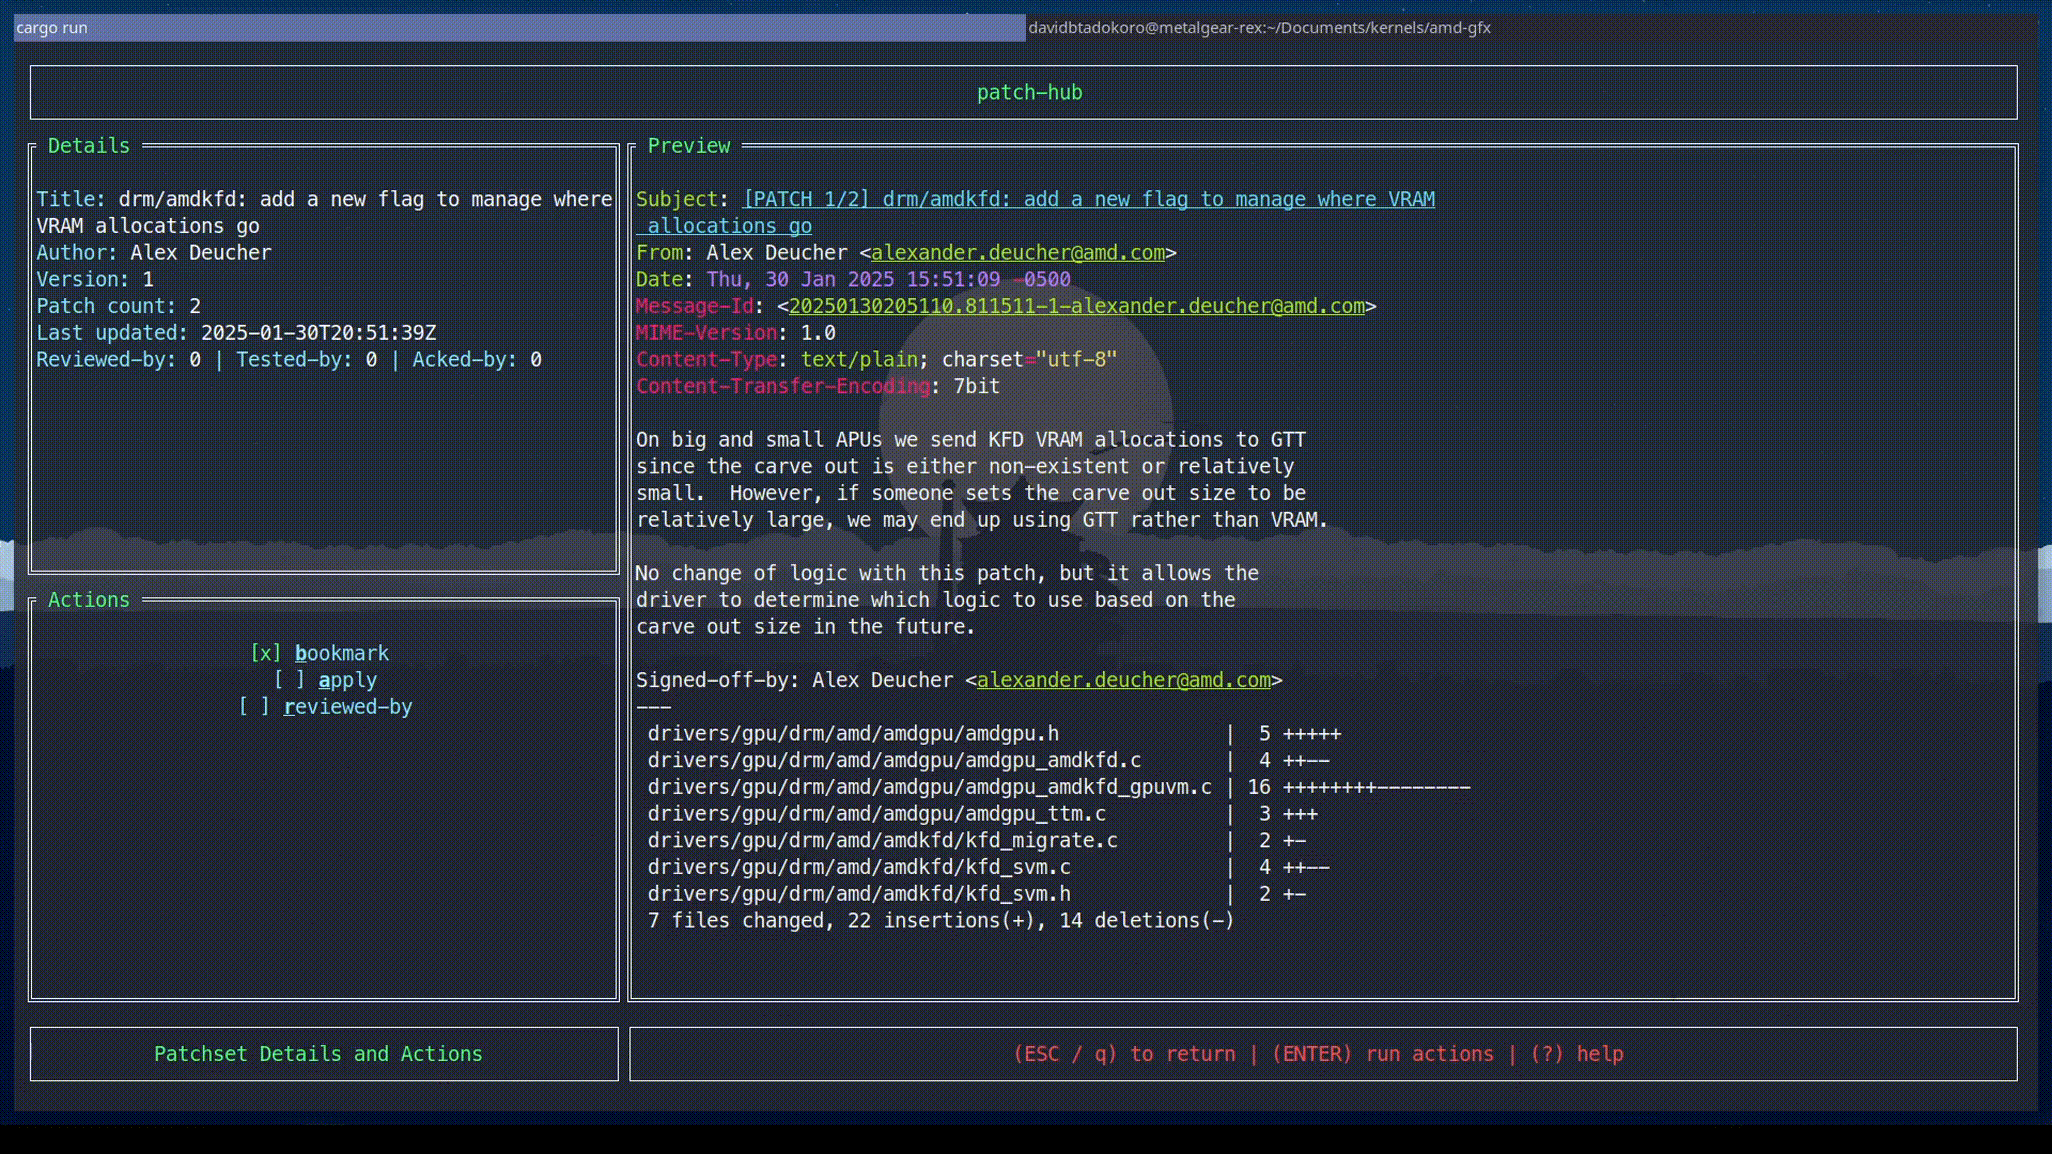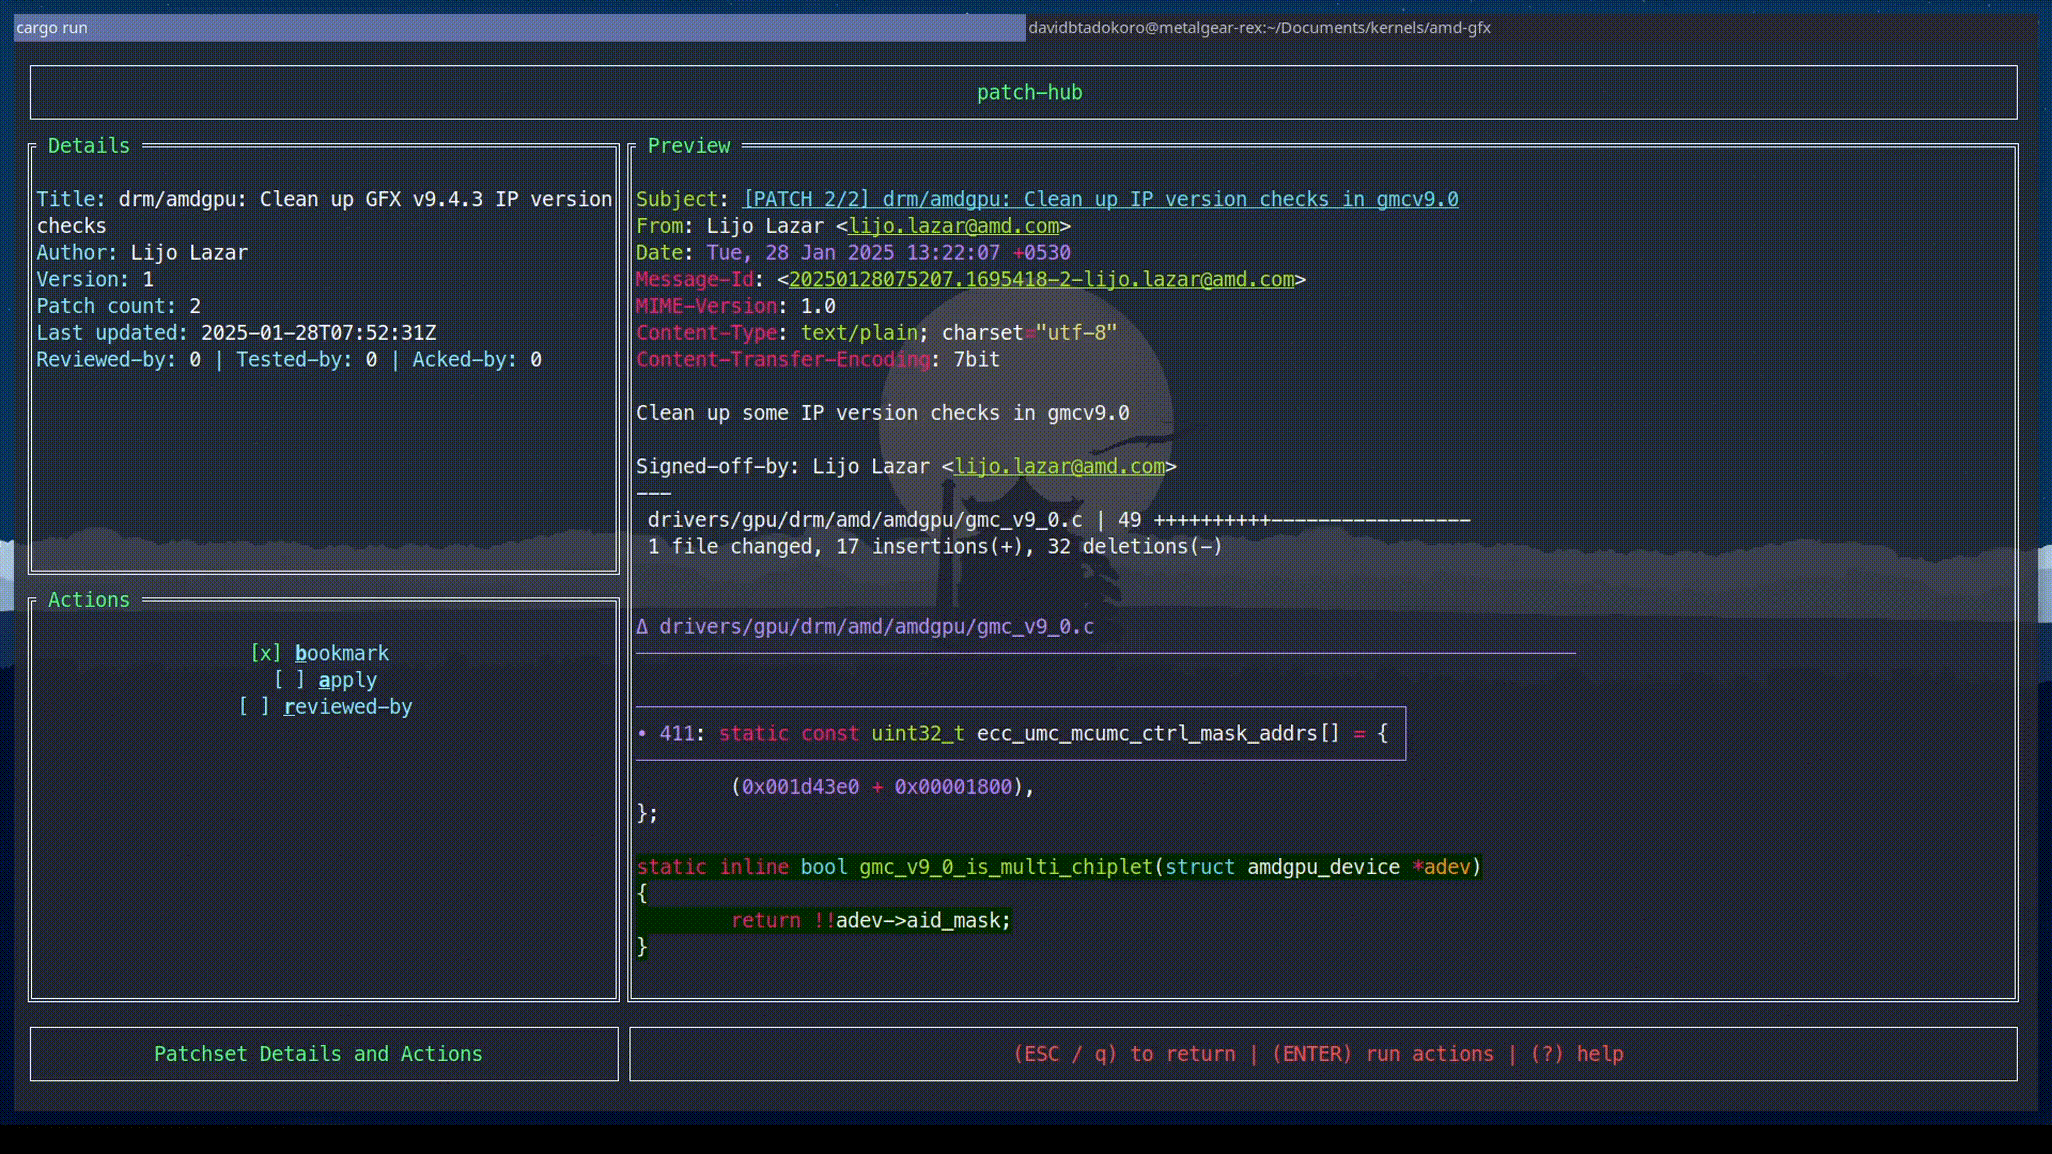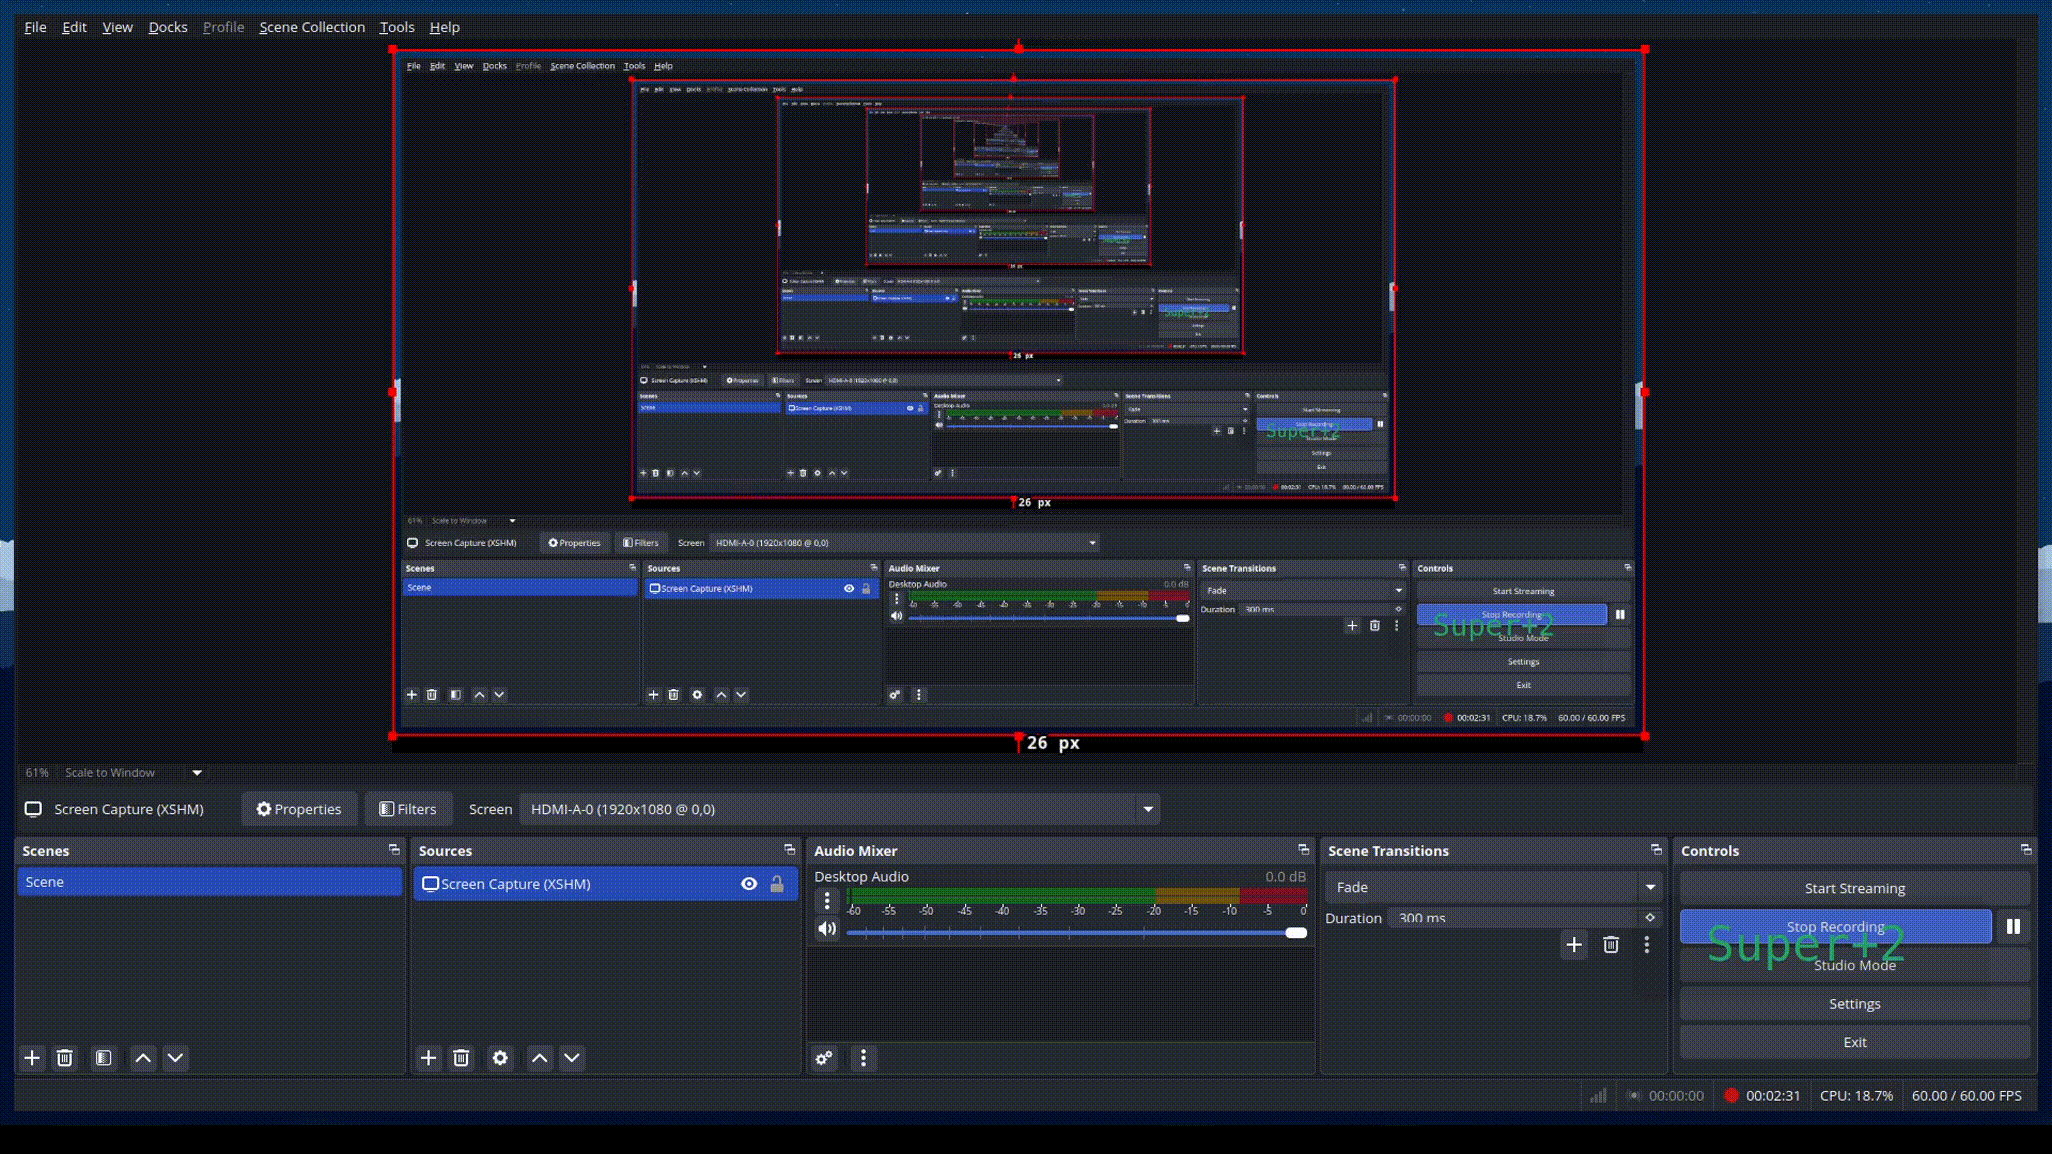
Demo Now a demo of how to use kw environment to deal with different devices, architectures and distributions in the same work tree without losing compiled files, build and deploy settings, .config file, remote access configuration and other settings specific for those three devices that I have.

Setup
  • Three devices:
    • laptop (debian x86 intel local)
    • SteamDeck (steamos x86 amd remote)
    • RaspberryPi 4 (raspbian arm64 broadcomm remote)
  • Goal: To validate a change on DRM/VKMS using a single kernel tree.
  • Kworkflow commands:
    • kw env
    • kw d
    • kw bd
    • kw device
    • kw debug
    • kw drm

Demo script In the same terminal and worktree.

First target device: Laptop (debian x86 intel local)
$ kw env --list # list environments available in this work tree
$ kw env --use LOCAL # select the environment of local machine (laptop) to use: loading pre-compiled files, kernel and kworkflow settings.
$ kw device # show device information
$ sudo modinfo vkms # show VKMS module information before applying kernel changes.
$ <open VKMS file and change module info>
$ kw bd # compile and install kernel with the given change
$ sudo modinfo vkms # show VKMS module information after kernel changes.
$ git checkout -- drivers
Second target device: RaspberryPi 4 (raspbian arm64 broadcomm remote)
$ kw env --use RPI_64 # move to the environment for a different target device.
$ kw device # show device information and kernel image name
$ kw drm --gui-off-after-reboot # set the system to not load graphical layer after reboot
$ kw b # build the kernel with the VKMS change
$ kw d --reboot # deploy the custom kernel in a Raspberry Pi 4 with Raspbian 64, and reboot
$ kw s # connect with the target machine via ssh and check the kernel image name
$ exit
Third target device: SteamDeck (steamos x86 amd remote)
$ kw env --use STEAMDECK # move to the environment for a different target device
$ kw device # show device information
$ kw debug --dmesg --follow --history --cmd="modprobe vkms" # run a command and show the related dmesg output
$ kw debug --dmesg --follow --history --cmd="modprobe -r vkms" # run a command and show the related dmesg output
$ <add a printk with a random msg to appear on dmesg log>
$ kw bd # deploy and install custom kernel to the target device
$ kw debug --dmesg --follow --history --cmd="modprobe vkms" # run a command and show the related dmesg output after build and deploy the kernel change

Q&A Most of the questions raised at the end of the presentation were actually suggestions and additions of new features to kworkflow. The first participant, that is also a kernel maintainer, asked about two features: (1) automatize getting patches from patchwork (or lore) and triggering the process of building, deploying and validating them using the existing workflow, (2) bisecting support. They are both very interesting features. The first one fits well the patch-hub subproject, that is under-development, and I ve actually made a similar request a couple of weeks before the talk. The second is an already existing request in kworkflow github project. Another request was to use kexec and avoid rebooting the kernel for testing. Reviewing my presentation I realized I wasn t very clear that kworkflow doesn t support kexec. As I replied, what it does is to install the modules and you can load/unload them for validations, but for built-in parts, you need to reboot the kernel. Another two questions: one about Android Debug Bridge (ADB) support instead of SSH and another about support to alternative ways of booting when the custom kernel ended up broken but you only have one kernel image there. Kworkflow doesn t manage it yet, but I agree this is a very useful feature for embedded devices. On Raspberry Pi 4, kworkflow mitigates this issue by preserving the distro kernel image and using config.txt file to set a custom kernel for booting. For ADB, there is no support too, and as I don t see currently users of KW working with Android, I don t think we will have this support any time soon, except if we find new volunteers and increase the pool of contributors. The last two questions were regarding the status of b4 integration, that is under development, and other debugging features that the tool doesn t support yet. Finally, when Andrea and I were changing turn on the stage, he suggested to add support for virtme-ng to kworkflow. So I opened an issue for tracking this feature request in the project github. With all these questions and requests, I could see the general need for a tool that integrates the variety of kernel developer workflows, as proposed by kworflow. Also, there are still many cases to be covered by kworkflow. Despite the high demand, this is a completely voluntary project and it is unlikely that we will be able to meet these needs given the limited resources. We will keep trying our best in the hope we can increase the pool of users and contributors too.

20 April 2025

Russ Allbery: Review: Up the Down Staircase

Review: Up the Down Staircase, by Bel Kaufman
Publisher: Vintage Books
Copyright: 1964, 1991, 2019
Printing: 2019
ISBN: 0-525-56566-3
Format: Kindle
Pages: 360
Up the Down Staircase is a novel (in an unconventional format, which I'll describe in a moment) about the experiences of a new teacher in a fictional New York City high school. It was a massive best-seller in the 1960s, including a 1967 movie, but seems to have dropped out of the public discussion. I read it from the library sometime in the late 1980s or early 1990s and have thought about it periodically ever since. It was Bel Kaufman's first novel. Sylvia Barrett is a new graduate with a master's degree in English, where she specialized in Chaucer. As Up the Down Staircase opens, it is her first day as an English teacher in Calvin Coolidge High School. As she says in a letter to a college friend:
What I really had in mind was to do a little teaching. "And gladly wolde he lerne, and gladly teche" like Chaucer's Clerke of Oxenford. I had come eager to share all I know and feel; to imbue the young with a love for their language and literature; to instruct and to inspire. What happened in real life (when I had asked why they were taking English, a boy said: "To help us in real life") was something else again, and even if I could describe it, you would think I am exaggerating.
She instead encounters chaos and bureaucracy, broken windows and mindless regulations, a librarian who is so protective of her books that she doesn't let any students touch them, a school guidance counselor who thinks she's Freud, and a principal whose sole interaction with the school is to occasionally float through on a cushion of cliches, dispensing utterly useless wisdom only to vanish again.
I want to take this opportunity to extend a warm welcome to all faculty and staff, and the sincere hope that you have returned from a healthful and fruitful summer vacation with renewed vim and vigor, ready to gird your loins and tackle the many important and vital tasks that lie ahead undaunted. Thank you for your help and cooperation in the past and future. Maxwell E. Clarke
Principal
In practice, the school is run by James J. McHare, Clarke's administrative assistant, who signs his messages JJ McH, Adm. Asst. and who Sylvia immediately starts calling Admiral Ass. McHare is a micro-managing control freak who spends the book desperately attempting to impose order over school procedures, the teachers, and the students, with very little success. The title of the book comes from one of his detention slips:
Please admit bearer to class Detained by me for going Up the Down staircase and subsequent insolence. JJ McH
The conceit of this book is that, except for the first and last chapters, it consists only of memos, letters, notes, circulars, and other paper detritus, often said to come from Sylvia's wastepaper basket. Sylvia serves as the first-person narrator through her long letters to her college friend, and through shorter but more frequent exchanges via intraschool memo with Beatrice Schachter, another English teacher at the same school, but much of the book lies outside her narration. The reader has to piece together what's happening from the discarded paper of a dysfunctional institution. Amid the bureaucratic and personal communications, there are frequent chapters with notes from the students, usually from the suggestion box that Sylvia establishes early in the book. These start as chaotic glimpses of often-misspelled wariness or open hostility, but over the course of Up the Down Staircase, some of the students become characters with fragmentary but still visible story arcs. This remains confusing throughout the novel there are too many students to keep them entirely straight, and several of them use pseudonyms for the suggestion box but it's the sort of confusion that feels like an intentional authorial choice. It mirrors the difficulty a teacher has in piecing together and remembering the stories of individual students in overstuffed classrooms, even if (like Sylvia and unlike several of her colleagues) the teacher is trying to pay attention. At the start, Up the Down Staircase reads as mostly-disconnected humor. There is a strong "kids say the darnedest things" vibe, which didn't entirely work for me, but the send-up of chaotic bureaucracy is both more sophisticated and more entertaining. It has the "laugh so that you don't cry" absurdity of a system with insufficient resources, entirely absent management, and colleagues who have let their quirks take over their personalities. Sylvia alternates between incredulity and stubbornness, and I think this book is at its best when it shows the small acts of practical defiance that one uses to carve out space and coherence from mismanaged bureaucracy. But this book is not just a collection of humorous anecdotes about teaching high school. Sylvia is sincere in her desire to teach, which crystallizes around, but is not limited to, a quixotic attempt to reach one delinquent that everyone else in the school has written off. She slowly finds her footing, she has a few breakthroughs in reaching her students, and the book slowly turns into an earnest portrayal of an attempt to make the system work despite its obvious unfitness for purpose. This part of the book is hard to review. Parts of it worked brilliantly; I could feel myself both adjusting my expectations alongside Sylvia to something less idealistic and also celebrating the rare breakthrough with her. Parts of it were weirdly uncomfortable in ways that I'm not sure I enjoyed. That includes Sylvia's climactic conversation with the boy she's been trying to reach, which was weirdly charged and ambiguous in a way that felt like the author's reach exceeding their grasp. One thing that didn't help my enjoyment is Sylvia's relationship with Paul Barringer, another of the English teachers and a frustrated novelist and poet. Everyone who works at the school has found their own way to cope with the stress and chaos, and many of the ways that seem humorous turn out to have a deeper logic and even heroism. Paul's, however, is to retreat into indifference and alcohol. He is a believable character who works with Kaufman's themes, but he's also entirely unlikable. I never understood why Sylvia tolerated that creepy asshole, let alone kept having lunch with him. It is clear from the plot of the book that Kaufman at least partially understands Paul's deficiencies, but that did not help me enjoy reading about him. This is a great example of a book that tried to do something unusual and risky and didn't entirely pull it off. I like books that take a risk, and sometimes Up the Down Staircase is very funny or suddenly insightful in a way that I'm not sure Kaufman could have reached with a more traditional novel. It takes a hard look at what it means to try to make a system work when it's clearly broken and you can't change it, and the way all of the characters arrive at different answers that are much deeper than their initial impressions was subtle and effective. It's the sort of book that sticks in your head, as shown by the fact I bought it on a whim to re-read some 35 years after I first read it. But it's not consistently great. Some parts of it drag, the characters are frustratingly hard to keep track of, and the emotional climax points are odd and unsatisfying, at least to me. I'm not sure whether to recommend it or not, but it's certainly unusual. I'm glad I read it again, but I probably won't re-read it for another 35 years, at least. If you are considering getting this book, be aware that it has a lot of drawings and several hand-written letters. The publisher of the edition I read did a reasonably good job formatting this for an ebook, but some of the pages, particularly the hand-written letters, were extremely hard to read on a Kindle. Consider paper, or at least reading on a tablet or computer screen, if you don't want to have to puzzle over low-resolution images. The 1991 trade paperback had a new introduction by the author, reproduced in the edition I read as an afterward (which is a better choice than an introduction). It is a long and fascinating essay from Kaufman about her experience with the reaction to this book, culminating in a passionate plea for supporting public schools and public school teachers. Kaufman's personal account adds a lot of depth to the story; I highly recommend it. Content note: Self-harm, plus several scenes that are closely adjacent to student-teacher relationships. Kaufman deals frankly with the problems of mostly-poor high school kids, including sexuality, so be warned that this is not the humorous romp that it might appear on first glance. A couple of the scenes made me uncomfortable; there isn't anything explicit, but the emotional overtones can be pretty disturbing. Rating: 7 out of 10

17 April 2025

Simon Josefsson: Verified Reproducible Tarballs

Remember the XZ Utils backdoor? One factor that enabled the attack was poor auditing of the release tarballs for differences compared to the Git version controlled source code. This proved to be a useful place to distribute malicious data. The differences between release tarballs and upstream Git sources is typically vendored and generated files. Lots of them. Auditing all source tarballs in a distribution for similar issues is hard and boring work for humans. Wouldn t it be better if that human auditing time could be spent auditing the actual source code stored in upstream version control instead? That s where auditing time would help the most. Are there better ways to address the concern about differences between version control sources and tarball artifacts? Let s consider some approaches: While I like the properties of the first solution, and have made effort to support that approach, I don t think normal source tarballs are going away any time soon. I am concerned that it may not even be a desirable complete solution to this problem. We may need tarballs with pre-generated content in them for various reasons that aren t entirely clear to us today. So let s consider the second approach. It could help while waiting for more experience with the first approach, to see if there are any fundamental problems with it. How do you know that the XZ release tarballs was actually derived from its version control sources? The same for Gzip? Coreutils? Tar? Sed? Bash? GCC? We don t know this! I am not aware of any automated or collaborative effort to perform this independent confirmation. Nor am I aware of anyone attempting to do this on a regular basis. We would want to be able to do this in the year 2042 too. I think the best way to reach that is to do the verification continuously in a pipeline, fixing bugs as time passes. The current state of the art seems to be that people audit the differences manually and hope to find something. I suspect many package maintainers ignore the problem and take the release source tarballs and trust upstream about this. We can do better. I have launched a project to setup a GitLab pipeline that invokes per-release scripts to rebuild that release artifact from git sources. Currently it only contain recipes for projects that I released myself. Releases which where done in a controlled way with considerable care to make reproducing the tarballs possible. The project homepage is here: https://gitlab.com/debdistutils/verify-reproducible-releases The project is able to reproduce the release tarballs for Libtasn1 v4.20.0, InetUtils v2.6, Libidn2 v2.3.8, Libidn v1.43, and GNU SASL v2.2.2. You can see this in a recent successful pipeline. All of those releases were prepared using Guix, and I m hoping the Guix time-machine will make it possible to keep re-generating these tarballs for many years to come. I spent some time trying to reproduce the current XZ release tarball for version 5.8.1. That would have been a nice example, wouldn t it? First I had to somehow mimic upstream s build environment. The XZ release tarball contains GNU Libtool files that are identified with version 2.5.4.1-baa1-dirty. I initially assumed this was due to the maintainer having installed libtool from git locally (after making some modifications) and made the XZ release using it. Later I learned that it may actually be coming from ArchLinux which ship with this particular libtool version. It seems weird for a distribution to use libtool built from a non-release tag, and furthermore applying patches to it, but things are what they are. I made some effort to setup an ArchLinux build environment, however the now-current Gettext version in ArchLinux seems to be more recent than the one that were used to prepare the XZ release. I don t know enough ArchLinux to setup an environment corresponding to an earlier version of ArchLinux, which would be required to finish this. I gave up, maybe the XZ release wasn t prepared on ArchLinux after all. Actually XZ became a good example for this writeup anyway: while you would think this should be trivial, the fact is that it isn t! (There is another aspect here: fingerprinting the versions used to prepare release tarballs allows you to infer what kind of OS maintainers are using to make releases on, which is interesting on its own.) I made some small attempts to reproduce the tarball for GNU Shepherd version 1.0.4 too, but I still haven t managed to complete it. Do you want a supply-chain challenge for the Easter weekend? Pick some well-known software and try to re-create the official release tarballs from the corresponding Git checkout. Is anyone able to reproduce anything these days? Bonus points for wrapping it up as a merge request to my project. Happy Supply-Chain Security Hacking!

16 April 2025

Otto Kek l inen: Going Full-Time as an Open Source Developer

Featured image of post Going Full-Time as an Open Source DeveloperAfter careful consideration, I ve decided to embark on a new chapter in my professional journey. I ve left my position at AWS to dedicate at least the next six months to developing open source software and strengthening digital ecosystems. My focus will be on contributing to Linux distributions (primarily Debian) and other critical infrastructure components that our modern society depends on, but which may not receive adequate attention or resources.

The Evolution of Open Source Open source won. Over the 25+ years I ve been involved in the open source movement, I ve witnessed its remarkable evolution. Today, Linux powers billions of devices from tiny embedded systems and Android smartphones to massive cloud datacenters and even space stations. Examine any modern large-scale digital system, and you ll discover it s built upon thousands of open source projects. I feel the priority for the open source movement should no longer be increasing adoption, but rather solving how to best maintain the vast ecosystem of software. This requires building robust institutions and processes to secure proper resourcing and ensure the collaborative development process remains efficient and leads to ever-increasing quality of software.

What is Special About Debian? Debian, established in 1993 by Ian Murdock, stands as one of these institutions that has demonstrated exceptional resilience. There is no single authority, but instead a complex web of various stakeholders, each with their own goals and sources of funding. Every idea needs to be championed at length to a wide audience and implemented through a process of organic evolution. Thanks to this approach, Debian has been consistently delivering production-quality, universally useful software for over three decades. Having been a Debian Developer for more than ten years, I m well-positioned to contribute meaningfully to this community. If your organization relies on Debian or its derivatives such as Ubuntu, and you re interested in funding cyber infrastructure maintenance by sponsoring Debian work, please don t hesitate to reach out. This could include package maintenance and version currency, improving automated upgrade testing, general quality assurance and supply chain security enhancements.
Best way to reach me is by e-mail otto at debian.org. You can also book a 15-minute chat with me for a quick introduction.

Grow or Die My four-year tenure as a Software Development Manager at Amazon Web Services was very interesting. I m grateful for my time at AWS and proud of my team s accomplishments, particularly for creating an open source contribution process that got Amazon from zero to the largest external contributor to the MariaDB open source database. During this time, I got to experience and witness a plethora of interesting things. I will surely share some of my key learnings in future blog posts. Unfortunately, the rate of progress in this mammoth 1.5 million employee organization was slowing down, and I didn t feel I learned much new in the last years. This realization, combined with the opportunity cost of not spending enough time on new cutting-edge technology, motivated me to take this leap. Being a full-time open source developer may not be financially the most lucrative idea, but I think it is an excellent way to force myself to truly assess what is important on a global scale and what areas I want to contribute to. Working fully on open source presents a fascinating duality: you re not bound by any external resource or schedule limitations, and can the progress you make is directly proportional to how much energy you decide to invest. Yet, you also depend on collaboration with people you might never meet and who are not financially incentivized to collaborate. This will undoubtedly expose me to all kinds of challenges. But what would be better in fostering holistic personal growth? I know that deep down in my DNA, I am not made to stay cozy or to do easy things. I need momentum. OK, let s get going

15 April 2025

Russell Coker: What Desktop PCs Need

It seems to me that we haven t had much change in the overall design of desktop PCs since floppy drives were removed, and modern PCs still have bays the size of 5.25 floppy drives despite having nothing modern that can fit in such spaces other than DVD drives (which aren t really modern) and carriers for 4*2.5 drives both of which most people don t use. We had the PC System Design Guide [1] which was last updated in 2001 which should have been updated more recently to address some of these issues, the thing that most people will find familiar in that standard is the colours for audio ports. Microsoft developed the Legacy Free PC [2] concept which was a good one. There s a lot of things that could be added to the list of legacy stuff to avoid, TPM 1.2, 5.25 drive bays, inefficient PSUs, hardware that doesn t sleep when idle or which prevents the CPU from sleeping, VGA and DVI ports, ethernet slower than 2.5Gbit, and video that doesn t include HDMI 2.1 or DisplayPort 2.1 for 8K support. There are recently released high-end PCs on sale right now with 1gbit ethernet as standard and hardly any PCs support resolutions above 4K properly. Here are some of the things that I think should be in a modern PC System Design Guide. Power Supply The power supply is a core part of the computer and it s central location dictates the layout of the rest of the PC. GaN PSUs are more power efficient and therefore require less cooling. A 400W USB power supply is about 1/4 the size of a standard PC PSU and doesn t have a cooling fan. A new PC standard should include less space for the PSU except for systems with multiple CPUs or that are designed for multiple GPUs. A Dell T630 server has an option of a 1600W PSU that is 20*8.5*4cm = 680cc. The typical dimensions of an ATX PSU are 15*8.6*14cm = 1806cc. The SFX (small form factor variant of ATX) PSU is 12.5*6.3*10cm = 787cc. There is a reason for the ATX and SFX PSUs having a much worse ratio of power to size and that is the airflow. Server class systems are designed for good airflow and can efficiently cool the PSU with less space and they are also designed for uses where people are less concerned about fan noise. But the 680cc used for a 1600W Dell server PSU that predates GaN technology could be used for a modern GaN PSU that supplies the ~600W needed for a modern PC while being quiet. There are several different smaller size PSUs for name-brand PCs (where compatibility with other systems isn t needed) that have been around for ~20 years but there hasn t been a standard so all white-box PC systems have had really large PSUs. PCs need USB-C PD ports that can charge a laptop etc. There are phones that can draw 80W for fast charging and it s not unreasonable to expect a PC to be able to charge a phone at it s maximum speed. GPUs should have USB-C alternate mode output and support full USB functionality over the cable as well as PD that can power the monitor. Having a monitor with a separate PSU, a HDMI or DP cable to the PC, and a USB cable between PC and monitor is an annoyance. There should be one cable between PC and monitor and then keyboard, mouse, etc should connect to the monior. All devices that are connected to a PC should use USB-C for power connection. That includes monitors that are using HDMI or DisplayPort for video, desktop switches, home Wifi APs, printers, and speakers (even when using line-in for the audio signal). The European Commission Common Charger Directive is really good but it only covers portable devices, keyboards, and mice. Motherboard Features Latest verions of Wifi and Bluetooth on the motherboard (this is becoming a standard feature). On motherboard video that supports 8K resolution. An option of a PCIe GPU is a good thing to have but it would be nice if the motherboard had enough video capabilities to satisfy most users. There are several options for video that have a higher resolution than 4K and making things just work at 8K means that there will be less e-waste in future. ECC RAM should be a standard feature on all motherboards, having a single bit error cause a system crash is a MS-DOS thing, we need to move past that. There should be built in hardware for monitoring the system status that is better than BIOS beeps on boot. Lenovo laptops have a feature for having the BIOS play a tune on a serious error with an Android app to decode the meaning of the tune, we could have a standard for this. For desktop PCs there should be a standard for LCD status displays similar to the ones on servers, this would be cheap if everyone did it. Case Features The way the Framework Laptop can be expanded with modules is really good [3]. There should be something similar for PC cases. While you can buy USB devices for these things they are messy and risk getting knocked out of their sockets when moving cables around. While the Framework laptop expansion cards are much more expensive than other devices with similar functions that are aimed at a mass market if there was a standard for PCs then the devices to fit them would become cheap. The PC System Design Guide specifies colors for ports (which is good) but not the feel of them. While some ports like Ethernet ports allow someone to feel which way the connector should go it isn t possible to easily feel which way a HDMI or DisplayPort connector should go. It would be good if there was a standard that required plastic spikes on one side or some other way of feeling which way a connector should go. GPU Placement In modern systems it s fairly common to have a high heatsink on the CPU with a fan to blow air in at the front and out the back of the PC. The GPU (which often dissipates twice as much heat as the CPU) has fans blowing air in sideways and not out the back. This gives some sort of compromise between poor cooling and excessive noise. What we need is to have air blown directly through a GPU heatsink and out of the case. One option for a tower case that needs minimal changes is to have the PCIe slot nearest the bottom of the case used for the GPU and have a grille in the bottom to allow air to go out, the case could have feet to keep it a few cm above the floor or desk. Another possibility is to have a PCIe slot parallel to the rear surface of the case (right angles to the other PCIe slots). A common case with desktop PCs is to have the GPU use more than half the total power of the PC. The placement of the GPU shouldn t be an afterthought, it should be central to the design. Is a PCIe card even a good way of installing a GPU? Could we have a standard GPU socket on the motherboard next to the CPU socket and use the same type of heatsink and fan for GPU and CPU? External Cooling There are a range of aftermarket cooling devices for laptops that push cool air in the bottom or suck it out the side. We need to have similar options for desktop PCs. I think it would be ideal to have a standard attachments for airflow on the front and back of tower PCs. The larger a fan is the slower it can spin to give the same airflow and therefore the less noise it will produce. Instead of just relying on 10cm fans at the front and back of a PC to push air in and suck it out you could have a conical rubber duct connected to a 30cm diameter fan. That would allow quieter fans to do most of the work in pushing air through the PC and also allow the hot air to be directed somewhere suitable. When doing computer work in summer it s not great to have a PC sending 300+W of waste heat into the room you are in. If it could be directed out a window that would be good. Noise For restricting noise of PCs we have industrial relations legislation that seems to basically require that workers not be exposed to noise louder than a blender, so if a PC is quieter than that then it s OK. For name brand PCs there are specs about how much noise is produced but there are usually caveats like under typical load or with a typical feature set that excuse them from liability if the noise is louder than expected. It doesn t seem possible for someone to own a PC, determine that the noise from it is what is acceptable, and then buy another that is close to the same. We need regulations about this, and the EU seems the best jurisdiction for it as they cover the purchase of a lot of computer equipment that is also sold without change in other countries. The regulations need to also cover updates, for example I have a Dell T630 which is unreasonably loud and Dell support doesn t have much incentive to be particularly helpful about it. BIOS updates routinely tweak things like fan speeds without the developers having an incentive to keep it as quiet as it was when it was sold. What Else? Please comment about other things you think should be standard PC features.

13 April 2025

Keith Packard: sanitizer-fun

Fun with -fsanitize=undefined and Picolibc Both GCC and Clang support the -fsanitize=undefined flag which instruments the generated code to detect places where the program wanders into parts of the C language specification which are either undefined or implementation defined. Many of these are also common programming errors. It would be great if there were sanitizers for other easily detected bugs, but for now, at least the undefined sanitizer does catch several useful problems. Supporting the sanitizer The sanitizer can be built to either trap on any error or call handlers. In both modes, the same problems are identified, but when trap mode is enabled, the compiler inserts a trap instruction and doesn't expect the program to continue running. When handlers are in use, each identified issue is tagged with a bunch of useful data and then a specific sanitizer handling function is called. The specific functions are not all that well documented, nor are the parameters they receive. Maybe this is because both compilers provide an implementation of all of the functions they use and don't really expect external implementations to exist? However, to make these useful in an embedded environment, picolibc needs to provide a complete set of handlers that support all versions both gcc and clang as the compiler-provided versions depend upon specific C (and C++) libraries. Of course, programs can be built in trap-on-error mode, but that makes it much more difficult to figure out what went wrong. Fixing Sanitizer Issues Once the sanitizer handlers were implemented, picolibc could be built with them enabled and all of the picolibc tests run to uncover issues within the library. As with the static analyzer adventure from last year, the vast bulk of sanitizer complaints came from invoking undefined or implementation-defined behavior in harmless ways: Signed integer shifts This is one area where the C language spec is just wrong. For left shift, before C99, it worked on signed integers as a bit-wise operator, equivalent to the operator on unsigned integers. After that, left shift of negative integers became undefined. Fortunately, it's straightforward (if tedious) to work around this issue by just casting the operand to unsigned, performing the shift and casting it back to the original type. Picolibc now has an internal macro, lsl, which does this:
    #define lsl(__x,__s) ((sizeof(__x) == sizeof(char)) ?                   \
                          (__typeof(__x)) ((unsigned char) (__x) << (__s)) :  \
                          (sizeof(__x) == sizeof(short)) ?                  \
                          (__typeof(__x)) ((unsigned short) (__x) << (__s)) : \
                          (sizeof(__x) == sizeof(int)) ?                    \
                          (__typeof(__x)) ((unsigned int) (__x) << (__s)) :   \
                          (sizeof(__x) == sizeof(long)) ?                   \
                          (__typeof(__x)) ((unsigned long) (__x) << (__s)) :  \
                          (sizeof(__x) == sizeof(long long)) ?              \
                          (__typeof(__x)) ((unsigned long long) (__x) << (__s)) : \
                          __undefined_shift_size(__x, __s))
Right shift is significantly more complicated to implement. What we want is an arithmetic shift with the sign bit being replicated as the value is shifted rightwards. C defines no such operator. Instead, right shift of negative integers is implementation defined. Fortunately, both gcc and clang define the >> operator on signed integers as arithmetic shift. Also fortunately, C hasn't made this undefined, so the program itself doesn't end up undefined. The trouble with arithmetic right shift is that it is not equivalent to right shift of unsigned values. Here's what Per Vognsen came up with using standard C operators:
    int
    __asr_int(int x, int s)  
        return x < 0 ? ~(~x >> s) : x >> s;
     
When the value is negative, we invert all of the bits (making it positive), shift right, then flip all of the bits back. Both GCC and Clang seem to compile this to a single asr instruction. This function is replicated for each of the five standard integer types and then the set of them wrapped in another sizeof-selecting macro:
    #define asr(__x,__s) ((sizeof(__x) == sizeof(char)) ?           \
                          (__typeof(__x))__asr_char(__x, __s) :       \
                          (sizeof(__x) == sizeof(short)) ?          \
                          (__typeof(__x))__asr_short(__x, __s) :      \
                          (sizeof(__x) == sizeof(int)) ?            \
                          (__typeof(__x))__asr_int(__x, __s) :        \
                          (sizeof(__x) == sizeof(long)) ?           \
                          (__typeof(__x))__asr_long(__x, __s) :       \
                          (sizeof(__x) == sizeof(long long)) ?      \
                          (__typeof(__x))__asr_long_long(__x, __s):   \
                          __undefined_shift_size(__x, __s))
The lsl and asr macros use sizeof instead of the type-generic mechanism to remain compatible with compilers that lack type-generic support. Once these macros were written, they needed to be applied where required. To preserve the benefits of detecting programming errors, they were only applied where required, not blindly across the whole codebase. There are a couple of common patterns in the math code using shift operators. One is when computing the exponent value for subnormal numbers.
for (ix = -1022, i = hx << 11; i > 0; i <<= 1)
    ix -= 1;
This code computes the exponent by shifting the significand left by 11 bits (the width of the exponent field) and then incrementally shifting it one bit at a time until the sign flips, which indicates that the most-significant bit is set. Use of the pre-C99 definition of the left shift operator is intentional here; so both shifts are replaced with our lsl operator. In the implementation of pow, the final exponent is computed as the sum of the two exponents, both of which are in the allowed range. The resulting sum is then tested to see if it is zero or negative to see if the final value is sub-normal:
hx += n << 20;
if (hx >> 20 <= 0)
    /* do sub-normal things */
In this case, the exponent adjustment, n, is a signed value and so that shift is replaced with the lsl macro. The test value needs to compute the correct the sign bit, so we replace this with the asr macro. Because the right shift operation is not undefined, we only use our fancy macro above when the undefined behavior sanitizer is enabled. On the other hand, the lsl macro should have zero cost and covers undefined behavior, so it is always used. Actual Bugs Found! The goal of this little adventure was both to make using the undefined behavior sanitizer with picolibc possible as well as to use the sanitizer to identify bugs in the library code. I fully expected that most of the effort would be spent masking harmless undefined behavior instances, but was hopeful that the effort would also uncover real bugs in the code. I was not disappointed. Through this work, I found (and fixed) eight bugs in the code:
  1. setlocale/newlocale didn't check for NULL locale names
  2. qsort was using uintptr_t to swap data around. On MSP430 in 'large' mode, that's a 20-bit type inside a 32-bit representation.
  3. random() was returning values in int range rather than long.
  4. m68k assembly for memcpy was broken for sizes > 64kB.
  5. freopen returned NULL, even on success
  6. The optimized version of memrchr was always performing unaligned accesses.
  7. String to float conversion had a table missing four values. This caused an array access overflow which resulted in imprecise values in some cases.
  8. vfwscanf mis-parsed floating point values by assuming that wchar_t was unsigned.
Sanitizer Wishes While it's great to have a way to detect places in your C code which evoke undefined and implementation defined behaviors, it seems like this tooling could easily be extended to detect other common programming mistakes, even where the code is well defined according to the language spec. An obvious example is in unsigned arithmetic. How many bugs come from this seemingly innocuous line of code?
    p = malloc(sizeof(*p) * c);
Because sizeof returns an unsigned value, the resulting computation never results in undefined behavior, even when the multiplication wraps around, so even with the undefined behavior sanitizer enabled, this bug will not be caught. Clang seems to have an unsigned integer overflow sanitizer which should do this, but I couldn't find anything like this in gcc. Summary The undefined behavior sanitizers present in clang and gcc both provide useful diagnostics which uncover some common programming errors. In most cases, replacing undefined behavior with defined behavior is straightforward, although the lack of an arithmetic right shift operator in standard C is irksome. I recommend anyone using C to give it a try.

12 April 2025

Kalyani Kenekar: Nextcloud Installation HowTo: Secure Your Data with a Private Cloud

Logo NGinx Nextcloud is an open-source software suite that enables you to set up and manage your own cloud storage and collaboration platform. It offers a range of features similar to popular cloud services like Google Drive or Dropbox but with the added benefit of complete control over your data and the server where it s hosted. I wanted to have a look at Nextcloud and the steps to setup a own instance with a PostgreSQL based database together with NGinx as the webserver to serve the WebUI. Before doing a full productive setup I wanted to play around locally with all the needed steps and worked out all the steps within KVM machine. While doing this I wrote down some notes to mostly document for myself what I need to do to get a Nextcloud installation running and usable. So this manual describes how to setup a Nextcloud installation on Debian 12 Bookworm based on NGinx and PostgreSQL.

Nextcloud Installation

Install PHP and PHP extensions for Nextcloud Nextcloud is basically a PHP application so we need to install PHP packages to get it working in the end. The following steps are based on the upstream documentation about how to install a own Nextcloud instance. Installing the virtual package package php on a Debian Bookworm system would pull in the depending meta package php8.2. This package itself would then pull also the package libapache2-mod-php8.2 as an dependency which then would pull in also the apache2 webserver as a depending package. This is something I don t wanted to have as I want to use NGinx that is already installed on the system instead. To get this we need to explicitly exclude the package libapache2-mod-php8.2 from the list of packages which we want to install, to achieve this we have to append a hyphen - at the end of the package name, so we need to use libapache2-mod-php8.2- within the package list that is telling apt to ignore this package as an dependency. I ended up with this call to get all needed dependencies installed.
$ sudo apt install php php-cli php-fpm php-json php-common php-zip \
  php-gd php-intl php-curl php-xml php-mbstring php-bcmath php-gmp \
  php-pgsql libapache2-mod-php8.2-
  • Check php version (optional step) $ php -v
PHP 8.2.28 (cli) (built: Mar 13 2025 18:21:38) (NTS)
Copyright (c) The PHP Group
Zend Engine v4.2.28, Copyright (c) Zend Technologies
    with Zend OPcache v8.2.28, Copyright (c), by Zend Technologies
  • After installing all the packages, edit the php.ini file: $ sudo vi /etc/php/8.2/fpm/php.ini
  • Change the following settings per your requirements:
max_execution_time = 300
memory_limit = 512M
post_max_size = 128M
upload_max_filesize = 128M
  • To make these settings effective, restart the php-fpm service $ sudo systemctl restart php8.2-fpm

Install PostgreSQL, Create a database and user This manual assumes we will use a PostgreSQL server on localhost, if you have a server instance on some remote site you can skip the installation step here. $ sudo apt install postgresql postgresql-contrib postgresql-client
  • Check version after installation (optinal step): $ sudo -i -u postgres $ psql -version
  • This output will be seen: psql (15.12 (Debian 15.12-0+deb12u2))
  • Exit the PSQL shell by using the command \q. postgres=# \q
  • Exit the CLI of the postgres user: postgres@host:~$ exit

Create a PostgreSQL Database and User:
  1. Create a new PostgreSQL user (Use a strong password!): $ sudo -u postgres psql -c "CREATE USER nextcloud_user PASSWORD '1234';"
  2. Create new database and grant access: $ sudo -u postgres psql -c "CREATE DATABASE nextcloud_db WITH OWNER nextcloud_user ENCODING=UTF8;"
  3. (Optional) Check if we now can connect to the database server and the database in detail (you will get a question about the password for the database user!). If this is not working it makes no sense to proceed further! We need to fix first the access then! $ psql -h localhost -U nextcloud_user -d nextcloud_db or $ psql -h 127.0.0.1 -U nextcloud_user -d nextcloud_db
  • Log out from postgres shell using the command \q.

Download and install Nextcloud
  • Use the following command to download the latest version of Nextcloud: $ wget https://download.nextcloud.com/server/releases/latest.zip
  • Extract file into the folder /var/www/html with the following command: $ sudo unzip latest.zip -d /var/www/html
  • Change ownership of the /var/www/html/nextcloud directory to www-data. $ sudo chown -R www-data:www-data /var/www/html/nextcloud

Configure NGinx for Nextcloud to use a certificate In case you want to use self signed certificate, e.g. if you play around to setup Nextcloud locally for testing purposes you can do the following steps.
  • Generate the private key and certificate: $ sudo openssl req -x509 -nodes -days 365 -newkey rsa:2048 -keyout nextcloud.key -out nextcloud.crt $ sudo cp nextcloud.crt /etc/ssl/certs/ && sudo cp nextcloud.key /etc/ssl/private/
  • If you want or need to use the service of Let s Encrypt (or similar) drop the step above and create your required key data by using this command: $ sudo certbot --nginx -d nextcloud.your-domain.com You will need to adjust the path to the key and certificate in the next step!
  • Change the NGinx configuration: $ sudo vi /etc/nginx/sites-available/nextcloud.conf
  • Add the following snippet into the file and save it.
# /etc/nginx/sites-available/nextcloud.conf
upstream php-handler  
    #server 127.0.0.1:9000;
    server unix:/run/php/php8.2-fpm.sock;
 

# Set the  immutable  cache control options only for assets with a cache
# busting  v  argument

map $arg_v $asset_immutable  
    "" "";
    default ", immutable";
 

server  
    listen 80;
    listen [::]:80;
    # Adjust this to the correct server name!
    server_name nextcloud.local;

    # Prevent NGinx HTTP Server Detection
    server_tokens off;

    # Enforce HTTPS
    return 301 https://$server_name$request_uri;
 

server  
    listen 443      ssl http2;
    listen [::]:443 ssl http2;
    # Adjust this to the correct server name!
    server_name nextcloud.local;

    # Path to the root of your installation
    root /var/www/html/nextcloud;

    # Use Mozilla's guidelines for SSL/TLS settings
    # https://mozilla.github.io/server-side-tls/ssl-config-generator/
    # Adjust the usage and paths of the correct key data! E.g. it you want to use Let's Encrypt key material!
    ssl_certificate /etc/ssl/certs/nextcloud.crt;
    ssl_certificate_key /etc/ssl/private/nextcloud.key;
    # ssl_certificate /etc/letsencrypt/live/nextcloud.your-domain.com/fullchain.pem; 
    # ssl_certificate_key /etc/letsencrypt/live/nextcloud.your-domain.com/privkey.pem;

    # Prevent NGinx HTTP Server Detection
    server_tokens off;

    # HSTS settings
    # WARNING: Only add the preload option once you read about
    # the consequences in https://hstspreload.org/. This option
    # will add the domain to a hardcoded list that is shipped
    # in all major browsers and getting removed from this list
    # could take several months.
    #add_header Strict-Transport-Security "max-age=15768000; includeSubDomains; preload" always;

    # set max upload size and increase upload timeout:
    client_max_body_size 512M;
    client_body_timeout 300s;
    fastcgi_buffers 64 4K;

    # Enable gzip but do not remove ETag headers
    gzip on;
    gzip_vary on;
    gzip_comp_level 4;
    gzip_min_length 256;
    gzip_proxied expired no-cache no-store private no_last_modified no_etag auth;
    gzip_types application/atom+xml text/javascript application/javascript application/json application/ld+json application/manifest+json application/rss+xml application/vnd.geo+json application/vnd.ms-fontobject application/wasm application/x-font-ttf application/x-web-app-manifest+json application/xhtml+xml application/xml font/opentype image/bmp image/svg+xml image/x-icon text/cache-manifest text/css text/plain text/vcard text/vnd.rim.location.xloc text/vtt text/x-component text/x-cross-domain-policy;

    # Pagespeed is not supported by Nextcloud, so if your server is built
    # with the  ngx_pagespeed  module, uncomment this line to disable it.
    #pagespeed off;

    # The settings allows you to optimize the HTTP2 bandwidth.
    # See https://blog.cloudflare.com/delivering-http-2-upload-speed-improvements/
    # for tuning hints
    client_body_buffer_size 512k;

    # HTTP response headers borrowed from Nextcloud  .htaccess 
    add_header Referrer-Policy                   "no-referrer"       always;
    add_header X-Content-Type-Options            "nosniff"           always;
    add_header X-Frame-Options                   "SAMEORIGIN"        always;
    add_header X-Permitted-Cross-Domain-Policies "none"              always;
    add_header X-Robots-Tag                      "noindex, nofollow" always;
    add_header X-XSS-Protection                  "1; mode=block"     always;

    # Remove X-Powered-By, which is an information leak
    fastcgi_hide_header X-Powered-By;

    # Set .mjs and .wasm MIME types
    # Either include it in the default mime.types list
    # and include that list explicitly or add the file extension
    # only for Nextcloud like below:
    include mime.types;
    types  
        text/javascript js mjs;
        application/wasm wasm;
     

    # Specify how to handle directories -- specifying  /index.php$request_uri 
    # here as the fallback means that NGinx always exhibits the desired behaviour
    # when a client requests a path that corresponds to a directory that exists
    # on the server. In particular, if that directory contains an index.php file,
    # that file is correctly served; if it doesn't, then the request is passed to
    # the front-end controller. This consistent behaviour means that we don't need
    # to specify custom rules for certain paths (e.g. images and other assets,
    #  /updater ,  /ocs-provider ), and thus
    #  try_files $uri $uri/ /index.php$request_uri 
    # always provides the desired behaviour.
    index index.php index.html /index.php$request_uri;

    # Rule borrowed from  .htaccess  to handle Microsoft DAV clients
    location = /  
        if ( $http_user_agent ~ ^DavClnt )  
            return 302 /remote.php/webdav/$is_args$args;


    location = /robots.txt  
        allow all;
        log_not_found off;
        access_log off;
     

    # Make a regex exception for  /.well-known  so that clients can still
    # access it despite the existence of the regex rule
    #  location ~ /(\. autotest ...)  which would otherwise handle requests
    # for  /.well-known .
    location ^~ /.well-known  
        # The rules in this block are an adaptation of the rules
        # in  .htaccess  that concern  /.well-known .

        location = /.well-known/carddav   return 301 /remote.php/dav/;  
        location = /.well-known/caldav    return 301 /remote.php/dav/;  

        location /.well-known/acme-challenge      try_files $uri $uri/ =404;  
        location /.well-known/pki-validation      try_files $uri $uri/ =404;  

        # Let Nextcloud's API for  /.well-known  URIs handle all other
        # requests by passing them to the front-end controller.
        return 301 /index.php$request_uri;
     

    # Rules borrowed from  .htaccess  to hide certain paths from clients
    location ~ ^/(?:build tests config lib 3rdparty templates data)(?:$ /)    return 404;  
    location ~ ^/(?:\. autotest occ issue indie db_ console)                  return 404;  

    # Ensure this block, which passes PHP files to the PHP process, is above the blocks
    # which handle static assets (as seen below). If this block is not declared first,
    # then NGinx will encounter an infinite rewriting loop when it prepend  /index.php 
    # to the URI, resulting in a HTTP 500 error response.
    location ~ \.php(?:$ /)  
        # Required for legacy support
        rewrite ^/(?!index remote public cron core\/ajax\/update status ocs\/v[12] updater\/.+ ocs-provider\/.+ .+\/richdocumentscode(_arm64)?\/proxy) /index.php$request_uri;

        fastcgi_split_path_info ^(.+?\.php)(/.*)$;
        set $path_info $fastcgi_path_info;

        try_files $fastcgi_script_name =404;

        include fastcgi_params;
        fastcgi_param SCRIPT_FILENAME $document_root$fastcgi_script_name;
        fastcgi_param PATH_INFO $path_info;
        fastcgi_param HTTPS on;

        fastcgi_param modHeadersAvailable true;         # Avoid sending the security headers twice
        fastcgi_param front_controller_active true;     # Enable pretty urls
        fastcgi_pass php-handler;

        fastcgi_intercept_errors on;
        fastcgi_request_buffering off;

        fastcgi_max_temp_file_size 0;
     

    # Serve static files
    location ~ \.(?:css js mjs svg gif png jpg ico wasm tflite map ogg flac)$  
        try_files $uri /index.php$request_uri;
        # HTTP response headers borrowed from Nextcloud  .htaccess 
        add_header Cache-Control                     "public, max-age=15778463$asset_immutable";
        add_header Referrer-Policy                   "no-referrer"       always;
        add_header X-Content-Type-Options            "nosniff"           always;
        add_header X-Frame-Options                   "SAMEORIGIN"        always;
        add_header X-Permitted-Cross-Domain-Policies "none"              always;
        add_header X-Robots-Tag                      "noindex, nofollow" always;
        add_header X-XSS-Protection                  "1; mode=block"     always;
        access_log off;     # Optional: Don't log access to assets
     

    location ~ \.woff2?$  
        try_files $uri /index.php$request_uri;
        expires 7d;         # Cache-Control policy borrowed from  .htaccess 
        access_log off;     # Optional: Don't log access to assets
     

    # Rule borrowed from  .htaccess 
    location /remote  
        return 301 /remote.php$request_uri;
     

    location /  
        try_files $uri $uri/ /index.php$request_uri;
     
 
  • Symlink configuration site available to site enabled. $ ln -s /etc/nginx/sites-available/nextcloud.conf /etc/nginx/sites-enabled/
  • Restart NGinx and access the URI in the browser.
  • Go through the installation of Nextcloud.
  • The user data on the installation dialog should point e.g to administrator or similar, that user will become administrative access rights in Nextcloud!
  • To adjust the database connection detail you have to edit the file $install_folder/config/config.php. Means here in the example within this post you would need to modify /var/www/html/nextcloud/config/config.php to control or change the database connection.
---%<---
    'dbname' => 'nextcloud_db',
    'dbhost' => 'localhost', #(Or your remote PostgreSQL server address if you have.)
    'dbport' => '',
    'dbtableprefix' => 'oc_',
    'dbuser' => 'nextcloud_user',
    'dbpassword' => '1234', #(The password you set for database user.)
--->%---
After the installation and setup of the Nextcloud PHP application there are more steps to be done. Have a look into the WebUI what you will need to do as additional steps like create a cronjob or tuning of some more PHP configurations. If you ve done all things correct you should see a login page similar to this: Login Page of your Nextcloud instance

Optional other steps for more enhanced configuration modifications

Move the data folder to somewhere else The data folder is the root folder for all user content. By default it is located in $install_folder/data, so in our case here it is in /var/www/html/nextcloud/data.
  • Move the data directory outside the web server document root. $ sudo mv /var/www/html/nextcloud/data /var/nextcloud_data
  • Ensure access permissions, mostly not needed if you move the folder. $ sudo chown -R www-data:www-data /var/nextcloud_data $ sudo chown -R www-data:www-data /var/www/html/nextcloud/
  • Update the Nextcloud configuration:
    1. Open the config/config.php file of your Nextcloud installation. $ sudo vi /var/www/html/nextcloud/config/config.php
    2. Update the datadirectory parameter to point to the new location of your data directory.
  ---%<---
     'datadirectory' => '/var/nextcloud_data'
  --->%---
  • Restart NGinx service: $ sudo systemctl restart nginx

Make the installation available for multiple FQDNs on the same server
  • Adjust the Nextcloud configuration to listen and accept requests for different domain names. Configure and adjust the key trusted_domains accordingly. $ sudo vi /var/www/html/nextcloud/config/config.php
  ---%<---
    'trusted_domains' => 
    array (
      0 => 'domain.your-domain.com',
      1 => 'domain.other-domain.com',
    ),
  --->%---
  • Create and adjust the needed site configurations for the webserver.
  • Restart the NGinx unit.

An error message about .ocdata might occur
  • .ocdata is not found inside the data directory
    • Create file using touch and set necessary permissions. $ sudo touch /var/nextcloud_data/.ocdata $ sudo chown -R www-data:www-data /var/nextcloud_data/

The password for the administrator user is unknown
  1. Log in to your server:
    • SSH into the server where your PostgreSQL database is hosted.
  2. Switch to the PostgreSQL user:
    • $ sudo -i -u postgres
  3. Access the PostgreSQL command line
    • psql
  4. List the databases: (If you re unsure which database is being used by Nextcloud, you can list all the databases by the list command.)
    • \l
  5. Switch to the Nextcloud database:
    • Switch to the specific database that Nextcloud is using.
    • \c nextclouddb
  6. Reset the password for the Nextcloud database user:
    • ALTER USER nextcloud_user WITH PASSWORD 'new_password';
  7. Exit the PostgreSQL command line:
    • \q
  8. Verify Database Configuration:
    • Check the database connection details in the config.php file to ensure they are correct. sudo vi /var/www/html/nextcloud/config/config.php
    • Replace nextcloud_db, nextcloud_user, and your_password with your actual database name, user, and password.
---%<---
    'dbname' => 'nextcloud_db',
    'dbhost' => 'localhost', #(or your PostgreSQL server address)
    'dbport' => '',
    'dbtableprefix' => 'oc_',
    'dbuser' => 'nextcloud_user',
    'dbpassword' => '1234', #(The password you set for nextcloud_user.)
--->%---
  1. Restart NGinx and access the UI through the browser.

11 April 2025

Reproducible Builds: Reproducible Builds in March 2025

Welcome to the third report in 2025 from the Reproducible Builds project. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. As usual, however, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. Debian bookworm live images now fully reproducible from their binary packages
  2. How NixOS and reproducible builds could have detected the xz backdoor
  3. LWN: Fedora change aims for 99% package reproducibility
  4. Python adopts PEP standard for specifying package dependencies
  5. OSS Rebuild real-time validation and tooling improvements
  6. SimpleX Chat server components now reproducible
  7. Three new scholarly papers
  8. Distribution roundup
  9. An overview of Supply Chain Attacks on Linux distributions
  10. diffoscope & strip-nondeterminism
  11. Website updates
  12. Reproducibility testing framework
  13. Upstream patches

Debian bookworm live images now fully reproducible from their binary packages Roland Clobus announced on our mailing list this month that all the major desktop variants (ie. Gnome, KDE, etc.) can be reproducibly created for Debian bullseye, bookworm and trixie from their (pre-compiled) binary packages. Building reproducible Debian live images does not require building from reproducible source code, but this is still a remarkable achievement. Some large proportion of the binary packages that comprise these live images can (and were) built reproducibly, but live image generation works at a higher level. (By contrast, full or end-to-end reproducibility of a bootable OS image will, in time, require both the compile-the-packages the build-the-bootable-image stages to be reproducible.) Nevertheless, in response, Roland s announcement generated significant congratulations as well as some discussion regarding the finer points of the terms employed: a full outline of the replies can be found here. The news was also picked up by Linux Weekly News (LWN) as well as to Hacker News.

How NixOS and reproducible builds could have detected the xz backdoor Julien Malka aka luj published an in-depth blog post this month with the highly-stimulating title How NixOS and reproducible builds could have detected the xz backdoor for the benefit of all . Starting with an dive into the relevant technical details of the XZ Utils backdoor, Julien s article goes on to describe how we might avoid the xz catastrophe in the future by building software from trusted sources and building trust into untrusted release tarballs by way of comparing sources and leveraging bitwise reproducibility, i.e. applying the practices of Reproducible Builds. The article generated significant discussion on Hacker News as well as on Linux Weekly News (LWN).

LWN: Fedora change aims for 99% package reproducibility Linux Weekly News (LWN) contributor Joe Brockmeier has published a detailed round-up on how Fedora change aims for 99% package reproducibility. The article opens by mentioning that although Debian has been working toward reproducible builds for more than a decade , the Fedora project has now:
progressed far enough that the project is now considering a change proposal for the Fedora 43 development cycle, expected to be released in October, with a goal of making 99% of Fedora s package builds reproducible. So far, reaction to the proposal seems favorable and focused primarily on how to achieve the goal with minimal pain for packagers rather than whether to attempt it.
The Change Proposal itself is worth reading:
Over the last few releases, we [Fedora] changed our build infrastructure to make package builds reproducible. This is enough to reach 90%. The remaining issues need to be fixed in individual packages. After this Change, package builds are expected to be reproducible. Bugs will be filed against packages when an irreproducibility is detected. The goal is to have no fewer than 99% of package builds reproducible.
Further discussion can be found on the Fedora mailing list as well as on Fedora s Discourse instance.

Python adopts PEP standard for specifying package dependencies Python developer Brett Cannon reported on Fosstodon that PEP 751 was recently accepted. This design document has the purpose of describing a file format to record Python dependencies for installation reproducibility . As the abstract of the proposal writes:
This PEP proposes a new file format for specifying dependencies to enable reproducible installation in a Python environment. The format is designed to be human-readable and machine-generated. Installers consuming the file should be able to calculate what to install without the need for dependency resolution at install-time.
The PEP, which itself supersedes PEP 665, mentions that there are at least five well-known solutions to this problem in the community .

OSS Rebuild real-time validation and tooling improvements OSS Rebuild aims to automate rebuilding upstream language packages (e.g. from PyPI, crates.io, npm registries) and publish signed attestations and build definitions for public use. OSS Rebuild is now attempting rebuilds as packages are published, shortening the time to validating rebuilds and publishing attestations. Aman Sharma contributed classifiers and fixes for common sources of non-determinism in JAR packages. Improvements were also made to some of the core tools in the project:
  • timewarp for simulating the registry responses from sometime in the past.
  • proxy for transparent interception and logging of network activity.
  • and stabilize, yet another nondeterminism fixer.

SimpleX Chat server components now reproducible SimpleX Chat is a privacy-oriented decentralised messaging platform that eliminates user identifiers and metadata, offers end-to-end encryption and has a unique approach to decentralised identity. Starting from version 6.3, however, Simplex has implemented reproducible builds for its server components. This advancement allows anyone to verify that the binaries distributed by SimpleX match the source code, improving transparency and trustworthiness.

Three new scholarly papers Aman Sharma of the KTH Royal Institute of Technology of Stockholm, Sweden published a paper on Build and Runtime Integrity for Java (PDF). The paper s abstract notes that Software Supply Chain attacks are increasingly threatening the security of software systems and goes on to compare build- and run-time integrity:
Build-time integrity ensures that the software artifact creation process, from source code to compiled binaries, remains untampered. Runtime integrity, on the other hand, guarantees that the executing application loads and runs only trusted code, preventing dynamic injection of malicious components.
Aman s paper explores solutions to safeguard Java applications and proposes some novel techniques to detect malicious code injection. A full PDF of the paper is available.
In addition, Hamed Okhravi and Nathan Burow of Massachusetts Institute of Technology (MIT) Lincoln Laboratory along with Fred B. Schneider of Cornell University published a paper in the most recent edition of IEEE Security & Privacy on Software Bill of Materials as a Proactive Defense:
The recently mandated software bill of materials (SBOM) is intended to help mitigate software supply-chain risk. We discuss extensions that would enable an SBOM to serve as a basis for making trust assessments thus also serving as a proactive defense.
A full PDF of the paper is available.
Lastly, congratulations to Giacomo Benedetti of the University of Genoa for publishing their PhD thesis. Titled Improving Transparency, Trust, and Automation in the Software Supply Chain, Giacomo s thesis:
addresses three critical aspects of the software supply chain to enhance security: transparency, trust, and automation. First, it investigates transparency as a mechanism to empower developers with accurate and complete insights into the software components integrated into their applications. To this end, the thesis introduces SUNSET and PIP-SBOM, leveraging modeling and SBOMs (Software Bill of Materials) as foundational tools for transparency and security. Second, it examines software trust, focusing on the effectiveness of reproducible builds in major ecosystems and proposing solutions to bolster their adoption. Finally, it emphasizes the role of automation in modern software management, particularly in ensuring user safety and application reliability. This includes developing a tool for automated security testing of GitHub Actions and analyzing the permission models of prominent platforms like GitHub, GitLab, and BitBucket.

Distribution roundup In Debian this month:
The IzzyOnDroid Android APK repository reached another milestone in March, crossing the 40% coverage mark specifically, more than 42% of the apps in the repository is now reproducible Thanks to funding by NLnet/Mobifree, the project was also to put more time into their tooling. For instance, developers can now run easily their own verification builder in less than 5 minutes . This currently supports Debian-based systems, but support for RPM-based systems is incoming. Future work in the pipeline, including documentation, guidelines and helpers for debugging.
Fedora developer Zbigniew J drzejewski-Szmek announced a work-in-progress script called fedora-repro-build which attempts to reproduce an existing package within a Koji build environment. Although the project s README file lists a number of fields will always or almost always vary (and there are a non-zero list of other known issues), this is an excellent first step towards full Fedora reproducibility (see above for more information).
Lastly, in openSUSE news, Bernhard M. Wiedemann posted another monthly update for his work there.

An overview of Supply Chain Attacks on Linux distributions Fenrisk, a cybersecurity risk-management company, has published a lengthy overview of Supply Chain Attacks on Linux distributions. Authored by Maxime Rinaudo, the article asks:
[What] would it take to compromise an entire Linux distribution directly through their public infrastructure? Is it possible to perform such a compromise as simple security researchers with no available resources but time?

diffoscope & strip-nondeterminism diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 290, 291, 292 and 293 and 293 to Debian:
  • Bug fixes:
    • file(1) version 5.46 now returns XHTML document for .xhtml files such as those found nested within our .epub tests. [ ]
    • Also consider .aar files as APK files, at least for the sake of diffoscope. [ ]
    • Require the new, upcoming, version of file(1) and update our quine-related testcase. [ ]
  • Codebase improvements:
    • Ensure all calls to our_check_output in the ELF comparator have the potential CalledProcessError exception caught. [ ][ ]
    • Correct an import masking issue. [ ]
    • Add a missing subprocess import. [ ]
    • Reformat openssl.py. [ ]
    • Update copyright years. [ ][ ][ ]
In addition, Ivan Trubach contributed a change to ignore the st_size metadata entry for directories as it is essentially arbitrary and introduces unnecessary or even spurious changes. [ ]

Website updates Once again, there were a number of improvements made to our website this month, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In March, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Add links to two related bugs about buildinfos.debian.net. [ ]
    • Add an extra sync to the database backup. [ ]
    • Overhaul description of what the service is about. [ ][ ][ ][ ][ ][ ]
    • Improve the documentation to indicate that need to fix syncronisation pipes. [ ][ ]
    • Improve the statistics page by breaking down output by architecture. [ ]
    • Add a copyright statement. [ ]
    • Add a space after the package name so one can search for specific packages more easily. [ ]
    • Add a script to work around/implement a missing feature of debrebuild. [ ]
  • Misc:
    • Run debian-repro-status at the end of the chroot-install tests. [ ][ ]
    • Document that we have unused diskspace at Ionos. [ ]
In addition:
  • James Addison made a number of changes to the reproduce.debian.net homepage. [ ][ ].
  • Jochen Sprickerhof updated the statistics generation to catch No space left on device issues. [ ]
  • Mattia Rizzolo added a better command to stop the builders [ ] and fixed the reStructuredText syntax in the README.infrastructure file. [ ]
And finally, node maintenance was performed by Holger Levsen [ ][ ][ ] and Mattia Rizzolo [ ][ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

2 April 2025

Dirk Eddelbuettel: nanotime 0.3.12 on CRAN: Maintenance

Another minor update 0.3.12 for our nanotime package is now on CRAN. nanotime relies on the RcppCCTZ package (as well as the RcppDate package for additional C++ operations) and offers efficient high(er) resolution time parsing and formatting up to nanosecond resolution, using the bit64 package for the actual integer64 arithmetic. Initially implemented using the S3 system, it has benefitted greatly from a rigorous refactoring by Leonardo who not only rejigged nanotime internals in S4 but also added new S4 types for periods, intervals and durations. This release responds to recent CRAN nag of also suggesting packages used in demos, makes a small update to the CI script, and improves one version comparison for conditional code. The NEWS snippet below has the fuller details.

Changes in version 0.3.12 (2025-04-02)
  • Update continuous integration to use r-ci action with bootstrap
  • Add ggplot2 to Suggests due to use in demo/ which is now scanned
  • Refine a version comparison for R 4.5.0 to be greater or equal

Thanks to my CRANberries, there is a diffstat report for this release. More details and examples are at the nanotime page; code, issue tickets etc at the GitHub repository and all documentation is provided at the nanotime documentation site.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

1 April 2025

Michael Ablassmeier: qmpbackup 0.46 - add image fleecing

I ve released qmpbackup 0.46 which now utilizes the image fleecing technique for backup. Usually, during backup, Qemu will use a so called copy-before-write filter so that data for new guest writes is sent to the backup target first, the guest write blocks until this operation is finished. If the backup target is flaky, or becomes unavailable during backup operation, this could lead to high I/O wait times or even complete VM lockups. To fix this, a so called fleecing image is introduced during backup being used as temporary cache for write operations by the guest. This image can be placed on the same storage as the virtual machine disks, so is independent from the backup target performance. The documentation on which steps are required to get this going, using the Qemu QMP protocol is, lets say.. lacking.. The following examples show the general functionality, but should be enhanced to use transactions where possible. All commands are in qmp-shell command format. Lets start with a full backup:
# create a new bitmap
block-dirty-bitmap-add node=disk1 name=bitmap persistent=true
# add the fleece image to the virtual machine (same size as original disk required)
blockdev-add driver=qcow2 node-name=fleecie file= "driver":"file","filename":"/tmp/fleece.qcow2" 
# add the backup target file to the virtual machine
blockdev-add driver=qcow2 node-name=backup-target-file file= "driver":"file","filename":"/tmp/backup.qcow2" 
# enable the copy-before-writer for the first disk attached, utilizing the fleece image
blockdev-add driver=copy-before-write node-name=cbw file=disk1 target=fleecie
# "blockdev-replace": make the copy-before-writer filter the major device (use "query-block" to get path parameter value, qdev node)
qom-set path=/machine/unattached/device[20] property=drive value=cbw
# add the snapshot-access filter backing the copy-before-writer
blockdev-add driver=snapshot-access file=cbw node-name=snapshot-backup-source
# create a full backup
blockdev-backup device=snapshot-backup-source target=backup-target-file sync=full job-id=test
[ wait until block job finishes]
# remove the snapshot access filter from the virtual machine
blockdev-del node-name=snapshot-backup-source
# switch back to the regular disk
qom-set path=/machine/unattached/device[20] property=drive value=node-disk1
# remove the copy-before-writer
blockdev-del node-name=cbw
# remove the backup-target-file
blockdev-del node-name=backup-target-file
# detach the fleecing image
blockdev-del node-name=fleecie
After this process, the temporary fleecing image can be deleted/recreated. Now lets go for a incremental backup:
# add the fleecing and backup target image, like before
blockdev-add driver=qcow2 node-name=fleecie file= "driver":"file","filename":"/tmp/fleece.qcow2" 
blockdev-add driver=qcow2 node-name=backup-target-file file= "driver":"file","filename":"/tmp/backup-incremental.qcow2" 
# add the copy-before-write filter, but utilize the bitmap created during full backup
blockdev-add driver=copy-before-write node-name=cbw file=disk1 target=fleecie bitmap= "node":"disk1","name":"bitmap" 
# switch device to the copy-before-write filter
qom-set path=/machine/unattached/device[20] property=drive value=cbw
# add the snapshot-access filter
blockdev-add driver=snapshot-access file=cbw node-name=snapshot-backup-source
# merge the bitmap created during full backup to the snapshot-access device so
# the backup operation can access it. (you better use an transaction here)
block-dirty-bitmap-add node=snapshot-backup-source name=bitmap
block-dirty-bitmap-merge node=snapshot-backup-source target=bitmap bitmaps=[ "node":"disk1","name":"bitmap" ]
# create incremental backup (you better use an transaction here)
blockdev-backup device=snapshot-backup-source target=backup-target-file job-id=test sync=incremental bitmap=bitmap
 [ wait until backup has finished ]
 [ cleanup like before ]
# clear the dirty bitmap (you better use an transaction here)
block-dirty-bitmap-clear node=disk1 name=bitmap
Or, use a simple reproducer by directly passing qmp commands via stdio:
#!/usr/bin/bash
qemu-img create -f raw disk 1M
qemu-img create -f raw fleece 1M
qemu-img create -f raw backup 1M
qemu-system-x86_64 -drive node-name=disk,file=disk,format=file -qmp stdio -nographic -nodefaults <<EOF
 "execute": "qmp_capabilities" 
 "execute": "block-dirty-bitmap-add", "arguments":  "node": "disk", "name": "bitmap" 
 "execute": "blockdev-add", "arguments":  "node-name": "fleece", "driver": "file", "filename": "fleece" 
 "execute": "blockdev-add", "arguments":  "node-name": "backup", "driver": "file", "filename": "backup" 
 "execute": "blockdev-add", "arguments":  "node-name": "cbw", "driver": "copy-before-write", "file": "disk", "target": "fleece", "bitmap":  "node": "disk", "name": "bitmap" 
 "execute": "query-block" 
 "execute": "qom-set", "arguments":  "path": "/machine/unattached/device[4]", "property": "drive", "value": "cbw" 
 "execute": "blockdev-add", "arguments":  "node-name": "snapshot", "driver": "snapshot-access", "file": "cbw" 
 "execute": "block-dirty-bitmap-add", "arguments":  "node": "snapshot", "name": "tbitmap" 
 "execute": "block-dirty-bitmap-merge", "arguments":  "node": "snapshot", "target": "tbitmap", "bitmaps": [ "node": "disk", "name": "bitmap" ] 
[..]
 "execute": "quit" 
EOF

Next.

Previous.