Search Results: "andy"

11 October 2013

Michal Čihař: Hackweek is over

10th hackweek is over and I think it has been again great chance to hack on something. This year we even had better food supplies so interruptions from hacking were even less frequent. As you've might have already noticed, I was working on Weblate whole week and I think it worked pretty well and I've implemented all what I wanted. First of all, Weblate now supports login using lot of third party services (like GitHub, Facebook, Google, ...). This was achieved by using python-social-auth for that. It is quite new module for this, so hopefully it's API will stay stable enough to be usable in the long term. It was surprisingly easy to implement, though I've spent quite a lot of tweaking of the login and registration process to make it work according to my expectations. After doing this quite big change, I thought it's about time to restructure the documentation and document new features in it. I think it now covers all important things, but if you can't find something or some parts are hard to understand, just let me know, I'll fix it. Another quite big feature (though it won't be much visible in upcoming 1.8 release) is source string tracking. This is prerequisite for many features people have requested in Weblate's issue tracker, but these will have to wait for next releases. If you want to see some feature earlier, you can support it by money on Bountysource :-). Weblate can now also search in all strings, which might become handy if grepping over dozen of Git repositories is not your favorite game. And last but not least, I've implemented simple Captcha protection for new registrations as the demo server is full of bots who register there and do nothing afterward. Basically I think this makes Weblate 1.8 feature complete and I'd like to stabilize it in upcoming weeks to release. Right now it is deployed on the demo server, where you can play with it and discover bugs :-). Also it's now time to work on Weblate translations!

Filed under: English SUSE Weblate 0 comments Flattr this!

2 October 2013

Raphael Geissert: A bashism a week: dangerous exports

As a user of a shell you have most likely had the need to export a variable to another process; i.e. set/modify an environment variable.

Now, how do you stop exporting an environment variable? can you export anything else?

The bash shell offers the -n option of the export built-in, claiming it "remove[s] the export property". However, this feature is not part of the POSIX:2001 standard and is, therefore, a bashism.

A portable way to stop exporting an environment variable is to unset it. E.g. the effect of "export MY_VAR=foo" can be reverted by calling "unset MY_VAR" - surely enough, this will also destroy the content of the variable.

An equivalent could then be:

# to stop exporting/"unexport" the MY_VAR environment variable:
my_var="$MY_VAR" ; unset MY_VAR ;
MY_VAR="$my_var" ; unset my_var ;


The above code will make a copy of the variable before destroying it and then restoring its content.

How about exporting other things? did you know that you can export shell functions?

With the bash shell, you can export a function with the -f parameter of the export built-in. Needless to say, this is a bashism. Its secret? it's just an environment variable with the name of the function and the rest of the function definition as its value.

Try this:

$ echo="() /bin/echo 'have some bash' ; " bash -c 'echo "Hello World!"'
have some bash


Yes, this means that if you can control the content of an environment variable passed to bash you can probably execute whatever code you want. It comes handy when you want to alter a script's behaviour without modifying the script itself.

Possibilities are endless thanks to bash's support for non-standard characters in function names. Functions with slashes can also be exported, for example:

/sbin/ifconfig()
echo "some people say you should be using ip(1) instead" ;


Are you into bug hunting? export exec='() echo mount this ; '

23 September 2013

Russell Coker: Hive Bluetooth Stereo Speakers

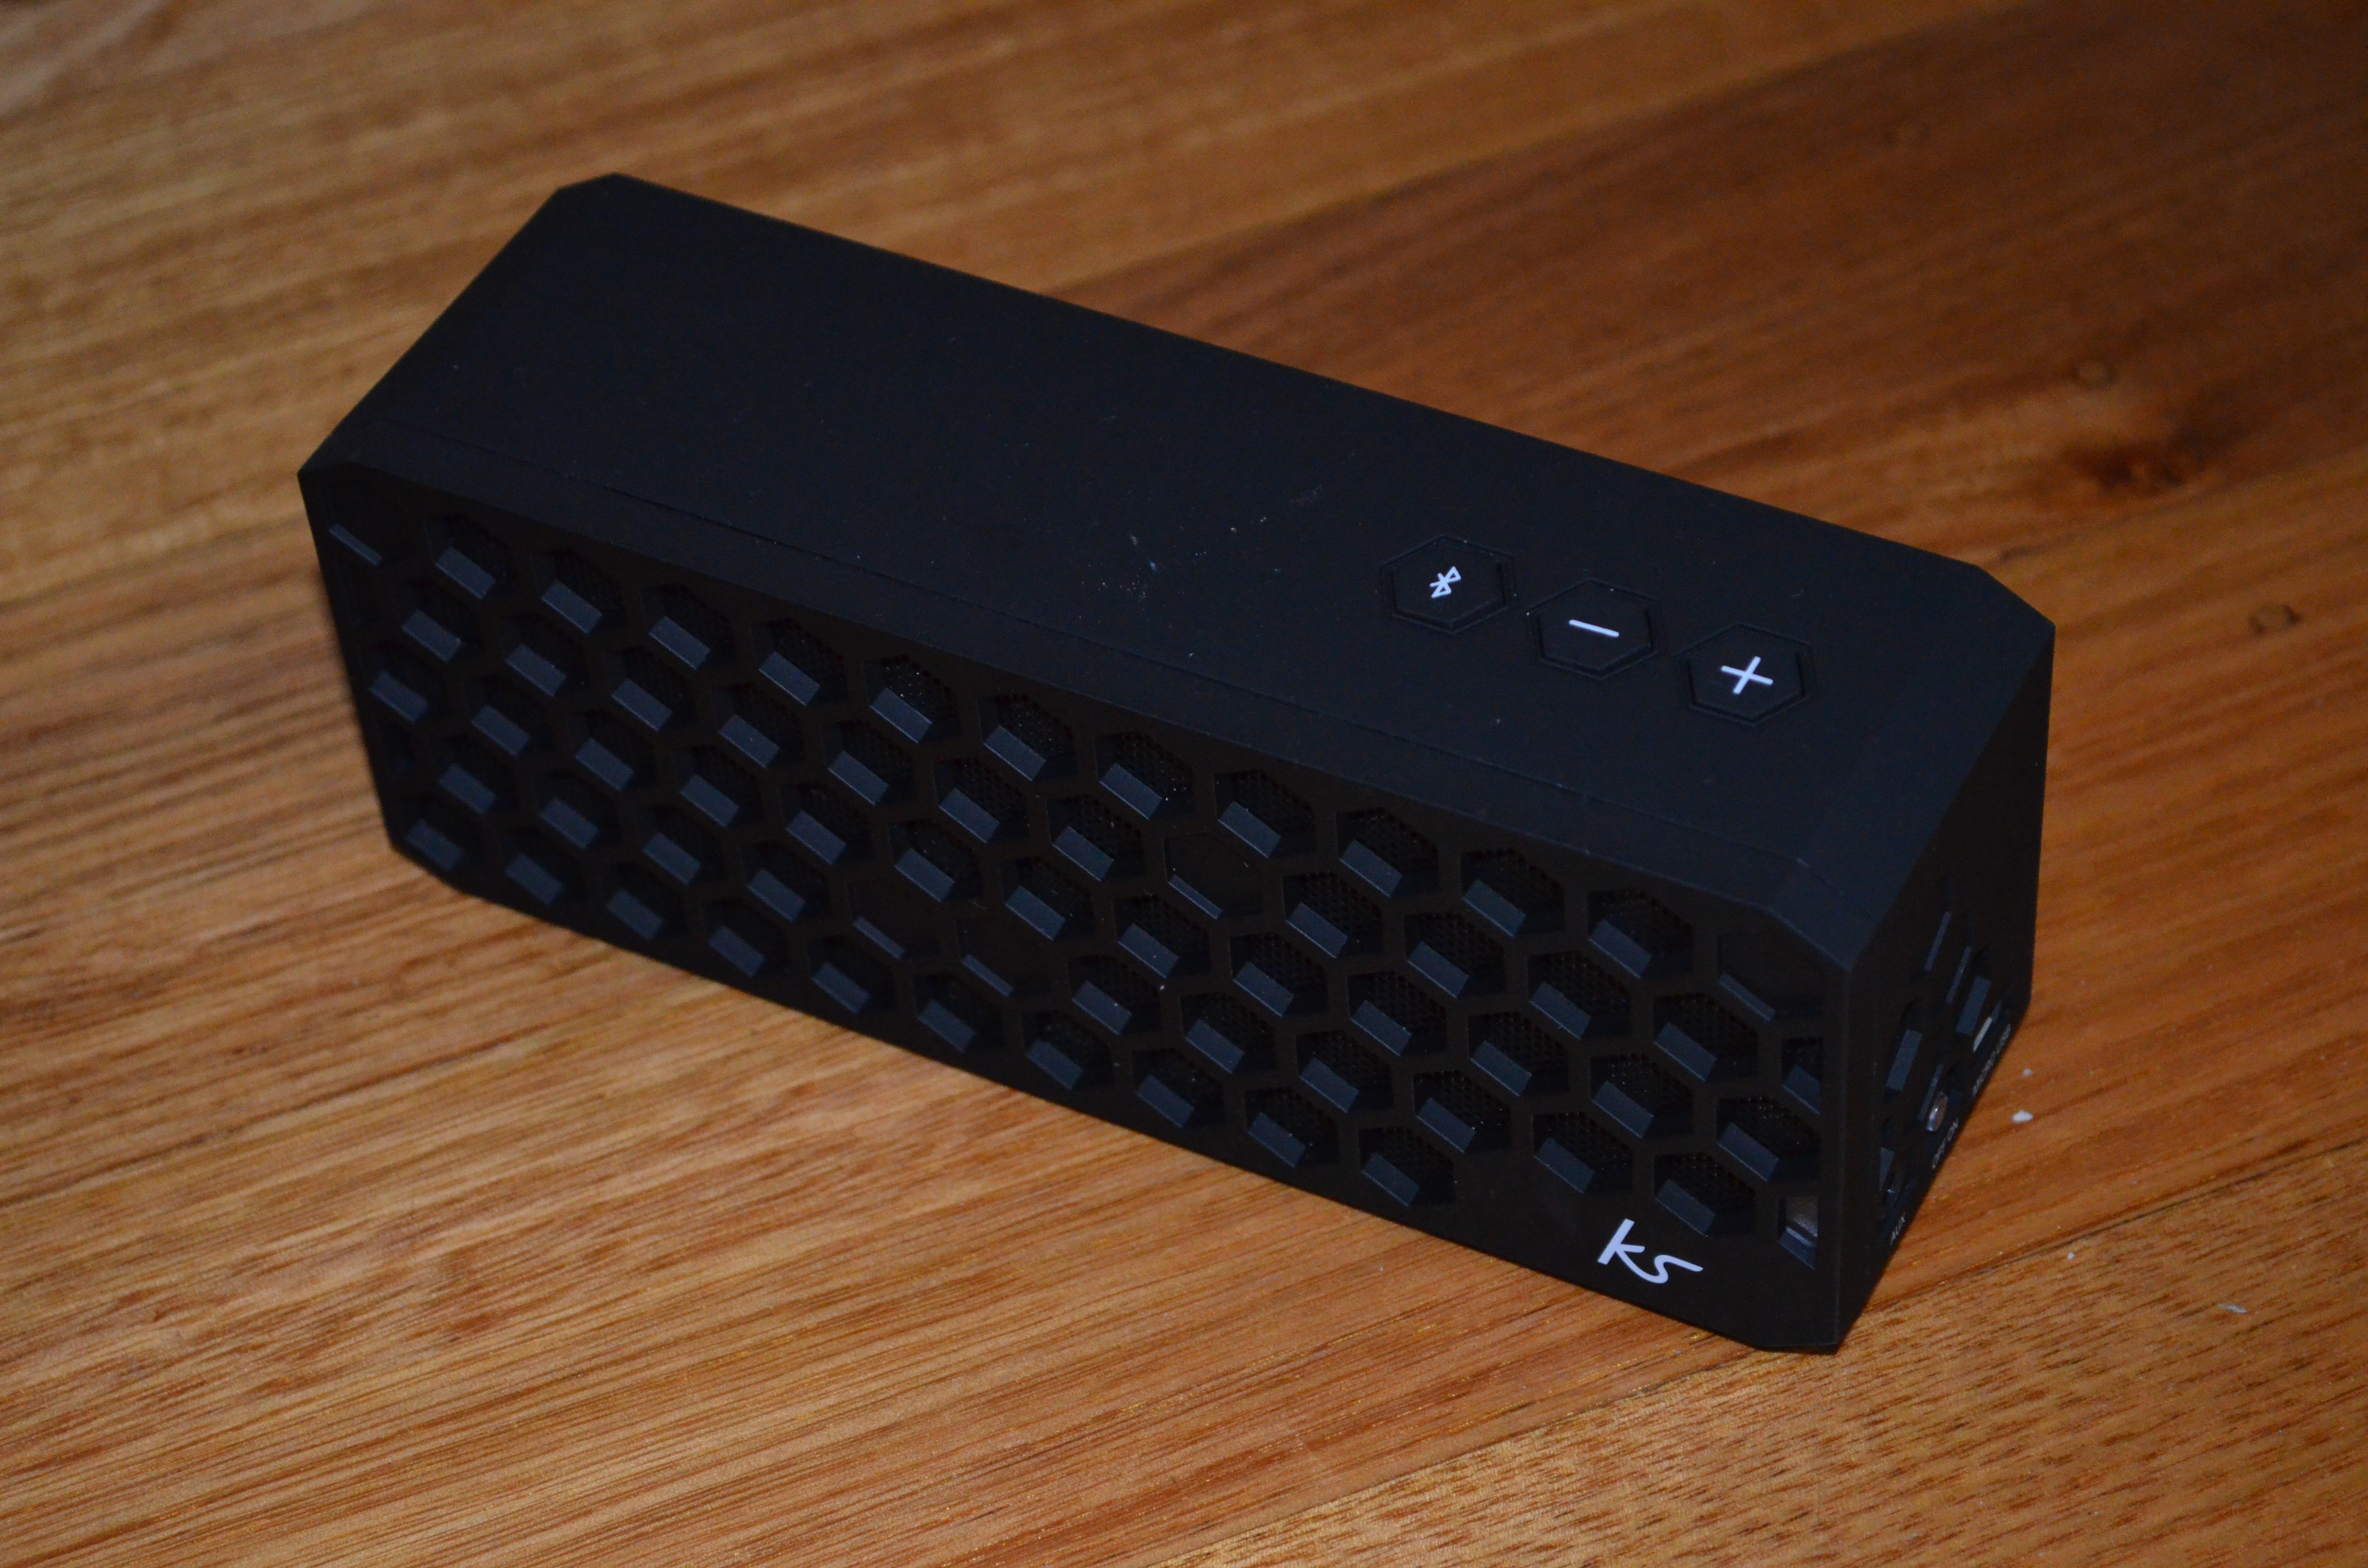
picture of Hive bluetooth speakers I ve just been given a set of Hive Bluetooth speakers by MobileZap (see this link for all their Bluetooth speakers) [1]. The speakers charge by a micro-USB cable so I started charging them in my car immediately after collecting them. To connect them to a phone or other Bluetooth device you just press the Bluetooth button on top and get the phone to be visible and scanning for devices, they identify themselves as Hive , after that they just work. My first test of using them was playing Ingress and the quality of the sound was impressive, I had thought that the Ingress recommendation to use headphones was due to the risk of annoying other people or alerting other players, but the quality of the sound was impressive and the internal speakers of a phone can t do it justice. After getting home I did some tests listening to music. For watching music videos it didn t work so well as the sound was too far removed from the video, but the audio quality was very good. I listened to Vow by Garbage (a good benchmark for stereo sound) and even though the Hive speakers are only 16.5cm wide I could still notice the stereo effect when they were about 1.5m away from me. The audio quality didn t compare well with my Bose QC-15 headphones, but for affordable and portable speakers it was quite good and an obvious improvement over the speakers that are built in to any phone I ve used. According to the Bluetooth Wikipedia page the range of a class 2 device is 10m and the range of a class 3 device is 1m. When my Samsung Galaxy Note 2 is talking to it I get a reliable range of about 5 meters and a mostly working range of 6 or 7 meters (sound randomly drops out and gets choppy). It could be that other phones would support a longer range due to having a higher transmission power (either class 1 or being closer to the limits of class 2) and a more sensitive receiver. But it doesn t seem likely that a 5m range is going to be a problem. Volume and Quality The speakers are rated at 5 Watt, when running at maximum volume (both through the phone volume setting and the volume control on the speakers) the sound is reasonably distortion free, as good as can be expected from playing an MP3 that s not compressed with the highest quality. Sound Meter [2] reports the sound volume as almost 85dB on a Galaxy S3 and as almost 100dB on a Galaxy Note 2, that would be somewhere between the volume of a busy street or alarm clock and the volume of a subway train or blow dryer which seems like a reasonable description, I find it very unpleasant to be within a meter of the speakers at maximum volume. With the typical amount of background noise in my house I can play music on the Hive speakers at one end of my house and hear it clearly at the other end. These speakers are more than capable of supplying the music for any party I d want to host or attend. I m not really into wild parties, but I think that anyone who has a one room party would be more than satisfied with the Hive speakers. Obviously the sound quality of portable speakers in a box that s 16.5cm wide and 6cm high isn t going to equal that of a full size set of speakers, but I think that hardly anyone who attends a party would expect better sound quality than the Hive speakers can provide. The aim of such speakers is to be portable, not really expensive, and to provide good sound quality within those constraints. I think that they meet such aims well. Over the years there have been many occasions when I have used a Thinkpad to provide the music for a party and found it to be quite loud enough. My current Thinkpad is a T420 which can produce 75dB according to my Galaxy S3 or 85dB according to my Galaxy Note 2. So it seems that I only really need about 10dB less than the maximum volume of the Hive speakers. Appearance The designers obviously made an effort on the appearance of the device. They have gone with the Hive concept and used hexagons everywhere. It really looks nice. Unfortunately when I took the photo there was some dust on it which didn t look bad to the eye but caught the camera flash. But with a matte black device there s always the problem of light colored dust. Even with a bit of dust it still looks great as a set of speakers, the dust just detracts from the appearance in photos. Line In One of the features I looked for was an audio line input so I could connect it directly to a non-Bluetooth device. I m assuming that this feature works as it s something that s difficult to stuff up when designing such a product, but I haven t got around to testing it. Once I started using the device I just found that I didn t have a real need for that feature. One thing that it might be useful for is PC desktop speakers that are powered by a USB port on the monitor. Currently I have a bearable (but not great) set of speakers for each PC and I don t need to change anything. But having the option of another set of speakers is very handy in case I suddenly need to make hardware changes. Other People s Reviews When I review a product I generally try and get opinions from random other people if possible. My mother and my mother-in-law were both impressed by the Hive speakers and expressed interest in owning a set. My mother-in-law was particularly interested as she uses her phone to listen to radio stations from outside Australia (I m going to get her onto Aldi for cheap 3G data ASAP so she can listen to Internet radio when travelling). Generally the impression that other people have of this device seems to be very positive. It seems that Bluetooth speakers aren t just a Geek toy. Conclusion While I m very impressed by this product, at this stage I m not sure whether I would pay for this one or something cheaper if I was paying for it. MobileZap offers a range of other products that look appealing at lower price points. It really depends on how much I use it. I ve just got a Makerbot Replicator 3D printer working and I ve found the Hive speakers very useful for the purpose of drowning out it s noise. If I keep doing that sort of thing then I ll get enough use out of the speakers to justify the price.

7 September 2013

Daniel Pocock: Evacuating Australia

With the news that Australia's 100mbit (and potentially gigabit) fibre to the home is to be abolished and replaced with a cheap 25mbps service using Europe's ADSL hand-me-downs (which will be obsolete in 5 years when the deployment is finished), I've had quite a few emails from people asking just how easy it is to move abroad.
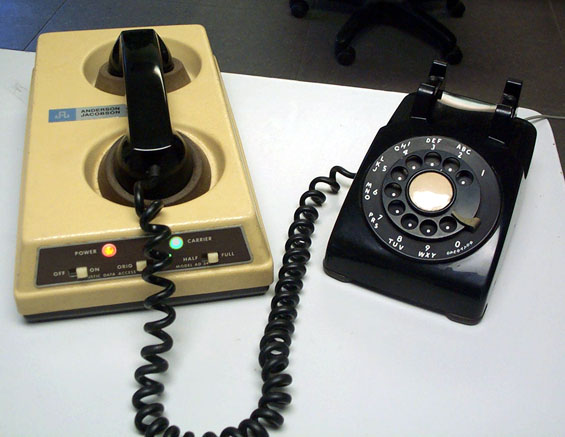
The acoustic modem has a nice retro look Word has got out that I've been spending some time in Switzerland enjoying the world-beating rate of IPv6 deployment. That is not the only reason to leave Australia of course, nor is it the only criteria for people choosing which country will give them a better deal than either of the two non-choices we had in Australia's elections. A free $20,000 for leaving Australia The first good news is that any recent graduate with a big bad ugly HECS bill is only obliged to pay this extra tax when they earn a salary from an Australian employer and file an Australian tax return. Australians who live abroad are not automatically obliged to file tax returns and are not slogged with this extra tax for having attended university. If somebody just graduated and has this hanging over their head, or if they've just started working and seen how much is being deducted on the payslip, moving abroad could make a lot of sense financially. If you have any moral qualms about this, just reflect on the fact that while the Government intimidates students with the feeling that they have to "pay" for fulfilling an education that makes them into a productive member of society, thousands of would-be athletes are given money with no obligation to repay it. The easiest route: a second passport One in four Australians has a parent born abroad. Most of those people qualify for a passport from their parent's country of birth. In some cases this also applies to people with grandparents born abroad. With the European Union now spanning 28 countries and guaranteeing the rights of any citizen from any country to live, work and study in any of the other 27 countries, a passport from any of the EU countries gives a lot of choices, including places where I have lived myself such as the UK, Ireland, France and Switzerland. Europe's citizen-friendly immigration In other words, an Australian with an Italian parent can go up to the Italian embassy in Canberra, collect an Italian passport and immediately fly into London and start working there with no bureaucratic delays, invasive and degrading medical checks or other Government interference in their life.
London's nightlife is popular for Australians. The UK started rolling out their high speed 21CN many years before Australia started the NBN. The rights also transfer automatically to all family members (spouse and children) - an Australian with a second passport is not restricted to living in Australia simply because they are married to somebody who does not have a second passport. As long as they arrive together at a European airport, they can simply show a marriage/birth certificate (in any language) and cross the border immediately, enjoy the same rights as a citizen, including work, study, healthcare and better broadband. No paperwork is necessary, no cottage industry for otherwise unemployable immigration agents, these are basic human rights for those living in Europe.
Eiffel tower: potentially part of the wireless network for France's new 4G internet, potentially two to four times the fixed-line speed planned for Australia's crippled broadband Uncle Sam wants more Australians Although it is not widely known, the US has a fast lane for immigration from Australia. The regular programs for skilled visas in the US are usually exhausted every year, whereas 10,000 "E3" class visas for Australians are never fully taken in any year. Surely it's not that easy to go to the US? It is. To qualify, an Australian only needs a university degree and a suitable job offer. Although the visa is for 2 years, it can be renewed and Australians who meet and marry an American have in various cases have gained full residence or citizenship. Anything is possible, you could even end up becoming a NASA Astronaut.
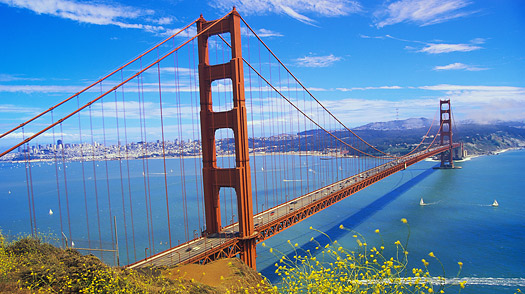
San Francisco, home to leading technology professionals and innovators from many countries. Some US cities such as Austin and Kansas City have let Google install fibre to the home, San Francisco could follow Working holiday schemes are not just for Britain Most Australians know somebody who went to London on a "working holiday" visa. These visas are not just for the UK and Australia has similar reciprocal programs with many other countries too. These rules for these schemes are rooted in the industrial age concept of workers with punch cards. Participants are typically limited to work 20 hours per week. Of particular interest for those in IT, such rules are hard to quantify for freelancers, web designers or creative people who earn their living charging fees per-project or undertaking management work without specified working hours. Although the visas are limited to 4 years, I've heard of Australians benefiting from the open borders of mainland Europe, spending 4 years in one country and then obtaining another 4 year visa for an adjacent country and travelling freely back and forth, building up a business and lifestyle of their own design. Singapore and Hong Kong Singapore and Hong Kong have become enormously popular destinations for Australians, particularly those with special skills in IT, finance, engineering and international business.
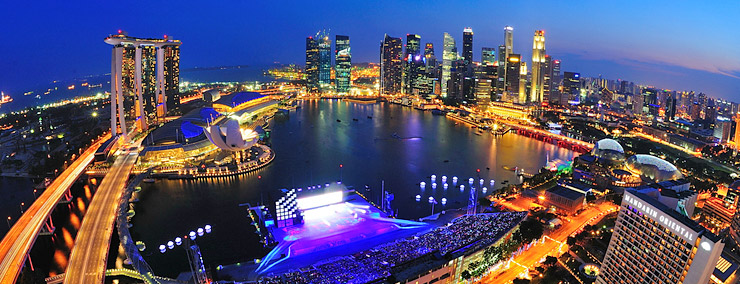
Singapore is respected as one of the cleanest and most orderly cities in Asia while embracing significant diversity in dining, shopping, leisure and lifestyle possibilities. They have recently boosted speeds to help people get a full 100MBit over fibre. A SIM card with high speed broadband charges SGD 7 (about $5) for 1 Gigabyte. These are not necessarily destinations that a graduate can easily move to. People are measured by their salary and the Government simply assumes that anybody earning a high salary is going to make a valuable contribution to society and they are given a visa in 1 or 2 weeks. Usually 3-5 years employment experience is required before making a move to one of these countries. The Not Ordinarily Resident (NOR) scheme gives some hints about the minimum salary level that ex-pats aim for, many earn significantly more with bonuses, stock programs and properly engineered tax-free offshore pension arrangements. These countries offer particularly low taxes (around 10%) and great technology. They have some rough edges too: like Europe, spouses are automatically given a visa too, but in contrast, their visa does not permit them to work unless they also work in a profession that is highly paid. Visas are issued quickly but they are also canceled very quickly if the job is terminated or the company goes bust. There have been various stories of people paying the typical 2-month deposit on an appartment in Singapore and then finding that it is forfeited when their job and visa are canceled and they have 4 weeks to leave. The bottom line is that people moving to these locations usually have a wide professional network and confidence to change their job quickly if necessary. Freestyle immigration and the visa run Not too long ago I was at a house party in Prague, Czech Republic, which is like a Paris of eastern Europe. Somebody introduced me to some Americans who I was told had similar interests in technology. They were operating an offshore web site and living very well. They had spent 10 years in Prague living on tourist visas. Authorities seemed quite happy for them to remain as long as they left every 3 months and spent 1 night abroad, a typical visa run. That could be as simple as a train journey to Vienna, Austria and an overnight stay.
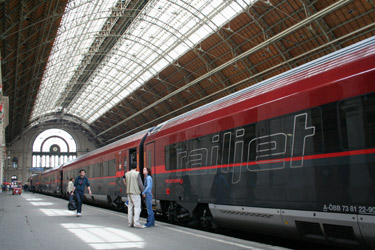
Making a visa run in comfort and style with European railways. The Railjet train pictured includes free wifi, a lot cheaper than the $20 billion Tony Abbott plans to spend rolling out yesterday's technology in Australia When European countries abolished border controls, this system became much more convoluted for those who depend on the visa run. However, it remains common in many Asian and Latin American countries and many ex-pats live this way. Officials in many of these medium sized economies recognise the value of people bringing in money from offshore business (such as web sites) and using it to pay rent, food and local services. To make this effective, the ex-pats typically need to have an international private health insurance policy (high quality offshore policies can be found quickly with a search engine) and not aspire to work in a normal 9-5 job. Conclusion Young Australians might not want to just consider travel, it may even become unavoidable. The reality is, by 2020, one in three Australians will be a retired baby boomer and one way or another, whichever Government is in office will be unable to avoid taxing those of working age to pay for the health care and pension promises made to older generations. Serious expenditure on public infrastructure such as broadband or high speed rail appears to remain a pipe dream. Moving abroad, however, is just so much fun. Look at the way multinational companies make countries compete to attract their new factories and other projects: why should any individual citizen be any less demanding in choosing where they work, play and get the best value for whatever taxes they have to pay? Some people raise questions of patriotism or responsibility to the nation. Think again. The 200,000 Australians who live abroad or travel extensively make a significant contribution to Australia's international profile, engage in new trade initiatives, bring skills back to Australia and generally represent what our country is really about much better than some of those who are paid to do so.

6 September 2013

Vincent Bernat: High availability with ExaBGP

When it comes to provide redundant services, several options are available: A common setup is a combination of those solutions: web servers are behind a couple of load-balancers achieving both redundancy and load-balancing. The load-balancers use VRRP to ensure redundancy. The whole setup is replicated to another datacenter and round-robin DNS is used to ensure both redundancy and load-balacing of the datacenters. There is a fourth option which is similar to VRRP but relies on dynamic routing and therefore is not limited to nodes in the same subnet: We will explore how to implement this fourth option using ExaBGP, the BGP swiss army knife of networking, in a small lab based on KVM. You can grab the complete lab from GitHub. ExaBGP 3.2.5 is needed to run this lab.

Environment We will be working in the following (IPv6-only) environment: Lab with three web nodes

BGP configuration BGP is enabled on ER2 and ER3 to exchange routes with peers and transits (only R1 for this lab). BIRD is used as a BGP daemon. Its configuration is pretty basic. Here is a fragment:
router id 1.1.1.2;
protocol static NETS   #  
  import all;
  export none;
  route 2001:db8::/40 reject;
 
protocol bgp R1   #  
  import all;
  export where proto = "NETS";
  local as 64496;
  neighbor 2001:db8:1000::1 as 64511;
 
protocol bgp ER3   #  
  import all;
  export all;
  next hop self;
  local as 64496;
  neighbor 2001:db8:1::3 as 64496;
 
First, in , we declare the routes that we want to export to our peers. We don t try to summarize them from the IGP. We just unconditonnaly export the networks that we own. Then, in , R1 is defined as a neighbor and we export the static route we declared previously. We import any route that R1 is willing to send us. In , we share everything we know with our pal, ER3, using internal BGP.

OSPF configuration OSPF will distribute routes inside the AS. It is enabled on ER2, ER3, DR6, DR7 and DR8. For example, here is the relevant part of the configuration of DR6:
router id 1.1.1.6;
protocol kernel  
   persist;
   import none;
   export all;
 
protocol ospf INTERNAL  
  import all;
  export none;
  area 0.0.0.0  
    networks  
      2001:db8:1::/64;
      2001:db8:6::/64;
     ;
    interface "eth0";
    interface "eth1"   stub yes;  ;
   ;
 
ER2 and ER3 inject a default route into OSPF:
protocol static DEFAULT  
  import all;
  export none;
  route ::/0 via 2001:db8:1000::1;
 
filter default_route  
  if proto = "DEFAULT" then accept;
  reject;
 
protocol ospf INTERNAL  
  import all;
  export filter default_route;
  area 0.0.0.0  
    networks  
      2001:db8:1::/64;
     ;
    interface "eth1";
   ;
 

Web nodes The web nodes are pretty basic. They have a default static route to the nearest router and that s all. The interesting thing here is that they are each on a separate IP subnet: we cannot share an IP using VRRP2. Why are those web servers on different subnets? Maybe they are not in the same datacenter or maybe your network architecture is using a routed access layer. Let s see how to use BGP to enable redundancy of those web nodes.

Redundancy with ExaBGP ExaBGP is a convenient tool to plug scripts into BGP. They can then receive and advertise routes. ExaBGP does the hard work of speaking BGP with your routers. The scripts just have to read routes from standard input or advertise them on standard output.

The big picture Here is the big picture: Using ExaBGP to advertise web services Let s explain it step by step:
  1. Three IP addresses will be allocated for our web service: 2001:db8:30::1, 2001:db8:30::2 and 2001:db8:30::3. Those are distinct from the real IP addresses of W1, W2 and W3.
  2. Each web node will advertise all of them to the route servers we added in the network. I will talk more about those route servers later.
  3. Each route comes with a metric to help the route server choose where it should be routed. We choose the metrics such that each IP address will be routed to a distinct web node (unless there is a problem).
  4. The route servers (which are not routers) will then advertise the best routes they learned to all the routers in our network. This is still done using BGP.
  5. Now, for a given IP address, each router knows to which web node the traffic should be directed.
Here are the respective metrics announced routes for W1, W2 and W3 when everything works as expected:
Route W1 W2 W3 Best Backup
2001:db8:30::1 102 101 100 W3 W2
2001:db8:30::2 101 100 102 W2 W1
2001:db8:30::3 100 102 101 W1 W3

ExaBGP configuration The configuration of ExaBGP is quite simple:
group rs  
  neighbor 2001:db8:1::4  
    router-id 1.1.1.11;
    local-address 2001:db8:6::11;
    local-as 65001;
    peer-as 65002;
   
  neighbor 2001:db8:8::5  
    router-id 1.1.1.11;
    local-address 2001:db8:6::11;
    local-as 65001;
    peer-as 65002;
   
  process watch-nginx  
      run /usr/bin/python /lab/healthcheck.py -s --config /lab/healthcheck-nginx.conf --start-ip 0;
   
 
A script is entailed to check if the service (an nginx web server) is up and running and advertise the appropriate IP addresses to the two declared route servers. If we run the script manually, we can see the advertised routes:
$ python /lab/healthcheck.py --config /lab/healthcheck-nginx.conf --start-ip 0
INFO[healthcheck] send announces for UP state to ExaBGP
announce route 2001:db8:30::3/128 next-hop self med 100
announce route 2001:db8:30::2/128 next-hop self med 101
announce route 2001:db8:30::1/128 next-hop self med 102
[...]
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
WARNING[healthcheck] Check command was unsuccessful: 7
INFO[healthcheck] Output of check command:  curl: (7) Failed connect to ip6-localhost:80; Connection refused
INFO[healthcheck] send announces for DOWN state to ExaBGP
announce route 2001:db8:30::3/128 next-hop self med 1000
announce route 2001:db8:30::2/128 next-hop self med 1001
announce route 2001:db8:30::1/128 next-hop self med 1002
When the service becomes unresponsive, the healthcheck script detect the situation and retry several times before acknowledging that the service is dead. Then, the IP addresses are advertised with higher metrics and the service will be routed to another node (the one advertising 2001:db8:30::3/128 with metric 101). This healthcheck script is now part of ExaBGP.

Route servers We could have connected our ExaBGP servers directly to each router. However, if you have 20 routers and 10 web servers, you now have to manage a mesh of 200 sessions. The route servers are here for three purposes:
  1. Reduce the number of BGP sessions (from 200 to 60) between equipments (less configuration, less errors).
  2. Avoid modifying the configuration on routers each time a new service is added.
  3. Separate the routing decision (the route servers) from the routing process (the routers).
You may also ask yourself: why not use OSPF? . Good question!
  • OSPF could be enabled on each web node and the IP addresses advertised using this protocol. However, OSPF has several drawbacks: it does not scale, there are restrictions on the allowed topologies, it is difficult to filter routes inside OSPF and a misconfiguration will likely impact the whole network. Therefore, it is considered a good practice to limit OSPF to network equipments.
  • The routes learned by the route servers could be injected into OSPF. On paper, OSPF has a next-hop field to provide an explicit next-hop. This would be handy as we wouldn t have to configure adjacencies with each router. However, I have absolutely no idea how to inject BGP next-hop into OSPF next-hop. What happens is that BGP next-hop is resolved locally using OSPF routes. For example, if we inject BGP routes into OSPF from RS4, RS4 will know the appropriate next-hop but other routers will route the traffic to RS4.
Let s look at how to configure our route servers. RS4 will use BIRD while RS5 will use Quagga. Using two different implementations will help with resiliency by avoiding a bug to hit the two route servers at the same time.

Bird configuration There are two sides for BGP configuration: the BGP sessions with the ExaBGP nodes and the ones with the routers. Here is the configuration for the later:
template bgp INFRABGP  
  export all;
  import none;
  local as 65002;
  rs client;
 
protocol bgp ER2 from INFRABGP  
  neighbor 2001:db8:1::2 as 65003;
 
protocol bgp ER3 from INFRABGP  
  neighbor 2001:db8:1::3 as 65003;
 
protocol bgp DR6 from INFRABGP  
  neighbor 2001:db8:1::6 as 65003;
 
protocol bgp DR7 from INFRABGP  
  neighbor 2001:db8:1::7 as 65003;
 
protocol bgp DR8 from INFRABGP  
  neighbor 2001:db8:1::8 as 65003;
 
The AS number used by our route server is 65002 while the AS number used for routers is 65003 (the AS numbers for web nodes will be 65001). They are reserved for private use by RFC 6996. All routes known by the route server are exported to the routers but no routes are accepted from them. Let s have a look at the other side:
# Only import loopback IPs
filter only_loopbacks   #  
  if net ~ [ 2001:db8:30::/64 128,128  ] then accept;
  reject;
 
# General template for an EXABGP node
template bgp EXABGP  
  local as 65002;
  import filter only_loopbacks; #  
  export none;
  route limit 10; #  
  rs client;
  hold time 6; #  
  multihop 10;
  igp table internal;
 
protocol bgp W1 from EXABGP  
  neighbor 2001:db8:6::11 as 65001;
 
protocol bgp W2 from EXABGP  
  neighbor 2001:db8:7::12 as 65001;
 
protocol bgp W3 from EXABGP  
  neighbor 2001:db8:8::13 as 65001;
 
To ensure separation of concerns, we are being a bit more picky. With and , we only accept loopback addresses and only if they are contained in the subnet that we reserved for this use. No server should be able to inject arbitrary addresses into our network. With , we also limit the number of routes that a server can advertise. With , we reduce the hold time from 240 to 6. It means that after 6 seconds, the peer is considered dead. This is quite important to be able to recover quickly from a dead machine. The minimal value is 3. We could have use a similar setting with the session with the routers.

Quagga configuration Quagga s configuration is a bit more verbose but should be strictly equivalent:
router bgp 65002 view EXABGP
 bgp router-id 1.1.1.5
 bgp log-neighbor-changes
 no bgp default ipv4-unicast
 neighbor R peer-group
 neighbor R remote-as 65003
 neighbor R ebgp-multihop 10
 neighbor EXABGP peer-group
 neighbor EXABGP remote-as 65001
 neighbor EXABGP ebgp-multihop 10
 neighbor EXABGP timers 2 6
!
 address-family ipv6
 neighbor R activate
 neighbor R soft-reconfiguration inbound
 neighbor R route-server-client
 neighbor R route-map R-IMPORT import
 neighbor R route-map R-EXPORT export
 neighbor 2001:db8:1::2 peer-group R
 neighbor 2001:db8:1::3 peer-group R
 neighbor 2001:db8:1::6 peer-group R
 neighbor 2001:db8:1::7 peer-group R
 neighbor 2001:db8:1::8 peer-group R
 neighbor EXABGP activate
 neighbor EXABGP soft-reconfiguration inbound
 neighbor EXABGP maximum-prefix 10
 neighbor EXABGP route-server-client
 neighbor EXABGP route-map RSCLIENT-IMPORT import
 neighbor EXABGP route-map RSCLIENT-EXPORT export
 neighbor 2001:db8:6::11 peer-group EXABGP
 neighbor 2001:db8:7::12 peer-group EXABGP
 neighbor 2001:db8:8::13 peer-group EXABGP
 exit-address-family
!
ipv6 prefix-list LOOPBACKS seq 5 permit 2001:db8:30::/64 ge 128 le 128
ipv6 prefix-list LOOPBACKS seq 10 deny any
!
route-map RSCLIENT-IMPORT deny 10
!
route-map RSCLIENT-EXPORT permit 10
  match ipv6 address prefix-list LOOPBACKS
!
route-map R-IMPORT permit 10
!
route-map R-EXPORT deny 10
!
The view is here to not install routes in the kernel3.

Routers Configuring BIRD to receive routes from route servers is straightforward:
# BGP with route servers
protocol bgp RS4  
  import all;
  export none;
  local as 65003;
  neighbor 2001:db8:1::4 as 65002;
  gateway recursive;
 
protocol bgp RS5  
  import all;
  export none;
  local as 65003;
  neighbor 2001:db8:8::5 as 65002;
  multihop 4;
  gateway recursive;
 
It is important to set gateway recursive because most of the time, the next-hop is not reachable directly. In this case, by default, BIRD will use the IP address of the advertising router (the route servers).

Testing Let s check that everything works as expected. Here is the view from RS5:
# show ipv6  bgp  
BGP table version is 0, local router ID is 1.1.1.5
Status codes: s suppressed, d damped, h history, * valid, > best, i - internal,
              r RIB-failure, S Stale, R Removed
Origin codes: i - IGP, e - EGP, ? - incomplete
   Network          Next Hop            Metric LocPrf Weight Path
*  2001:db8:30::1/128
                    2001:db8:6::11         102             0 65001 i
*>                  2001:db8:8::13         100             0 65001 i
*                   2001:db8:7::12         101             0 65001 i
*  2001:db8:30::2/128
                    2001:db8:6::11         101             0 65001 i
*                   2001:db8:8::13         102             0 65001 i
*>                  2001:db8:7::12         100             0 65001 i
*> 2001:db8:30::3/128
                    2001:db8:6::11         100             0 65001 i
*                   2001:db8:8::13         101             0 65001 i
*                   2001:db8:7::12         102             0 65001 i
Total number of prefixes 3
For example, traffic to 2001:db8:30::2 should be routed through 2001:db8:7::12 (which is W2). Other IP are affected to W1 and W3. RS4 should see the same thing4:
$ birdc6 show route 
BIRD 1.3.11 ready.
2001:db8:30::1/128 [W3 22:07 from 2001:db8:8::13] * (100/20) [AS65001i]
                   [W1 23:34 from 2001:db8:6::11] (100/20) [AS65001i]
                   [W2 22:07 from 2001:db8:7::12] (100/20) [AS65001i]
2001:db8:30::2/128 [W2 22:07 from 2001:db8:7::12] * (100/20) [AS65001i]
                   [W1 23:34 from 2001:db8:6::11] (100/20) [AS65001i]
                   [W3 22:07 from 2001:db8:8::13] (100/20) [AS65001i]
2001:db8:30::3/128 [W1 23:34 from 2001:db8:6::11] * (100/20) [AS65001i]
                   [W3 22:07 from 2001:db8:8::13] (100/20) [AS65001i]
                   [W2 22:07 from 2001:db8:7::12] (100/20) [AS65001i]
Let s have a look at DR6:
$ birdc6 show route
2001:db8:30::1/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]
2001:db8:30::2/128 via fe80::5054:60ff:fe02:3681 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:60ff:fe02:3681 on eth0 (100/20) [AS65001i]
2001:db8:30::3/128 via 2001:db8:6::11 on eth1 * (100/10) [AS65001i]
                   via 2001:db8:6::11 on eth1 (100/10) [AS65001i]
So, 2001:db8:30::3 is owned by W1 which is behind DR6 while the two others are in another part of the network and will be reached through the appropriate link-local addresses learned by OSPF. Let s kill W1 by stopping nginx. A few seconds later, DR6 learns the new routes:
$ birdc6 show route
2001:db8:30::1/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]
2001:db8:30::2/128 via fe80::5054:60ff:fe02:3681 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:60ff:fe02:3681 on eth0 (100/20) [AS65001i]
2001:db8:30::3/128 via fe80::5054:56ff:fe6e:98a6 on eth0 * (100/20) [AS65001i]
                   via fe80::5054:56ff:fe6e:98a6 on eth0 (100/20) [AS65001i]

Demo For a demo, have a look at the following video (it is also available as an Ogg Theora video).

  1. The primary target of VRRP is to make a default gateway for an IP network highly available by exposing a virtual router which is an abstract representation of multiple routers. The virtual IP address is held by the master router and any backup router can be promoted to master in case of a failure. In practice, VRRP can be used to achieve high availability of services too.
  2. However, you could deploy an L2 overlay network using, for example, VXLAN and use VRRP on it.
  3. I have been told on the Quagga mailing-list that such a setup is quite uncommon and that it would be better to not use views but use --no_kernel flag for bgpd instead. You may want to look at the whole thread for more details.
  4. The output of birdc6 shows both the next-hop as advertised in BGP and the resolved next-hop if the route have to be exported into another protocol. I have simplified the output to avoid confusion.

5 September 2013

Gergely Nagy: What's cooking in syslog-ng 3.5?

The first alpha of syslog-ng 3.4 was released more than a year ago, and the first stable release earlier this year, development on syslog-ng 3.5 has been going on steadlily since then, with a lot of interesting features and changes pouring in. While the 3.5 release will not bring as many overwhelming changes as the previous two releases did, the sheer number of improvements is still substantial. Our focus was on smaller developments all over the place this time, instead of big sweeping changes. In this post, we will go over most of these features, with use-cases, examples and a few words about why they are so useful and awesome.Multi-line support, new destinations, new template functions, type hinting, unit suffixes, and other things. Read on, and be amazed!These are only bigger features, there has been a lot of small tweaking going on, and of course, all of the fixes that went into prior versions will also be in 3.5 too, and there's still a chance that something else may find its way in before the feature freeze.Multi-line supportOne of the major new features in the 3.5 release will be support for multi-line messages, a feature that has been available in syslog-ng PE for a good while, and which has been ported to and improved upon to the open source edition. Two variants of multi-line are supported, which will be detailed below. Both of them are available for the file() and pipe() sources only.Indented multi-lineThe easiest variant is indented multi-line, where each line can be followed by others, indented by whitespace, and the message continues until the first non-indented line. This is the format used by the Linux kernel too, from version 3.5, for /dev/log. This type of multi-line can be used as follows:
source s_multiline   file("/path/to/file" multi-line-mode(indented));  ;
Consider that /path/to/file has the following content:
First line
 Continuation 1;
 Continuation 2;
Second line
With the indented multi-line-mode() setting, this would turn into two log messages:
First line\n Continuation 1;\n Continuation 2;
Second line
Regexp-based multilineIf multi-line input is not based on indentation, one can use the regexp multi-line-mode() instead, which makes two new settings available: multi-line-prefix() and multi-line-garbage(). These can be used to define the start and the end of a log message: any string between a the beginning matching prefix and a matching garbage will be considered a single message. That is, the prefix will be included, the garbage will not be: it will be discarded.To illustrate:
source s_multiline  
 file("/path/to/file" multi-line-mode(regexp)
                      multi-line-prefix("^prefix")
                      multi-line-garbage(" garbage$"));
 ;
If the source contains these lines:
prefix message
continuing garbage
This will turn into the following log message:
prefix message\ncontinuing
New destinationsIt would be pretty hard to do a syslog-ng release without new destinations, and with 3.5, we will have three of them!STOMPWhile we had AMQP before, we now have a STOMP destination too, so we can stream logs to any STOMP server, with a few simple lines:
stomp(
 host("localhost")
 port(61613)
 destination("/topic/syslog")
 routing_key("")
 persistent(yes)
 ack(no)
 username("someone")
 password("something")
 body("This is the body! YAY! Here's a message: $MESSAGE!\n")
 value-pairs(scope(nv-pairs, syslog-proto, selected-macros))
)
Of course, none of these settings need to be set, you can just use the defaults, and it will just work!RiemannDid you know that syslog-ng is far more than a log collector and processor? No? You do now. When you have access to a lot of logs, and a tremendous amount of power in parsing them, you can use these tools for monitoring easily! And when we're talking monitoring, riemann is a great asset in our toolbox, and with the new destination, we can easily forward metrics to it:
riemann(
 server("localhost")
 port(5555)
 host("$HOST")
 service("$PROGRAM")
 description("$PROGRAM pids")
 metric(int("$PID"))
 ttl(300)
);
Of course, the above is a very silly example, it would make much more sense to extract data from a log message instead, but this will serve as an example.New template functions
$(upper-case TEXT...), $(lower-case TEXT...)
To turn some text into *upper-* or *lower-case*, these two template functions come in handy. They simply turn all their arguments into the respecitve case.
$(delimit DELIMITERS NEW-DELIMITER TEXT)
Sometimes one has a delimited string, where one wishes to replace the delimiters. This function does just that: give it a list of delimiters (you may need to quote it, if it contains whitespace), a replacement, and a text to replace delimiters in, and it does the rest. For example, to replace tabs and spaces with a vertical bar, one could write a template like this:
template("$(delimit \"\t \" \" \" $MESSAGE)\n")
$(env VARIABLE...)
Have you ever felt the need to check an environment variable from within syslog-ng? I did, and now I can.
Type hintingWhile syslog-ng supported sending log messages into various data stores and message queues for a while (SQL at first, MongoDB, JSON and AMQP later), even when those supported different types of data than strings, we could not do anything else. Until now. It is now possible - at places where it makes sense - to annotate templates with type hints, which the destination driver can optionally use. Type hinting is implemented for the mongodb() destination and the $(format-json) template function for now. When no type hint is specified, syslog-ng defaults to string.To add type hints, simply wrap the respective template with the hinted type, like this:
mongodb(
 value-pairs(pair("date", datetime("$UNIXDATE"))
             pair("pid", int64("$PID")))
);
Currently the following type hints exist: boolean (anything that begins with a t or 1 is true, anything that begins with f or 0 is false, everything else is an error), string, literal (same as string, but not quoted if it would be quoted otherwise), int32 (int is an alias for this), int64, and datetime. Only UNIX timestamps can be type-hinted to datetime, anything else will likely result in a casting error.It is also possible to control what happens when type casting fails: syslog-ng can drop the whole message, drop the property, or fall back to string. It can also do all of these silently:
options  
 typecast(on-error(silently-drop-property));
 ;
Using this feature with $(format-json) is very similary too:
$(format-json date=datetime("$UNIXDATE") pid=int64("$PID"))
With this feature in place, you can now store your non-string values with their proper types!Unit suffixesUnit suffixes make it considerably easier to set limits and describe numbers within the syslog-ng configuration. We no longer need to spell out sizes to the byte precious, it is now enough to write: log-fifo-size(200MiB). Now, syslog-ng will understand suffixes for kilo-, mega-, and giga-bytes, (K, M, G, respectively) either in base-10 or base-2 (with an extra i after the suffix). One can also omit the trailing b from the end.So, to set the log-fifo-size() to 2097152 bytes, one can simply use 2MiB. Or, to set it to 2000000, 2Mb. That's a whole lot easier, isn't it? No more counting zeros, no more silly typos in a ten-digit number, no more pain, but easily readable units!Miscellaneous featuresApart from the features above, there have been a lot of other changes and improvements in the code base:

Keith Packard: Airfest-altimeter-testing

Altimeter Testing at Airfest Bdale and I, along with AJ Towns and Mike Beattie, spent last weekend in Argonia, Kansas, flying rockets with our Kloudbusters friends at Airfest 19. We had a great time! AJ and Mike both arrived a week early at Bdale s to build L3 project airframes, and both flew successful cert flights at Airfest! Airfest was an opportunity for us to test fly prototypes of new flight electronics Bdale and I have spent the last few weeks developing, and I thought I d take a few minutes today to write some notes about what we built and flew. TeleMega We ve been working on TeleMega for quite a while. It s a huge step up in complexity from our original TeleMetrum, as it has a raft of external sensors and six pyro circuits. Bdale flew TeleMega in his new fiberglass 4 airframe on a Loki 75mm blue M demo motor. GPS tracking was excellent; you can see here that GPS altitude tracked the barometric sensor timing exactly: GPS lost lock when the motor lit, but about 3 seconds after motor burnout, it re-acquired the satellite signals and was reporting usable altitude data right away. The GPS reported altitude was higher than the baro sensor, but that can be explained by our approximation of an atmospheric model used to convert pressure into altitude. The rest of the flight was also nominal; TeleMega deployed drogue and main chutes just fine. TeleMetrum We ve redesigned TeleMetrum. The new version uses better sensors (MS5607 baro sensor, MMA6555 accelerometer) and a higher power radio (CC1120 40mW). The board is the same size, all the connectors are in the same places so it s a drop-in replacement, and it s still got two pyro channels and USB for configuration, data download and battery charging. I loaded up my Candy-Cane airframe with a small 5 grain 38mm CTI classic: The flight computer worked perfectly, but GPS reception was not as good as we d like to see: Given how well TeleMega was receiving GPS signals, I m hopeful that we ll be able to tweak TeleMetrum to improve performance. TeleMini We ve also redesigned TeleMini. It s still a two-channel flight computer with logging and telemetry, but we ve replaced the baro sensor with the MS5607, added on-board flash for increased logging space and added on-board screw terminals for an external battery and power switch. You can still use one of our 3.7V batteries, but you can also use another battery providing from 3.7 to 15V. I was hoping to finish up the firmware and fly it, but I ran out of time before the launch. The good news is that all of the components of the board have been tested and work correctly, and the firmware is feature complete , meaning we ve gotten all of the features coded, it s just not quite working yet. EasyMini EasyMini is a new product for us. It s essentially the same as a TeleMini, but without a radio. Two channels, baro-only, with logging. Like TeleMini, it includes an on-board USB connector and can use either one of our 3.7V batteries, or an external battery from 3.7V to 15V. EasyMini and TeleMini are the same size, and have holes in the same places, so you can swap between them easily. I flew EasyMini in my Koala airframe with a 29mm 3 grain CTI blue-streak motor. EasyMini successfully deployed the main chute and logged flight data: We also sent a couple of boards home with Kevin Trojanowski and Greg Rothman for them to play with. TeleGPS TeleGPS is a GPS tracker, incorporating a u-blox Max receiver and a 70cm transmitter. It can send position information via APRS or our usual digital telemetry formats. I was also hoping to have the TeleGPS firmware working, and I spent a couple of nights in the motel coding, but didn t manage to finish up. So, no data from this board either. Production Plans Given the success of the latest TeleMega prototype, we re hoping to have it into production first. We ll do some more RF testing on the bench with the boards to make sure it meets our standards before sending it out for the first production run. The goal is to have TeleMega ready to sell by the end of October. TeleMetrum clearly needs work on the layout to improve GPS RF performance. With the testing equipment that Bdale is in the midst of re-acquiring, it should be possible to finish this up fairly soon. However, the flight firmware looks great, so we re hoping to get these done in time to sell by the end of November. TeleMini is looking great from a hardware perspective, but the firmware needs work. Once the firmware is running, we ll need to make enough test flights to shake out any remaining issues before moving forward with it. EasyMini is also looking finished; I ve got a stack of prototypes and will be getting people to fly them at my local launch in another couple of weeks. The plan here is to build a small batch by hand and get them into the store once we re finished testing, using those to gauge interest before we pay for a larger production run.

12 August 2013

Sylvain Le Gall: Migrating a puppet maintained computer from Squeeze to Wheezy

This blog post is a little recipe to do a Debian migration for a node using Puppet and some other good practices. We do all the following commands as root, which on of the exceptional situation where you should have a real root session (login through console, or su -). I tend to avoid using the X server while doing an upgrade, so my 'best' setup is to have a laptop to take note and check things on the internet and a session to the computer to upgrade (ssh + su - or login as root into console). In both case, I use screen during the upgrade so that I can handle disconnection. Create or update your admin-syscheck script First of all, a good practice is to have a script that runs various test on the system that checks everything is ok. This is not only for upgrade but in general. But in the case of upgrade, it can be particularly useful. I call this script admin-syscheck. This is a simple bash script. This script check various aspect of the system and serve me as my external worker to check the most advanced knowledge I have gathered about setting up a service. For example, I know that having *.bak or *.dpkg-dist in /etc/ means that something needs to be merged and a file should be deleted. Another example is about setting up the right alias for 127.0.0.1 and ::1 (which you can differentiate using getent ahostsv4 and getent ahostsv6). I have packaged this script and distributed it using a specific apt-get repository. You can just distribute it using puppet. I recommend to run it daily to track changes (e.g. after an apt-get dist-upgrade) and to check that my setup is aligned with my most up-to-date knowledge about setting up a service (i.e. this is my external worker). In our case we are interested in checking presence of old and new configuration files, before and after upgrading. Here is this specific section of my script:
if ! $IS_ROOT; then
  warning "Not trying to detect dpkg leftover file in /etc/."
else
  LEFTOVER_FILES=( $(find /etc/ \
      -name "*.dpkg-dist" -o \
      -name "*.dpkg-old" -o \
      -name "*.ucf-old" -o \
      -name "*.ucf-dist" -o \
      -name "*.bak") )
  for i in "$ LEFTOVER_FILES[@] "; do
    if [ "$i" = "/etc/hosts.deny.purge.bak" ]; then
      continue
    fi
    if $fix; then
      BASE=$ i%.* 
      cond_exec vim -d $BASE $i
      read -p "Delete $i (y/N)? " ans
      if [ "$ans" = "y" ]; then
        cond_exec rm $i
      fi
    else
       report_error "dpkg leftover file: '$i'."
    fi
  done
fi
(cond_exec allows to do a dry run, you can just remove it). Setting $fix to true will spawn a vim -d old new command where you can edit and then delete the leftover file. This is extremly handy. Upgrading to Wheezy I strongly recommend to read first the upgrade chapter of the release notes. This gives you a more complete overview of the upgrade procedure. I just go through the basic step here. 1. Update everything on the system:
$> apt-get update 
$> apt-get dist-upgrade
2. Check that the current configuration apply cleanly:
$> puppet agent --test
3. Run admin-syscheck:
$> admin-syscheck
And fix all the problems. 4. Disable puppet: I use a cronjob to run puppet, so I just comment the line for the job (/etc/cron.d/puppet-custom). You should disable puppet by stopping the daemon and preventing it to run by editing /etc/default/puppet and set START=no. 4. Fix your sources and pinning: Change squeeze to wheezy in /etc/apt/sources.list and remove useless files in /etc/apt/sources.lists.d/. (You may keep certain sources that refers to stable, like google-chrome.list).
$> rm /etc/apt/sources.list.d/* # Check if this ok to do this with your system.
Although, I tend to fully purge /etc/apt/sources.list expect for the main line (removing backports and security is fine for a short time). The first run of puppet after upgrade will anyway reset this file.
$> rm /etc/apt/preferences.d/* # (at least the ones that do pin some version)
You can although remove all pinning from /etc/apt/preferences. 5. Now you start the real upgrade:
$> apt-get update 
$> apt-get dist-upgrade
6. During the upgrade you will be asked if you want to keep old configuration files or install the newer one from the maintainer. I have always wondered what to answer to this. But here is the answer after a few major upgrade: always install configuration files from maintainer if the service has no ultra-specific settings that could break during the upgrade. The only file, that I should not upgrade on my system, is /etc/sudoers. In this very specific case, you need to make sure before the upgrade that the old and new configuration can coexist. In the squeeze to wheezy case, I have just setup a few extra augeas rules to set the secure_path before the upgrade and it was fine. This is typically the kind of situation where you are thankful to have a real root session. 7. The upgrade can be long and require various fixing to remove/re-add packages to circumvent problems. At the end you will have a set of file *.dpkg-old and *.ucf-old (and some *.dpkg-dist and *.ucf-dist). The *-old files are your old version of the file, while the corresponding files match the maintainer version of it. The *-dist files are the maintainer version of the file and the corresponding files match your old version of it. Starting from here you have 2 options: First upgrade This is the tricky part, you'll have to spend a little time on it: 1. Go over all *. ucf,dpkg - old,dist and merge them with the corresponding configuration file. Use admin-syscheck with fix=true 2. Make a copy of your /etc directory into /etc.new:
$> cp -rp /etc /etc.new
3. Run puppet again:
$> puppet agent --test
4. Disable again the automatic run of puppet, if the previous command has re-enabled it. 5. Make a diff between /etc and /etc.new. Since you have a run of puppet, you know what has changed and should not have changed.
$> diff -Nurd /etc.new /etc
Everytime you find some files that doesn't match your expectation for the upgrade with puppet, change the corresponding puppet manifest to have what you expect. For example, if this is a file:
if ($lsbdistcodename == 'wheezy')  
  file  
    "/etc/foo":
        source => "puppet:///files/foo.wheezy"
    
  else  
  file  
    "/etc/foo":
        source => "puppet:///files/foo.squeeze"
    
 
People working with augeas and puppet, will appreciate the fact that they probably have 0 changes to make for this to work (since it only does a few replacement in configuration files). 6. Once you are happy with the changes, copy back /etc.new to /etc and go to step 3 until the difference is almost 0. 7. Re-enable automatic run of puppet. Do this procedure for a least each computer category you have (e.g. Desktop and Server nodes). Once you are fully confident your new puppet setup works, you will be able to use 'further upgrade' for the other nodes. Further upgrade. This one is super easy compare to a first upgrade: 1. Re-enable puppet and have it run at least once:
$> puppet agent --test
2. Merge *. dpkg,ucf - dist,old with corresponding files (you can run admin-syscheck with fix=true). This is mostly a sanity check since you should have already solved most problem with the 'first upgrade' procedure. That's it. Enjoy your upgrade to Wheezy with puppet.

1 August 2013

Julien Danjou: The definitive guide on how to use static, class or abstract methods in Python

Doing code reviews is a great way to discover things that people might struggle to comprehend. While proof-reading OpenStack patches recently, I spotted that people were not using correctly the various decorators Python provides for methods. So here's my attempt at providing me a link to send them to in my next code reviews. :-) How methods work in Python A method is a function that is stored as a class attribute. You can declare and access such a function this way:
>>> class Pizza(object):
... def __init__(self, size):
... self.size = size
... def get_size(self):
... return self.size
...
>>> Pizza.get_size
<unbound method Pizza.get_size>

What Python tells you here, is that the attribute get_size of the class Pizza is a method that is unbound. What does this mean? We'll know as soon as we'll try to call it:
>>> Pizza.get_size()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
TypeError: unbound method get_size() must be called with Pizza instance as first argument (got nothing instead)

We can't call it because it's not bound to any instance of Pizza. And a method wants an instance as its first argument (in Python 2 it must be an instance of that class; in Python 3 it could be anything). Let's try to do that then:
>>> Pizza.get_size(Pizza(42))
42

It worked! We called the method with an instance as its first argument, so everything's fine. But you will agree with me if I say this is not a very handy way to call methods; we have to refer to the class each time we want to call a method. And if we don't know what class is our object, this is not going to work for very long. So what Python does for us, is that it binds all the methods from the class Pizza to any instance of this class. This means that the attribute get_size of an instance of Pizza is a bound method: a method for which the first argument will be the instance itself.
>>> Pizza(42).get_size
<bound method Pizza.get_size of <__main__.Pizza object at 0x7f3138827910>>
>>> Pizza(42).get_size()
42

As expected, we don't have to provide any argument to get_size, since it's bound, its self argument is automatically set to our Pizza instance. Here's a even better proof of that:
>>> m = Pizza(42).get_size
>>> m()
42

Indeed, you don't even have to keep a reference to your Pizza object. Its method is bound to the object, so the method is sufficient to itself. But what if you wanted to know which object this bound method is bound to? Here's a little trick:
>>> m = Pizza(42).get_size
>>> m.__self__
<__main__.Pizza object at 0x7f3138827910>
>>> # You could guess, look at this:
...
>>> m == m.__self__.get_size
True

Obviously, we still have a reference to our object, and we can find it back if we want. In Python 3, the functions attached to a class are not considered as unbound method anymore, but as simple functions, that are bound to an object if required. So the principle stays the same, the model is just simplified.
>>> class Pizza(object):
... def __init__(self, size):
... self.size = size
... def get_size(self):
... return self.size
...
>>> Pizza.get_size
<function Pizza.get_size at 0x7f307f984dd0>

Static methods Static methods are a special case of methods. Sometimes, you'll write code that belongs to a class, but that doesn't use the object itself at all. For example:
class Pizza(object):
@staticmethod
def mix_ingredients(x, y):
return x + y

def cook(self):
return self.mix_ingredients(self.cheese, self.vegetables)

In such a case, writing mix_ingredients as a non-static method would work too, but it would provide it a self argument that would not be used. Here, the decorator @staticmethod buys us several things:
>>> Pizza().cook is Pizza().cook
False
>>> Pizza().mix_ingredients is Pizza.mix_ingredients
True
>>> Pizza().mix_ingredients is Pizza().mix_ingredients
True

Class methods Having said that, what are class methods? Class methods are methods that are not bound to an object, but to a class!
>>> class Pizza(object):
... radius = 42
... @classmethod
... def get_radius(cls):
... return cls.radius
...
>>>
>>> Pizza.get_radius
<bound method type.get_radius of <class '__main__.Pizza'>>
>>> Pizza().get_radius
<bound method type.get_radius of <class '__main__.Pizza'>>
>>> Pizza.get_radius is Pizza().get_radius
True
>>> Pizza.get_radius()
42

Whatever the way you use to access this method, it will be always bound to the class it is attached too, and its first argument will be the class itself (remember that classes are objects too). When to use this kind of methods? Well class methods are mostly useful for two types of methods:
class Pizza(object):
def __init__(self, ingredients):
self.ingredients = ingredients

@classmethod
def from_fridge(cls, fridge):
return cls(fridge.get_cheese() + fridge.get_vegetables())

class Pizza(object):
def __init__(self, radius, height):
self.radius = radius
self.height = height

@staticmethod
def compute_circumference(radius):
return math.pi * (radius ** 2)

@classmethod
def compute_volume(cls, height, radius):
return height * cls.compute_circumference(radius)

def get_volume(self):
return self.compute_volume(self.height, self.radius)

Abstract methods An abstract method is a method defined in a base class, but that may not provide any implementation. In Java, it would describe the methods of an interface. So the simplest way to write an abstract method in Python is:
class Pizza(object):
def get_radius(self):
raise NotImplementedError

Any class inheriting from Pizza should implement and override the get_radius method, otherwise an exception would be raised. This particular way of implementing abstract method has a drawback. If you write a class that inherits from Pizza and forget to implement get_radius, the error will only be raised when you'll try to use that method.
>>> Pizza()
<__main__.Pizza object at 0x7fb747353d90>
>>> Pizza().get_radius()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "<stdin>", line 3, in get_radius
NotImplementedError

There's a way to triggers this way earlier, when the object is being instantiated, using the abc module that's provided with Python.
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_radius(self):
"""Method that should do something."""

Using abc and its special class, as soon as you'll try to instantiate BasePizza or any class inheriting from it, you'll get a TypeError.
>>> BasePizza()
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
TypeError: Can't instantiate abstract class BasePizza with abstract methods get_radius

Mixing static, class and abstract methods When building classes and inheritances, the time will come where you will have to mix all these methods decorators. So here's some tips about it. Keep in mind that declaring a class as being abstract, doesn't freeze the prototype of that method. That means that it must be implemented, but i can be implemented with any argument list.
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_ingredients(self):
"""Returns the ingredient list."""

class Calzone(BasePizza):
def get_ingredients(self, with_egg=False):
egg = Egg() if with_egg else None
return self.ingredients + egg

This is valid, since Calzone fulfil the interface requirement we defined for BasePizza objects. That means that we could also implement it as being a class or a static method, for example:
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

@abc.abstractmethod
def get_ingredients(self):
"""Returns the ingredient list."""

class DietPizza(BasePizza):
@staticmethod
def get_ingredients():
return None

This is also correct and fulfil the contract we have with our abstract BasePizza class. The fact that the get_ingredients method don't need to know about the object to return result is an implementation detail, not a criteria to have our contract fulfilled. Therefore, you can't force an implementation of your abstract method to be a regular, class or static method, and arguably you shouldn't. Starting with Python 3 (this won't work as you would expect in Python 2, see issue5867), it's now possible to use the @staticmethod and @classmethod decorators on top of @abstractmethod:
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

ingredient = ['cheese']

@classmethod
@abc.abstractmethod
def get_ingredients(cls):
"""Returns the ingredient list."""
return cls.ingredients

Don't misread this: if you think this going to force your subclasses to implement get_ingredients as a class method, you are wrong. This simply implies that your implementation of get_ingredients in the BasePizza class is a class method. An implementation in an abstract method? Yes! In Python, contrary to methods in Java interfaces, you can have code in your abstract methods and call it via super():
import abc

class BasePizza(object):
__metaclass__ = abc.ABCMeta

default_ingredients = ['cheese']

@classmethod
@abc.abstractmethod
def get_ingredients(cls):
"""Returns the ingredient list."""
return cls.default_ingredients

class DietPizza(BasePizza):
def get_ingredients(self):
return ['egg'] + super(DietPizza, self).get_ingredients()

In such a case, every pizza you will build by inheriting from BasePizza will have to override the get_ingredients method, but will be able to use the default mechanism to get the ingredient list by using super().

27 July 2013

Julien Danjou: OpenStack Ceilometer Havana-2 milestone released

Last week, the second milestone of the Havana developement branch of Ceilometer has been released and is now available for testing and download. This means the first half of the OpenStack Havana development has passed! New features Ten blueprints have been implemented as you can see on the release page. I'm going to talk through some of them here, that are the most interesting for users.
The Ceilometer API now returns all the samples sorted by timestamp. This blueprint is the first one implemented by Terri Yu, our OPW intern! In the same spirit, I've added the ability to limit the number of samples returned. On the alarming front, things evolved a lot. I've implemented the notifier system that will be used to run actions when alarms are triggered. To trigger these alarms, Eoghan Glynn (RedHat) worked on the alarm evaluation system that will use the Ceilometer API to check for alarm states. I've reworked the publisher system so it now uses URL formatted target for publication. That now allows to publish different meters to different target using the same publishing protocol (e.g. via UDP toward different hosts). Sandy Walsh (RackSpace) have been working on the StackTach like functionality and added the ability for the collector to optionally store the notification events received. Finally, Mehdi Abaakouk (eNovance) implemented a TTL system for the database, so you're now able to expire your data whenever you like. Bug fixes Thirty-five bugs were fixed, though most of them might not interest you so I won't elaborate too much on that. Go read the list if you are curious. Toward Havana 3 We now have 30 blueprints targeting the Ceilometer's third Havana milestone, with some of them are already started.I'll try to make sure we'll get there without too much trouble for the 6th September 2013. Stay tuned!

22 July 2013

Keith Packard: async flip

Asynchronous Display Flipping for Linux Using display (or plane or page) flipping is a nice optimization for screen updates as it avoids copying the application render buffer to the separate scanout buffer. However, in the current DRM interface, the flip operation is not performed immediately. Rather, the flip operation must be presented to the kernel before the vertical blank interval preceding the desired display time. If the flip operation is even slightly delayed, the new scanout image will not be visible until the following frame. With many applications pushing the performance of the graphics hardware right to the edge, it s not at all uncommon for an occasional frame to just miss and cause an ugly jerk on the screen. The GLX_EXT_swap_control_tear extension provides a way for applications to request that when the swap request is delivered too late, instead of delaying for the next frame, the contents should be presented as soon as possible, even if that might cause some tearing artifacts on the screen. This gives the application developer the choice between the two visual artifacts (tearing vs judder). A Linux interface for Async Flipping This part was pretty easy to implement. First, a new capability value, DRM_CAP_ASYNC_PAGE_FLIP was added so that applications could discover whether the driver offered this feature or not. Second, a new flag value, DRM_MODE_PAGE_FLIP_ASYNC was added to the DRM_IOCTL_MODE_PAGE_FLIP ioctl. To get the new flag down into the driver required adding the flag parameter to the page_flip crtc function. Async Display Flipping support in Intel Hardware Recent Intel display hardware has support for asynchronous flipping, either through the ring using the MI_DISPLAY_FLIP instruction or directly through the registers. There are some limitations however: I ve also only implemented flipping on Sandybridge and Ivybridge hardware as that s what I ve got for testing. Using Async Display Flipping with Present I m using async display flipping when the kernel supports it in the current Present implementation. This offers the ability to short-circuit multiple presentations targeting the same scanout frame. I haven t exposed the ability to select this to applications over the Present protocol yet, but that s not a big change. Implementing the GLX_EXT_swap_control_tear extension I haven t even looked at implementing this extension; I m hoping that once I ve gotten the functionality exposed over the X protocol that someone will at least help me figure out how to hook this up. Getting the Bits The interesting pieces here are the new kernel bits; the DRM library changes simply add new defines to existing APIs.

11 July 2013

Daniel Pocock: Using debcheckout to build strongSwan 5.0 on Debian wheezy

Normally most people try to use packages from a stable Linux distribution because of their convenience and security support. Sometimes it's necessary to use a newer version, I recently had to do this with strongSwan and I'm sharing the procedure for other people to try. These days, it is actually very very easy to build a new version of a package from source and this procedure will work for many Debian packages. Debian wheezy ships with strongSwan version 4.5 packages. These are lacking support for a couple of features I needed, including dual-stack IPv4/IPv6 virtual IPs on a single user connection and maintaining the DNS server list on road-warriors Oddly enough, for a variety of reasons, I had to rebuild strongSwan on all the platforms where I wanted to use it (not just on Debian). I recently described how to build it with ECDSA support on Fedora and also how to build it with ECDSA support on OpenWRT. Following all of these procedures you will end up with strongSwan packages on all systems that can interoperate using dual stack IPv4, IPv6 and establish connections quickly, securely and reliably using ECC certificates. Get the build dependencies Many packages require extra tools and header files when building. These are packages that are not usually installed or required when running the package. However, they are very easy to get. For strongSwan:
sudo apt-get update
sudo apt-get install devscripts fakeroot
sudo apt-get build-dep strongswan
This should download and install the necessary dependencies. Notice we also installed the devscripts package, it provides the very handy debcheckout utility. Obtain and build the package Now for the real work. Fortunately this is not too hard either:
mkdir ~/ws
cd ~/ws
debcheckout strongswan
cd strongswan
dpkg-buildpackage -rfakeroot -uc -b
Look in the directory ~/ws and you will find the .deb package files. Problems? On my own system, I observed that I could upgrade from the existing packages to the v5.0.4-6 package without any change to the configuration files. It just worked. Hopefully, these packages will eventually end up in Debian's backports catalog where you can install them without compiling. Nonetheless, problems for these packages can still be submitted through Debian's bug tracker - just make sure you clearly indicate that you built the package from source and give the git commit number (output of the command cd ~/ws/strongswan && git show head -1) Before trying the package and definitely before reporting any problem, it is worth checking the bug tracker and the Package Tracking System for known issues

10 July 2013

Neil McGovern: Kerning in LibreOffice

Are you a fan of kerning? Are all your letters running together? Do you want your documents in LibreOffice to look normal again? Try turning off hardware acceleration: Tools -> Options -> View -> Use hardware acceleration. Brought to you by the handy department of readable text.

Russell Coker: Samsung Galaxy Note 2

A few weeks ago I bought a new Samsung Galaxy Note 2 Android phone. As I predicted in my post about Phone and Tablet Sizes [1] the Note 2 with a 5.55 display is a bit too big for me to have an ideal single handed side grasp (I estimate that about 5.2 would be ideal). But I can stretch a bit and move it around in my hand to touch all parts of the screen with my thumb. Although when doing that I don t have a tight grip, with my previous phone the Samsung Galaxy S3 [2] I could properly wrap my hand around it to grip it tightly while using it with one hand. The Note 2 will be easier for me to drop or for a thief to snatch it from me. While the big screen makes the phone difficult to use with one hand it does allow viewing more data. The ConnectBot SSH client (Play Store link) [3] (F-Droid repository link) [4] works a lot better on a larger screen I ve also discovered that the volume control buttons can be used to change the font size in ConnectBot which is handy as the default is really tiny. Also Klaus Weidner s Hacker s Keyboard (Play Store link) [5] (F-Droid repository link) [6] works a lot better with a larger screen. When I tested the Hacker s keyboard on a smaller phone I found the 5 row layout too difficult to use, but on the Note 2 it works well. As an aside I wish I could quickly and easily toggle between 4 row mode (good for SMS) and 5 row mode (good for sysadmin work) in the Hackers Keyboard. For less serious use the large screen on the Note 2 is good for watching TV. I ve got a collection of mp4s of TV shows that I ve been meaning to watch, now I watch them in bed on my phone. Another advantage of the Note 2 is the battery life. When playing Ingress and doing all the usual email checks etc my Note 2 will last about as long as my wife s Galaxy S3 with it s power case. So without any extra batteries a Note 2 will probably last about twice as long as a Galaxy S3. The Note 2 has more RAM than the S3 I used to use (I had the S3 with 1G of RAM) and it also apparently has a faster CPU. The CPU speed hasn t been an issue for me but the extra RAM is a real benefit, it means that I can usually switch between Ingress and other programs without having to restart Ingress each time. As an aside I think that Google and LG should release a Nexus Ingress 4 phone or some other device that s optimised for Ingress, I m sure it would sell well. Some people make a big deal about the stylus that comes with the Note 2. It is a neat feature to have the device know when the stylus tip is hovering over the screen but it s not very useful for me. If I was going to create art work on a phone (as some people do) then it would interest me, but I m more interested in email and ssh for fine input and my fingers are generally good enough for those tasks. I have got thin fingers, so I think that people with thicker fingers could really benefit from the stylus. I recently bought a batch of stylus pens from Kogan which have a pen at one end and a rubber stylus tip at the other for fat fingered people I know who need to use an Android phone but can t afford a Note or Note 2. I also like the software build on it which is almost the same as that on the Galaxy S3. It seems that many people prefer the apparently stock features on the Nexus 4 but I like the way Samsung does things. Conclusion I m very happy with my new phone. The bigger screen allows me to see things more clearly, this is good for web browsing, reading email, and now that I can use the Hackers Keyboard I can type more effectively. The longer battery life is really good too, although I think that Samsung could have done better if the phone was 3mm thicker then it could have a much bigger battery and have a larger CCD for the camera. I don t think that the phone is really different, at least not for my use. Samsung has promoted it for artistic use and I ve seen evidence to support their claims. But for most people it ll just be a phone with a larger screen and a bigger battery. Some people criticise it for being too big, but it s still smaller than the handsets on most desk phones so it s not big by the standards of old fashioned phones. The increased size has not only allowed me to do the same things more effectively but also allowed me to do things I hadn t tried doing on a phone before such as watching TV. This isn t because of the phone being particularly special in any way, it s just that the change in size gives more possibilities for ways of using it. The Samsung Galaxy Mega is the largest smart phone. The 5.8 version of the Mega has a resolution of only 960*540 (less than the Note and Note 2 not good enough IMHO) and the 6.3 version has the same resolution as the Note 2 of 1280*720. I think that both Mega variants are too big for me, I need to be able to use a phone with one hand. So it seems that the Note 2 is probably the best phone for me right now.

7 July 2013

Raphael Geissert: Dealing with bashisms in proprietary software

Sometimes it happens that for one reason or another there's a need to use a proprietary application (read: can not be modified due to its licence) that contains bashisms. Since the application can not be modified and it might not be desirable to change the default /bin/sh, dealing with such applications can be a pain. Or not.

The switchsh program (available in Debian) by Marco d'Itri can be used to execute said application under a namespace where bash is bind-mounted on /bin/sh. The result:

$ sh --help
sh: Illegal option --
$ switchsh sh --help head -n1
GNU bash, version 4.1.5(1)-release-(i486-pc-linux-gnu)

Simple, yet handy.

2 July 2013

Ond&#345;ej &#268;ert&iacute;k: My impressions from the SciPy 2013 conference

I have attended the SciPy 2013 conference in Austin, Texas. Here are my impressions.

Number one is the fact that the IPython notebook was used by pretty much everyone. I use it a lot myself, but I didn't realize how ubiquitous it has become. It is quickly becoming the standard now. The IPython notebook is using Markdown and in fact it is better than Rest. The way to remember the "[]()" syntax for links is that in regular text you put links into () parentheses, so you do the same in Markdown, and append [] for the text of the link. The other way to remember is that [] feel more serious and thus are used for the text of the link. I stressed several times to +Fernando Perez and +Brian Granger how awesome it would be to have interactive widgets in the notebook. Fortunately that was pretty much preaching to the choir, as that's one of the first things they plan to implement good foundations for and I just can't wait to use that.

It is now clear, that the IPython notebook is the way to store computations that I want to share with other people, or to use it as a "lab notebook" for myself, so that I can remember what exactly I did to obtain the results (for example how exactly I obtained some figures from raw data). In other words --- instead of having sets of scripts and manual bash commands that have to be executed in particular order to do what I want, just use IPython notebook and put everything in there.

Number two is that how big the conference has become since the last time I attended (couple years ago), yet it still has the friendly feeling. Unfortunately, I had to miss a lot of talks, due to scheduling conflicts (there were three parallel sessions), so I look forward to seeing them on video.

+Aaron Meurer and I have done the SymPy tutorial (see the link for videos and other tutorial materials). It's been nice to finally meet +Matthew Rocklin (very active SymPy contributor) in person. He also had an interesting presentation
about symbolic matrices + Lapack code generation. +Jason Moore presented PyDy.
It's been a great pleasure for us to invite +David Li (still a high school student) to attend the conference and give a presentation about his work on sympygamma.com and live.sympy.org.

It was nice to meet the Julia guys, +Jeff Bezanson and +Stefan Karpinski. I contributed the Fortran benchmarks on the Julia's website some time ago, but I had the feeling that a lot of them are quite artificial and not very meaningful. I think Jeff and Stefan confirmed my feeling. Julia seems to have quite interesting type system and multiple dispatch, that SymPy should learn from.

I met the VTK guys +Matthew McCormick and +Pat Marion. One of the keynotes was given by +Will Schroeder from Kitware about publishing. I remember him stressing to manage dependencies well as well as to use BSD like license (as opposed to viral licenses like GPL or LGPL). That opensource has pretty much won (i.e. it is now clear that that is the way to go).

I had great discussions with +Francesc Alted, +Andy Terrel, +Brett Murphy, +Jonathan Rocher, +Eric Jones, +Travis Oliphant, +Mark Wiebe, +Ilan Schnell, +St fan van der Walt, +David Cournapeau, +Anthony Scopatz, +Paul Ivanov, +Michael Droettboom, +Wes McKinney, +Jake Vanderplas, +Kurt Smith, +Aron Ahmadia, +Kyle Mandli, +Benjamin Root and others.


It's also been nice to have a chat with +Jason Vertrees and other guys from Schr dinger.

One other thing that I realized last week at the conference is that pretty much everyone agreed on the fact that NumPy should act as the default way to represent memory (no matter if the array was created in Fortran or other code) and allow manipulations on it. Faster libraries like Blaze or ODIN should then hook themselves up into NumPy using multiple dispatch. Also SymPy would then hook itself up so that it can be used with array operations natively. Currently SymPy does work with NumPy (see our tests for some examples what works), but the solution is a bit fragile (it is not possible to override NumPy behavior, but because NumPy supports general objects, we simply give it SymPy objects and things mostly work).

Similar to this, I would like to create multiple dispatch in SymPy core itself, so that other (faster) libraries for symbolic manipulation can hook themselves up, so that their own (faster) multiplication, expansion or series expansion would get called instead of the SymPy default one implemented in pure Python.

Other blog posts from the conference:

22 June 2013

Justus Winter: My first week and some promising though hacky results

Hi Planet Debian :) my name is Justus Winter, I'm a computer science student at the University of Hamburg. I'm participating in the GSOC 2013, my task is to make Debian/Hurd systems boot using the same initialization scripts Debian/Linux uses. I spent the community bonding period with some gsoc related administrative tasks, updating my development machine and getting reacquainted with the Hurd system. It was nice to see how far Debian/Hurd has come since my last "serious" encounter with it. I've setup a continuous build solution on one of my Hurd VMs and prepared a package repository. I'll post details once I have some packages to share. I built the hurd, sysvinit and ifupdown packages and dived into the interesting world of literate programming. I'm going to write about that when I start looking into the ifupdown related issues. But most importantly I started writing a tool to automate all the tasks I would do during my work that could possibly be automated. As I'm working on the boot process, it makes sense to use some kind of virtualization software so I can work in the comfort of my usual development environment. My virtualization solution of choice is qemu and I actually wrote a qemu based black-box test solution for a former employer once, so I already was familiar with qemu and wrapping my own code around it. Without further ado, here it is: https://bitbucket.org/teythoon/hurdtest Provided that you have golang installed, you can compile it easily:
teythoon@europa /tmp % export GOPATH= pwd 
teythoon@europa /tmp % go get bitbucket.org/teythoon/hurdtest
teythoon@europa /tmp % bin/hurdtest
Usage: hurdtest [options] <command> [<arguments...>]
Currently it has the following subcommands:
test
Starts a VM, logs in as root, tests the interaction with the VM, verifies that certain VFS locations are writable, tests the network connectivity, the DNS resolution and installs and runs the hello package.
update
Executes aptitude update && aptitude full-upgrade, reboots the system and runs the test subcommand. If successful, it commits the changes to the virtual disk and creates a snapshot.
overlay
Takes as argument the path to a directory that is copied to the VM, reboots the machine and runs the test subcommand.
The update command is nice because it allows me to keep the VM up to date while ensuring that the image remains usable, with respect to what the test command considers a usable state of a Debian system. I'd really like to get some suggestions on how to test the "health" of a Debian system. You can look at how the tests are implemented in test.go, it's quite easy to add more and more interesting tests, and you don't even have to clean up after them or worry about any side-effects as the changes are not committed to the virtual disk. This is hurdtest doing an update:
teythoon@europa ~/repos/hurd/hurd-tests % bin/hurdtest update
2013/06/22 19:59:45 starting kvm [-drives file=image.qcow2,cache=writeback,snapshot=on -serial unix:/tmp/285813369/serial -monitor unix:/tmp/285813369/monitor -nographic -m 512]
2013/06/22 19:59:45 Waiting for grub...
2013/06/22 19:59:46 Waiting for login prompt...
2013/06/22 20:00:05 Updating system
2013/06/22 20:02:52 Get: 1 http://www.local unstable InRelease [8279 B]
Get: 2 http://http.debian.net sid InRelease [205 kB]
Get: 3 http://ftp.debian-ports.org unreleased InRelease [23.9 kB]
[...]
Setting up perl (5.14.2-21) ...
Reading package lists...
Building dependency tree...
Reading state information...
Reading extended state information...
Initializing package states...
Reading task descriptions...
2013/06/22 20:02:52 Update successful. Snapshotting system...
2013/06/22 20:02:53 Rebooting system...
2013/06/22 20:02:54 Waiting for grub...
2013/06/22 20:02:59 Waiting for login prompt...
2013/06/22 20:03:16 Running main.testTrue...
2013/06/22 20:03:16 Running main.testFalse...
2013/06/22 20:03:17 Running main.testClean...
[...]
2013/06/22 20:03:18 Running main.testNetwork...
2013/06/22 20:03:18 Running main.testResolver...
2013/06/22 20:03:20 Running main.testAptitudeInstall...
2013/06/22 20:03:46 Test successful. Reverting system...
2013/06/22 20:03:48 Halting system...
2013/06/22 20:03:53 Committing changes...
2013/06/22 20:03:57 Creating snapshot...
2013/06/22 20:04:04 All done.
bin/hurdtest update  157.31s user 69.71s system 87% cpu 4:18.94 total
The overlay command implements my work flow. I can edit scripts or drop hacked up executables onto my VM and see the results without any manual intervention. There's the -interactive flag that does this in a loop, avoiding the VM startup time using qemu snapshots. With this I can apply an overlay and see the results of the test suite in about a minute on my system. From early experiments I knew that simply running /etc/rcS.d/S* prevented the system from booting correctly, so I figured my first task should be to figure out what went wrong there. Using my tool (and developing it in that process) and many iterations later I came up with a surprisingly small diff of scripts in the initscripts and utilities shipped with the hurd package. For your convenience here is a tarball that you can extract to the root of your Debian/Hurd installation to reproduce my results (of course I invite you to use my tool for that purpose):
% bin/hurdtest overlay test
2013/06/22 21:35:31 starting kvm [-drive file=image.qcow2,cache=writeback,snapshot=on -serial unix:/tmp/345188134/serial -monitor unix:/tmp/345188134/monitor -nographic -m 512]
2013/06/22 21:35:31 Waiting for grub...
2013/06/22 21:35:31 Waiting for login prompt...
2013/06/22 21:35:48 Creating tarball...
./
./etc/
./etc/hurd/
./etc/hurd/rc
./etc/init.d/
./etc/init.d/checkroot.sh
./etc/init.d/mountall.sh
./runme
./lib/
./lib/init/
./lib/init/mount-functions.sh
./sbin/
./sbin/swapon
./bin/
./bin/mount
2013/06/22 21:35:48 Extracting overlay...
2013/06/22 21:35:49 Rebooting system...
2013/06/22 21:35:49 Waiting for grub...
2013/06/22 21:35:55 Writing log to /tmp/bootlog-802006344
2013/06/22 21:35:55 Waiting for login prompt...
2013/06/22 21:36:20 Booting successful.
2013/06/22 21:36:20 Running main.testTrue...
2013/06/22 21:36:21 Running main.testFalse...
2013/06/22 21:36:21 Running main.testClean...
2013/06/22 21:36:21 Running anonymous function...
2013/06/22 21:36:22 Running anonymous function...
2013/06/22 21:36:22 Running main.testUname...
2013/06/22 21:36:22 Running main.testNetwork...
2013/06/22 21:36:22 Running main.testResolver...
2013/06/22 21:36:23 Running main.testAptitudeInstall...
bin/hurdtest overlay ../hurd-tests-old/test  44.20s user 20.01s system 82% cpu 1:17.94 total
And here is the boot log:
Loading GNU Mach ...
Loading the Hurd ...
GNU Mach 1.3.99-486
AT386 boot: physical memory map from 0x0 to 0x9f400
AT386 boot: physical memory map from 0x100000 to 0x1fffe000
AT386 boot: physical memory from 0x0 to 0x1fffe000
Enabling FXSR
pcibios_init : BIOS32 Service Directory structure at 0xfcff0
pcibios_init : BIOS32 Service Directory entry at 0xfc7ba
pcibios_init : PCI BIOS revision 2.10 entry at 0xfc78c
Probing PCI hardware.
ide: Intel 82371 PIIX3 (dual FIFO) DMA Bus Mastering IDE
    Controller on PCI bus 0 function 9
ide: BM-DMA feature is not enabled (BIOS), enabling
    ide0: BM-DMA at 0xc100-0xc107
    ide1: BM-DMA at 0xc108-0xc10f
hd0: got CHS=762/128/63 CTL=c8 from BIOS
hd0: QEMU HARDDISK, 3001MB w/256kB Cache, CHS=762/128/63, DMA
hd2: QEMU DVD-ROM, ATAPI CDROM drive
ide0 at 0x1f0-0x1f7,0x3f6 on irq 14
ide1 at 0x170-0x177,0x376 on irq 15
Floppy drive(s): fd0 is 1.44M
FDC 0 is a S82078B
probing scsi 0/22: advansys probing scsi 1/22: BusLogic probing scsi 2/22: UltraStor 14F/34F rev. 4.33.00  probing scsi 3/22: UltraStor 14F/24F/34F probing scsi 4/22: Adaptec 152x SCSI driver; $Revision: 1.1 $ probing scsi 5/22: Adaptec 1542 Invalid address for shpnt with 1542.
Invalid address for shpnt with 1542.
probing scsi 6/22: Adaptec 174x (EISA) probing scsi 7/22:  probing scsi 8/22: Always IN2000 probing scsi 9/22:  probing scsi 10/22:  probing scsi 11/22:  probing scsi 12/22: Trantor T128/T128F/T228 probing scsi 13/22: DTC 3180/3280  probing scsi 14/22: Tekram DC390(T) V1.11 Feb-05-1997 probing scsi 15/22:  probing scsi 16/22: ncr53c8xx - revision 2.5f.1 probing scsi 17/22: EATA (Extended Attachment) PIO driver probing scsi 18/22: Western Digital WD-7000 Failed initialization of WD-7000 SCSI card!
probing scsi 19/22: EATA/DMA 2.0x rev. 4.33.00  probing eata on 1f0EATA0: address 0x1f0 in use, skipping probe.
probing eata on 1c88probing eata on 2c88probing eata on 3c88probing eata on 4c88probing eata on 5c88probing eata on 6c88probing eata on 7c88probing eata on 8c88probing eata on 9c88probing eata on ac88probing eata on bc88probing eata on cc88probing eata on dc88probing eata on ec88probing eata on fc88probing eata on 170EATA0: address 0x170 in use, skipping probe.
probing eata on 230probing eata on 330probing scsi 20/22: AM53C974 probing scsi 21/22: Iomega parport ZIP drive ppa: Version 1.42
ppa: Probing port 03bc
ppa: Probing port 0378
ppa:     SPP port present
ppa:     PS/2 bidirectional port present
ppa: Probing port 0278
done
scsi : 0 hosts.
scsi : detected total.
Partition check (DOS partitions):
 hd0: hd0s1 hd0s2 < hd0s5 >
lpr0: at atbus0, port = 378, spl = 6, pic = 7.
module 0: ext2fs --readonly --multiboot-command-line=$ kernel-command-line  --host-priv-port=$ host-port  --device-master-port=$ device-port  --exec-server-task=$ exec-task  -T typed $ root  $(task-create) $(task-resume) module 1: exec /hurd/exec $(exec-task=task-create)                                                                                                                                                                           2 multiboot modules                                                                                                                                                                                                                    task loaded: ext2fs --readonly --multiboot-command-line=root=device:hd0s1 console=com0 --host-priv-port=1 --device-master-port=2 --exec-server-task=3 -T typed device:hd0s1
task loaded: exec /hurd/exec
start ext2fs: Hurd server bootstrap: ext2fs[device:hd0s1] exec init proc auth
Using makefile-style concurrent boot in runlevel S.
ERROR: could not open /proc/stat: No such file or directory
Activating swap...done.
Checking root file system...fsck from util-linux 2.20.1
hd2 : tray open or drive not ready
end_request: I/O error, dev 02:00, sector 0
ext2fs_check_if_mount: Can't check if filesystem is mounted due to missing mtab file while determining whether /dev/hd0s1 is mounted.
/dev/hd0s1: clean, 44328/181056 files, 288266/723200 blocks
done.
Cleaning up temporary files... /tmp.
mount: /run: Unknown device or filesystem
mount: /run/lock: Unknown device or filesystem
mount: /proc: Unknown device or filesystem
mount: /run/shm: Unknown device or filesystem
/etc/rcS.d/S06mtab.sh: 48: /etc/rcS.d/S06mtab.sh: cannot open /proc/mounts: No such file
Activating lvm and md swap...(default pager): Already paging to partition hd0s5!
done.
Checking file systems...fsck from util-linux 2.20.1
hd2 : tray open or drive not ready
end_request: I/O error, dev 02:00, sector 0
done.
Mounting local filesystems...mount: invalid option -- 'O'
Try  mount --help' or  mount --usage' for more information.
failed.
Activating swapfile swap...(default pager): Already paging to partition hd0s5!
done.
df: Warning: cannot read table of mounted file systems: No such file or directory
Cleaning up temporary files....
Configuring network interfaces...inetutils-ifconfig: invalid arguments
ifup: failed to open pid file /run/network/ifup-/dev/eth0.pid: No such file or directory
Internet Systems Consortium DHCP Client 4.2.2
Copyright 2004-2011 Internet Systems Consortium.
All rights reserved.
For info, please visit https://www.isc.org/software/dhcp/
can't create /var/lib/dhcp/dhclient./dev/eth0.leases: No such file or directory
Listening on Socket//dev/eth0
Sending on   Socket//dev/eth0
DHCPDISCOVER on /dev/eth0 to 255.255.255.255 port 67 interval 5
DHCPREQUEST on /dev/eth0 to 255.255.255.255 port 67
DHCPOFFER from 10.0.2.2
DHCPACK from 10.0.2.2
can't create /var/lib/dhcp/dhclient./dev/eth0.leases: No such file or directory
bound to 10.0.2.15 -- renewal in 36884 seconds.
done.
Cleaning up temporary files....
Setting up X socket directories... /tmp/.X11-unix /tmp/.ICE-unix.
Using makefile-style concurrent boot in runlevel 2.
Starting enhanced syslogd: rsyslogd.
Starting deferred execution scheduler: atd.
Starting periodic command scheduler: cron.
Starting system message bus: dbusFailed to set socket option"/var/run/dbus/system_bus_socket": Protocol not available.
Starting OpenBSD Secure Shell server: sshd.
GNU 0.3 (debian) (console)
login:
I know it isn't that pretty, but it yields a working Debian/Hurd system that is more like a Debian/Linux system. For example /dev/shm and /run ,/* are connected to a tmpfs translator. I think this is a rather encouraging first result. I added my findings to the list of open issues. Another nice thing about hurdtest is that it is not even Hurd specific (only a tiny bit GNU Mach specific). I'm going to make it work nicely with Debian/Linux and Debian/kFreeBSD, since this is a very handy tool for anyone hacking on the Debian boot process (and with some changes for any OS). If anyone tries it out, I'd love to get feedback and patches. The tool requires the guest to be configured to use the first serial console for grub, the kernel and the userspace. The password for the user root must be empty. The guest has to have a working network connection setup at boot time. I will provide a suitable image as soon as I devise a good way to zero-fill the free space on the virtual disk. Is there any better way than to fill the disk with a huge file containing zeros? Without doing that the image is too large even compressed with xz. So this was my first week working for Debian. Next week I will focus on getting patches for the hurd and initscripts package in shape, I need to add some functionality to the mount utility shipped with the hurd package. It provides a mount-like experience on the Hurd, on which binding a translator (e. g. /hurd/ext2fs) to a filesystem node is an operation that does not involve the kernel (GNU Mach) at all, and is in fact a operation that any unprivileged user may perform. That is one of the nice features the Hurd has, it empowers its users.

9 June 2013

Paul Tagliamonte: Automatically lint your packages with debuild.me

Over my time working with Debian packages, I've always been concerned that I have been missing catchable mistakes by not running all the static checking tools I could run. As a result, I've been interested in writing some code that automates this process, a place where I can push a package and come back a few hours later to check on the results. This is great, since it provides a slightly less scary interface to new packagers, and helps avoid thinking they've just been told off by a Developer. I've spent the time to actually write this code, and I've called it debuild.me. The code itself is in its fourth iteration, and is built up from a few core components. The client / server code (lucy and ethel) are quite interconnected, but firehose works great on it's own, and is a single, unified (and sane!) spec that is easy to hack with (or even on!). Hopefully, this means that our wrappers will be usable outside of debuild.me, which is a win for everyone. Backend Design The backend (lucy) was the first part I wanted to design. I made the decision (very early on) that everything was going to be 100% Python 3.3+. This lets me use some of the (frankly, sweet) tools in the stdlib. Since I've written this type of thing before (i've tried to write this tool many, many, many, many times before), so I had a rough sense of how I wanted to design the backend. Past iterations had suffered from and overly complex server half, so I decided to go ultra minimal with the design of debuild.me. <aside class="left"> You can find the code for the server (lucy) on my GitHub </aside> The backend watches a directory (using a simple inotify script) and processes .changes files as they come in. If the package is a source package, a set of jobs are triggered (such as lintian, build and desktop-file-validate), as well as a different set for binary packages (such as lintian, piuparts and adequite). Only people may upload source packages (without any debs) and only builders can upload binary packages (without source). The client and server talk using XML-RPC with BASIC HTTP auth. I'm going to (eventually) SSL secure the transport layer, but for now, this will work as a proof of concept. Since I tend to like to keep my codebase simple and straightforward, I've used MongoDB as Lucy's DB. This lets me move between documents in Mongo to Python objects without any trouble. In addition, I evaluated some of the queue code out there (ZMQ, etc), and they all seemed like overkill for my problem, and had a hard time keeping track of jobs that (must never!) get lost. As a result, I wrote my own (very simple) job queue in Mongo, which has no sense of scheduling (at all), but can do it's job (and do it well). Jobs describe what's to be built with a link to the package document that the job relates to, and it's arch and suite (don't worry about the rest just yet). Jobs get assigned via natural sort on it's UUID based _id, and assigned to the first builder that can process it's arch / suite. Source packages are considered arch:all / suite:unstable (so they always get the most up-to-date linters on any arch that comes along). Lucy also allows for uploads to be given an X-Lucy-Group tag to manage which set of packages they're a part of. This comes in handy for doing partial archive rebuilds, or eventually using it to manage what jobs should be run on which uploads. This will allow me to run much more time-consuming tools for packages I want to review versus rebuilding to ensure packages don't FTBFS or aren't adequite. Client Design The buildd client (ethel) talks with lucy via XML-RPC to get assigned new jobs, release old jobs, close finished jobs, and upload package report data. When the etheld requests a new job, it also passes along what suites it knows of, which arches it can build, as well as what types it can run (stuff like lintian, build or cppcheck.) Lucy then assigns the builder to that job (so that we don't allocate the same job twice), and what time it was assigned at. <aside class="right"> You can find the code for the client (ethel) on my GitHub </aside> Ethel then takes the result of the job (in the form of a firehose.model tree) and transmits it over the line back to the Lucy server as a report (which also contains information on if the build failed or not), at which point lucy hands back a location (on the lucy host) that the daemon can write the log to. If the job was a binary build, the etheld process will dput the package to the server, with a special X-Lucy-Job tag to signal which job that build relates to, so that future lint runs can fetch the deb files that the build produced. Tooling Ethel runs a set of static checkers on the source code, which are basically fancy wrappers around the tools we all know and love (like lintian, desktop-file-validate, or piuparts) which output Firehose in place of home-grown stdout. This allows us to programmatically deal with the output of these tools in a normal and consistent way. <aside class="left"> You can read more about Firehose over in the Firehose README.rst </aside> Some of the more complex runners are made of 3 parts - a runner, wrapper and command. The server invokes the command routine, which invokes the runner (the command just provides a unified interface to all the runners), who's output gets parsed by the wrapper to turn it into a Firehose model tree. The goal here is that tons of very quick-running tools get run over a distributed network, and machine-readable reports get filed in a central location to aid in reviewing packages. Ricky In addition to the actual code to run builds, I've worked on a few tools to aid with using debuild.me for my DD related life. I have some uncommon use-cases that are nice to support. One such use-case is the ability to rebuild packages from the archive (unmodified) to check that they rebuild OK against the target. This is handy for things like arch:all packages that get uploaded (since they never get rebuilt on the buildd machines, and FTBFSs are sadly common) or packages that have had a Build-Dependency change on them. Ricky is able to create a .dsc url to your friendly local mirror, and fetch that exact version of the package. Ricky can then also use the .dsc (in a monumental hack) to forge a package_version_source.changes file, and sign it with an autobuild key and upload it to the debuild.me instance. Since it can also modify the .changes's target distribution, you can also use this to test if a package will build on stable or testing, unmodified. Fred Fred is a wrapper around Ricky, to help with fetching packages that may not exist yet. Fred also contains an email scraper to read off such lists as debian-devel-changes, and add an entry to fetch that upload when it becomes available on the local mirror, pass it to ricky, and allow debuild.me to rebuild new packages that match a set of criteria. I'm currently playing around with the idea of rebuilding all incoming Python packages to ensure they don't FTBFS in a clean chroot. Loofah Loofah is also another wrapper around Ricky, but for use manually. Loofah is able to sync down the apt Sources list, and place it in Mongo for fast queries. This than allows me to manually run rebuilds on any Source package that fits a set of critera (written in the form of a Mongo query), which get pulled and uploaded by Ricky. An example script to rebuild any packages that Build-Depend on python3-all-dev in Debian unstable / main would look like: <aside class="right"> You can find more queries in the Loofah examples </aside>
[
      "version": "unstable", "suite": "main"  ,
      "Build-Depends": "python3-all-dev"  
]
Or, a script to rebuild any package that depends on CDBS:
[
     ,
     "$or": [ "Build-Depends": "cdbs" ,
              "Build-Depends-Indep": "cdbs" ] 
]
You can use anything that exists in the Sources.gz file to query off of ( including Maintainer!) Future Work The future work on debuild.me will be centered around making it easier for buildd nodes to be added to the network, with more and more automation in that process (likely in the form of debs). I also want to add better control over the jobs, so that packages I upload only go to my personal servers. I'd also very much like to get better EC2 / Virtualization support integrated into the network, so that the buildd count grows with the queue size. This is a slightly hard problem that I'm keen to fix. I'm also considering moving the log parsing code out of the workers, so that the parsing code can be fixed without upgrading all the workers. This would also drop the Firehose dep on the client code, which would be nice. Migration from a debuild.me build into a local reprepro repo is something that would be fairly easy to do as well, likely to be done remotely via the XML-RPC interface, which calls a couple of reprepro commands (such as includedsc and includedeb) and publishes it to the user's repo. This is a nice use of the debs that get built, and could also allow debuild.me to be used like a PPA system, but this allows the user to not migrate packages that may contain piuparts issues.

8 June 2013

Michael Stapelberg: Survey answers part 1: systemd has too many dependencies, or it is bloated, or it does too many things, or is too complex

This blog post is the first of a series of posts dealing with the results of the Debian systemd survey. I intend to give a presentation at DebConf 2013, too, so you could either read my posts, or watch the talk, or both :-). The top concern shared by most people is:
systemd has too many dependencies, or it is bloated, or it does too many things, or is too complex
Now this concern actually has a lot of different facets, and I am trying to share my opinion on each of them. systemd has too many dependencies First, let s start with too many dependencies , because that is easy to check and reason about. I have created a document which lists all dependencies of the systemd binary itself (pid 1) and all the binaries which are currently shipped by the systemd Debian package. If you don t want to take my word for granted, please read that document. Have you read the document? Very nice! As you can see, the systemd binary itself has 10 dependencies (excluding libc). Now, the question is, what is bad about dependencies? Why do people list dependencies as a top concern?
  1. Cyclic dependencies. When you hear that your init system depends on DBus, you might argue that there is a cyclic dependency here, because DBus needs to be started by the init system. However, systemd does NOT depend on dbus-daemon (!) to boot your machine. Instead of using the system bus, it uses a private UNIX socket. Therefore, systemd uses DBus merely as a serialization format for IPC between its different processes. Only when you want to access systemd via its API as a user (non-root), you actually use the system bus. Since we are talking about DBus: DBus provides a well-tested serialization format and IPC mechanism so that systemd doesn t have to reinvent the wheel and instead benefits from wide support within languages.
  2. Complicated code. I feel like there is the implicit assumption that lots of dependencies correlate with complicated code that is easy to break. I encourage you to have a look at systemd s source code: look for the places where specific libraries are used, e.g. enforce_user which uses libcap. You ll notice that the code is not complex and usage of the libraries is clear.
  3. Software dragging in lots of library packages. The libraries which systemd uses are already in widespread use (e.g. DBus, udev, selinux, libcap, pcre, ). On a typical Debian installation, only very few of them will be dragged in by systemd, if at all. As an example, on a fresh Debian Wheezy installation, less than 10 packages will end up on your machine when running apt-get install systemd .
  4. More memory use. The Linux kernel maps libraries into memory only once, no matter how many processes use them. As stated in the dependency list, on machines where the libraries are not already loaded, systemd brings in about 500 KiB of additional memory-mapped libraries in the worst case. On the machines we have these days, this is a reasonable cost to pay for all the benefits systemd gets us. This holds true on embedded systems with only a few MiB of RAM and especially on typical workstations with 8+ GiB of RAM.
systemd is bloated Now, let s talk about bloat. Again, this is a point which has many facets. I d like to quote the Wikipedia definition of software bloat:
Software bloat is a process whereby successive versions of a computer program become perceptibly slower, use more memory or processing power, or have higher hardware requirements than the previous version whilst making only dubious user-perceptible improvements.
The first part of the definition certainly does not match systemd it is measurably faster than sysvinit. As for memory usage: systemd s RSS is 1.8 MiB, whereas sysvinit uses 0.8 MiB. As I argued on the More memory use point in the dependencies section, I think the additional resource cost is well worth the benefits. Also note that systemd s features are NOT all implemented in the binary which is PID 1. As explained in the dependency list, systemd consists of many cleanly separated binaries. So if a new version of systemd gathers an additional feature, this does not mean that your PID 1 will be bigger. While systemd runs on any hardware, it has an indirect hardware requirement: it requires some Linux kernel features (which are all enabled in Debian kernels). That might rule out usage of systemd on really old embedded hardware where you don t have a chance to update the kernel. While it is sad that those machines cannot profit from systemd, switching to systemd as a default has no downside either: Debian continues to support sysvinit for quite some time, so these machines will continue to work even with upcoming Debian versions. systemd does too many things The Wikipedia definition continues:
[ ] perceived bloat can occur from the software servicing a large, diverse marketplace with many differing requirements. Most end users will feel they only need some limited subset of the available functions and will regard the others as unnecessary bloat, even if people with different requirements do use them.
I think the last part of the Wikipedia definition applies to systemd: it does service a large and diverse marketplace . That marketplace is the entirety of existing software which is started by an init system. Also, systemd can be used on a wide range of hardware (embedded devices, tablets, phones, notebooks, desktops, servers) which requires different features. As an example: on a desktop system you typically don t care strongly about a watchdog feature, but on embedded or servers that feature is very handy. Similarly, on a tablet, forward secure sealing of logfiles is not as important as on a server. Therefore, I can understand if you feel that you don t need many of the features systemd provides. But please think of other users and maintainers who are very happy with systemd s benefits. Also note that while systemd supports many things (in separate binaries!), you don t have to use them all. It still makes sense to ship them all in the same package. Take coreutils as another example in that area. The binaries belong together, even though you most likely haven t used all of them (e.g. od, pr, ptx, :-)). systemd is too complex The remaining concern is that systemd is too complex. In my experience, complexity is often inherent to a specific area and one cannot simply make it go away. Instead, there are different models of how that complexity is represented. Think of the monolithic Linux kernel versus the MINIX microkernel. The latter has a very small amount of lines of source in the kernel, but puts the complexity into userspace. The former uses a different approach with more source in the kernel. The arguments between both camps show that neither is clearly right or clearly wrong. In a way, sysvinit represents the MINIX model: it has a small core (the init binary itself), but a lot of complexity in shell scripts and external programs. The fact that solutions are copied from one init script to another leads to lots of subtle errors and makes code reuse really hard. systemd however has more source code in the binaries, but requires only very simple, descriptive, textual configuration instead of complex init scripts. To me, it seems preferable to have the complexity in a single place instead of distributed across lots of people and projects. Conclusion In a way, you are right. systemd centralizes complexity from tons of init scripts into a single place. However, it therefore makes it very easy for maintainers to write service files (equivalent of an init script) and provides a consistent and reliable interface for service management. Furthermore, it is different than sysvinit, and different solutions often seem complex at first. While systemd consumes more resources than sysvinit, it uses them to make more information available about services; its finer-grained service management requires more state-keeping, but in turn offers you more control over your services.

31 May 2013

Julien Danjou: OpenStack Ceilometer Havana-1 milestone released

Yesterday, the first milestone of the Havana developement branch of Ceilometer has been released and is now available for testing and download. This means the first quarter of the OpenStack Havana development has passed! New features Ten blueprints have been implemented as you can see on the release page. I'm going to talk through some of them here, that are the most interesting for users. Ceilometer can now counts the scheduling attempt of instances done by nova-scheduler. This can be useful to eventually bill such information or for audit (implemented by me for eNovance).
People using the HBase backend can now do requests filtering on any of the counter fields, something we call metadata queries, and which was missing for this backend driver. Thanks to Shengjie Min (Dell) for the implementation. Counters can now be sent over UDP instead of the Oslo RPC mechanism (AMQP based by default). This allows counter transmission to be done in a much faster way, though less reliable. The primary use case being not audit or billing, but the alarming features that we are working on (implemented by me for eNovance).
The initial alarm API has been designed and implemented, thanks to Mehdi Abaakouk (eNovance) and Angus Salkled (RedHat) who tackled this. We're now able to do CRUD actions on these. Posting of meters via the HTTP API is now possible. This is now another conduct that can be used to publish and collector meter. Thanks to Angus Salkled (RedHat) for implementing this. I've been working on an somewhat experimental notifier driver for Oslo notification that publishes Ceilometer counters instead of the standard notification, using the Ceilometer pipeline setup. Sandy Walsh (Rackspace) has put in place the base needed to store raw notifications (events), with the final goal of bringing more functionnalities around these into Ceilometer. Obviously, all of this blueprint and bugfixes wouldn't be implemented or fixed without the harden eyes of our entire team, reviewing code and advising restlessly the developers. Thanks to them! Bug fixes Thirty-one bugs were fixed, though most of them might not interest you so I won't elaborate too much on that. Go read the list if you are curious. Toward Havana 2 We now have 21 blueprints targetting the Ceilometer's second Havana milestone, with some of them are already started. I'll try to make sure we'll get there without too much trouble for the 18th July 2013. Stay tuned!

Next.

Previous.