Search Results: "will"

10 October 2017

Iain R. Learmonth: Automatic Updates

We have instructions for setting up new Tor relays on Debian. The only time the word upgrade is mentioned here is:
Be sure to set your ContactInfo line so we can contact you if you need to upgrade or something goes wrong.
This isn t great. We should have some decent instructions for keeping your relay up to date too. I ve been compiling a set of documentation for enabling automatic updates on various Linux distributions, here s a taste of what I have so far:

Debian Make sure that unattended-upgrades is installed and then enable the installation of updates (as root):
apt install unattended-upgrades
dpkg-reconfigure -plow unattended-upgrades

Fedora 22 or later Beginning with Fedora 22, you can enable automatic updates via:
dnf install dnf-automatic
In /etc/dnf/automatic.conf set:
apply_updates = yes
Now enable and start automatic updates via:
systemctl enable dnf-automatic.timer
systemctl start dnf-automatic.timer
(Thanks to Enrico Zini I know all about these timer units in systemd now.)

RHEL or CentOS For CentOS, RHEL, and older versions of Fedora, the yum-cron package is the preferred approach:
yum install yum-cron
In /etc/yum/yum-cron.conf set:
apply_updates = yes
Enable and start automatic updates via:
systemctl start yum-cron.service

I d like to collect together instructions also for other distributions (and *BSD and Mac OS). Atlas knows which platform a relay is running on, so there could be a link in the future to some platform specific instructions on how to keep your relay up to date.

Lars Wirzenius: Debian and the GDPR

GDPR is a new EU regulation for privacy. The name is short for "General Data Protection Regulation" and it covers all organisations that handle personal data of EU citizens and EU residents. It will become enforceable May 25, 2018 (Towel Day). This will affect Debian. I think it's time for Debian to start working on compliance, mainly because the GDPR requires sensible things. I'm not an expert on GDPR legislation, but here's my understanding of what we in Debian should do: There's more, but let's start with those. I think Debian has at least the following systems that will need to be reviewed with regards to the GDPR: There may be more; these are just off the top of my head. I expect that mostly Debian will be OK, but we can't just assume that.

Reproducible builds folks: Reproducible Builds: Weekly report #128

Here's what happened in the Reproducible Builds effort between Sunday October 1 and Saturday October 7 2017: Media coverage Documentation updates Packages reviewed and fixed, and bugs filed Reviews of unreproducible packages 32 package reviews have been added, 46 have been updated and 62 have been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development strip-nondeterminism development Rob Browning noticed that strip-nondeterminism was causing serious performance regressions in the Clojure programming language within Debian. After some discussion, Chris Lamb also posted a query to debian-devel in case there were any other programming languages that might be suffering from the same problem. reprotest development Versions 0.7.1 and 0.7.2 were uploaded to unstable by Ximin Luo: It included contributions already covered by posts of the previous weeks, as well as new ones from: tests.reproducible-builds.org Misc. This week's edition was written by Bernhard M. Wiedemann, Chris Lamb, Holger Levsen, Mattia Rizzolo & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

9 October 2017

Vincent Fourmond: Define a function with inline Ruby code in QSoas

QSoas can read and execute Ruby code directly, while reading command files, or even at the command prompt. For that, just write plain Ruby code inside a ruby...ruby end block. Probably the most useful possibility is to define elaborated functions directly from within QSoas, or, preferable, from within a script; this is an alternative to defining a function in a completely separated Ruby-only file using ruby-run. For instance, you can define a function for plain Michaelis-Menten kinetics with a file containing:

ruby
def my_func(x, vm, km)
  return vm/(1 + km/x)
end
ruby end

This defines the function my_func with three parameters, , (vm) and (km), with the formula:

You can then test that the function has been correctly defined running for instance:

QSoas> eval my_func(1.0,1.0,1.0)
 => 0.5
QSoas> eval my_func(1e4,1.0,1.0)
 => 0.999900009999

This yields the correct answer: the first command evaluates the function with x = 1.0, vm = 1.0 and km = 1.0. For , the result is (here 0.5). For , the result is almost . You can use the newly defined my_func in any place you would use any ruby code, such as in the optional argument to generate-buffer, or for arbitrary fits:

QSoas> generate-buffer 0 10 my_func(x,3.0,0.6)
QSoas> fit-arb my_func(x,vm,km)

To redefine my_func, just run the ruby code again with a new definition, such as:
ruby
def my_func(x, vm, km)
  return vm/(1 + km/x**2)
end
ruby end
The previous version is just erased, and all new uses of my_func will refer to your new definition.


See for yourselfThe code for this example can be found there. Browse the qsoas-goodies github repository for more goodies !

About QSoasQSoas is a powerful open source data analysis program that focuses on flexibility and powerful fitting capacities. It is released under the GNU General Public License. It is described in Fourmond, Anal. Chem., 2016, 88 (10), pp 5050 5052. Current version is 2.1. You can download its source code or buy precompiled versions for MacOS and Windows there.

Markus Koschany: My Free Software Activities in September 2017

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games Debian Java Debian LTS This was my nineteenth month as a paid contributor and I have been paid to work 15,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Misc QA upload Thanks for reading and see you next time.

Ben Hutchings: Debian LTS work, September 2017

I was assigned 15 hours of work by Freexian's Debian LTS initiative and carried over 6 hours from August. I only worked 12 hours, so I will carry over 9 hours to the next month. I prepared and released another update on the Linux 3.2 longterm stable branch (3.2.93). I then rebased the Debian linux package onto this version, added further security fixes, and uploaded it (DLA-1099-1).

Michal Čihař: Better acess control in Weblate

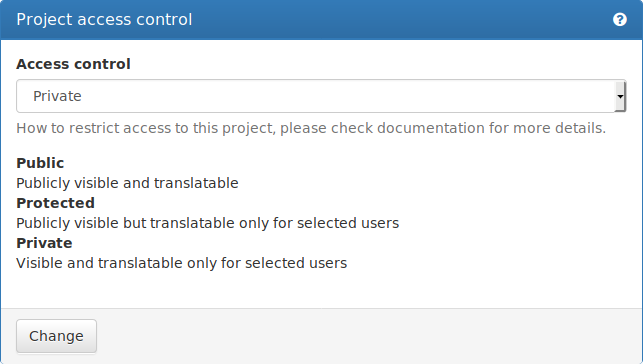
Upcoming Weblate 2.17 will bring improved access control settings. Previously this could be controlled only by server admins, but now the project visibility and access presets can be configured. This allows you to better tweak access control for your needs. There is additional choice of making the project public, but restricting translations, what has been requested by several projects. You can see the possible choices on the UI screenshot: Weblate overall experience On Hosted Weblate this feature is currently available only to commercial hosting customers. Projects hosted for free are limited to public visibility only.

Filed under: Debian English SUSE Weblate

Antonio Terceiro: pristine-tar updates

Introduction pristine-tar is a tool that is present in the workflow of a lot of Debian people. I adopted it last year after it has been orphaned by its creator Joey Hess. A little after that Tomasz Buchert joined me and we are now a functional two-person team. pristine-tar goals are to import the content of a pristine upstream tarball into a VCS repository, and being able to later reconstruct that exact same tarball, bit by bit, based on the contents in the VCS, so we don t have to store a full copy of that tarball. This is done by storing a binary delta files which can be used to reconstruct the original tarball from a tarball produced with the contents of the VCS. Ultimately, we want to make sure that the tarball that is uploaded to Debian is exactly the same as the one that has been downloaded from upstream, without having to keep a full copy of it around if all of its contents is already extracted in the VCS anyway. The current state of the art, and perspectives for the future pristine-tar solves a wicked problem, because our ability to reconstruct the original tarball is affected by changes in the behavior of tar and of all of the compression tools (gzip, bzip2, xz) and by what exact options were used when creating the original tarballs. Because of this, pristine-tar currently has a few embedded copies of old versions of compressors to be able to reconstruct tarballs produced by them, and also rely on a ever-evolving patch to tar that is been carried in Debian for a while. So basically keeping pristine-tar working is a game of Whac-A-Mole. Joey provided a good summary of the situation when he orphaned pristine-tar. Going forward, we may need to rely on other ways of ensuring integrity of upstream source code. That could take the form of signed git tags, signed uncompressed tarballs (so that the compression doesn t matter), or maybe even a different system for storing actual tarballs. Debian bug #871806 contains an interesting discussion on this topic. Recent improvements Even if keeping pristine-tar useful in the long term will be hard, too much of Debian work currently relies on it, so we can t just abandon it. Instead, we keep figuring out ways to improve. And I have good news: pristine-tar has recently received updates that improve the situation quite a bit. In order to be able to understand how better we are getting at it, I created a "visualization of the regression test suite results. With the help of data from there, let s look at the improvements made since pristine-tar 1.38, which was the version included in stretch. pristine-tar 1.39: xdelta3 by default. This was the first release made after the stretch release, and made xdelta3 the default delta generator for newly-imported tarballs. Existing tarballs with deltas produced by xdelta are still supported, this only affects new imports. The support for having multiple delta generator was written by Tomasz, and was already there since 1.35, but we decided to only flip the switch after using xdelta3 was supported in a stable release. pristine-tar 1.40: improved compression heuristics pristine-tar uses a few heuristics to produce the smaller delta possible, and this includes trying different compression options. In the release Tomasz included a contribution by Lennart Sorensen to also try the --gnu, which gretly improved the support for rsyncable gzip compressed files. We can see an example of the type of improvement we got in the regression test suite data for delta sizes for faad2_2.6.1.orig.tar.gz: In 1.40, the delta produced from the test tarball faad2_2.6.1.orig.tar.gz went down from 800KB, almost the same size of tarball itself, to 6.8KB pristine-tar 1.41: support for signatures This release saw the addition of support for storage and retrieval of upstream signatures, contributed by Chris Lamb. pristine-tar 1.42: optionally recompressing tarballs I had this idea and wanted to try it out: most of our problems reproducing tarballs come from tarballs produced with old compressors, or from changes in compressor behavior, or from uncommon compression options being used. What if we could just recompress the tarballs before importing then? Yes, this kind of breaks the pristine bit of the whole business, but on the other hand, 1) the contents of the tarball are not affected, and 2) even if the initial tarball is not bit by bit the same that upstream release, at least future uploads of that same upstream version with Debian revisions can be regenerated just fine. In some cases, as the case for the test tarball util-linux_2.30.1.orig.tar.xz, recompressing is what makes it possible to reproduce the tarball (and thus import it with pristine-tar) possible at all: util-linux_2.30.1.orig.tar.xz can only be imported after being recompressed In other cases, if the current heuristics can t produce a reasonably small delta, recompressing makes a huge difference. It s the case for mumble_1.1.8.orig.tar.gz: with recompression, the delta produced from mumble_1.1.8.orig.tar.gz goes from 1.2MB, or 99% of the size to the original tarball, to 14.6KB, 1% of the size of original tarball Recompressing is not enabled by default, and can be enabled by passing the --recompress option. If you are using pristine-tar via a wrapper tool like gbp-buildpackage, you can use the $PRISTINE_TAR environment variable to set options that will affect any pristine-tar invocations. Also, even if you enable recompression, pristine-tar will only try it if the delta generations fails completely, of if the delta produced from the original tarball is too large. You can control what too large means by using the --recompress-threshold-bytes and --recompress-threshold-percent options. See the pristine-tar(1) manual page for details.

Michal Čihař: stardicter 1.1

Stardicter 1.1, the set of scripts to convert some freely available dictionaries to StarDict format, has been released today. The biggest change is that it will also keep source data together with generated dictionaries. This is good for licensing reasons and will also allow to actually build these as packages within Debian. Full list of changes: As usual, you can install from pip, download source or download generated dictionaries from my website. The package should be soon available in Debian as well.

Filed under: Debian English StarDict

Gunnar Wolf: Achievement unlocked - Made with Creative Commons translated to Spanish! (Thanks, @xattack!)

I am very, very, very happy to report this And I cannot believe we have achieved this so fast: Back in June, I announced I'd start working on the translation of the Made with Creative Commons book into Spanish. Over the following few weeks, I worked out the most viable infrastructure, gathered input and commitments for help from a couple of friends, submitted my project for inclusion in the Hosted Weblate translations site (and got it approved!) Then, we quietly and slowly started working. Then, as it usually happens in late August, early September... The rush of the semester caught me in full, and I left this translation project for later For the next semester, perhaps... Today, I received a mail that surprised me. That stunned me. 99% of translated strings! Of course, it does not look as neat as "100%" would, but there are several strings not to be translated. So, yay for collaborative work! Oh, and FWIW Thanks to everybody who helped. And really, really, really, hats off to Luis Enrique Amaya, a friend whom I see way less than I should. A LIDSOL graduate, and a nice guy all around. Why to him specially? Well... This has several wrinkles to iron out, but, by number of translated lines: ...Need I say more? Luis, I hope you enjoyed reading the book :-] There is still a lot of work to do, and I'm asking the rest of the team some days so I can get my act together. From the mail I just sent, I need to:
  1. Review the Pandoc conversion process, to get the strings formatted again into a book; I had got this working somewhere in the process, but last I checked it broke. I expect this not to be too much of a hurdle, and it will help all other translations.
  2. Start the editorial process at my Institute. Once the book builds, I'll have to start again the stylistic correction process so the Institute agrees to print it out under its seal. This time, we have the hurdle that our correctors will probably hate us due to part of the work being done before we had actually agreed on some important Spanish language issues... which are different between Mexico, Argentina and Costa Rica (where translators are from). Anyway This sets the mood for a great start of the week. Yay!
AttachmentSize
Screenshot from 2017-10-08 20-55-30.png103.1 KB

8 October 2017

Joachim Breitner: e.g. in TeX

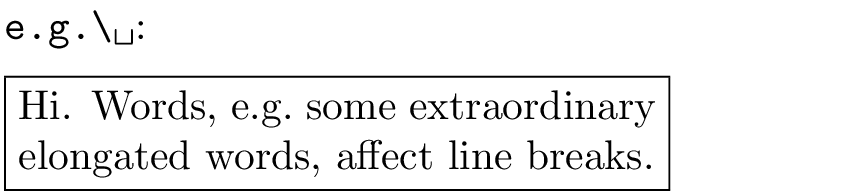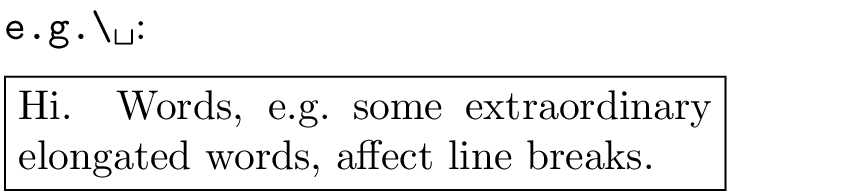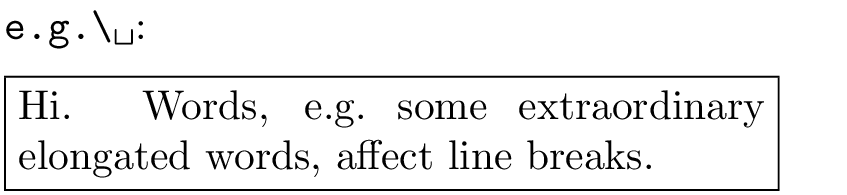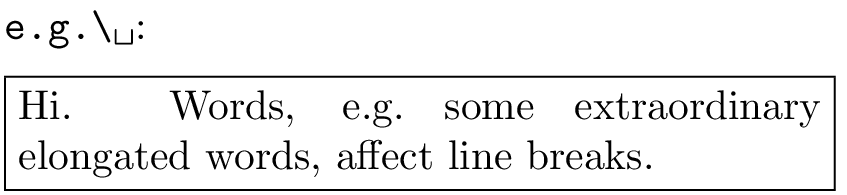
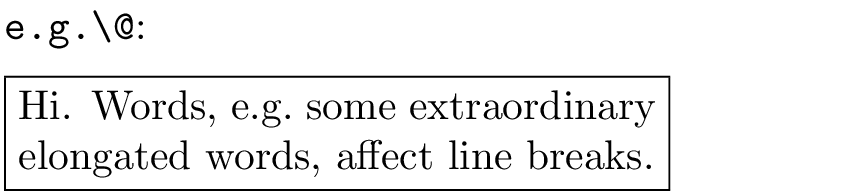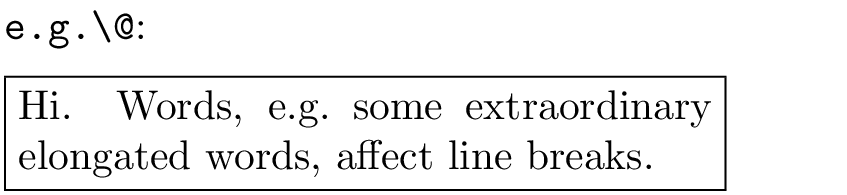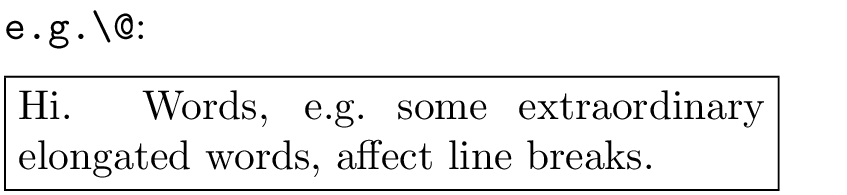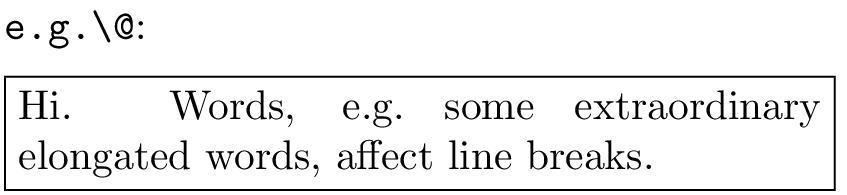
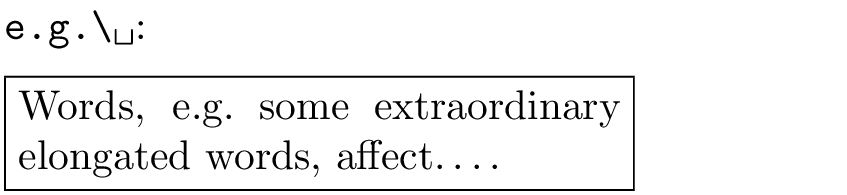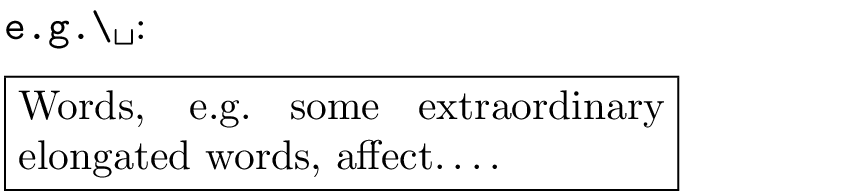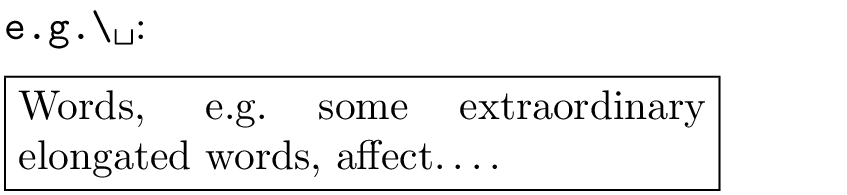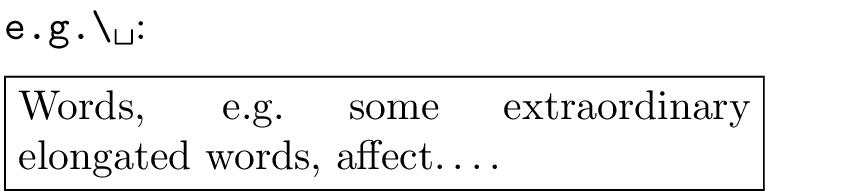
When I learned TeX, I was told to not write e.g. something, because TeX would think the period after the g ends a sentence, and introduce a wider, inter-sentence space. Instead, I was to write e.g.\ . Years later, I learned from a convincing, but since forgotten source, that in fact e.g.\@ is the proper thing to write. I vaguely remembering that e.g.\ supposedly affected the inter-word space in some unwanted way. So I did that for many years. Until I recently was called out for doing it wrong, and that infact e.g.\ is the proper way. This was supported by a StackExchange answer written by a LaTeX authority and backed by a reference to documentation. The same question has, however, another answer by another TeX authority, backed by an analysis of the implementation, which concludes that e.g.\@ is proper. What now? I guess I just have to find it out myself.
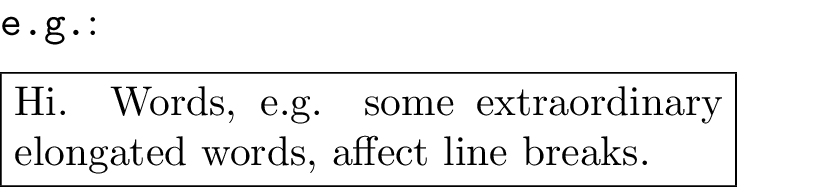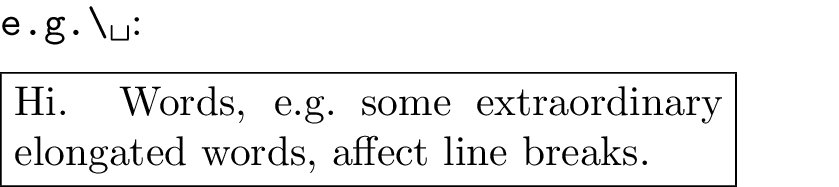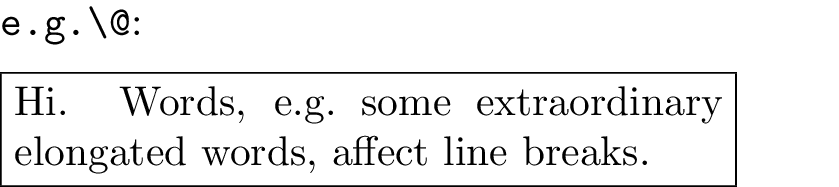
The problem and two solutions

The problem and two solutions

The above image shows three variants: The obviously broken version with e.g., and the two contesting variants to fix it. Looks like they yield equal results! So maybe the difference lies in how \@ and \ react when the line length changes, and the word wrapping require differences in the inter-word spacing. Will there be differences? Let s see;
Expanding whitespace, take 1

Expanding whitespace, take 1

Expanding whitespace, take 2

Expanding whitespace, take 2

I cannot see any difference. But the inter-sentence whitespace ate most of the expansion. Is there a difference visible if we have only inter-word spacing in the line?
Expanding whitespace, take 3

Expanding whitespace, take 3

Expanding whitespace, take 4

Expanding whitespace, take 4

Again, I see the same behaviour. Conclusion: It does not matter, but e.g.\ is less hassle when using lhs2tex than e.g.\@ (which has to be escaped as e.g.\@@), so the winner is e.g.\ ! (Unless you put it in a macro, then \@ might be preferable, and it is still needed between a captial letter and a sentence period.)

Daniel Pocock: A step change in managing your calendar, without social media

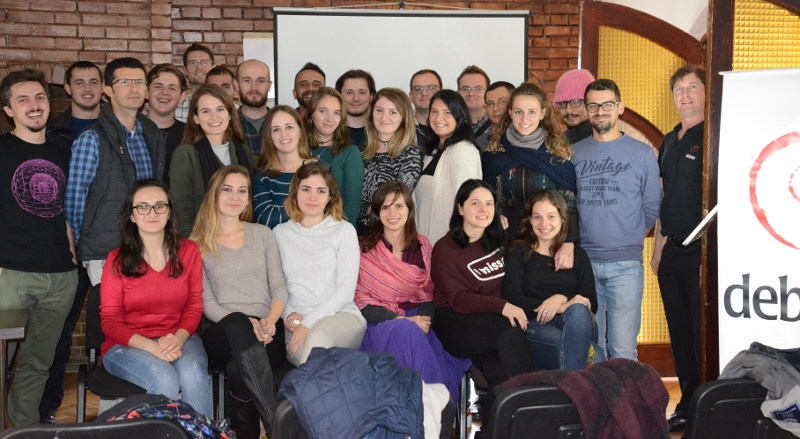
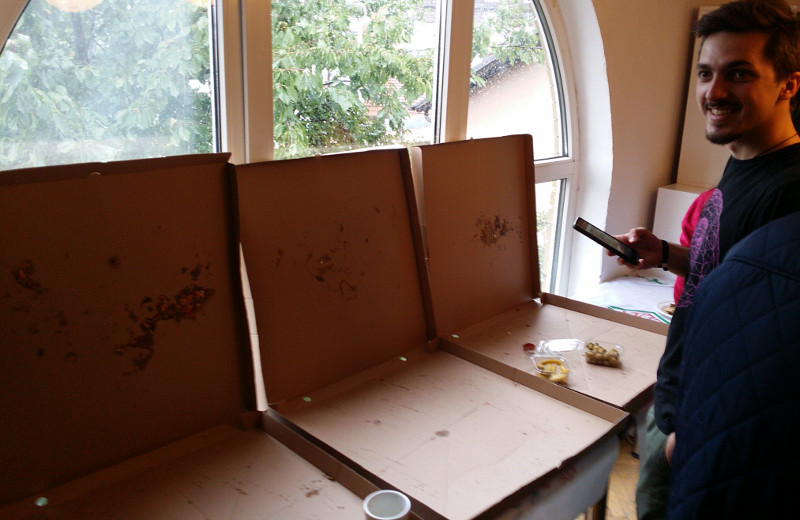
Have you been to an event recently involving free software or a related topic? How did you find it? Are you organizing an event and don't want to fall into the trap of using Facebook or Meetup or other services that compete for a share of your community's attention? Are you keen to find events in foreign destinations related to your interest areas to coincide with other travel intentions? Have you been concerned when your GSoC or Outreachy interns lost a week of their project going through the bureaucracy to get a visa for your community's event? Would you like to make it easier for them to find the best events in the countries that welcome and respect visitors? In many recent discussions about free software activism, people have struggled to break out of the illusion that social media is the way to cultivate new contacts. Wouldn't it be great to make more meaningful contacts by attending more a more diverse range of events rather than losing time on social media? Making it happen There are already a number of tools (for example, Drupal plugins and Wordpress plugins) for promoting your events on the web and in iCalendar format. There are also a number of sites like Agenda du Libre and GriCal who aggregate events from multiple communities where people can browse them. How can we take these concepts further and make a convenient, compelling and global solution? Can we harvest event data from a wide range of sources and compile it into a large database using something like PostgreSQL or a NoSQL solution or even a distributed solution like OpenDHT? Can we use big data techniques to mine these datasources and help match people to events without compromising on privacy? Why not build an automated iCalendar "to-do" list of deadlines for events you want to be reminded about, so you never miss the deadlines for travel sponsorship or submitting a talk proposal? I've started documenting an architecture for this on the Debian wiki and proposed it as an Outreachy project. It will also be offered as part of GSoC in 2018. Ways to get involved If you would like to help this project, please consider introducing yourself on the debian-outreach mailing list and helping to mentor or refer interns for the project. You can also help contribute ideas for the specification through the mailing list or wiki. Mini DebConf Prishtina 2017 This weekend I've been at the MiniDebConf in Prishtina, Kosovo. It has been hosted by the amazing Prishtina hackerspace community. Watch out for future events in Prishtina, the pizzas are huge, but that didn't stop them disappearing before we finished the photos:
Iain R. Learmonth: Tor Relays on Twitter

A while ago I played with a Twitter bot that would track radio amateurs using a packet radio position reporting system, tweet their location and a picture from Flickr that was taken near to their location and a link to their packet radio activity on aprs.fi. It s really not that hard to put these things together and they can be a lot of fun. The tweets looked like this: This isn t about building a system that serves any critical purpose, it s about fun. As the radio stations were chosen essentially at random, there could be some cool things showing up that you wouldn t otherwise have seen. Maybe you d spot a callsign of a station you ve spoken to before on HF or perhaps you d see stations in areas near you or in cool places. On Friday evening I took a go at hacking together a bot for Tor relays. The idea being to have regular snippets of information from the Tor network and perhaps you ll spot something insightful or interesting. Not every tweet is going to be amazing, but it wasn t running for very long before I spotted a relay very close to its 10th birthday: The relays are chosen at random, and tweet templates are chosen at random too. So far, tweets about individual relays can be about age or current bandwidth contribution to the Tor network. There are also tweets about how many relays run in a particular autonomous system (again, chosen at random) and tweets about the total number of relays currently running. The total relays tweets come with a map: The maps are produced using xplanet. The Earth will rotate to show the current side in daylight at the time the tweet is posted. Unfortunately, the bot currently cannot tweet as the account has been suspended. You should still be able to though and tweets will begin appearing again once I ve resolved the suspension. I plan to rewrite the mess of cron-activated Python scripts into a coherent Python (maybe Java) application and publish the sources soon. There are also a number of new templates for tweets I d like to explore, including number of relays and bandwidth contributed per family and statistics on operating system diversity. Update (2017-10-08): The @TorAtlas account should now be unsuspended.

5 October 2017

Ross Gammon: My FOSS activities for August & September 2017

I am writing this from my hotel room in Bologna, Italy before going out for a pizza. After a successful Factory Acceptance Test today, I might also allow myself to celebrate with a beer. But anyway, here is what I have been up to in the FLOSS world for the last month and a bit. Debian
  • Uploaded gramps (4.2.6) to stretch-backports & jessie-backports-sloppy.
  • Started working on the latest release of node-tmp. It needs further work due to new documentation being included etc.
  • Started working on packaging the latest goocanvas-2.0 package. Everything is ready except for producing some autopkgtests.
  • Moved node-coffeeify experimental to unstable.
  • Updated the Multimedia Blends Tasks with all the latest ITPs etc.
  • Reviewed doris for Antonio Valentino, and sponsored it for him.
  • Reviewed pyresample for Antonio Valentino, and sponsored it for him.
  • Reviewed a new parlatype package for Gabor Karsay, and sponsored it for him.
Ubuntu
  • Successfully did my first merge using git-ubuntu for the Qjackctl package. Thanks to Nish for patiently answering my questions, reviewing my work, and sponsoring the upload.
  • Refreshed the gramps backport request to 4.2.6. Still no willing sponsor.
  • Tested Len s rewrite of ubuntustudio-controls, adding a CPU governor option in particular. There are a couple of minor things to tidy up, but we have probably missed the chance to get it finalised for Artful.
  • Tested the First Beta release of Ubuntu Studio 17.10 Artful and wrote the release notes. Also drafted my first release announcement on the Ubunti Studio website which Eylul reviewed and published.
  • Refreshed the ubuntustudio-meta package and requested sponsorship. This was done by Steve Langasek. Thanks Steve.
  • Tested the Final Beta release of Ubuntu Studio 17.10 Artful and wrote the release notes.
  • Started working on a new Carla package, starting from where V ctor Cuadrado Juan left it (ITP in Debian).

Wouter Verhelst: Patching Firefox

At work, I help maintain a smartcard middleware that is provided to Belgian citizens who want to use their electronic ID card to, e.g., log on to government websites. This middleware is a piece of software that hooks into various browsers and adds a way to access the smartcard in question, through whatever APIs the operating system and the browser in question provide for that purpose. The details of how that is done differ between each browser (and in the case of Google Chrome, for the same browser between different operating systems); but for Firefox (and Google Chrome on free operating systems), this is done by way of a PKCS#11 module. For Firefox 57, mozilla decided to overhaul much of their browser. The changes are large and massive, and in some ways revolutionary. It's no surprise, therefore, that some of the changes break compatibility with older things. One of the areas in which breaking changes were made is in the area of extensions to the browser. Previously, Firefox had various APIs available for extensions; right now, all APIs apart from the WebExtensions API are considered "legacy" and support for them will be removed from Firefox 57 going forward. Since installing a PKCS#11 module manually is a bit complicated, and since the legacy APIs provided a way to do so automatically provided the user would first install an add-on (or provided the installer of the PKCS#11 module sideloads it), most parties who provide a PKCS#11 module for use with Firefox will provide an add-on to automatically install it. Since the alternative involves entering the right values in a dialog box that's hidden away somewhere deep in the preferences screen, the add-on option is much more user friendly. I'm sure you can imagine my dismay when I found out that there was no WebExtensions API to provide the same functionality. So, after asking around a bit, I filed bug 1357391 to get a discussion started. While it took some convincing initially to get people to understand the reasons for wanting such an API, eventually the bug was assigned the "P5" priority -- essentially, a "we understand the need and won't block it, but we don't have the time to implement it. Patches welcome, though" statement. Since having an add-on was something that work really wanted, and since I had the time, I got the go-ahead from management to look into implementing the required code myself. I made it obvious rather quickly that my background in Firefox was fairly limited, though, and so was assigned a mentor to help me through the process. Having been a Debian Developer for the past fifteen years, I do understand how to develop free software. Yet, the experience was different enough that still learned some new things about free software development, which was somewhat unexpected. Unfortunately, the process took much longer than I had hoped, which meant that the patch was not ready by the time Firefox 57 was branched off mozilla's "central" repository. The result of that is that while my patch has been merged into what will eventually become Firefox 58, it looks strongly as though it won't make it into Firefox 57. That's going to cause some severe headaches, which I'm not looking forward to; and while I can certainly understand the reasons for not wanting to grant the exception for the merge into 57, I can't help but feeling like this is a missed opportunity. Anyway, writing code for the massive Open Source project that mozilla is has been a load of fun, and in the process I've learned a lot -- not only about Open Source development in general, but also about this weird little thing that Javascript is. That might actually be useful for this other project that I've got running here. In closing, I'd like to thank Tomislav 'zombie' Jovanovic for mentoring me during the whole process, without whom it would have been doubtful if I would even have been ready by now. Apologies for any procedural mistakes I've made, and good luck in your future endeavours! :-)

4 October 2017

Norbert Preining: Einstein and Freud s letters on Why War? 85th anniversary

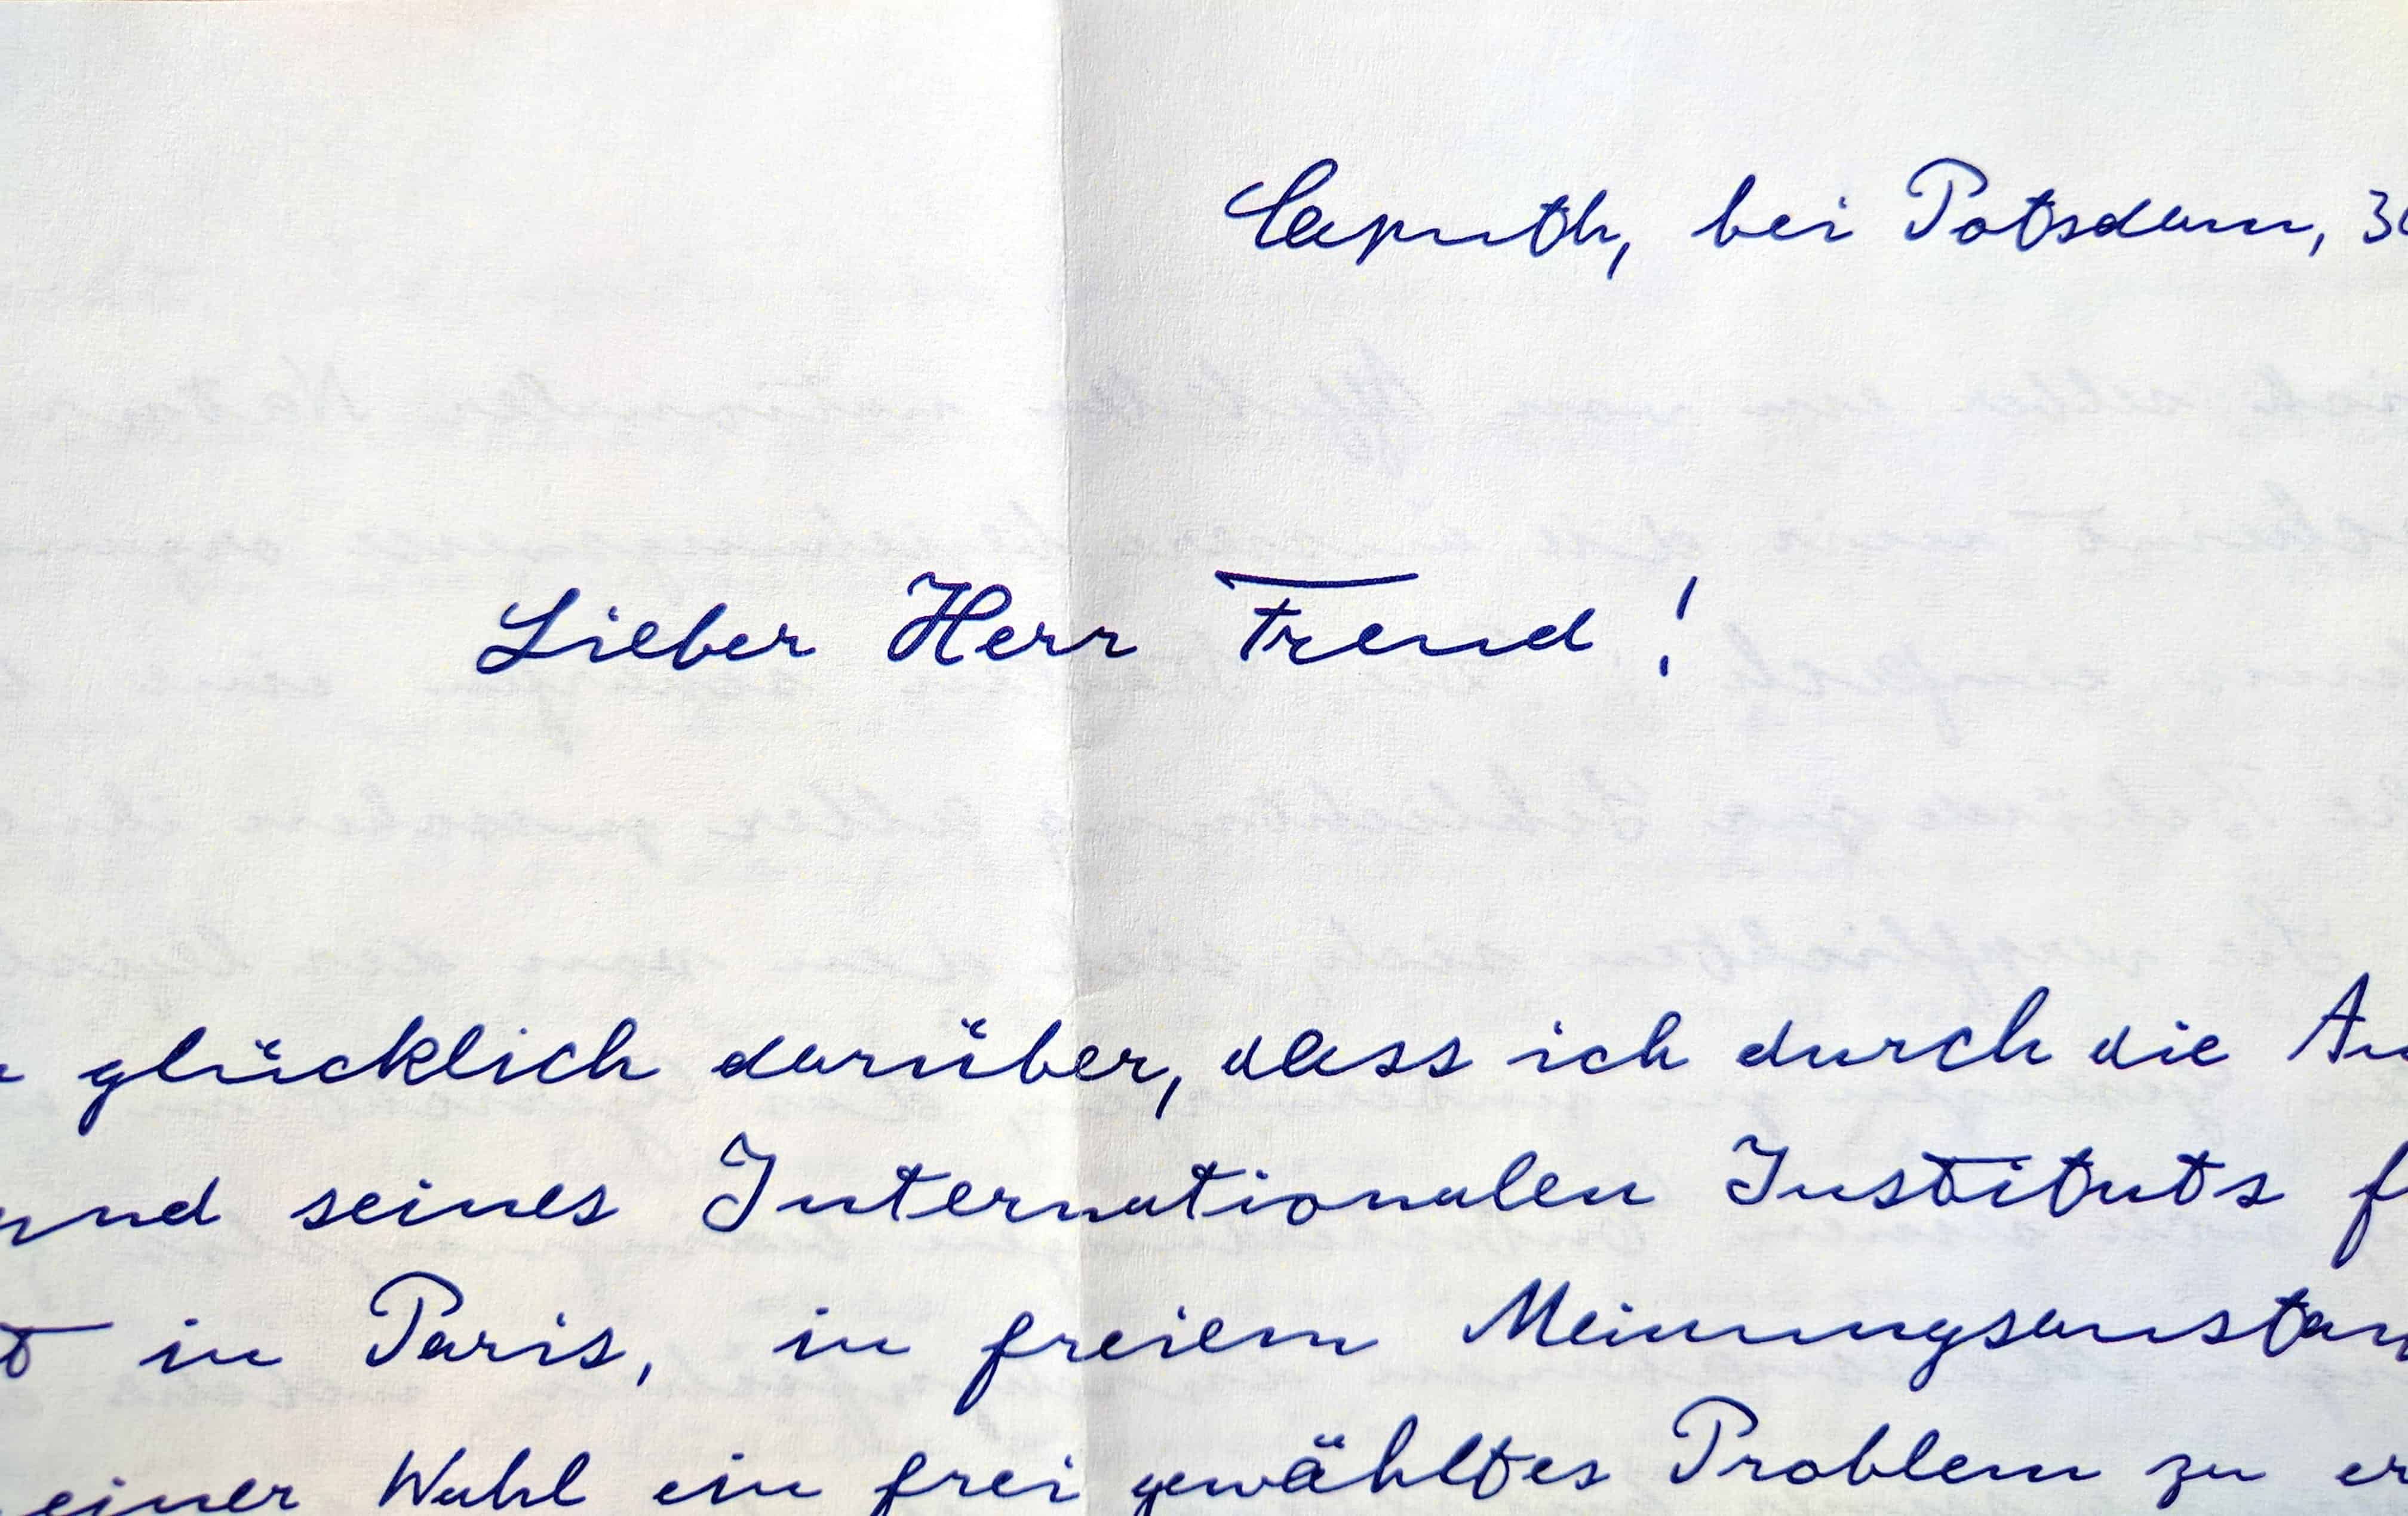
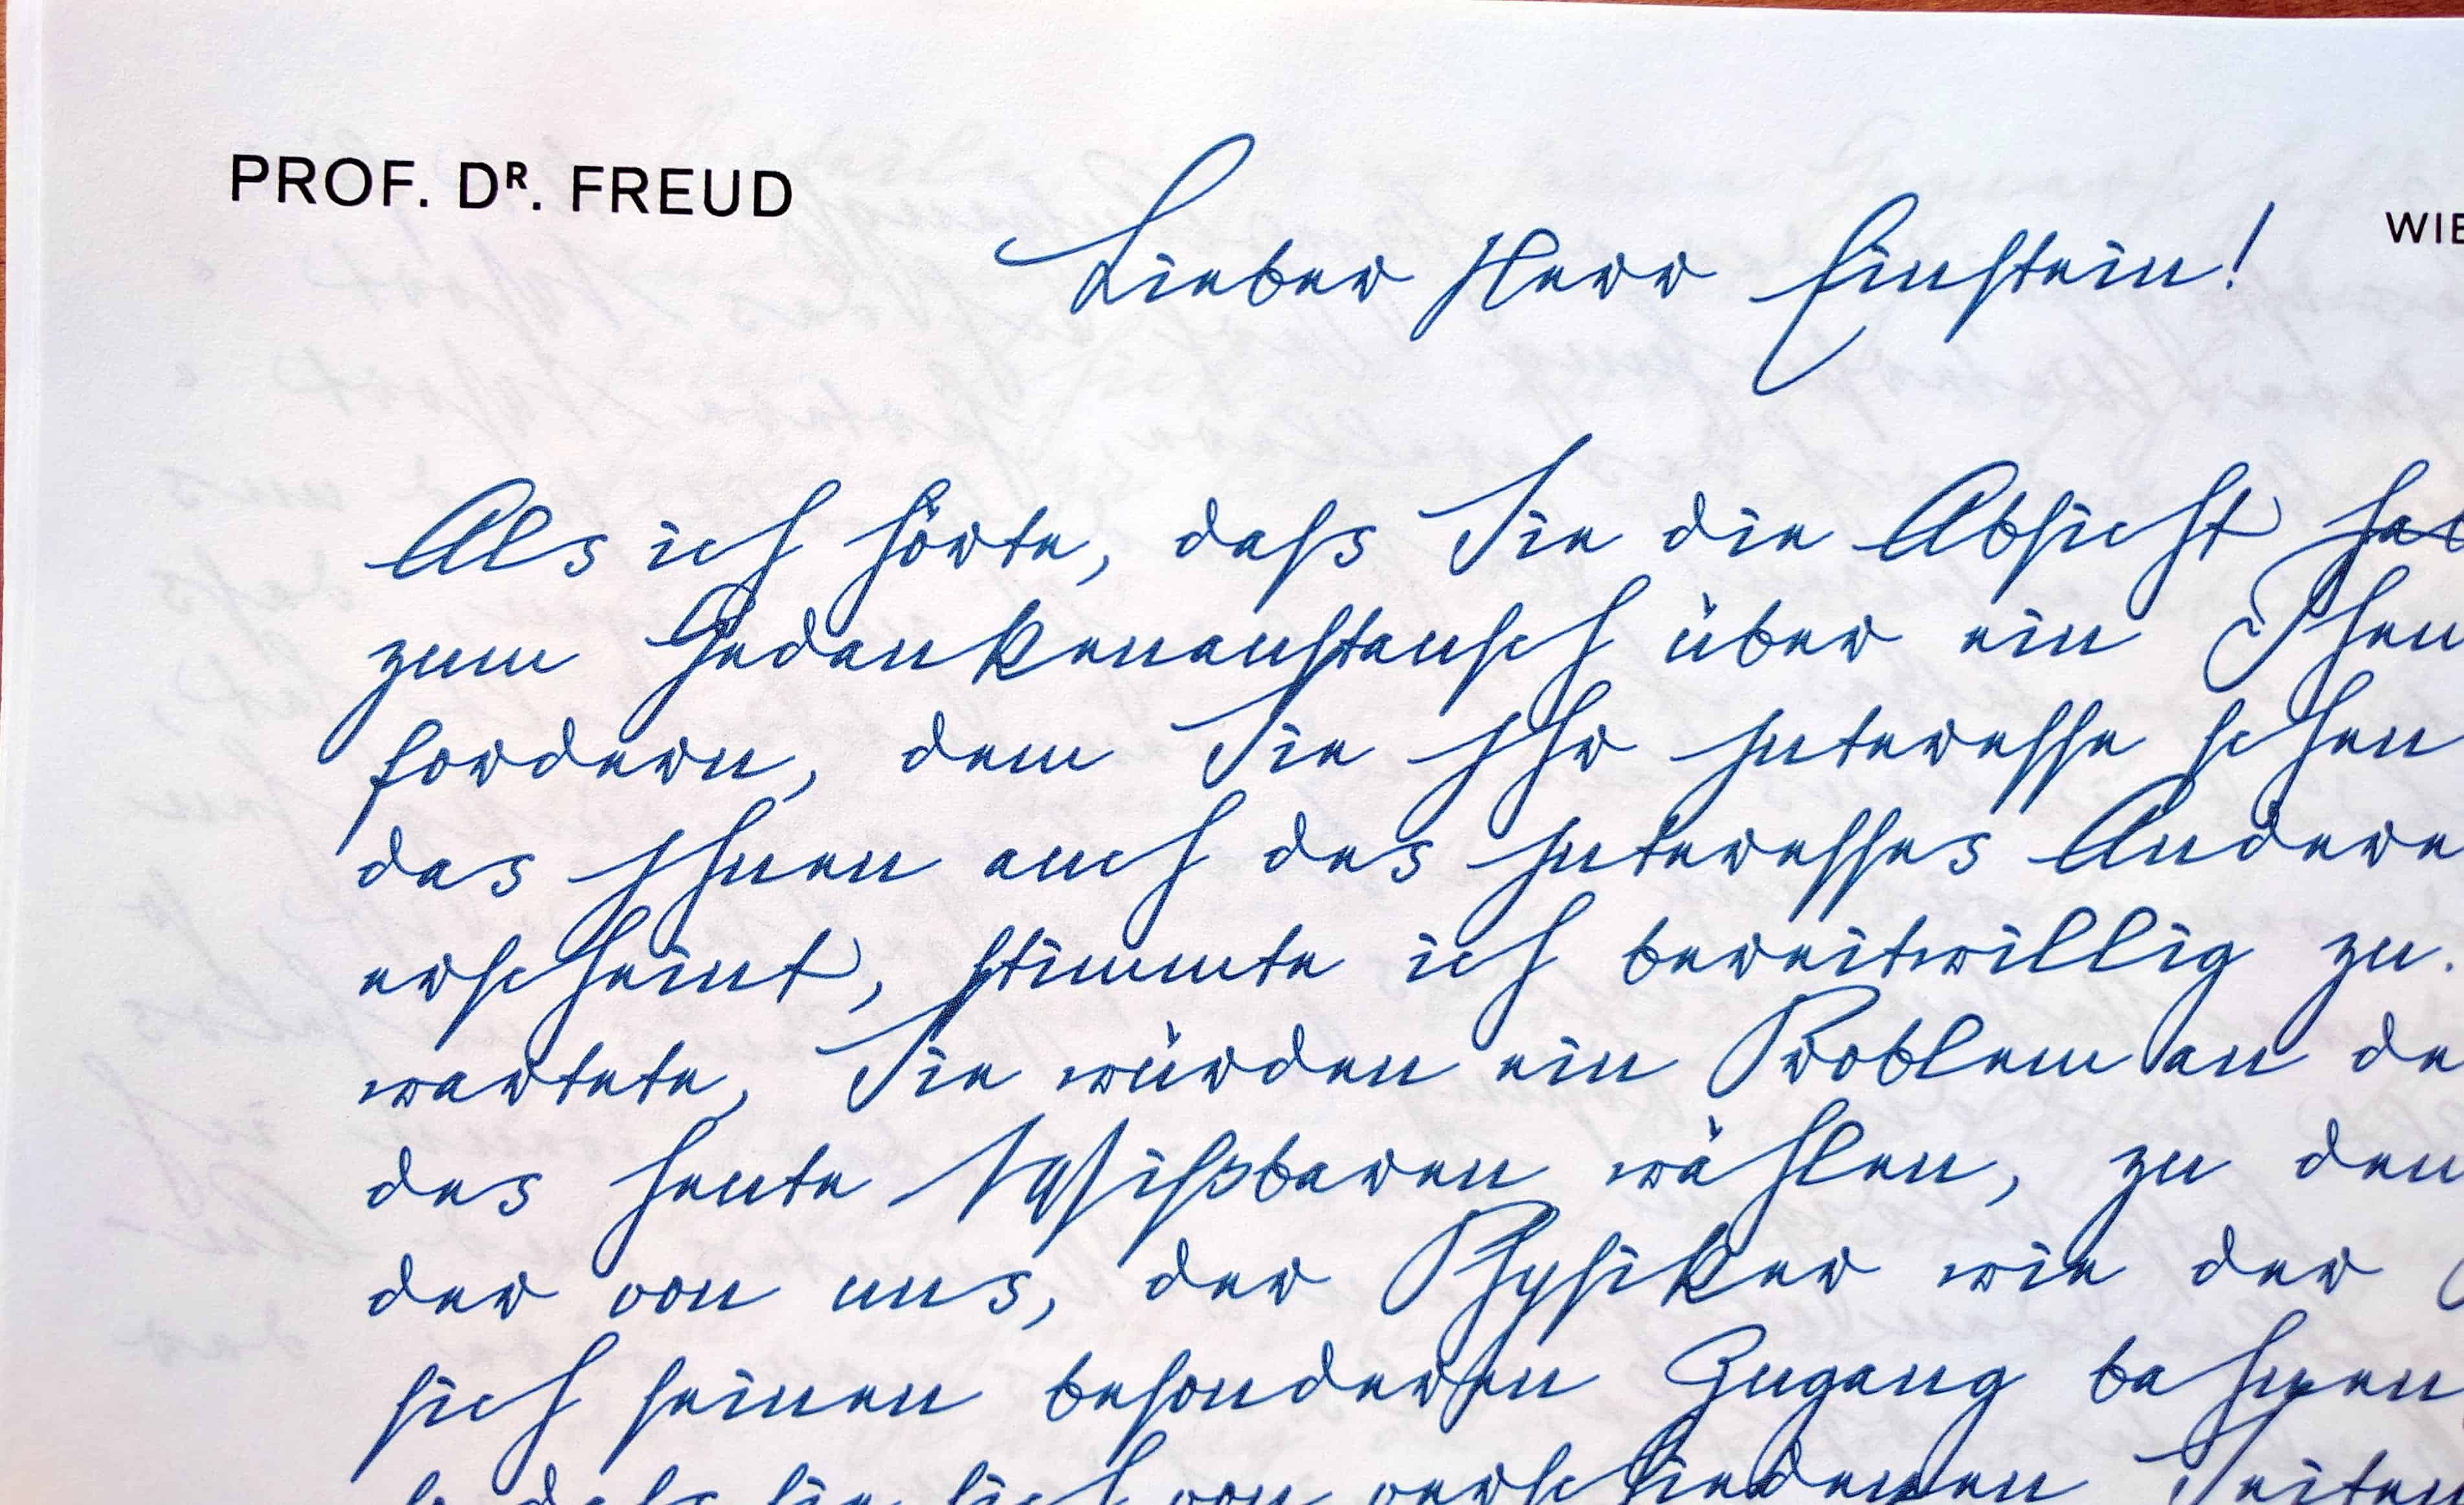
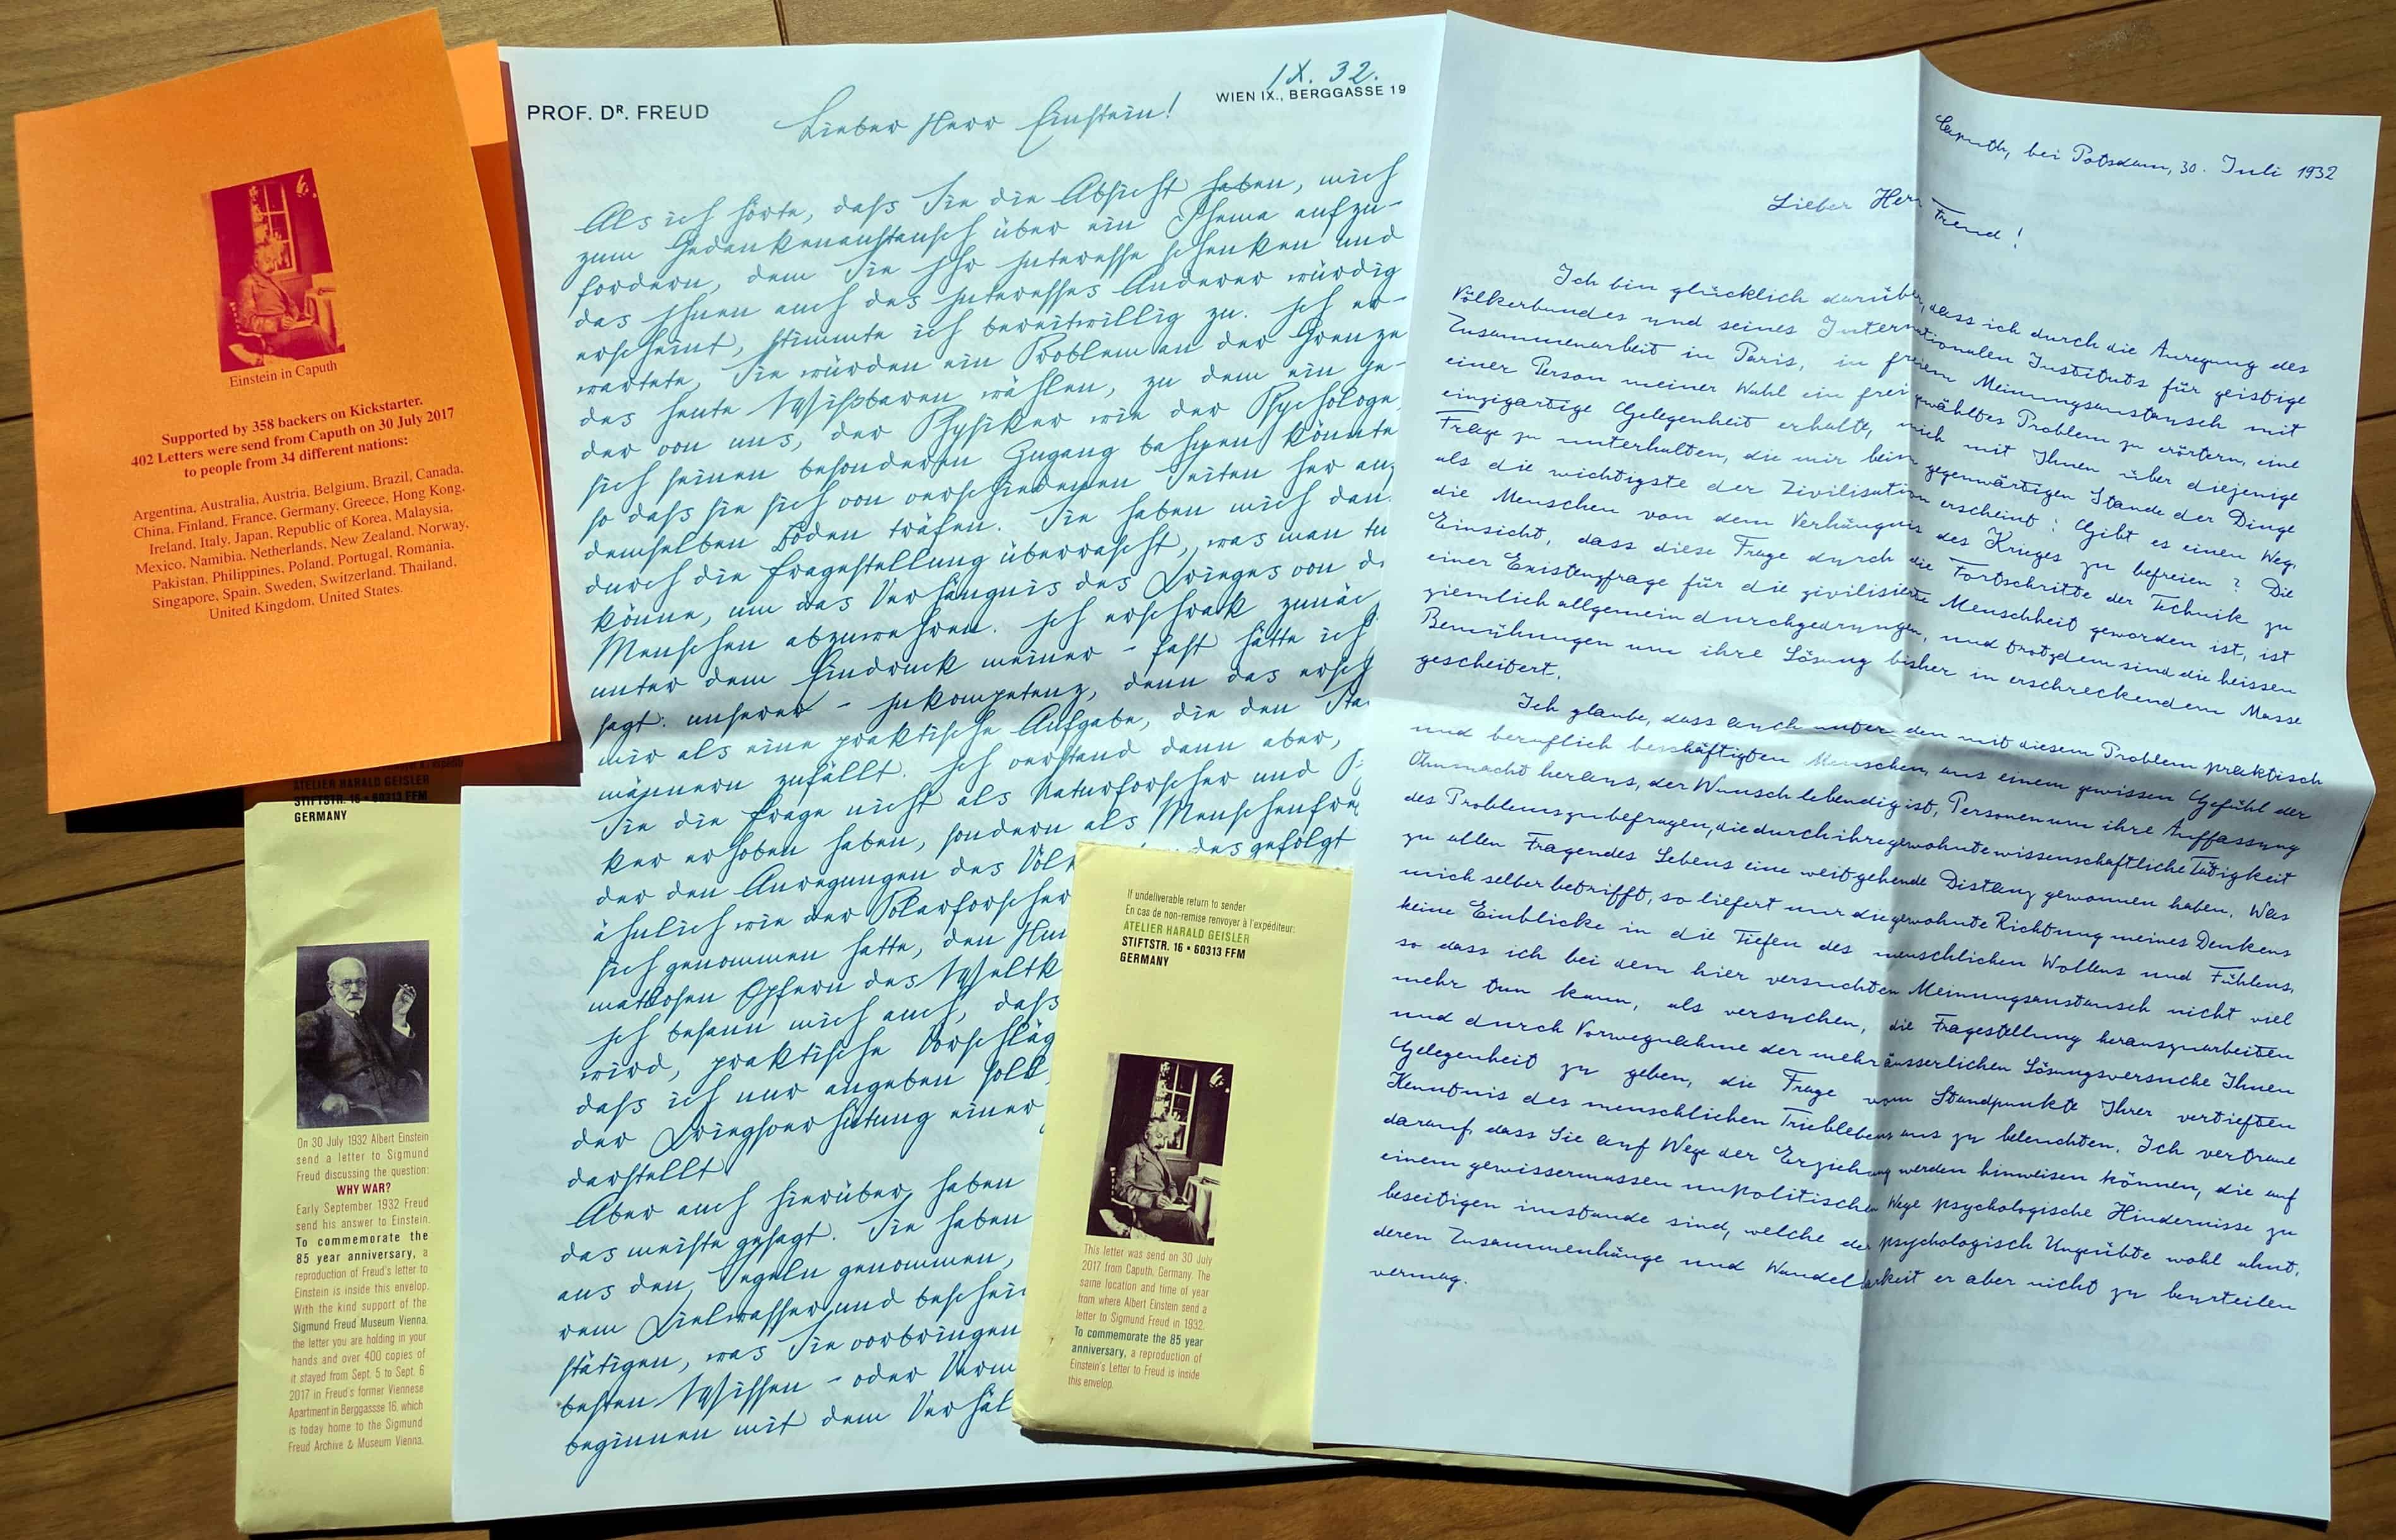
85 years ago, on 30 July 1932, Albert Einstein send a letter to Sigmund Freud discussing the question: Why War? Freud answered to this letter in early September 1932. To commemorate the 85 year anniversary, the German typographer Harald Geisler has started a project on Kickstarter to recreate the letters send back then. Over the last weeks the two letters have arrived at my place in Japan:
But not only were the letters reproduces, but typeset in the original digitized handwriting and sent from the original locations. Harald Geisler crafted fonts based on the hand-writing of Einstein and Freud, an layout out the pages of the letters according to the originals. Since the letters were originally written in German, an English translation also typeset in the hand-writing font was added.
In addition to the a bit archaic hand writing of Freud which even many German natives will not be able to read, the German text of his letter has been included in normal print style. Not only that, Harald Geisler even managed to convince the Sigmund Freud Museum to let rest the letters for one night in the very office where the original letter was written, so all the letters send out actually came from Freud s office.
This project was one of the first Kickstarter projects I supported, and I really liked the idea, and would like to thanks Harald Geisler for realizing it. These kind of activities, combining of typography, history, action, dedication, keep our culture and history alive. Thanks.
Harald Geisler also invites us all to continue the dialog on Why War?, which is getting more and more relevant again, with war-mongering becoming respected practice.

3 October 2017

Reproducible builds folks: Reproducible Builds: Weekly report #127

Here's what happened in the Reproducible Builds effort between Sunday September 24 and Saturday September 30 2017: Development and fixes in key packages Kai Harries did an initial packaging of the Nix package manager for Debian. You can track his progress in #877019. Uploads in Debian: Packages reviewed and fixed, and bugs filed Patches sent upstream: Reproducible bugs (with patches) filed in Debian: QA bugs filed in Debian: Reviews of unreproducible packages 103 package reviews have been added, 153 have been updated and 78 have been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Mattia Rizzolo uploaded version 87 to stretch-backports. strip-nondeterminism development reprotest development tests.reproducible-builds.org reproducible-website development Misc. This week's edition was written by Ximin Luo, Bernhard M. Wiedemann, Holger Levsen and Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Christoph Egger: Another Xor (CSAW 2017)

A short while ago, FAUST participated in this year's CSAW qualification and -- as usual -- I was working on the Crypto challenges again. The first puzzle I worked on was called "Another Xor" -- and, while there are quite some write ups already our solution was somewhat different (maybe even the intended solution given how nice things worked out) and certainly interesting. The challenge provides a cipher-text. It's essentially a stream cipher with key repeated to generate the key stream. The plain-text was plain + key + checksum.
p = this is a plaintextThis is the keyfa5d46a2a2dcdeb83e0241ee2c0437f7
k = This is the keyThis is the keyThis is the keyThis is the keyThis i
Key length Our first step was figuring out the key length. Let's assume for now the key was This is the key. Notice that the key is also part of the plain-text and we know something about its location -- it ends at 32 characters from the back. If we only take a look at the encrypted key it should have the following structure:
p' = This is the key
k' = he keyThis is t
The thing to notice here is that every character in the Key appears both in the plain-text and key stream sequence. And the cipher-text is the XOR ( ) of both. Therefore XOR over the cipher-text sequence encrypting the key should equal 0 ( (p') (k') = 0). So remove the last 32 characters and find all suffixes that result in a XOR of 0. Fortunately there is exactly one such suffix (there could be multiple) and therefore we know the key size: 67. To put it in code, this basically is the function we implemented for this:
def calculate(ciphertextcandidate):
    accumulator = 0
    for char in ciphertextcandidate:
        accumulator = accumulator ^ char
Which, for the matching plain-text and key-stream fragments is equal (due to the XOR encryption) to
def calculate(plainfragment, keyfragment):
    accumulator = 0
    for i in range(len(plainfragment):
        accumulator = accumulator ^ (plainfragment[i] ^ keyfragment[i])
Now XOR lets us nicely reorder this to
def calculate(plainfragment, keyfragment):
    accumulator = 0
    for i in range(len(plainfragment):
        accumulator = accumulator ^ (plainfragment[i] ^
                                     keyfragment[(i + 6) % len(plainfragment)])
And, as plainfragment[i] and keyfragment[(i + 6) % len(plainfragment)] are equal for the plain-text range encoding the key this becomes
def calculate(plainfragment, keyfragment):
    accumulator = 0
    for i in range(len(plainfragment):
        accumulator = accumulator ^ 0
Or simply 0 if the guess of the cipher-text range is correct. Key recovery Now the nice thing to notice is that the length of the key (67) is a prime (and 38, the plain-text length, is a generator). As a result, we only need to guess one byte of the key: Assume you know one byte of the key (and the position). Now you can use that one byte of the key to decrypt the next byte of the key (using the area where the key is part of the plain-text). Due to the primeness of the key length this allows recovery of the full key. Finally you can either print all 256 options and look for the one that looks reasonable or you can verify the md5sum which will give you the one valid solution, flag sti11_us3_da_x0r_for_my_s3cratz . Code

cipher = b"'L\x10\x12\x1a\x01\x00I[P-U\x1cU\x7f\x0b\x083X]\x1b'\x03\x0bR(\x04\r7SI\n\x1c\x02T\x15\x05\x15%EQ\x18\x00\x19\x11SJ\x00RV\n\x14YO\x0b\x1eI\n\x01\x0cE\x14A\x1e\x07\x00\x14aZ\x18\x1b\x02R\x1bX\x03\x05\x17\x00\x02\x07K\n\x1aLAM\x1f\x1d\x17\x1d\x00\x15\x1b\x1d\x0fH\x0eI\x1e\x02I\x01\x0c\x15\x00P\x11\\PXPCB\x03B\x13TBL\x11PC\x0b^\tM\x14IW\x08\rDD%FC"
def keycover(guess):
    key = dict()
    pos = 38
    key[38] = guess
    for i in range(67):
        newpos = (pos % 67) + 38
        key[newpos] = xor(cipher[pos:], key[pos])
        pos = newpos
    try:
        return b''.join([ key[i] for i in range(38, 105, 1) ])
    except:
        return b'test'
for guess in range(256):
    keycand = keycover(bytes([guess]))
    plaincand = xor(cipher, repeat(keycand, len(cipher)))
    if md5(plaincand[:-32]).hexdigest().encode() == plaincand[-32:]:
        print(keycand, plaincand)

2 October 2017

Antoine Beaupr : My free software activities, September 2017

Debian Long Term Support (LTS) This is my monthly Debian LTS report. I mostly worked on the git, git-annex and ruby packages this month but didn't have time to completely use my allocated hours because I started too late in the month.

Ruby I was hoping someone would pick up the Ruby work I submitted in August, but it seems no one wanted to touch that mess, understandably. Since then, new issues came up, and not only did I have to work on the rubygems and ruby1.9 package, but now the ruby1.8 package also had to get security updates. Yes: it's bad enough that the rubygems code is duplicated in one other package, but wheezy had the misfortune of having two Ruby versions supported. The Ruby 1.9 also failed to build from source because of test suite issues, which I haven't found a clean and easy fix for, so I ended up making test suite failures non-fatal in 1.9, which they were already in 1.8. I did keep a close eye on changes in the test suite output to make sure tests introduced in the security fixes would pass and that I wouldn't introduce new regressions as well. So I published the following advisories:
  • ruby 1.8: DLA-1113-1, fixing CVE-2017-0898 and CVE-2017-10784. 1.8 doesn't seem affected by CVE-2017-14033 as the provided test does not fail (but it does fail in 1.9.1). test suite was, before patch:
    2199 tests, 1672513 assertions, 18 failures, 51 errors
    
    and after patch:
    2200 tests, 1672514 assertions, 18 failures, 51 errors
    
  • rubygems: uploaded the package prepared in August as is in DLA-1112-1, fixing CVE-2017-0899, CVE-2017-0900, CVE-2017-0901. here the test suite passed normally.
  • ruby 1.9: here I used the used 2.2.8 release tarball to generate a patch that would cover all issues and published DLA-1114-1 that fixes the CVEs of the two packages above. the test suite was, before patches:
    10179 tests, 2232711 assertions, 26 failures, 23 errors, 51 skips
    
    and after patches:
    1.9 after patches (B): 10184 tests, 2232771 assertions, 26 failures, 23 errors, 53 skips
    

Git I also quickly issued an advisory (DLA-1120-1) for CVE-2017-14867, an odd issue affecting git in wheezy. The backport was tricky because it wouldn't apply cleanly and the git package had a custom patching system which made it tricky to work on.

Git-annex I did a quick stint on git-annex as well: I was able to reproduce the issue and confirm an approach to fixing the issue in wheezy, although I didn't have time to complete the work before the end of the month.

Other free software work

New project: feed2exec I should probably make a separate blog post about this, but ironically, I don't want to spend too much time writing those reports, so this will be quick. I wrote a new program, called feed2exec. It's basically a combination of feed2imap, rss2email and feed2tweet: it allows you to fetch RSS feeds and send them in a mailbox, but what's special about it, compared to the other programs above, is that it is more generic: you can basically make it do whatever you want on new feed items. I have, for example, replaced my feed2tweet instance with it, using this simple configuration:
[anarcat]
url = https://anarc.at/blog/index.rss
output = feed2exec.plugins.exec
args = tweet "%(title)0.70s %(link)0.70s"
The sample configuration file also has examples to talk with Mastodon, Pump.io and, why not, a torrent server to download torrent files available over RSS feeds. A trivial configuration can also make it work as a crude podcast client. My main motivation to work on this was that it was difficult to extend feed2imap to do what I needed (which was to talk to transmission to download torrent files) and rss2email didn't support my workflow (which is delivering to feed-specific mail folders). Because both projects also seemed abandoned, it seemed like a good idea at the time to start a new one, although the rss2email community has now restarted the project and may produce interesting results. As an experiment, I tracked my time working on this project. It turns out it took about 45 hours to write that software. Considering feed2exec is about 1400 SLOC, that's 30 lines of code per hour. I don't know if that's slow or fast, but it's an interesting metric for future projects. It sure seems slow to me, but we need to keep in mind those 30 lines of code don't include documentation and repeated head banging on the keyboard. For example, I found two issues with the upstream feedparser package which I use to parse feeds which also seems unmaintained, unfortunately. Feed2exec is beta software at this point, but it's working well enough for me and the design is much simpler than the other programs of the kind. The main issue people can expect from it at this point is formatting issues or parse errors on exotic feeds, and noisy error messages on network errors, all of which should be fairly easy to fix in the test suite. I hope it will be useful for the community and, as usual, I welcome contributions, help and suggestions on how to improve the software.

More Python templates As part of the work on feed2exec, I did cleanup a few things in the ecdysis project, mostly to hook tests up in the CI, improve on the advancedConfig logger and cleanup more stuff. While I was there, it turns out that I built a pretty decent basic CI configuration for Python on GitLab. Whereas the previous templates only had a non-working Django example, you should now be able to chose a Python template when you configure CI on GitLab 10 and above, which should hook you up with normal Python setup procedures like setup.py install and setup.py test.

Selfspy I mentioned working on a monitoring tool in my last post, because it was a feature from Workrave missing in SafeEyes. It turns out there is already such a tool called selfspy. I did an extensive review of the software to make sure it wouldn't leak out confidential information out before using it, and it looks, well... kind of okay. It crashed on me at least once so far, which is too bad because then it loses track of the precious activity. I have used it at least once to figure out what the heck I worked on during the day, so it's pretty useful. I particularly used it to backtrack my work on feed2exec as I didn't originally track my time on the project. Unfortunately, selfspy seems unmaintained. I have proposed a maintenance team and hopefully the project maintainer will respond and at least share access so we don't end up in a situation like linkchecker. I also sent a bunch of pull requests to fix some issues like being secure by default and fixing the build. Apart from the crash, the main issue I have found with the software is that it doesn't detect idle time which means certain apps are disproportionatly represented in statistics. There are also some weaknesses in the crypto that should be adressed for people that encrypt their database. Next step is to package selfspy in Debian which should hopefully be simple enough...

Restic documentation security As part of a documentation patch on the Restic backup software, I have improved on my previous Perl script to snoop on process commandline arguments. A common flaw in shell scripts and cron jobs is to pass secret material in the environment (usually safe) but often through commandline arguments (definitely not safe). The challenge, in this peculiar case, was the env binary, but the last time I encountered such an issue was with the Drush commandline tool, which was passing database credentials in clear to the mysql binary. Using my Perl sniffer, I could get to 60 checks per second (or 60Hz). After reimplementing it in Python, this number went up to 160Hz, which still wasn't enough to catch the elusive env command, which is much faster at hiding arguments than MySQL, in large part because it simply does an execve() once the environment is setup. Eventually, I just went crazy and rewrote the whole thing in C which was able to get 700-900Hz and did catch the env command about 10-20% of the time. I could probably have rewritten this by simply walking /proc myself (since this is what all those libraries do in the end) to get better result, but then my point was made. I was able to prove to the restic author the security issues that warranted the warning. It's too bad I need to repeat this again and again, but then my tools are getting better at proving that issue... I suspect it's not the last time I have to deal with this issue and I am happy to think that I can come up with an even more efficient proof of concept tool the next time around.

Ansible 101 After working on documentation last month, I ended up writing my first Ansible playbook this month, converting my tasksel list to a working Ansible configuration. This was a useful exercise: it allow me to find a bunch of packages which have been removed from Debian and provides much better usability than tasksel. For example, it provides a --diff argument that shows which packages are missing from a given setup. I am still unsure about Ansible. Manifests do seem really verbose and I still can't get used to the YAML DSL. I could probably have done the same thing with Puppet and just run puppet apply on the resulting config. But I must admit my bias towards Python is showing here: I can't help but think Puppet is going to be way less accessible with its rewrite in Clojure and C (!)... But then again, I really like Puppet's approach of having generic types like package or service rather than Ansible's clunky apt/yum/dnf/package/win_package types...

Pat and Ham radio After responding (too late) to a request for volunteers to help in Puerto Rico, I realized that my amateur radio skills were somewhat lacking in the "packet" (data transmission in ham jargon) domain, as I wasn't used to operate a Winlink node. Such a node can receive and transmit actual emails over the airwaves, for free, without direct access to the internet, which is very useful in disaster relief efforts. Through summary research, I stumbled upon the new and very promising Pat project which provides one of the first user-friendly Linux-compatible Winlink programs. I provided improvements on the documentation and some questions regarding compatibility issues which are still pending. But my pet issue is the establishment of pat as a normal internet citizen by using standard protocols for receiving and sending email. Not sure how that can be implemented, but we'll see. I am also hoping to upload an official Debian package and hopefully write more about this soon. Stay tuned!

Random stuff I ended up fixing my Kodi issue by starting it as a standalone systemd service, instead of gdm3, which is now completely disabled on the media box. I simply used the following /etc/systemd/service/kodi.service file:
[Unit]
Description=Kodi Media Center
After=systemd-user-sessions.service network.target sound.target
[Service]
User=xbmc
Group=video
Type=simple
TTYPath=/dev/tty7
StandardInput=tty
ExecStart=/usr/bin/xinit /usr/bin/dbus-launch --exit-with-session /usr/bin/kodi-standalone -- :1 -nolisten tcp vt7
Restart=on-abort
RestartSec=5
[Install]
WantedBy=multi-user.target
The downside of this is that it needs Xorg to run as root, whereas modern Xorg can now run rootless. Not sure how to fix this or where... But if I put needs_root_rights=no in Xwrapper.config, I get the following error in .local/share/xorg/Xorg.1.log:
[  2502.533] (EE) modeset(0): drmSetMaster failed: Permission denied
After fooling around with iPython, I ended up trying the xonsh shell, which is supposed to provide a bash-compatible Python shell environment. Unfortunately, I found it pretty unusable as a shell: it works fine to do Python stuff, but then all my environment and legacy bash configuration files were basically ignored so I couldn't get working quickly. This is too bad because the project looked very promising... Finally, one of my TLS hosts using a Let's Encrypt certificate wasn't renewing properly, and I figured out why. It turns out the ProxyPass command was passing everything to the backend, including the /.well-known requests, which obviously broke ACME verification. The solution was simple enough, disable the proxy for that directory:
ProxyPass /.well-known/ !

Next.

Previous.