Intro
RAID sucks, and so do all other Free alternatives in the Linux
world.
Having been in exactly the same situation several times in the
past, I have been following
Russell
Coker's
posts
regarding data integrity with interest. FWIW, the correct answer to
"BTRFS (sic) and Xen" is: subvolumes.
Now that Fedora has,
once again, decided to
postpone their switch to Btrfs as default file system, I
decided to write up my own take on this topic.
Any and all my considerations are made under the assumption that
important data is backed up while semi-important data is at least
living on two different machines. Beware, this is a long post, but
I do like to think it's well worth reading.
RAID
Disk failures
Let's recap the current situation for "traditional" file systems
like xfs, ext 2..4 , etc. In case you need to freshen up on the
technical details go
here.
- Single disks: Fine for many use cases like Laptops, Desktops,
etc, they are what most of us are using for most storage
needs.
- RAID 0:If you are using that, you are most likely doing it
wrong. Barring increasing caches for SSD-based volumes on machines
which you simply take out of your cluster if there is any
kind of problem, I don't know of not a sigle valid use case. Other
than to get rid of data, that is.
- RAID 1: The default for small servers and important machines
which don't need a lot of disk space.
- RAID 5: OK for personal storage servers, avoid once disks
become larger than 500GB-1TB, depending on personal preference. To
write data, you need to calculate new checksums and thus read all
data from all corresponding slices, impacting write performance
significantly.
- RAID 6: The RAID 10 people will disagree, but I like this RAID
level best. While your write performance will definitely take a
hit, you can mitigate this by decreasing your volume sizes. The
extra cost in ways of power, disks, controllers, and rack space are
a price we gladly pay for the ability to lose two disks
and still retain all data.
- RAID 10: Great write performance until the day when two disks
in the same RAID position die right after each other and your
company's main mail storage dies. Yes, this has happenend to me and
it sucks.
- RAID 2,3,4,50,60,foo: Mostly irrelevant in the real world;
disregard.
Silent corruption
All the RAID levels with redundancy are fine and dandy if you
lose a whole disk and put in a new one. Of course, that does not
help you the tiniest bit once you get read errors. Controllers
which manage RAID 1 or 10 may or may not compare the data while
it's being read and may or may not tell you about discrepancies.
They can then toss a coin and give you either result. There is no
way to determine which is correct. RAID 2, 3, 4, 5, and 6 could, in
theory, verify the data as it's being read, but that would limit
your read rate to that of a single disk so no one does that.
We actually had a massive web presence fail over night, once. No
one knew what the cause was as there hadn't been any kind of access
logged. As that particular deployment is done directly from a VCS,
we simply ran a diff and found one change. We traced the failure
down to a syntax error; a one character change made everything
fail. Looking at the ASCII table, it was clear that one single bit
had flipped. This sucked. A lot.
Mitigation
So you end up
scrubbing your
RAID sets on a weekly basis, recovering from silent corruption with
the help of your RAID 6's two parity stripes. And even though you
schedule the scrubbings with the least priority, you still take a
performance hit when randomly seeking a lot.
ZFS
Some smart people at Sun set out to fix these problems and more,
and fix it they did. The "Z" in ZFS is meant to imply that this is
the last file system you will ever need and if not for its license,
this might have worked. Of course, "last" and "forever" mean "not
now" and "10 years" respectively, in computer terms. The limits
within ZFS have been chosen so that the entropy needed to create a
disk able to max out a ZFS volume would, literally, require our
oceans to boil. Let's just say that you won't encounter these
limits any time soon.
While that is a nice thing to know, it does not say anything
about data integrity.
There are several mechanisms ensuring data integrity built in
ZFS, the most fundamental being extensive checksumming. Checksums
are vastly superior to live comparisions which RAID would have to
perform as it does not need to sacrifice any significant i/o
reading checksum data. With HDD access, you are i/o-bound, and not
CPU-bound, anyway, so performing the checksum calculations is
laughably cheap when factoring in the added safety. Everything, be
data, metadata, inodes, you name it, is checksummed. Every read
operation
must go through the checksumming functions,
ensuring that all data which reaches your user space is correct. If
ZFS can't verify the checksum, it will not deliver any data at all,
ensuring noticeable, as opposed to silent, corruption. So how does
ZFS recover when the checksum does not match the data?
copies= 1..3
The easy way is to store several copies of your data within your
volume. Mount a ZFS volume or subvolume with copies=2 or 3 and all
data that is being written
from then on will be copied
twice or three times. Trivial in principle, but powerful when built
into a file system.
RAIDz 1..3
This is where things start to get interesting. RAIDz1, 2, and 3
will allow you to lose 1, 2, or 3 disks respectively while still
retaining your data; at the obvious expense of the storage capacity
of as many disks. Basically, RAIDz2 is ZFS' variant of RAID 6, but
it's so much better than mere RAID 6.
Moo!
RAIDz will not assign fixed slices and fill them up like RAID
does. It will look at the current write speeds and use appropriate
slice sizes dynamically. As a direct result, data which has been
written at roughly the same time will always be near other data
written at the same time. This is very nice for functionality like
snapshots, writeable subvolumes and other things and is called
COW, ZFS'
variant of super cow powers. This also enables ZFS to write data,
read it back and verify the checksum and only
then point
to the new data. Atomic commits done right.
Keep rollin'
As ZFS has to keep track of what data is still in use in which
volumes and subvolumes anyway, it knows which regions are free to
be reclaimed. Instead of filling up random places, ZFS will roll
over your disks, overwriting unused data on the fly.
This bears repeating: Contrary to RAID 5 and 6, ZFS will never
need to read old data in order to write new data. Write performance
galore and anyone still stuck on RAID 10 can finally enjoy the
increased data security.
Btrfs
To be completely honest, I do not know Btrfs as well as I know
ZFS. If I get anything wrong, correct me. If I offend anyone with
my outsider's interpretation, that is not my intention.
Btrfs has been initiated by Oracle way before it ever even
thought about buying Sun or history might have run a different
course, for worse or a lot worse. The closing of Java, Solaris,
ZFS, Hudson, OpenOffice (since then "gifted" aka thrown away), and
others makes me think the latter. As there are few technological
developments which caused me as much stress, overtime and pain as
OCFS2, I am naturally wary of file systems sponsored by Oracle and
their data focus integrity/availability. The fact that there's
still no way to fsck a Btrfs volume could be birthing pain or yet
another facet of Oracle's stance on this topic, I honestly don't
know. Either way, it's a good idea to be wary for now.
I can't say too much on Btrfs' technical underpinnings, but I
know it uses COW and that it has its own variant of RAID. Toss in
snapshots (writeable?), subvolumes and integrated block device
management, and you have the building blocks of a decent file
system.
Still, Btrfs is
not ready for prime time. Btrfs has
been "one or two years in the future" for a few years now so I will
not be holding my breath. And once the first distributions are
starting to use Btrfs by default, people
will lose data. A
year or three after that, I will feel comfortable to use it myself
and in production.
Commercial solutions
You can either hand a lot of money to proprietary vendors who
will not tell you a thing about how things work internally (and no
way to fix things directly) or you can buy solutions that employ
ZFS in the back-end. I prefer my storage hardware to be relatively
dumb while keeping the intelligent bits where I can see and poke
them so this is not really part of these considerations.
So what can you do?
Test your disks before deploying them
Easy, but vitally important:
disk=/dev/foo
smartctl -a $disk
smartctl -t long $disk
badblocks -swo $vendor_$model_$serial_$timestamp.badblocks.swo $disk
smartctl -a $disk
If you are lazy, get a copy of
disktest, a tool I wrote
to do exactly this. It should wait for the long self-test to
finish, can not read out all vendor names, and does not have a way
to document who ran the test, but it's a start. Patches and
feedback are, obviously, welcome.
And yes, I will package this soonish.
Using your disks
This list is surprisingly short. You can use
- distinct disks
- RAID as per above
- ZFS-FUSE
- Debian/kFreeBSD
- Nexenta
And that's it.
At work, I prefer small RAID 6 volume sets. It sucks, but there
is nothing better.
For personal use, I have a machine with a FUSE-based RAIDz2
mounted with copies=2. Three disks can fail and my data is still
secure. While this setup is slow as molasses due to FUSE, speed is
not a consideration for me here; data safety is. A migration to
Debian/kFreeBSD in the medium term is still likely.
If you have things to add or disagree with me, I would love to
hear from you.
Update: Jan Christian Kaessens pointed out
that, contrary to my experience, zfsonlinux did not bring down his
sytem in flames. As zfsonlinux is a kernel module, potential
performance is a lot better. Also, it supports ZFS Pool Version 28
as opposed to FUSE-ZFS' 23. While the really nice features are in v
29 and 30 (which are closed thanks to Oracle) v 28 still has some
nice changes.
 In the last few days, people on the debian-devel mailing list have been debating again (and again, and again...) how much the ports and architectures used only by an handful of people should influence the direction of the project. With this post I want to briefly summarize my position.
The reason we support niche architectures and toy ports is that that some people are interested in doing the work, and that these do not hinder development of the architectures that people actually use.
When m68k started inconveniencing too much the real world development, the port was killed and the sky did not fall, notwithstanding the complaints of the few retrocomputing enthusiasts who still used and developed it.
I do not mind if some people like to play with kFreeBSD and Hurd as long as they do not inconvenience me too much, both as a user and as a developer.
While it is true that targeting multiple architectures helps finding bugs, after we have covered all the useful combinations of endianity, size of variables and char signedness the incremental benefits of adopting a new architecture just for its sake are minimal.
I am a Red Hat customer (also because of Debian shortcomings), I do not like it much and I do not want to be one forever: please do not kill my hopes.
 For some time, we use
 The 13th Debian Conference is just around the corner.


 Nagios or Icinga users probably know the problem that neither the default plugin packages (nagios-plugins-basic and -standard)
nor the few other plugin packages ship all the plugins you need to monitor your hardware and software properly. And unless you
have
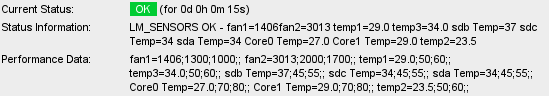
 ).
We might also also have a similar package in contrib as a lot of commonly used plugins require non-free software, so don't hesitate to prepare plugins for inclusion in such a package and let us know!
Suggestions and ideas for improvement are always welcome. And so is help to maintain the packages!
 <style type="text/css">
@import "/pub/special-css/venk.css";
</style>

 The

 I m in the process of getting the tests passing for the 0.03 release of NIST::NVD::Store::SQLite3 wherein our hero imports the CWE data and cross-indexes it with CVEs and CPEs.
Follow along and suggest some patches. I m developing on Debian Wheezy, but I would very much like input from devs on other platforms.
 As many would know,

 Talking about Secure Boot again, I'm afraid. One of the things that's made discussion of this difficult is that, while the specification isn't overly complicated, some of the outcomes aren't obvious at all until you spend a long time thinking about it. So here's some clarification on a few points.
 I was at FOSDEM over the last weekend, so here's my report for two weeks
now: