Search Results: "reg"

24 August 2015

Dirk Eddelbuettel: RcppDE 0.1.3

A pure maintenance release 0.1.3 of the RcppDE package arrived on CRAN yesterday. RcppDE is a "port" of DEoptim, a popular package for derivative-free optimisation using differential optimization, to C++. By using RcppArmadillo, the code becomes a lot shorter and more legible. This version simply fixes a typo in the vignette metadata noticed by Kurt, and updates the package in a few other spots to update it to current CRAN Repository Policy standards. Courtesy of CRANberries, there is also a diffstat report for the most recent release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 August 2015

Simon Kainz: DUCK challenge: Final week

Well, here are the stats for the final week of the DUCK challenge as well as DebConf15: So we had 21 packages fixed and uploaded by 14 different uploaders. People were really working hard on this during DebConf. A big "Thank You" to you!! Since the start of this challenge, a total of 89 packages, were fixed. Here is a quick overview:
Week 1 Week 2 Week 3 Week 4 Week 5 Week 6 Week 7
# Packages 10 15 10 14 10 9 21
Total 10 25 35 49 59 68 89
Thank you all for participating - either on purpose or "accidentially": Some people were really surprised as i sneaked up on them at DebConf15, confronting them with a green lighter! I just tried to put even more fun into Debian, i hope this worked out Pevious articles are here: Week 1, Week 2, Week 3, Week 4, Week 5,Week 6.

19 August 2015

Russell Coker: The Purpose of a Code of Conduct

On a private mailing list there have been some recent discussions about a Code of Conduct which demonstrate some great misunderstandings. The misunderstandings don t seem particular to that list so it s worthy of a blog post. Also people tend to think more about what they do when their actions will be exposed to a wider audience so hopefully people who read this post will think before they respond. Jokes The first discussion concerned the issue of making jokes . When dealing with the treatment of other people (particularly minority groups) the issue of jokes is a common one. It s fairly common for people in positions of power to make jokes about people with less power and then complain if someone disapproves. The more extreme examples of this concern hate words which are strongly associated with violence, one of the most common is a word used to describe gay men which has often been associated with significant violence and murder. Men who are straight and who conform to the stereotypes of straight men don t have much to fear from that word while men who aren t straight will associate it with a death threat and tend not to find any amusement in it. Most minority groups have words that are known to be associated with hate crimes. When such words are used they usually send a signal that the minority groups in question aren t welcome. The exception is when the words are used by other members of the group in question. For example if I was walking past a biker bar and heard someone call out geek or nerd I would be a little nervous (even though geeks/nerds have faced much less violence than most minority groups). But at a Linux conference my reaction would be very different. As a general rule you shouldn t use any word that has a history of being used to attack any minority group other than one that you are a member of, so black rappers get to use a word that was historically used by white slave-owners but because I m white I don t get to sing along to their music. As an aside we had a discussion about such rap lyrics on the Linux Users of Victoria mailing list some time ago, hopefully most people think I m stating the obvious here but some people need a clear explanation. One thing that people should consider jokes is the issue of punching-down vs punching-up [1] (there are many posts about this topic, I linked to the first Google hit which seems quite good). The basic concept is that making jokes about more powerful people or organisations is brave while making jokes about less powerful people is cowardly and serves to continue the exclusion of marginalised people. When I raised this issue in the mailing list discussion a group of men immediately complained that they might be bullied by lots of less powerful people making jokes about them. One problem here is that powerful people tend to be very thin skinned due to the fact that people are usually nice to them. While the imaginary scenario of less powerful people making jokes about rich white men might be unpleasant if it happened in person, it wouldn t compare to the experience of less powerful people who are the target of repeated jokes in addition to all manner of other bad treatment. Another problem is that the impact of a joke depends on the power of the person who makes it, EG if your boss makes a joke about you then you have to work on your CV, if a colleague or subordinate makes a joke then you can often ignore it. Who does a Code of Conduct Protect One member of the mailing list wrote a long and very earnest message about his belief that the CoC was designed to protect him from off-topic discussions. He analysed the results of a CoC on that basis and determined that it had failed due to the number of off-topic messages on the mailing lists he subscribes to. Being so self-centered is strongly correlated with being in a position of power, he seems to sincerely believe that everything should be about him, that he is entitled to all manner of protection and that any rule which doesn t protect him is worthless. I believe that the purpose of all laws and regulations should be to protect those who are less powerful, the more powerful people can usually protect themselves. The benefit that powerful people receive from being part of a system that is based on rules is that organisations (clubs, societies, companies, governments, etc) can become larger and achieve greater things if people can trust in the system. When minority groups are discouraged from contributing and when people need to be concerned about protecting themselves from attack the scope of an organisation is reduced. When there is a certain minimum standard of treatment that people can expect then they will be more willing to contribute and more able to concentrate on their contributions when they don t expect to be attacked. The Public Interest When an organisation declares itself to be acting in the public interest (EG by including Public Interest in the name of the organisation) I think that we should expect even better treatment of minority groups. One might argue that a corporation should protect members of minority groups for the sole purpose of making more money (it has been proven that more diverse groups produce better quality work). But an organisation that s in the Public Interest should be expected to go way beyond that and protect members of minority groups as a matter of principle. When an organisation is declared to be operating in the Public Interest I believe that anyone who s so unable to control their bigotry that they can t refrain from being bigoted on the mailing lists should not be a member.

18 August 2015

Arturo Borrero Gonz lez: 2015 FLOSS summer report

debian logo
Good news. Many things happened since my last report (8 months ago), some of them very interesting :-)

debian maintainer

Back in April 2015 I applied to become Debian Maintainer (DM). I was supported by several Debian Developers (DD), including Ana Guerrero, Anibal Monsalve, Michael Prokop and Vicent Cheng. They are people I have been somehow involved with in the last times (developing, in-person meetings, other talks...).

After a month or two, my PGP key was added to the debian keyring.

And what means this? If a DD gives me the corresponding authorization, I can now upload packages directly to the archive without the need for a sponsor.

I have been maintaining packages as a standard contributor since early 2014. From 2014 to 2015 I've learned many many things about Debian. That knowledge was key to become DM.

Google Summer of Code 2015

This is my 3 year in GSoC. In 2013 and 2014 I was involved with the Netfilter Project, but this time I'm contributing to the Debian project.
In concrete, my project is "Improve the Debian port mipsel".

Most of the software is developed to run in common CPU architectures like amd64 and i386. However, Debian can run in a large variety of arches (not so many operating systems have this power). Developers tend to consider these arches 'exotic' and don't pay much attention to them.
The mips/mipsel architecture is somewhat similar to arm: its mainly intended for small devices.

My tasks consist mainly into fixing bugs and FTBFS errors in the mipsel architecture.

Roughly speaking, this can be done in two ways: emulating the mipsel arch using qemu, or using a physical mipsel machine. The qemu way is very very slow. Fortunately, as part of my GSoC involvement, I was given a ci20 mipsel board by Imagination Technologies. I have been using this board for all my GSoC work.

Detailing my work during this GSoC deserves his own blog post. However, the Debian workflow for GSoC'15 requires a weekly report, and here are mine:

  1. week 1
  2. week 2
  3. week 3
  4. week 4
  5. week 5
  6. week 6
  7. week 7
  8. week 8
  9. week 9
  10. week 10
  11. week 11
  12. week 12

no longer involved with the Netfilter Project

Such is life. Days only have 24 hours. I had to 'refactor' my priorities and my involvement with the Netfilter Project is now almost none. This happened back in May'15. I was in so many business that I had stress and even had anxiety. Among other things, this hard decision meant that I missed the Netfilter Workshop 2015 in Budapest :-(

My plan for 2016 is to focus in the University and pay bills with my full-time job as a system administrator.

other debian sutff

Regarding packaging, it worth mention my latest new package: liquidprompt. For people who get their hands dirty with the CLI, I recommend it :-)
I made lot of updates to the other packages as well.

The nftables package is now in jessie-backports. Debian includes now Linux v4 in jessie-backports as well, which mean you can start playing with a full-featured nftables right now :-)
I'm looking forward to package the following version of upstream nftables, which is to include new exciting changes.

best regards!

Russell Coker: BTRFS Training

Some years ago Barwon South Water gave LUV 3 old 1RU Sun servers for any use related to free software. We gave one of those servers to the Canberra makerlab and another is used as the server for the LUV mailing lists and web site and the 3rd server was put aside for training. The servers have hot-swap 15,000rpm SAS disks IE disks that have a replacement cost greater than the budget we have for hardware. As we were given a spare 70G disk (and a 140G disk can replace a 70G disk) the LUV server has 2*70G disks and the 140G disks (which can t be replaced) are in the server for training. On Saturday I ran a BTRFS and ZFS training session for the LUV Beginners SIG. This was inspired by the amount of discussion of those filesystems on the mailing list and the amount of interest when we have lectures on those topics. The training went well, the meeting was better attended than most Beginners SIG meetings and the people who attended it seemed to enjoy it. One thing that I will do better in future is clearly documenting commands that are expected to fail and documenting how to login to the system. The users all logged in to accounts on a Xen server and then ssh d to root at their DomU. I think that it would have saved a bit of time if I had aliased commands like btrfs to echo you must login to your virtual server first or made the shell prompt at the Dom0 include instructions to login to the DomU. Each user or group had a virtual machine. The server has 32G of RAM and I ran 14 virtual servers that each had 2G of RAM. In retrospect I should have configured fewer servers and asked people to work in groups, that would allow more RAM for each virtual server and also more RAM for the Dom0. The Dom0 was running a BTRFS RAID-1 filesystem and each virtual machine had a snapshot of the block devices from my master image for the training. Performance was quite good initially as the OS image was shared and fit into cache. But when many users were corrupting and scrubbing filesystems performance became very poor. The disks performed well (sustaining over 100 writes per second) but that s not much when shared between 14 active users. The ZFS part of the tutorial was based on RAID-Z (I didn t use RAID-5/6 in BTRFS because it s not ready to use and didn t use RAID-1 in ZFS because most people want RAID-Z). Each user had 5*4G virtual disks (2 for the OS and 3 for BTRFS and ZFS testing). By the end of the training session there was about 76G of storage used in the filesystem (including the space used by the OS for the Dom0), so each user had something like 5G of unique data. We are now considering what other training we can run on that server. I m thinking of running training on DNS and email. Suggestions for other topics would be appreciated. For training that s not disk intensive we could run many more than 14 virtual machines, 60 or more should be possible. Below are the notes from the BTRFS part of the training, anyone could do this on their own if they substitute 2 empty partitions for /dev/xvdd and /dev/xvde. On a Debian/Jessie system all that you need to do to get ready for this is to install the btrfs-tools package. Note that this does have some risk if you make a typo. An advantage of doing this sort of thing in a virtual machine is that there s no possibility of breaking things that matter.
  1. Making the filesystem
    1. Make the filesystem, this makes a filesystem that spans 2 devices (note you must use the-f option if there was already a filesystem on those devices):
      mkfs.btrfs /dev/xvdd /dev/xvde
    2. Use file(1) to see basic data from the superblocks:
      file -s /dev/xvdd /dev/xvde
    3. Mount the filesystem (can mount either block device, the kernel knows they belong together):
      mount /dev/xvdd /mnt/tmp
    4. See a BTRFS df of the filesystem, shows what type of RAID is used:
      btrfs filesystem df /mnt/tmp
    5. See more information about FS device use:
      btrfs filesystem show /mnt/tmp
    6. Balance the filesystem to change it to RAID-1 and verify the change, note that some parts of the filesystem were single and RAID-0 before this change):
      btrfs balance start -dconvert=raid1 -mconvert=raid1 -sconvert=raid1 force /mnt/tmp
      btrfs filesystem df /mnt/tmp
    7. See if there are any errors, shouldn t be any (yet):
      btrfs device stats /mnt/tmp
    8. Copy some files to the filesystem:
      cp -r /usr /mnt/tmp
    9. Check the filesystem for basic consistency (only checks checksums):
      btrfs scrub start -B -d /mnt/tmp
  2. Online corruption
    1. Corrupt the filesystem:
      dd if=/dev/zero of=/dev/xvdd bs=1024k count=2000 seek=50
    2. Scrub again, should give a warning about errors:
      btrfs scrub start -B /mnt/tmp
    3. Check error count:
      btrfs device stats /mnt/tmp
    4. Corrupt it again:
      dd if=/dev/zero of=/dev/xvdd bs=1024k count=2000 seek=50
    5. Unmount it:
      umount /mnt/tmp
    6. In another terminal follow the kernel log:
      tail -f /var/log/kern.log
    7. Mount it again and observe it correcting errors on mount:
      mount /dev/xvdd /mnt/tmp
    8. Run a diff, observe kernel error messages and observe that diff reports no file differences:
      diff -ru /usr /mnt/tmp/usr/
    9. Run another scrub, this will probably correct some errors which weren t discovered by diff:
      btrfs scrub start -B -d /mnt/tmp
  3. Offline corruption
    1. Umount the filesystem, corrupt the start, then try mounting it again which will fail because the superblocks were wiped:
      umount /mnt/tmp
      dd if=/dev/zero of=/dev/xvdd bs=1024k count=200
      mount /dev/xvdd /mnt/tmp
      mount /dev/xvde /mnt/tmp
    2. Note that the filesystem was not mountable due to a lack of a superblock. It might be possible to recover from this but that s more advanced so we will restore the RAID.
      Mount the filesystem in a degraded RAID mode, this allows full operation.
      mount /dev/xvde /mnt/tmp -o degraded
    3. Add /dev/xvdd back to the RAID:
      btrfs device add /dev/xvdd /mnt/tmp
    4. Show the filesystem devices, observe that xvdd is listed twice, the missing device and the one that was just added:
      btrfs filesystem show /mnt/tmp
    5. Remove the missing device and observe the change:
      btrfs device delete missing /mnt/tmp
      btrfs filesystem show /mnt/tmp
    6. Balance the filesystem, not sure this is necessary but it s good practice to do it when in doubt:
      btrfs balance start /mnt/tmp
    7. Umount and mount it, note that the degraded option is not needed:
      umount /mnt/tmp
      mount /dev/xvdd /mnt/tmp
  4. Experiment
    1. Experiment with the btrfs subvolume create and btrfs subvolume delete commands (which act like mkdir and rmdir).
    2. Experiment with btrfs subvolume snapshot SOURCE DEST and btrfs subvolume snapshot -r SOURCE DEST for creating regular and read-only snapshots of other subvolumes (including the root).

Dirk Eddelbuettel: RcppArmadillo 0.5.400.2.0

armadillo image A new Armadillo release 5.400.2 was just released by Conrad. Consequently, a new RcppArmadillo release 0.5.400.2.0 went out to CRAN and into Debian. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. This release contains the following extensions:
Changes in RcppArmadillo version 0.5.400.2.0 (2015-08-17)
  • Upgraded to Armadillo 5.400.2 ("Plutocracy Incorporated Deluxe")
    • added find_unique() for finding indices of unique values
    • added diff() for calculating differences between consecutive elements
    • added cumprod() for calculating cumulative product
    • added null() for finding the orthonormal basis of null space
    • expanded interp1() to handle repeated locations
    • expanded unique() to handle complex numbers
    • faster flupud()
    • faster row-wise cumsum()
    • fix for k-means clustering in gmm_diag class
  • corrected use of kitten() thanks to Grant Brown
Courtesy of CRANberries, there is also a diffstat report for the most recent CRAN release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

16 August 2015

Ben Armstrong: McIntosh Run Hike the Greenbelt event, August 2015

Just came back from a wonderful time hiking with my daughter at the finale Hike the Greenbelt event at the Backlands/McIntosh Run! This photo slideshow is from my HP snapshot camera which unfortunately has dust in the lens. But I felt it was more important to get them up soon than to get them perfect, so please click the photo below to start the slideshow. I want to thank everyone who made this event a success, and not going to name specific names as I m sure I ll miss someone important. But thanks especially to Martin, the leader of our group. [slb_group]
Marcos Zentilli explaining geology of the region. Click photo to start slideshow.Marcos Zentilli explaining geology of the region. Click photo to start slideshow.
Barrens Barrens Barrens Barrens DIGITAL CAMERA Jack Pine in Jack Pine ;) DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA Part of the waterway DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA DIGITAL CAMERA
facebooktwittergoogle_plusredditpinterestlinkedinmail

John Goerzen: First steps: Debian on an Asus t100, and some negative experience with Gnome

The Asus t100 tablet is this amazing and odd little thing: it sells for under $200, yet has a full-featured Atom 64-bit CPU, 2GB RAM, 32 or 64GB SSD, etc. By default, it ships with Windows 8.1. It has a detachable keyboard, so it can be used as a tablet or a very small 10 laptop. I have never been a fan of Windows on it. It does the trick for web browsing and email, but I d like to ssh into my machines sometimes, and I just can t bring myself to type sensitive passwords into Windows. I decided to try installing Debian on it. After a lot of abortive starts due to the UEFI-only firmware, I got jessie installed. (The installer was fine; it was Debian Live that wouldn t boot.) I got wifi and battery status working via an upgrade to the 4.1 kernel. A little $10 Edimax USB adapter was handy to spare a bunch of copying via USB disks. I have been using XFCE with XMonad for so many years that I am somewhat a stranger to other desktop environments. XMonad isn t really suitable for a tablet, however, so I thought I d try Gnome, especially after a fairly glowing review about its use on a tablet. I am already disappointed after just a few minutes. There is no suspend button on the menu. Some Googling showed that holding Alt while hovering over the power off button will change it to a suspend button. And indeed it does. But uh, what? That is so common and so non-obvious. And pushing the power button does nothing. That s right, nothing. Apparently the way to enable some action when you push the power button is to type in a settings command in a terminal. There s no setting in the settings panel. I initially ditched Gnome some years ago due to its penchant for removing features. I had hoped that this much time later, it would have passed that stage, but I m already disappointed. I was hoping for some really nice integration with the system. But my XFCE setup has a very clear When power button is pressed setting. I have no idea why Gnome doesn t. Also, the touch screen works fine and it registers my touches, but whenever I touch anywhere, the cursor disappears. Weird, eh? There are some things to fix yet on the tablet (sound, brightness adjustment, and making suspend reliable) but others have solved these in Ubuntu so I don t think it ll be too hard. In the meantime, any suggestions regarding Gnome? Is it just going to annoy me? Maybe I should try KDE also. I ve heard good things about Plasma Active, but don t see it in Debian though.

15 August 2015

Simon Kainz: DUCK challenge: week 6

Well, here are the stats for week 6 of the DUCK challenge: So we had 9 packages fixed and uploaded by 7 different uploaders. A big "Thank You" to you!! Since the start of this challenge, a total of 68 packages, were fixed. Here is a quick overview:
Week 1 Week 2 Week 3 Week 4 Week 5 Week 6 Week 7
# Packages 10 15 10 14 10 9 -
Total 10 25 35 49 59 68 -
The list of the fixed and updated packages is availabe here. I will try to update this ~daily. If I missed one of your uploads, please drop me a line. So, assuming that the current rate of packages fixed will be somewhat stable and there will be no additional regessions, the number of packages with issues should be down to 0 in about 209 weeks (~ 4 years ) I just arrived at DebConf15 in Heidelberg, and will try to find all of you who fixed & uploaded packages. If you are one of the guys and see me lingering around, please talk to me and get your lighter! The DUCK Challenge will run until the end of DebConf15, but as there might be some delay by my scripts detecting your upload, please contact my directly. Pevious articles are here: Week 1, Week 2, Week 3, Week 4, Week 5.

14 August 2015

Ben Hutchings: DebCamp 2015

I've now spent nearly at week in Heidelberg, attending DebCamp and working on 'kernel stuff'. It's been very sunny and warm here, sometimes uncomfortably so. I've been sitting in a outdoor hacklab - covered but otherwise open to the elements. Right now it is mild and raining, and quite comfortable here. Linux 3.2.71 Hot on the heels of Linux 3.2.70, I prepared another stable update for 3.2 which was announced today. I've now caught up with fixes in Linus's tree up to 4.2-rc5, though there are plenty of others still to consider. Kernel packaging in git I finally completed the scripts and configuration needed to convert the kernel team's Subversion repository to git, with most of the history of the relevant packages accurately represented. (Several packages are obsolete or had been separately moved to git.) Thanks to Subversion's flexibility with directory layout, this was quite challenging. There were a number of changes of layout in 2005-2006, tags that were copied from the wrong directory level, and merges that somehow didn't get recorded as such. I pushed the new git repositories onto Alioth on Tuesday and disabled writes to the packaging in Subversion. So far no-one's complained about breakage, so I think I got it all right. Autopkgtest for Linux I've been worried for a while that I have so little ability to test for regressions in the kernel. I am mostly reliant on getting bug reports on versions in experimental and unstable to prevent these from getting to testing and stable. However this doesn't help with stable updates for security or general bug fixes. The autopkgtest framework provides a way to (mostly) automatically test Debian packages, and I've been exploring how this can be used for the linux package. It already allows for tests that need a whole (virtual) machine to themselves and that may need to reboot the machine, so installing and running new kernel packages is fine. I don't want to have to reconfigure a boot loader, and there is no way to specify which boot loader should be used, so at least initially I'm using kexec to boot into the test kernel. The linux source tree includes a growing number of self-test programs which roughly follow a single spec, although the requirements for some of them (kernel and machine configuration) are not all clearly documented. So far, I have most of the tests passing on 4.2-rc6 under autopkgtest, a few failures that are expected given the kernel configuration we use, and several more failures that I don't yet understand. Once I have these self-tests integrated, I'd like to move on and add some separate test suites such as xfstests and LTP. Or I may add to the self-tests myself. liblockdep I reviewed the 2014 version of "What's new in the Linux kernel" in order to write the follow-up section at the start of this year's talk. Last year I mentioned liblockdep, a port of lockdep to userland that tests use of the pthreads locking APIs, which wasn't packaged. As this is part of the linux source tree, I probably should have worked on it myself. To avoid embarrassment right at the start of my talk, I worked to add liblockdep binary packages to the linux-tools source package. These are now in the binary-NEW queue, headed for experimental. As lockdep is sadly lacking in documentation and liblockdep seems to be missing the ability to explicitly define lock classes, I'm not sure how useful it will be. Packaging it should make it easier for people to try out, though. What's new in the Linux kernel I'm about half way through writing the 2015 version of this talk, which I'm due to give on Monday afternoon. This year I think I've avoided having to spend most of the preceding day preparing it, which was why I skipped the day trip last year.

Dirk Eddelbuettel: Rblpapi: Connecting R to Bloomberg

big deal Whit, John and I are thrilled to announce Rblapi, a new CRAN package which connects R to the Bloomberg backends. Rebuilt from scratch using only the Bloomberg C++ API and the Rcpp and BH packages, it offers efficient and direct access from R to a truly vast number of financial data series, pricing tools and more. The package has been tested on Windows, OS X and Linux. As is standard for CRAN packages, binaries for Windows and OS X are provided (or will be once the builders caught up). Needless to say, a working Bloomberg installation is required to use the package. Please see the Rblapi package page for more details, including a large part of the introductory vignette document. As a teaser, here are just three of the core functions:
## Bloomberg Data Point Query
bdp(c("ESA Index", "SPY US Equity"), c("PX_LAST", "VOLUME"))
## Bloomberg Data Set Query
bds("GOOG US Equity", "TOP_20_HOLDERS_PUBLIC_FILINGS")
## Bloomberg Data History Query
bdh("SPY US Equity", c("PX_LAST", "VOLUME"), start.date=Sys.Date()-31)
## Get OHLCV bars (by default hourly and just six of them)
getBars("ES1 Index")
## Get Tick Data (by default last hour)
getTicks("ES1 Index")
Source code for the package is at the Rblpapi GitHub repo where issue tickets can be filed as well. The sibbling blp GitHub repo contains the Bloomberg code required to build and link the package (which is automated during the build of the CRAN package). Last but not least the Rblpapi package page has more details about the package.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Norbert Preining: QMapShack GPS and Maps on Linux

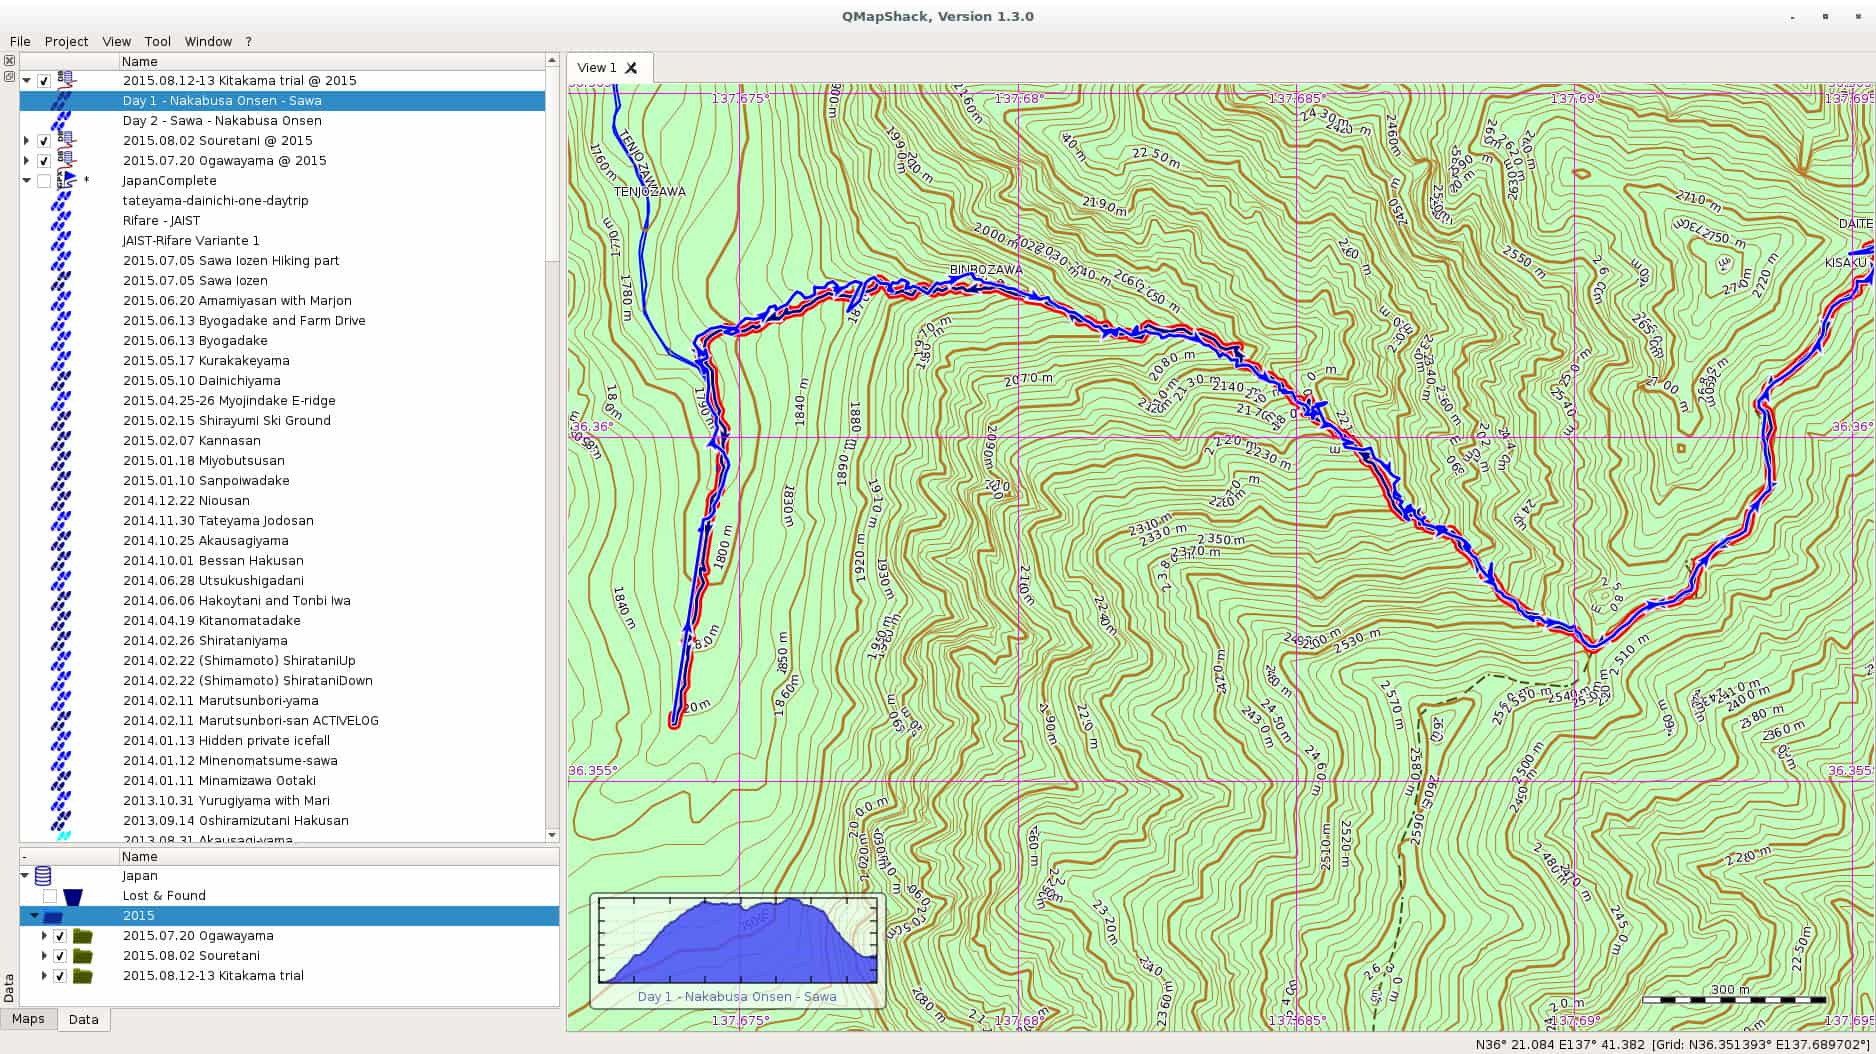
In one of the comments on my last post on Windows 10, a friendly reader from my home country pointed me at QMapShack as a replacement for QuoVadis. I have been using QuoVadis now for many many years, and it contains my mountaineering history all the way back. All the guiding work, all the track. QuoVadis is a great program, able to work with various commercial digital maps as well as GPS receivers. It only has one disadvantage, it doesn t work on Linux. QMapShack is very similar in the target audience, but very different in usage. The one big difference is of course the set of maps one can use with QMapShack. Fortunately, Garmin Maps are supported, and since all my maps regarding Japan are Garmin maps, I am now in the process to converting to QMapShack at least for my Japan GPS data. qmapshack Let us start with the program I was using since ages, and still are using, QuoVadis. QuoVadis is a great program, there is nothing to complain. It is extremely feature-rich, and above all it can work with many different maps. While working as mountain guide in Europe it was an essential tool for me. I could use the digital raster maps of Austria, Switzerland (SwissTOPO), Germany, France, Italy, as well as Garmin vector maps. For serious work as a professional it was indispensable for me. Unfortunately, it never worked on Linux. For some time I had a VirtualBox installation of Windows, but that was more a clutch than anything else. So for most of the GPS work I had to reboot my laptop to Windows, do my stuff there, and then switch back to Linux. QMapShack is far from as feature rich as QuoVadis, but as far as I see now, it does have enough features for me and my mountaineering in Japan. Dealing with GPS units is not a problem, this is the easy part. The difficult part are the digital maps. Fortunately, QMapShack supports Garmin vector maps, the only maps that are (as far as I know) available digitally for Japan. Getting used to QMapShack is a bit a challenge coming from QuoVadis, but the Wiki help pages allowed a quick start. Within short time I had maps set up. Next step was to download a data from my last weekend trip to Yarigadake, Kitakama-ridge (unfortunately we had to turn back due to rain). Connecting the unit and mounting it was already enough to show up in QMapShack, and allowed me to copy the tracks to my local database. Next I switched to Windows and exported some tracks from my Japan folder to a gpx file. After rebooting to Linux, I loaded the gpx file into QMapShack and without failure all the tracks and routes showed up, as it can be seen in the above screenshot (click on it to get a bigger version). Also the display of the Garmin map worked perfectly. Update: Please see the comment section for explanation of the necessary functions. QMapShack does provide similar functionality. Thanks to Oliver for pointing me at it! After some time of working there are a few functions from QuoVadis I am missing for now at QMapShack: Although these two functionalities are missing, all in all I am very happy for now with QMapShack. My next steps are: Finally, above all, I see a future where I do not need to reboot into Windows for doing my GPS work. For now I will import all the data into both applications, but if QMapShack holds its promises from the first day of usage, I am confident that this will not be necessary in future. Enjoy.

12 August 2015

Daniel Pocock: Recording live events like a pro (part 2: video)

In the first blog in this series, we looked at how to capture audio effectively for a range of different events. While recording audio appears less complicated than video, it remains fundamental to a good recording. For some types of event, like a speech or a debate, you can have quite a bad video with poor lighting and other defects but people will still be able to watch it if the audio is good. Therefore, if you haven't already looked at the previous blog, please do so now. As mentioned in the earlier blog, many people now have high quality equipment for recording both audio and video and a wide range of opportunities to use it, whether it is a talk at a conference, a wedding or making a Kickstarter video. The right camera for video recording The fundamental piece of equipment is the camera itself. You may have a DSLR camera that can record video or maybe you have a proper handheld video camera. The leading DSLR cameras, combined with a good lens, make higher quality recordings than many handheld video cameras. Unfortunately, although you pay good money to buy a very well engineered DSLR that could easily record many hours of video, most DSLRs are crippled to record a maximum of 30 minutes in one recording. This issue and some workarounds are discussed later in this blog. If you don't have any camera at all you need to think carefully about which type to buy. If you are only going to use it once you may want to consider renting or borrowing or asking for other people attending the event to bring whatever cameras they have to help make multiple recordings (the crowdsourcing solution). If you are a very keen photographer then you will probably have a preference for a DSLR. Accessories Don't just look at the cost of your camera and conclude that is all the budget you need. For professional quality video recording, you will almost certainly need some accessories. You may find they are overpriced at the retail store where you bought your camera, but you still need some of them, so have a look online.
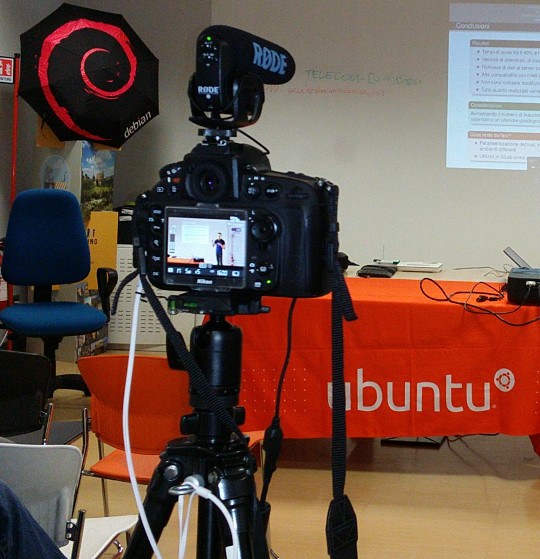
Recording a talk at a free software event with a Nikon D800 on a very basic tripod with Rode VideoMic Pro, headphones (white cable) and external power (black cable) If you want to capture audio with the camera and record it in the video file (discussed in more detail below), you will need to purchase a microphone that mounts on the camera. The built-in microphones on cameras are often quite bad, even on the most expensive cameras. If you are just using the built-in microphone for reference audio (to help with time synchronization when you combine different audio files with the video later) then the built-in microphone may be acceptable. Camera audio is discussed in more detail below. If your camera has a headphone socket, get some headphones for listening to the audio. Make sure you have multiple memory cards. Look carefully at the speed of the memory cards, slow ones are cheaper but they can't keep up with the speed of writing 1080p video. At a minimum, you should aim to buy memory cards that can handle one or two days worth of data for whatever it is you do. A tripod is essential for most types of video. If you use a particularly heavy camera or lens or if you are outdoors and it may be windy you will need a heavier tripod for stability. For video, it is very useful to have a tripod with a handle for panning left and right but if the camera will be stationary for the whole recording then the handle is not essential. Carrying at least one spare battery is another smart move. On one visit to the Inca Trail in Peru, we observed another member of our group hiking up and down the Andes with a brand new DSLR that they couldn't use because the battery was flat. For extended periods of recording, batteries will not be sufficient and you will need to purchase a mains power supply (PSU). These are available for most types of DSLR and video camera. The camera vendors typically design cameras with unusual power sockets so that you can only use a very specific and heavily overpriced PSU from the same company. Don't forget a surge protector too. There are various smartphone apps that allow you to remotely control the camera from the screen of your phone, such as the qDslrDashboard app. These often give a better preview than the screen built-in to the camera and may even allow you to use the touch screen to focus more quickly on a specific part of the picture. A regular USB cable is not suitable for this type of app, you need to buy a USB On-The-Go (OTG) cable.
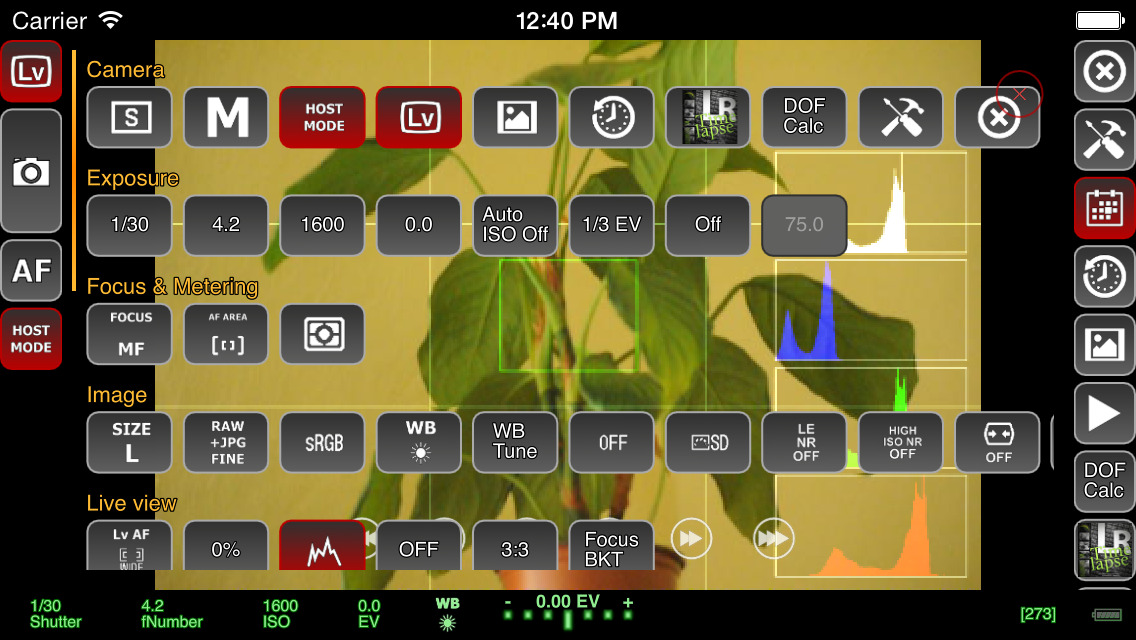
Screenshot of qDslrDashboard app on a smartphone, controlling a DSLR camera If you plan to copy the video from the camera to a computer at the event, you will need to make sure you have a fast memory card reader. The memory card readers in some laptops are quite slow and others can be quite fast so you may not need to buy an extra card reader. Camera audio Most cameras, including DSLRs, have a built-in microphone and a socket for connecting an external microphone. The built-in microphones obtain very poor quality sound. For many events, it is much better to have independent microphones, such as a lapel microphone attached to a smartphone or wireless transmitter. Those solutions are described in part one of this blog series. Nonetheless, there are still some benefits of capturing audio in the camera. The biggest benefit is the time synchronization: if you have audio recordings in other devices, you will need to align them with the video using post-production software. If the camera recorded an audio stream too, even if the quality is not very good, you can visualize the waveform on screen and use it to align the other audio recordings much more easily and precisely. If the camera will be very close to the people speaking then it may be acceptable to use a microphone mounted on the camera. This will be convenient for post-production because the audio will be synchronized with the video. It may still not be as good as a lapel microphone though, but the quality of these camera-mounted microphones is still far higher than the built-in microphones. I've been trying the Rode VideoMic Pro, it is definitely better than recording with the built-in microphone on the camera and also better than the built-in microphone on my phone. One problem that most people encounter is the sound of the lens autofocus mechanism being detected by the microphone. This occurs with both the built-in microphone and any other microphone you mount on the camera. A microphone mounted on top of the camera doesn't detect this noise with the same intensity as the built-in microphone but it is still present in the recordings. If using a camera-mounted microphone to detect the audio from an audience, you may need to have an omnidirectional microphone. Many camera-mounted microphones are directional and will not detect very much sound from the sides or behind the camera. When using any type of external microphone with the camera, it is recommend to disable automatic gain control (AGC) in the camera settings and then manually adjust the microphone sensitivity/volume level. Use headphones A final word on audio - most good cameras have an audio output socket. Connect headphones and wear them, to make sure you are always capturing audio. Otherwise, if the microphone's battery goes flat or if a wireless microphone goes out of range you may not notice. Choosing a lens The more light you get, the better. Bigger and more expensive lenses allow more light into the camera. Many of the normal lenses sold with a DSLR camera are acceptable but if it is a special occasion you may want to rent a more expensive lens for the day. If you already have a lens, it is a very good idea to test it in conditions similar to those you expect for the event you want to record. Recording duration limits Most DSLR cameras with video capability impose a 30 minute maximum recording duration This is basically the result of a friendly arrangement between movie studios and politicians to charge an extra tax on video recording technology and potentially make the movie studio bosses richer, supposedly justified by the fact that a tiny but exaggerated number of people use their cameras to record movies at the cinema. As a consequence, most DSLR manufacturers limit the duration of video recording so their product won't be subject to the tax, ensuring the retail price is lower and more attractive. On top of this, many DSLR cameras also have a 4GB file size limit if they use the FAT filesystem. Recording 1080p video at a high frame rate may hit the file size limit in 10 minutes, well before you encounter the 30 minute maximum recording duration. To deal with the file size issue, you can record at 720p instead of 1080p and use the frame rate 24fps. For events longer than 30 minutes or where you really want 1080p or a higher frame rate, there are some other options you can consider:
  • Buy or rent a proper video camera instead of using a DSLR camera
  • Using multiple cameras that can stop and be restarted at different times.
  • Manually stopping and restarting the camera if there are breaks in the event where it is safe to do so.
  • Use an app to control the camera and program it to immediately restart the recording each time it stops
  • Extract the raw output from the camera's HDMI socket and record into some other device or computer. There are several purpose-built devices
    that can be used this way with an embedded SSD for storage.
  • There are also some people distributing unofficial/alternative firmware images that remove the artificial 30 minute recording limit.
Camera settings There are many online tutorials and demonstration videos on YouTube that will help you optimize the camera settings for video. You may have already made recordings using the automatic mode. Adjusting some or all of the settings manually may help you create a more optimal recording. You will need to spend some time familiarizing yourself with the settings first. The first thing to check is white balance. This tells the camera the type of lighting in the location. If you set this incorrectly then the colours will be distorted. Many cameras have the ability to automatically set the white balance. For video, you may be able to change one or more settings that control the recording quality. These settings control the file compression ratio and image size. Typical image size settings are 720p and 1080p. Compression ratio may be controlled by a high/medium/low quality setting. Choosing the highest quality and biggest picture requires more space on the memory card and also means you reach the 4GB file size limit more quickly. A higher quality setting also implies a faster memory card is required, because the rate of megabytes per second written to the memory card is higher. Next you need to think about the frame rate. Events that involve fast moving subjects, such as sports, typically benefit from a higher frame rate. For other events it is quite acceptable to use 24 frames per second (fps). Higher frame rates also imply bigger file size and a requirement for a faster memory card. Once you have decided on the frame rate, the next thing to do is set the shutter speed. Use a shutter speed that is double the frame rate. For example, if using 24fps or 25fps, use a 1/50 shutter speed. The final two settings you need to adjust are the ISO and aperture. Set these based on the lighting conditions and extent to which the subjects are moving. For example, if the setting is dark or if you are trying to record fast moving subjects like athletes, vehicles or animals, use an ISO value of 800 or higher. Once you have chosen ISO, adjust the aperture to ensure the picture is sufficiently illuminated. Aperture also has a significant impact on the depth of field. Operating the camera: zoom and focus Many people use zoom lenses. It is not always necessary to change the zoom while recording a video, you can use software to zoom in and out on individual parts of the picture when editing it in post-production. If you do change the zoom while recording, it may be more difficult to maintain focus. Almost all lenses support manual focus (turning the focus ring by hand) and many support automatic focus. When shooting photographs with a DSLR, the mirror is down and the camera can use dedicated sensors for focus and light sensing. When shooting video, the mirror is up and the camera can not use the same focus sensors that are used in photography. Video recording uses a digital focussing algorithm based on contrast in the picture. If you take a lot of photos you are probably quite accustomed to the fast and precise autofocus for photography and you will notice that keeping a video in focus is more challenging. As mentioned already, one of the first things you can do to keep focus simple is to avoid zooming while recording. Record in a higher resolution than you require and then zoom with software later. Some people record using 4k resolution even when they only want to produce a 720p video, as they can digitally zoom in to different parts of the 4k recording without losing detail. If the subject is very stationary (people sitting at a desk for an interview is a typical example), you may be able to set the camera to manual focus and not change it at all while recording. If you choose to enable autofocus while recording, any built-in camera microphone or microphone mounted on the camera is likely to detect sounds from the motorized focus system. Ultimately, the autofocus mechanism is not accurate for all subjects and you may be unable to stop them moving around so you will need to change the focus manually while recording. It requires some practice to be able to do this quickly without overshooting the right focus. To make life more tricky, Nikon and Canon focus rings rotate in the opposite direction, so if you are proficient using one brand you may feel awkward if you ever have to use the other. A good way to practice this skill is to practice while in the car or on the train, pointing at different subjects outside the window and trying to stay in focus as you move from one subject to the next. Make a trial run Many events, from weddings right up to the Olympic Games opening ceremony, have a trial run the day before. One reason for that is to test the locations and settings of all the recording and broadcasting equipment. If a trial run isn't possible for your event, you may find some similar event to practice recording and test your equipment. For example, if you are planning to record a wedding, you could try and record a Sunday mass in the same church. Backup and duplicate the recordings before leaving the event If you only have one copy of the recordings and the equipment is stolen or damaged you may be very disappointed. Before your event, make a plan to duplicate the raw audio and video recordings so that several people can take copies away with them. Decide in advance who will be responsible for this, ensure there will be several portable hard disks and estimate how much time it will take to prepare the copies and factor this into the schedule. Conclusion All the products described can be easily purchased from online retailers. You may not need every accessory that is mentioned as it depends on the type of event you record. The total cost of buying or renting the necessary accessories may be as much as the cost of the camera itself so if you are new to this you may need to think carefully about making a budget with a spreadsheet to do it correctly. Becoming familiar with the camera controls and practicing the techniques for manual focus and zoom can take weeks or months. If you enjoy photography this can be time well spent but if you don't enjoy it then you may not want to commit the time necessary to make good quality video. Don't rule out options like renting equipment instead of buying it or crowdsourcing, asking several participants or friends to help make recordings with their own equipment. For many events, audio is far more indispensable than video and as emphasizing at the beginning of this article, it is recommended that you should be one hundred percent confident in your strategy for recording audio before you start planning to record video.

11 August 2015

Jonathan McDowell: Programming the FST-01 (gnuk) with a Bus Pirate + OpenOCD

Last year at DebConf14 Lucas authorized the purchase of a handful of gnuk devices, one of which I obtained. At the time it only supported 2048 bit RSA keys. I took a look at what might be involved in adding 4096 bit support during DebConf and managed to brick my device several times in doing so. Thankfully gniibe was on hand with his STLinkV2 to help me recover. However subsequently I was loathe to experiment further at home until I had a suitable programmer. As it is this year has been busy and the 1.1.x release train is supposed to have 4K RSA (as well as ECC) support. DebConf15 is coming up and I felt I should finally sort out playing with the device properly. I still didn t have a suitable programmer. Or did I? Could my trusty Bus Pirate help? The FST-01 has an STM32F103TB on it. There is an exposed SWD port. I found a few projects that claimed to do SWD with a Bus Pirate - Will Donnelly has a much cloned Python project, the MC HCK project have a programmer in Ruby and there s LibSWD though that s targeted to smarter programmers. None of them worked for me; I could get the Python bits as far as correctly doing the ID of the device, but not reading the option bytes or successfully flashing (though I did manage an erase). Enter the old favourite, OpenOCD. This already has SWD support and there s an outstanding commit request to add Bus Pirate support. NodoNogard has a post on using the ST-Link/V2 with OpenOCD and the FST-01 which provided some useful pointers. I grabbed the patch from Gerrit, applied it to OpenOCD git and built an openocd.cfg that contained:
source [find interface/buspirate.cfg]
buspirate_port /dev/ttyUSB0
buspirate_vreg 1
buspirate_mode normal
transport select swd
source [find target/stm32f1x.cfg]
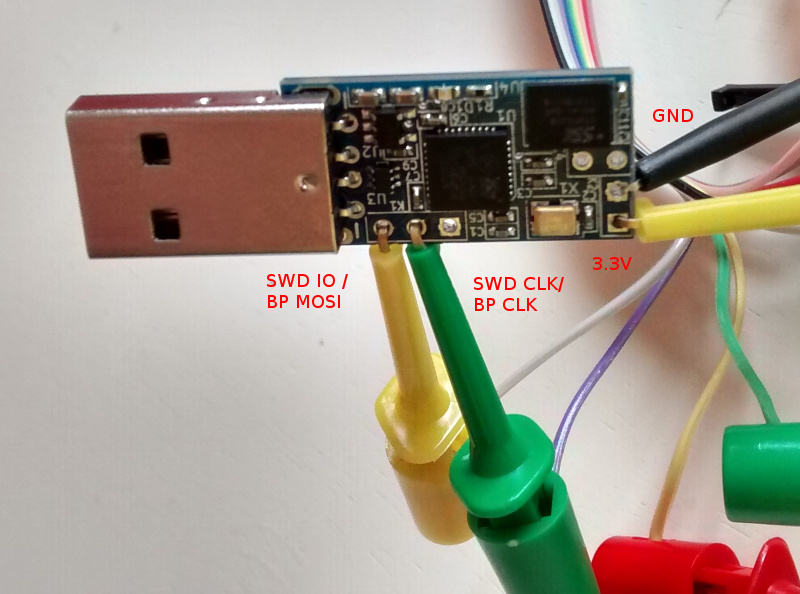
My BP has the Seeed Studio probe cable, so my hookups look like this: Bus Pirate + FST-01 SWD connection That s BP MOSI (grey) to SWD IO, BP CLK (purple) to SWD CLK, BP 3.3V (red) to FST-01 PWR and BP GND (brown) to FST-01 GND. Once that was done I fired up OpenOCD in one terminal and did the following in another:

$ telnet localhost 4444
Trying ::1...
Trying 127.0.0.1...
Connected to localhost.
Escape character is '^]'.
Open On-Chip Debugger
> reset halt
target state: halted
target halted due to debug-request, current mode: Thread
xPSR: 0x01000000 pc: 0xfffffffe msp: 0xfffffffc
Info : device id = 0x20036410
Info : SWD IDCODE 0x1ba01477
Error: Failed to read memory at 0x1ffff7e2
Warn : STM32 flash size failed, probe inaccurate - assuming 128k flash
Info : flash size = 128kbytes
> stm32f1x unlock 0
Device Security Bit Set
stm32x unlocked.
INFO: a reset or power cycle is required for the new settings to take effect.
> reset halt
target state: halted
target halted due to debug-request, current mode: Thread
xPSR: 0x01000000 pc: 0xfffffffe msp: 0xfffffffc
> flash write_image erase /home/noodles/checkouts/gnuk/src/build/gnuk.elf
auto erase enabled
wrote 109568 bytes from file /home/noodles/checkouts/gnuk/src/build/gnuk.elf in 95.055603s (1.126 KiB/s)
> stm32f1x lock 0
stm32x locked
> reset halt
target state: halted
target halted due to debug-request, current mode: Thread 
xPSR: 0x01000000 pc: 0x08000280 msp: 0x20005000
Then it was a matter of disconnecting the gnuk from the BP, plugging it into my USB port and seeing it come up successfully:
usb 1-2: new full-speed USB device number 11 using xhci_hcd
usb 1-2: New USB device found, idVendor=234b, idProduct=0000
usb 1-2: New USB device strings: Mfr=1, Product=2, SerialNumber=3
usb 1-2: Product: Gnuk Token
usb 1-2: Manufacturer: Free Software Initiative of Japan
usb 1-2: SerialNumber: FSIJ-1.1.7-87063020
usb 1-2: ep 0x82 - rounding interval to 1024 microframes, ep desc says 2040 microframes
More once I actually have a 4K key loaded on it.

10 August 2015

Daniel Pocock: Going 4K

I recently started using a 4K monitor. I've generally had a positive experience and thought I would share some comments about it. What can you do with 4K resolution?
  • View the entire London Underground map or Swiss railway map without having to zoom or scroll
  • Run a mail client like Thunderbird/Icedove and an IRC client side-by-side
  • Run Eclipse and the Android emulator side-by-side
  • Run Eclipse and some other program you are debugging side-by-side
  • When reading a PDF, show a whole page at a time but only using half the screen
Are there hardware issues? Originally the hardware was expensive and people would have to do things like using multiple cables to join their video card to their 4K screen. The latest generation of video cards and monitors don't have this problem. I chose to use NVIDIA's entry-level Quadro K420 card, the smallest and least expensive Quadro supporting 4K. The PC is a HP Z800 workstation. HP suggests they only certify the K420 with their latest workstations (e.g. Z840) but I have observed no problem using it in a Z800. The monitor is a 32" BenQ display. After reading comments from other 4K users, I felt that any monitor less than 30" would not help me get the most from the world of 4K. The monitor connects to the video card using a DisplayPort 1.2 cable that was in the box with the monitor. I've been able to get sound through the monitor but I found the volume is always a bit low and at one point sound stopped completely. What about software issues? Everything just appeared to work although the fonts are a bit smaller than what I'm used to. This appears to be related to DPI issues. DPI is not automatically detected and several applications have their own way of handling non-standard DPI. Discussion about this started on the debian-devel mailing list, given that non-standard DPI will be an issue with many newer monitors, handheld devices and more exotic displays such as televisions. Some web sites just don't look so good when the browser window is maximized to 4K resolution while others use the extra space really well. For example, using the AirBNB search, the maps show more detail but using another hotel booking site I found that it was still trying to render a map within a constant size region using less than ten percent of the page.

Mirco Bauer: Smuxi 1.0 "Finally" Release

And here we go again! We're proud to announce the new version of Smuxi, release 1.0 "Finally". During the development, 20 bug reports and 10 feature requests in 285 commits were worked on.

Finally 1.0 Smuxi is celebrating its 10th anniversary! 10 years ago, Mirco Bauer made the first commit to the Smuxi source code repository and is still very committed to it. He started the Gnosmirc project in 2005 when the only way a 24/7 "always-on" experience with IRC meant you had to use a console based IRC client like bitchx, irssi or epic combined with screen and SSH. This looks very practical at first and is a powerful Unix-ish way of accomplishing that job, but it has the big downside that it doesn't integrate with a desktop environment like GNOME. A bit later the Gnosmirc project was renamed to Smuxi when the new code architecture allowed other frontend implementations besides the GNOME one. The ncurses/STFL based text frontend was later implemented and is considered stable and useful enough for day to day use, but still has some rough edges. WinForms and WPF frontends also exist but need more work to reach a usable state. At this point Smuxi 1.0 contains all features that we could have imagined and even goes beyond with very advanced features like message patterns or language agnostic scripting.

Changes since Smuxi 0.11

Message Persistence One of the biggest drawbacks of the IRC protocol ever was that messages can't be retrieved from the IRC server because the IRC server is simply relaying messages to the connected clients. So, if an IRC client is freshly started and connects it starts to receive new messages, but all message you had received before are no longer available. This always made IRC in a way "volatile" unlike other communication systems like email where messages are relayed and stored on the client side. One common approach for IRC clients is to store log files in a text file. This is a simple feature and gives the user the possibility to read older conversations. Smuxi also supports text file logging like other IRC clients but it has a big user experience drawback as you need to open the file from the disk outside of the IRC client. In Smuxi 1.0 messages sent and received are now stored on the disk in a way they can automatically be retrieved/loaded when you restart Smuxi. It is like you have never closed Smuxi! This feature was already available in Smuxi for some time as a technical preview and it used the Db4o object database, but we were never happy about the performance neither with the stability so it always stayed an optional feature you need to enable. This year we tried a new message buffer backend using the famous SQLite database and it works much faster and stable as a rock. So finally we can enable this feature by default because it just works and enhanced your experience. We hope you enjoy it. Documentation of how you can change Smuxi message buffer backend and behavior can be found here. For instructions how to convert your existing db4o history to SQLite can be found in the "smuxi-message-buffer tool" section.

User Interface Enhancements
  • Synced message markers: the position of of the seen/unseen messages marker is pushed to the smuxi-server and remembered when the frontend reconnects. (Sebastian Poeplau)
  • Persistent message markers: the message marker position is also remembered across Smuxi(-server) restarts.
  • Message Counter: in addition to the highlight counter next to a chat new/unseen messages are also counted. This makes it easy to identify chats with much traffic.
  • Single application instance support. If you start Smuxi again from the menu it will bring the existing instance into the foreground. This makes the Ubuntu Messaging Menu much nicer.
  • The command/message entry is alignment with the messages. (Lex Berezhny)

Text Frontend Enhancements
  • The console background color can now be configured using: /config set STFL/Interface/TerminalBackgroundColor = #000000 (Ond ej Ho ek)
  • The text color contrast if nicks with the background is now ensured (Ond ej Ho ek) #1033
  • Messages containing images will not be skipped but their alternative text is shown instead (Ond ej Ho ek) #1035

New smuxi-message-buffer tool This is a new commandline tool that allows you to convert and export the message history of Smuxi message buffer files. This can be used to convert your existing Db4o history to SQLite like this for example:
for DB_DB4O in $HOME/.local/share/smuxi/buffers/*/*/*/*.db4o; do
    DB_SQLITE=$ DB_DB4O/.db4o/.sqlite3 
    smuxi-message-buffer convert $DB_DB4O $DB_SQLITE
done
Smuxi shouldn't be running when using this tool.

Scripting Enhancements

New Hook Points Smuxi 1.0 supports with the following new hook points:
  • engine/protocol-manager/on-presence-status-changed/ This hook point is raised when the presence status of a protocol manager changes. This happens for example when an IRC connection toggles the away state.
  • engine/session/on-event-message/ This hook point raises event messages that usually begin with "-!-". This can be useful to track state changes that are shown as a message without having a dedicated hook point for it.
  • engine/session/command-$cmd/ This hook point is raised on the engine side for commands, e.g. /some_command that isn't handled by the frontend or engine built-in commands. This is useful for commands that should be available for all frontends and isn't specific to the frontend environment.

New Plugins The following new plugins are supported by Smuxi 1.0:
  • topic-diff: Shows the word differences of the topic after topic changes. (meebey)
  • away-nick: Automatically appends and removes $AWAY_SUFFIX to/from the nick name when you go away using the /away command or by disconnecting all frontends from the smuxi-server. (meebey)
  • system-info: Shows system info. Includes system kernel version, distro name, and CPU vendor information. (AK0)
  • now-playing: This plugin is not new but was rewritten in Python to get rid of the spaghetti code monster which was written in Bash. (jamesaxl)

IRC Enhancements
  • NICKSERV support Notices from Nick/ChanServ are no longer shown on all channels as they like to send greeting messages and other spam which is annoying to see on all channels. #868
  • Automatic rejoin of channels protected with a key works as expected again
  • Connecting to irc.gitter.im is now supported. Gitter's IRCd implementation has a bug in the IRC protocol which is now tolerated.

Twitter Enhancements
  • The /search command shows tweets as live stream
  • Added /delete, /favorite and /unfavorite commands

Behind the Scenes
  • Re-licensed smuxi-common from GPLv2 to MIT/X11

Contributors Contributors to this release are the following people:
  • Mirco Bauer (199 commits)
  • Carlos Mart n Nieto (15 commits)
  • Andr s G. Aragoneses (14 commits)
  • Piotr Dr g (12 commits)
  • Ond ej Ho ek (11 commits)
  • Oliver Schneider (5 commits)
  • Calvin B (4 commits)
  • Victor Seva (3 commits)
  • Will Johansson (2 commits)
  • Sebastian Poeplau (2 commits)
  • Julian Taylor (2 commits)
  • James Axl (2 commits)
  • Daniel Mustieles (2 commits)
  • Christopher James Halse Rogers (2 commits)
  • . Uzun (1 commit)
  • Lex Berezhny (1 commit)
  • Kalle Kaitala (1 commit)
  • Jordi Mas (1 commit)
  • Joe Hansen (1 commit)
  • Jimmie Elvenmark (1 commit)
  • Dimitris Spingos (1 commit)
  • Dean Lee (1 commit)
  • Cl ment Bourgeois (1 commit)
  • Carlos Hernandez (1 commit)
Thank you very much for your contributions to Smuxi! Want this? Go here and grab it right now!

Posted Sun Aug 9 17:48:18 2015

9 August 2015

Yves-Alexis Perez: WPS and Network Manager

So, everybody knows that WPS (Wi-Fi Protected Setup) is broken. But sometimes, you don't own the access point, and you'd just want the wireless to work. That happens for example when you're a guest in some place using an Orange Livebox and you don't have the WPA passphrase (usually because it's written somewhere you don't have access too, or because someone forgot to tell you). Liveboxes WPS is the press button thing: you press a button on the front for one second, then any device can connect in the next two minutes. That works fine with Android devices, for example, but it didn't work with my laptop and NetworkManager, which doesn't support WPS at all. Fortunately, the underlying piece of software (wpa_supplicant) does support WPS, and even the push button style. And you can nicely ask it to reveal the passphrase to you with the following trick.
  1. Disconnect NetworkManager from the network, disable the wireless link, stop it; just make sure wpa_supplicant is not running;
  2. Put a stub wpa_supplicant.conf file with only the following content:
    update_config=1
    
  3. Start wpa_supplicant in the foreground with your stub config file:
    wpa_supplicant -iwlan0 -c wpa_supplicant.conf
    
  4. Start wpa_cli
Inside wpa_cli:
  1. Scan the network:
    scan
    
  2. Get the results:
    scan_results
    
    and identity the bssid of the Livebox
  3. Press the WPS button on the Livebox
  4. Run
    wps_pbc <bssid>
    ; some text should appear in the wpa_cli window, and it should eventually connect successfully (at that point you can even run a dhclient on wlan0)
  5. Run
    save_config
    
The last command will update your stub configuration file, adding a new network block with the passphrase in the clear. You can then use that passphrase inside Network Manager if it's more convenient for you. There might be something easier, but at least it worked just fine for me during the holidays.

DebConf team: TecKids @ DebConf: Register Until Tuesday (Posted by DebConf Team)

We are happy to announce that TecKids, a non-profit specialising in working with kids, teaching them technonology, and fostering self-sustaining communities amongst them, will be holding a workshop from 15.08. to 18.08. The focus is on kids aged 10-15 years old, but kids aged 8-16 years old are welcome to attend if they can follow the course without supervision of theirs parents. Admission is free of charge, but registration through TecKids web form is mandatory. Registration is open until Tuesday, 11 August. The rough schedule for now is: You will be kept up to date on any changes to the schedule and other details by the TecKids team after registration. It is important that you check mail before heading to DebConf in order to receive any last-minute informations.

8 August 2015

Dirk Eddelbuettel: drat 0.1.0: Even more repository support

drat and double drat A new version 0.1.0 of the drat package arrived on CRAN today. Its name stands for drat R Archive Template, and it helps with easy-to-create and easy-to-use repositories for R packages, and is finding increasing by other projects. This version 0.1.0 builds on the previous releases and now adds complete support for binaries for both Windows and OS X. This builds on what had been added in the previous release 0.0.4. This and other new features are listed below: Also of note: The rOpenSci project now uses drat to distribute their code, and Carl Boettiger has written a nice blog post about it. Courtesy of CRANberries, there is a comparison to the previous release. More detailed information is on the drat page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

6 August 2015

Eduard Sanou: Reproducible builds on Debian for GSoC 2015, 1st update

This is the second blog post I m writing about my experiences contributing to Debian for Google Summer of Code 2015 (check my first post)

Status update

First month It s been two months and a few days since the GSoC started. During the first month I worked on fixing specific packages, mainly concerning issues with timestamps, which is a very common source of unreproducibility. In many cases, during the build process files are compressed into gzip or zip archives, which store the creation time of files in the metadata. This can lead to unreproducible results when there is timezone variation between builds (easily fixed setting the timezone to UTC before the compression happens). In some cases the compressed files are generated during the build, and thus add build times in the metadata of compressed files (in this case the creation date of the files needs to be normalized somehow). As explained in my application, I finished exams on the end of June, that s why I chose to work on small fixes first, so that I could make the most out of my time between studying and finishing university projects and reports. I m happy with my first month, as I have worked as originally planned. Actually, my estimation of the number of bugs I could submit every week was surpassed in reality!

Second month Once the university was over, I started dedicating myself fully to the project. This allowed me to start working on toolchain fixes, following my original plan on working with timestamp related issues. In particular I have been working a lot in implementing a proposal for deterministic timestamps that appeared in the reproducible builds project. The idea is to define an environment variable called SOURCE_DATE_EPOCH that contains a known timestamp in Unix epoch format. With this variable exported, tools that would embed the localtime in their generated or processed files, can use this externally supplied date. This would happen only if SOURCE_DATE_EPOCH is exported, so the behaviour of the tool wouldn t change if the variable is not set. The first package I patched to implement this behaviour was gcc. The reason behind this is that there are about 420 unreproducible packages due to using the __DATE__, __TIME__ and __TIMESTAMP__ C macros. My patch changes the behavior of the macros __DATE__ and __TIME__ if SOURCE_DATE_EPOCH is exported. I submitted this patch to the gcc-patches list. Even though there was some interesting discussions in the list, the patch has not been accepted yet. Seeing how the reproducible builds idea is gaining momentum and becoming widespread, I m positive that at some point the gcc people will be more receptive for such patch. The second work with SOURCE_DATE_EPOCH was in debhelper; I patched this building tool to export the variable with the latest debian/changelog entry timestamp. With this patch, all the tools that run under dh will be able to use it to embed deterministic timestamps. Unfortunately some parts of the build process of some packages don t happen under debhelper, so the variable needs to be exported in a different way. Having submitted the debhelper patch allowed many packages to become reproducible after the tools that embedded timestamps were patched to honour SOURCE_DATE_EPOCH. As of today, the toolchain packages I have patched to do that are: gcc, libxslt, gettext, ghostscript and qt4-x11 (qhelpgenerator). I have also continued working on fixing individual packages affected by timestamps, random orderings (such as the ones from listing hash keys) and locale depending orderings; I have tagged packages in our infrastructure to note what kind of issue makes them unreproducible; I have updated some parts of the Reproducible Builds Wiki.

Impressions about reproducible builds The work I did during the first month felt a bit tedious sometimes: it didn t require much creativity or thinking as most of the fixes where quite mechanical, following a recipe. After I became free from university duties, I started looking into less trivial issues, which require more deep investigation and feel more rewarding once they are fixed. I also worked on toolchain fixes, which need more work and need more care. Fixing toolchain packages feels particularly rewarding because they can cause many packages to become reproducible at once. There is a very active community in the reproducible builds project! It s great to see so many people contributing to this project spending so many hours and putting so much effort. I ve felt very welcome from the beginning and I have gotten kind replies and helpful answers to all the questions and doubts I ve had, both from my mentor and from the other people in the project. I want to add that I m still amazed by the awesome infrastructure set up for the reproducible builds project. The team is using a Jenkins machine to continuously build packages to check for reproducibility, with irc notifications for changes, and also with a really useful web interface to list all the packages organized by issues that allows exploring them individually with all the available information. Also not only the infrastructure is used to build Debian amd64 packages, but also FreeBSD, NetBSD, OpenWRT, coreboot and lately Debian armhf with the help of a few new arm nodes.

Impressions about working on a free software project This was my first time working on a community driven free software project and I ve learned so many things. Something I learned during the first days, which is even more present in such wide project like the reproducible builds, is that contributing is not just writing patches for the features you want; you also need to convince the maintainer of the package to accept the patch! I was a bit surprised at the beginning because even if this is a Debian project, that aims to make changes to the whole distribution, decisions are not absolute for the whole Debian project. After taking decisions within the reproducible builds teams on how to approach things, we need to convince the rest of the Debian developers (mainly maintainers) to follow them, as they are allowed to disagree. So it is required to work together for solutions that makes everyone comfortable, usually with discussions on mailing lists or irc. There is another fact that I wasn t expecting before getting involved in this project. The kind of teamwork I have done previously involves having a leader who decides how stuff is done, who takes decisions when needed and oversees the whole project. There seems to be a different philosophy in Debian. Instead of having a leader, everyone tries their best, trying to convince the others that their solution is good, often by showing an implementation of the solution and providing proof that it works, rather than trying to get the solution accepted before coding it. Also, solutions and ideas are valued for their quality rather than by the position of the person submitting them, and there is no hierarchy within the group: all comments and advices are taken equally, valuing their usefulness regardless of who gives them. Usually there are no votes when deciding things. Members try their best on their approaches, trying to convince others as best as they can. And even if someone disagrees they may end up accepting the solution if they don t manage to convince the original proposer of doing things differently. The idea is to spend more time working and coding than arguing and deciding on the way to do things. So far I ve seen this approach to be very efficient :) I ve been told by my mentor that for difficult cases there exist a Debian committee that helps mediate on disagreements, but that is only used as a last option, probably when the discussion gets heated up.

Personal experience Overall I m very happy to finally having set my foot in the free software community, where I m able to contribute to the kind of software I have been using for years. The sense of community in Debian is really big, and everyone is invited to participate. I think that Google is doing an awesome job with the Google Summer of Code, not only because it gives a lot to free software but because it helps students to join the free software world as contributors (which is something that may be difficult to get into when you don t know how to begin, as it happened to myself for some time). I plan to continue contributing to the free software world, and I d encourage anyone to find projects to get involved and contribute as well! Happy hacking to everyone!

Next.

Previous.