Search Results: "ron"

20 August 2016

Francois Marier: Remplacer un disque RAID d fectueux

Traduction de l'article original anglais https://feeding.cloud.geek.nz/posts/replacing-a-failed-raid-drive/. Voici la proc dure que j'ai suivi pour remplacer un disque RAID d fectueux sur une machine Debian.

Remplacer le disque Apr s avoir remarqu que /dev/sdb a t expuls de mon RAID, j'ai utilis smartmontools pour identifier le num ro de s rie du disque retirer :
smartctl -a /dev/sdb
Cette information en main, j'ai ferm l'ordinateur, retir le disque d fectueux et mis un nouveau disque vide la place.

Initialiser le nouveau disque Apr s avoir d marr avec le nouveau disque vide, j'ai copi la table de partitions avec parted. Premi rement, j'ai examin la table de partitions sur le disque dur non-d fectueux :
$ parted /dev/sda
unit s
print
et cr une nouvelle table de partitions sur le disque de remplacement :
$ parted /dev/sdb
unit s
mktable gpt
Ensuite j'ai utilis la commande mkpart pour mes 4 partitions et je leur ai toutes donn la m me taille que les partitions quivalentes sur /dev/sda. Finalement, j'ai utilis les commandes toggle 1 bios_grub (partition d'amorce) et toggle X raid (o X est le num ro de la partition) pour toutes les partitions RAID, avant de v rifier avec la commande print que les deux tables de partitions sont maintenant identiques.

Resynchroniser/recr er les RAID Pour synchroniser les donn es du bon disque (/dev/sda) vers celui de remplacement (/dev/sdb), j'ai ex cut les commandes suivantes sur mes partitions RAID1 :
mdadm /dev/md0 -a /dev/sdb2
mdadm /dev/md2 -a /dev/sdb4
et j'ai gard un oeil sur le statut de la synchronisation avec :
watch -n 2 cat /proc/mdstat
Pour acc l rer le processus, j'ai utilis le truc suivant :
blockdev --setra 65536 "/dev/md0"
blockdev --setra 65536 "/dev/md2"
echo 300000 > /proc/sys/dev/raid/speed_limit_min
echo 1000000 > /proc/sys/dev/raid/speed_limit_max
Ensuite, j'ai recr ma partition swap RAID0 comme suit :
mdadm /dev/md1 --create --level=0 --raid-devices=2 /dev/sda3 /dev/sdb3
mkswap /dev/md1
Par que la partition swap est toute neuve (il n'est pas possible de restorer une partition RAID0, il faut la re-cr er compl tement), j'ai d faire deux choses:
  • remplacer le UUID pour swap dans /etc/fstab, avec le UUID donn par la commande mkswap (ou bien en utilisant la command blkid et en prenant le UUID pour /dev/md1)
  • remplacer le UUID de /dev/md1 dans /etc/mdadm/mdadm.conf avec celui retourn pour /dev/md1 par la commande mdadm --detail --scan

S'assurer que l'on peut d marrer avec le disque de remplacement Pour tre certain de bien pouvoir d marrer la machine avec n'importe quel des deux disques, j'ai r install le boot loader grub sur le nouveau disque :
grub-install /dev/sdb
avant de red marrer avec les deux disques connect s. Ceci confirme que ma configuration fonctionne bien. Ensuite, j'ai d marr sans le disque /dev/sda pour m'assurer que tout fonctionnerait bien si ce disque d cidait de mourir et de me laisser seulement avec le nouveau (/dev/sdb). Ce test brise videmment la synchronisation entre les deux disques, donc j'ai d red marrer avec les deux disques connect s et puis r -ajouter /dev/sda tous les RAID1 :
mdadm /dev/md0 -a /dev/sda2
mdadm /dev/md2 -a /dev/sda4
Une fois le tout fini, j'ai red marrer nouveau avec les deux disques pour confirmer que tout fonctionne bien :
cat /proc/mdstat
et j'ai ensuite ex cuter un test SMART complet sur le nouveau disque :
smartctl -t long /dev/sdb

Russell Coker: Basics of Backups

I ve recently had some discussions about backups with people who aren t computer experts, so I decided to blog about this for the benefit of everyone. Note that this post will deliberately avoid issues that require great knowledge of computers. I have written other posts that will benefit experts. Essential Requirements Everything that matters must be stored in at least 3 places. Every storage device will die eventually. Every backup will die eventually. If you have 2 backups then you are covered for the primary storage failing and the first backup failing. Note that I m not saying only have 2 backups (I have many more) but 2 is the bare minimum. Backups must be in multiple places. One way of losing data is if your house burns down, if that happens all backup devices stored there will be destroyed. You must have backups off-site. A good option is to have backup devices stored by trusted people (friends and relatives are often good options). It must not be possible for one event to wipe out all backups. Some people use cloud backups, there are many ways of doing this with Dropbox, Google Drive, etc. Some of these even have free options for small amounts of storage, for example Google Drive appears to have 15G of free storage which is more than enough for all your best photos and all your financial records. The downside to cloud backups is that a computer criminal who gets access to your PC can wipe it and the backups. Cloud backup can be a part of a sensible backup strategy but it can t be relied on (also see the paragraph about having at least 2 backups). Backup Devices USB flash sticks are cheap and easy to use. The quality of some of those devices isn t too good, but the low price and small size means that you can buy more of them. It would be quite easy to buy 10 USB sticks for multiple copies of data. Stores that sell office-supplies sell USB attached hard drives which are quite affordable now. It s easy to buy a couple of those for backup use. The cheapest option for backing up moderate amounts of data is to get a USB-SATA device. This connects to the PC by USB and has a cradle to accept a SATA hard drive. That allows you to buy cheap SATA disks for backups and even use older disks as backups. With choosing backup devices consider the environment that they will be stored in. If you want to store a backup in the glove box of your car (which could be good when travelling) then a SD card or USB flash device would be a good choice because they are resistant to physical damage. Note that if you have no other options for off-site storage then the glove box of your car will probably survive if your house burns down. Multiple Backups It s not uncommon for data corruption or mistakes to be discovered some time after it happens. Also in recent times there is a variety of malware that encrypts files and then demands a ransom payment for the decryption key. To address these problems you should have older backups stored. It s not uncommon in a corporate environment to have backups every day stored for a week, backups every week stored for a month, and monthly backups stored for some years. For a home use scenario it s more common to make backups every week or so and take backups to store off-site when it s convenient. Offsite Backups One common form of off-site backup is to store backup devices at work. If you work in an office then you will probably have some space in a desk drawer for personal items. If you don t work in an office but have a locker at work then that s good for storage too, if there is high humidity then SD cards will survive better than hard drives. Make sure that you encrypt all data you store in such places or make sure that it s not the secret data! Banks have a variety of ways of storing items. Bank safe deposit boxes can be used for anything that fits and can fit hard drives. If you have a mortgage your bank might give you free storage of papers as part of the service (Commonwealth Bank of Australia used to offer that). A few USB sticks or SD cards in an envelope could fit the papers criteria. An accounting firm may also store documents for free for you. If you put a backup on USB or SD storage in your waller then that can also be a good offsite backup. For most people losing data from disk is more common than losing their wallet. A modern mobile phone can also be used for backing up data while travelling. For a few years I ve been doing that. But note that you have to encrypt all data stored on a phone so an attacker who compromises your phone can t steal it. In a typical phone configuration the mass storage area is much less protected than application data. Also note that customs and border control agents for some countries can compel you to provide the keys for encrypted data. A friend suggested burying a backup device in a sealed plastic container filled with dessicant. That would survive your house burning down and in theory should work. I don t know of anyone who s tried it. Testing On occasion you should try to read the data from your backups and compare it to the original data. It sometimes happens that backups are discovered to be useless after years of operation. Secret Data Before starting a backup it s worth considering which of the data is secret and which isn t. Data that is secret needs to be treated differently and a mixture of secret and less secret data needs to be treated as if it s all secret. One category of secret data is financial data. If your accountant provides document storage then they can store that, generally your accountant will have all of your secret financial data anyway. Passwords need to be kept secret but they are also very small. So making a written or printed copy of the passwords is part of a good backup strategy. There are options for backing up paper that don t apply to data. One category of data that is not secret is photos. Photos of holidays, friends, etc are generally not that secret and they can also comprise a large portion of the data volume that needs to be backed up. Apparently some people have a backup strategy for such photos that involves downloading from Facebook to restore, that will help with some problems but it s not adequate overall. But any data that is on Facebook isn t that secret and can be stored off-site without encryption. Backup Corruption With the amounts of data that are used nowadays the probability of data corruption is increasing. If you use any compression program with the data that is backed up (even data that can t be compressed such as JPEGs) then errors will be detected when you extract the data. So if you have backup ZIP files on 2 hard drives and one of them gets corrupt you will easily be able to determine which one has the correct data. Failing Systems update 2016-08-22 When a system starts to fail it may limp along for years and work reasonably well, or it may totally fail soon. At the first sign of trouble you should immediately make a full backup to separate media. Use different media to your regular backups in case the data is corrupt so you don t overwrite good backups with bad ones. One traditional sign of problems has been hard drives that make unusual sounds. Modern drives are fairly quiet so this might not be loud enough to notice. Another sign is hard drives that take unusually large amounts of time to read data. If a drive has some problems it might read a sector hundreds or even thousands of times until it gets the data which dramatically reduces system performance. There are lots of other performance problems that can occur (system overheating, software misconfiguration, and others), most of which are correlated with potential data loss. A modern SSD storage device (as used in a lot of the recent laptops) doesn t tend to go slow when it nears the end of it s life. It is more likely to just randomly fail entirely and then work again after a reboot. There are many causes of systems randomly hanging or crashing (of which overheating is common), but they are all correlated with data loss so a good backup is a good idea. When in doubt make a backup. Any Suggestions? If you have any other ideas for backups by typical home users then please leave a comment. Don t comment on expert issues though, I have other posts for that.

19 August 2016

Simon D saulniers: [GSOC] Final report


The Google Summer of Code is now over. It has been a great experience and I m very glad I ve been able to make it. I ve had the pleasure to contribute to a project showing very good promise for the future of communication: Ring. The words privacy and freedom in terms of technologies are being more and more present in the mind of people. All sorts of projects wanting to achieve these goals are coming to life each days like decentralized web networks (ZeroNet for e.g.), blockchain based applications, etc.

Debian I ve had the great opportunity to go to the Debian Conference 2016. I ve been introduced to the debian community and debian developpers ( dd in short :p). I was lucky to meet with great people like the president of the FSF, John Sullivan. You can have a look at my Debian conference report here. If you want to read my debian reports, you can do so by browsing the Google Summer Of Code category on this blog.

What I have done Ring is now in official debian repositories since June 30th. This is a good news for the GNU/Linux community. I m proud to say that I ve been able to contribute to debian by working on OpenDHT and developing new functionalities to reduce network traffic. The goal behind this was to finally optimize the data persistence traffic consumption on the DHT. Github repository: https://github.com/savoirfairelinux/opendht

Queries Issues:
  • #43: DHT queries
Pull requests:
  • #79: [DHT] Queries: remote values filtering
  • 93: dht: return consistent query from local storage
  • #106: [dht] rework get timings after queries in master

Value pagination Issues:
  • #71: [DHT] value pagination
Pull requests:
  • #110: dht: Value pagination using queries
  • #113: dht: value pagination fix

Indexation (feat. Nicolas Reynaud) Pull requests:
  • #77: pht: fix invalid comparison, inexact match lookup
  • #78: [PHT] Key consistency

General maintenance of OpenDHT Issues:
  • #72: Packaging issue for Python bindings with CMake: $DESTDIR not honored
  • #75: Different libraries built with Autotools and CMake
  • #87: OpenDHT does not build on armel
  • #92: [DhtScanner] doesn t compile on LLVM 7.0.2
  • #99: 0.6.2 filenames in 0.6.3
Pull requests:
  • #73: dht: consider IPv4 or IPv6 disconnected on operation done
  • #74: [packaging] support python installation with make DESTDIR=$DIR
  • #84: [dhtnode] user experience
  • #94: dht: make main store a vector>
  • #94: autotools: versionning consistent with CMake
  • #103: dht: fix sendListen loop bug
  • #106: dht: more accurate name for requested nodes count
  • #108: dht: unify bootstrapSearch and refill method using node cache

View by commits You can have a look at my work by commits just by clicking this link: https://github.com/savoirfairelinux/opendht/commits/master?author=sim590

What s left to be done

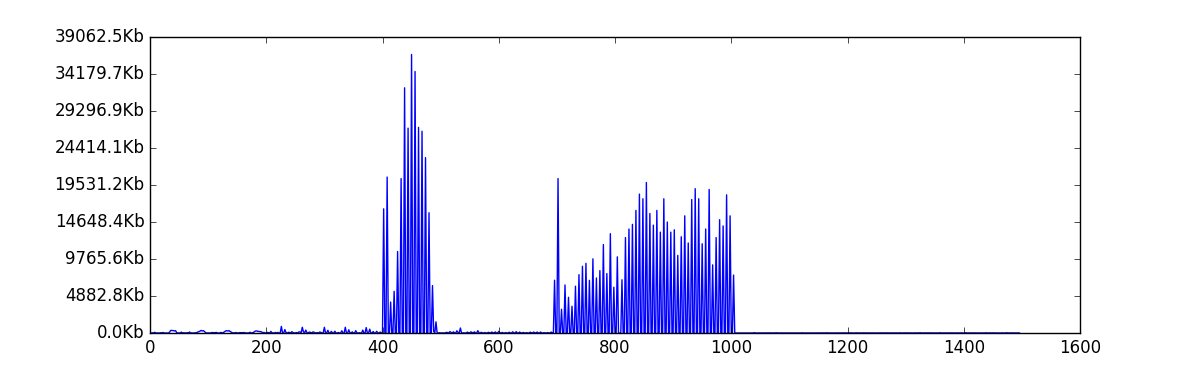
Data persistence The only thing left before achieving the totality of my work is to rigorously test the data persistence behavior to demonstrate the network traffic reduction. To do so we use our benchmark python module. We are able to analyse traffic and produce plots like this one:

Plot: 32 nodes, 1600 values with normal condition test.
This particular plot was drawn before the enhancements. We are confident to improve the results using my work produced during the GSOC.

TCP In the middle of the GSOC, we soon realized that passing from UDP to TCP would ask too much efforts in too short lapse of time. Also, it is not yet clear if we should really do that.

Olivier Gr goire: Conclusion Google Summer of Code 2016

SmartInfo project with Debian alt text 1. Me Before getting into the thick of my project, let me present myself:
I am Olivier Gr goire (Gasuleg), and I study IT engineering at cole de Technologie sup rieure in Montreal.
I am an technician in electronics, and I began object-oriented programming just last year.
I applied to GSoC because I loved the concept of the project that I would work on and I really wanted to be part of it. I also wanted to discover the word of the free software. 2. My Project During this GSoC, I worked on the Ring project. Ring is a free software for communication that allows its users to make audio or video calls, in pairs or groups, and to send messages, safely and freely, in confidence. Savoir-faire Linux and a community of contributors worldwide develop Ring. It is available on GNU/Linux, Windows, Mac OSX and Android. It can be associated with a conventional phone service or integrated with any connected object. Under this very easy to use software, there is a combination of technologies and innovations opening all kinds of perspectives to its users and developers. Ring is a free software whose code is open. Therefore, it is not the software that controls you. With Ring, you take control of your communication! Ring is an open source software under the GPL v3 license. Everyone can verify the codes and propose new ones to improve the software s performace. It is a guarantee of transparency and freedom for everyone!
Source: ring.cx The problem is about the typical user of Ring, the one who don t use the terminal to launch Ring. He has no information about what has happened in the system. My goal is to create a tool that display statistics of Ring. 3. Quick Explanation of What My Program Can Do The Code
Here are the links to the code I was working on all throughout the Google Summer of Code (You can see what I have done after the GSoC by clicking on the newest patchs):
Patch Status
Daemon On Review
Lib Ring Client (LRC) On Review
Gnome client On review
Remove unused code Merged
!!!!!CHANGE LINK TO PUT THE LATEST PATCHES BEFORE THE END OF GSOC!!!!! What Can Be Displayed?
This is the final list of information I can display and some ideas on what information we could display in the future:
Information Details Done?
Call ID The identification number of the call Yes
Resolution Local and remote Yes
Framerate Local and remote Yes
Codec Audio and video in local and remote Yes
Bandwidth Download and upload No
Performance use CPU, GPU, RAM No
Security level In SIP call No
Connection time No
Packets lost No

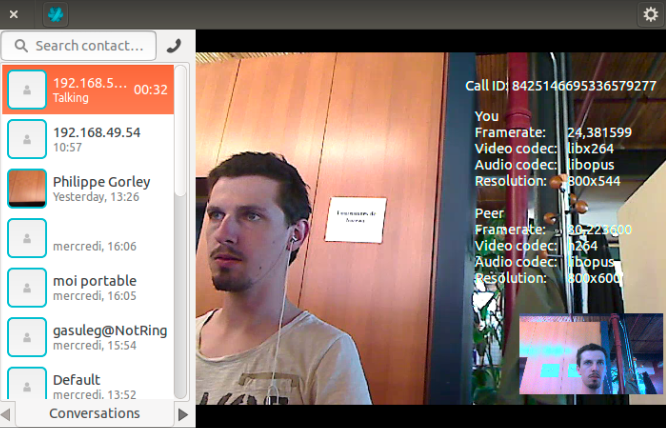
To launch it you need to right click on the call and click on Show advanced information .
alt text
To stop it, same thing: right click on the call and click on Hide advanced information .
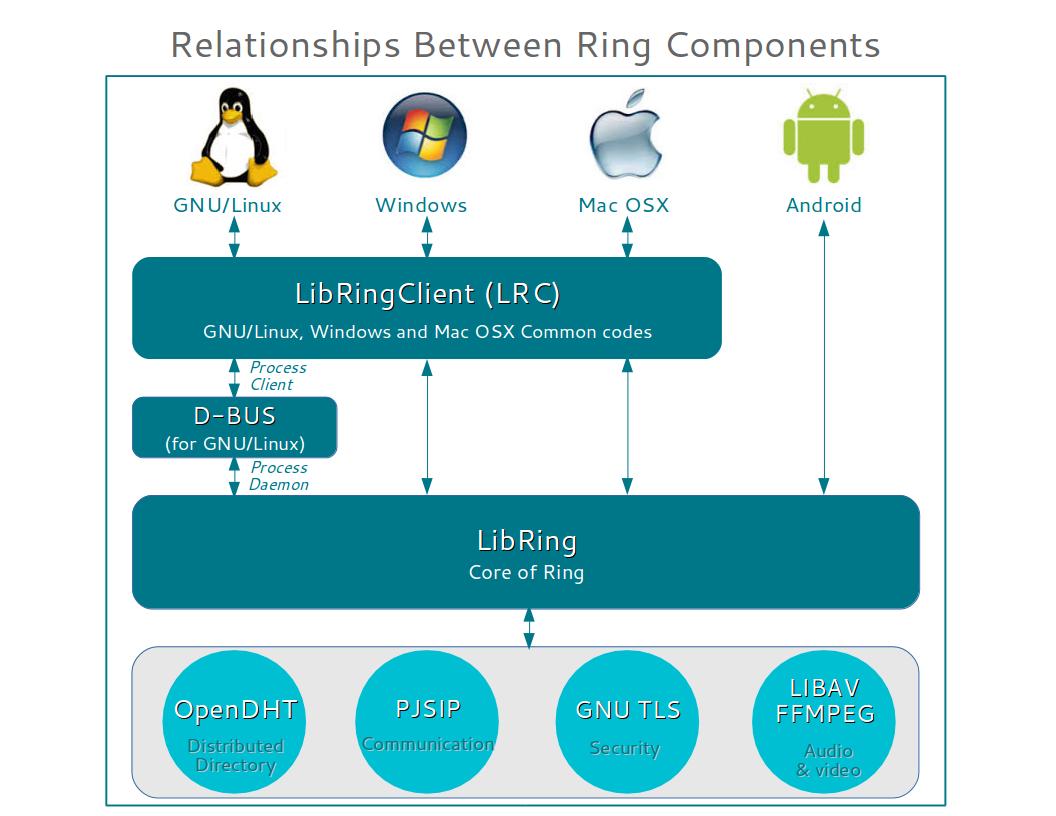
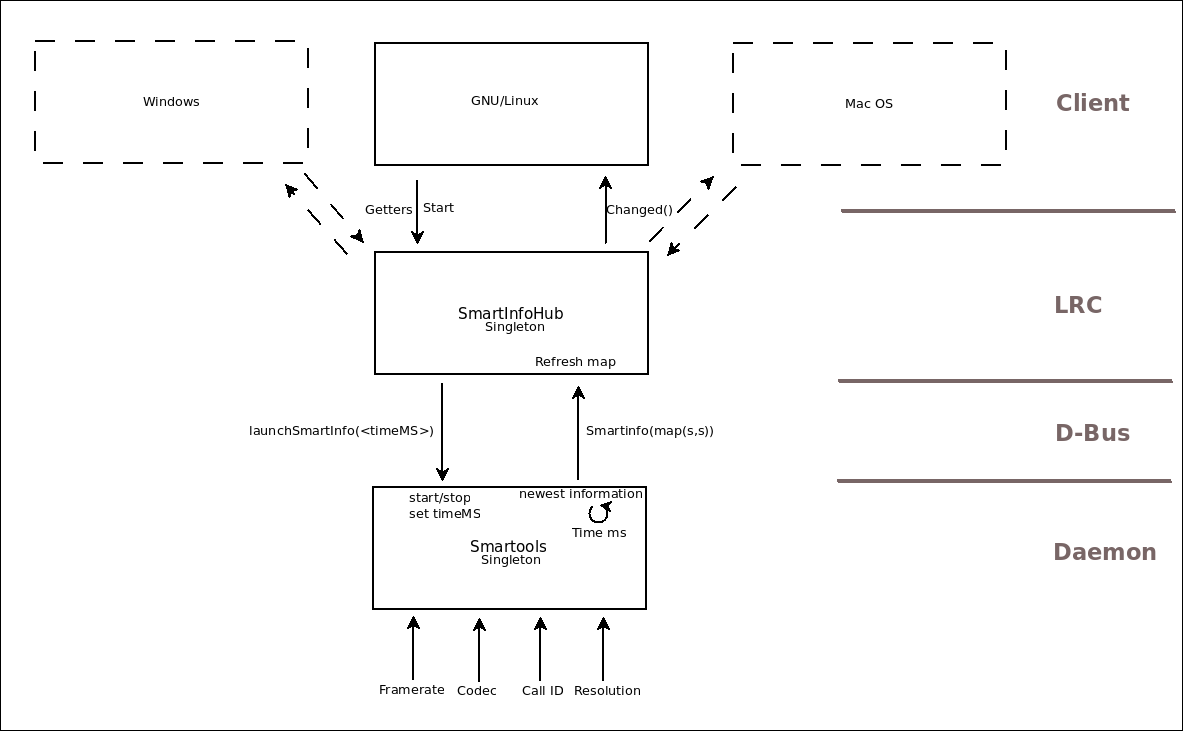
4. More Details About My Project My program needs to retrieve information from the daemon (LibRing) and then display it in gnome client. So, I needed to create a patch for the daemon, the D-Bus layer (in the daemon patch), LibRingClient and the GNU/Linux (Gnome) client.
This is what the architecture of the project looks like.
alt text
source: ring.cx And this is how I implemented my project.
alt text
5. Future of the Project 6. Thanks I would like to thank the following:
- The Google Summer of Code organisation, for this wonderful experience.
- Debian, for accepting my project proposal and letting me embark on this fantastic adventure.
- My mentor, Mr Guillaume Roguez, and all his team, for being there to help me.

Olivier Gr goire: Conclusion Google Summer of Code 2016

SmartInfo project with Debian alt text 1. Me Before getting into the thick of my project, let me present myself:
I am Olivier Gr goire (Gasuleg), and I study IT engineering at cole de Technologie sup rieure in Montreal.
I am a technician in electronics, and I began object-oriented programming just last year.
I applied to GSoC because I loved the concept of the project that I would work on and I really wanted to be part of it. I also wanted to discover the word of the free software. 2. My Project During this GSoC, I worked on the Ring project. Ring is a free software for communication that allows its users to make audio or video calls, in pairs or groups, and to send messages, safely and freely, in confidence. Savoir-faire Linux and a community of contributors worldwide develop Ring. It is available on GNU/Linux, Windows, Mac OSX and Android. It can be associated with a conventional phone service or integrated with any connected object. Under this very easy to use software, there is a combination of technologies and innovations opening all kinds of perspectives to its users and developers. Ring is a free software whose code is open. Therefore, it is not the software that controls you. With Ring, you take control of your communication! Ring is an open source software under the GPL v3 license. Everyone can verify the codes and propose new ones to improve the software s performace. It is a guarantee of transparency and freedom for everyone!
Source: ring.cx The problem is about the typical user of Ring, the one who don t use the terminal to launch Ring. He has no information about what has happened in the system. My goal is to create a tool that display statistics of Ring. 3. Quick Explanation of What My Program Can Do The Code
Here are the links to the code I was working on all throughout the Google Summer of Code (You can see what I have done after the GSoC by clicking on the newest patchs):
Patch Status
Daemon Merged
Lib Ring Client (LRC) On Review
Gnome client On Review
Remove unused code Merged

What Can Be Displayed?
This is the final list of information I can display and some ideas on what information we could display in the future:
Information Details Done?
Call ID The identification number of the call Yes
Resolution Local and remote Yes
Framerate Local and remote Yes
Codec Audio and video in local and remote Yes
Bandwidth Download and upload No
Performance use CPU, GPU, RAM No
Security level In SIP call No
Connection time No
Packets lost No

To launch it you need to right click on the call and click on Show advanced information .
alt text
To stop it, same thing: right click on the call and click on Hide advanced information .
4. More Details About My Project My program needs to retrieve information from the daemon (LibRing) and then display it in gnome client. So, I needed to create a patch for the daemon, the D-Bus layer (in the daemon patch), LibRingClient and the GNU/Linux (Gnome) client.
This is what the architecture of the project looks like.
alt text
source: ring.cx And this is how I implemented my project.
alt text
5. Future of the Project Weekly report link Thanks I would like to thank the following:
- The Google Summer of Code organisation, for this wonderful experience.
- Debian, for accepting my project proposal and letting me embark on this fantastic adventure.
- My mentor, Mr Guillaume Roguez, and all his team, for being there to help me.

Guido G nther: Foreman's Ansible integration

Gathering from some recent discussions it seems to be not that well known that Foreman (a lifecycle tool for your virtual machines) does not only integrate well with Puppet but also with ansible. This is a list of tools I find useful in this regard: There's also support for triggering ansible runs from within Foreman itself but I've not used that so far.

Zlatan Todori : Defcon24

I went to Defcon24 as Purism representative. It was (as usual) held in Las Vegas, the city of sin. In the same module as with DebConf, here we go with good, bad and ugly. Good Badges are really cool. You can find good hackers here and there (but very small number compared to total number). Some talks are good and workshop + village idea looks good (although I didn't manage to attend any workshop as there was place for 1100 and there were 22000 attendees). The movie night idea is cool and Arcade space (where you can play old arcade games, relax and hack and also listen to some cool music) is really lovely. Also you have a camp/village for kids learning things such as electronics, soldering etc but you need to pay attention that they don't see too much of twisted folks that also gather on this con. And that's it. Oh, yea, Dark Tangent appears actually to be cool dude. Bad One does not simply hold a so-called hacker conference in Las Vegas. Having a conference inside hotel/casino where you mix with gamblers and casino workes (for good or for bad) is simply not in hacker spirit and certainly brings all kind of people to the same place. Also, there were simply not enough space for 22000 Defcon attendees, and you don't get proud of having on average ONLY 40min lines. You get proud if you don't have lines! Organization is not the strongest part of Defcon. Huge majority of attendees are not hackers. They are script kiddies, hacker wannabes, comic con people, few totally lost souls etc etc. That simply brings the quality of a conference down. Yes it is cool to have mix of many diverse people but not for the sake of just having people. Ugly They lack Code of Conduct (everyone knows I am not in favor of any writens rules how people should behave but after Defcon I clearly see need for it). Actually, tbh, they do have it but no one gives a damn about it. And you should report to Goons, more about them below. Sexism is huge here. I remember and hear about stories of sexual harassment in IT industry, but Debian somehow mitigated that before me entering its domains, so I never experienced it. The sheer number of sexist behavior on Defcon is tremendous. It appears to me that those people had lonely childhood and now they act as a spoiled 6 year old: they're spoiled, they need to yell to show their point, they have low and stupid sexist jokes and they simply think that is cool. Majority of Goons (their coordinators or whatever) are simply idiots. I don't know do they feel they have some superpowers, or are drunk or just stupid but yelling on people, throwing low jokes on people, more yelling, cursing all the time, more yelling - simply doesn't work for me. So now you can see the irony of CoC on Defcon. They even like to say, hey we are old farts, let us our con be as we want it to be. So no real diversity there. Either it is their way, and god forsaken if you try to change something for better and make them stop cursing or throwing sexist jokes ("squeeze, people. together, touch each other, trust me it will feel good"), or highway. Also it appears that to huge number of vocal people, word "fuck" has some fetish meaning. Either it needs to show how "fucking awesome this con or they are" or to "fucking tell few things about random fucking stuff". Thank you, but no thank you. So what did I do during con. I attended few talks, had some discussion with people, went to one party (great DJs, again people doing stupid things, like breaking invertory to name just one of them) and had so much time (read "I was bored") that I bought domain, brough up server on which I configured nginx and cp'ed this blog to blog.zlatan.tech (yes, recently I added letsencrypt because it is, let me be in Defcon mood, FUCKING AWESOME GRRR UGH) and now I even made .onion domain for it. What can boredom do to people, right? So the ultimate question is - would I go again to Defcon. I am strongly leaning to no, but in my nature is to give second chance and now I have more experience (and I also have thick skin so I guess I can play calm for one more round).

18 August 2016

Zlatan Todori : DebConf16 - new age in Debian community gathering

DebConf16 Finally got some time to write this blog post. DebConf for me is always something special, a family gathering of weird combination of geeks (or is weird a default geek state?). To be honest, I finally can compare Debian as hacker conference to other so-called hacker conferences. With that hat on, I can say that Debian is by far the most organized and highest quality conference. Maybe I am biased, but I don't care too much about that. I simply love Debian and that is no secret. So lets dive into my view on DebConf16 which was held in Cape Town, South Africa. Cape Town This was the first time we had conference on African continent (and I now see for the first time DebConf bid for Asia, which leaves only Australia and beautiful Pacific islands to start a bid). Cape Town by itself, is pretty much Europe-like city. That was kinda a bum for me on first day, especially as we were hosted at University of Cape Town (which is quite beautiful uni) and the surrounding neighborhood was very European. Almost right after the first day I was fine because I started exploring the huge city. Cape Town is really huge, it has by stats ~4mil people, and unofficially it has ~6mil. Certainly a lot to explore and I hope one day to be back there (I actually hope as soon as possible). The good, bad and ugly I will start with bad and ugly as I want to finish with good notes. Racism down there is still HUGE. You don't have signs on the road saying that, but there is clearly separation between white and black people. The houses near uni all had fences on walls (most of them even electrical ones with sharp blades on it) with bars on windows. That just bring tensions and certainly doesn't improve anything. To be honest, if someone wants to break in they still can do easily so the fences maybe need to bring intimidation but they actually only bring tension (my personal view). Also many houses have sign of Armed Force Response (something in those lines) where in case someone would start breaking in, armed forces would come to protect the home. Also compared to workforce, white appear to hold most of profit/big business positions and fields, while black are street workers, bar workers etc etc. On the street you can feel from time to time the tension between people. Going out to bars also showed the separation - they were either almost exclusively white or exclusively black. Very sad state to see. Sharing love and mixing is something that pushes us forward and here I saw clear blockades for such things. The bad part of Cape Town is, and this is not only special to Cape Town but to almost all major cities, is that small crime is on wide scale. Pickpocketing here is something you must pay attention to it. To me, personally, nothing happened but I heard a lot of stories from my friends on whom were such activities attempted (although I am not sure did the criminals succeed). Enough of bad as my blog post will not change this and it is a topic for debate and active involvement which I can't unfortunately do at this moment. THE GOOD! There are so many great local people I met! As I mentioned, I want to visit that city again and again and again. If you don't fear of those bad things, this city has great local cuisine, a lot of great people, awesome art soul and they dance with heart (I guess when you live in rough times, you try to use free time at your best). There were difference between white and black bars/clubs - white were almost like standard European, a lot of drinking and not much dancing, and black were a lot of dancing and not much drinking (maybe the economical power has something to do with it but I certainly felt more love in black bars). Cape Town has awesome mountain, the Table Mountain. I went on hiking with my friends, and I must say (again to myself) - do the damn hiking as much as possible. After every hike I feel so inspired, that I will start thinking that I hate myself for not doing it more often! The view from Table mountain is just majestic (you can even see the Cape of Good Hope). The WOW moments are just firing up in you. Now lets transfer to DebConf itself. As always, organization was on quite high level. I loved the badge design, it had a map and nice amount of information on it. The place we stayed was kinda not that good but if you take it into account that those a old student dorms (in we all were in female student dorm :D ) it is pretty fancy by its own account. Talks were near which is always good. The general layout of talks and front desk position was perfect in my opinion. All in one place basically. Wine and Cheese this year was kinda funny story because of the cheese restrictions but Cheese cabal managed to pull out things. It was actually very well organized. Met some new people during the party/ceremony which always makes me grow as a person. Cultural mix on DebConf is just fantastic. Not only you learn a lot about Debian, hacking on it, but sheer cultural diversity makes this small con such a vibrant place and home to a lot. Debian Dinner happened in Aquarium were I had nice dinner and chat with my old friends. Aquarium by itself is a thing where you can visit and see a lot of strange creatures that live on this third rock from Sun. Speaking of old friends - I love that I Apollo again rejoined us (by missing the DebConf15), seeing Joel again (and he finally visited Banja Luka as aftermath!), mbiebl, ah, moray, Milan, santiago and tons of others. Of course we always miss a few such as zack and vorlon this year (but they had pretty okay-ish reasons I would say). Speaking of new friends, I made few local friends which makes me happy and at least one Indian/Hindu friend. Why did I mention this separately - well we had an accident during Group Photo (btw, where is our Lithuanian, German based nowdays, photographer?!) where 3 laptops of our GSoC students were stolen :( . I was luckily enough to, on behalf of Purism, donate Librem11 prototype to one of them, which ended up being the Indian friend. She is working on real time communications which is of interest also to Purism for our future projects. Regarding Debian Day Trip, Joel and me opted out and we went on our own adventure through Cape Town in pursue of meeting and talking to local people, finding out interesting things which proved to be a great decision. We found about their first Thursday of month festival and we found about Mama Africa restaurant. That restaurant is going into special memories (me playing drums with local band must always be a special memory, right?!). Huh, to be honest writing about DebConf would probably need a book by itself and I always try to keep my posts as short as possible so I will try to stop here (maybe I write few bits in future more about it but hardly). Now the notes. Although I saw the racial segregation, I also saw the hope. These things need time. I come from country that is torn apart in nationalism and religious hate so I understand this issues is hard and deep on so many levels. While the tensions are high, I see people try to talk about it, try to find solution and I feel it is slowly transforming into open society, where we will realize that there is only one race on this planet and it is called - HUMAN RACE. We are all earthlings, and as sooner we realize that, sooner we will be on path to really build society up and not fake things that actually are enslaving our minds. I just want in the end to say thank you DebConf, thank you Debian and everyone could learn from this community as a model (which can be improved!) for future societies.

17 August 2016

Raphaël Hertzog: Freexian s report about Debian Long Term Support, July 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In July, 136.6 work hours have been dispatched among 11 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours jumped to 159 hours per month thanks to GitHub joining as our second platinum sponsor (funding 3 days of work per month)! Our funding goal is getting closer but it s not there yet. The security tracker currently lists 22 packages with a known CVE and the dla-needed.txt file likewise. That s a sharp decline compared to last month. Thanks to our sponsors New sponsors are in bold.

2 comments Liked this article? Click here. My blog is Flattr-enabled.

Raphaël Hertzog: My Free Software Activities in July 2016

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. DebConf 16 I was in South Africa for the whole week of DebConf 16 and gave 3 talks/BoF. You can find the slides and the videos in the links of their corresponding page: I was a bit nervous about the third BoF (on using Debian money to fund Debian projects) but discussed with many persons during the week and it looks like the project evolved quite a bit in the last 10 years and while it s still a sensitive topic (and rightfully so given the possible impacts) people are willing to discuss the issues and to experiment. You can have a look at the gobby notes that resulted from the live discussion. I spent most of the time discussing with people and I did not do much technical work besides trying (and failing) to fix accessibility issues with tracker.debian.org (help from knowledgeable people is welcome, see #830213). Debian Packaging I uploaded a new version of zim to fix a reproducibility issue (and forwarded the patch upstream). I uploaded Django 1.8.14 to jessie-backports and had to fix a failing test (pull request). I uploaded python-django-jsonfield 1.0.1 a new upstream version integrating the patches I prepared in June. I managed the (small) ftplib library transition. I prepared the new version in experimental, ensured reverse build dependencies do still build and coordinated the transition with the release team. This was all triggered by a reproducible build bug that I got and that made me look at the package last time upstream had disappeared (upstream URL was even gone) but it looks like he became active again and he pushed a new release. I filed wishlist bug #832053 to request a new deblog command in devscripts. It should make it easier to display current and former build logs. Kali related Debian work I worked on many issues that were affecting Kali (and Debian Testing) users: Thanks See you next month for a new summary of my activities.

3 comments Liked this article? Click here. My blog is Flattr-enabled.

Michal Čihař: Weekly phpMyAdmin contributions 2016-W32

Tonight phpMyAdmin 4.0.10.17, 4.4.15.8, and 4.6.4 were released and you can probably see that there are quite some security issues fixed. Most of them are not really exploitable unless your PHP and webserver are poorly configured, but still it's good idea to upgrade. If you are running Debian unstable, use our phpMyAdmin PPA for Ubuntu or use phpMyAdmin Docker image upgrading should be as simple as pulling new version. Besides fixing security issues, we're generally hardening our infrastructure. I'm really grateful that Emanuel Bronshtein (@e3amn2l) is doing great review of all of our code and helps us in this area. This will really make our code and infrastructure much better. Handled issues:

Filed under: Debian English phpMyAdmin 0 comments

Ben Hutchings: Debian LTS work, July 2016

I was assigned another 14.7 hours of work by Freexian's Debian LTS initiative and carried over 1 from last month. I worked a total of 15 hours, carrying over a fraction of an hour. I spent another week in the Front Desk role and triaged various new CVEs for wheezy. I spent the remainder of the time working on the next Linux stable updates (3.2.82 and Debian 3.2.81-2), but didn't release them - that will be done in the next few days.

16 August 2016

Lars Wirzenius: 20 years ago I became a Debian developer

Today it is 23 years ago since Ian Murdock published his intention to develop a new Linux distribution, Debian. It also about 20 years since I became a Debian developer and made my first package upload. In the time since: It's been a good twenty years. And the fun ain't over yet.

Keith Packard: udevwrap

Wrapping libudev using LD_PRELOAD Peter Hutterer and I were chasing down an X server bug which was exposed when running the libinput test suite against the X server with a separate thread for input. This was crashing deep inside libudev, which led us to suspect that libudev was getting run from multiple threads at the same time. I figured I'd be able to tell by wrapping all of the libudev calls from the server and checking to make sure we weren't ever calling it from both threads at the same time. My first attempt was a simple set of cpp macros, but that failed when I discovered that libwacom was calling libgudev, which was calling libudev. Instead of recompiling the world with my magic macros, I created a new library which exposes all of the (public) symbols in libudev. Each of these functions does a bit of checking and then simply calls down to the 'real' function. Finding the real symbols Here's the snippet which finds the real symbols:
static void *udev_symbol(const char *symbol)
 
    static void *libudev;
    static pthread_mutex_t  find_lock = PTHREAD_MUTEX_INITIALIZER;
    void *sym;
    pthread_mutex_lock(&find_lock);
    if (!libudev)  
        libudev = dlopen("libudev.so.1.6.4", RTLD_LOCAL   RTLD_NOW);
     
    sym = dlsym(libudev, symbol);
    pthread_mutex_unlock(&find_lock);
    return sym;
 
Yeah, the libudev version is hard-coded into the source; I didn't want to accidentally load the wrong one. This could probably be improved... Checking for re-entrancy As mentioned above, we suspected that the bug was caused when libudev got called from two threads at the same time. So, our checks are pretty simple; we just count the number of calls into any udev function (to handle udev calling itself). If there are other calls in process, we make sure the thread ID for those is the same as the current thread.
static void udev_enter(const char *func)  
    pthread_mutex_lock(&check_lock);
    assert (udev_running == 0   udev_thread == pthread_self());
    udev_thread = pthread_self();
    udev_func[udev_running] = func;
    udev_running++;
    pthread_mutex_unlock(&check_lock);
 
static void udev_exit(void)  
    pthread_mutex_lock(&check_lock);
    udev_running--;
    if (udev_running == 0)
    udev_thread = 0;
    udev_func[udev_running] = 0;
    pthread_mutex_unlock(&check_lock);
 
Wrapping functions Now, the ugly part -- libudev exposes 93 different functions, with a wide variety of parameters and return types. I constructed a hacky macro, calls for which could be constructed pretty easily from the prototypes found in libudev.h, and which would construct our stub function:
#define make_func(type, name, formals, actuals)         \
    type name formals                       \
    type ret;                       \
    static void *f;                     \
    if (!f)                         \
        f = udev_symbol(__func__);              \
    udev_enter(__func__);                   \
    ret = ((typeof (&name)) f) actuals;         \
    udev_exit();                        \
    return ret;                     \
     
There are 93 invocations of this macro (or a variant for void functions) which look much like:
make_func(struct udev *,
      udev_ref,
      (struct udev *udev),
      (udev))
Using udevwrap To use udevwrap, simply stick the filename of the .so in LD_PRELOAD and run your program normally:
# LD_PRELOAD=/usr/local/lib/libudevwrap.so Xorg 
Source code I stuck udevwrap in my git repository: http://keithp.com/cgi-bin/gitweb.cgi?p=udevwrap;a=summary You can clone it using
$ git git://keithp.com/git/udevwrap

15 August 2016

Russ Allbery: Review: Winds of Fate

Review: Winds of Fate, by Mercedes Lackey
Series: Mage Winds #1
Publisher: DAW
Copyright: 1991
Printing: July 1992
ISBN: 0-88677-516-7
Format: Mass market
Pages: 460
As a kid working my way through nearly everything in the children's section of the library, I always loved book series, since it meant I could find a lot more of something I liked. But children's book series tended to be linear, with a well-defined order. When I moved into the adult SF section, I encountered a new type of series: one that moves backwards and forwards in time to fill in a broader story. I mention that here because Winds of Fate, although well into the linked series that make up Valdemar, was one of the first Valdemar books I read. (I think it was the first, but my memory is hazy.) Therefore, in my brain, this is where the story of Valdemar "begins": with Elspeth, a country that has other abilities but has forgotten about magic, a rich world full of various approaches to magic, and very pushy magic horses. Talia's story, and particularly Vanyel's, were always backstory, the events that laid the groundwork for Elspeth's story. (I didn't encounter Tarma and Kethry until somewhat later.) Read now in context, this is obviously not the case. The Mage Winds trilogy, of which this is the first book, are clearly sequels to the Arrows of the Queen trilogy. Valdemar was victorious in the first round of war with Ancar, but the Heralds have slowly (and with great difficulty) become aware of their weakness against magic and their surprising lack of it. Elspeth has grown into the role of heir, but she's also one of the few who find it easy to talk about and think about magic (perhaps due to her long association with Kerowyn, who came into Valdemar from the outside world in By the Sword). She therefore takes on the mission of finding an Adept who can return to Valdemar, solve the mystery of whatever is keeping magic out of the kingdom, and start training mages for the kingdom again. Meanwhile, we get the first viewpoint character from the Tayledras: the elf-inspired mages who work to cleanse the Pelagiris forests from magic left over from a long-ago war. They appeared briefly in Vanyel's story, since his aunt was friends with a farther-north tribe of them and Valdemar of the time had contact with mages. Darkwind and his people are far to the south, up against the rim of the Dhorisha crater. Something has gone horribly wrong with Heartstone of the k'Sheyna, his tribe: it cracked when being drained, killing most of the experienced mages including Darkwind's mother, and now it is subtly wrong, twisting and undermining the normal flow of magic inside their Vale. In the aftermath of that catastrophe, Darkwind has forsworn magic and become a scout, putting him sharply at odds with his father. And it's a matter of time before less savory magic users in the area realize how vulnerable k'Sheyna is. Up to this point in the Valdemar series, Lackey primarily did localized world-building to support the stories and characters she was writing about. Valdemar and its Heralds and Companions have been one of the few shared elements, and only rarely did the external magic-using world encounter them. Here, we get the first extended contact between the fairly naive Heralds and experienced mages who understand how they and their Companions fit into the broader system of magic. We also finally get the origin of the Dhorisha Plains and the Tayledras and Shin'a'in, and a much better sense of the broader history of this world. And Need, which started as Kethry's soul-bonded sword and then became Kerowyn's, joins the story in a much more active way. The world-building is a definite feature if you like this sort of thing. It doesn't withstand too much thinking about the typical sword and sorcery lack of technology, but for retroactive coherence constructed from originally scattered stories, it's pretty fun. (I suspect part of why I like the Valdemar world-building is that it feels a lot like large shared universe world-building in comics.) And Need is the high point of the story: she brings a much-needed cynical stubbornness to the cast and is my favorite character in this book. What is not a feature, unfortunately, is the characterization. Darkwind is okay but a largely unremarkable here, more another instance of the troubled but ethical Tayledras type than a clearly defined character. But Elspeth is just infuriating, repeatedly making decisions and taking hard positions that seem entirely unwarranted by the recorded events of the book. This is made worse by how frequently she's shown to be correct in ways that seem like authorial cheating. At times, it feels like she's the heroine by authorial fiat, not because she's doing a particularly good job. I can muster some sympathy for not wanting to follow the plan of the Companions when it became clear they were acting entirely out of character and actively intervening, but she expresses that with petulant, childish insistence rather than reasoned argument. And she suddenly decides Skif is in love with her and treating her like a fragile princess on the basis of absolutely no action that occurs on camera in this book so far as I can tell, and proceeds to treat him like dirt for large sections of the book. That Skif then lives down to this suddenly negative impression doesn't help. This book also has quite a lot of the U-shaped story arc in which everything gets worse and more horrific and more hopeless for the heroes over the course of the book until it turns into torture, and only then do they manage to claw their way back out. I've come to dislike this way of building tension. It's undeniably effective, but the parts of the story near the bottom of the U are difficult and painful reading. I prefer a bit more evenly-spread hurt/comfort storytelling in my popcorn fantasy reading. Winds of Fate is, sadly, not a very good book. Most of the characterization is intensely irritating, the writing is a bit uneven, and the middle section of the book is rather painful to read. For me, though, that's balanced by the world-building and the sense of broadened scope, by Need's abrasive decisiveness, and by some really entertaining reactions to the combination of Elspeth, Need, and her Companion walking naive into the broader world. I still have a fond spot in my heart for it, but I'm hoping the remaining books of the trilogy are better. Rating: 6 out of 10

Paul Tagliamonte: Minica - lightweight TLS for everyone!

A while back, I found myself in need of some TLS certificates set up and issued for a testing environment. I remembered there was some code for issuing TLS certs in Docker, so I yanked some of that code and made a sensable CLI API over it. Thus was born minica! Something as simple as minica tag@domain.tls domain.tld will issue two TLS certs (one with a Client EKU, and one server) issued from a single CA. Next time you re in need of a few TLS keys (without having to worry about stuff like revocation or anything), this might be the quickest way out!

14 August 2016

Steinar H. Gunderson: Linear interpolation, source alignment, and Debian's embedding policy

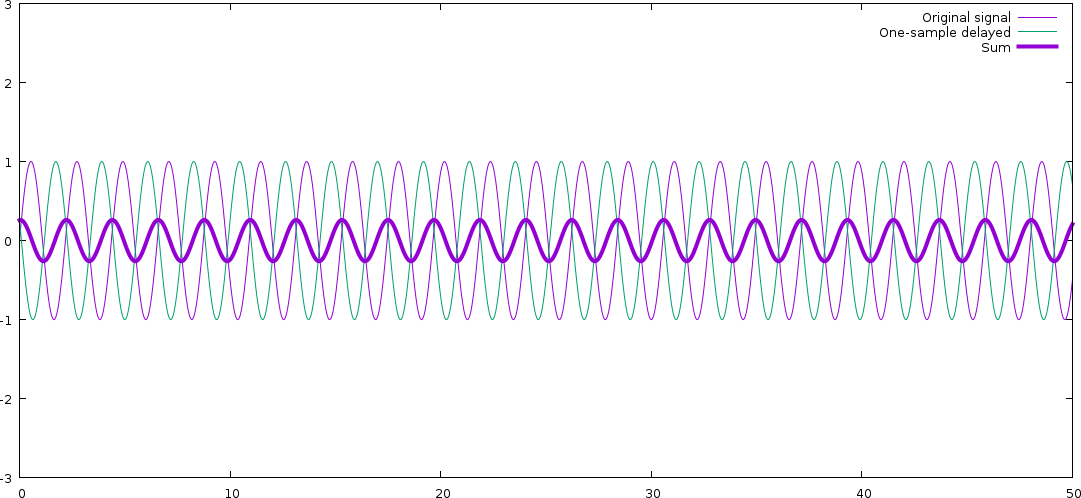
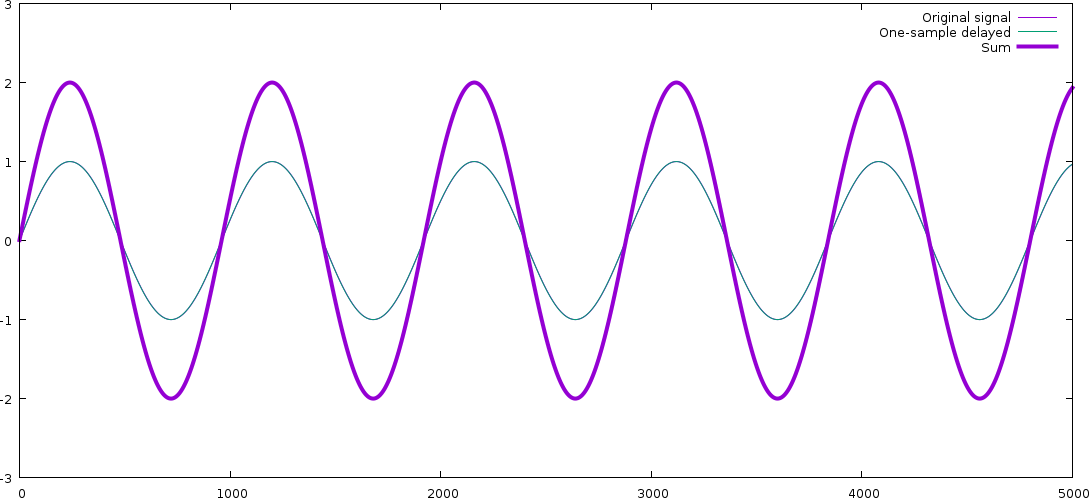
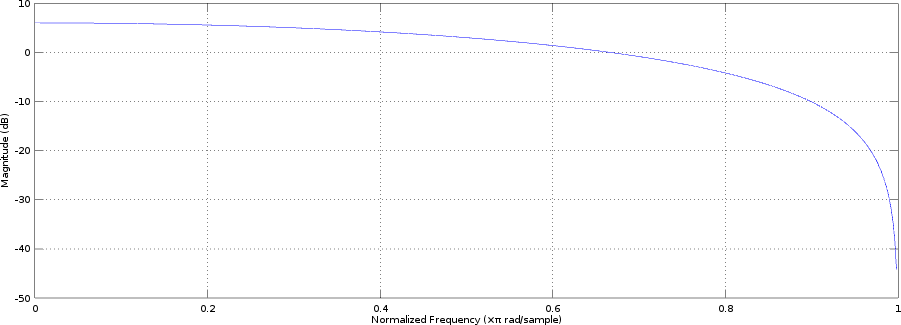
At some point back when the dinosaurs roamed the Earth and I was in high school, I borrowed my first digital signal processing book from a friend. I later went on to an engineering education and master's thesis about DSP, but the very basics of DSP never stop to fascinate me. Today, I wanted to write something about one of them and how it affects audio processing in Nageru (and finally, how Debian's policies put me in a bit of a bind on this issue). DSP texts tend to obscure profound truths with large amounts of maths, so I'll try to present a somewhat less general result that doesn't require going into the mathematical details. That rule is: Adding a signal to weighted, delayed copies of itself is a filtering operation. (It's simple, but ignoring it will have sinister effects, as we'll see later.) Let's see exactly what that means with a motivating example. Let's say that I have a signal where I want to get rid of (or rather, reduce) high frequencies. The simplest way I can think of is to add every neighboring sample; that is, set yn = xn + xn-1. For each sample, we add the previous sample, ie., the signal as it was one sample ago. (We ignore what happens at the edges; the common convention is to assume signals extend out to infinity with zeros.) What effect will this have? We can figure it out with some trigonometry, but let's just demonstrate it by plotting instead: We assume 48 kHz sample rate (which means that our one-sample delay is 20.83 s) and a 22 kHz note (definitely treble!), and plot the signal with one-sample delay (the x axis is sample number): Filtered 22 kHz As you can see, the resulting signal is a new signal of the same frequency (which is always true; linear filtering can never create new frequencies, just boost or dampen existing ones), but with much lower amplitude. The signal and the delayed version of it end up cancelling each other mostly out. Also note that there signal has changed phase; the resulting signal has been a bit delayed compared to the original. Now let's look at a 50 Hz signal (turn on your bass face). We need to zoom out a bit to see full 50 Hz cycles: Filtered 50 Hz The original signal and the delayed one overlap almost exactly! For a lower frequency, the one-sample delay means almost nothing (since the waveform is varying so slowly), and thus, in this case, the resulting signal is amplified, not dampened. (The signal has changed phase here, too actually exactly as much in terms of real time but we don't really see it, because we've zoomed out.) Real signals are not pure sines, but they can be seen as sums of many sines (another fundamental DSP result), and since filtering is a linear operation, it affects those sines independently. In other words, we now have a very simple filter that will amplify low frequencies and dampen high frequencies (and delay the entire signal a little bit). We can do this for all frequencies from 0 to 24000 Hz; let's ask Octave to do it for us: Frequency plot for simple filter (Of course, in a real filter, we'd probably multiply the result with 0.5 to leave the bass untouched instead of boosting it, but it doesn't really change anything. A real filter would have a lot more coefficients, though, and they wouldn't all be the same!) Let's now turn to a problem that will at first seem different: Combining audio from multiple different time sources. For instance, when mixing video, you could have input from two different cameras or sounds card and would want to combine them (say, a source playing music and then some audience sound from a camera). However, unless you are lucky enough to have a professional-grade setup where everything runs off the same clock (and separate clock source cables run to every device), they won't be in sync; sample clocks are good, but they are not perfect, and they have e.g. some temperature variance. Say we have really good clocks and they only differ by 0.01%; this means that after an hour of streaming, we have 360 ms delay, completely ruining lip sync! This means we'll need to resample at least one of the sources to match the other; that is, play one of them faster or slower than it came in originally. There are two problems here: How do you determine how much to resample the signals, and how do we resample them? The former is a difficult problem in its own right; about every algorithm not backed in solid control theory is doomed to fail in one way or another, and when they fail, it's extremely annoying to listen to. Nageru follows a 2012 paper by Fons Adriaensen; GStreamer does well, something else. It fails pretty badly in a number of cases; see e.g. this 2015 master's thesis that tries to patch it up. However, let's ignore this part of the problem for now and focus on the resampling. So let's look at the case where we've determined we have a signal and need to play it 0.01% faster (or slower); in a real situation, this number would vary a bit (clocks are not even consistently wrong). This means that at some point, we want to output sample number 3000 and that corresponds to input sample number 3000.3, ie., we need to figure out what's between two input samples. As with so many other things, there's a way to do this that's simple, obvious and wrong, namely linear interpolation. The basis of linear interpolation is to look at the two neighboring samples and weigh them according to the position we want. If we need sample 3000.3, we calculate y = 0.7 x3000 + 0.3 x3001 (don't switch the two coefficients!), or, if we want to save one multiplication and get better numerical behavior, we can use the equivalent y = x3000 + 0.3 (x3001 - x3000). And if we need sample 5000.5, we take y = 0.5 x5000 + 0.5 x5001. And after a while, we'll be back on integer samples; output sample 10001 corresponds to x10000 exactly. By now, I guess it should be obvious what's going on: We're creating a filter! Linear interpolation will inevitably result in high frequencies being dampened; and even worse, we are creating a time-varying filter, which means that the amount of dampening will vary over time. This manifests itself as a kind of high-frequency flutter , where the amount of flutter depends on the relative resampling frequencies. There's also cubic resampling (which can mean any of several different algorithms), but it only really reduces the problem, it doesn't really solve it. The proper way of interpolating depends a lot on exactly what you want (e.g., whether you intend to change the rate quickly or not); this paper lays out a bunch of them, and was the paper that originally made me understand why linear interpolation is so bad. Nageru outsources this problem to zita-resampler, again by Fons Adriaensen; it yields extremely high-quality resampling under controlled delay, through a relatively common technique known as polyphase filters. Unfortunately, doing this kind of calculations takes CPU. Not a lot of CPU, but Nageru runs in rather CPU-challenged environments (ultraportable laptops where the GPU wants most of the TDP, and the CPU has to go down to the lowest frequency), and it is moving in a direction where it needs to resample many more channels (more on the later), so every bit of CPU helps. So I coded up an SSE optimization of the inner loop for a particular common case (stereo signals) and sent it in for upstream inclusion. (It made the code 2.7 times as fast without any structural changes or reducing precision, which is pretty much what you can expect from SSE.) Unfortunately, after a productive discussion, suddenly upstream went silent. I tried pinging, pinging again, and after half a year pinging again, but to no avail. I filed the patch in Debian's BTS, but the maintainer understandably is reluctant to carry a delta against upstream. I also can't embed a copy; Debian policy would dictate that I build against the system's zita-resampler. I could work around it by rewriting zita-resampler until it looks nothing like the original, which might be a good idea anyway if I wanted to squeeze out the last drops of speed; there are AVX optimizations to be had in addition to SSE, and the structure as-is isn't ideal for SSE optimizations (although some of the changes I have in mind would have to be offset against increased L1 cache footprint, so careful benchmarking would be needed). But in a sense, it feels like just working around a policy that's there for good reason. So like I said, I'm in a bit of a bind. Maybe I should just buy a faster laptop. Oh, and how does GStreamer solve this? Well, it doesn't use linear interpolation. It does something even worse it uses nearest neighbor. Gah. Update: I was asked to clarify that this is about the audio resampling done by the GStreamer audio sink to sync signals, not in the audioresample element, which solves a related but different problem (static sample rate conversion). The audioresample element supports a number of different resampling methods; I haven't evaluated them.
David Moreno: Deploying a Dancer app on Heroku

There s a few different posts out there on how to run Perl apps, such as Mojolicious-based, on Heroku, but I d like to show how to deploy a Perl Dancer application on Heroku. The startup script of a Dancer application (bin/app.pl) can be used as a PSGI file. With that in mind, I was able to take the good work of Miyagawa s Heroku buildpack for general PSGI apps and hack it a little bit to use Dancer s, specifically. What I like about Miyagawa s approach is that uses the fantastic cpanm and makes it available within your application, instead of the monotonous cpan, to solve dependencies. Let s make a simple Dancer app to show how to make this happen:
/tmp $ dancer -a heroku
+ heroku
+ heroku/bin
+ heroku/bin/app.pl
+ heroku/config.yml
+ heroku/environments
+ heroku/environments/development.yml
+ heroku/environments/production.yml
+ heroku/views
+ heroku/views/index.tt
+ heroku/views/layouts
+ heroku/views/layouts/main.tt
+ heroku/MANIFEST.SKIP
+ heroku/lib
heroku/lib/
+ heroku/lib/heroku.pm
+ heroku/public
+ heroku/public/css
+ heroku/public/css/style.css
+ heroku/public/css/error.css
+ heroku/public/images
+ heroku/public/500.html
+ heroku/public/404.html
+ heroku/public/dispatch.fcgi
+ heroku/public/dispatch.cgi
+ heroku/public/javascripts
+ heroku/public/javascripts/jquery.js
+ heroku/t
+ heroku/t/002_index_route.t
+ heroku/t/001_base.t
+ heroku/Makefile.PL
Now, you already know that by firing perl bin/app.pl you can get your development server up and running. So I ll just proceed to show how to make this work on Heroku, you should already have your development environment configured for it:
/tmp $ cd heroku/
/tmp/heroku $ git init
Initialized empty Git repository in /private/tmp/heroku/.git/
/tmp/heroku :master $ git add .
/tmp/heroku :master $ git commit -a -m 'Dancer on Heroku'
[master (root-commit) 6c0c55a] Dancer on Heroku
22 files changed, 809 insertions(+), 0 deletions(-)
create mode 100644 MANIFEST
create mode 100644 MANIFEST.SKIP
create mode 100644 Makefile.PL
create mode 100755 bin/app.pl
create mode 100644 config.yml
create mode 100644 environments/development.yml
create mode 100644 environments/production.yml
create mode 100644 lib/heroku.pm
create mode 100644 public/404.html
create mode 100644 public/500.html
create mode 100644 public/css/error.css
create mode 100644 public/css/style.css
create mode 100755 public/dispatch.cgi
create mode 100755 public/dispatch.fcgi
create mode 100644 public/favicon.ico
create mode 100644 public/images/perldancer-bg.jpg
create mode 100644 public/images/perldancer.jpg
create mode 100644 public/javascripts/jquery.js
create mode 100644 t/001_base.t
create mode 100644 t/002_index_route.t
create mode 100644 views/index.tt
create mode 100644 views/layouts/main.tt
/tmp/heroku :master $
And now, run heroku create, please note the buildpack URL, http://github.com/damog/heroku-buildpack-perl.git:
/tmp/heroku :master $ heroku create --stack cedar --buildpack http://github.com/damog/heroku-buildpack-perl.git
Creating blazing-beach-7280... done, stack is cedar
http://blazing-beach-7280.herokuapp.com/   git@heroku.com:blazing-beach-7280.git
Git remote heroku added
/tmp/heroku :master $
And just push:
/tmp/heroku :master $ git push heroku master
Counting objects: 34, done.
Delta compression using up to 4 threads.
Compressing objects: 100% (30/30), done.
Writing objects: 100% (34/34), 40.60 KiB, done.
Total 34 (delta 3), reused 0 (delta 0)
-----> Heroku receiving push
-----> Fetching custom buildpack... done
-----> Perl/PSGI Dancer! app detected
-----> Bootstrapping cpanm
Successfully installed JSON-PP-2.27200
Successfully installed CPAN-Meta-YAML-0.008
Successfully installed Parse-CPAN-Meta-1.4404 (upgraded from 1.39)
Successfully installed version-0.99 (upgraded from 0.77)
Successfully installed Module-Metadata-1.000009
Successfully installed CPAN-Meta-Requirements-2.122
Successfully installed CPAN-Meta-2.120921
Successfully installed Perl-OSType-1.002
Successfully installed ExtUtils-CBuilder-0.280205 (upgraded from 0.2602)
Successfully installed ExtUtils-ParseXS-3.15 (upgraded from 2.2002)
Successfully installed Module-Build-0.4001 (upgraded from 0.340201)
Successfully installed App-cpanminus-1.5015
12 distributions installed
-----> Installing dependencies
Successfully installed ExtUtils-MakeMaker-6.62 (upgraded from 6.55_02)
Successfully installed YAML-0.84
Successfully installed Test-Simple-0.98 (upgraded from 0.92)
Successfully installed Try-Tiny-0.11
Successfully installed HTTP-Server-Simple-0.44
Successfully installed HTTP-Server-Simple-PSGI-0.14
Successfully installed URI-1.60
Successfully installed Test-Tester-0.108
Successfully installed Test-NoWarnings-1.04
Successfully installed Test-Deep-0.110
Successfully installed LWP-MediaTypes-6.02
Successfully installed Encode-Locale-1.03
Successfully installed HTTP-Date-6.02
Successfully installed HTML-Tagset-3.20
Successfully installed HTML-Parser-3.69
Successfully installed Compress-Raw-Bzip2-2.052 (upgraded from 2.020)
Successfully installed Compress-Raw-Zlib-2.054 (upgraded from 2.020)
Successfully installed IO-Compress-2.052 (upgraded from 2.020)
Successfully installed HTTP-Message-6.03
Successfully installed HTTP-Body-1.15
Successfully installed MIME-Types-1.35
Successfully installed HTTP-Negotiate-6.01
Successfully installed File-Listing-6.04
Successfully installed HTTP-Daemon-6.01
Successfully installed Net-HTTP-6.03
Successfully installed HTTP-Cookies-6.01
Successfully installed WWW-RobotRules-6.02
Successfully installed libwww-perl-6.04
Successfully installed Dancer-1.3097
29 distributions installed
-----> Installing Starman
Successfully installed Test-Requires-0.06
Successfully installed Hash-MultiValue-0.12
Successfully installed Devel-StackTrace-1.27
Successfully installed Test-SharedFork-0.20
Successfully installed Test-TCP-1.16
Successfully installed Class-Inspector-1.27
Successfully installed File-ShareDir-1.03
Successfully installed Filesys-Notify-Simple-0.08
Successfully installed Devel-StackTrace-AsHTML-0.11
Successfully installed Plack-0.9989
Successfully installed Net-Server-2.006
Successfully installed HTTP-Parser-XS-0.14
Successfully installed Data-Dump-1.21
Successfully installed Starman-0.3001
14 distributions installed
-----> Discovering process types
Procfile declares types -> (none)
Default types for Perl/PSGI Dancer! -> web
-----> Compiled slug size is 2.7MB
-----> Launching... done, v4
http://blazing-beach-7280.herokuapp.com deployed to Heroku
To git@heroku.com:blazing-beach-7280.git
* [new branch] master -> master
/tmp/heroku :master $
And you can confirm it works: Please note that the environment it runs on is deployment . The backend server it uses is the great Starman, also by the great Miyagawa. Now, if you add or change dependencies on Makefile.PL, next time you push, those will get updated. Very cool, right? :)

David Moreno: One year

A year ago today, I started working for Booking.com. I wish I could say that the time has flown by, but it really hasn t. It has been one hell of a ride on all fronts: work, learning experiences, friends, but specially at home, since working for this company didn t come without a complete life change. So far so good, and for that I m grateful :)

David Moreno: Twitter feed for Planet Perl Iron Man

I like to read Planet Perl Iron Man, but since I m less and less of a user of Google Reader these days, I prefer to follow interesting feeds on Twitter instead: I don t have to digest all of the content on my timeline, only when I m in the mood to see what s going on out there. So, if you wanna follow the account, find it as @perlironman. If interested, you can also follow me. That is all.

Next.

Previous.